use-‐case that introduced me to “big data” and truly needs the type of intui%on that gets described as “big data”. It has nothing to do with my current employment responsibili>es. 2. I will talk generically about the problem, with a focus on data processing and storage requirements. My goal is to uncover and sample the problem space. 3. At the end of the talk, you may find parallels with your “big data” problem, and can turn to a huge amount of wisdom and papers in the Internet adver>sing industry to come up with proper solu>ons and architecture. 4. Have fun, learn, and soak up some sun J
paid search adver>sements had become a dominant mone>za>on method in Internet search companies: ◦ Adver>sers liked that they paid for these adver>sements only when they were clicked – the age of “pay for performance” marke>ng had begun ◦ The cost per click (CPC) was decided by the bid placed by the adver>ser on the keywords in the search – however, only the top bidders were shown ini%ally. Later, this was replaced by a ranking of the top “expected revenue”, considering the recent history of clicks on each of the paid search adver>sements ◦ Given a handful of search companies, the adver>sers did not worry about losing an “opportunity” if they picked the right keywords and budget alloca>on among search companies usually by running some trials. 2. The world of adver>sing on web pages (display adver>sing) was however wildly different. There were so many web publishers, and liUle knowledge of who was surfing to which web page and when. 3. Most important to understand that adver%sers run product “marke>ng campaigns” for actual human eye-‐ balls. While they care about the web page or search results so that they don’t get associated with “disreputable” stuff, they don’t care that much more. They want their “demographic” from some>mes specific “geo” loca>ons, over a specified period of >me without repeatedly reaching and “>ring” the same person. The most important concepts for them are “reach” and “frequency”.
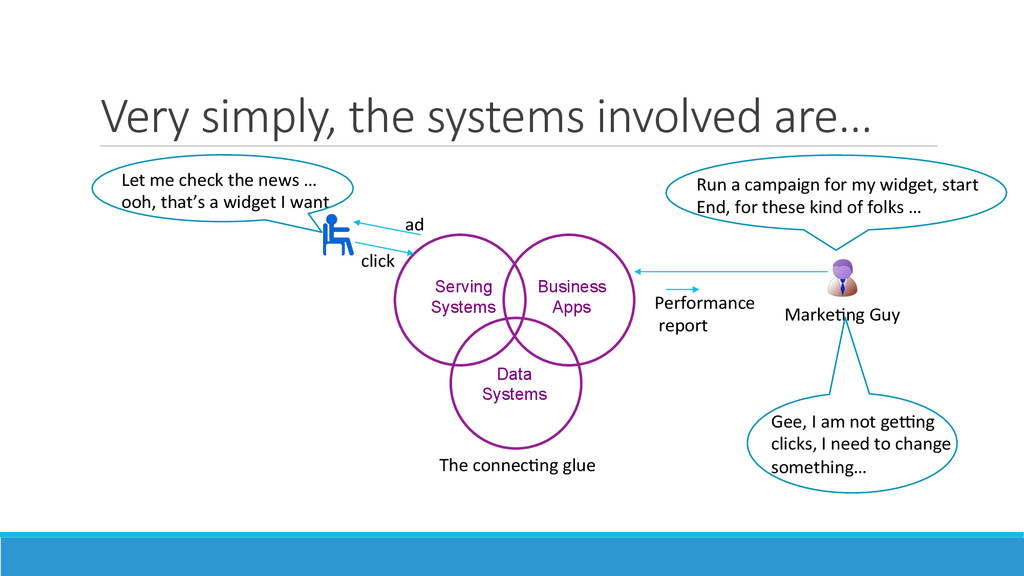
Data Systems Marke>ng Guy Run a campaign for my widget, start End, for these kind of folks … Performance report Gee, I am not ge]ng clicks, I need to change something… Let me check the news … ooh, that’s a widget I want ad click The connec>ng glue
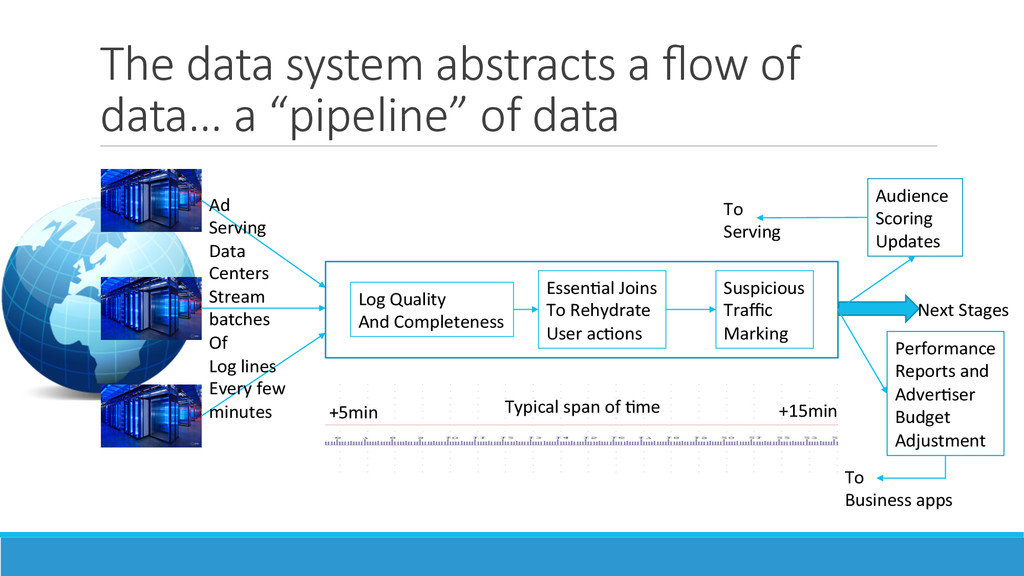
“pipeline” of data Ad Serving Data Centers Stream batches Of Log lines Every few minutes Log Quality And Completeness Essen>al Joins To Rehydrate User ac>ons Suspicious Traffic Marking +5min +15min Audience Scoring Updates Performance Reports and Adver>ser Budget Adjustment Next Stages Typical span of >me To Serving To Business apps
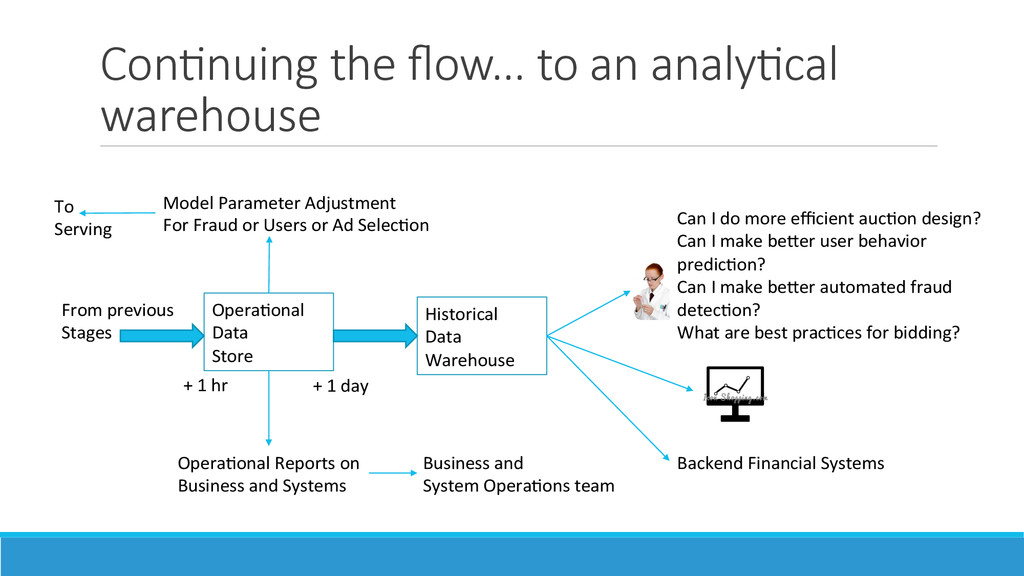
Stages Opera>onal Data Store Model Parameter Adjustment For Fraud or Users or Ad Selec>on Opera>onal Reports on Business and Systems + 1 hr + 1 day Historical Data Warehouse Can I do more efficient auc>on design? Can I make beUer user behavior predic>on? Can I make beUer automated fraud detec>on? What are best prac>ces for bidding? Backend Financial Systems To Serving Business and System Opera>ons team
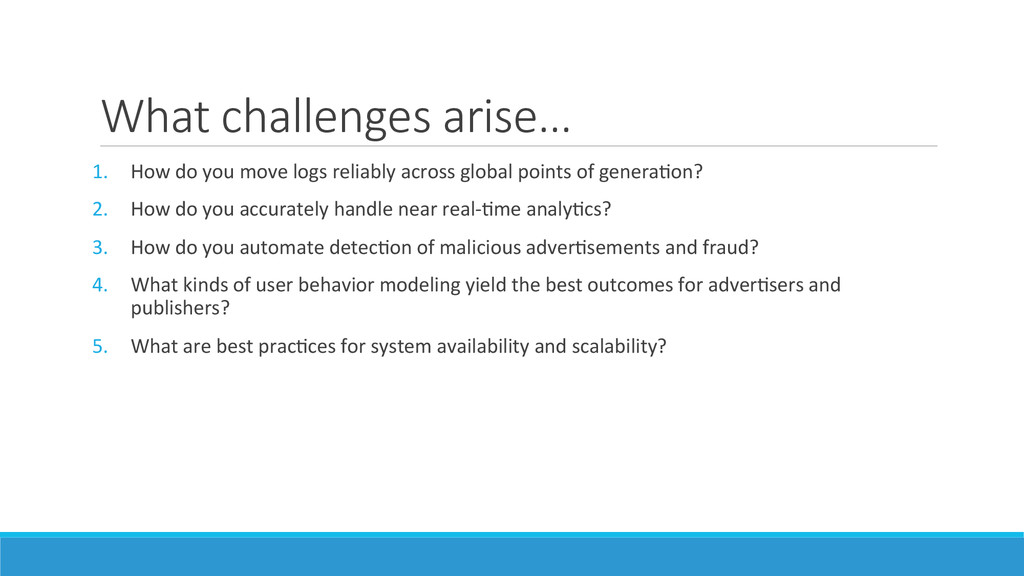
across global points of genera>on? 2. How do you accurately handle near real-‐>me analy>cs? 3. How do you automate detec>on of malicious adver>sements and fraud? 4. What kinds of user behavior modeling yield the best outcomes for adver>sers and publishers? 5. What are best prac>ces for system availability and scalability?
need to be >ghtly controlled for required fields and custom fields for various applica>ons. Design of libraries make sure that erroneous or skipped entry of fields by one subsystem or applica>on does not corrupt others by pu]ng each of them in spill-‐proof (oken nested) containers. Various applica>ons are allowed to change some parts of their schema without requiring coordina>on with the data team. 2. Counters from points of log genera>on are some>mes carried in-‐line or off-‐line for checking completeness of log collec>on over defined >me-‐periods. Books are maintained and closed when checks pass. When books cannot be closed, some es>mate of percentage completeness is sent to downstream systems for appropriate handling of payload. 3. Servers are adequately buffered for temporary network outages. Before buffers spill, the servers stop accep>ng ad serving requests. Servers are allowed to replay old buffers if not flushed. 4. Since many ad serving is done in “experimenta>on” mode – a lot of development has happened in how to effec%vely experiment with users. Phase A/B is well known, how about mul>-‐armed bandit?
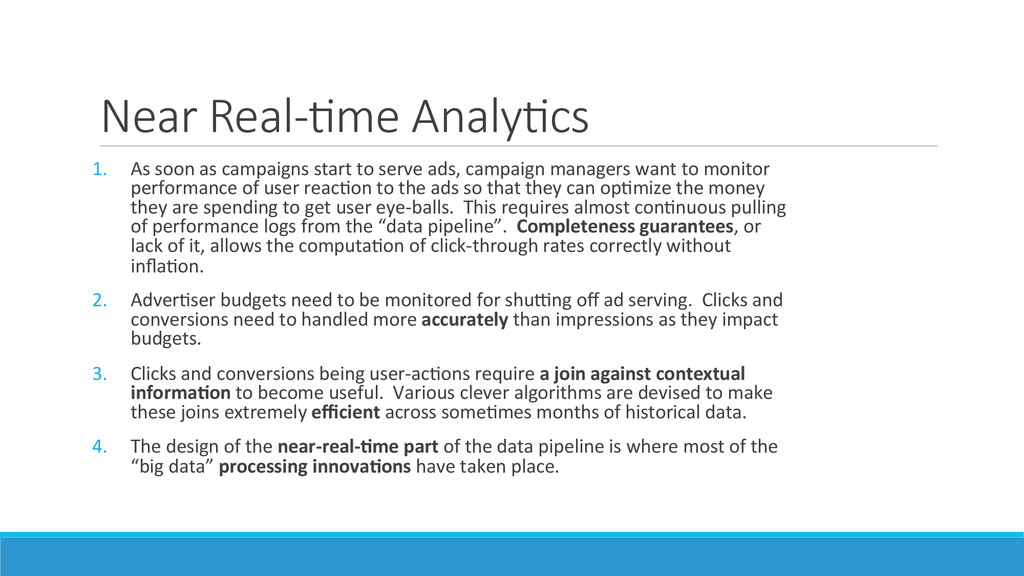
serve ads, campaign managers want to monitor performance of user reac>on to the ads so that they can op>mize the money they are spending to get user eye-‐balls. This requires almost con>nuous pulling of performance logs from the “data pipeline”. Completeness guarantees, or lack of it, allows the computa>on of click-‐through rates correctly without infla>on. 2. Adver>ser budgets need to be monitored for shu]ng off ad serving. Clicks and conversions need to handled more accurately than impressions as they impact budgets. 3. Clicks and conversions being user-‐ac>ons require a join against contextual informa%on to become useful. Various clever algorithms are devised to make these joins extremely efficient across some>mes months of historical data. 4. The design of the near-‐real-‐%me part of the data pipeline is where most of the “big data” processing innova%ons have taken place.
to be monitored for 1. Promo>on or selling of counterfeit, illegal, or fraudulent goods and services; 2. False, misleading claims; 3. Leading users to unsafe or phishing sites or sites that cause them to download malware; 4. Leading to other adver>sements in some kind of arbitrage se]ng; 5. And the list is endless… This is the area of vigorous machine learning working with human supervision for tracking quality of ads. A few False posi>ves and False nega>ves can both have adverse effects and so the machine learning is done with very high stakes. hUp://www.engadget.com/ 2014/10/24/cryptowall-‐ ransomware-‐aUack-‐ proofpoint-‐report/? ncid=rss_truncated A widespread aUack has exposed millions to malware that holds files to ransom. The campaign, which was first detected a month ago, placed fake adverts on websites such as Yahoo, AOL and The Atlan*c that installed so-‐called "ransomware" onto a vic>m's computer….
behavior How much of recent historical user behavior is predic>ve of future behavior? 1. In search, immediate click history of the keywords localized by geography appropriately is oken preUy good; 2. In display, click history is modeled in different categories of user interests with different decay rates of interest. A user is put in several categories given his or her recent history and used to compute the appropriate ad with most likelihood of clicking. 3. Some>mes, the content of the page along with user history is used to choose an ad. There is no “good” answer – oken ads need to be experimented with con>nuously. This is again a very ac>ve field for supervised machine learning. Also, has legal implica>ons regarding protec>ng privacy of user data, and respec>ng of “opt-‐out”.
always, ac>ve machine. Great pains is taken for local fault recovery, as well as big geographic disasters. Typically – 1. Data centers separated tectonically and influenced by different weather and other natural disaster systems are used to run processing with similar intent and event streams but as much other kinds of independence as possible; 2. Data checksums are frequently compared for divergences for a core, complete, and minimal data-‐set. The secondary system is usually made to follow the primary but cause for divergences are carefully inves>gated. 3. Procedures exist to quickly bring up another secondary if per chance the primary had to be replaced by the secondary.
systems bought machines for processing and storage separately. Near real >me processing bought machines by throughput, and later stages by storage. With new genera>on systems like Hadoop that combine processing and storage, throughput or storage whichever is the most demanding wins capacity planning. Not always the wisest move! 2. Running debate rages whether capacity should be planned by worst case scenario, or with average expected scenario. Not unlike what happens with telecom capacity … should it be mostly available, or available when people need it so much that it overwhelms average capacity? 3. Machine replacement before they actually die is an evolving art. 4. Capacity costs, and opera>onal costs some>mes are usually the biggest and trickiest line-‐ items to manage and predict for growth. Opera>onal intelligence is an evolving science.
I could. Hope this has been interes>ng, and a liUle bit enlightening! 2. Note that I have not men>oned Hadoop or any par>cular data fabric. The business needs are so severe that they automa>cally get to “create” a Hadoop like system as a solu>on. But note that “Hadoop” may not be the only solu>on and over >me may not be a solu>on at all. 3. Machine Learning is not a nice-‐to-‐have – it is a “must have” in many places (I have pointed out only a few areas but lek out things like inventory or demand forecas>ng or ad selec>on.) 4. Stream processing, No-‐SQL processing, fast batch processing, centralized schedulers with intelligence of retries and recovery of datasets under management, decentralized schedulers with easy crea>on and scalability all get to play a part in one way or another. 5. The field is ge]ng into mul>-‐tenancy for publishers and adver>sers to bring their own processing to the data – an interes>ng development to be tracked. THANK YOU!


 teamclairvoyant
 taketakekaho
 endonanana
 iktakahiro
 takonda
 techtekt
 rfdnxbro
 ymotongpoo
 odashi
 terurou
 usanchuu
 jozono
 makocchi
 varn
 mlcsv
 skoyamalab
 samlambert
 rasmusluckow
 shlominoach
 inesmontani
 bcantrill
 marktimemedia
 frankvandijk
 lemiorhan