Share
Embed

Transcript
23 slides
-
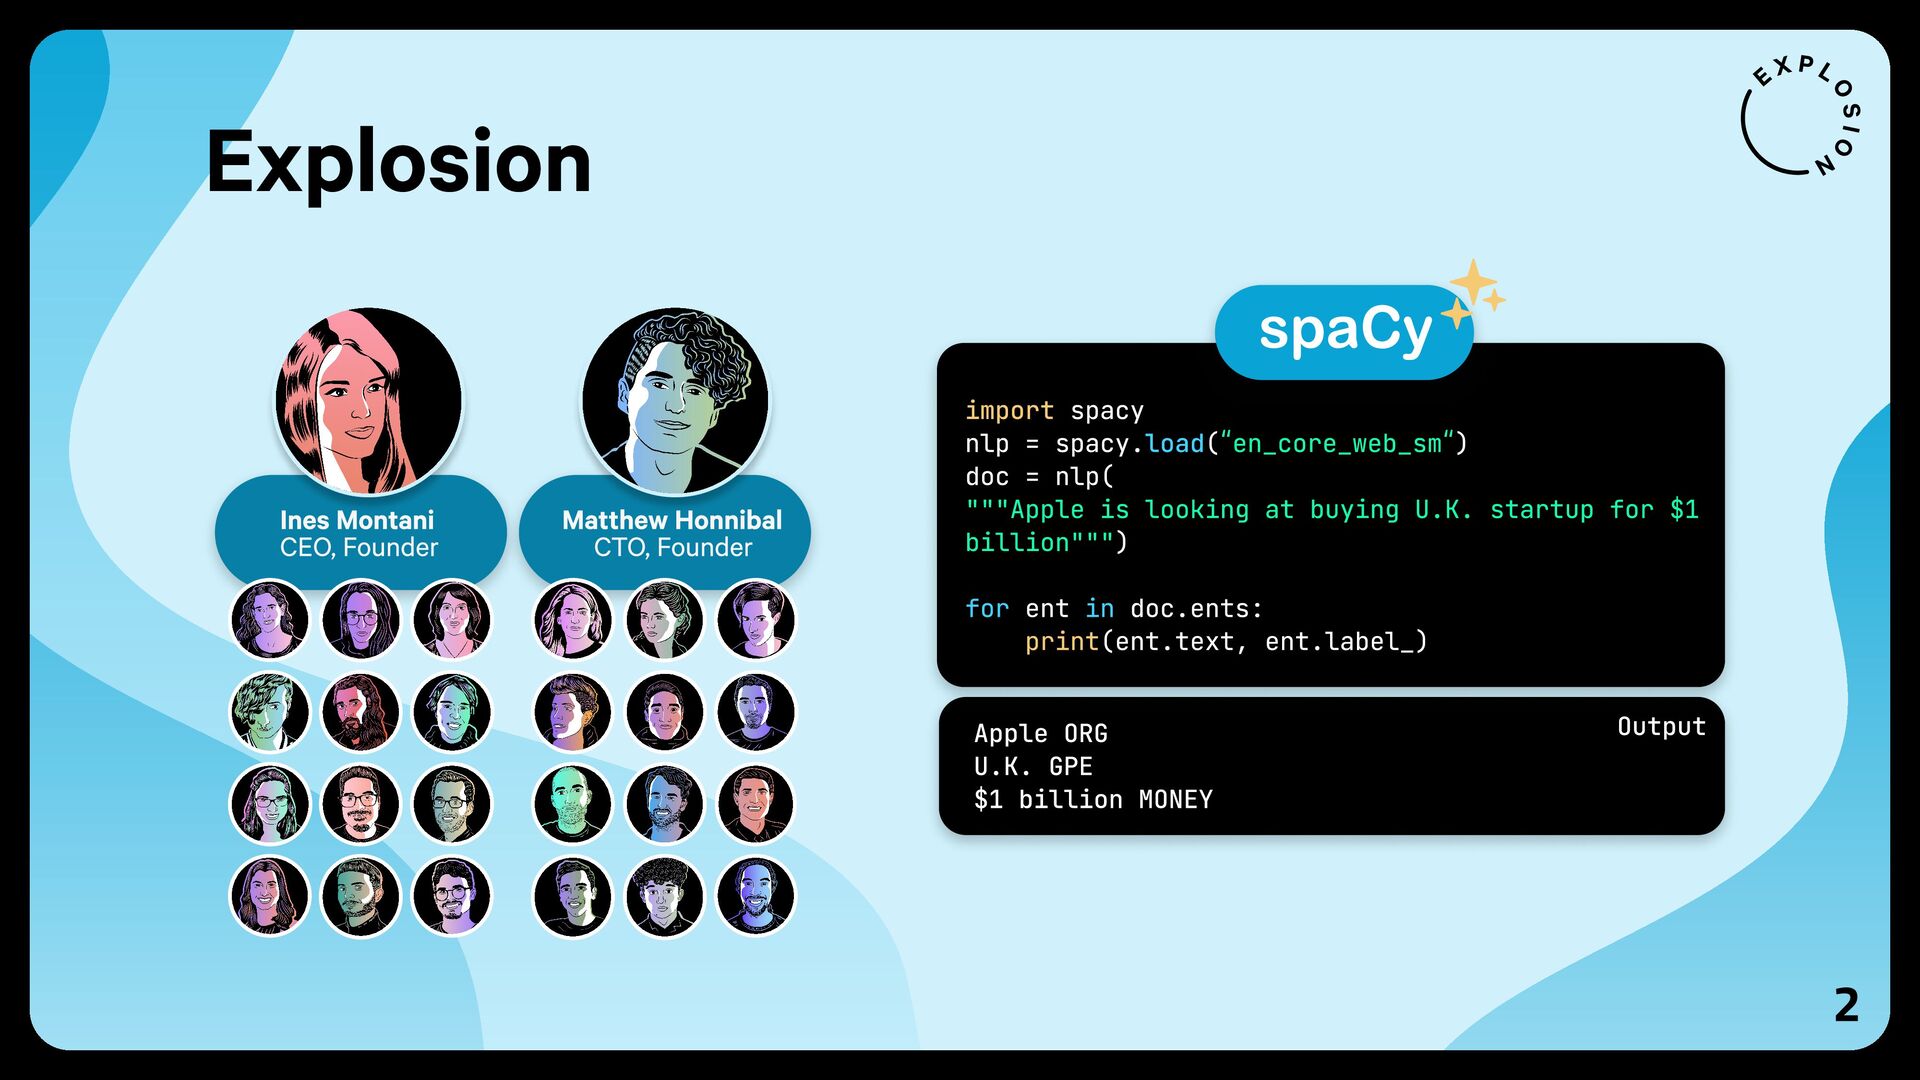
2 Apple ORG U.K. GPE $1 billion MONEY Output import
print spacy nlp = spacy. ( ) doc = nlp( ) ent doc.ents: (ent.text, ent.label_) load for in “en_core_web_sm“ """Apple is looking at buying U.K. startup for $1 billion""" Matthew Honnibal CTO, Founder Ines Montani CEO, Founder Explosion -
3 About this presentation Akos Kadar Machine Learning Engineer Victoria
Slocum Developer Advocate Live Demo Case study #2 Pipelines for entities Slide 15-21 Case study #1 Rulers & NER Slide 4-14 Intro to spaCy and components Slide 23 Wrap up and questions -
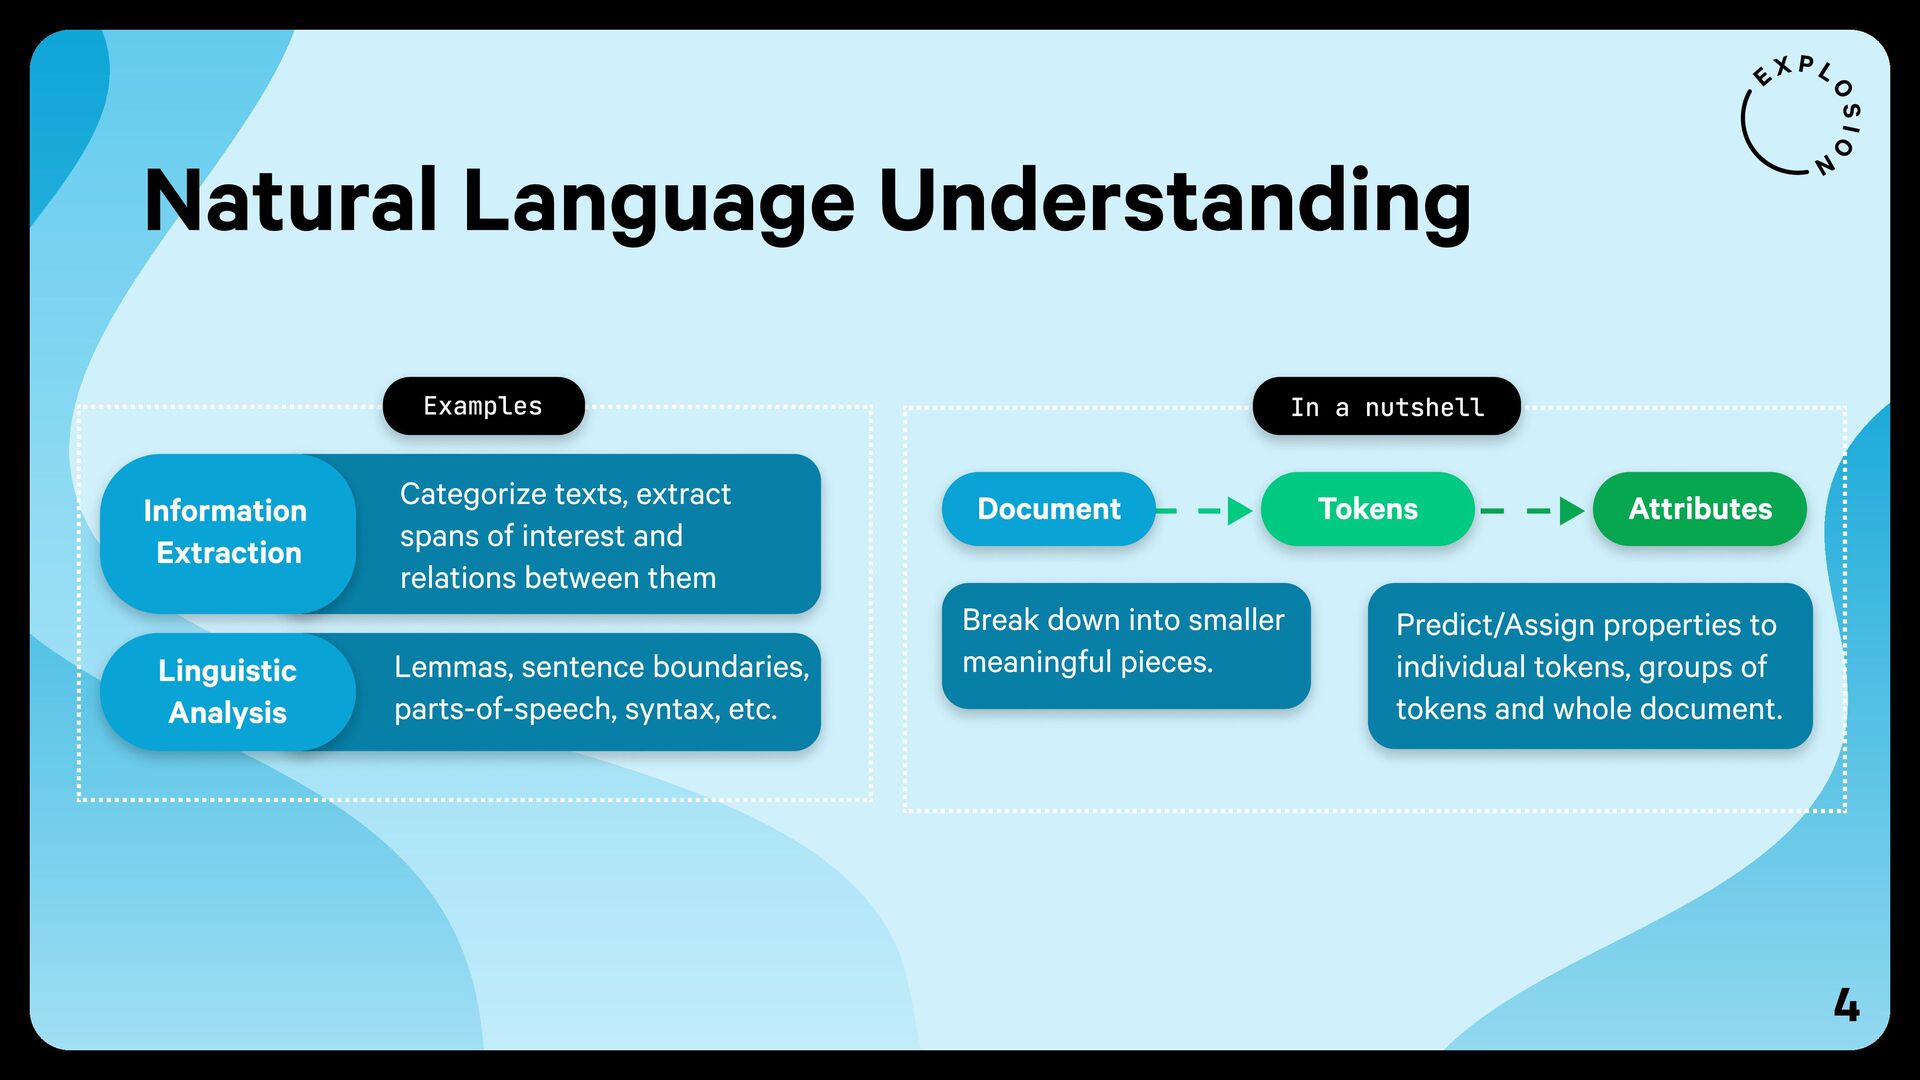
4 Natural Language Understanding Document Tokens Attributes Break down into
smaller meaningful pieces. Predict/Assign properties to individual tokens, groups of tokens and whole document. In a nutshell Categorize texts, extract spans of interest and relations between them Lemmas, sentence boundaries, parts-of-speech, syntax, etc. Examples Information Extraction Linguistic Analysis -
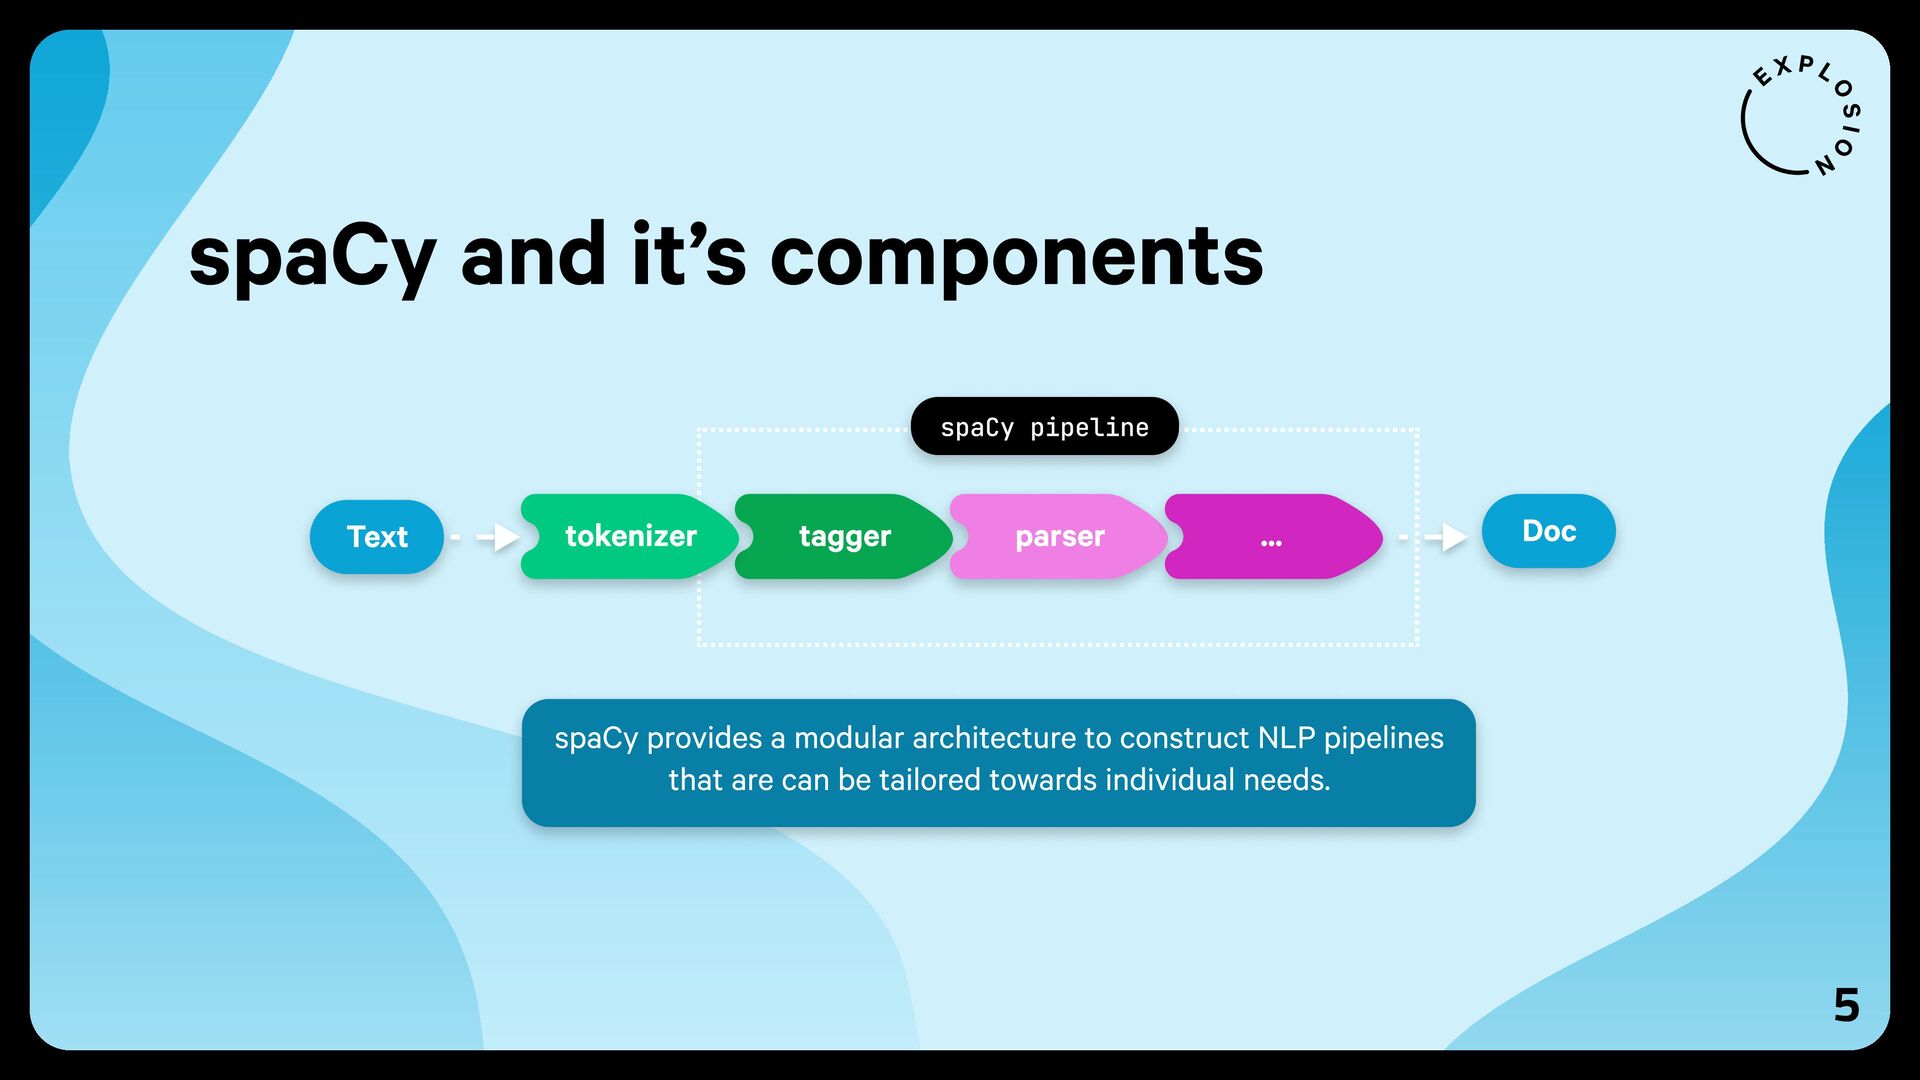
5 spaCy and it’s components spaCy provides a modular architecture
to construct NLP pipelines that are can be tailored towards individual needs. Text Doc tagger parser ... spaCy pipeline tokenizer -
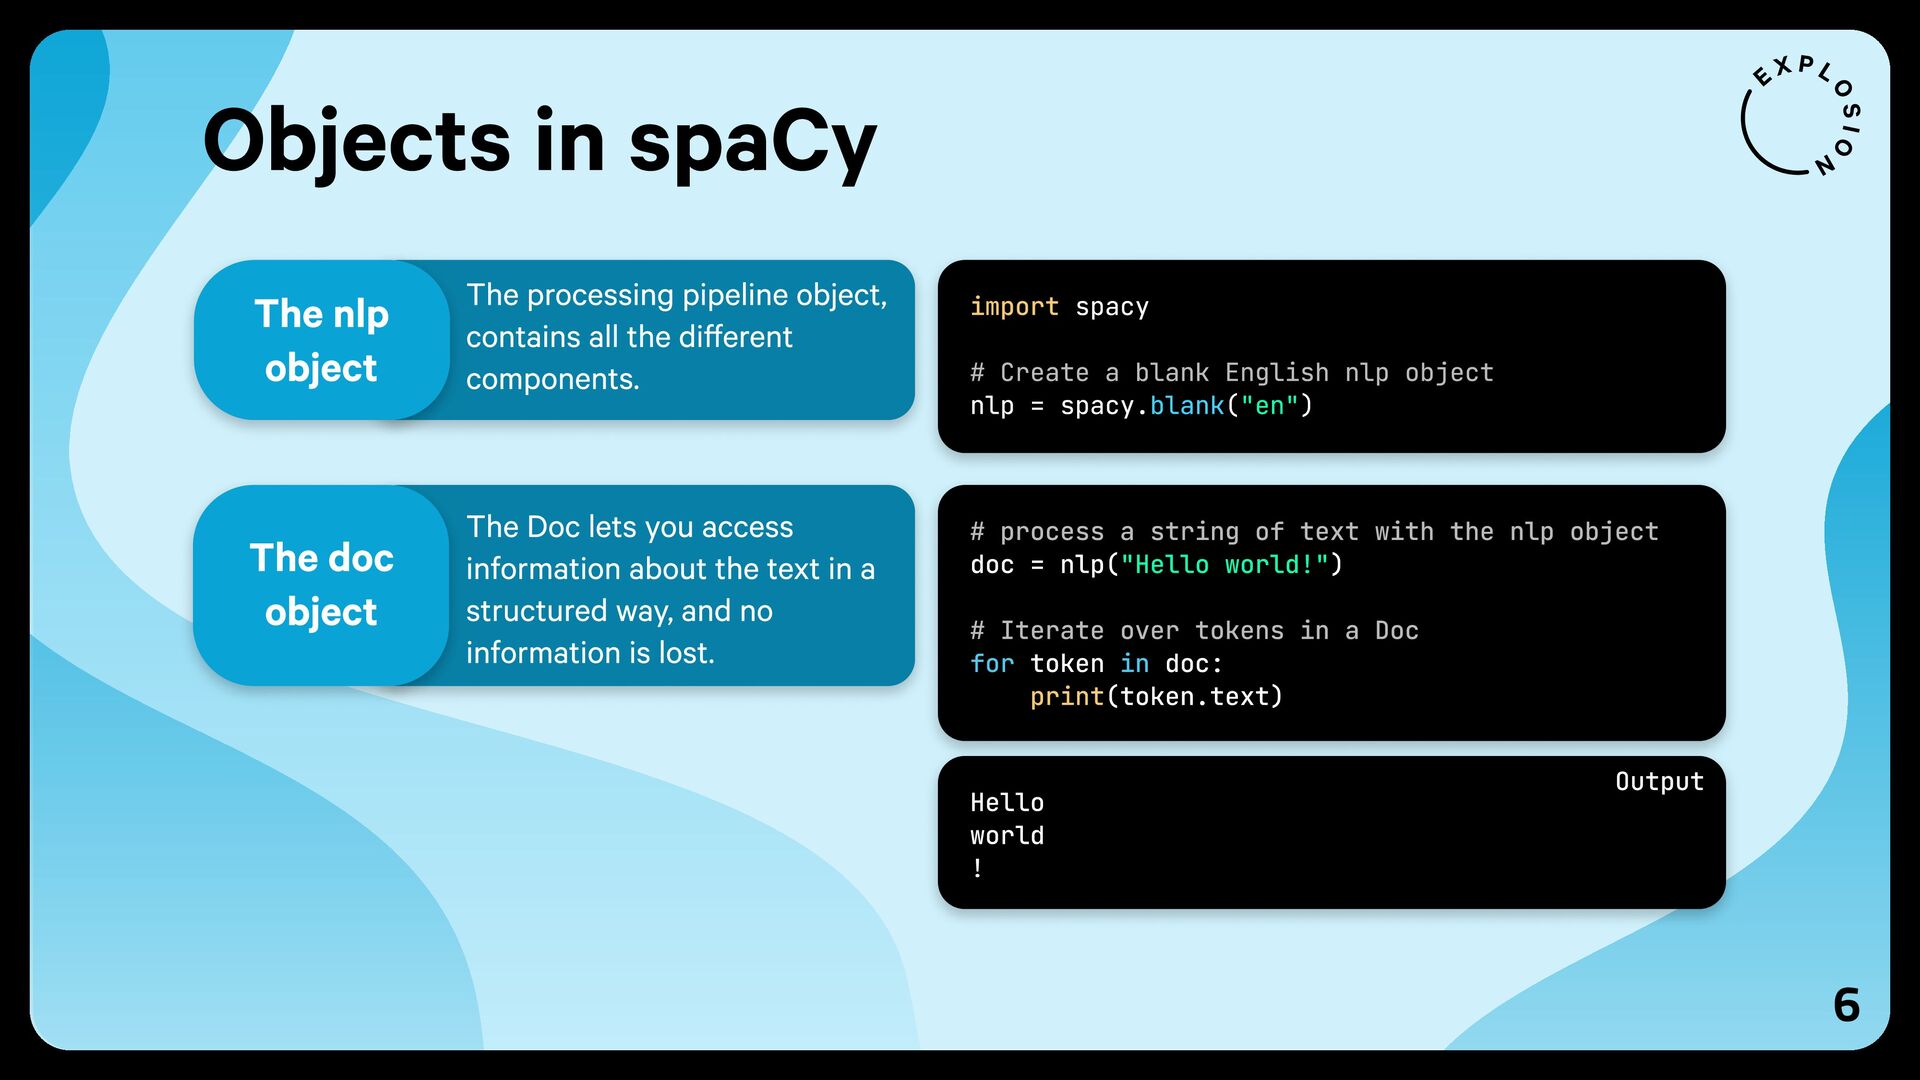
6 The processing pipeline object, contains all the different components.
The nlp object import spacy nlp = spacy. ( ) # Create a blank English nlp object blank "en" The Doc lets you access information about the text in a structured way, and no information is lost. The doc object # process a string of text with the nlp object # Iterate over tokens in a Doc doc = nlp( ) token doc: (token.text) "Hello world!" for in print Hello world ! Output Objects in spaCy -
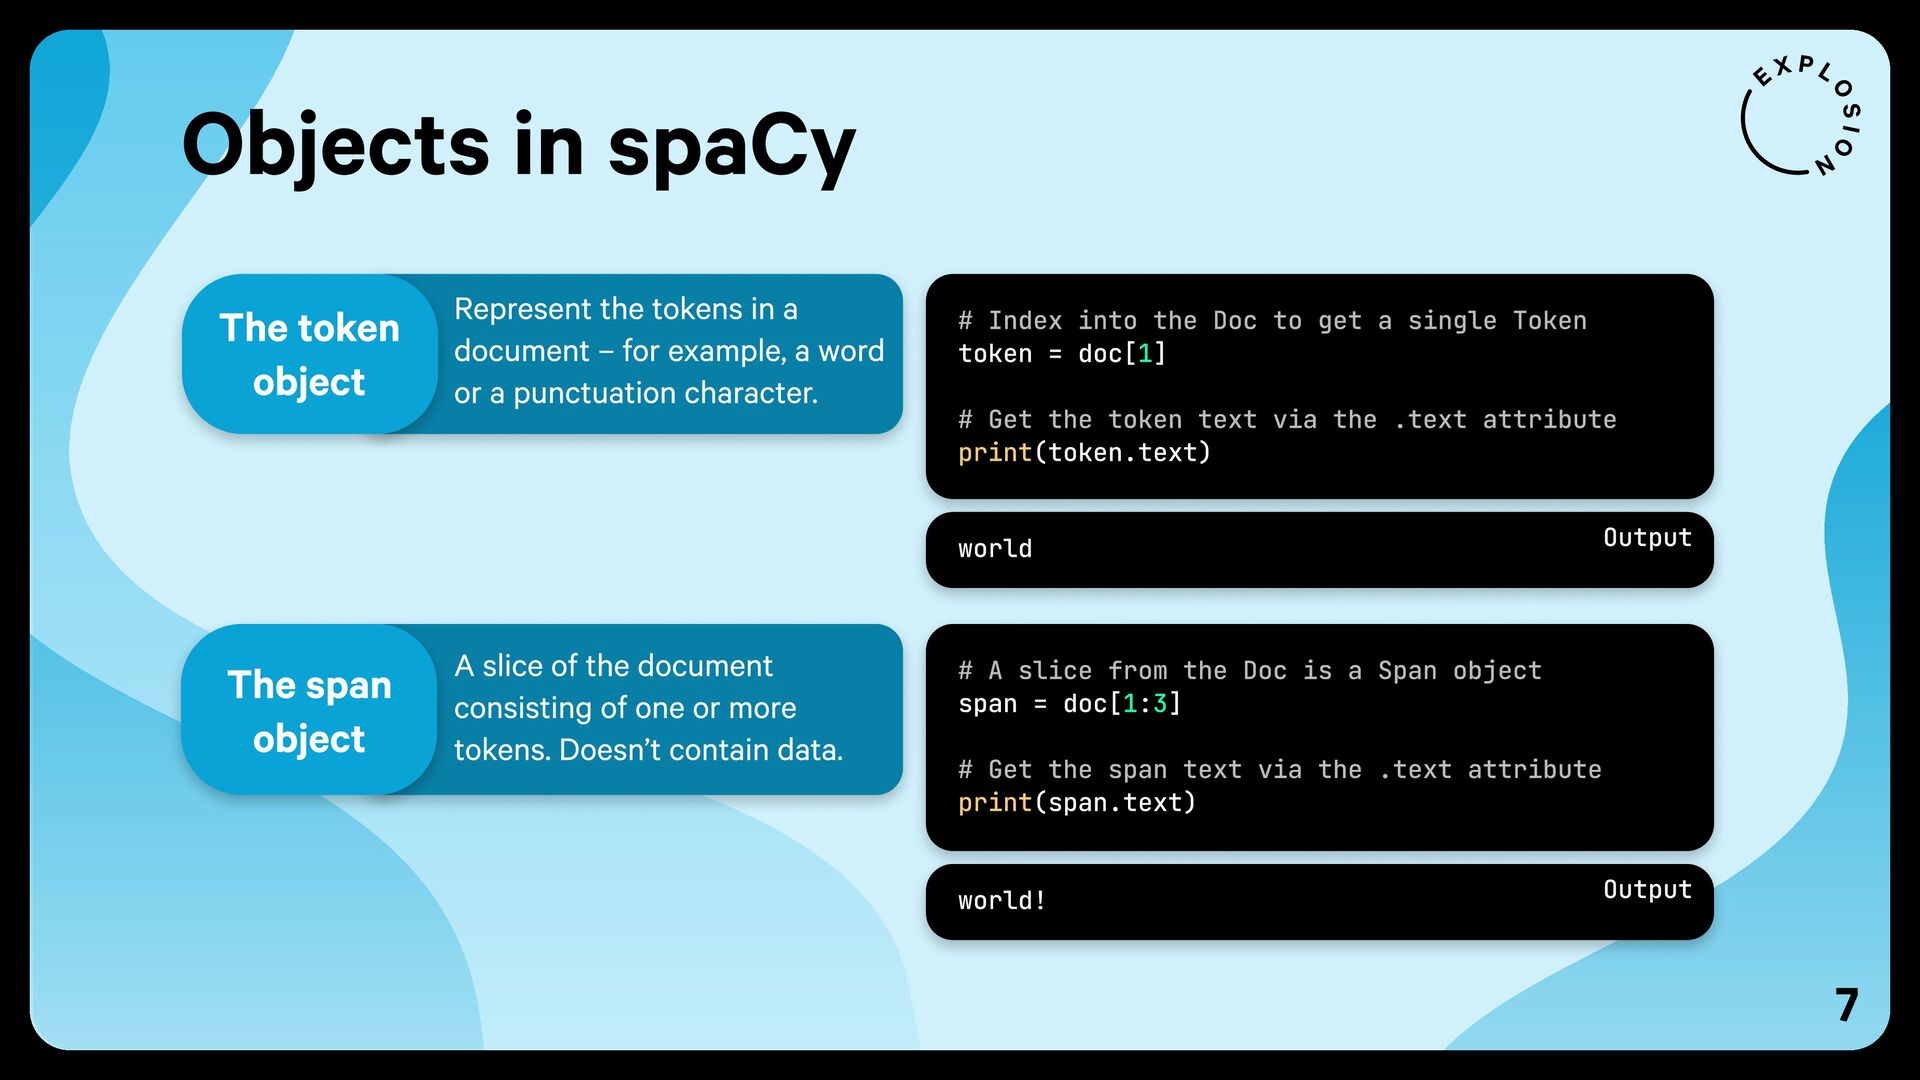
7 Represent the tokens in a document – for example,
a word or a punctuation character. The token object # Index into the Doc to get a single Token # Get the token text via the .text attribute token = doc[ ] (token.text) 1 print A slice of the document consisting of one or more tokens. Doesn’t contain data. The span object # A slice from the Doc is a Span object # Get the span text via the .text attribute span = doc[ : ] (span.text) 1 3 print Objects in spaCy world Output world! Output -
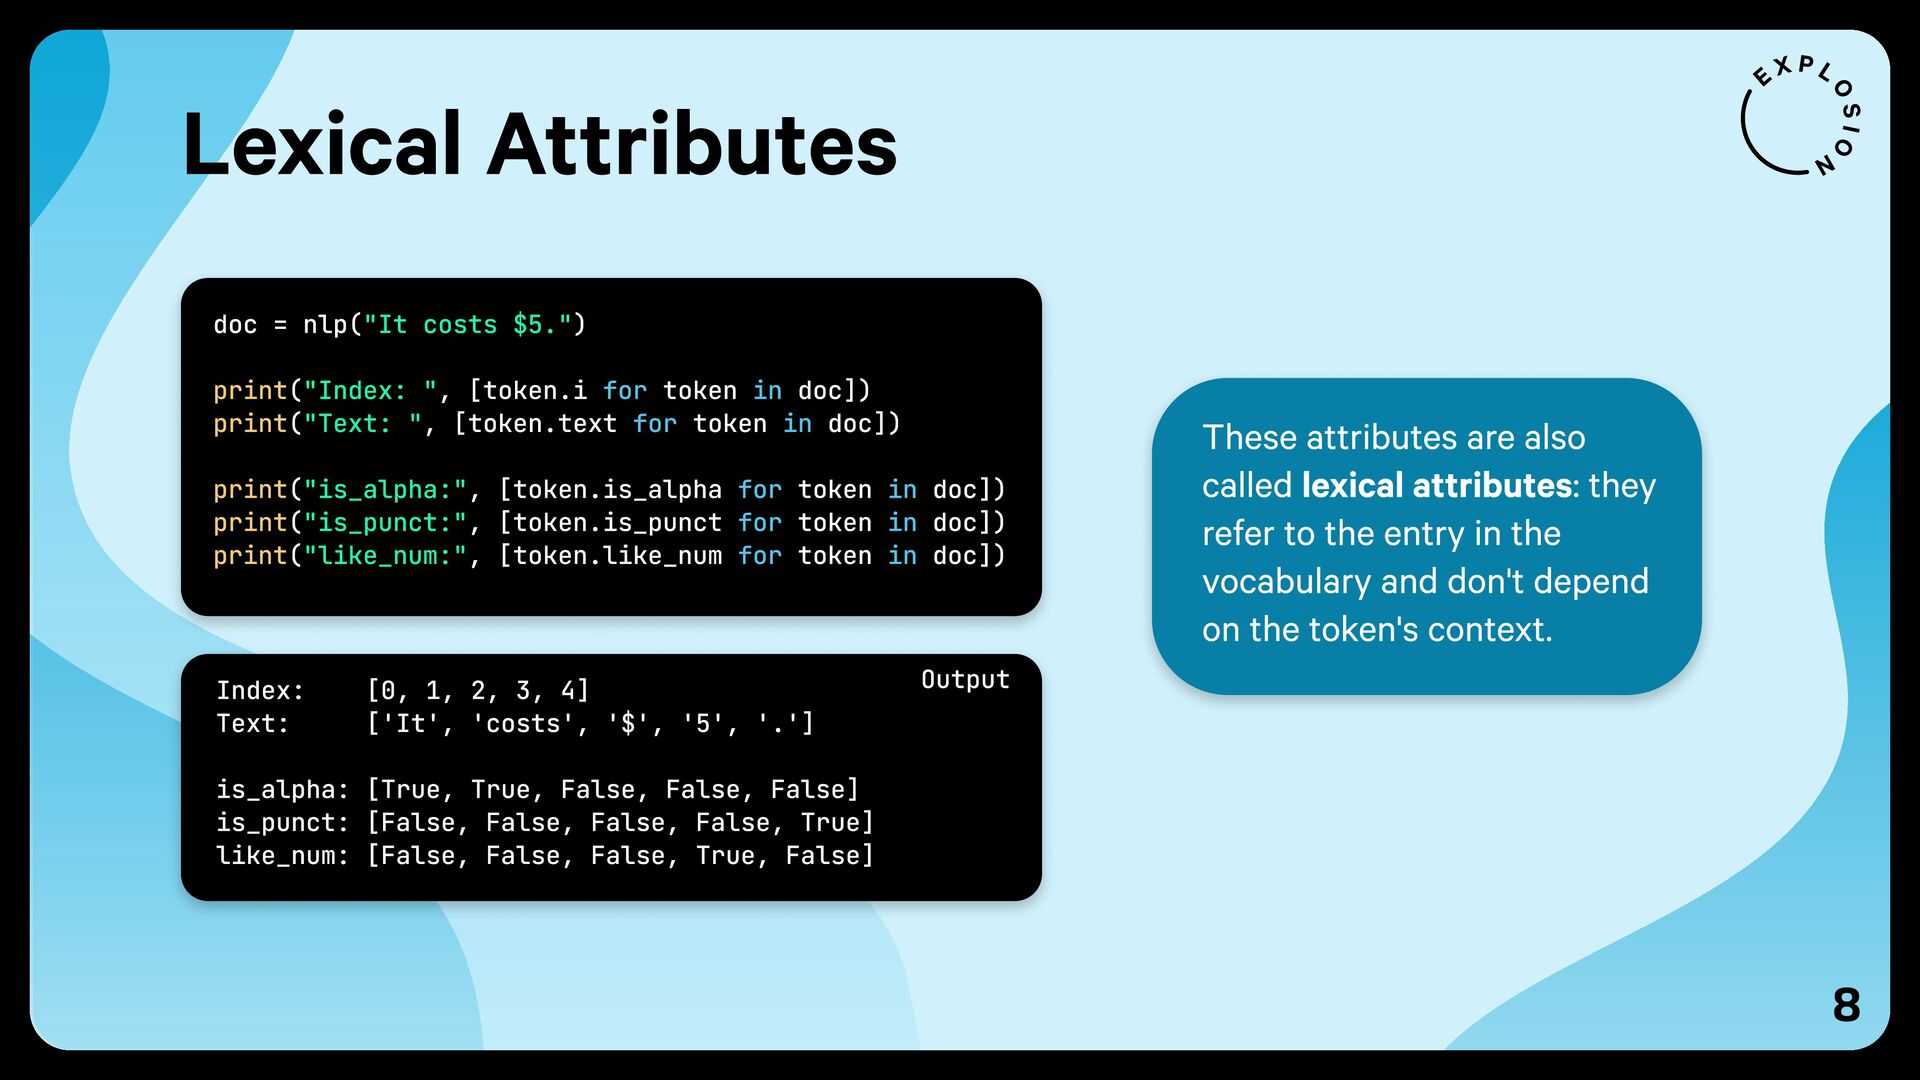
8 These attributes are also called lexical attributes: they refer
to the entry in the vocabulary and don't depend on the token's context. doc = nlp( ) ( , [token.i token doc]) ( , [token.text token doc]) ( , [token.is_alpha token doc]) ( , [token.is_punct token doc]) ( , [token.like_num token doc]) "It costs $5." "Index: " "Text: " "is_alpha:" "is_punct:" "like_num:" print print print print print for in for in for in for in for in Lexical Attributes Index: [0, 1, 2, 3, 4] Text: ['It', 'costs', '$', '5', '.'] is_alpha: [True, True, False, False, False] is_punct: [False, False, False, False, True] like_num: [False, False, False, True, False] Output -
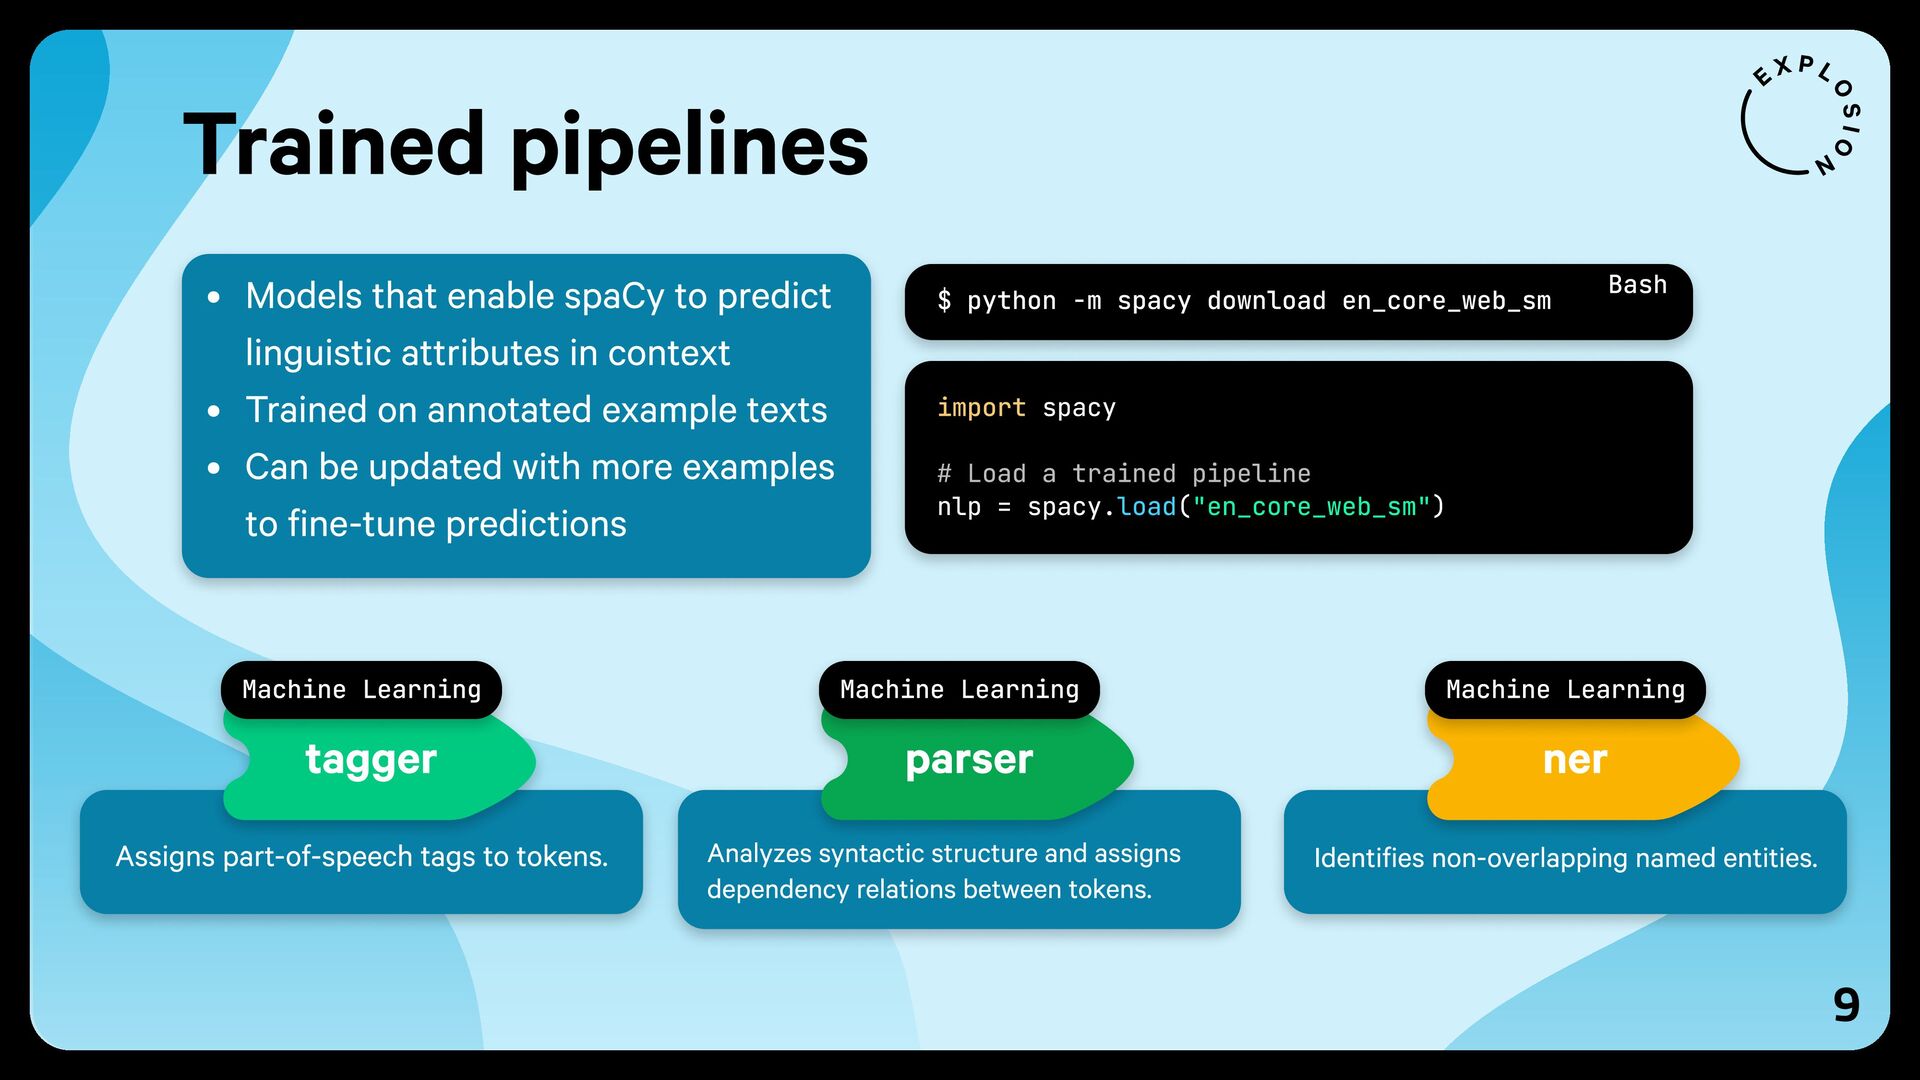
9 Trained pipelines import spacy nlp = spacy. ( )
# Load a trained pipeline load "en_core_web_sm" $ python -m spacy download en_core_web_sm Bash e Models that enable spaCy to predict linguistic attributes in contex e Trained on annotated example texth e Can be updated with more examples to fine-tune predictions Assigns part-of-speech tags to tokens. tagger Machine Learning Analyzes syntactic structure and assigns dependency relations between tokens. parser Machine Learning Identifies non-overlapping named entities. ner Machine Learning -
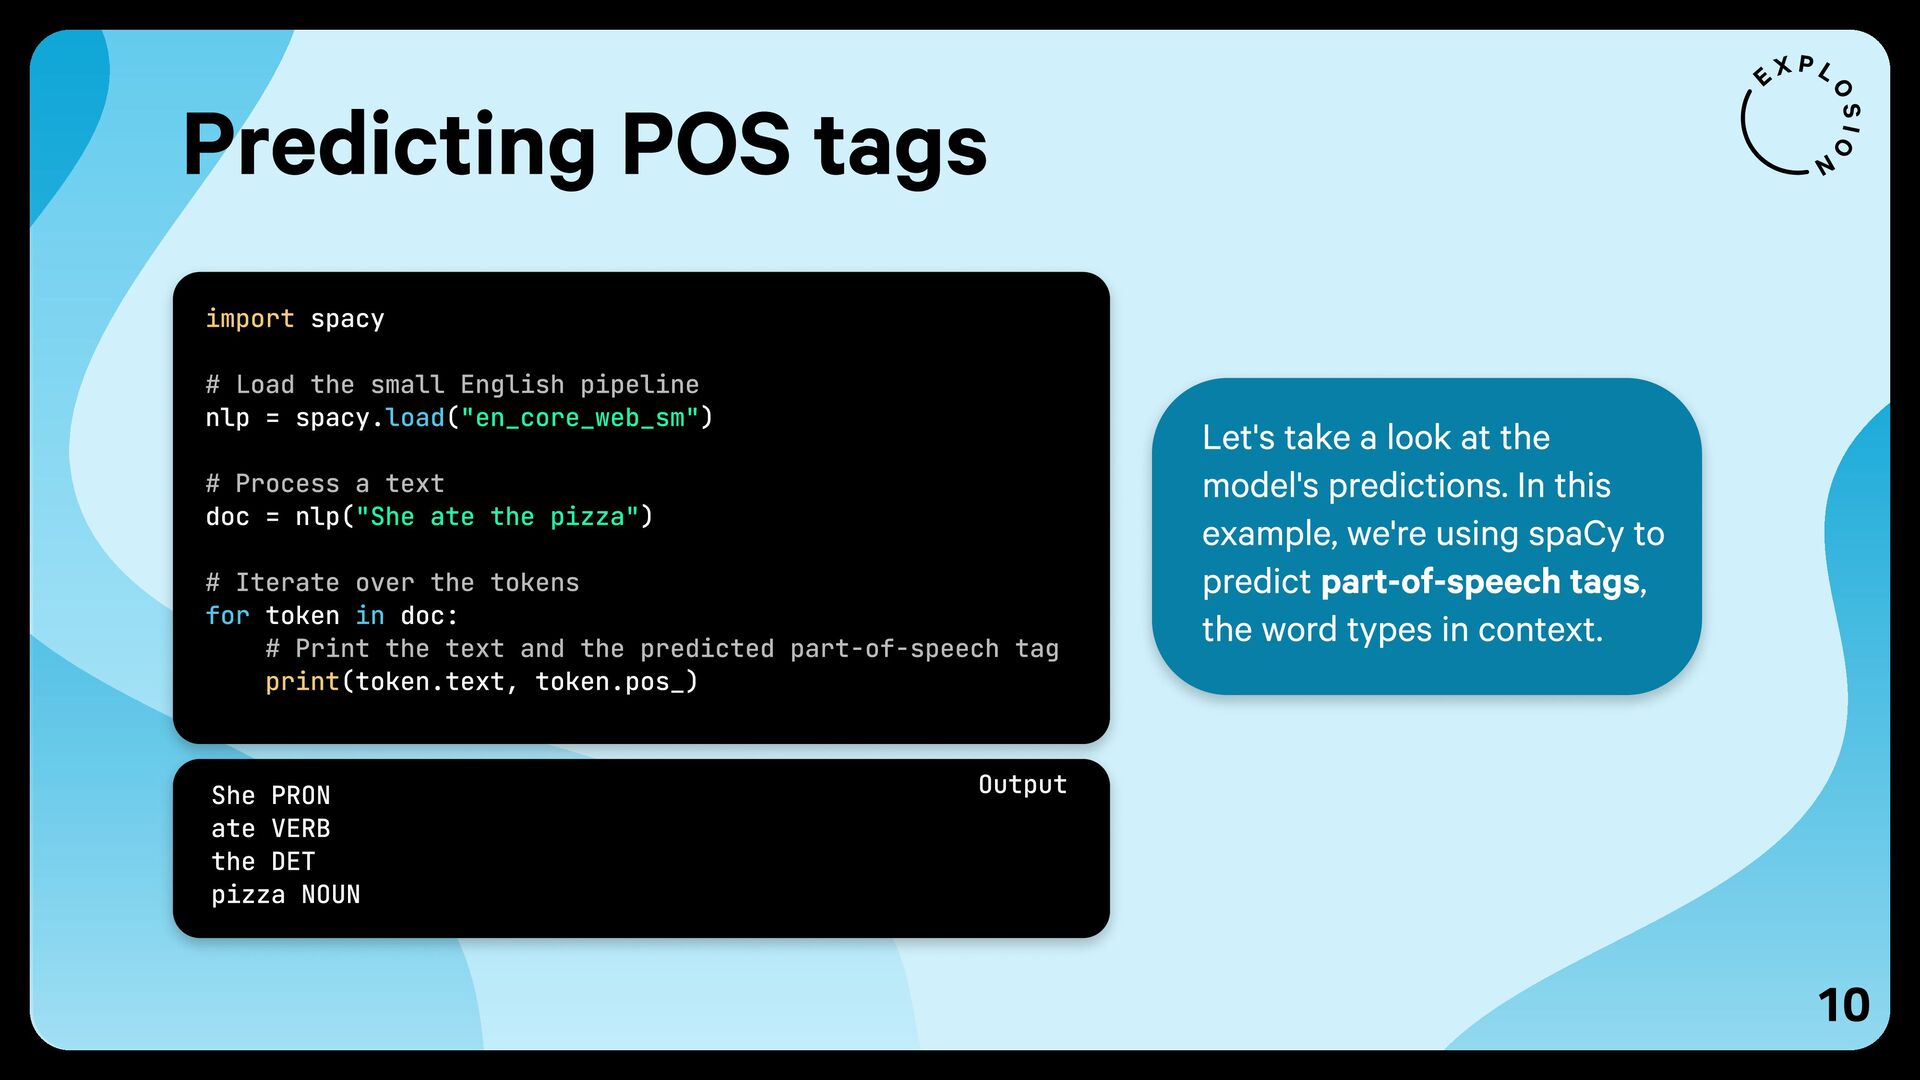
10 Let's take a look at the model's predictions. In
this example, we're using spaCy to predict part-of-speech tags, the word types in context. import print spacy nlp = spacy. ( ) doc = nlp( ) token doc: (token.text, token.pos_) # Load the small English pipeline # Process a text # Iterate over the tokens # Print the text and the predicted part-of-speech tag load for in "en_core_web_sm" "She ate the pizza" Predicting POS tags She PRON ate VERB the DET pizza NOUN Output -
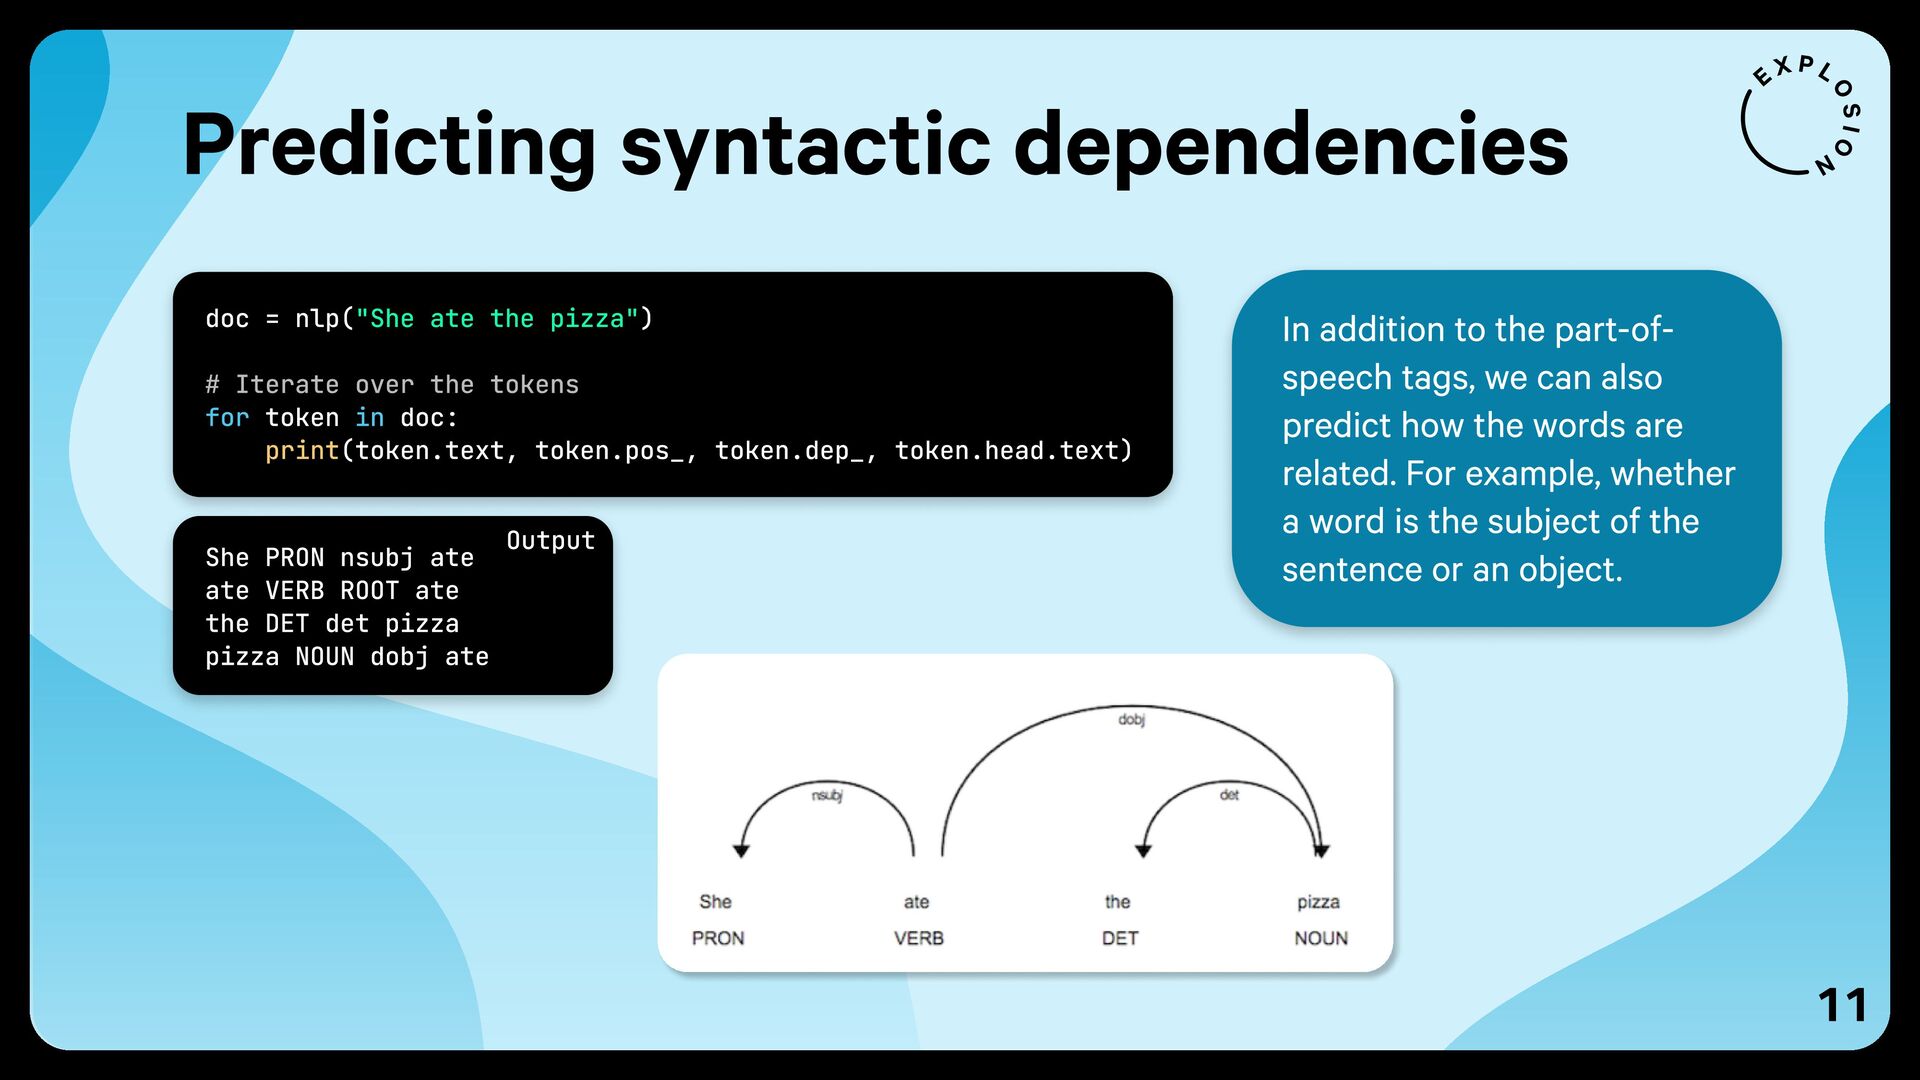
11 In addition to the part-of- speech tags, we can
also predict how the words are related. For example, whether a word is the subject of the sentence or an object. doc = nlp( ) token doc: (token.text, token.pos_, token.dep_, token.head.text) "She ate the pizza" # Iterate over the tokens for in print Predicting syntactic dependencies She PRON nsubj ate ate VERB ROOT ate the DET det pizza pizza NOUN dobj ate Output -
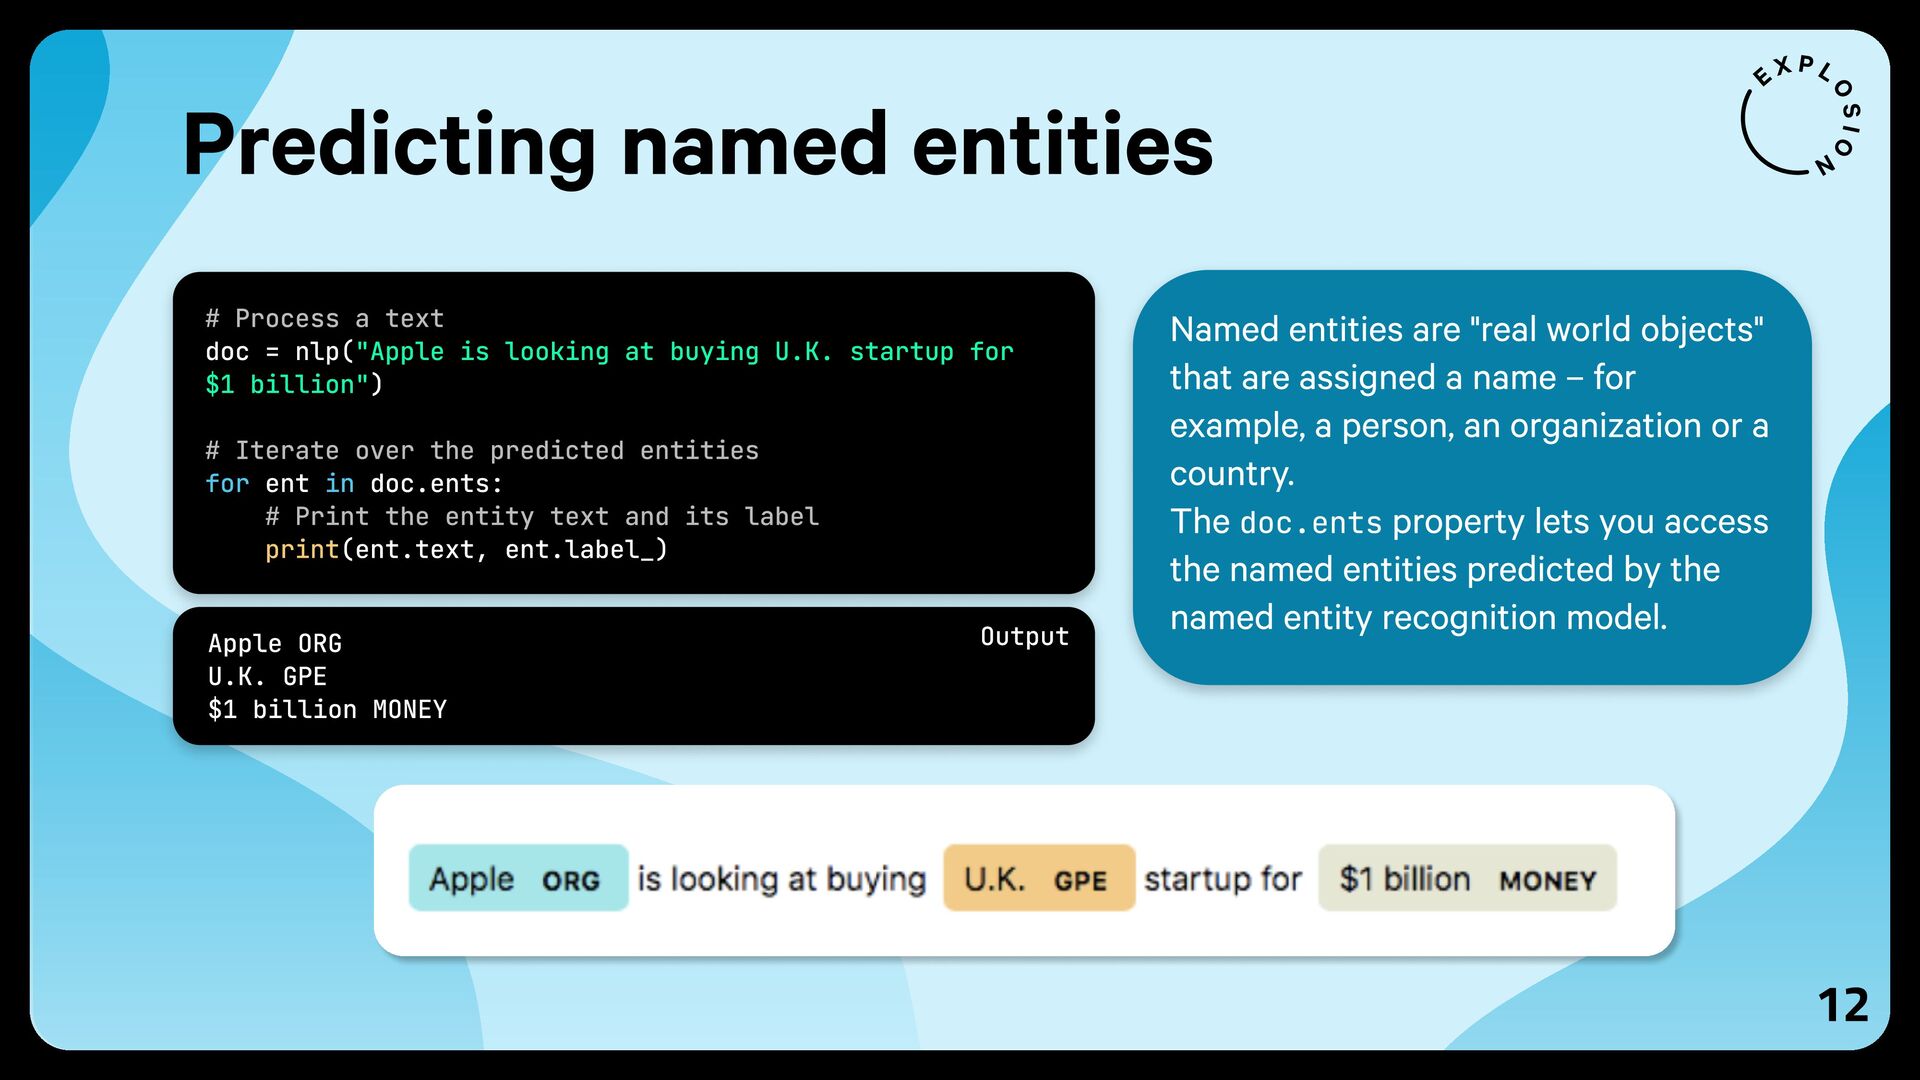
12 Named entities are "real world objects" that are assigned
a name – for example, a person, an organization or a country. The doc.ents property lets you access the named entities predicted by the named entity recognition model. # Process a text # Iterate over the predicted entities # Print the entity text and its label doc = nlp( ) ent doc.ents: (ent.text, ent.label_) "Apple is looking at buying U.K. startup for $1 billion" for in print Predicting named entities Apple ORG U.K. GPE $1 billion MONEY Output -
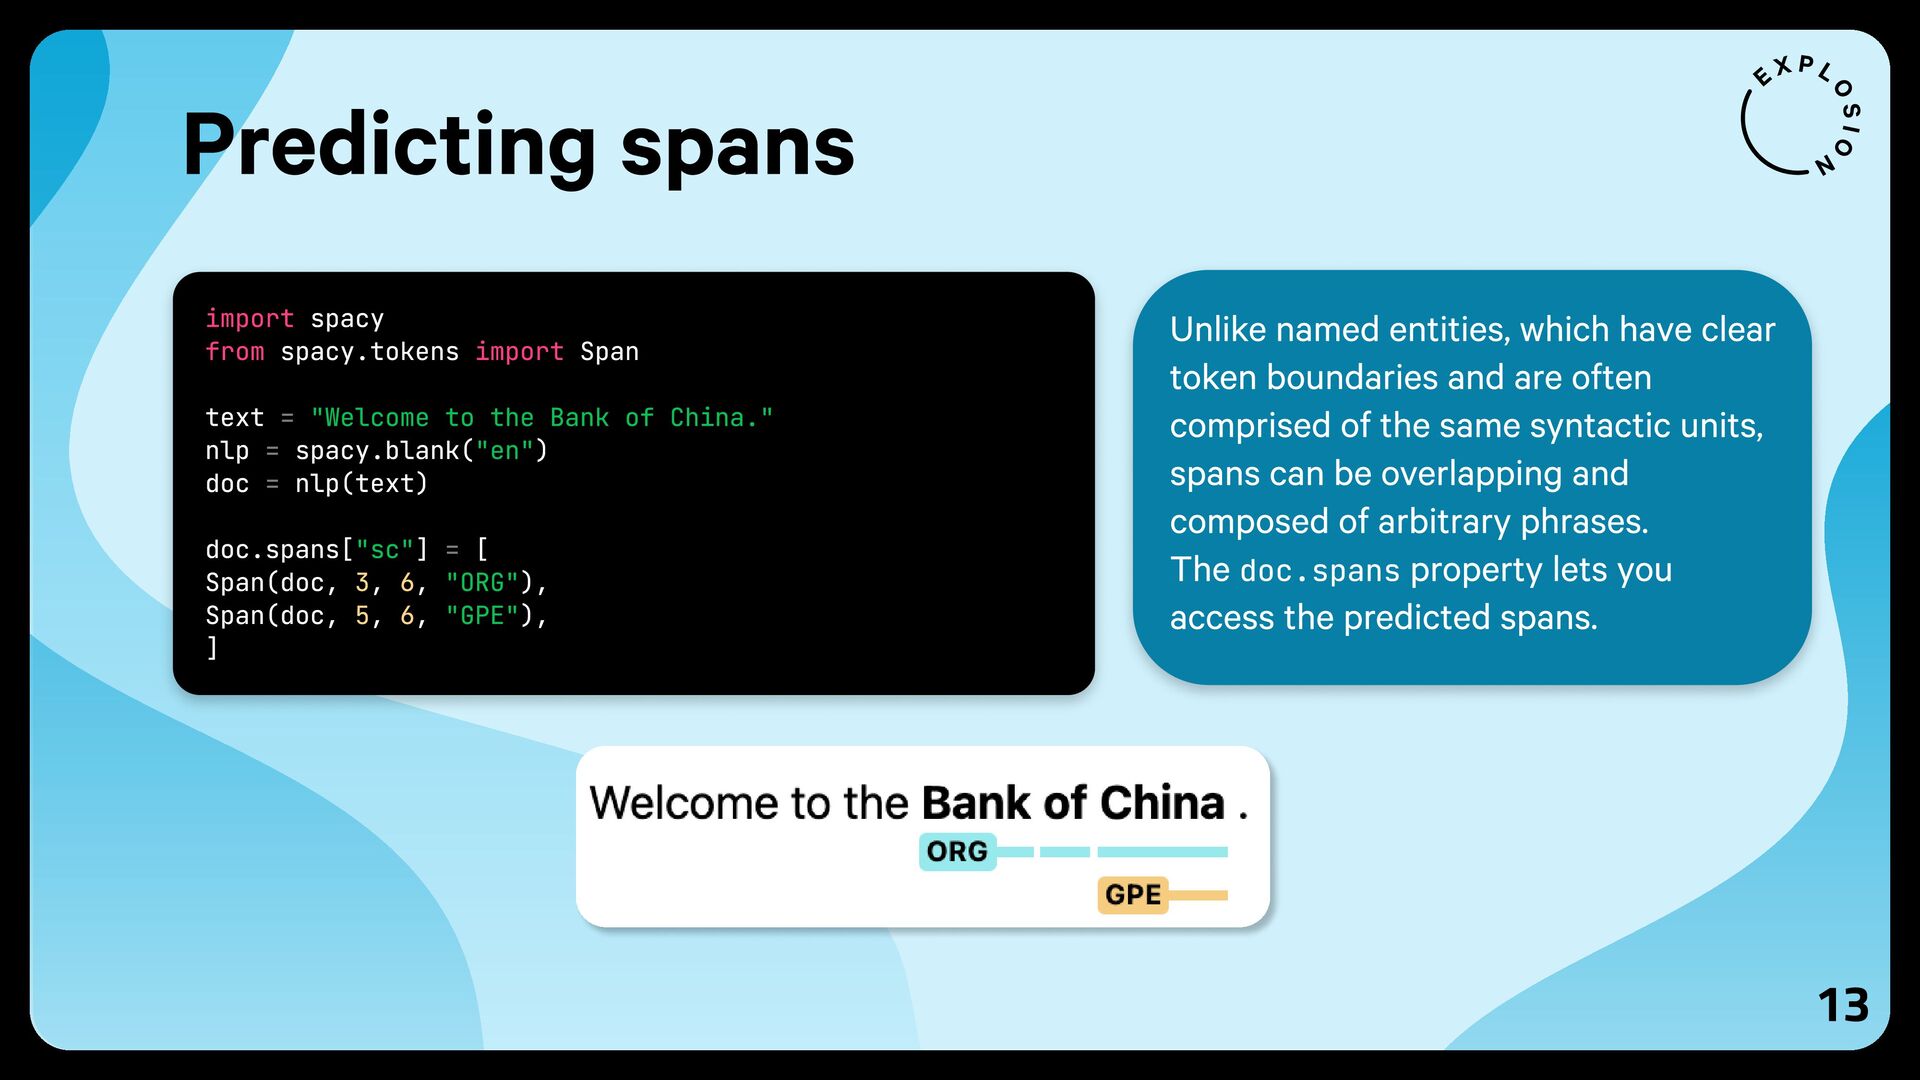
13 Unlike named entities, which have clear token boundaries and
are often comprised of the same syntactic units, spans can be overlapping and composed of arbitrary phrases. The doc.spans property lets you access the predicted spans. import from import spacy spacy.tokens Span text nlp spacy.blank( ) doc nlp(text) doc.spans[ ] [ Span(doc, , , ), Span(doc, , , ), ] = = = = "Welcome to the Bank of China." "en" "sc" "ORG" "GPE" 3 6 5 6 Predicting spans -
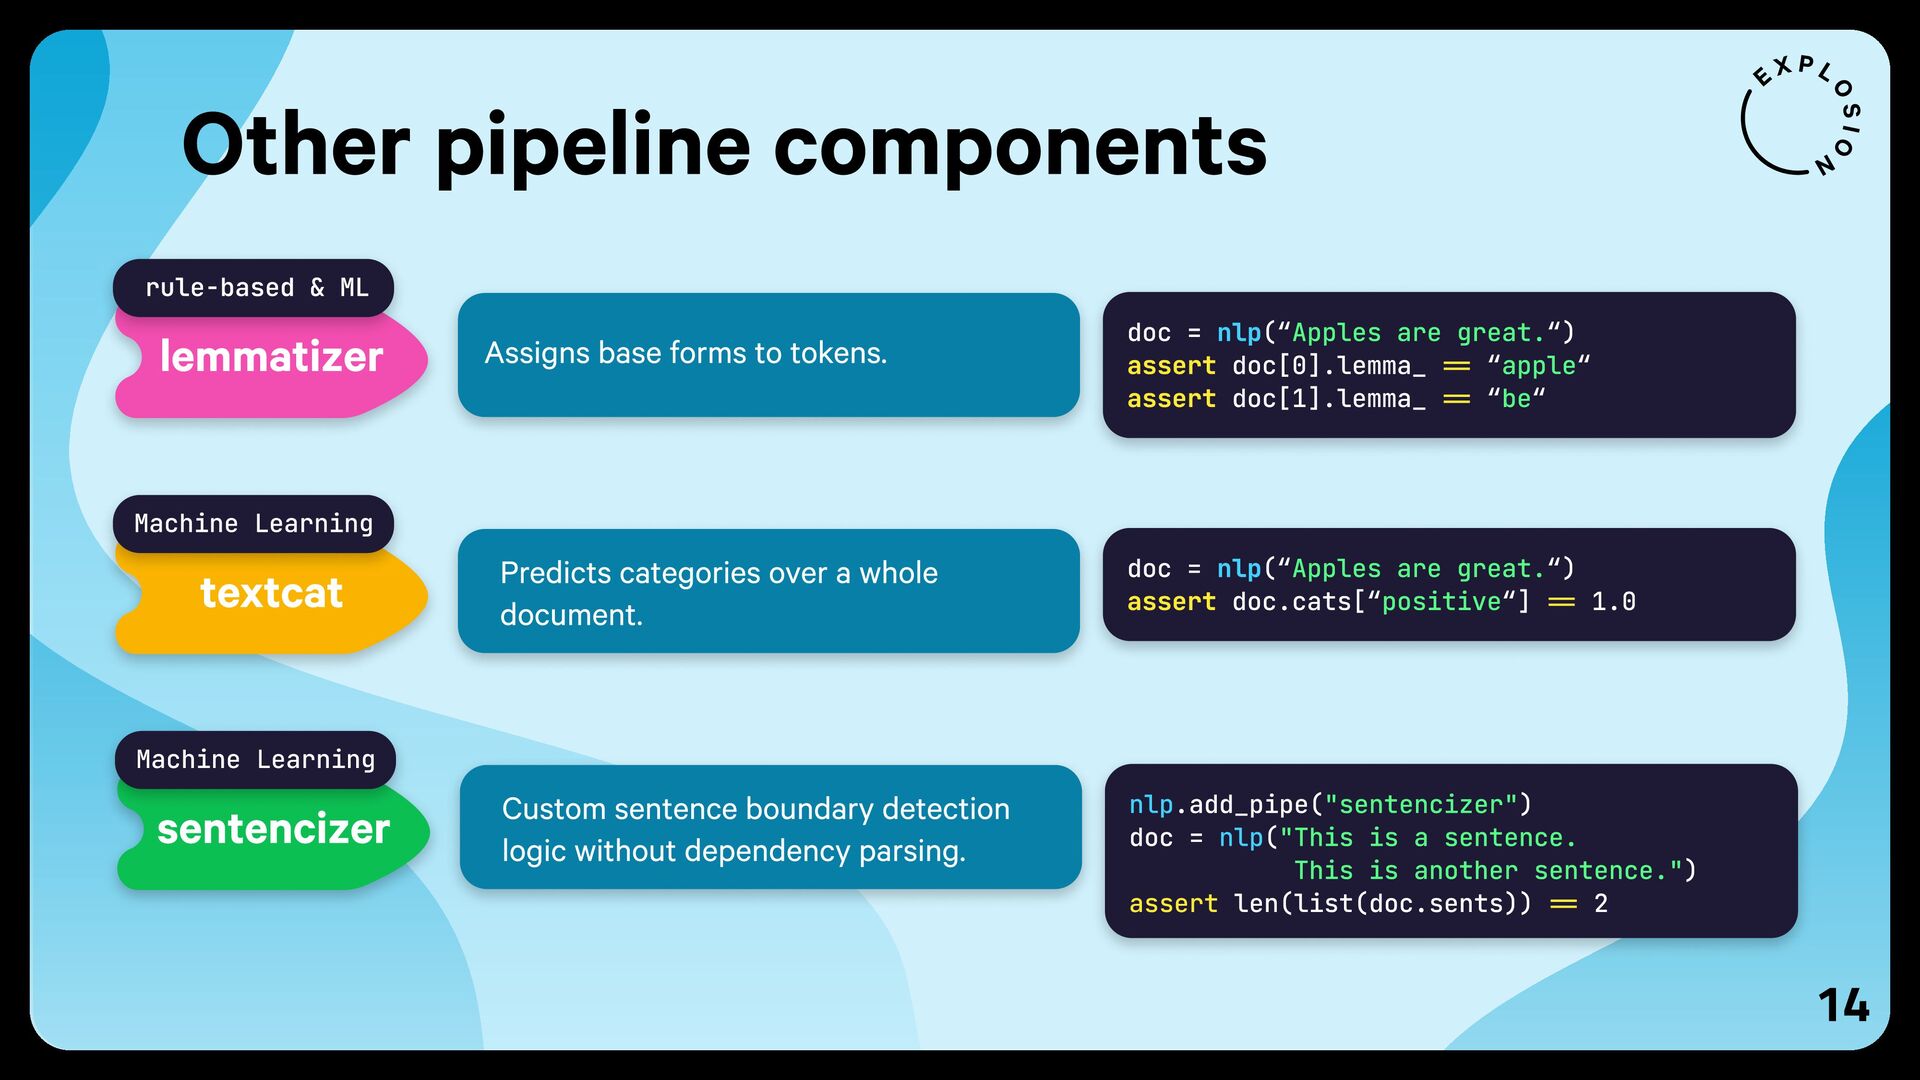
14 Assigns base forms to tokens. lemmatizer rule-based & ML
doc = (“ “) doc[0].lemma_ “ “ doc[1].lemma_ “ “ nlp Apples are great. apple be assert == assert == Predicts categories over a whole document. textcat Machine Learning doc = (“ “) doc.cats[“ “] 1.0 nlp Apples are great. positive assert == Custom sentence boundary detection logic without dependency parsing. sentencizer Machine Learning nlp nlp .add_pipe( ) doc = ( ) len(list(doc.sents)) 2 "sentencizer" "This is a sentence. This is another sentence." assert == Other pipeline components -
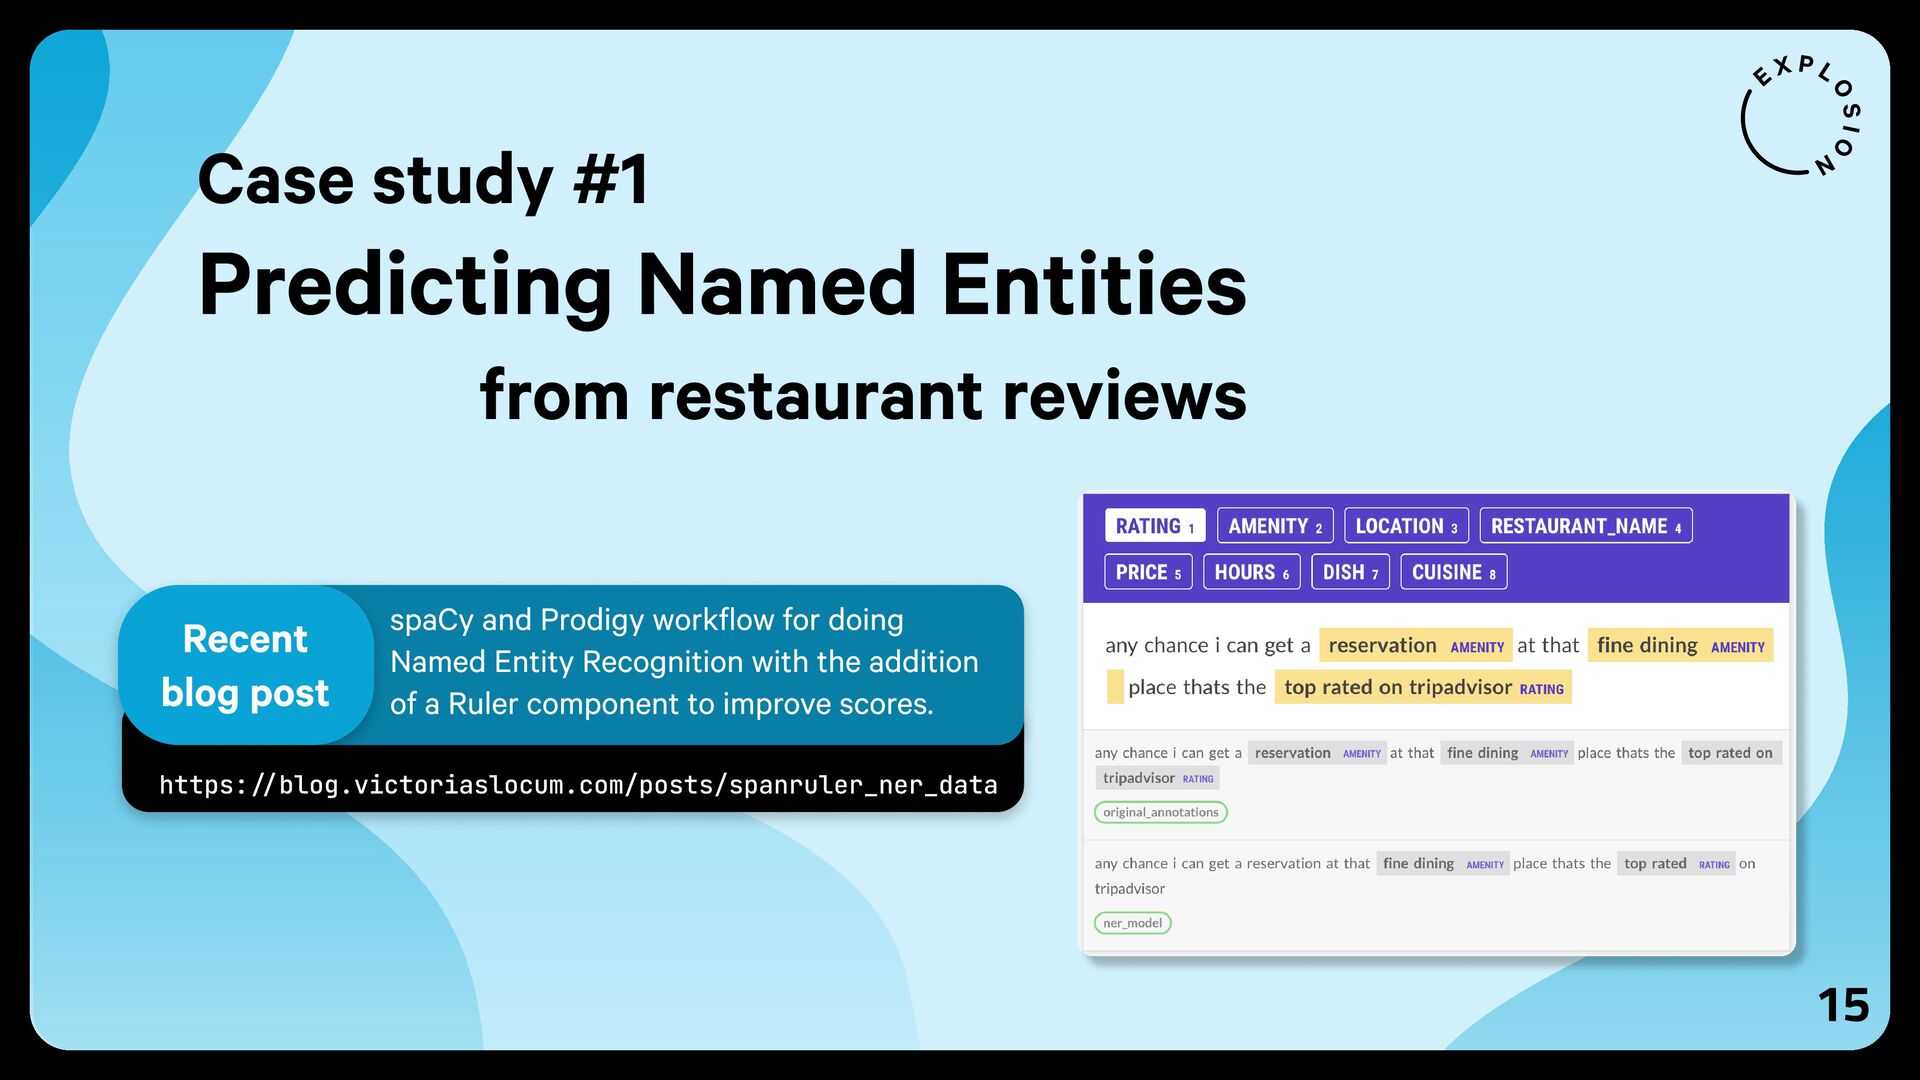
15 https://blog.victoriaslocum.com/posts/spanruler_ner_data spaCy and Prodigy workflow for doing Named Entity
Recognition with the addition of a Ruler component to improve scores. Recent blog post Case study #1 Predicting Named Entities from restaurant reviews -
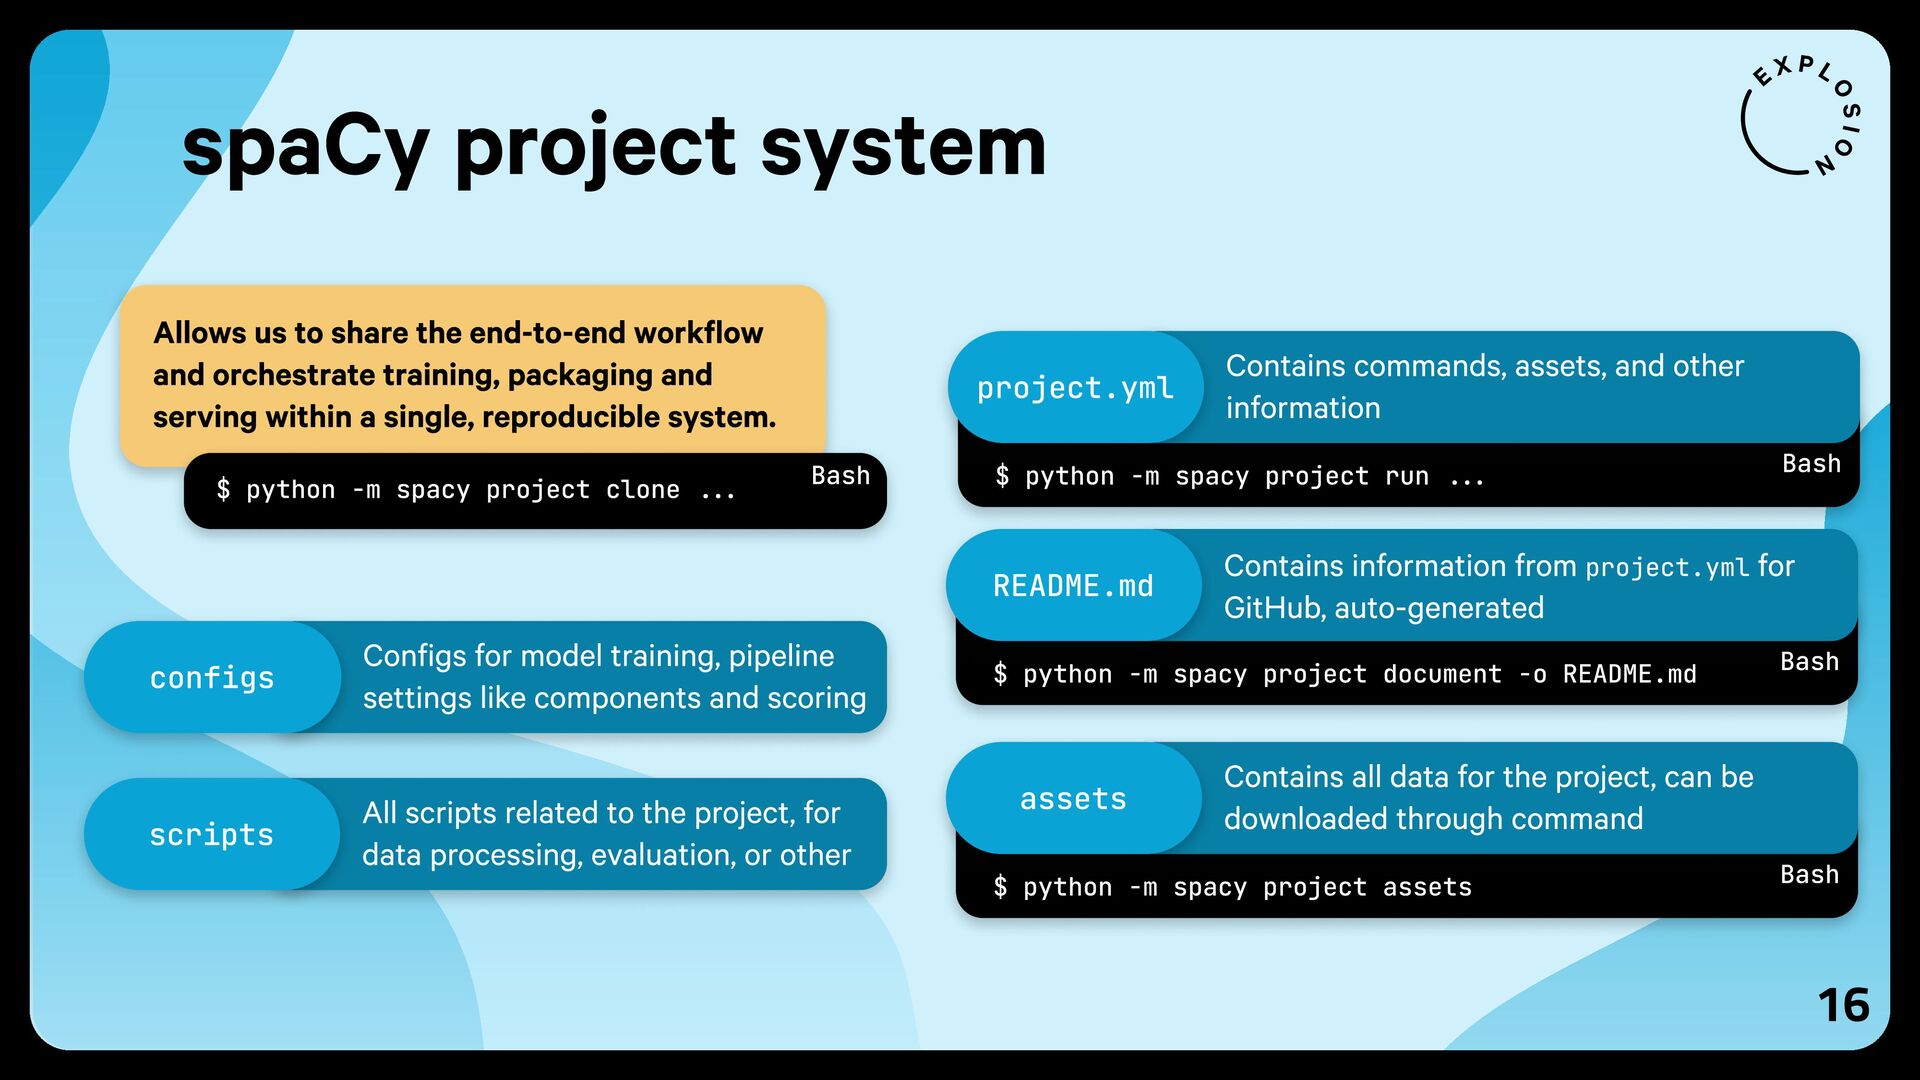
16 $ python -m spacy project run ... Bash Contains
commands, assets, and other information project.yml $ python -m spacy project document -o README.md Bash Contains information from project.yml for GitHub, auto-generated README.md $ python -m spacy project assets Bash Contains all data for the project, can be downloaded through command assets All scripts related to the project, for data processing, evaluation, or other scripts Configs for model training, pipeline settings like components and scoring configs spaCy project system Allows us to share the end-to-end workflow and orchestrate training, packaging and serving within a single, reproducible system. $ python -m spacy project clone ... Bash -
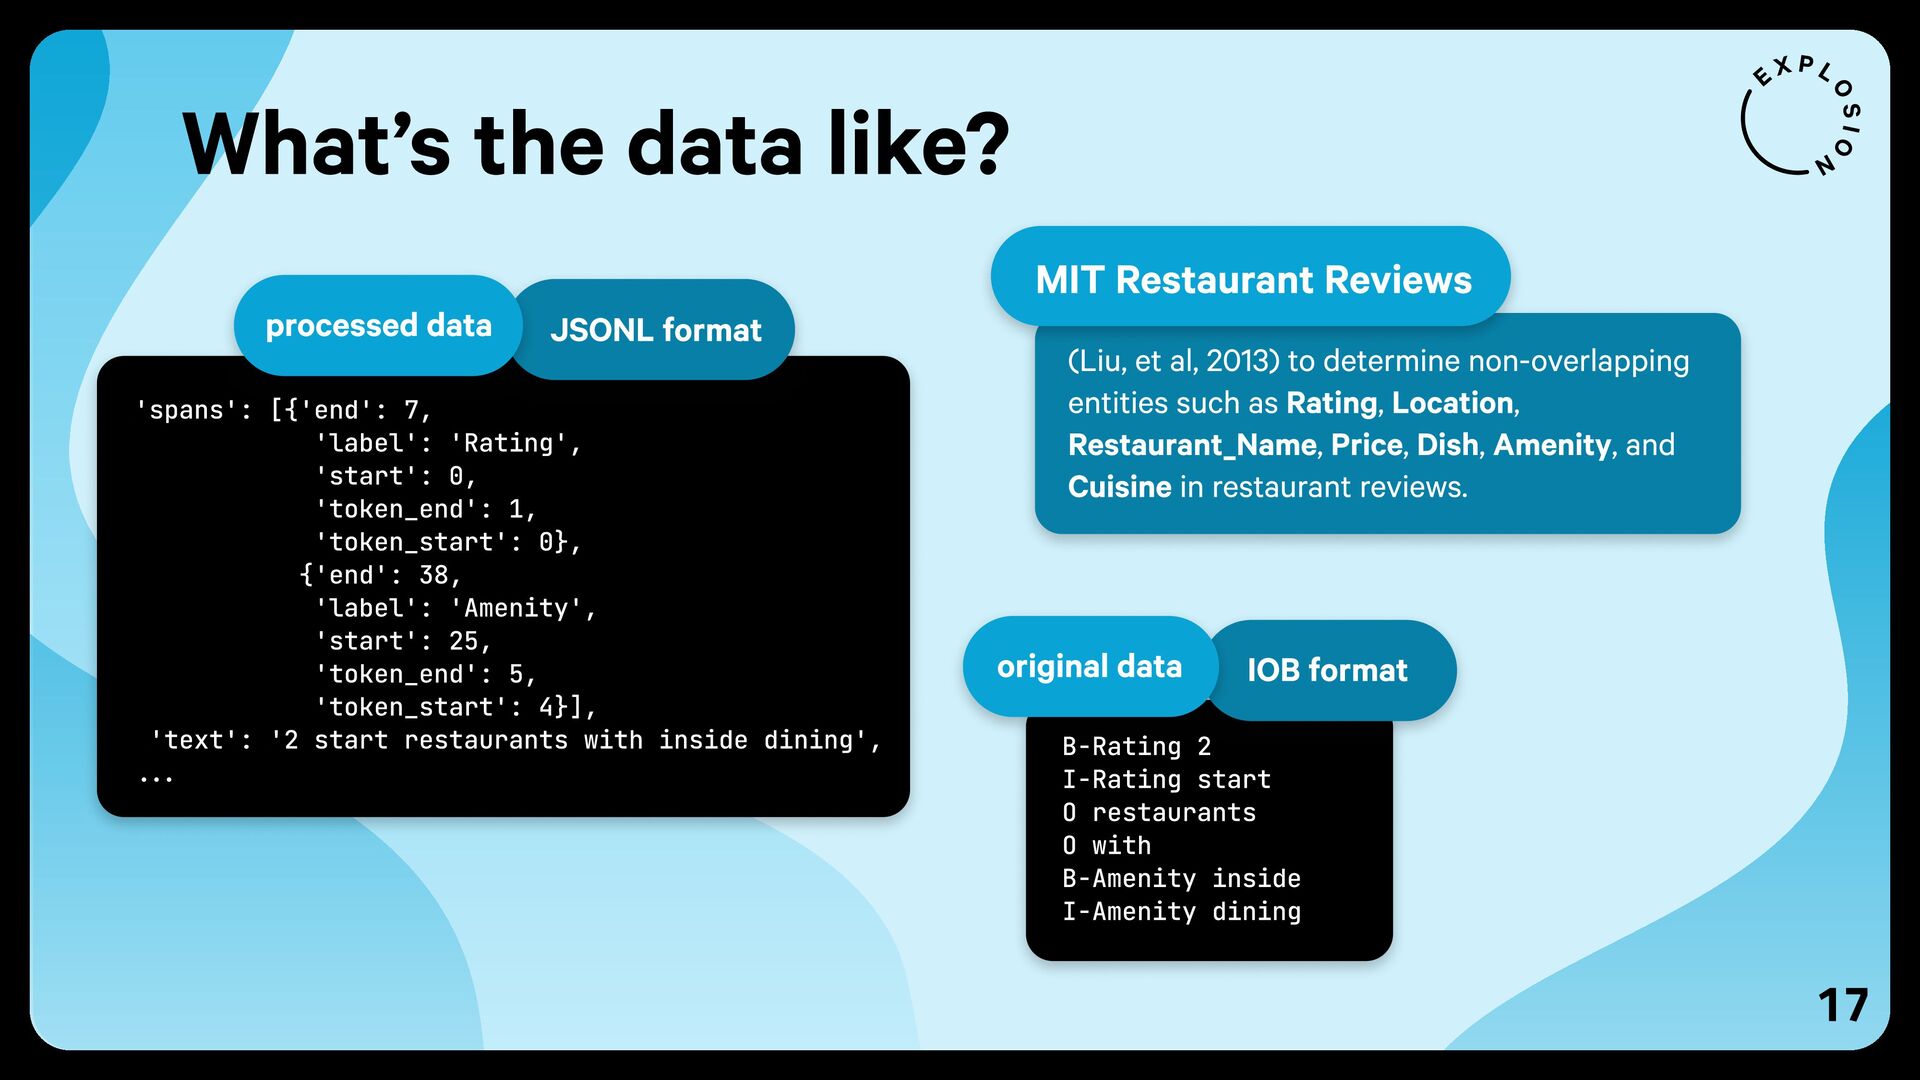
17 B-Rating 2 I-Rating start O restaurants O with B-Amenity
inside I-Amenity dining IOB format original data 'spans': [{'end': 7, 'label': 'Rating', 'start': 0, 'token_end': 1, 'token_start': 0}, {'end': 38, 'label': 'Amenity', 'start': 25, 'token_end': 5, 'token_start': 4}], 'text': '2 start restaurants with inside dining', ... JSONL format processed data (Liu, et al, 2013) to determine non-overlapping entities such as Rating, Location, Restaurant_Name, Price, Dish, Amenity, and Cuisine in restaurant reviews. MIT Restaurant Reviews What’s the data like? -
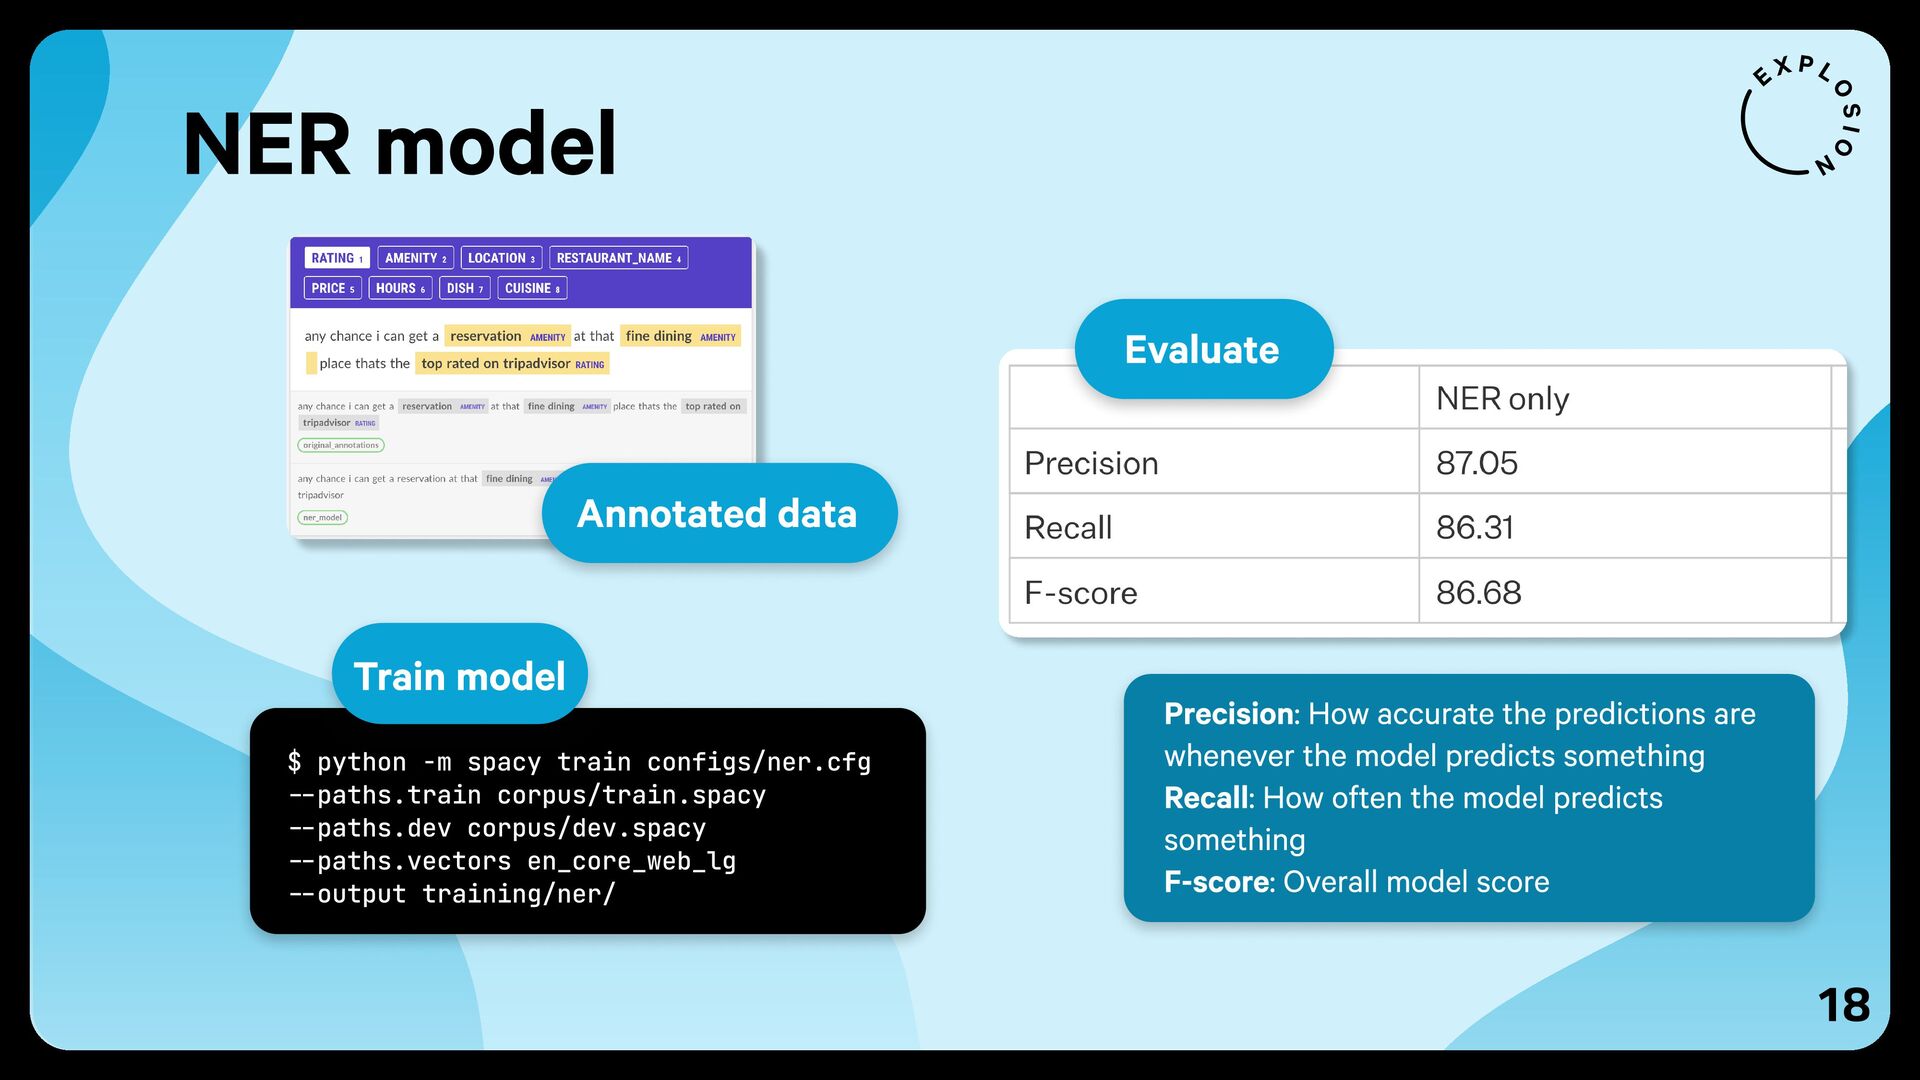
18 Evaluate Precision: How accurate the predictions are whenever the
model predicts something Recall: How often the model predicts something F-score: Overall model score $ python -m spacy train configs/ner.cfg --paths.train corpus/train.spacy --paths.dev corpus/dev.spacy --paths.vectors en_core_web_lg --output training/ner/ Train model NER model Annotated data -
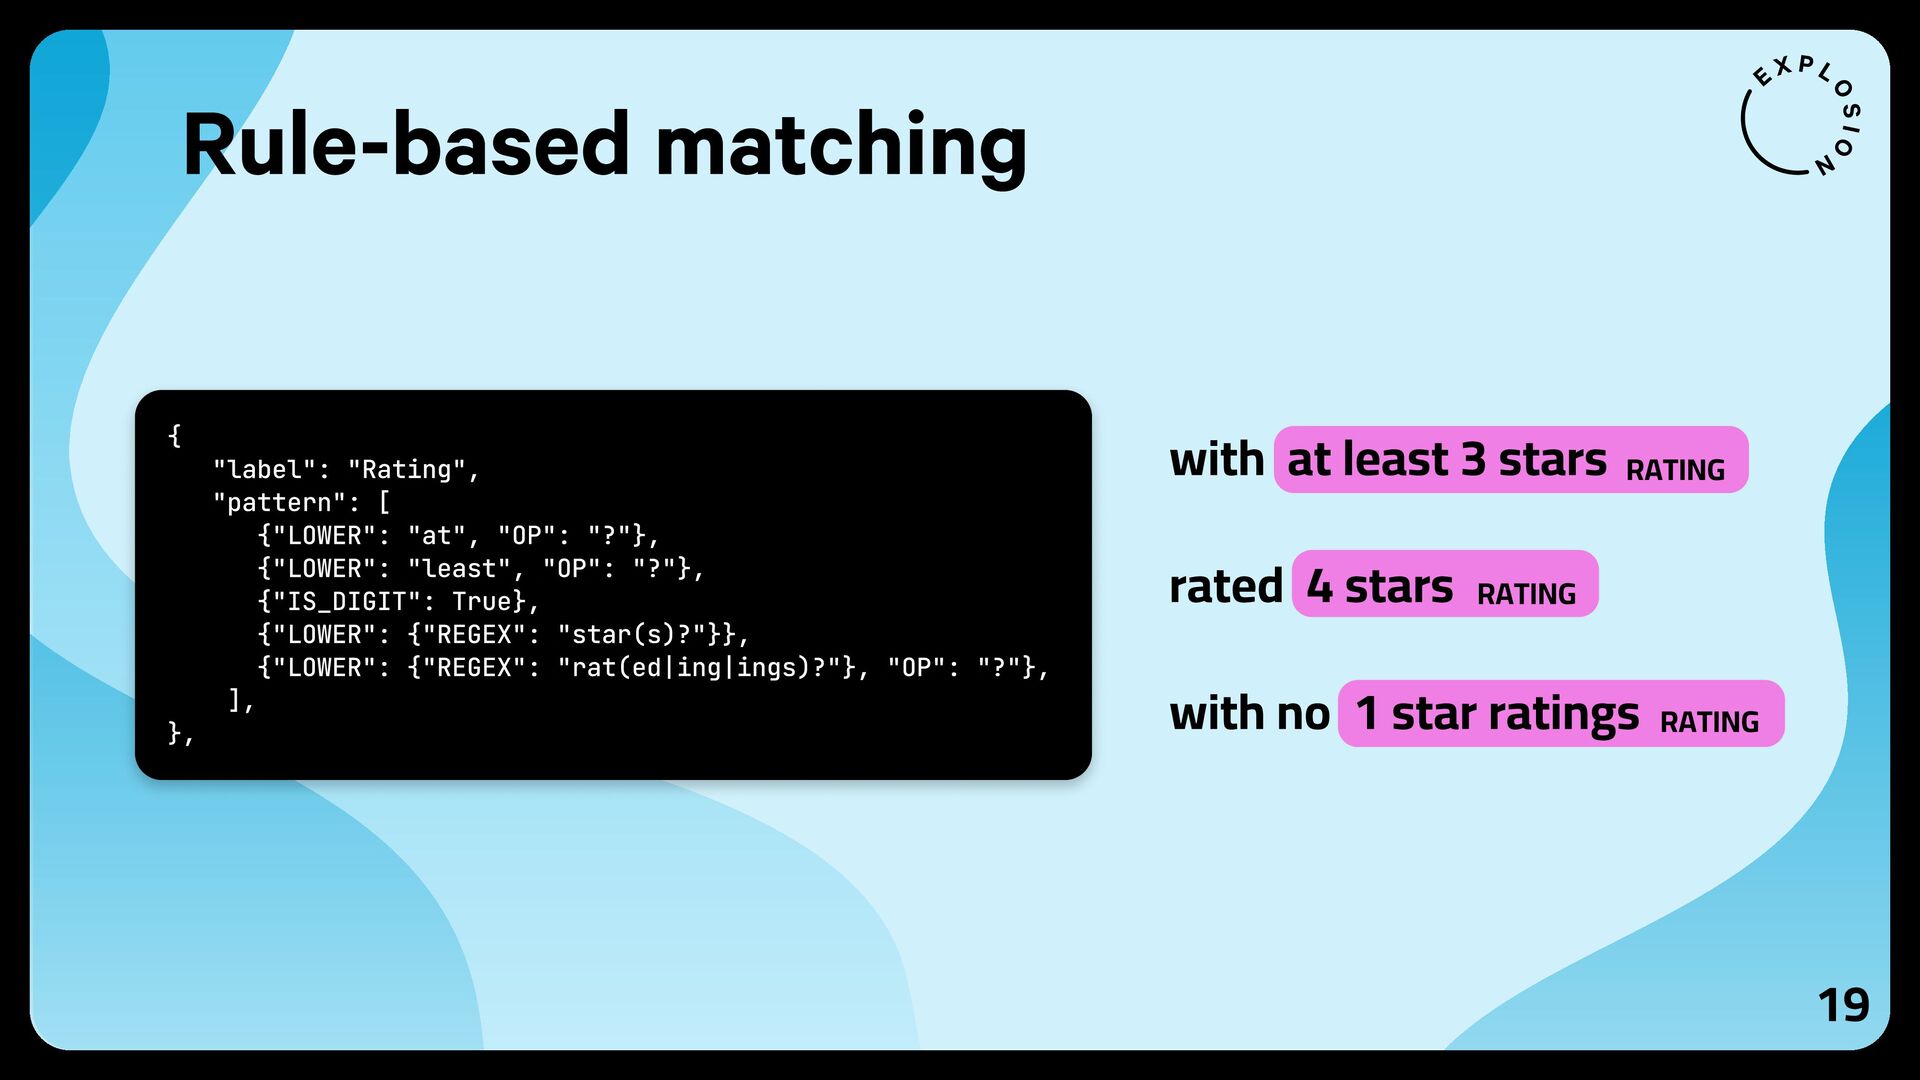
19 { "label": "Rating", "pattern": [ {"LOWER": "at", "OP": "?"},
{"LOWER": "least", "OP": "?"}, {"IS_DIGIT": True}, {"LOWER": {"REGEX": "star(s)?"}}, {"LOWER": {"REGEX": "rat(ed|ing|ings)?"}, "OP": "?"}, ], }, Rule-based matching RATING with at least 3 stars RATING with no 1 star ratings RATING rated 4 stars -
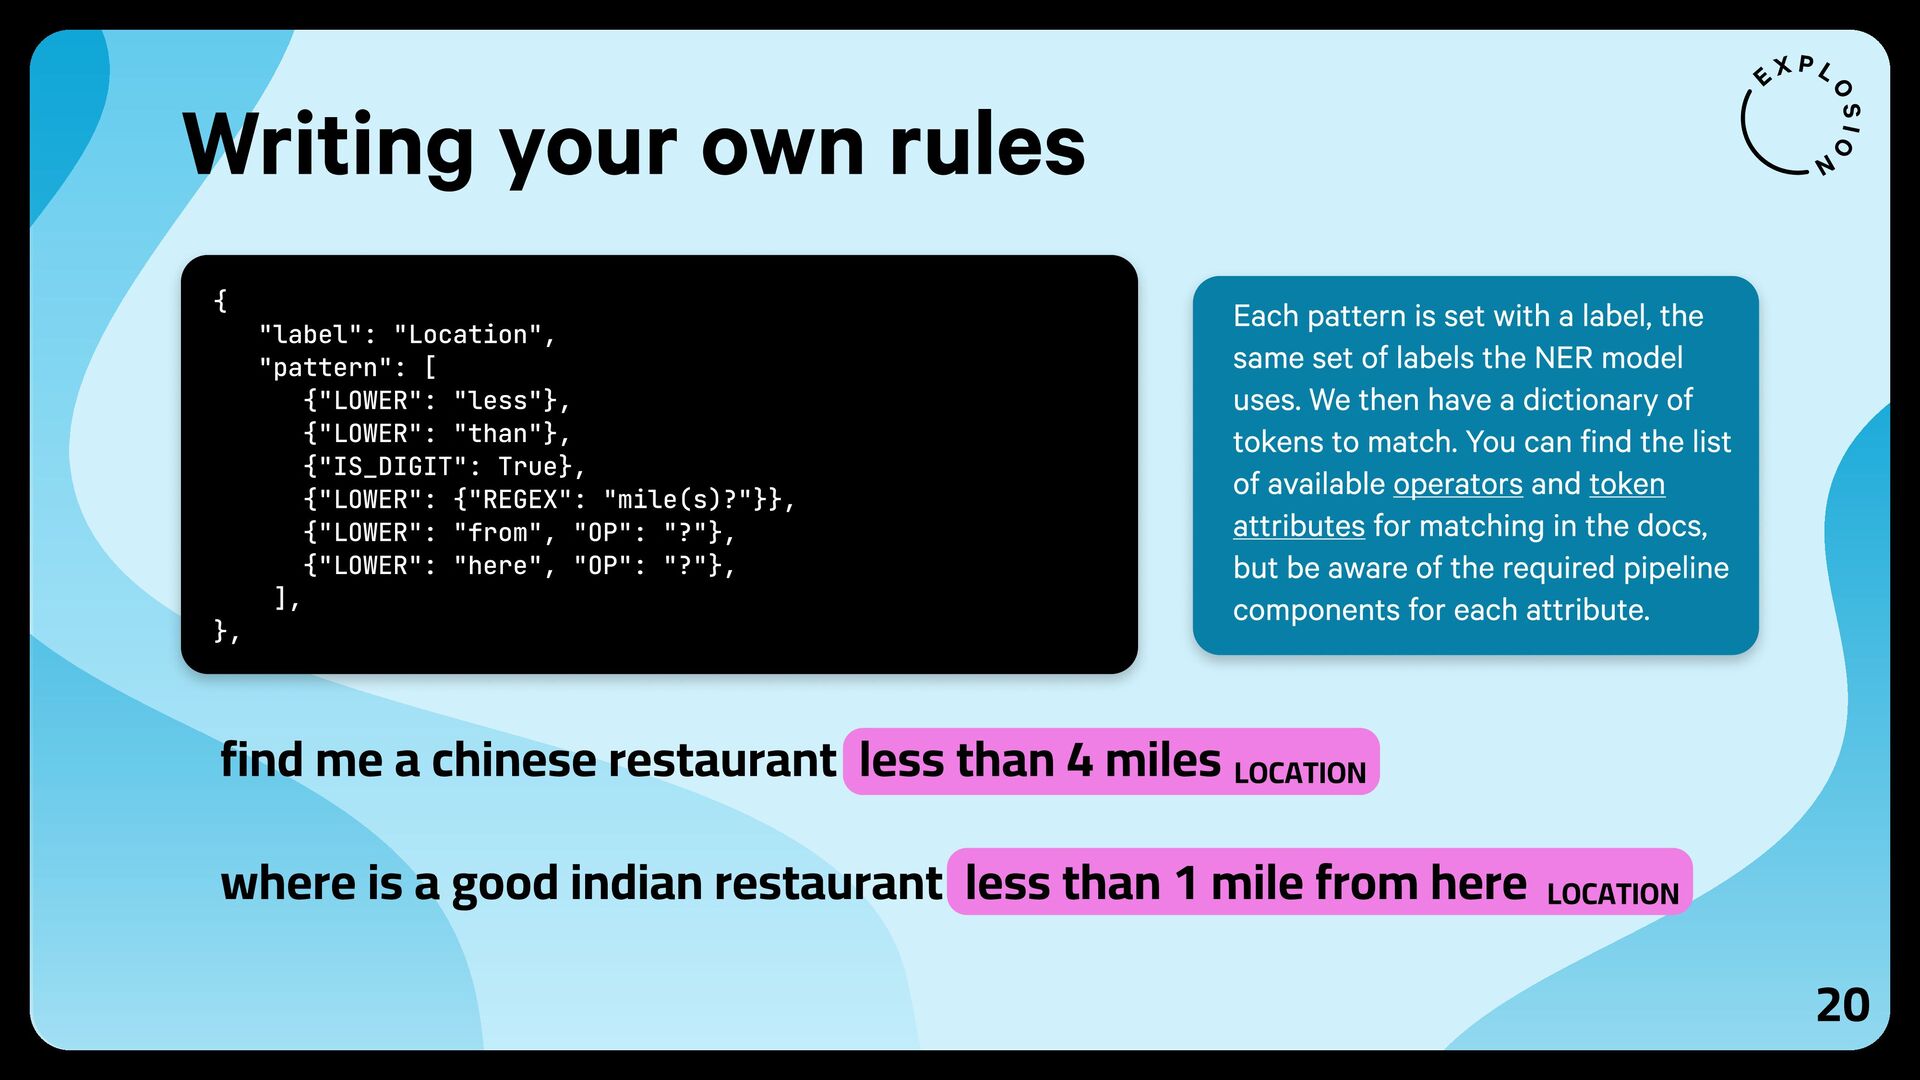
20 Writing your own rules { "label": "Location", "pattern": [
{"LOWER": "less"}, {"LOWER": "than"}, {"IS_DIGIT": True}, {"LOWER": {"REGEX": "mile(s)?"}}, {"LOWER": "from", "OP": "?"}, {"LOWER": "here", "OP": "?"}, ], }, LOCATION find me a chinese restaurant less than 4 miles LOCATION where is a good indian restaurant less than 1 mile from here Each pattern is set with a label, the same set of labels the NER model uses. We then have a dictionary of tokens to match. You can find the list of available operators and token attributes for matching in the docs, but be aware of the required pipeline components for each attribute. -
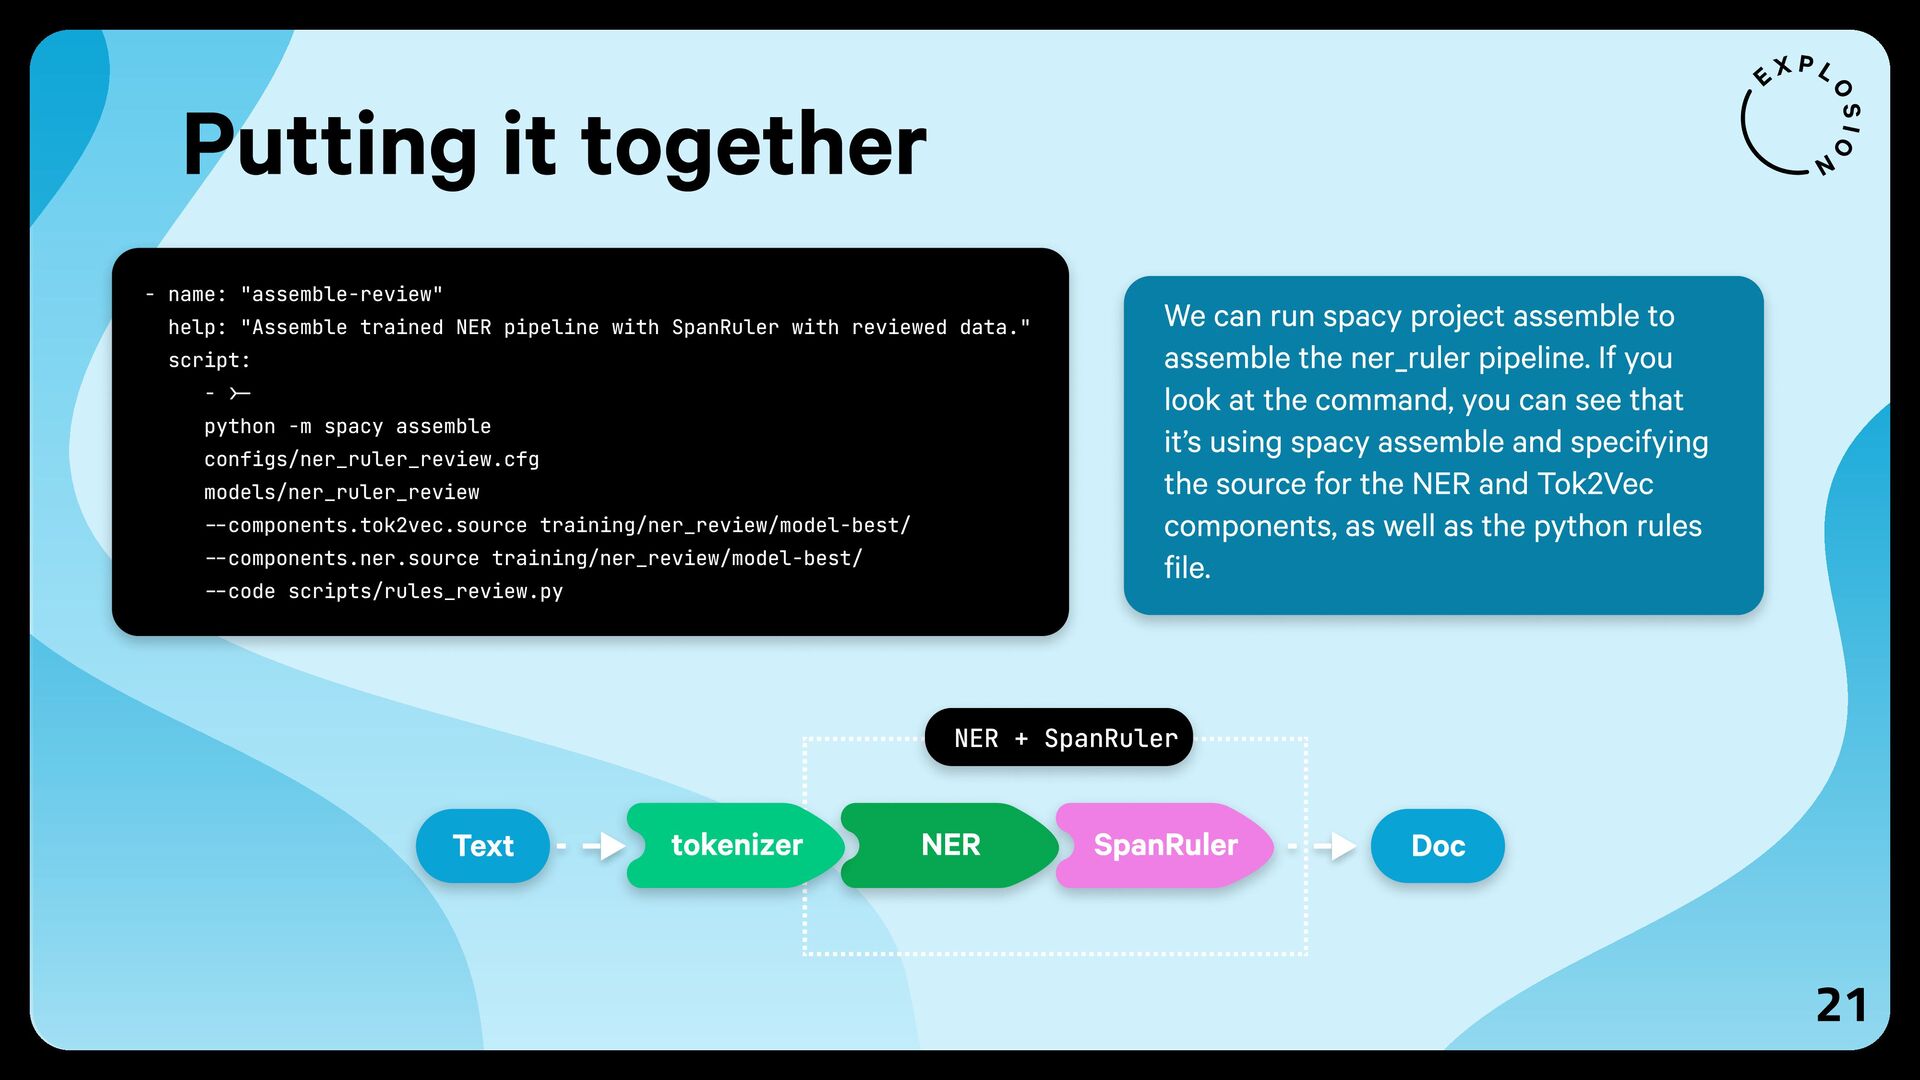
21 We can run spacy project assemble to assemble the
ner_ruler pipeline. If you look at the command, you can see that it’s using spacy assemble and specifying the source for the NER and Tok2Vec components, as well as the python rules file. Text Doc NER SpanRuler NER + SpanRuler tokenizer Putting it together - name: "assemble-review" help: "Assemble trained NER pipeline with SpanRuler with reviewed data." script: - >- python -m spacy assemble configs/ner_ruler_review.cfg models/ner_ruler_review --components.tok2vec.source training/ner_review/model-best/ --components.ner.source training/ner_review/model-best/ --code scripts/rules_review.py -
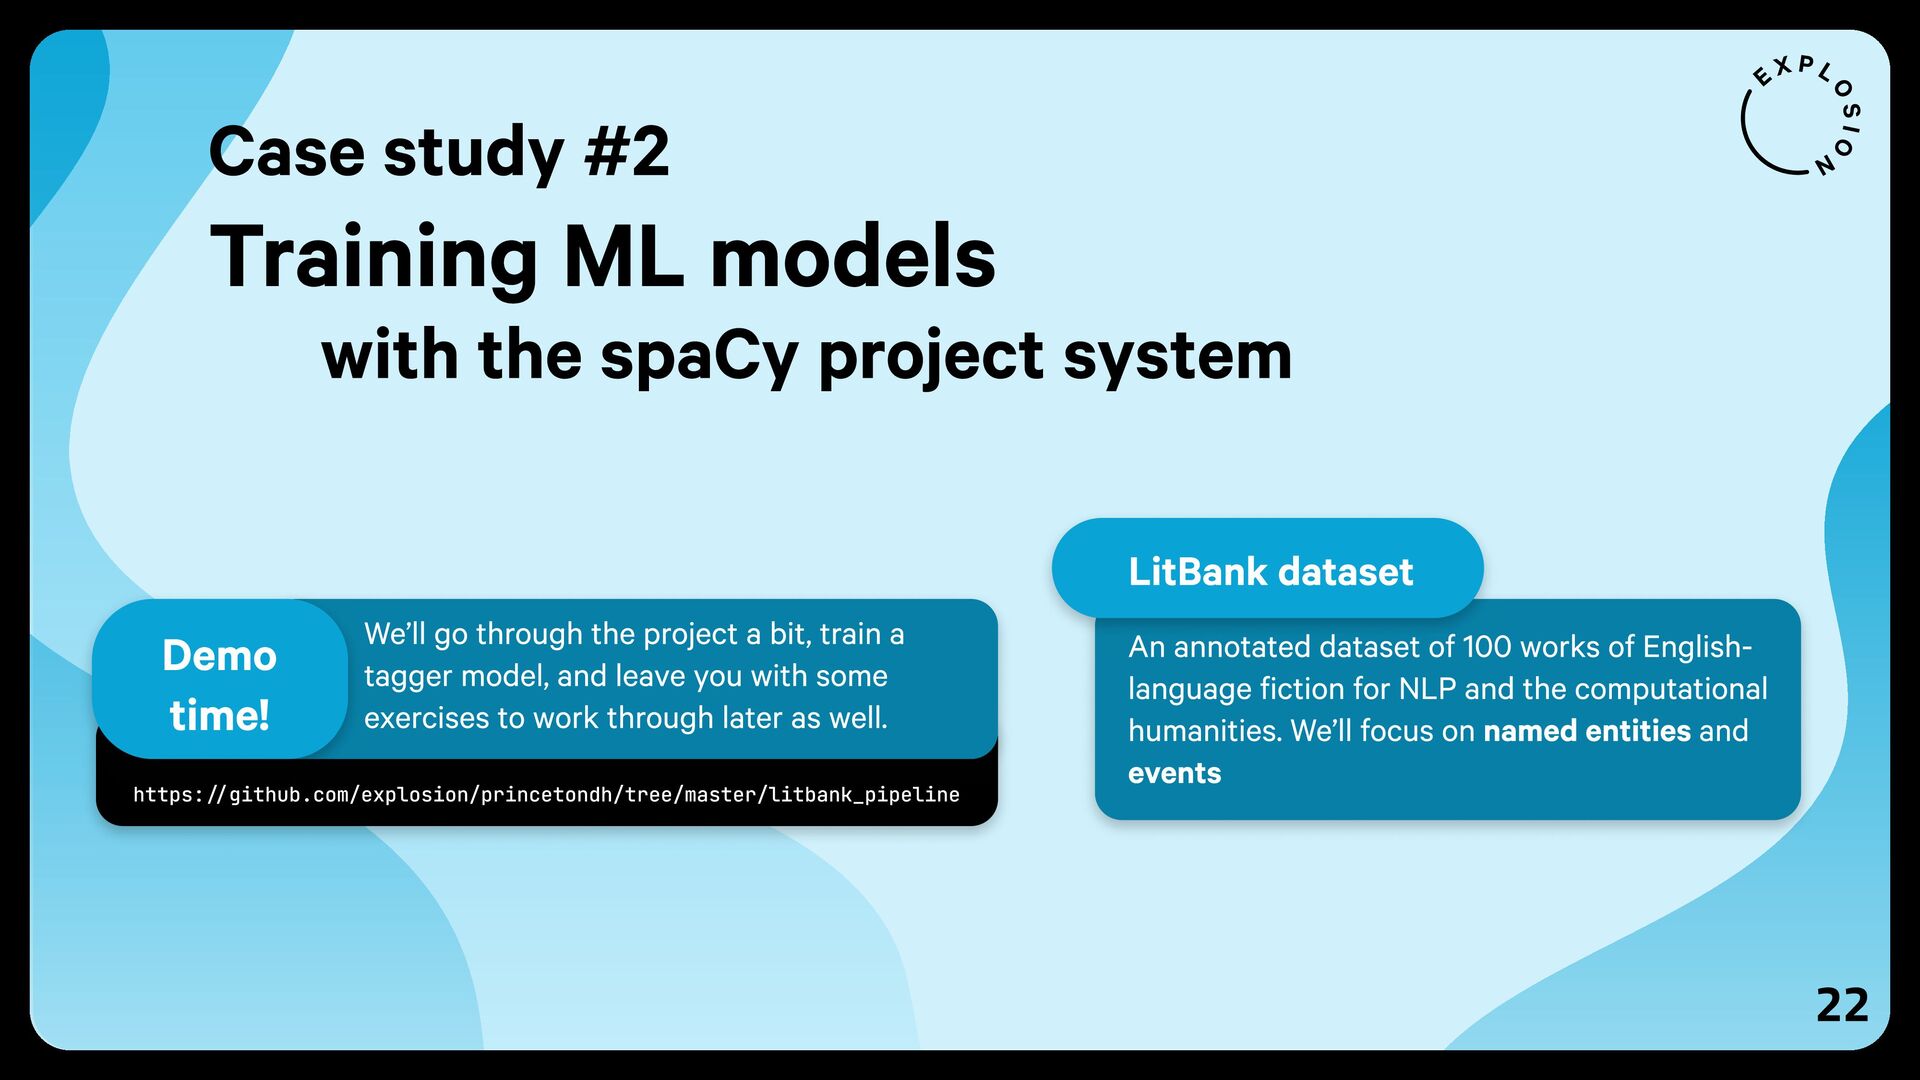
22 https://github.com/explosion/princetondh/tree/master/litbank_pipeline We’ll go through the project a bit, train
a tagger model, and leave you with some exercises to work through later as well. Demo time! Case study #2 Training ML models with the spaCy project system An annotated dataset of 100 works of English- language fiction for NLP and the computational humanities. We’ll focus on named entities and events LitBank dataset -
23 Thanks so much for being here! 8 (blog.) .co3
8 twitter.com/ 8 linkedin.com/in/ 8 @explosion.ai victoriaslocum victorialslocu3 victorialslocu3 victoria 8 .ai/bloh 8 youtube.com/@ 8 twitter.com/ explosion ExplosionAy spacy_io 8 twitter.com/ 8 @explosion.ai kadarako akos
 victorialslocum
 inesmontani
 maguroalternative
 miu_crescent
 manabuseki
 shadowhat
 ivry_presentationmaterials
 akihiro0038
 shumpei3
 miriamschwab
 110y
 kaminashi
 minorun365
 emna__ayadi
 rakko
 swwweet
 baasie
 moore
 takai
 ryanjones
 cromwellryan
 katarinadahlin
 akosma
 holman