Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
NLTK Intro for PUGS
Search
Sponsored
·
SiteGround - Reliable hosting with speed, security, and support you can count on.
→
Victor Neo
March 27, 2012
Programming
620
7
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
NLTK Intro for PUGS
Slides for the NLTK talk given on March 2012 for Python User Group SG Meetup.
Victor Neo
March 27, 2012
More Decks by Victor Neo
See All by Victor Neo
Django - The Next Steps
victorneo
5
710
DevOps: Python tools to get started
victorneo
9
13k
Git and Python workshop
victorneo
2
830
Other Decks in Programming
See All in Programming
WebMCP Challenge に星空観察アプリで参加した話
okajun35
0
180
モジュールの視点からSwiftを読み解く #iosdc
s_shimotori
0
180
{ Android | Kotlin } Gradle Plugin in 2026
ryunen344
1
320
標準パッケージに uuid が追加された 背景から見る Go らしい意思決定 / go_127_uuid_decision
convto
5
7.3k
Intent as Code
shoppingjaws
6
1k
wkhtmltopdfの次どうするか問題2026
willnet
2
1.3k
The Good Stuff, Not the Slop: Engineering High-Quality Android Apps with Modern AI Tooling
danybony
1
250
世界の中心で、AI(App Intents)をさけぶ ー App Intents中心設計の実践ガイド
touyou
0
600
個人開発基盤をまるごとCloudflareに引っ越して爆速で総合的体験を向上させた話
tinykitten
0
190
thread_parallel_with_free-threaded_Python_and_NumPy.pdf
riku_sakamoto
0
340
技術的負債を組織課題として解く-増えすぎたマイクロサービスとの戦い-
reimaru
1
2k
更なる可用性を求めて、5年間運用したKotlinのアプリケーションをGoでリプレイスする話
ken_tunc
0
290
Featured
See All Featured
How to build a perfect <img>
jonoalderson
1
6k
30 Presentation Tips
portentint
PRO
1
400
How to Think Like a Performance Engineer
csswizardry
28
2.8k
Hiding What from Whom? A Critical Review of the History of Programming languages for Music
tomoyanonymous
3
1.2k
DevOps and Value Stream Thinking: Enabling flow, efficiency and business value
helenjbeal
1
390
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k
Exploring anti-patterns in Rails
aemeredith
4
510
Groundhog Day: Seeking Process in Gaming for Health
codingconduct
0
350
For a Future-Friendly Web
brad_frost
183
10k
Future Trends and Review - Lecture 12 - Web Technologies (1019888BNR)
signer
PRO
0
3.7k
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
The Organizational Zoo: Understanding Human Behavior Agility Through Metaphoric Constructive Conversations (based on the works of Arthur Shelley, Ph.D)
kimpetersen
PRO
0
460
Transcript
Natural Language Toolkit @victorneo
Natural Language Processing
"the process of a computer extracting meaningful information from natural
language input and/or producing natural language output"
None
Getting started with NLTK
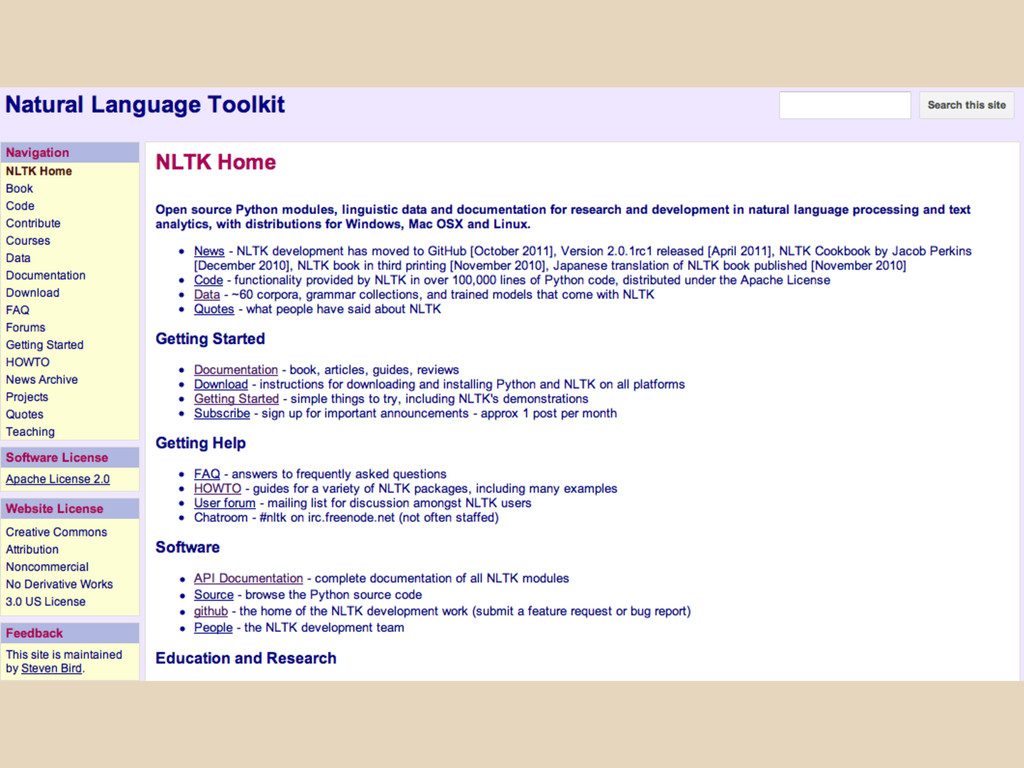
Open source Python modules, linguistic data and documentation for research
and development in natural language processing and text analytics, with distributions for Windows, Mac OSX and Linux. NLTK
None
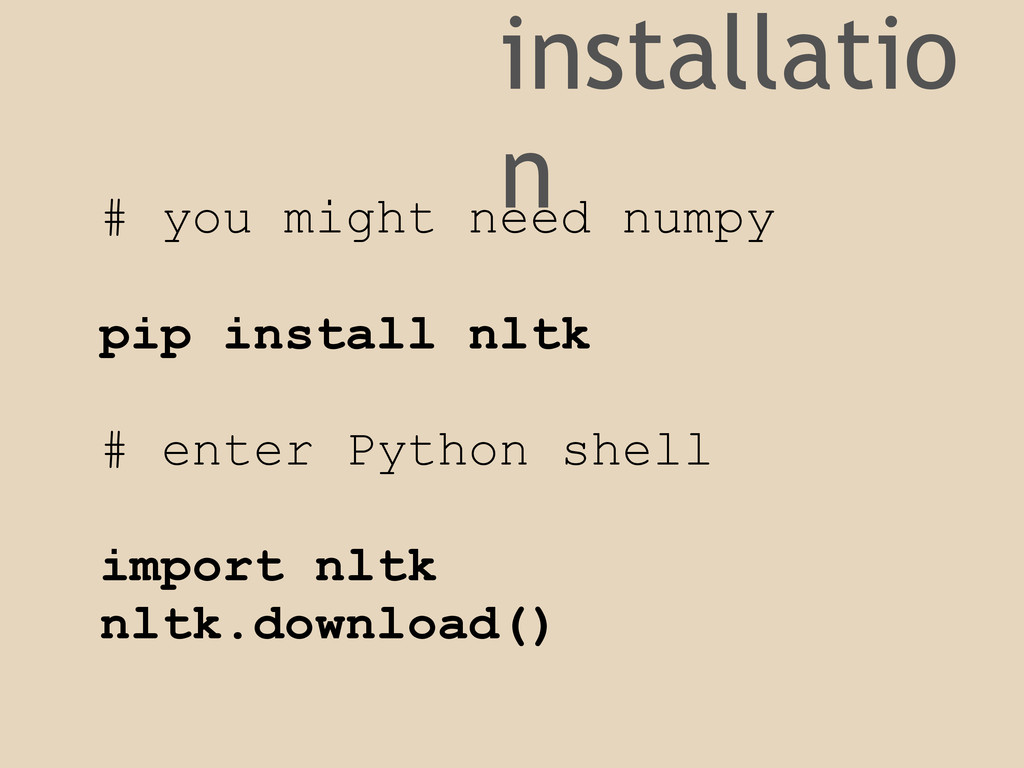
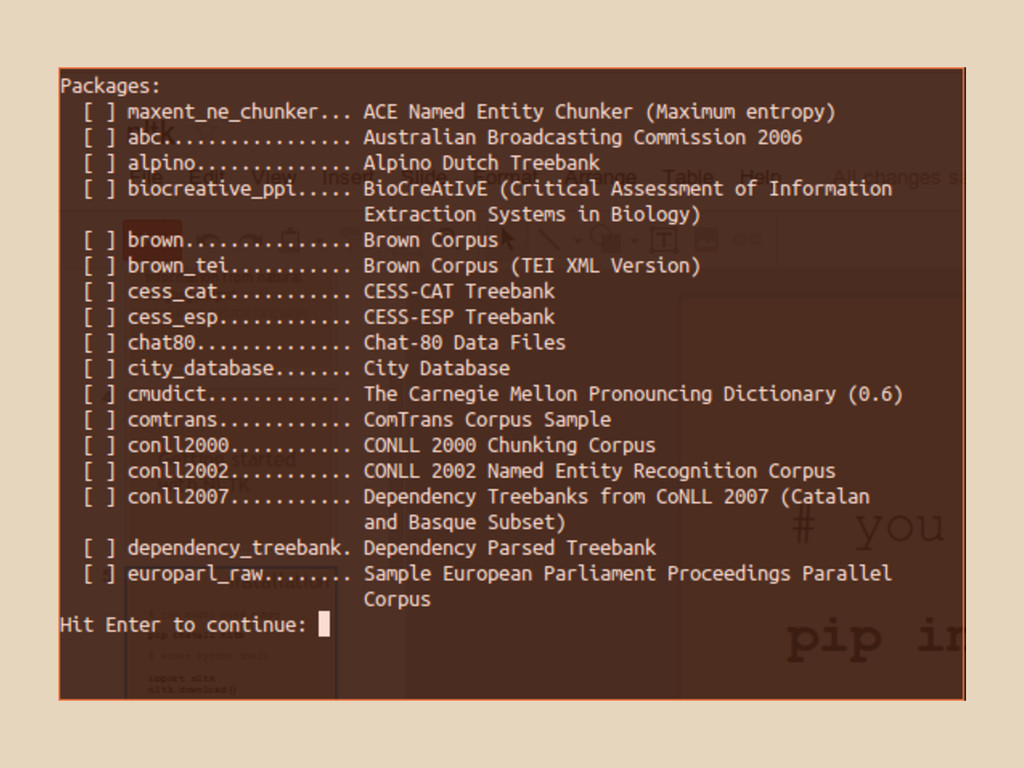
installatio n # you might need numpy pip install nltk
# enter Python shell import nltk nltk.download()
None
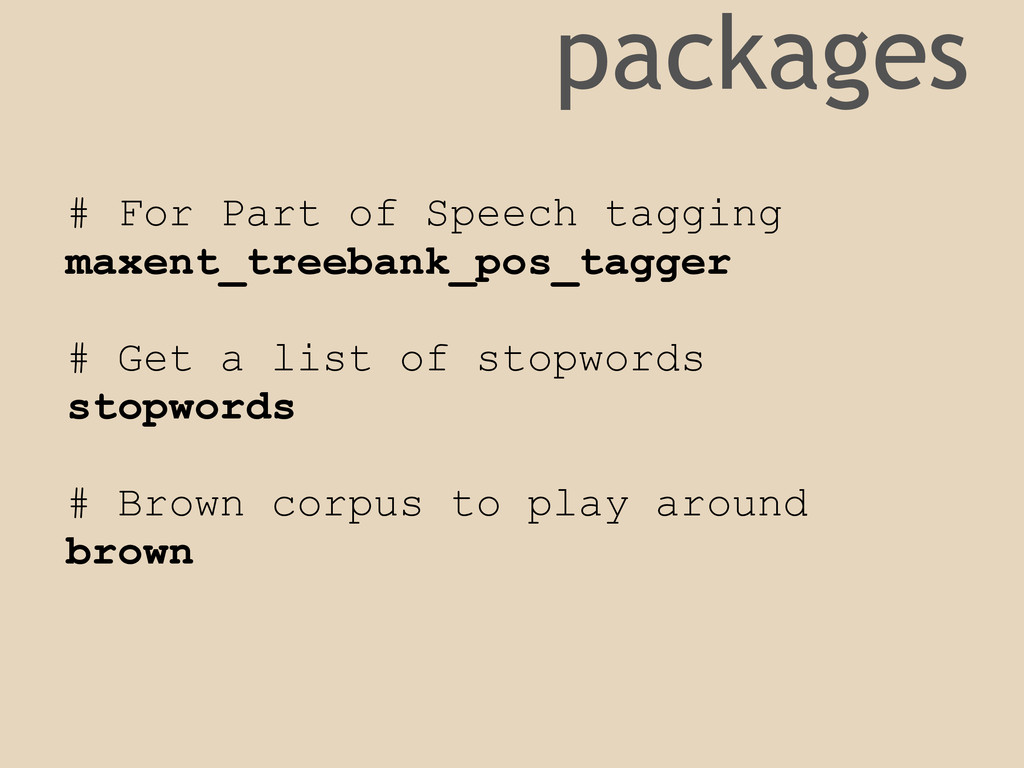
packages # For Part of Speech tagging maxent_treebank_pos_tagger # Get
a list of stopwords stopwords # Brown corpus to play around brown
Preparing data / corpus
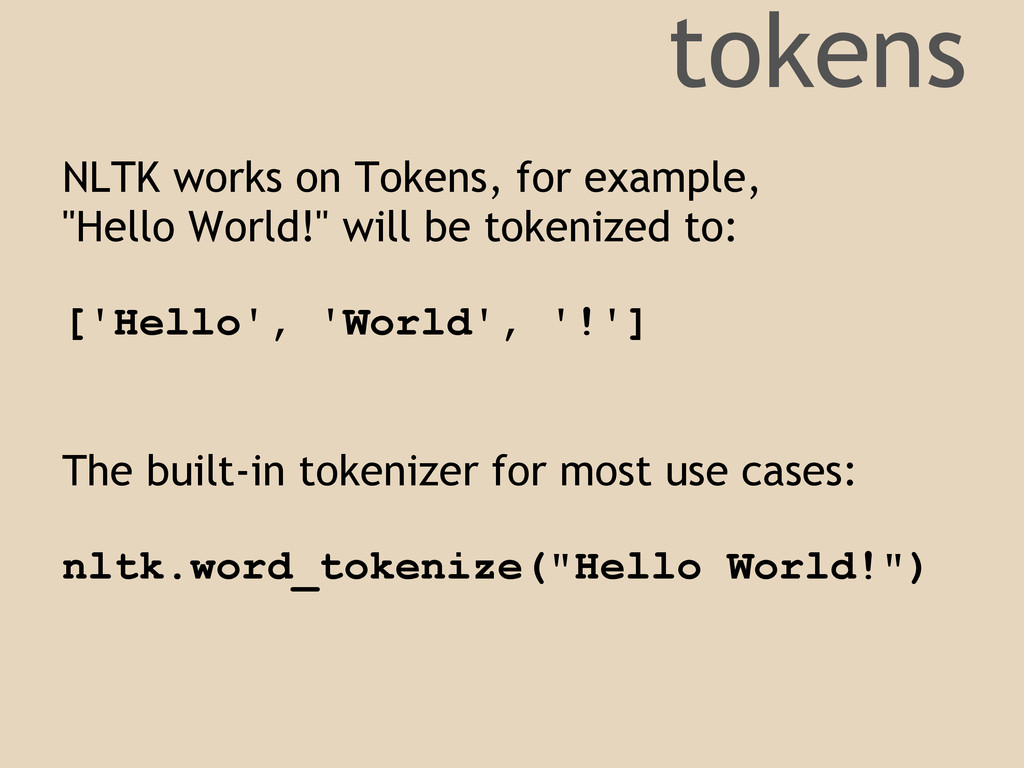
tokens NLTK works on Tokens, for example, "Hello World!" will
be tokenized to: ['Hello', 'World', '!'] The built-in tokenizer for most use cases: nltk.word_tokenize("Hello World!")
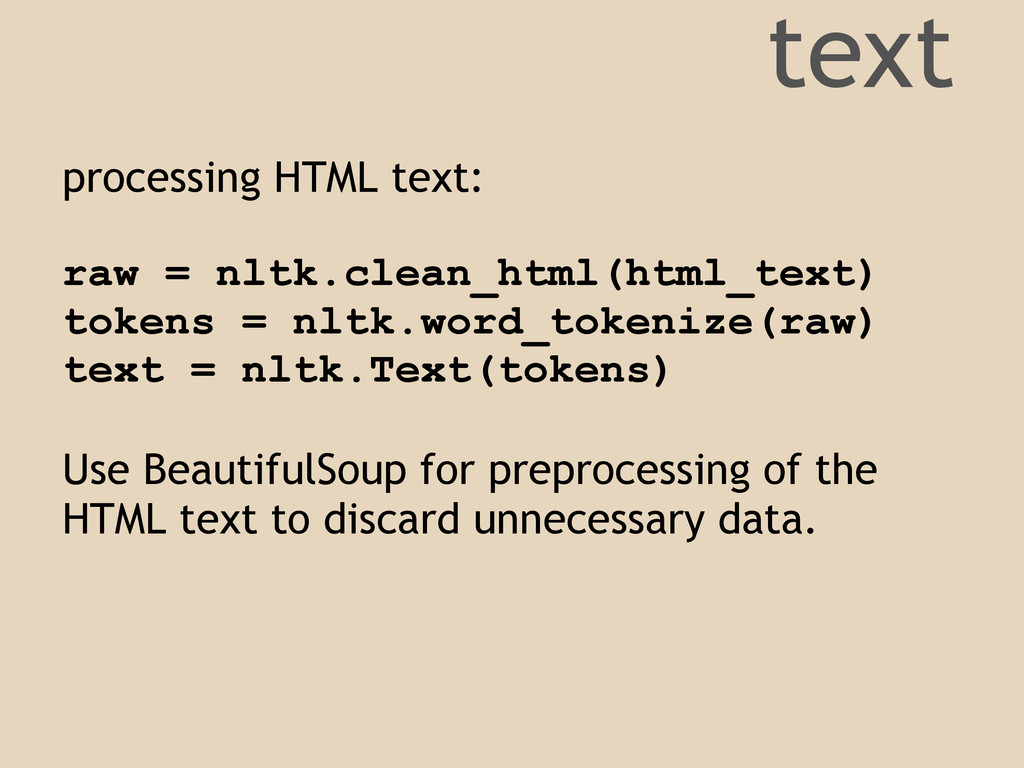
text processing HTML text: raw = nltk.clean_html(html_text) tokens = nltk.word_tokenize(raw)
text = nltk.Text(tokens) Use BeautifulSoup for preprocessing of the HTML text to discard unnecessary data.
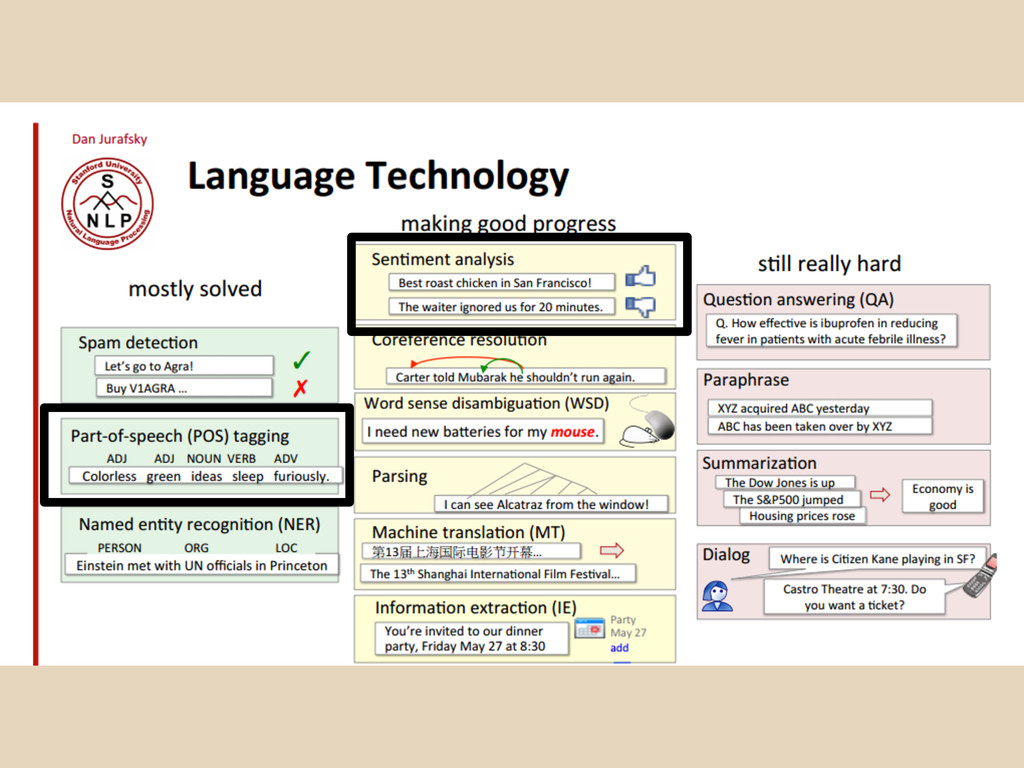
Part-of-speech tagging
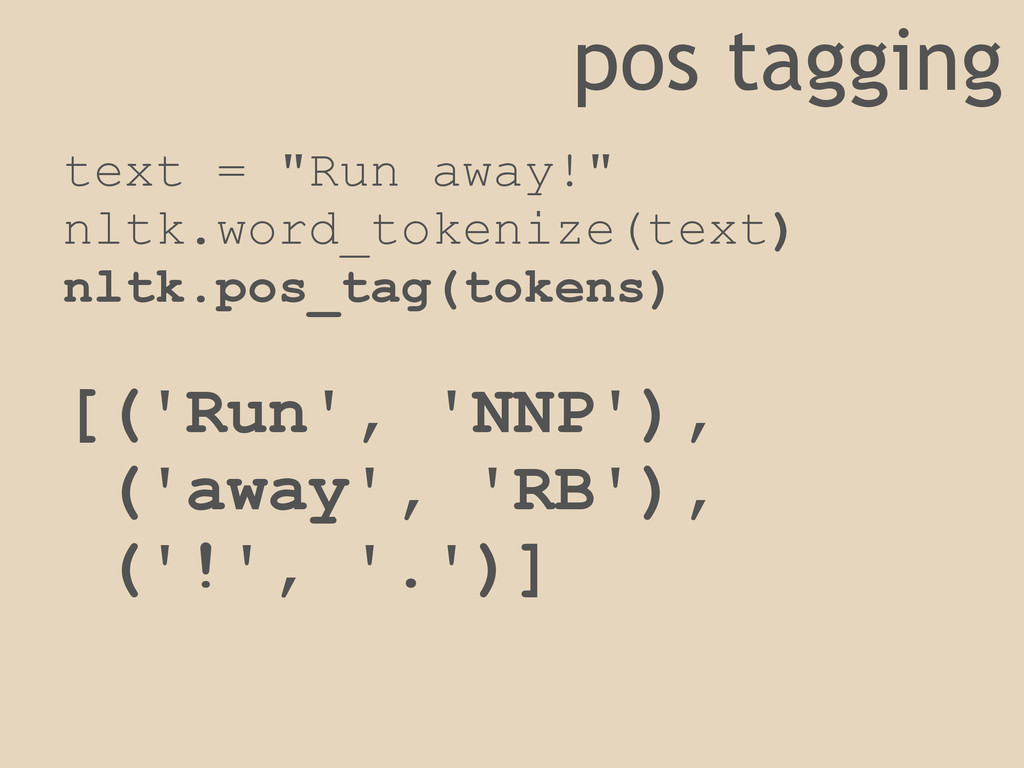
pos tagging text = "Run away!" nltk.word_tokenize(text) nltk.pos_tag(tokens) [('Run', 'NNP'),
('away', 'RB'), ('!', '.')]
pos tagging [('Run', 'NNP'), ('away', 'RB'), ('!', '.')] NNP: Proper
Noun, Singular RB : Adverb http://www.ling.upenn.edu/courses/Fall_2003/ling001/penn_treebank_pos. html
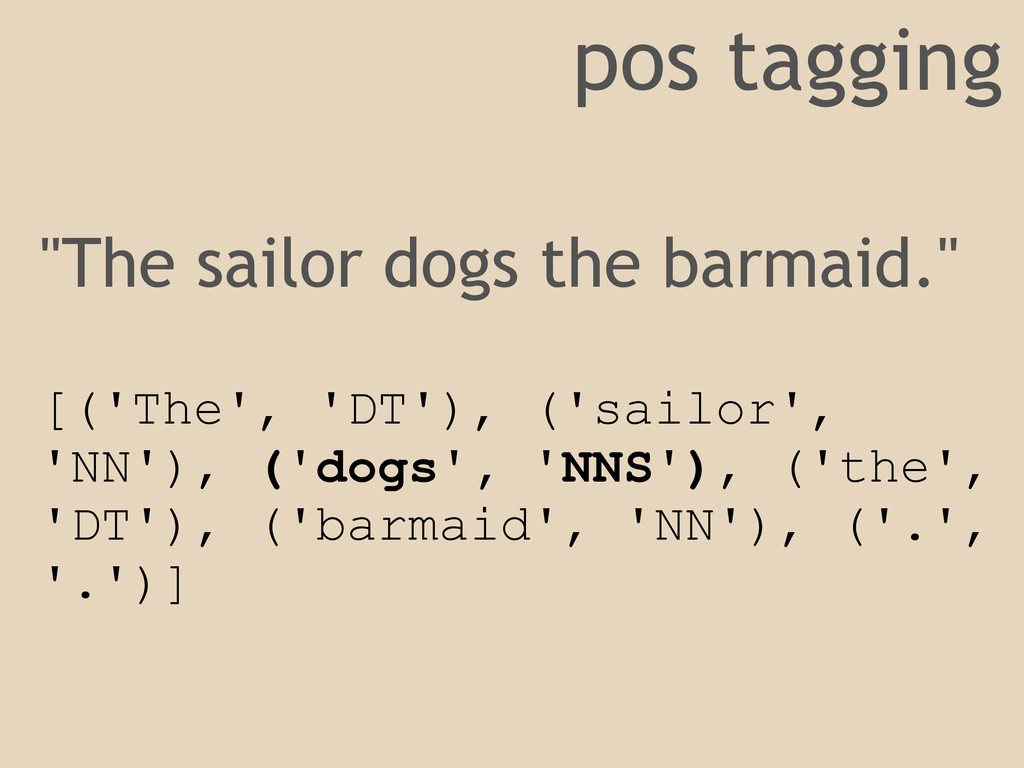
pos tagging "The sailor dogs the barmaid." [('The', 'DT'), ('sailor',
'NN'), ('dogs', 'NNS'), ('the', 'DT'), ('barmaid', 'NN'), ('.', '.')]
Sentiment Analysis Code: http://bit.ly/GLu2Q9
Differentiate between "happy" and "sad" tweets. Teach the classifier the
"features" of happy & sad tweets and test how good it is.
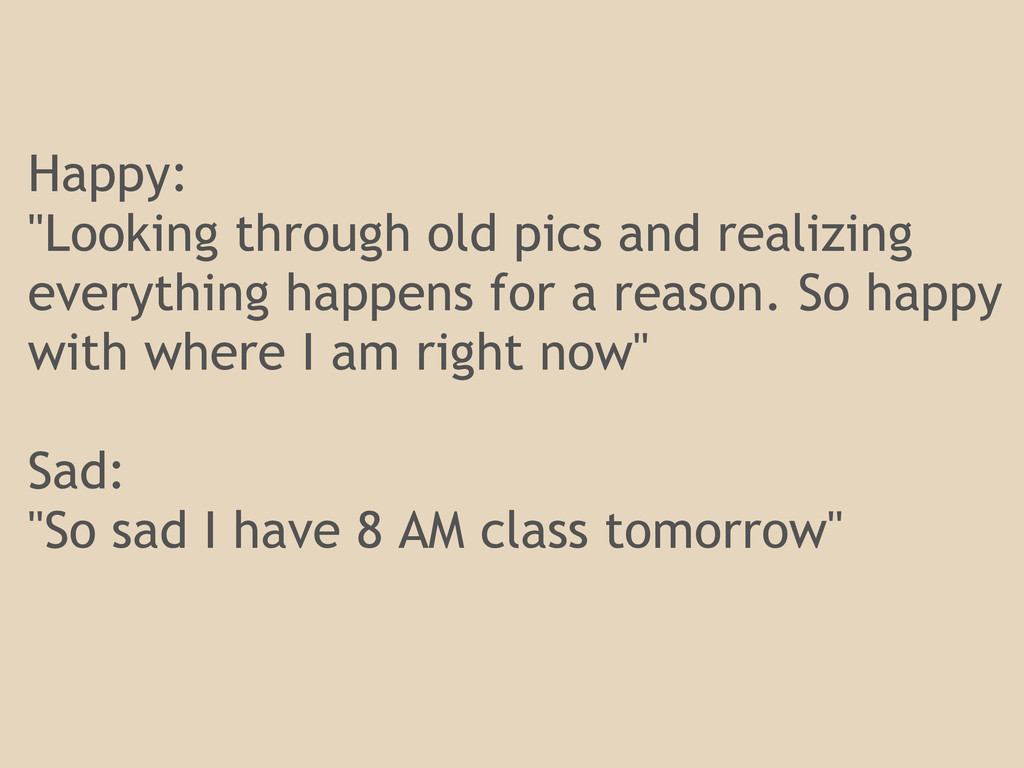
Happy: "Looking through old pics and realizing everything happens for
a reason. So happy with where I am right now" Sad: "So sad I have 8 AM class tomorrow"
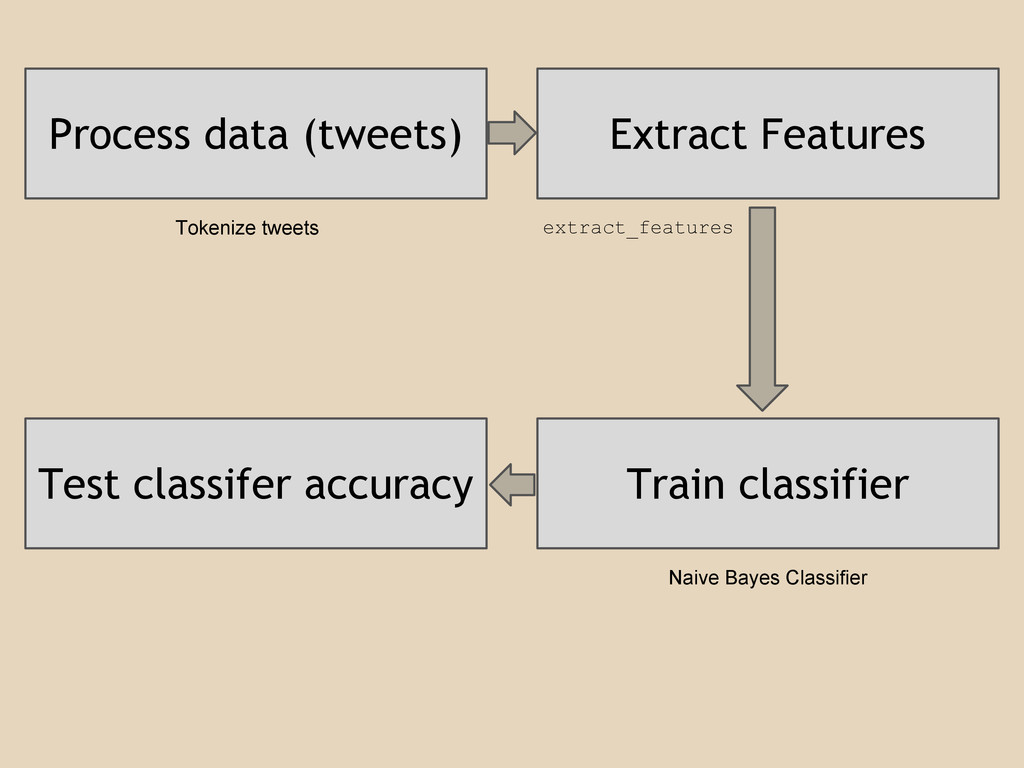
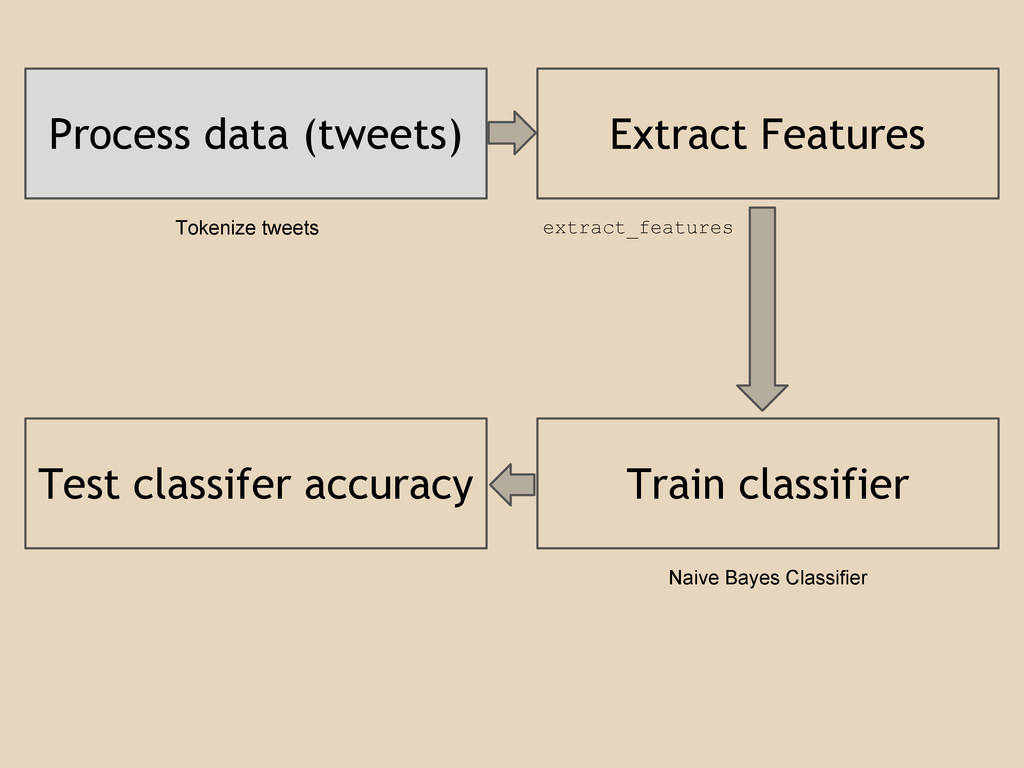
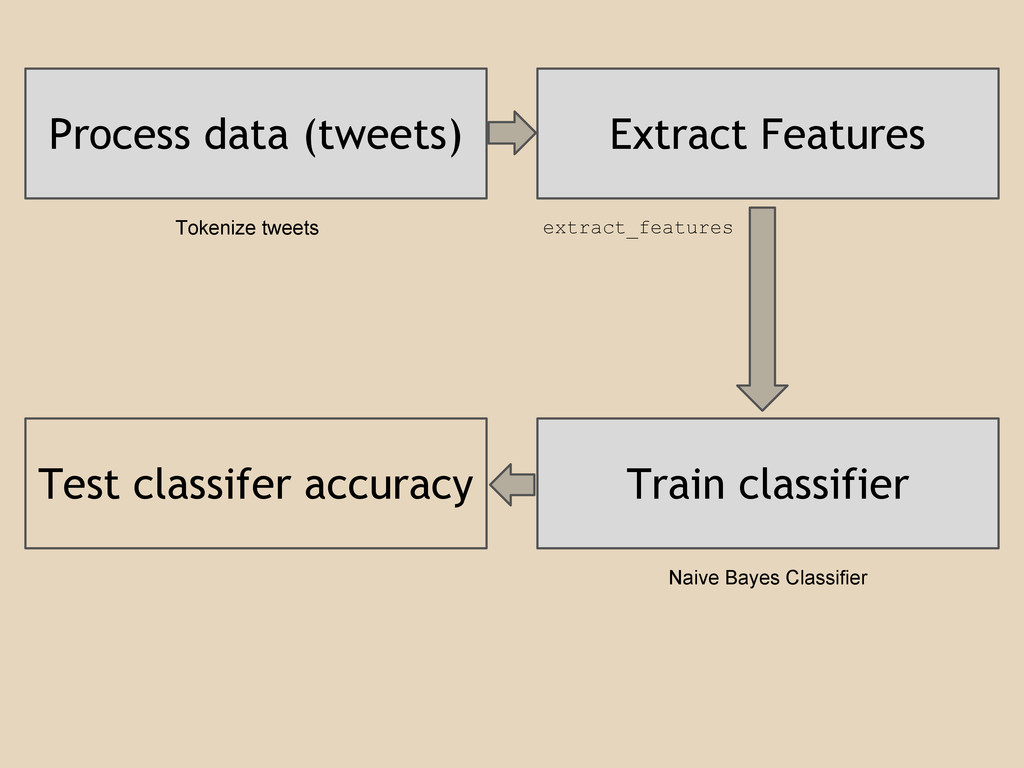
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
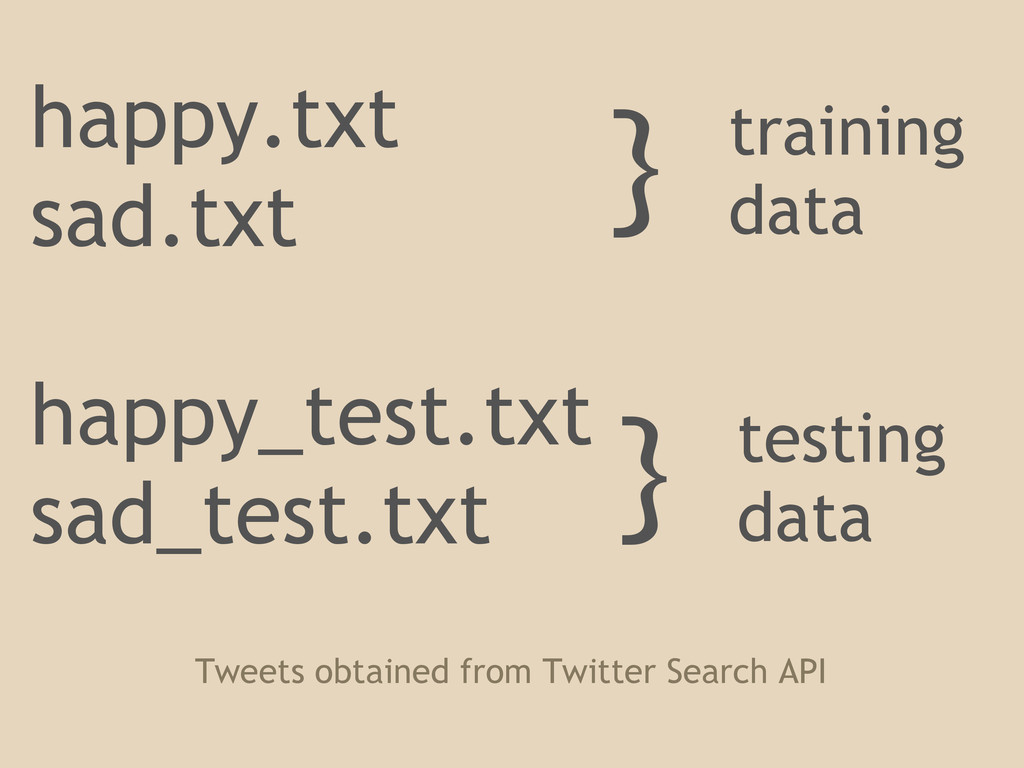
happy.txt sad.txt happy_test.txt sad_test.txt } training data } testing data
Tweets obtained from Twitter Search API
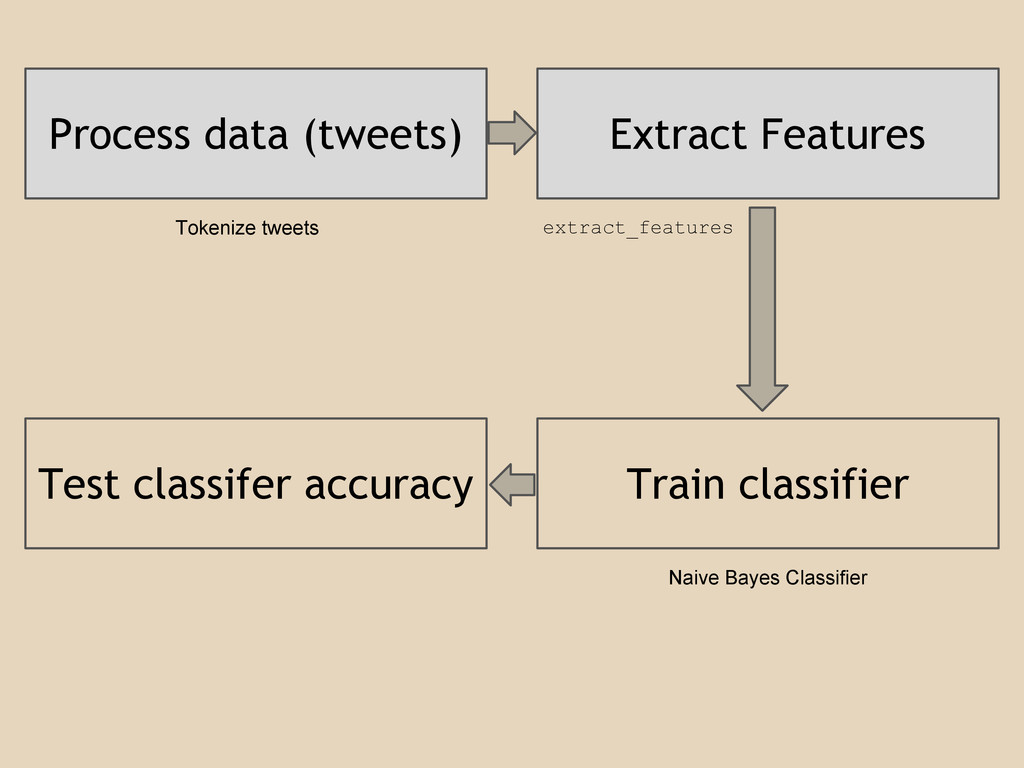
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
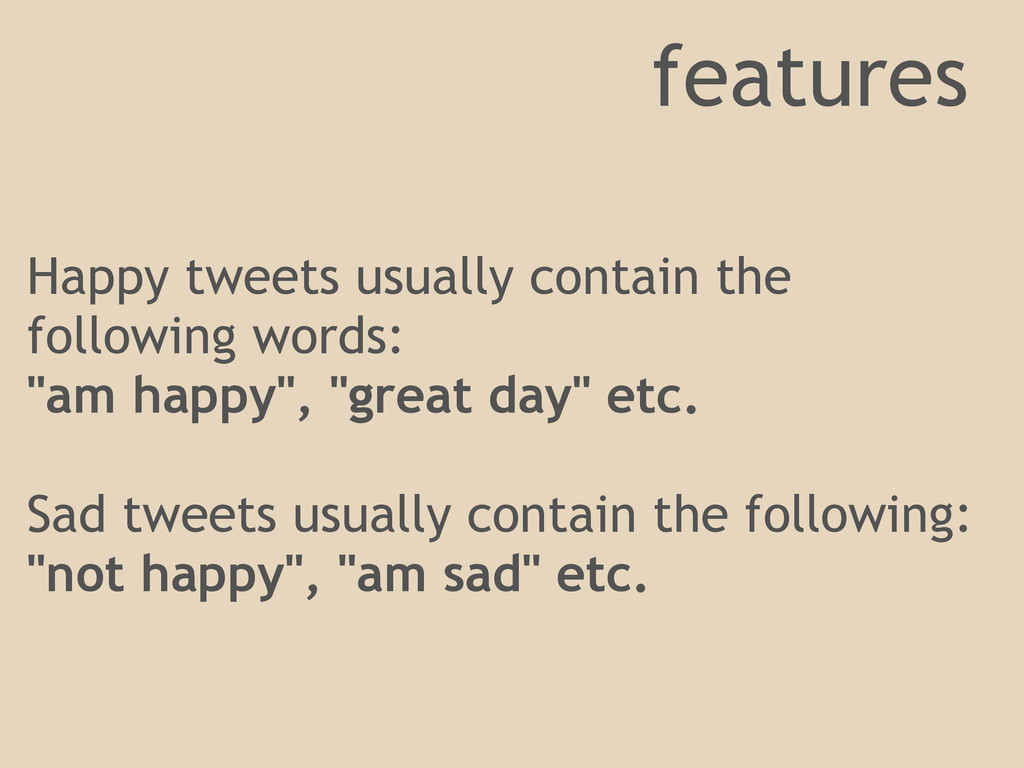
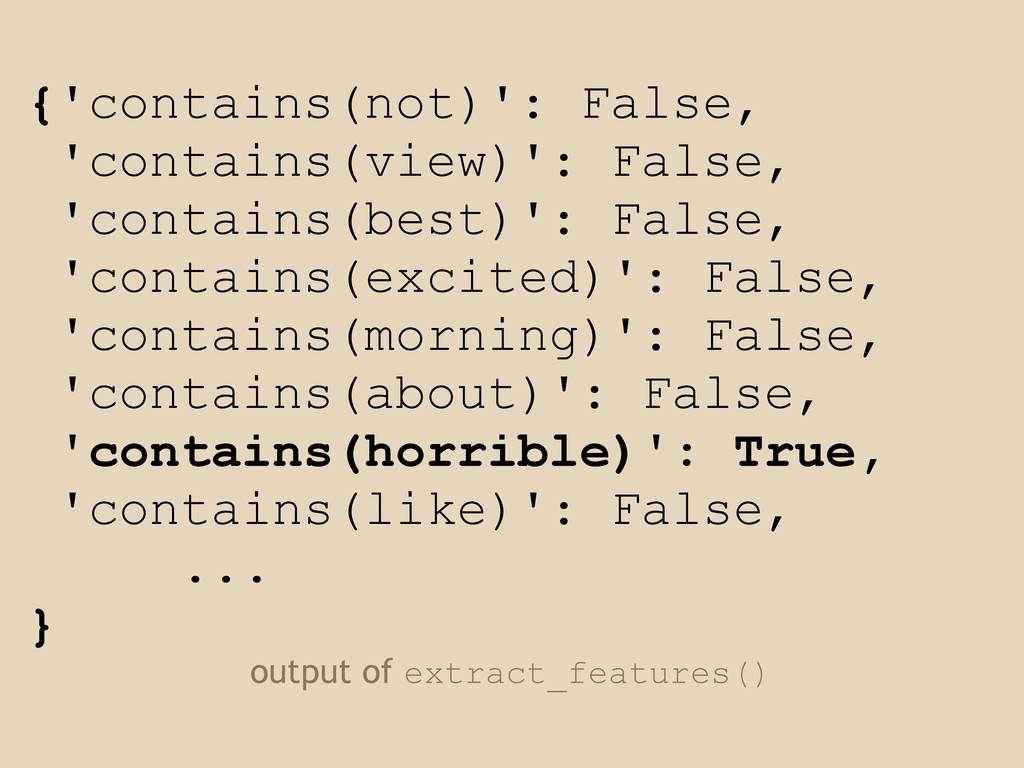
Happy tweets usually contain the following words: "am happy", "great
day" etc. Sad tweets usually contain the following: "not happy", "am sad" etc. features
{'contains(not)': False, 'contains(view)': False, 'contains(best)': False, 'contains(excited)': False, 'contains(morning)': False,
'contains(about)': False, 'contains(horrible)': True, 'contains(like)': False, ... } output of extract_features()
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
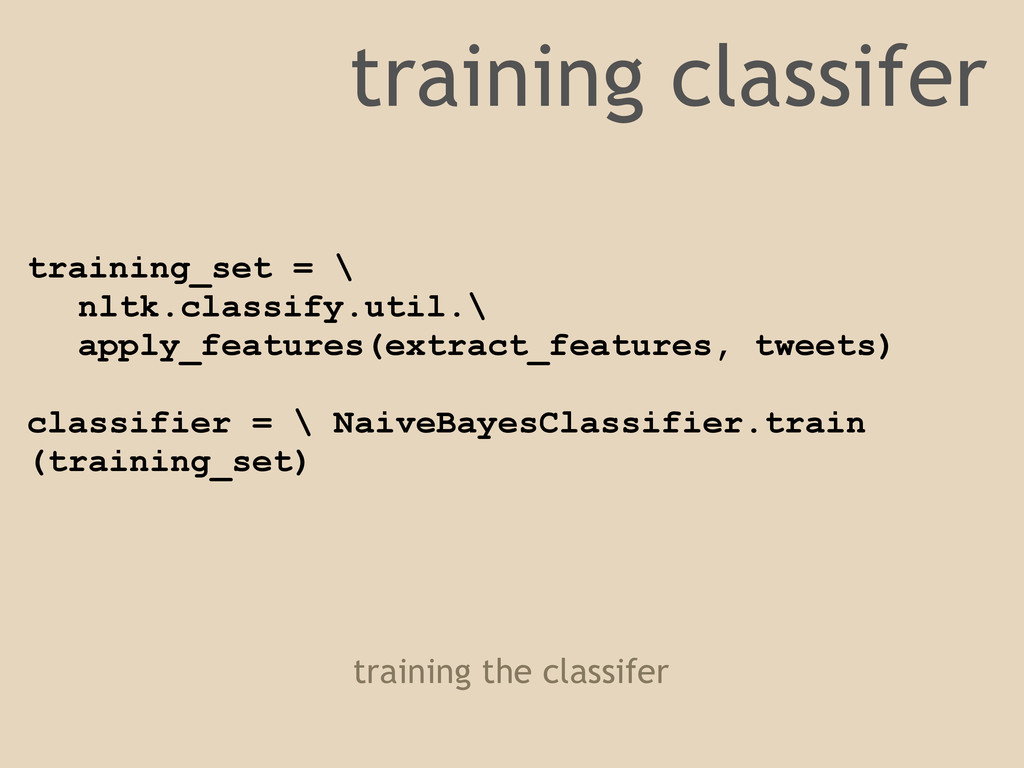
training_set = \ nltk.classify.util.\ apply_features(extract_features, tweets) classifier = \ NaiveBayesClassifier.train
(training_set) training the classifer training classifer
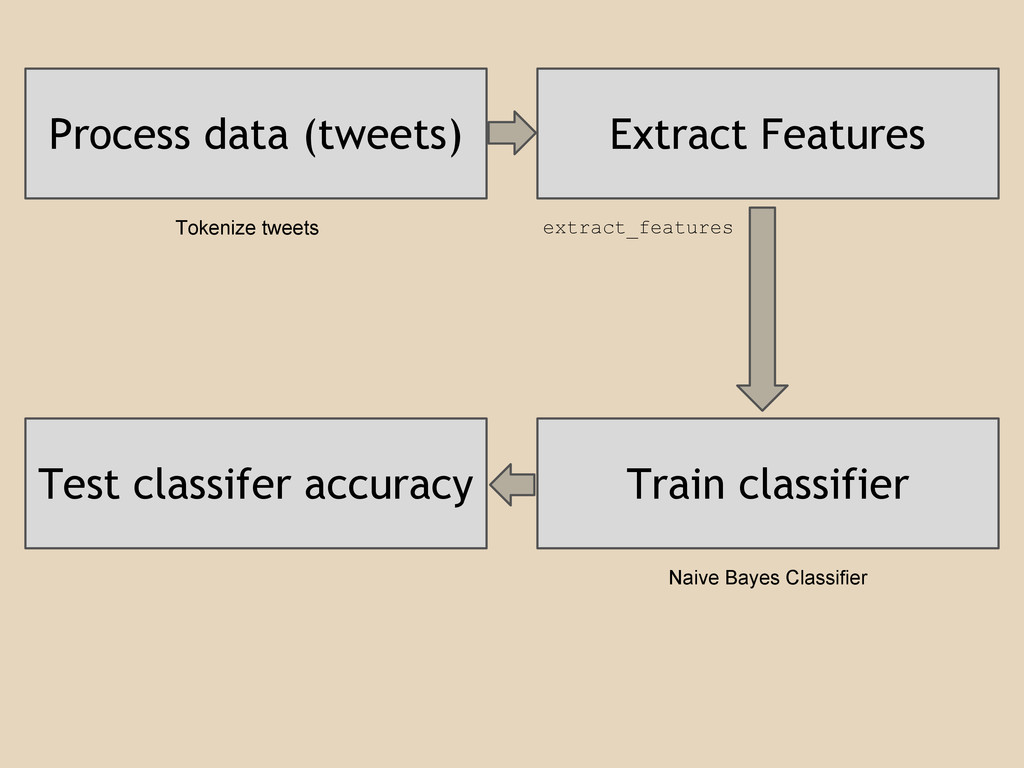
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
def classify_tweet(tweet): return \ classifier.classify(extract_features (tweet)) testing classifer
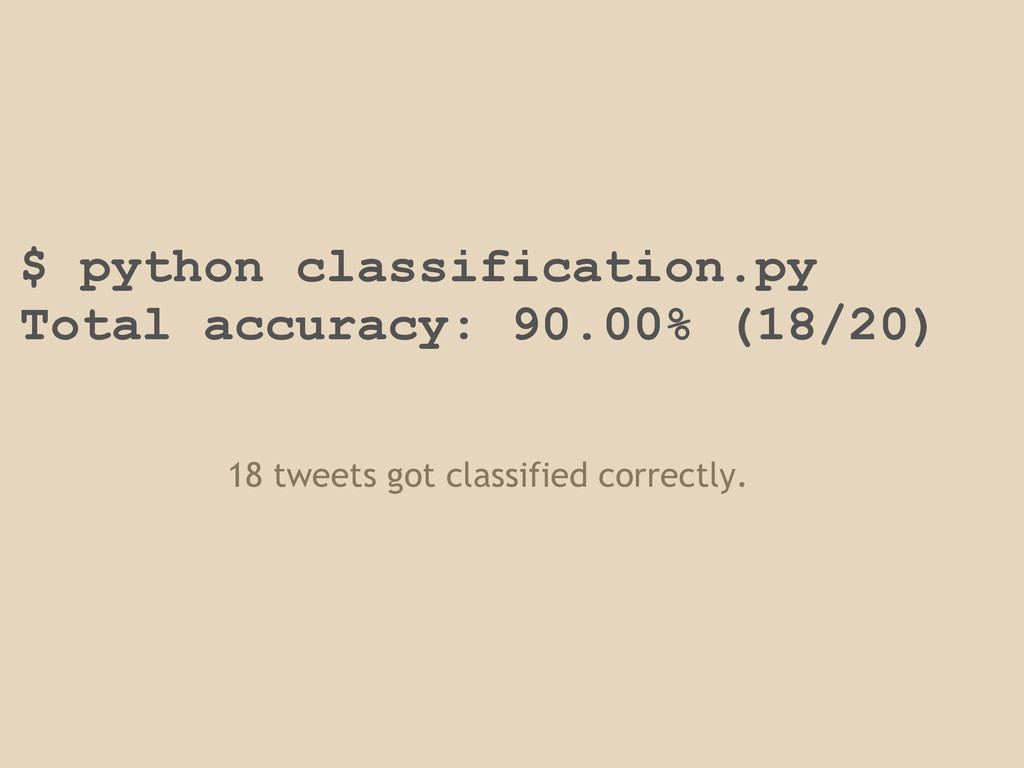
$ python classification.py Total accuracy: 90.00% (18/20) 18 tweets got
classified correctly.
Where to go from here.
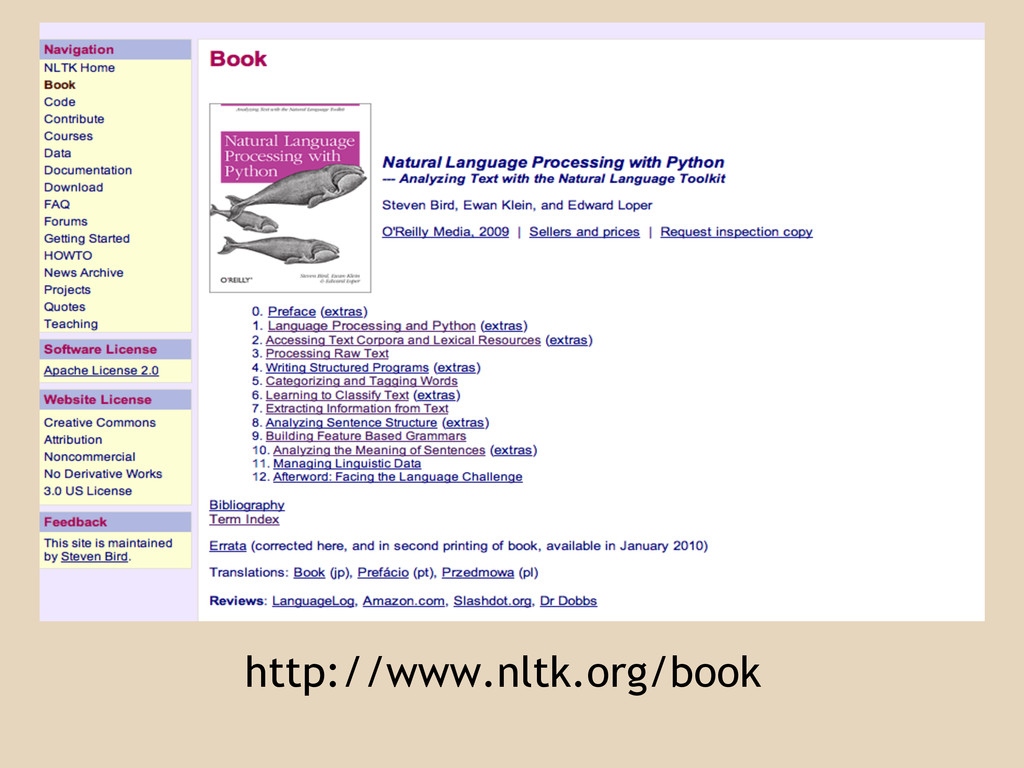
http://www.nltk.org/book
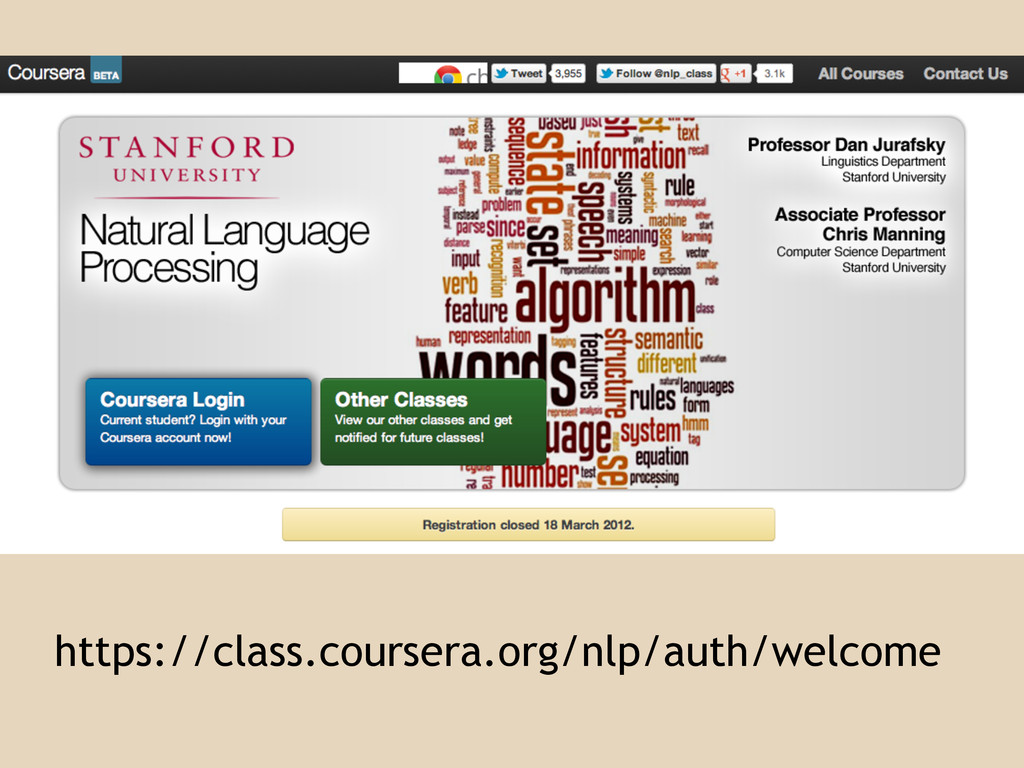
https://class.coursera.org/nlp/auth/welcome
http://www.slideshare.net/shanbady/nltk-boston-text-analytics
[('Thank', 'NNP'), ('you', 'PRP'), ('.', '.')] @victorneo

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 victorneo
 okajun35
 s_shimotori
 ryunen344
 convto
 shoppingjaws
 willnet
 danybony
 touyou
 tinykitten
 riku_sakamoto
 reimaru
 ken_tunc
 jonoalderson
 portentint
 csswizardry
 tomoyanonymous
 helenjbeal
 destraynor
 aemeredith
 codingconduct
 brad_frost
 signer
 samlambert
 kimpetersen