Share
Embed
Introduction to Elasticsearch
Global introduction to elastisearch presented at BigData meetup.
Use cases, getting started, Rest CRUD API, Mapping, Search API, Query DSL with queries and filters, Analyzers, Analytics with facets and aggregations, Percolator, High Availability, Clients & Integrations, ...
Eric Rodriguez
May 27, 2014
Transcript
53 slides
-
Introduction to Elasticsearch 27th May 2014 - BigData Meetup Eric
Rodriguez @wavyx -
About Me Eric Rodriguez Founder of data.be ! • Web
entrepreneur • Data addict • Multi-Language: PHP, Java/ Groovy/Grails, .Net, … be.linkedin.com/in/erodriguez ! github.com/wavyx ! @wavyx -
Elasticsearch - Company • Founded in 2012 => http://www.elasticsearch.com •
Professional services • Training • Consultancy / Development support • Production support subscription (3 levels of SLAs) -
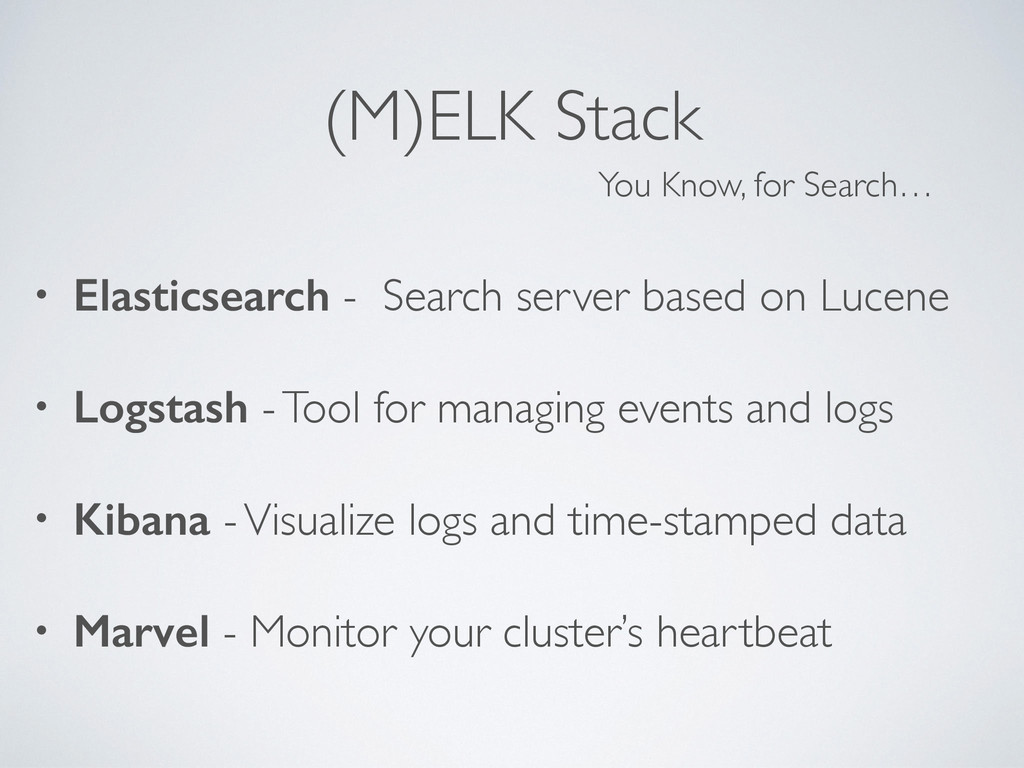
(M)ELK Stack • Elasticsearch - Search server based on Lucene
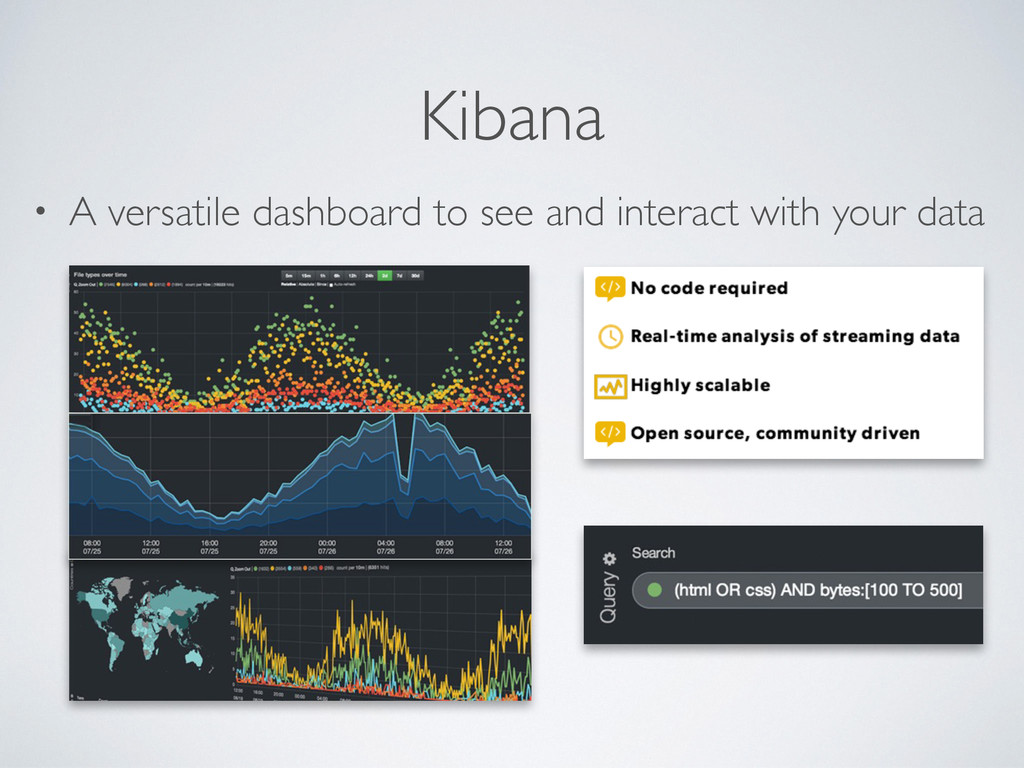
• Logstash - Tool for managing events and logs • Kibana - Visualize logs and time-stamped data • Marvel - Monitor your cluster’s heartbeat You Know, for Search… -
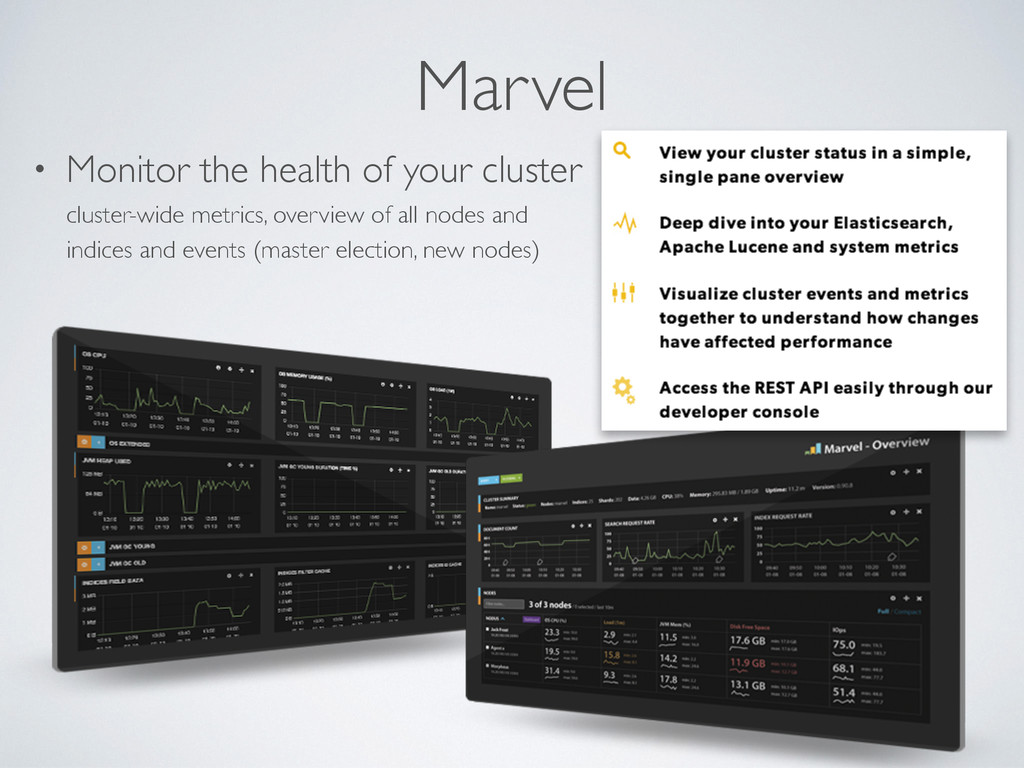
Marvel • Monitor the health of your cluster cluster-wide metrics,
overview of all nodes and indices and events (master election, new nodes) -
real time, search and analytics engine open-source Lucene JSON schema
free document store RESTful API documentation scalability high availability distributed multi tenancy per-operation persistence -
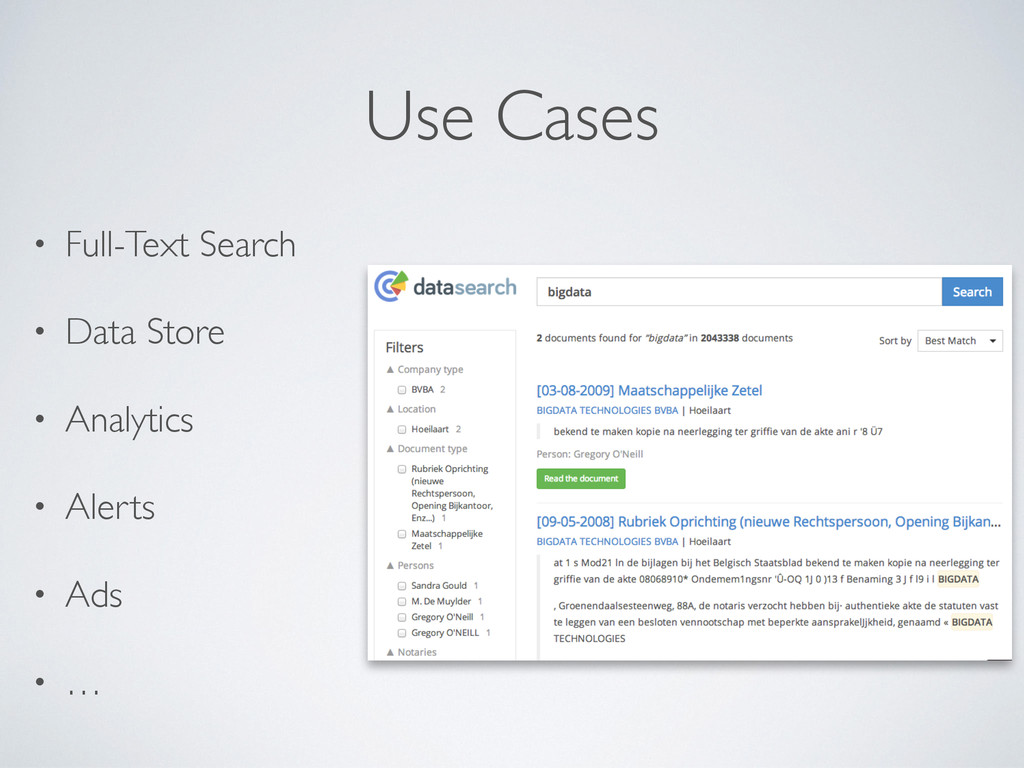
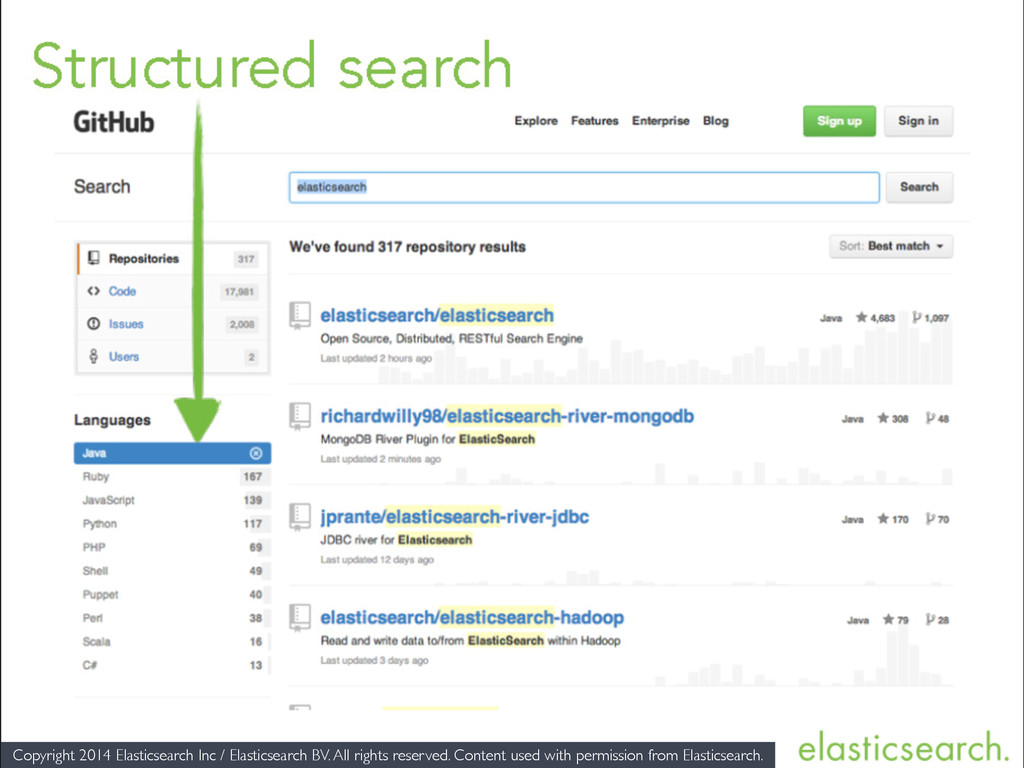
Use Cases • Full-Text Search • Data Store • Analytics
• Alerts • Ads • … -
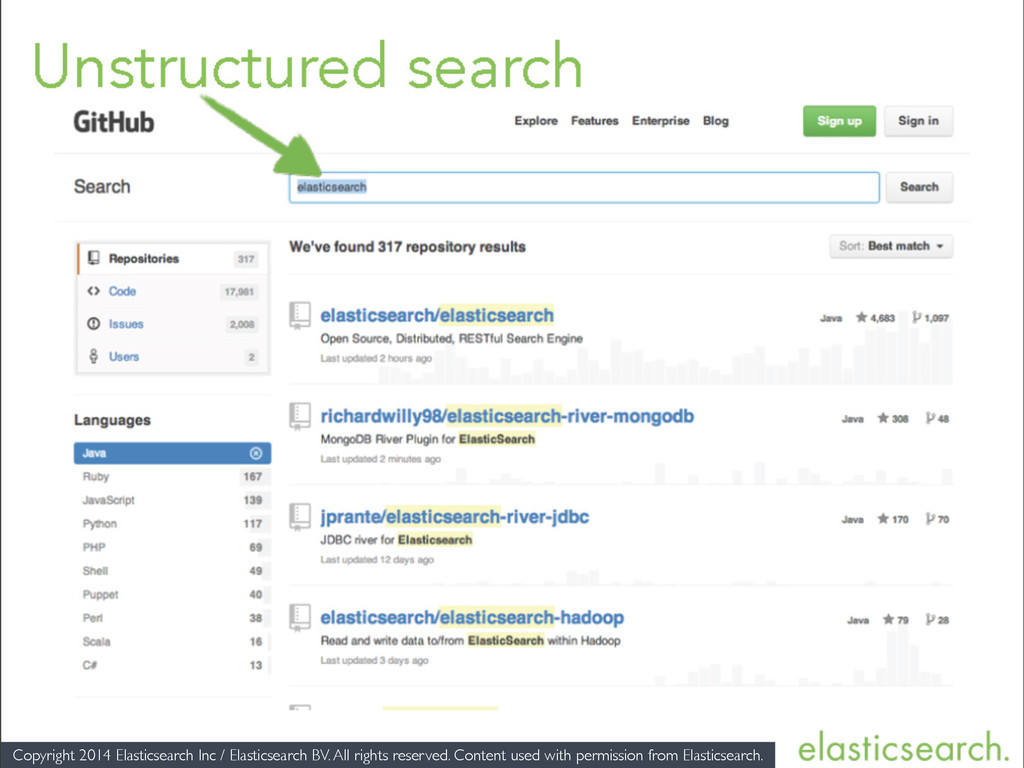
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
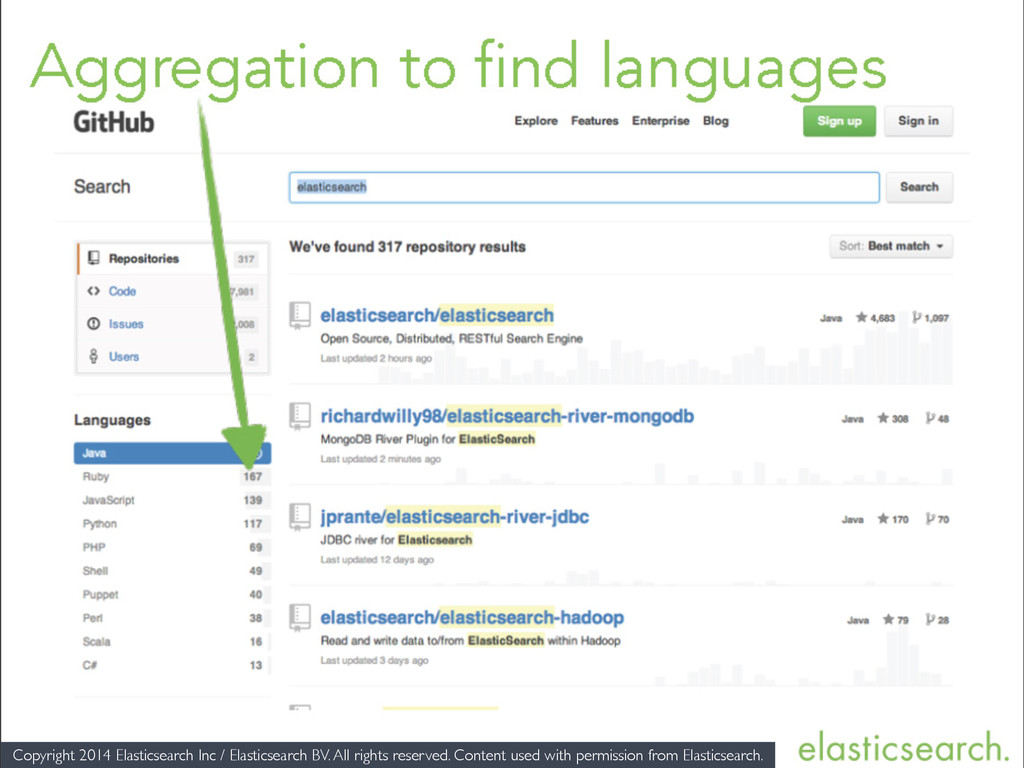
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
Elasticsearch core • Apache Lucene is a high-performance, full-featured text
search engine library written entirely in Java • Elasticsearch added value: “Simple is best” • Simple API (with documentation) • JSON & RESTful • Sharding & Replication • Extensibility: plugins and scripts • Interoperability: clients and integrations -
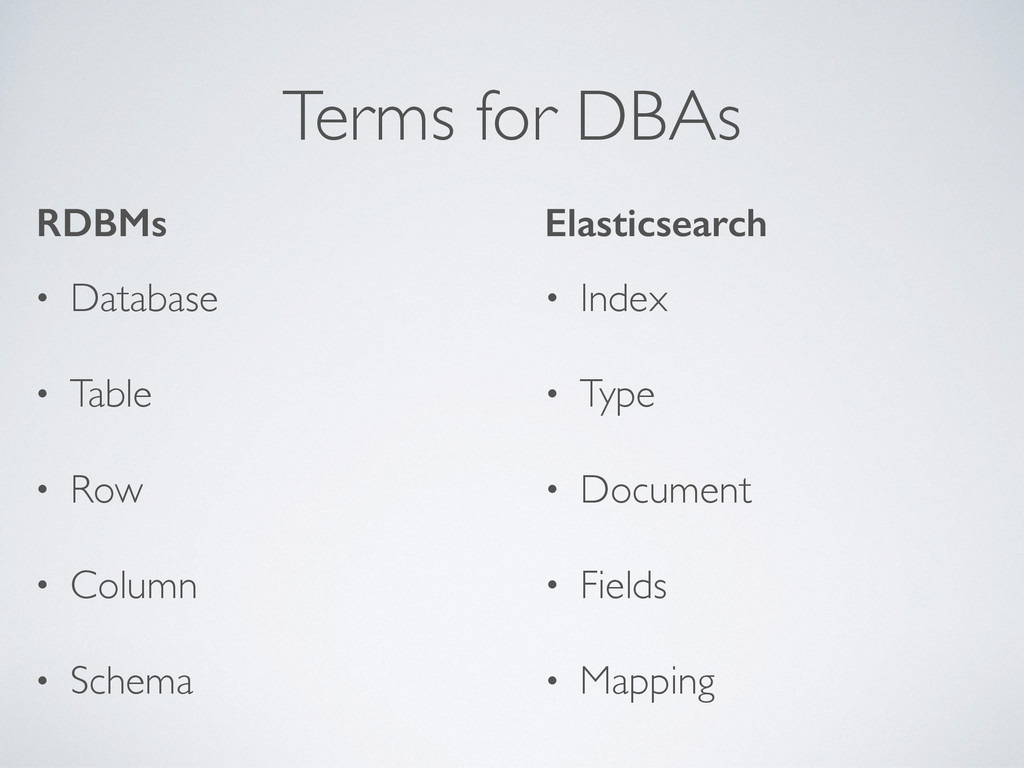
Terms for DBAs • Index • Type • Document •
Fields • Mapping Elasticsearch RDBMs • Database • Table • Row • Column • Schema -
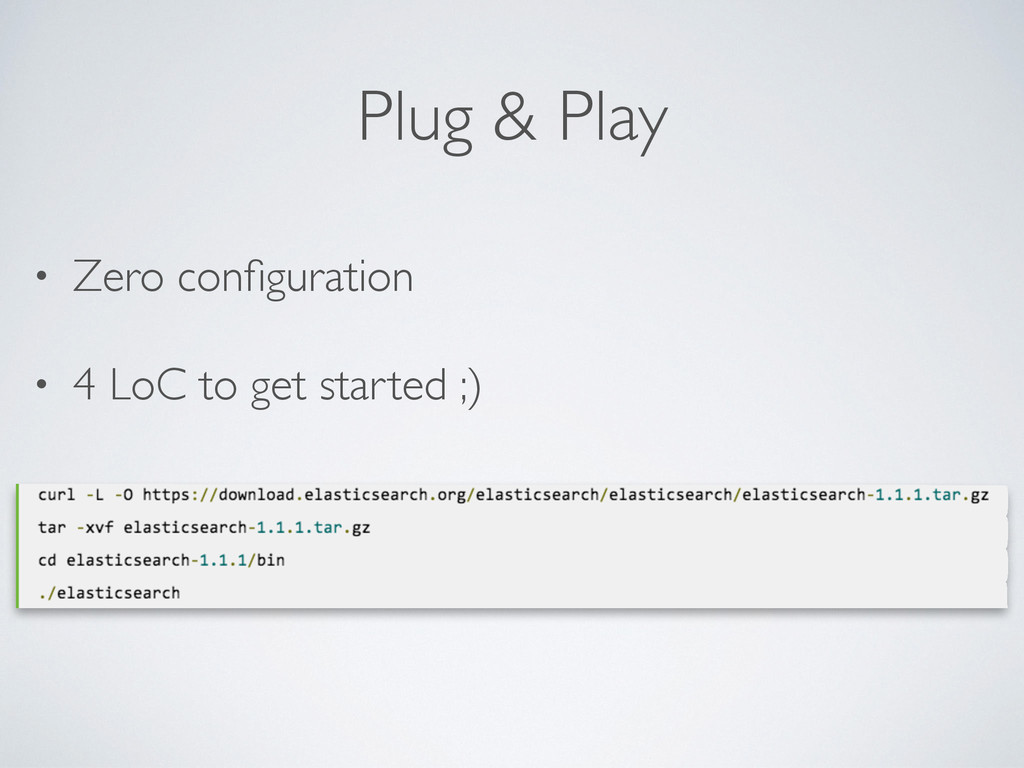
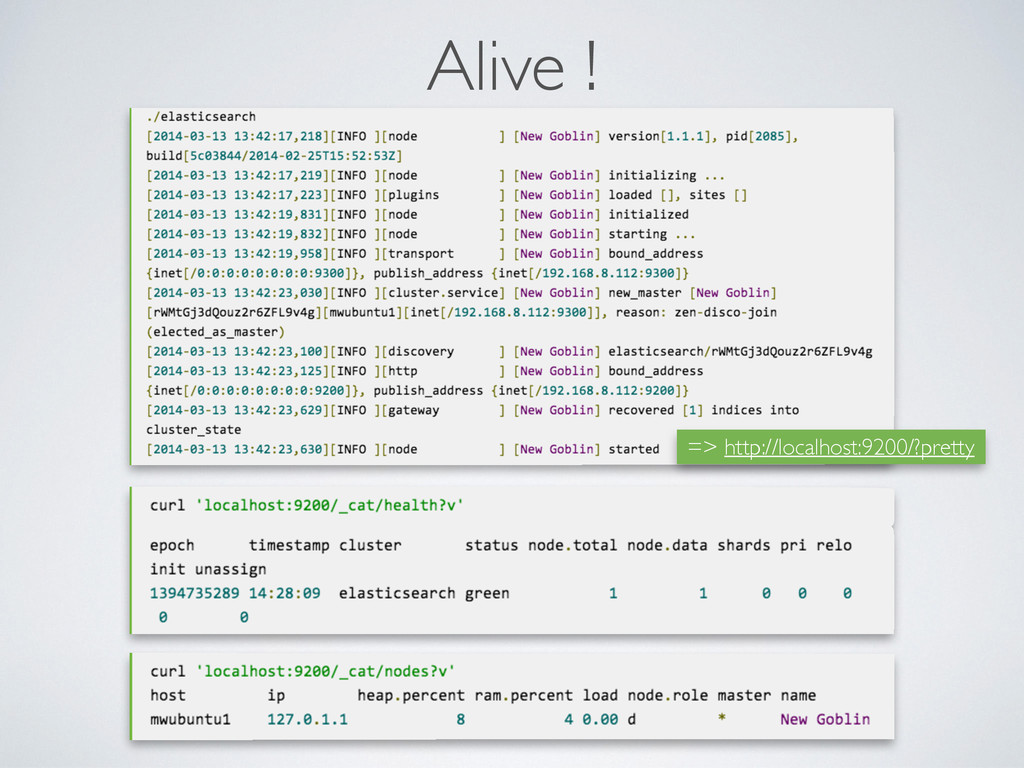
Plug & Play • Zero configuration • 4 LoC to
get started ;) -
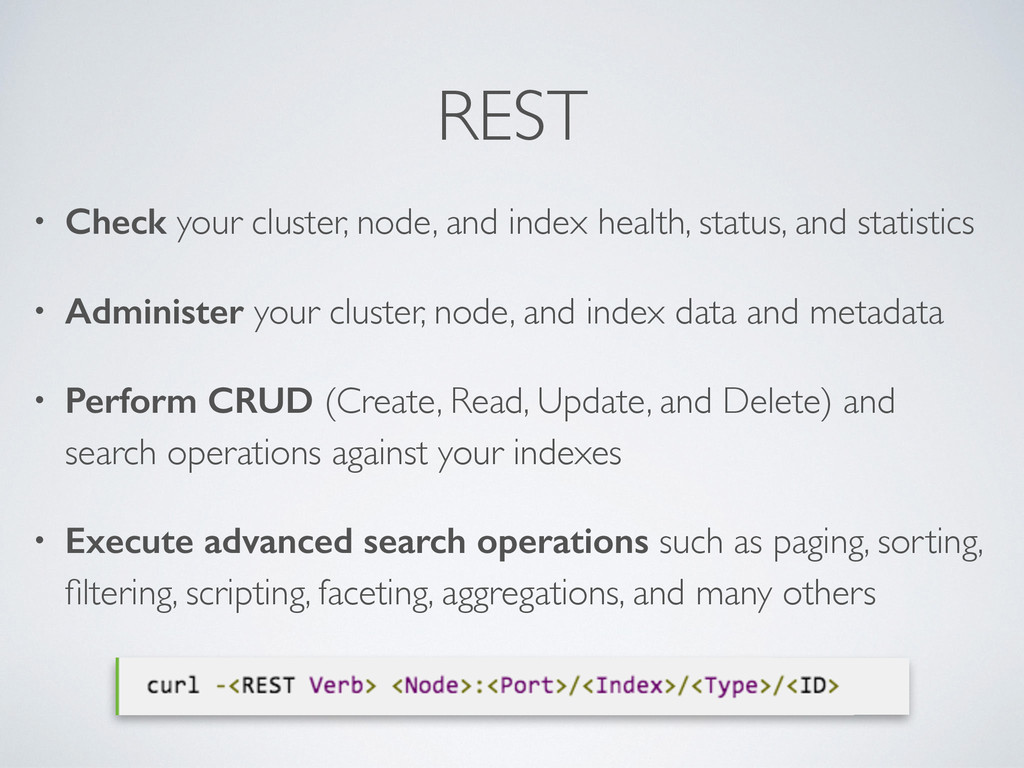
REST • Check your cluster, node, and index health, status,
and statistics • Administer your cluster, node, and index data and metadata • Perform CRUD (Create, Read, Update, and Delete) and search operations against your indexes • Execute advanced search operations such as paging, sorting, filtering, scripting, faceting, aggregations, and many others -
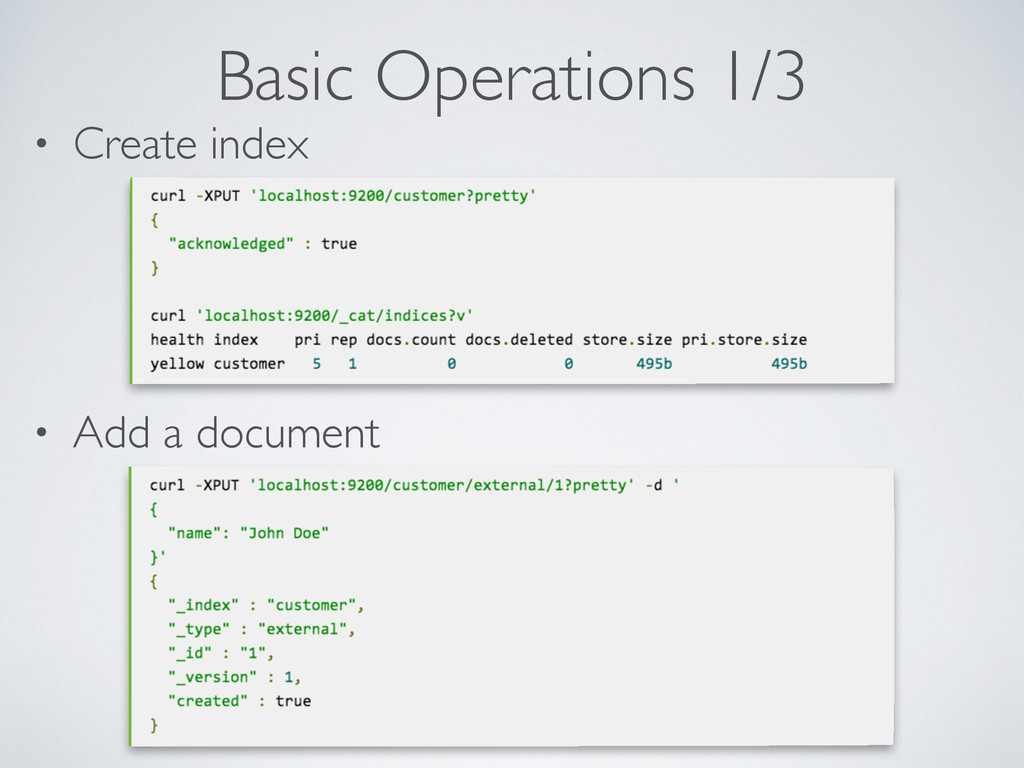
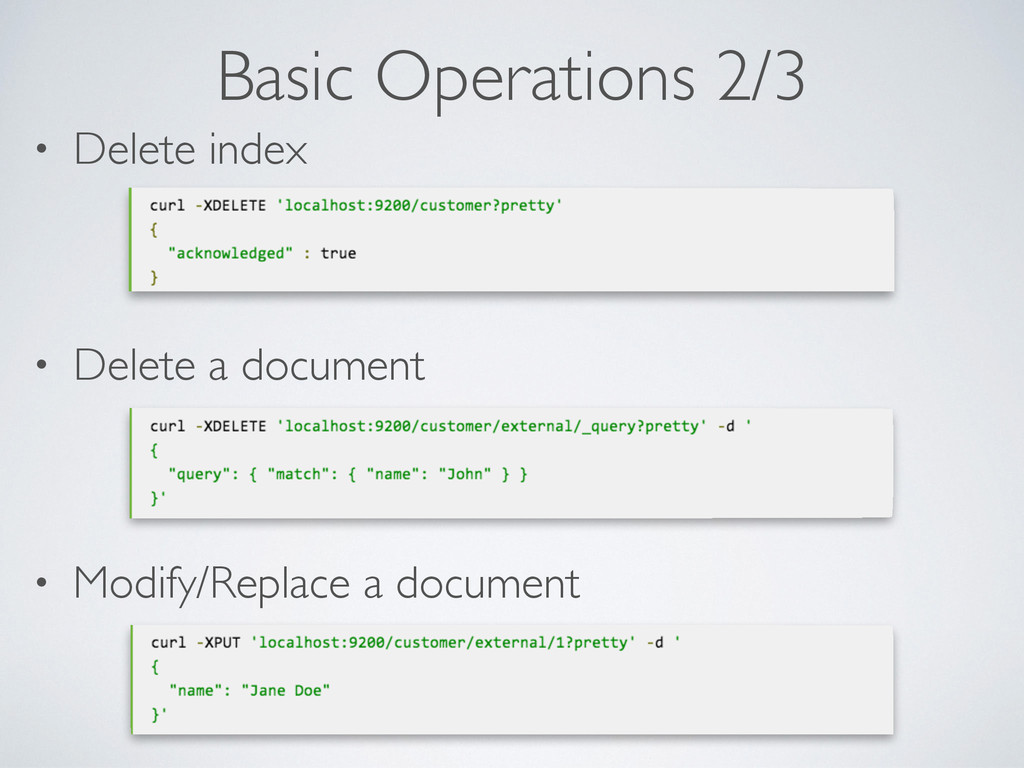
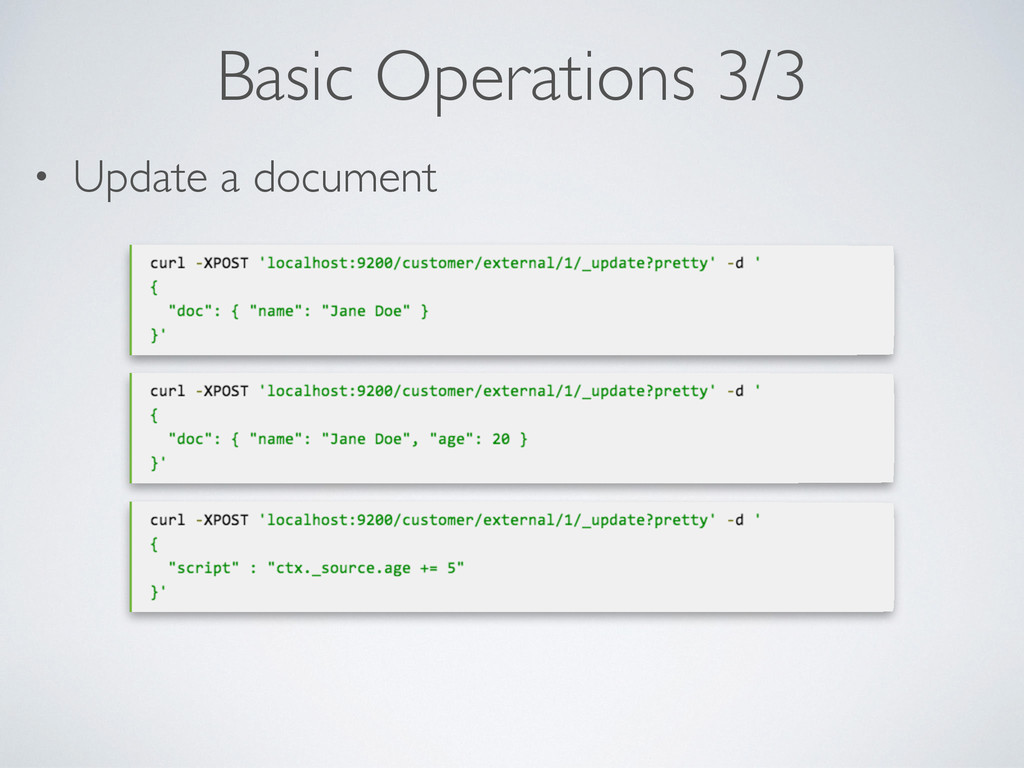
Basic Operations 2/3 • Modify/Replace a document • Delete a
document • Delete index -
Mapping 1/2 • Define how a document should be mapped
(similar to schema): searchable fields, tokenization, storage, .. • Explicit mapping is defined on an index/type level • A default mapping is automatically created -
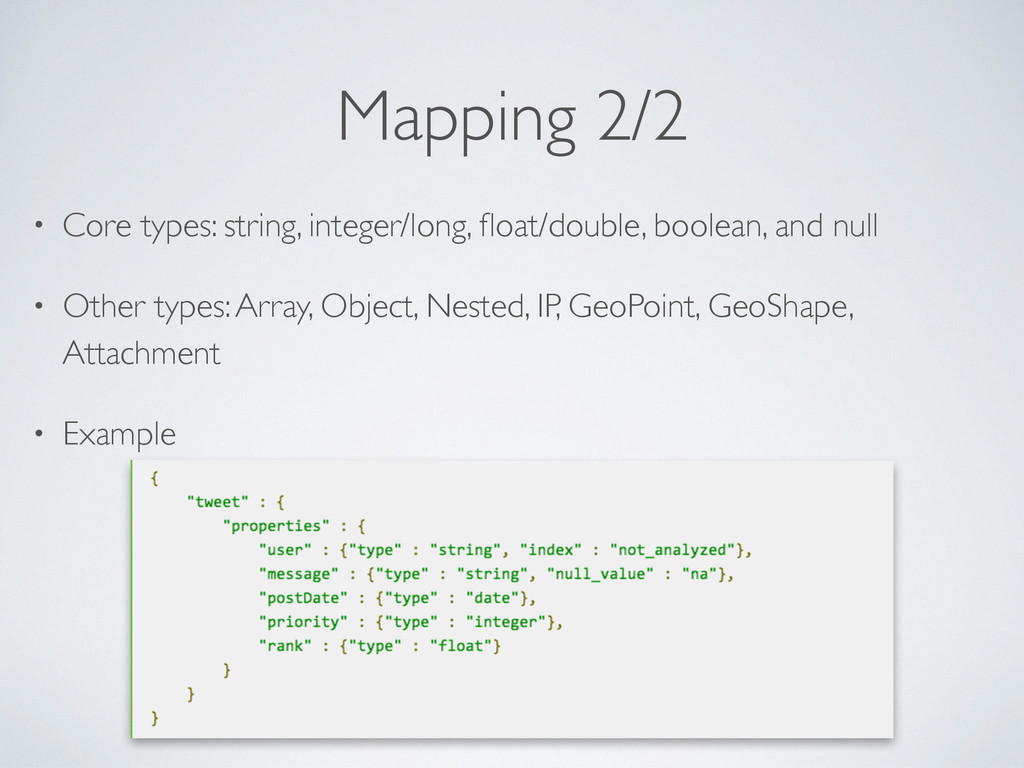
Mapping 2/2 • Core types: string, integer/long, float/double, boolean, and
null • Other types: Array, Object, Nested, IP, GeoPoint, GeoShape, Attachment • Example -
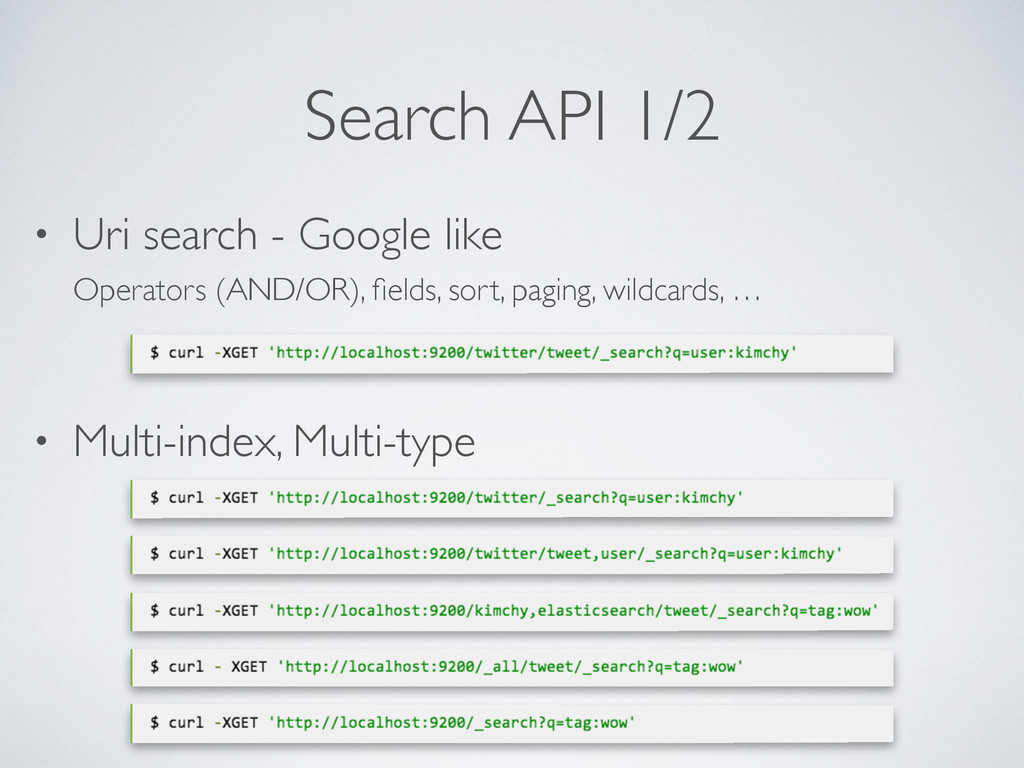
Search API 1/2 • Multi-index, Multi-type • Uri search -
Google like Operators (AND/OR), fields, sort, paging, wildcards, … -
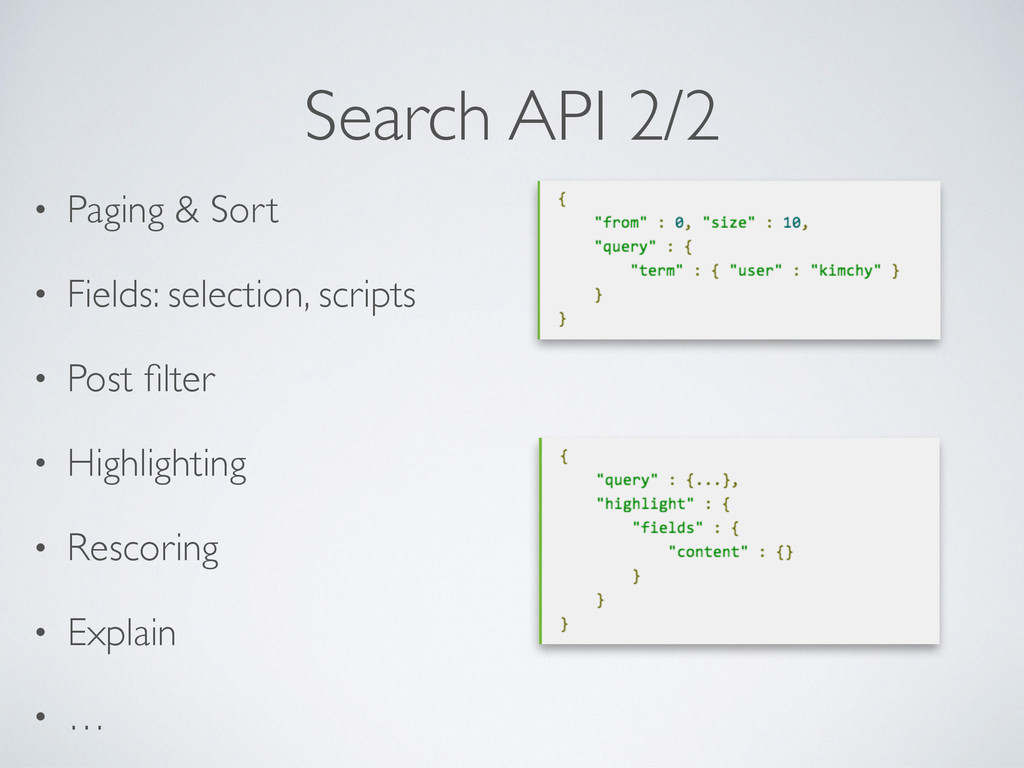
Search API 2/2 • Paging & Sort • Fields: selection,
scripts • Post filter • Highlighting • Rescoring • Explain • … -
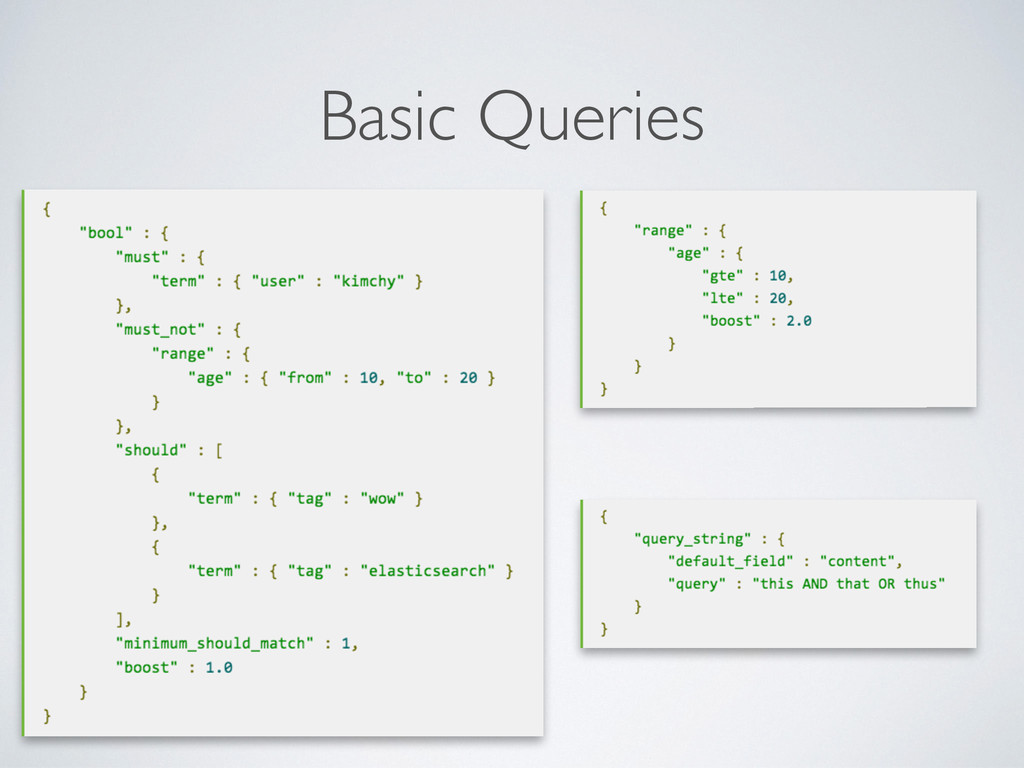
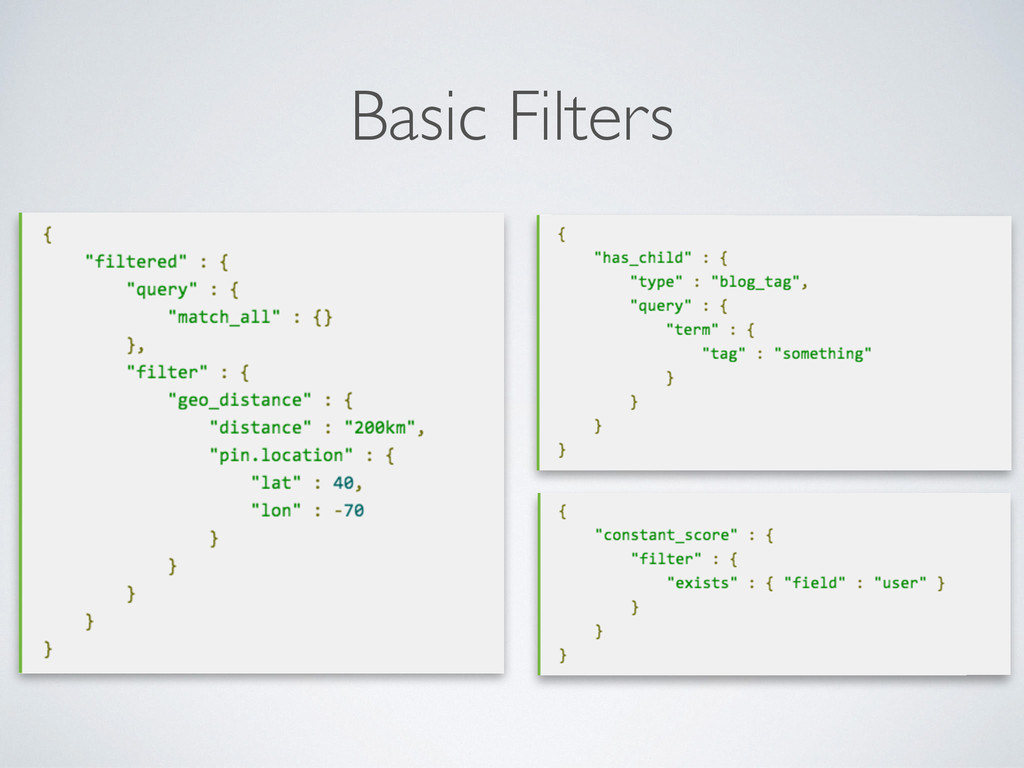
Query DSL • “SQL” for elasticsearch • Queries should be
used • for full text search • where the result depends on a relevance score • Filters should be used • for binary yes/no searches • for queries on exact values -
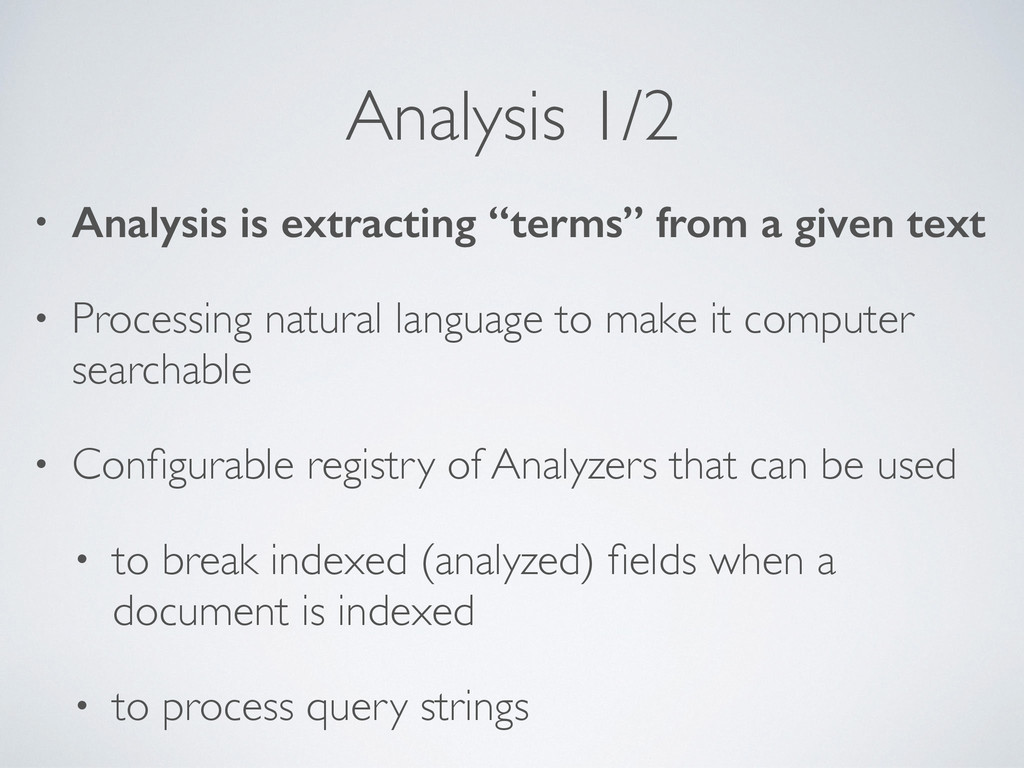
Analysis 1/2 • Analysis is extracting “terms” from a given
text • Processing natural language to make it computer searchable • Configurable registry of Analyzers that can be used • to break indexed (analyzed) fields when a document is indexed • to process query strings -
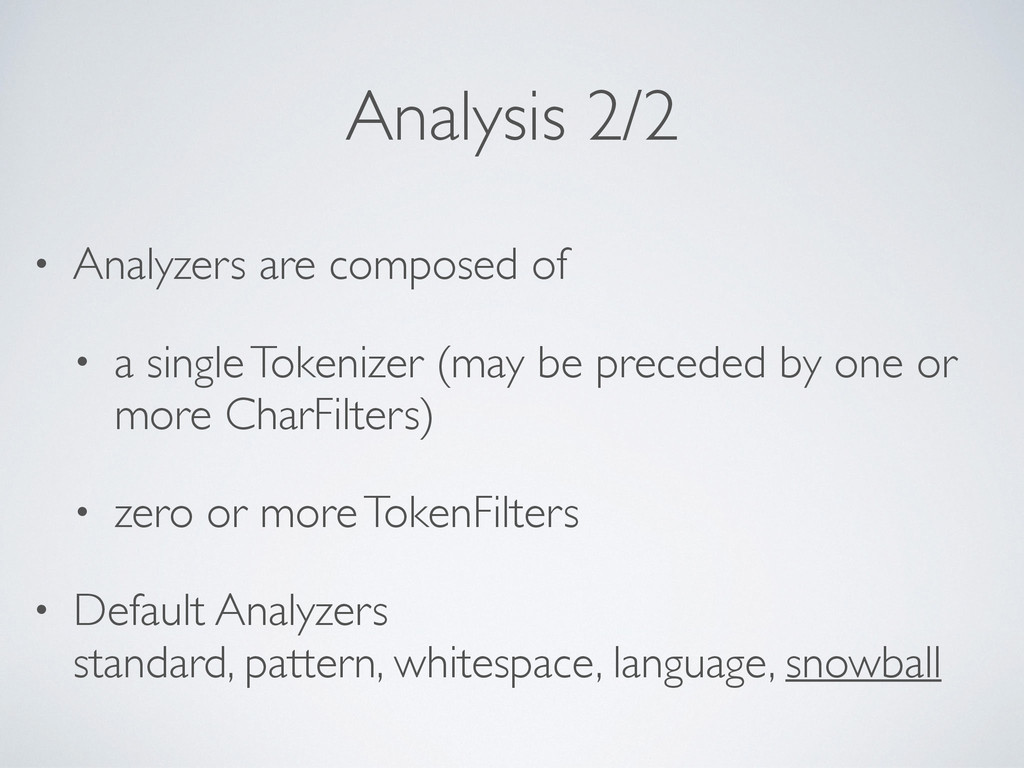
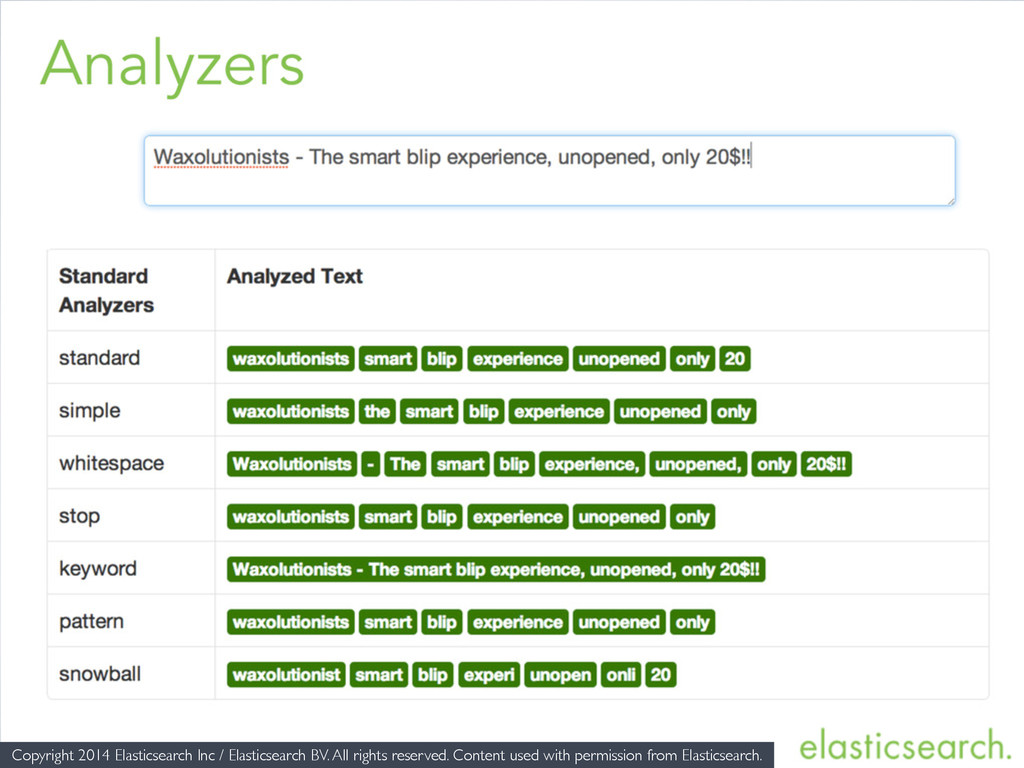
Analysis 2/2 • Analyzers are composed of • a single
Tokenizer (may be preceded by one or more CharFilters) • zero or more TokenFilters • Default Analyzers standard, pattern, whitespace, language, snowball -
Copyright 2014 Elasticsearch Inc / Elasticsearch BV. All rights reserved.
Content used with permission from Elasticsearch. -
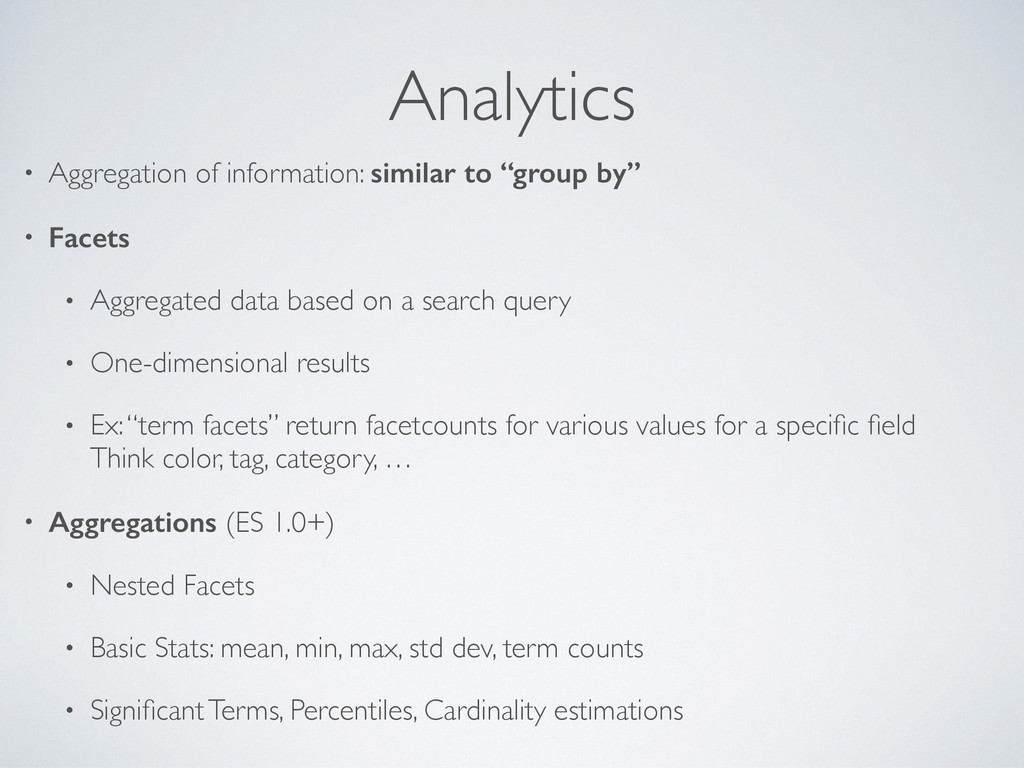
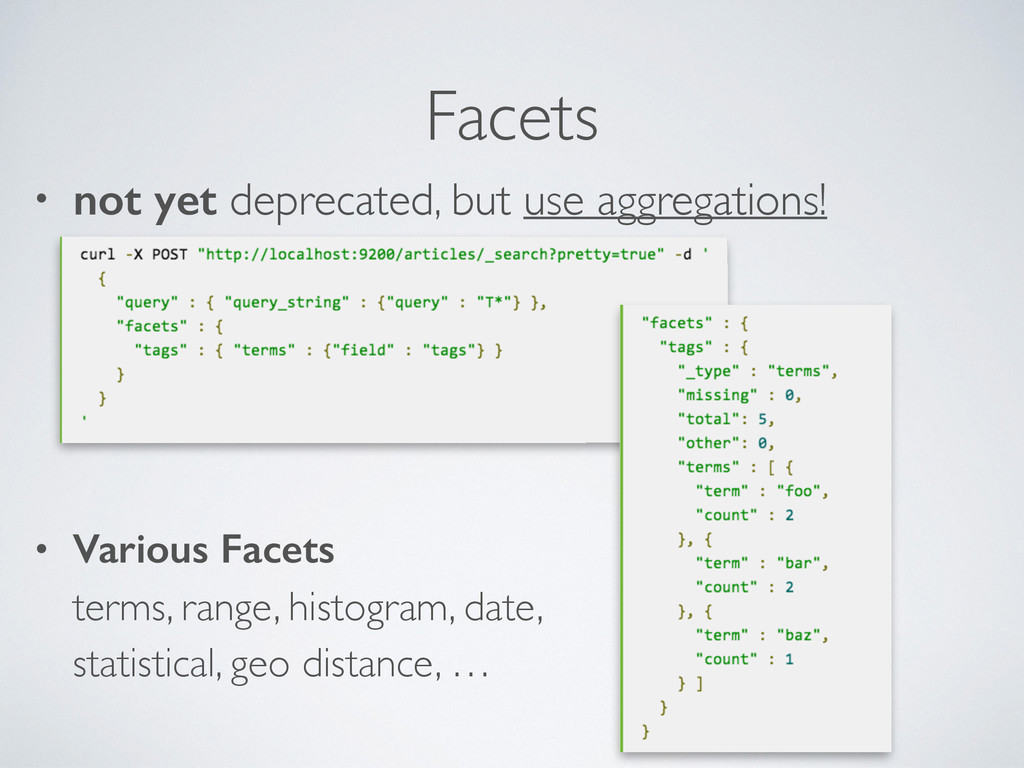
Analytics • Aggregation of information: similar to “group by” •
Facets • Aggregated data based on a search query • One-dimensional results • Ex: “term facets” return facetcounts for various values for a specific field Think color, tag, category, … • Aggregations (ES 1.0+) • Nested Facets • Basic Stats: mean, min, max, std dev, term counts • Significant Terms, Percentiles, Cardinality estimations -
Facets • not yet deprecated, but use aggregations! • Various
Facets terms, range, histogram, date, statistical, geo distance, … -
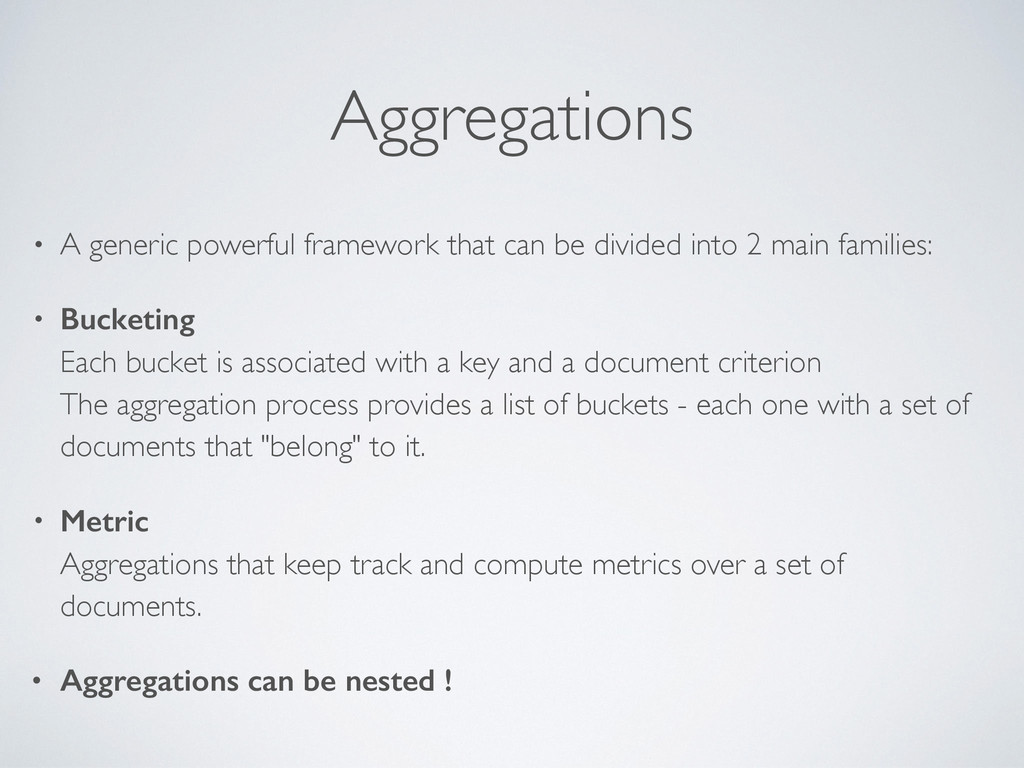
Aggregations • A generic powerful framework that can be divided
into 2 main families: • Bucketing Each bucket is associated with a key and a document criterion The aggregation process provides a list of buckets - each one with a set of documents that "belong" to it. • Metric Aggregations that keep track and compute metrics over a set of documents. • Aggregations can be nested ! -
Bucket Aggregators • global • filter • missing • terms
• range • date range • ip range • histogram • date histogram • geo distance • geohash grid • nested • reverse nested • top hits (version 1.3) -
Metrics Aggregators • count • stats • extended stats •
cardinality • percentiles • min • max • sum • avg -
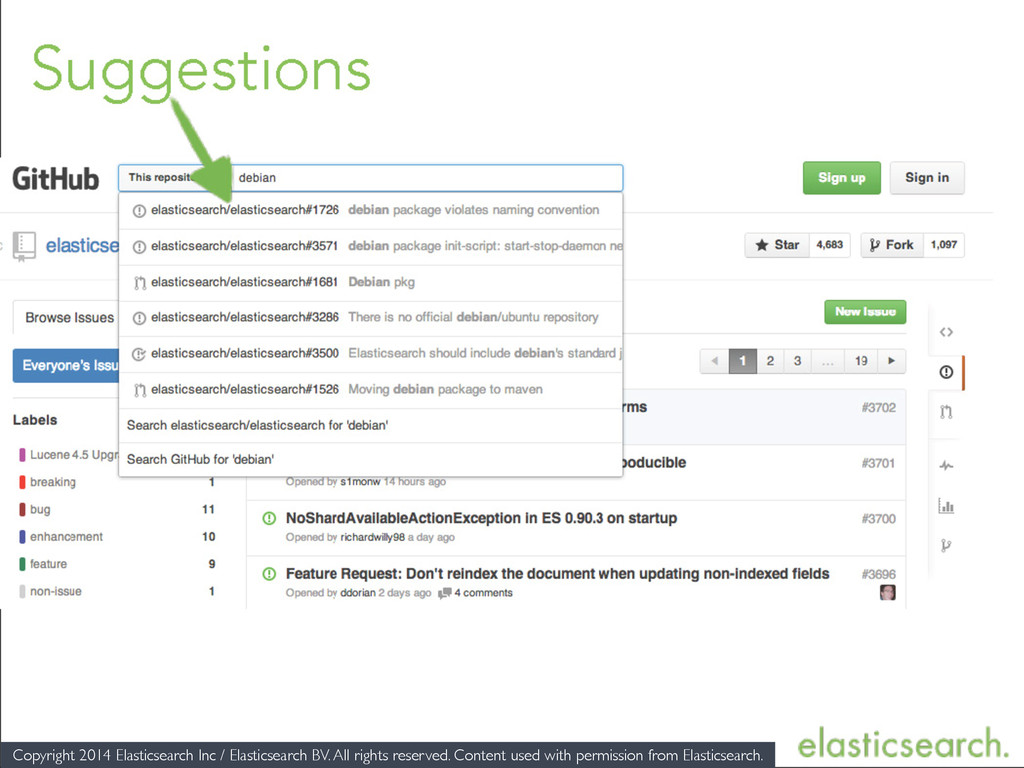
Search for end users • Suggesters - “Did you mean”
Terms, Phrases, Completion, Context • “More like this” Find documents that are "like" provided text by running it against one or more fields -
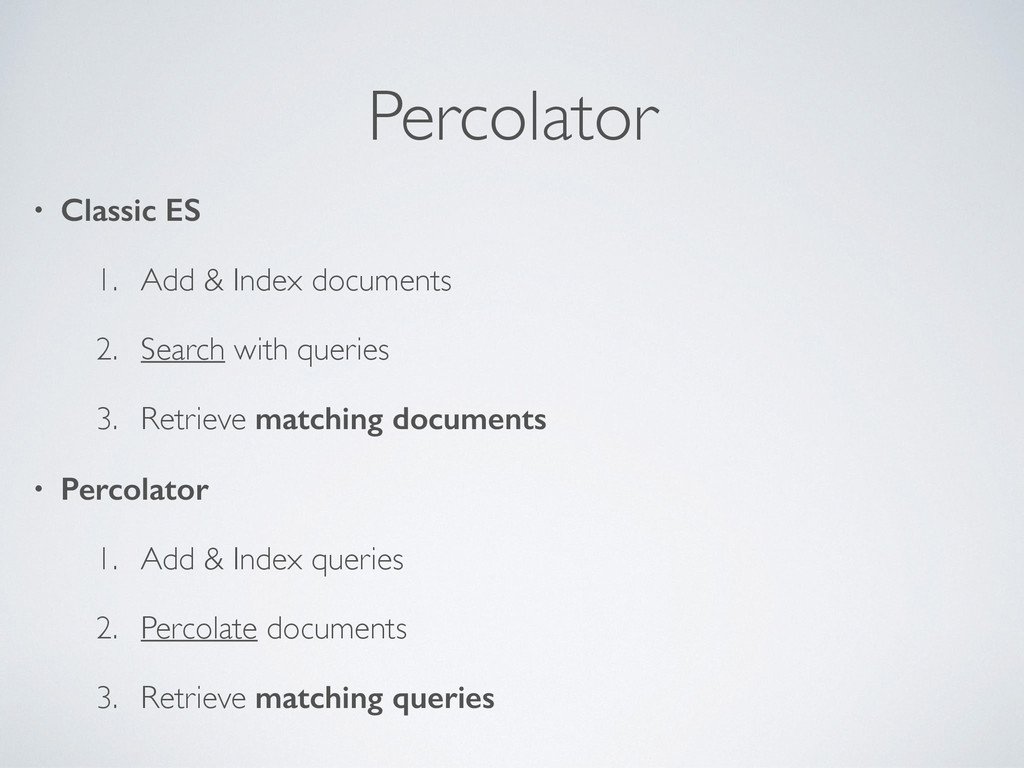
Percolator • Classic ES 1. Add & Index documents 2.
Search with queries 3. Retrieve matching documents • Percolator 1. Add & Index queries 2. Percolate documents 3. Retrieve matching queries -
Why Percolate ?! • Alerts: social media mentions, weather forecast,
news alerts • Automatic Monitoring: price monitoring, stock alerts, logs • Ads: display targeted ads based on user’s search queries • Enrich: percolate new documents, then add query matches as document tags -
High Availability 1/2 • Sharding - Write Scalability • Split
logical data over multiple machines & Control data flows • Each index has a fixed number of shards • Improve indexing performance • Replication - Read Scalability • Each shard can have 0-many replicas (dynamic setup) • Removing SPOF (Single Point Of Failure) • Improve search performance -
High Availability 2/2 • Zen Discovery • Automatic discovery of
nodes within a cluster and electing a master node • Useful for failover and replication • Specific modules: Amazon EC2, Microsoft Azure, Google Compute Engine • Snapshot & Restore module -
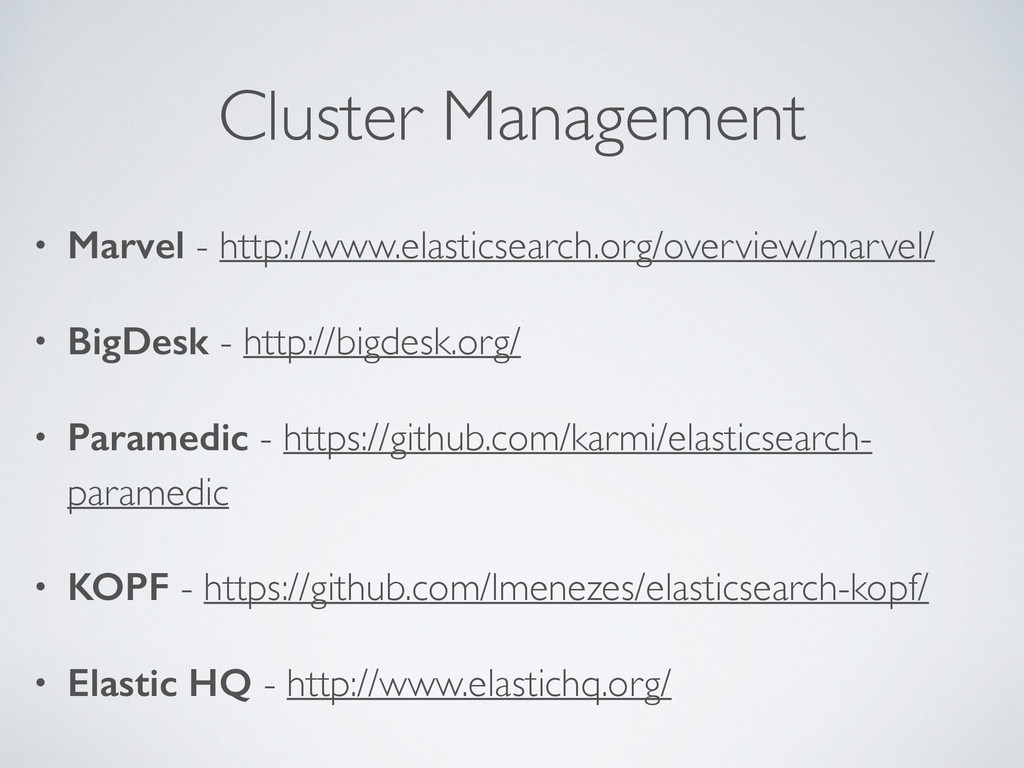
Cluster Management • Marvel - http://www.elasticsearch.org/overview/marvel/ • BigDesk - http://bigdesk.org/
• Paramedic - https://github.com/karmi/elasticsearch- paramedic • KOPF - https://github.com/lmenezes/elasticsearch-kopf/ • Elastic HQ - http://www.elastichq.org/ -
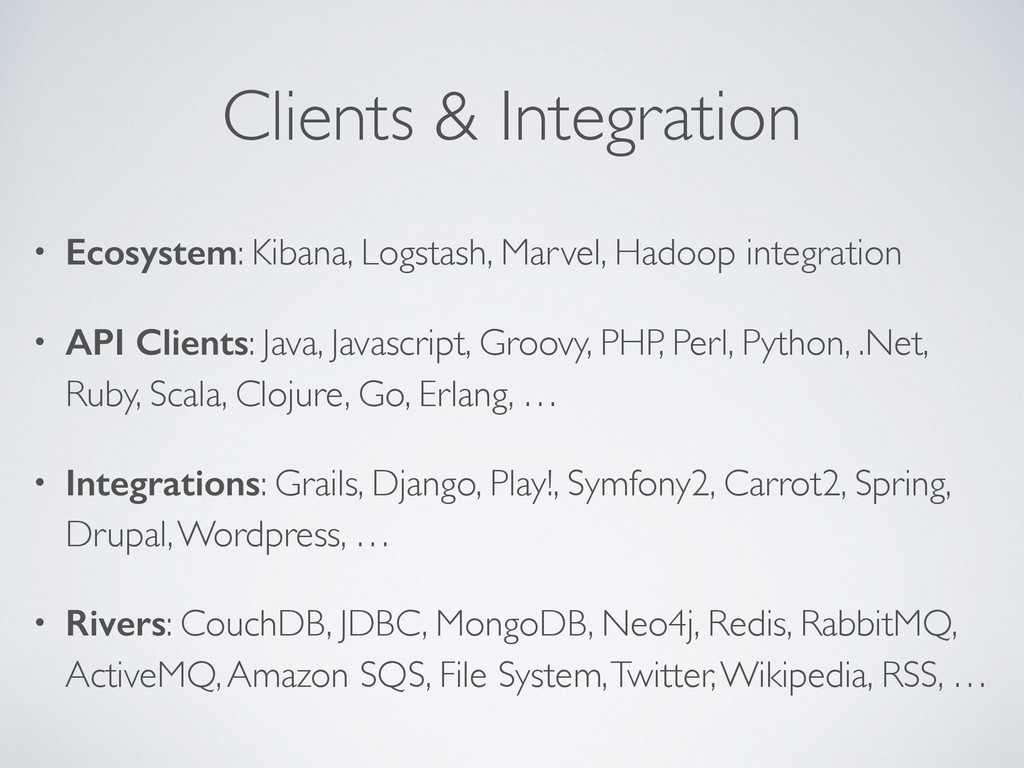
Clients & Integration • Ecosystem: Kibana, Logstash, Marvel, Hadoop integration
• API Clients: Java, Javascript, Groovy, PHP, Perl, Python, .Net, Ruby, Scala, Clojure, Go, Erlang, … • Integrations: Grails, Django, Play!, Symfony2, Carrot2, Spring, Drupal, Wordpress, … • Rivers: CouchDB, JDBC, MongoDB, Neo4j, Redis, RabbitMQ, ActiveMQ, Amazon SQS, File System, Twitter, Wikipedia, RSS, … -
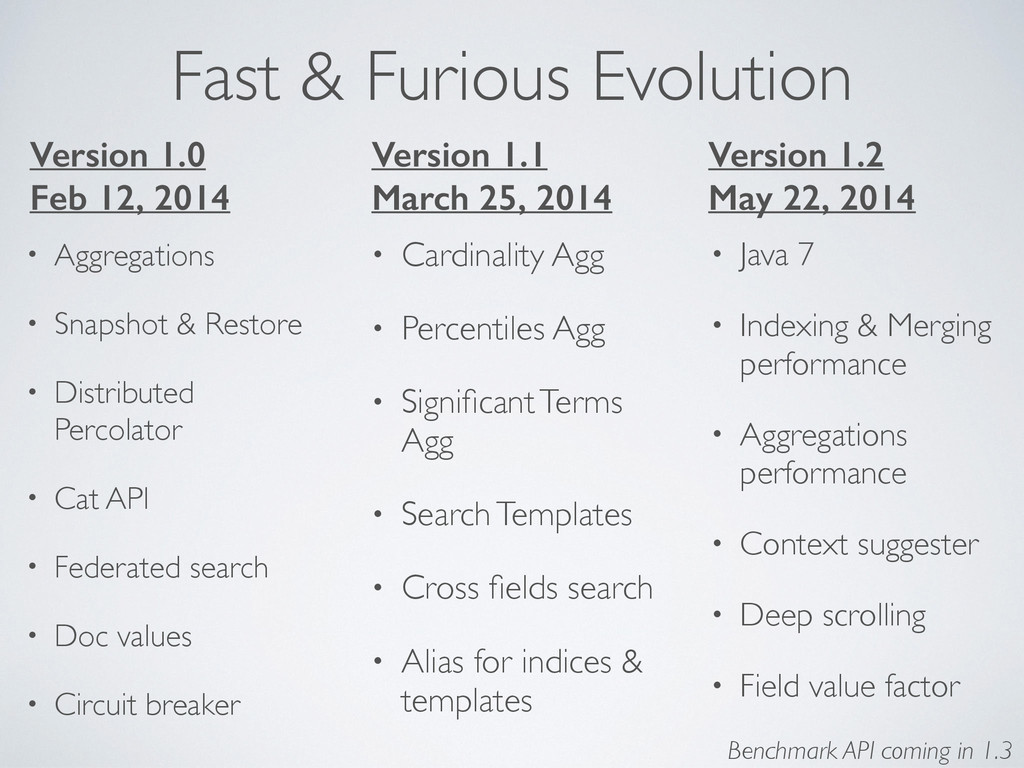
Fast & Furious Evolution Version 1.1 March 25, 2014 •
Cardinality Agg • Percentiles Agg • Significant Terms Agg • Search Templates • Cross fields search • Alias for indices & templates Version 1.2 May 22, 2014 • Java 7 • Indexing & Merging performance • Aggregations performance • Context suggester • Deep scrolling • Field value factor Benchmark API coming in 1.3 Version 1.0 Feb 12, 2014 • Aggregations • Snapshot & Restore • Distributed Percolator • Cat API • Federated search • Doc values • Circuit breaker -
Resources • http://www.elasticsearch.org/guide/ • http://www.elasticsearch.org/videos/ • http://www.elasticsearchtutorial.com/ • http://exploringelasticsearch.com/ •
http://joelabrahamsson.com/elasticsearch-101/ • http://belczyk.com/2014/01/elasticsearch-recomended-learning-materials/ • http://www.elasticsearch.org/guide/en/elasticsearch/reference/1.x/modules- plugins.html -
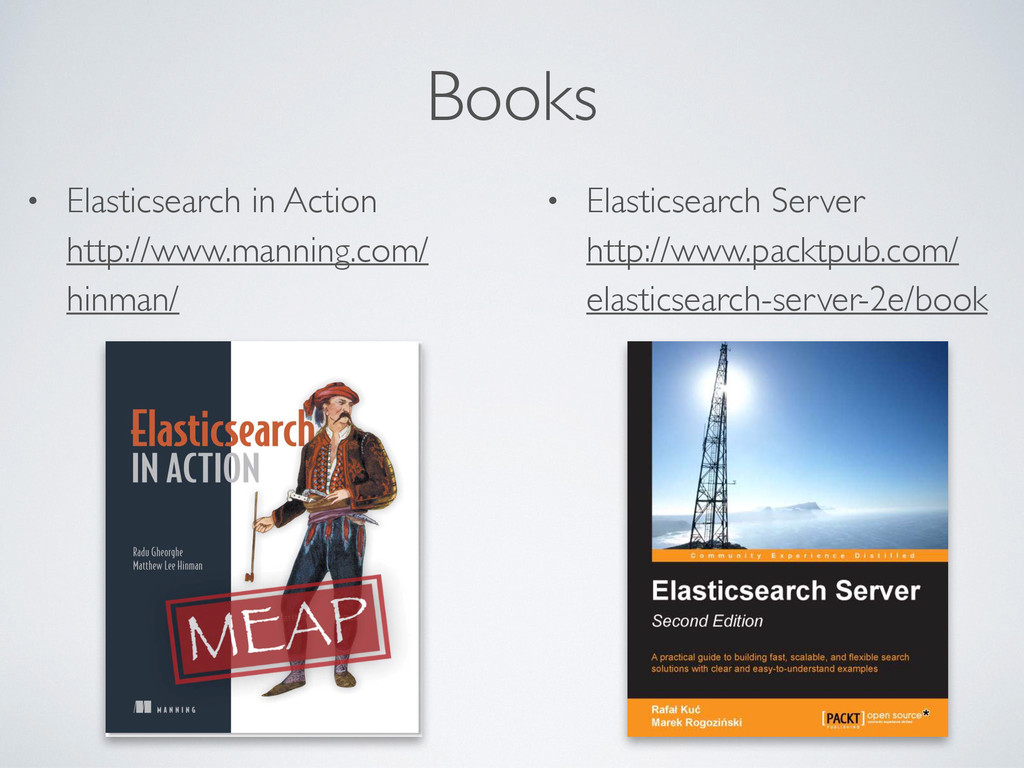
Books • Elasticsearch Server http://www.packtpub.com/ elasticsearch-server-2e/book • Elasticsearch in Action
http://www.manning.com/ hinman/ -
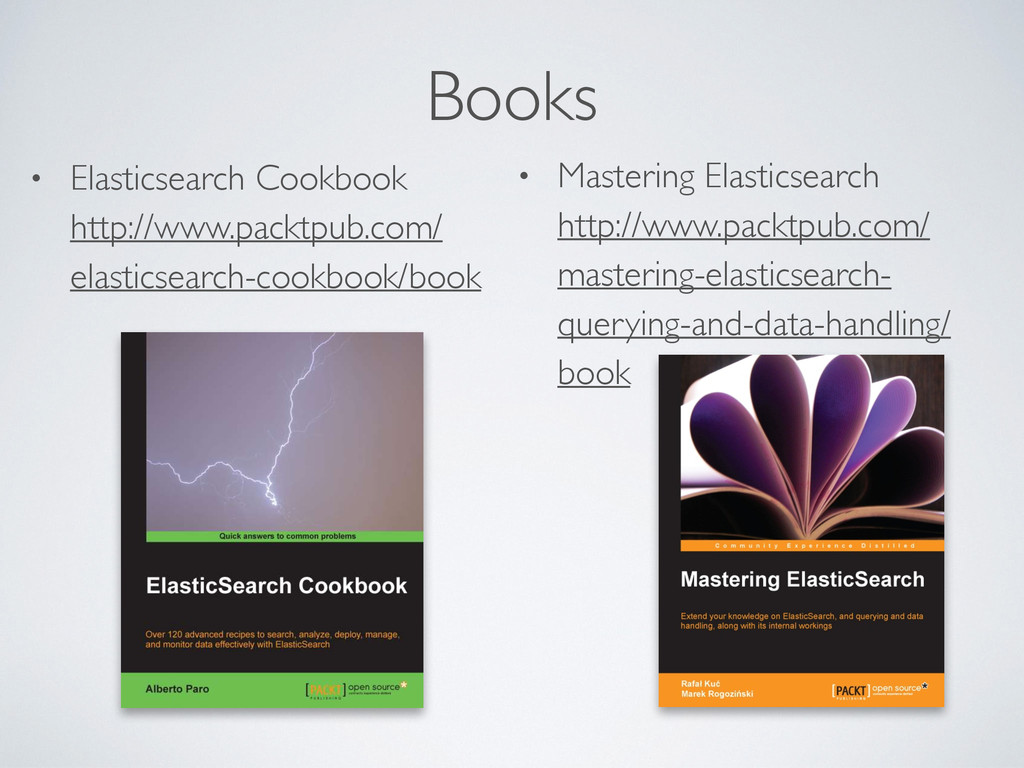
Books • Elasticsearch Cookbook http://www.packtpub.com/ elasticsearch-cookbook/book • Mastering Elasticsearch http://www.packtpub.com/
mastering-elasticsearch- querying-and-data-handling/ book