Upgrade to Pro — share decks privately, control downloads, hide ads and more …

CV勉強会_Post-Training-Survey_ExploreVLA

welldone
October 24, 2026
140

 CV勉強会_Post-Training-Survey_ExploreVLA

welldone

October 24, 2026

Transcript

18 slides
  1. ECCV 2026 読み会 Post Training Survey & ExploreVLA 1. Post-Training

    in End-to-End Autonomous Driving: Taxonomy, Methods, and Challenges 2. ExploreVLA: Dense World Modeling and Exploration for End-to-End Autonomous Driving 2026/10/25 welldone 1
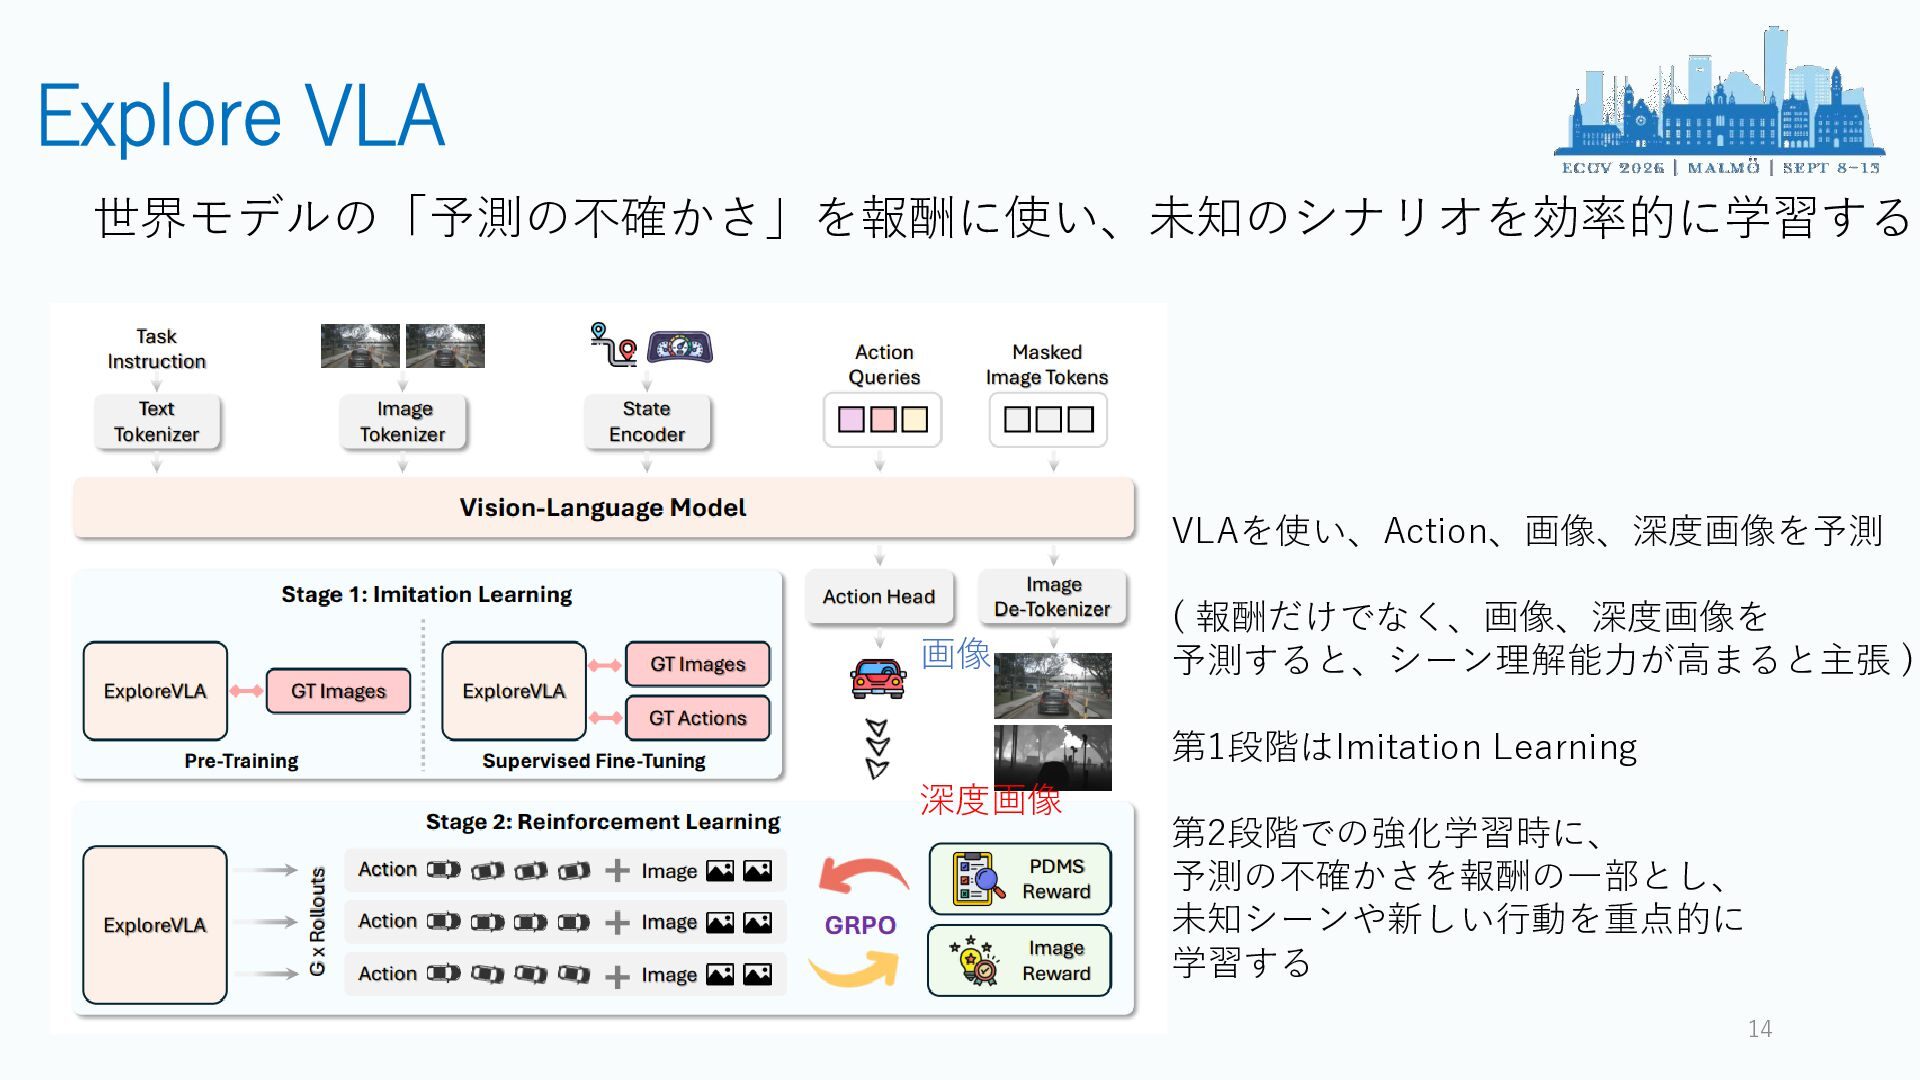
  2. 目的 最新の強化学習の潮流を25分で、広く、深く 勉強したい 紹介する論文 : 1. Post-Training in End-to-End Autonomous

    Driving: Taxonomy, Methods, and Challenges ・強化学習を含む、模倣学習後の後学習を網羅的にサーベイ ・Workshop Drive XのBest Paper 2. ExploreVLA: Dense World Modeling and Exploration for End-to-End Autonomous Driving ・Bosch Researchから提案された世界モデルを活用した強化学習 ・クローズドループでなく、シナリオの新規性を表現するのに世界モデルを活用 2
  3. 1. Post-Training in End-to-End Autonomous Driving: Taxonomy, Methods, and Challenges

    Yang, Ruining, et al. "Post-Training in End-to-End Autonomous Driving: Taxonomy, Methods, and Challenges." [Archival Track] ECCV 2026 DriveX-6th Workshop on Foundation Models for Autonomous Driving. 3
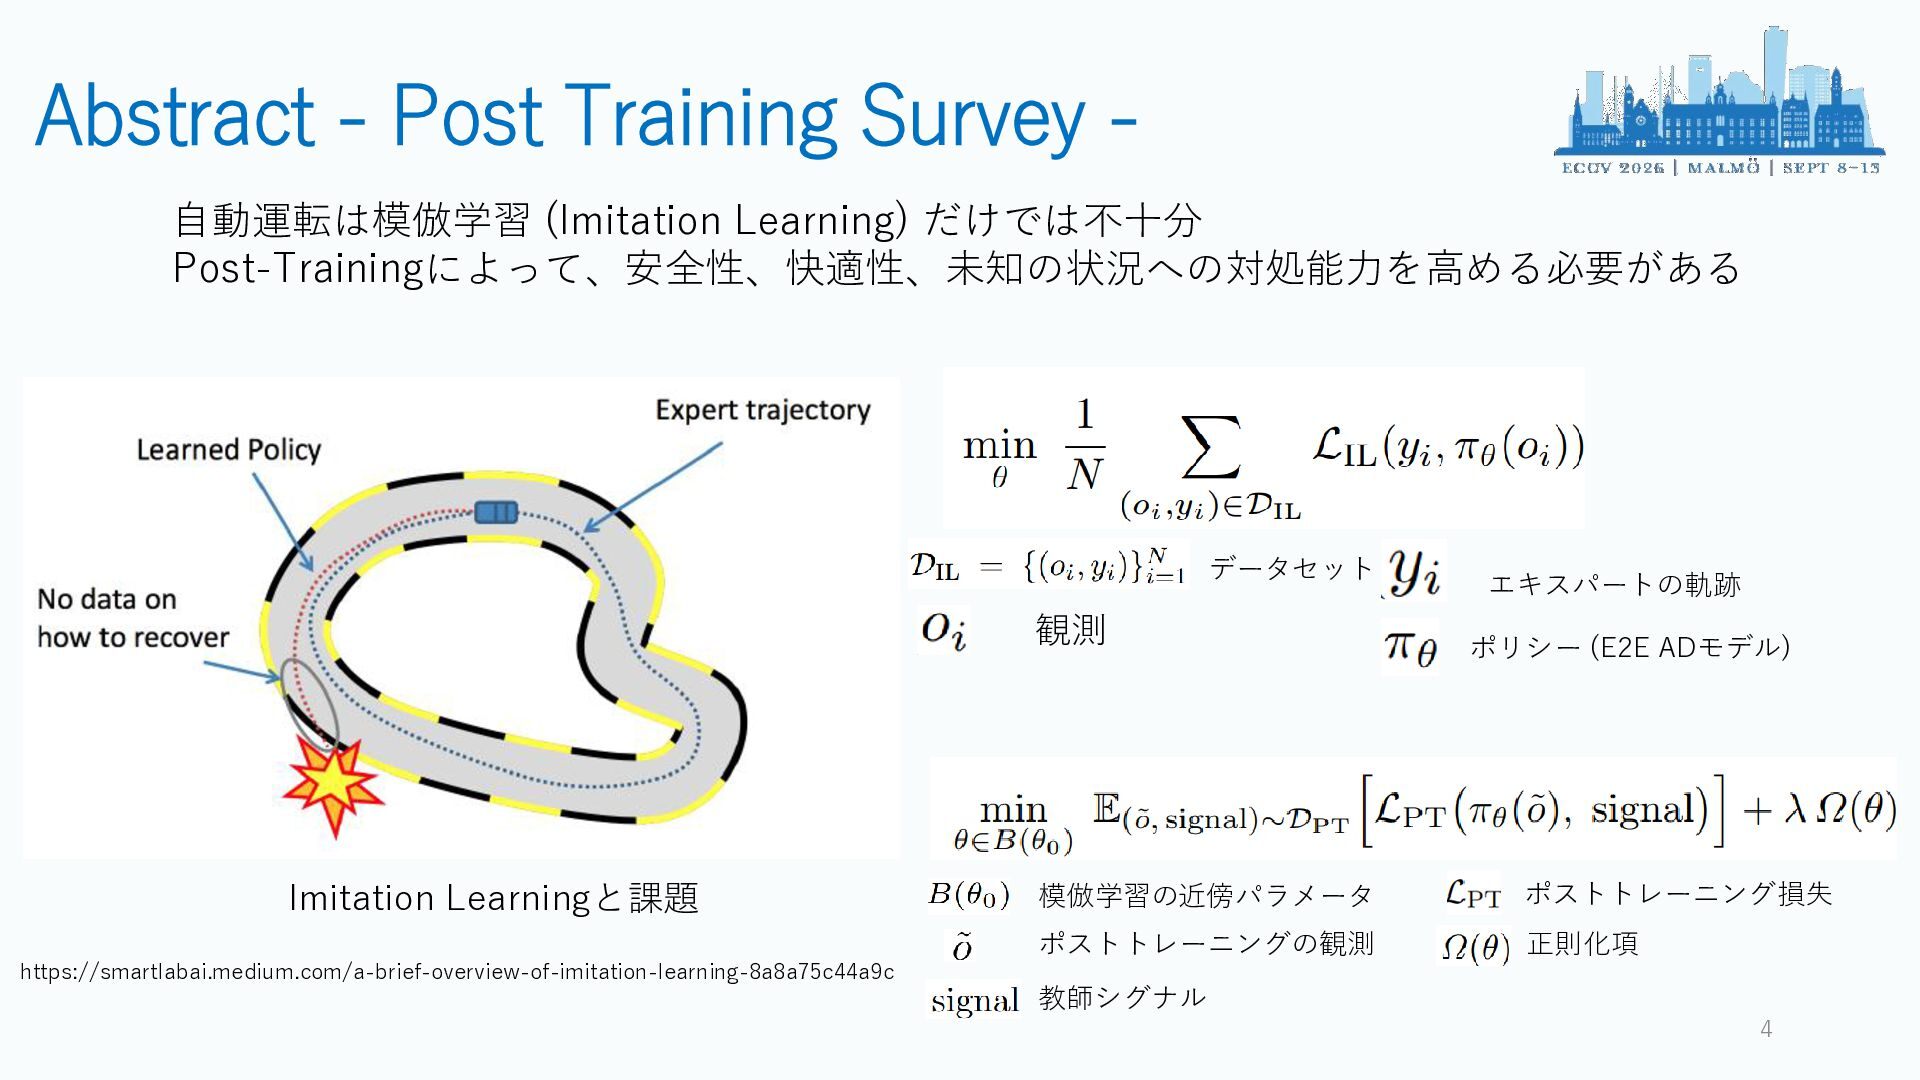
  4. Abstract - Post Training Survey 自動運転は模倣学習 (Imitation Learning) だけでは不十分 Post-Trainingによって、安全性、快適性、未知の状況への対処能力を高める必要がある

    データセット 観測 Imitation Learningと課題 エキスパートの軌跡 ポリシー (E2E ADモデル) 模倣学習の近傍パラメータ ポストトレーニング損失 ポストトレーニングの観測 正則化項 https://smartlabai.medium.com/a-brief-overview-of-imitation-learning-8a8a75c44a9c 教師シグナル 4
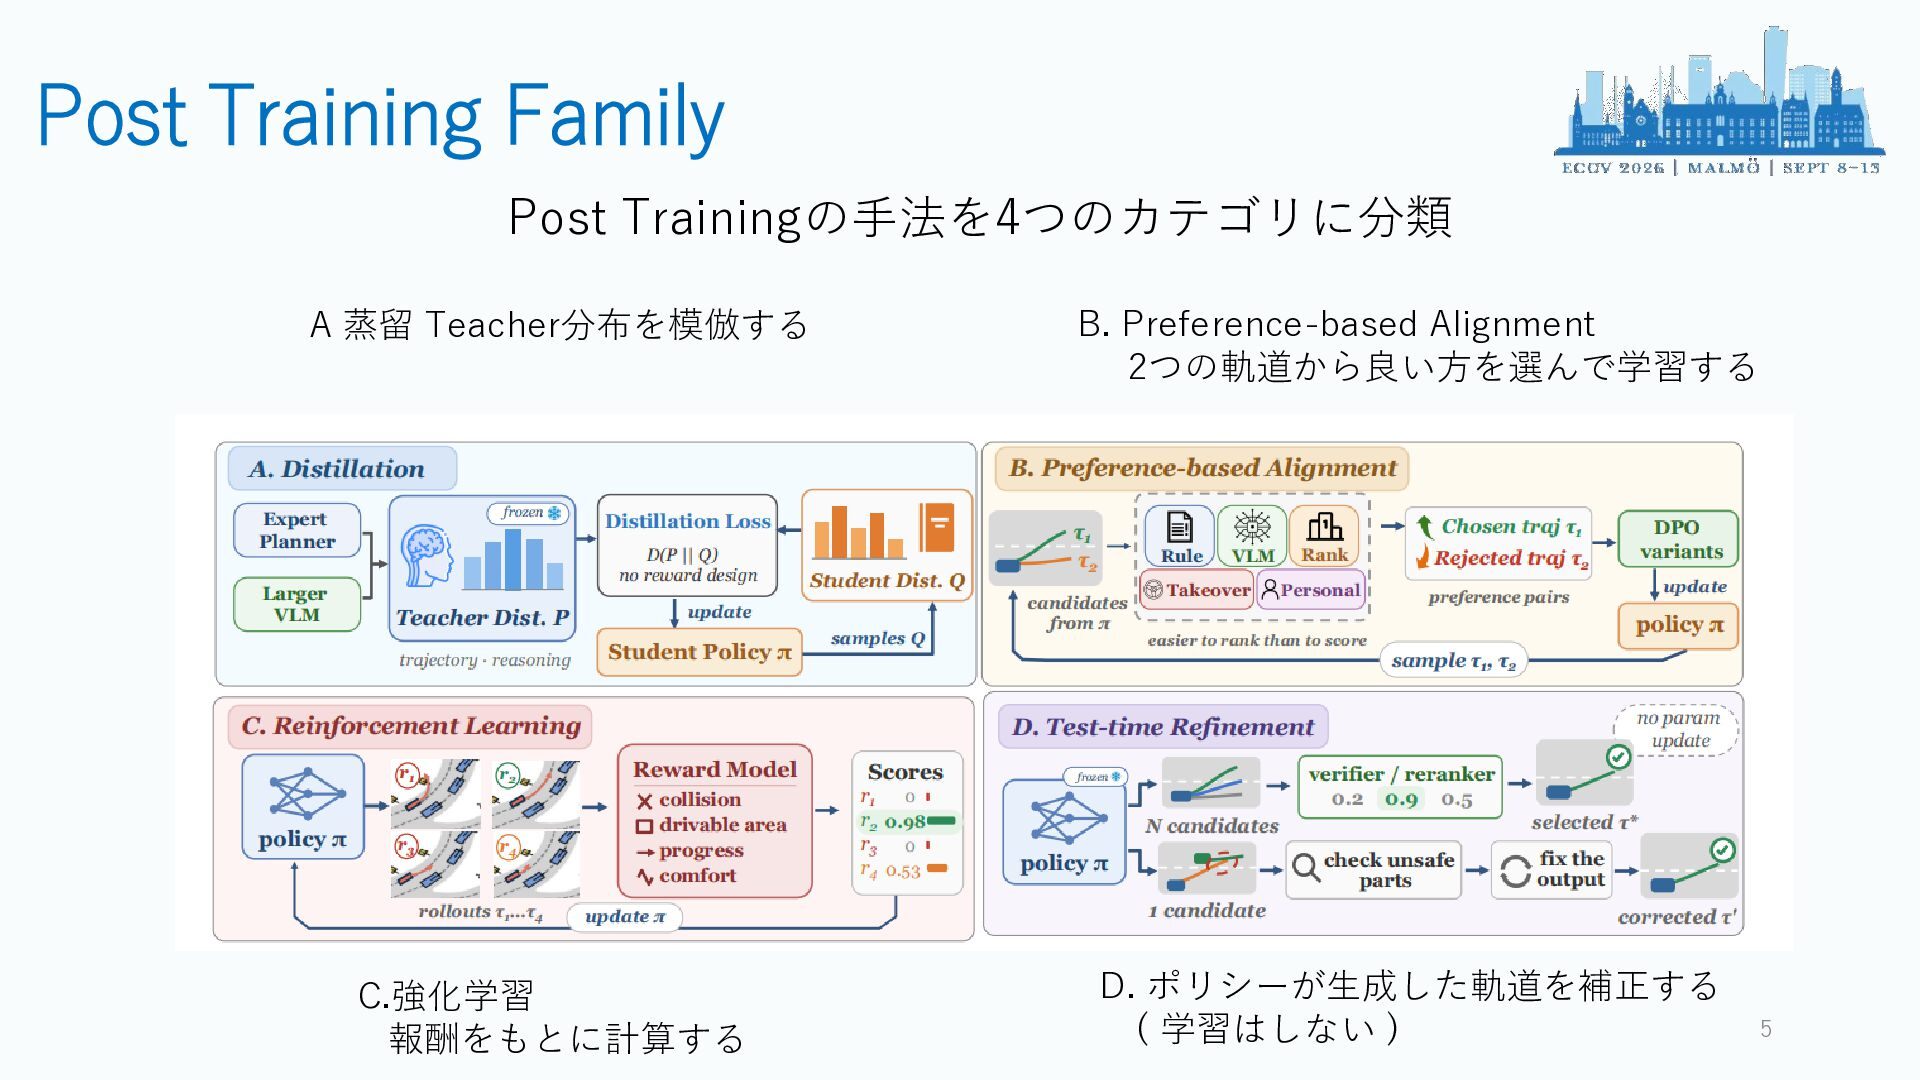
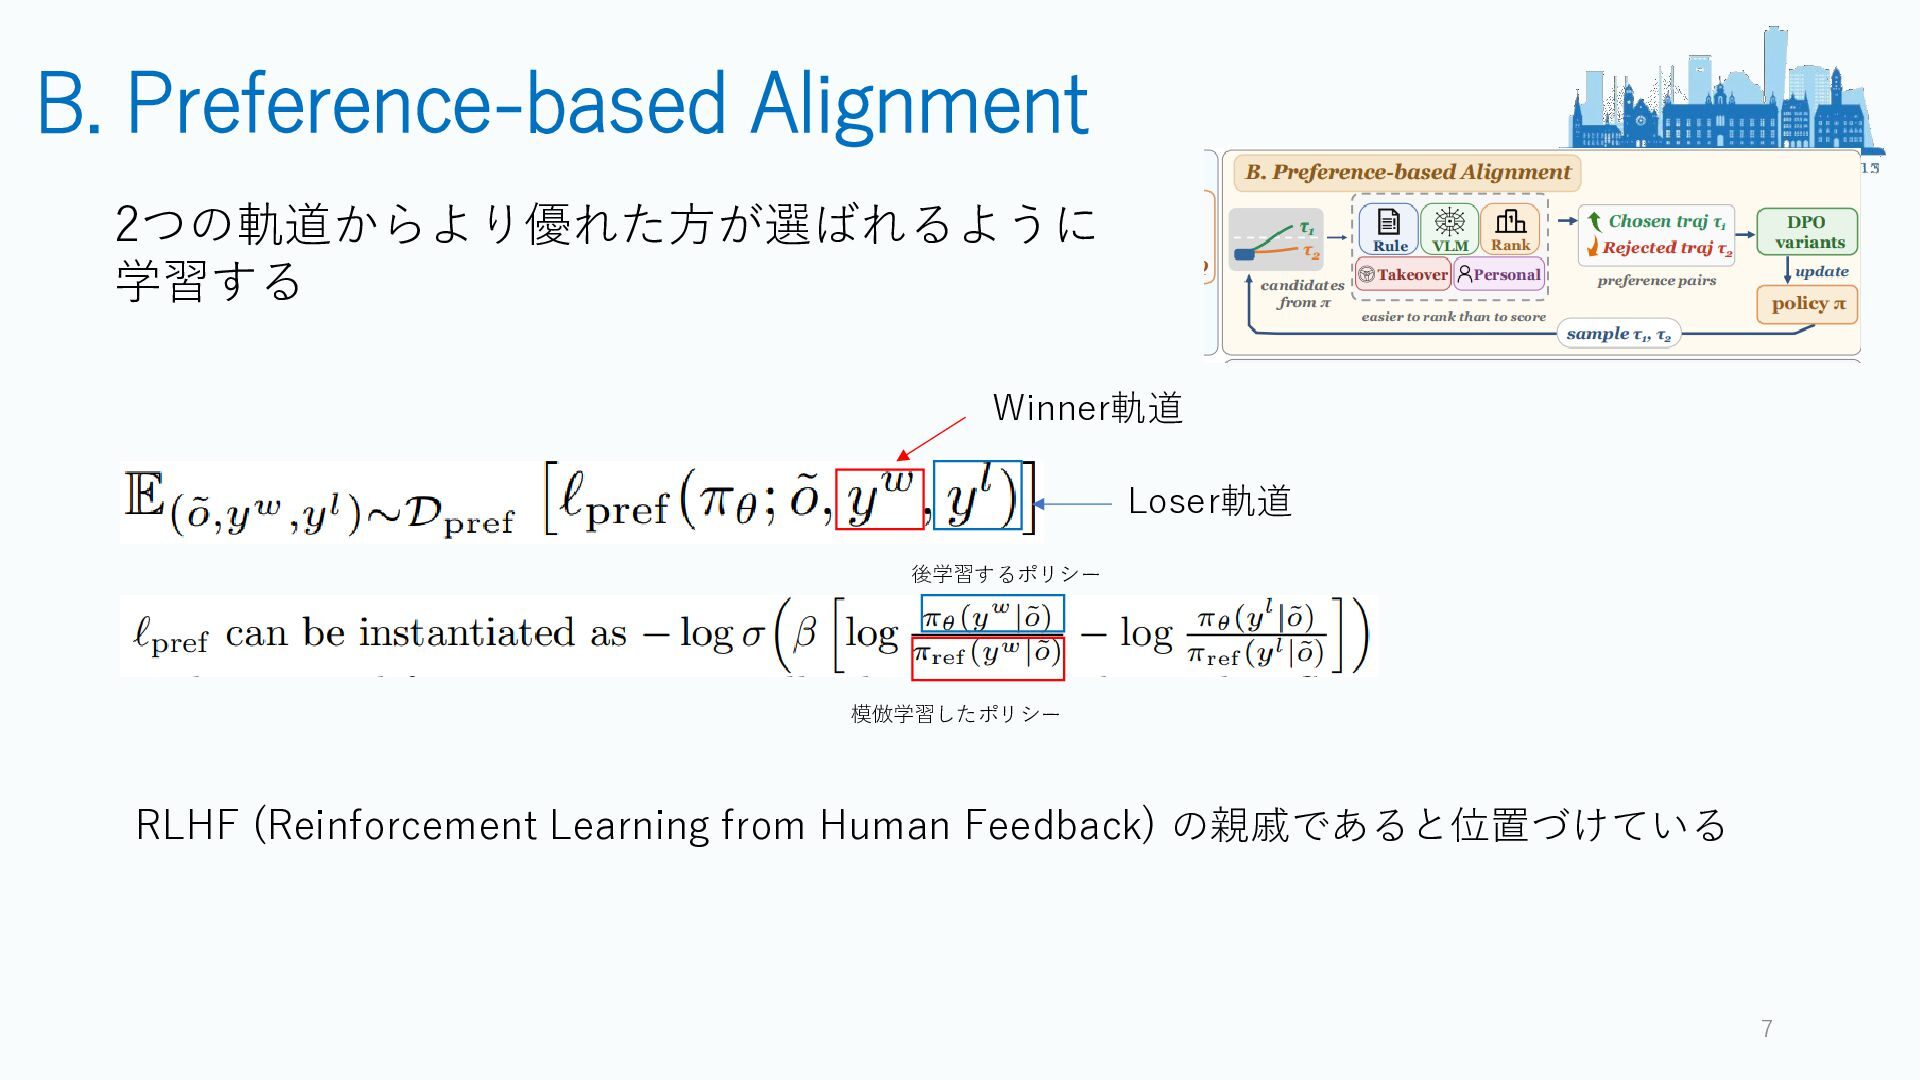
  5. Post Training Family Post Trainingの手法を4つのカテゴリに分類 A 蒸留 Teacher分布を模倣する B. Preference-based

    Alignment 2つの軌道から良い方を選んで学習する C.強化学習 報酬をもとに計算する D. ポリシーが生成した軌道を補正する ( 学習はしない ) 5
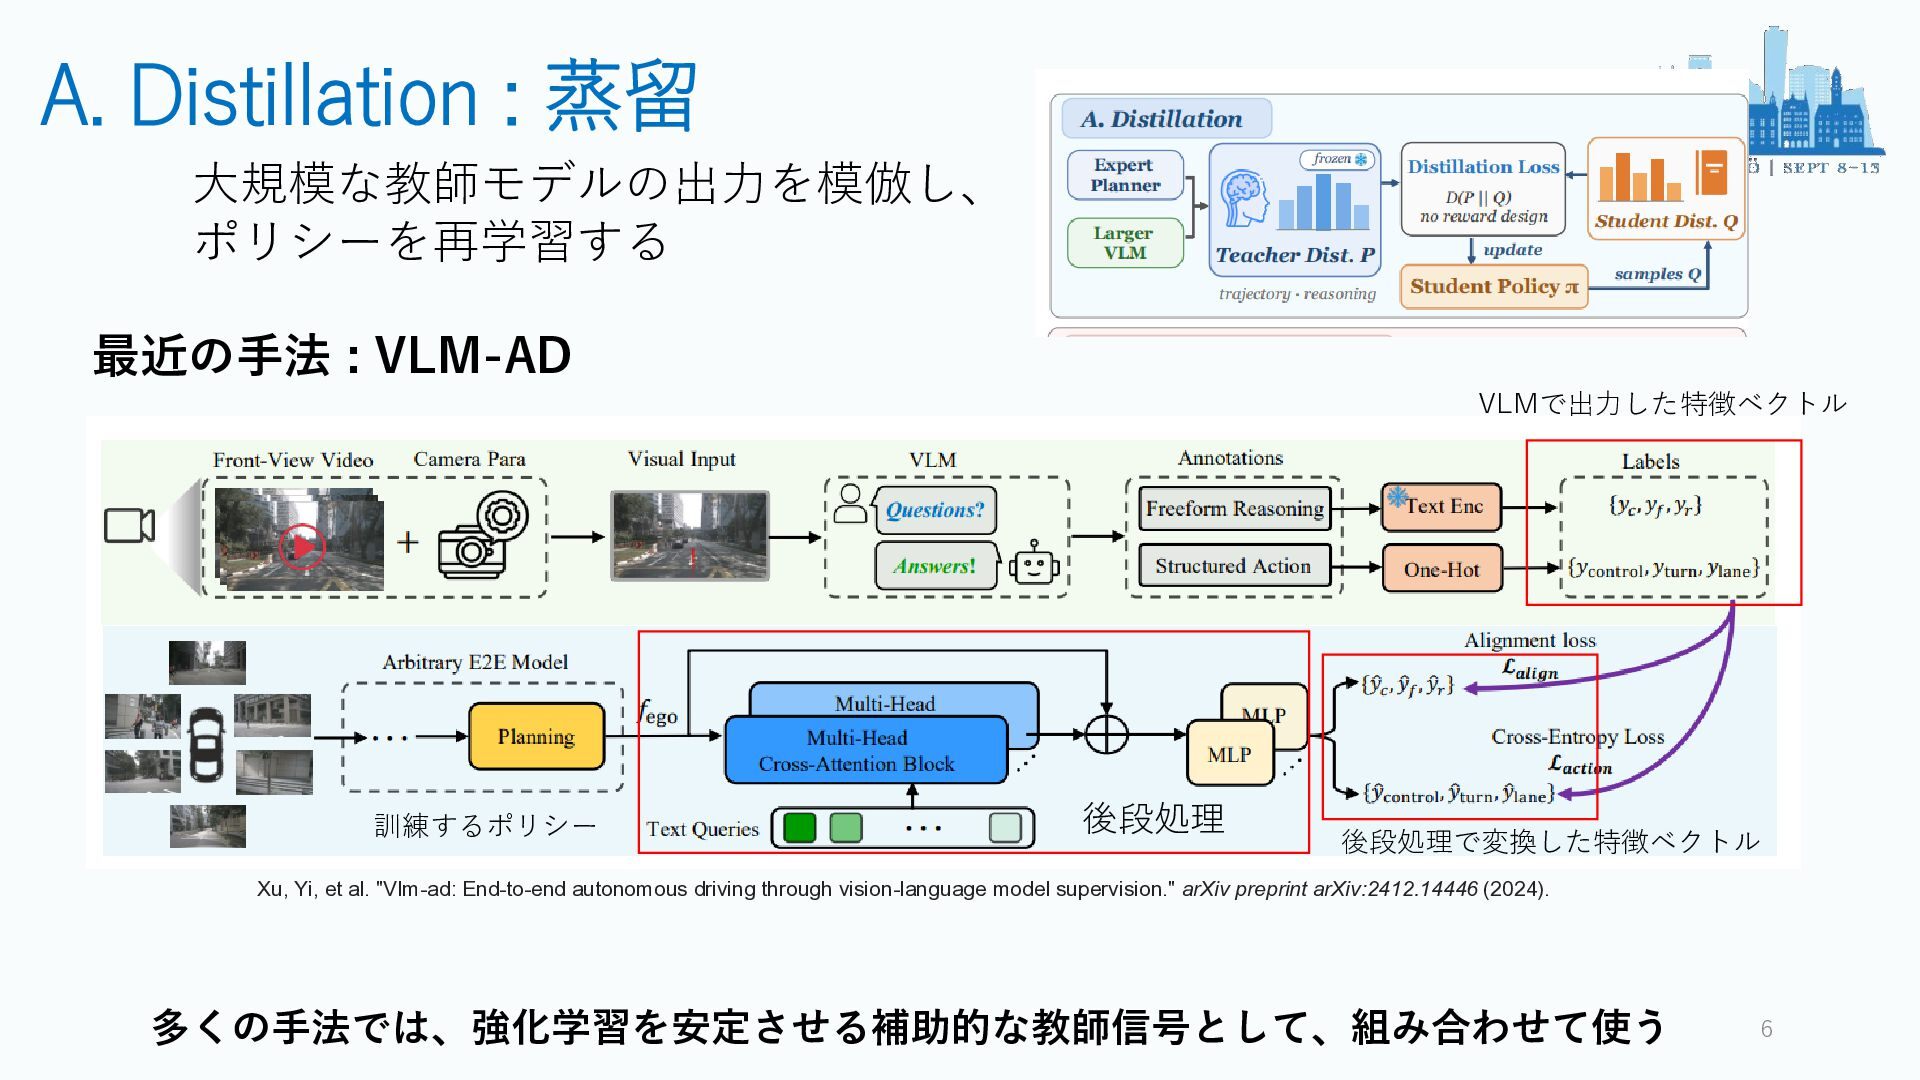
  6. A. Distillation : 蒸留 大規模な教師モデルの出力を模倣し、 ポリシーを再学習する 最近の手法 : VLM-AD VLMで出力した特徴ベクトル

    訓練するポリシー 後段処理 後段処理で変換した特徴ベクトル Xu, Yi, et al. "Vlm-ad: End-to-end autonomous driving through vision-language model supervision." arXiv preprint arXiv:2412.14446 (2024). 多くの手法では、強化学習を安定させる補助的な教師信号として、組み合わせて使う 6
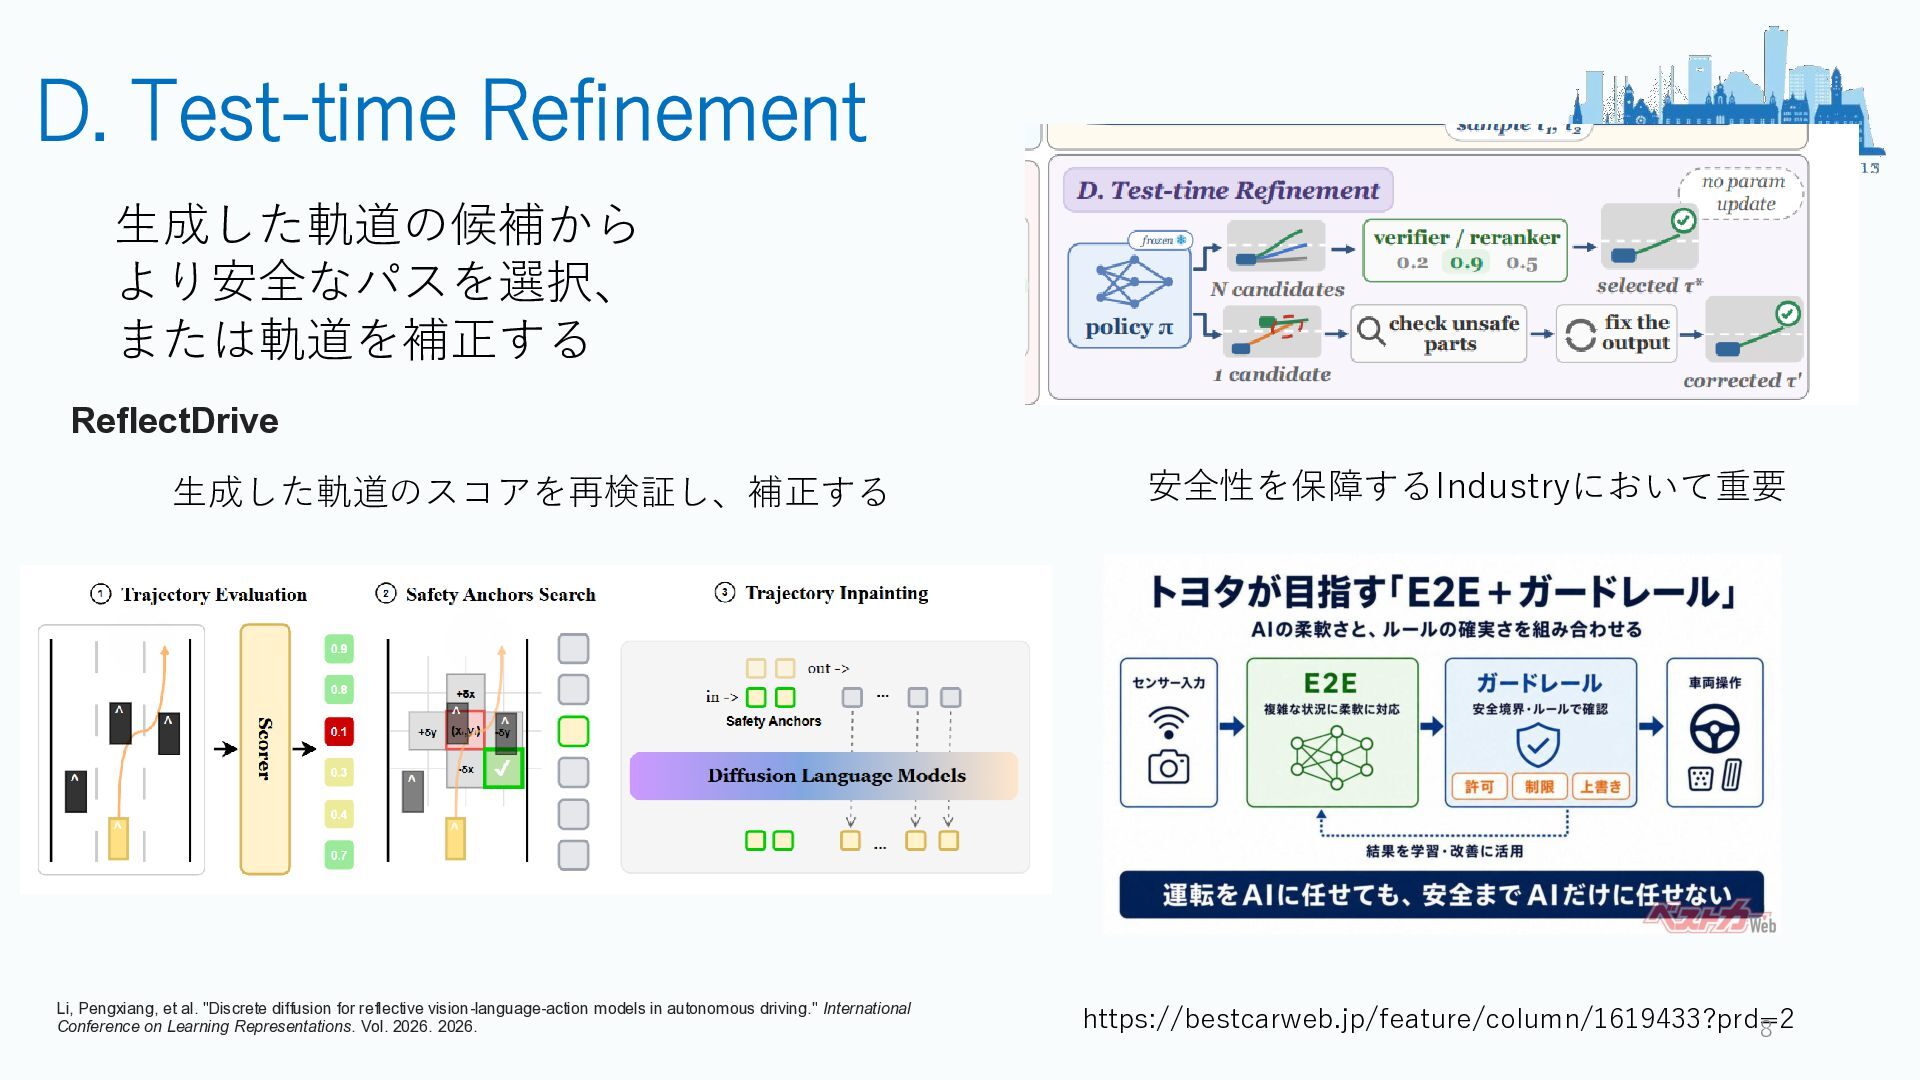
  7. D. Test-time Refinement 生成した軌道の候補から より安全なパスを選択、 または軌道を補正する ReflectDrive 生成した軌道のスコアを再検証し、補正する Li, Pengxiang,

    et al. "Discrete diffusion for reflective vision-language-action models in autonomous driving." International Conference on Learning Representations. Vol. 2026. 2026. 安全性を保障するIndustryにおいて重要 https://bestcarweb.jp/feature/column/1619433?prd=2 8
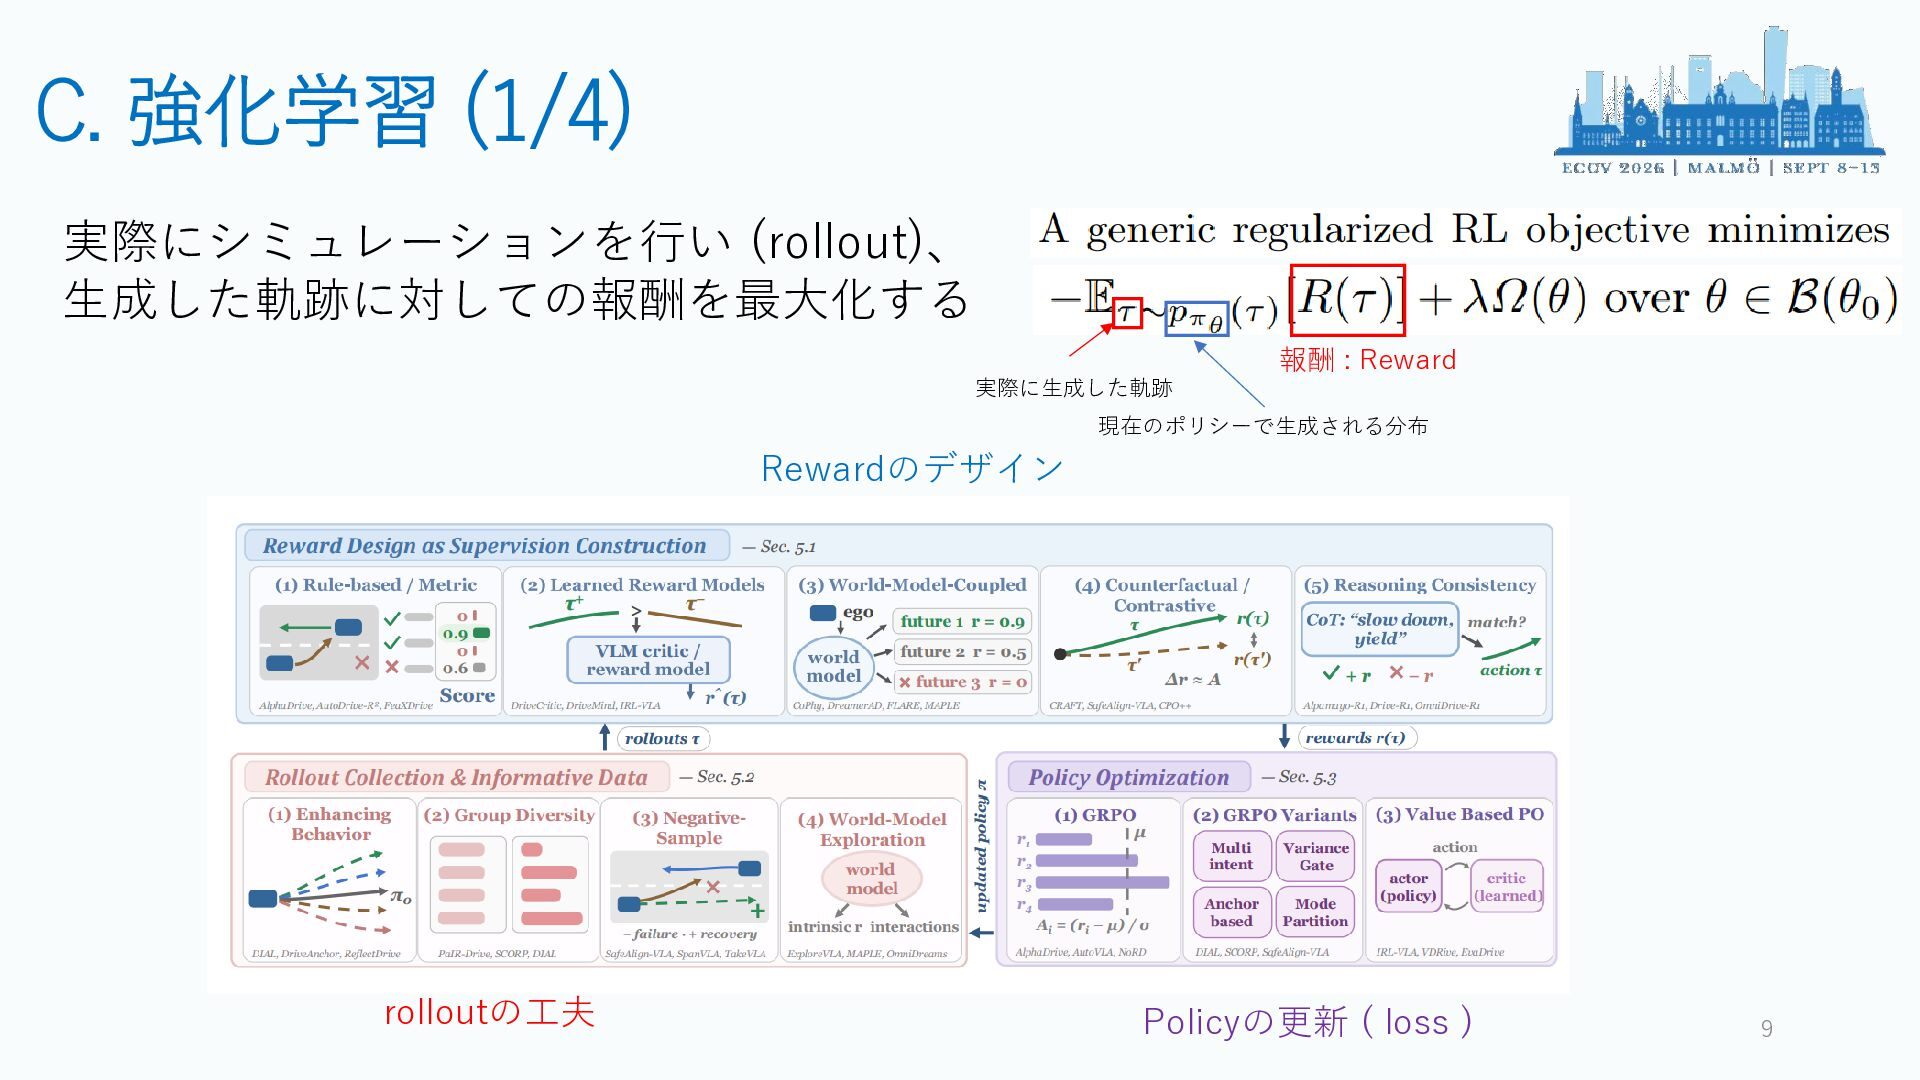
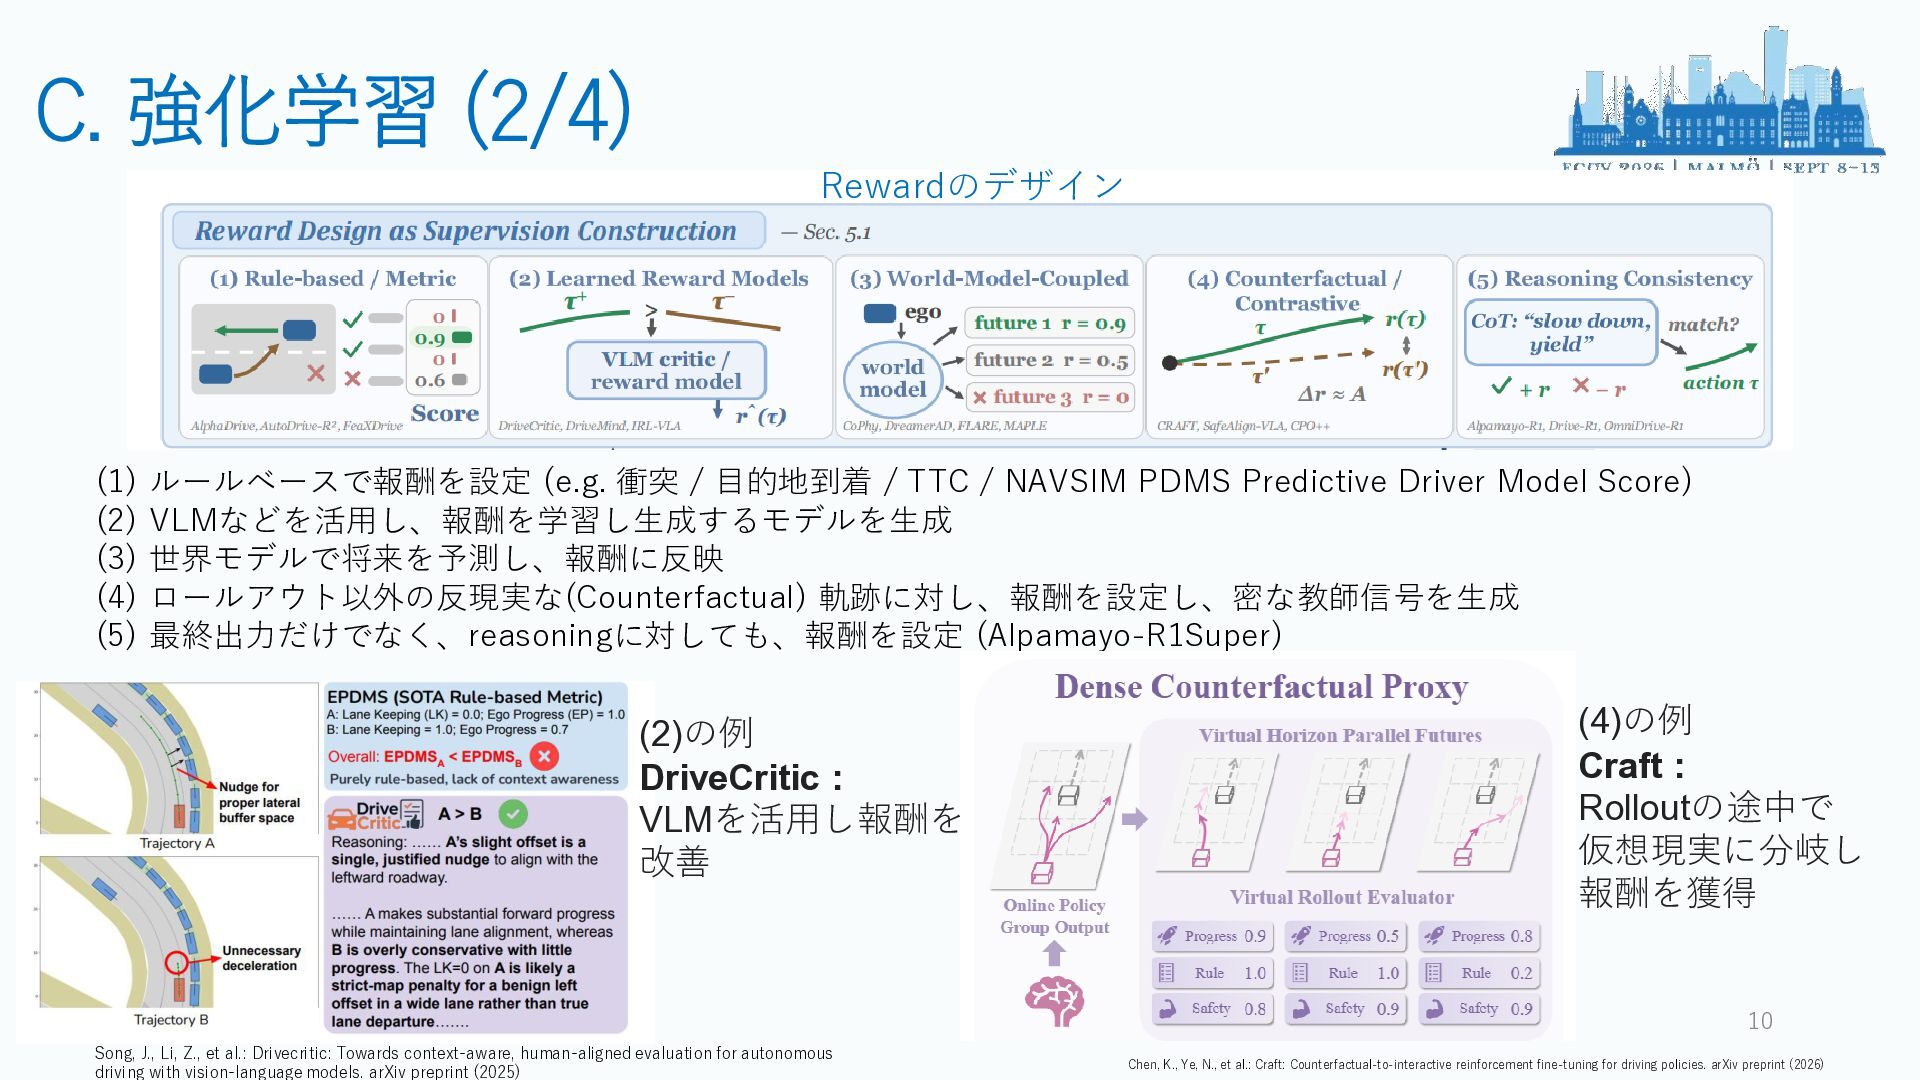
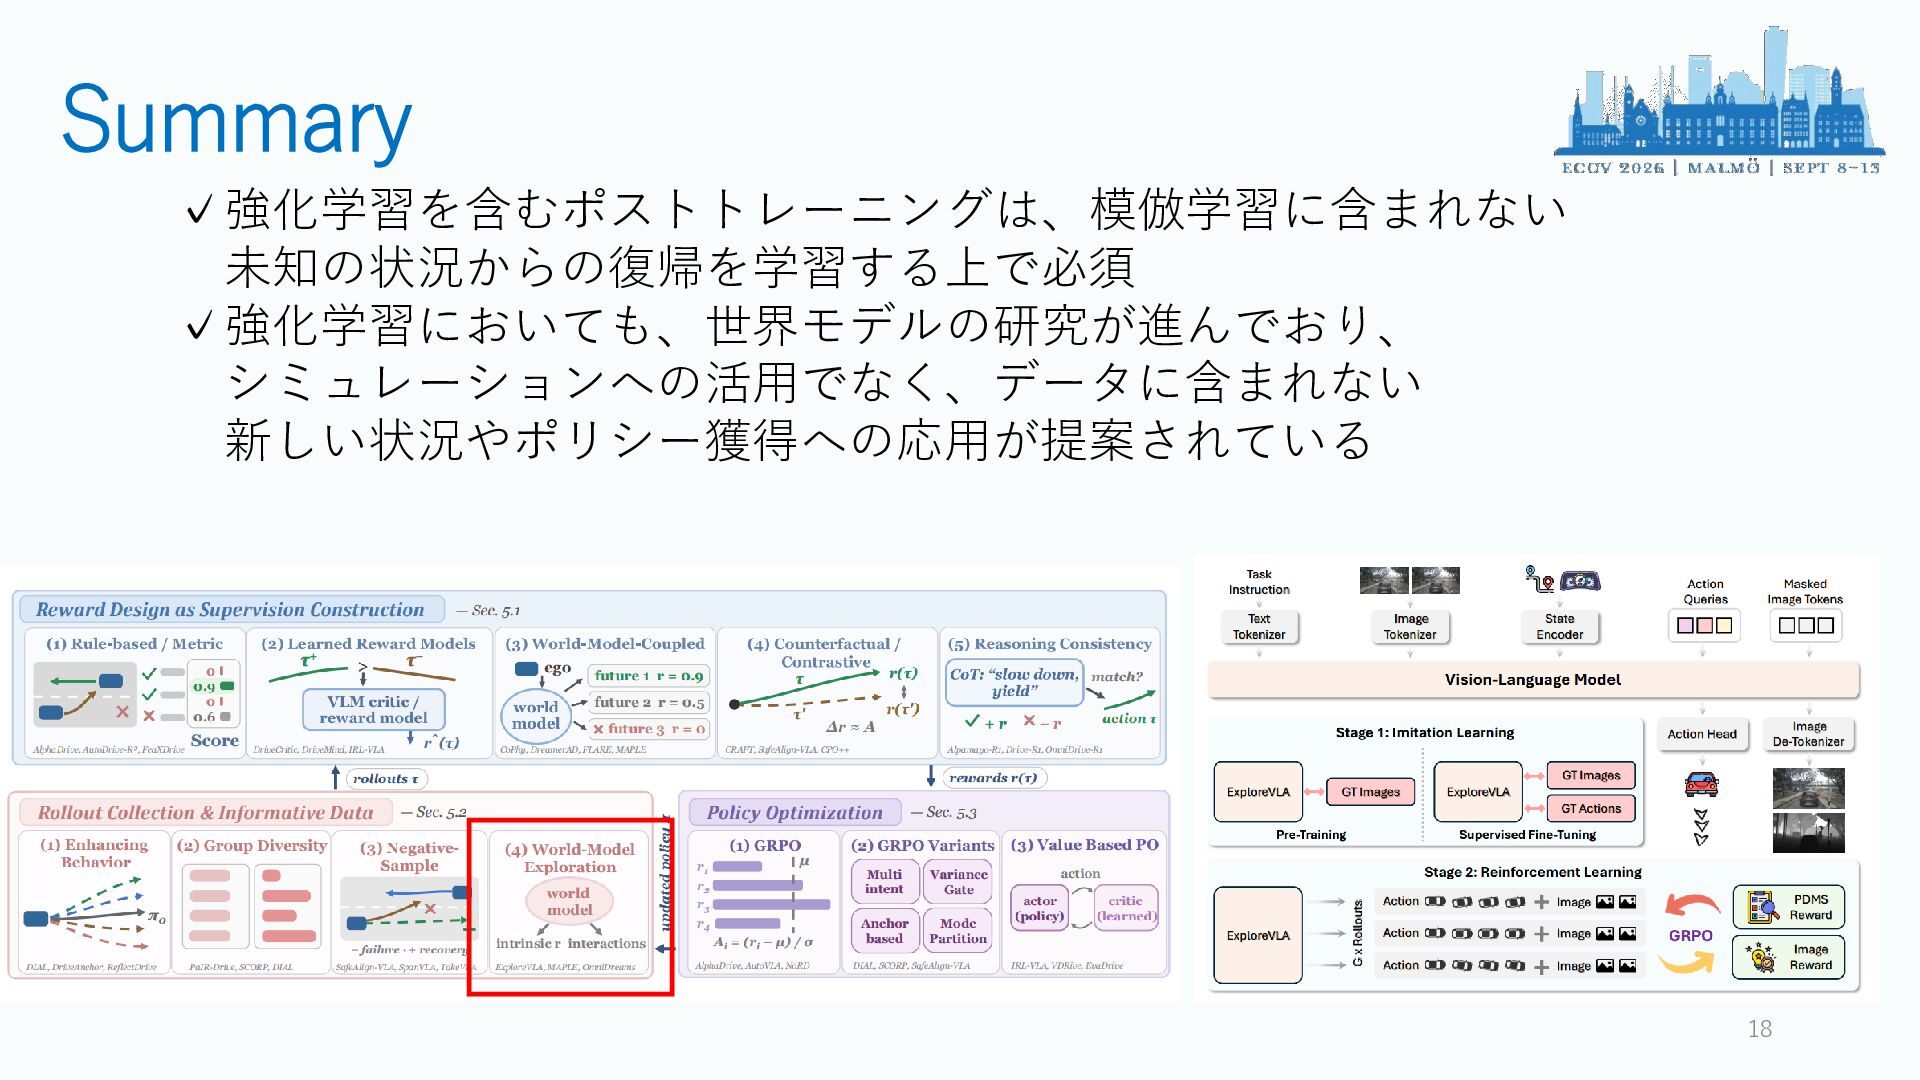
  8. C. 強化学習 (2/4) Rewardのデザイン (1) ルールベースで報酬を設定 (e.g. 衝突 / 目的地到着

    / TTC / NAVSIM PDMS Predictive Driver Model Score) (2) VLMなどを活用し、報酬を学習し生成するモデルを生成 (3) 世界モデルで将来を予測し、報酬に反映 (4) ロールアウト以外の反現実な(Counterfactual) 軌跡に対し、報酬を設定し、密な教師信号を生成 (5) 最終出力だけでなく、reasoningに対しても、報酬を設定 (Alpamayo-R1Super) (2)の例 DriveCritic : VLMを活用し報酬を 改善 (4)の例 Craft : Rolloutの途中で 仮想現実に分岐し 報酬を獲得 10 Song, J., Li, Z., et al.: Drivecritic: Towards context-aware, human-aligned evaluation for autonomous driving with vision-language models. arXiv preprint (2025) Chen, K., Ye, N., et al.: Craft: Counterfactual-to-interactive reinforcement fine-tuning for driving policies. arXiv preprint (2026)
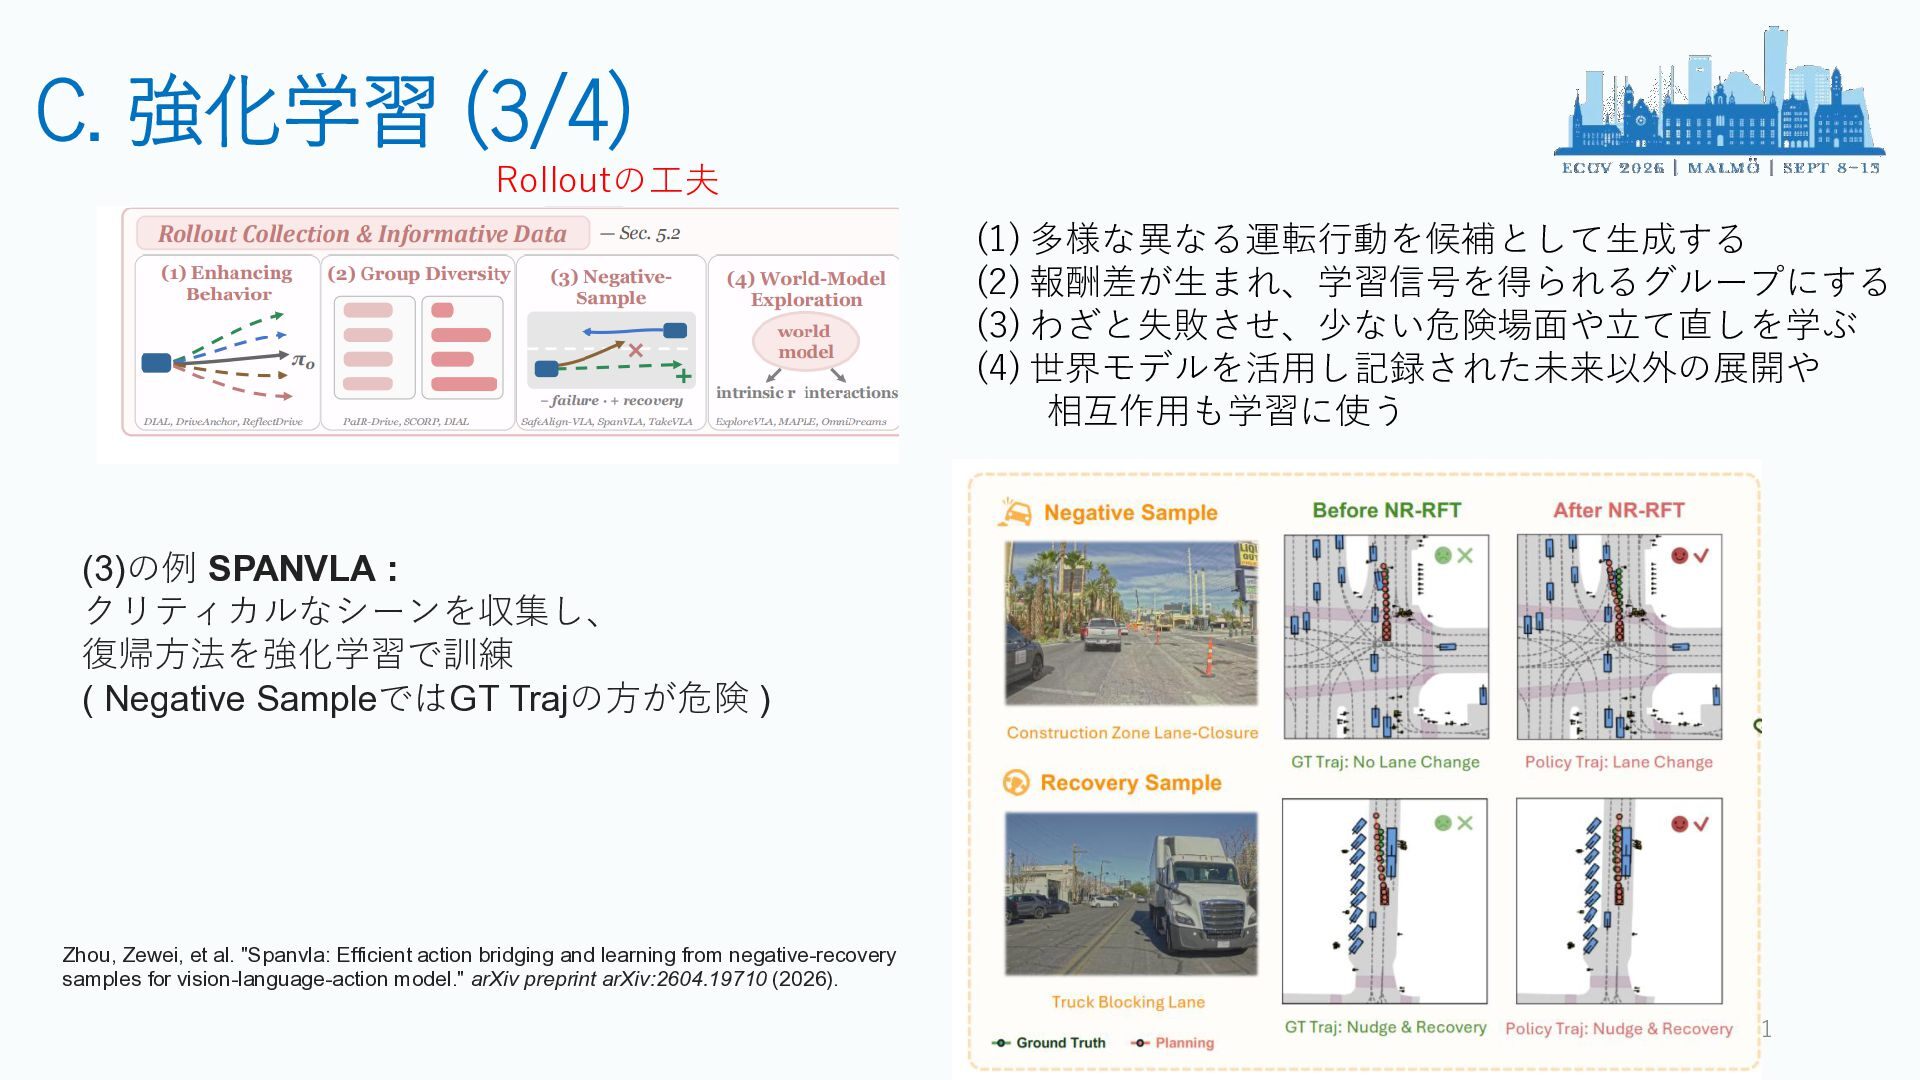
  9. C. 強化学習 (3/4) Rolloutの工夫 (1) 多様な異なる運転行動を候補として生成する (2) 報酬差が生まれ、学習信号を得られるグループにする (3) わざと失敗させ、少ない危険場面や立て直しを学ぶ

    (4) 世界モデルを活用し記録された未来以外の展開や 相互作用も学習に使う (3)の例 SPANVLA : クリティカルなシーンを収集し、 復帰方法を強化学習で訓練 ( Negative SampleではGT Trajの方が危険 ) Zhou, Zewei, et al. "Spanvla: Efficient action bridging and learning from negative-recovery samples for vision-language-action model." arXiv preprint arXiv:2604.19710 (2026). 11
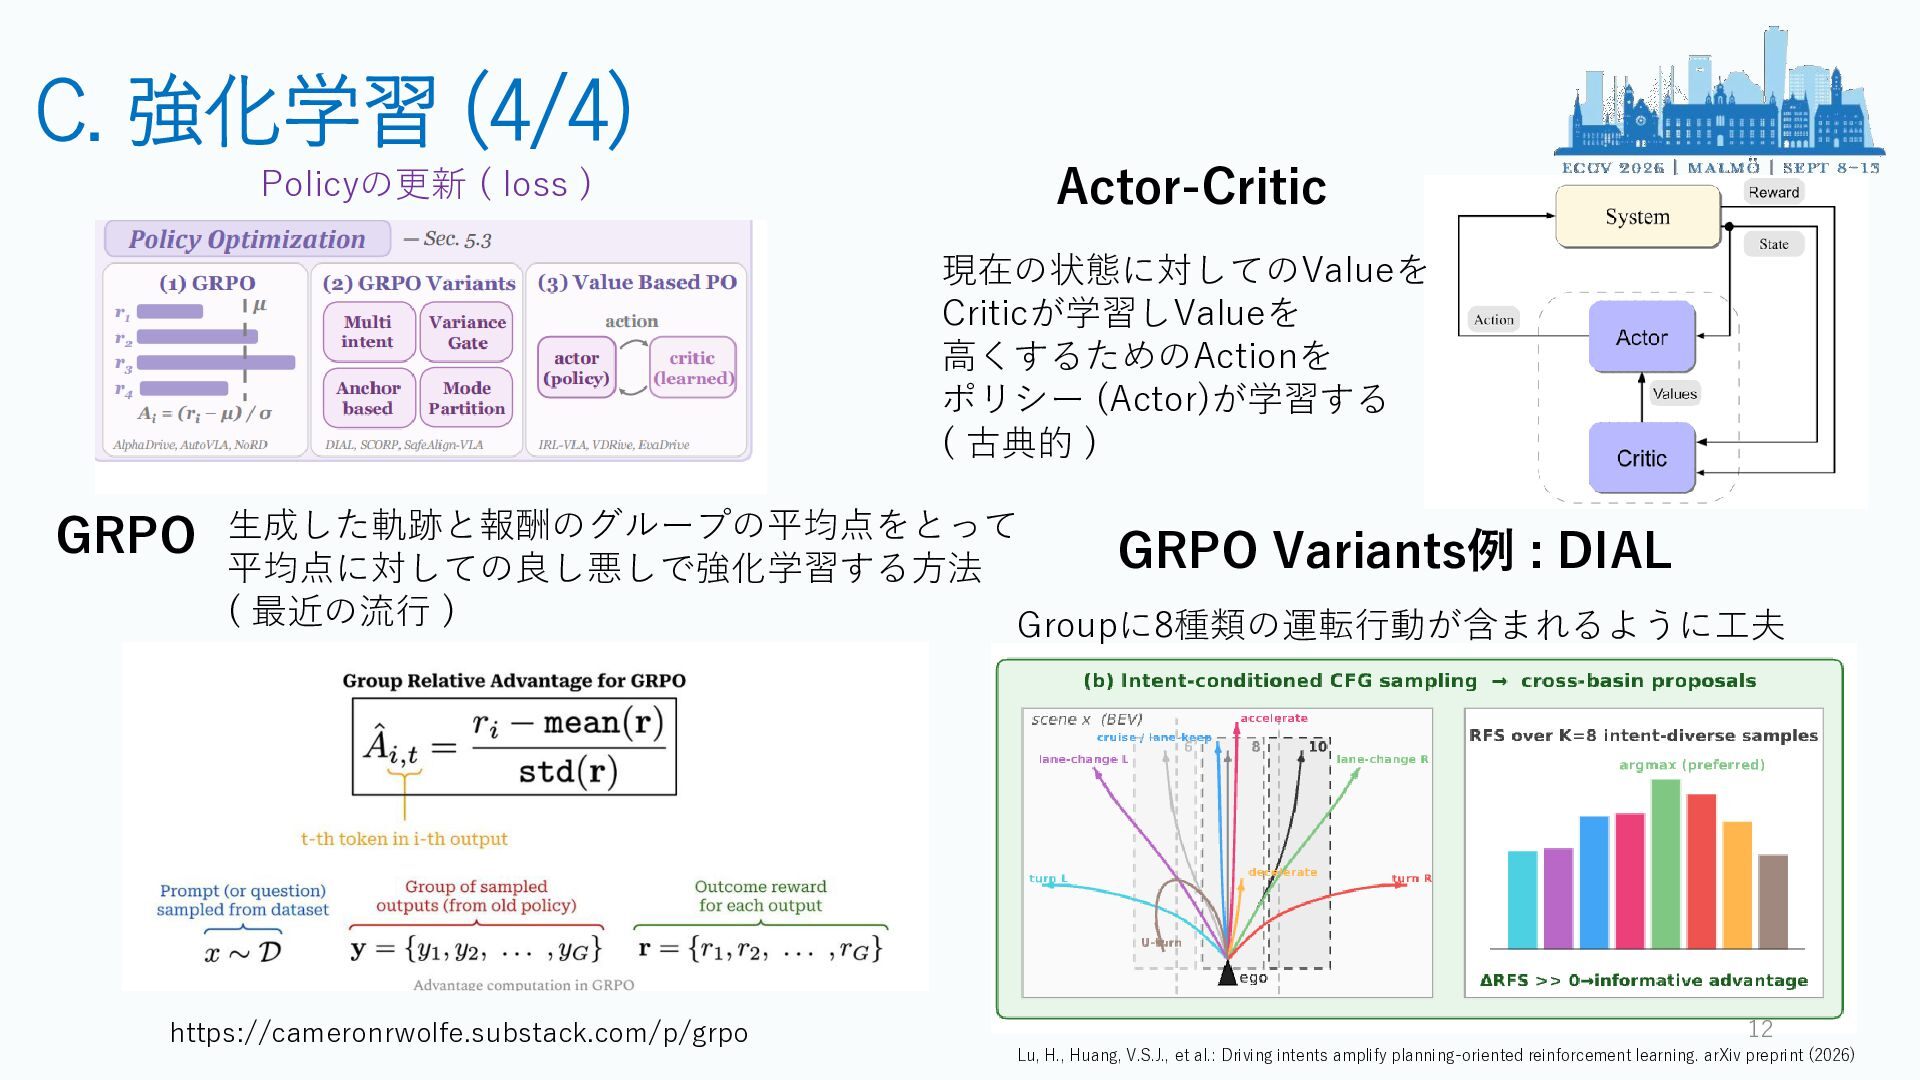
  10. C. 強化学習 (4/4) Actor-Critic Policyの更新 ( loss ) 現在の状態に対してのValueを Criticが学習しValueを

    高くするためのActionを ポリシー (Actor)が学習する ( 古典的 ) GRPO 生成した軌跡と報酬のグループの平均点をとって GRPO Variants例 : DIAL 平均点に対しての良し悪しで強化学習する方法 ( 最近の流行 ) Groupに8種類の運転行動が含まれるように工夫 https://cameronrwolfe.substack.com/p/grpo 12 Lu, H., Huang, V.S.J., et al.: Driving intents amplify planning-oriented reinforcement learning. arXiv preprint (2026)
  11. 2. ExploreVLA: Dense World Modeling and Exploration for End-to-End Autonomous

    Driving Sheng, Zihao, et al. "Explorevla: Dense world modeling and exploration for end-to-end autonomous driving." European Conference on Computer Vision. Cham: Springer Nature Switzerland, 2026. 13
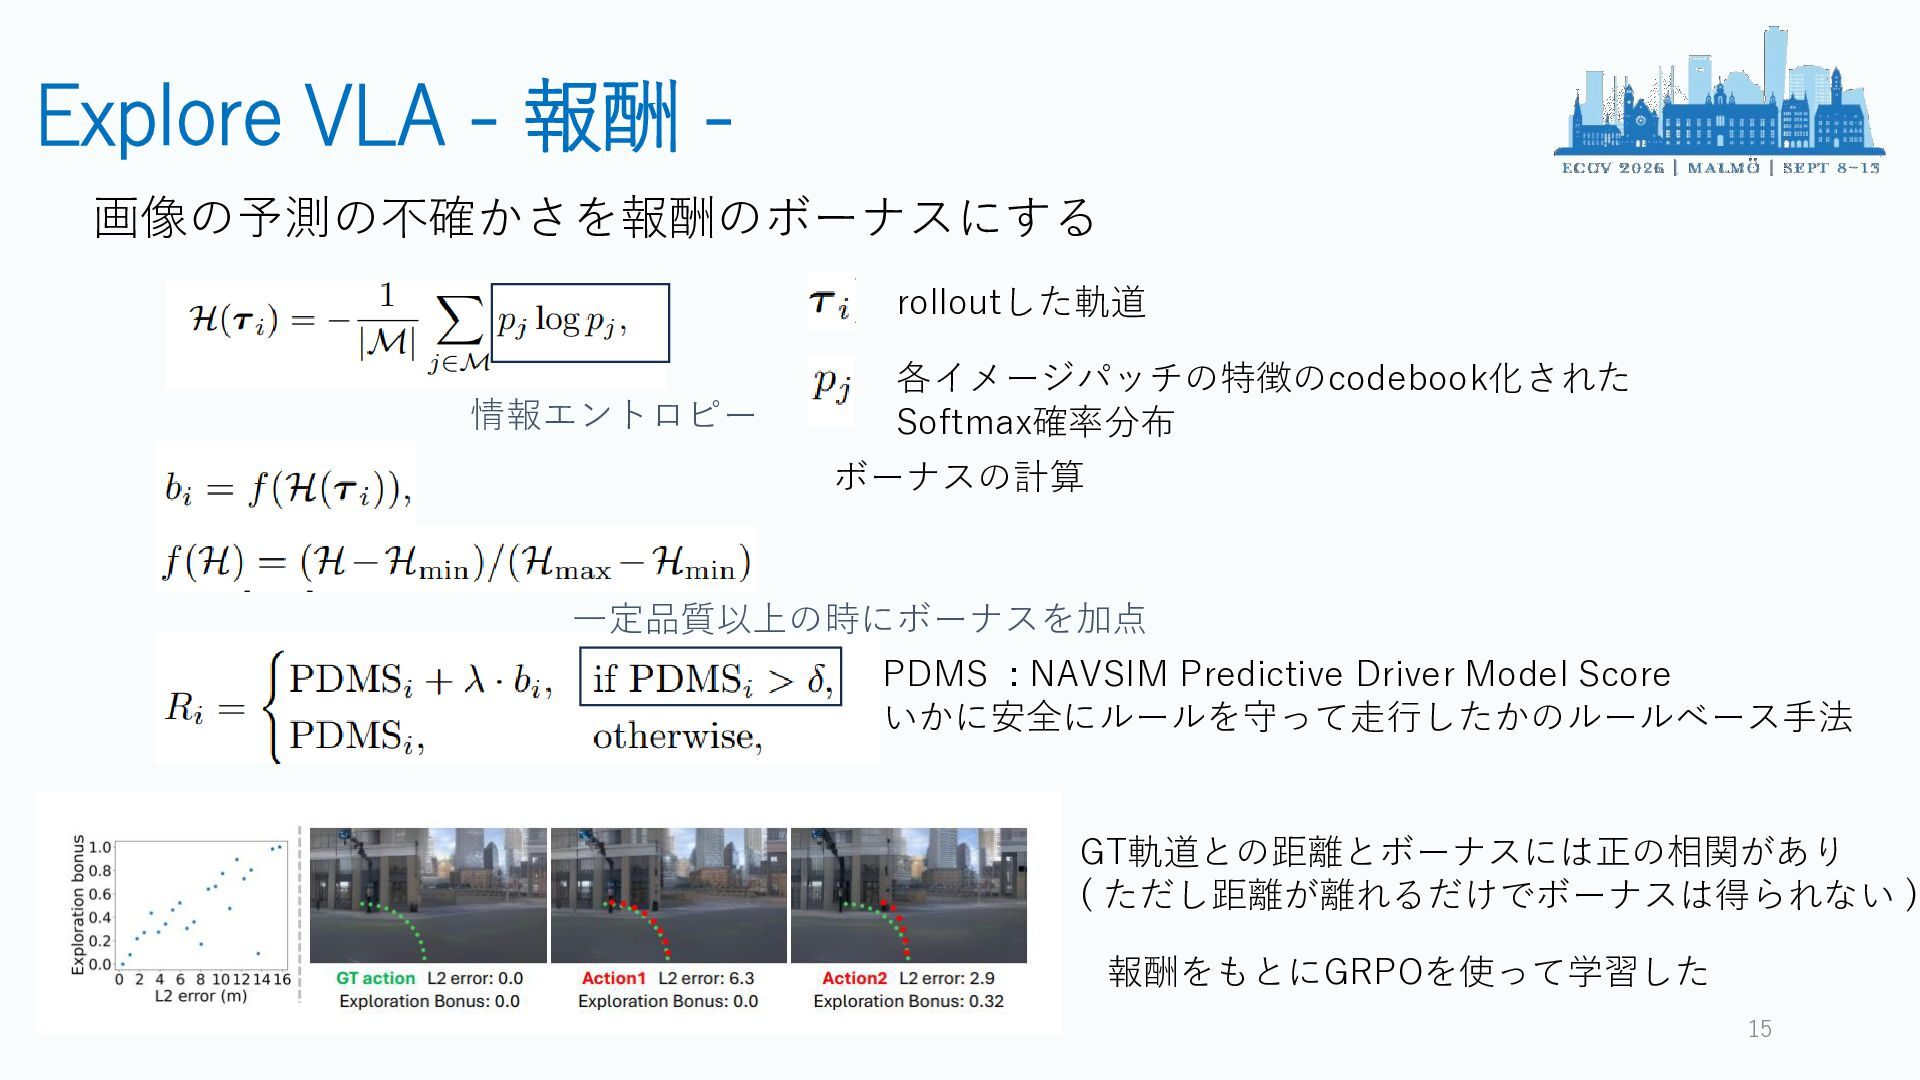
  12. Explore VLA - 報酬 画像の予測の不確かさを報酬のボーナスにする rolloutした軌道 情報エントロピー 各イメージパッチの特徴のcodebook化された Softmax確率分布 ボーナスの計算

    一定品質以上の時にボーナスを加点 PDMS : NAVSIM Predictive Driver Model Score いかに安全にルールを守って走行したかのルールベース手法 GT軌道との距離とボーナスには正の相関があり ( ただし距離が離れるだけでボーナスは得られない ) 報酬をもとにGRPOを使って学習した 15
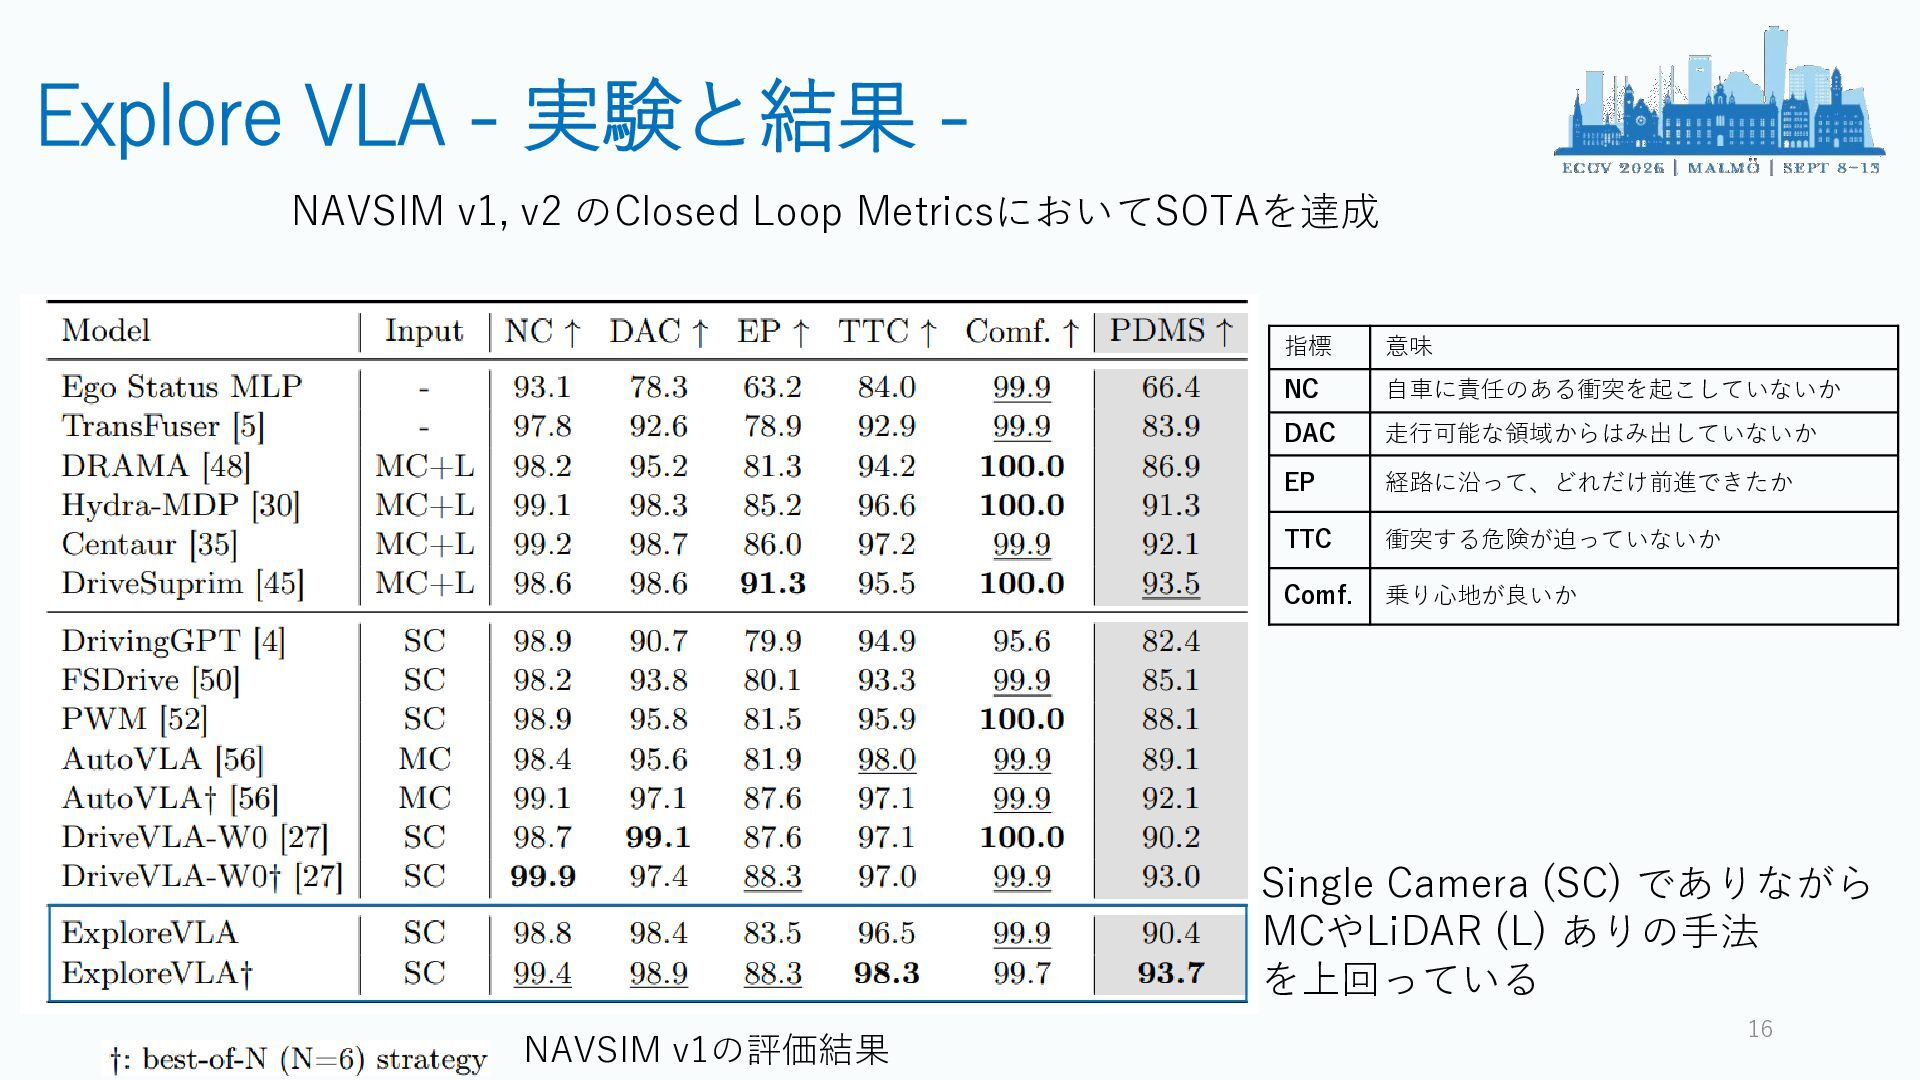
  13. Explore VLA - 実験と結果 NAVSIM v1, v2 のClosed Loop MetricsにおいてSOTAを達成

    指標 意味 NC 自車に責任のある衝突を起こしていないか DAC 走行可能な領域からはみ出していないか EP 経路に沿って、どれだけ前進できたか TTC 衝突する危険が迫っていないか Comf. 乗り心地が良いか Single Camera (SC) でありながら MCやLiDAR (L) ありの手法 を上回っている NAVSIM v1の評価結果 16
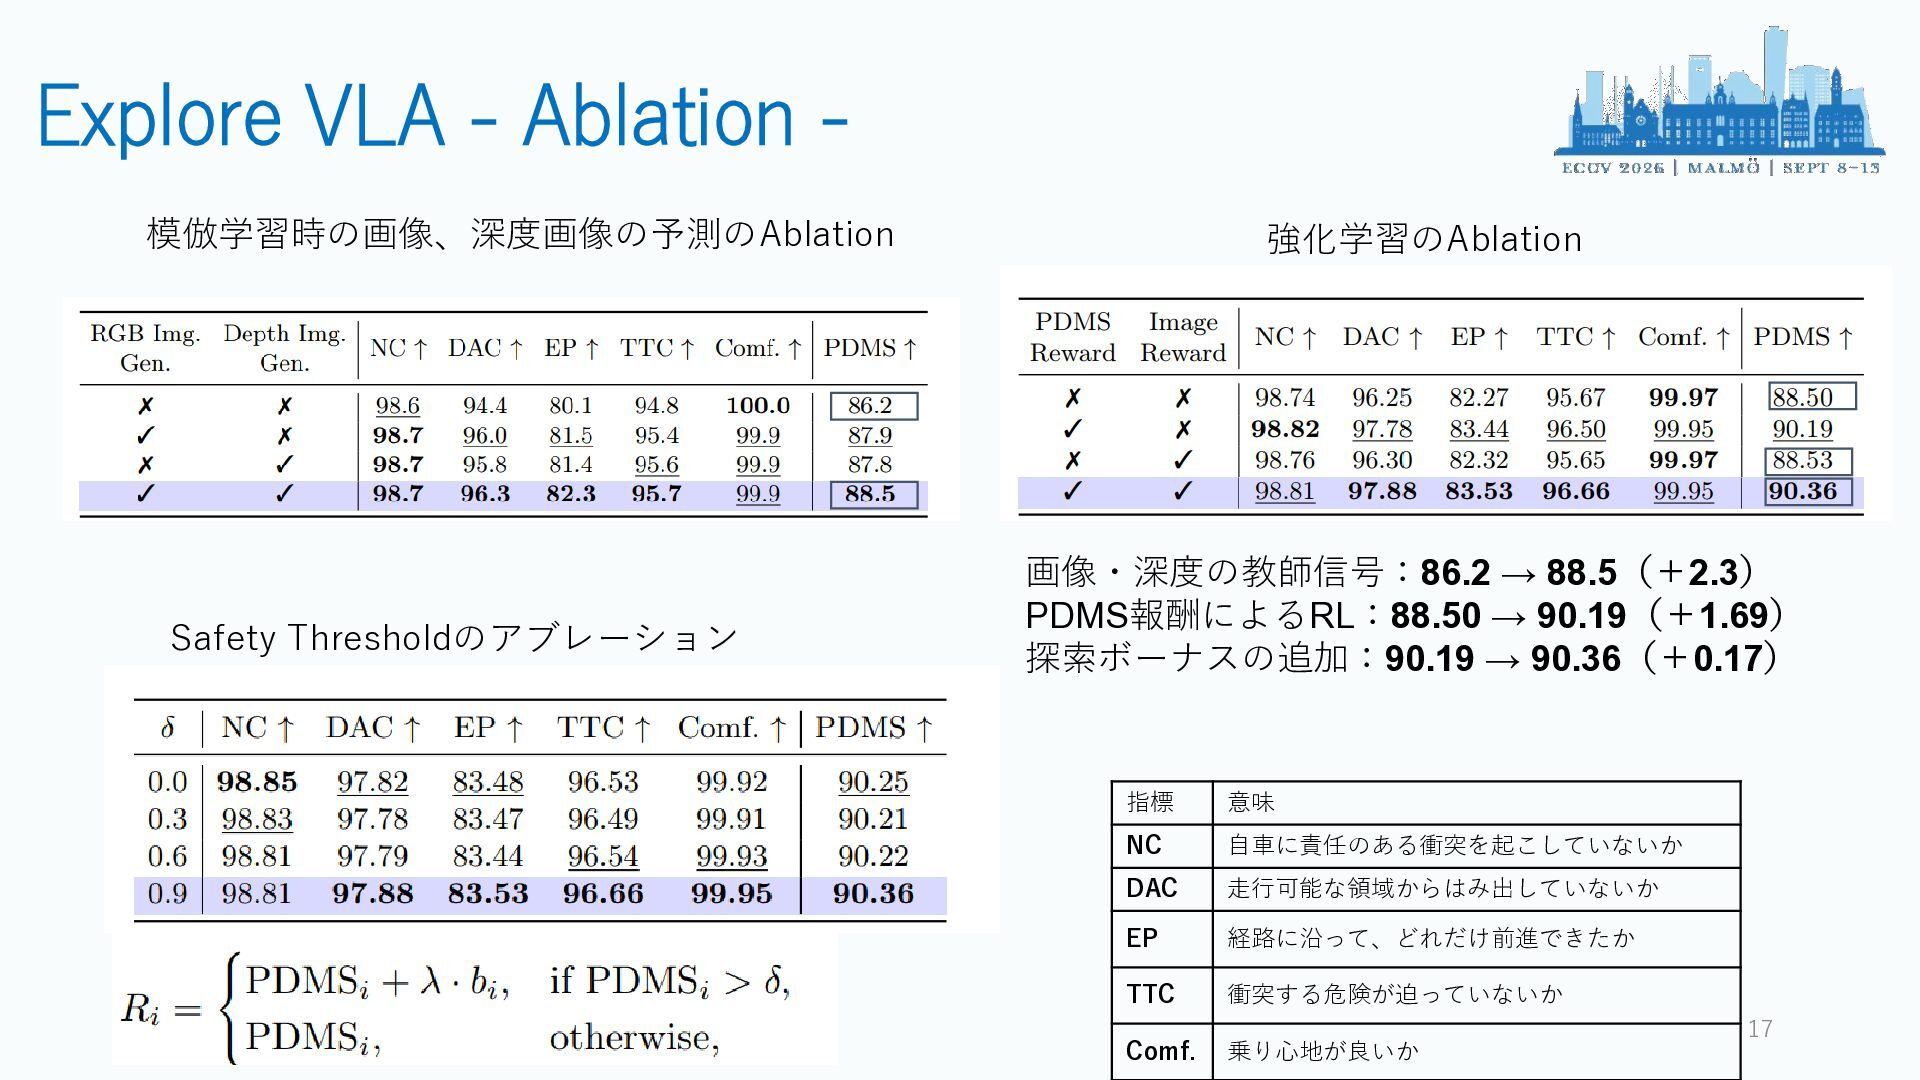
  14. Explore VLA - Ablation 模倣学習時の画像、深度画像の予測のAblation Safety Thresholdのアブレーション 強化学習のAblation 画像・深度の教師信号:86.2 →

    88.5(+2.3) PDMS報酬によるRL:88.50 → 90.19(+1.69) 探索ボーナスの追加:90.19 → 90.36(+0.17) 指標 意味 NC 自車に責任のある衝突を起こしていないか DAC 走行可能な領域からはみ出していないか EP 経路に沿って、どれだけ前進できたか TTC 衝突する危険が迫っていないか Comf. 乗り心地が良いか 17