Share
Embed
Transcript
39 slides
-
Utilize Kubernetes on OpenStack Cellular Genetics Informatics team (Sanger), Gene
Expression team (EBI) -
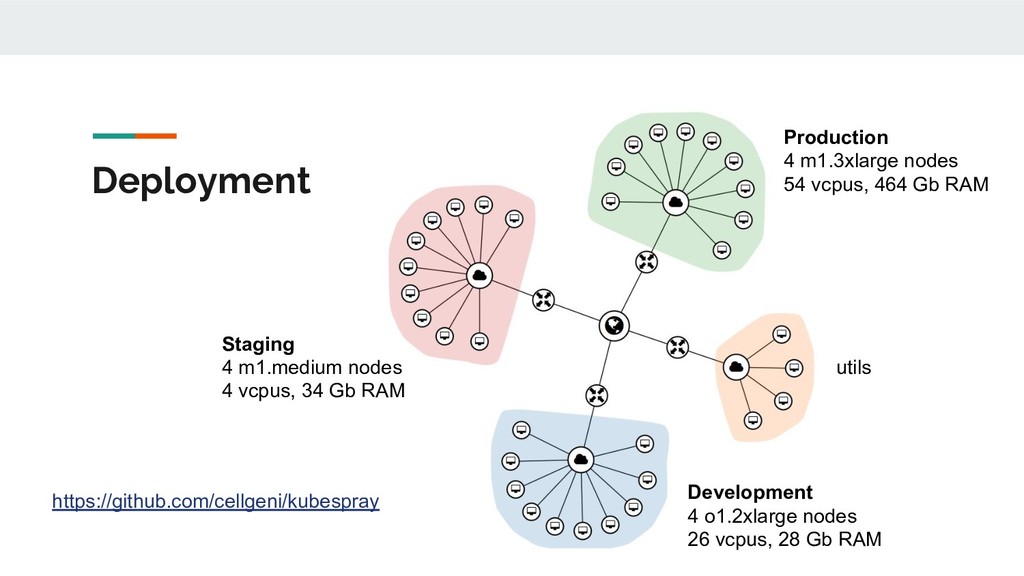
Deployment Production 4 m1.3xlarge nodes 54 vcpus, 464 Gb RAM
Staging 4 m1.medium nodes 4 vcpus, 34 Gb RAM Development 4 o1.2xlarge nodes 26 vcpus, 28 Gb RAM utils https://github.com/cellgeni/kubespray -
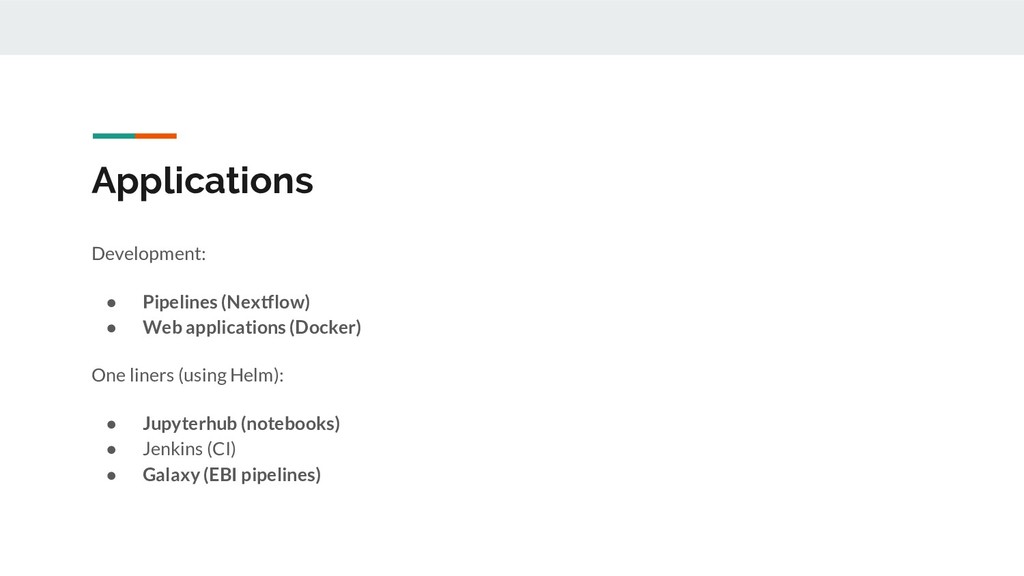
Applications Development: • Pipelines (Nextflow) • Web applications (Docker) One
liners (using Helm): • Jupyterhub (notebooks) • Jenkins (CI) • Galaxy (EBI pipelines) -
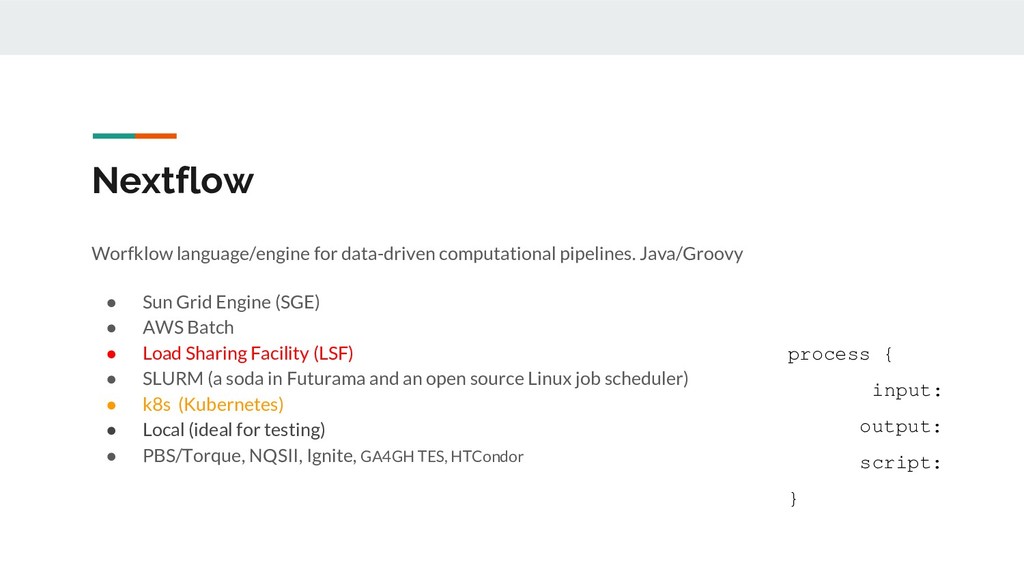
Nextflow Worfklow language/engine for data-driven computational pipelines. Java/Groovy • Sun
Grid Engine (SGE) • AWS Batch • Load Sharing Facility (LSF) • SLURM (a soda in Futurama and an open source Linux job scheduler) • k8s (Kubernetes) • Local (ideal for testing) • PBS/Torque, NQSII, Ignite, GA4GH TES, HTCondor process { input: output: script: } -
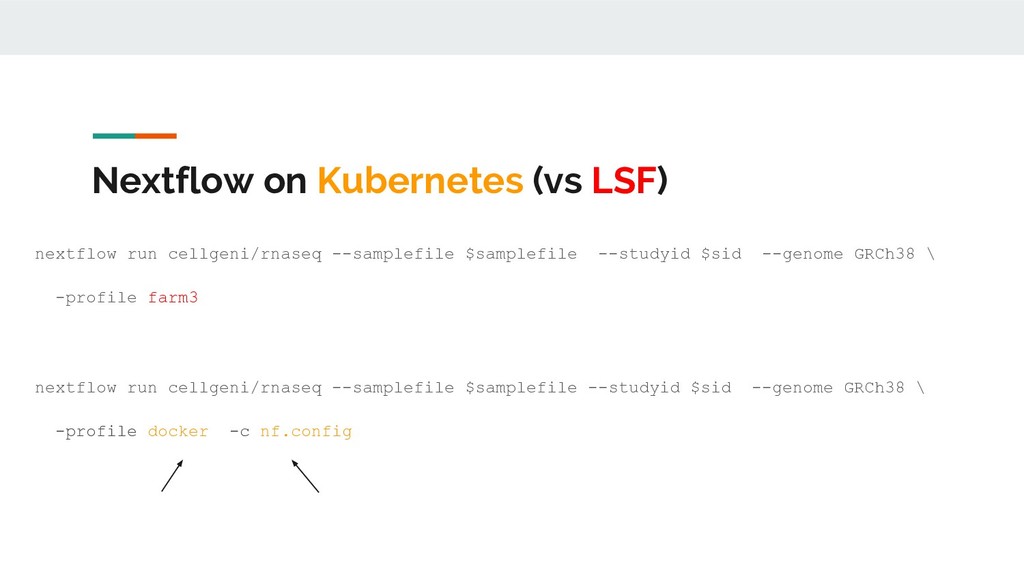
Nextflow on Kubernetes (vs LSF) nextflow run cellgeni/rnaseq --samplefile $samplefile
--studyid $sid --genome GRCh38 \ -profile farm3 nextflow run cellgeni/rnaseq --samplefile $samplefile --studyid $sid --genome GRCh38 \ -profile docker -c nf.config -
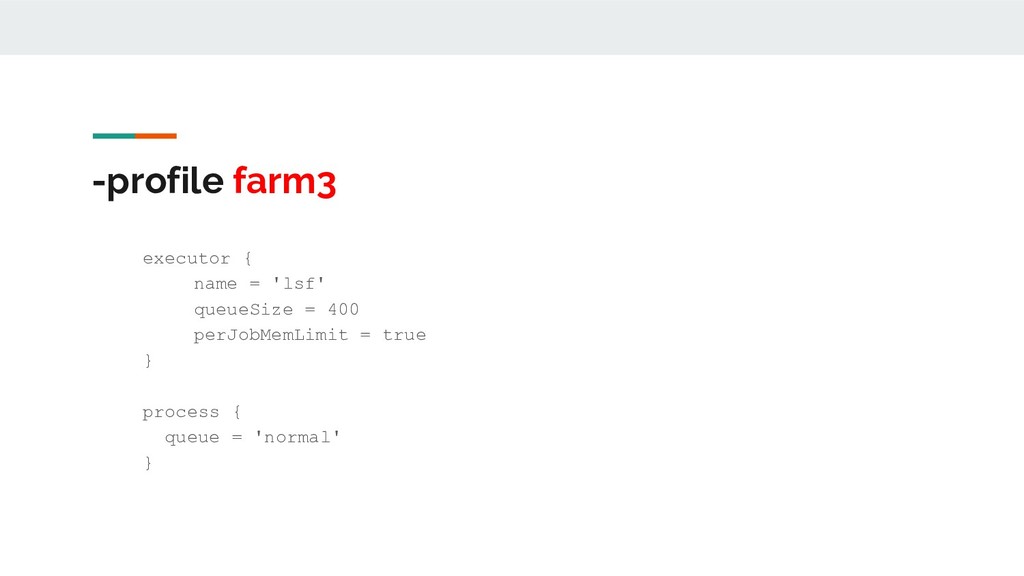
-profile farm3 • executor { • name = 'lsf' •
queueSize = 400 • perJobMemLimit = true • } • • process { • queue = 'normal' • } • -
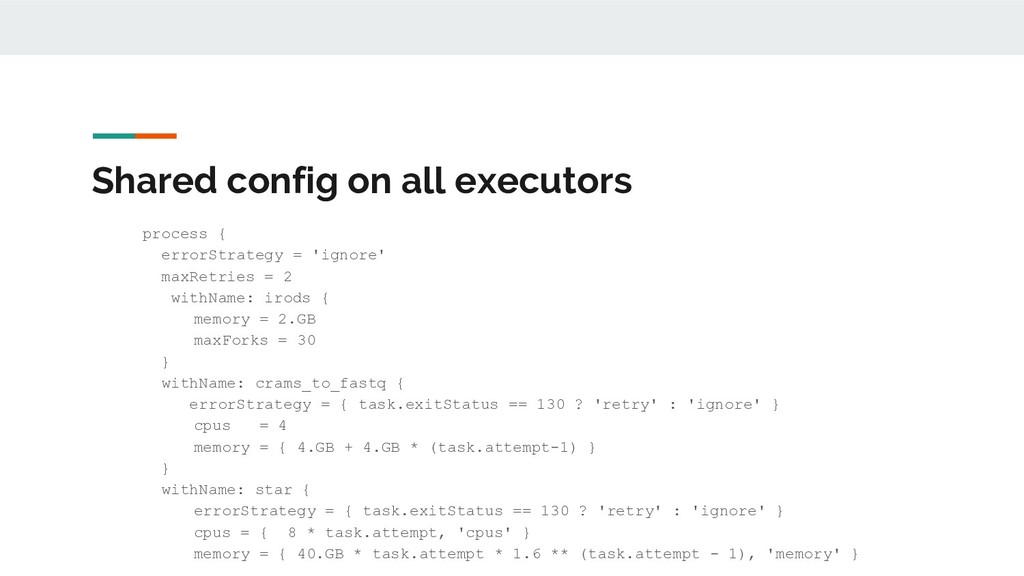
Shared config on all executors • process { • errorStrategy
= 'ignore' • maxRetries = 2 • withName: irods { • memory = 2.GB • maxForks = 30 • } • withName: crams_to_fastq { • errorStrategy = { task.exitStatus == 130 ? 'retry' : 'ignore' } • cpus = 4 • memory = { 4.GB + 4.GB * (task.attempt-1) } • } • withName: star { • errorStrategy = { task.exitStatus == 130 ? 'retry' : 'ignore' } • cpus = { 8 * task.attempt, 'cpus' } • memory = { 40.GB * task.attempt * 1.6 ** (task.attempt - 1), 'memory' } -
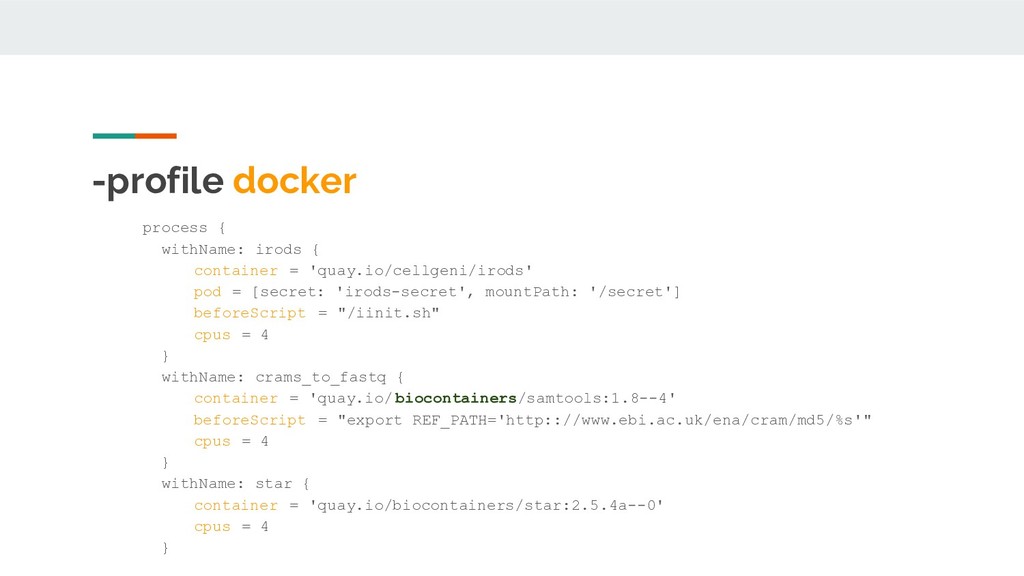
-profile docker • process { • withName: irods { •
container = 'quay.io/cellgeni/irods' • pod = [secret: 'irods-secret', mountPath: '/secret'] • beforeScript = "/iinit.sh" • cpus = 4 • } • withName: crams_to_fastq { • container = 'quay.io/ biocontainers/samtools:1.8--4' • beforeScript = "export REF_PATH='http:://www.ebi.ac.uk/ena/cram/md5/%s'" • cpus = 4 • } • withName: star { • container = 'quay.io/biocontainers/star:2.5.4a--0' • cpus = 4 • } • -
-c nf.config • process { • maxForks = 40 #
adapt to our cluster size, fake batch system • afterScript = 'sleep 1' # deal with timestamps and caching • cache = 'lenient' # idem • } • • executor { queueSize = 40 } # adapt to cluster size • • k8s { • storageClaimName = 'nf-pvc' # gluster settings • storageMountPath = '/mnt/gluster’ # • } • • -
Issues and notes • Samtools failure to populate reference sometimes.
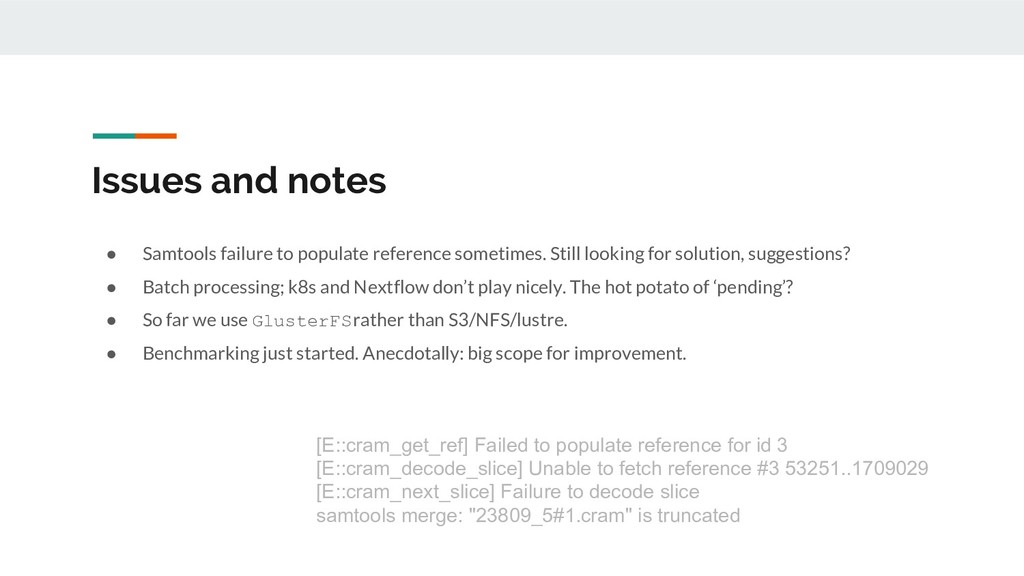
Still looking for solution, suggestions? • Batch processing; k8s and Nextflow don’t play nicely. The hot potato of ‘pending’? • So far we use GlusterFS rather than S3/NFS/lustre. • Benchmarking just started. Anecdotally: big scope for improvement. [E::cram_get_ref] Failed to populate reference for id 3 [E::cram_decode_slice] Unable to fetch reference #3 53251..1709029 [E::cram_next_slice] Failure to decode slice samtools merge: "23809_5#1.cram" is truncated -
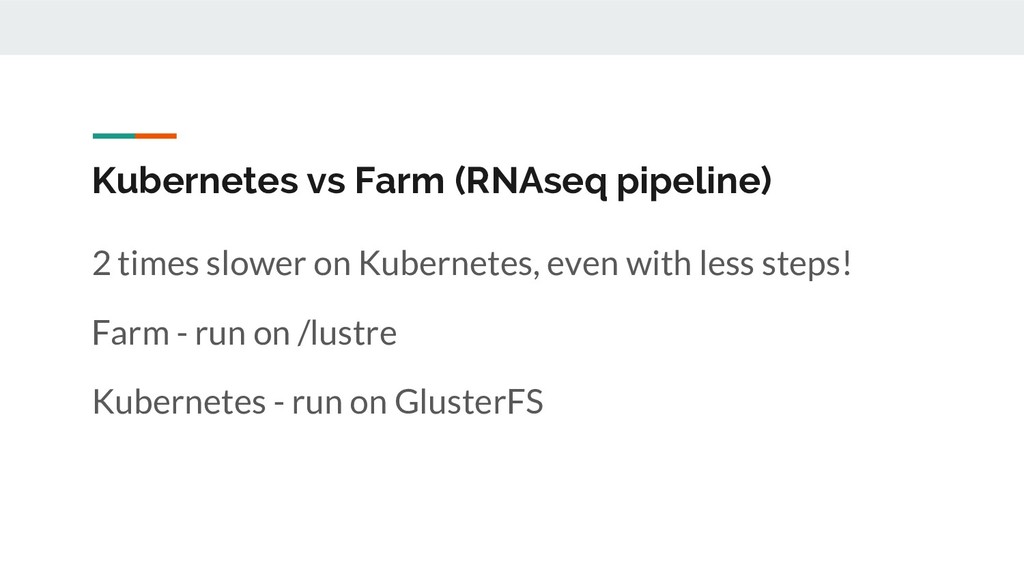
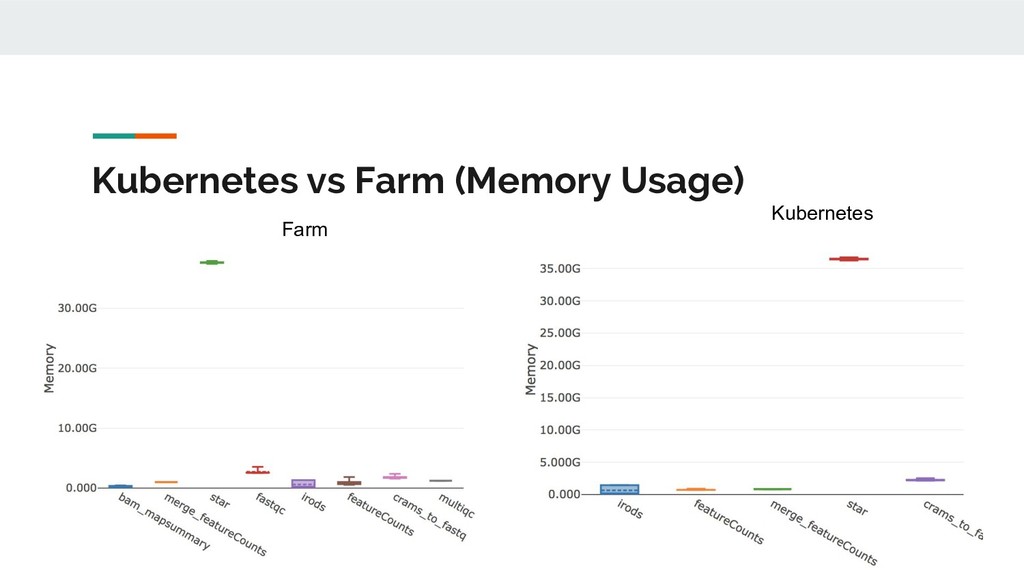
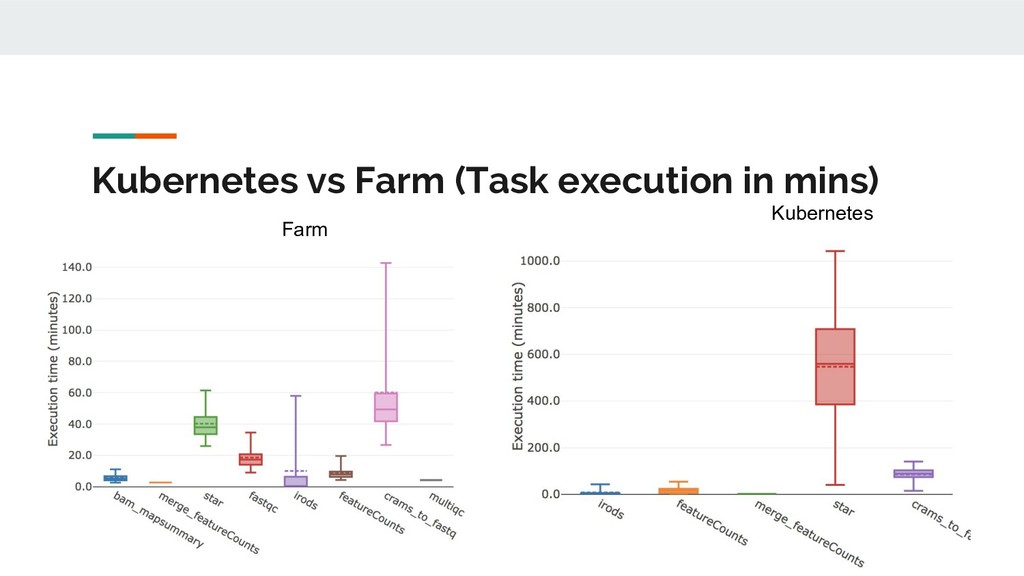
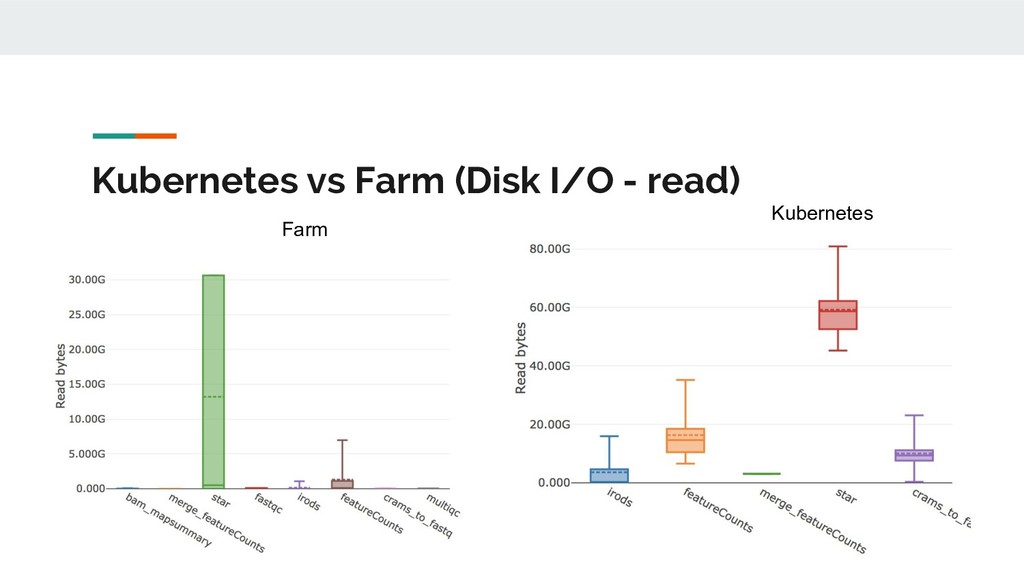
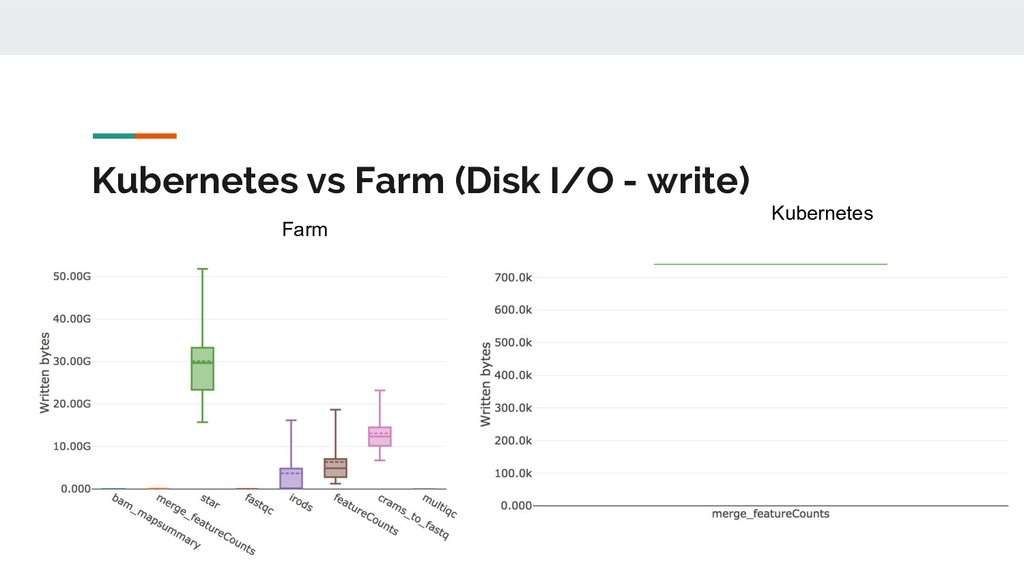
Kubernetes vs Farm (RNAseq pipeline) 2 times slower on Kubernetes,
even with less steps! Farm - run on /lustre Kubernetes - run on GlusterFS -
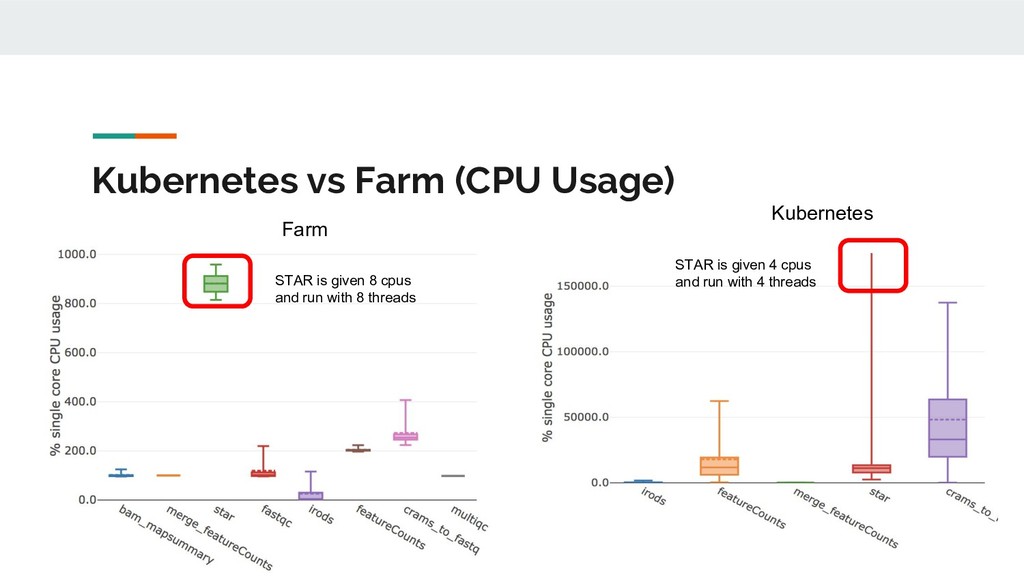
Kubernetes vs Farm (CPU Usage) STAR is given 8 cpus
and run with 8 threads STAR is given 4 cpus and run with 4 threads Kubernetes Farm -
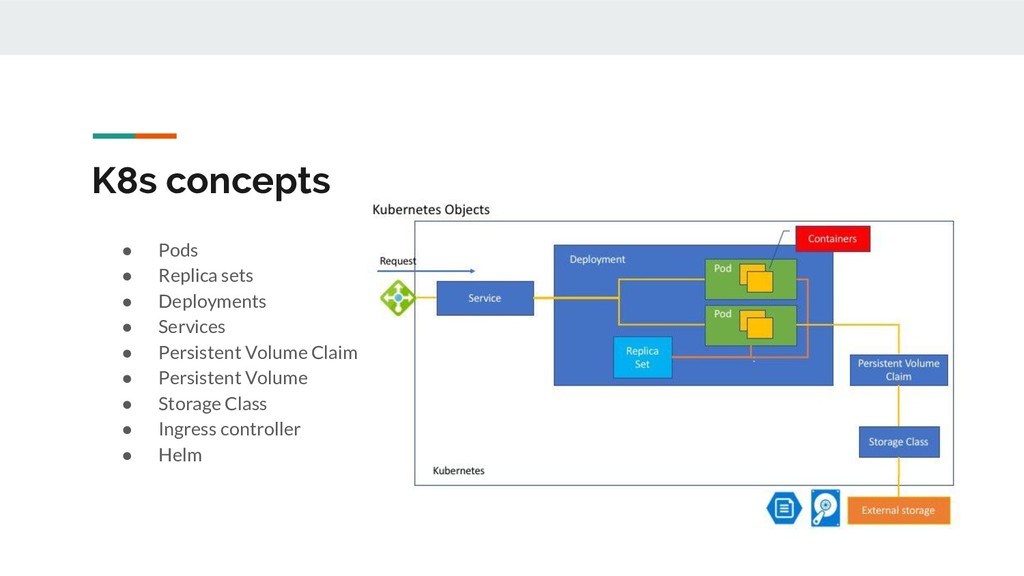
K8s concepts • Pods • Replica sets • Deployments •
Services • Persistent Volume Claim • Persistent Volume • Storage Class • Ingress controller • Helm -
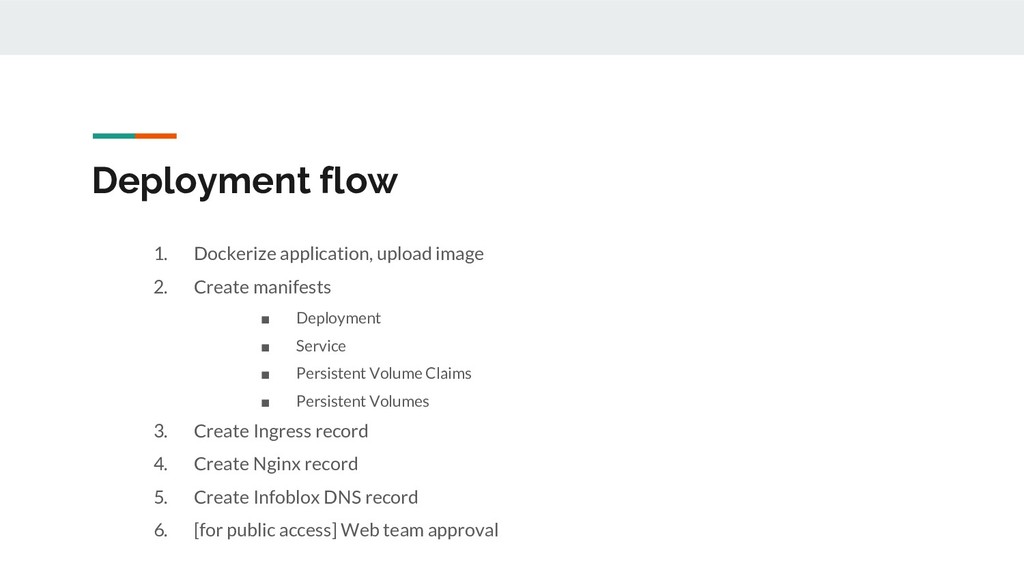
Deployment flow 1. Dockerize application, upload image 2. Create manifests
▪ Deployment ▪ Service ▪ Persistent Volume Claims ▪ Persistent Volumes 3. Create Ingress record 4. Create Nginx record 5. Create Infoblox DNS record 6. [for public access] Web team approval -
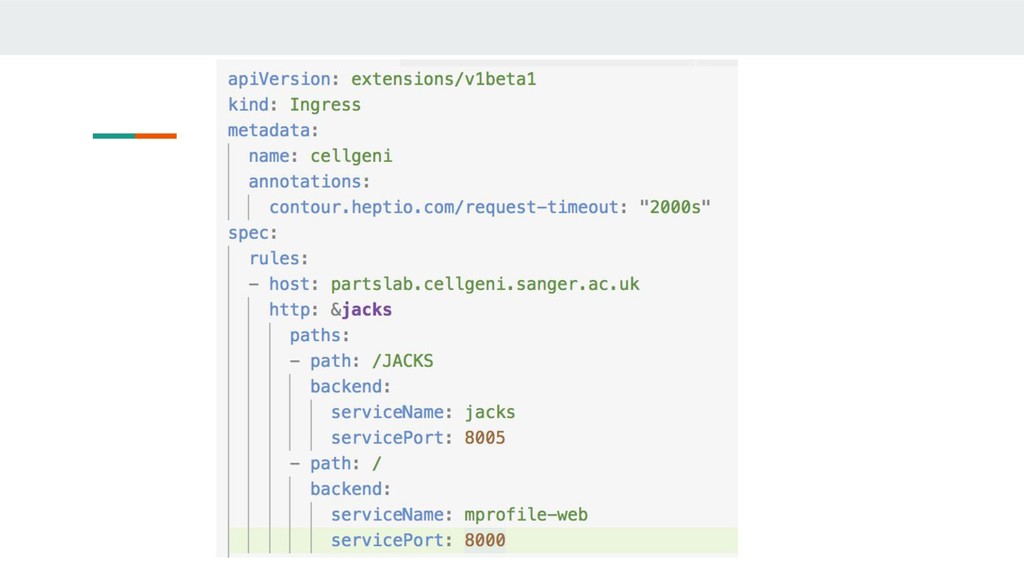
Example: partslab.sanger.ac.uk • Two independent services: ◦ FORECasT ◦ JACKS
• FORECasT ◦ Front end ◦ Method back end • JACKS ◦ Front end ◦ Redis ◦ Celery -
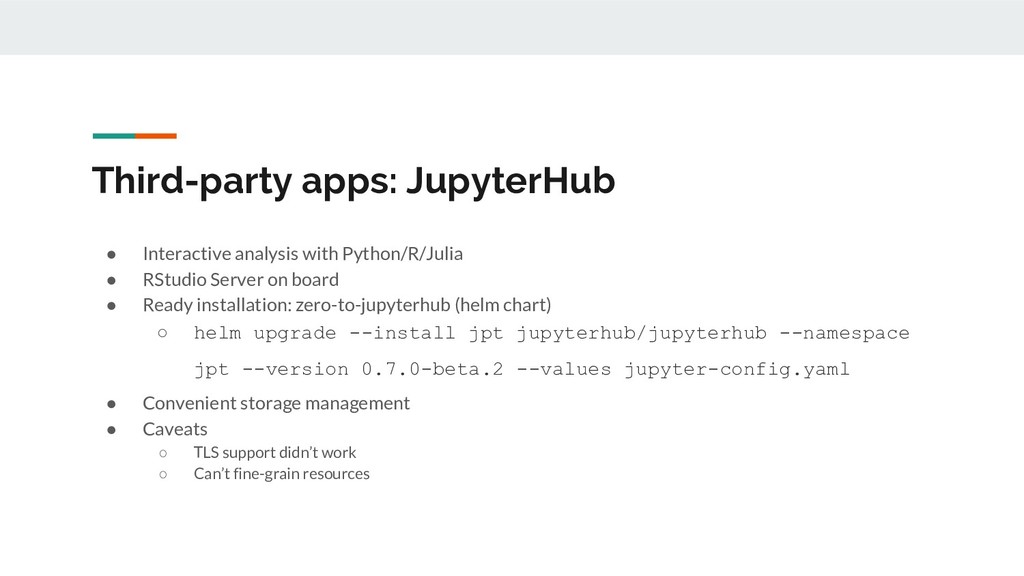
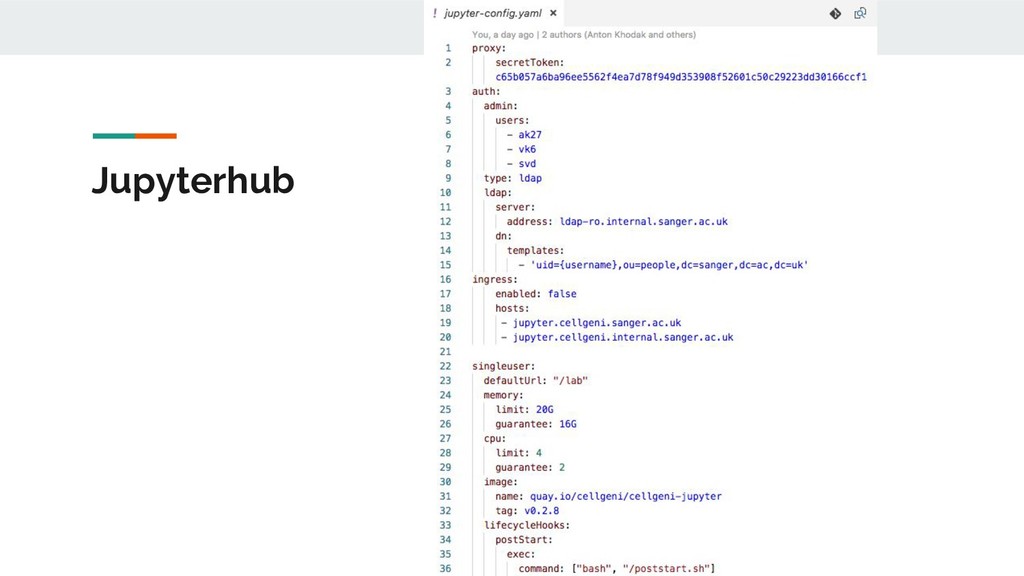
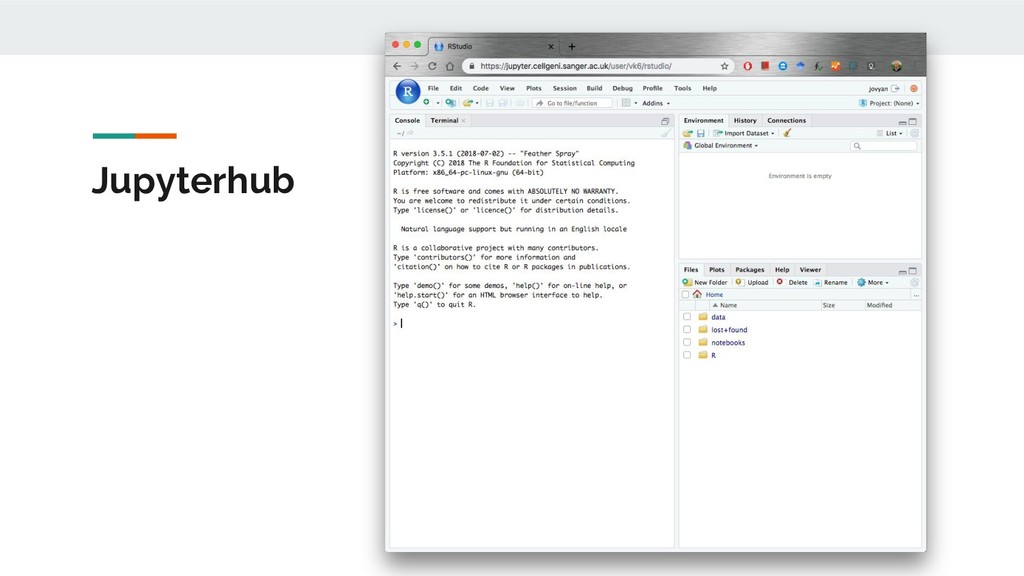
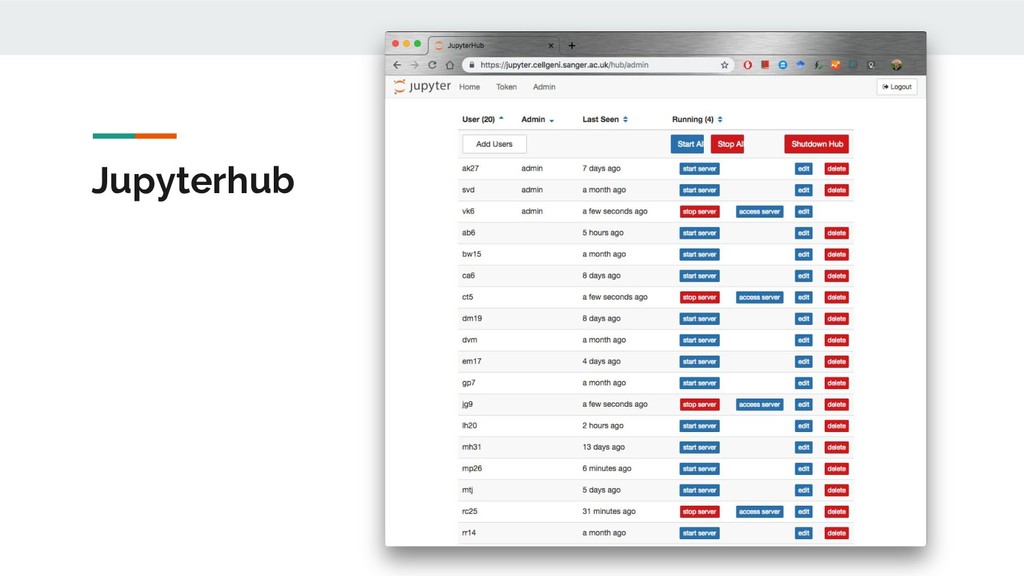
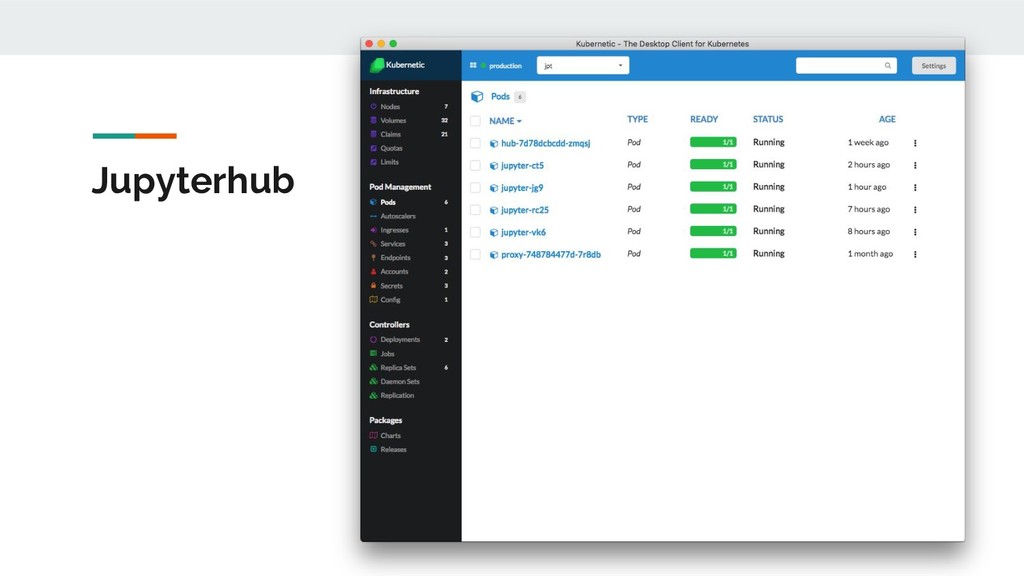
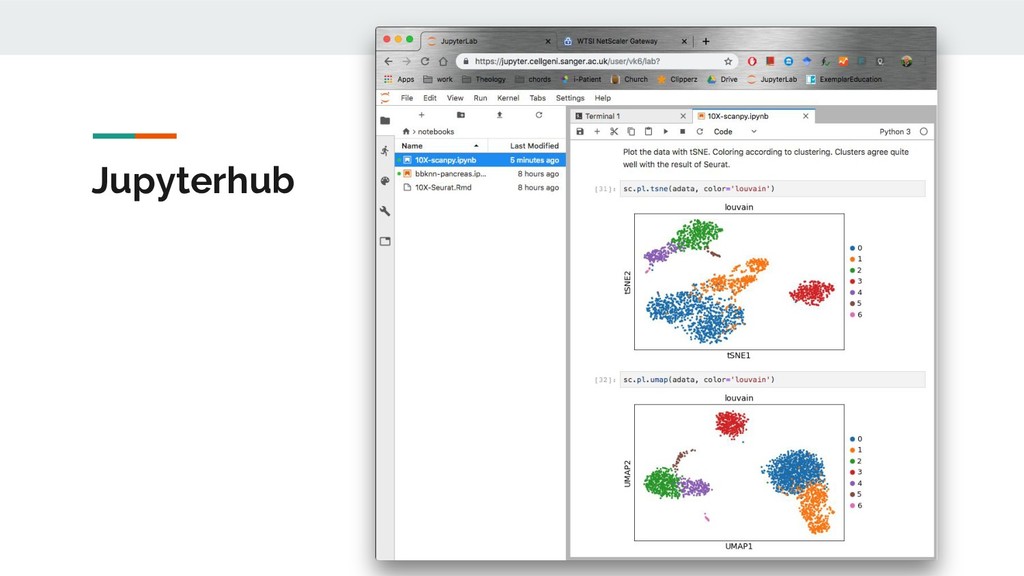
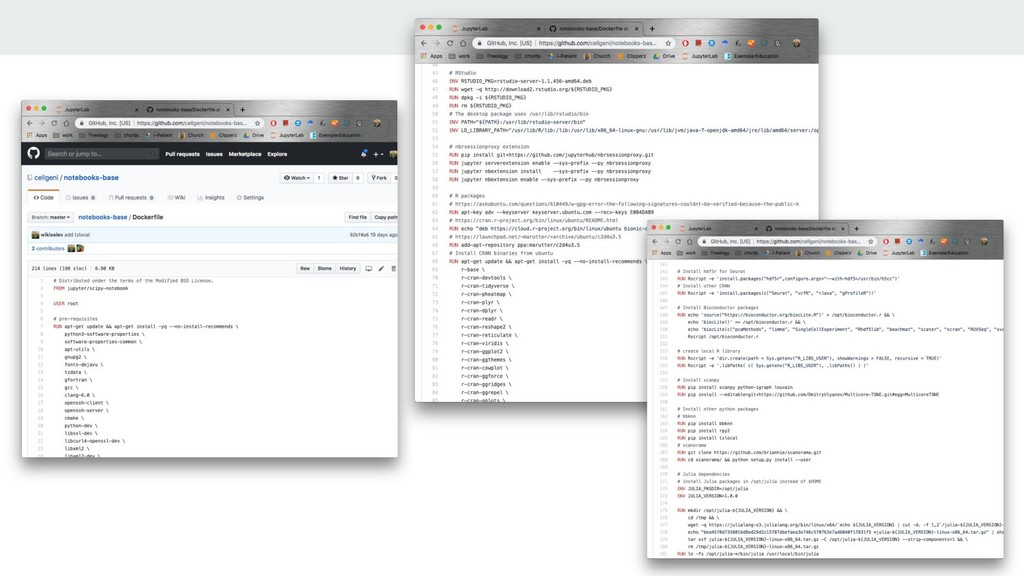
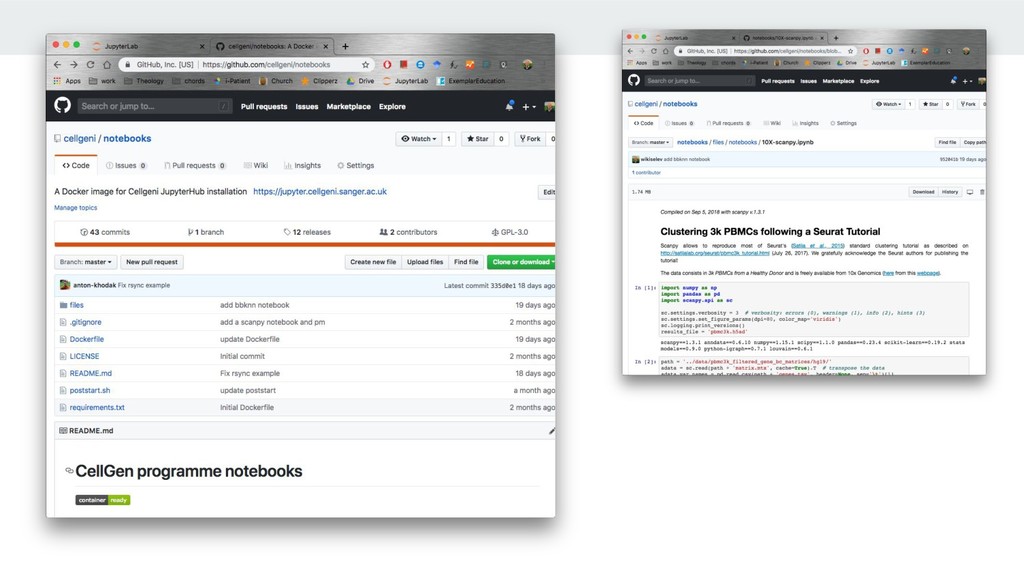
Third-party apps: JupyterHub • Interactive analysis with Python/R/Julia • RStudio
Server on board • Ready installation: zero-to-jupyterhub (helm chart) ◦ helm upgrade --install jpt jupyterhub/jupyterhub --namespace jpt --version 0.7.0-beta.2 --values jupyter-config.yaml • Convenient storage management • Caveats ◦ TLS support didn’t work ◦ Can’t fine-grain resources -
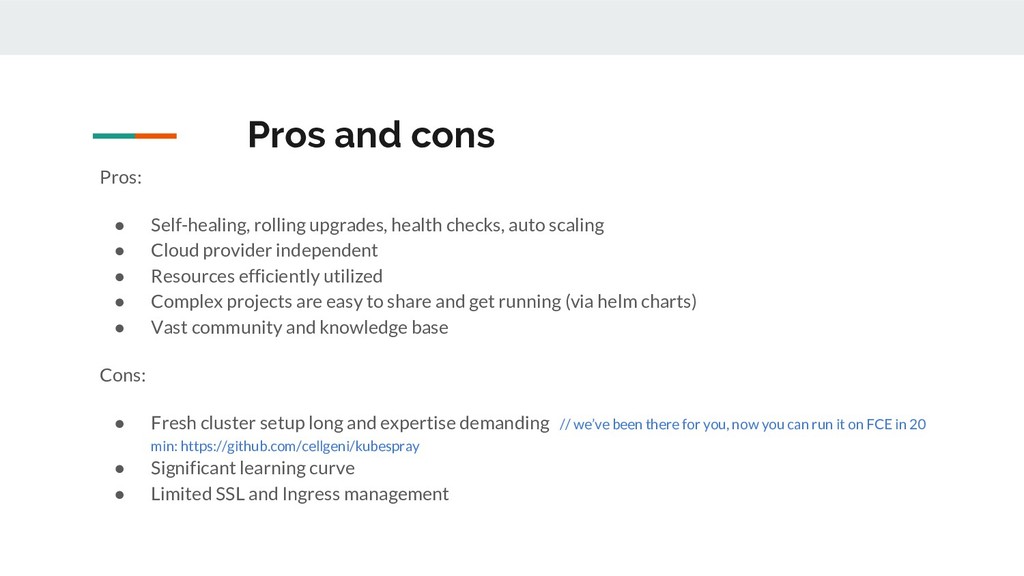
Pros and cons Pros: • Self-healing, rolling upgrades, health checks,
auto scaling • Cloud provider independent • Resources efficiently utilized • Complex projects are easy to share and get running (via helm charts) • Vast community and knowledge base Cons: • Fresh cluster setup long and expertise demanding // we’ve been there for you, now you can run it on FCE in 20 min: https://github.com/cellgeni/kubespray • Significant learning curve • Limited SSL and Ingress management -
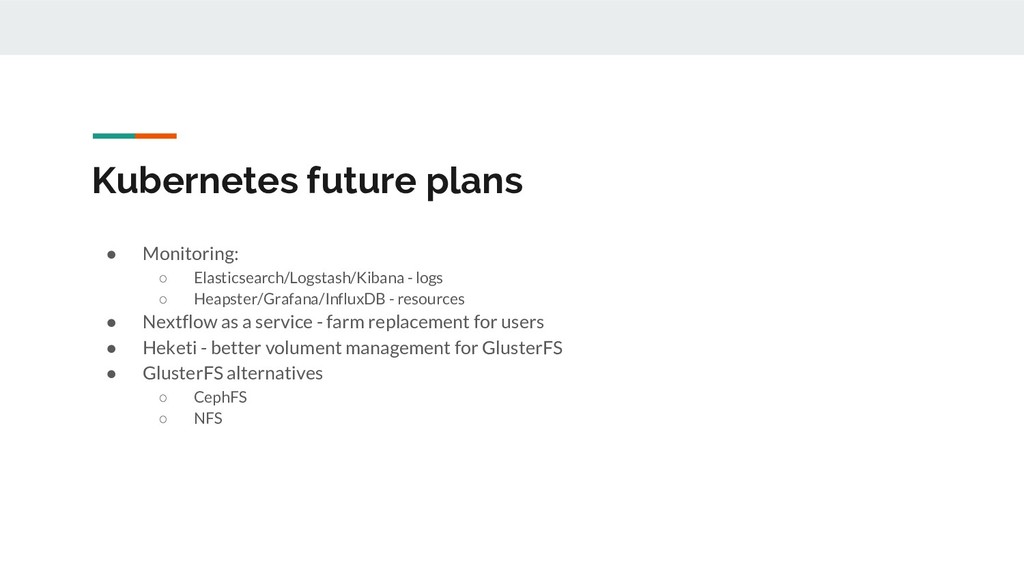
Kubernetes future plans • Monitoring: ◦ Elasticsearch/Logstash/Kibana - logs ◦
Heapster/Grafana/InfluxDB - resources • Nextflow as a service - farm replacement for users • Heketi - better volument management for GlusterFS • GlusterFS alternatives ◦ CephFS ◦ NFS -
Paolo Di Tommaso Pablo Moreno Phil Ewels Acknowledgments Helen Cousins
Theo Barber-Bany Peter Clapham Tim Cutts Joe Garfoot James Smith Paul Bevan Nick Boughton