Share
Natural Language Processing with Less Data and More Structures
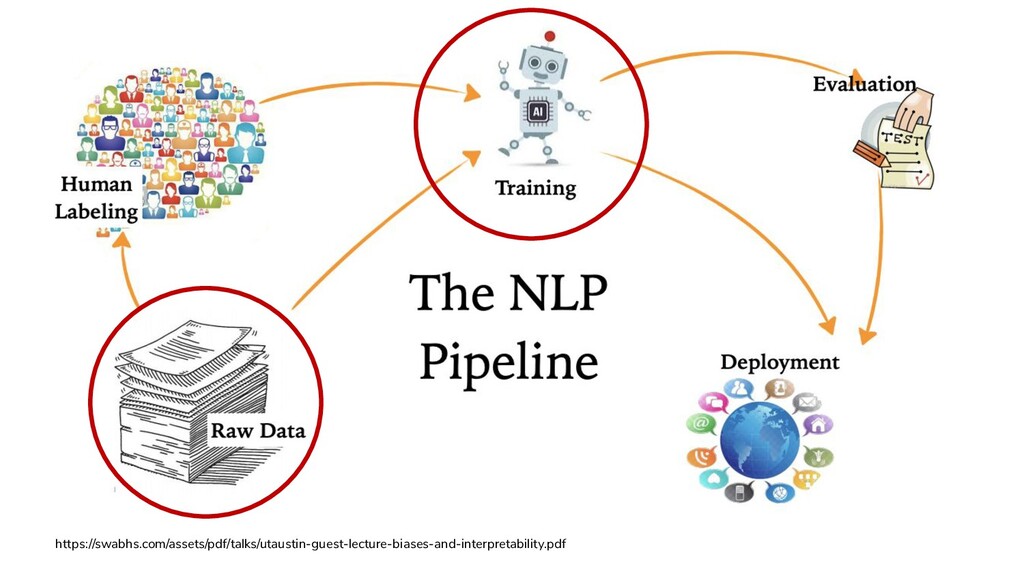
Recently, natural language processing (NLP) has had increasing success and produced extensive industrial applications. Despite being sufficient to enable these applications, current NLP systems often ignore the structures of language and heavily rely on massive labeled data. In this talk, we take a closer look at the interplay between language structures and computational methods via two lines of work. The first one studies how to incorporate linguistically-informed relations between different training data to help both text classification and sequence labeling tasks when annotated data is limited. The second part demonstrates how various structures in conversations can be utilized to generate better dialog summaries for everyday interaction.
wing.nus
Transcript
107 slides
-
Natural Language Processing with Less Data and More Structures Diyi
Yang School of Interactive Computing Georgia Tech -
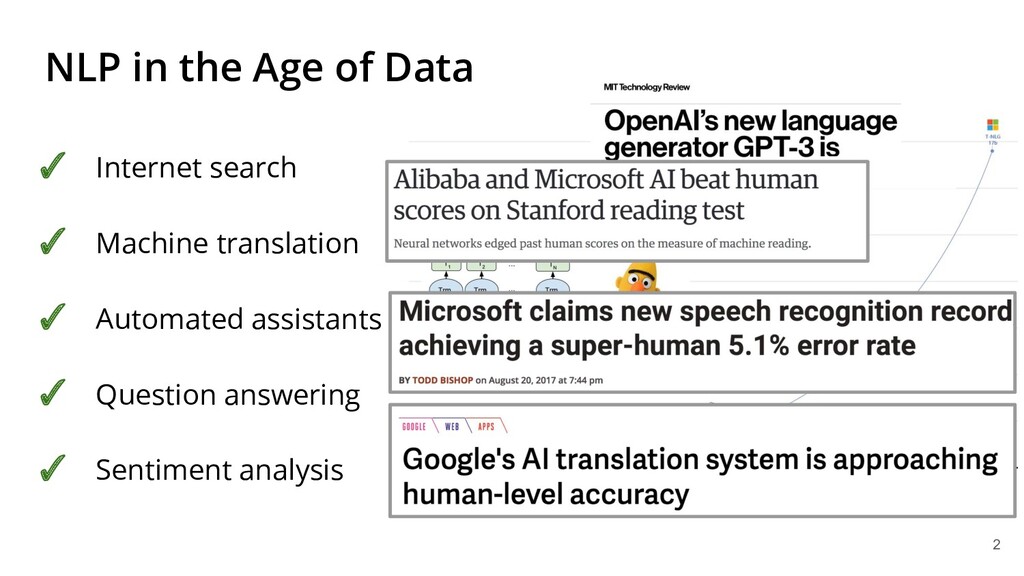
NLP in the Age of Data ✓ Internet search ✓
Machine translation ✓ Automated assistants ✓ Question answering ✓ Sentiment analysis 2 -
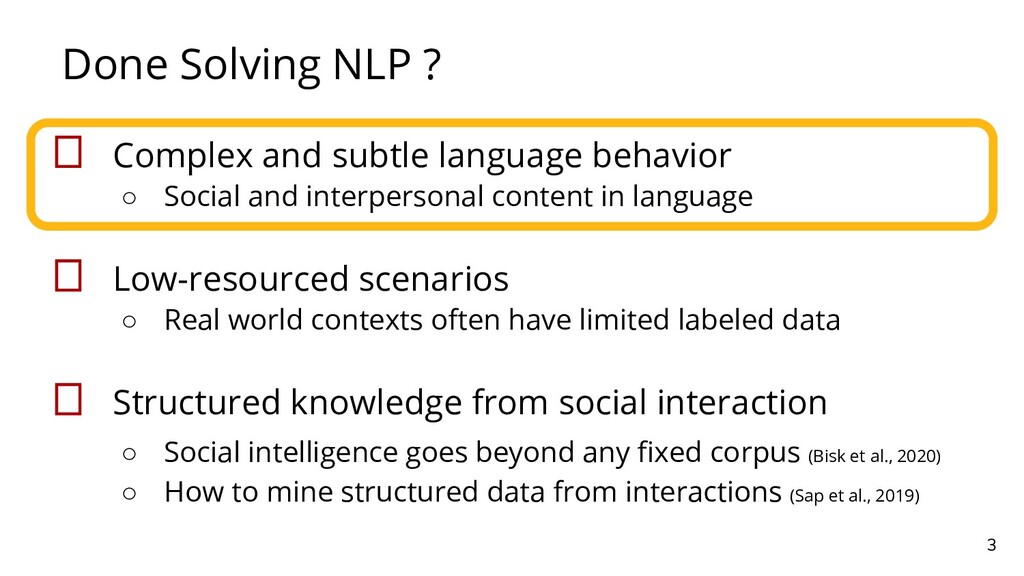
Done Solving NLP ? 3 Complex and subtle language behavior
◦ Social and interpersonal content in language Low-resourced scenarios ◦ Real world contexts often have limited labeled data Structured knowledge from social interaction ◦ Social intelligence goes beyond any fixed corpus (Bisk et al., 2020) ◦ How to mine structured data from interactions (Sap et al., 2019) -
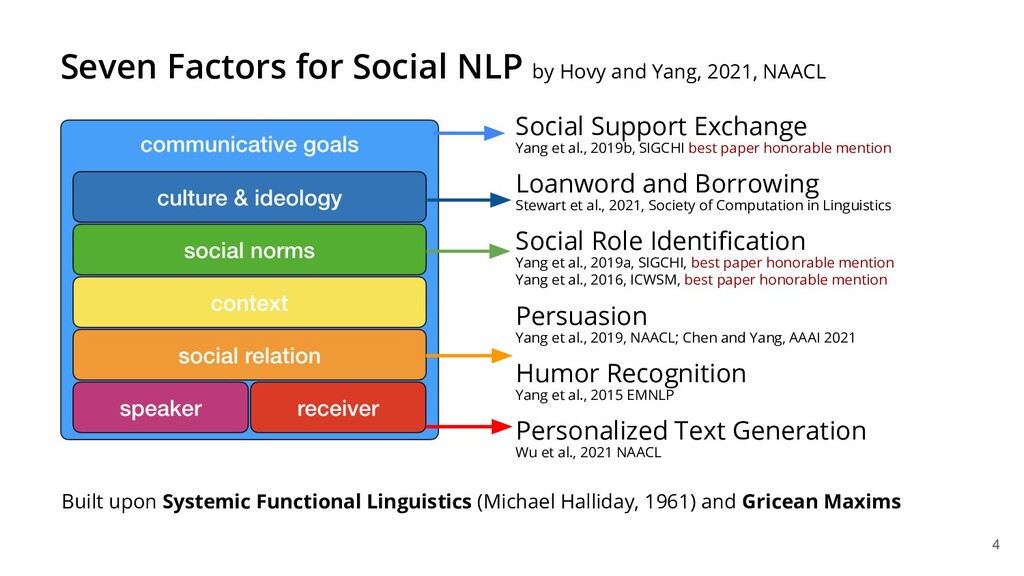
Built upon Systemic Functional Linguistics (Michael Halliday, 1961) and Gricean
Maxims Seven Factors for Social NLP by Hovy and Yang, 2021, NAACL Social Support Exchange Yang et al., 2019b, SIGCHI best paper honorable mention Loanword and Borrowing Stewart et al., 2021, Society of Computation in Linguistics Social Role Identification Yang et al., 2019a, SIGCHI, best paper honorable mention Yang et al., 2016, ICWSM, best paper honorable mention Persuasion Yang et al., 2019, NAACL; Chen and Yang, AAAI 2021 Humor Recognition Yang et al., 2015 EMNLP Personalized Text Generation Wu et al., 2021 NAACL 4 -
5 “Speak to our head of sales - he has
over 15 years’ experience” “In high demand - only 2 left on our site” “The picture of widow Bunisia holding her baby in front of her meager home brings tears to my eyes.” ✓ Translate theories into measurable language cues, such as scarcity, authority, emotion, reciprocity, etc ✓ Model persuasion via semi-supervised nets ✓ Ordering of rhetorical persuasion strategies on request success What makes language persuasive (NAACL 2019, EMNLP 2020; AAAI 2021) -
Done Solving NLP ? 6 Complex and subtle language behavior
◦ Social and interpersonal content in language Low-resourced scenarios ◦ Real world contexts often have limited labeled data Structured knowledge from social interaction ◦ Social intelligence goes beyond any fixed corpus (Bisk et al., 2020) ◦ How to mine structured data from interactions (Sap et al., 2019) -
Overview of This Talk 7 ❏ Low-Resourced Scenarios ❏ Text
Mixup for Semi-supervised Classification ❏ LADA for Named Entity Recognition ❏ Structured Knowledge from Conversations ❏ Summarization via Conversation Structures ❏ Summarization via Action and Discourse Graphs -
Overview of This Talk 8 ➢ Low-Resourced Scenarios ➢ Text
Mixup for Semi-supervised Classification Jiaao Chen, Zichao Yang, Diyi Yang. MixText: Linguistically-Informed Interpolation of Hidden Space for Semi-Supervised Text Classification. ACL 2020 -
Lots of (Socially) Low-Resourced Settings 10 ❏ Rich social information
in text ❏ Often unlabeled in real-world settings ❏ How to utilize limited data for learning -
Prior Work on Semi-Supervised Text Classification ◦ Confident predictions on
unlabeled data for self-training (Lee, 2013; Grandvalet and Bengio, 2004; Meng et al., 2018) ◦ Consistency training on unlabeled data (Miyato et al., 2019, 2017; Xie et al., 2019) ◦ Pre-training on unlabeled data, then fine-tuning on labeled data (Devlin et al., 2019) 11 -
Why Is It Not Enough? ❏ Labeled and unlabeled data
are treated separately ❏ Models may easily overfit on labeled data while still underfit on the unlabeled data 12 -
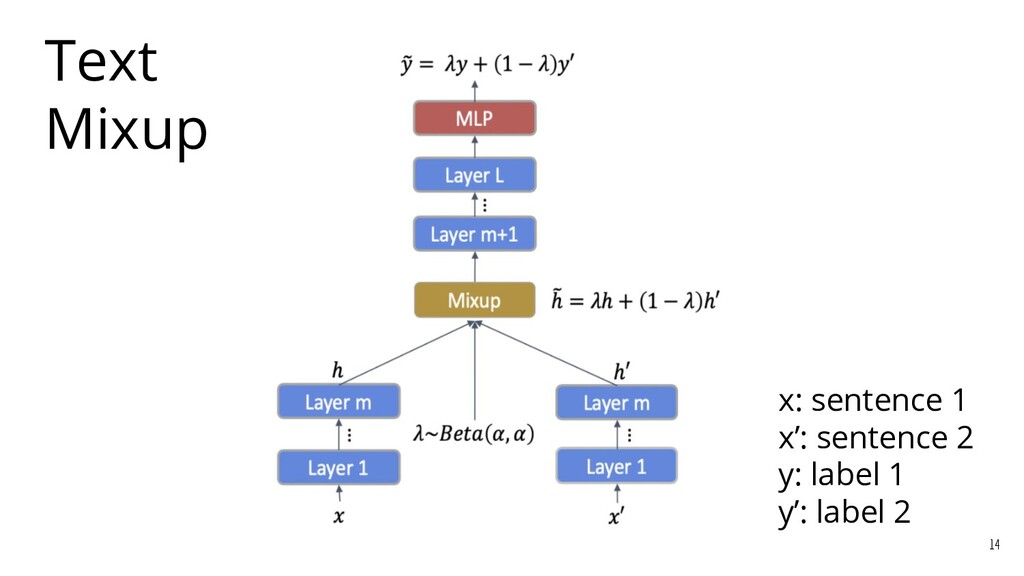
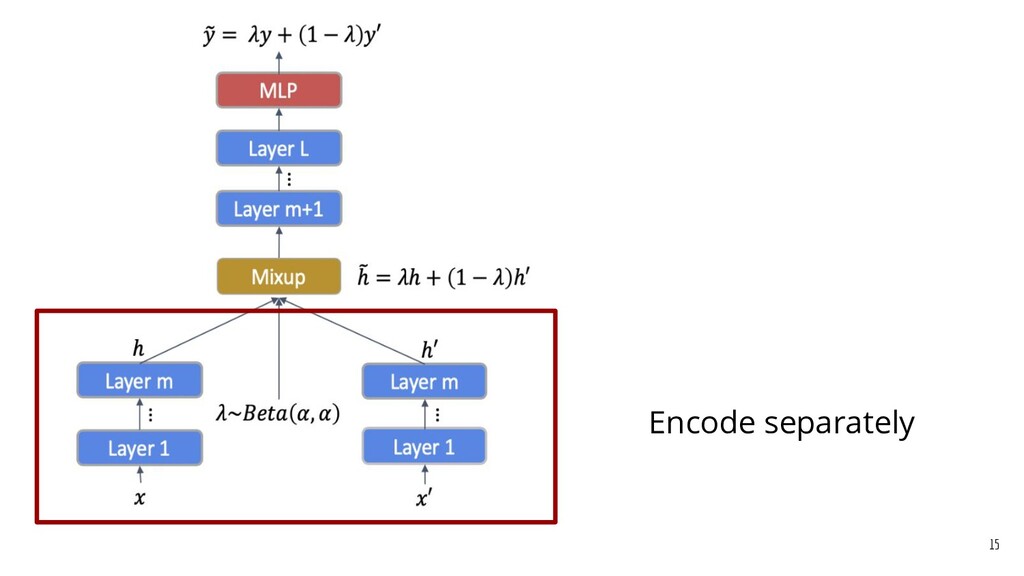
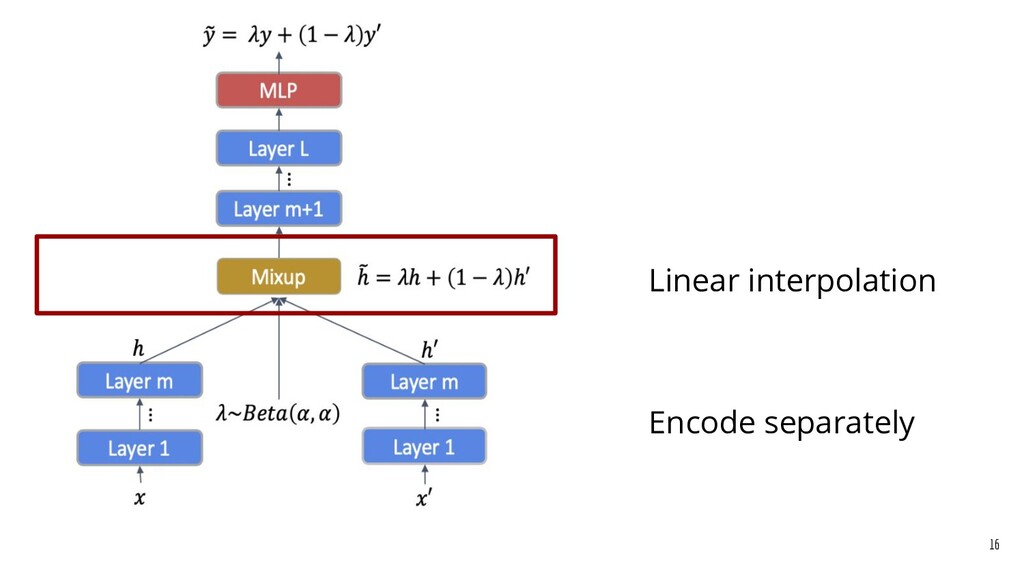
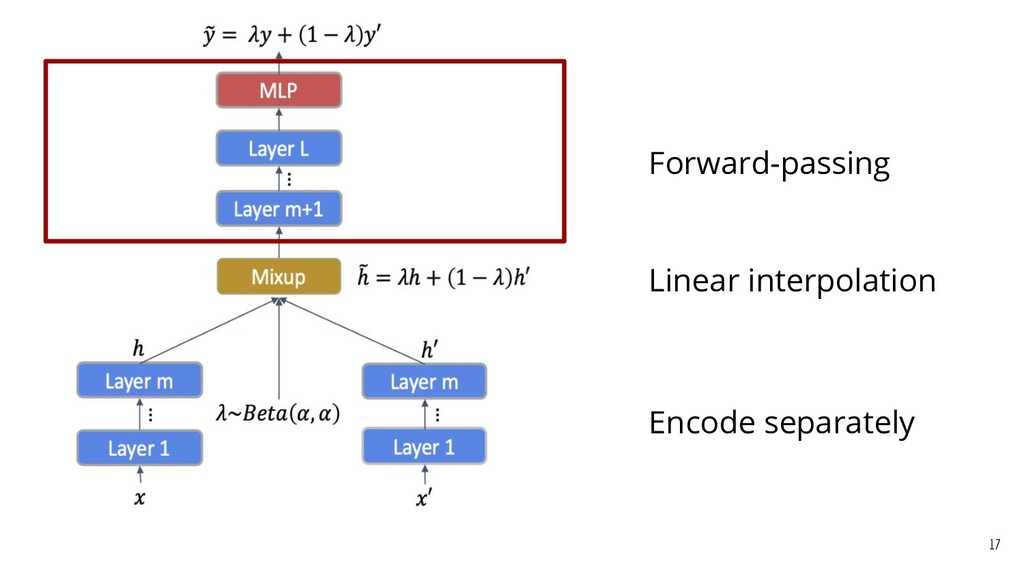
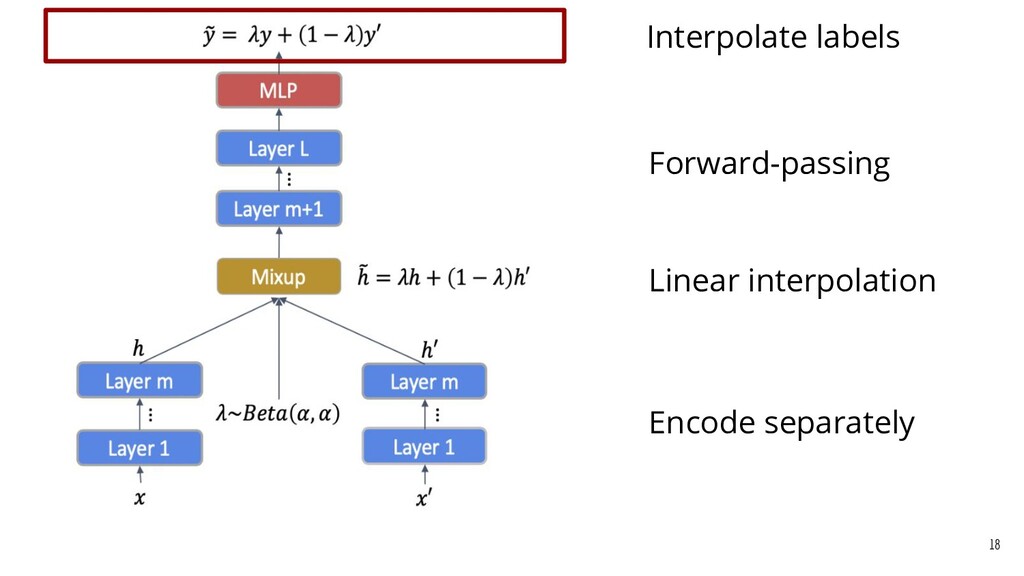
Text Mixup built on mixup in CV (Zhang et al.,
2017; Berthelot et al., 2019) 13 ✓ performs linear interpolations in textual hidden space between different training sentences ✓ allows information to share across different sentences and creates infinite augmented training samples -
14 x: sentence 1 x’: sentence 2 y: label 1
y’: label 2 Text Mixup -
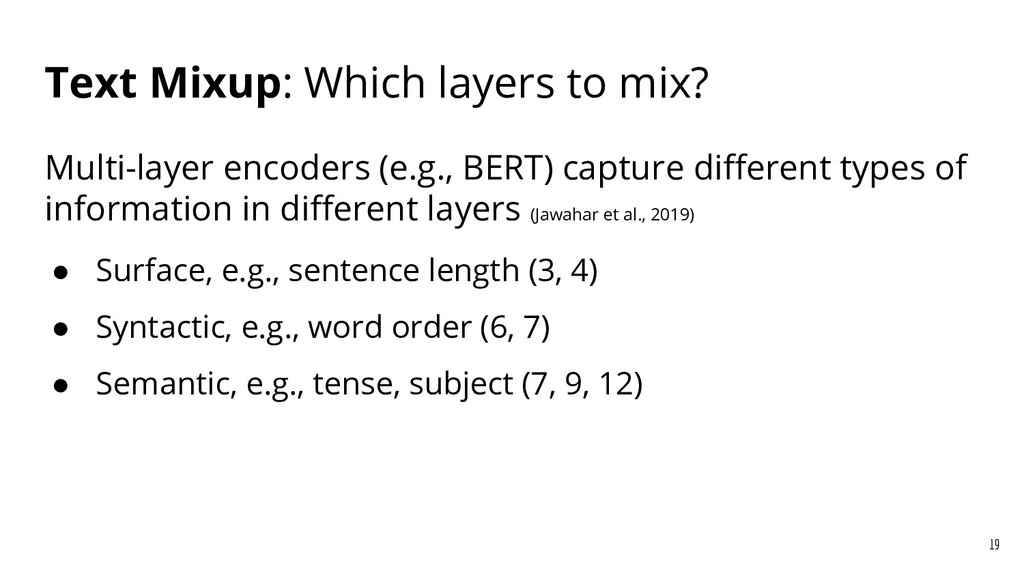
Text Mixup: Which layers to mix? Multi-layer encoders (e.g., BERT)
capture different types of information in different layers (Jawahar et al., 2019) • Surface, e.g., sentence length (3, 4) • Syntactic, e.g., word order (6, 7) • Semantic, e.g., tense, subject (7, 9, 12) 19 -
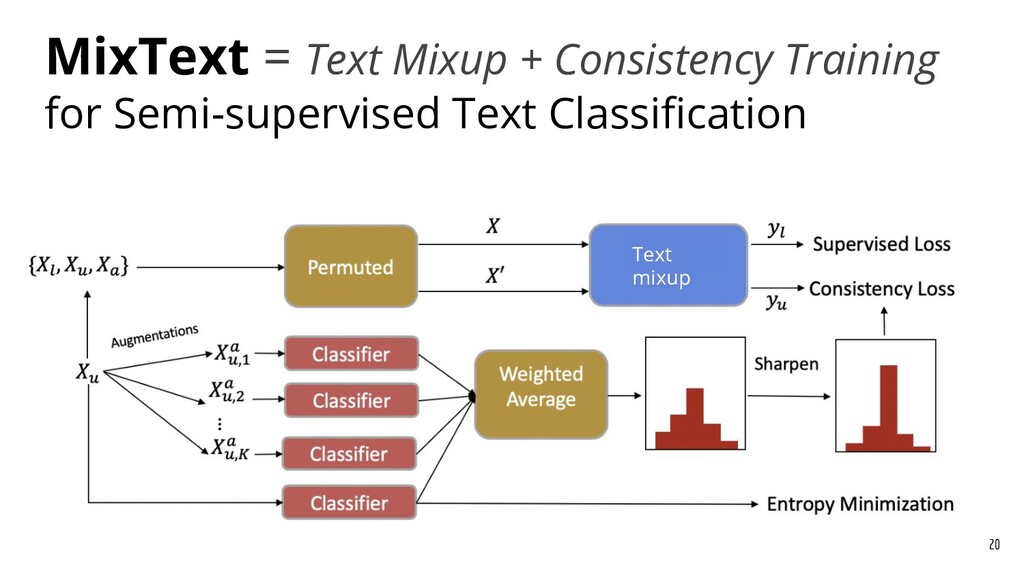
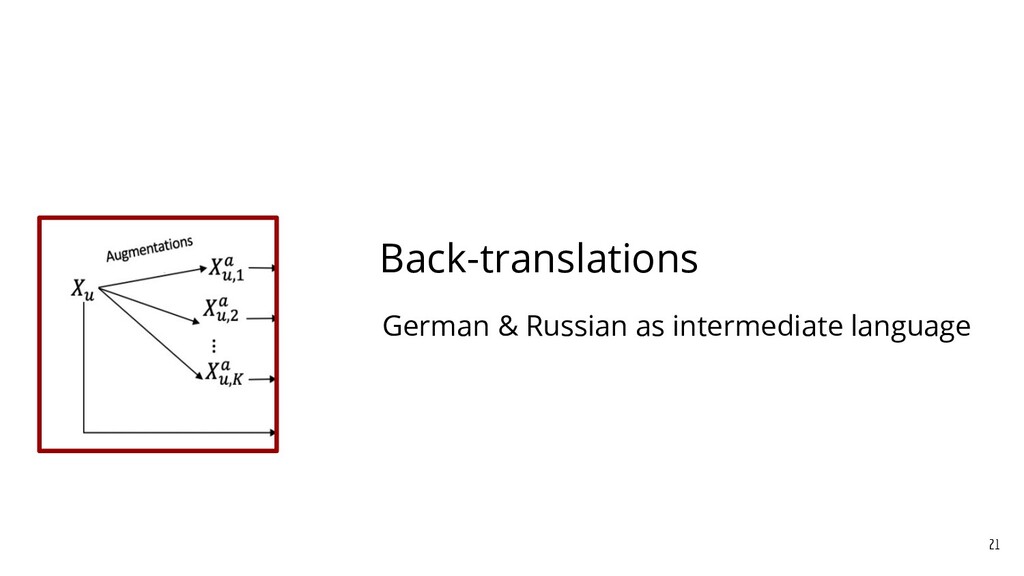
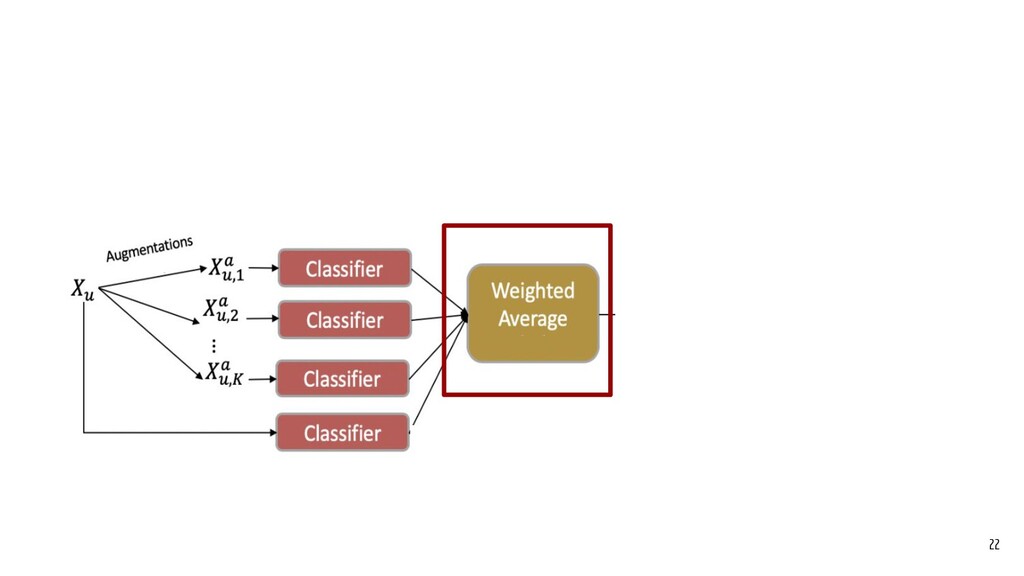
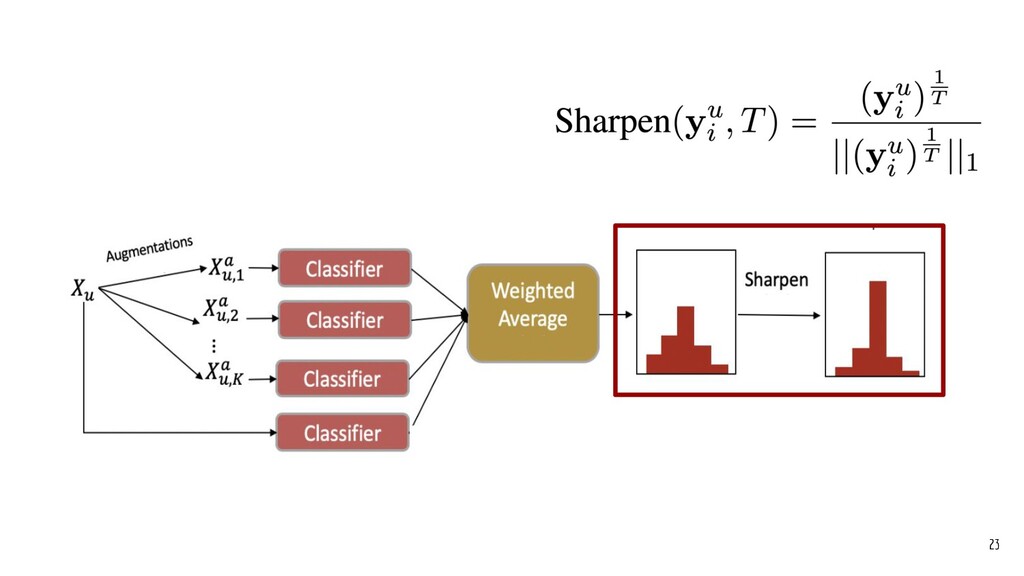
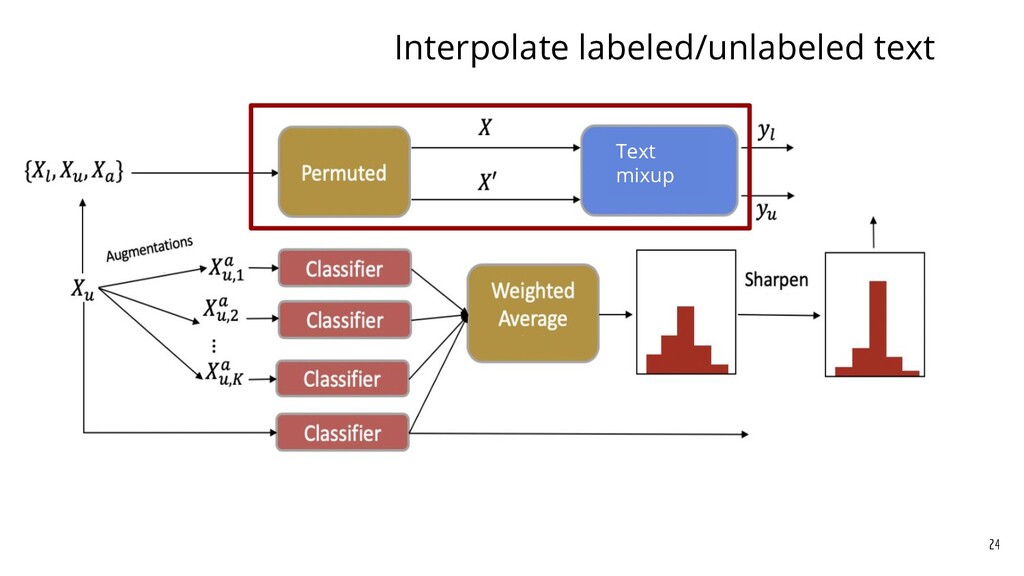
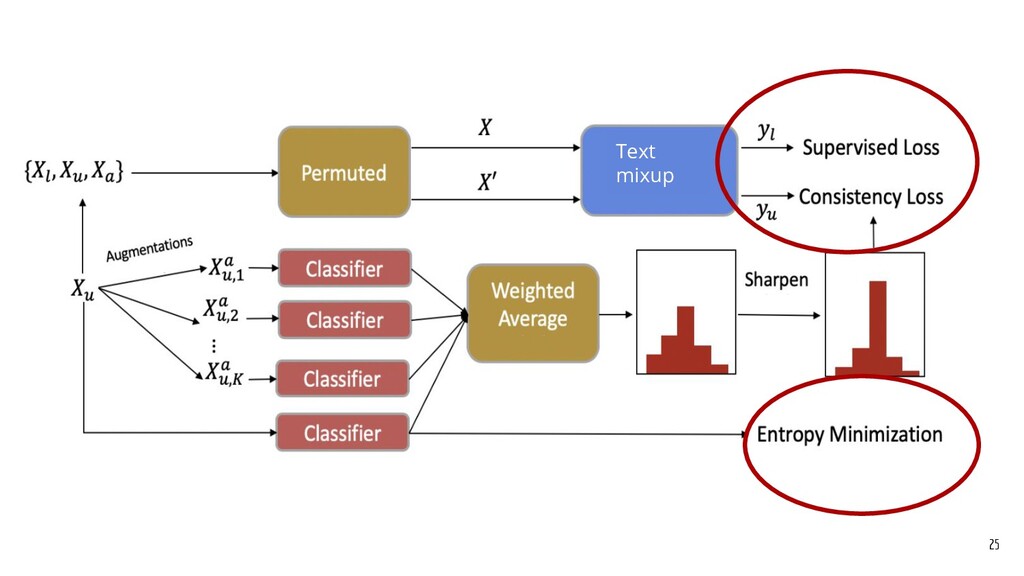
MixText = Text Mixup + Consistency Training for Semi-supervised Text
Classification 20 Text mixup -
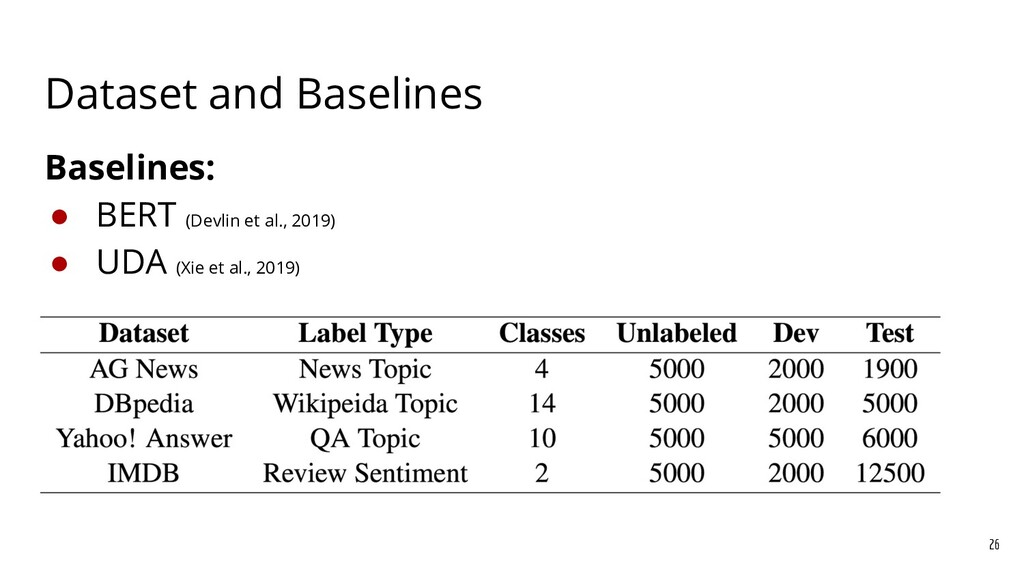
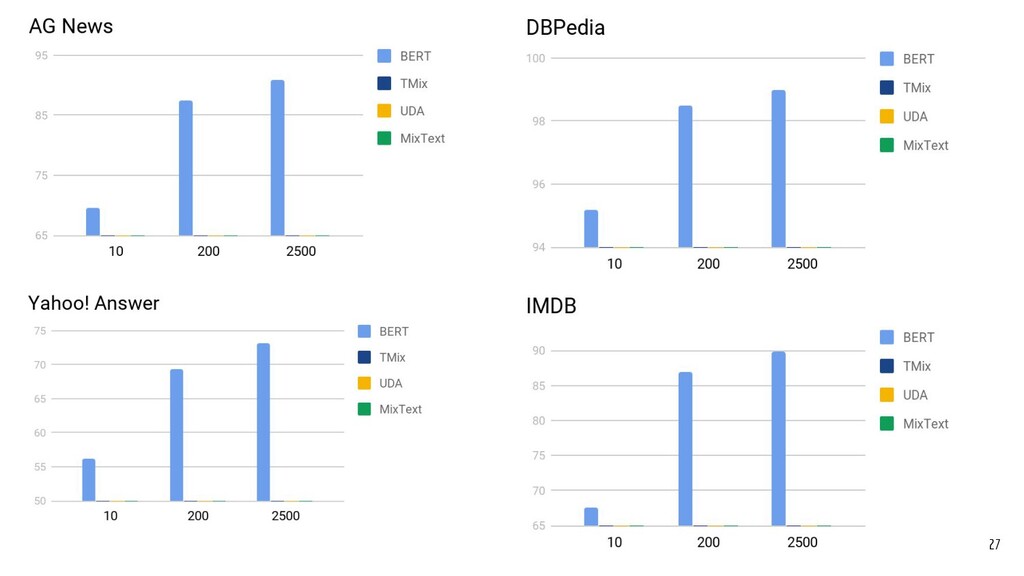
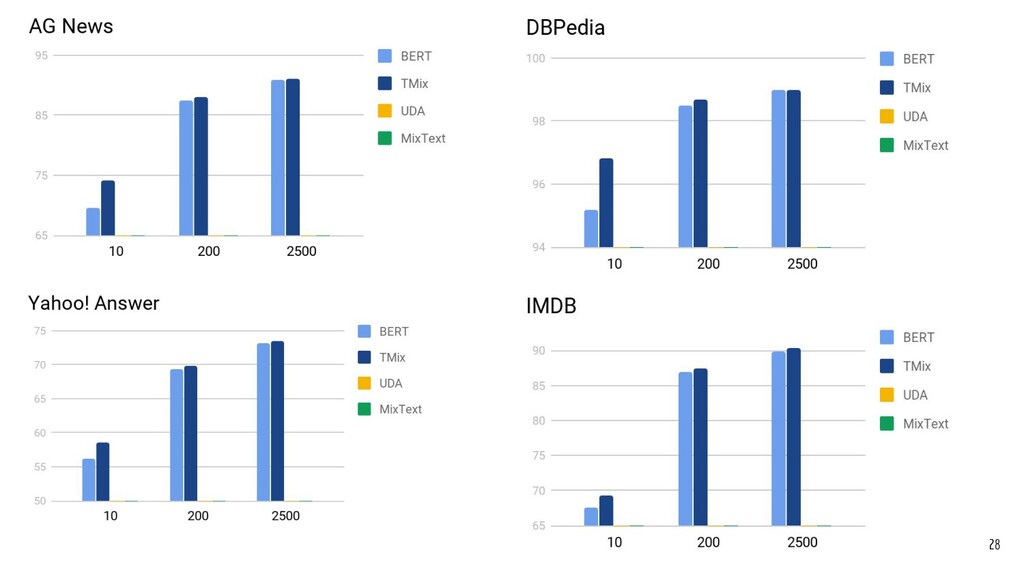
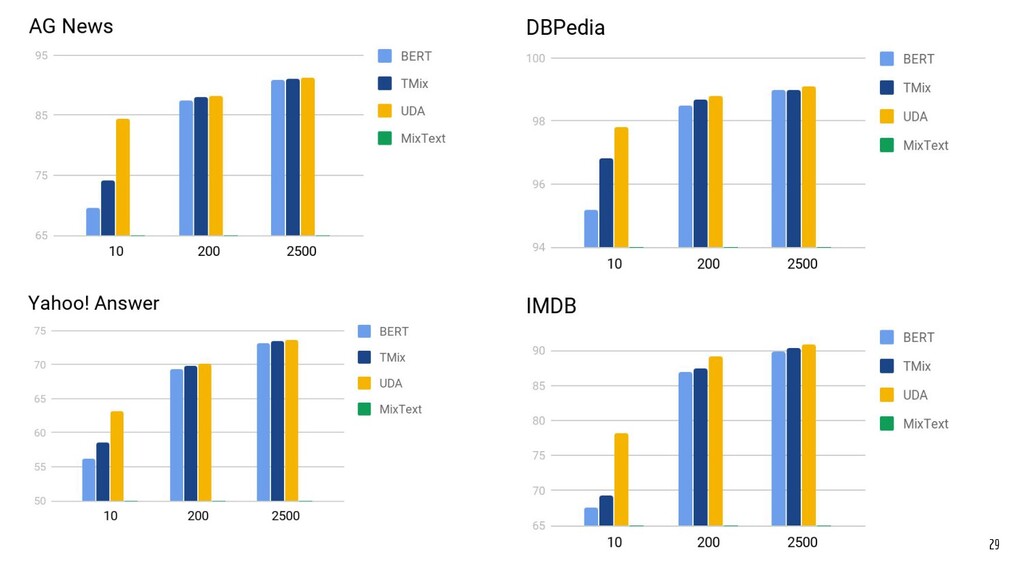
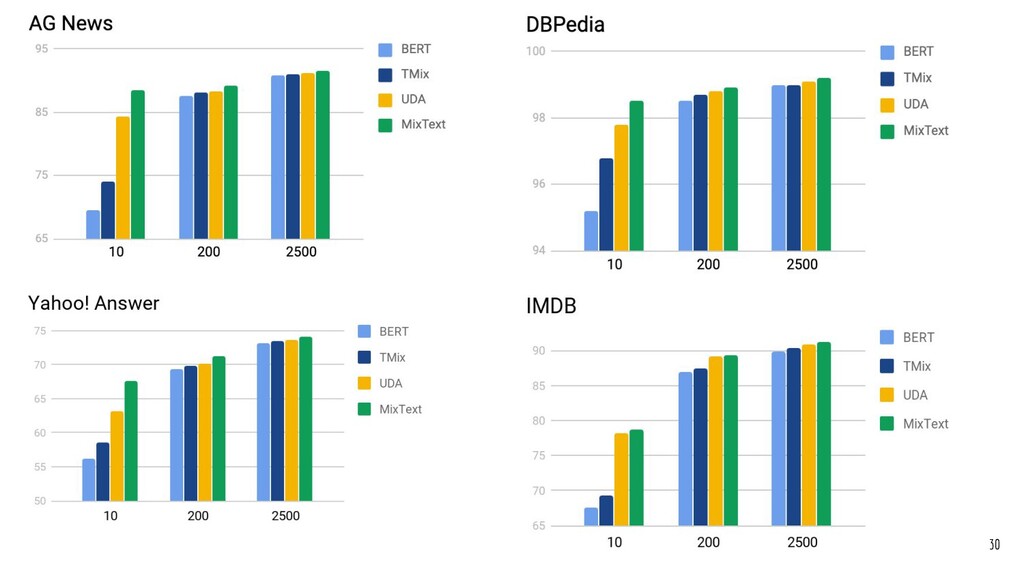
Dataset and Baselines Baselines: • BERT (Devlin et al., 2019)
• UDA (Xie et al., 2019) 26 -
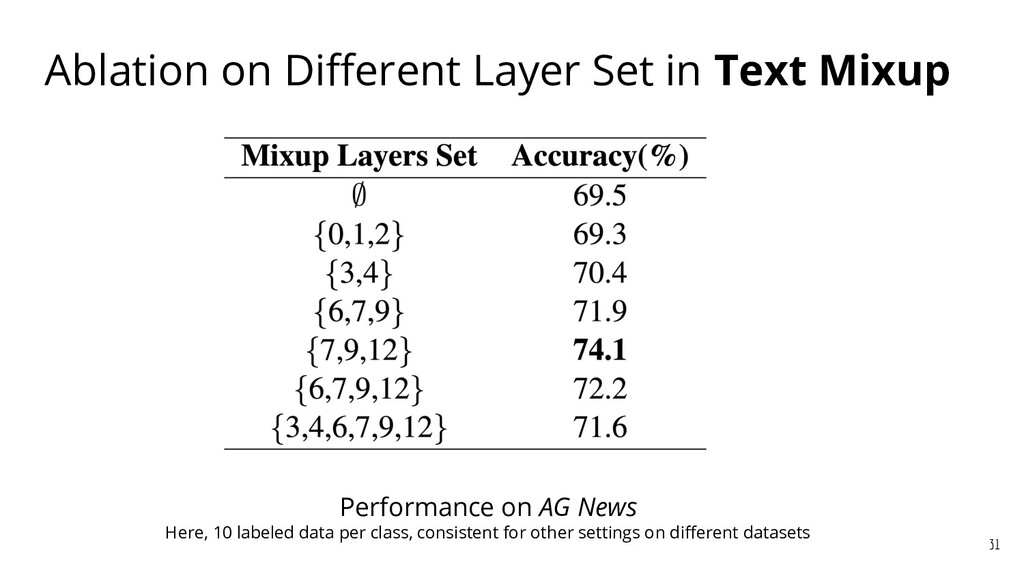
Ablation on Different Layer Set in Text Mixup Performance on
AG News Here, 10 labeled data per class, consistent for other settings on different datasets 31 -
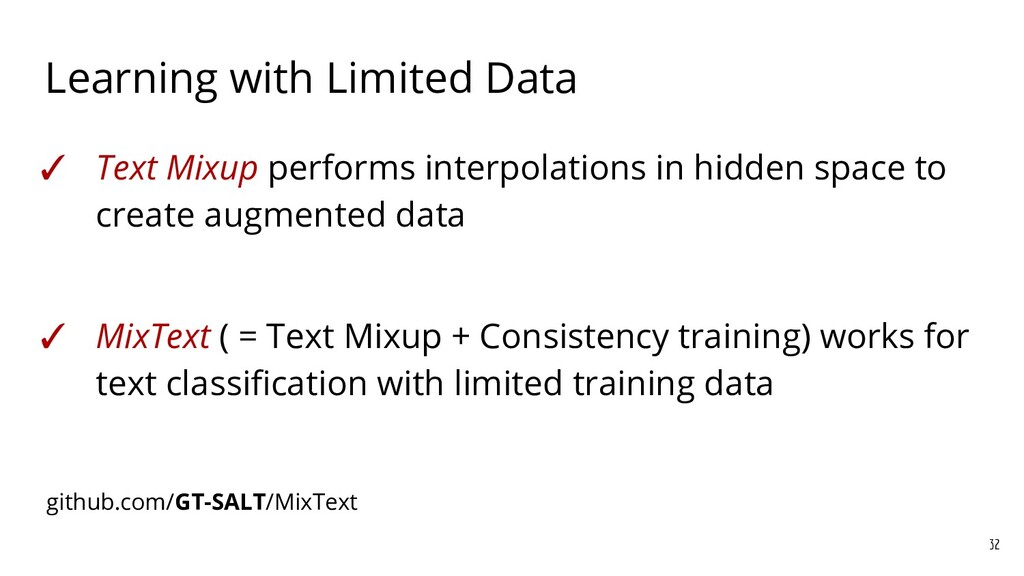
Learning with Limited Data ✓ Text Mixup performs interpolations in
hidden space to create augmented data ✓ MixText ( = Text Mixup + Consistency training) works for text classification with limited training data 32 github.com/GT-SALT/MixText -
Overview of This Talk 33 ➢ Low-resourced scenarios ✓ Text
Mixup for Semi-supervised Classification ➢ LADA for Named Entity Recognition Local Additivity Based Data Augmentation for Semi-supervised NER. Jiaao Chen*, Zhenghui Wang*, Ran Tian, Zichao Yang and Diyi Yang. EMNLP, 2020. -
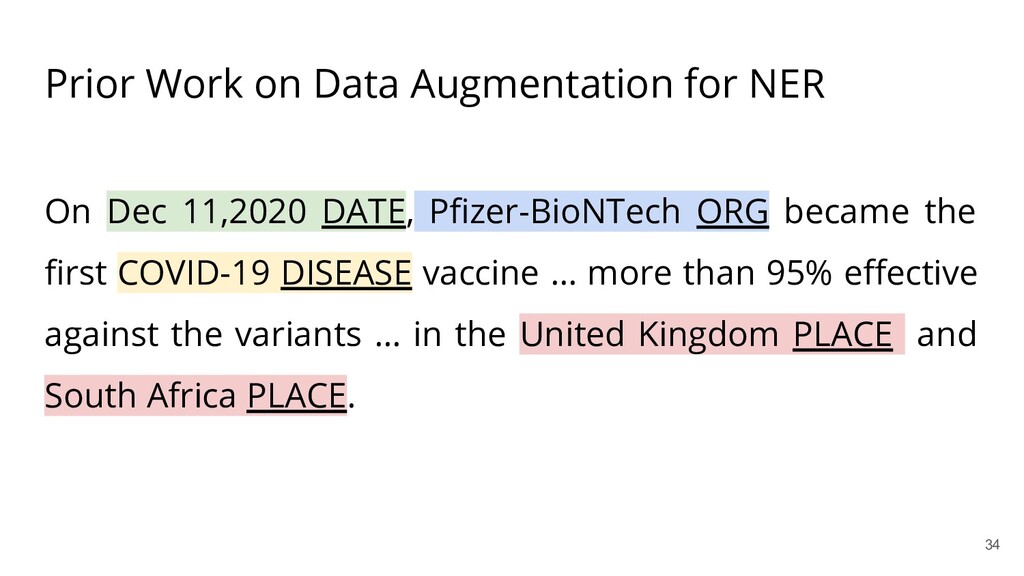
Prior Work on Data Augmentation for NER 34 On Dec
11,2020 DATE, Pfizer-BioNTech ORG became the first COVID-19 DISEASE vaccine … more than 95% effective against the variants ... in the United Kingdom PLACE and South Africa PLACE. -
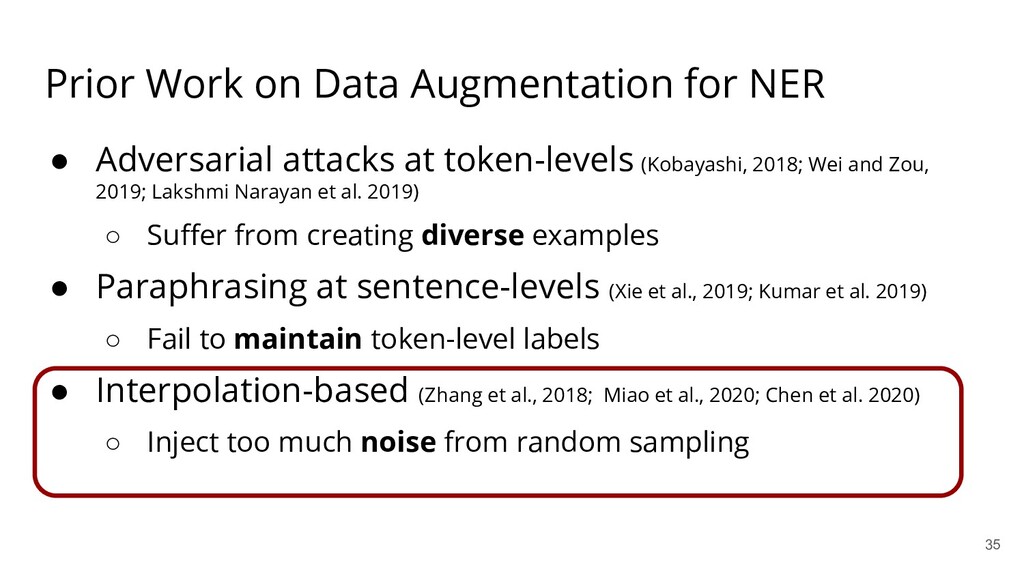
Prior Work on Data Augmentation for NER • Adversarial attacks
at token-levels (Kobayashi, 2018; Wei and Zou, 2019; Lakshmi Narayan et al. 2019) ◦ Suffer from creating diverse examples • Paraphrasing at sentence-levels (Xie et al., 2019; Kumar et al. 2019) ◦ Fail to maintain token-level labels • Interpolation-based (Zhang et al., 2018; Miao et al., 2020; Chen et al. 2020) ◦ Inject too much noise from random sampling 35 -
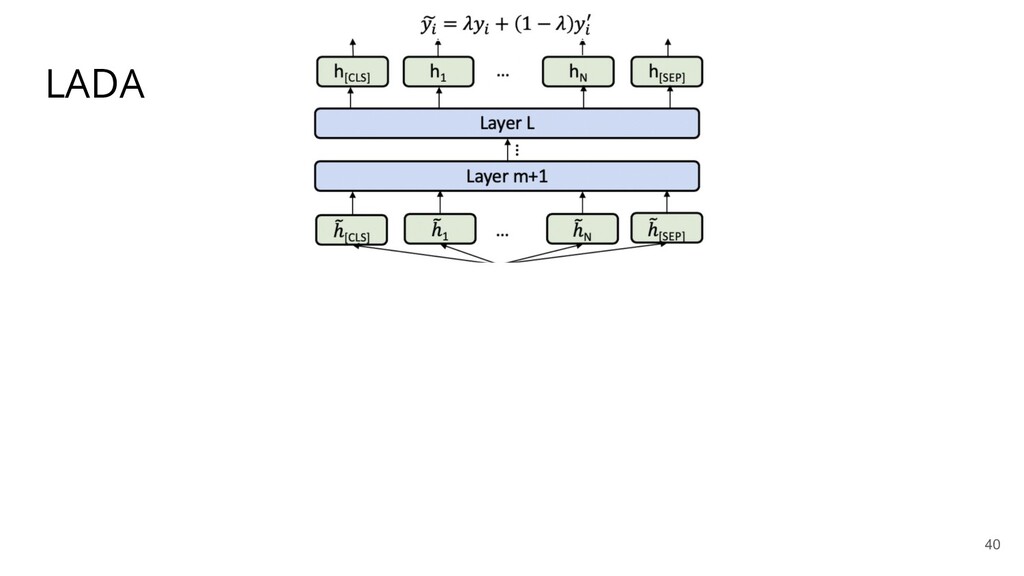
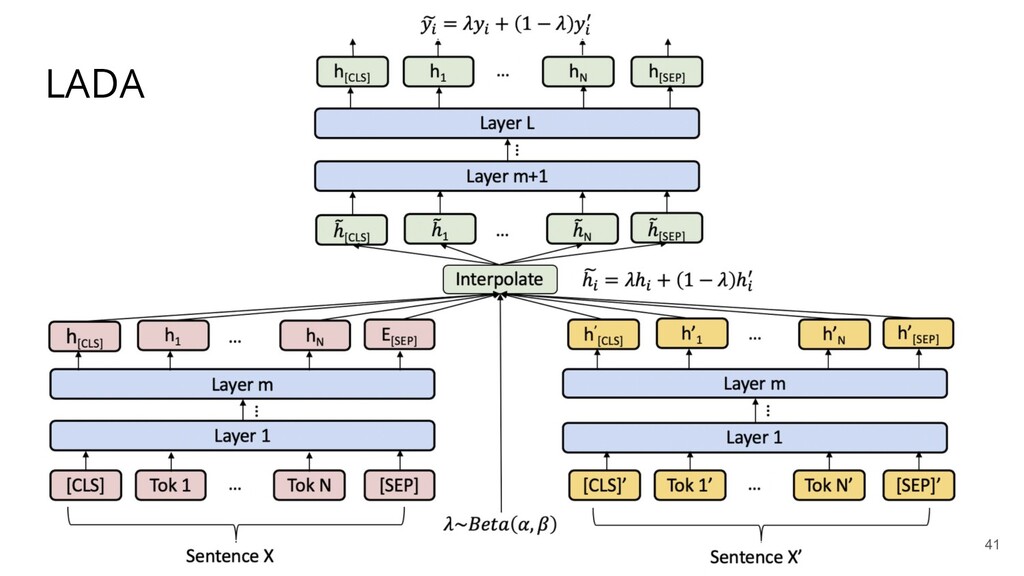
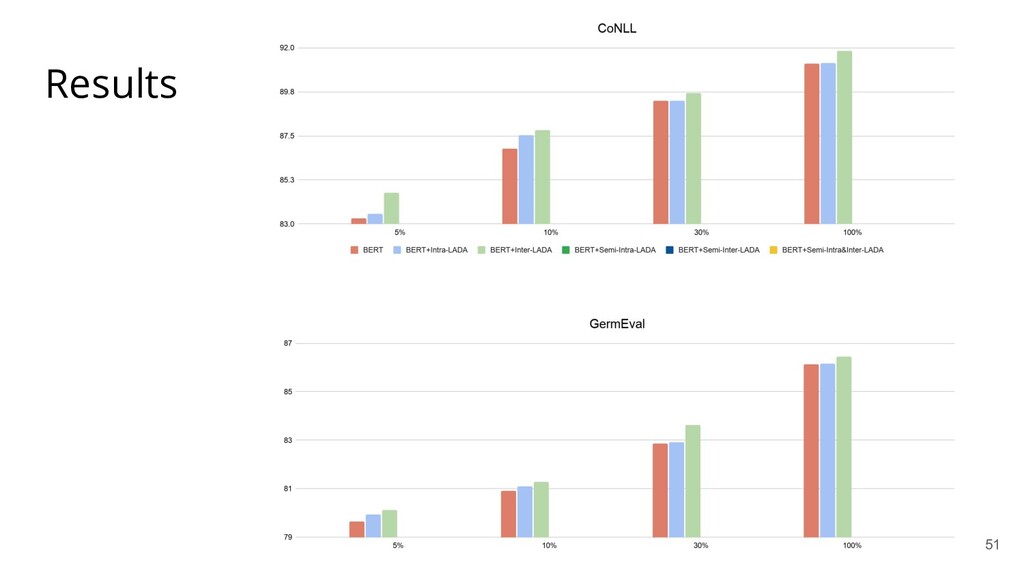
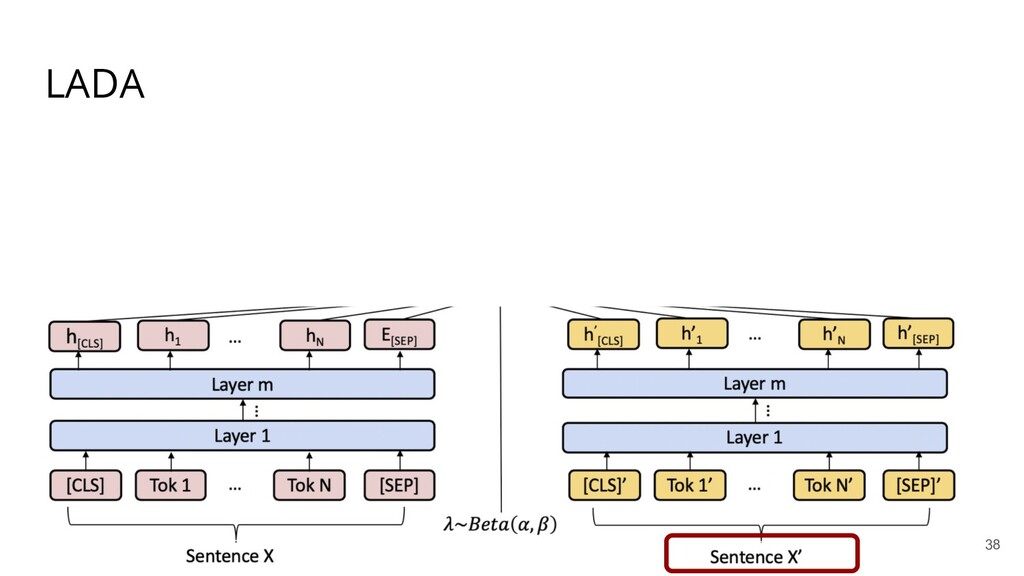
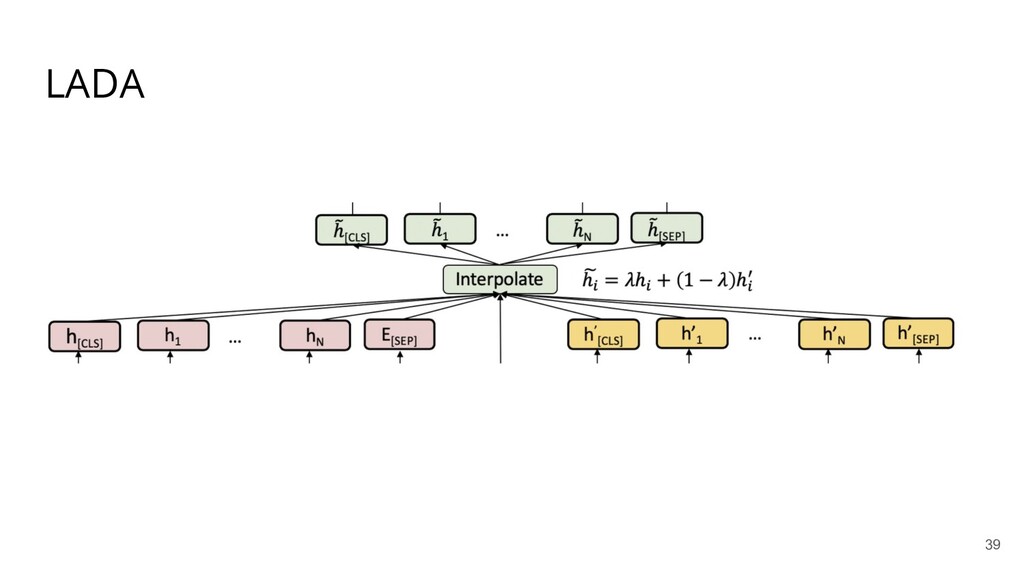
Local Additivity based Data Augmentation (LADA) What if directly using
Mixup for NER? Didn’t work Strategic LADA to help: Intra-LADA and Inter-LADA 42 -
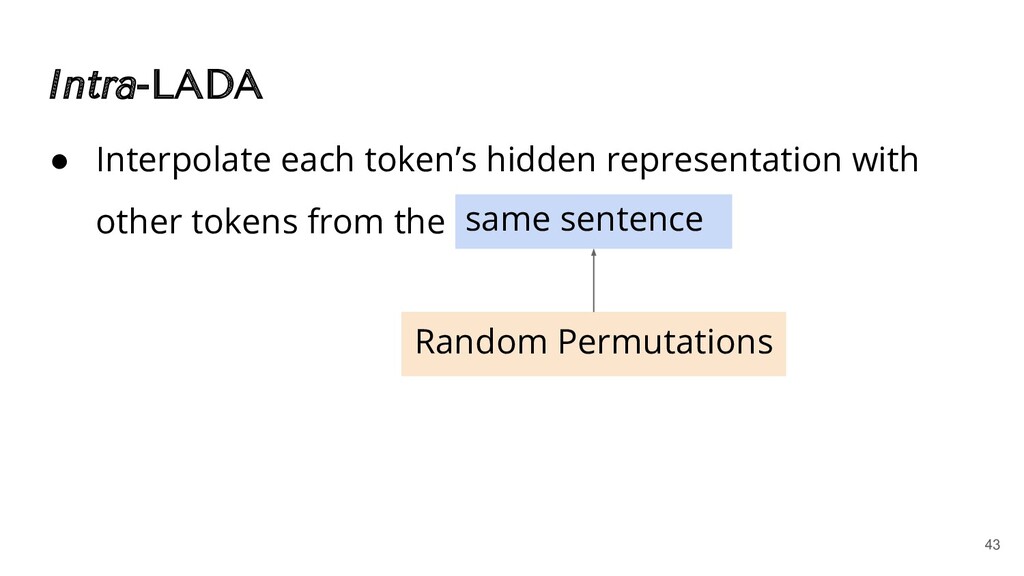
Intra-LADA • Interpolate each token’s hidden representation with other tokens
from the 43 same sentence Random Permutations -
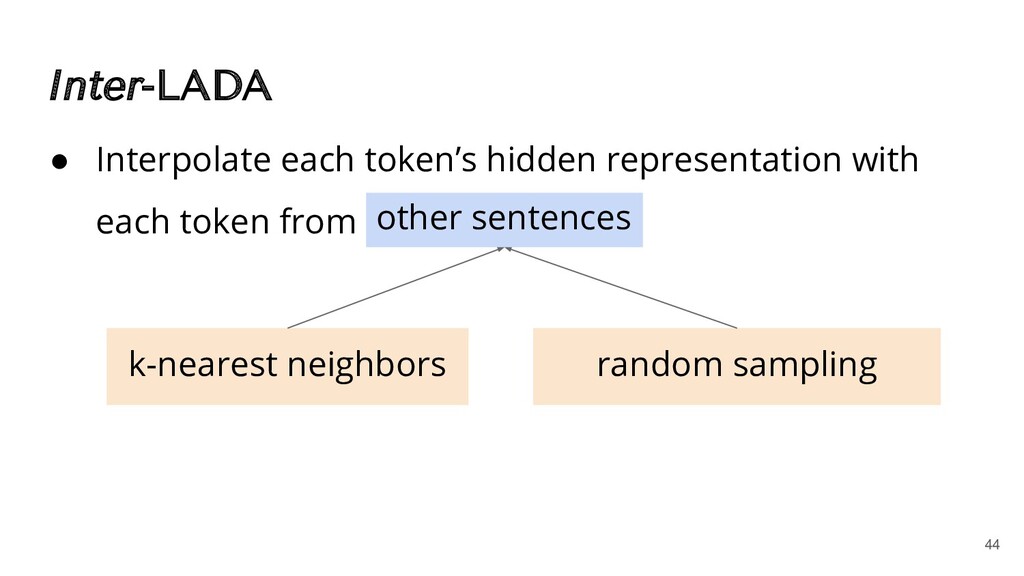
Inter-LADA • Interpolate each token’s hidden representation with each token
from random sampling k-nearest neighbors 44 other sentences -
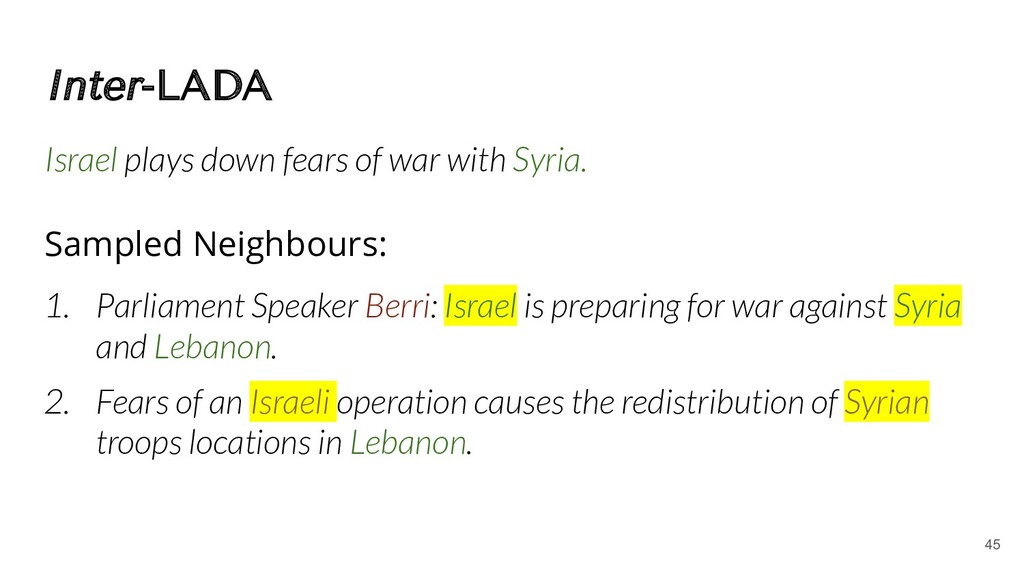
Inter-LADA 45 Israel plays down fears of war with Syria.
Sampled Neighbours: 1. Parliament Speaker Berri: Israel is preparing for war against Syria and Lebanon. 2. Fears of an Israeli operation causes the redistribution of Syrian troops locations in Lebanon. -
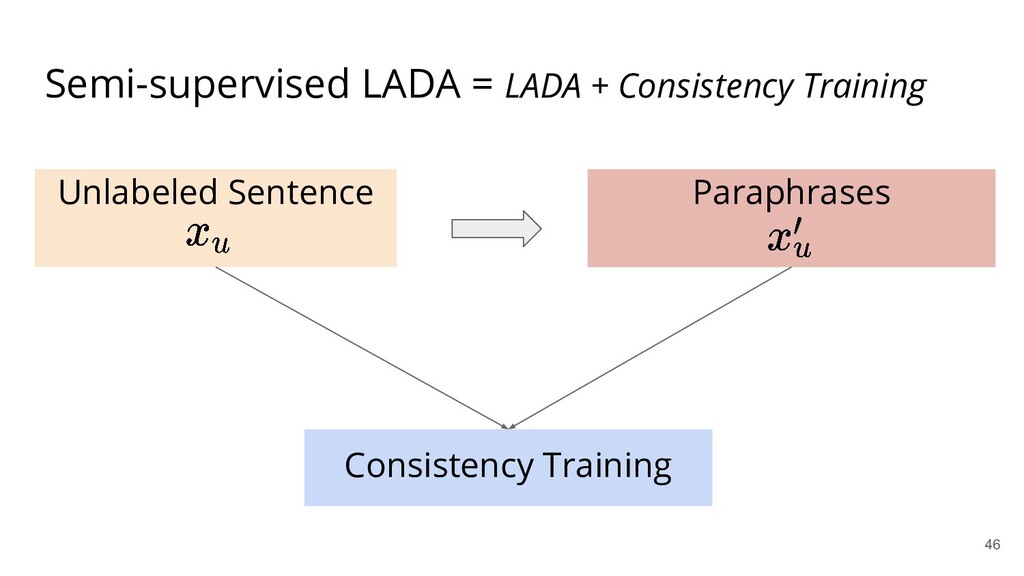
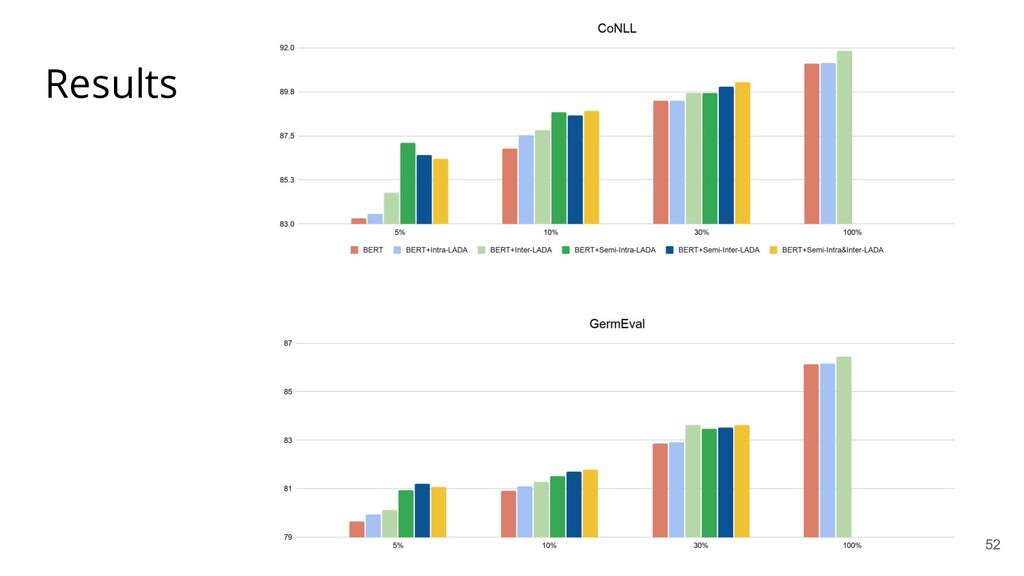
Semi-supervised LADA = LADA + Consistency Training 46 Paraphrases Unlabeled
Sentence Consistency Training -
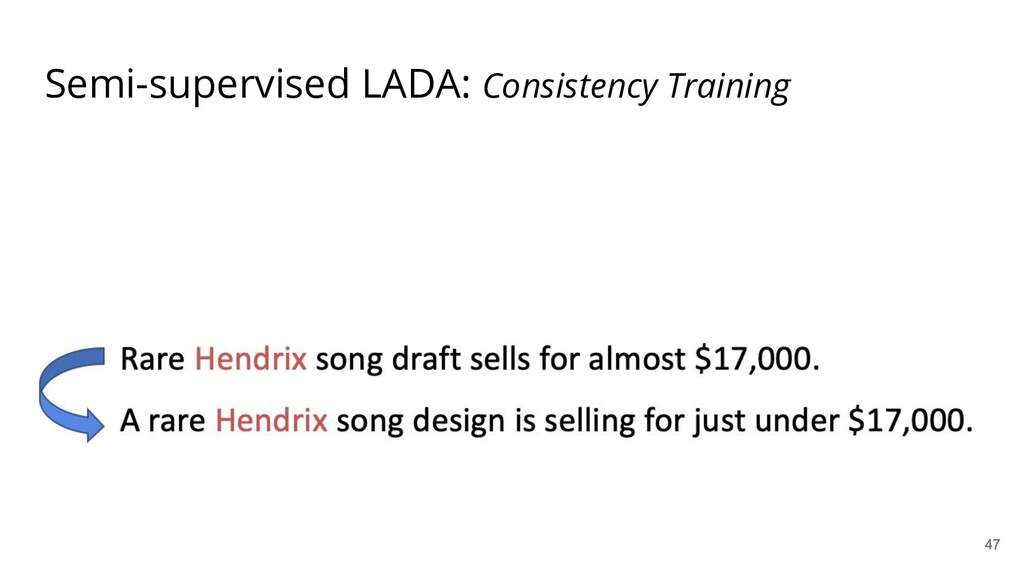
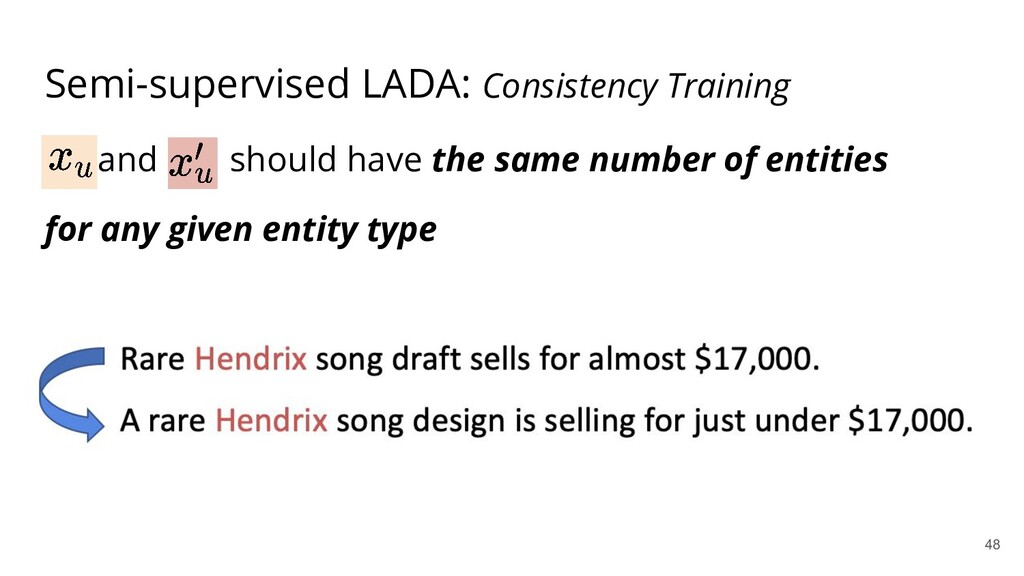
Semi-supervised LADA: Consistency Training 48 and should have the same
number of entities for any given entity type -
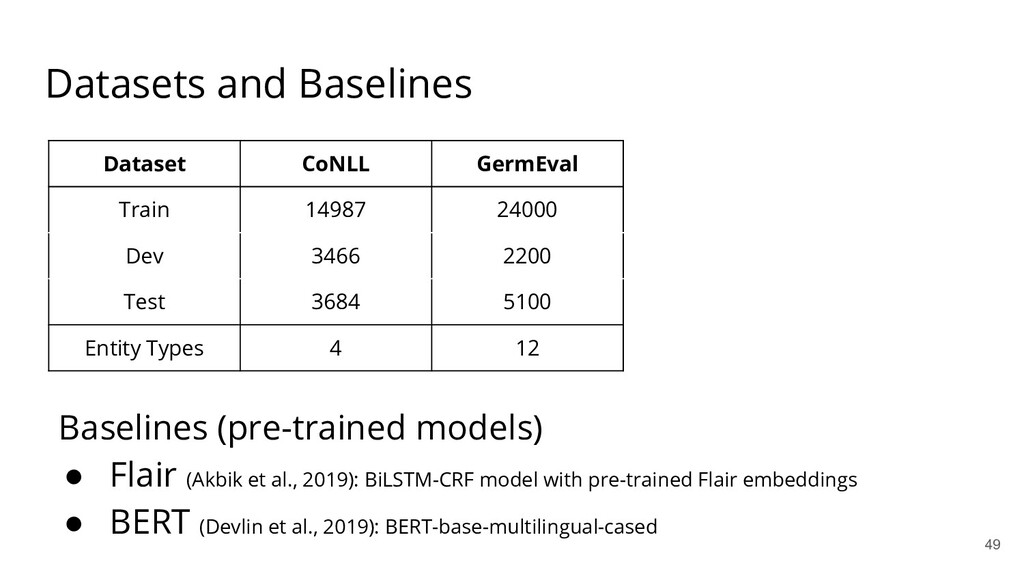
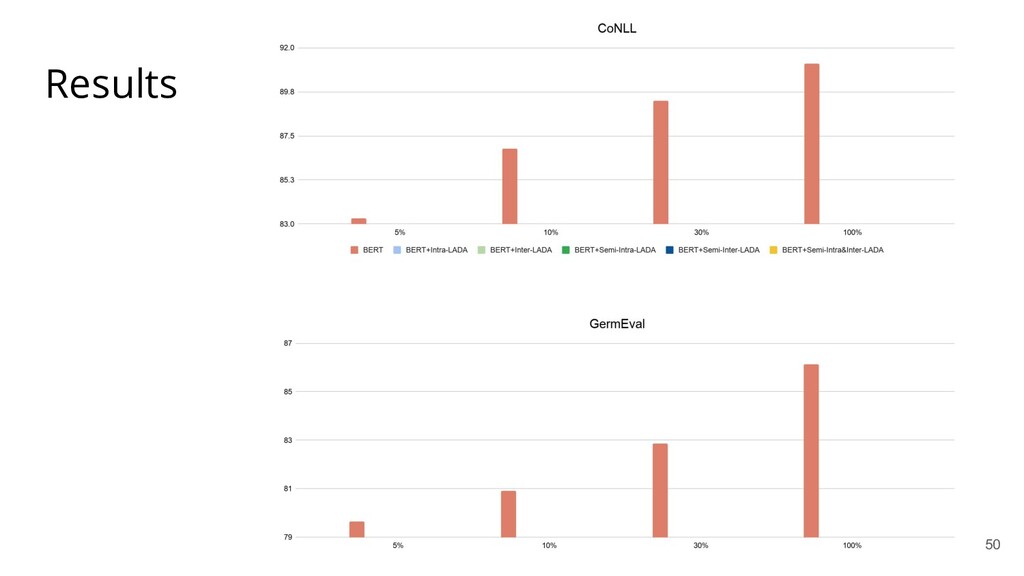
Datasets and Baselines 49 Baselines (pre-trained models) • Flair (Akbik
et al., 2019): BiLSTM-CRF model with pre-trained Flair embeddings • BERT (Devlin et al., 2019): BERT-base-multilingual-cased Dataset CoNLL GermEval Train 14987 24000 Dev 3466 2200 Test 3684 5100 Entity Types 4 12 -
Takeaways • LADA performs interpolations in hidden space among close
examples to generate augmented data • The sampling strategies of mixup for sequence learning are important • Semi-LADA designed for NER improves performances with limited training data 53 https://github.com/GT-SALT/LADA -
Overview of This Talk 54 ✓ Low-resourced scenarios ✓ Text
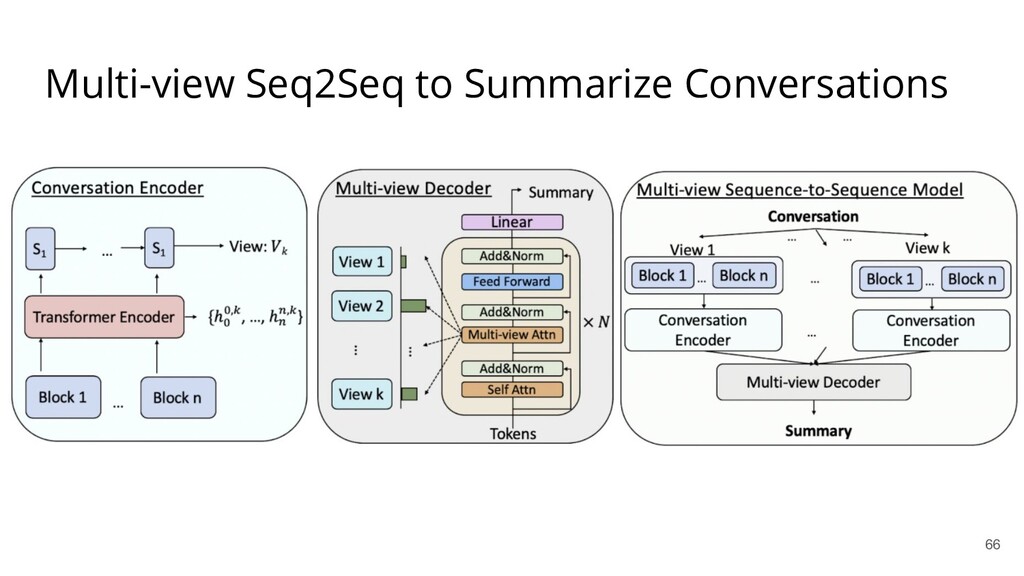
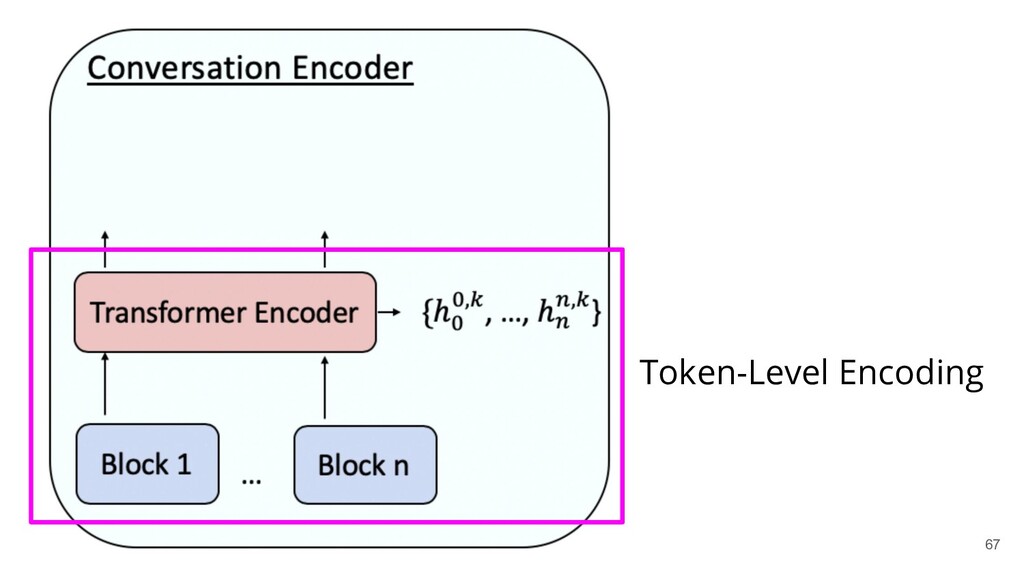
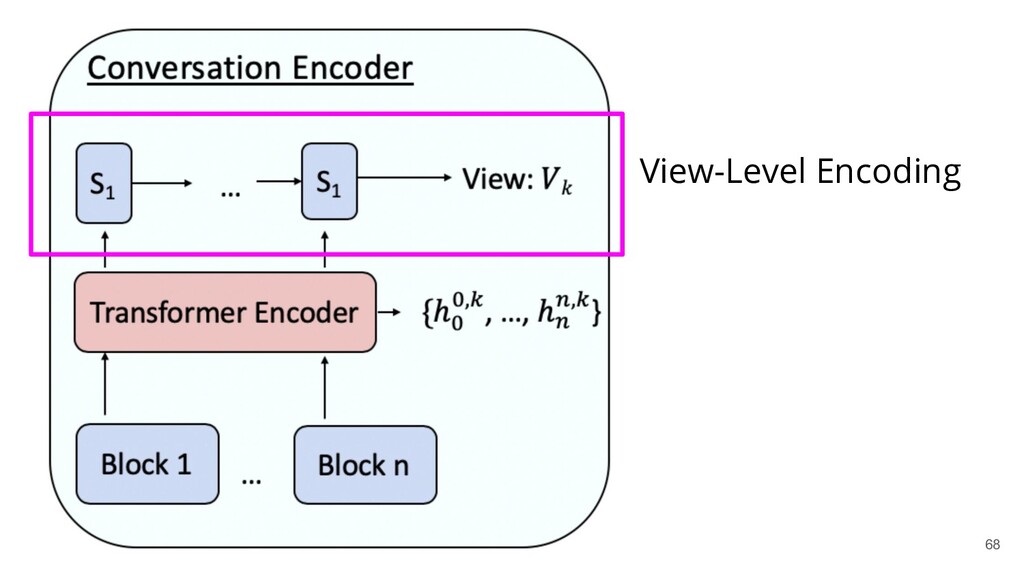
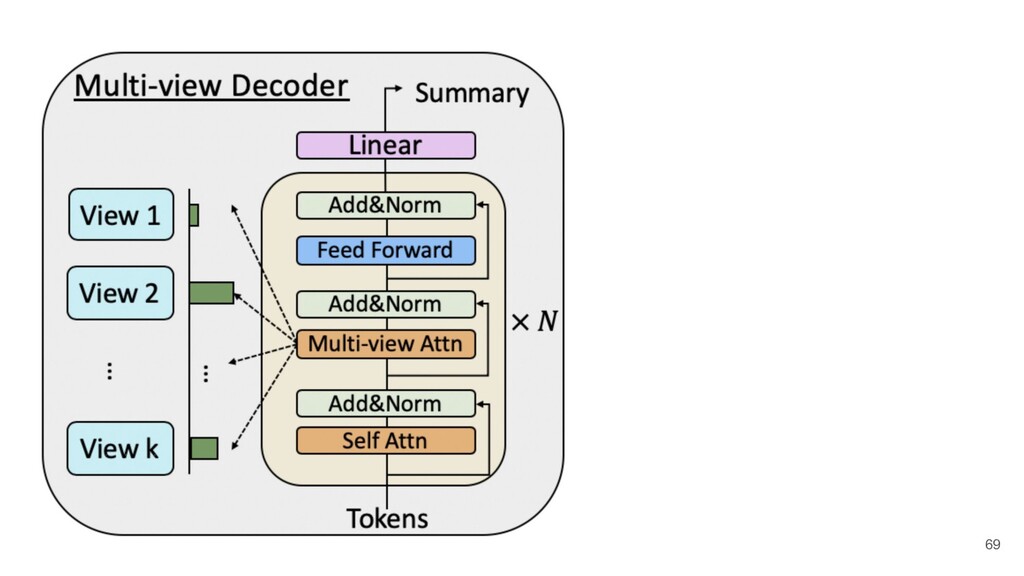
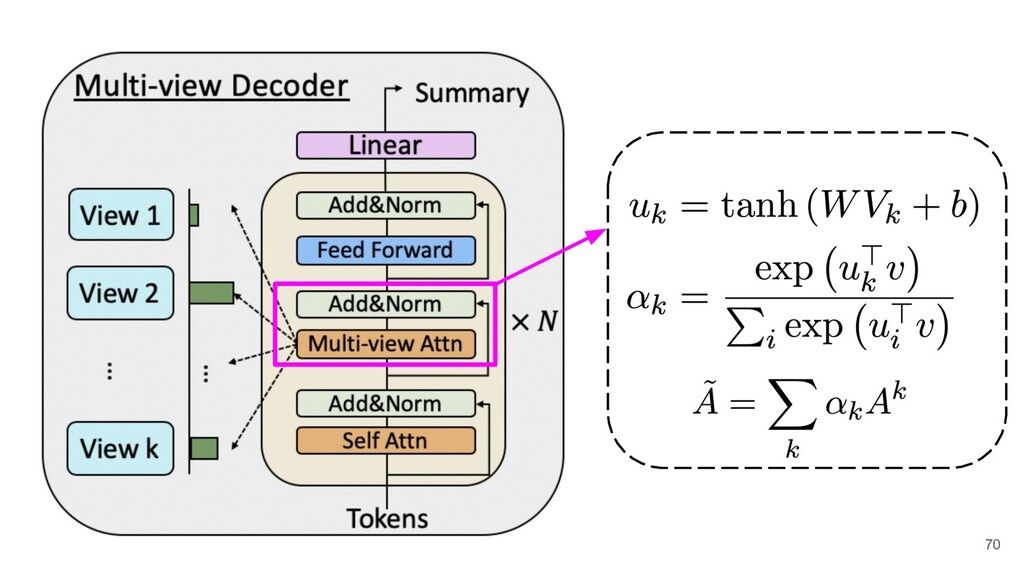
Mixup for Semi-supervised Classification ✓ LADA for Named Entity Recognition ➢ Structured knowledge from social interaction ➢ Summarization via Conversation Structures Jiaao Chen, Diyi Yang. Multi-View Sequence-to-Sequence Models with Conversational Structure for Abstractive Dialogue Summarization. EMNLP 2020 -
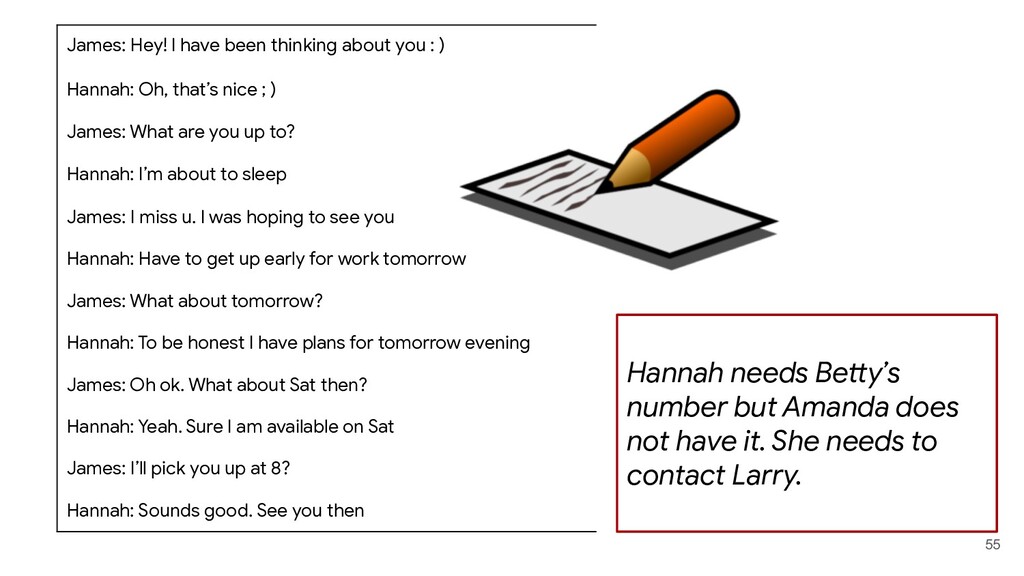
55 Hannah needs Betty’s number but Amanda does not have
it. She needs to contact Larry. James: Hey! I have been thinking about you : ) Hannah: Oh, that’s nice ; ) James: What are you up to? Hannah: I’m about to sleep James: I miss u. I was hoping to see you Hannah: Have to get up early for work tomorrow James: What about tomorrow? Hannah: To be honest I have plans for tomorrow evening James: Oh ok. What about Sat then? Hannah: Yeah. Sure I am available on Sat James: I’ll pick you up at 8? Hannah: Sounds good. See you then -
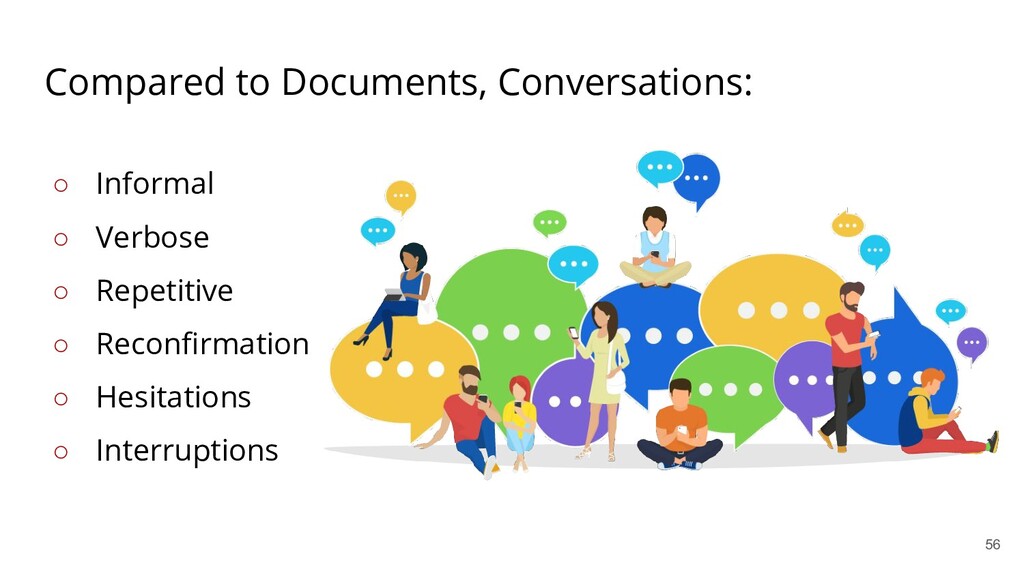
Compared to Documents, Conversations: ◦ Informal ◦ Verbose ◦ Repetitive
◦ Reconfirmation ◦ Hesitations ◦ Interruptions 56 -
Classical Views for Conversations 1. Global view treats conversation as
a whole 2. Discrete view treats it as multiple utterances 57 -
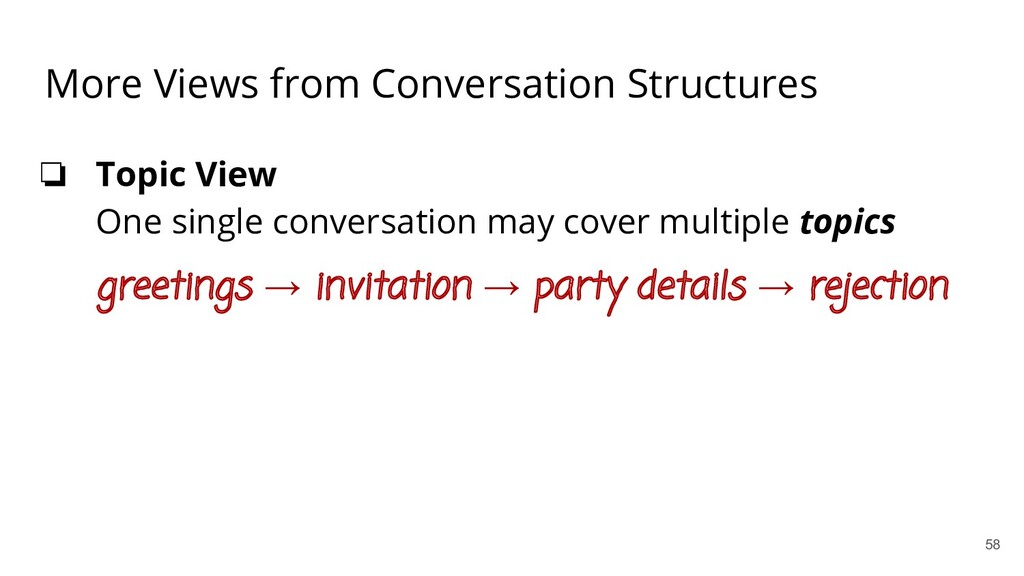
More Views from Conversation Structures ❏ Topic View One single
conversation may cover multiple topics greetings → invitation → party details → rejection 58 -
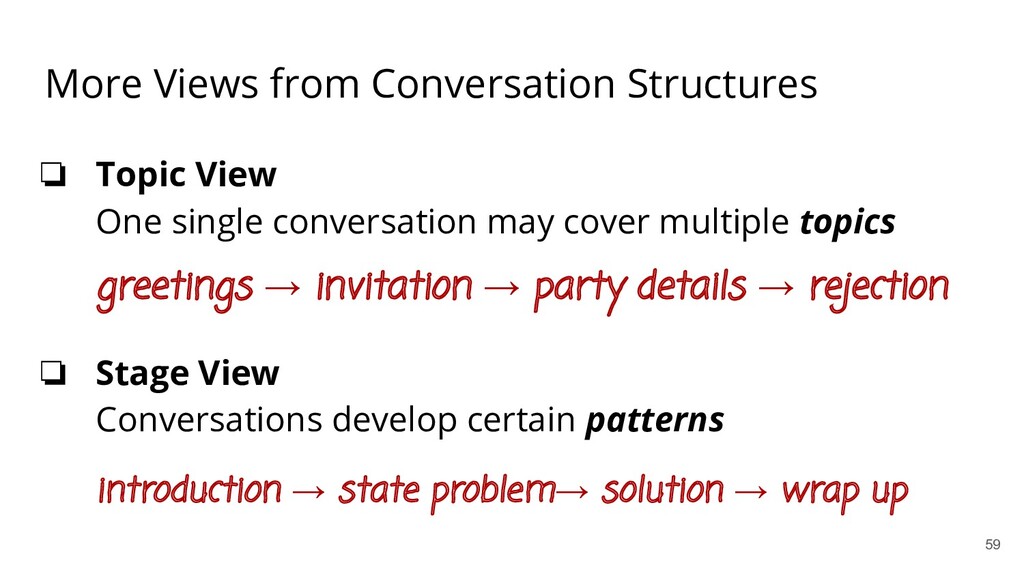
More Views from Conversation Structures ❏ Topic View One single
conversation may cover multiple topics greetings → invitation → party details → rejection ❏ Stage View Conversations develop certain patterns introduction → state problem→ solution → wrap up 59 -
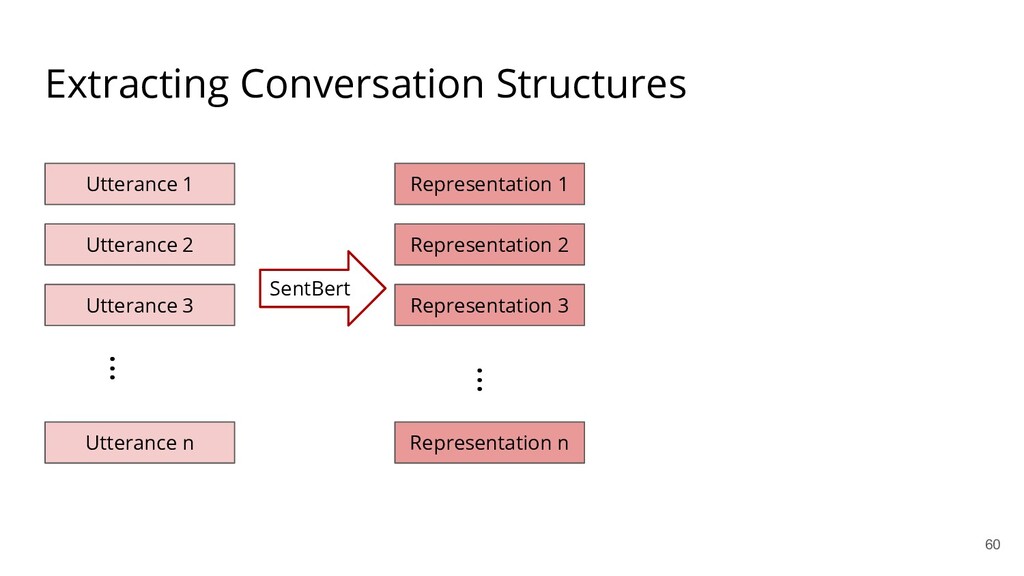
Extracting Conversation Structures Utterance 1 Utterance 2 ... Utterance n
Utterance 3 SentBert Representation 1 Representation 2 ... Representation n Representation 3 60 -
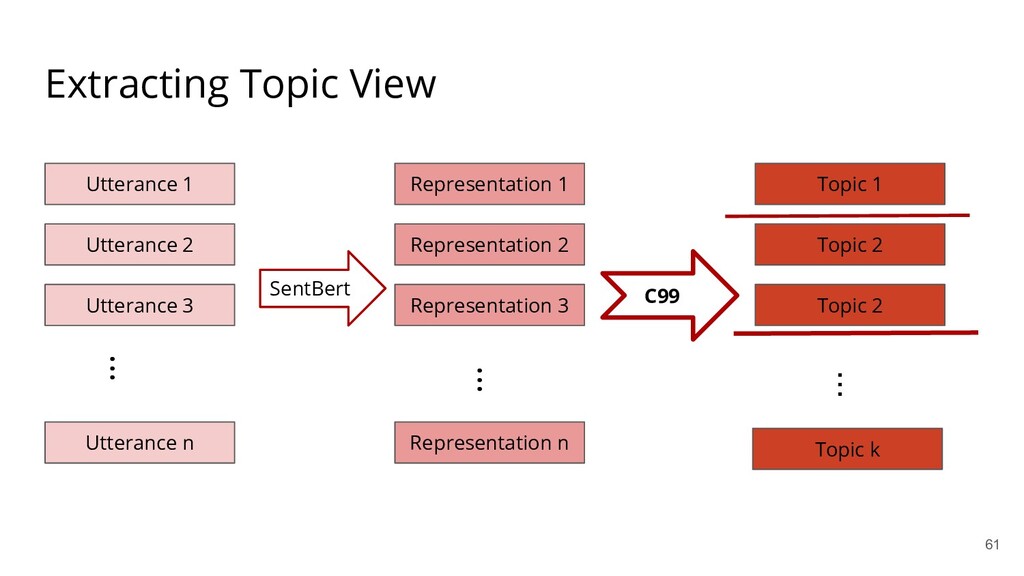
Extracting Topic View Utterance 1 Utterance 2 ... Utterance n
Utterance 3 SentBert Representation 1 Representation 2 ... Representation n Representation 3 61 Topic 1 Topic 2 Topic k ... Topic 2 C99 -
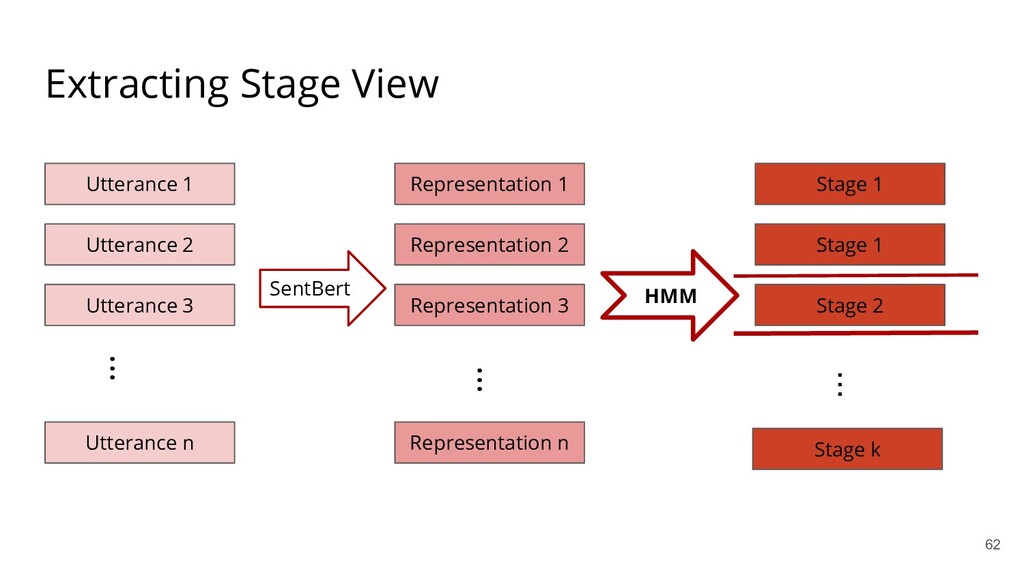
Extracting Stage View Utterance 1 Utterance 2 ... Utterance n
Utterance 3 SentBert Representation 1 Representation 2 ... Representation n Representation 3 62 Stage 1 Stage 1 Stage k ... Stage 2 HMM -
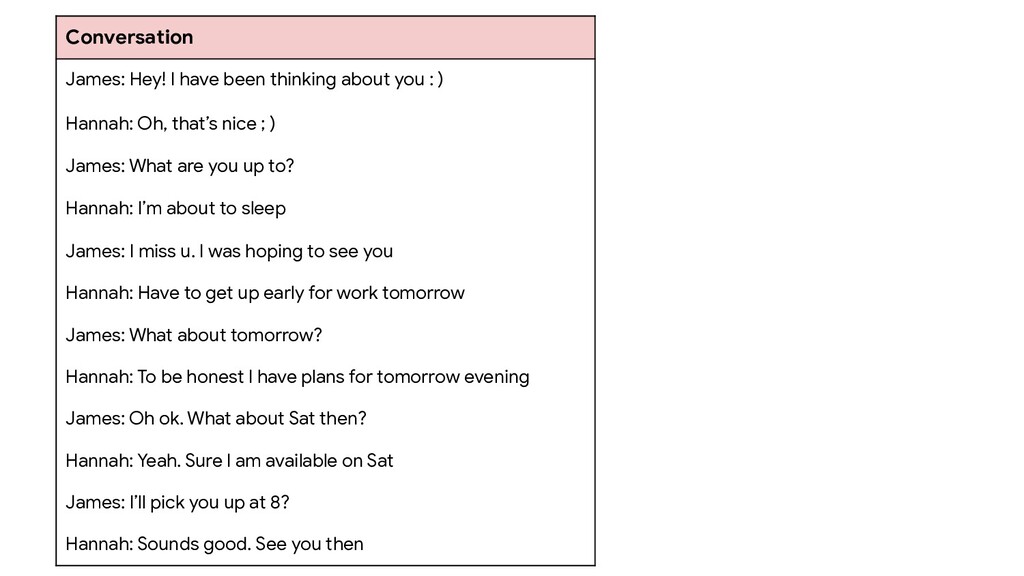
Conversation James: Hey! I have been thinking about you :
) Hannah: Oh, that’s nice ; ) James: What are you up to? Hannah: I’m about to sleep James: I miss u. I was hoping to see you Hannah: Have to get up early for work tomorrow James: What about tomorrow? Hannah: To be honest I have plans for tomorrow evening James: Oh ok. What about Sat then? Hannah: Yeah. Sure I am available on Sat James: I’ll pick you up at 8? Hannah: Sounds good. See you then -
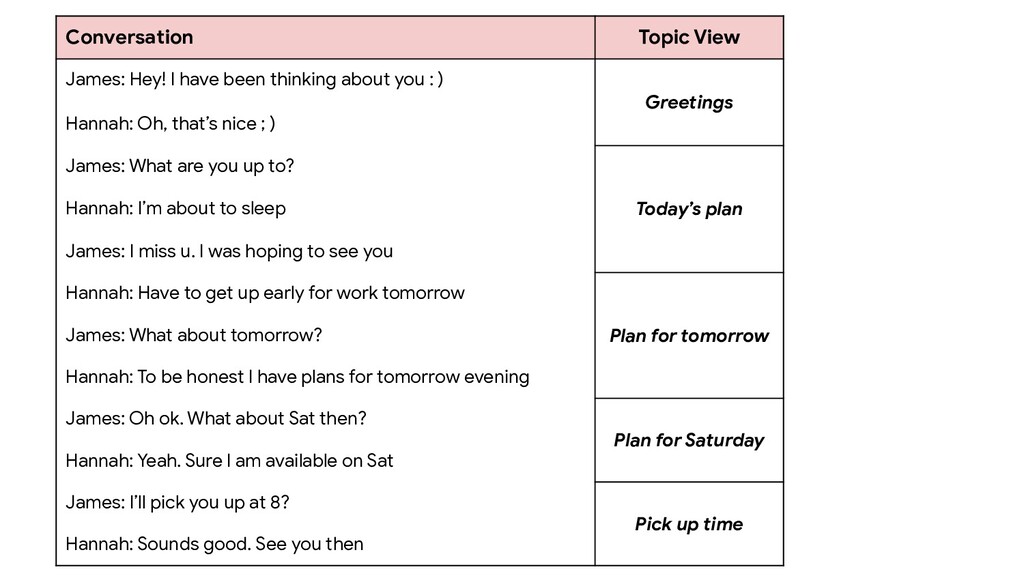
Conversation Topic View James: Hey! I have been thinking about
you : ) Greetings Hannah: Oh, that’s nice ; ) James: What are you up to? Today’s plan Hannah: I’m about to sleep James: I miss u. I was hoping to see you Hannah: Have to get up early for work tomorrow Plan for tomorrow James: What about tomorrow? Hannah: To be honest I have plans for tomorrow evening James: Oh ok. What about Sat then? Plan for Saturday Hannah: Yeah. Sure I am available on Sat James: I’ll pick you up at 8? Pick up time Hannah: Sounds good. See you then -
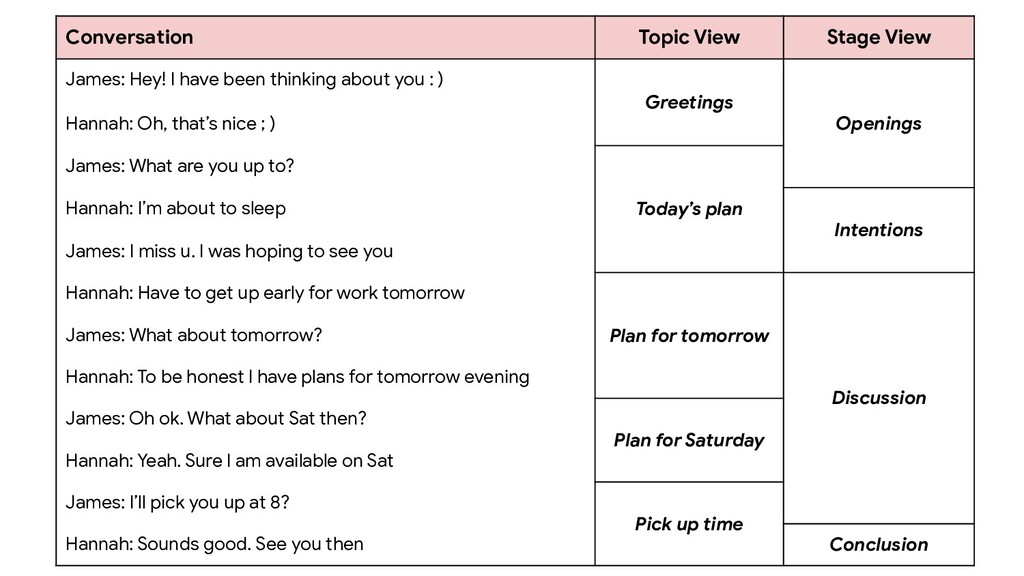
Conversation Topic View Stage View James: Hey! I have been
thinking about you : ) Greetings Openings Hannah: Oh, that’s nice ; ) James: What are you up to? Today’s plan Hannah: I’m about to sleep Intentions James: I miss u. I was hoping to see you Hannah: Have to get up early for work tomorrow Plan for tomorrow Discussion James: What about tomorrow? Hannah: To be honest I have plans for tomorrow evening James: Oh ok. What about Sat then? Plan for Saturday Hannah: Yeah. Sure I am available on Sat James: I’ll pick you up at 8? Pick up time Hannah: Sounds good. See you then Conclusion -
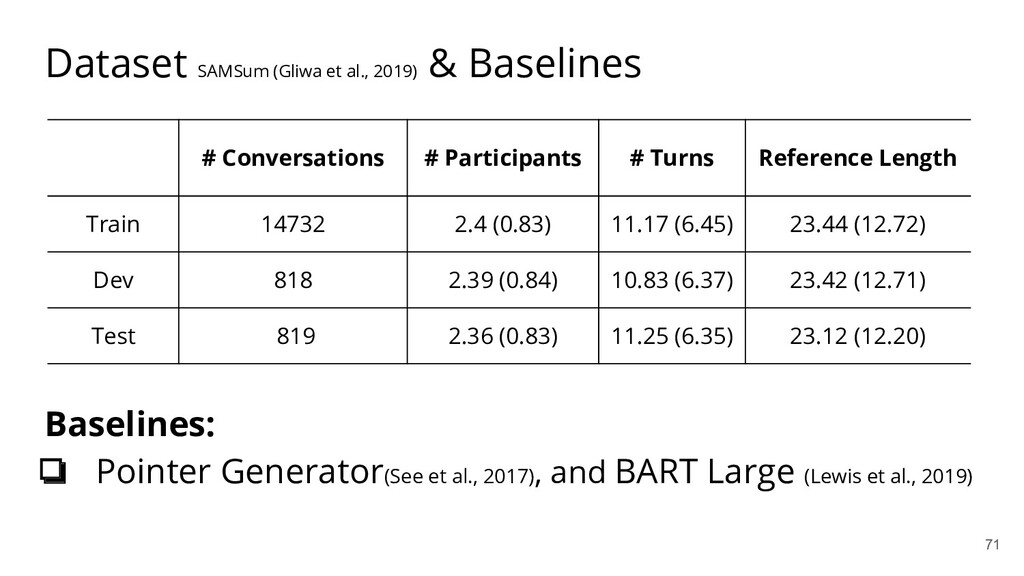
Dataset SAMSum (Gliwa et al., 2019) & Baselines Baselines: ❏
Pointer Generator(See et al., 2017), and BART Large (Lewis et al., 2019) 71 # Conversations # Participants # Turns Reference Length Train 14732 2.4 (0.83) 11.17 (6.45) 23.44 (12.72) Dev 818 2.39 (0.84) 10.83 (6.37) 23.42 (12.71) Test 819 2.36 (0.83) 11.25 (6.35) 23.12 (12.20) -
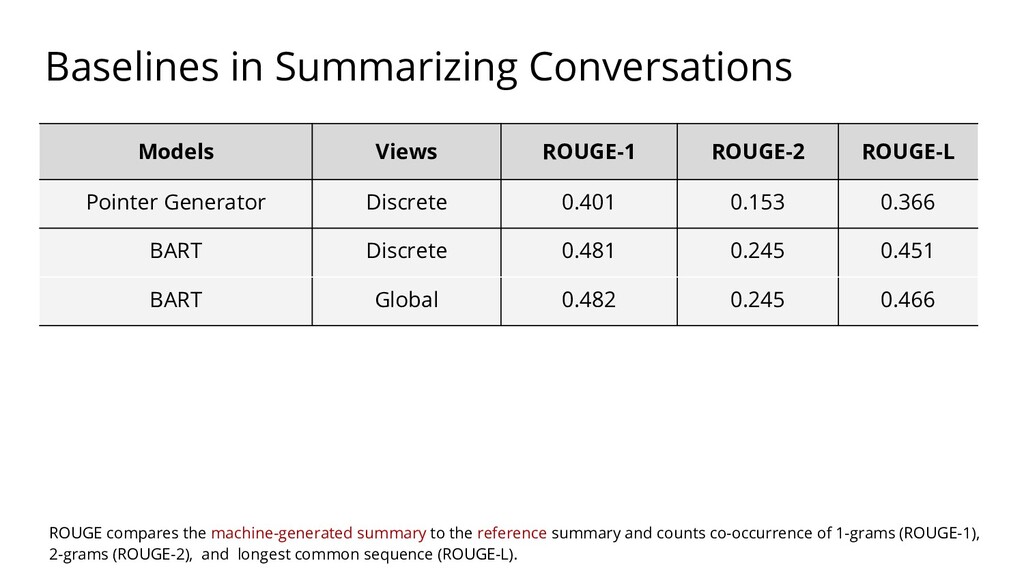
Models Views ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator Discrete 0.401 0.153
0.366 BART Discrete 0.481 0.245 0.451 BART Global 0.482 0.245 0.466 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams (ROUGE-1), 2-grams (ROUGE-2), and longest common sequence (ROUGE-L). Baselines in Summarizing Conversations -
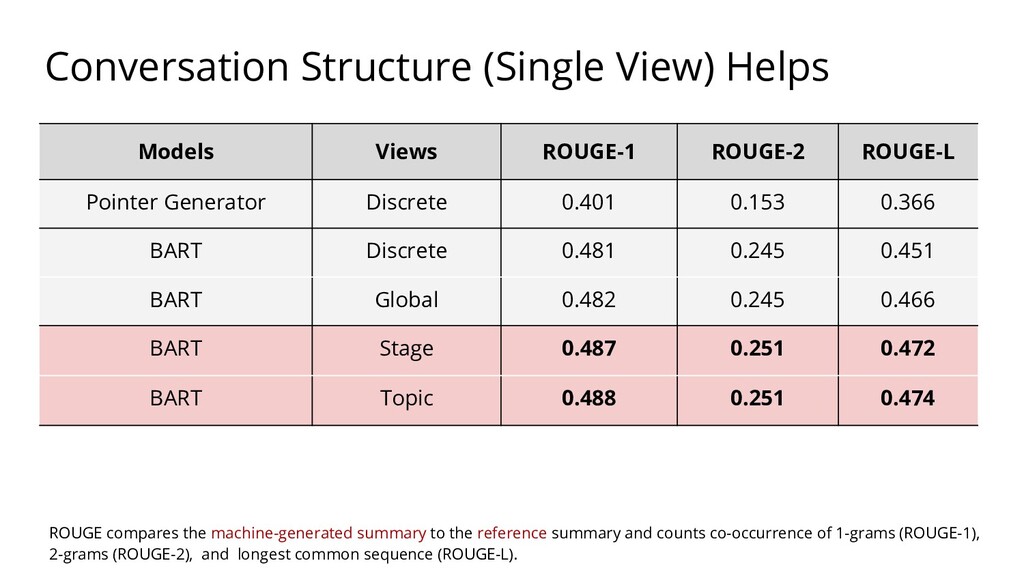
Models Views ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator Discrete 0.401 0.153
0.366 BART Discrete 0.481 0.245 0.451 BART Global 0.482 0.245 0.466 BART Stage 0.487 0.251 0.472 BART Topic 0.488 0.251 0.474 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams (ROUGE-1), 2-grams (ROUGE-2), and longest common sequence (ROUGE-L). Conversation Structure (Single View) Helps -
Models Views ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator Discrete 0.401 0.153
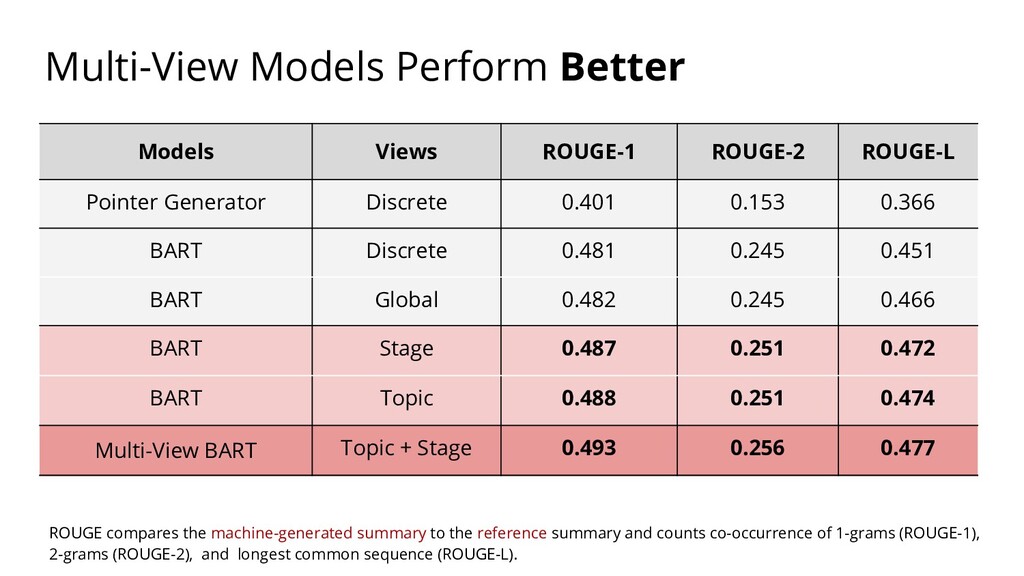
0.366 BART Discrete 0.481 0.245 0.451 BART Global 0.482 0.245 0.466 BART Stage 0.487 0.251 0.472 BART Topic 0.488 0.251 0.474 Multi-View BART Topic + Stage 0.493 0.256 0.477 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams (ROUGE-1), 2-grams (ROUGE-2), and longest common sequence (ROUGE-L). Multi-View Models Perform Better -
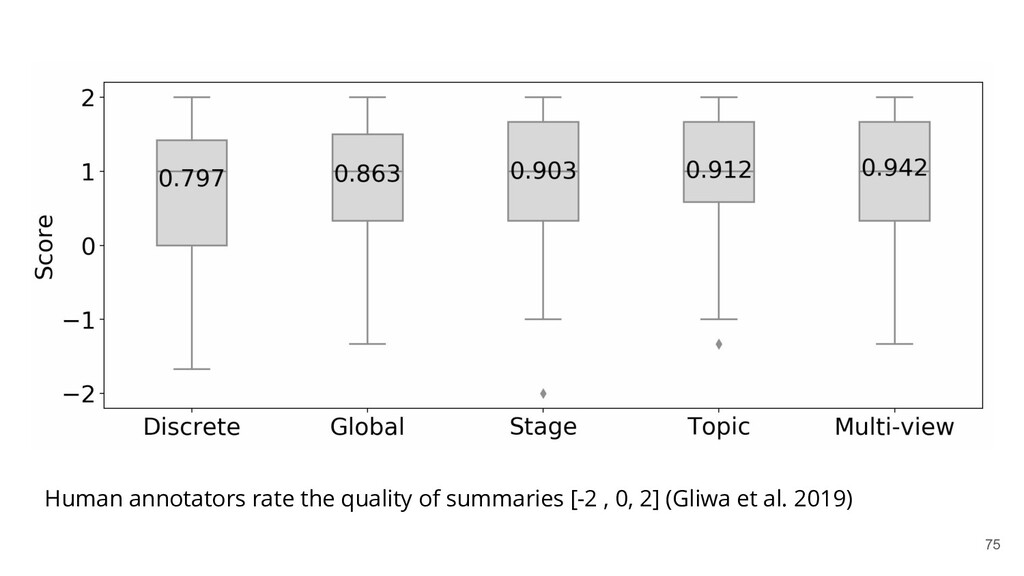
Human annotators rate the quality of summaries [-2 , 0,
2] (Gliwa et al. 2019) 75 -
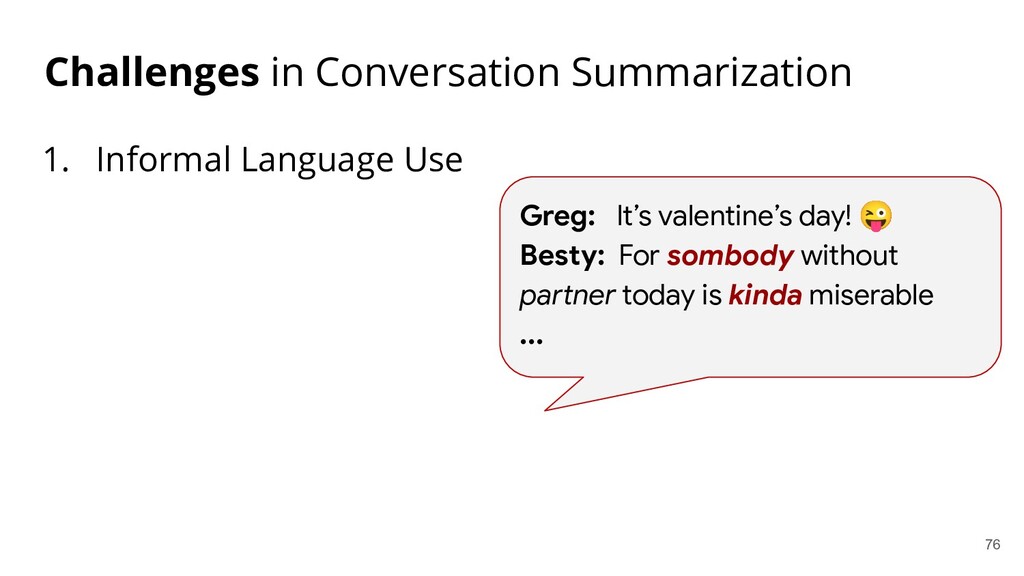
Challenges in Conversation Summarization 1. Informal Language Use 76 Greg:
It’s valentine’s day! 😜 Besty: For sombody without partner today is kinda miserable ... -
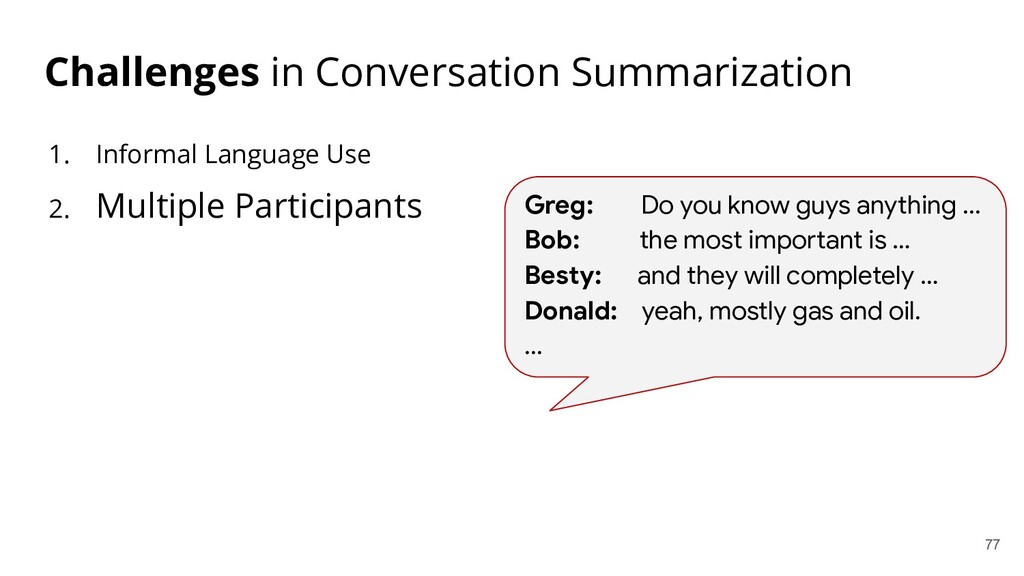
1. Informal Language Use 2. Multiple Participants 77 Greg: Do
you know guys anything ... Bob: the most important is … Besty: and they will completely … Donald: yeah, mostly gas and oil. ... Challenges in Conversation Summarization -
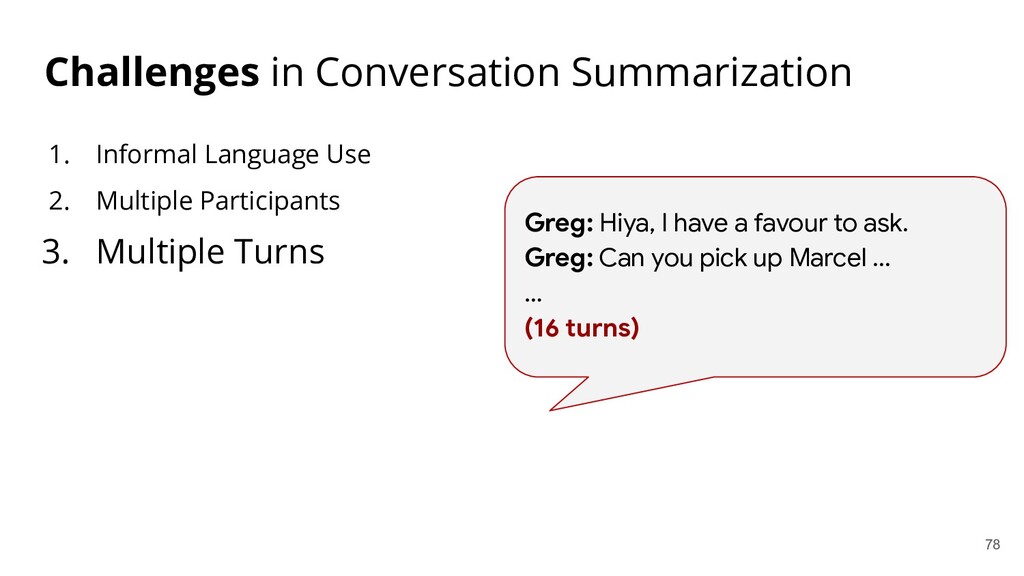
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
78 Challenges in Conversation Summarization Greg: Hiya, I have a favour to ask. Greg: Can you pick up Marcel ... … (16 turns) -
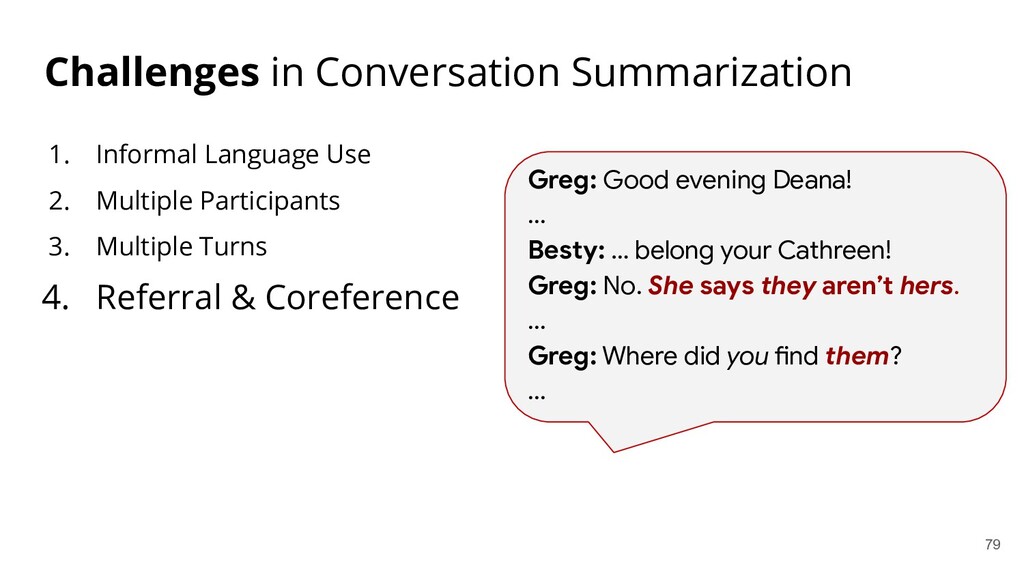
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
4. Referral & Coreference 79 Challenges in Conversation Summarization Greg: Good evening Deana! ... Besty: … belong your Cathreen! Greg: No. She says they aren’t hers. ... Greg: Where did you find them? ... -
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
4. Referral & Coreference 5. Repetition & Interruption 80 Challenges in Conversation Summarization Greg: Well, could you pick him up? Besty: What if I can’t? Greg: Besty? Besty: What if I can’t? Greg: Can’t you, really? Besty: I can’t. ... ... -
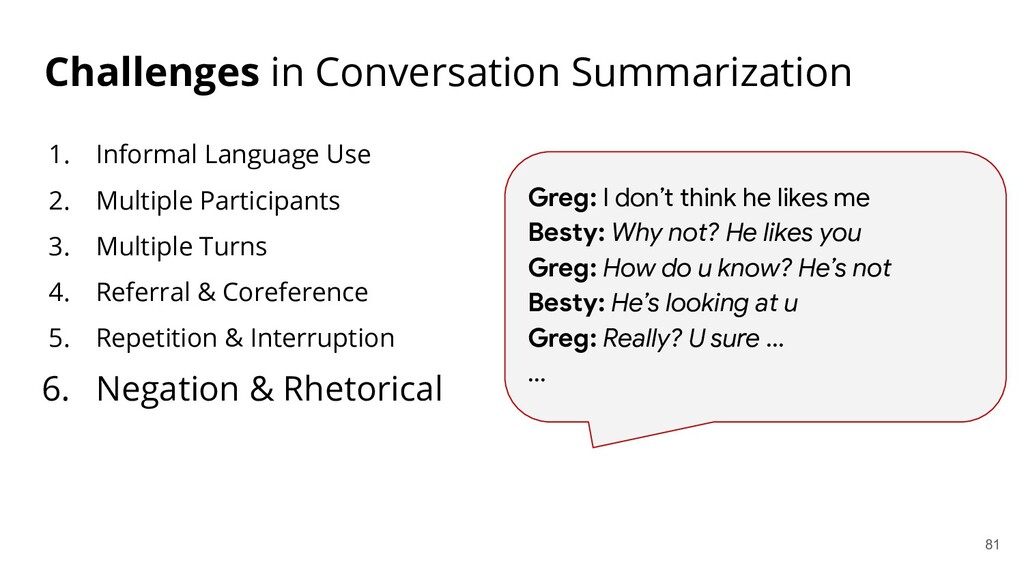
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
4. Referral & Coreference 5. Repetition & Interruption 6. Negation & Rhetorical 81 Challenges in Conversation Summarization Greg: I don’t think he likes me Besty: Why not? He likes you Greg: How do u know? He’s not Besty: He’s looking at u Greg: Really? U sure ... ... -
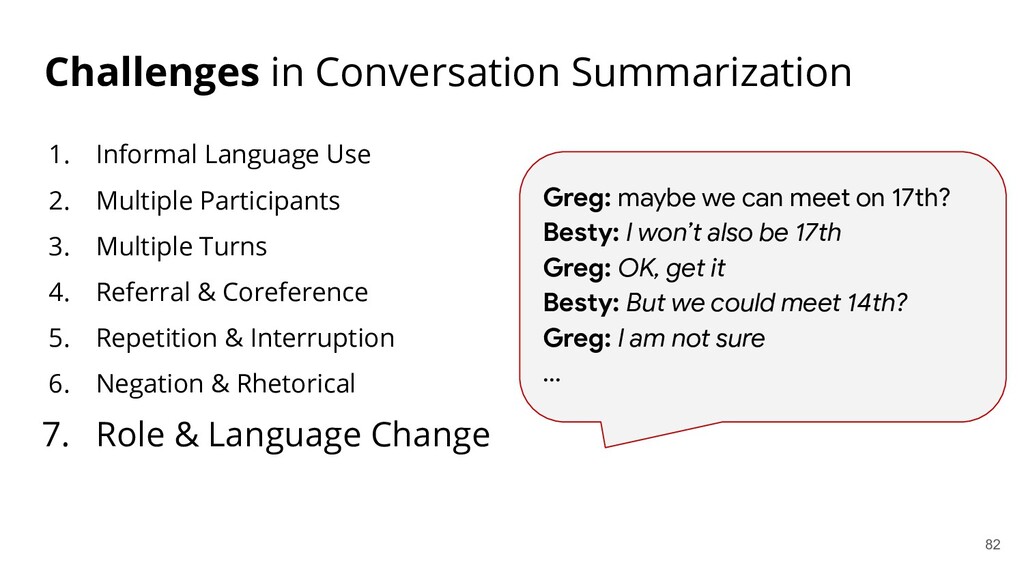
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
4. Referral & Coreference 5. Repetition & Interruption 6. Negation & Rhetorical 7. Role & Language Change 82 Challenges in Conversation Summarization Greg: maybe we can meet on 17th? Besty: I won’t also be 17th Greg: OK, get it Besty: But we could meet 14th? Greg: I am not sure ... -
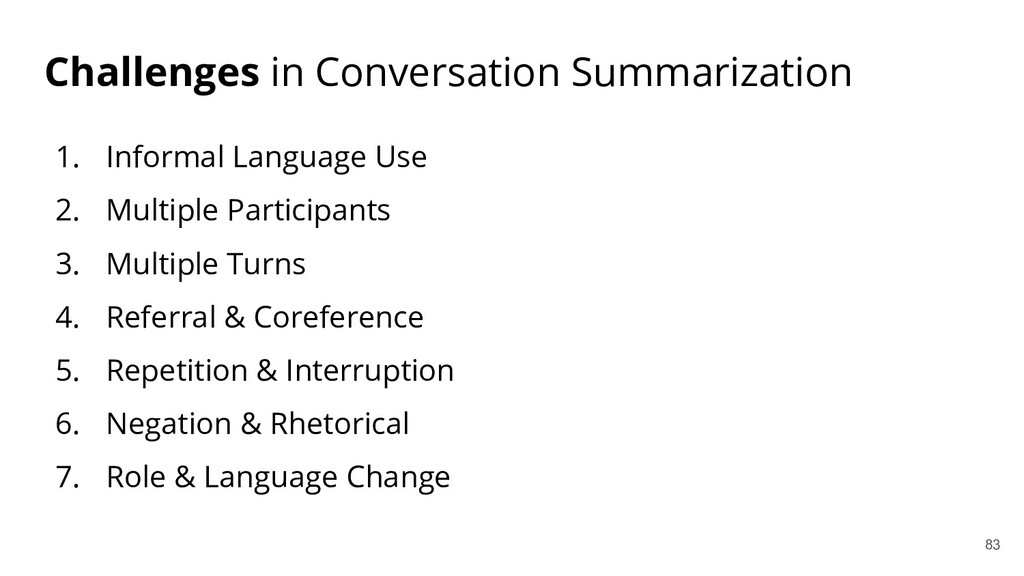
1. Informal Language Use 2. Multiple Participants 3. Multiple Turns
4. Referral & Coreference 5. Repetition & Interruption 6. Negation & Rhetorical 7. Role & Language Change 83 Challenges in Conversation Summarization -
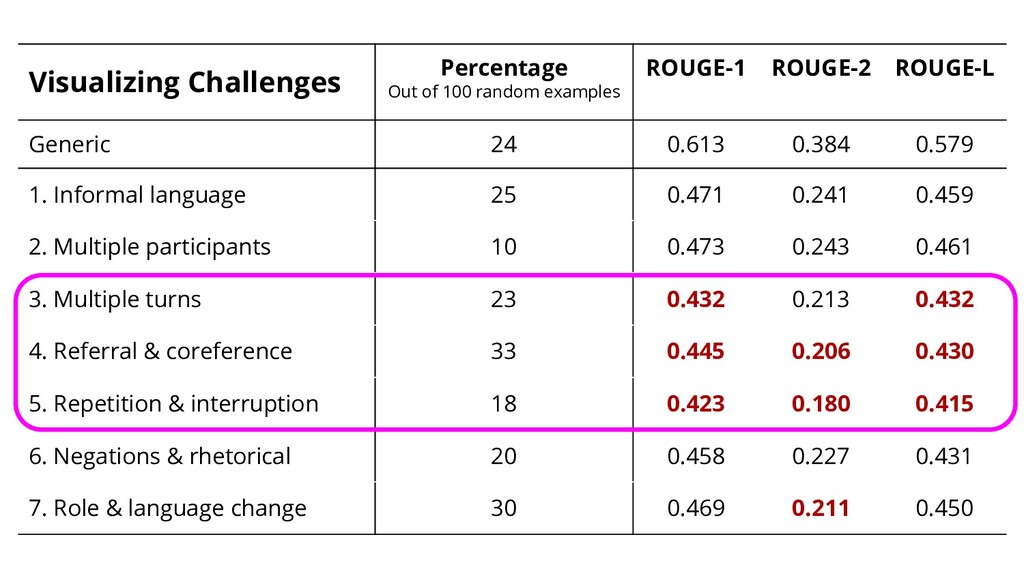
Visualizing Challenges Percentage Out of 100 random examples ROUGE-1 ROUGE-2
ROUGE-L Generic 24 0.613 0.384 0.579 1. Informal language 25 0.471 0.241 0.459 2. Multiple participants 10 0.473 0.243 0.461 3. Multiple turns 23 0.432 0.213 0.432 4. Referral & coreference 33 0.445 0.206 0.430 5. Repetition & interruption 18 0.423 0.180 0.415 6. Negations & rhetorical 20 0.458 0.227 0.431 7. Role & language change 30 0.469 0.211 0.450 -
Overview of This Talk 85 ✓ Low-Resourced Scenarios ✓ Text
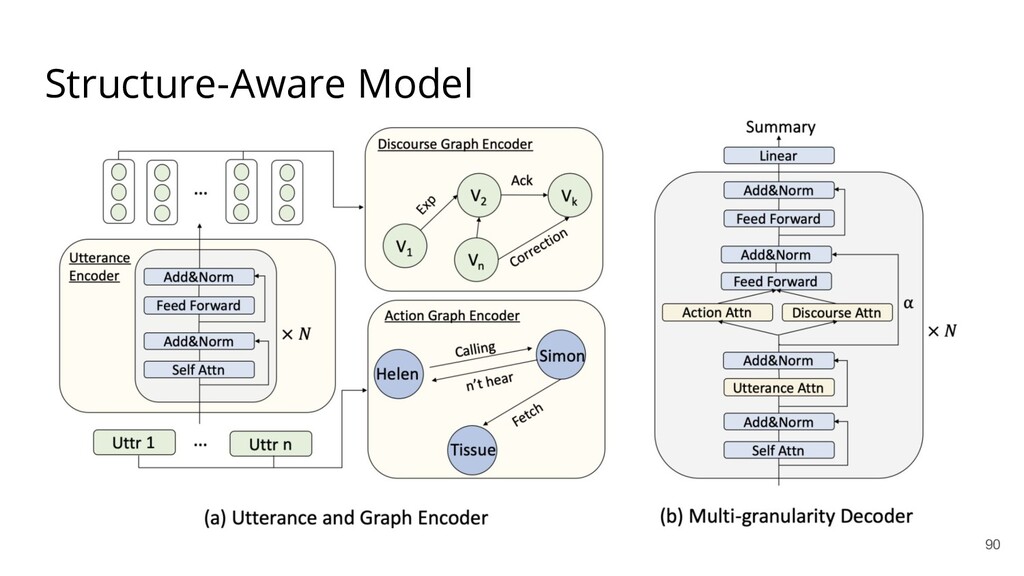
Mixup for Semi-supervised Classification ✓ LADA for Named Entity Recognition ✓ Structured Knowledge from Conversations ✓ Summarization via Conversation Structures ➢ Summarization via Action and Discourse Graphs Jiaao Chen, Diyi Yang. Structure-Aware Abstractive Conversation Summarization via Discourse and Action Graphs. NAACL 2021 -
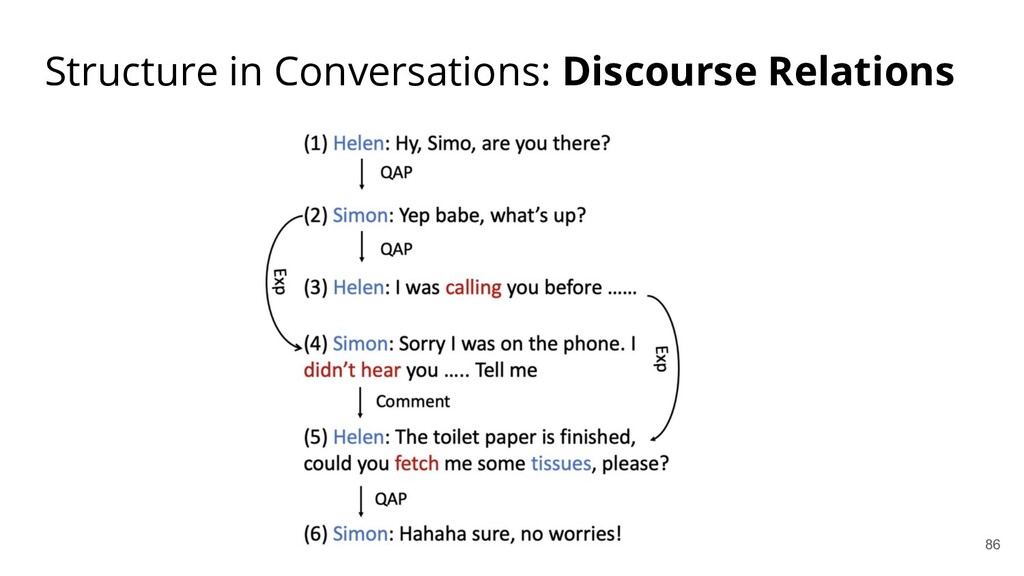
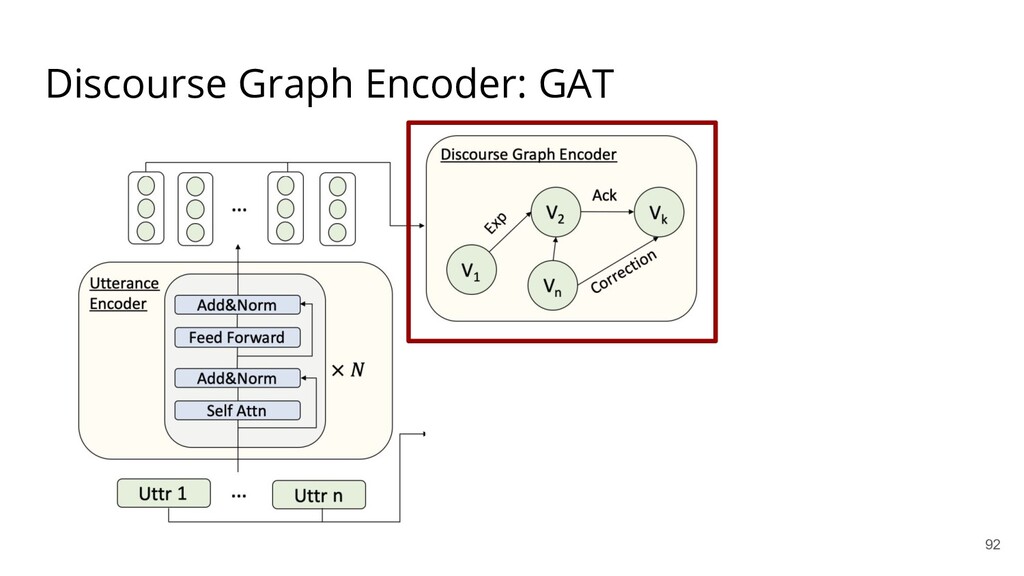
Discourse Relation Graph Extraction • Pre-train a parser on an
annotated corpus (Asher et al. 2016) with 77.5 F1 • Predict discourse edges between utterances 87 -
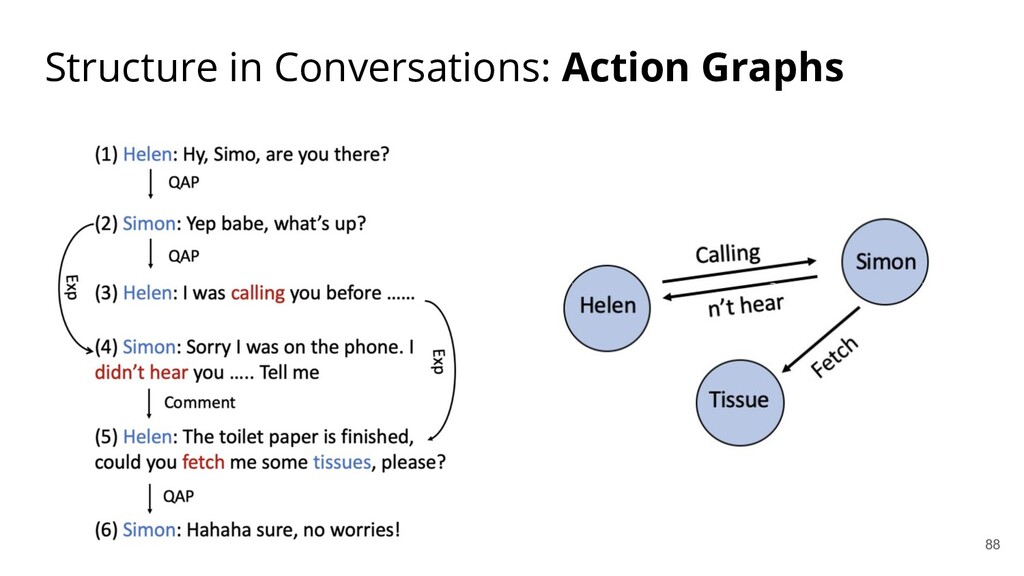
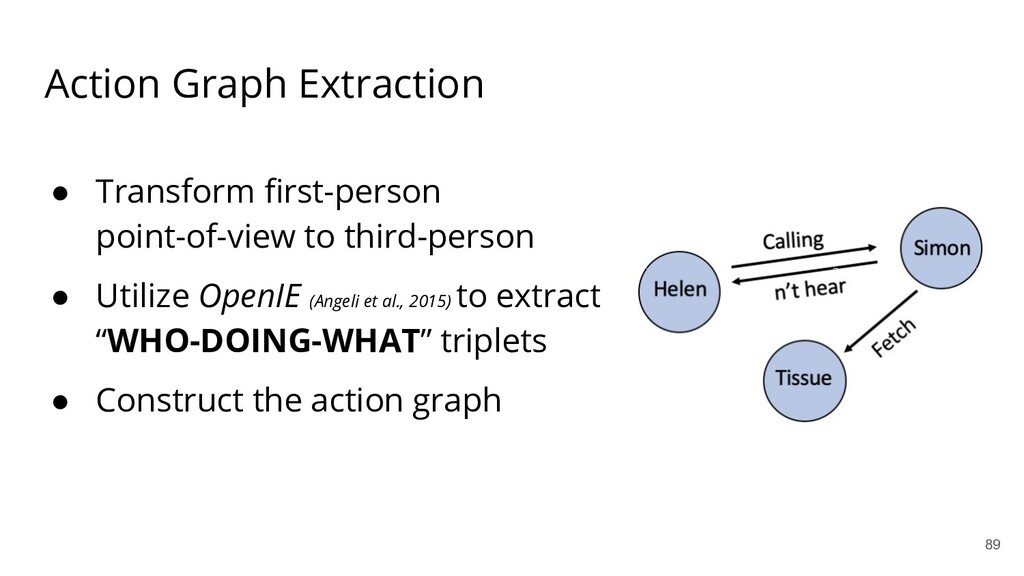
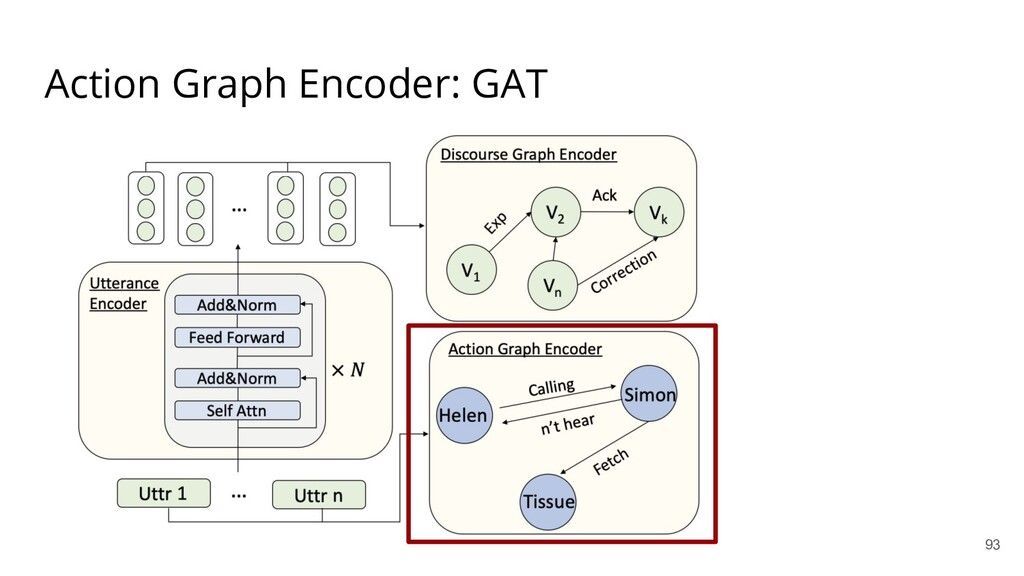
Action Graph Extraction • Transform first-person point-of-view to third-person •
Utilize OpenIE (Angeli et al., 2015) to extract “WHO-DOING-WHAT” triplets • Construct the action graph 89 -
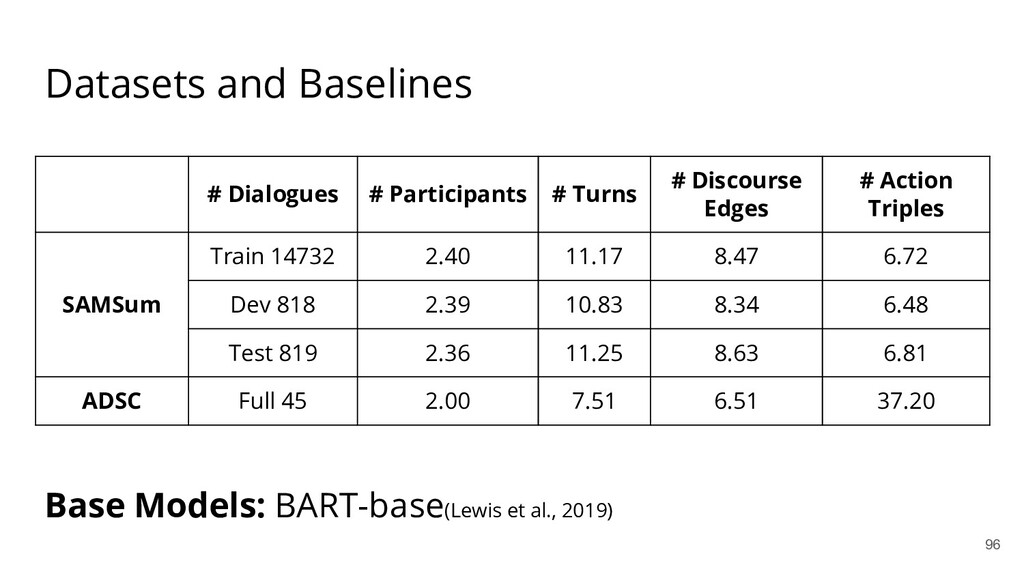
Datasets and Baselines Base Models: BART-base(Lewis et al., 2019) 96
# Dialogues # Participants # Turns # Discourse Edges # Action Triples SAMSum Train 14732 2.40 11.17 8.47 6.72 Dev 818 2.39 10.83 8.34 6.48 Test 819 2.36 11.25 8.63 6.81 ADSC Full 45 2.00 7.51 6.51 37.20 -
Experiments Results (in-domain) Models ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator 0.401
0.153 0.366 BART 0.481 0.245 0.451 BART 0.482 0.245 0.466 BART 0.487 0.251 0.472 BART 0.488 0.251 0.474 Multi-View BART 0.493 0.256 0.477 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 97 -
Experiments Results (in-domain) Models ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator 40.08
15.28 36.63 BART-base 45.15 21.66 44.46 Multi-view BART-base 45. 0.245 0.466 BART 0.487 0.251 0.472 BART 0.488 0.251 0.474 Multi-View BART 0.493 0.256 0.477 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 98 Baseline Results -
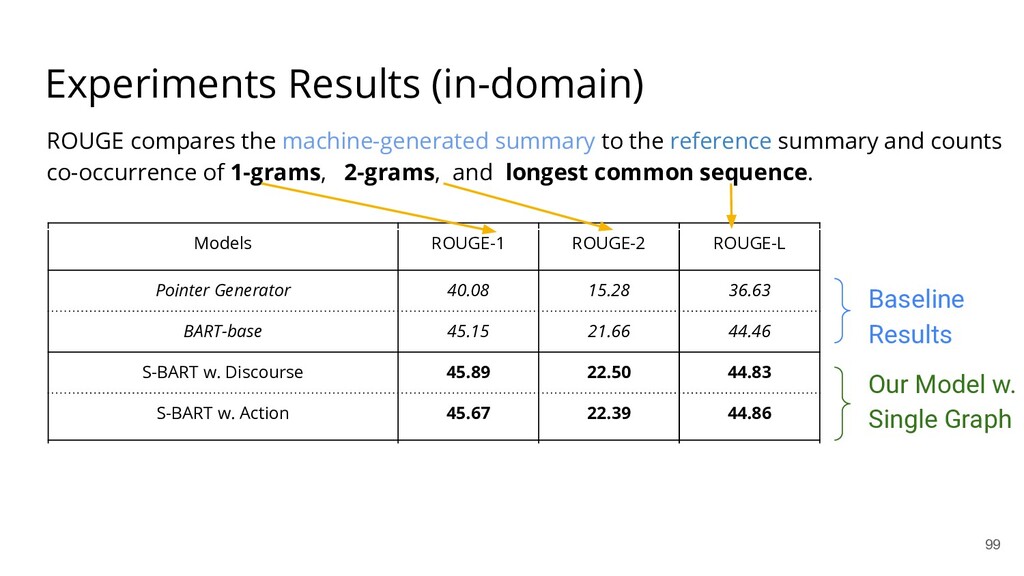
Experiments Results (in-domain) Models ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator 40.08
15.28 36.63 BART-base 45.15 21.66 44.46 S-BART w. Discourse 45.89 22.50 44.83 S-BART w. Action 45.67 22.39 44.86 BART 0.488 0.251 0.474 Multi-View BART 0.493 0.256 0.477 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 99 Baseline Results Our Model w. Single Graph -
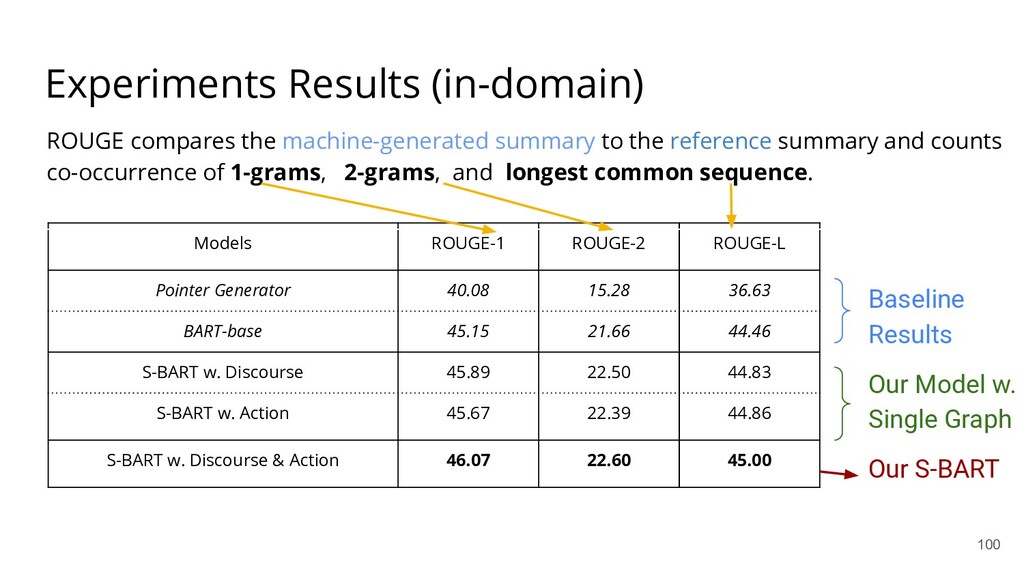
Experiments Results (in-domain) Models ROUGE-1 ROUGE-2 ROUGE-L Pointer Generator 40.08
15.28 36.63 BART-base 45.15 21.66 44.46 S-BART w. Discourse 45.89 22.50 44.83 S-BART w. Action 45.67 22.39 44.86 S-BART w. Discourse & Action 46.07 22.60 45.00 ROUGE compares the machine-generated summary to the reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 100 Baseline Results Our Model w. Single Graph Our S-BART -
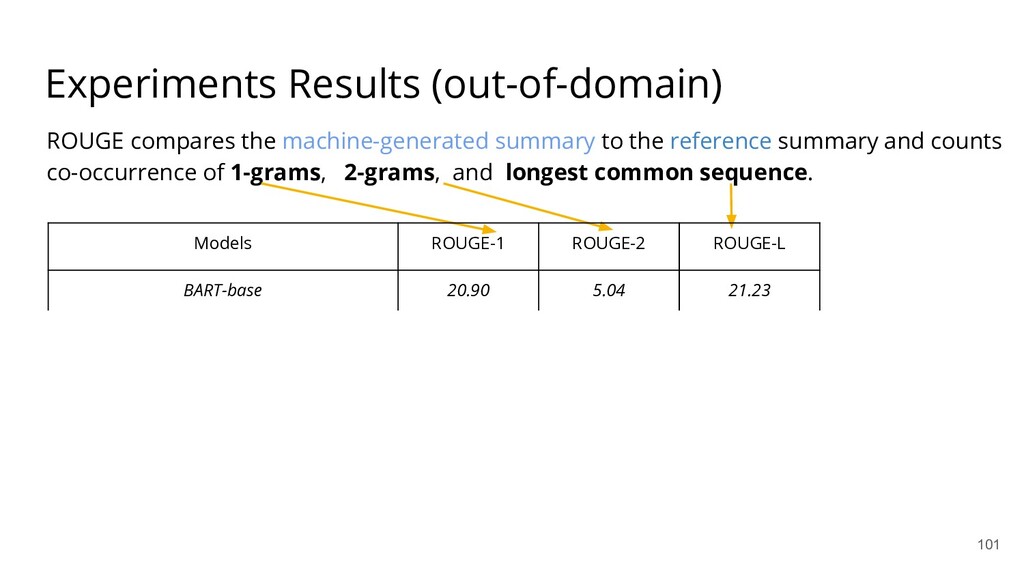
Experiments Results (out-of-domain) ROUGE compares the machine-generated summary to the
reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 101 Models ROUGE-1 ROUGE-2 ROUGE-L BART-base 20.90 5.04 21.23 S-BART w. Discourse 22.42 5.58 22.16 S-BART w. Action 30.91 20.64 35.30 S-BART w. Discourse & Action 34.74 23.86 38.69 -
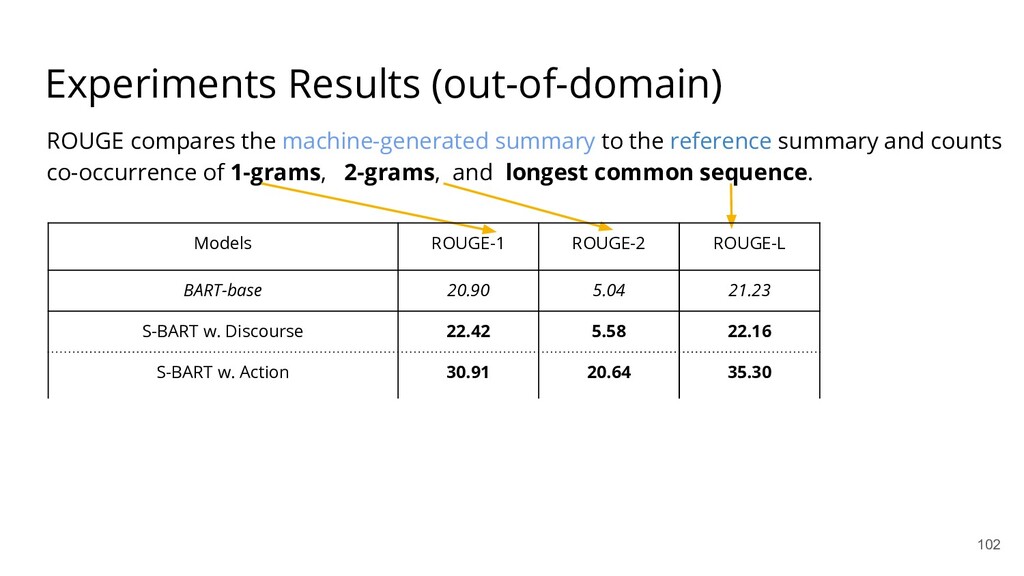
Experiments Results (out-of-domain) ROUGE compares the machine-generated summary to the
reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 102 Models ROUGE-1 ROUGE-2 ROUGE-L BART-base 20.90 5.04 21.23 S-BART w. Discourse 22.42 5.58 22.16 S-BART w. Action 30.91 20.64 35.30 S-BART w. Discourse & Action 34.74 23.86 38.69 -
Experiments Results (out-of-domain) ROUGE compares the machine-generated summary to the
reference summary and counts co-occurrence of 1-grams, 2-grams, and longest common sequence. 103 Models ROUGE-1 ROUGE-2 ROUGE-L BART-base 20.90 5.04 21.23 S-BART w. Discourse 22.42 5.58 22.16 S-BART w. Action 30.91 20.64 35.30 S-BART w. Discourse & Action 34.74 23.86 38.69 -
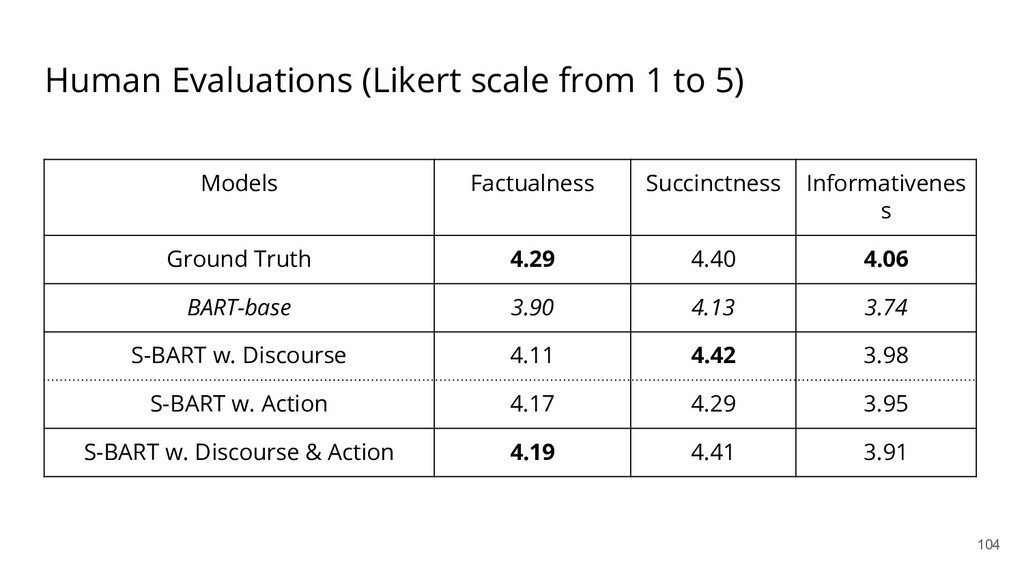
Human Evaluations (Likert scale from 1 to 5) 104 Models
Factualness Succinctness Informativenes s Ground Truth 4.29 4.40 4.06 BART-base 3.90 4.13 3.74 S-BART w. Discourse 4.11 4.42 3.98 S-BART w. Action 4.17 4.29 3.95 S-BART w. Discourse & Action 4.19 4.41 3.91 -
Conclusion on Summarizing Conversations ✓ Conversation structures help summarizations ✓
Structures also improve generalization performances ✓ Dialogue summarizations still face MANY challenges 105 github.com/GT-SALT/Multi-View-Seq2Seq github.com/GT-SALT/Structure-Aware-BART -
Overview of This Talk 106 ✓ Low-Resourced Scenarios ✓ Text
Mixup for Semi-supervised Classification ✓ LADA for Named Entity Recognition ✓ Structured Knowledge from Conversations ✓ Summarization via Conversation Structures ✓ Summarization via Action and Discourse Graphs -
Natural Language Processing with Less Data and More Structures Diyi
Yang Twitter: @Diyi_Yang www.cc.gatech.edu/~dyang888 Thank You