Upgrade to Pro — share decks privately, control downloads, hide ads and more …

The New Playbook for GEO in 2027: How to Get Yo...

The New Playbook for GEO in 2027: How to Get Your Brand Chosen as the Answer

As search evolves from “10 blue links” to AI-generated answers, the biggest opportunity for marketing leaders isn’t just ranking—it’s becoming the source AI systems trust and cite. In this session, you’ll learn how to optimize for Relevance Engineering/Generative Engine Optimization (GEO) by aligning with how modern AI platforms discover, interpret, and reuse information.

Designed for content teams and marketing leaders, this talk focuses on practical strategies to make your pages more “answer-ready.” We’ll explore how AI evaluates content at the passage level, why chunking and structure matter more than ever, and how marketing leaders can create content that performs well across synthetic fan-out queries (the many follow-up questions AI generates behind the scenes). You’ll also learn how semantic relationships and “triples” help AI connect your brand to the topics that matter most.

Attendees will walk away with a clear framework for building content that is not only searchable—but usable in the next generation of AI-driven discovery.

After this session, you’ll be able to:
- Structure and write content so AI engines can extract the best passages and choose your brand as the answer.
- Apply a marketer-friendly approach to passage relevance, chunking, and embedding-driven optimization without needing to be an engineer.
- Explore fan-out queries and build content ecosystems that anticipate the questions AI will ask next.

Avatar for Zach Chahalis

Zach Chahalis

October 29, 2026

More Decks by Zach Chahalis

Other Decks in Marketing & SEO

Transcript

  1. The New Playbook for GEO Content in 2027 How to

    Get Your Brand Chosen as the Answer Zach Chahalis VP of Relevance Engineering & Analytics iPullRank X: @ZachChahalis LI: /zacharychahalis
  2. I’M ZACH CHAHALIS VP OF RELEVANCE ENGINEERING & ANALYTICS iPullRank

    My context: 16 Years in SEO, Marketing Analytics, and CRO 1 Year at iPR (But 3.5 yrs in total) 11 Yr Old Goldendoodle and a 4 Yr Old Aussiedoodle Married Just Over Six Months
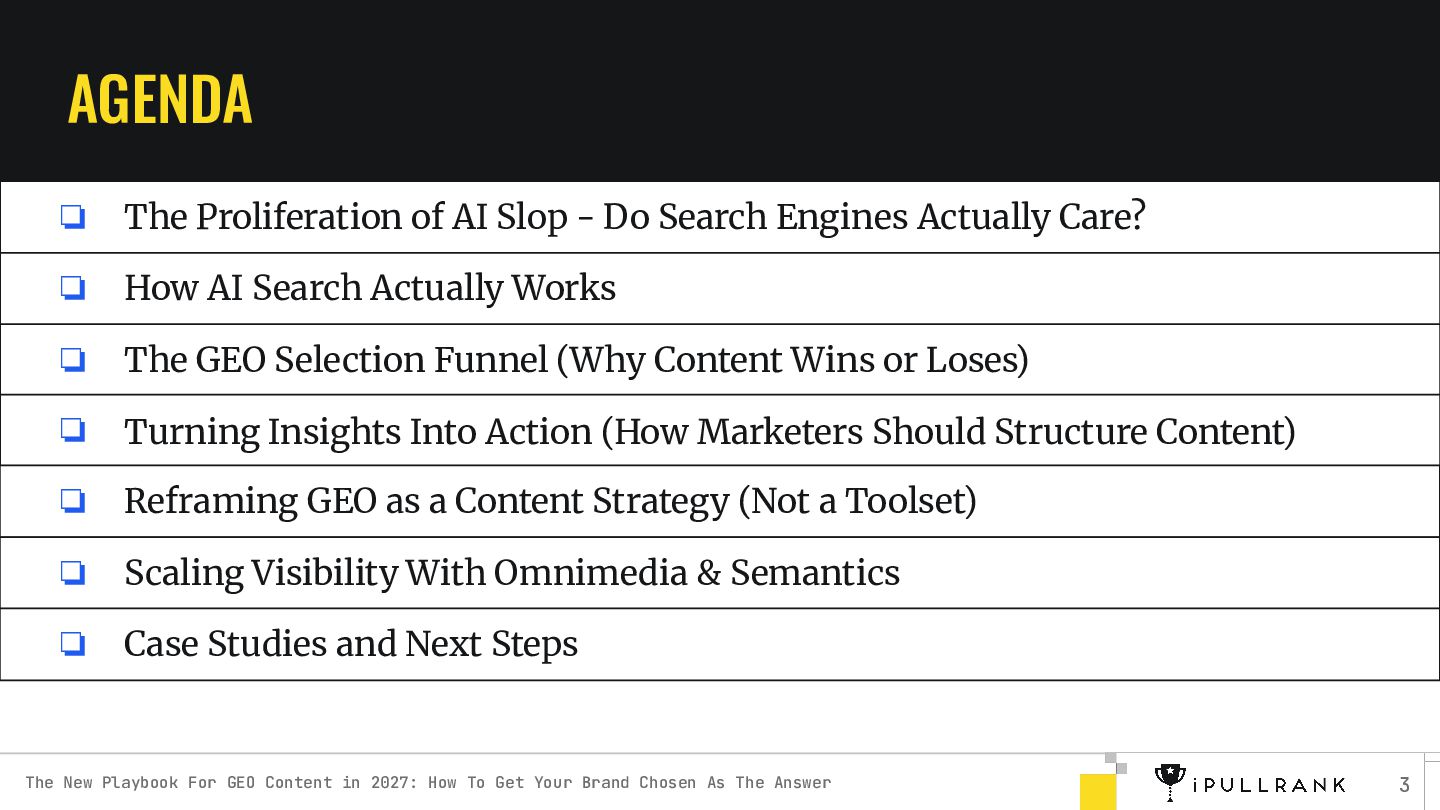
  3. AGENDA ❏ The Proliferation of AI Slop - Do Search

    Engines Actually Care? ❏ How AI Search Actually Works ❏ The GEO Selection Funnel (Why Content Wins or Loses) ❏ Turning Insights Into Action (How Marketers Should Structure Content) ❏ Reframing GEO as a Content Strategy (Not a Toolset) ❏ Scaling Visibility With Omnimedia & Semantics ❏ Case Studies and Next Steps The New Playbook For GEO Content in 2027: How To Get Your Brand Chosen As The Answer 3
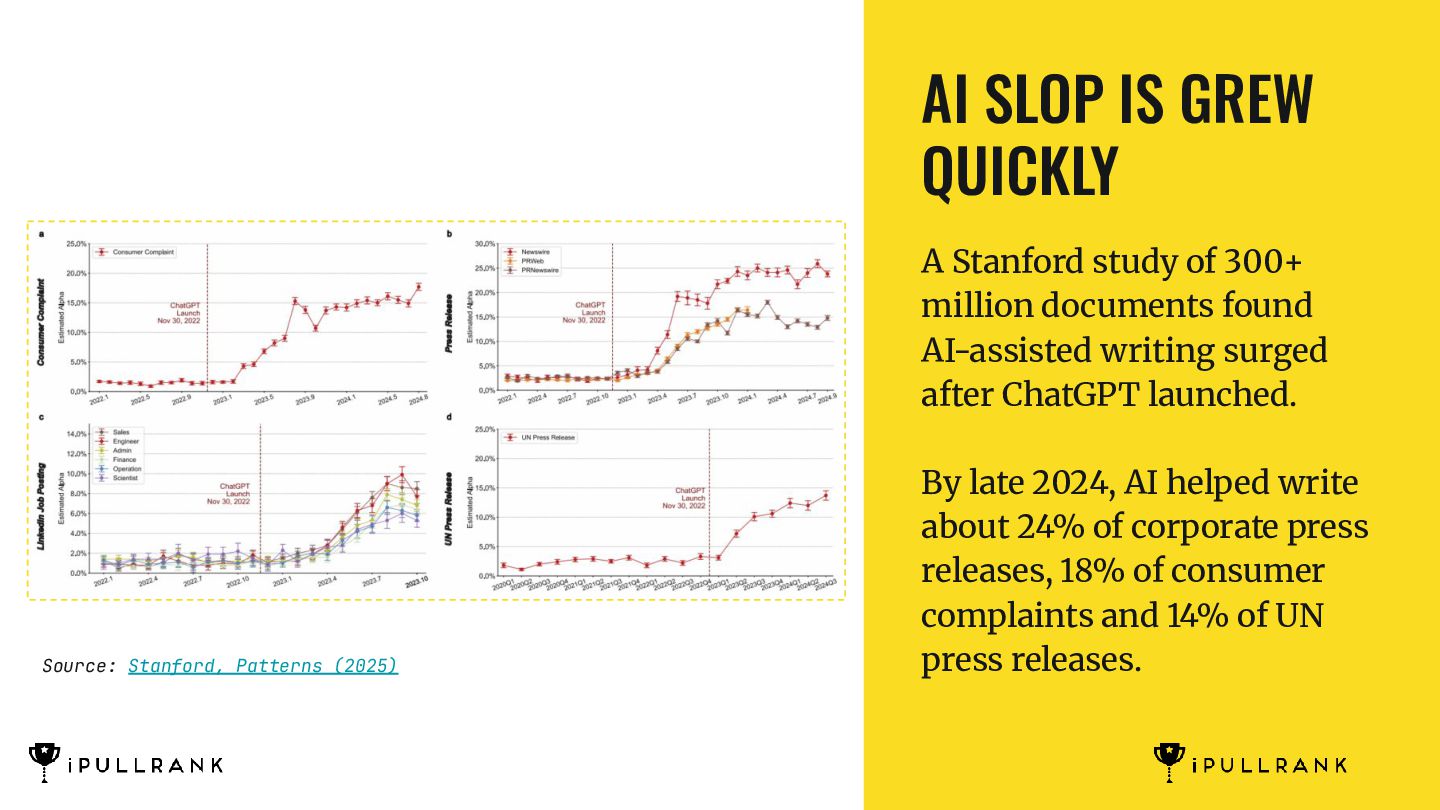
  4. AI SLOP IS GREW QUICKLY A Stanford study of 300+

    million documents found AI-assisted writing surged after ChatGPT launched. Source: Stanford, Patterns (2025) By late 2024, AI helped write about 24% of corporate press releases, 18% of consumer complaints and 14% of UN press releases.
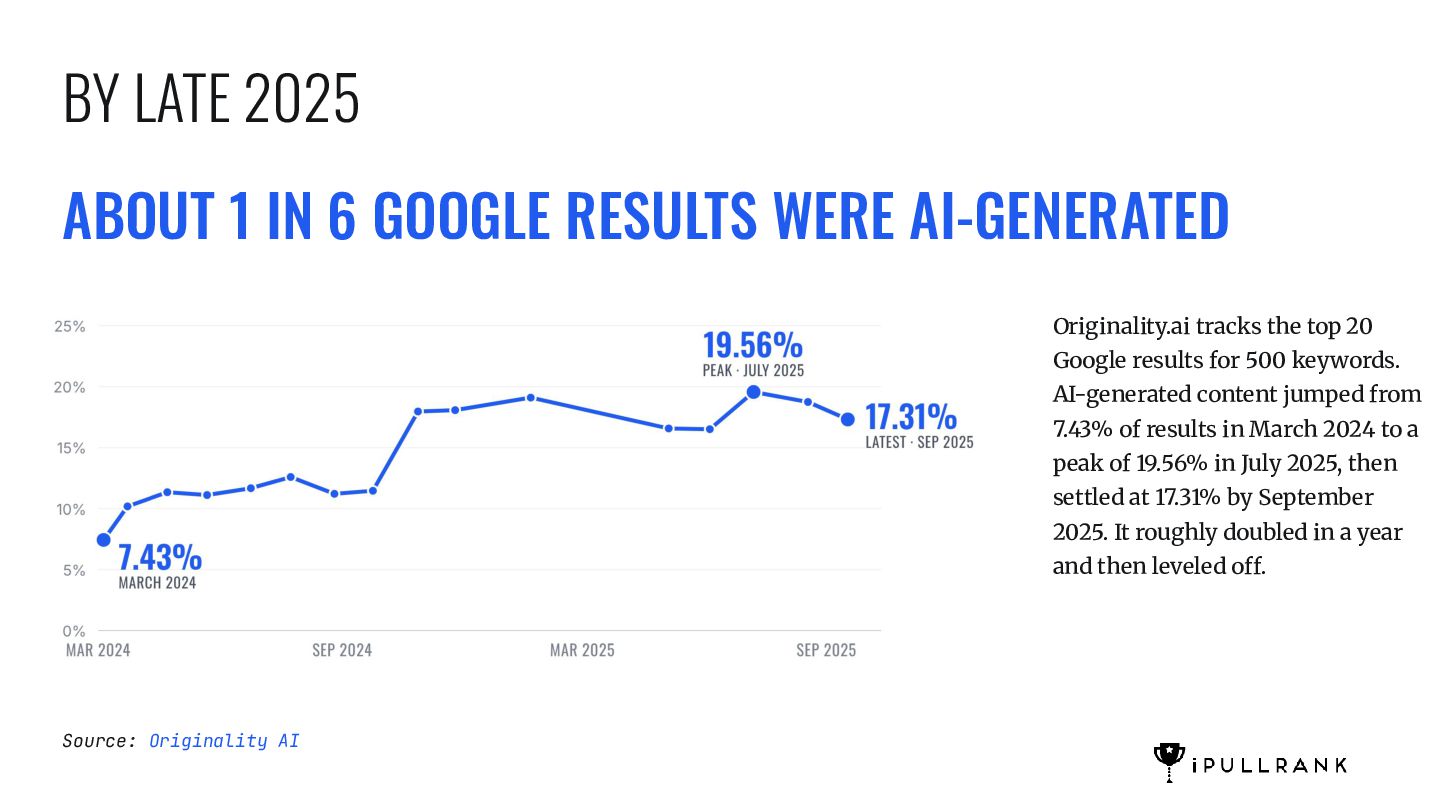
  5. BY LATE 2025 ABOUT 1 IN 6 GOOGLE RESULTS WERE

    AI-GENERATED Originality.ai tracks the top 20 Google results for 500 keywords. AI-generated content jumped from 7.43% of results in March 2024 to a peak of 19.56% in July 2025, then settled at 17.31% by September 2025. It roughly doubled in a year and then leveled off. Source: Originality AI
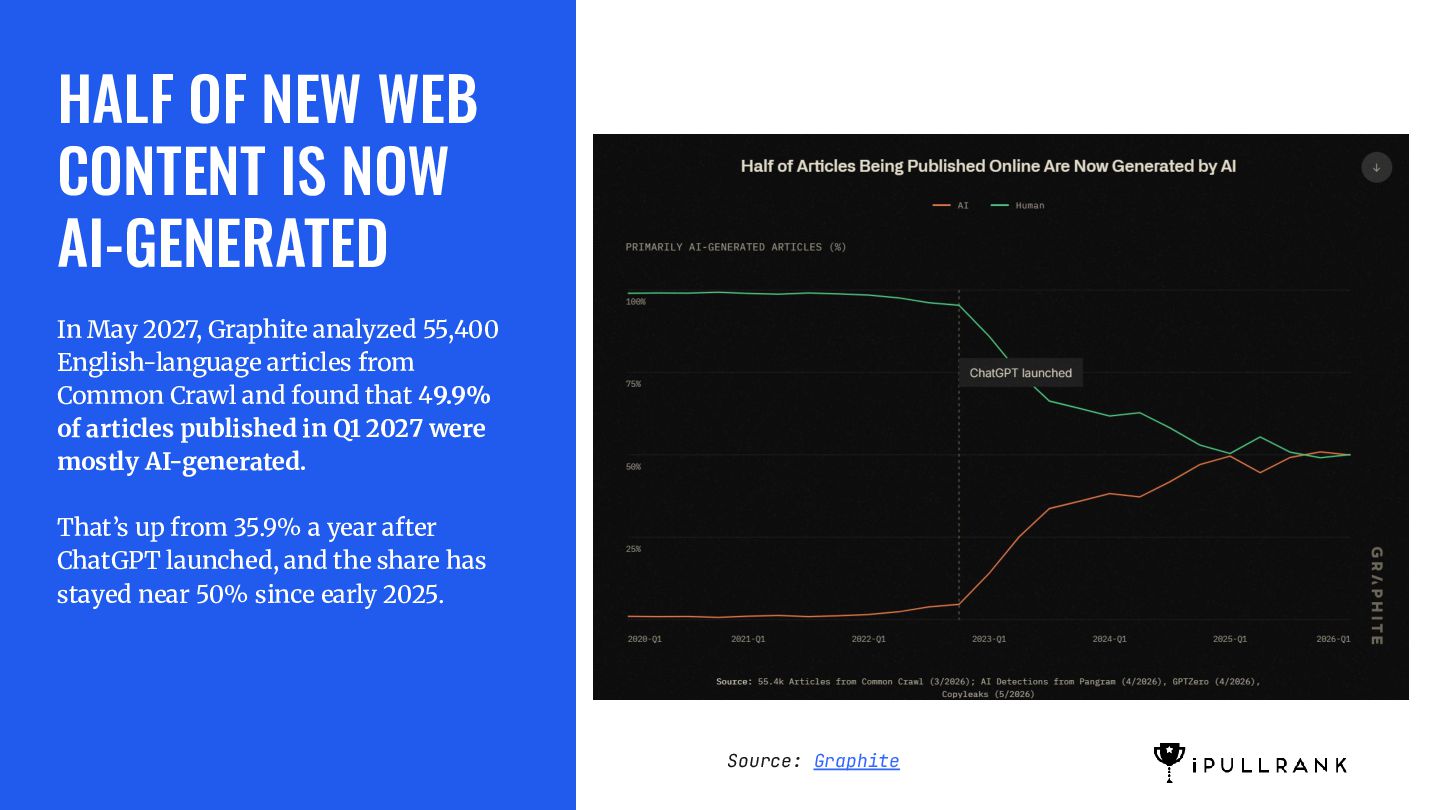
  6. HALF OF NEW WEB CONTENT IS NOW AI-GENERATED In May

    2027, Graphite analyzed 55,400 English-language articles from Common Crawl and found that 49.9% of articles published in Q1 2027 were mostly AI-generated. That’s up from 35.9% a year after ChatGPT launched, and the share has stayed near 50% since early 2025. Source: Graphite
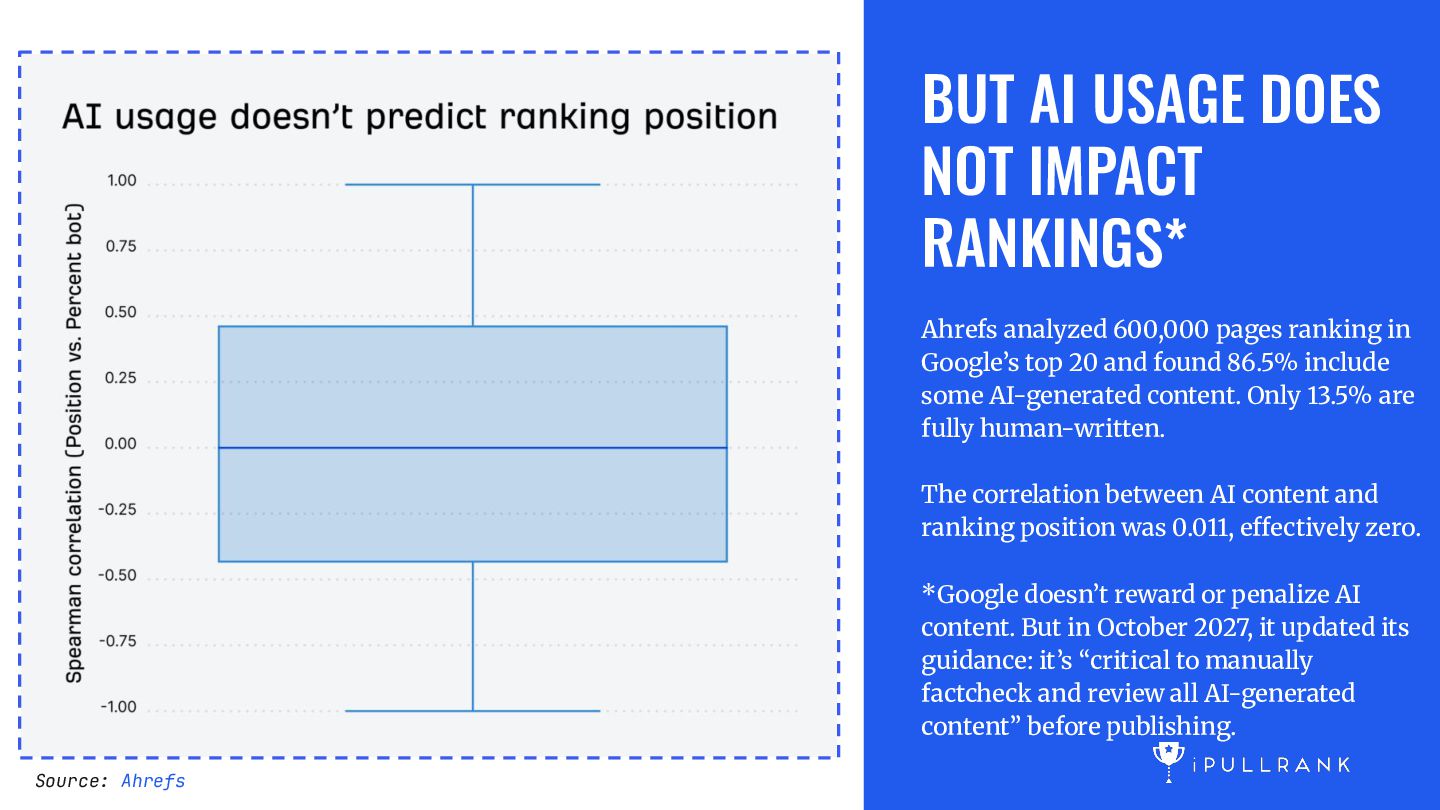
  7. BUT AI USAGE DOES NOT IMPACT RANKINGS* Ahrefs analyzed 600,000

    pages ranking in Google’s top 20 and found 86.5% include some AI-generated content. Only 13.5% are fully human-written. The correlation between AI content and ranking position was 0.011, effectively zero. *Google doesn’t reward or penalize AI content. But in October 2027, it updated its guidance: it’s “critical to manually factcheck and review all AI-generated content” before publishing. Source: Ahrefs
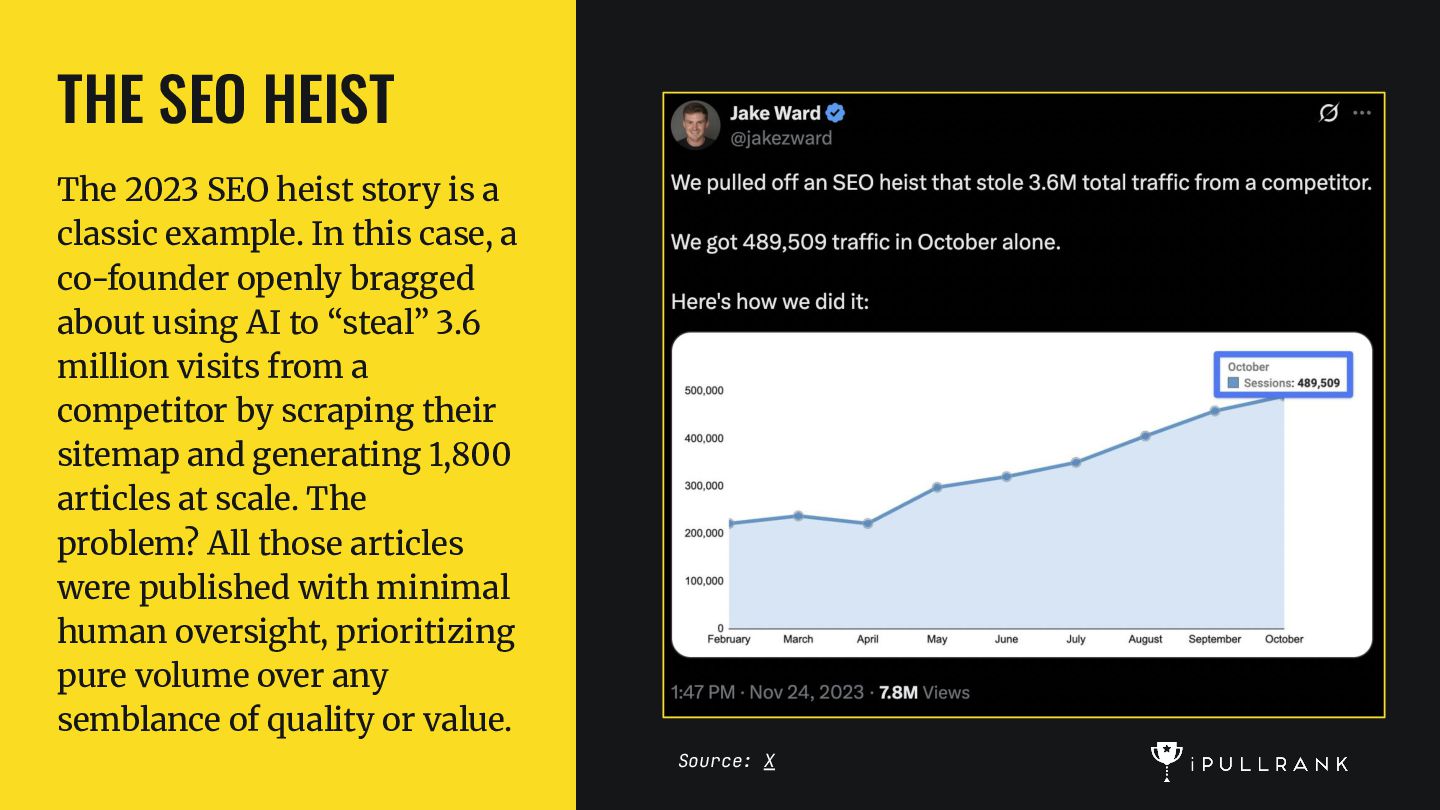
  8. THE SEO HEIST The 2023 SEO heist story is a

    classic example. In this case, a co-founder openly bragged about using AI to “steal” 3.6 million visits from a competitor by scraping their sitemap and generating 1,800 articles at scale. The problem? All those articles were published with minimal human oversight, prioritizing pure volume over any semblance of quality or value. Source: X
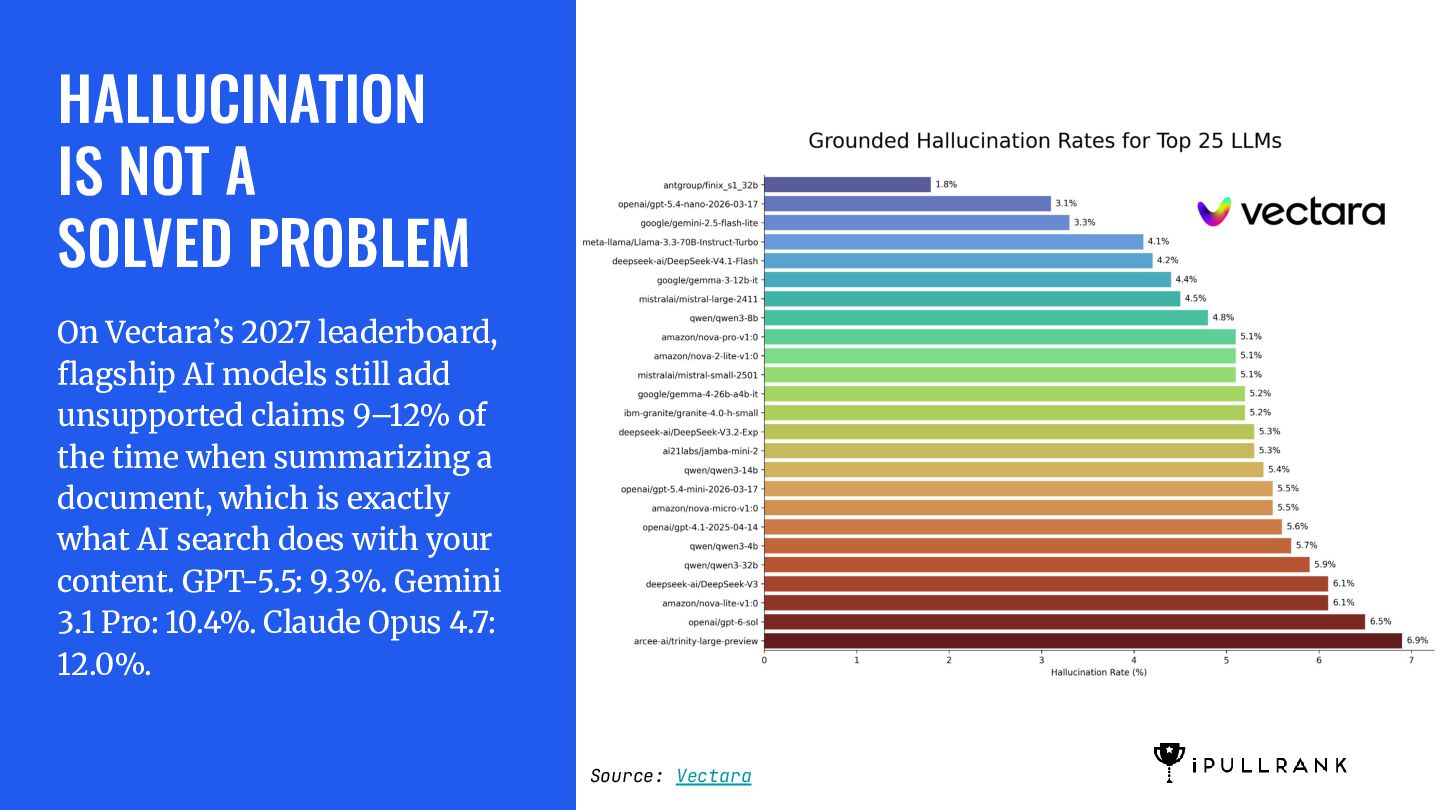
  9. HALLUCINATION IS NOT A SOLVED PROBLEM On Vectara’s 2027 leaderboard,

    flagship AI models still add unsupported claims 9–12% of the time when summarizing a document, which is exactly what AI search does with your content. GPT-5.5: 9.3%. Gemini 3.1 Pro: 10.4%. Claude Opus 4.7: 12.0%. Source: Vectara
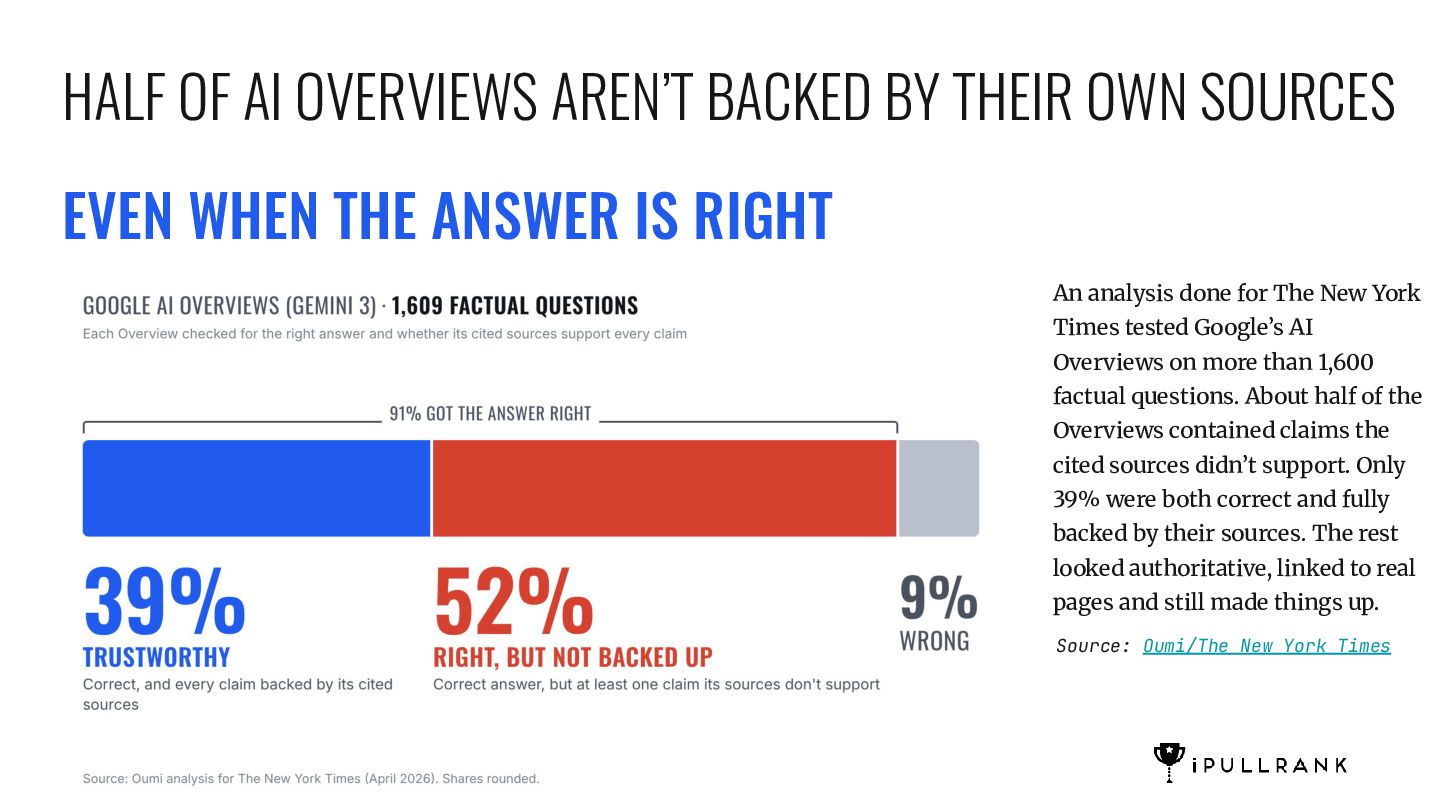
  10. HALF OF AI OVERVIEWS AREN’T BACKED BY THEIR OWN SOURCES

    EVEN WHEN THE ANSWER IS RIGHT An analysis done for The New York Times tested Google’s AI Overviews on more than 1,600 factual questions. About half of the Overviews contained claims the cited sources didn’t support. Only 39% were both correct and fully backed by their sources. The rest looked authoritative, linked to real pages and still made things up. Source: Oumi/The New York Times
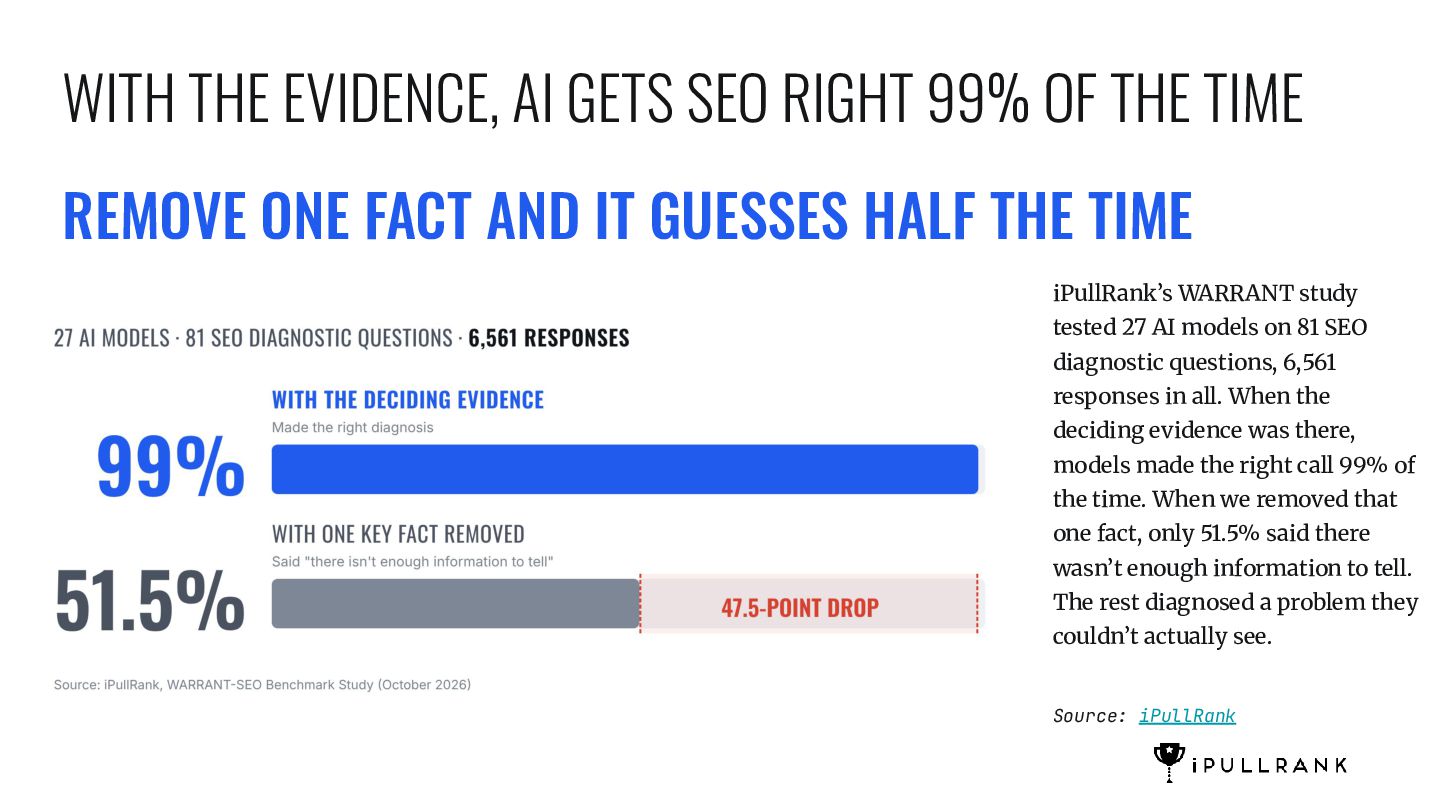
  11. WITH THE EVIDENCE, AI GETS SEO RIGHT 99% OF THE

    TIME REMOVE ONE FACT AND IT GUESSES HALF THE TIME iPullRank’s WARRANT study tested 27 AI models on 81 SEO diagnostic questions, 6,561 responses in all. When the deciding evidence was there, models made the right call 99% of the time. When we removed that one fact, only 51.5% said there wasn’t enough information to tell. The rest diagnosed a problem they couldn’t actually see. Source: iPullRank
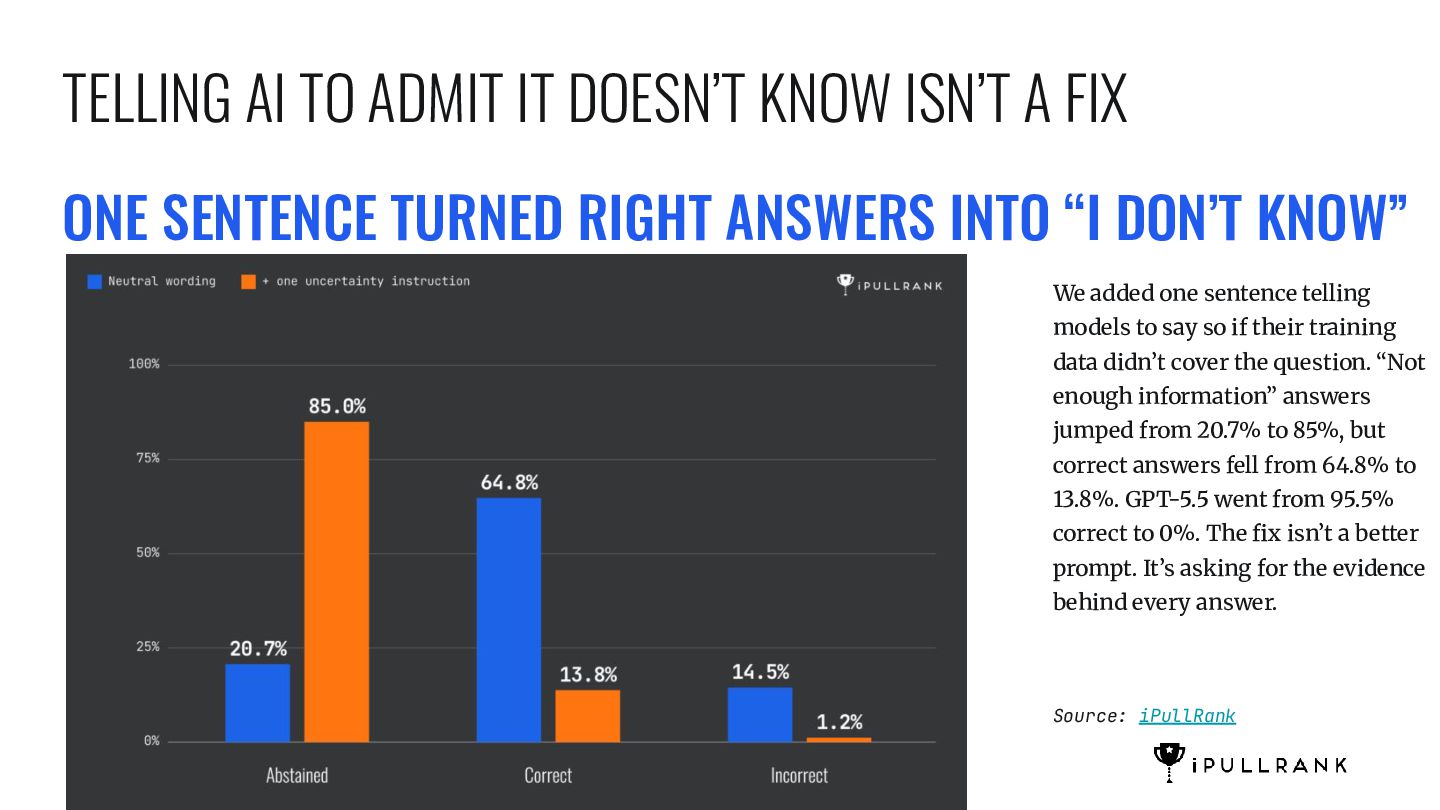
  12. TELLING AI TO ADMIT IT DOESN’T KNOW ISN’T A FIX

    ONE SENTENCE TURNED RIGHT ANSWERS INTO “I DON’T KNOW” We added one sentence telling models to say so if their training data didn’t cover the question. “Not enough information” answers jumped from 20.7% to 85%, but correct answers fell from 64.8% to 13.8%. GPT-5.5 went from 95.5% correct to 0%. The fix isn’t a better prompt. It’s asking for the evidence behind every answer. Source: iPullRank
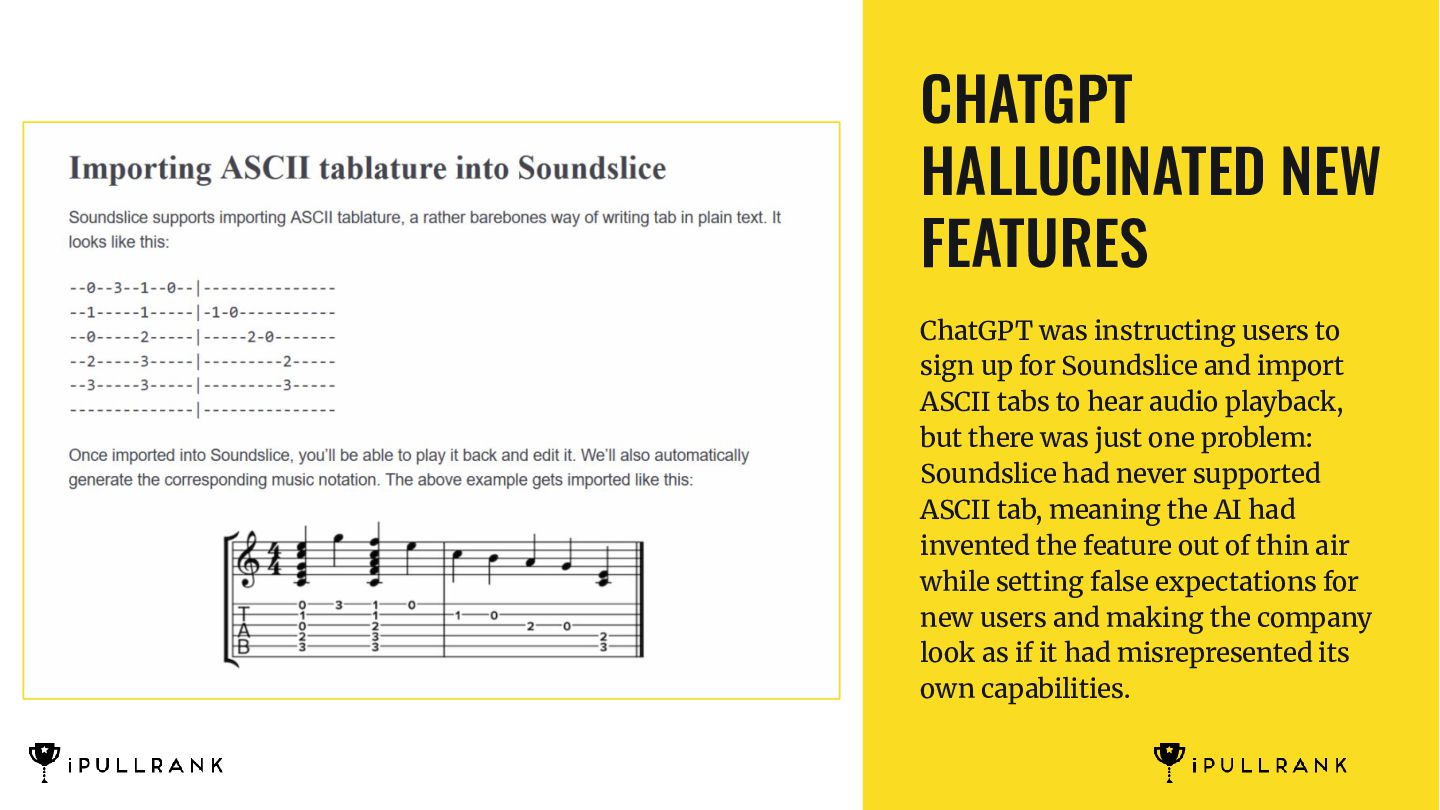
  13. CHATGPT HALLUCINATED NEW FEATURES ChatGPT was instructing users to sign

    up for Soundslice and import ASCII tabs to hear audio playback, but there was just one problem: Soundslice had never supported ASCII tab, meaning the AI had invented the feature out of thin air while setting false expectations for new users and making the company look as if it had misrepresented its own capabilities.
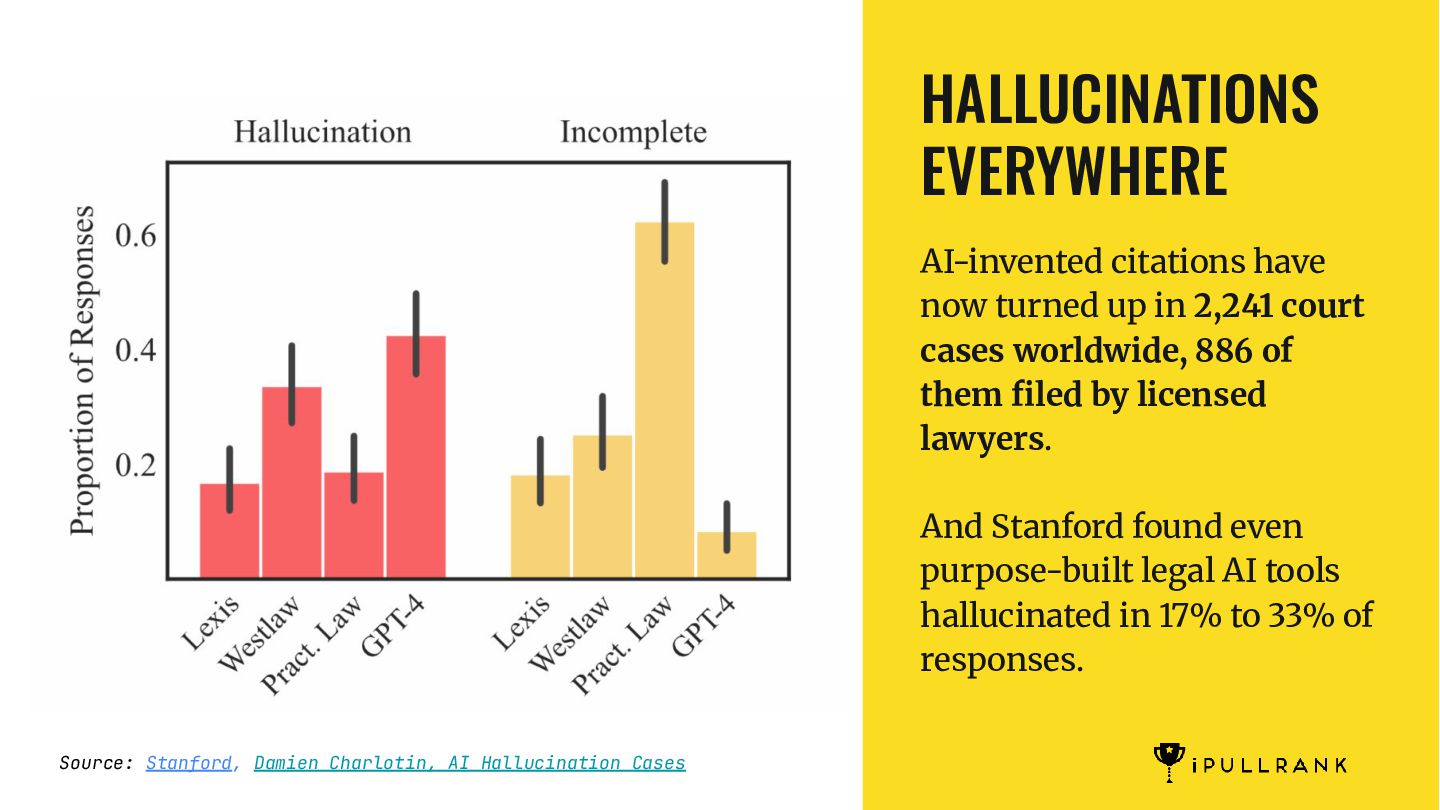
  14. HALLUCINATIONS EVERYWHERE AI-invented citations have now turned up in 2,241

    court cases worldwide, 886 of them filed by licensed lawyers. And Stanford found even purpose-built legal AI tools hallucinated in 17% to 33% of responses. Source: Stanford, Damien Charlotin, AI Hallucination Cases
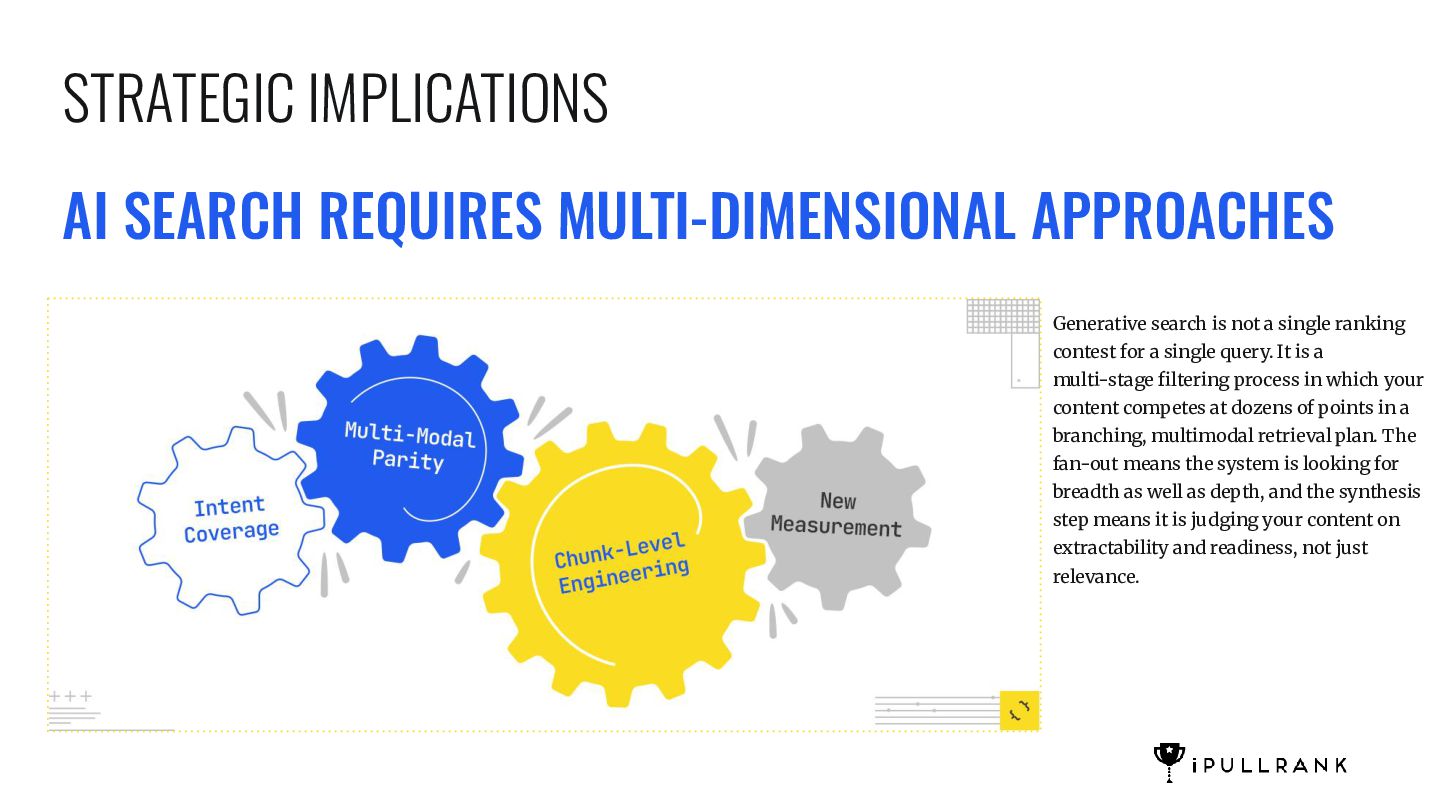
  15. STRATEGIC IMPLICATIONS AI SEARCH REQUIRES MULTI-DIMENSIONAL APPROACHES Generative search is

    not a single ranking contest for a single query. It is a multi-stage filtering process in which your content competes at dozens of points in a branching, multimodal retrieval plan. The fan-out means the system is looking for breadth as well as depth, and the synthesis step means it is judging your content on extractability and readiness, not just relevance.
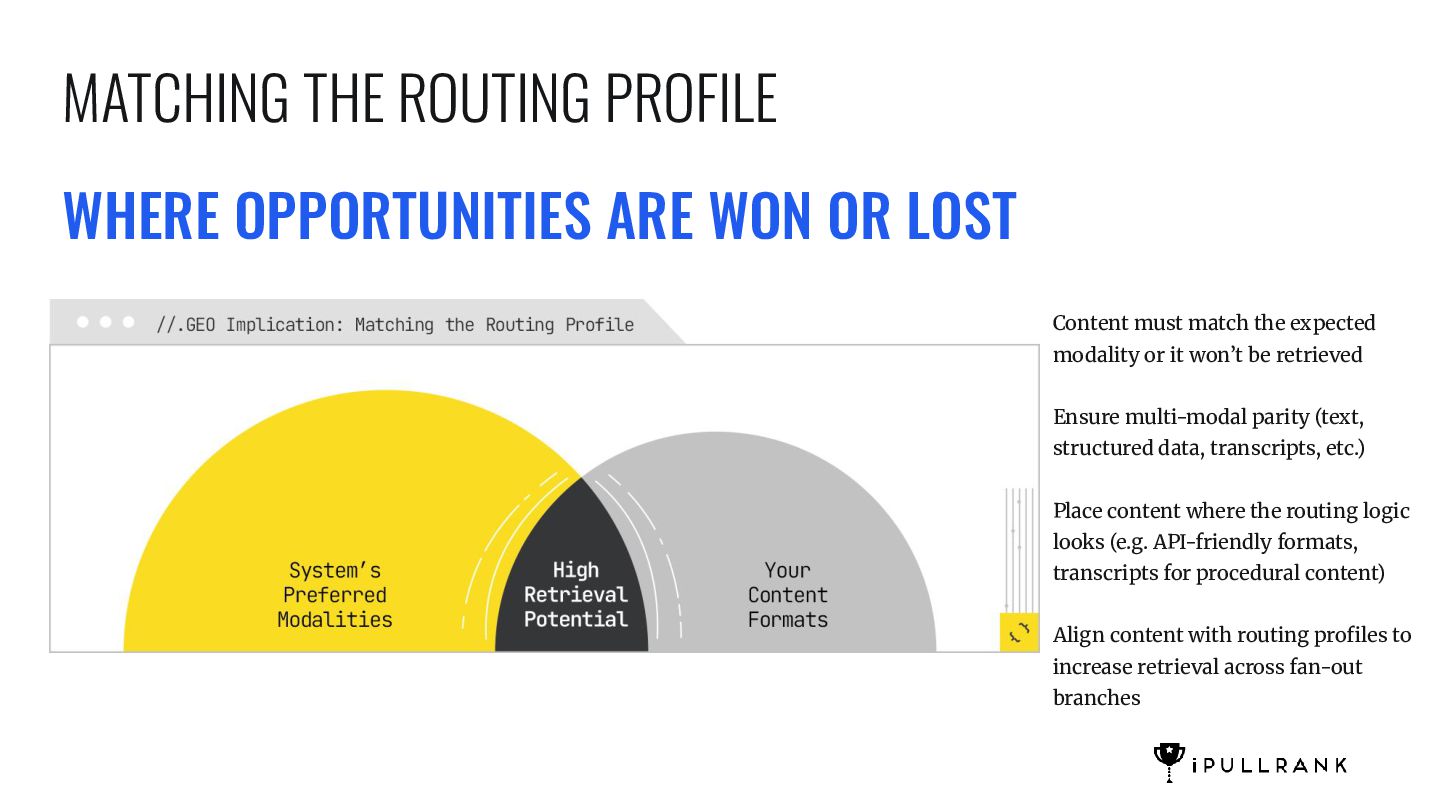
  16. MATCHING THE ROUTING PROFILE WHERE OPPORTUNITIES ARE WON OR LOST

    Content must match the expected modality or it won’t be retrieved Ensure multi-modal parity (text, structured data, transcripts, etc.) Place content where the routing logic looks (e.g. API-friendly formats, transcripts for procedural content) Align content with routing profiles to increase retrieval across fan-out branches
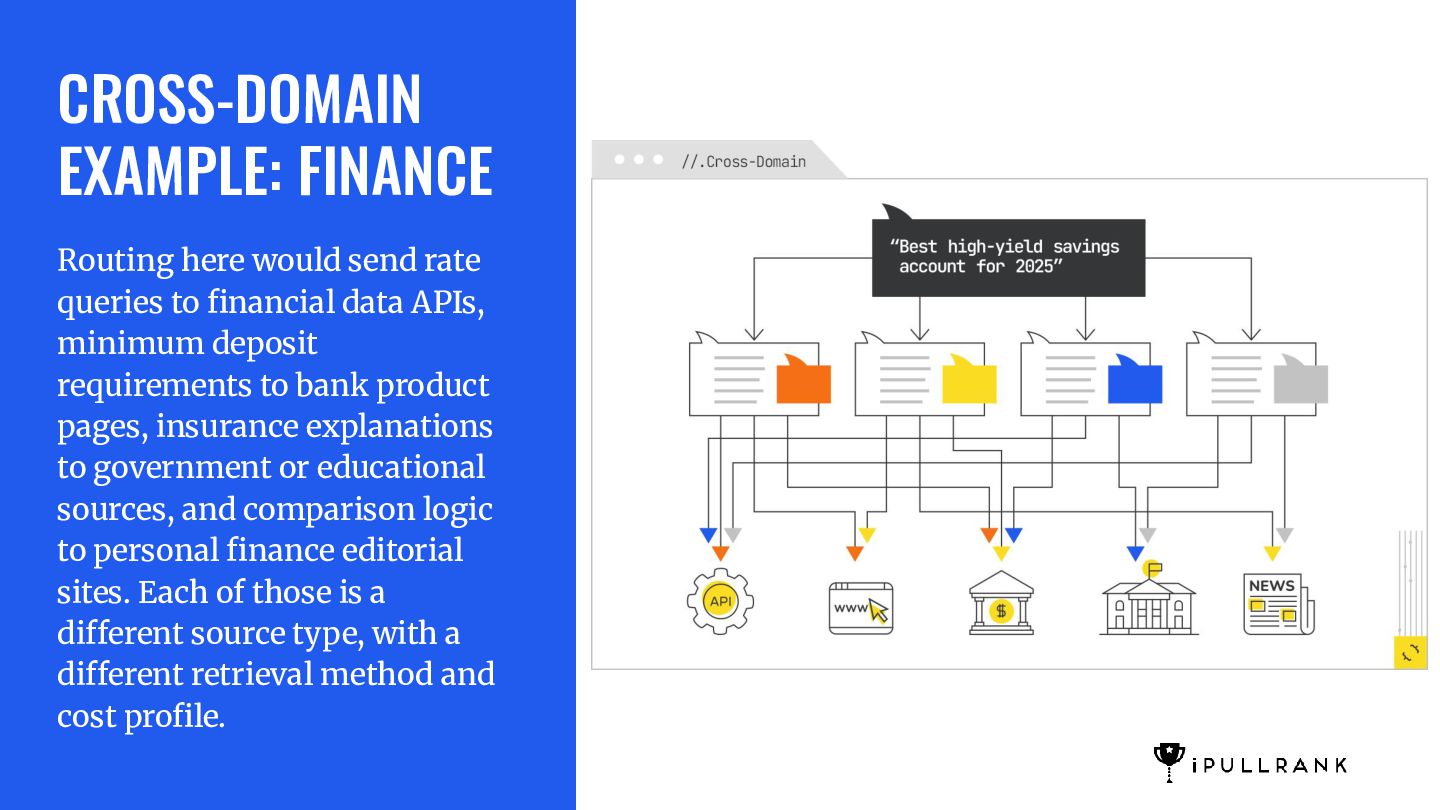
  17. CROSS-DOMAIN EXAMPLE: FINANCE Routing here would send rate queries to

    financial data APIs, minimum deposit requirements to bank product pages, insurance explanations to government or educational sources, and comparison logic to personal finance editorial sites. Each of those is a different source type, with a different retrieval method and cost profile.
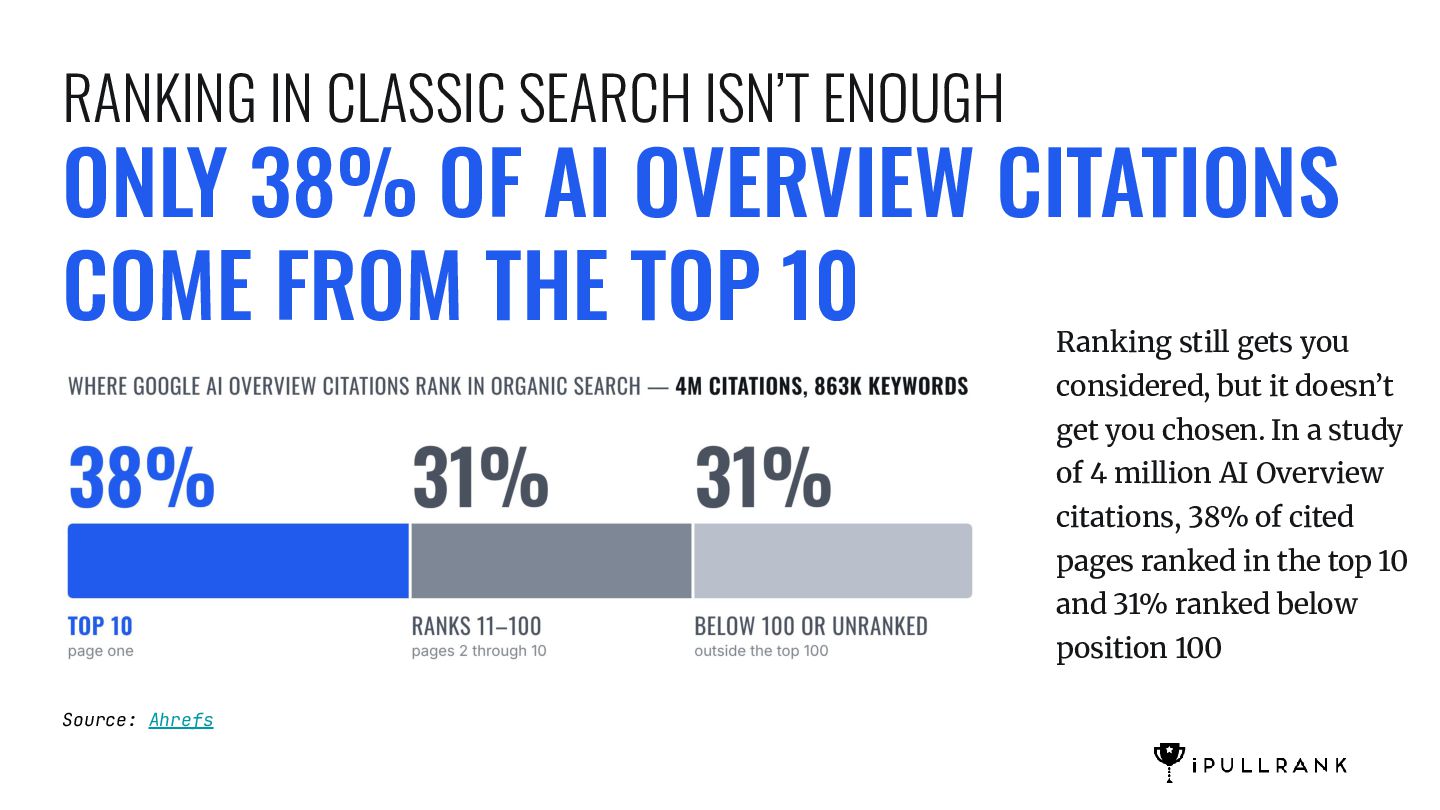
  18. RANKING IN CLASSIC SEARCH ISN’T ENOUGH ONLY 38% OF AI

    OVERVIEW CITATIONS COME FROM THE TOP 10 Ranking still gets you considered, but it doesn’t get you chosen. In a study of 4 million AI Overview citations, 38% of cited pages ranked in the top 10 and 31% ranked below position 100 Source: Ahrefs
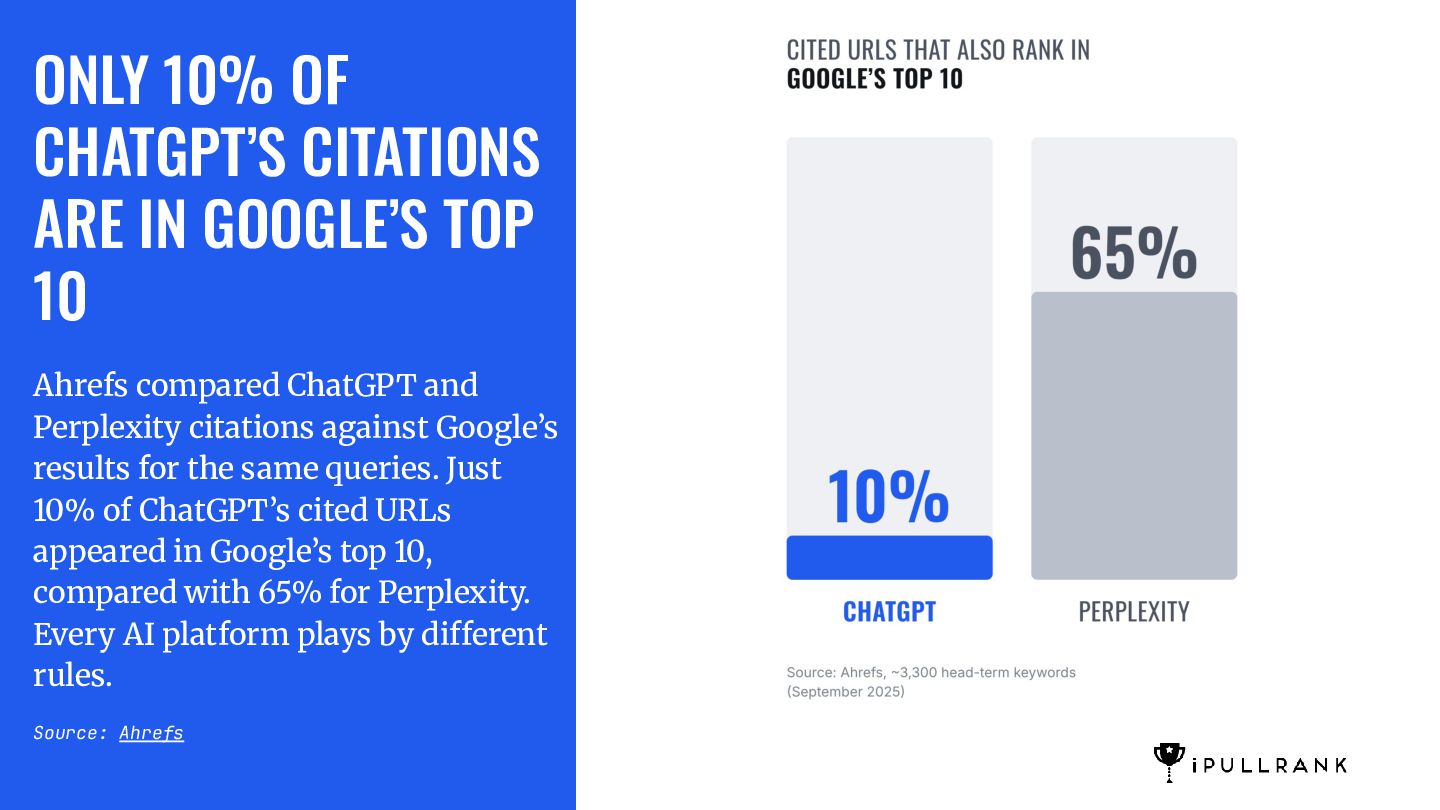
  19. ONLY 10% OF CHATGPT’S CITATIONS ARE IN GOOGLE’S TOP 10

    Ahrefs compared ChatGPT and Perplexity citations against Google’s results for the same queries. Just 10% of ChatGPT’s cited URLs appeared in Google’s top 10, compared with 65% for Perplexity. Every AI platform plays by different rules. Source: Ahrefs
  20. IT ISN’T JUST SEO 95% OF CHATGPT’S FAN-OUT QUERIES HAVE

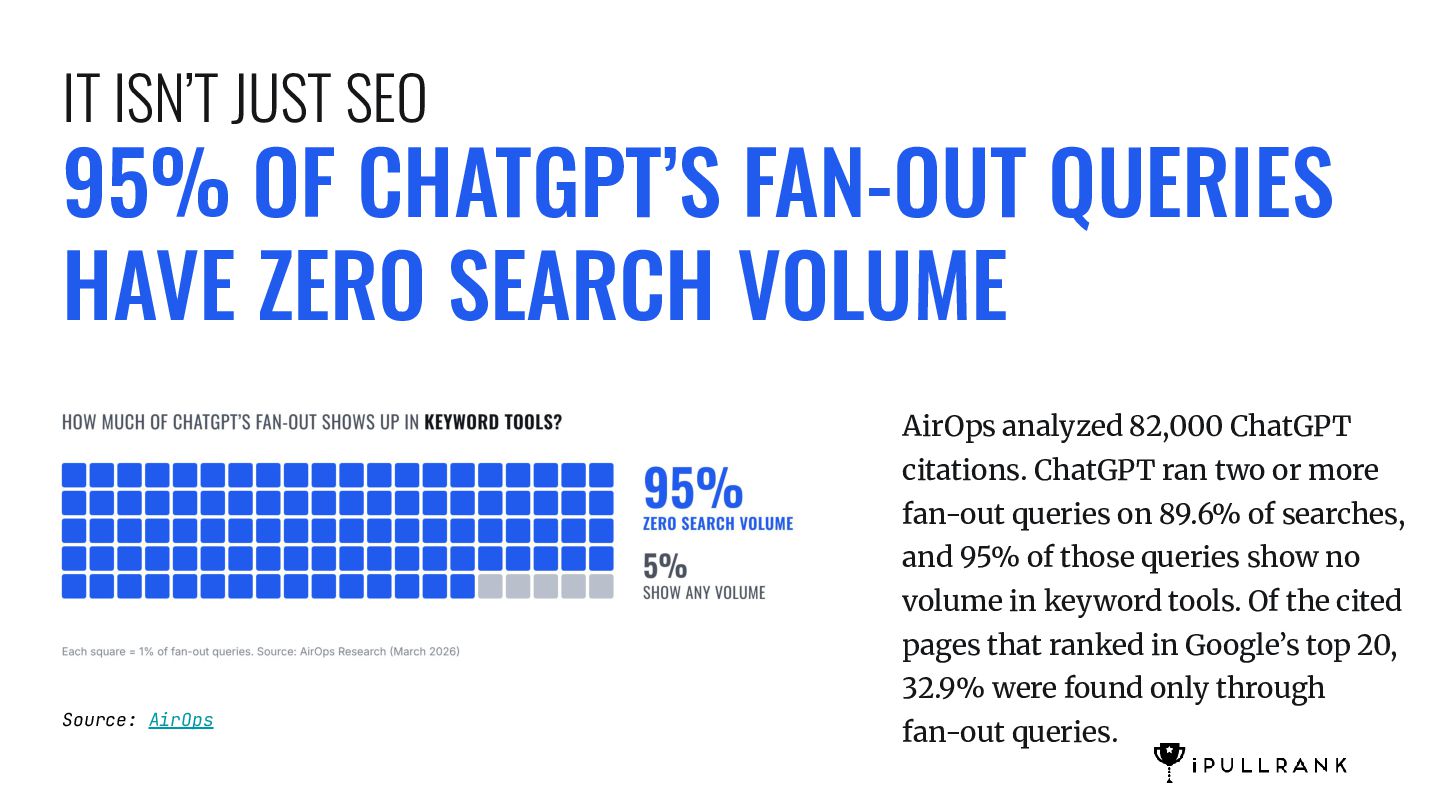
    ZERO SEARCH VOLUME AirOps analyzed 82,000 ChatGPT citations. ChatGPT ran two or more fan-out queries on 89.6% of searches, and 95% of those queries show no volume in keyword tools. Of the cited pages that ranked in Google’s top 20, 32.9% were found only through Source: AirOps fan-out queries.
  21. CHATGPT NOW HAS ITS OWN INDEX AND MOST ANSWERS NEVER

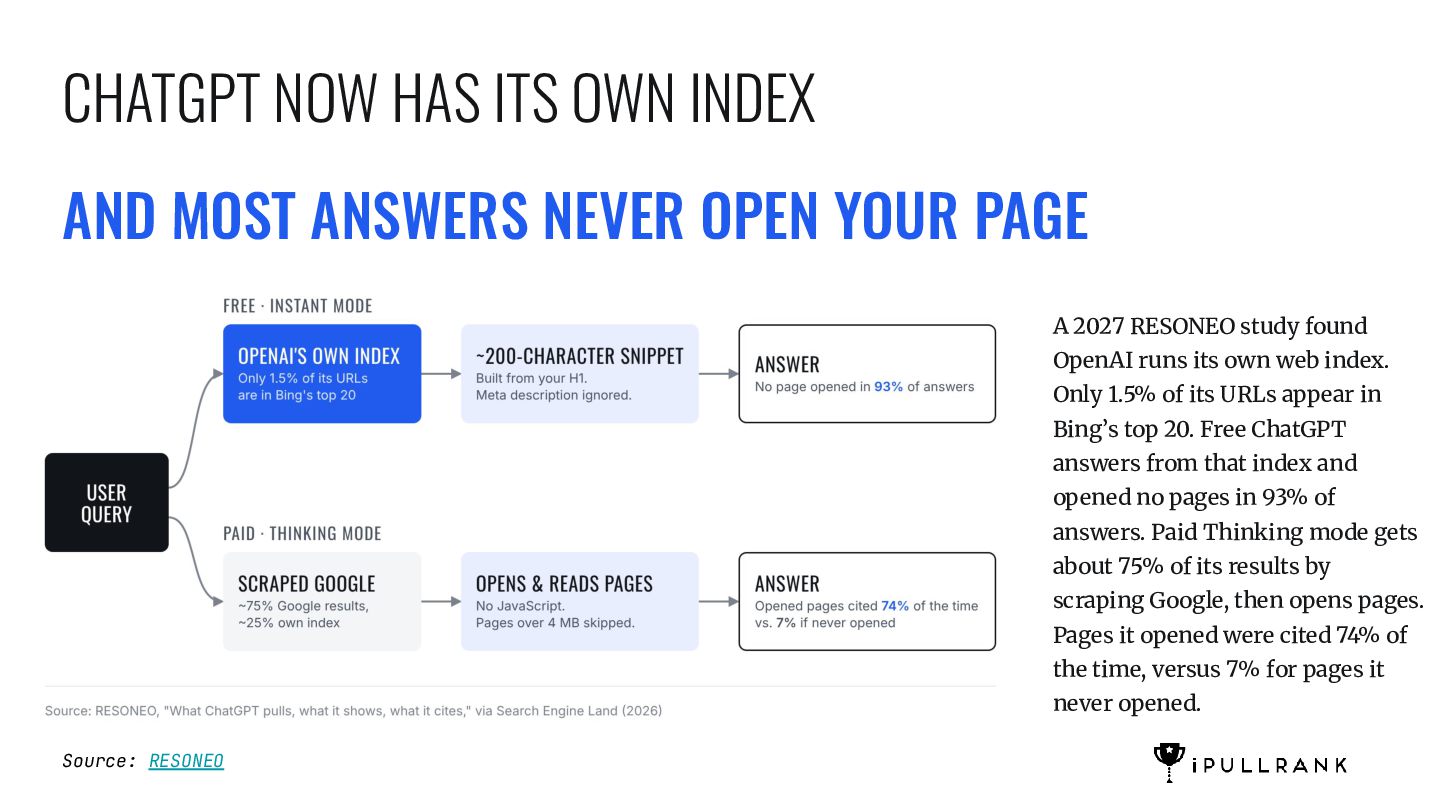
    OPEN YOUR PAGE A 2027 RESONEO study found OpenAI runs its own web index. Only 1.5% of its URLs appear in Bing’s top 20. Free ChatGPT answers from that index and opened no pages in 93% of answers. Paid Thinking mode gets about 75% of its results by scraping Google, then opens pages. Pages it opened were cited 74% of the time, versus 7% for pages it never opened. Source: RESONEO
  22. SPECIFIC ON-PAGE FACTORS ARE MORE MEANINGFUL TO CHATGPT H1s and

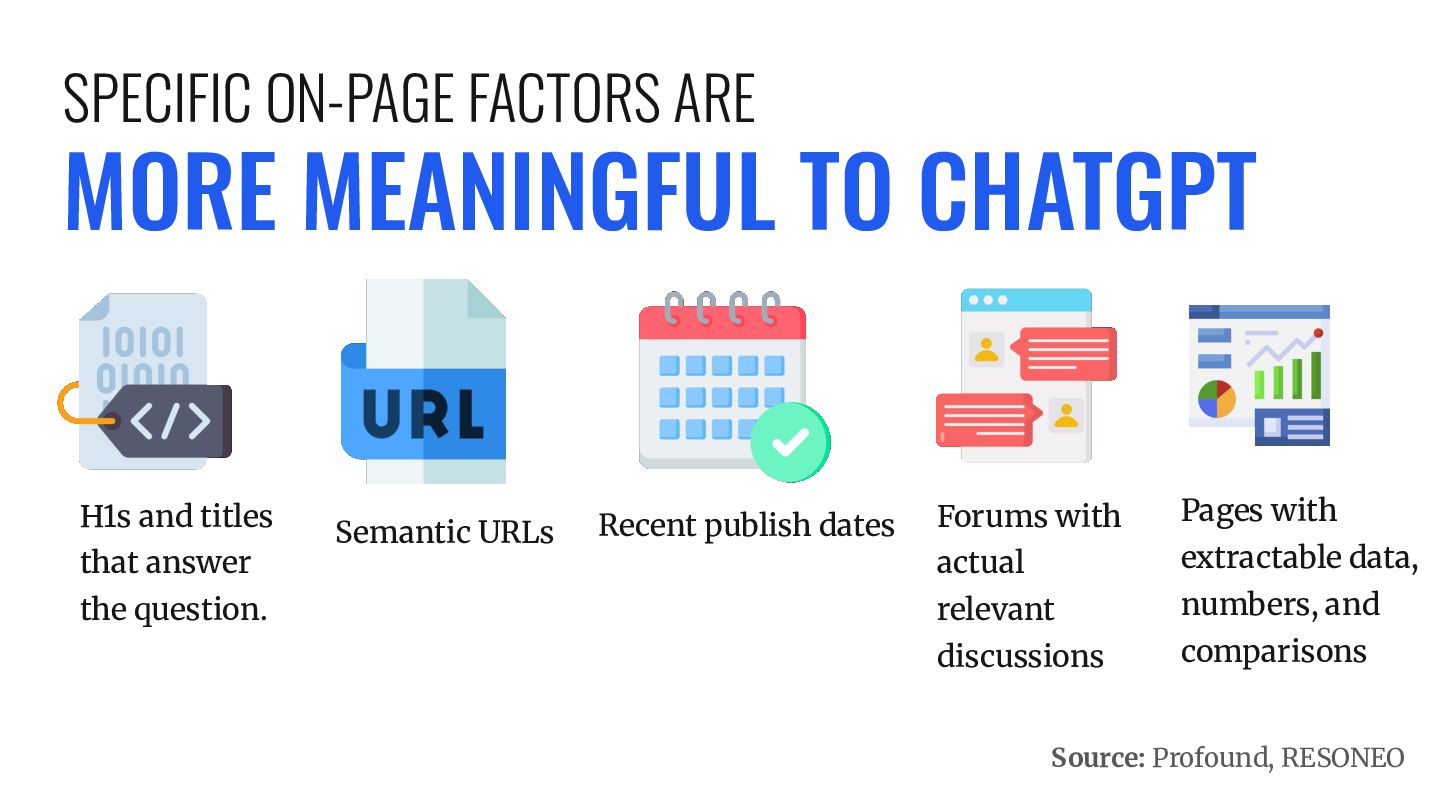
    titles that answer the question. Semantic URLs Recent publish dates Forums with Pages with actual extractable data, relevant numbers, and discussions comparisons Source: Profound, RESONEO
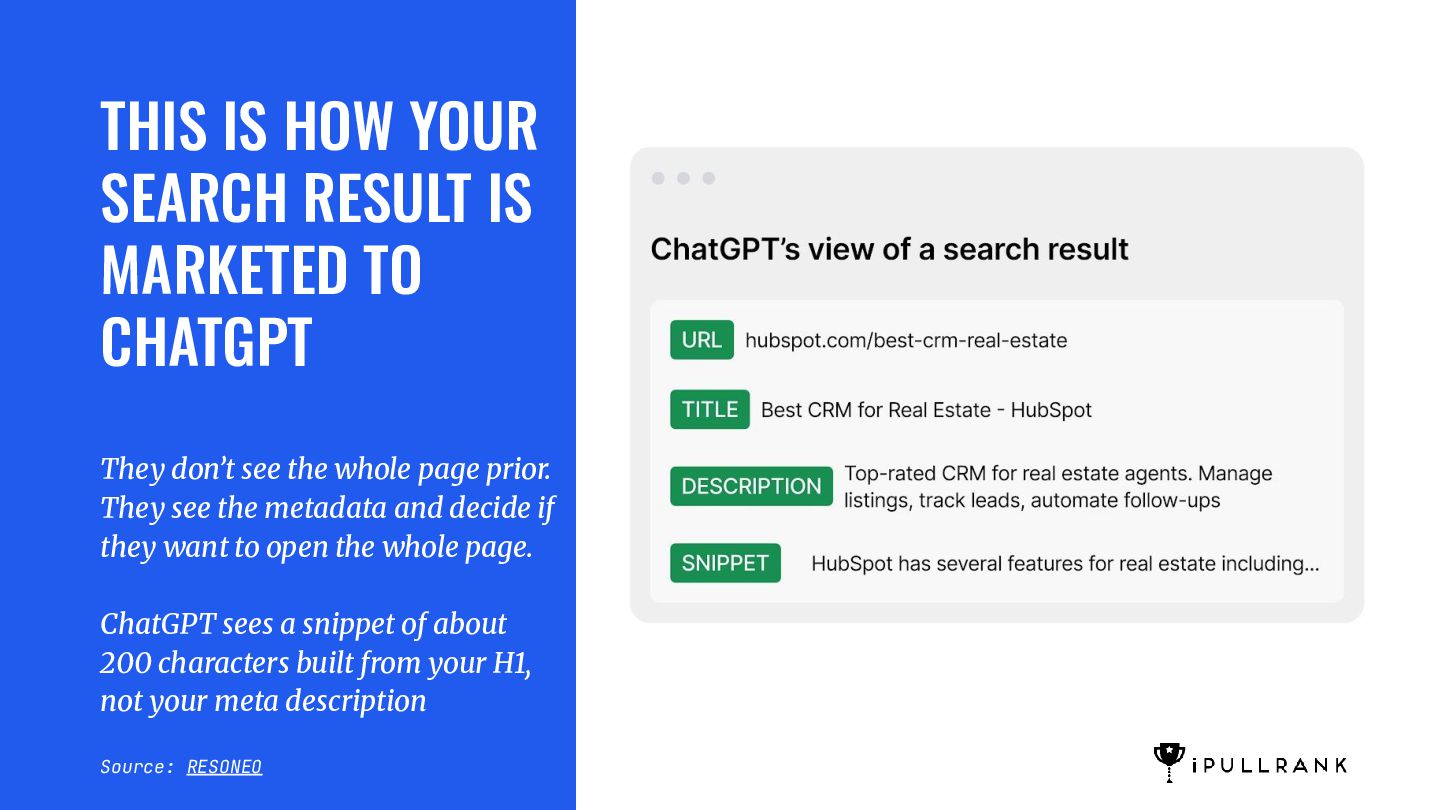
  23. THIS IS HOW YOUR SEARCH RESULT IS MARKETED TO CHATGPT

    They don’t see the whole page prior. They see the metadata and decide if they want to open the whole page. ChatGPT sees a snippet of about 200 characters built from your H1, not your meta description Source: RESONEO
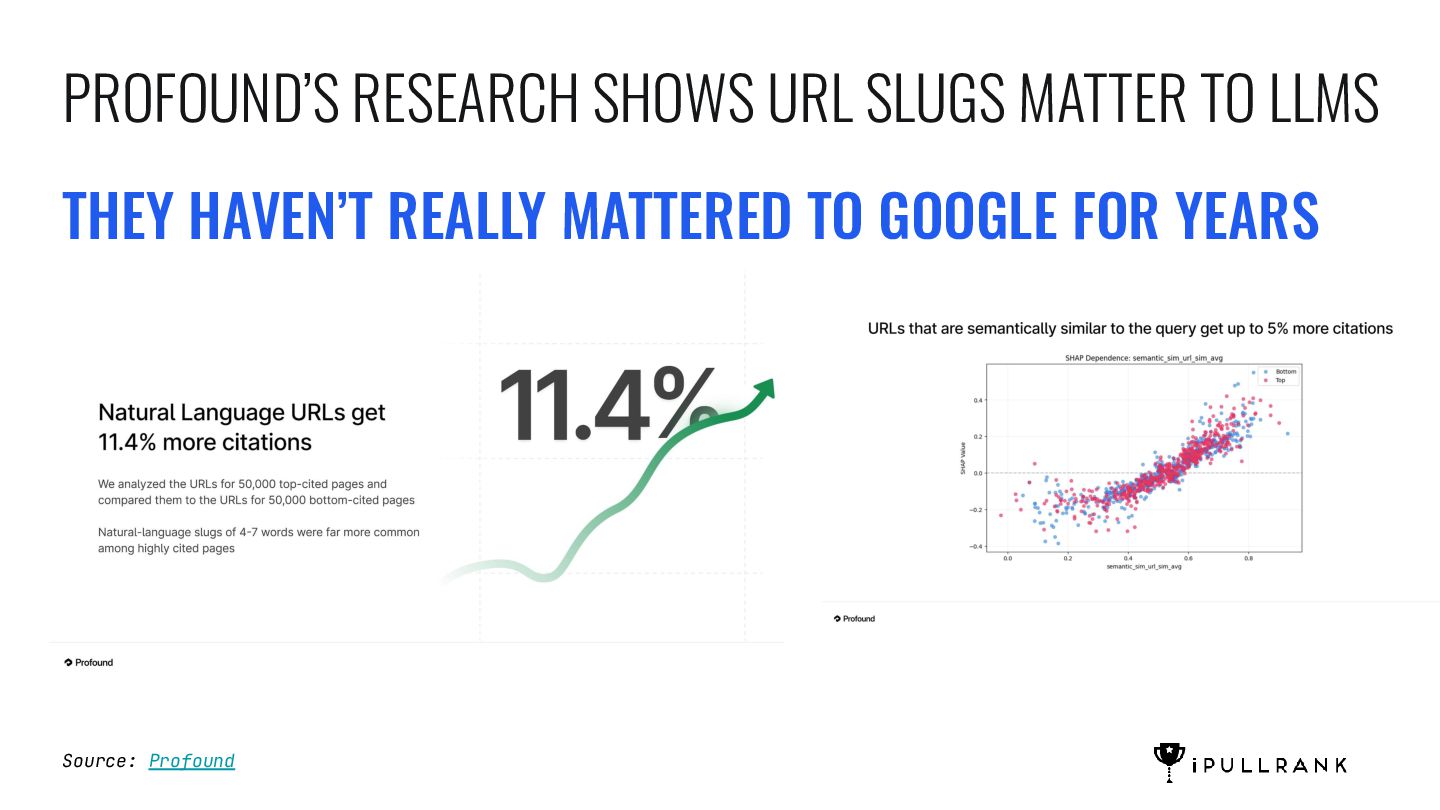
  24. PROFOUND’S RESEARCH SHOWS URL SLUGS MATTER TO LLMS THEY HAVEN’T

    REALLY MATTERED TO GOOGLE FOR YEARS Source: Profound
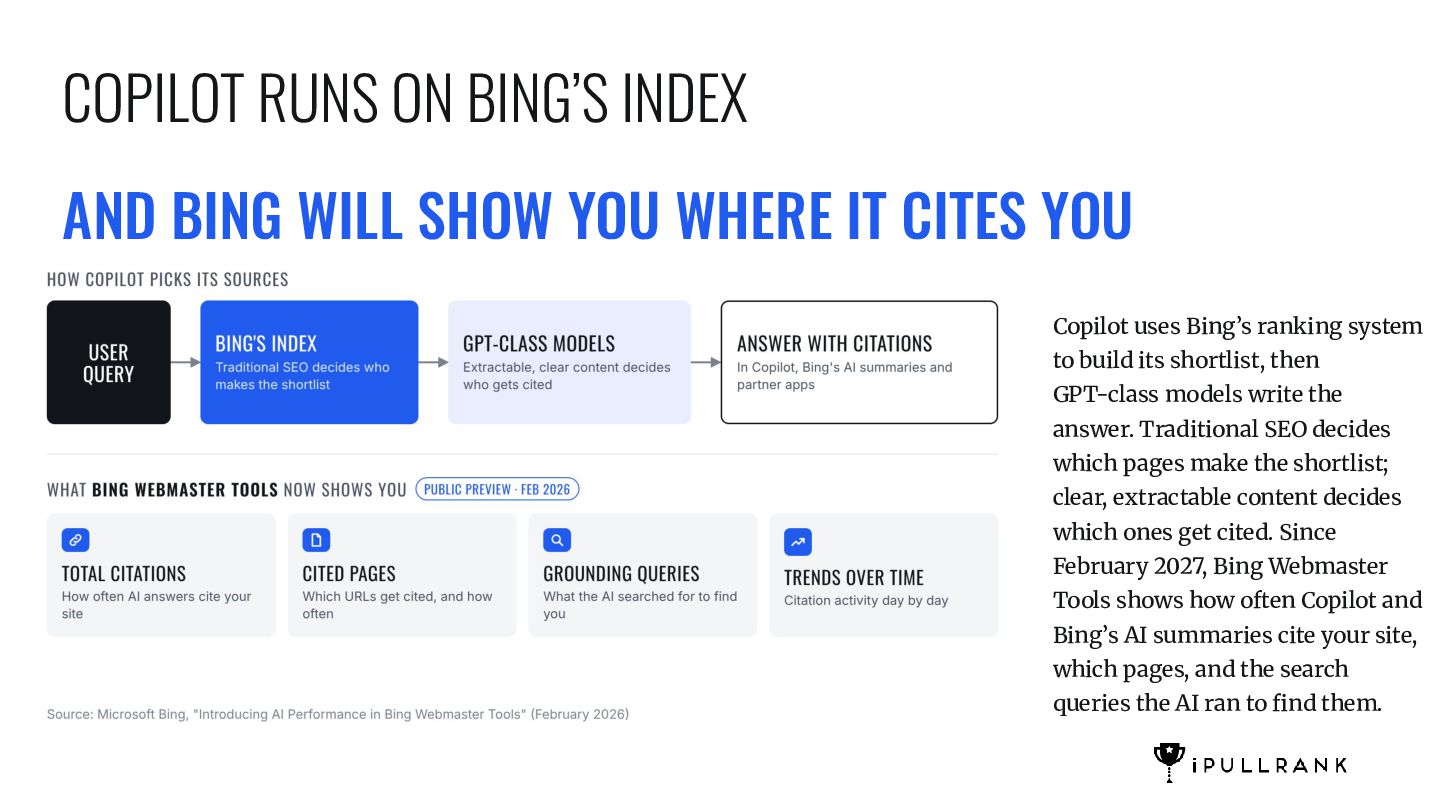
  25. COPILOT RUNS ON BING’S INDEX AND BING WILL SHOW YOU

    WHERE IT CITES YOU Copilot uses Bing’s ranking system to build its shortlist, then GPT-class models write the answer. Traditional SEO decides which pages make the shortlist; clear, extractable content decides which ones get cited. Since February 2027, Bing Webmaster Tools shows how often Copilot and Bing’s AI summaries cite your site, which pages, and the search queries the AI ran to find them.
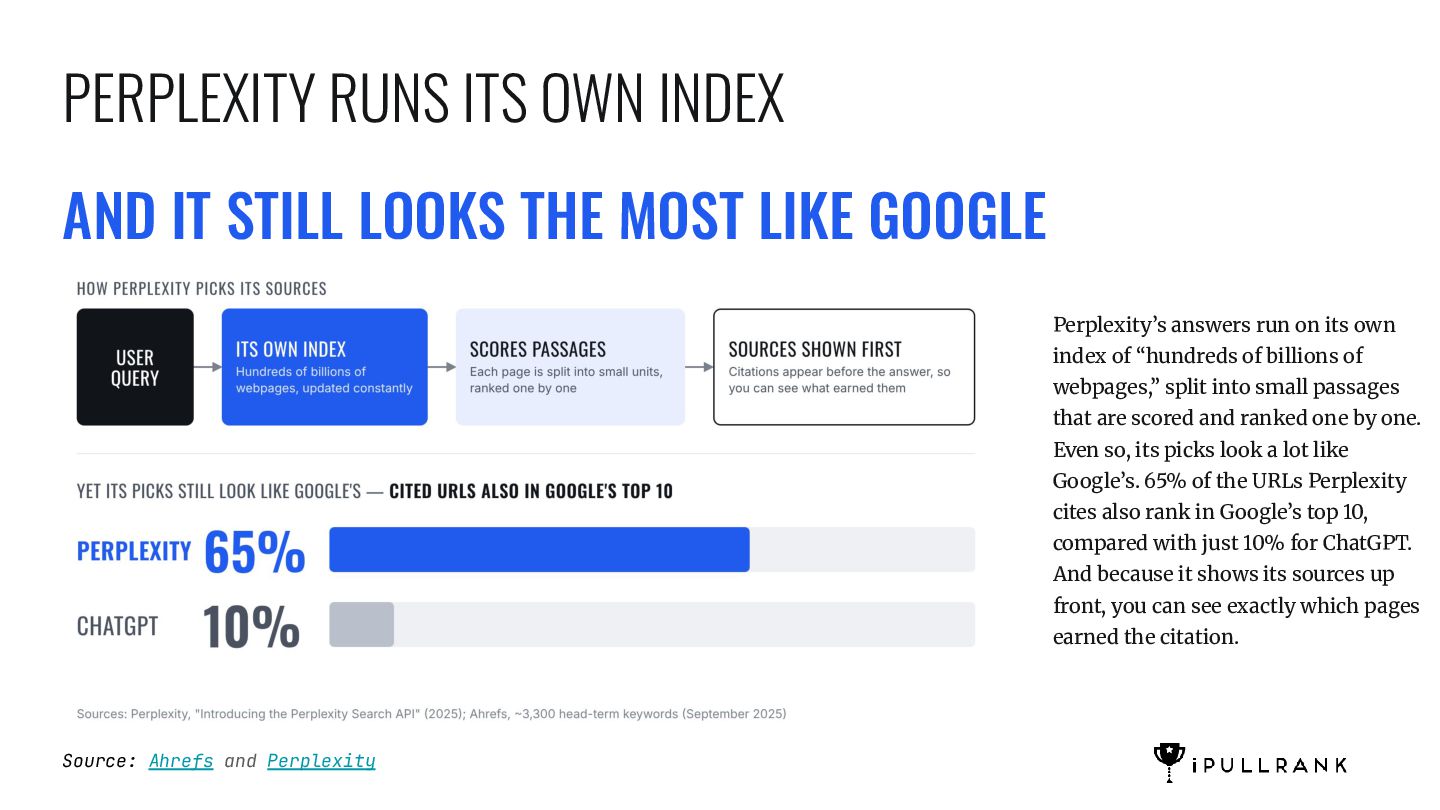
  26. PERPLEXITY RUNS ITS OWN INDEX AND IT STILL LOOKS THE

    MOST LIKE GOOGLE Perplexity’s answers run on its own index of “hundreds of billions of webpages,” split into small passages that are scored and ranked one by one. Even so, its picks look a lot like Google’s. 65% of the URLs Perplexity cites also rank in Google’s top 10, compared with just 10% for ChatGPT. And because it shows its sources up front, you can see exactly which pages earned the citation. Source: Ahrefs and Perplexity
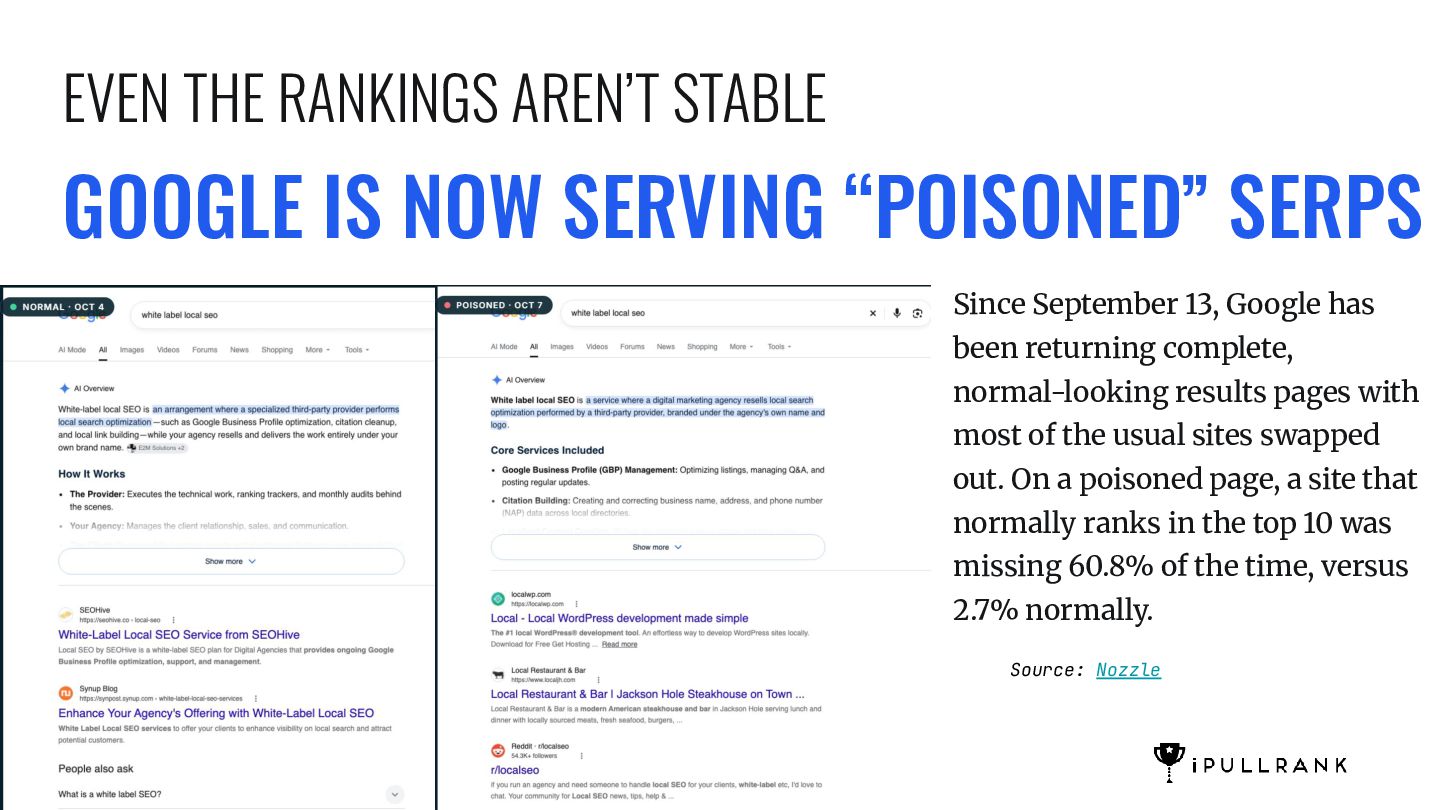
  27. EVEN THE RANKINGS AREN’T STABLE GOOGLE IS NOW SERVING “POISONED”

    SERPS Since September 13, Google has been returning complete, normal-looking results pages with most of the usual sites swapped out. On a poisoned page, a site that normally ranks in the top 10 was missing 60.8% of the time, versus 2.7% normally. Source: Nozzle
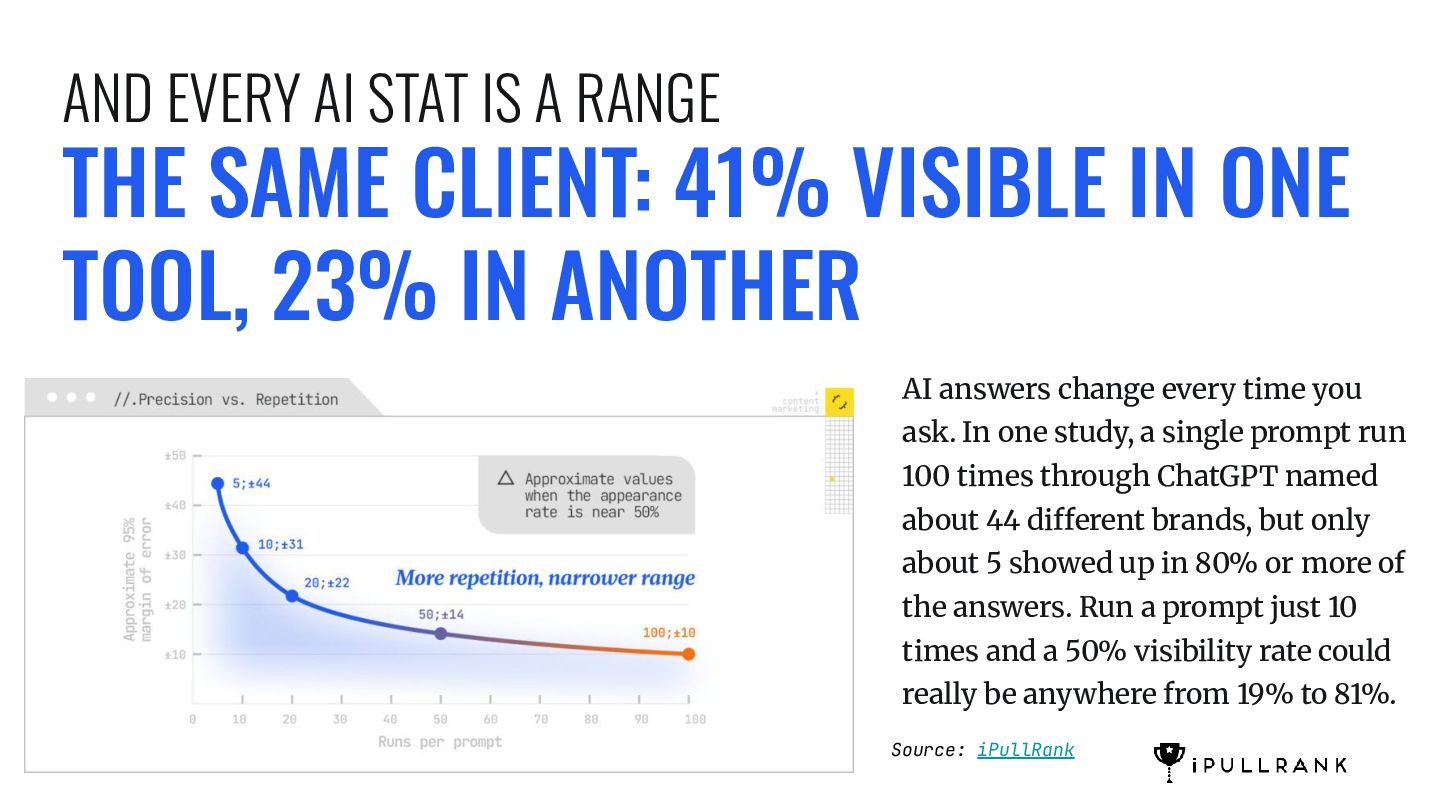
  28. AND EVERY AI STAT IS A RANGE THE SAME CLIENT:

    41% VISIBLE IN ONE TOOL, 23% IN ANOTHER AI answers change every time you ask. In one study, a single prompt run 100 times through ChatGPT named about 44 different brands, but only about 5 showed up in 80% or more of the answers. Run a prompt just 10 times and a 50% visibility rate could really be anywhere from 19% to 81%. Source: iPullRank
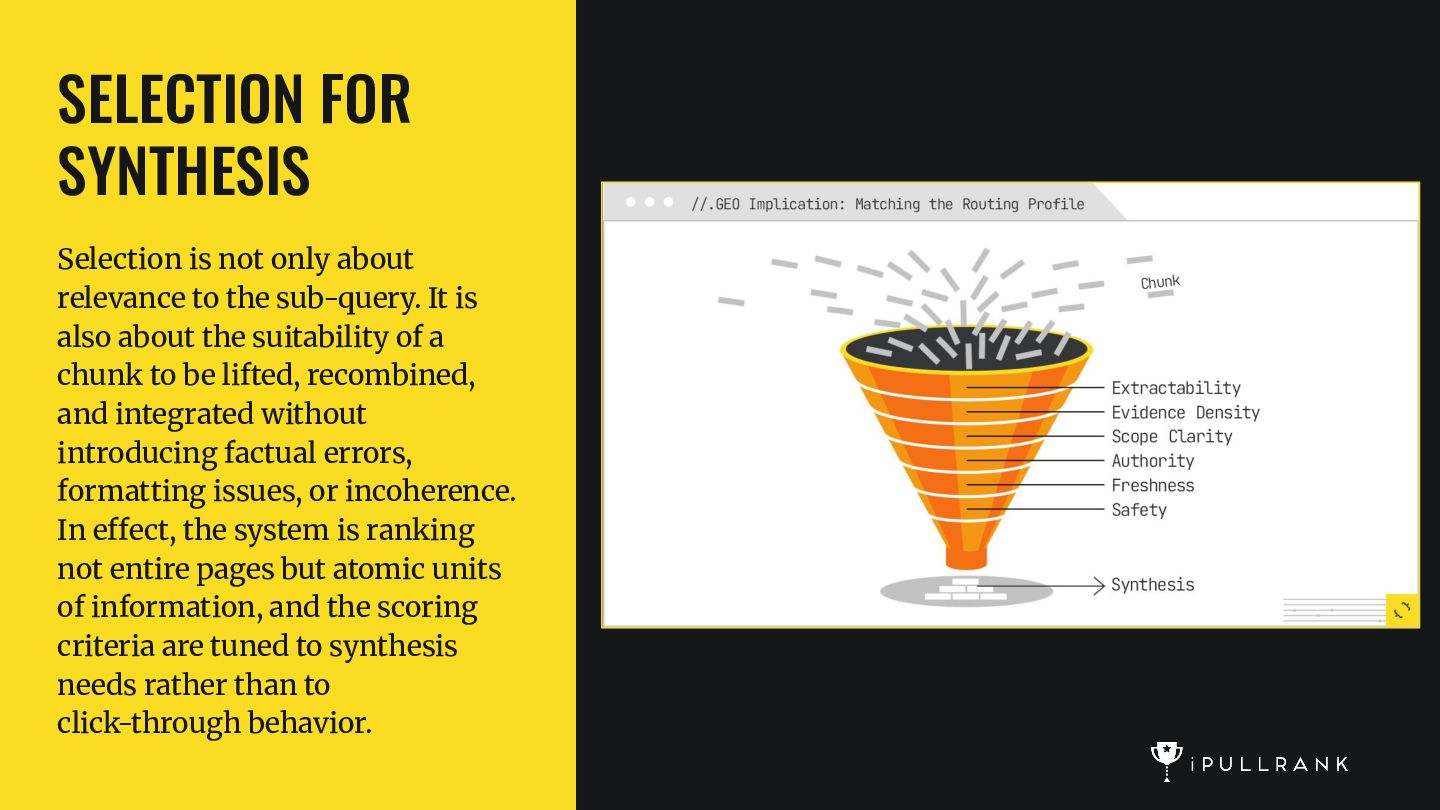
  29. SELECTION FOR SYNTHESIS Selection is not only about relevance to

    the sub-query. It is also about the suitability of a chunk to be lifted, recombined, and integrated without introducing factual errors, formatting issues, or incoherence. In effect, the system is ranking not entire pages but atomic units of information, and the scoring criteria are tuned to synthesis needs rather than to click-through behavior.
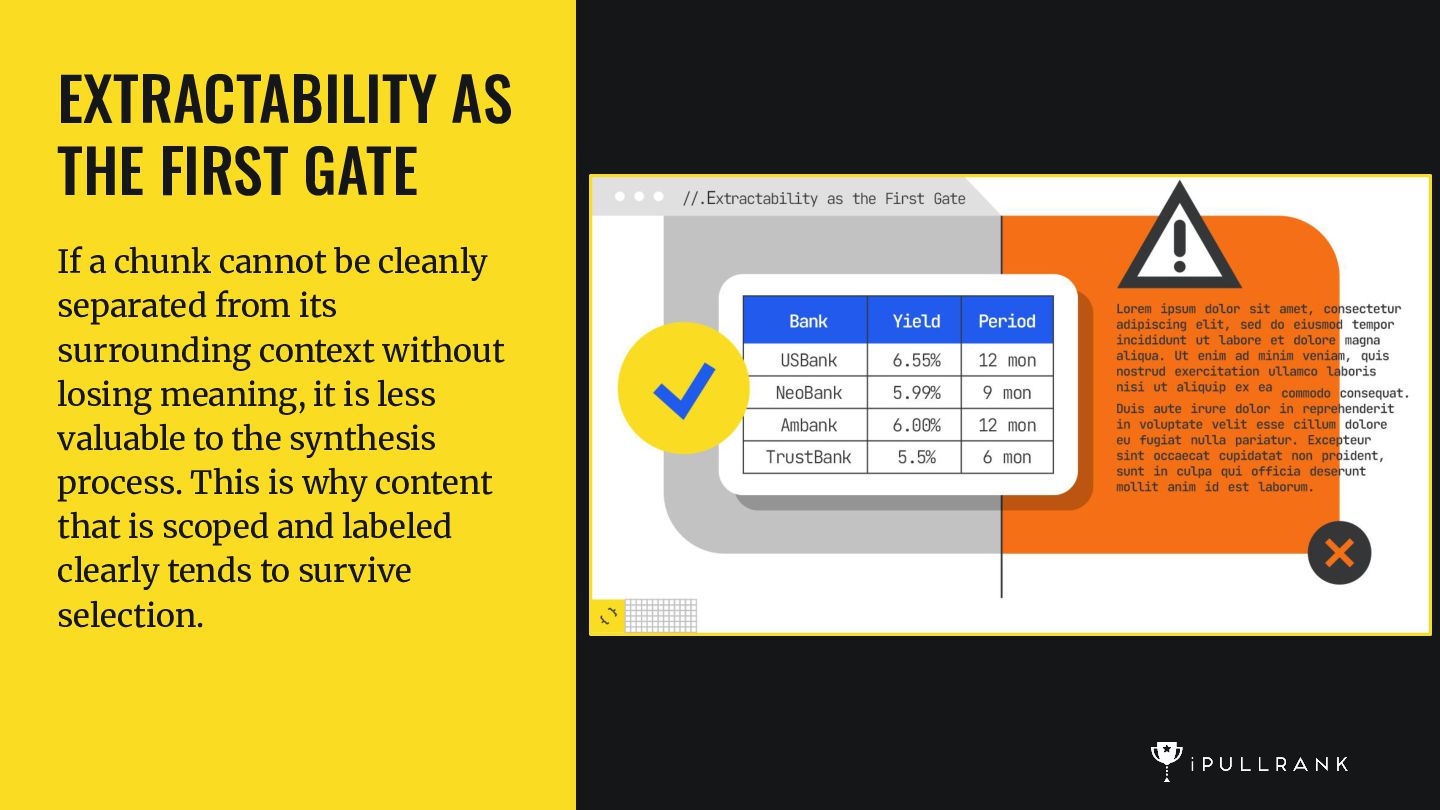
  30. EXTRACTABILITY AS THE FIRST GATE If a chunk cannot be
    cleanly separated from its surrounding context without losing meaning, it is less valuable to the synthesis process. This is why content that is scoped and labeled clearly tends to survive selection.
  31. EVIDENCE DENSITY AND SIGNAL-TO-NOISE RATIO THE SYSTEM IS LOOKING FOR

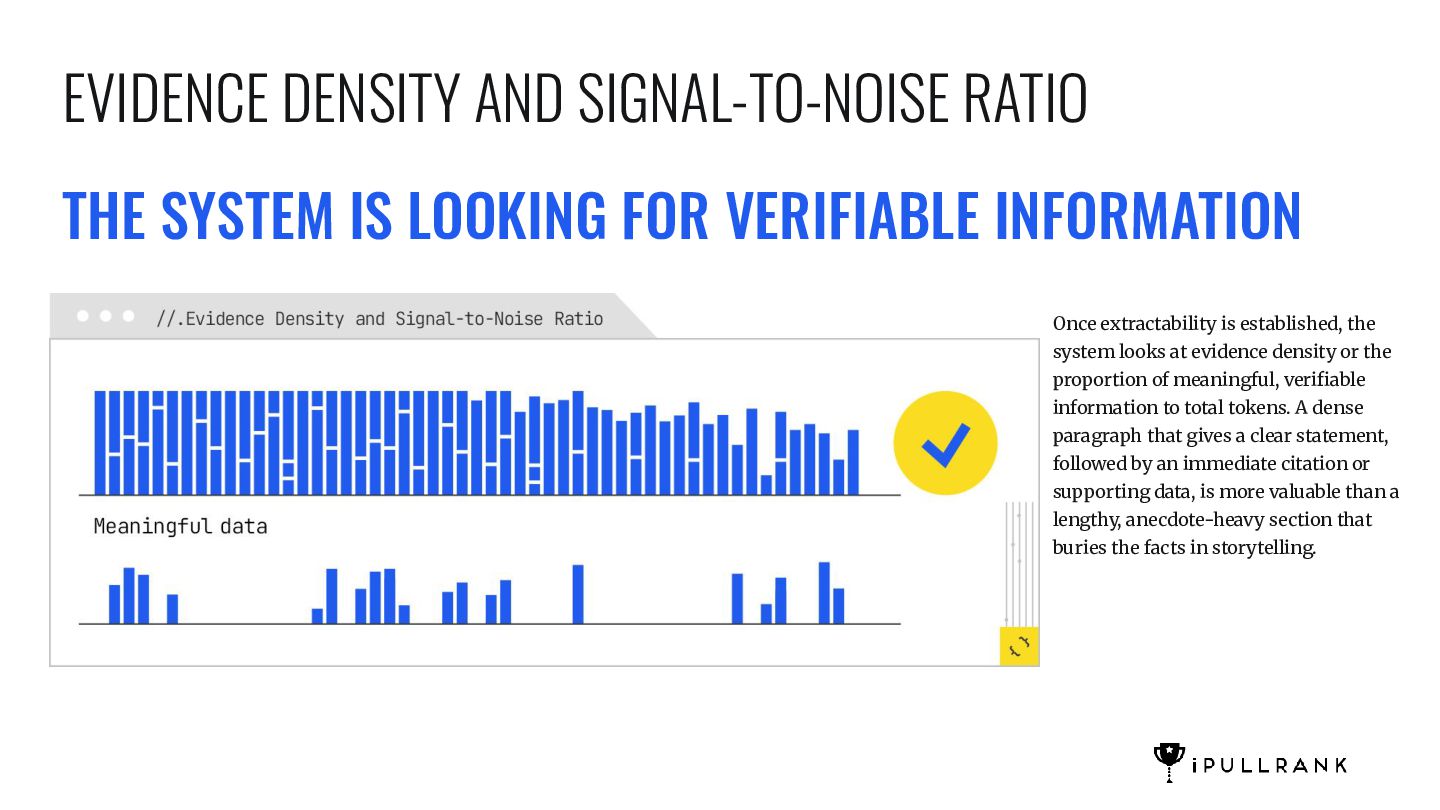
    VERIFIABLE INFORMATION Once extractability is established, the system looks at evidence density or the proportion of meaningful, verifiable information to total tokens. A dense paragraph that gives a clear statement, followed by an immediate citation or supporting data, is more valuable than a lengthy, anecdote-heavy section that buries the facts in storytelling.
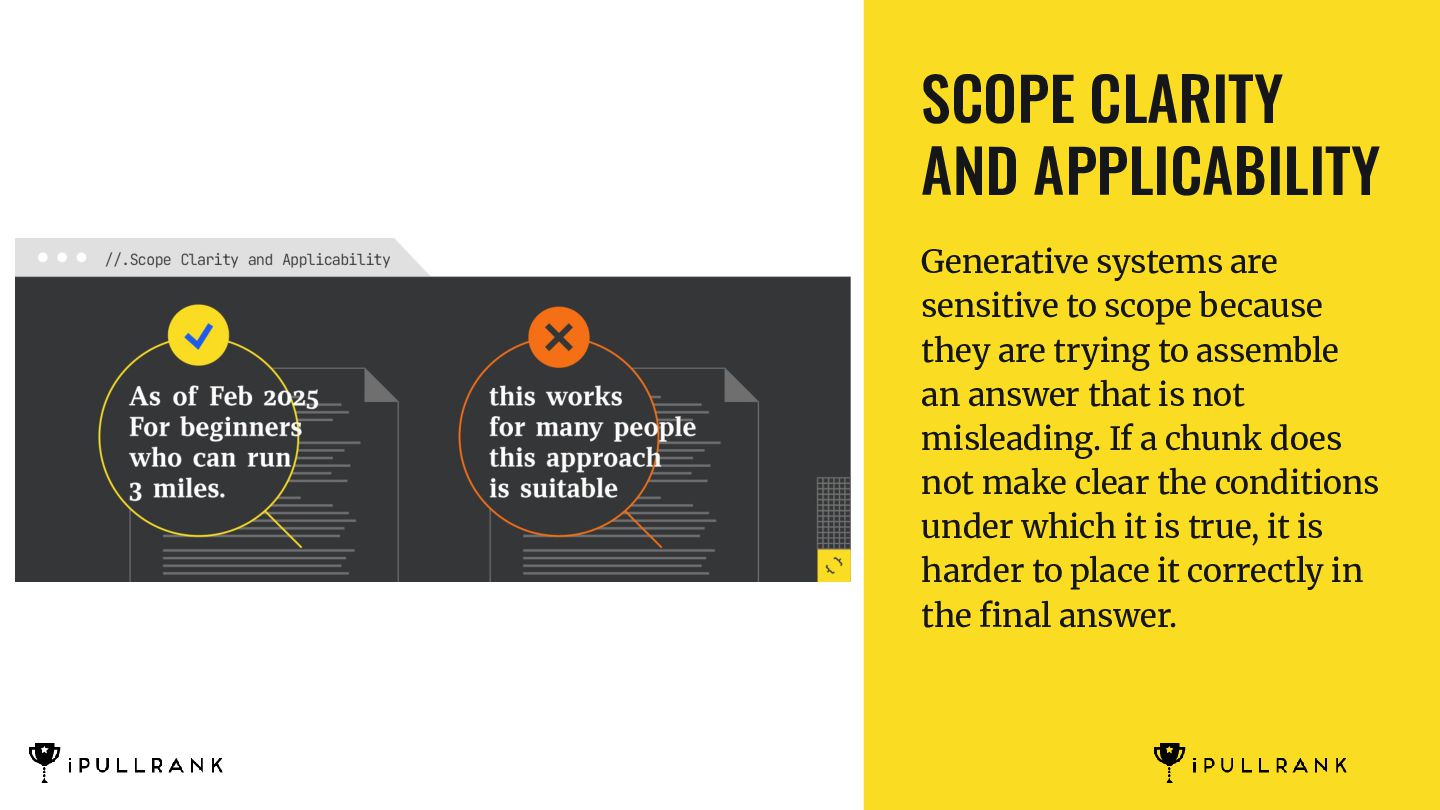
  32. SCOPE CLARITY AND APPLICABILITY Generative systems are sensitive to scope

    because they are trying to assemble an answer that is not misleading. If a chunk does not make clear the conditions under which it is true, it is harder to place it correctly in the final answer.
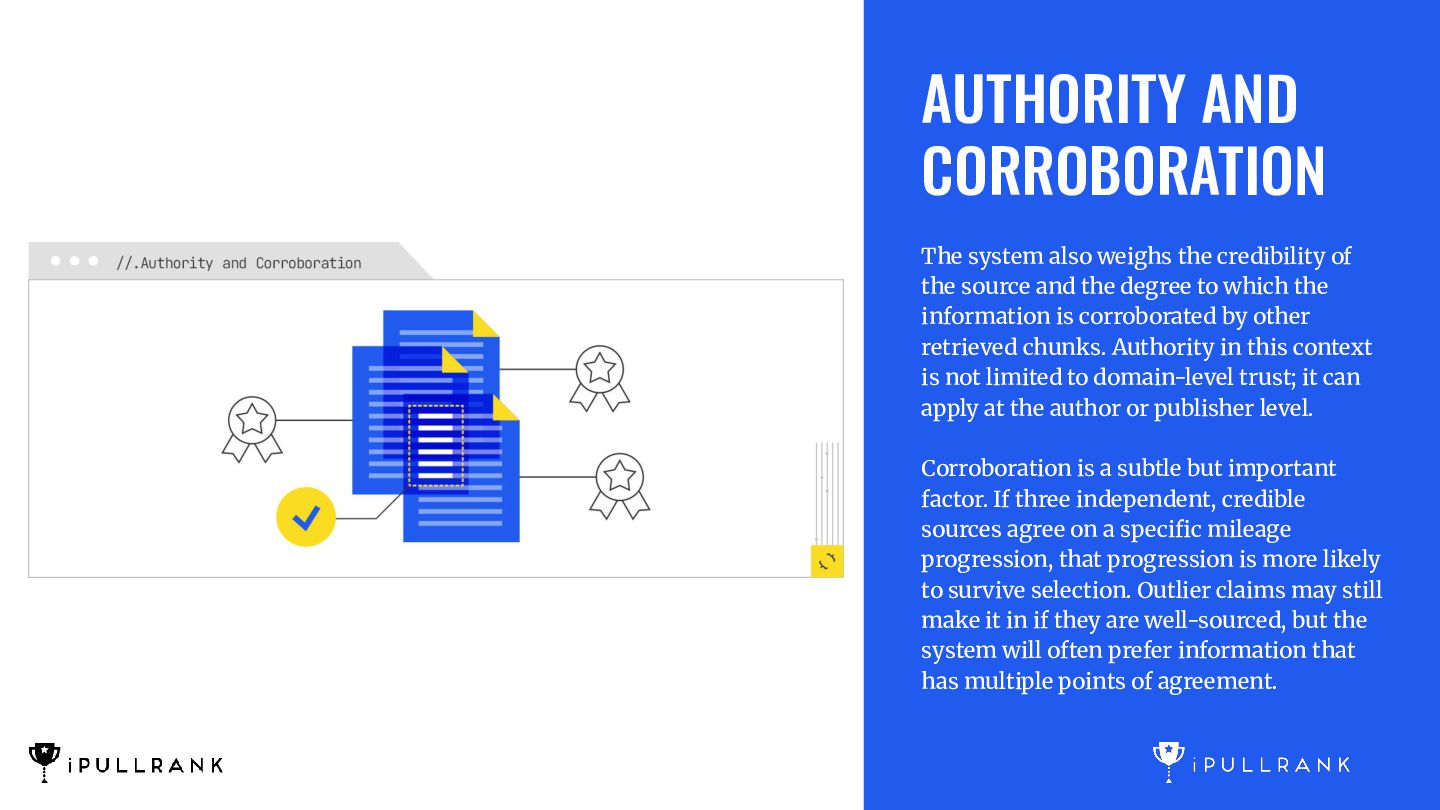
  33. AUTHORITY AND CORROBORATION The system also weighs the credibility of

    the source and the degree to which the information is corroborated by other retrieved chunks. Authority in this context is not limited to domain-level trust; it can apply at the author or publisher level. Corroboration is a subtle but important factor. If three independent, credible sources agree on a specific mileage progression, that progression is more likely to survive selection. Outlier claims may still make it in if they are well-sourced, but the system will often prefer information that has multiple points of agreement.
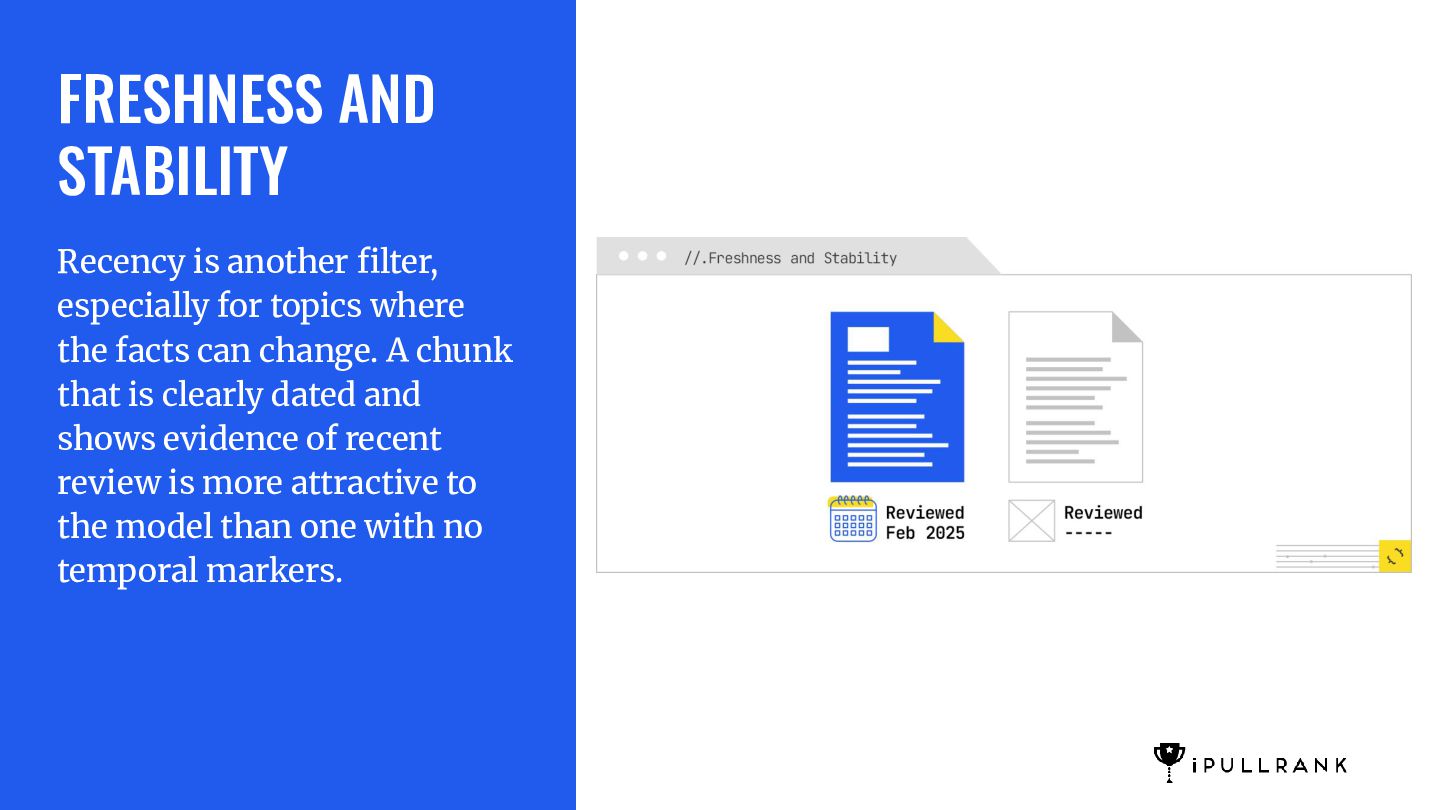
  34. FRESHNESS AND STABILITY Recency is another filter, especially for topics

    where the facts can change. A chunk that is clearly dated and shows evidence of recent review is more attractive to the model than one with no temporal markers.
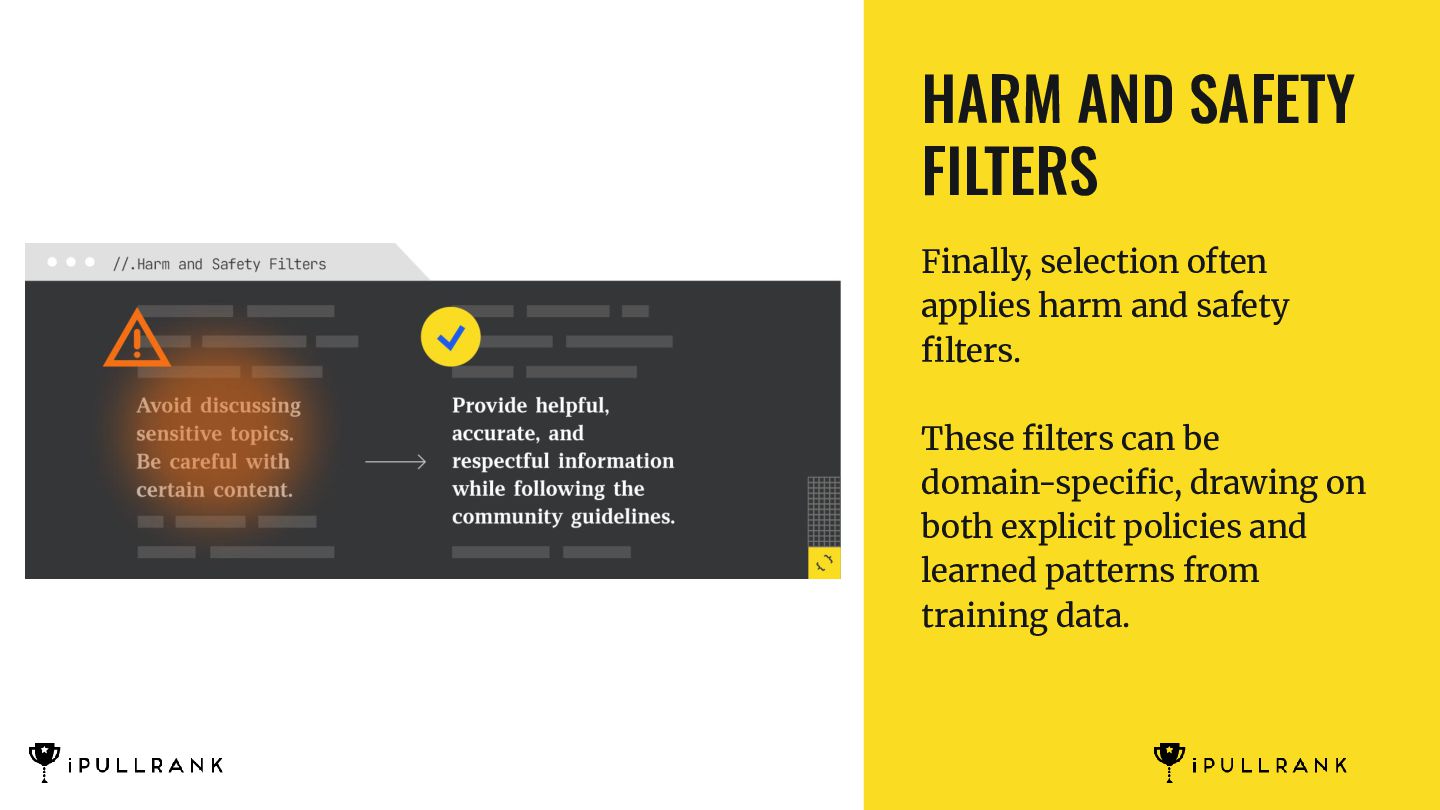
  35. HARM AND SAFETY FILTERS Finally, selection often applies harm and

    safety filters. These filters can be domain-specific, drawing on both explicit policies and learned patterns from training data.
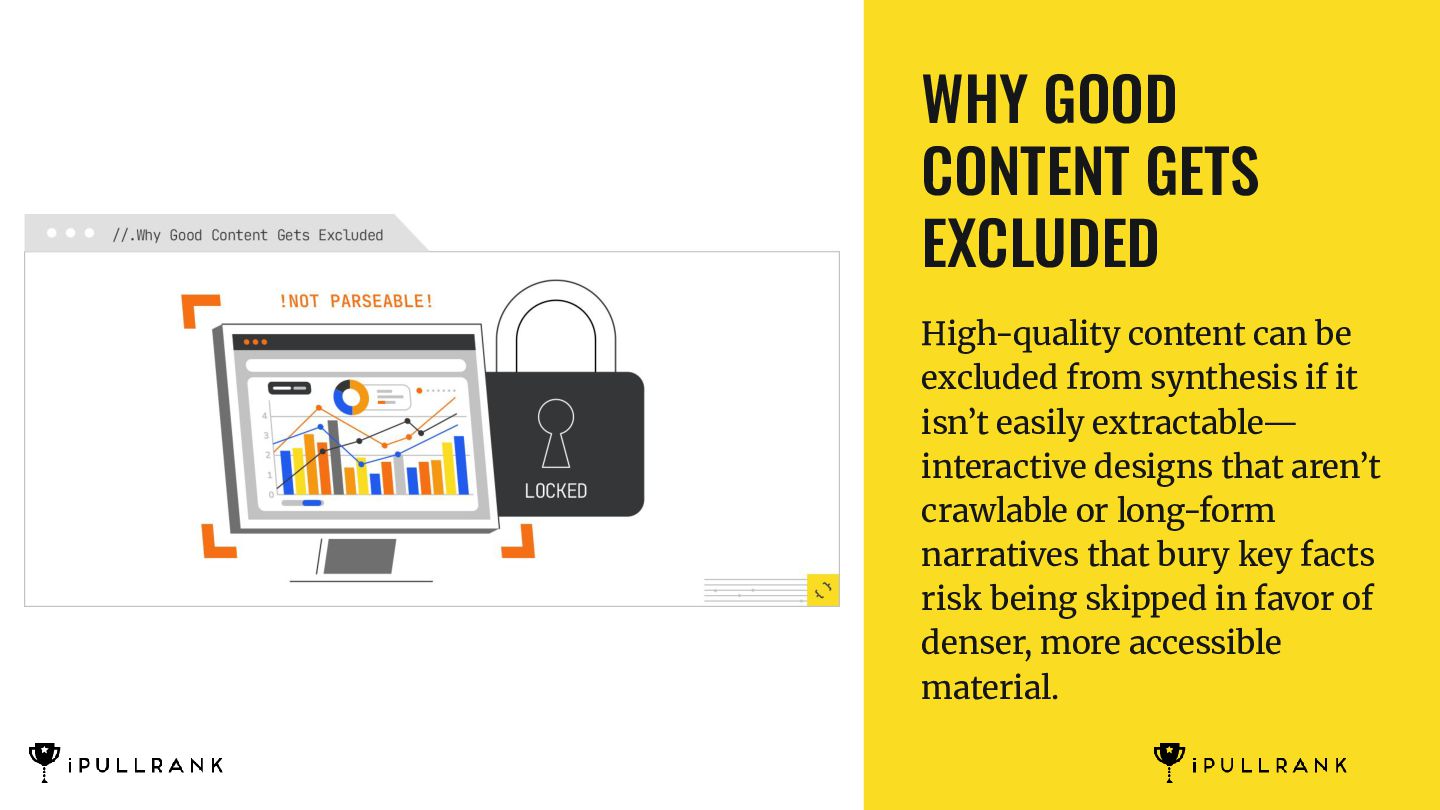
  36. WHY GOOD CONTENT GETS EXCLUDED High-quality content can be excluded

    from synthesis if it isn’t easily extractable— interactive designs that aren’t crawlable or long-form narratives that bury key facts risk being skipped in favor of denser, more accessible material.
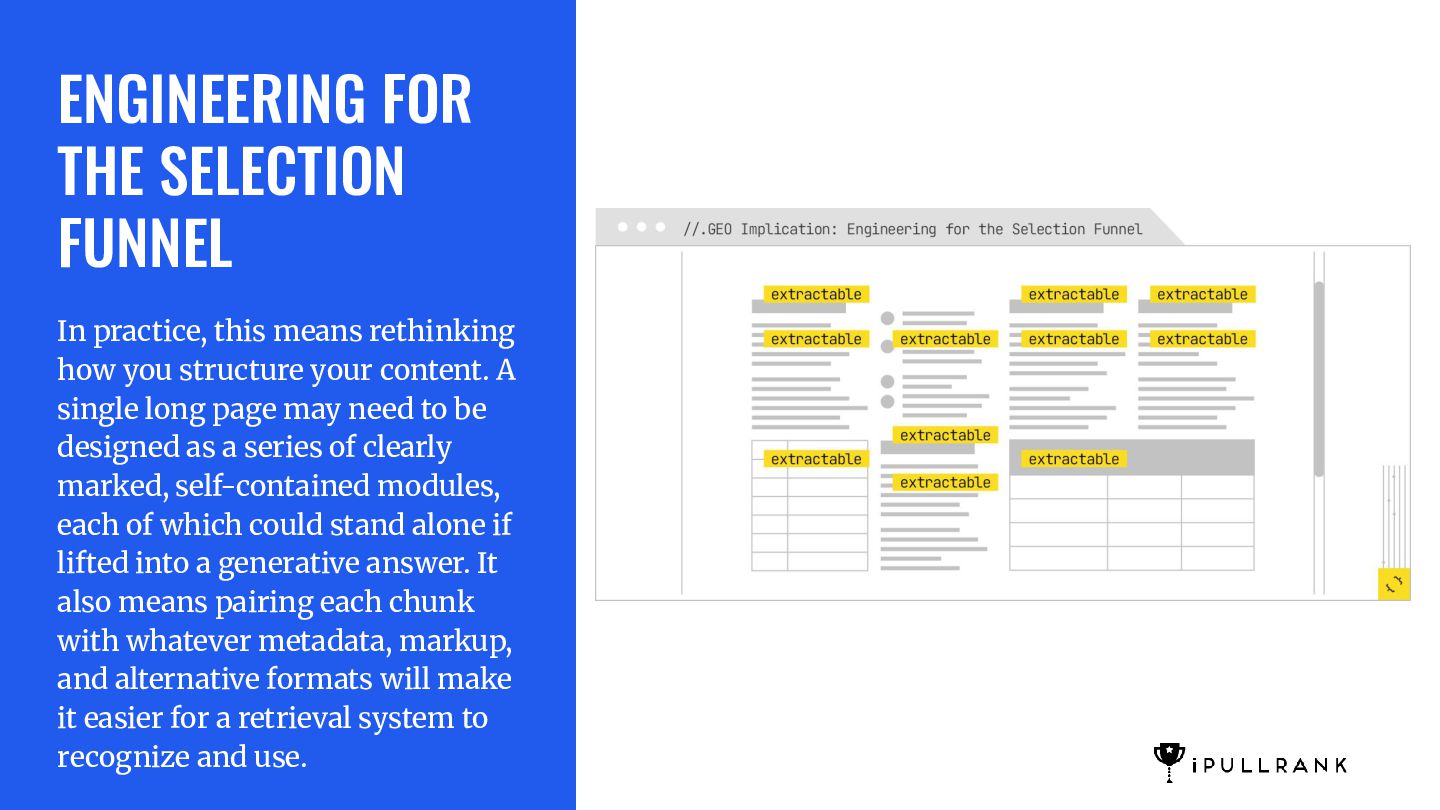
  37. ENGINEERING FOR THE SELECTION FUNNEL In practice, this means rethinking

    how you structure your content. A single long page may need to be designed as a series of clearly marked, self-contained modules, each of which could stand alone if lifted into a generative answer. It also means pairing each chunk with whatever metadata, markup, and alternative formats will make it easier for a retrieval system to recognize and use.
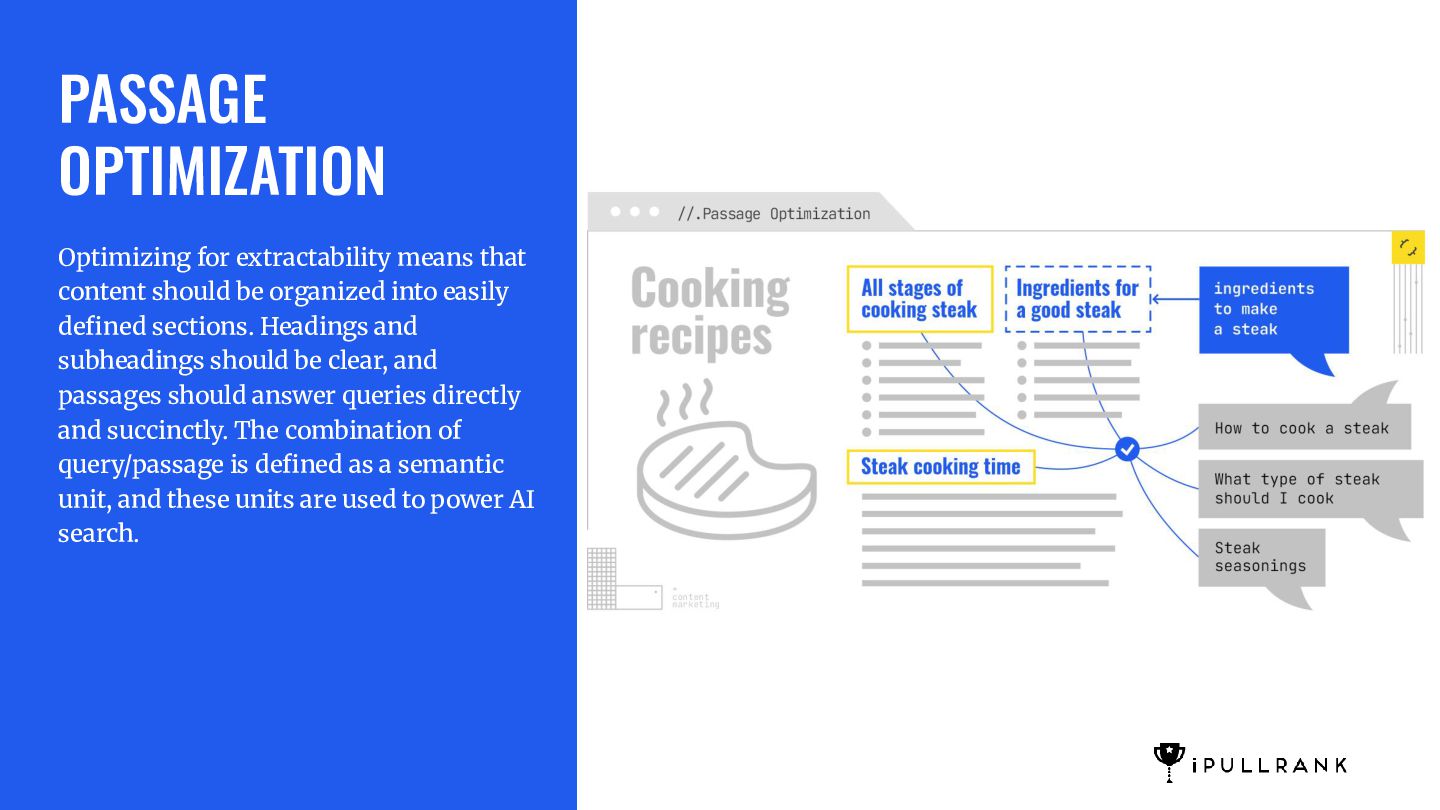
  38. PASSAGE OPTIMIZATION Optimizing for extractability means that content should be

    organized into easily defined sections. Headings and subheadings should be clear, and passages should answer queries directly and succinctly. The combination of query/passage is defined as a semantic unit, and these units are used to power AI search.
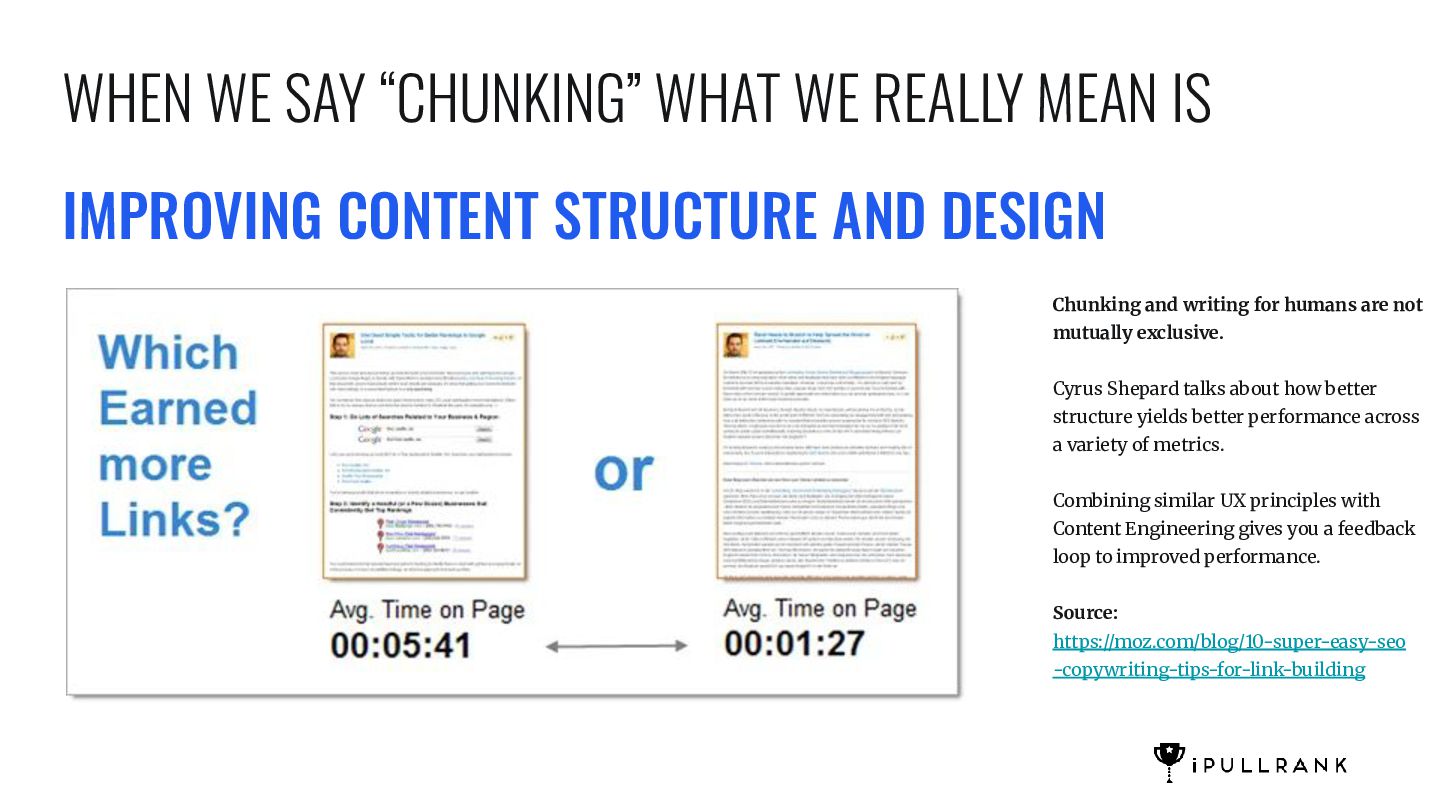
  39. WHEN WE SAY “CHUNKING” WHAT WE REALLY MEAN IS IMPROVING

    CONTENT STRUCTURE AND DESIGN Chunking and writing for humans are not mutually exclusive. Cyrus Shepard talks about how better structure yields better performance across a variety of metrics. Combining similar UX principles with Content Engineering gives you a feedback loop to improved performance. Source: https://moz.com/blog/10-super-easy-seo -copywriting-tips-for-link-building
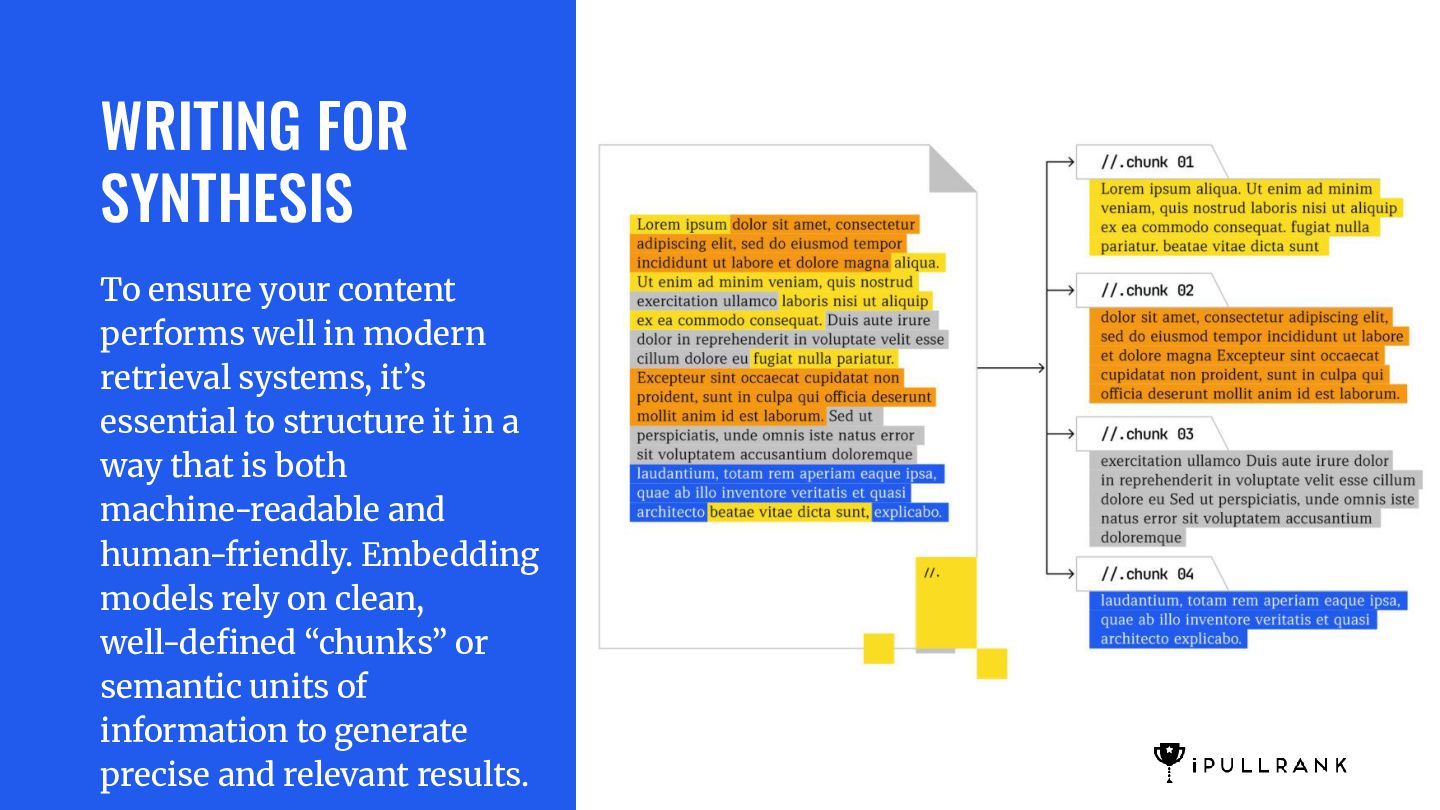
  40. WRITING FOR SYNTHESIS To ensure your content performs well in

    modern retrieval systems, it’s essential to structure it in a way that is both machine-readable and human-friendly. Embedding models rely on clean, well-defined “chunks” or semantic units of information to generate precise and relevant results.
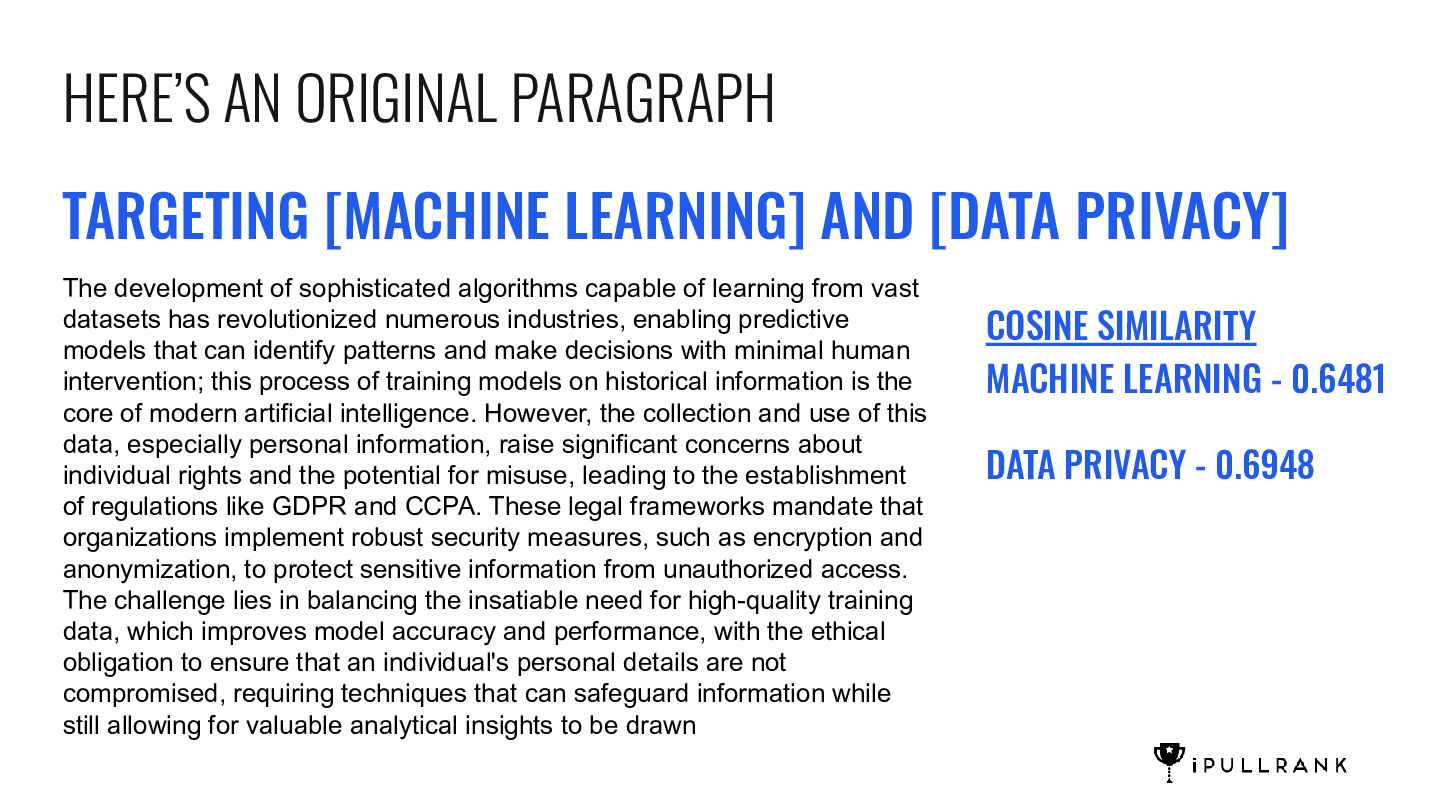
  41. HERE’S AN ORIGINAL PARAGRAPH TARGETING [MACHINE LEARNING] AND [DATA PRIVACY]

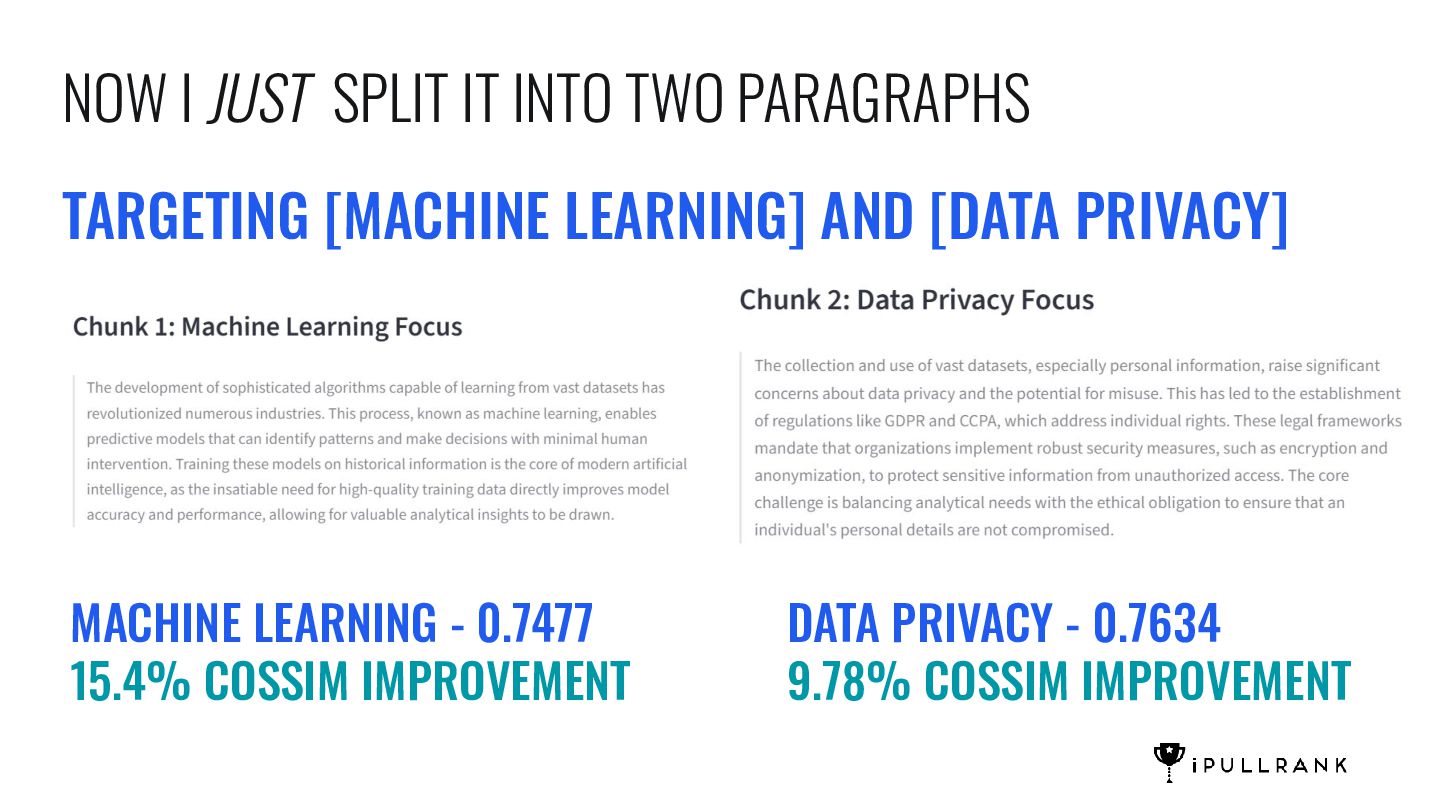
    The development of sophisticated algorithms capable of learning from vast datasets has revolutionized numerous industries, enabling predictive models that can identify patterns and make decisions with minimal human intervention; this process of training models on historical information is the core of modern artificial intelligence. However, the collection and use of this data, especially personal information, raise significant concerns about individual rights and the potential for misuse, leading to the establishment of regulations like GDPR and CCPA. These legal frameworks mandate that organizations implement robust security measures, such as encryption and anonymization, to protect sensitive information from unauthorized access. The challenge lies in balancing the insatiable need for high-quality training data, which improves model accuracy and performance, with the ethical obligation to ensure that an individual's personal details are not compromised, requiring techniques that can safeguard information while still allowing for valuable analytical insights to be drawn COSINE SIMILARITY MACHINE LEARNING - 0.6481 DATA PRIVACY - 0.6948
  42. NOW I JUST SPLIT IT INTO TWO PARAGRAPHS TARGETING [MACHINE

    LEARNING] AND [DATA PRIVACY] MACHINE LEARNING - 0.7477 15.4% COSSIM IMPROVEMENT DATA PRIVACY - 0.7634 9.78% COSSIM IMPROVEMENT
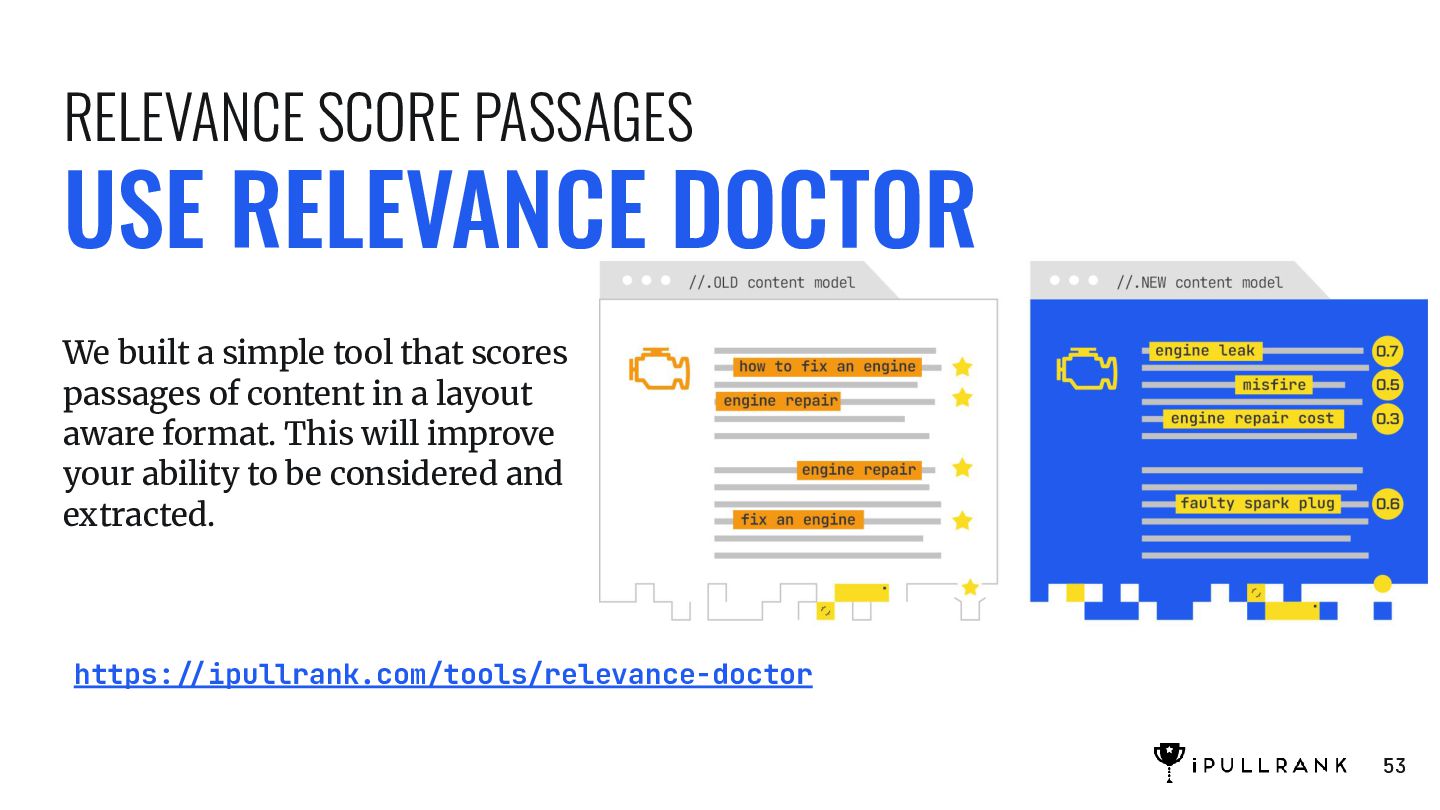
  43. RELEVANCE SCORE PASSAGES USE RELEVANCE DOCTOR We built a simple

    tool that scores passages of content in a layout aware format. This will improve your ability to be considered and extracted. https://ipullrank.com/tools/relevance-doctor 53
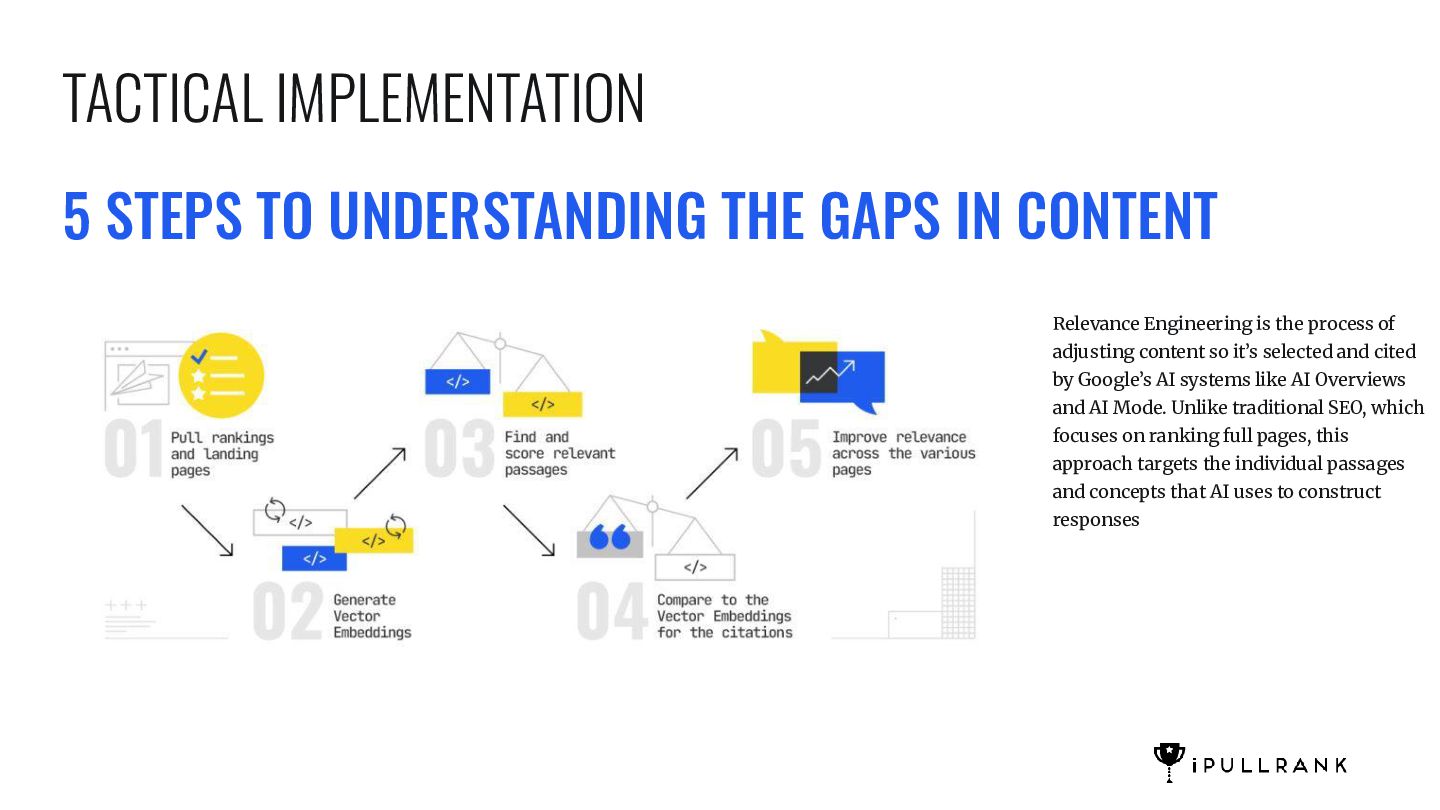
  44. TACTICAL IMPLEMENTATION 5 STEPS TO UNDERSTANDING THE GAPS IN CONTENT

    Relevance Engineering is the process of adjusting content so it’s selected and cited by Google’s AI systems like AI Overviews and AI Mode. Unlike traditional SEO, which focuses on ranking full pages, this approach targets the individual passages and concepts that AI uses to construct responses
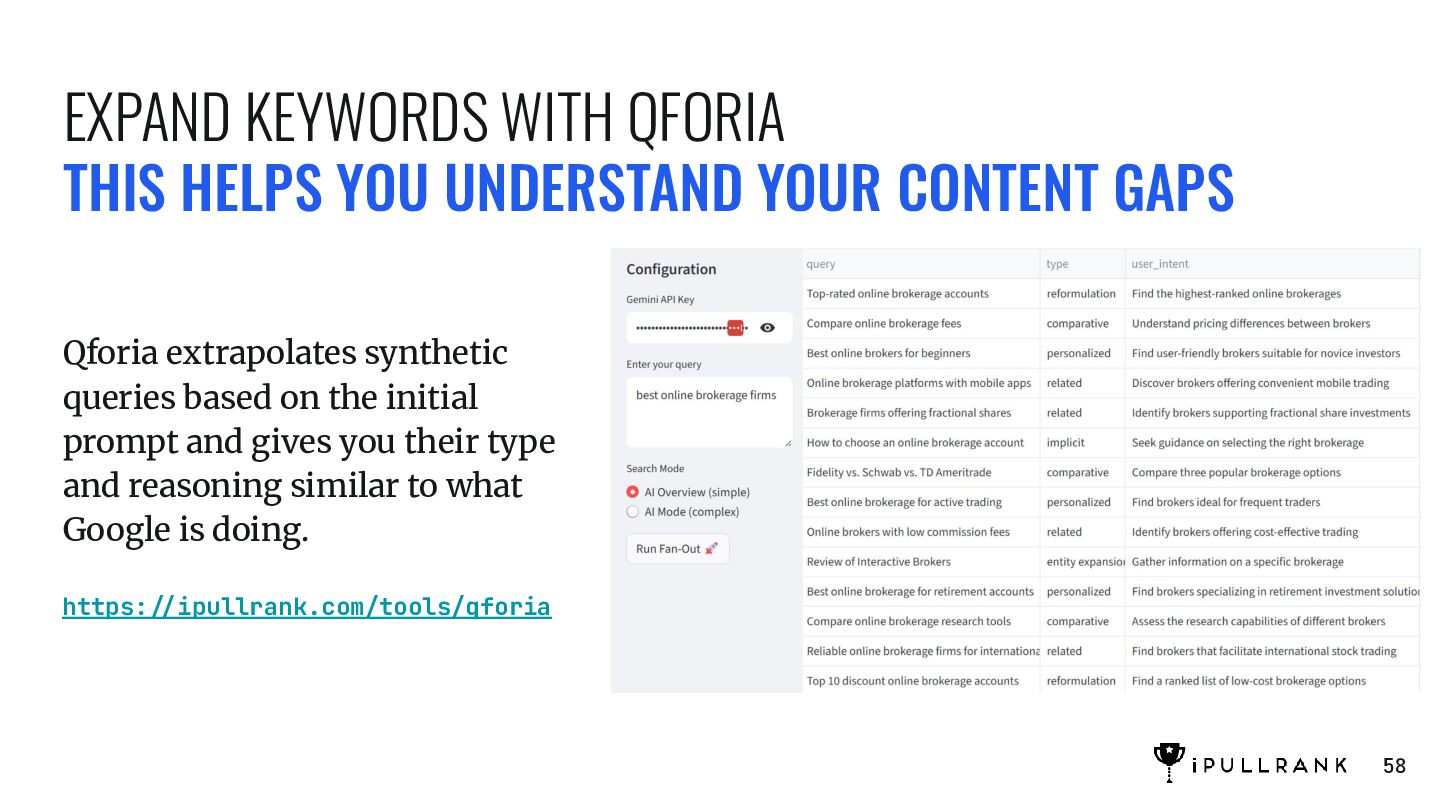
  45. EXPAND KEYWORDS WITH QFORIA THIS HELPS YOU UNDERSTAND YOUR CONTENT

    GAPS Qforia extrapolates synthetic queries based on the initial prompt and gives you their type and reasoning similar to what Google is doing. https://ipullrank.com/tools/qforia 58
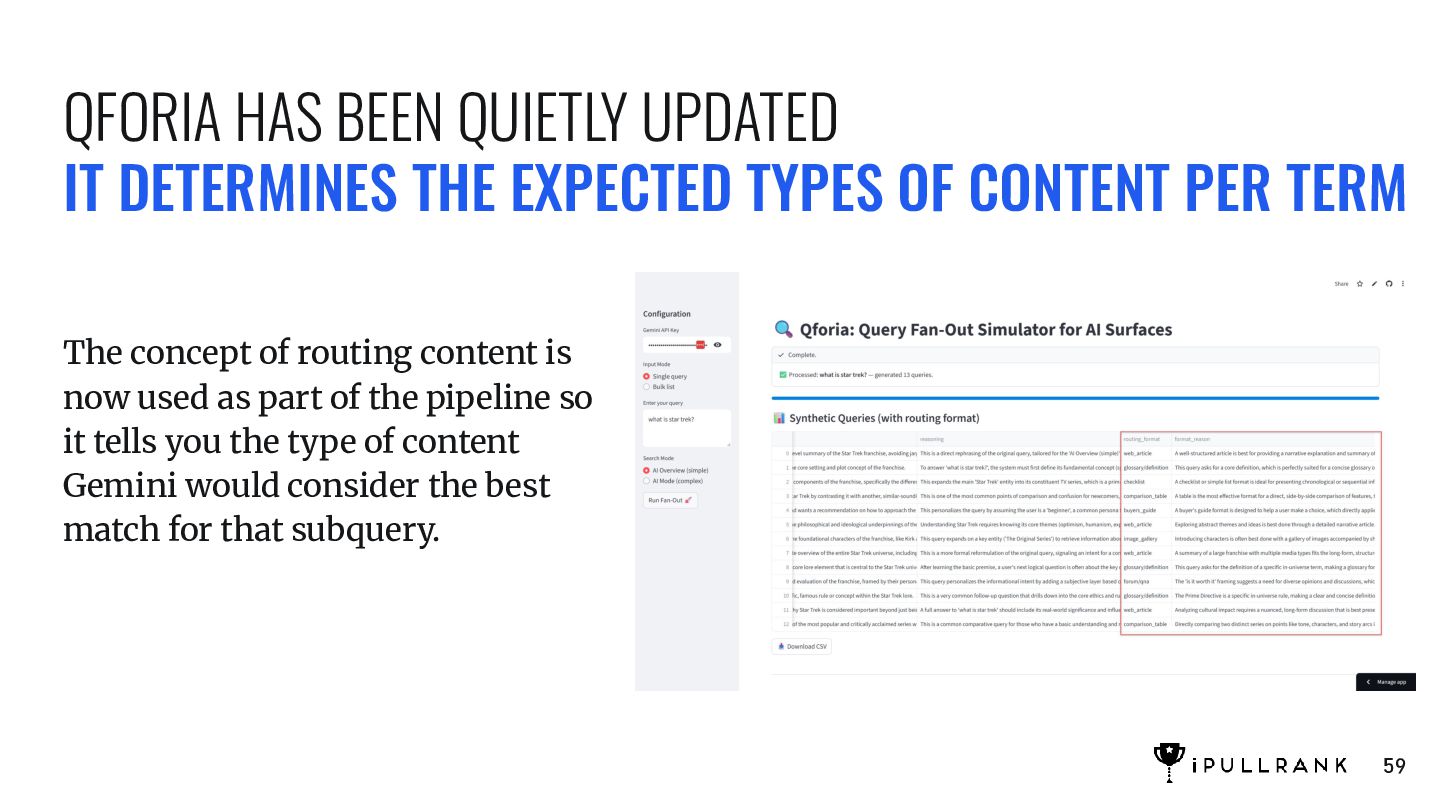
  46. QFORIA HAS BEEN QUIETLY UPDATED IT DETERMINES THE EXPECTED TYPES

    OF CONTENT PER TERM The concept of routing content is now used as part of the pipeline so it tells you the type of content Gemini would consider the best match for that subquery. 59
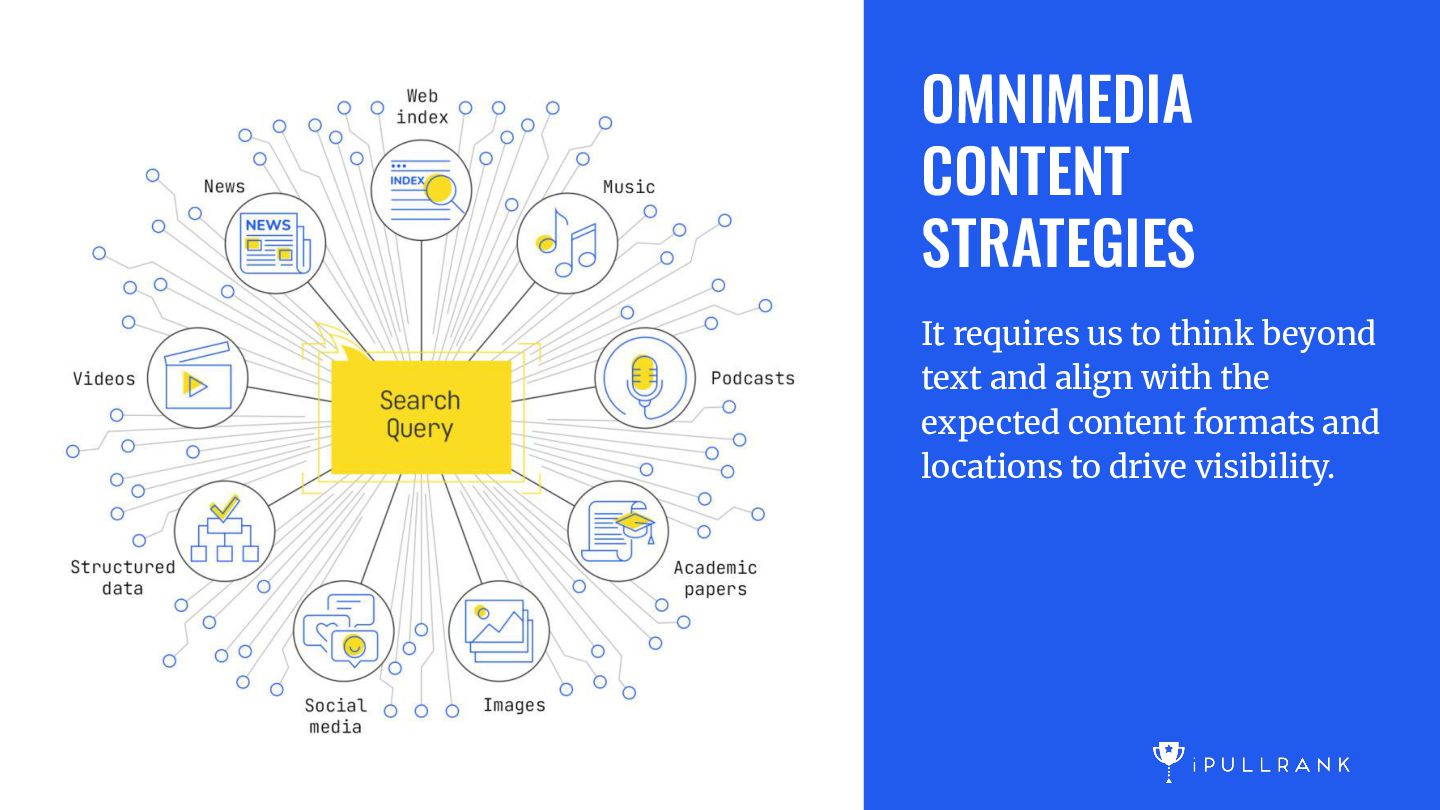
  47. OMNIMEDIA CONTENT STRATEGIES It requires us to think beyond text

    and align with the expected content formats and locations to drive visibility.
  48. UGC For queries involving troubleshooting, product comparisons, lived experiences, or

    niche use cases, user-generated content (UGC) and forum discussions are often prioritized by AI systems. Generative models value this type of content because it reflects authentic, diverse, and situational insights that can’t always be found in more polished corporate content.
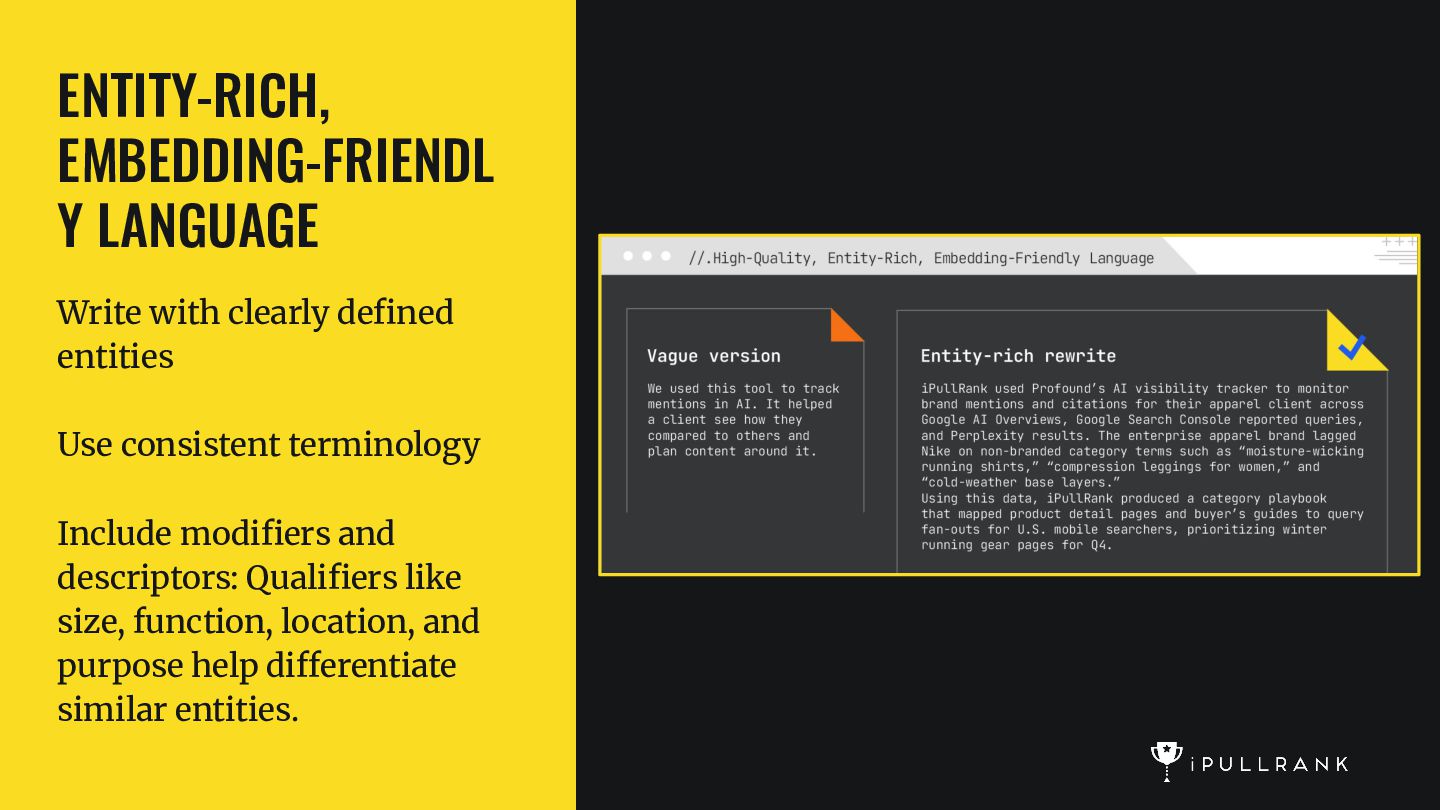
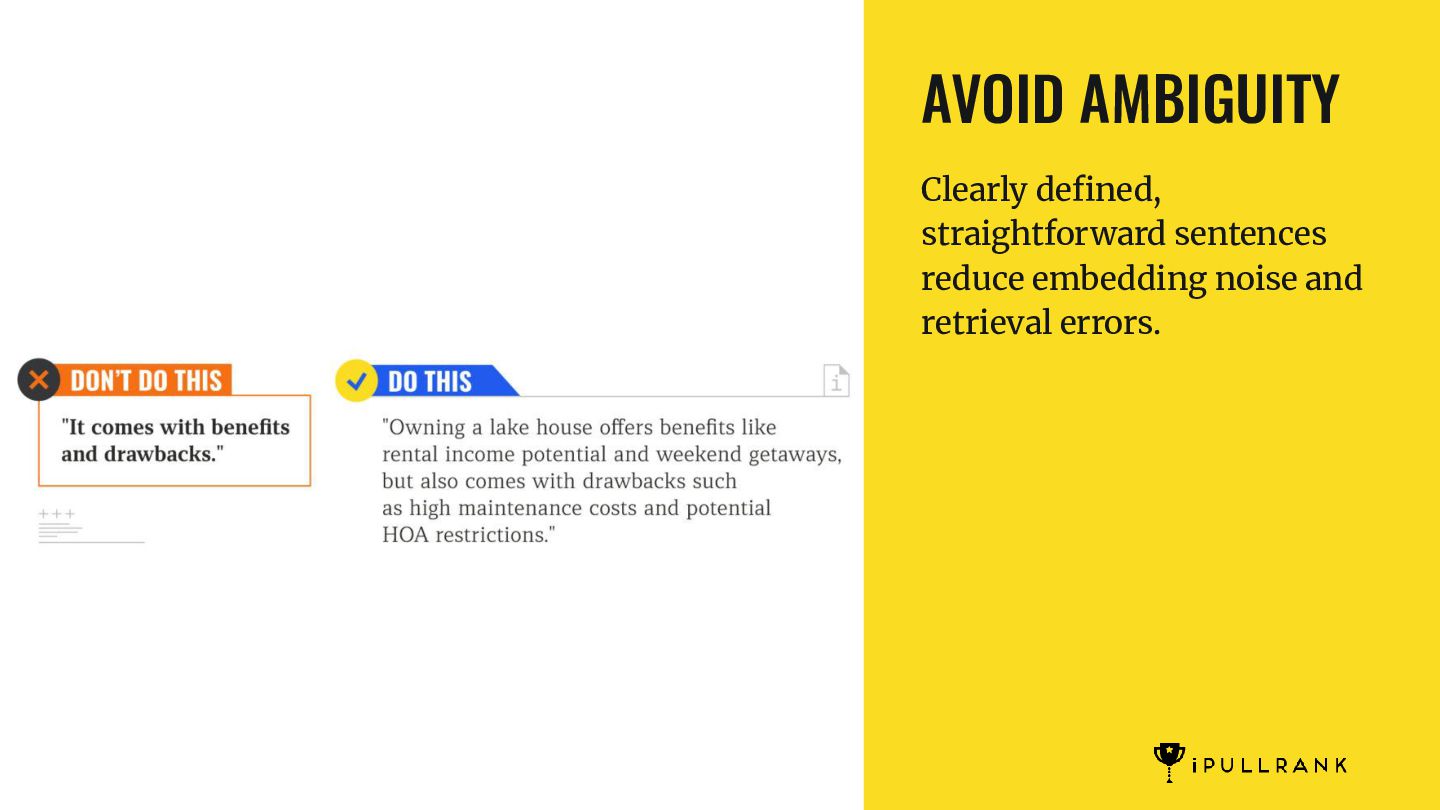
  49. ENTITY-RICH, EMBEDDING-FRIENDL Y LANGUAGE Write with clearly defined entities Use

    consistent terminology Include modifiers and descriptors: Qualifiers like size, function, location, and purpose help differentiate similar entities.
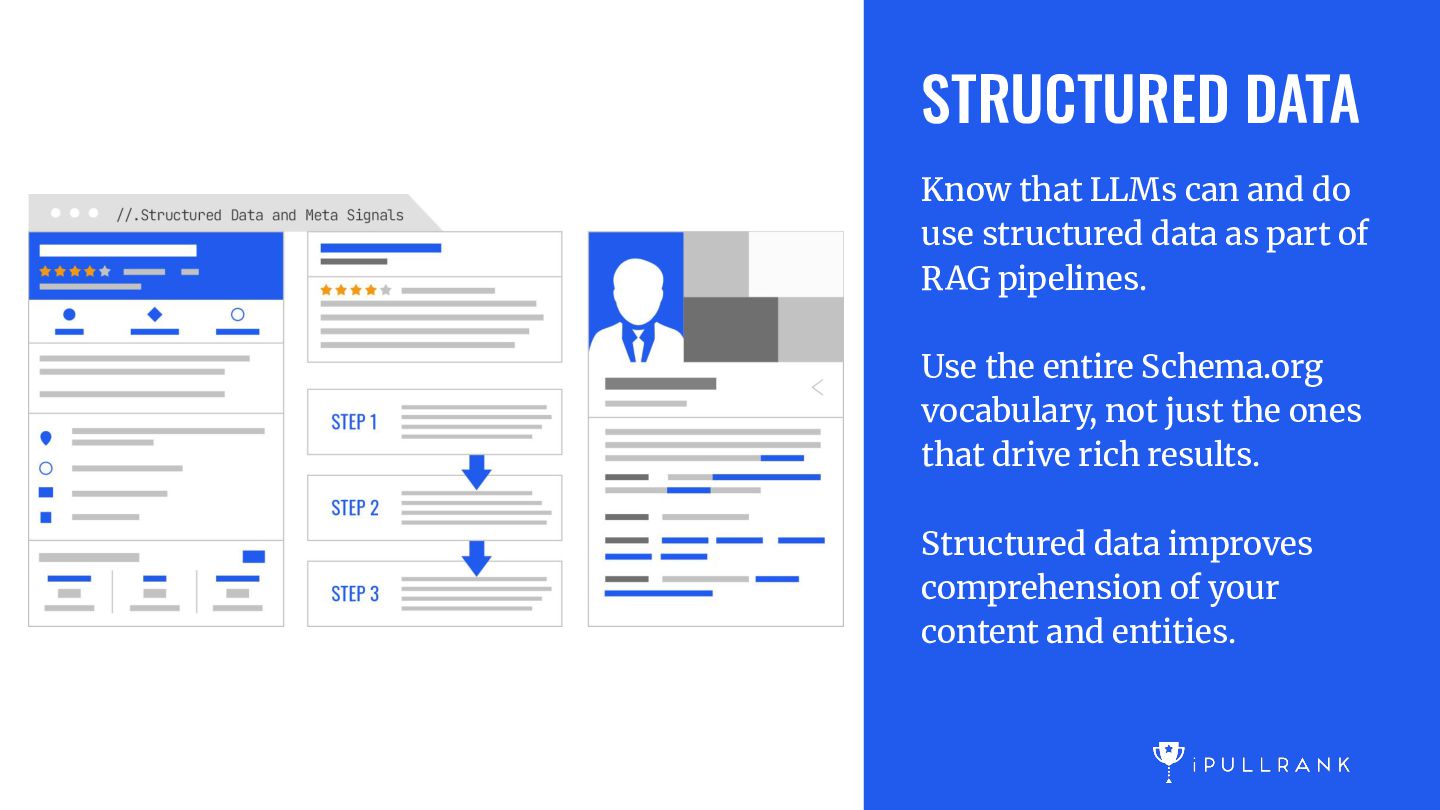
  50. STRUCTURED DATA Know that LLMs can and do use structured

    data as part of RAG pipelines. Use the entire Schema.org vocabulary, not just the ones that drive rich results. Structured data improves comprehension of your content and entities.
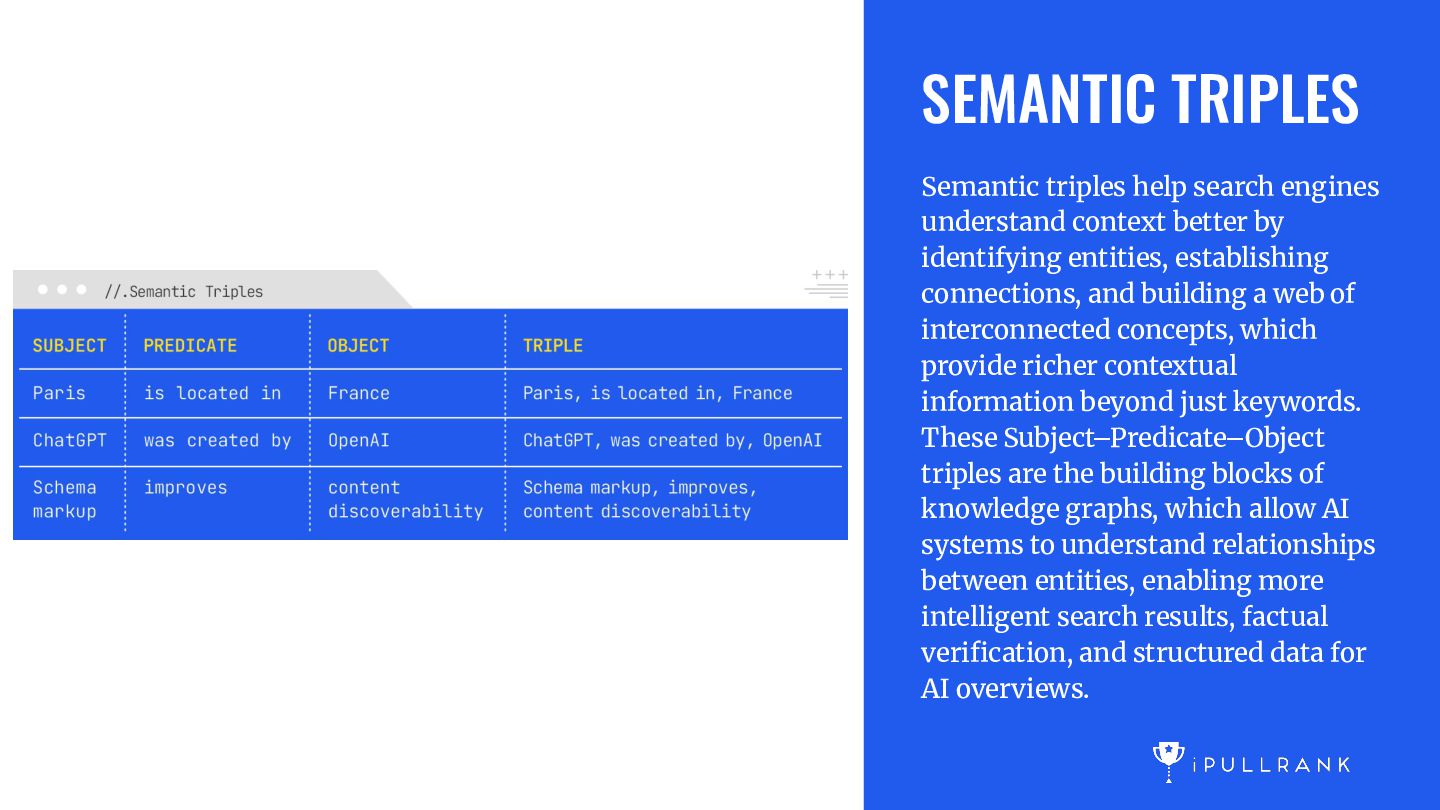
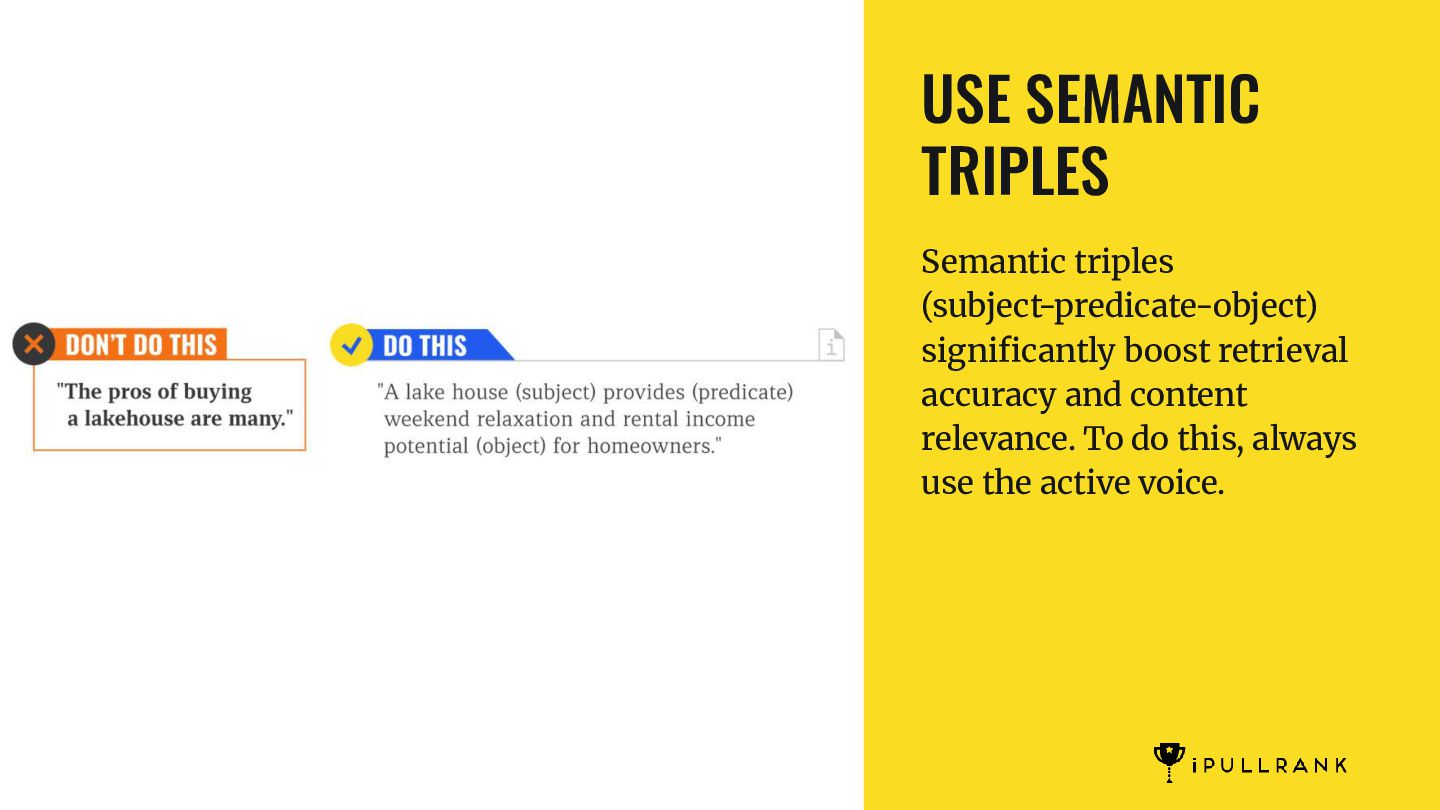
  51. SEMANTIC TRIPLES Semantic triples help search engines understand context better

    by identifying entities, establishing connections, and building a web of interconnected concepts, which provide richer contextual information beyond just keywords. These Subject–Predicate–Object triples are the building blocks of knowledge graphs, which allow AI systems to understand relationships between entities, enabling more intelligent search results, factual verification, and structured data for AI overviews.
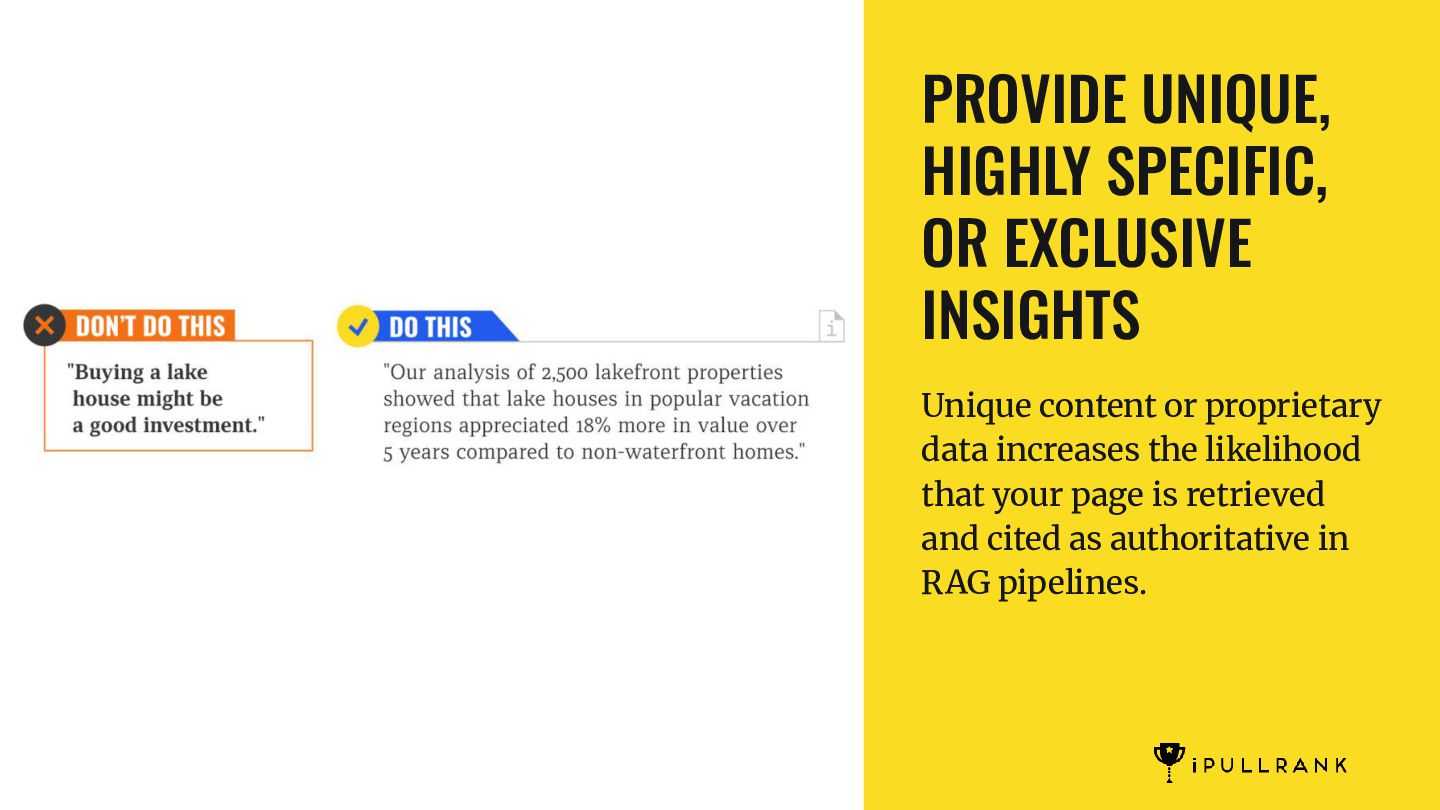
  52. PROVIDE UNIQUE, HIGHLY SPECIFIC, OR EXCLUSIVE INSIGHTS Unique content or

    proprietary data increases the likelihood that your page is retrieved and cited as authoritative in RAG pipelines.
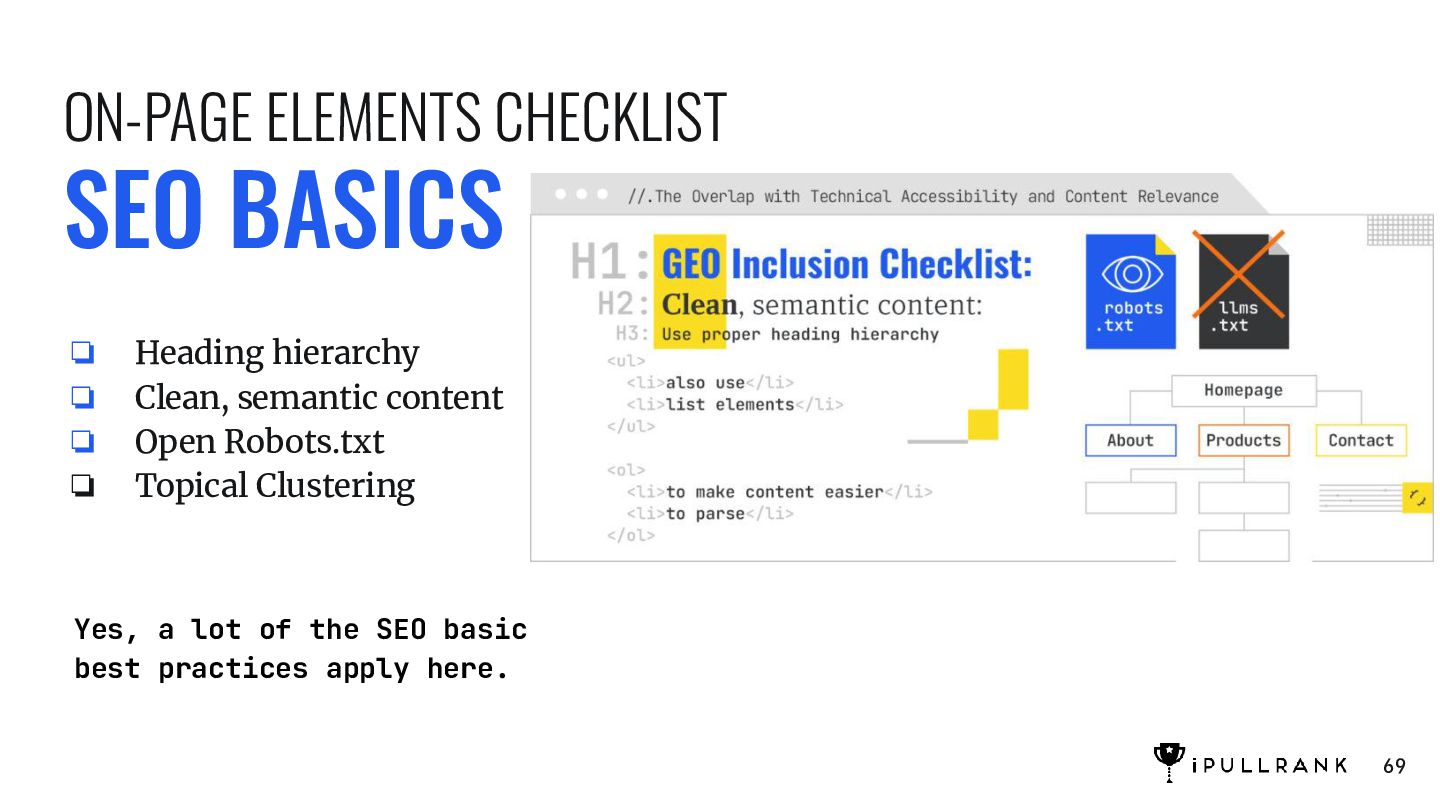
  53. ON-PAGE ELEMENTS CHECKLIST SEO BASICS ❏ ❏ ❏ ❏ Heading

    hierarchy Clean, semantic content Open Robots.txt Topical Clustering Yes, a lot of the SEO basic best practices apply here. 69
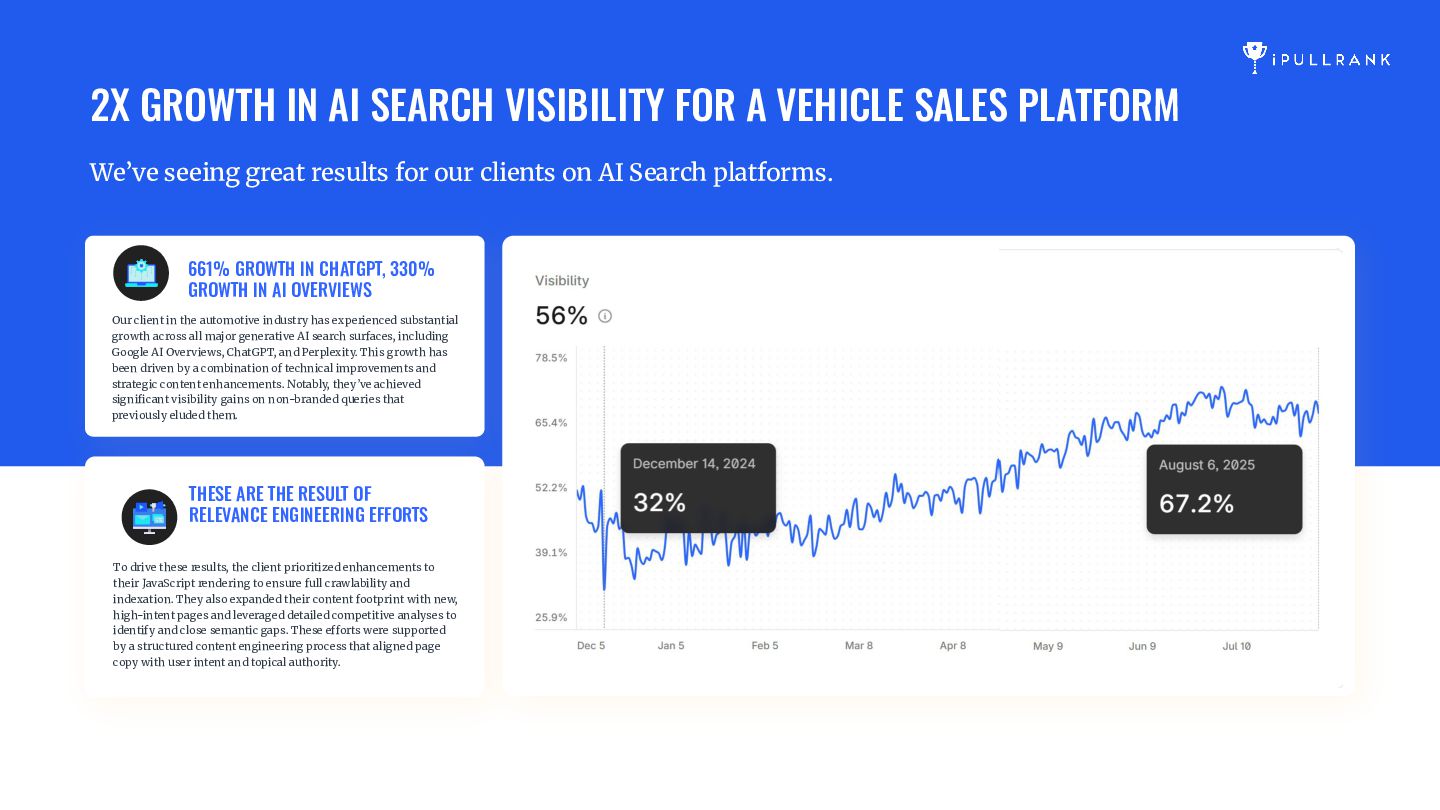
  54. 2X GROWTH IN AI SEARCH VISIBILITY FOR A VEHICLE SALES

    PLATFORM We’ve seeing great results for our clients on AI Search platforms. 661% GROWTH IN CHATGPT, 330% GROWTH IN AI OVERVIEWS Our client in the automotive industry has experienced substantial growth across all major generative AI search surfaces, including Google AI Overviews, ChatGPT, and Perplexity. This growth has been driven by a combination of technical improvements and strategic content enhancements. Notably, they’ve achieved significant visibility gains on non-branded queries that previously eluded them. THESE ARE THE RESULT OF RELEVANCE ENGINEERING EFFORTS To drive these results, the client prioritized enhancements to their JavaScript rendering to ensure full crawlability and indexation. They also expanded their content footprint with new, high-intent pages and leveraged detailed competitive analyses to identify and close semantic gaps. These efforts were supported by a structured content engineering process that aligned page copy with user intent and topical authority.
  55. HOW A CATEGORY LEADING TELECOMMUNICATIONS BRAND ACHIEVED 253% GROWTH IN

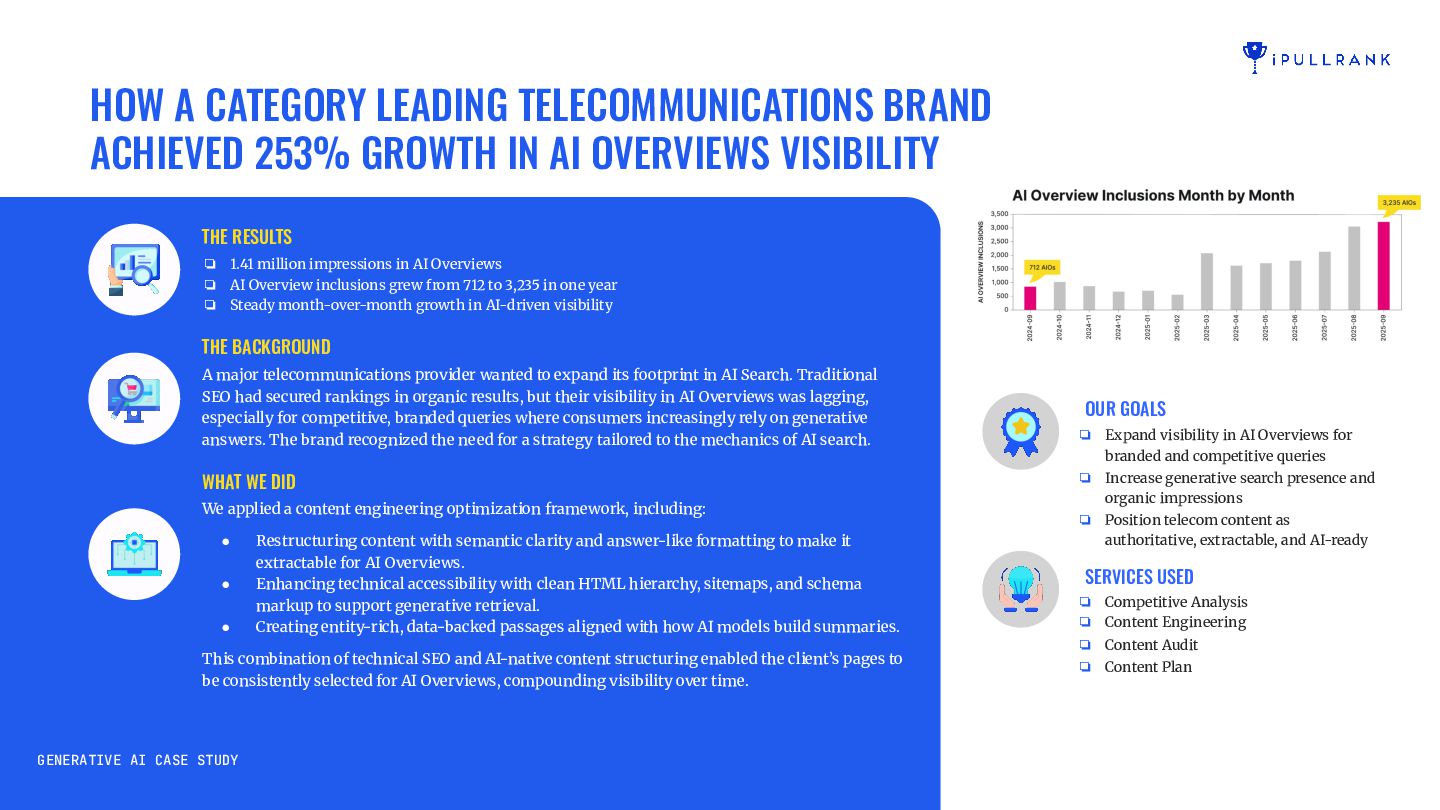
    AI OVERVIEWS VISIBILITY THE RESULTS ❏ 1.41 million impressions in AI Overviews ❏ AI Overview inclusions grew from 712 to 3,235 in one year ❏ Steady month-over-month growth in AI-driven visibility THE BACKGROUND A major telecommunications provider wanted to expand its footprint in AI Search. Traditional SEO had secured rankings in organic results, but their visibility in AI Overviews was lagging, especially for competitive, branded queries where consumers increasingly rely on generative answers. The brand recognized the need for a strategy tailored to the mechanics of AI search. WHAT WE DID We applied a content engineering optimization framework, including: • • • Restructuring content with semantic clarity and answer-like formatting to make it extractable for AI Overviews. Enhancing technical accessibility with clean HTML hierarchy, sitemaps, and schema markup to support generative retrieval. Creating entity-rich, data-backed passages aligned with how AI models build summaries. This combination of technical SEO and AI-native content structuring enabled the client’s pages to be consistently selected for AI Overviews, compounding visibility over time. GENERATIVE AI CASE STUDY OUR GOALS ❏ Expand visibility in AI Overviews for branded and competitive queries ❏ Increase generative search presence and organic impressions ❏ Position telecom content as authoritative, extractable, and AI-ready SERVICES USED ❏ Competitive Analysis ❏ Content Engineering ❏ Content Audit ❏ Content Plan
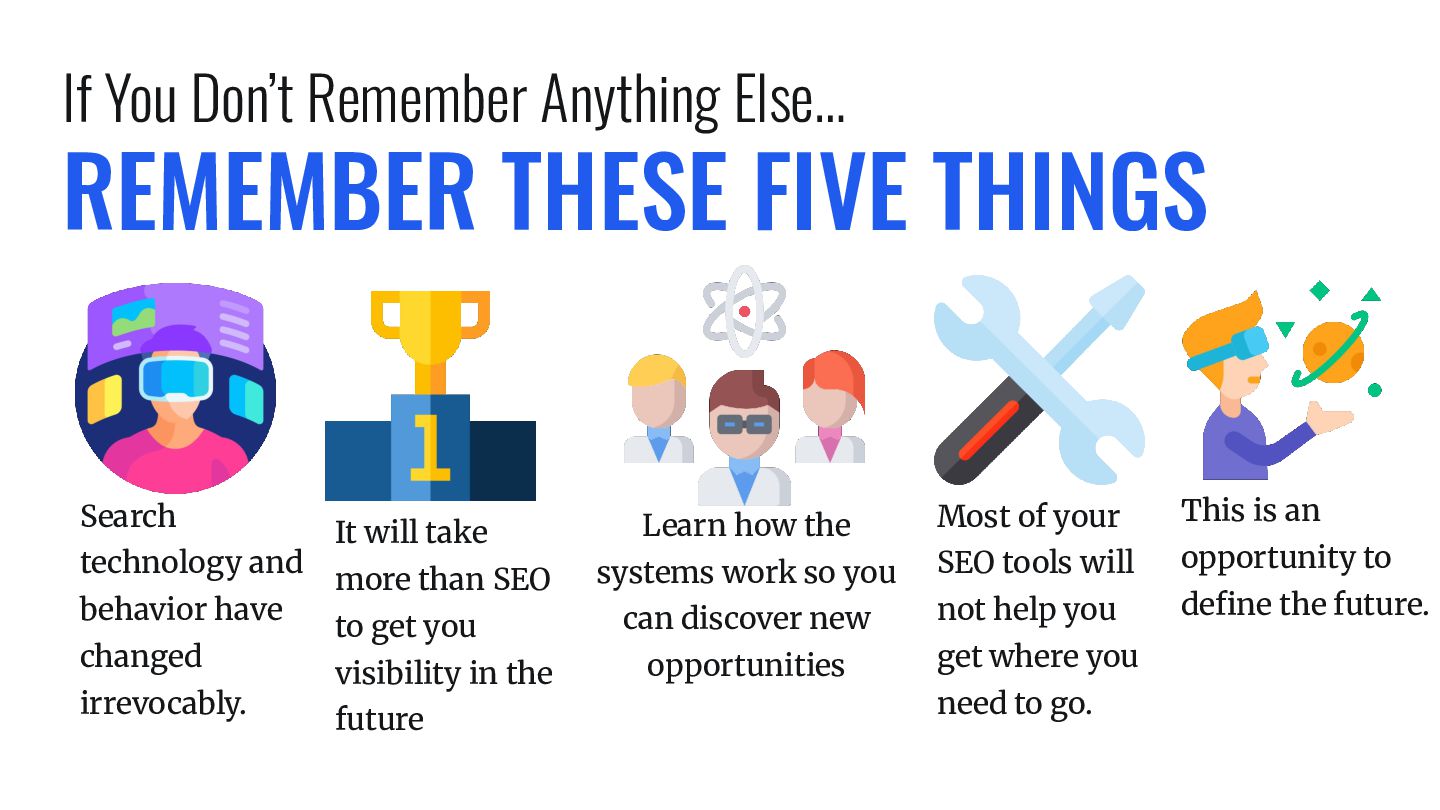
  56. If You Don’t Remember Anything Else… REMEMBER THESE FIVE THINGS

    Search technology and behavior have changed irrevocably. It will take more than SEO to get you visibility in the future Learn how the systems work so you can discover new opportunities Most of your This is an SEO tools will opportunity to not help you define the future. get where you need to go.
  57. The New Playbook For GEO Content in 2027: How To

    Get Your Brand Chosen As The Answer
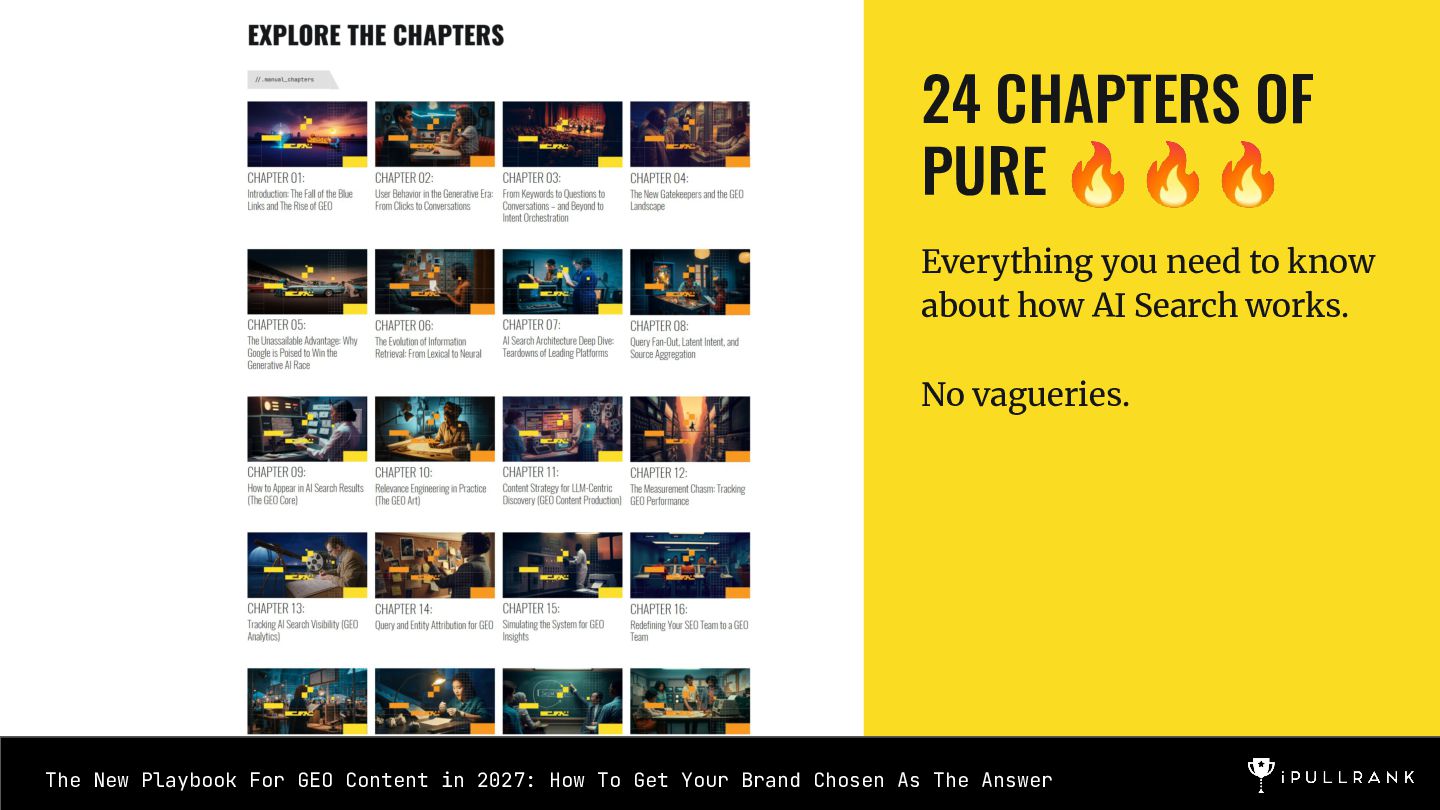
  58. 24 CHAPTERS OF PURE 🔥🔥🔥 Everything you need to know

    about how AI Search works. No vagueries. The New Playbook For GEO Content in 2027: How To Get Your Brand Chosen As The Answer
  59. ipullrank.com/ai-search-manual AI Search to Sale: What the Data Reveals About

    AI Search eCommerce Behavior The New Playbook For GEO Content in 2027: How To Get Your Brand Chosen As The Answer
  60. THANK YOU // Q&A Zach Chahalis Vice President of Relevance

    Engineering & Analytics iPullRank X: @ZachChahalis LI: /zacharychahalis Title Tap in with us: ipullrank.com The New Playbook For GEO Content in 2027: How To Get Your Brand Chosen As The Answer Get the Slides:
  61. 81