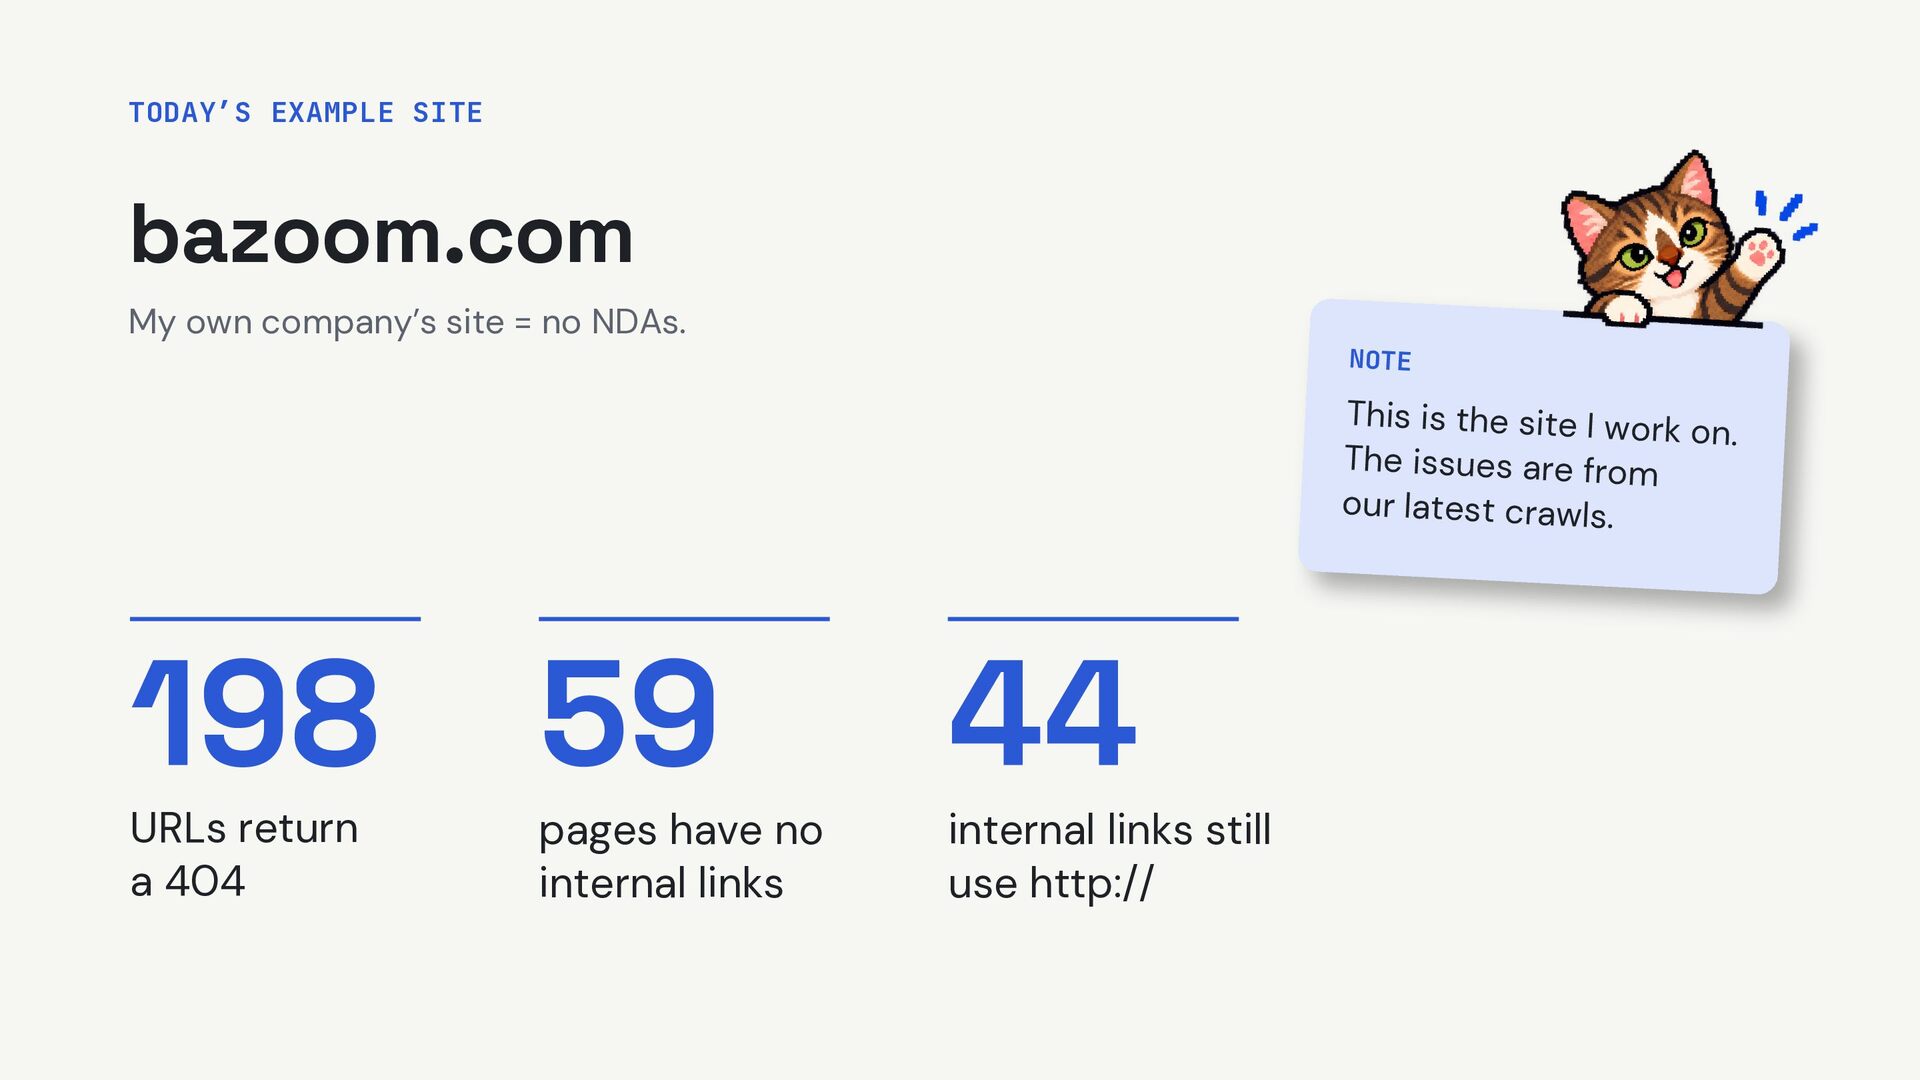
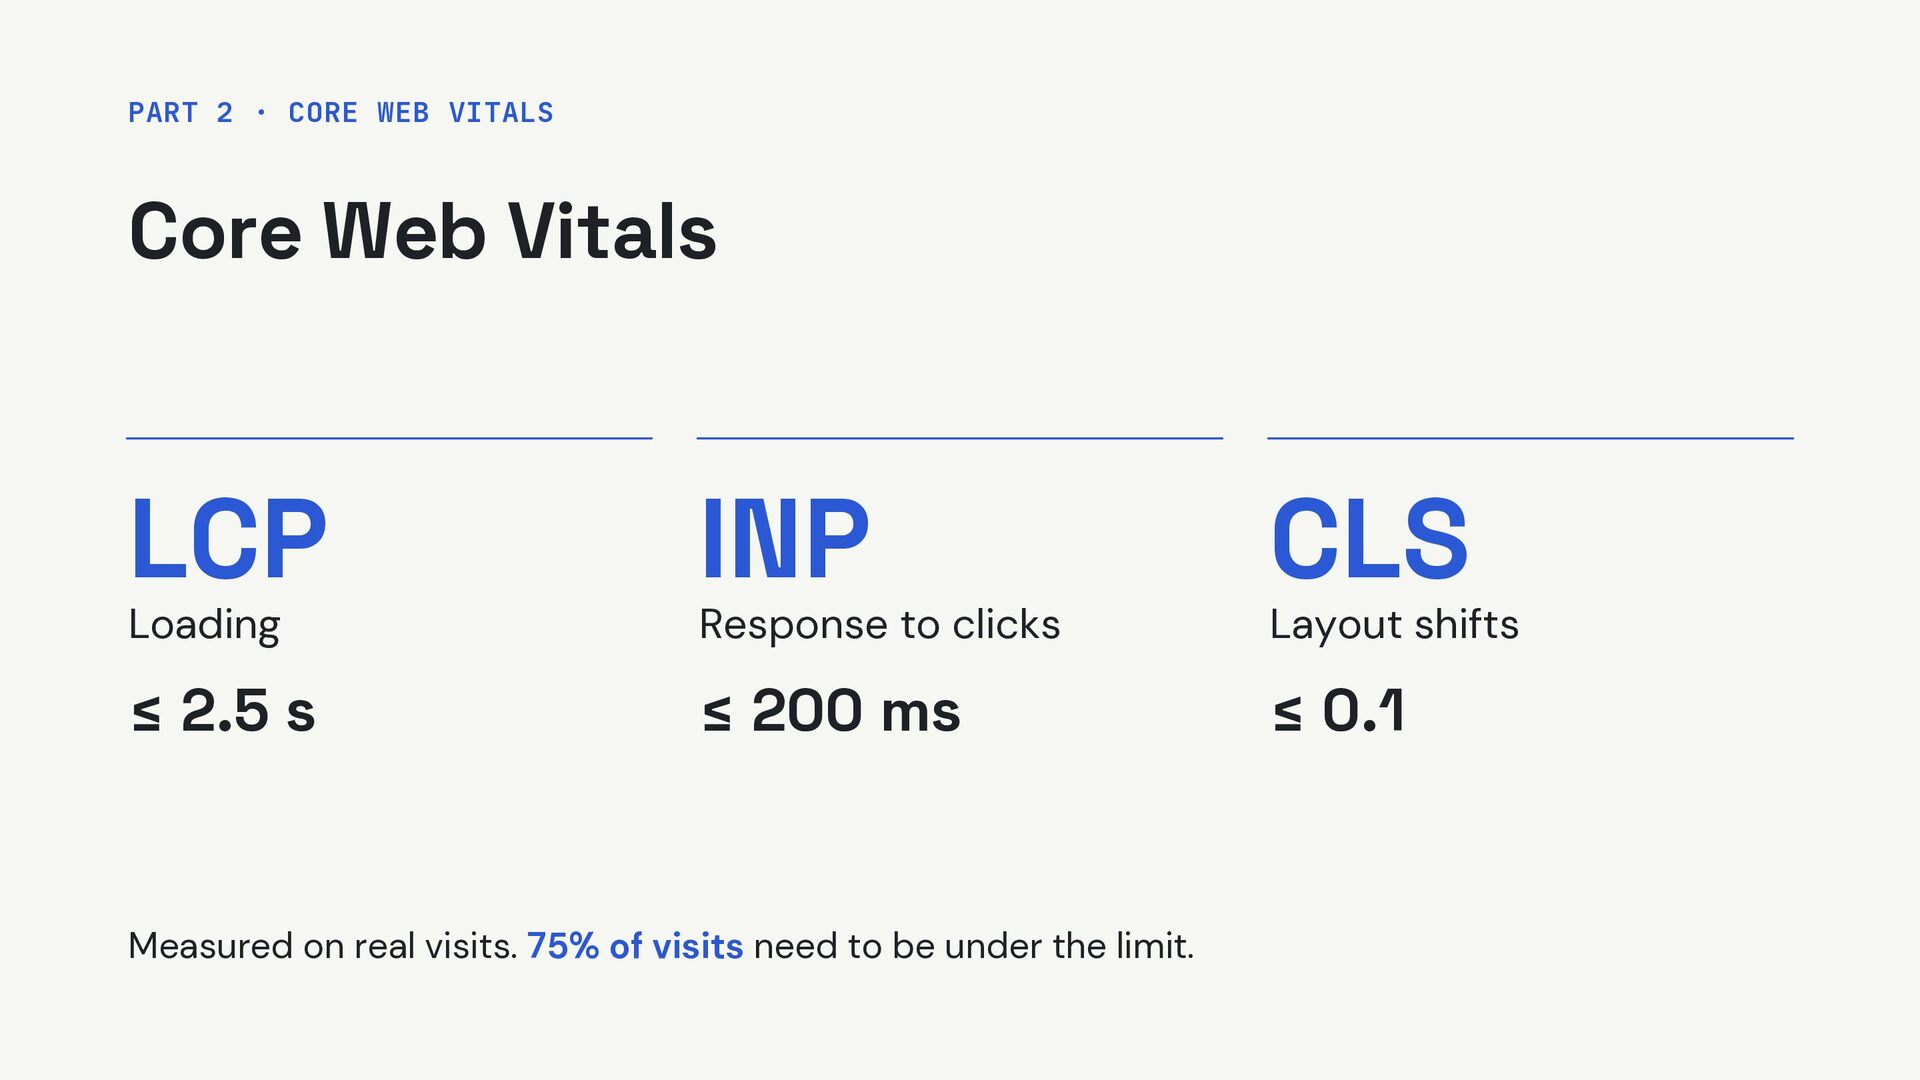
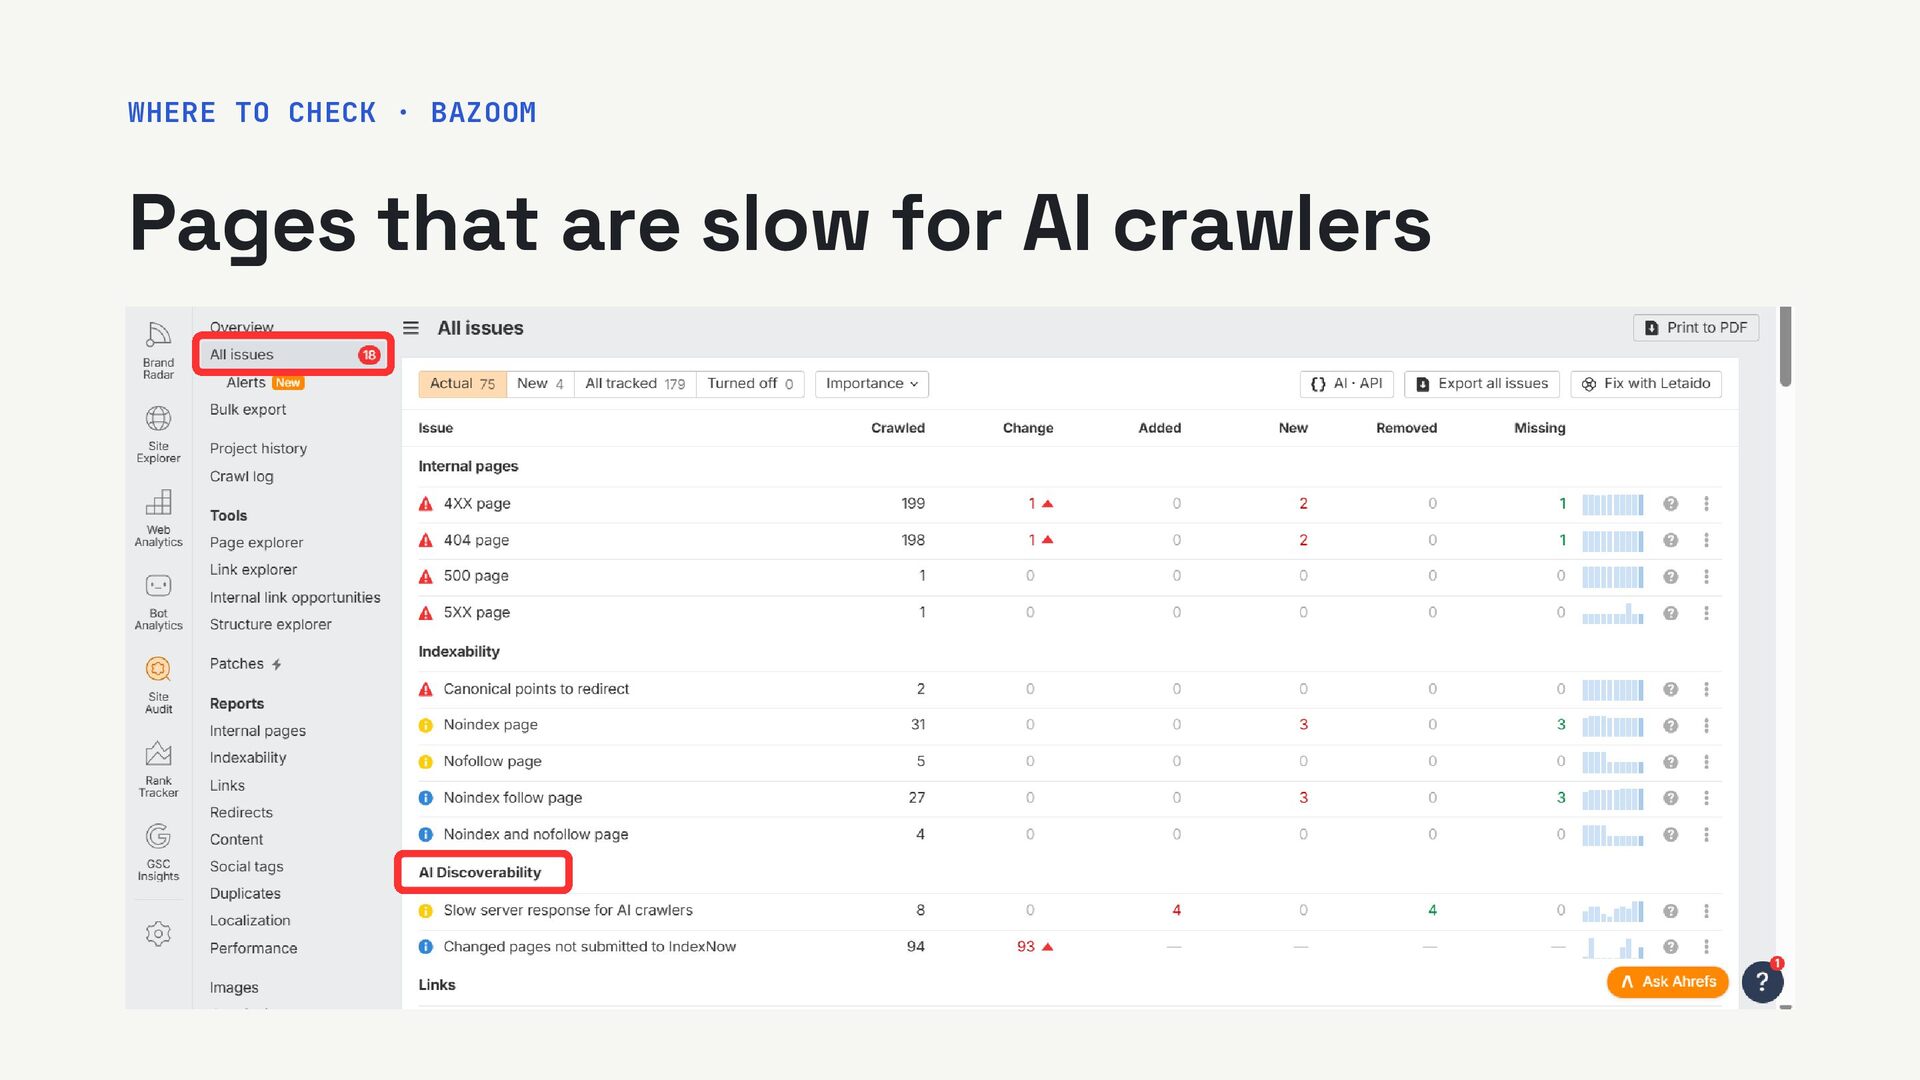
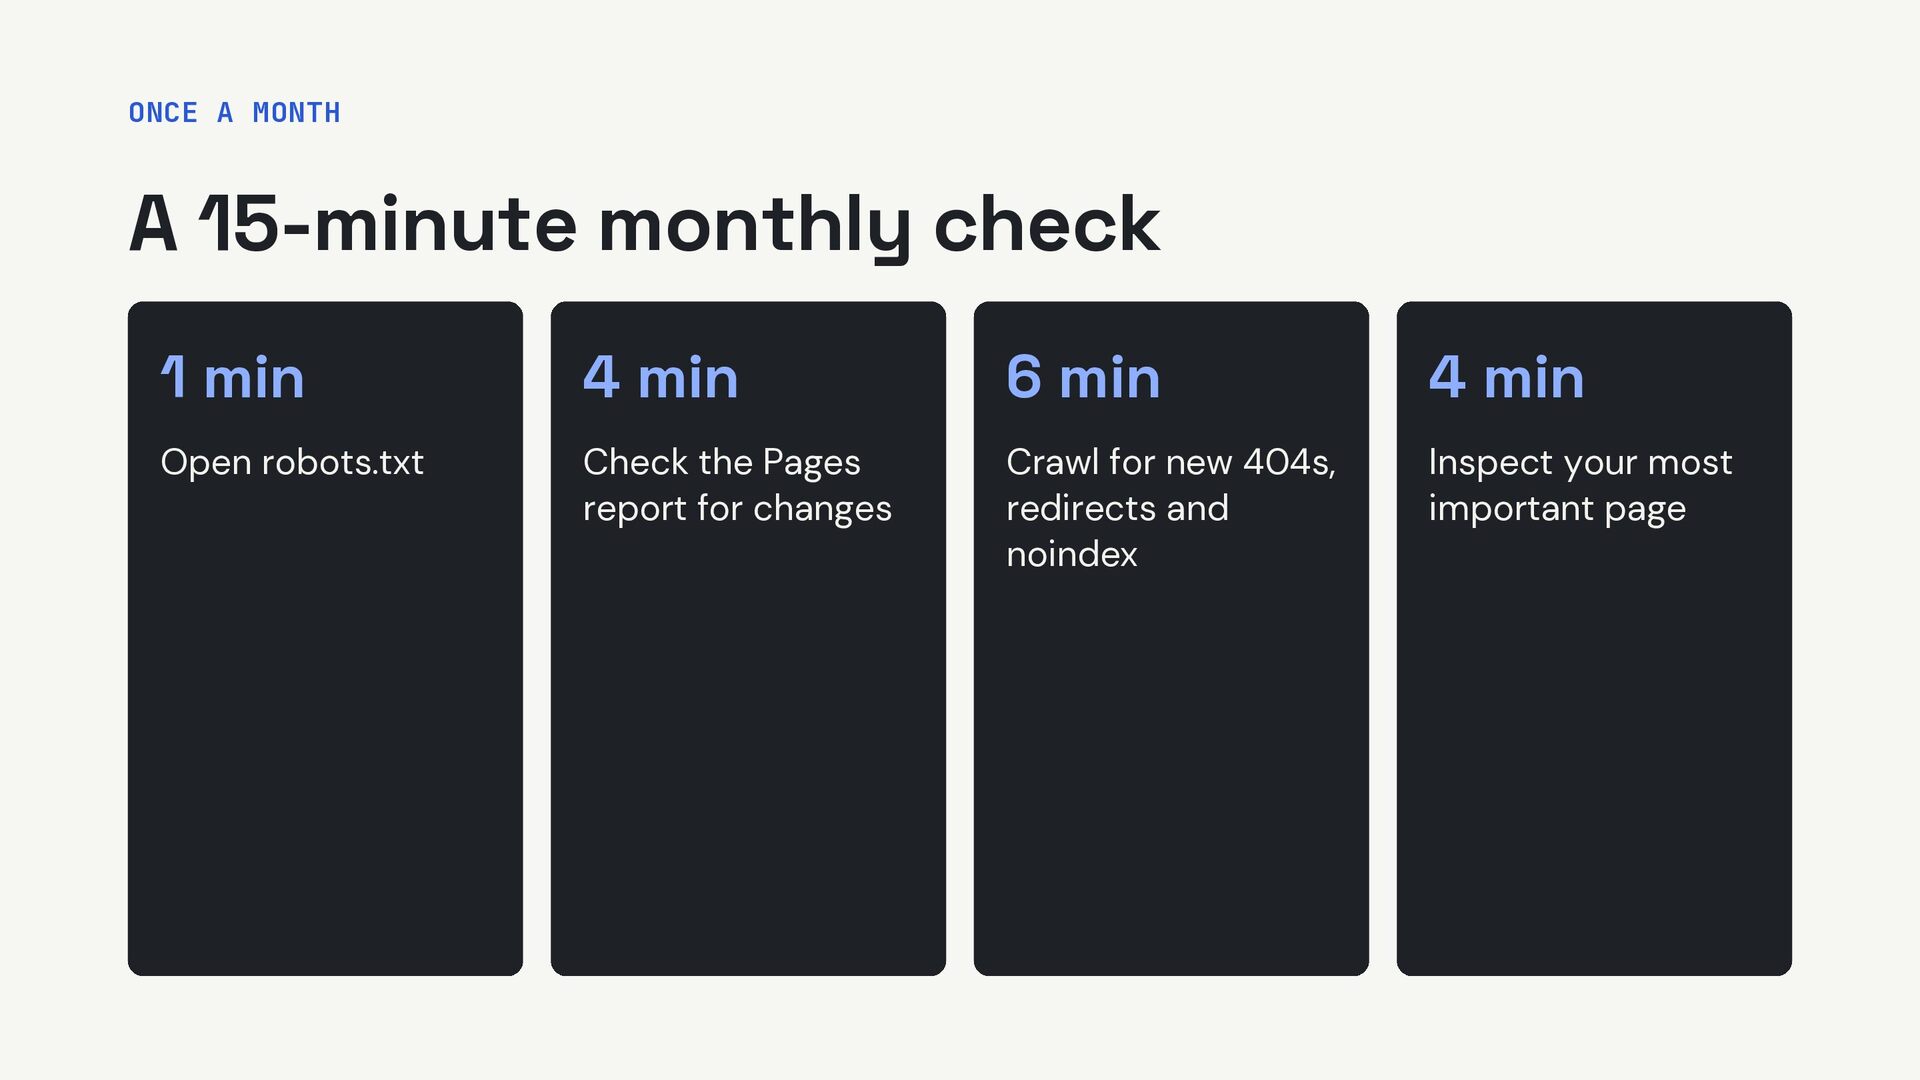
NDAs. NOTE This is the site I work o n. The issues are from our latest crawls. 198 URLs return a 404 59 pages have no internal links 44 internal links still use http://
behind them 02 Search Console, Rich Results, Core Web Vitals 03 Status codes, links, canonicals and more 04 AI crawlers 05 Practical fixes Pick one URL from a site you work on, or use my examples. We’ll need this for the site clinics.
opened a robots.txt file? Who has used URL Inspection? Who has never done a technical audit? No GSC access? Most checks today work without a login, so don’t worry!
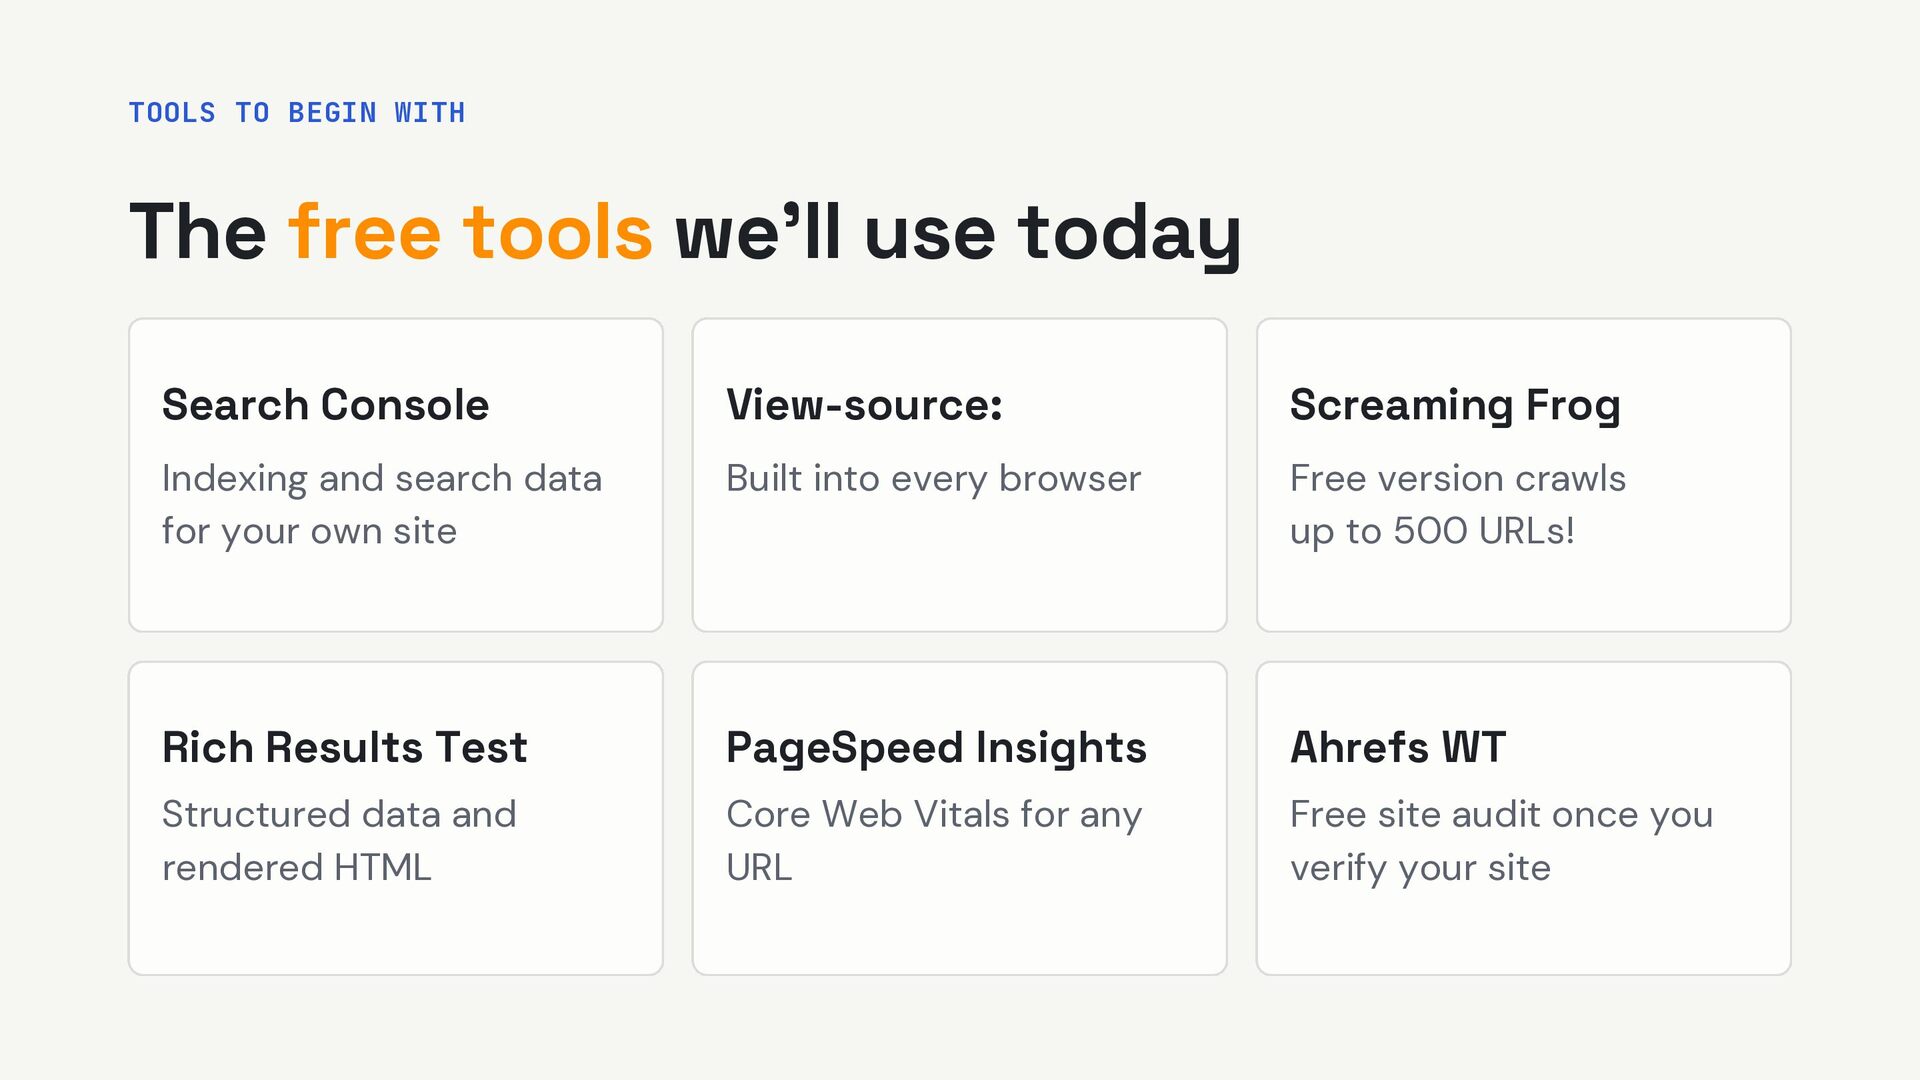
Search Console View-source: Screaming Frog Indexing and search data for your own site Built into every browser Free version crawls up to 500 URLs! Rich Results Test PageSpeed Insights Ahrefs WT Structured data and rendered HTML Core Web Vitals for any URL Free site audit once you verify your site
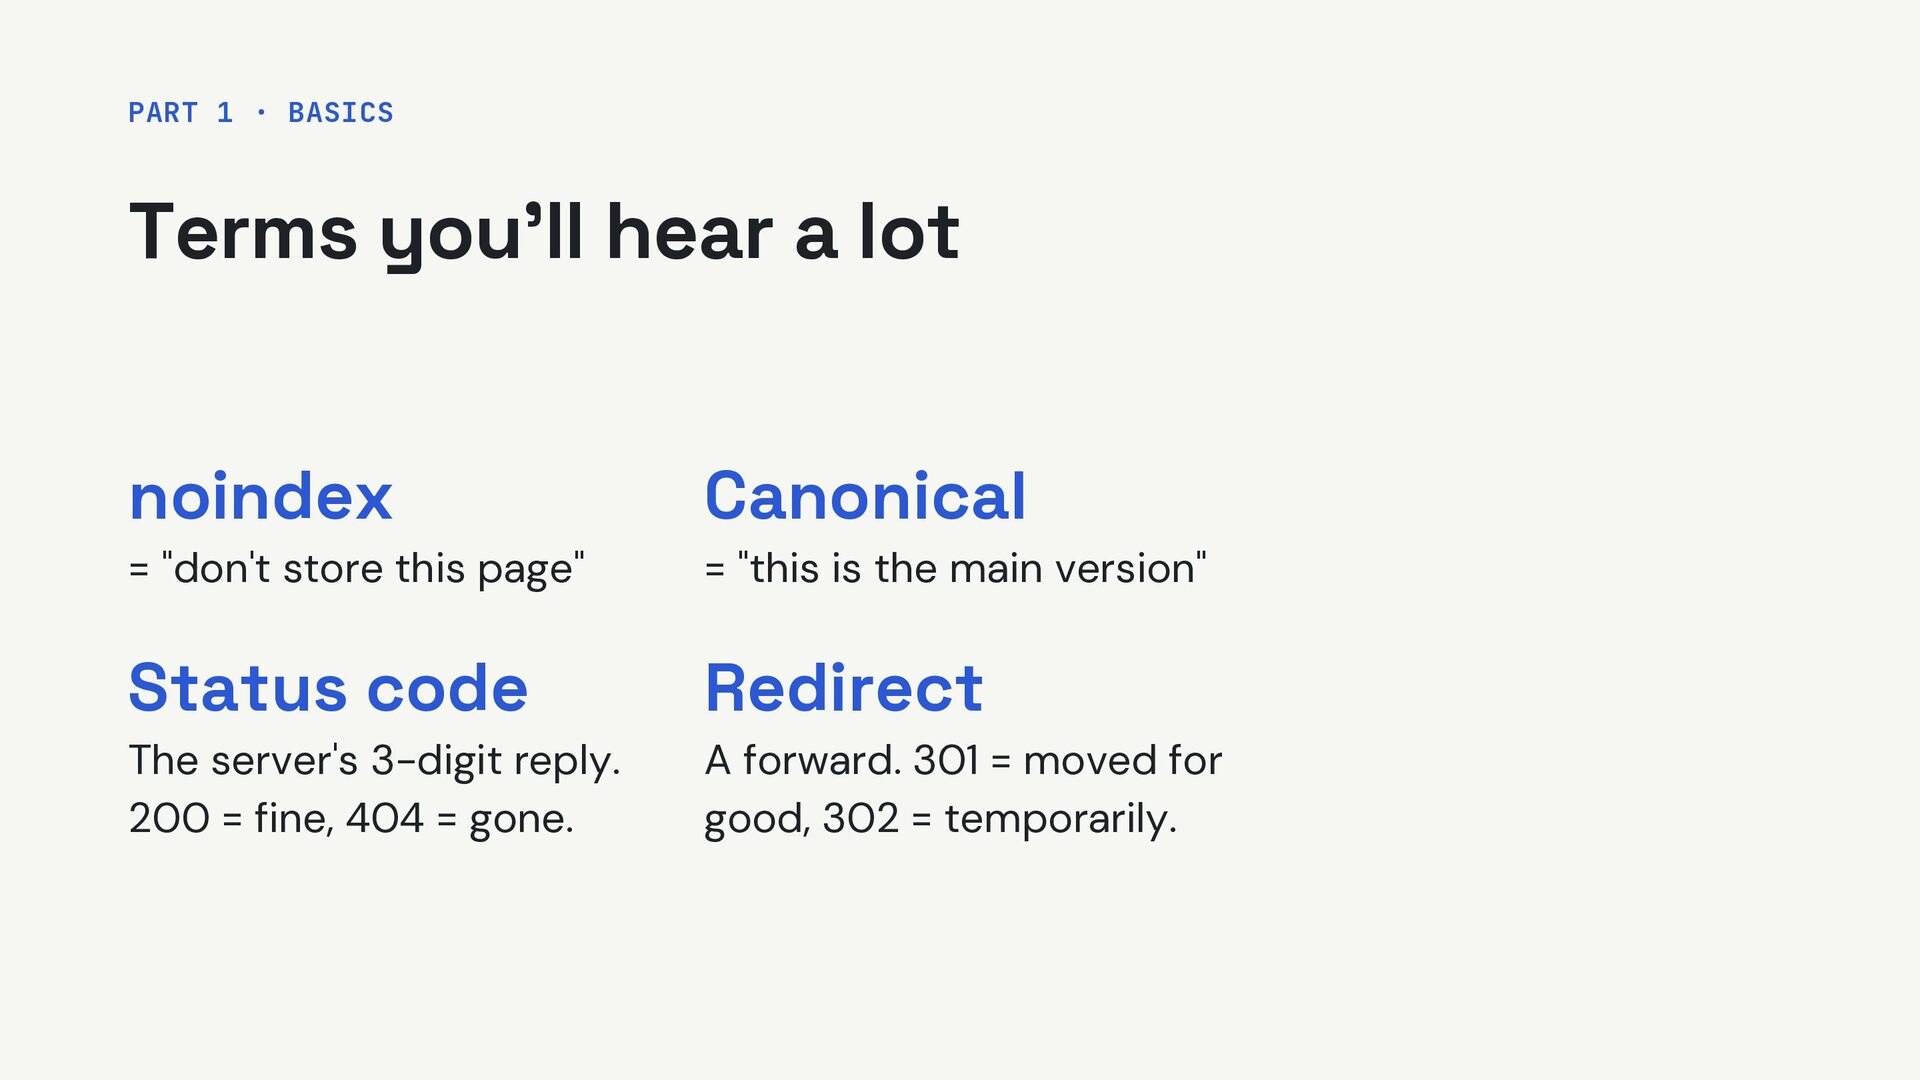
Canonical = "don't store this page" = "this is the main version" Status code Redirect The server's 3-digit reply. 200 = fine, 404 = gone. A forward. 301 = moved for good, 302 = temporarily.
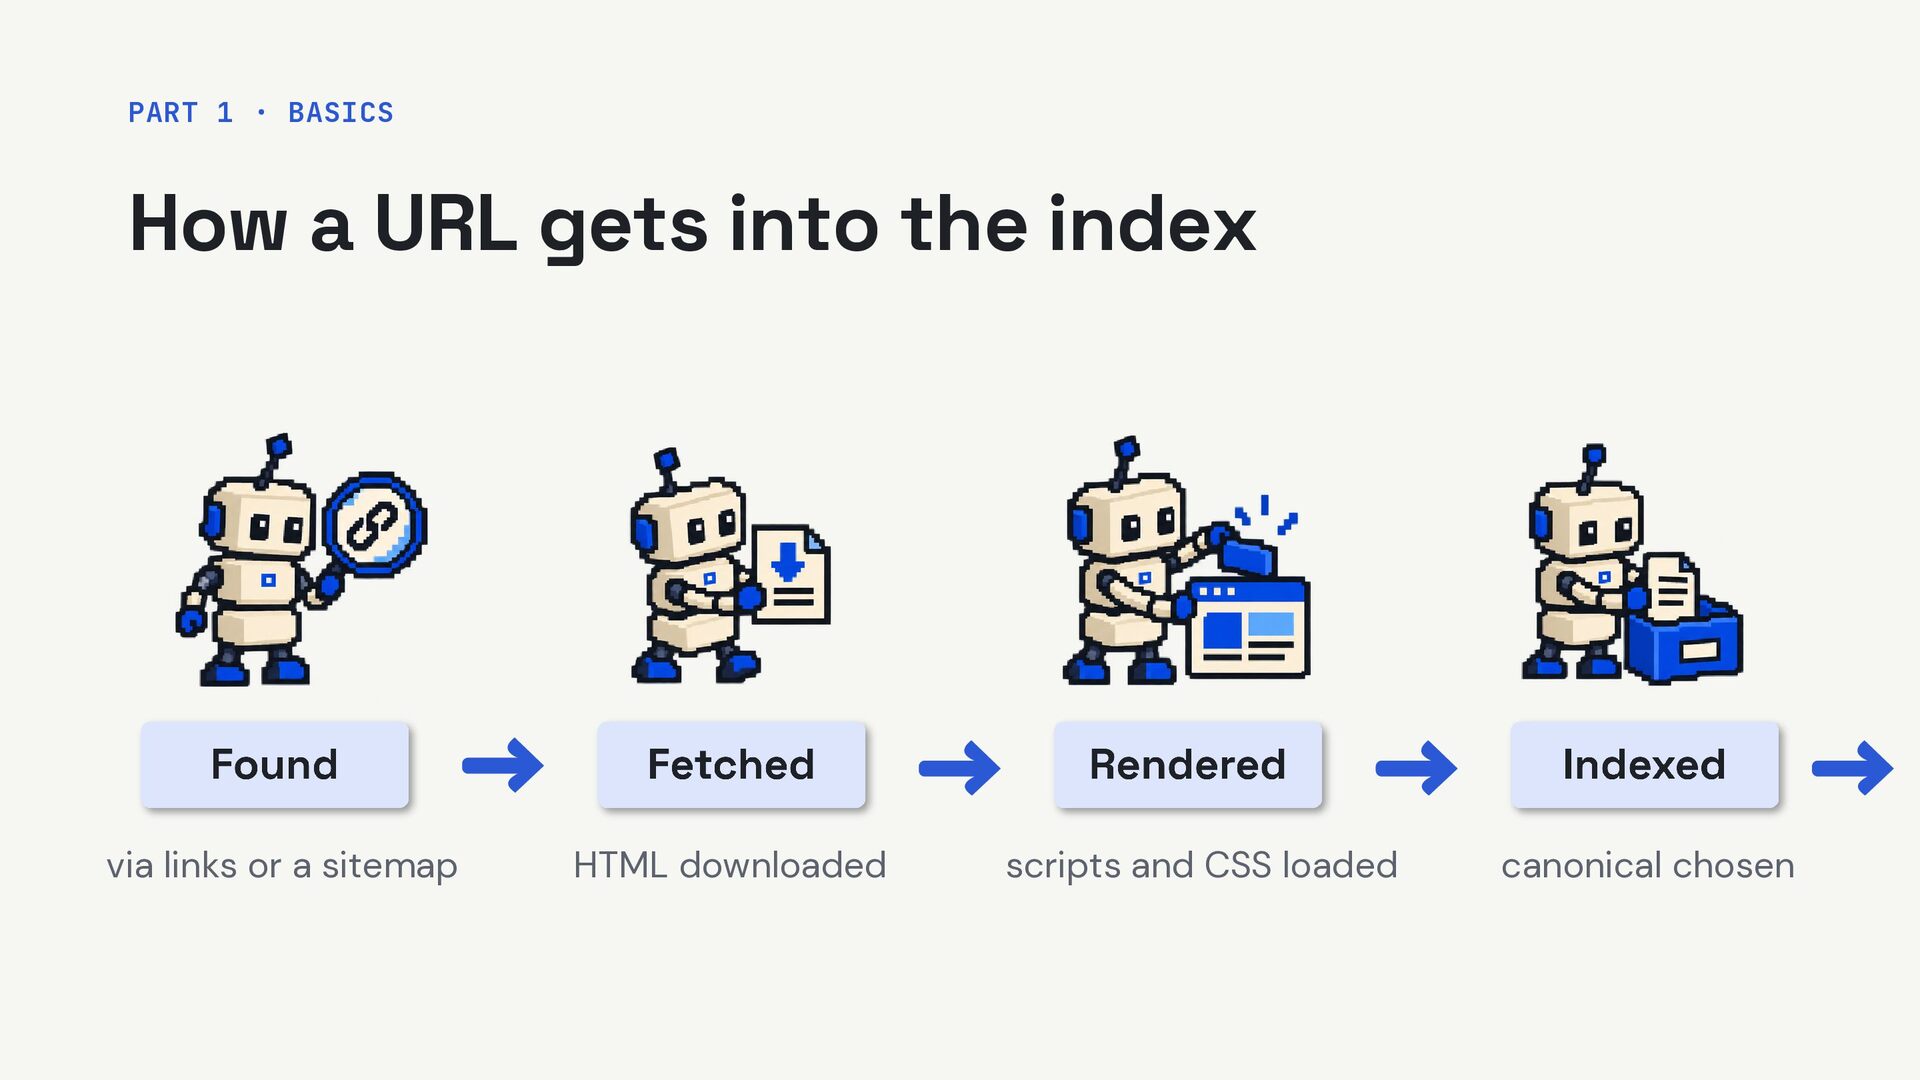
index Technical SEO = removing friction at Found to Indexed. Content and links do the heavy lifting at Ranked and Cited. shows for a query used in AI answers
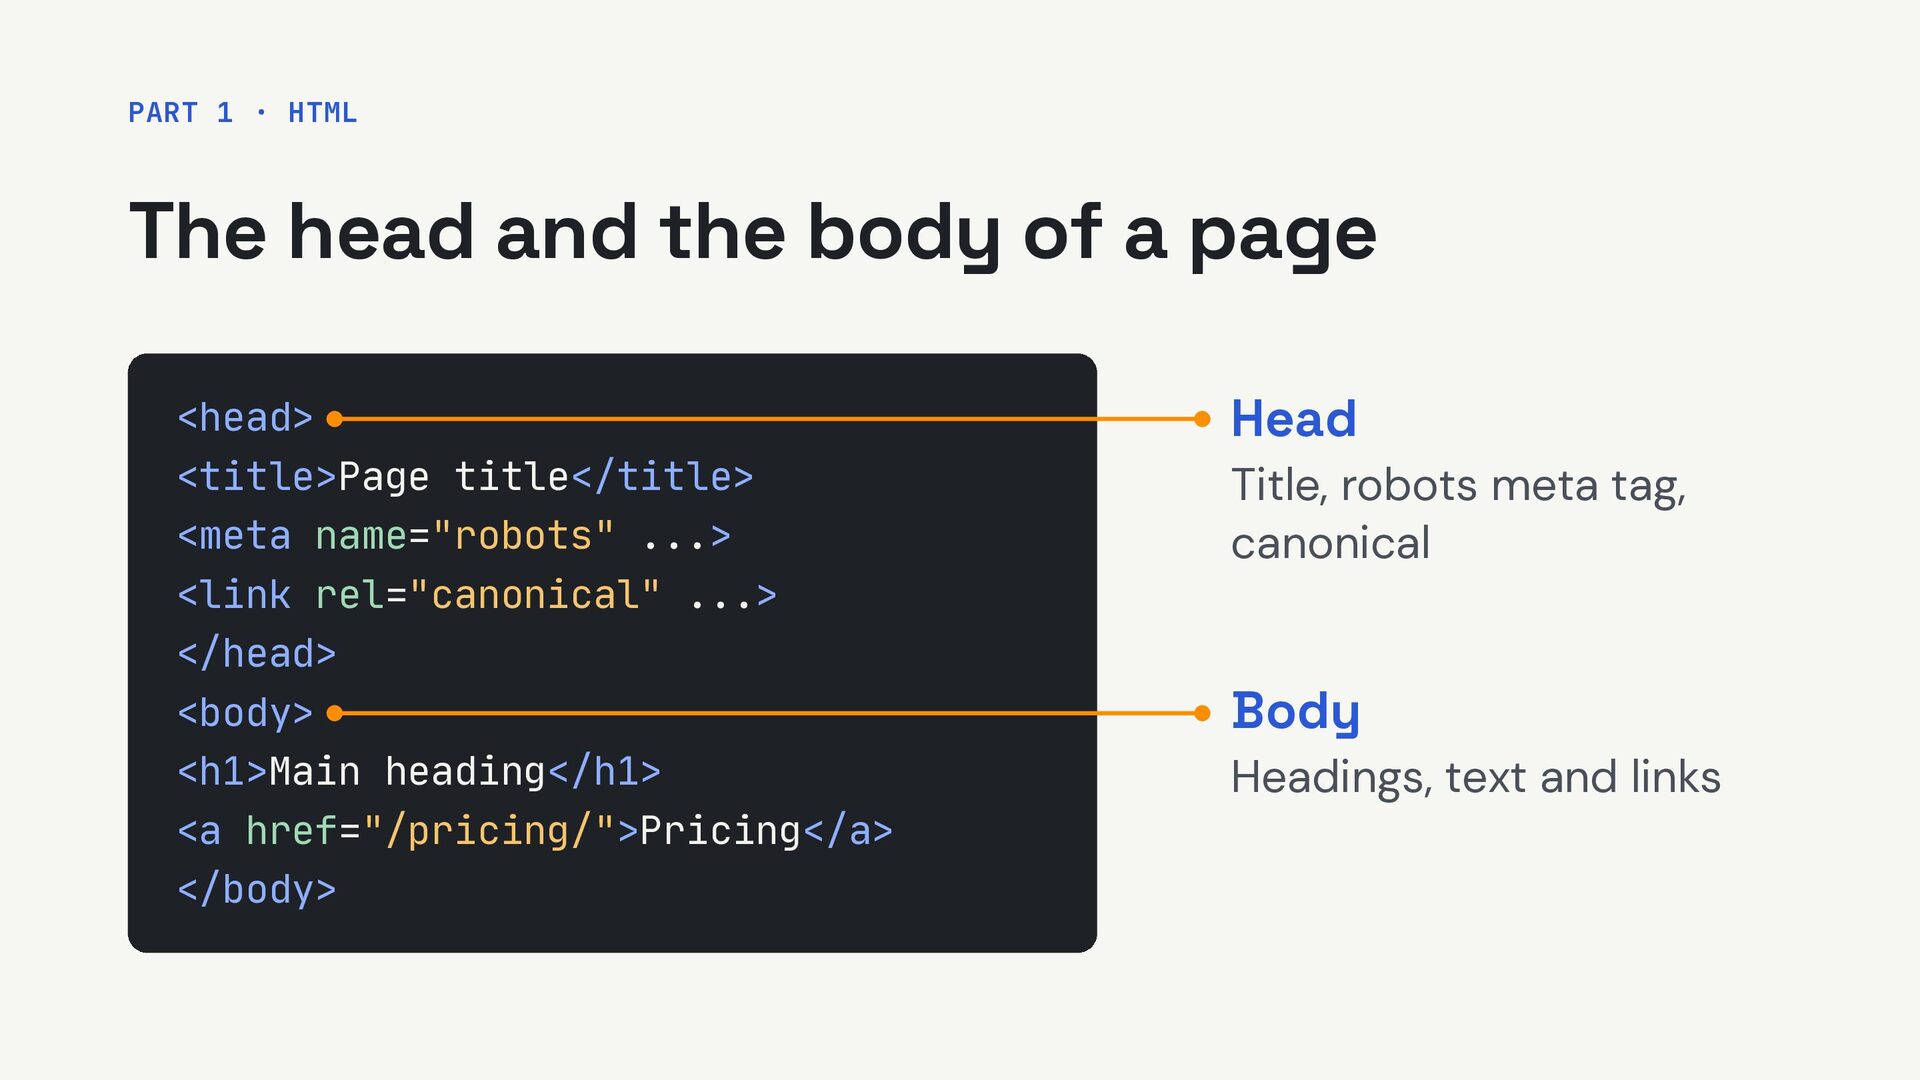
a page <head> Head <title>Page title</title> Title, robots meta tag, canonical <meta name="robots" ...> <link rel="canonical" ...> </head> <body> Body <h1>Main heading</h1> Headings, text and links <a href="/pricing/">Pricing</a> </body>
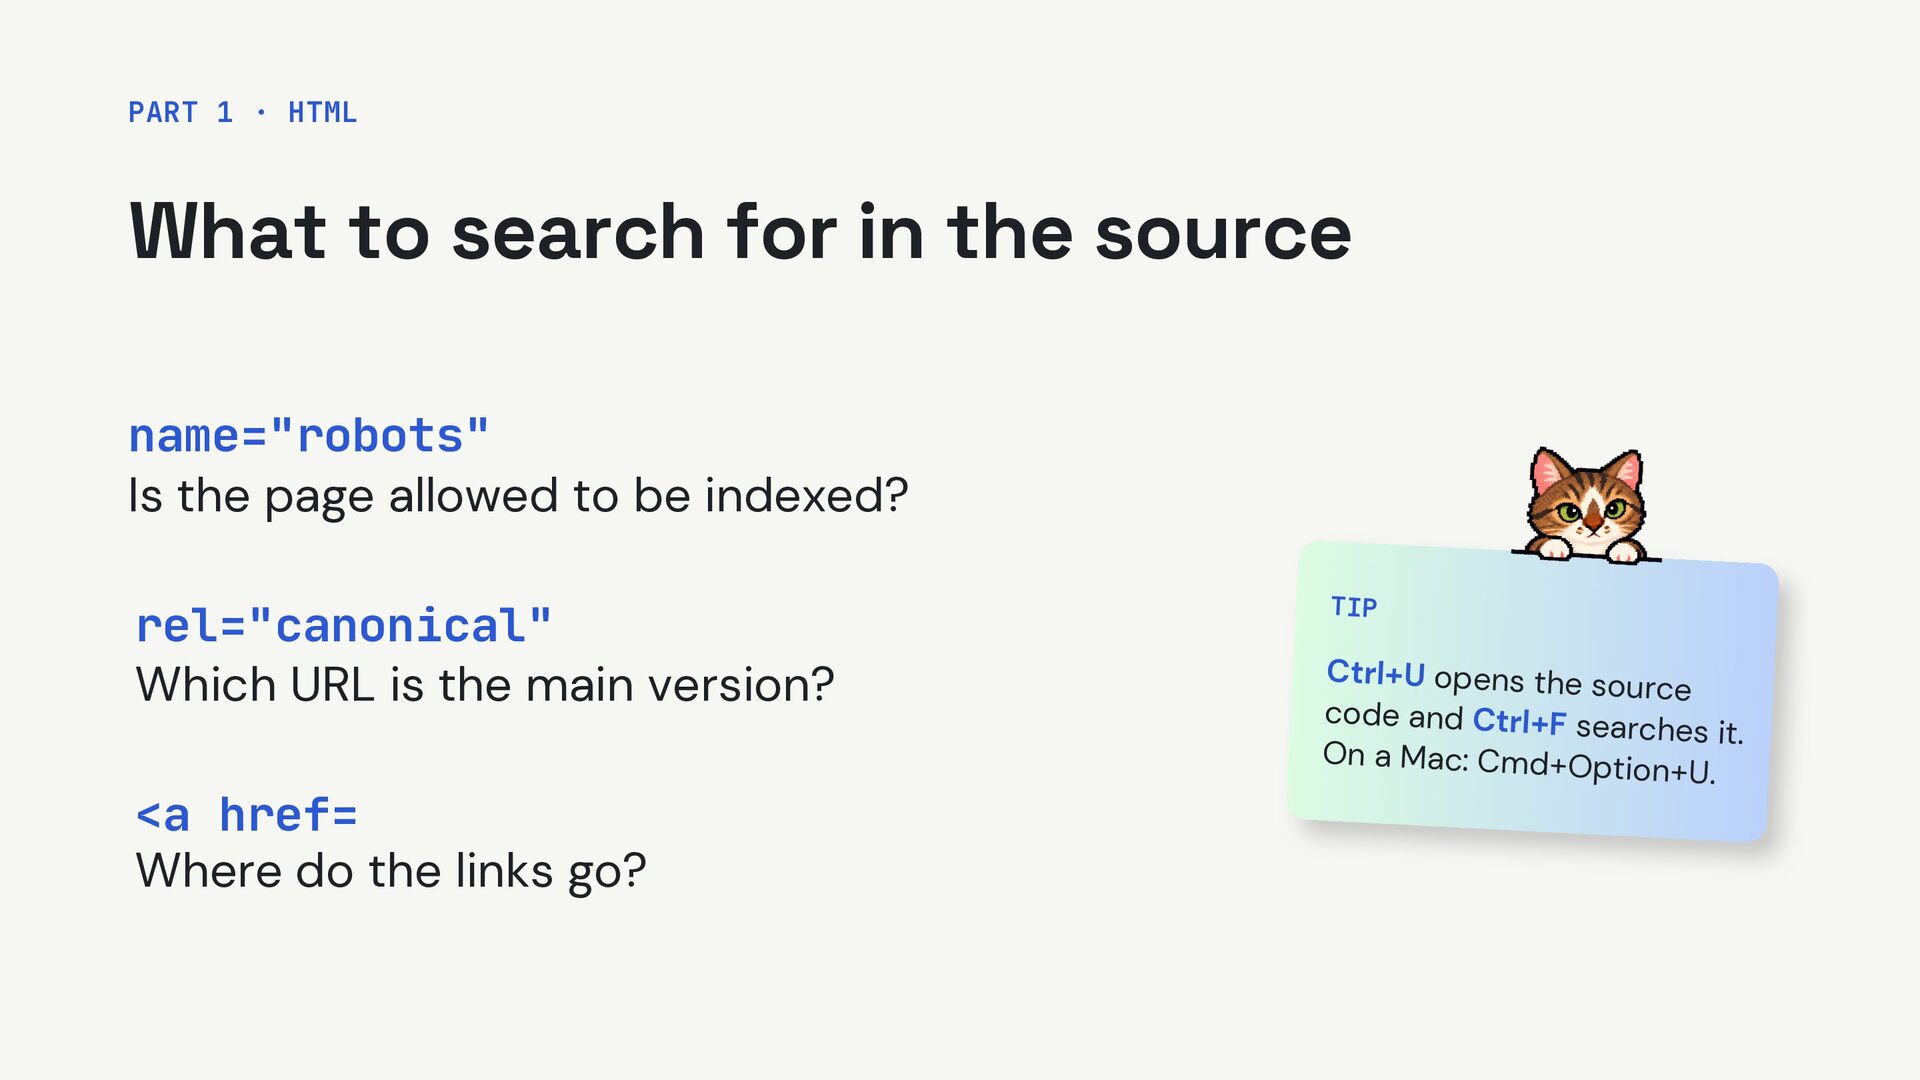
source name="robots" Is the page allowed to be indexed? rel="canonical" Which URL is the main version? <a href= Where do the links go? TIP Ctrl+U opens the sou rce code and Ctrl+F searc hes it. On a Mac: Cmd+Opti o n+ U .
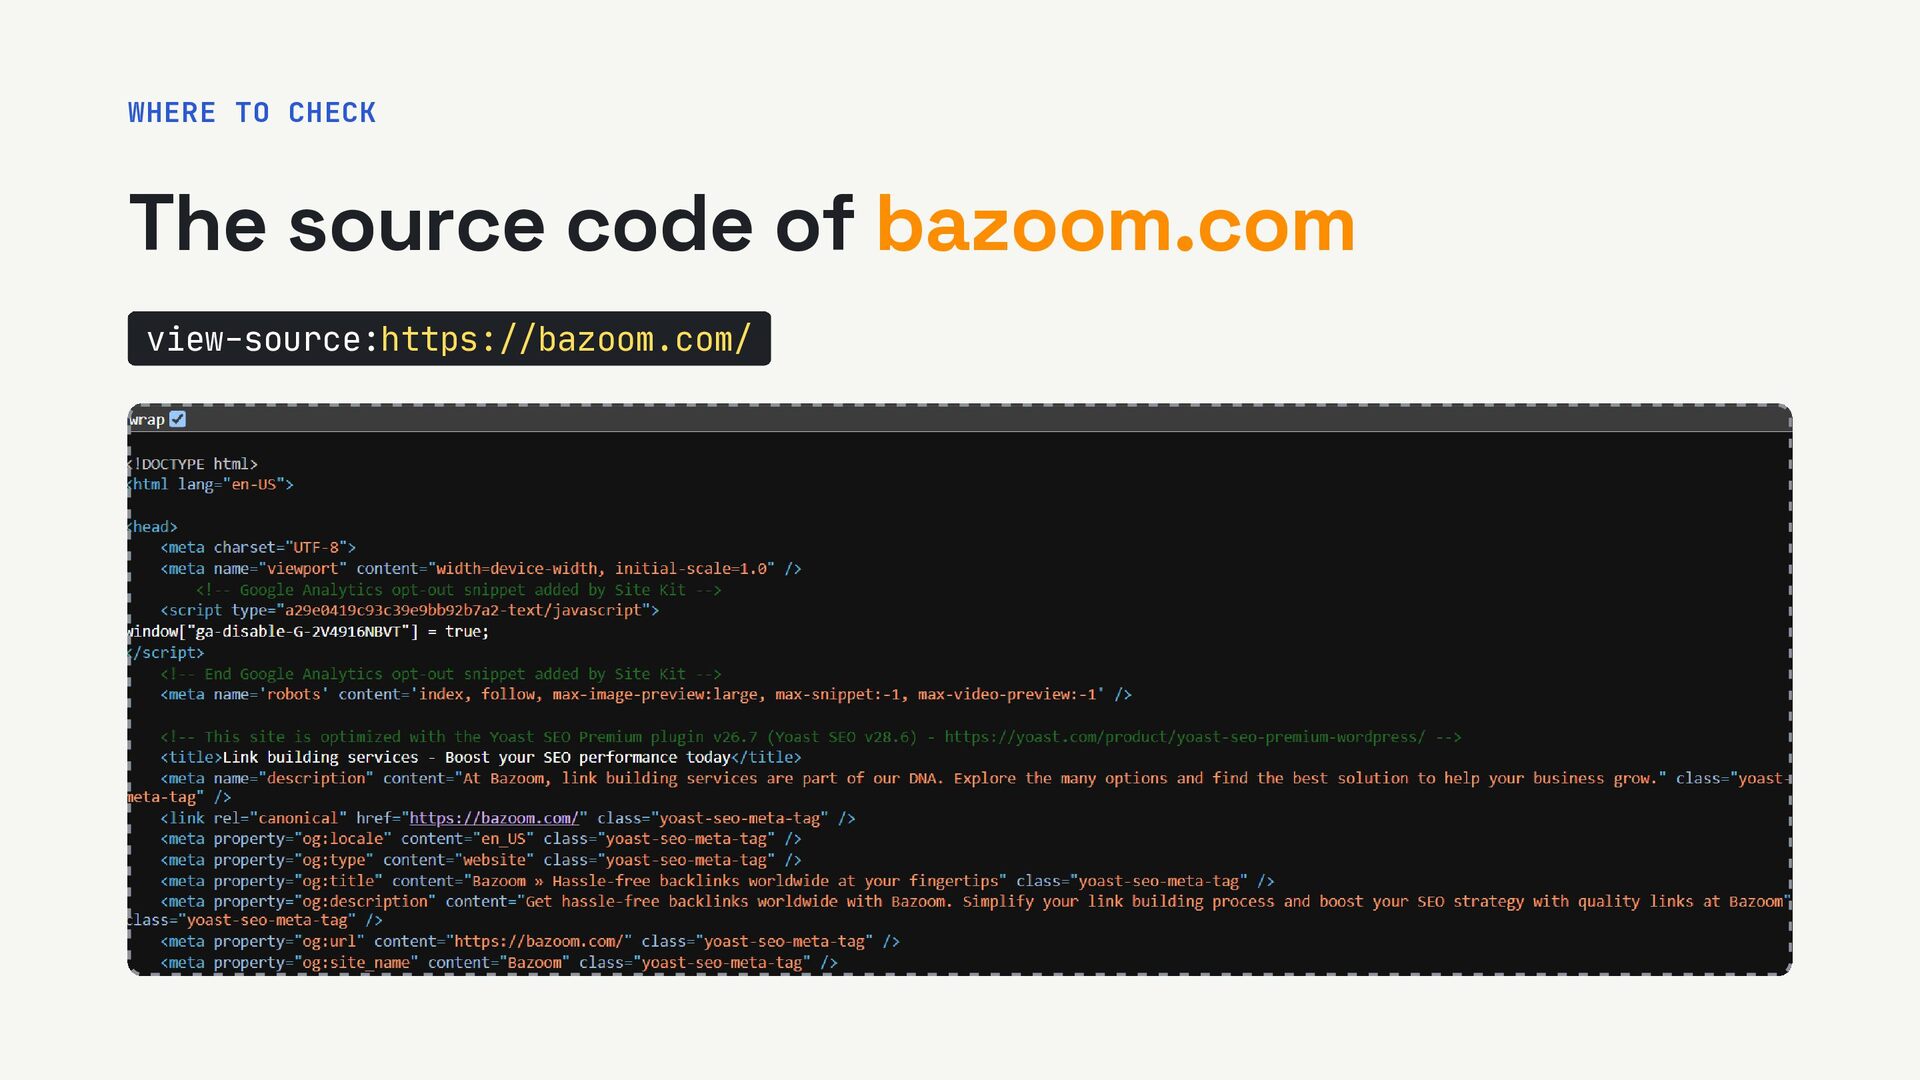
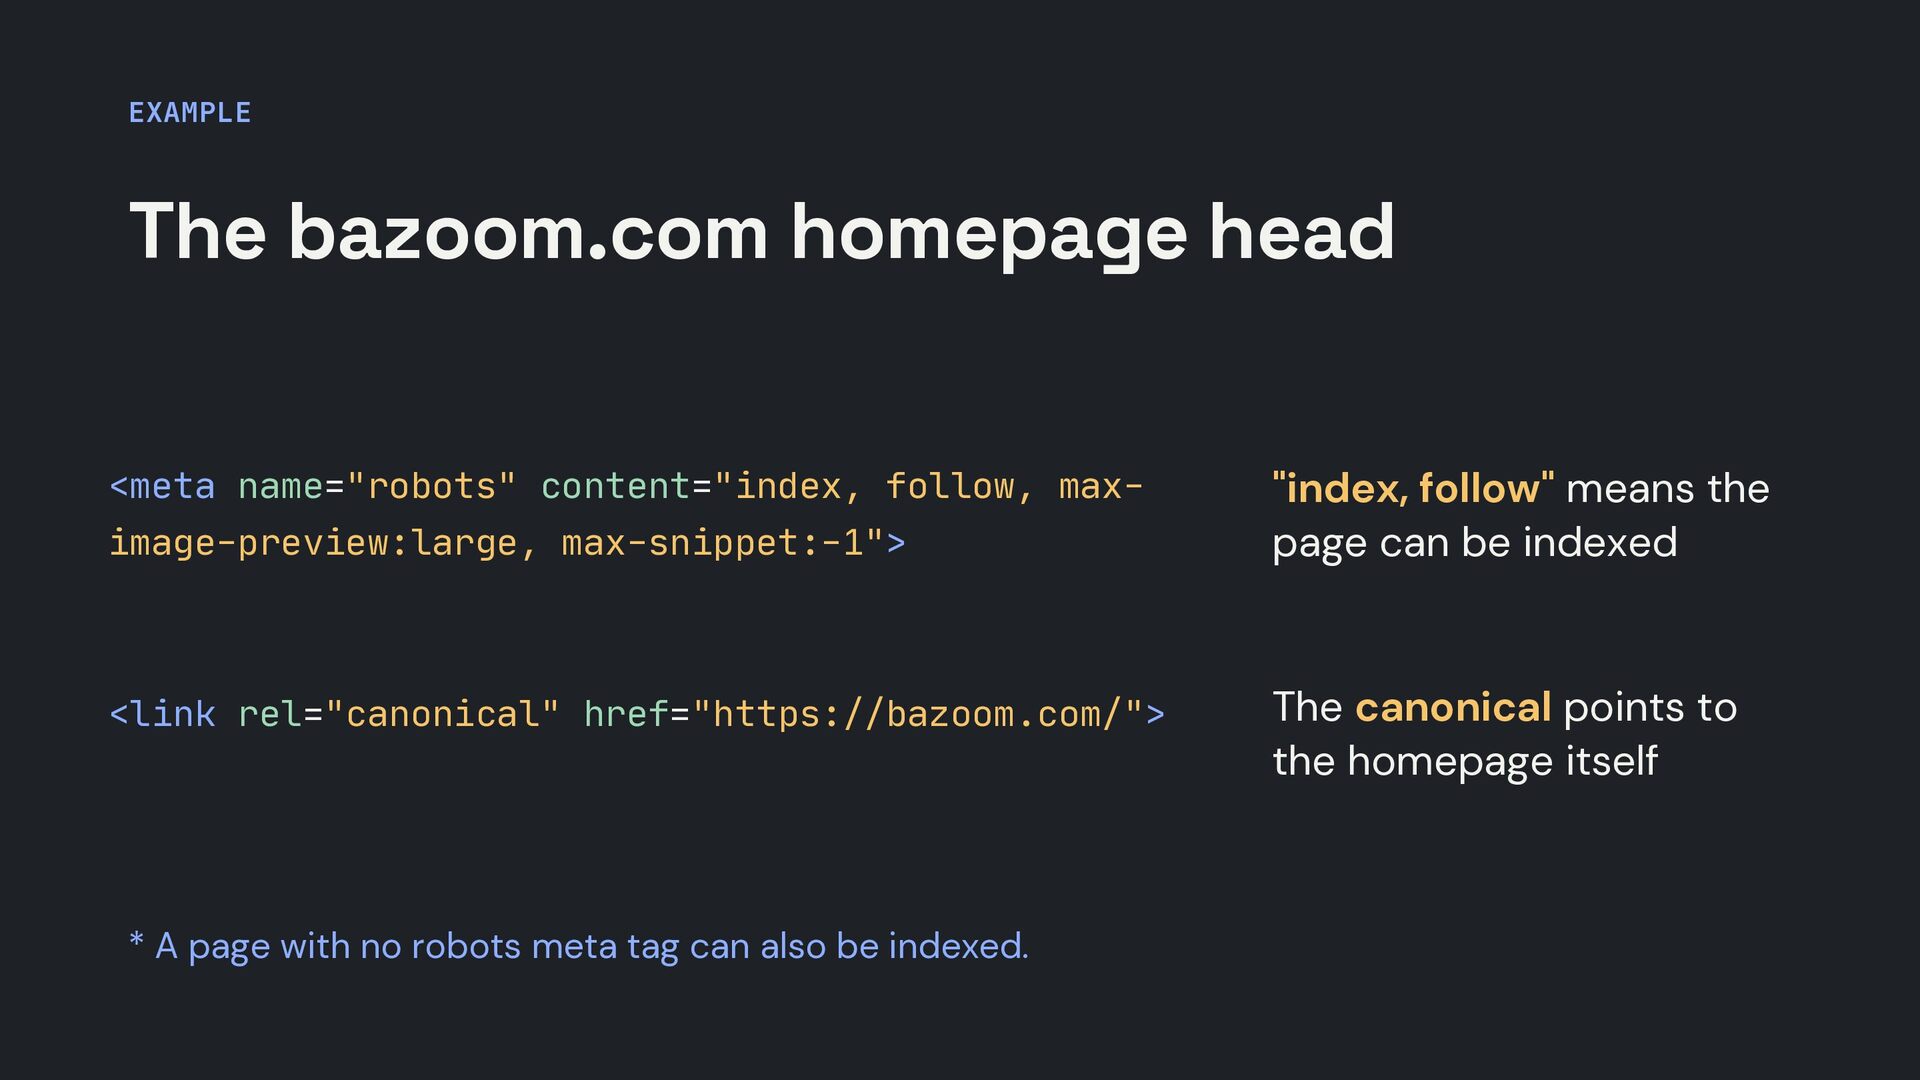
max-snippet:-1"> <link rel="canonical" href="https://bazoom.com/"> * A page with no robots meta tag can also be indexed. "index, follow" means the page can be indexed The canonical points to the homepage itself
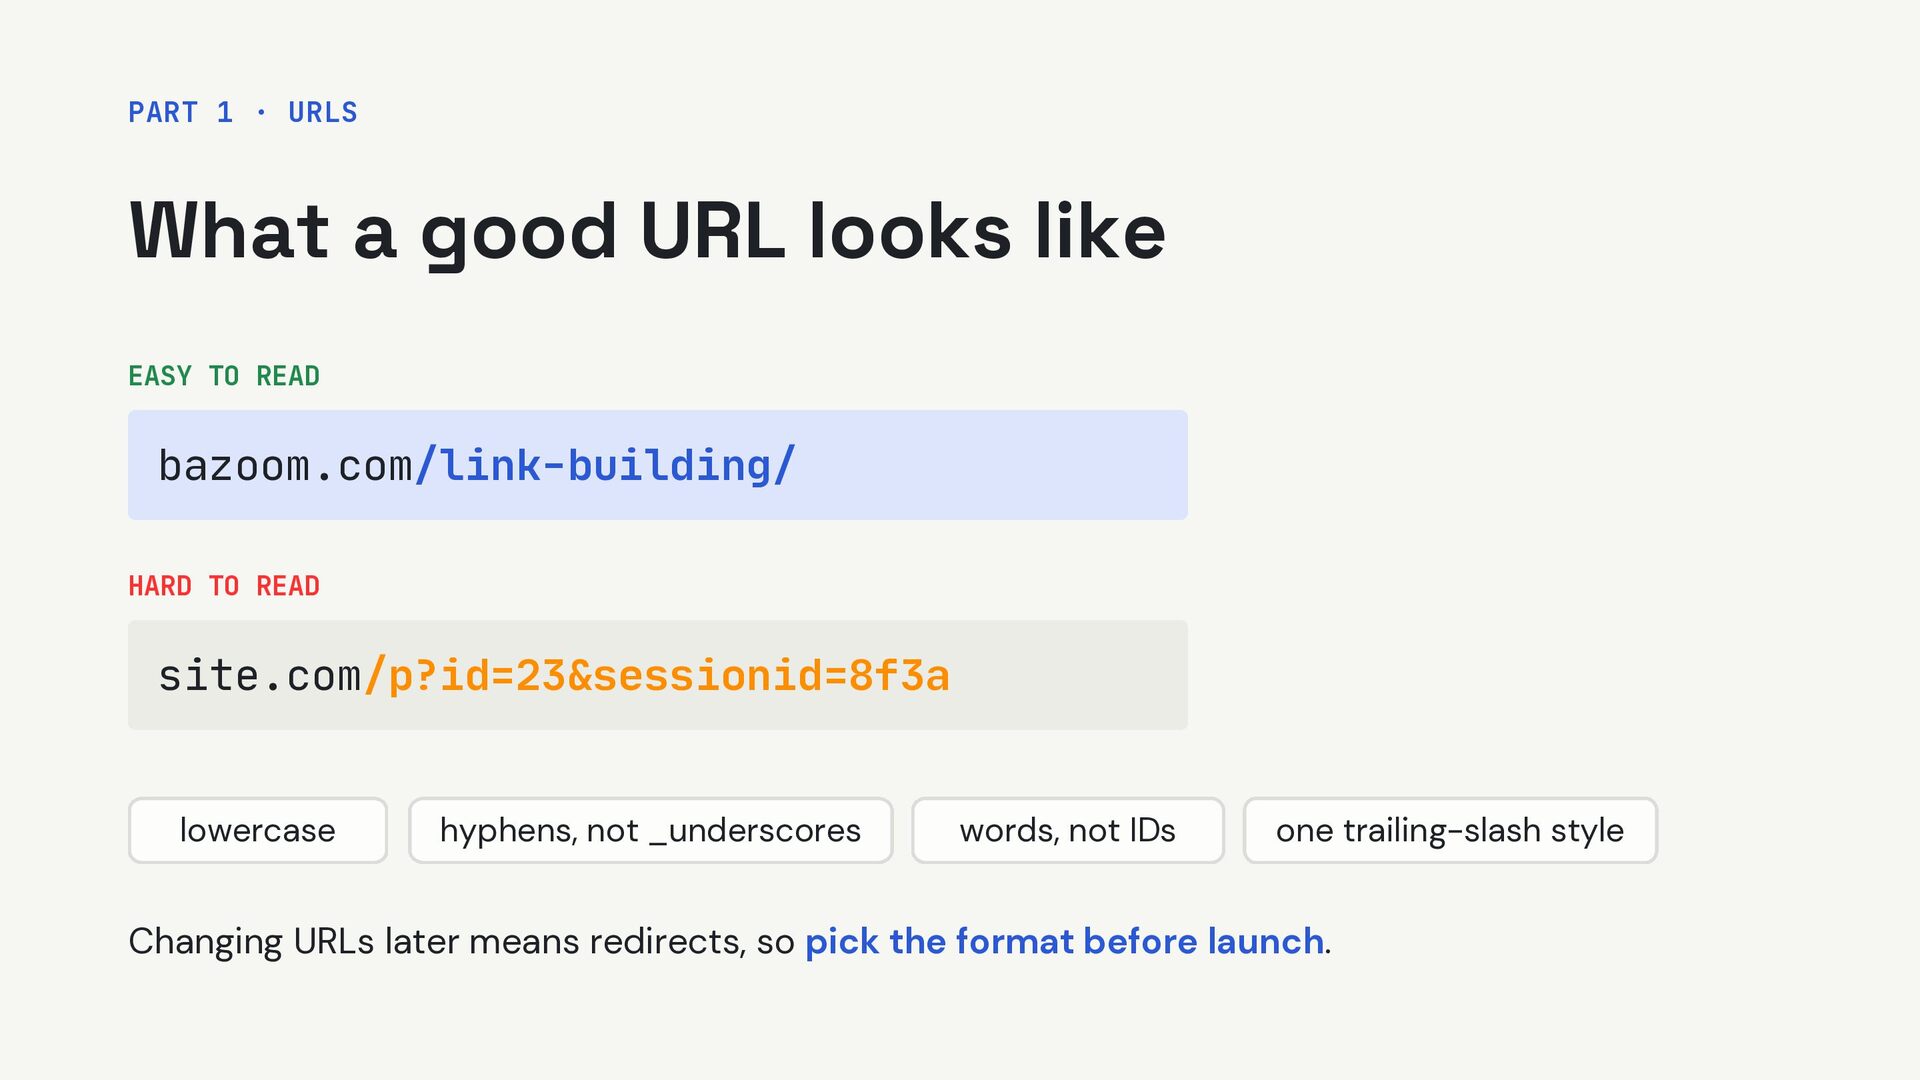
EASY TO READ bazoom.com/link-building/ HARD TO READ site.com/p?id=23&sessionid=8f3a lowercase hyphens, not _underscores words, not IDs one trailing-slash style Changing URLs later means redirects, so pick the format before launch.
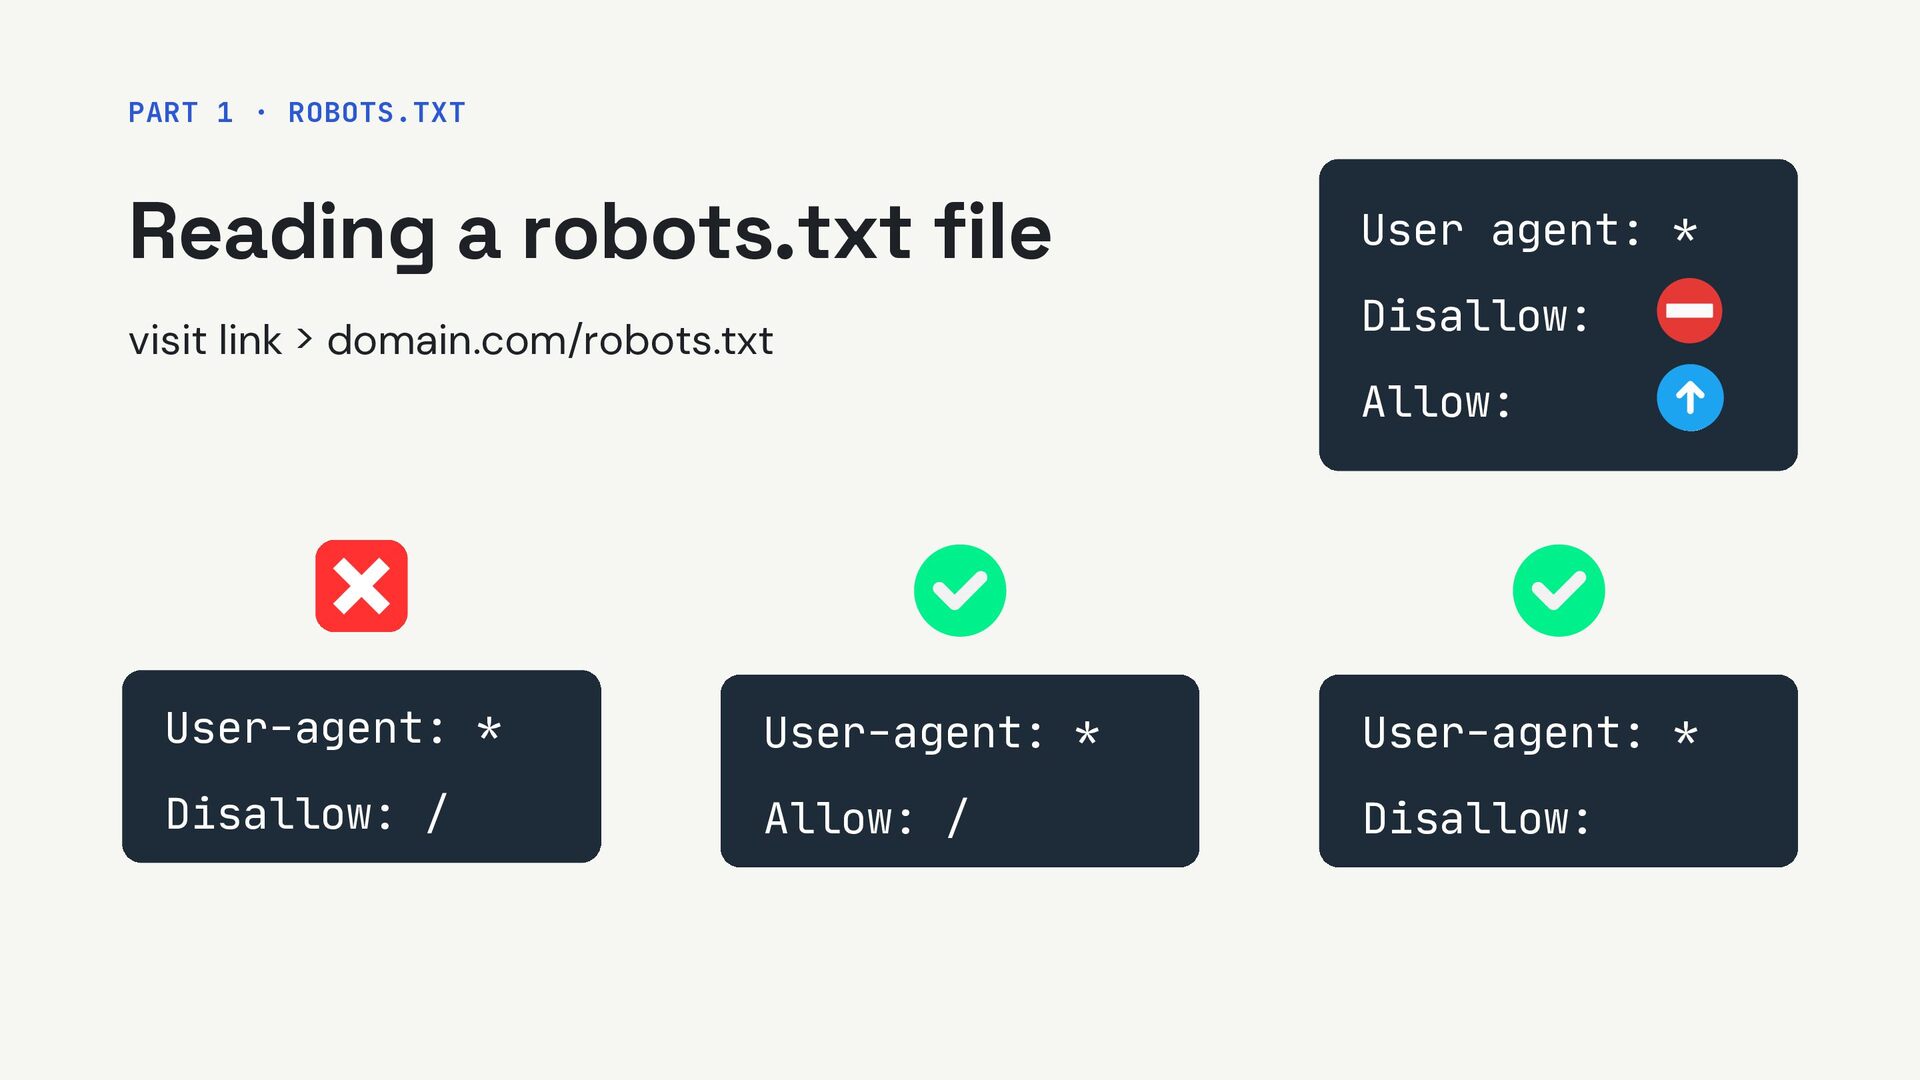
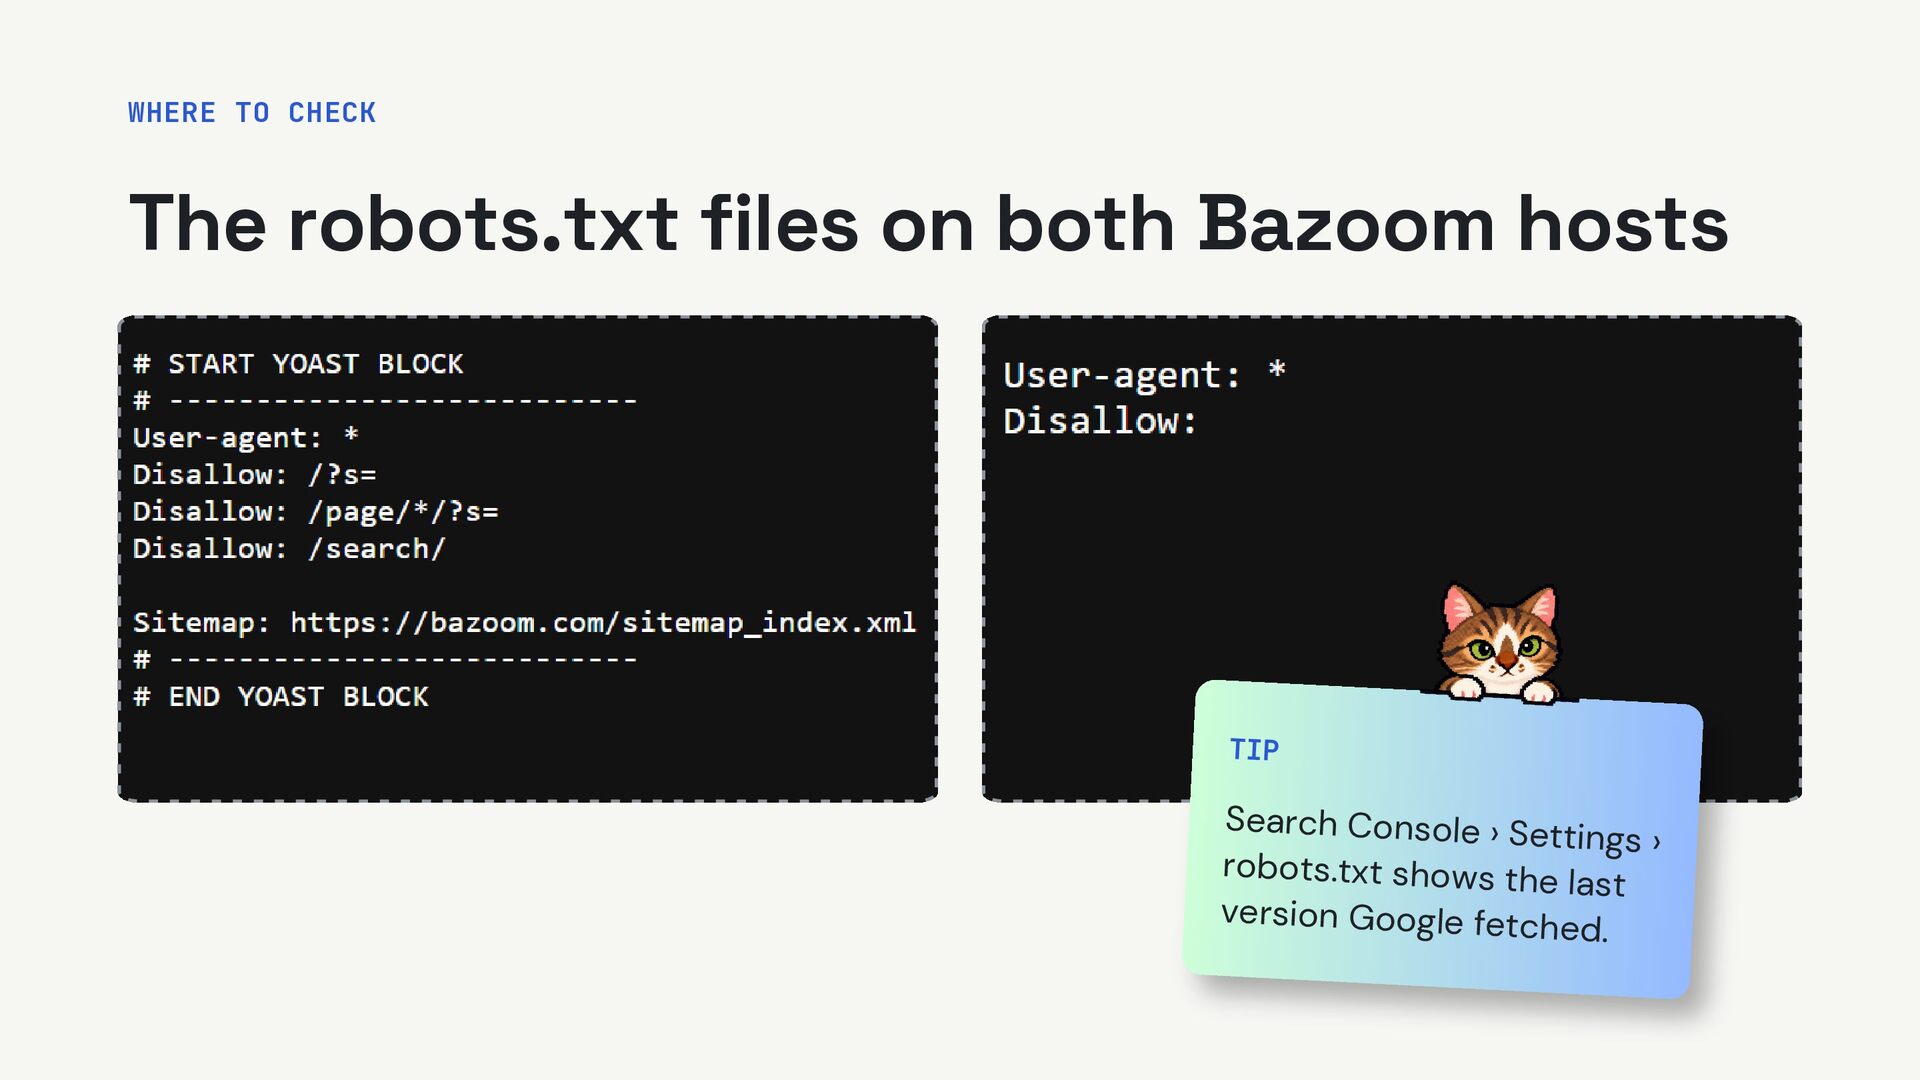
which paths they shouldn't fetch. It doesn't remove a page from search, and it doesn't hide it from people. Each subdomain also has its own robots.txt file.
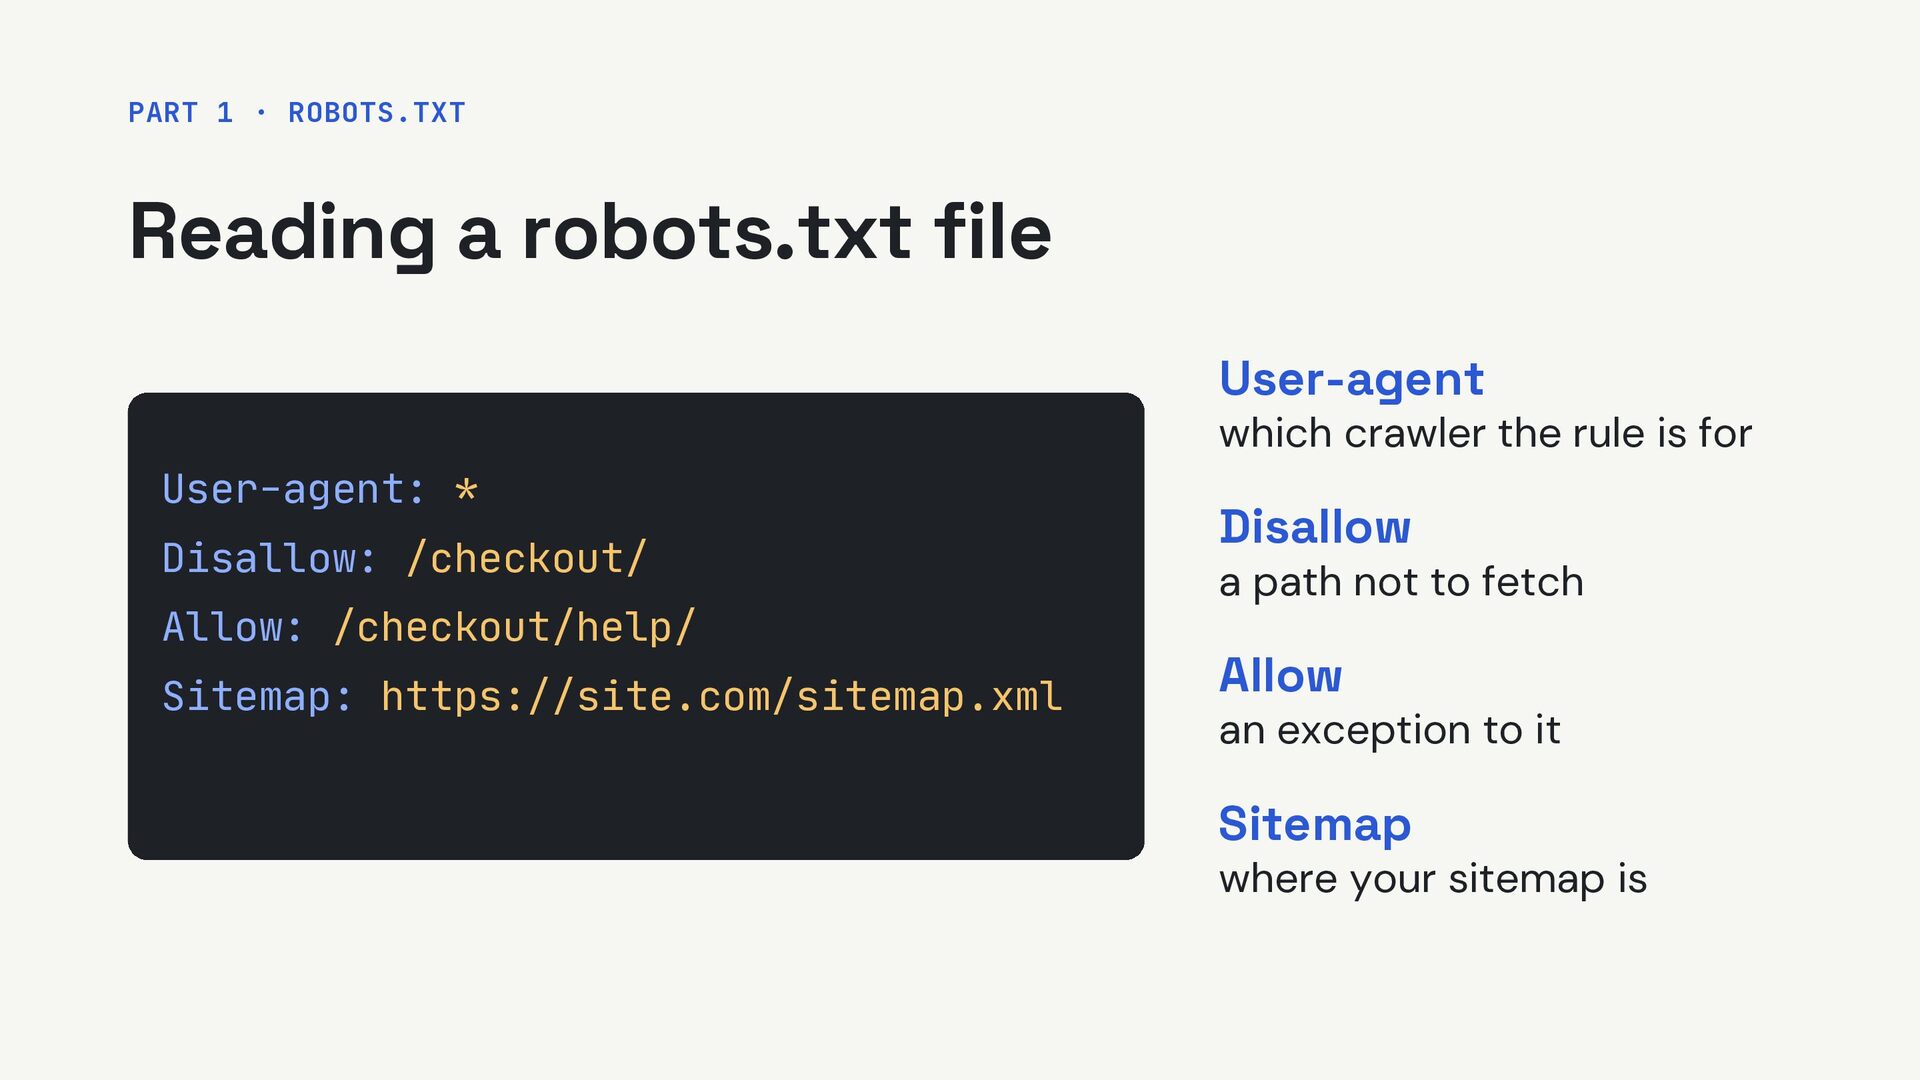
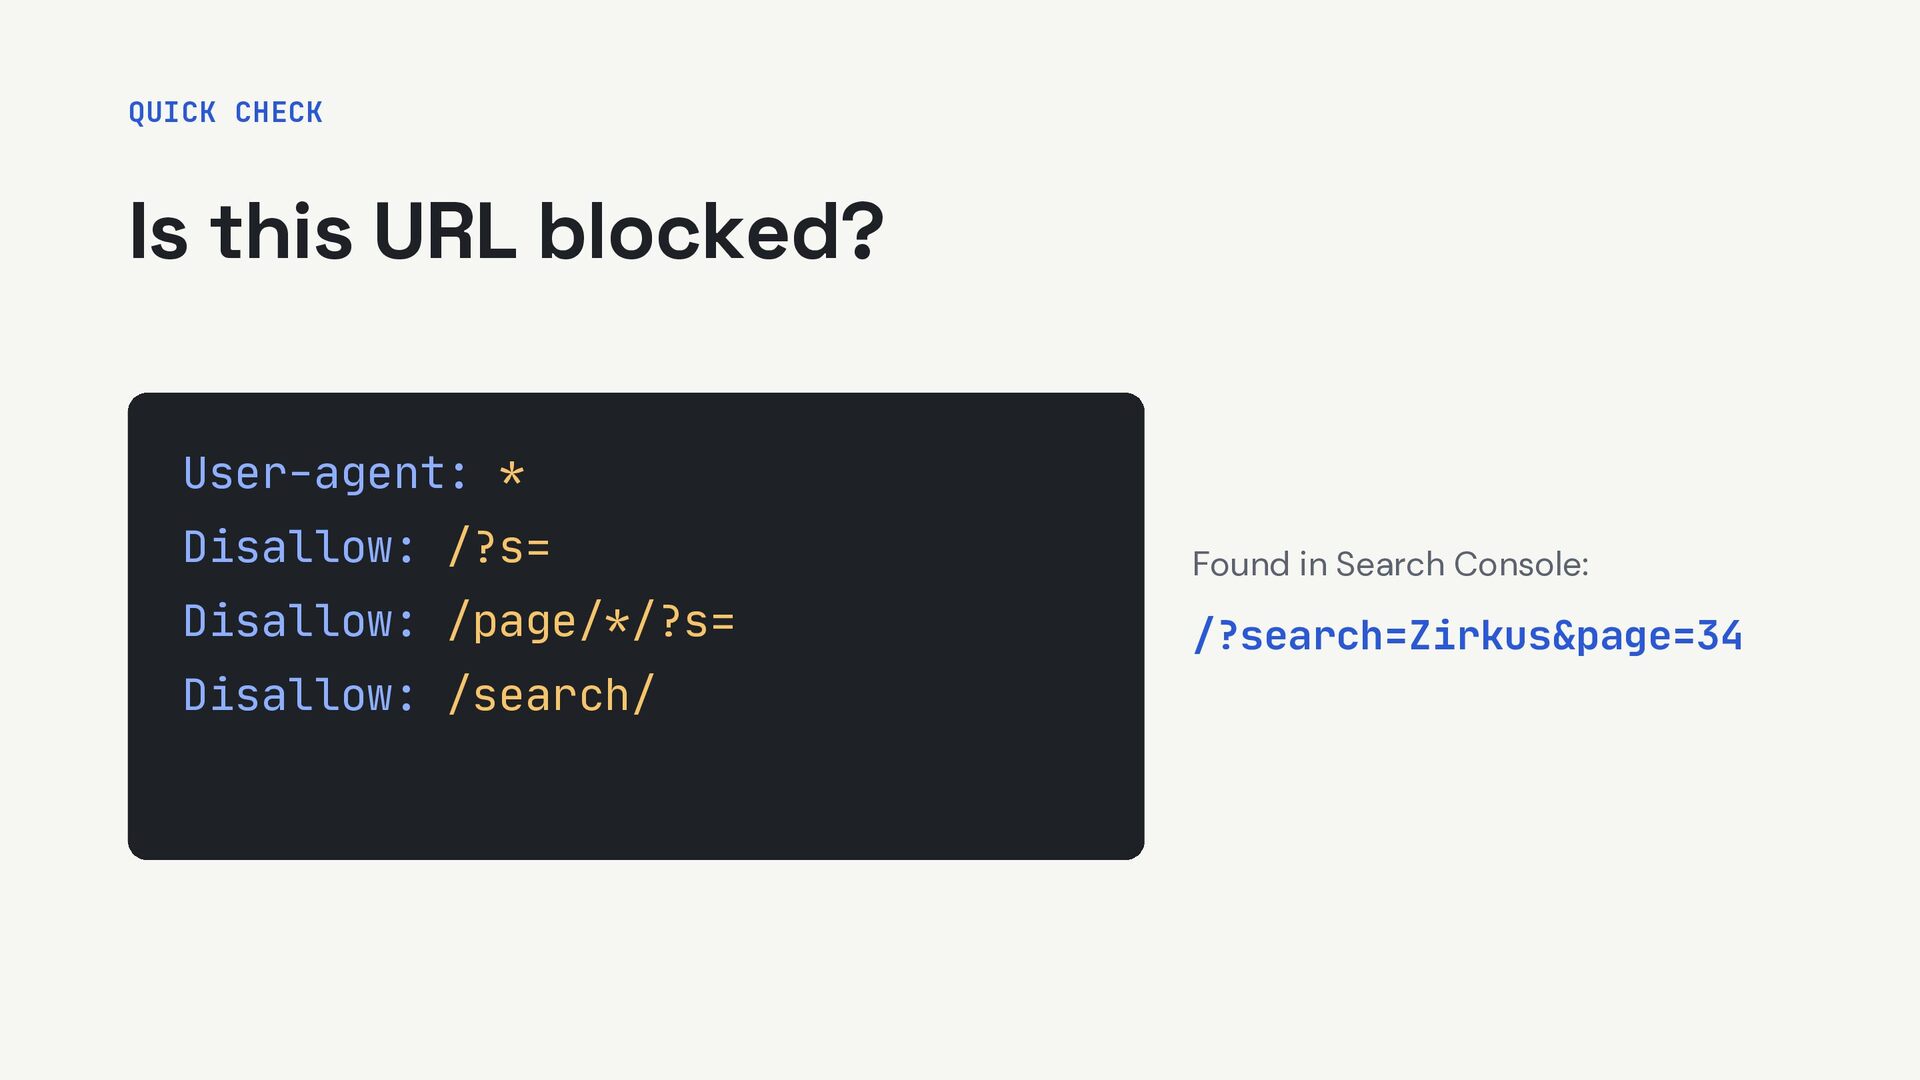
crawler the rule is for User-agent: * Disallow: /checkout/ Allow: /checkout/help/ Sitemap: https://site.com/sitemap.xml Disallow a path not to fetch Allow an exception to it Sitemap where your sitemap is
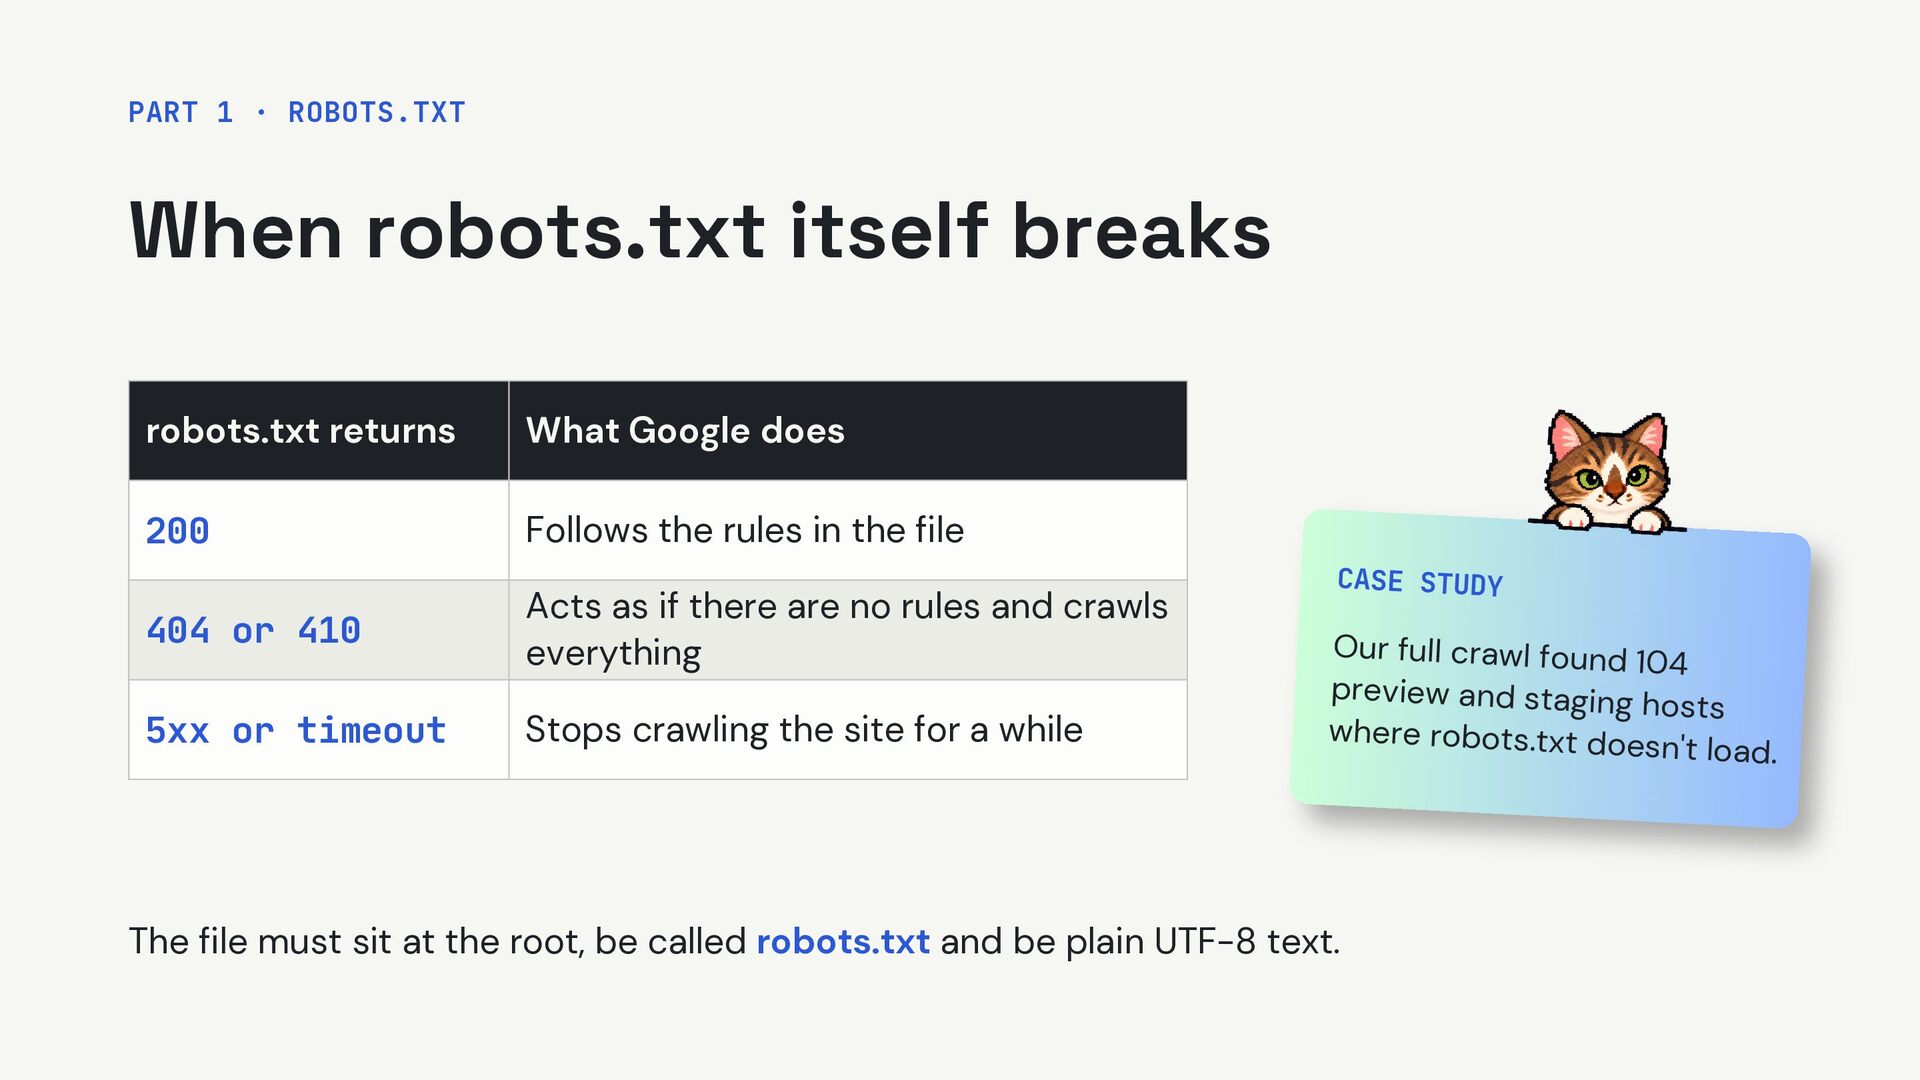
What Google does 200 Follows the rules in the file 404 or 410 Acts as if there are no rules and crawls everything 5xx or timeout Stops crawling the site for a while CASE STUDY Our full crawl found 10 4 preview and staging h osts where robots.txt doe sn't load. The file must sit at the root, be called robots.txt and be plain UTF-8 text.
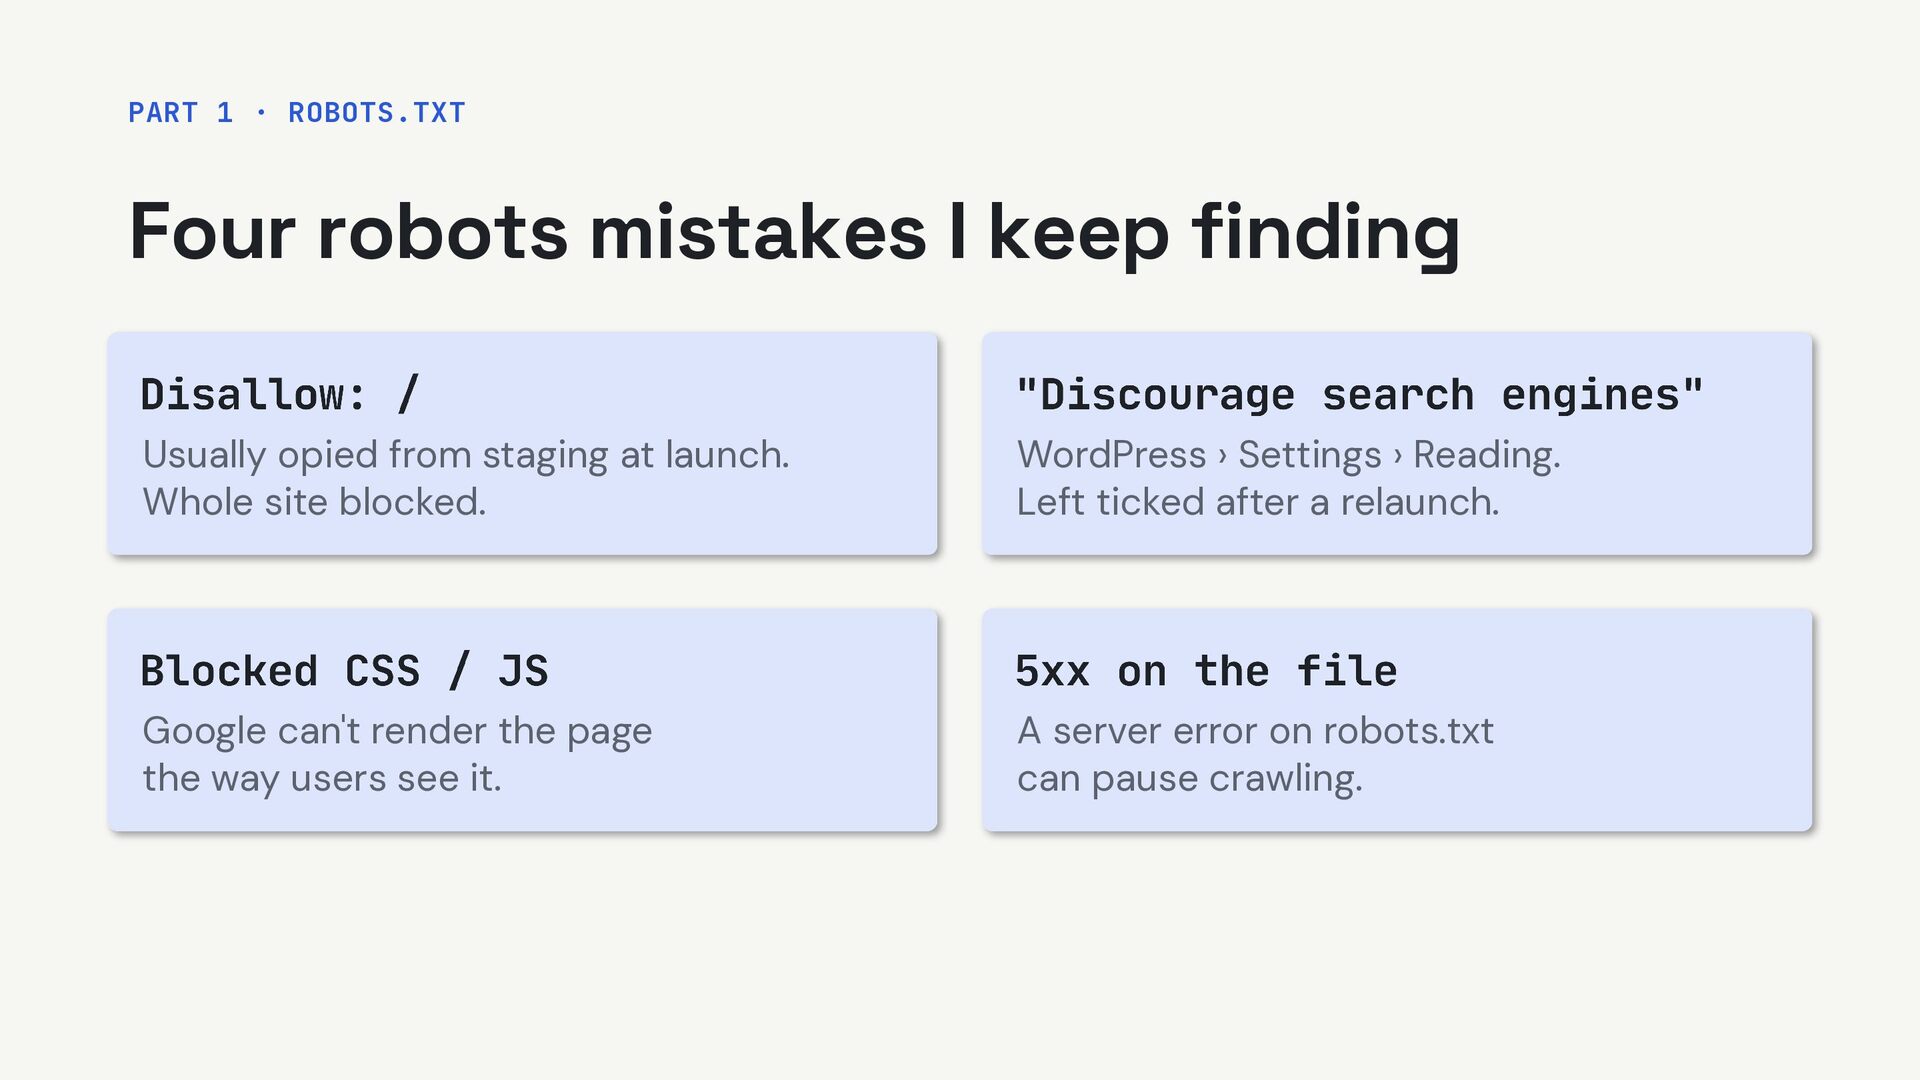
Usually opied from staging at launch. Whole site blocked. WordPress › Settings › Reading. Left ticked after a relaunch. Google can't render the page the way users see it. A server error on robots.txt can pause crawling.
Go to yourdomain.com/robots.txt 2. Find a rule that could affect your URL 3. Tell me what it does Works on any site, no login needed. Use examples: lego.com, techcrunch.com
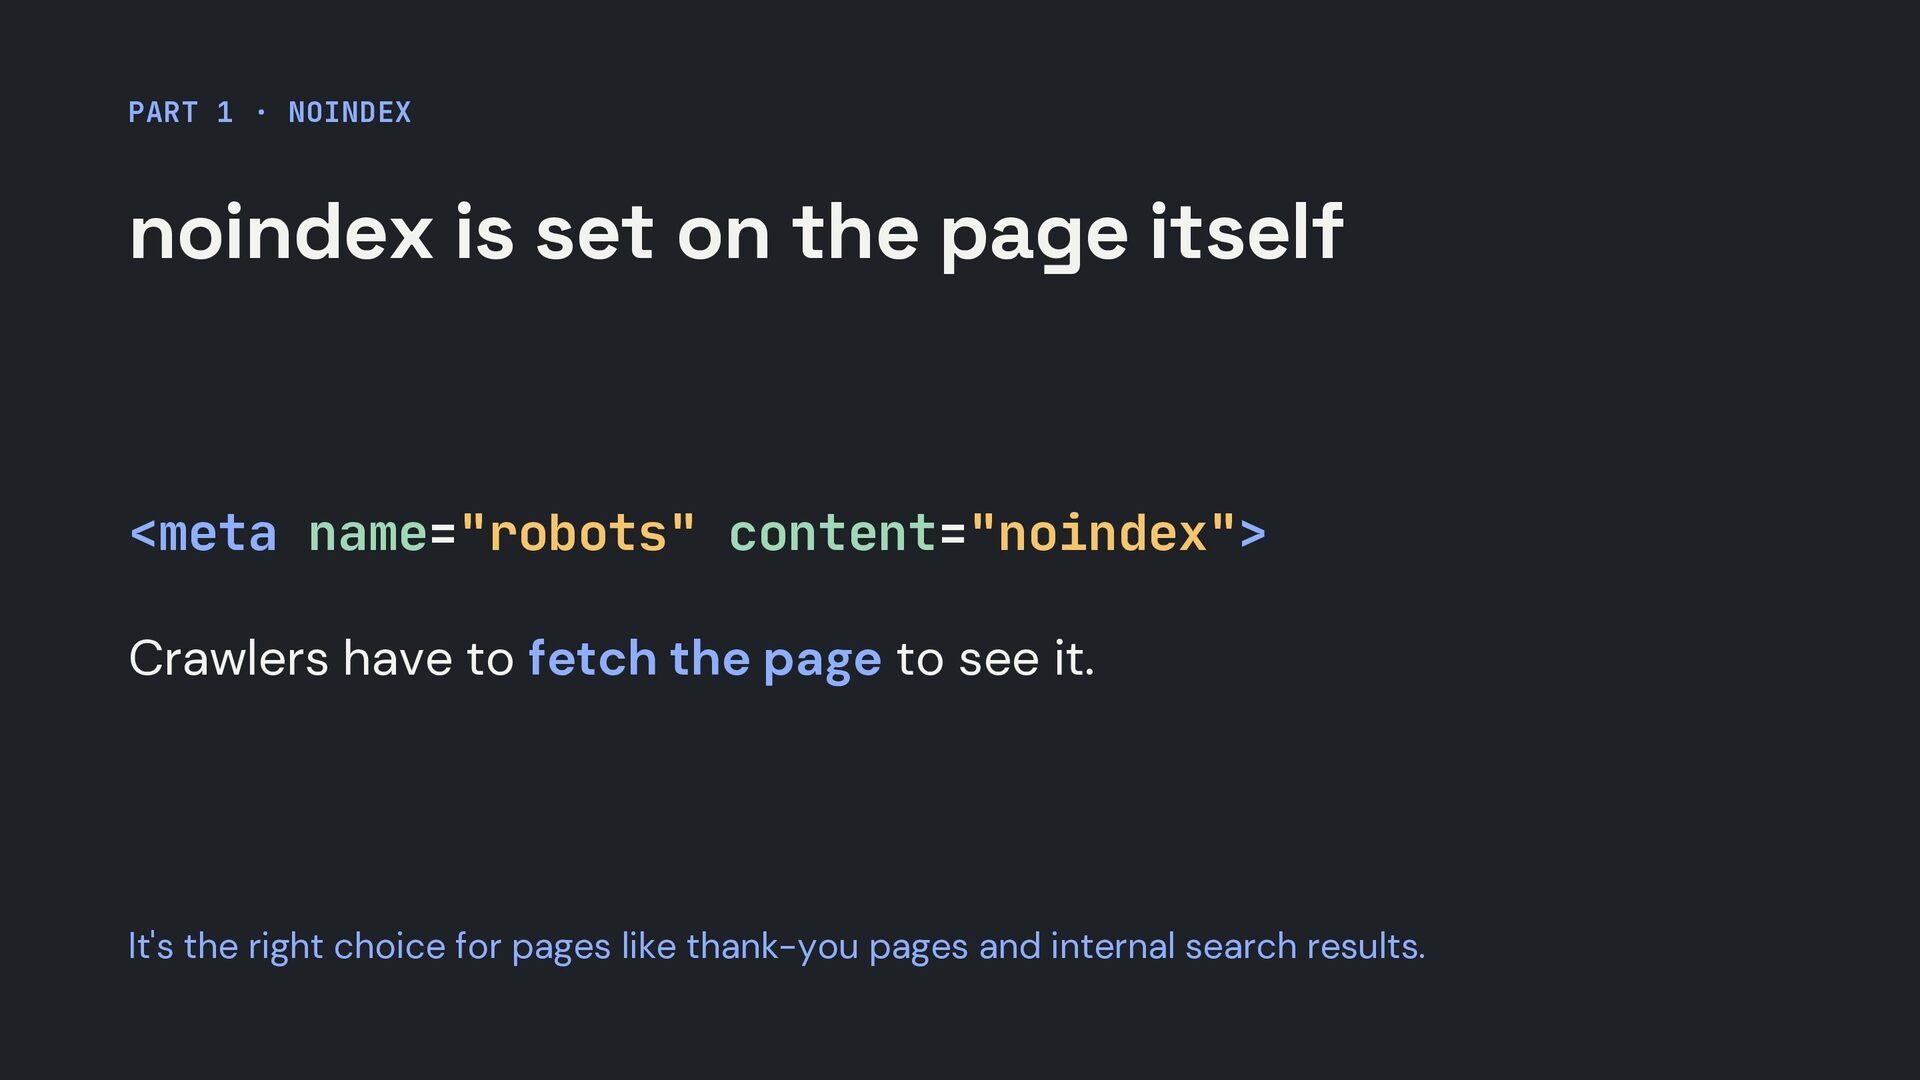
itself <meta name="robots" content="noindex"> Crawlers have to fetch the page to see it. It's the right choice for pages like thank-you pages and internal search results.
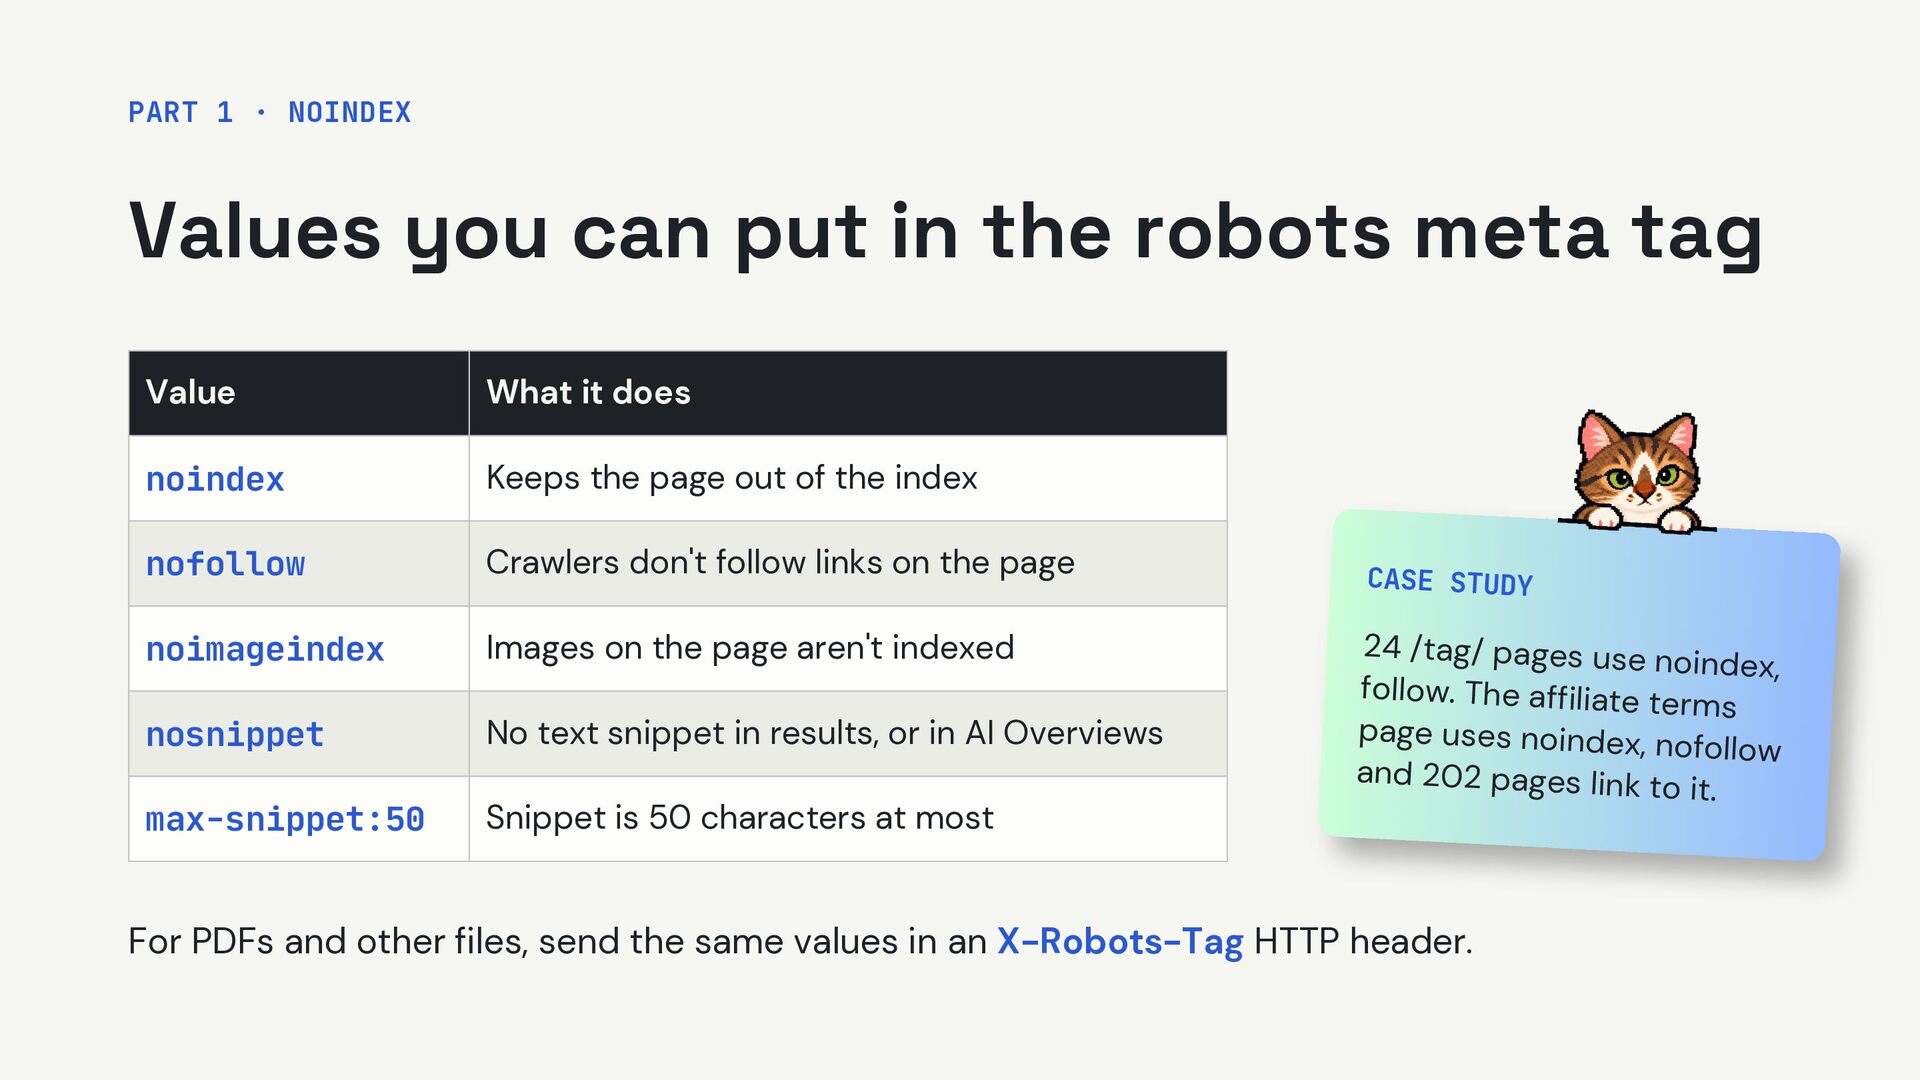
robots meta tag Value What it does noindex Keeps the page out of the index nofollow Crawlers don't follow links on the page noimageindex Images on the page aren't indexed nosnippet No text snippet in results, or in AI Overviews max-snippet:50 Snippet is 50 characters at most CASE STUDY 24 /tag/ pages use no index, follow. The affiliate te rms page uses noindex, n ofollow and 202 pages link to it. For PDFs and other files, send the same values in an X-Robots-Tag HTTP header.
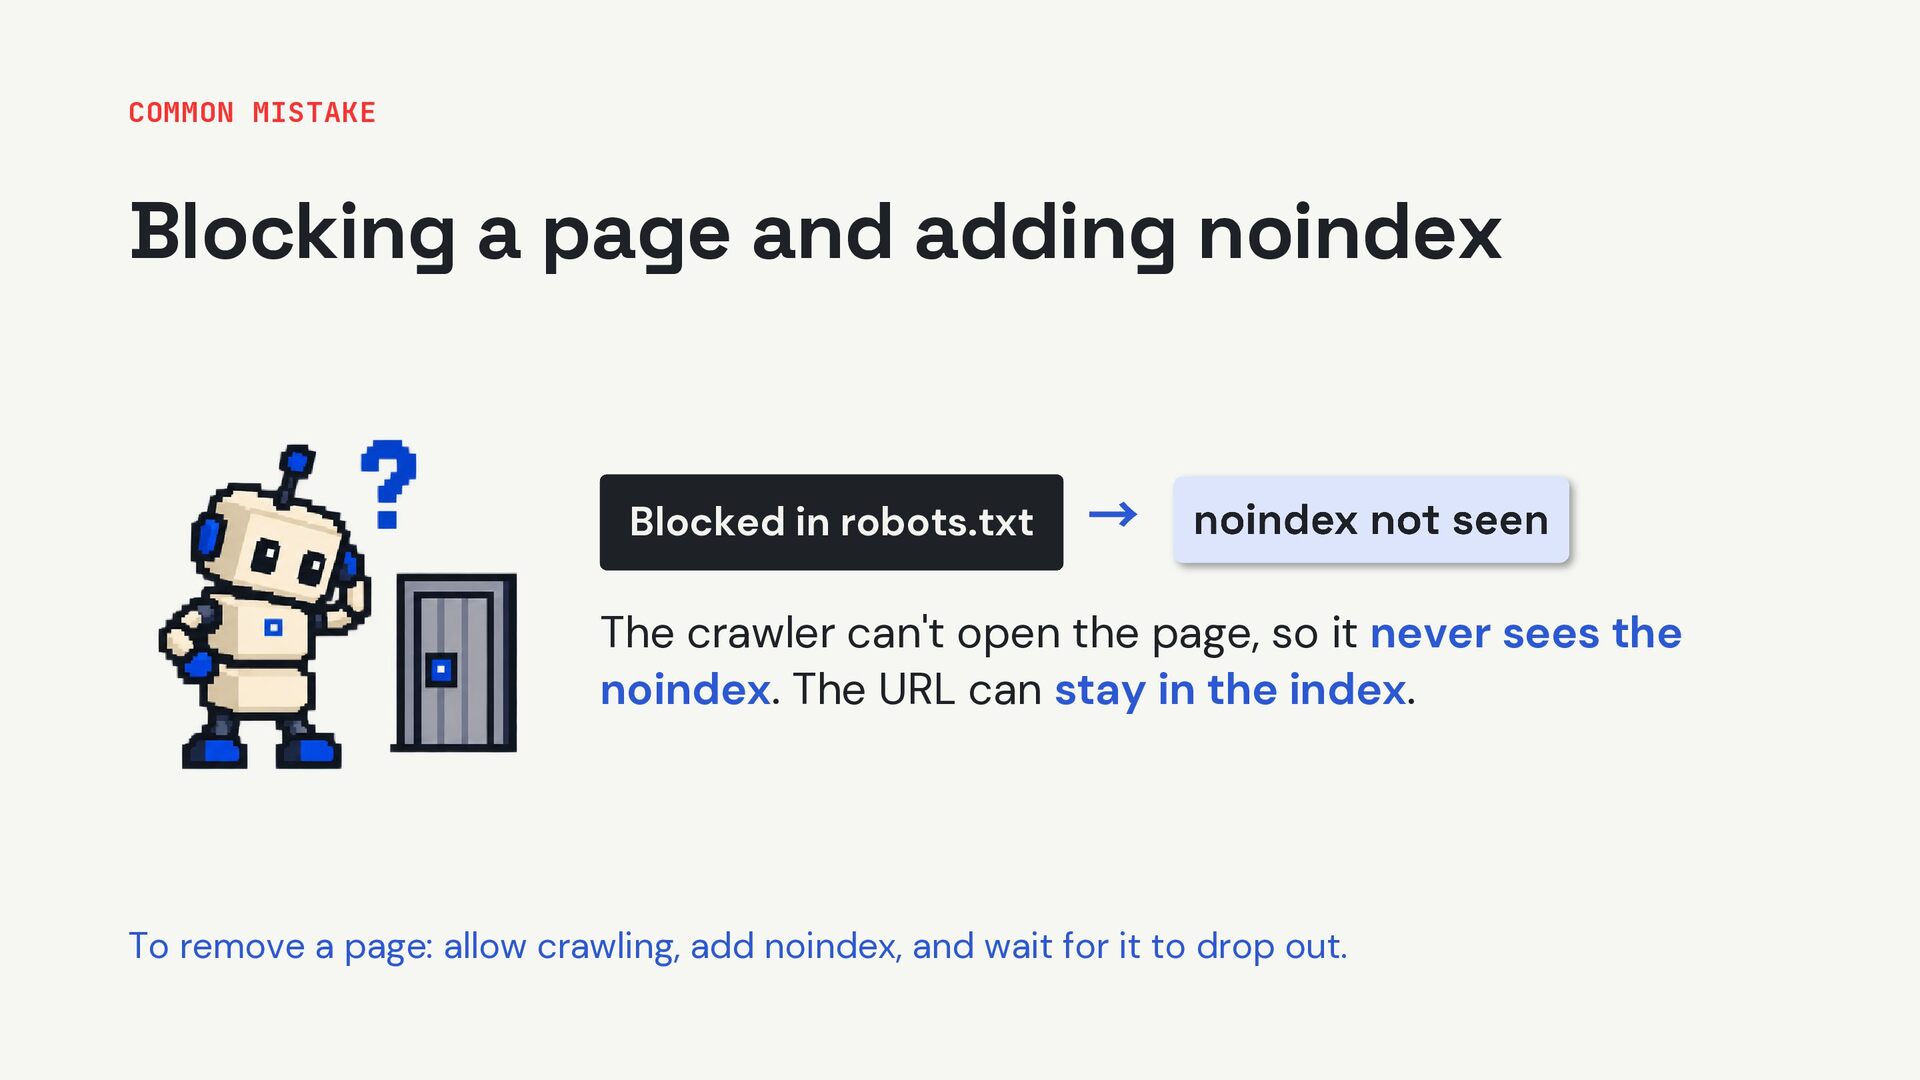
robots.txt → The crawler can't open the page, so it never sees the noindex. The URL can stay in the index. To remove a page: allow crawling, add noindex, and wait for it to drop out.
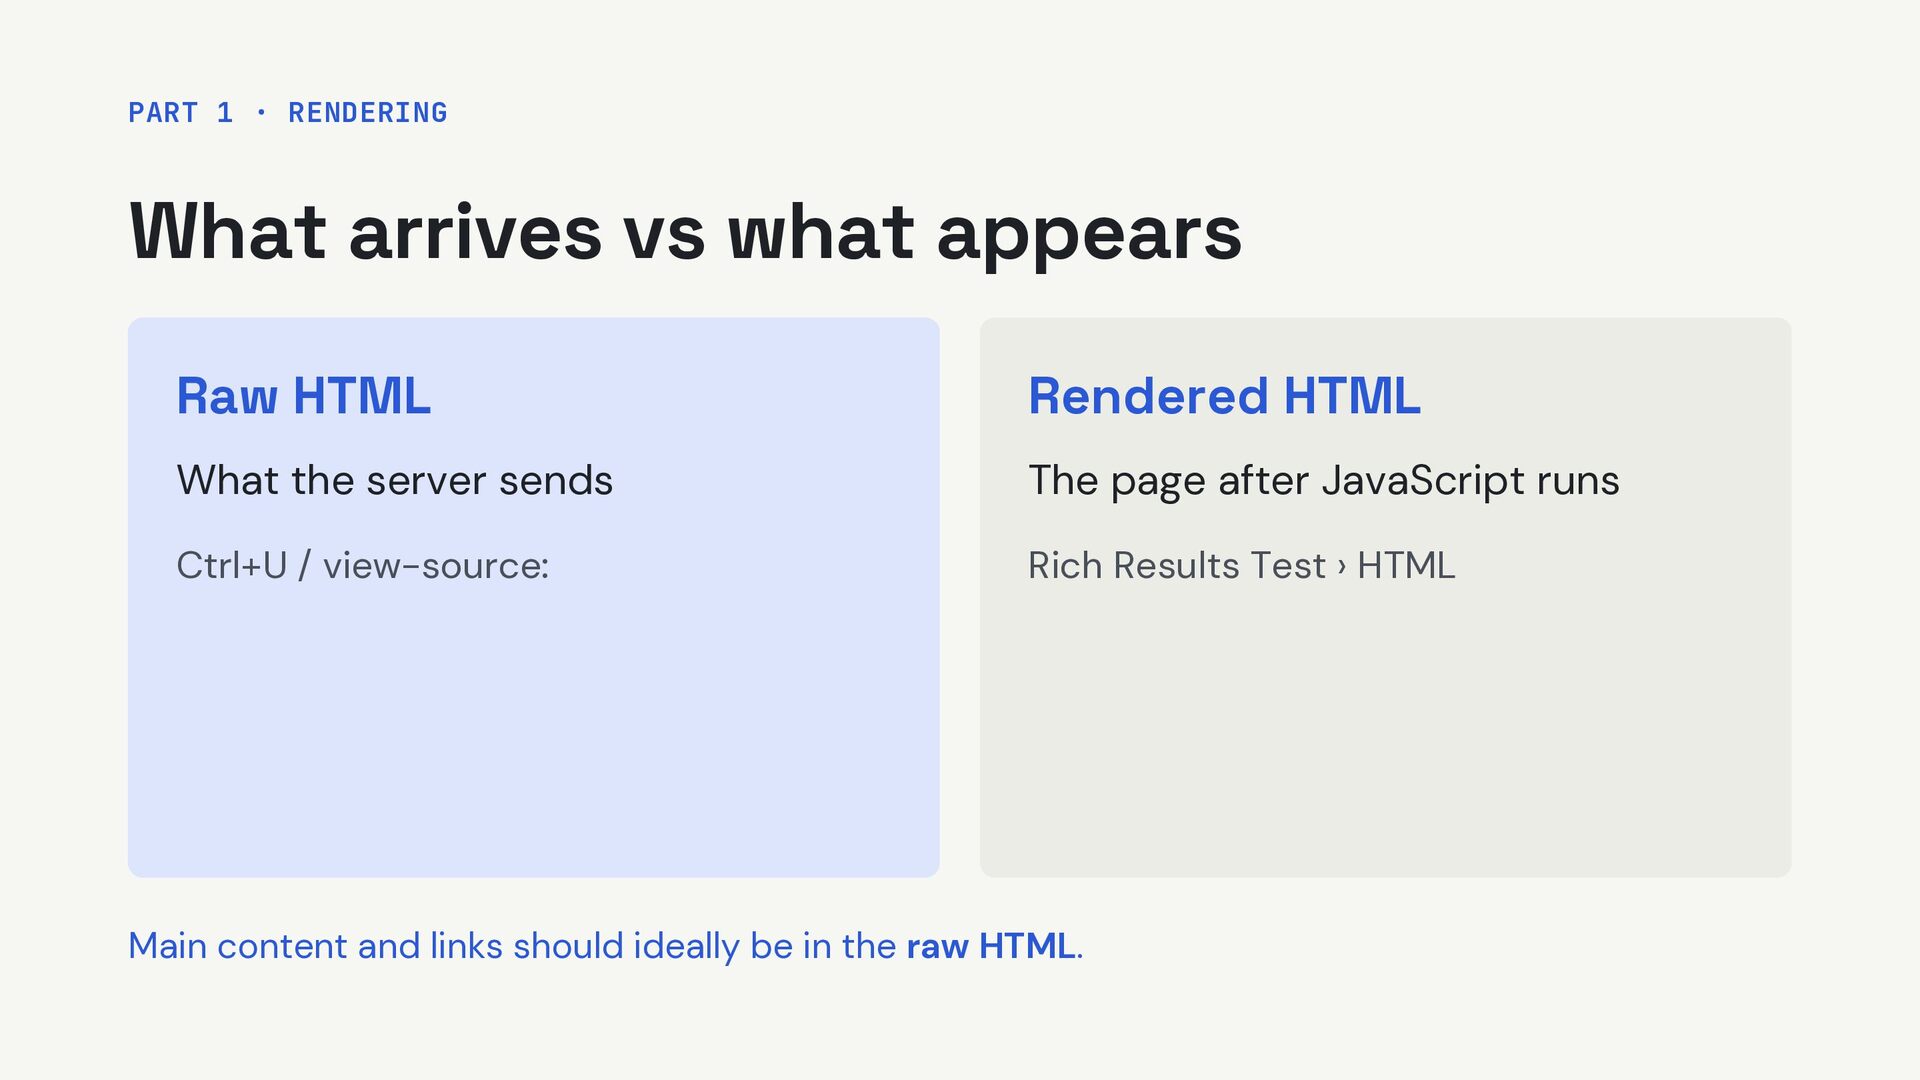
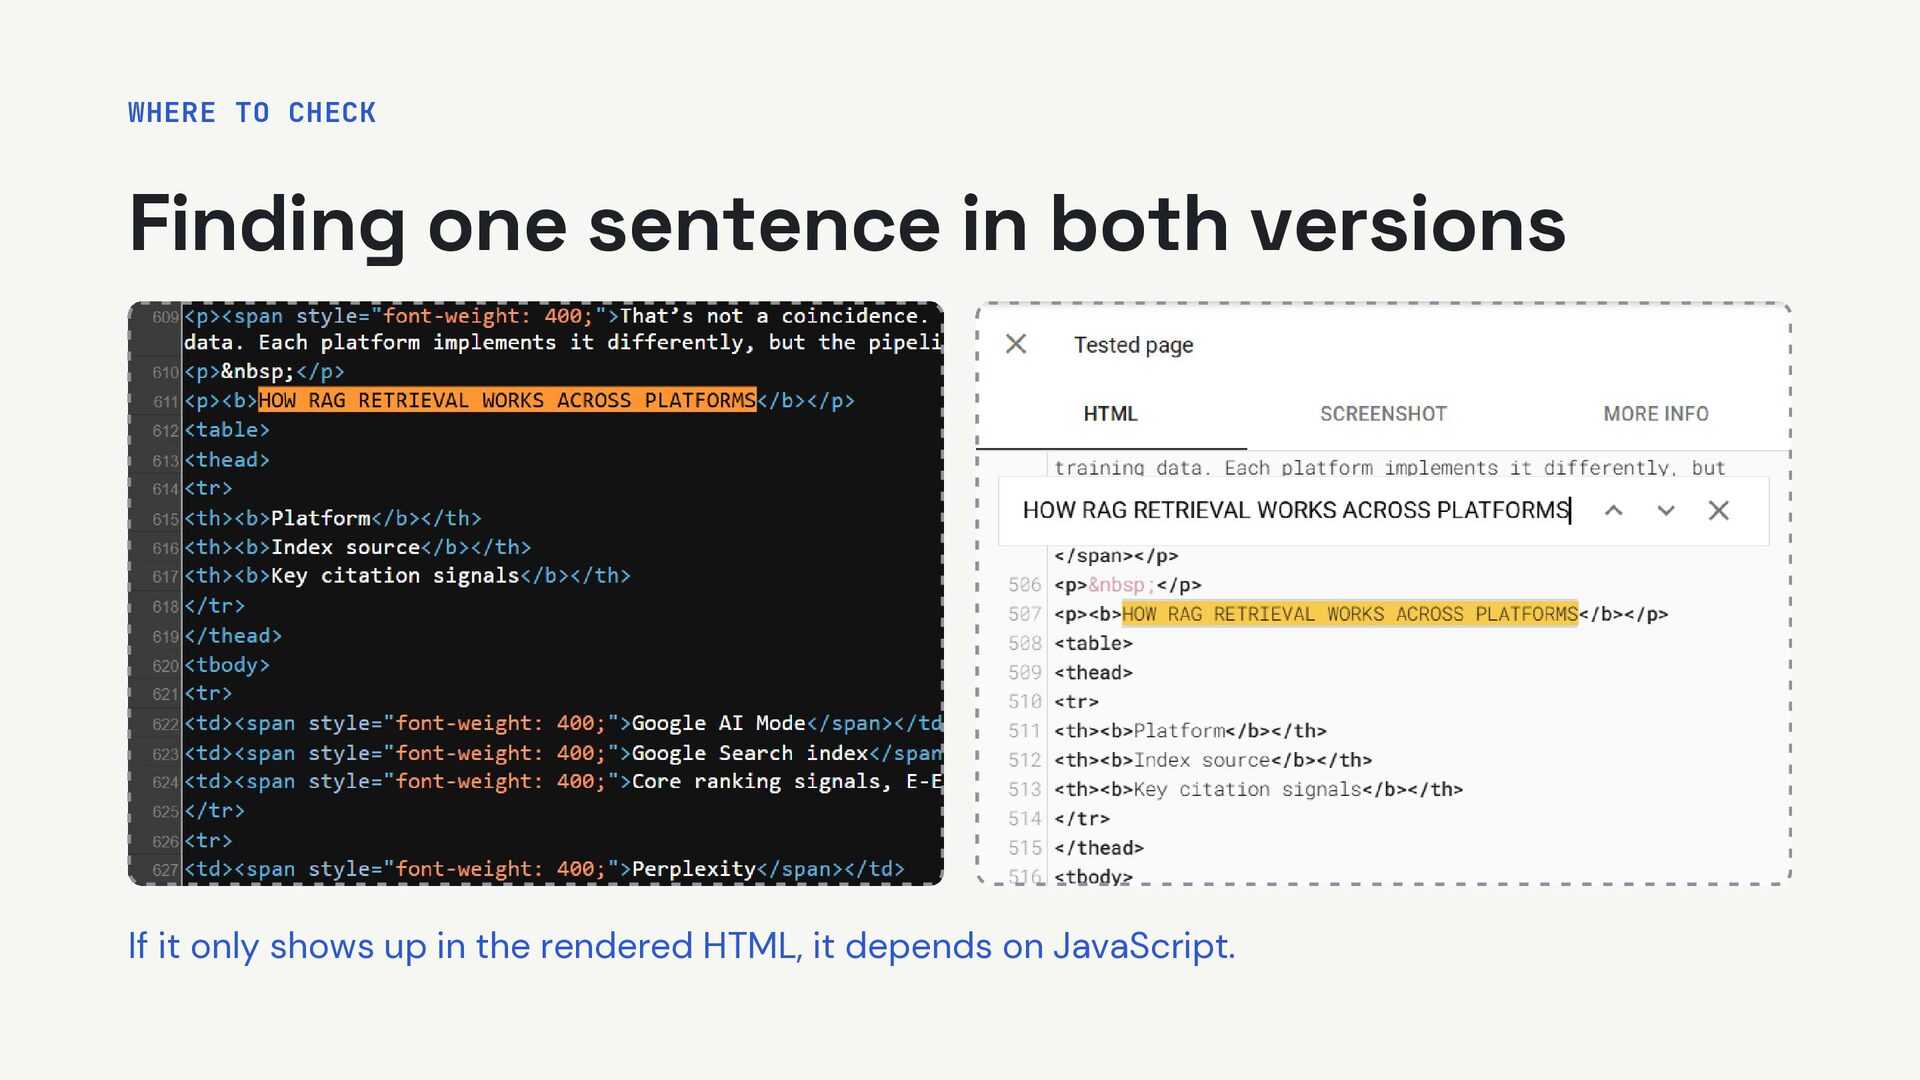
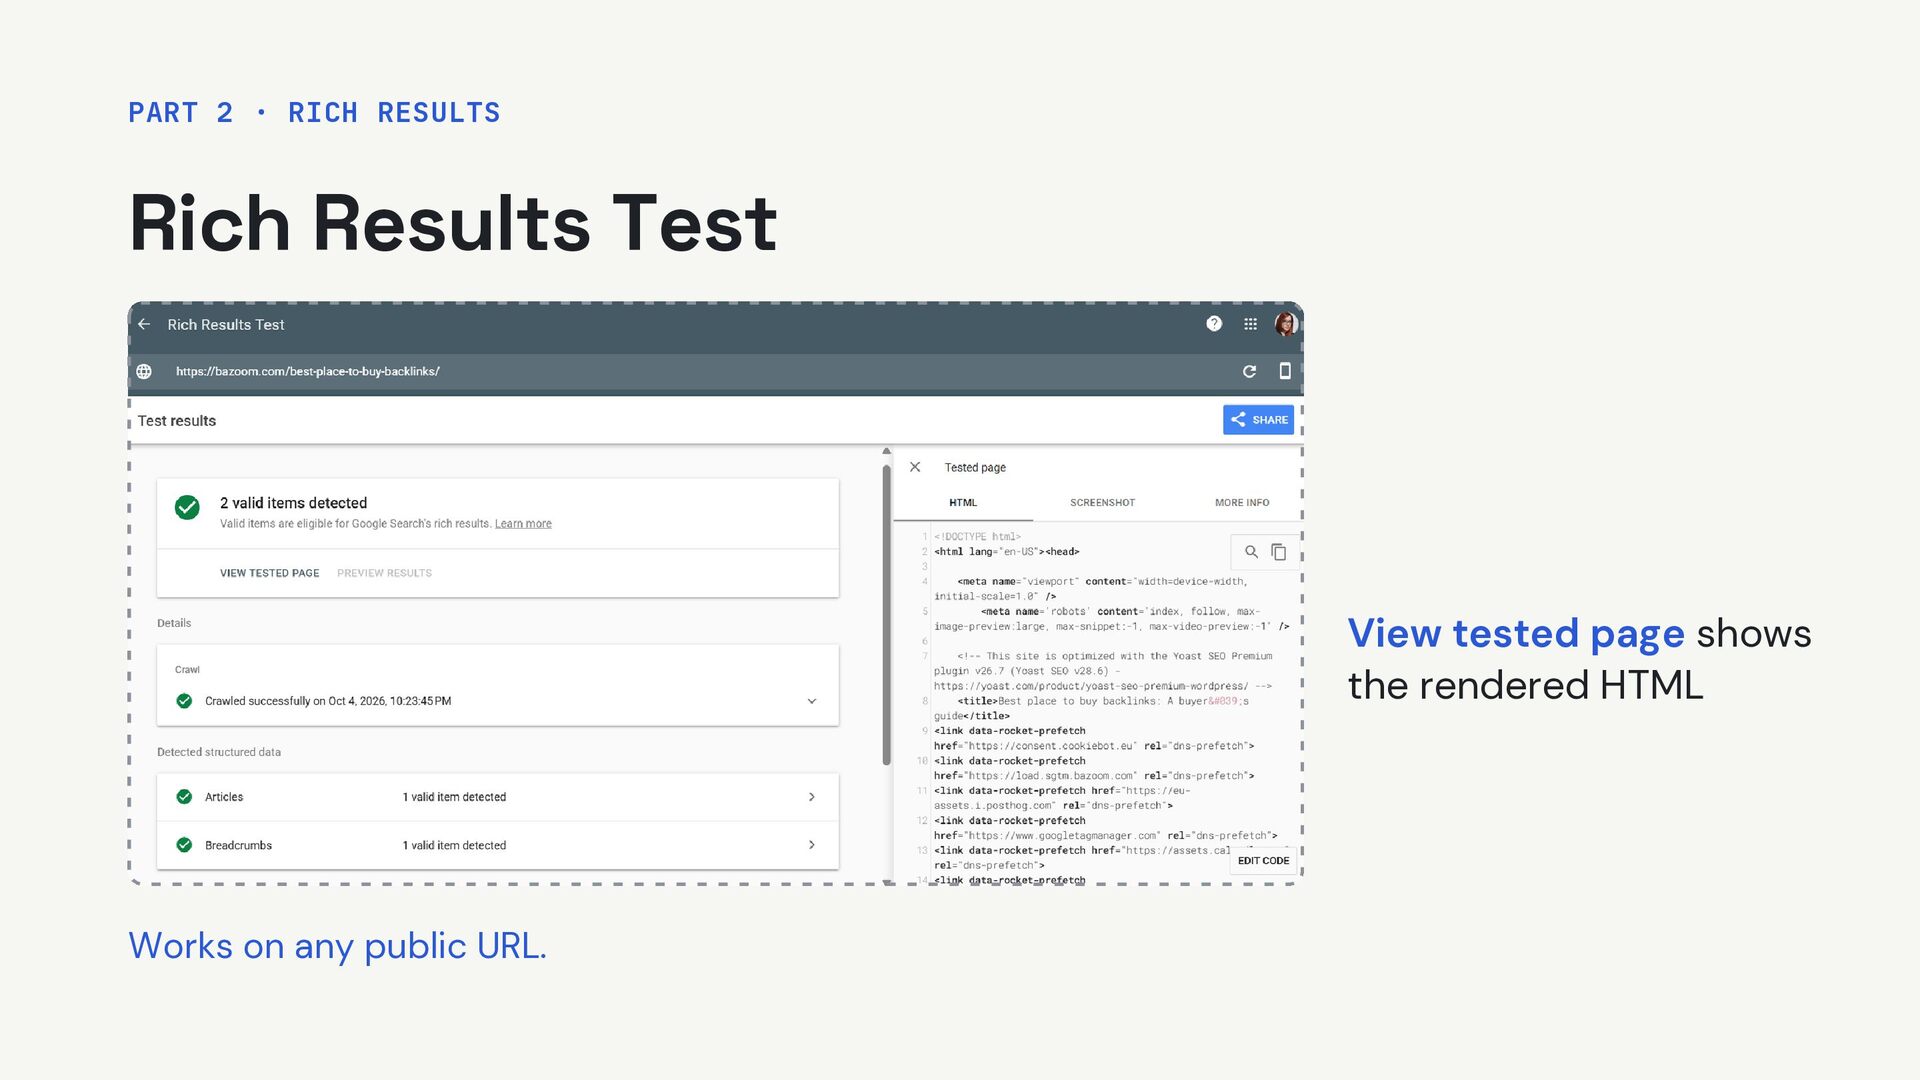
HTML Rendered HTML What the server sends The page after JavaScript runs Ctrl+U / view-source: Rich Results Test › HTML Main content and links should ideally be in the raw HTML.
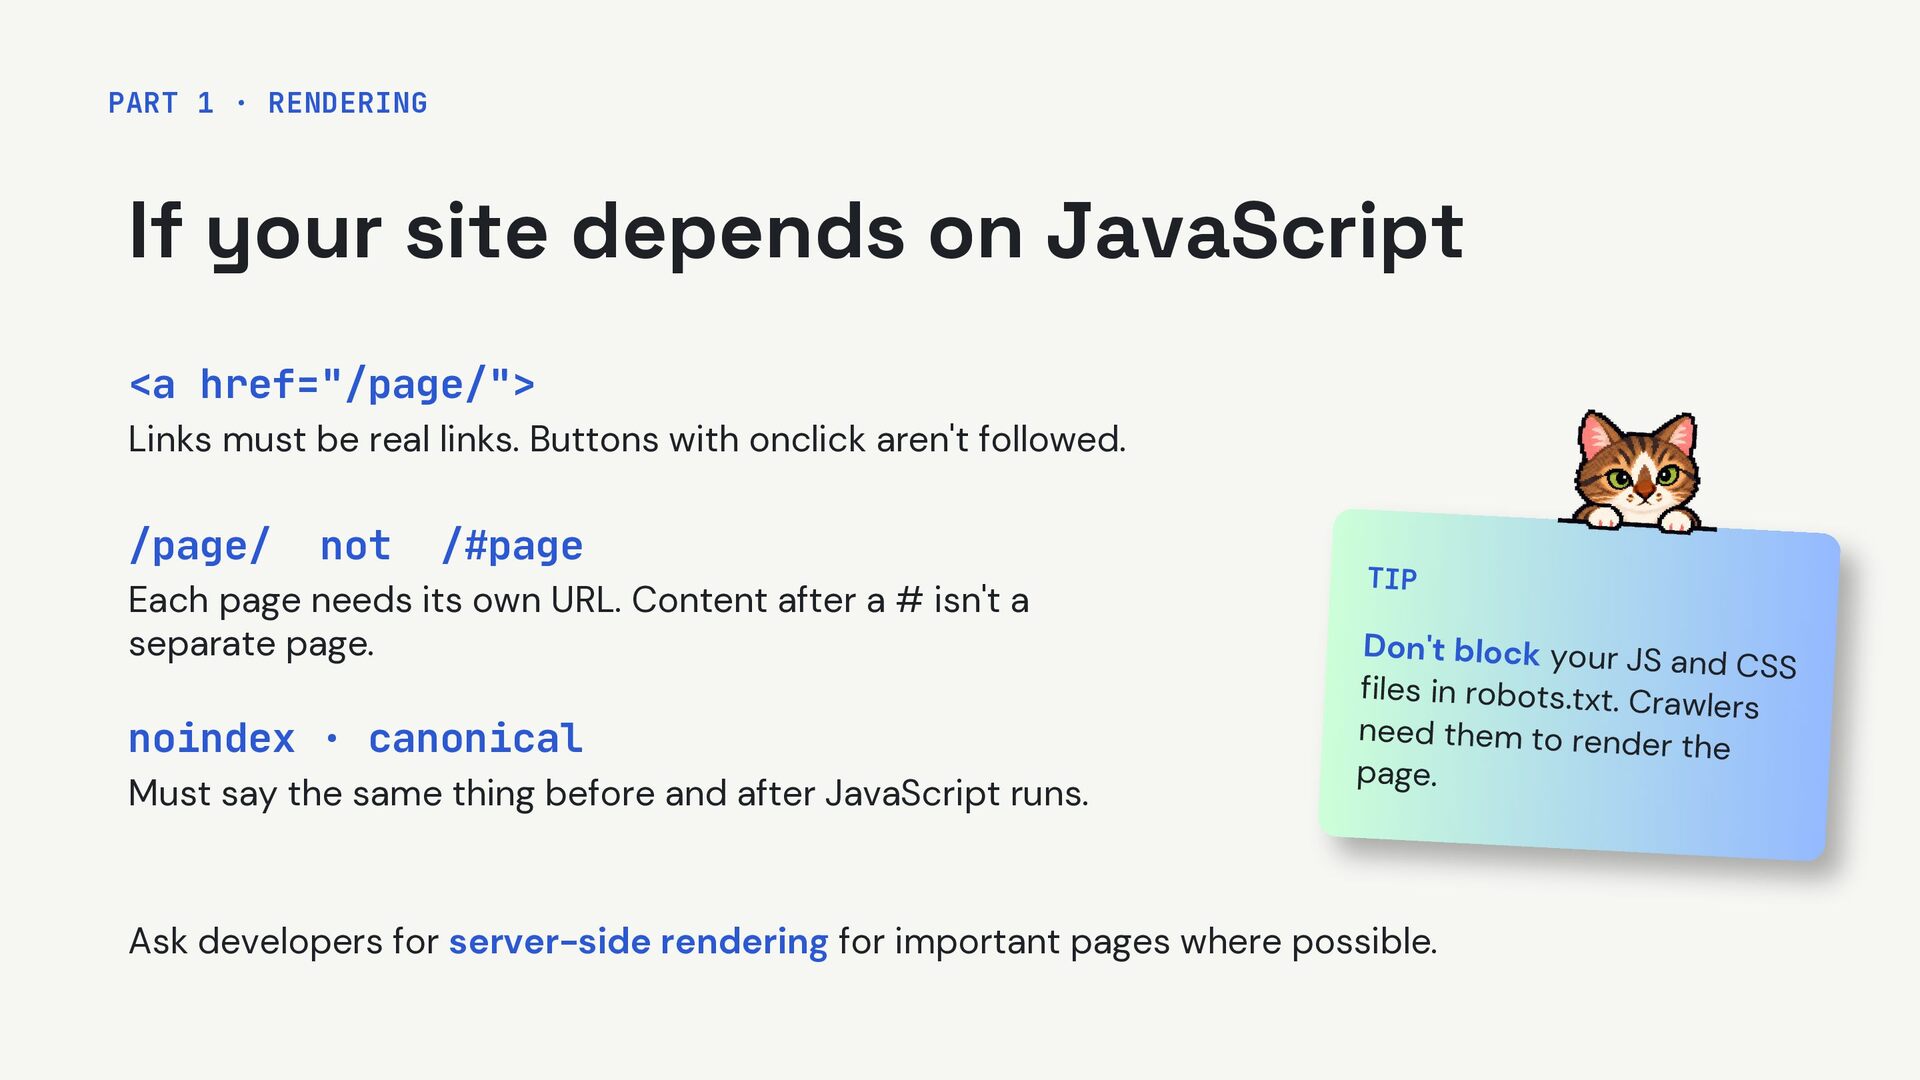
<a href="/page/"> Links must be real links. Buttons with onclick aren't followed. /page/ not /#page Each page needs its own URL. Content after a # isn't a separate page. noindex · canonical Must say the same thing before and after JavaScript runs. TIP Don't block your JS a nd CSS files in robots.txt. Cra wlers need them to render the page. Ask developers for server-side rendering for important pages where possible.
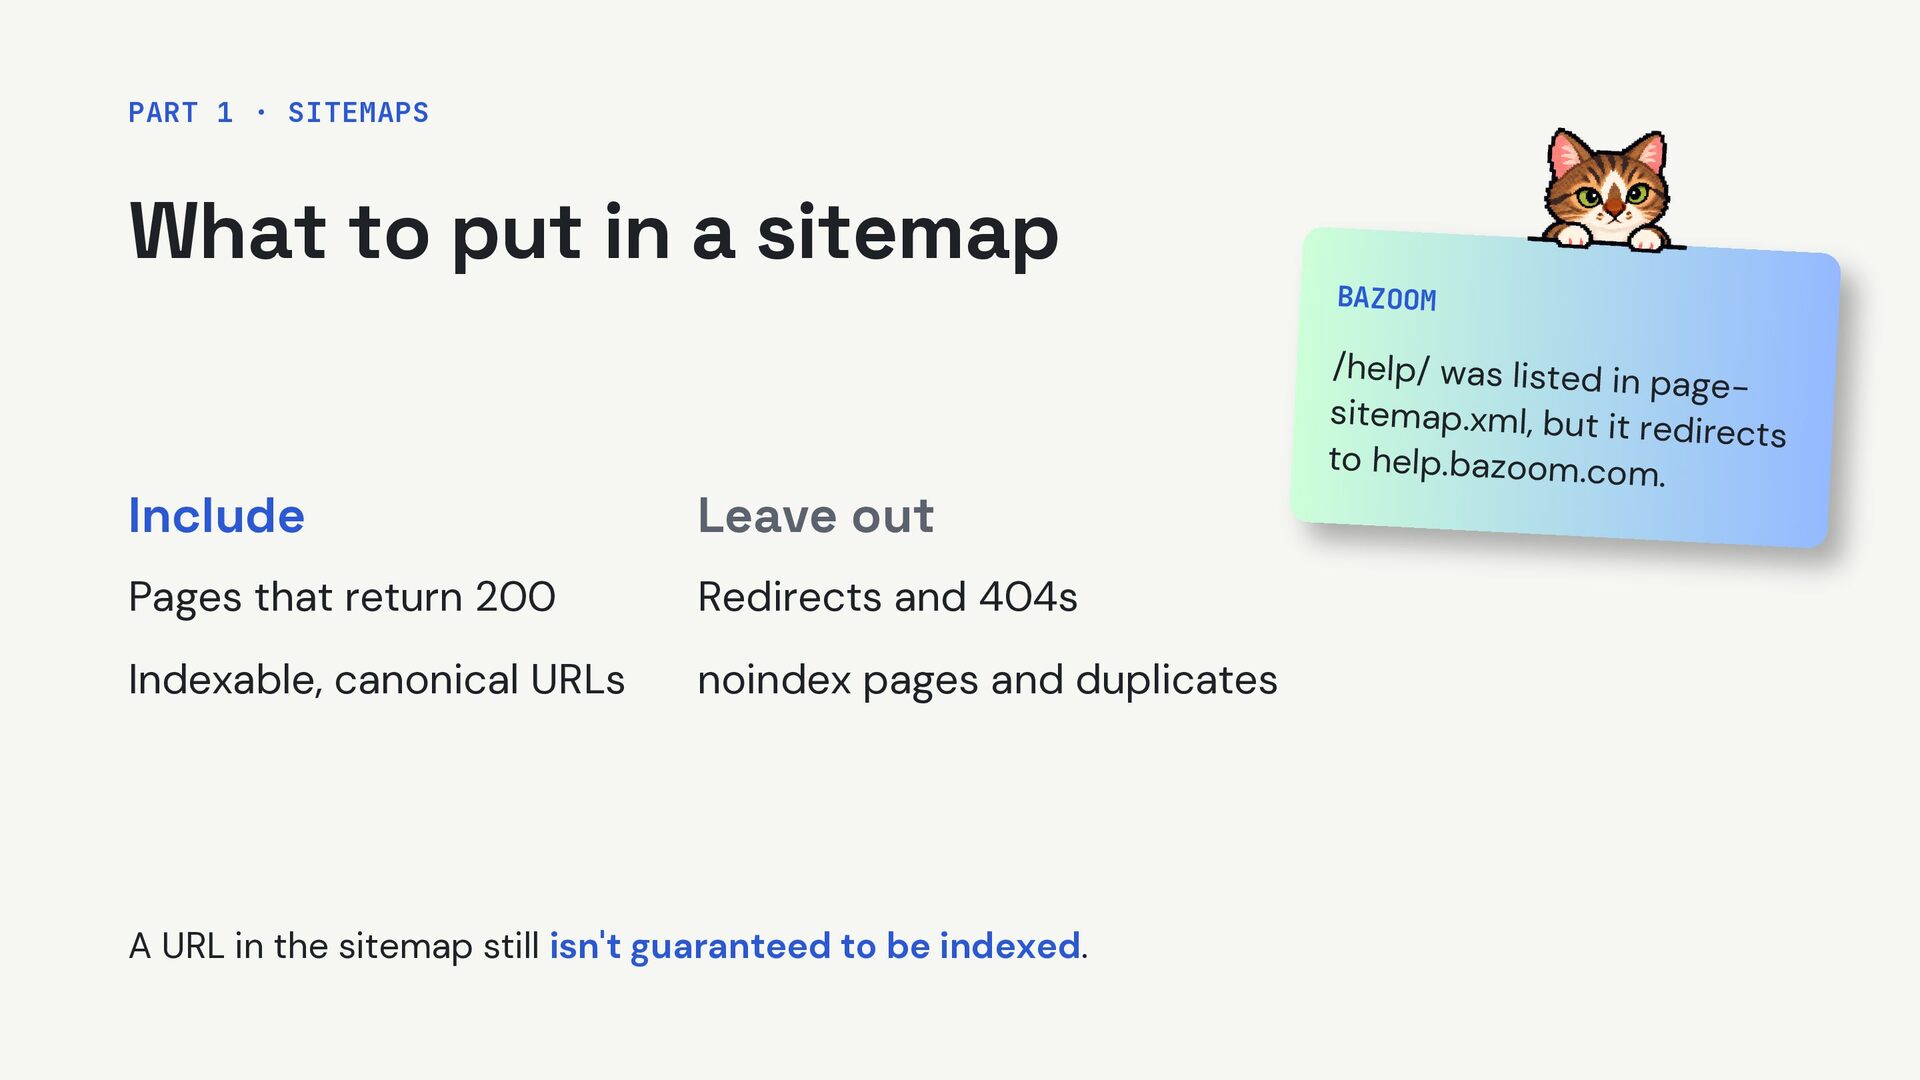
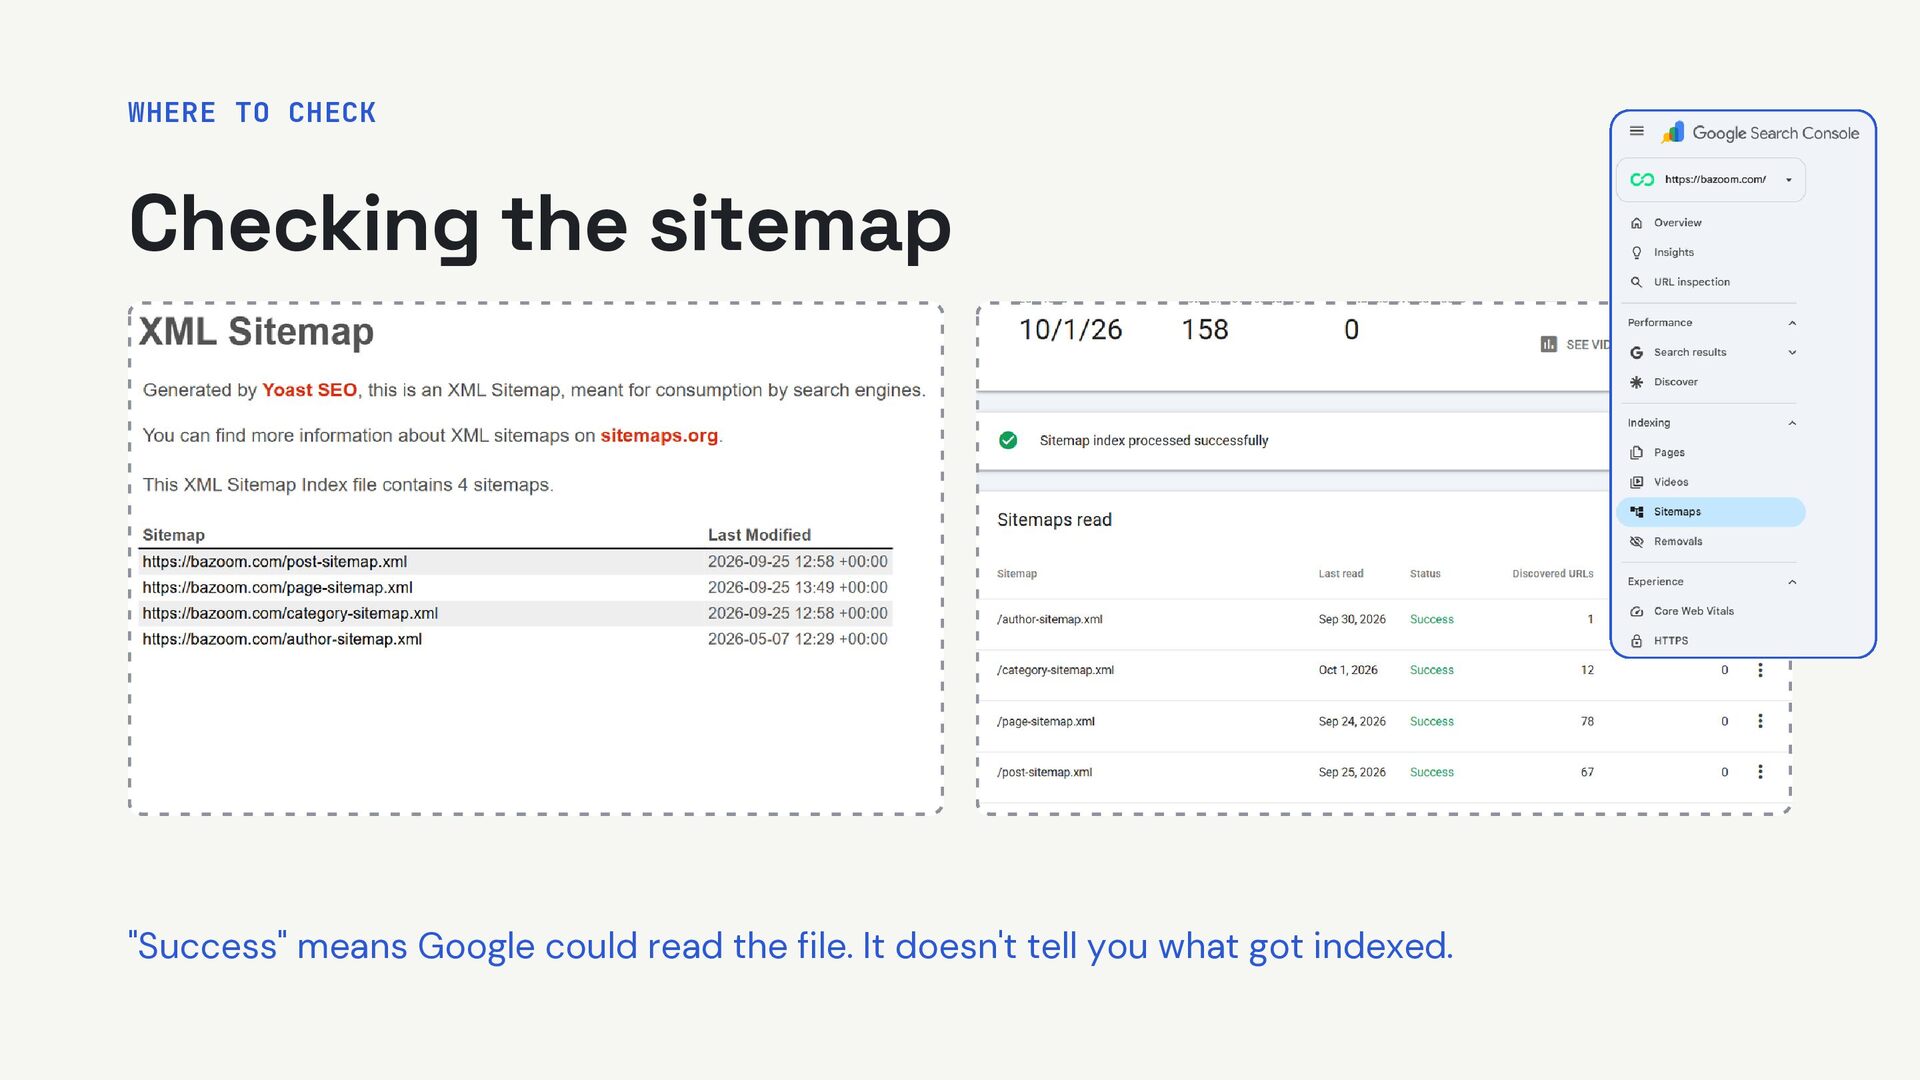
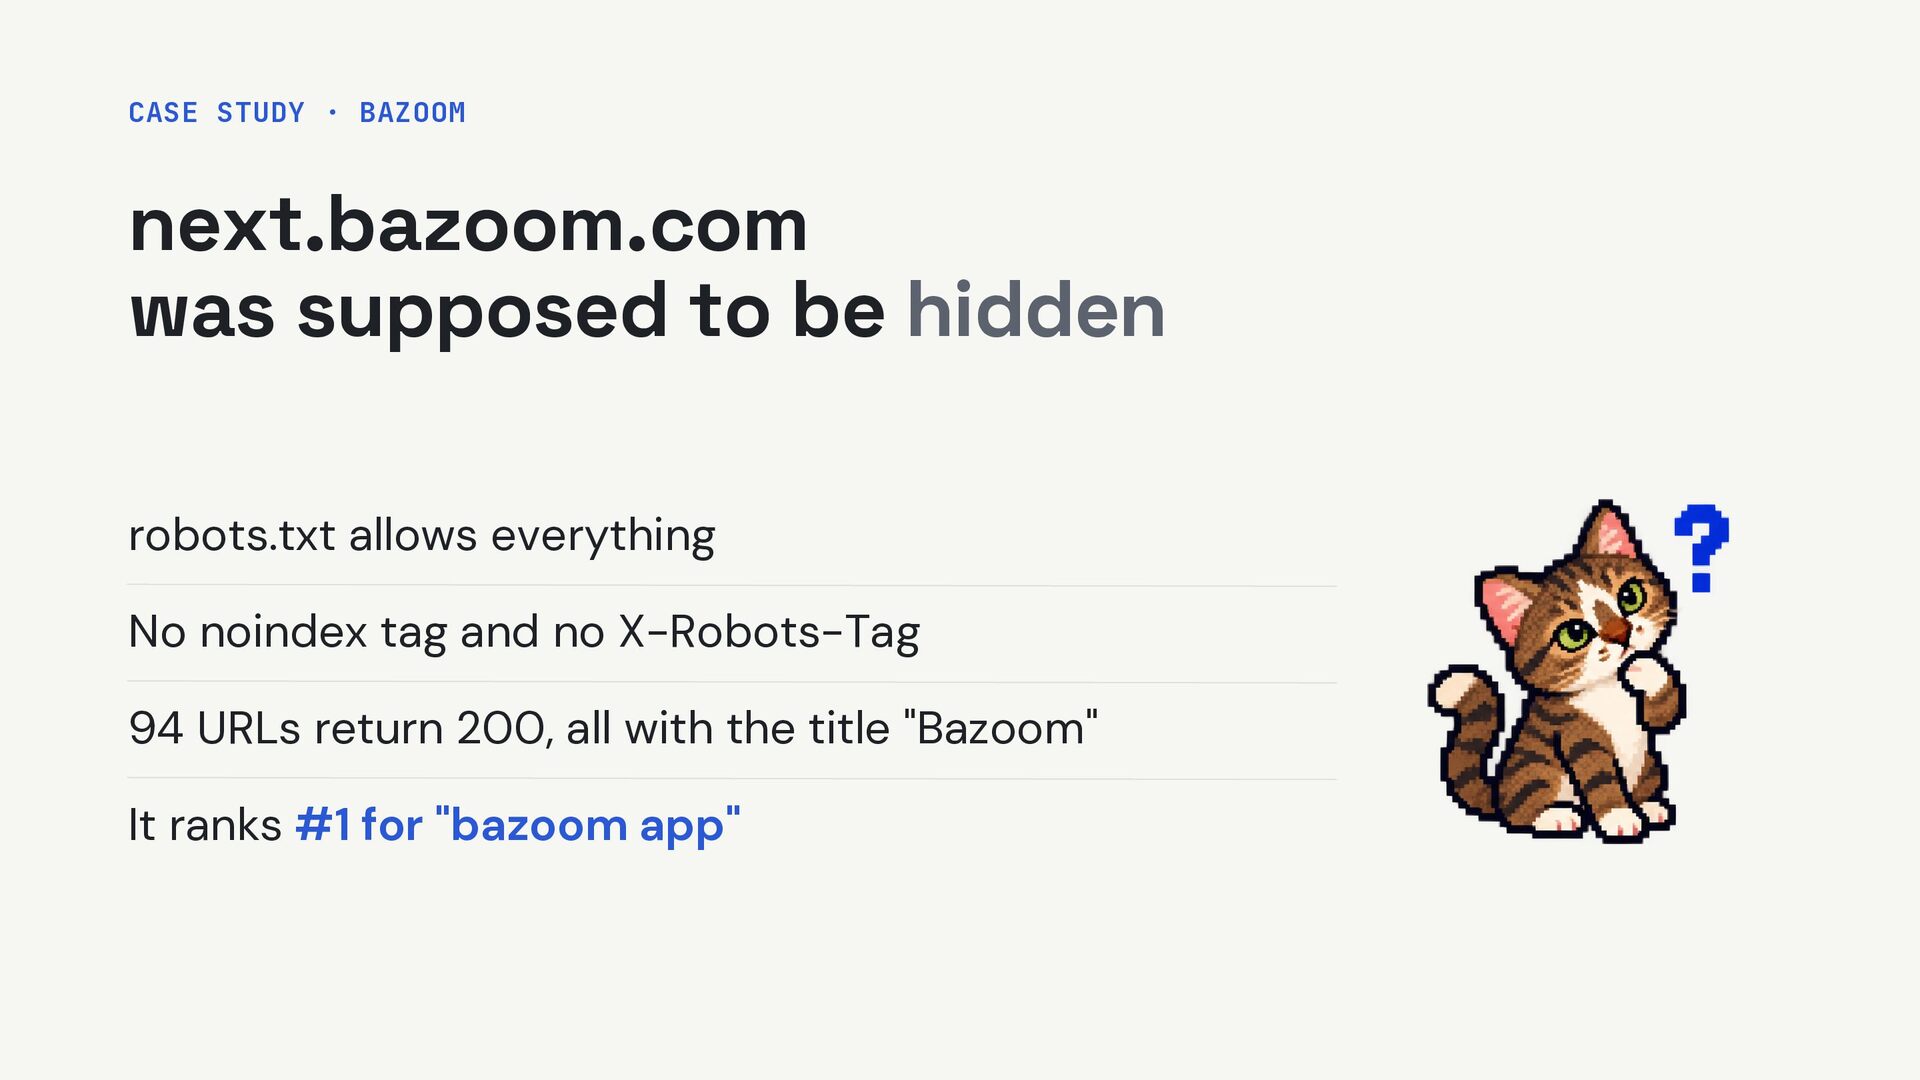
Include Leave out Pages that return 200 Redirects and 404s Indexable, canonical URLs noindex pages and duplicates A URL in the sitemap still isn't guaranteed to be indexed. BAZOOM /help/ was listed in p agesitemap.xml, but it re directs to help.bazoom.com.
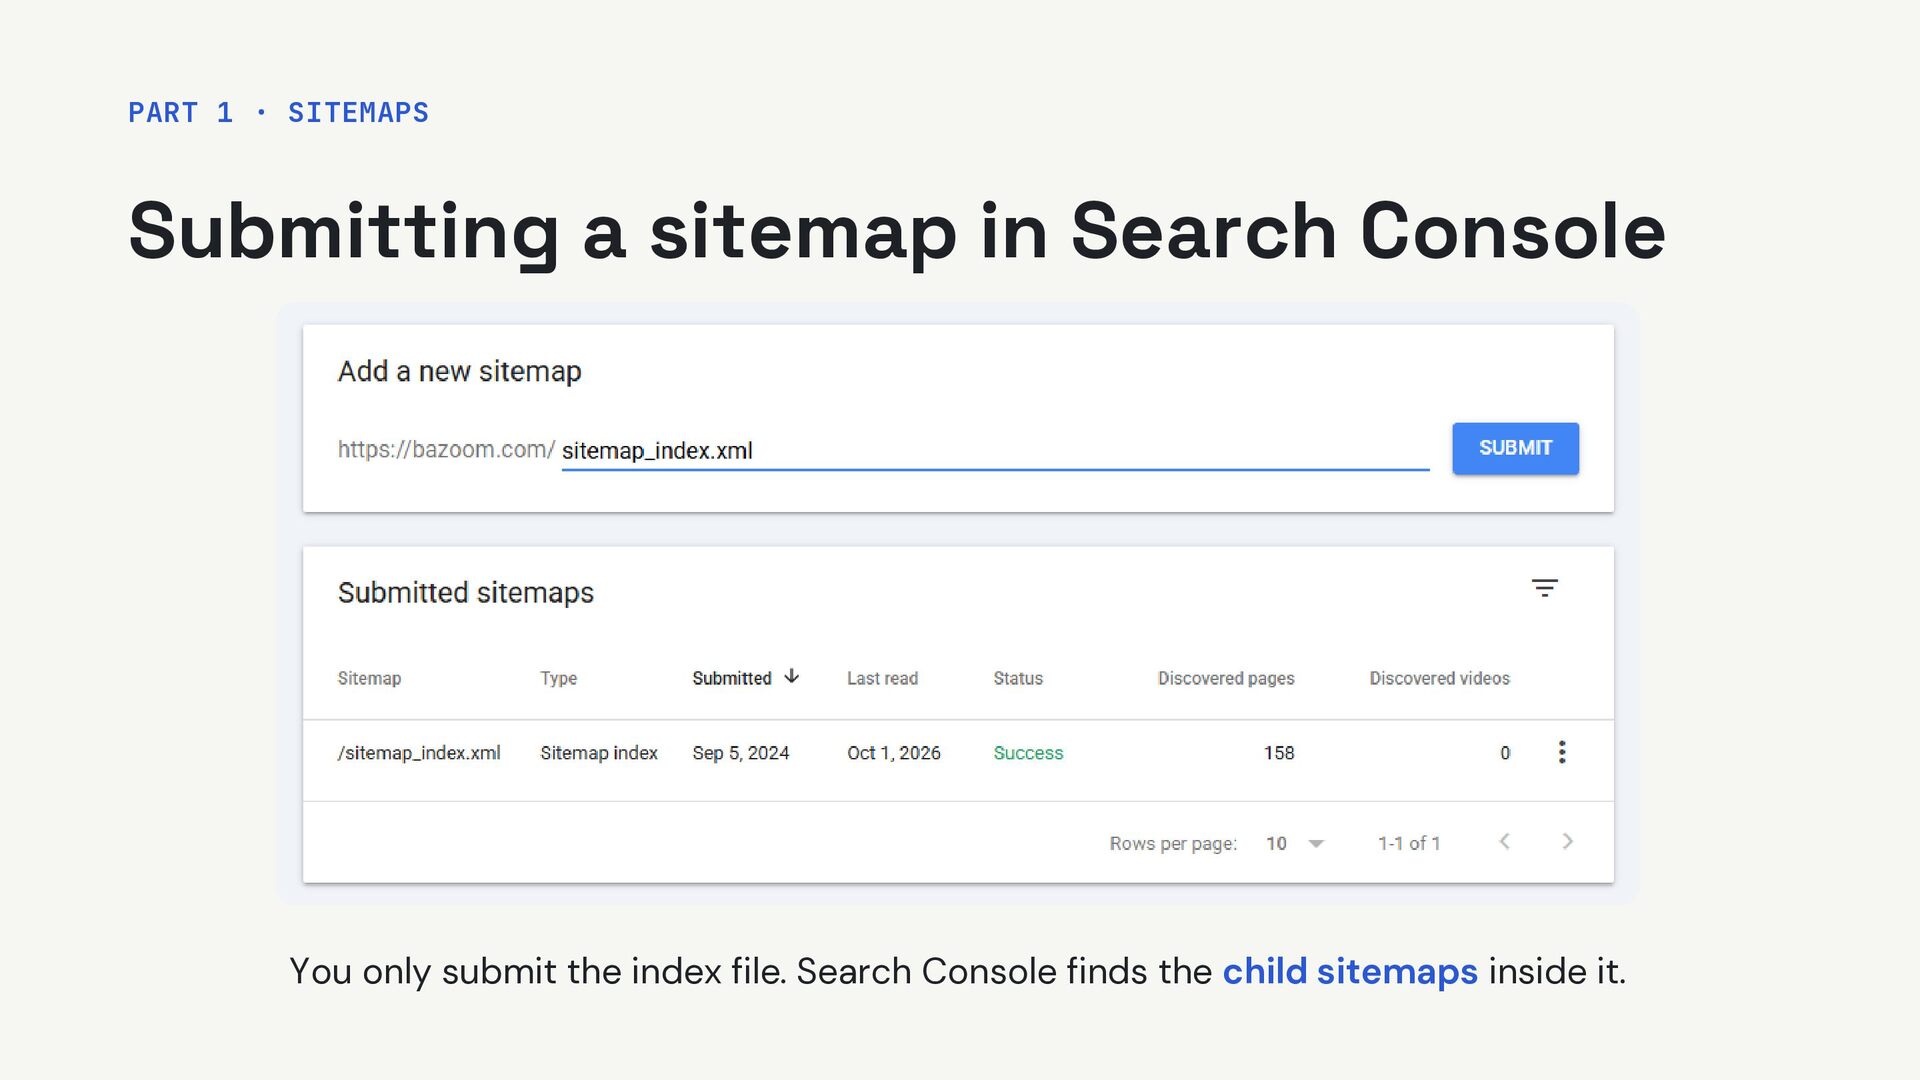
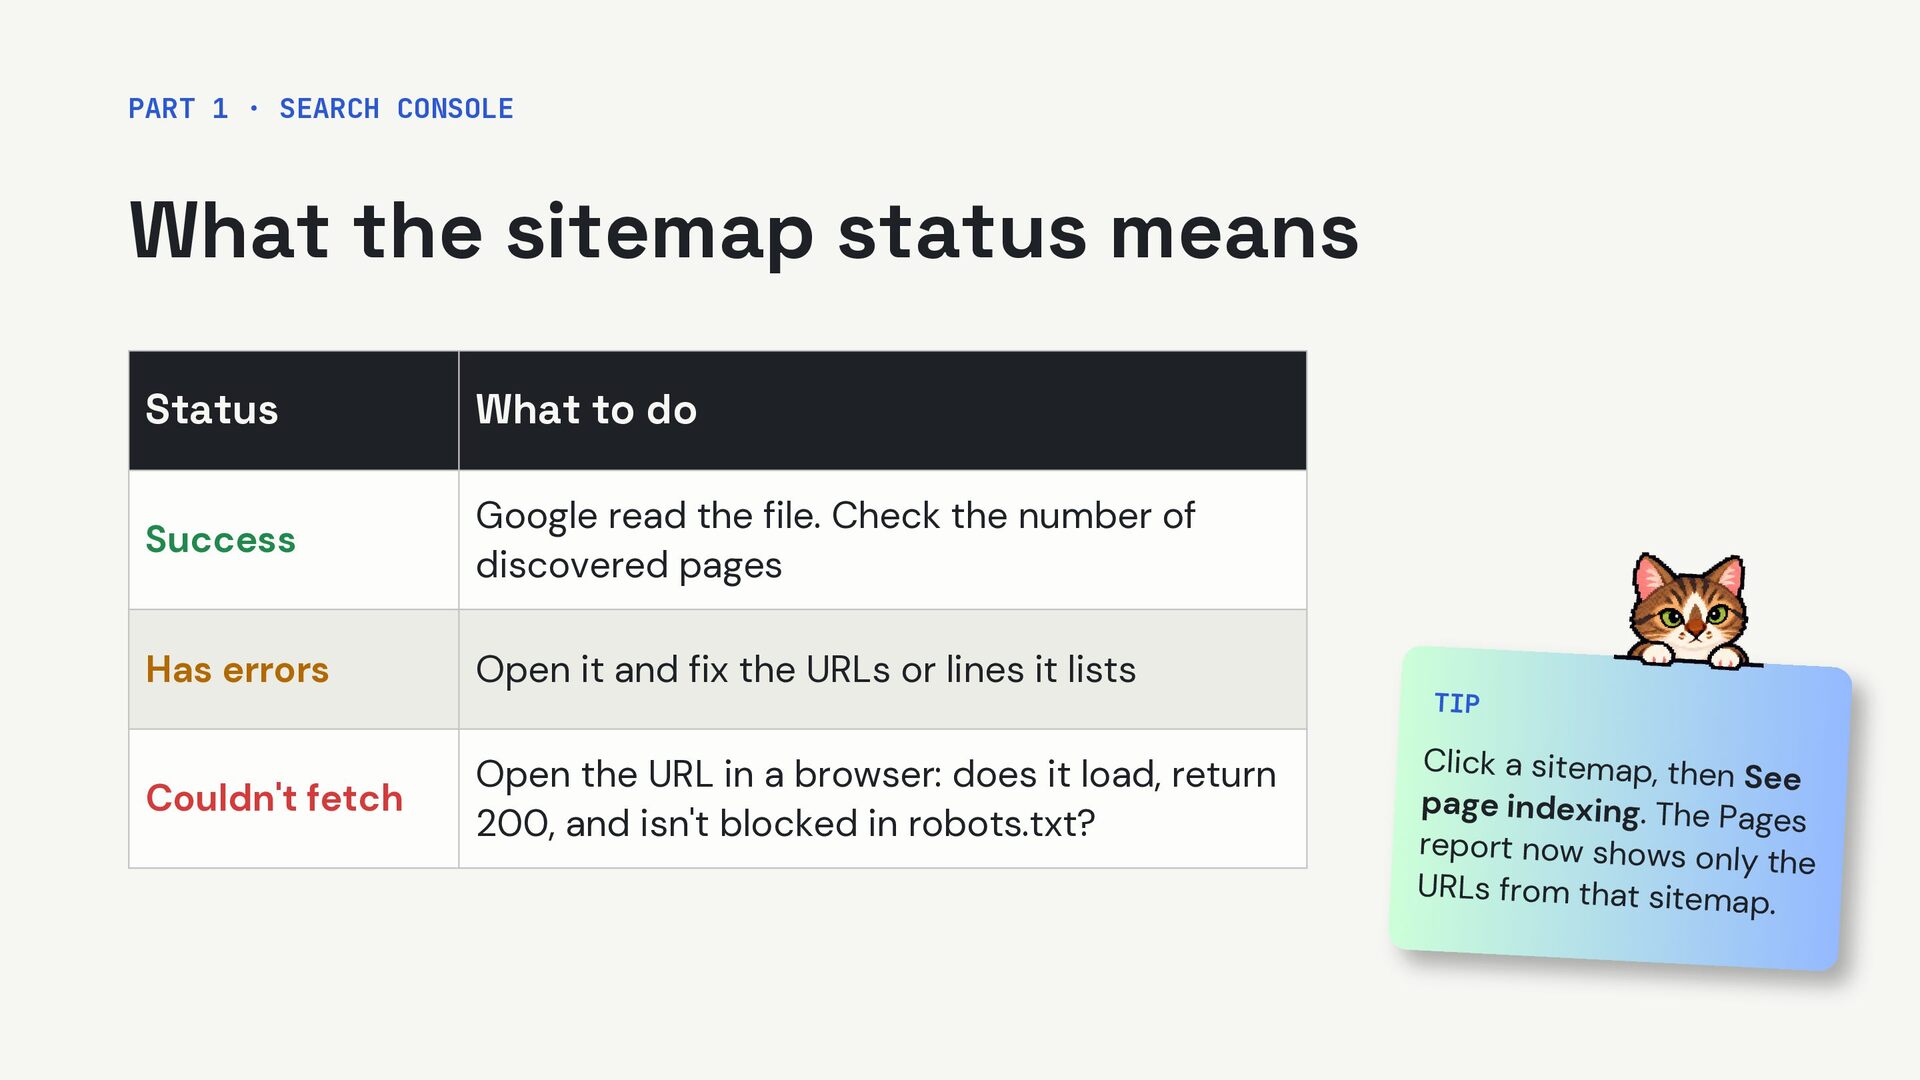
Status What to do Success Google read the file. Check the number of discovered pages Has errors Open it and fix the URLs or lines it lists Couldn't fetch Open the URL in a browser: does it load, return 200, and isn't blocked in robots.txt? TIP Click a sitemap, then See page indexing. The Pa ges report now shows only the URLs from that sitema p.
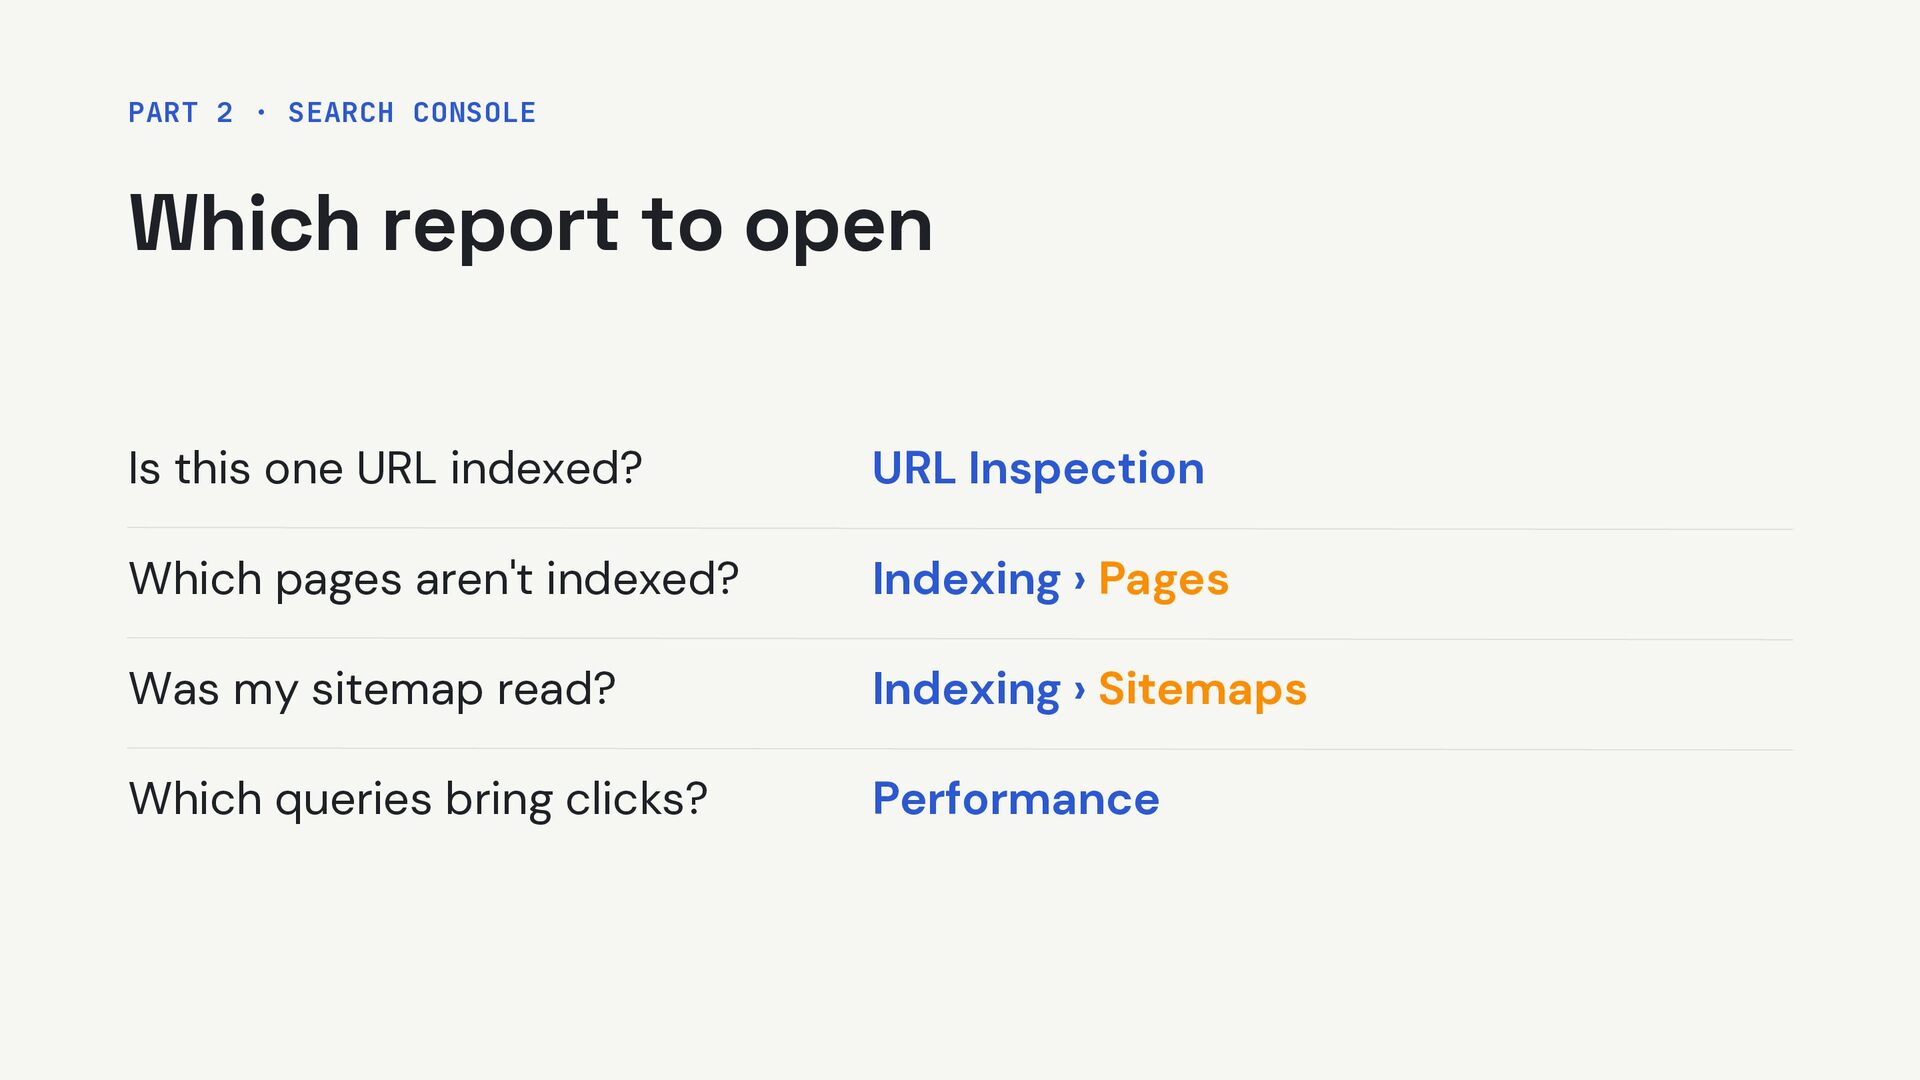
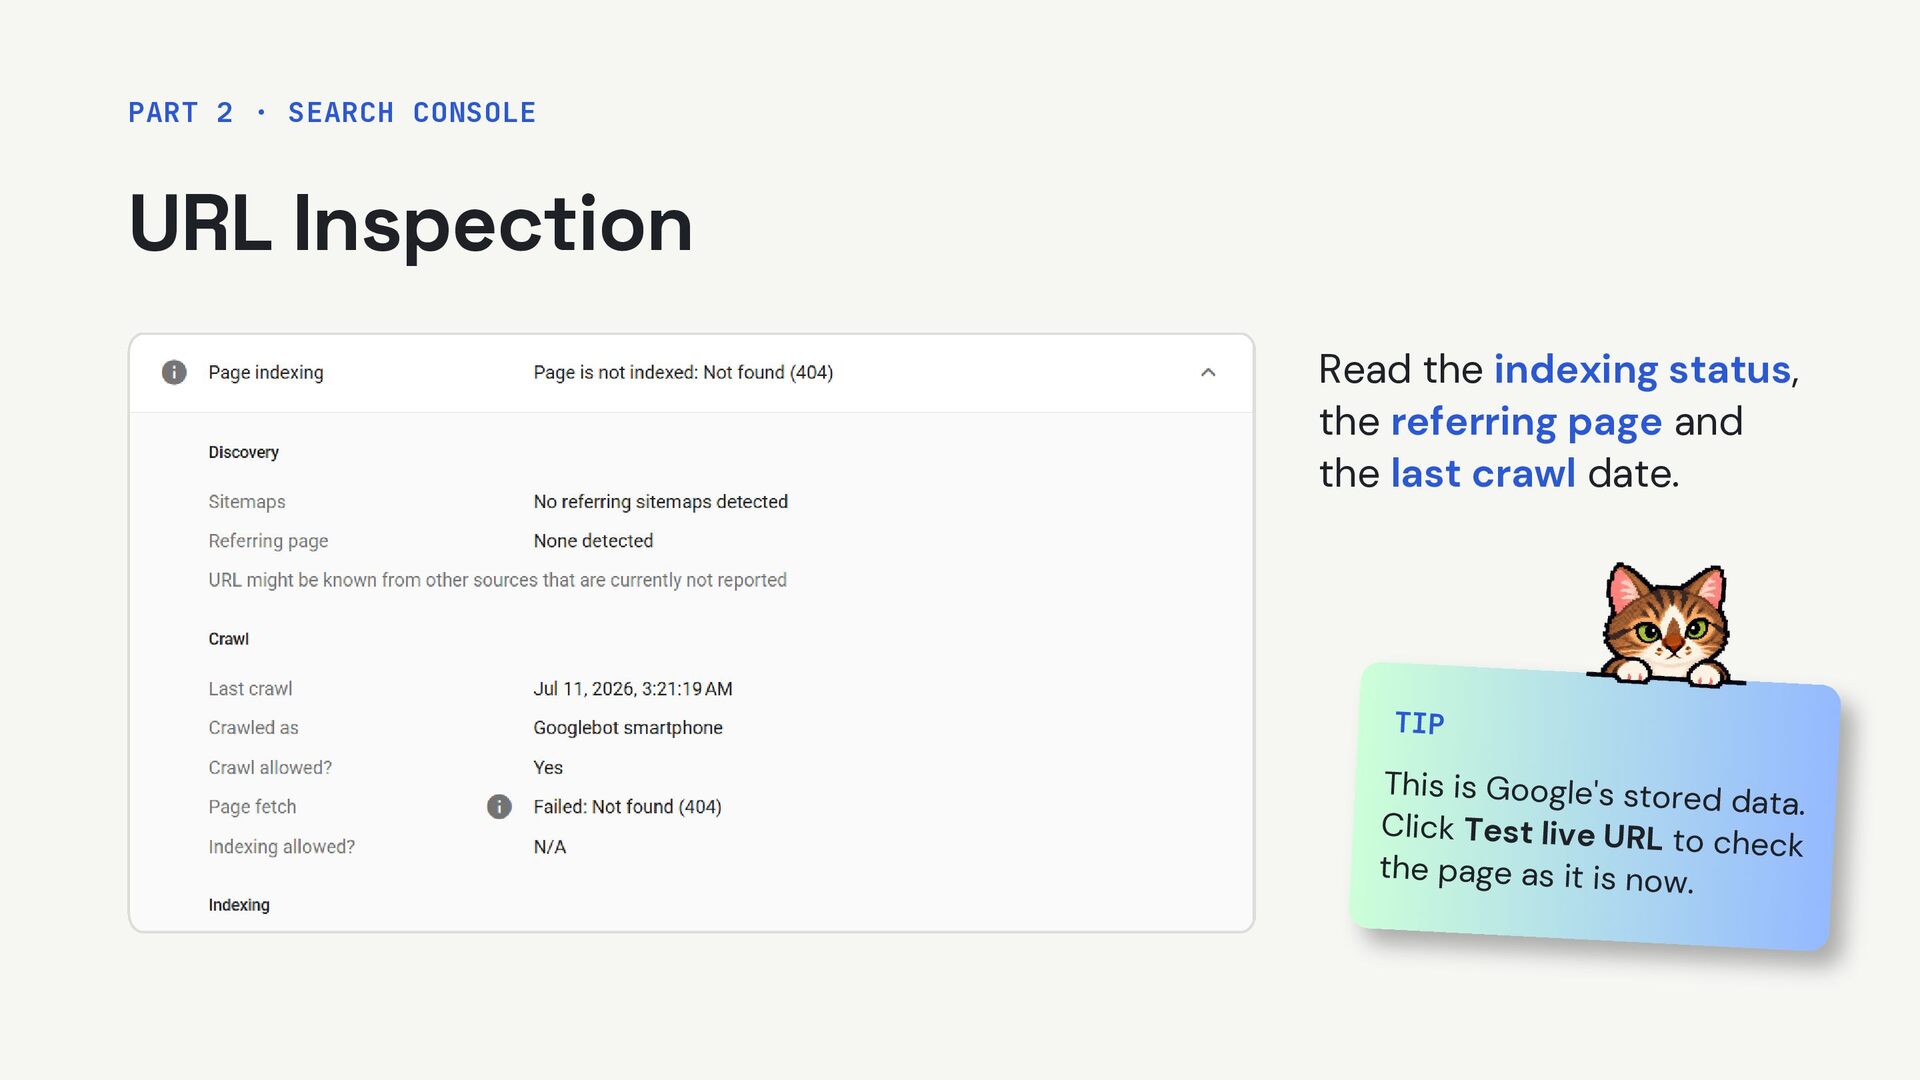
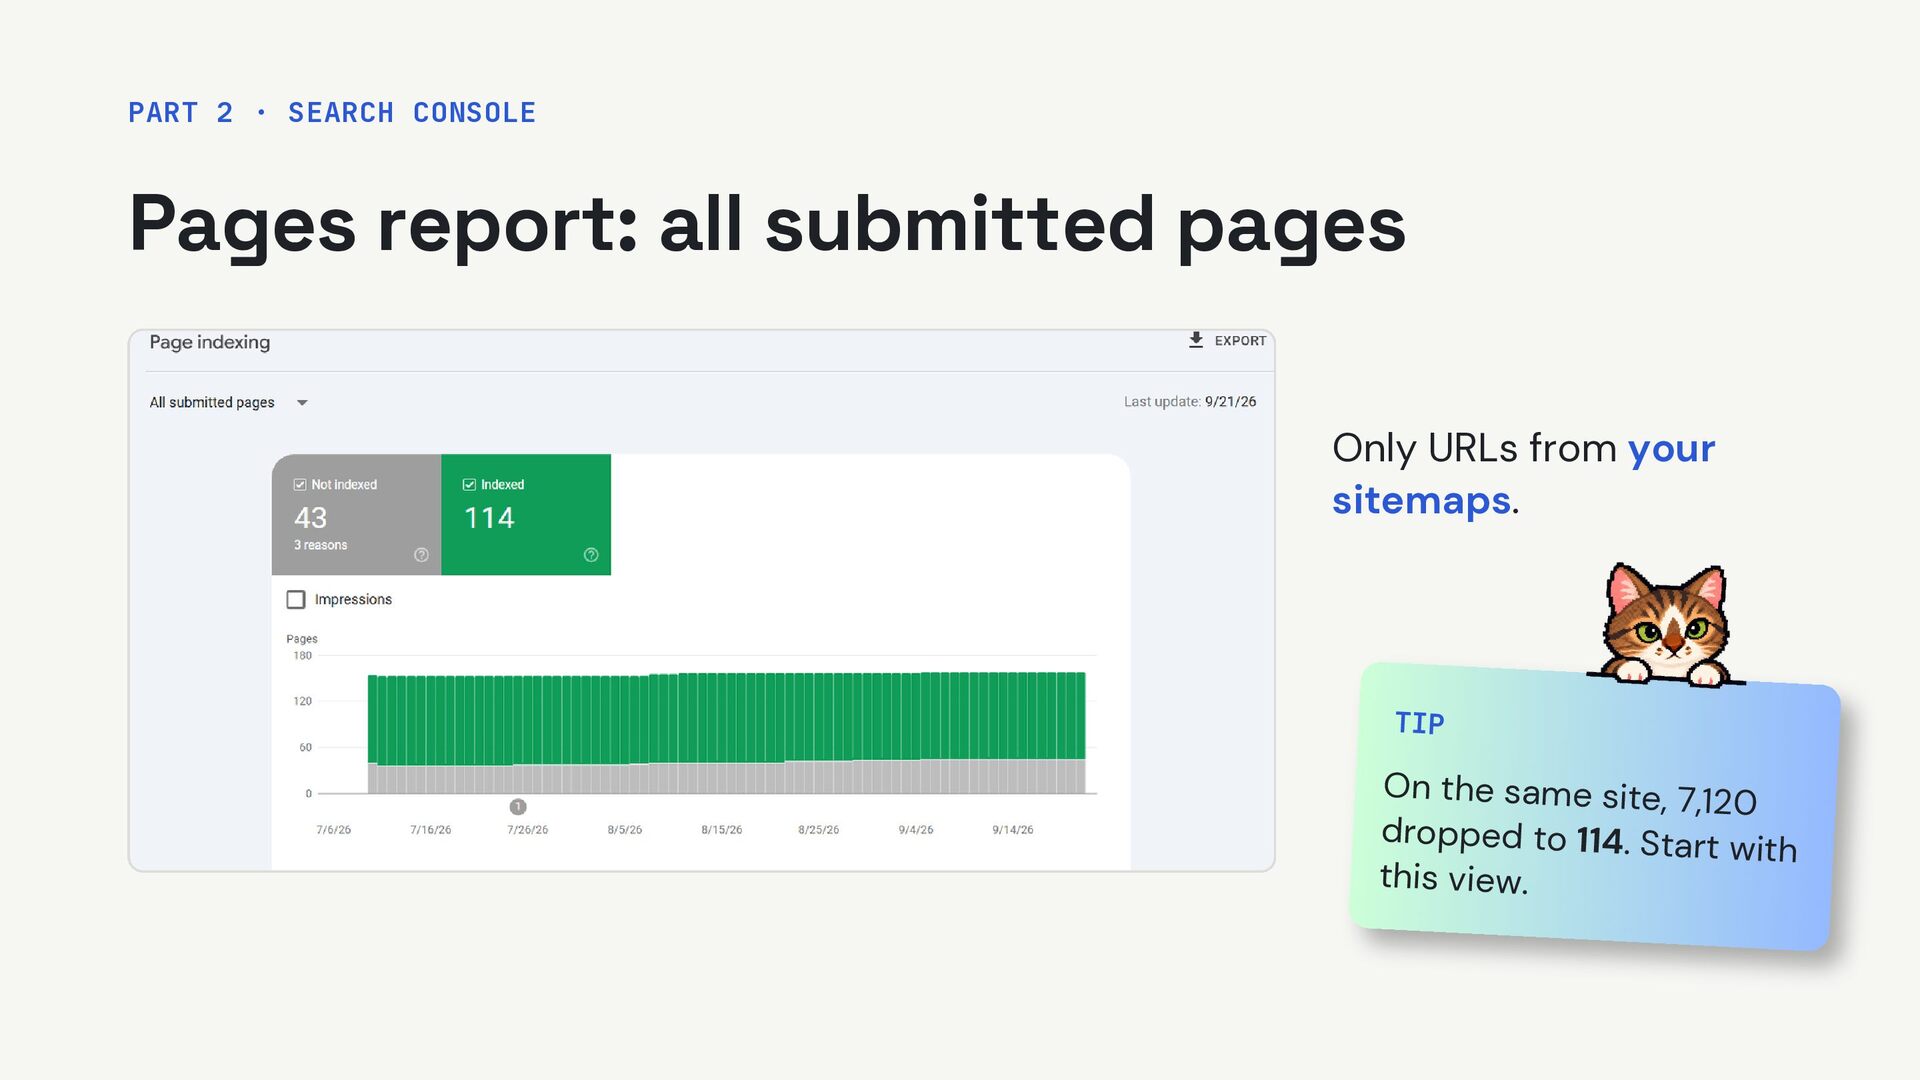
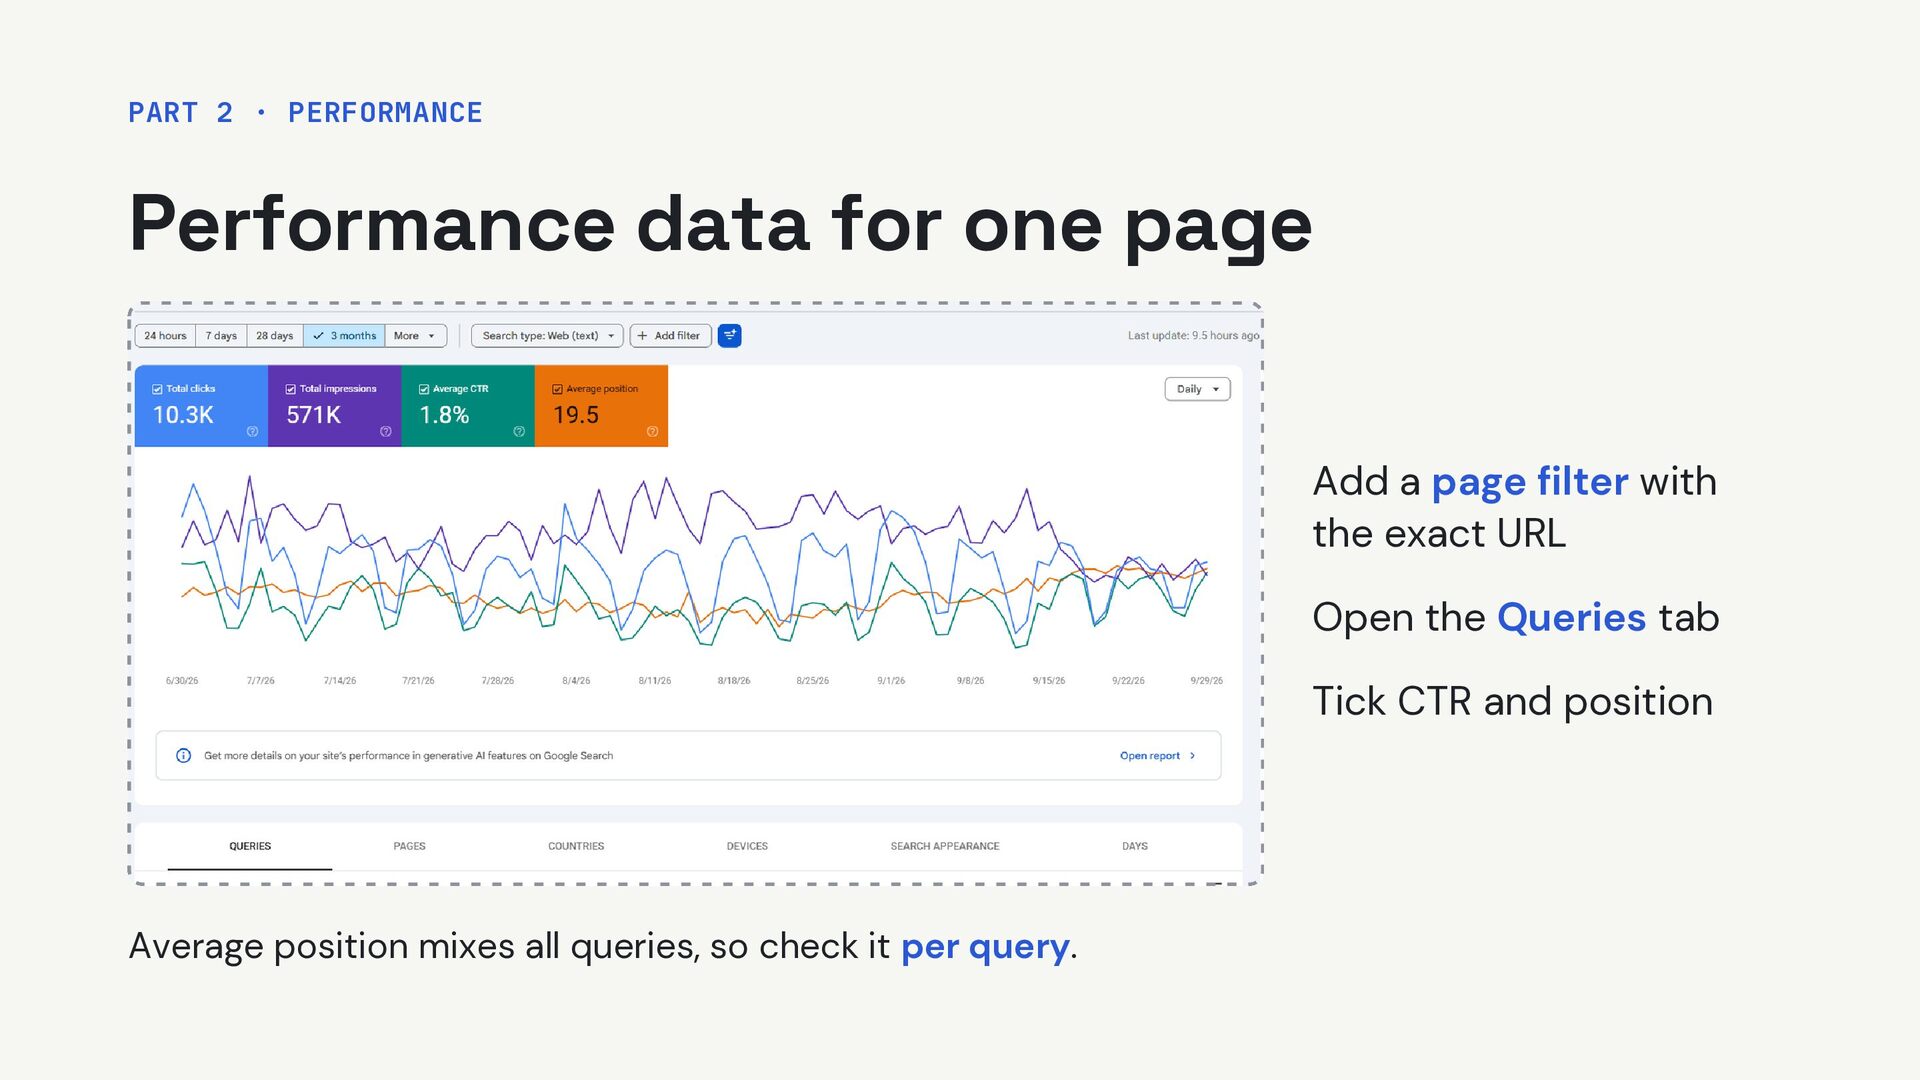
this one URL indexed? URL Inspection Which pages aren't indexed? Indexing › Pages Was my sitemap read? Indexing › Sitemaps Which queries bring clicks? Performance
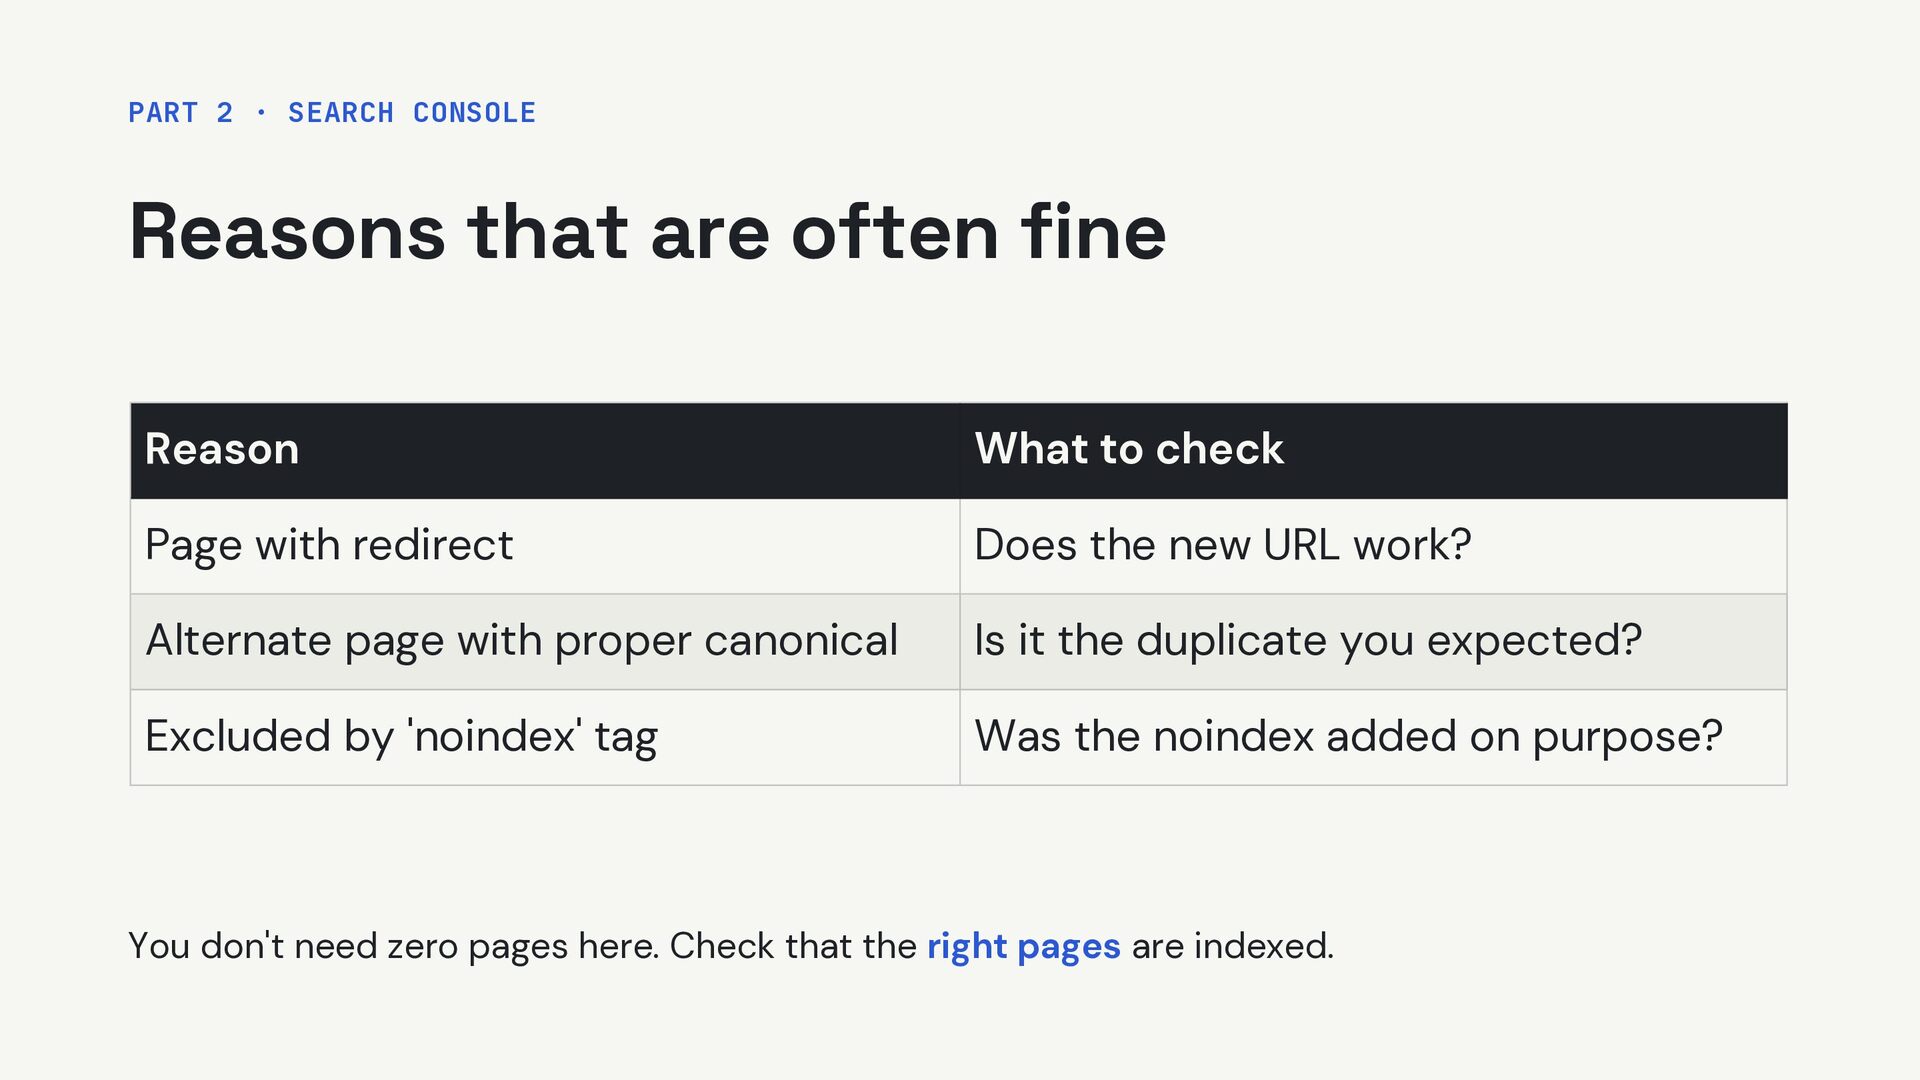
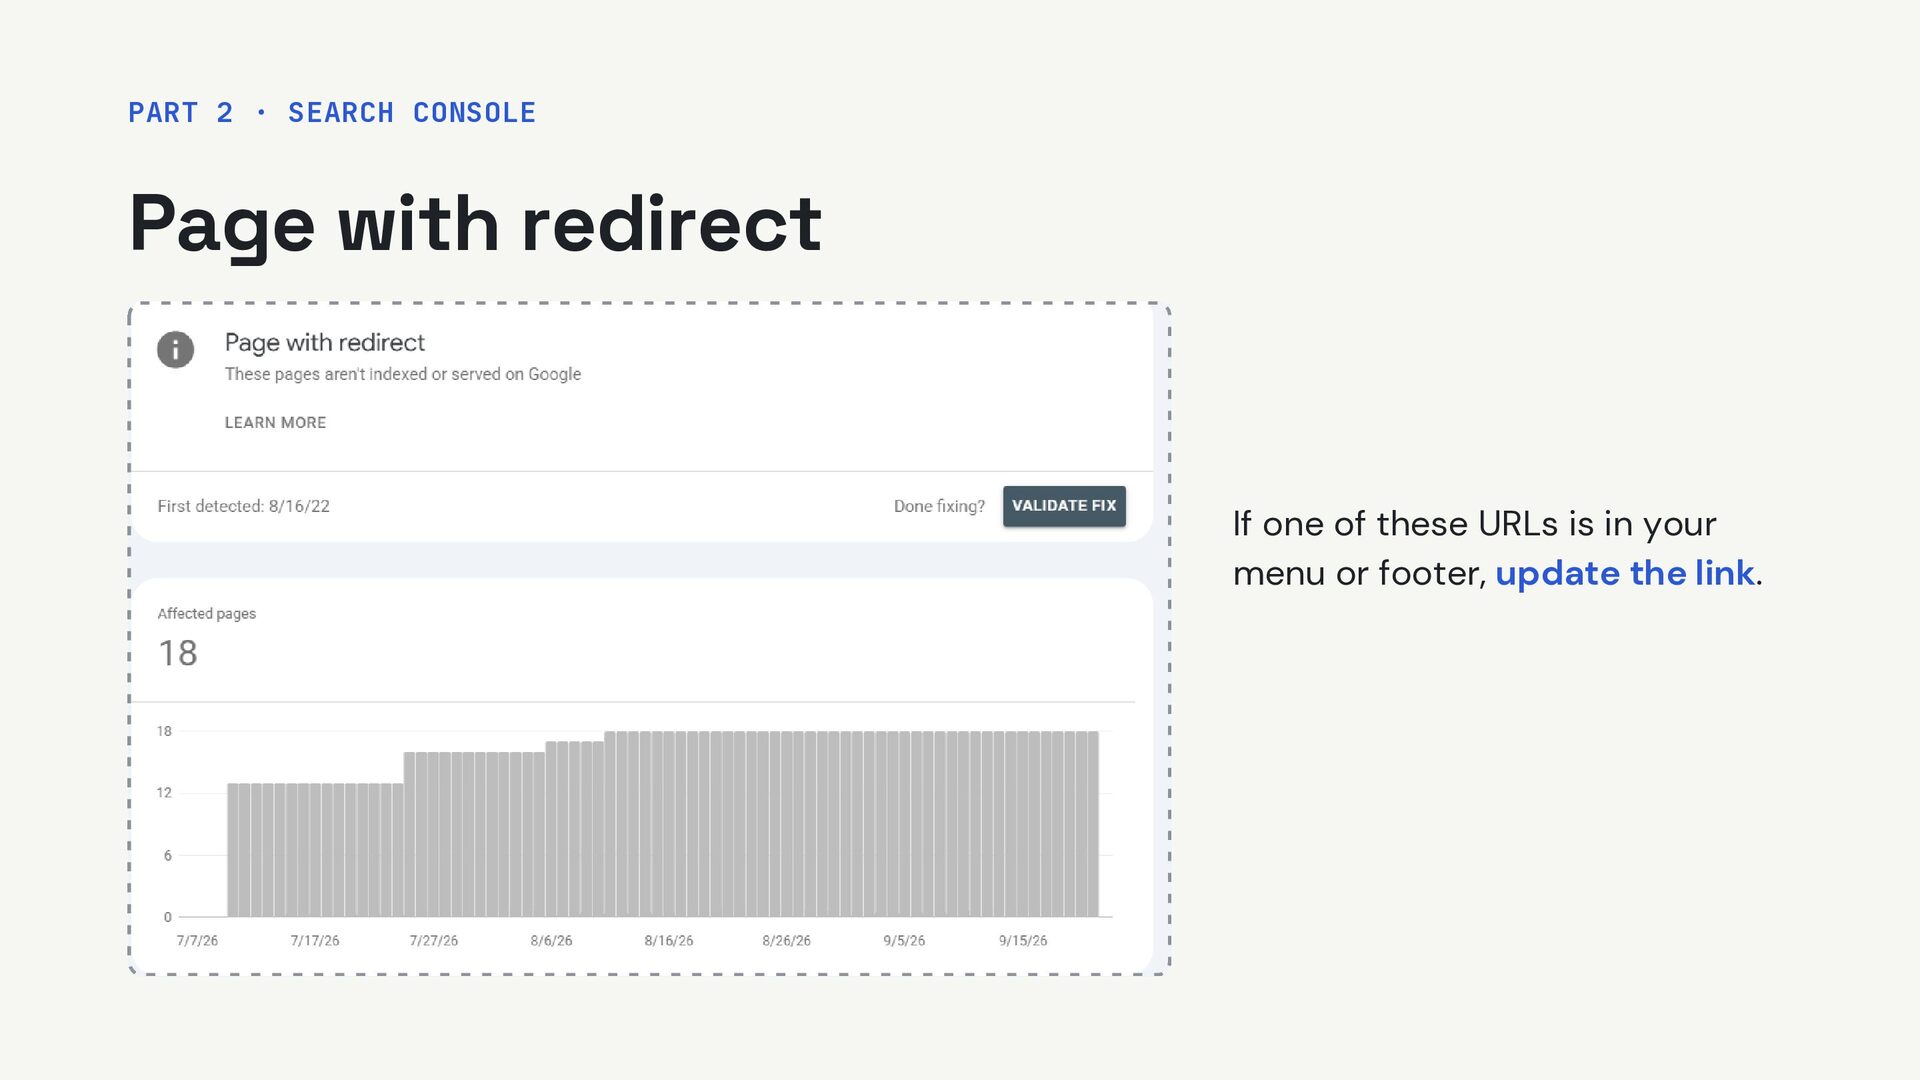
Reason What to check Page with redirect Does the new URL work? Alternate page with proper canonical Is it the duplicate you expected? Excluded by 'noindex' tag Was the noindex added on purpose? You don't need zero pages here. Check that the right pages are indexed.
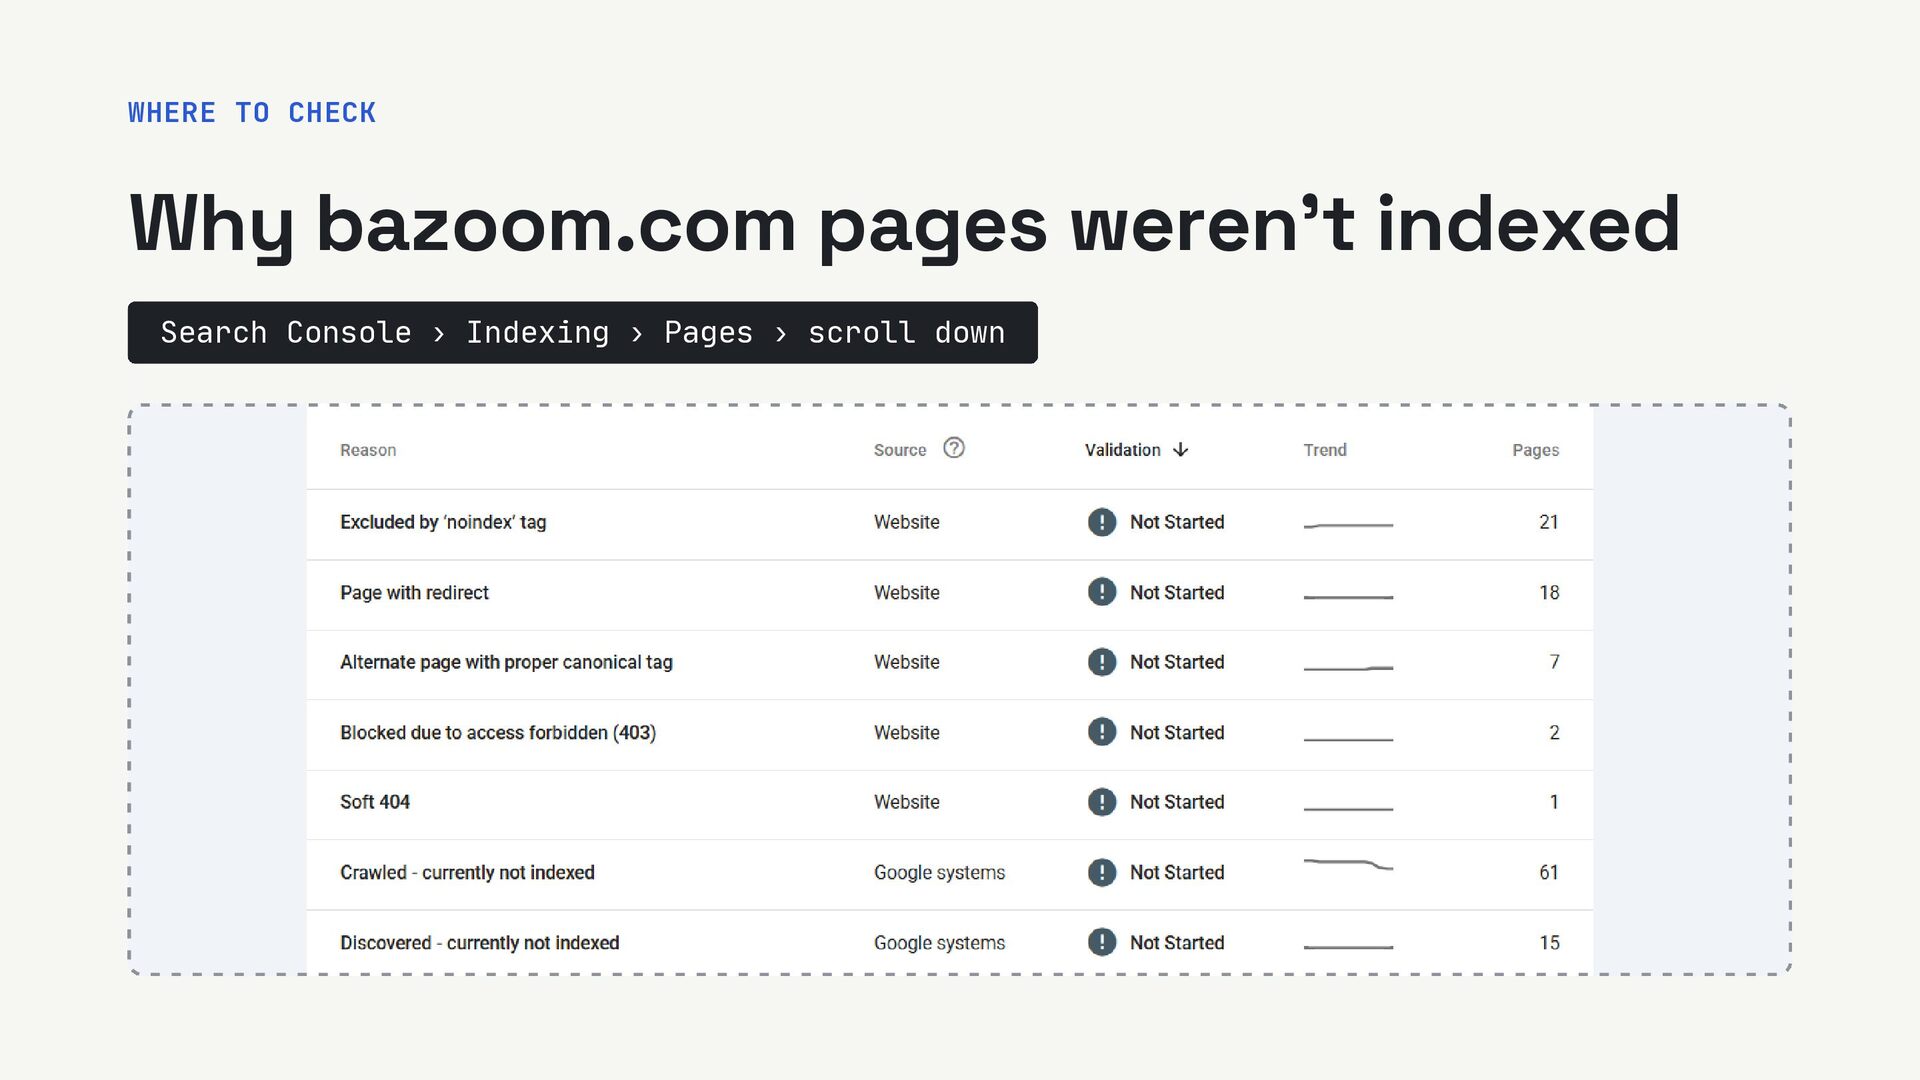
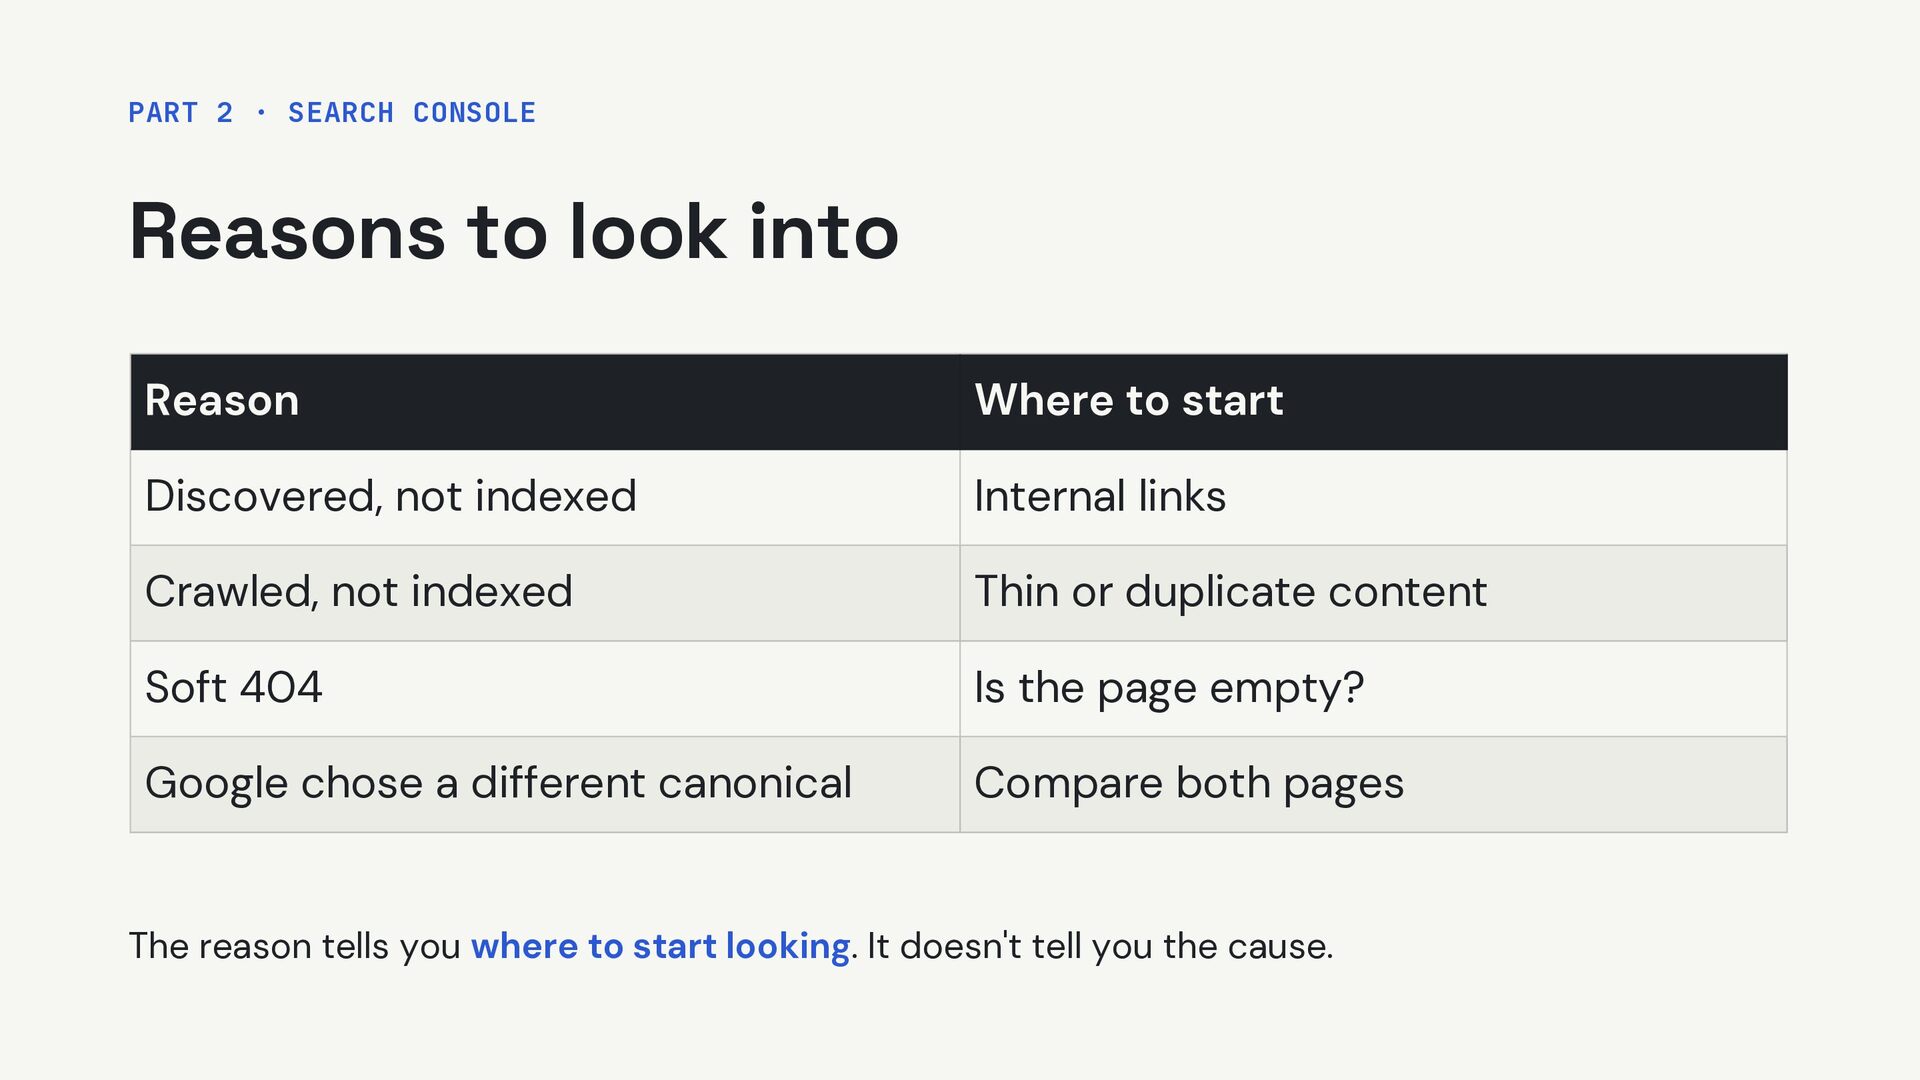
Where to start Discovered, not indexed Internal links Crawled, not indexed Thin or duplicate content Soft 404 Is the page empty? Google chose a different canonical Compare both pages The reason tells you where to start looking. It doesn't tell you the cause.
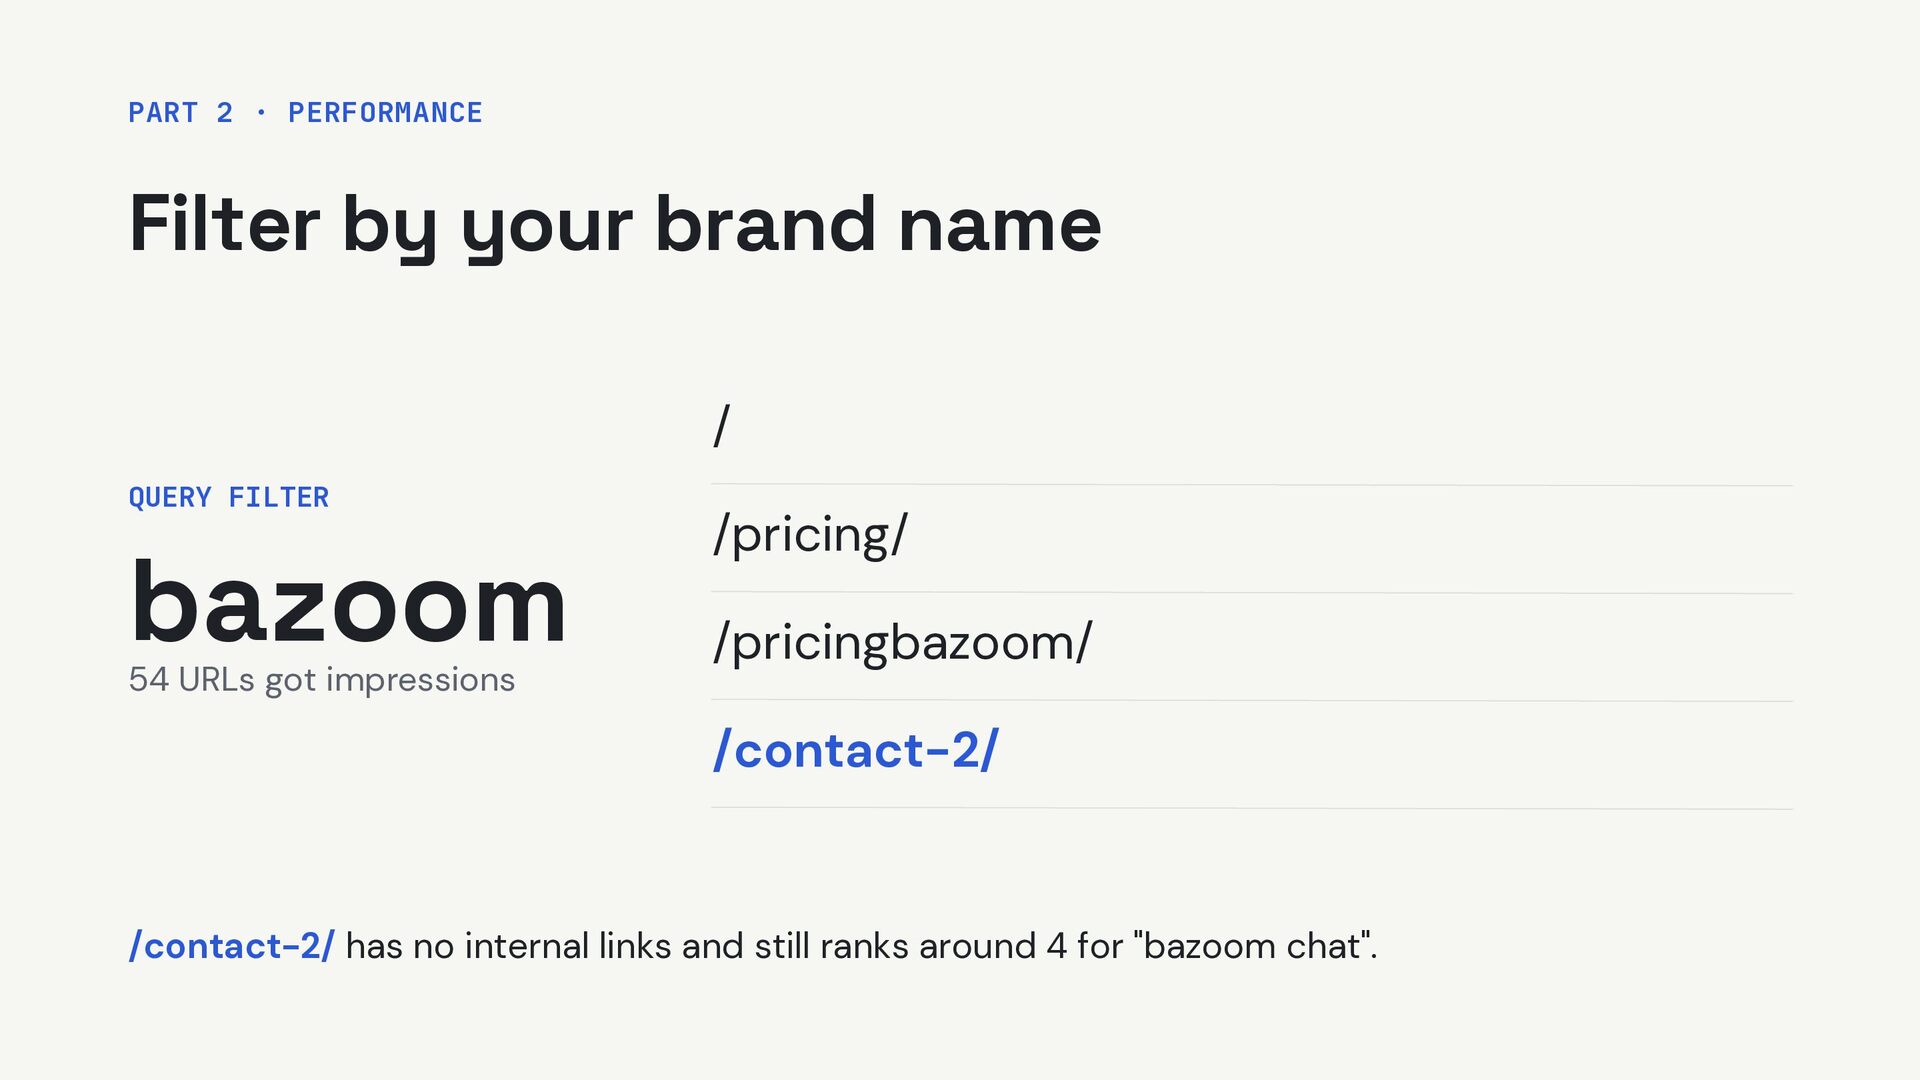
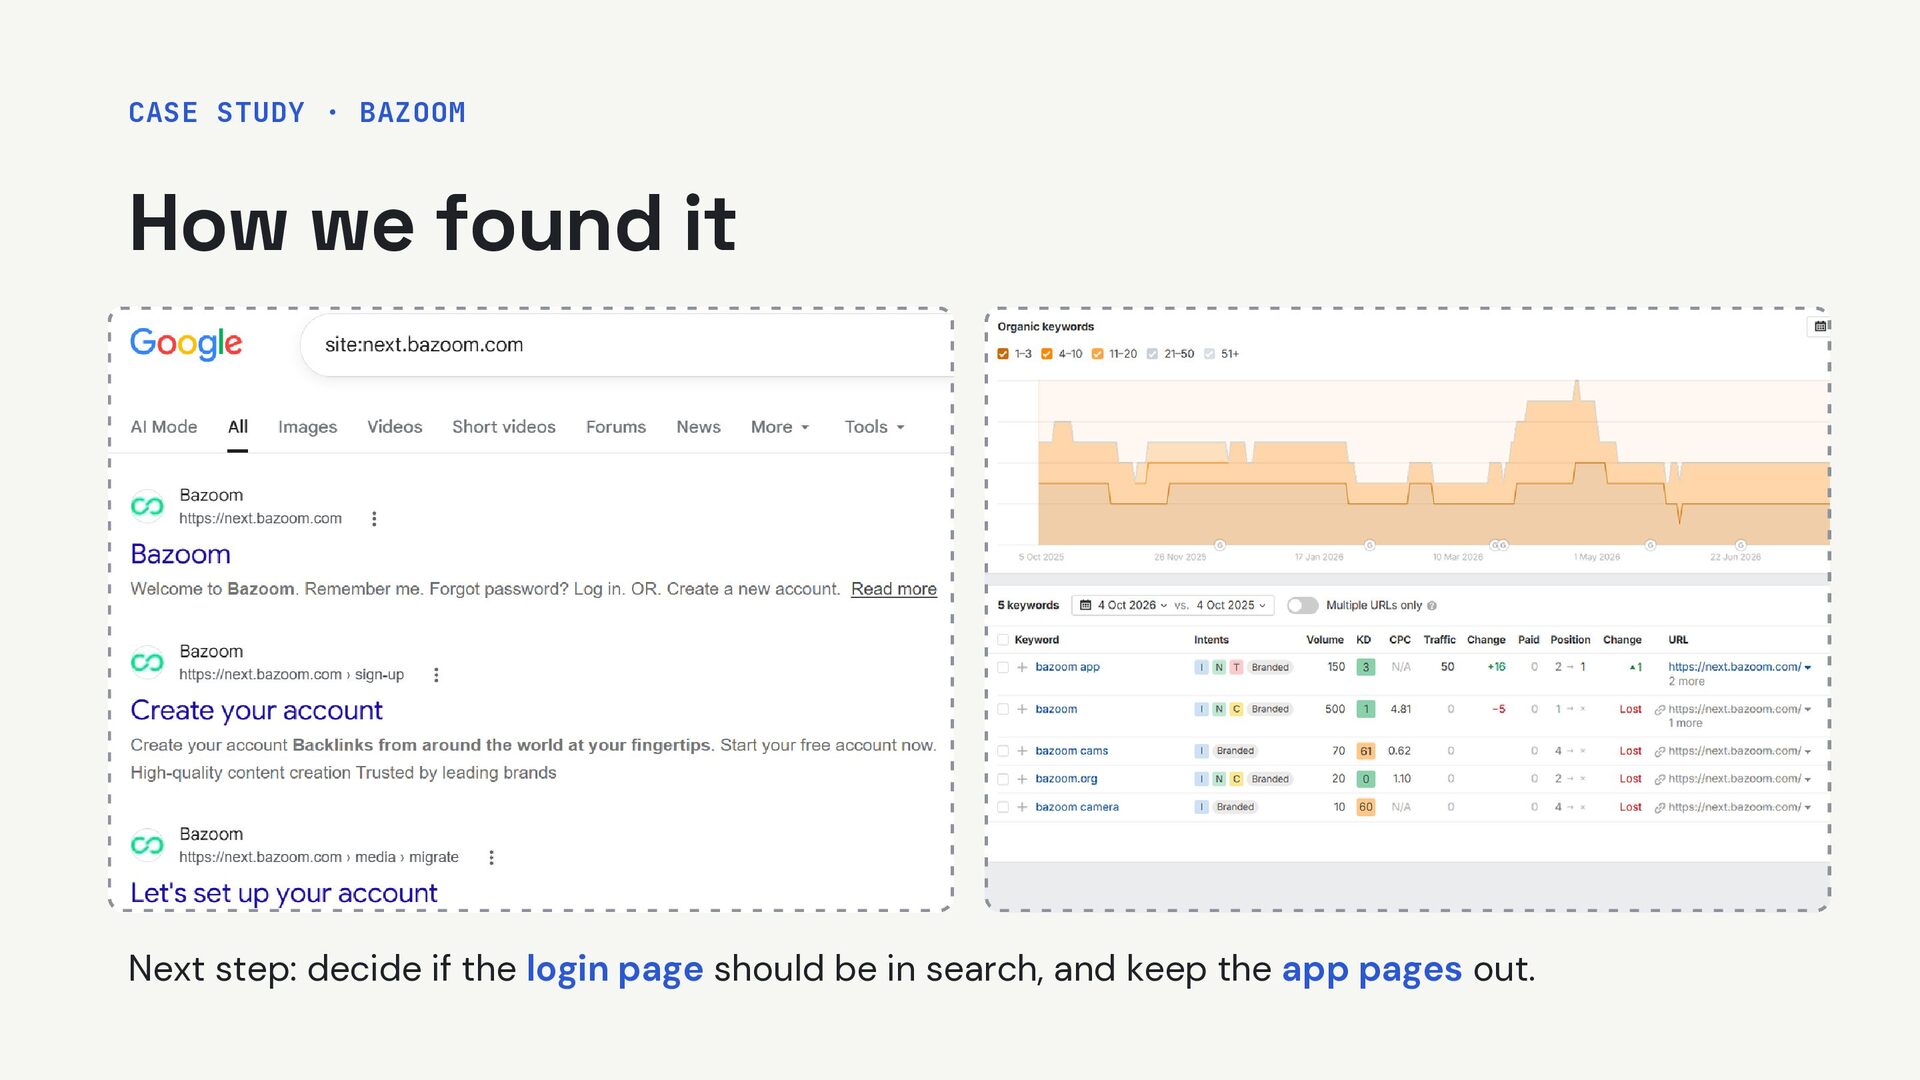
QUERY FILTER bazoom 54 URLs got impressions /pricing/ /pricingbazoom/ /contact-2/ /contact-2/ has no internal links and still ranks around 4 for "bazoom chat".
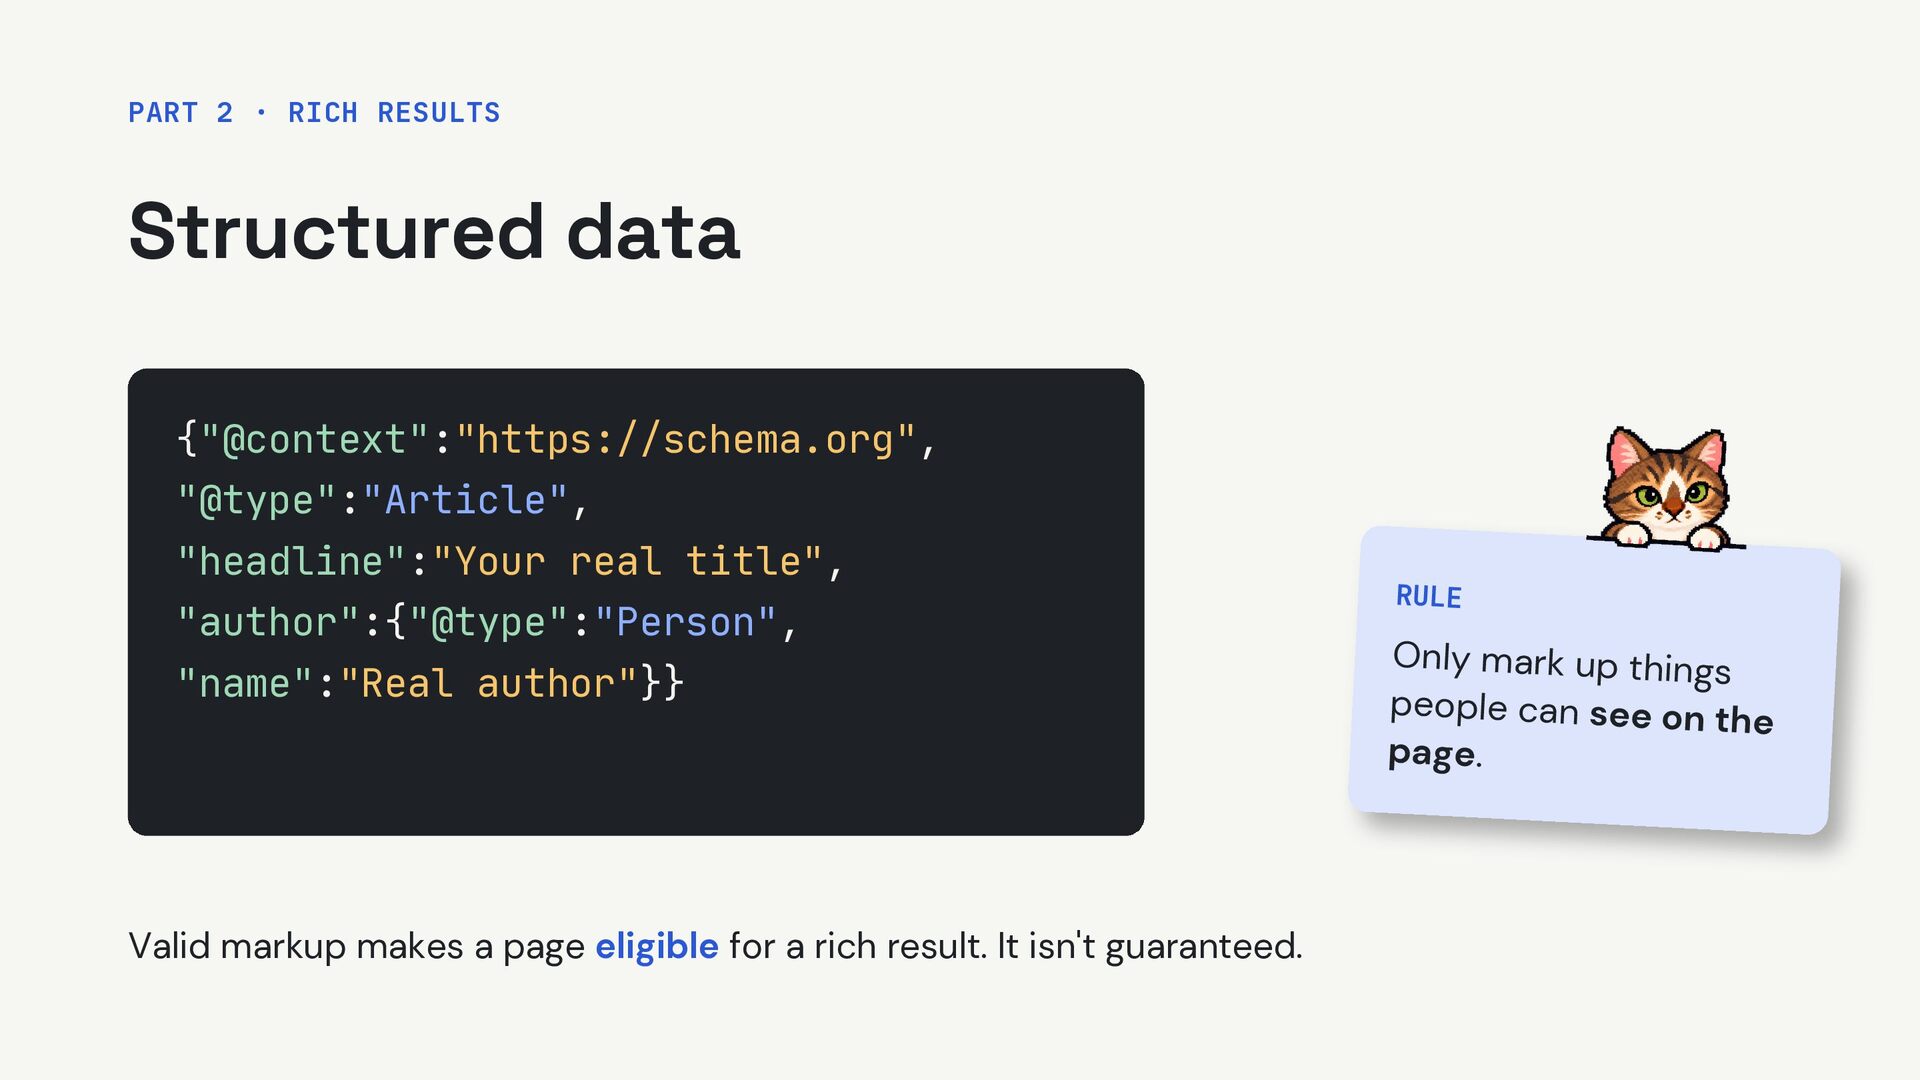
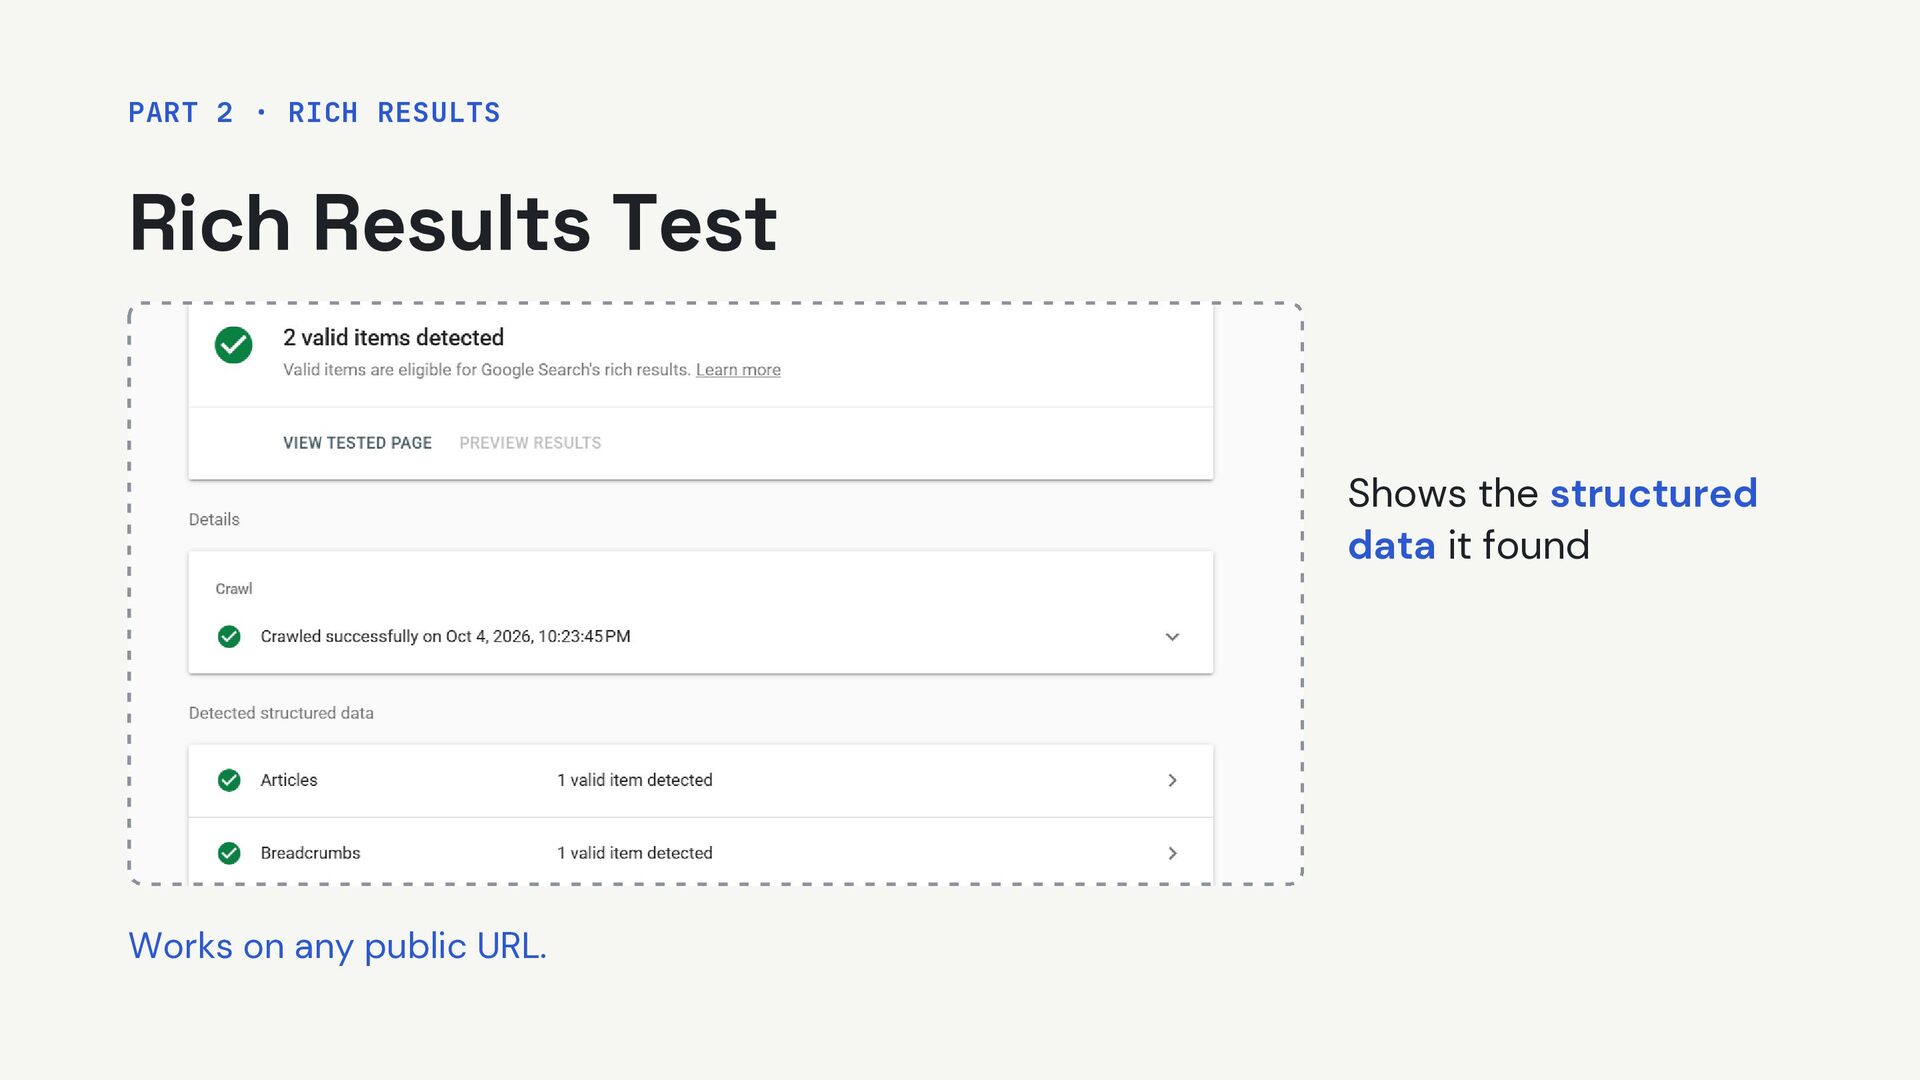
real title", "author":{"@type":"Person", "name":"Real author"}} Valid markup makes a page eligible for a rich result. It isn't guaranteed. RULE Only mark up things people can see on th e page.
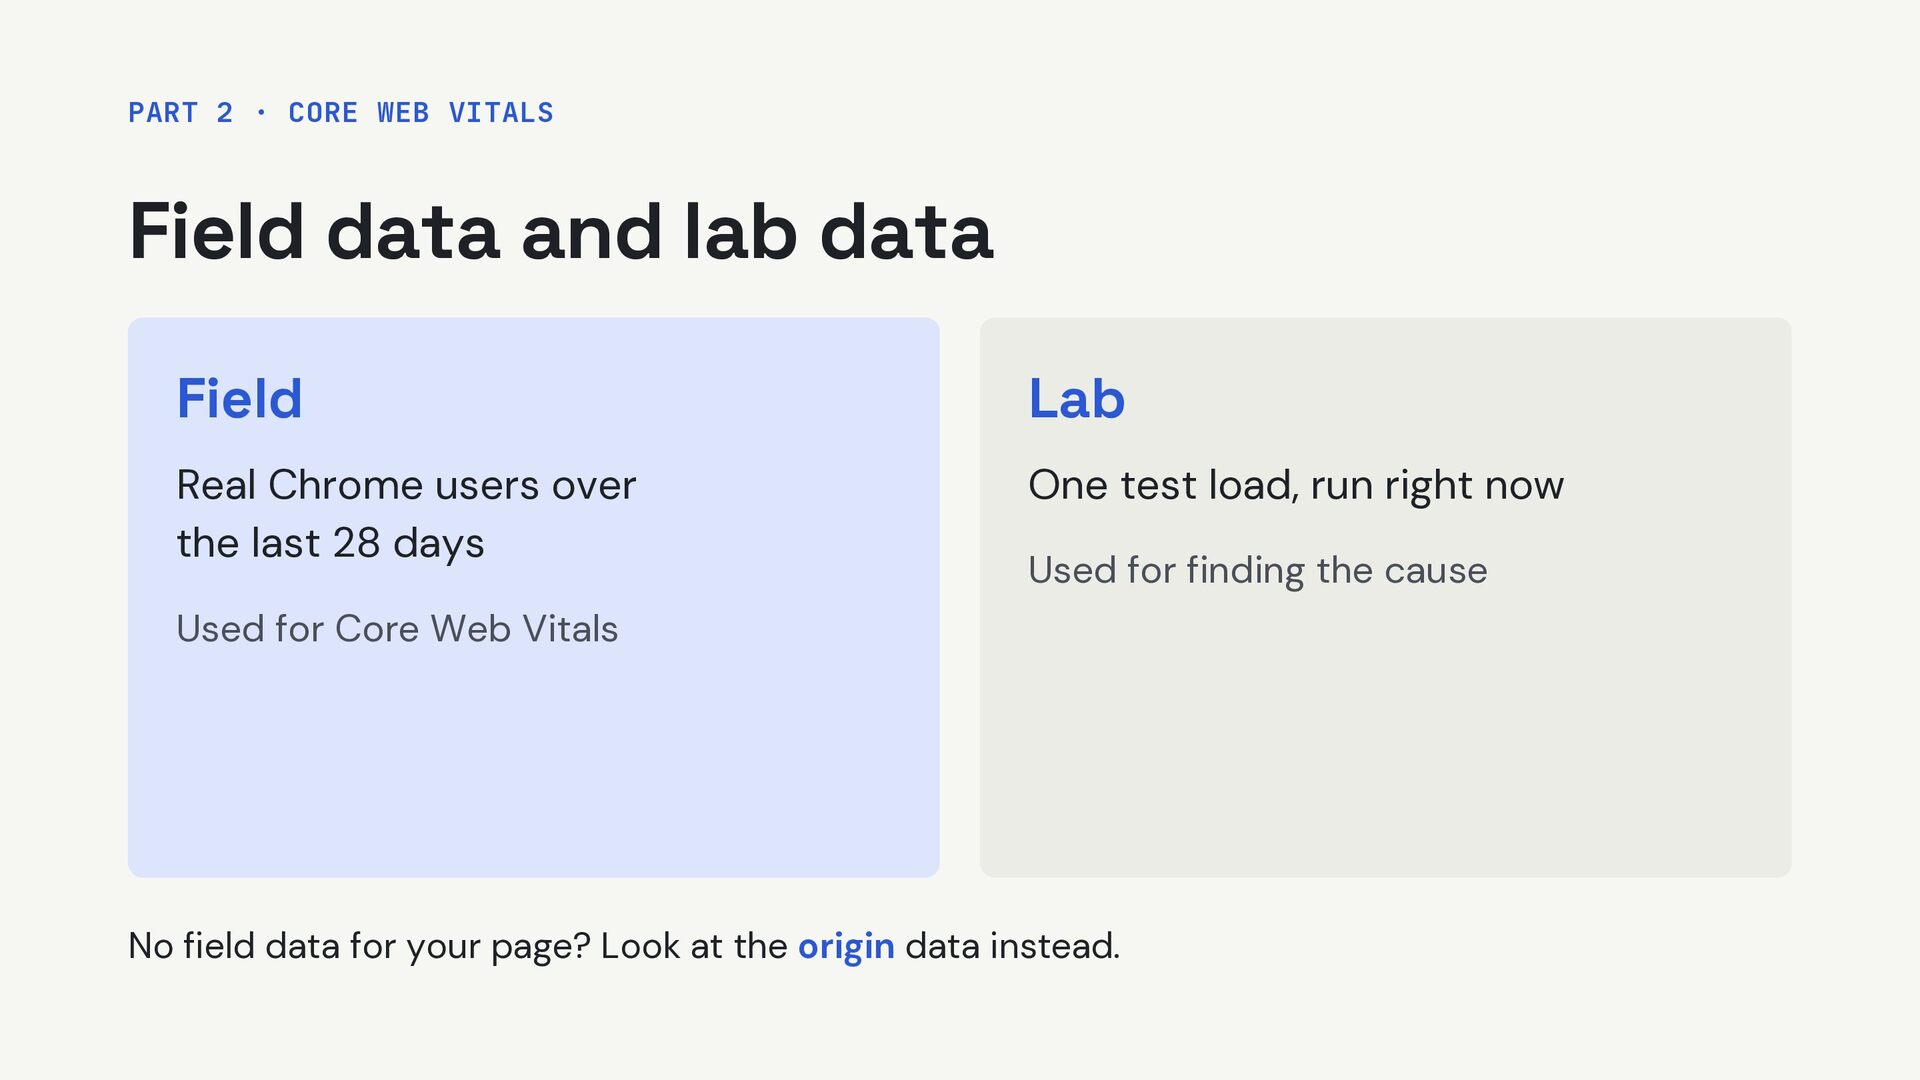
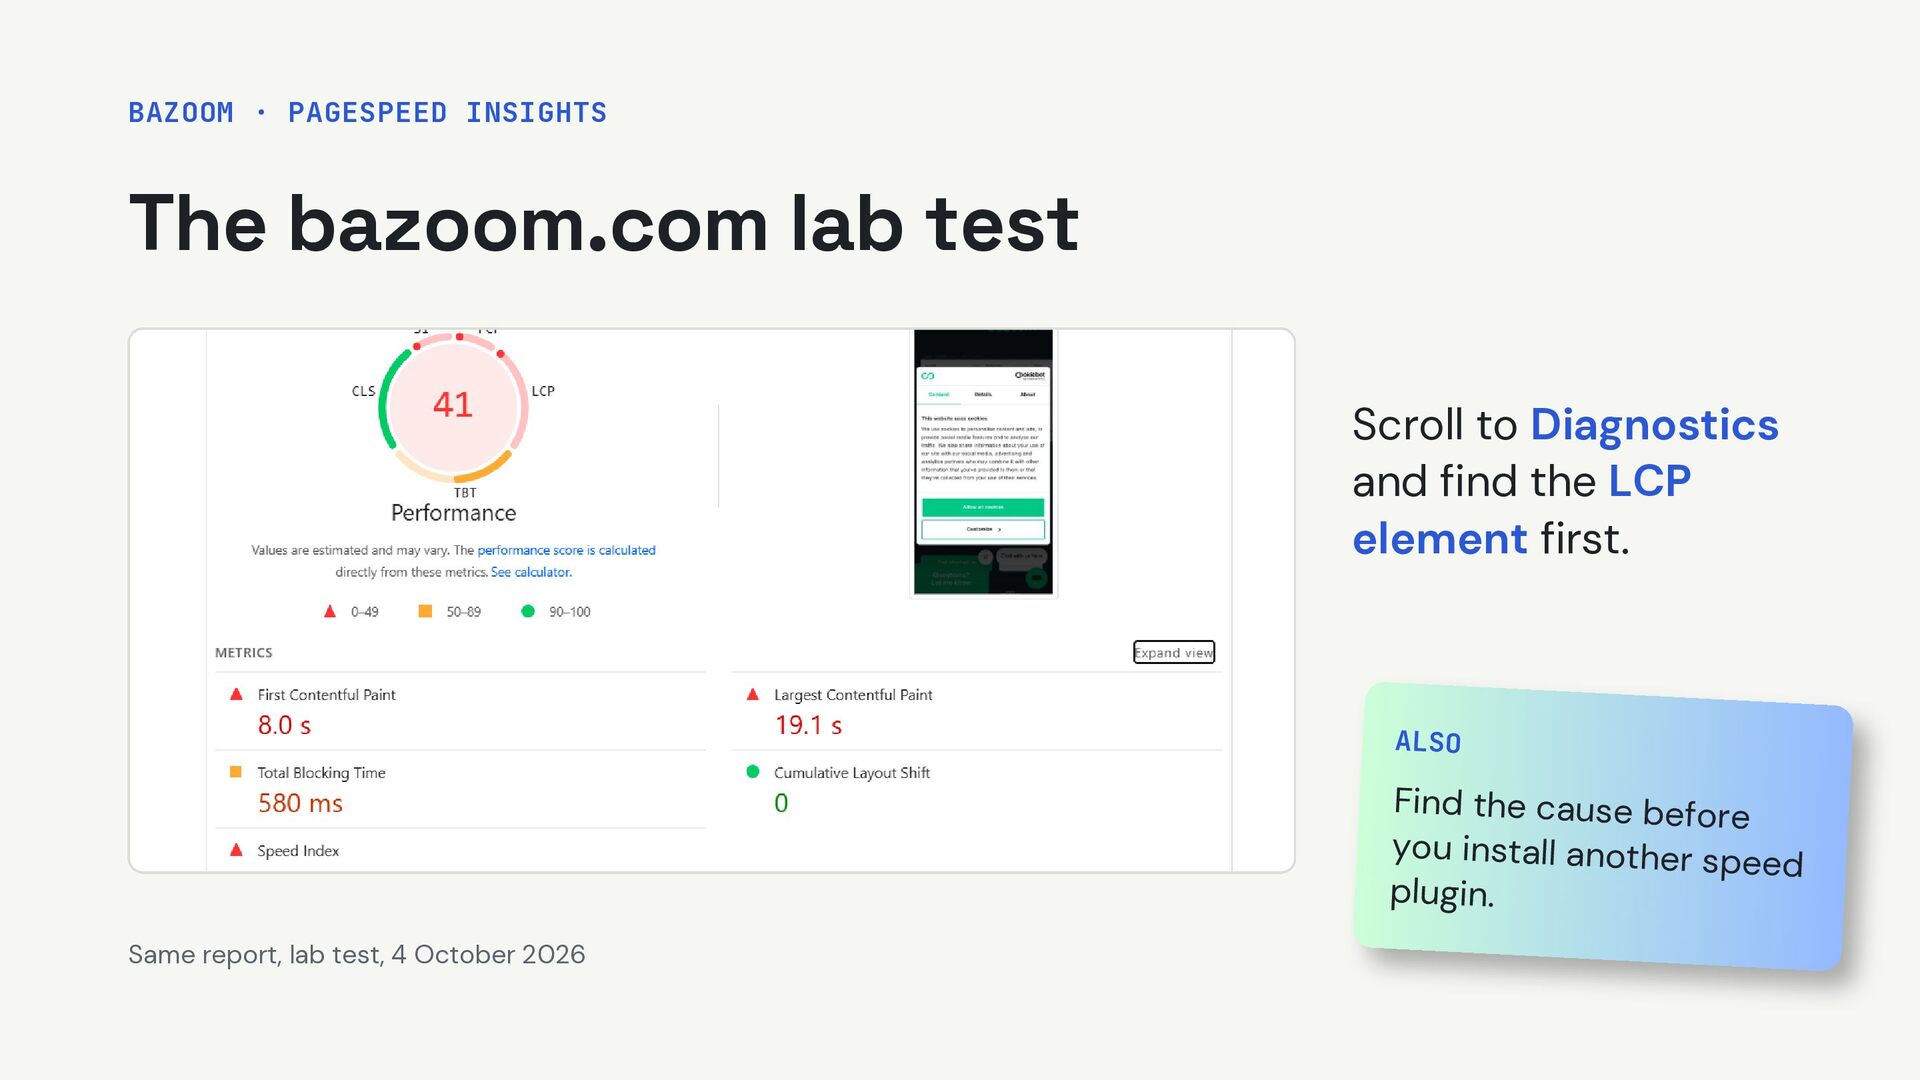
data Field Lab Real Chrome users over the last 28 days One test load, run right now Used for finding the cause Used for Core Web Vitals No field data for your page? Look at the origin data instead.
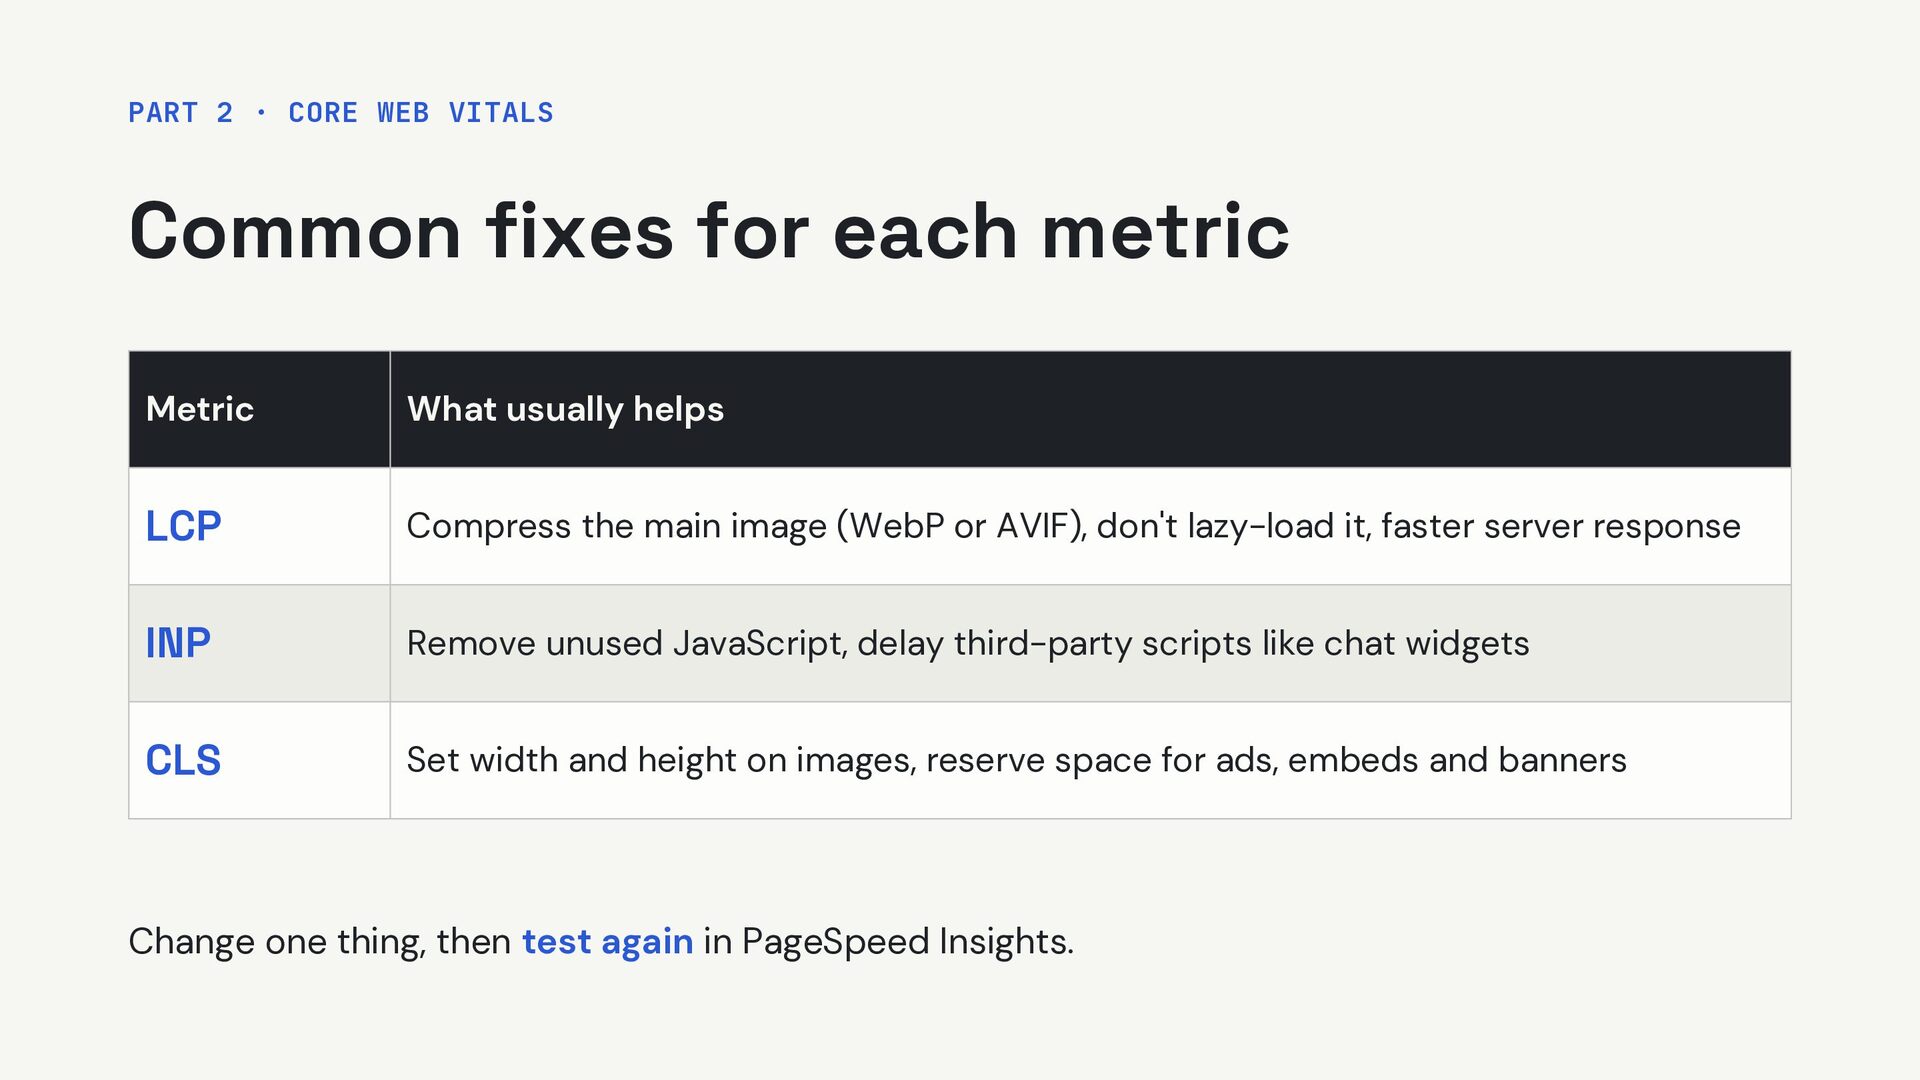
metric Metric What usually helps LCP Compress the main image (WebP or AVIF), don't lazy-load it, faster server response INP Remove unused JavaScript, delay third-party scripts like chat widgets CLS Set width and height on images, reserve space for ads, embeds and banners Change one thing, then test again in PageSpeed Insights.
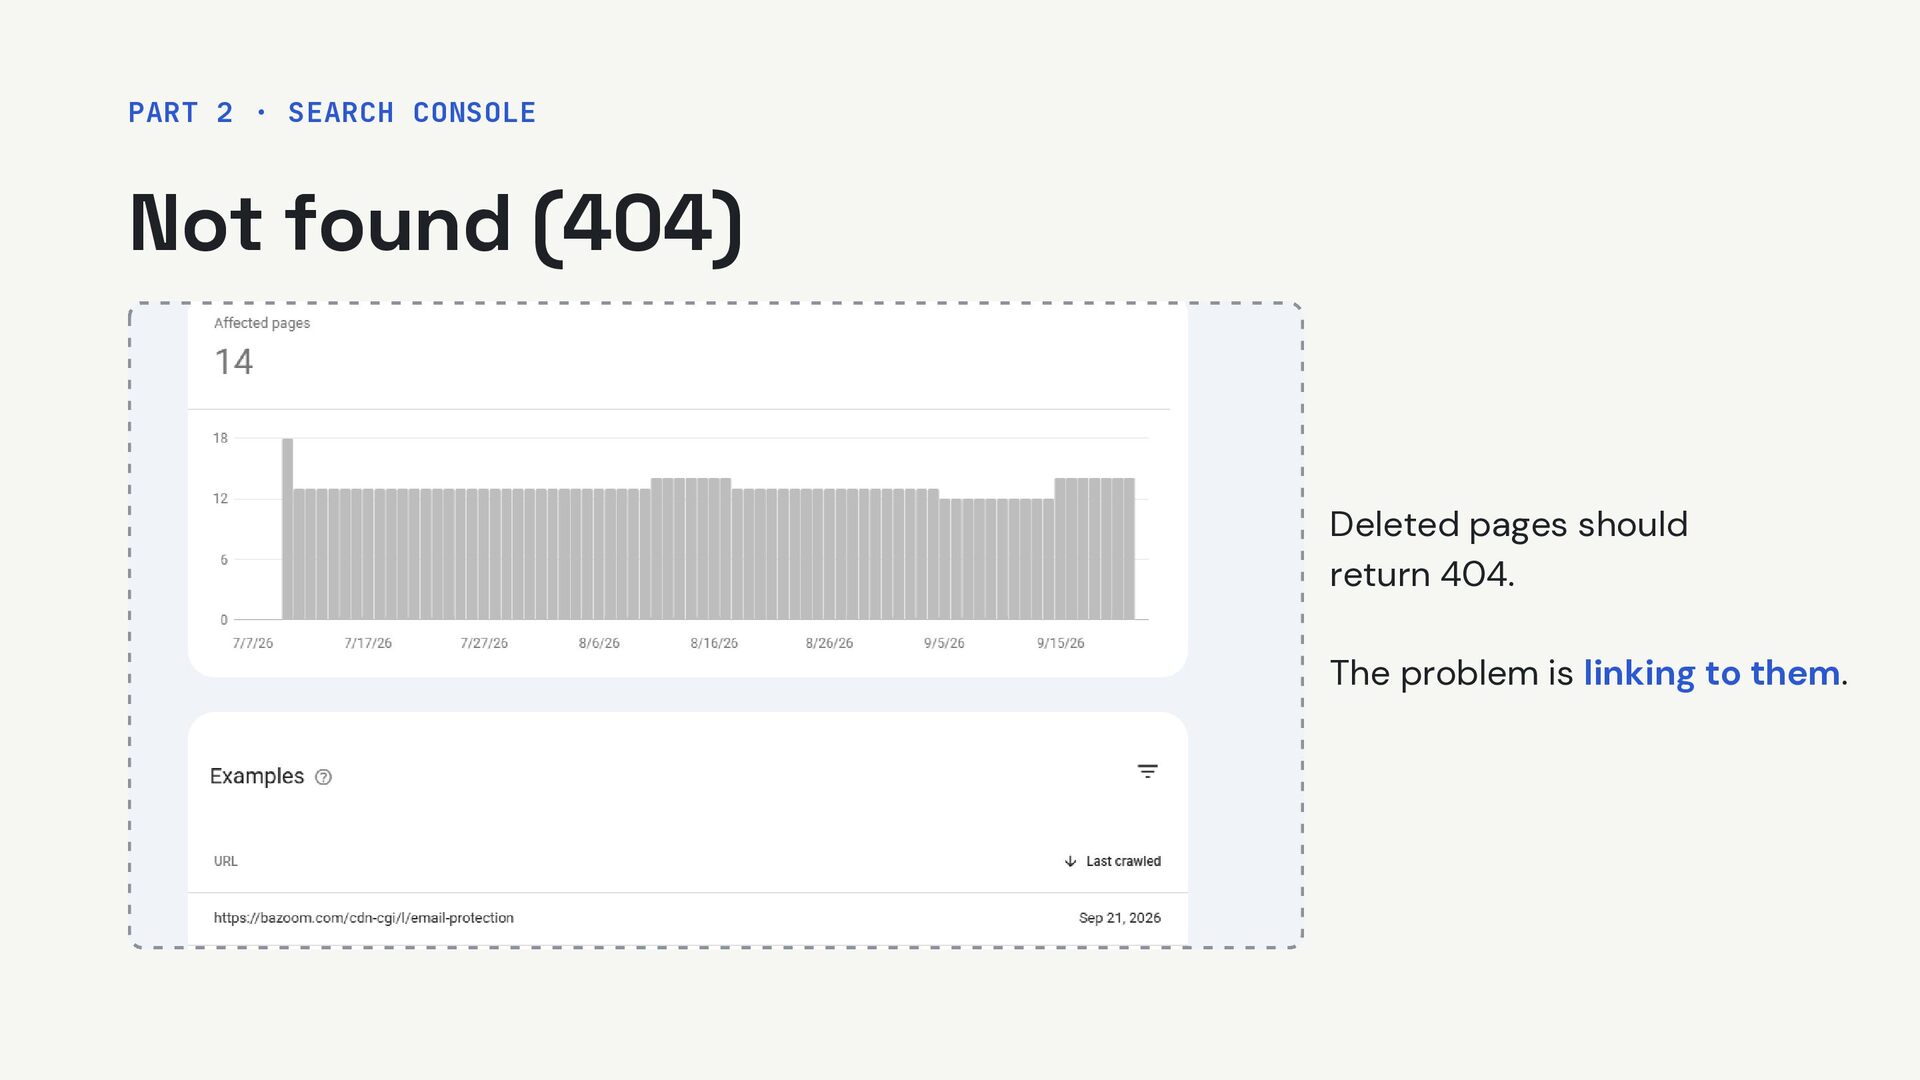
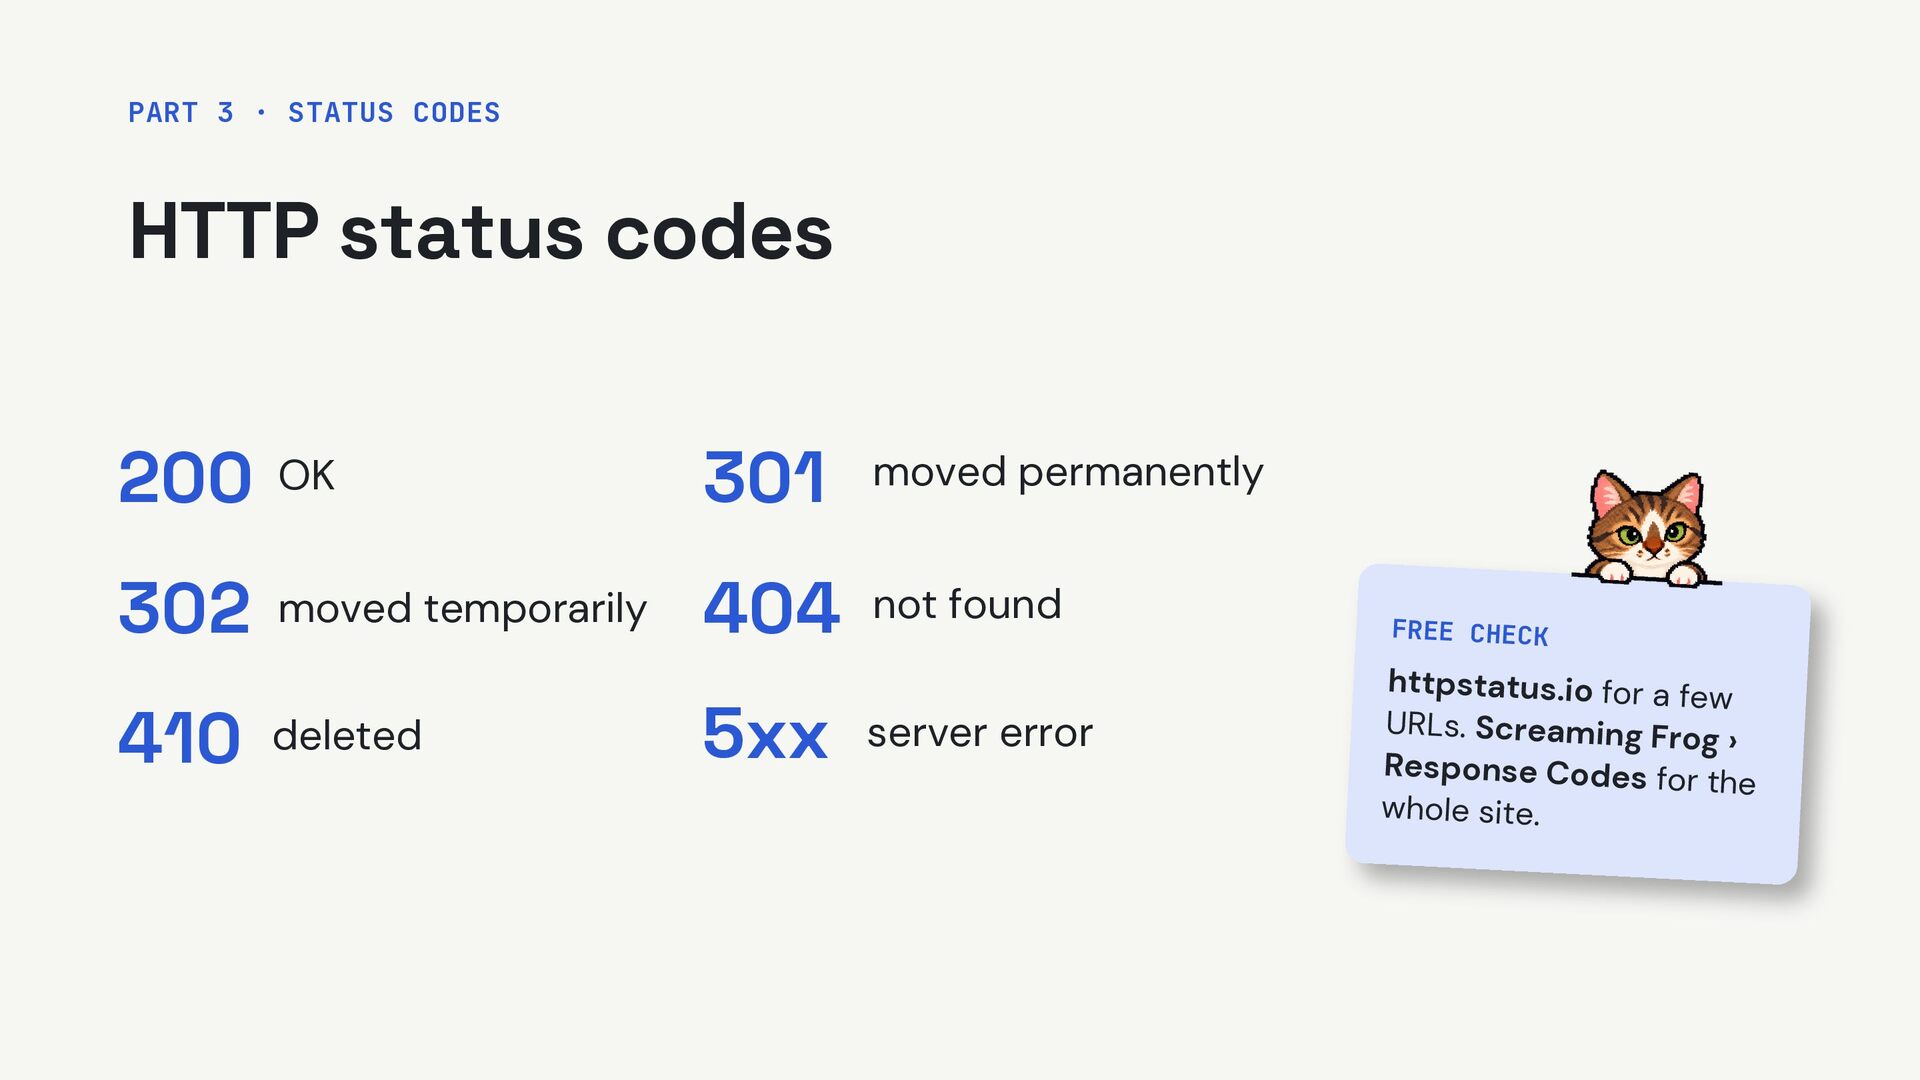
301 moved permanently 302 moved temporarily 404 not found 410 deleted 5xx server error FREE CHECK httpstatus.io for a fe w URLs. Screaming Fro g› Response Codes for the whole site.
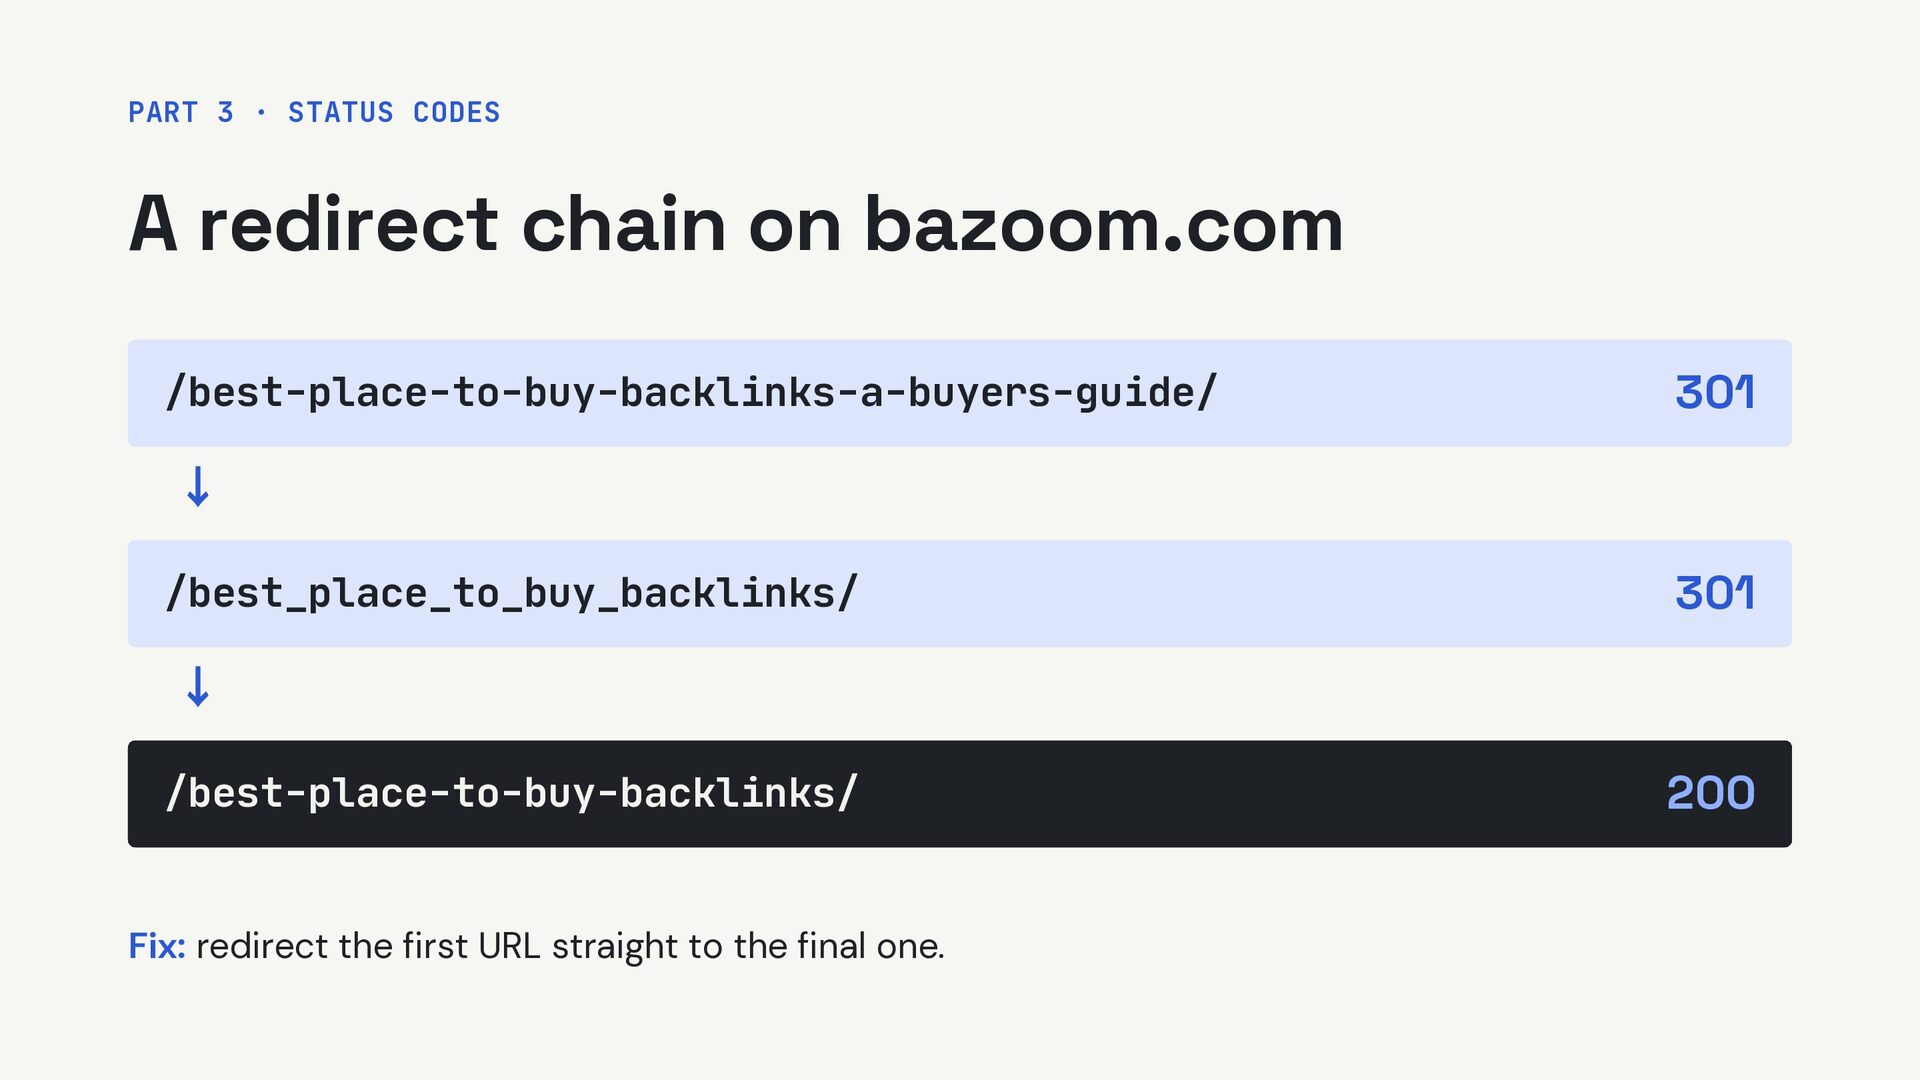
/best-place-to-buy-backlinks-a-buyers-guide/ ↓ /best_place_to_buy_backlinks/ ↓ /best-place-to-buy-backlinks/ Fix: redirect the first URL straight to the final one. 301 301 200
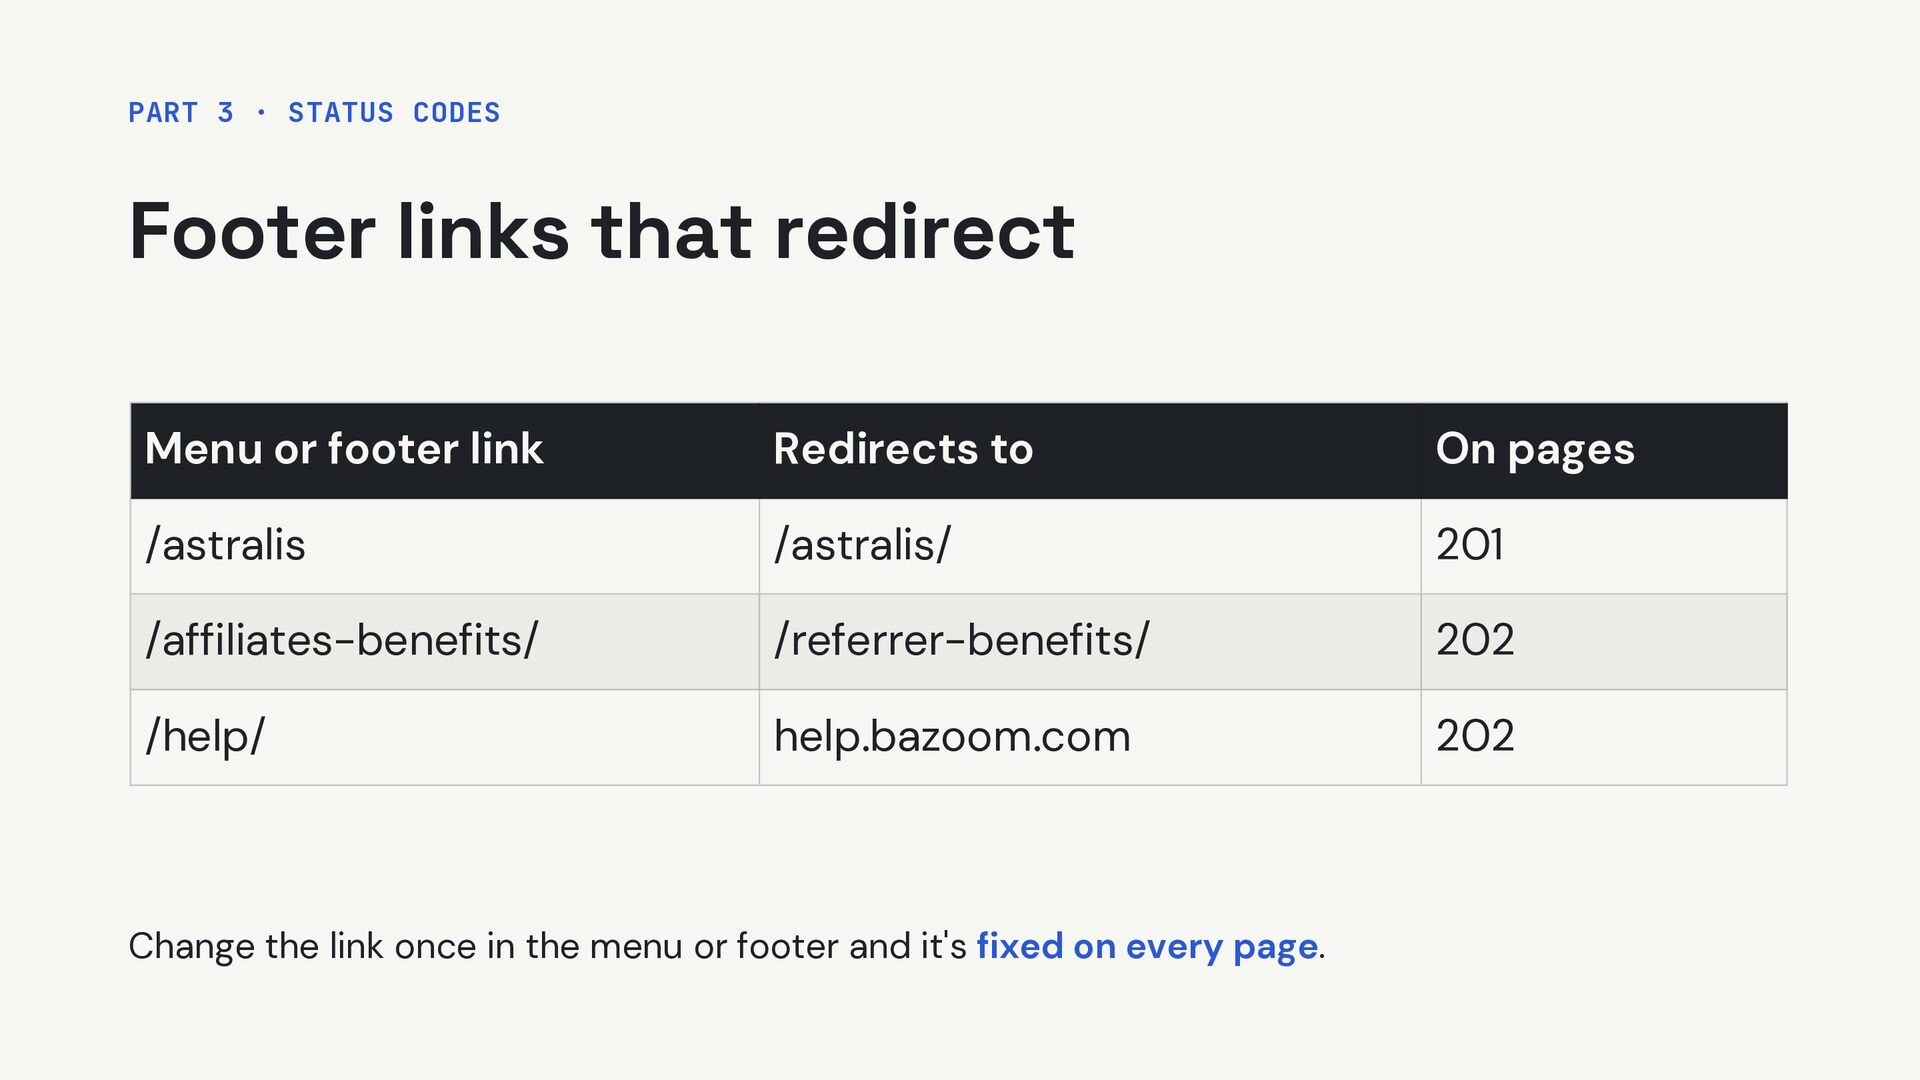
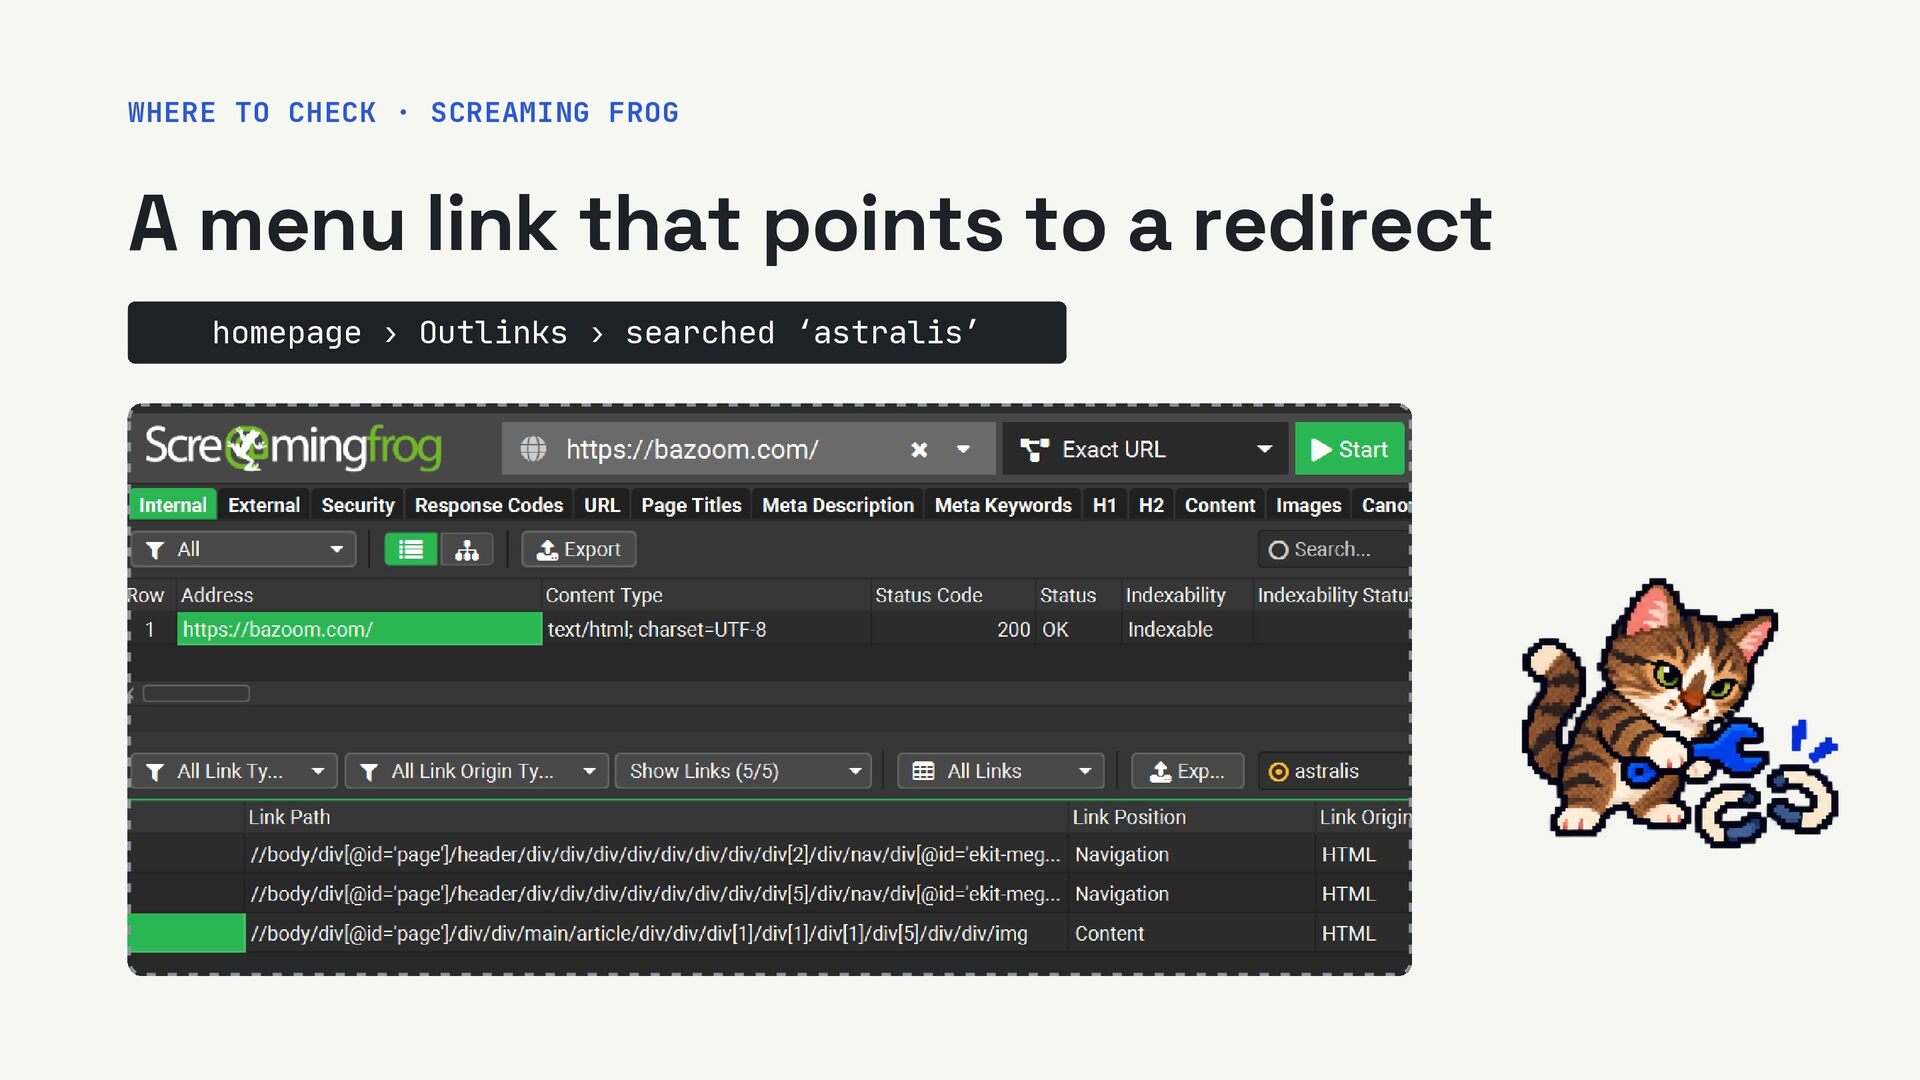
or footer link Redirects to On pages /astralis /astralis/ 201 /affiliates-benefits/ /referrer-benefits/ 202 /help/ help.bazoom.com 202 Change the link once in the menu or footer and it's fixed on every page.
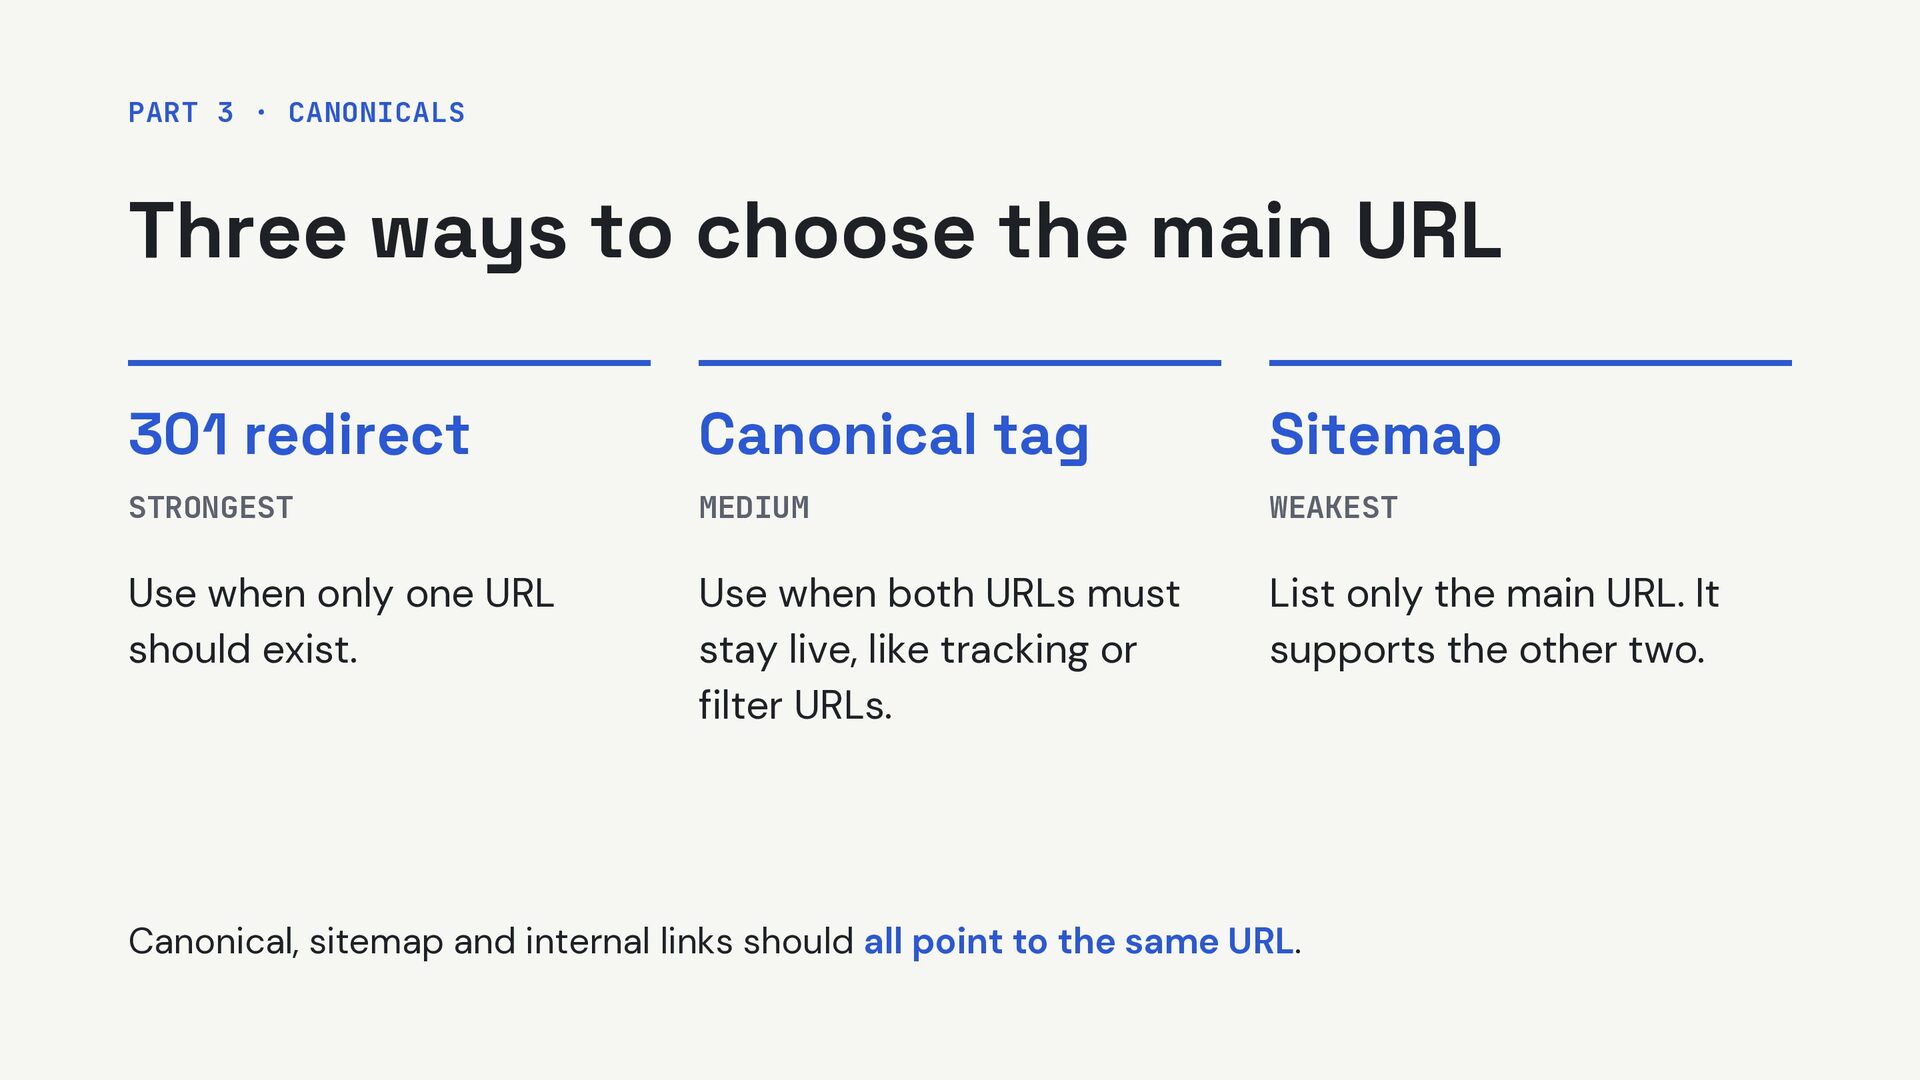
URL 301 redirect Canonical tag Sitemap STRONGEST MEDIUM WEAKEST Use when only one URL should exist. Use when both URLs must stay live, like tracking or filter URLs. List only the main URL. It supports the other two. Canonical, sitemap and internal links should all point to the same URL.
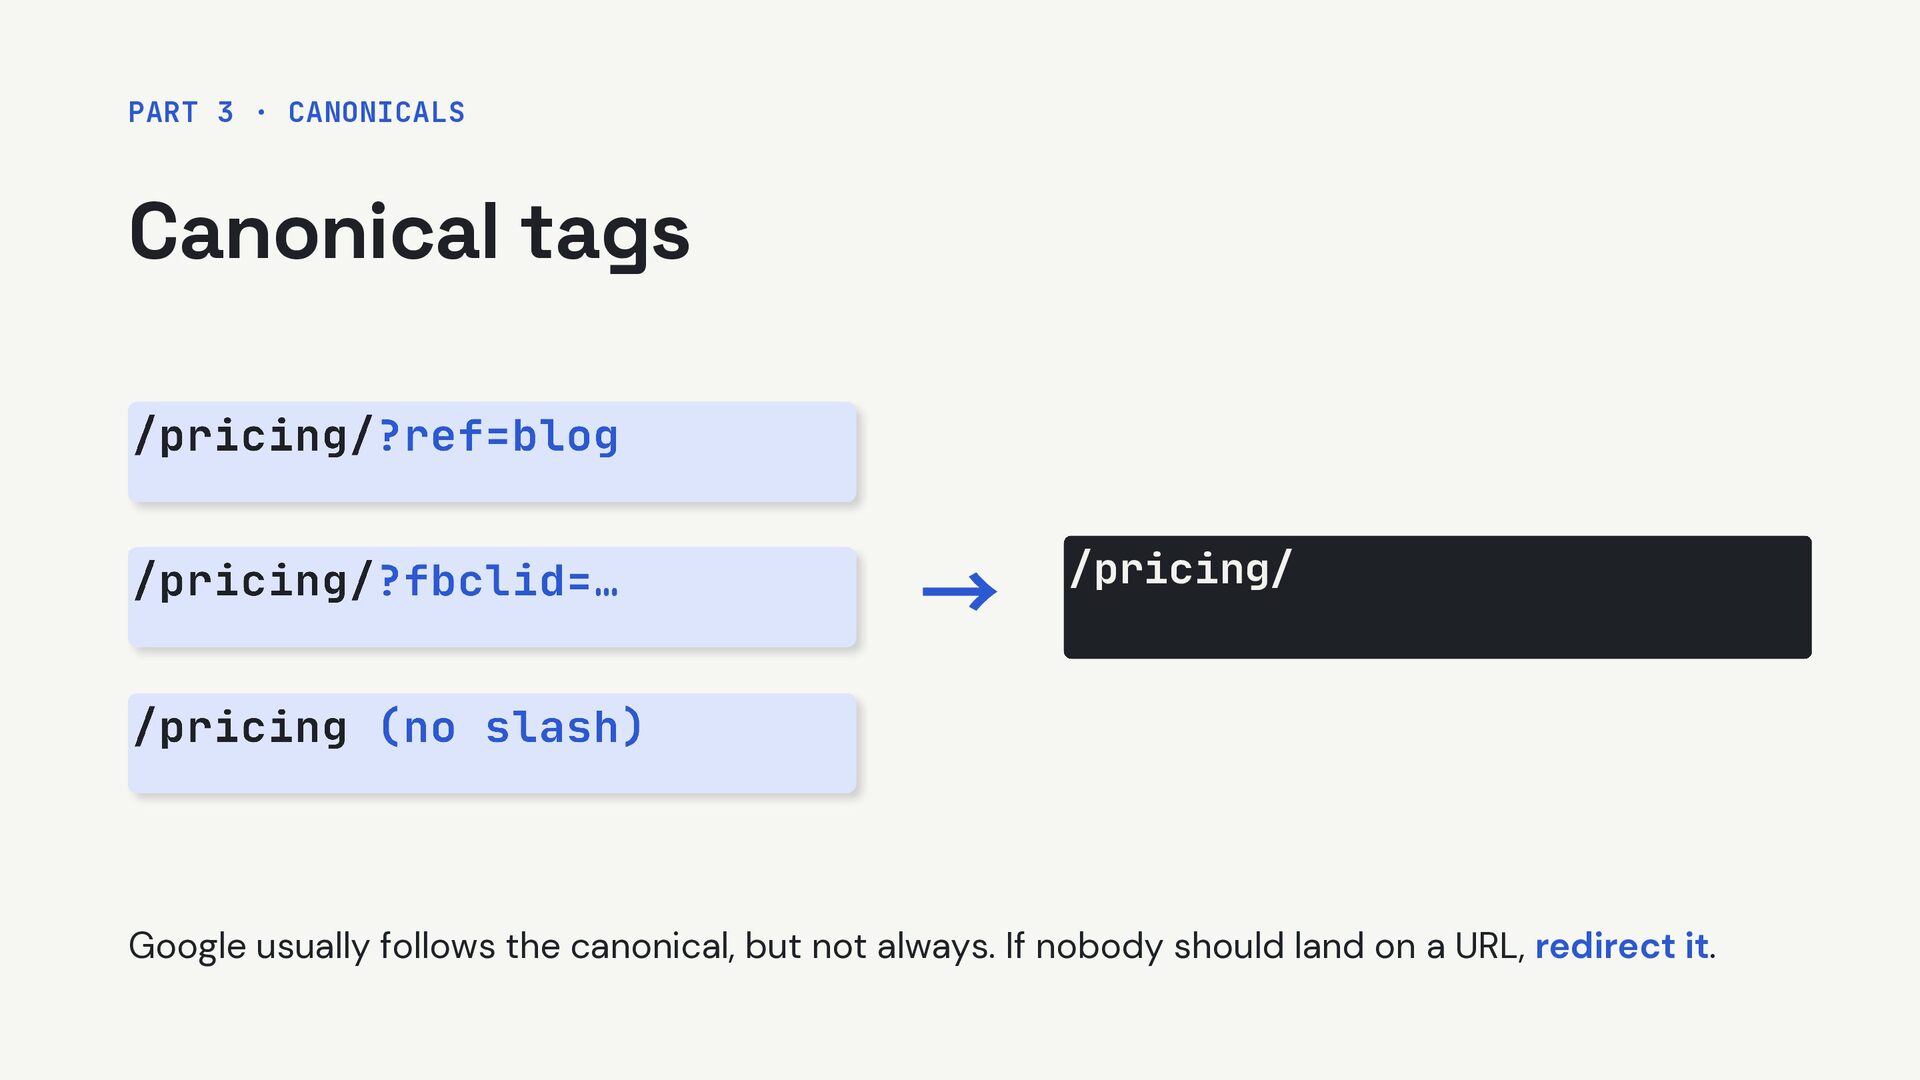
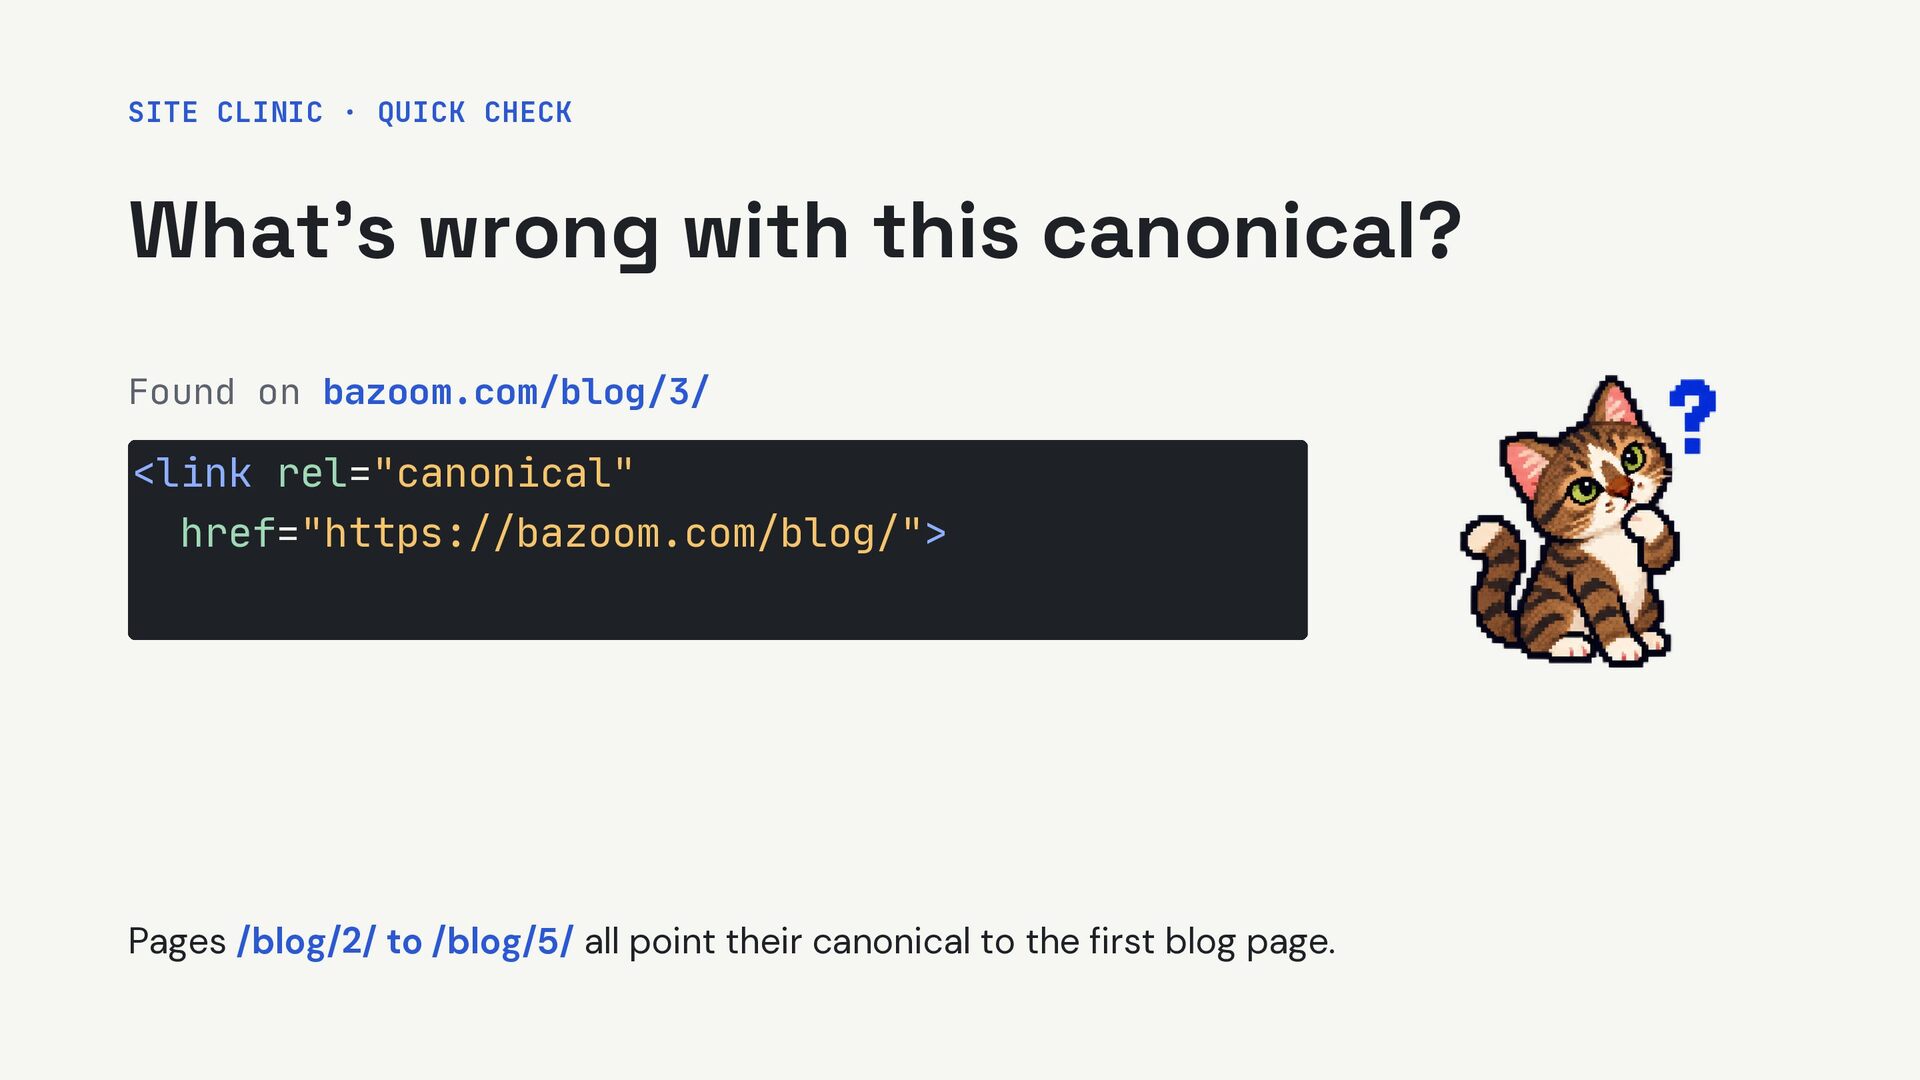
Found on bazoom.com/blog/3/ <link rel="canonical" href="https://bazoom.com/blog/"> Pages /blog/2/ to /blog/5/ all point their canonical to the first blog page.
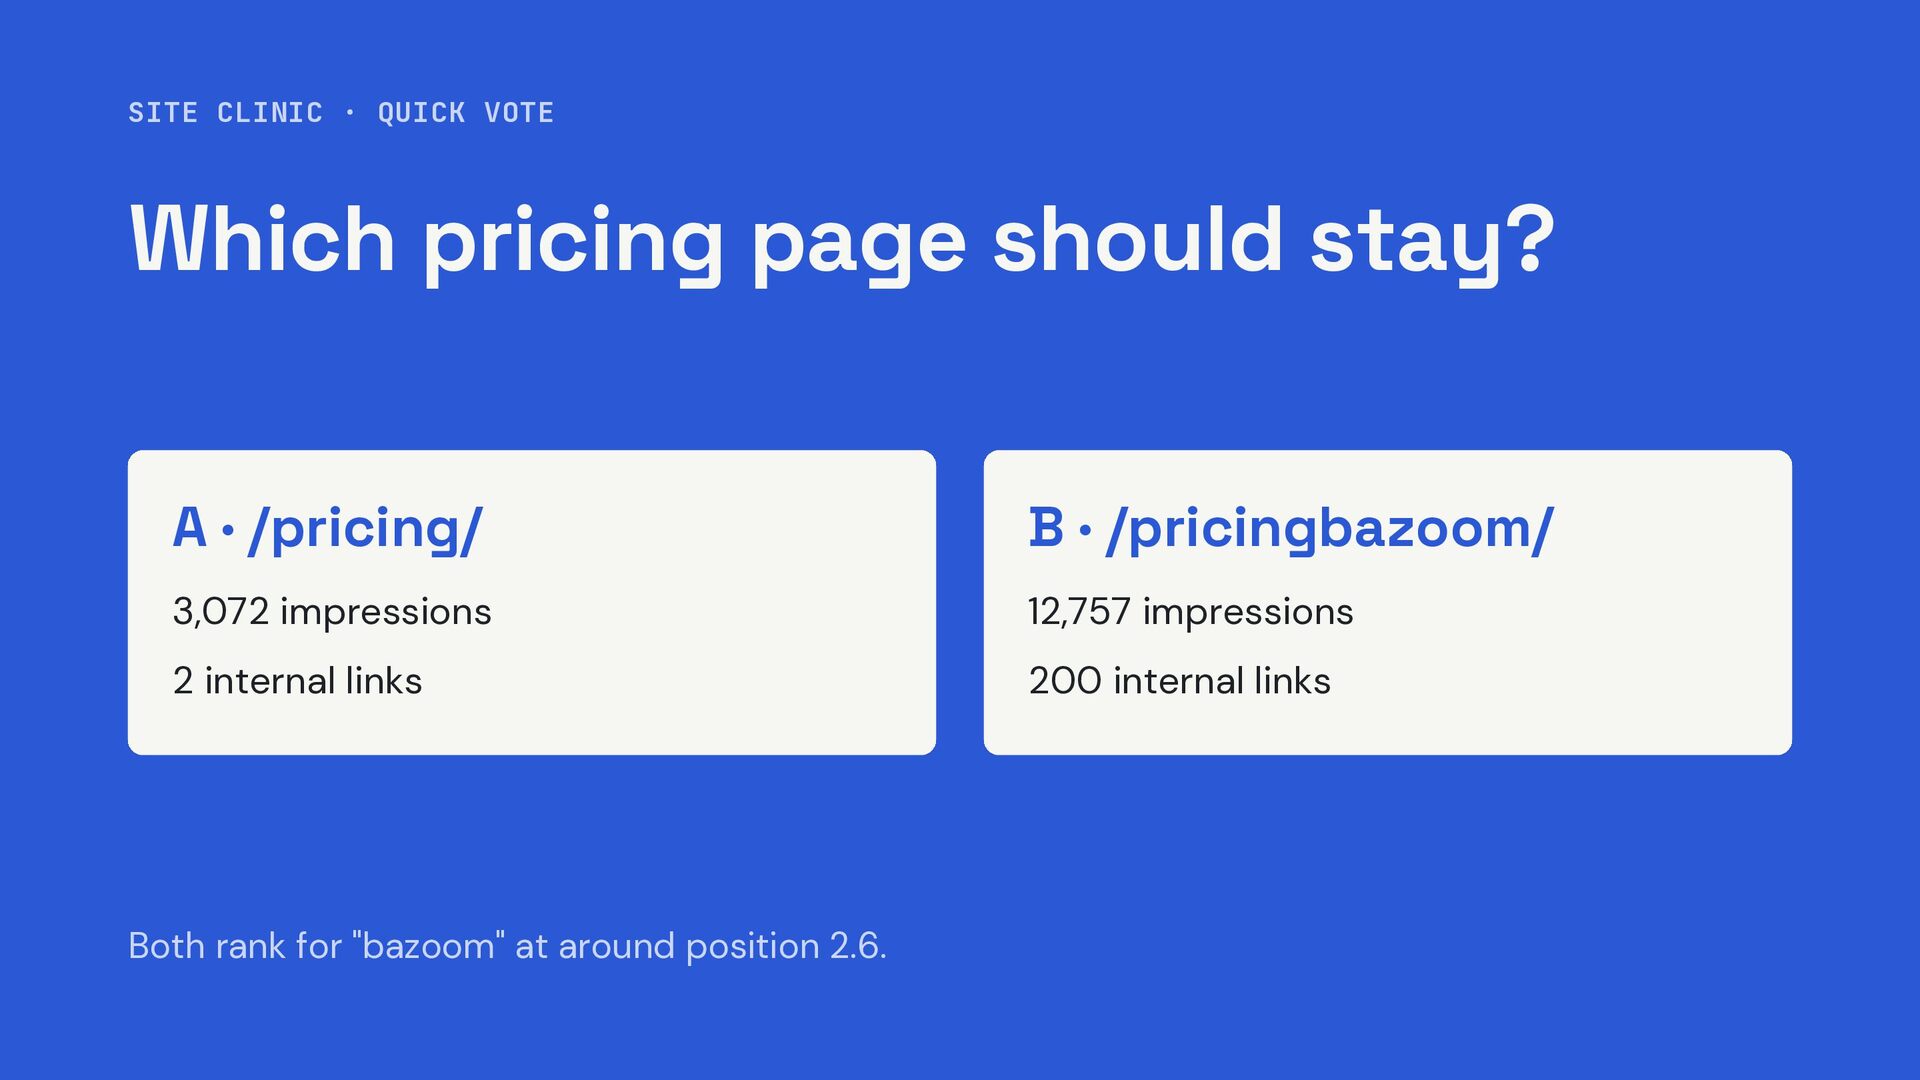
A · /pricing/ B · /pricingbazoom/ 3,072 impressions 12,757 impressions 2 internal links 200 internal links Both rank for "bazoom" at around position 2.6.
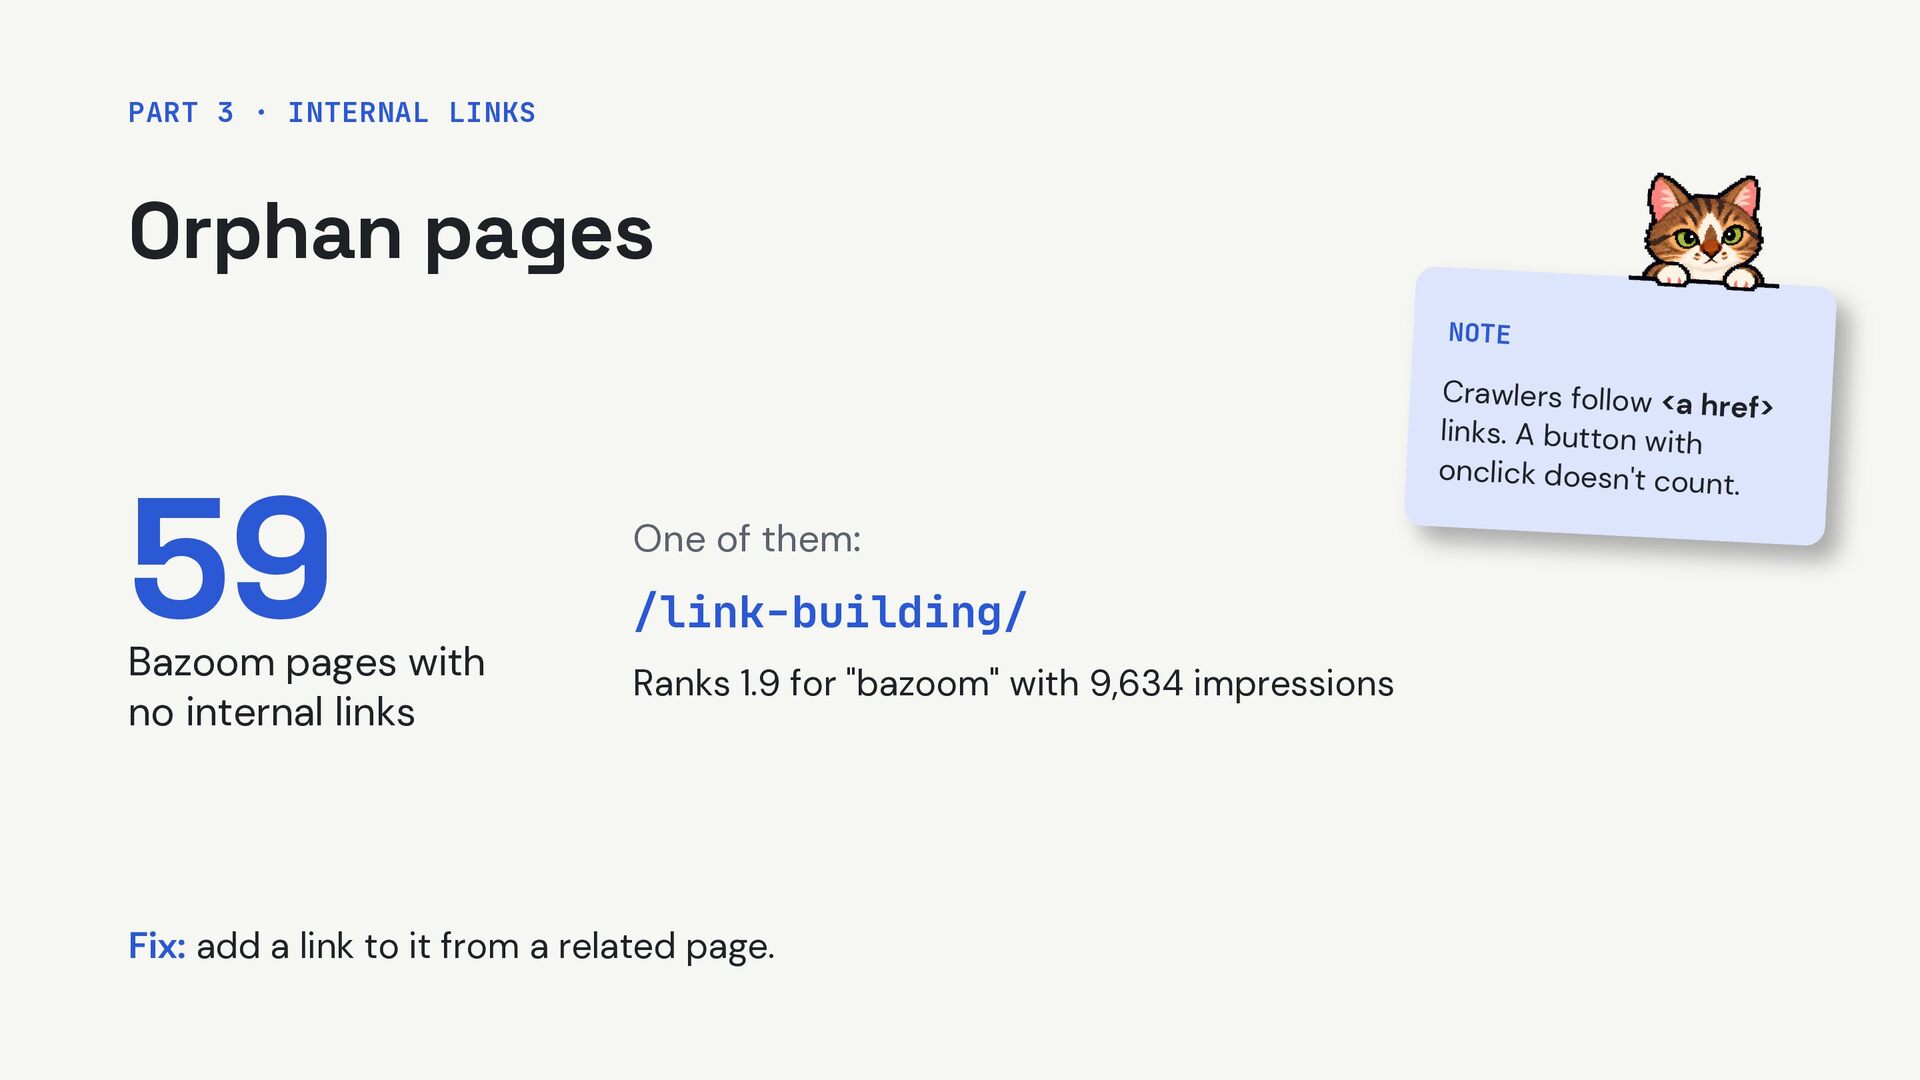
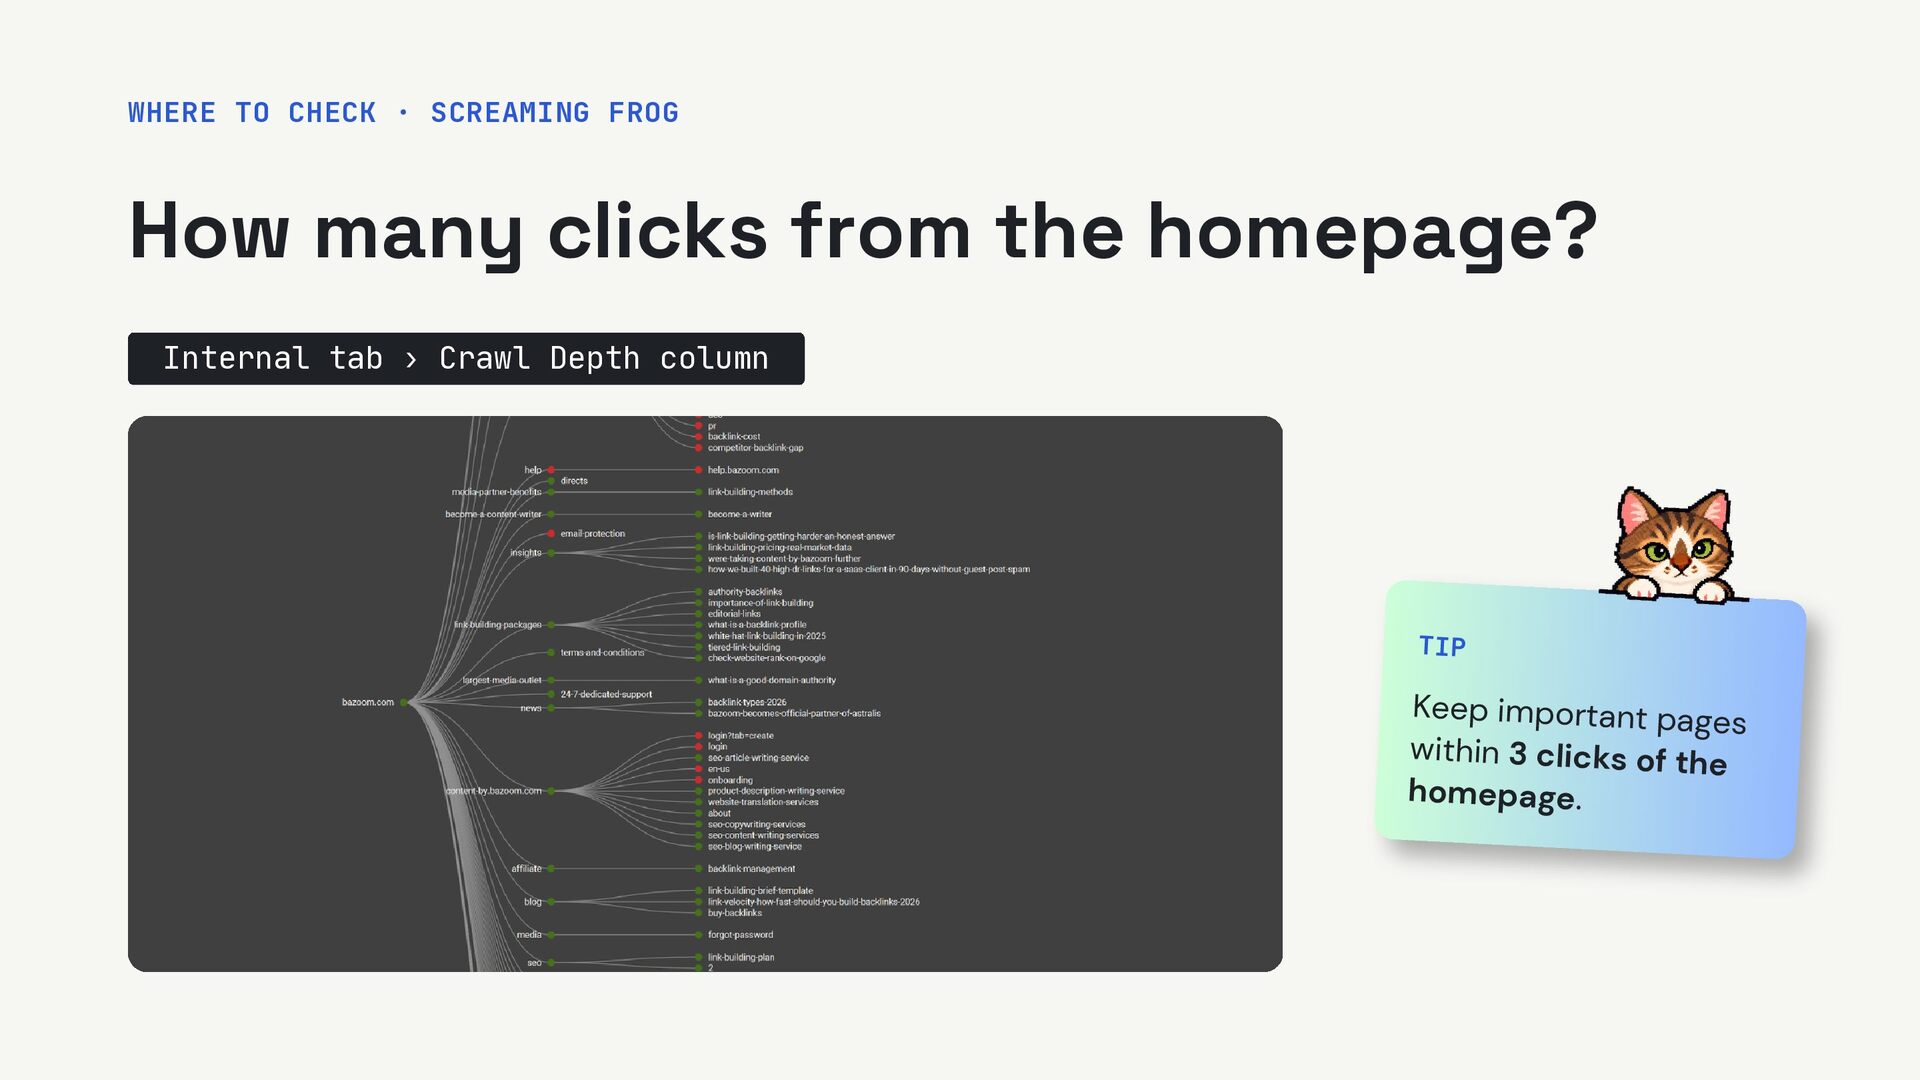
pages with no internal links Crawlers follow <a hre f> links. A button with onclick doesn't count. One of them: /link-building/ Ranks 1.9 for "bazoom" with 9,634 impressions Fix: add a link to it from a related page.
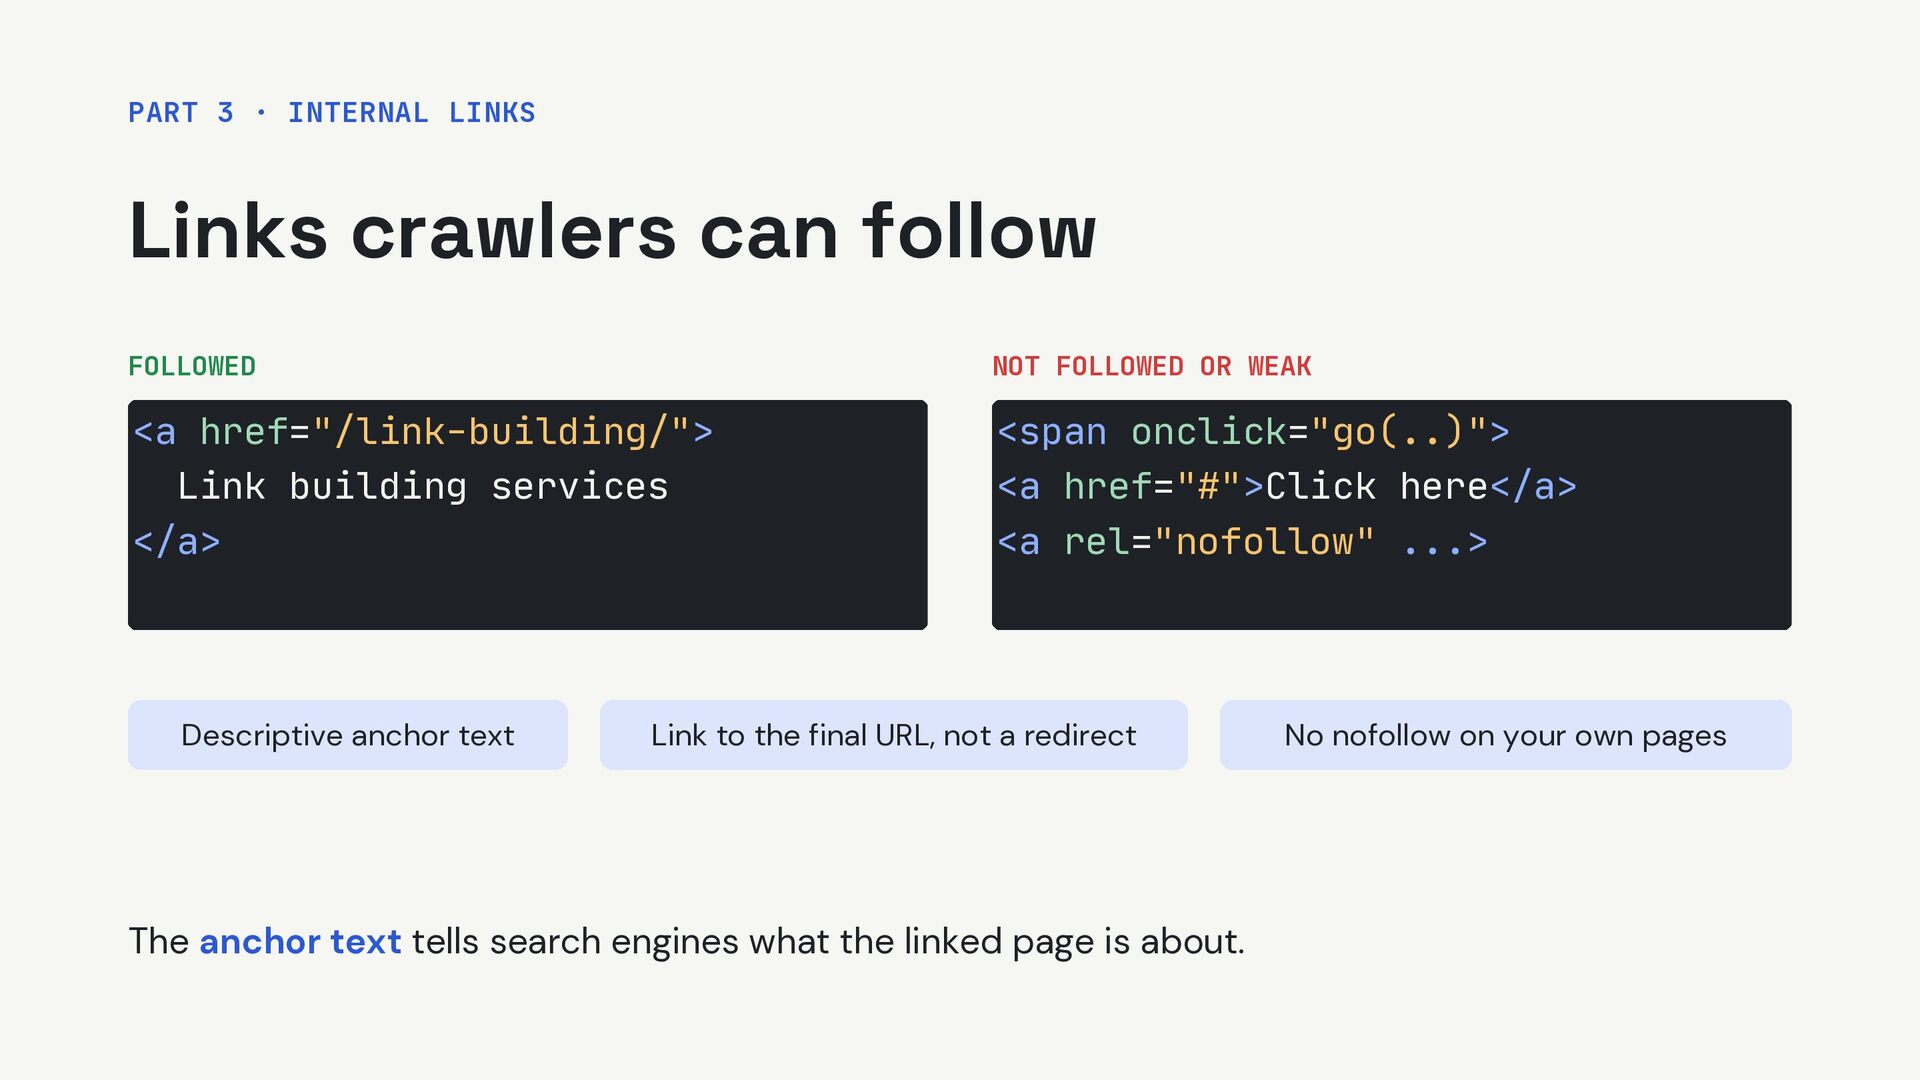
NOT FOLLOWED OR WEAK <a href="/link-building/"> Link building services </a> <span onclick="go(..)"> <a href="#">Click here</a> <a rel="nofollow" ...> Descriptive anchor text Link to the final URL, not a redirect The anchor text tells search engines what the linked page is about. No nofollow on your own pages
HTTPS Same content and links as on desktop http:// redirects to https:// Menu and text work on a phone Internal links use https:// Bazoom still has 44 internal links that use http://.
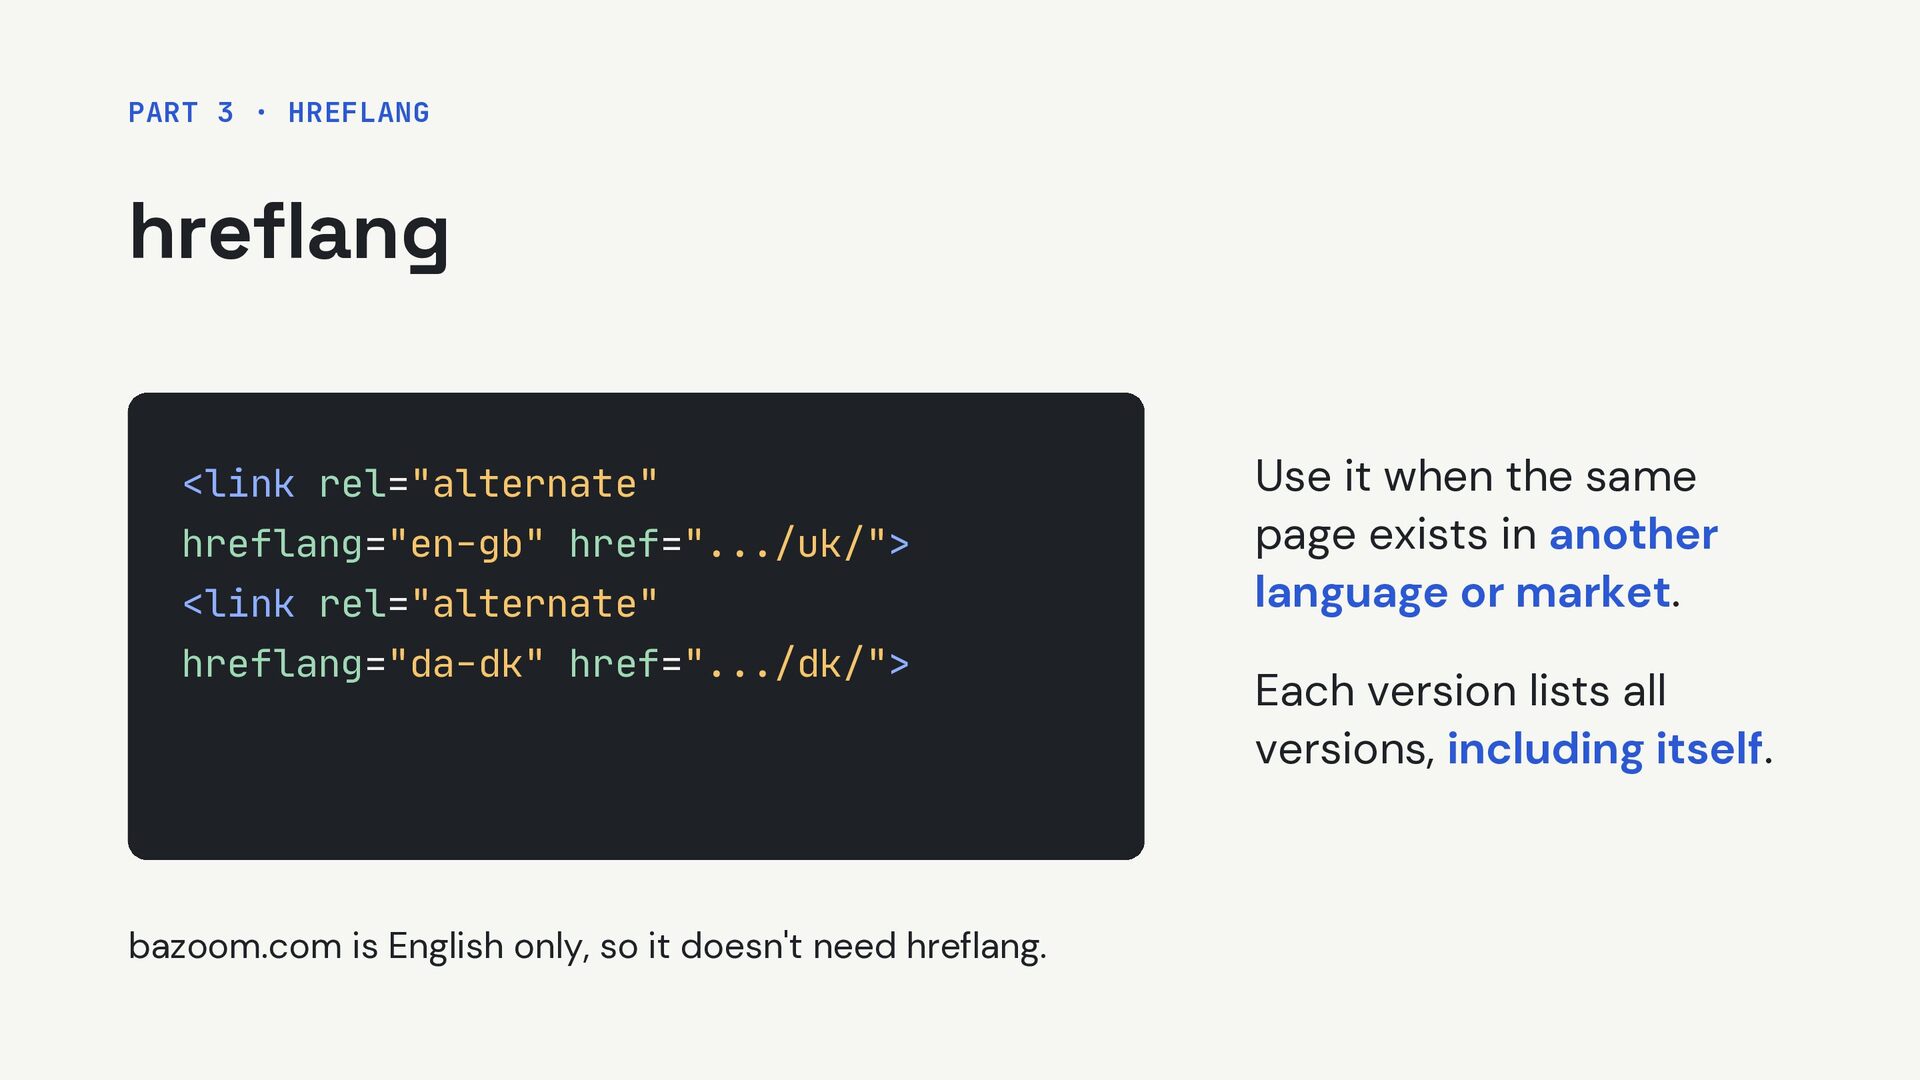
rel="alternate" hreflang="da-dk" href=".../dk/"> bazoom.com is English only, so it doesn't need hreflang. Use it when the same page exists in another language or market. Each version lists all versions, including itself.
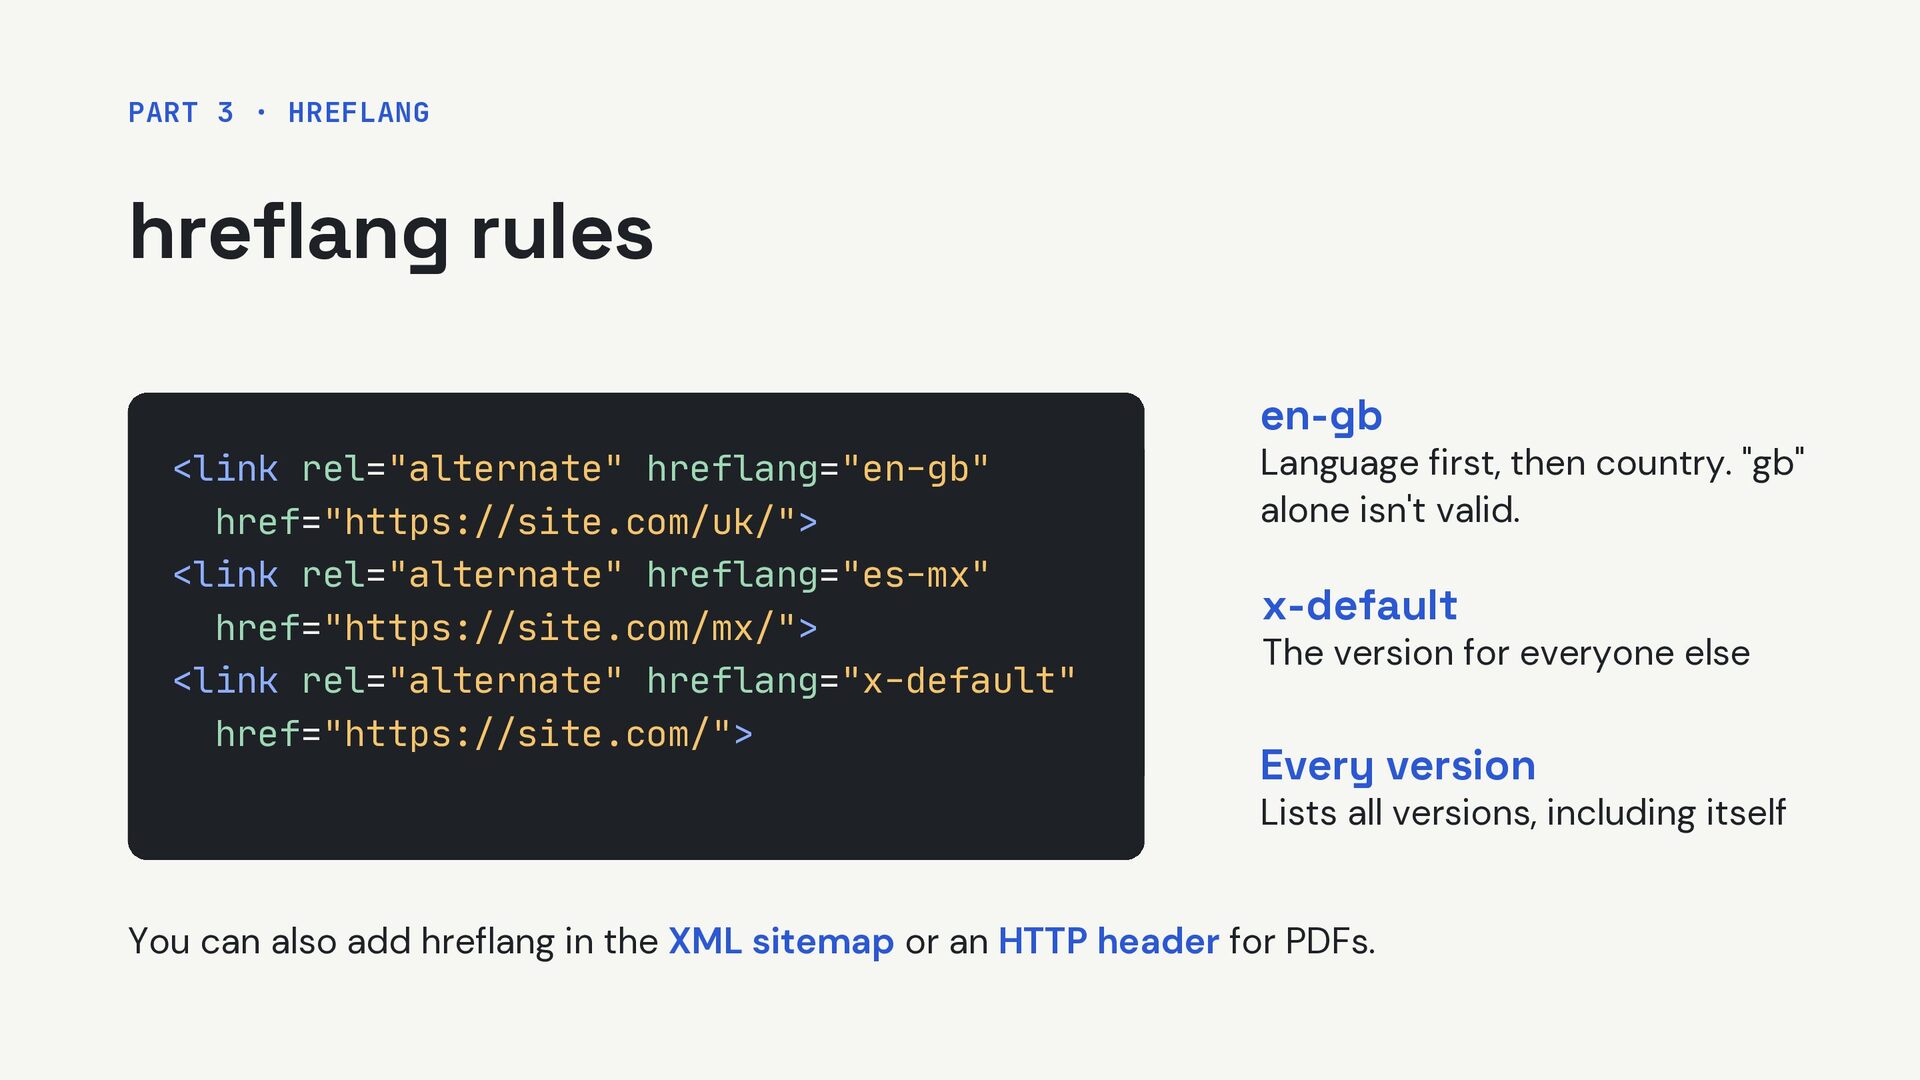
href="https://site.com/uk/"> <link rel="alternate" hreflang="es-mx" href="https://site.com/mx/"> <link rel="alternate" hreflang="x-default" href="https://site.com/"> Language first, then country. "gb" alone isn't valid. x-default The version for everyone else Every version Lists all versions, including itself You can also add hreflang in the XML sitemap or an HTTP header for PDFs.
normal index To appear in AI Overviews or AI Mode, a page has to be indexed and allowed to show a snippet. There's no extra file or markup you need for this. 😉
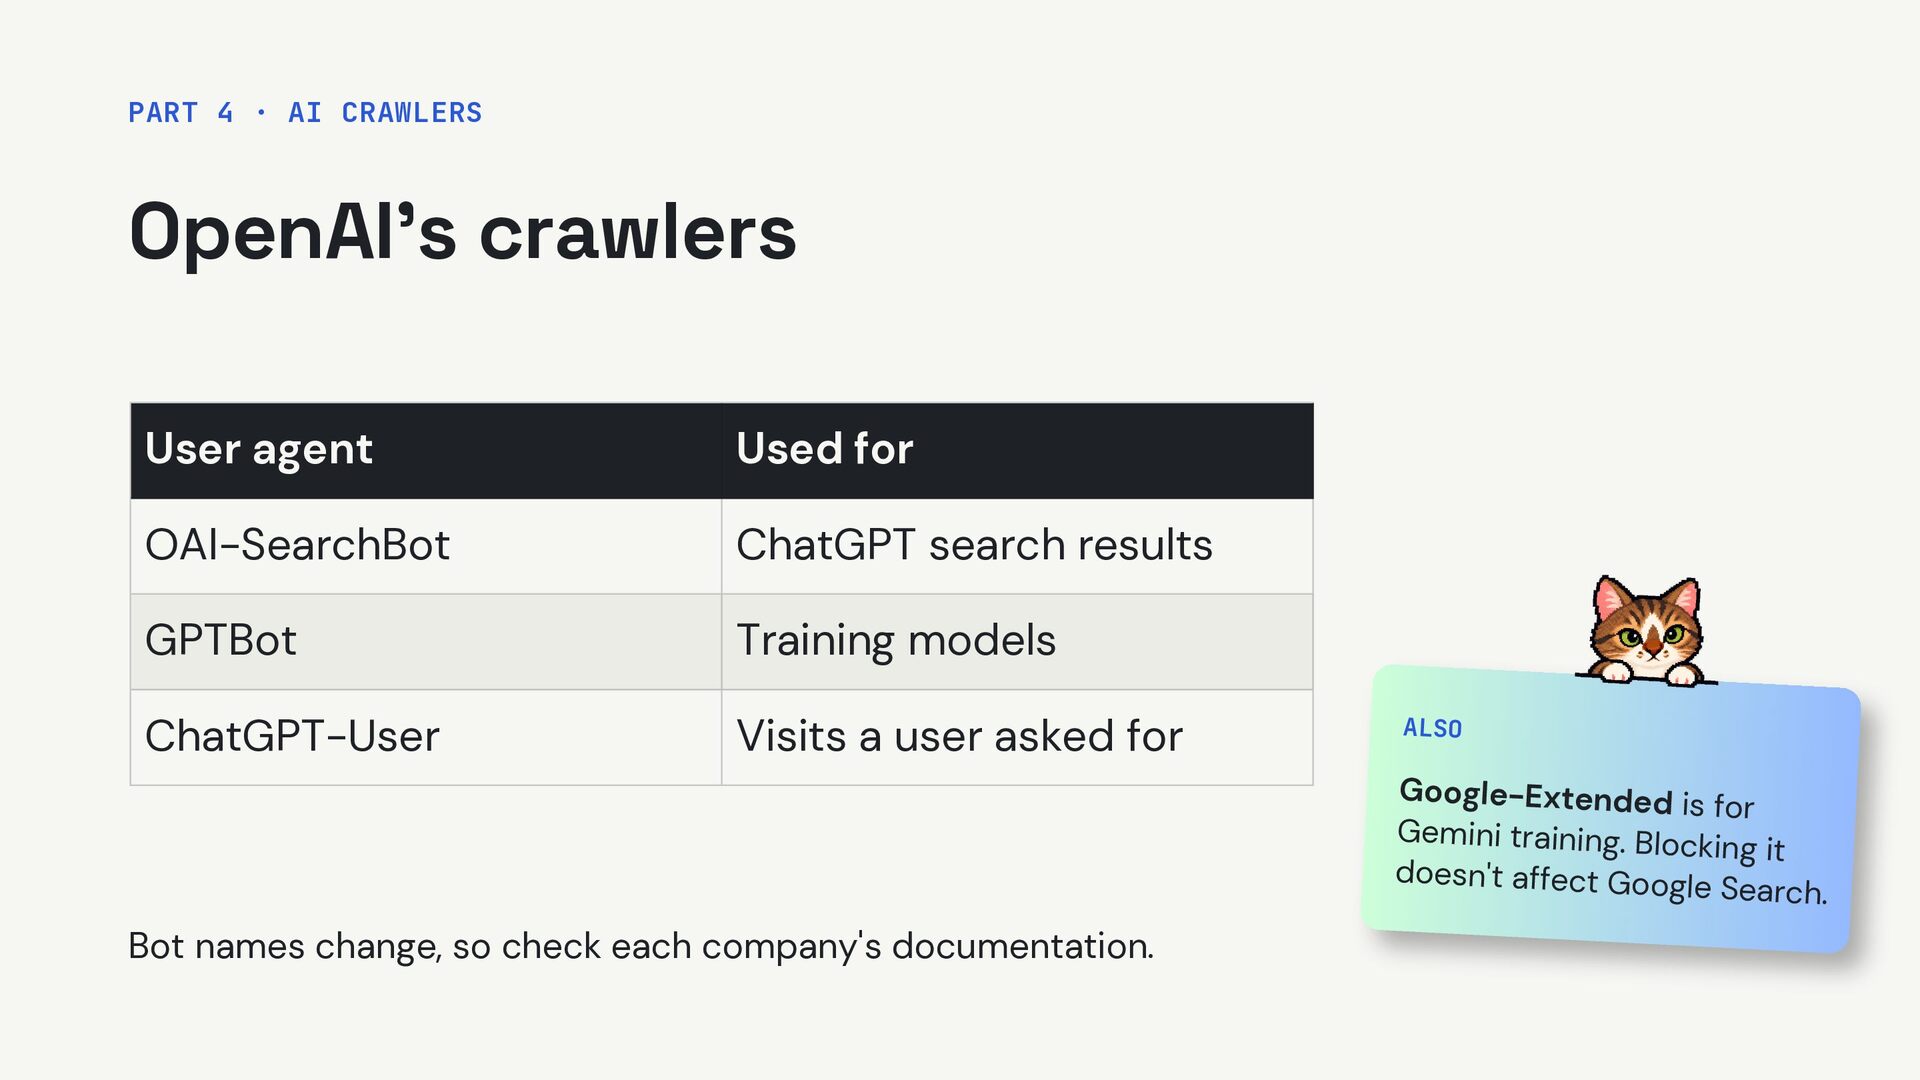
for OAI-SearchBot ChatGPT search results GPTBot Training models ChatGPT-User Visits a user asked for ALSO Google-Extended is for Gemini training. Block ing it doesn't affect Google Search. Bot names change, so check each company's documentation.
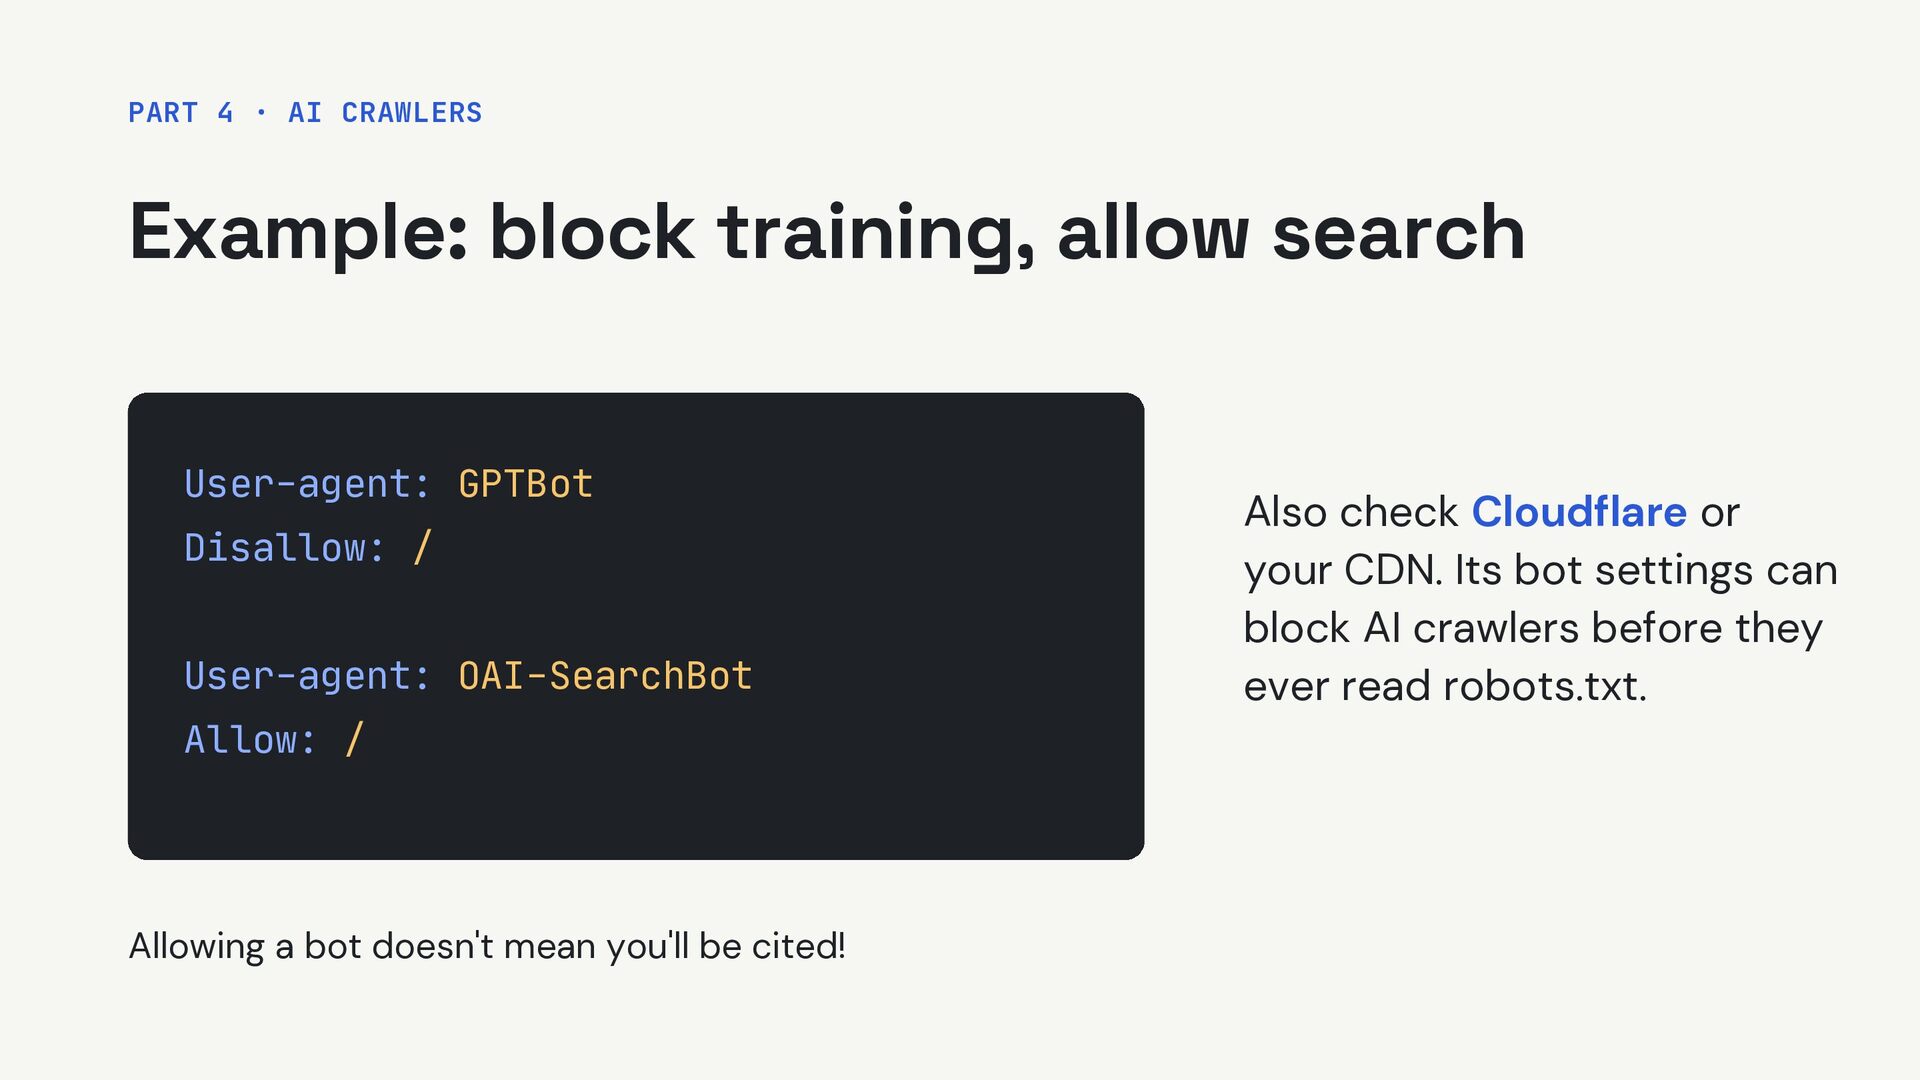
User-agent: GPTBot Disallow: / User-agent: OAI-SearchBot Allow: / Allowing a bot doesn't mean you'll be cited! Also check Cloudflare or your CDN. Its bot settings can block AI crawlers before they ever read robots.txt.
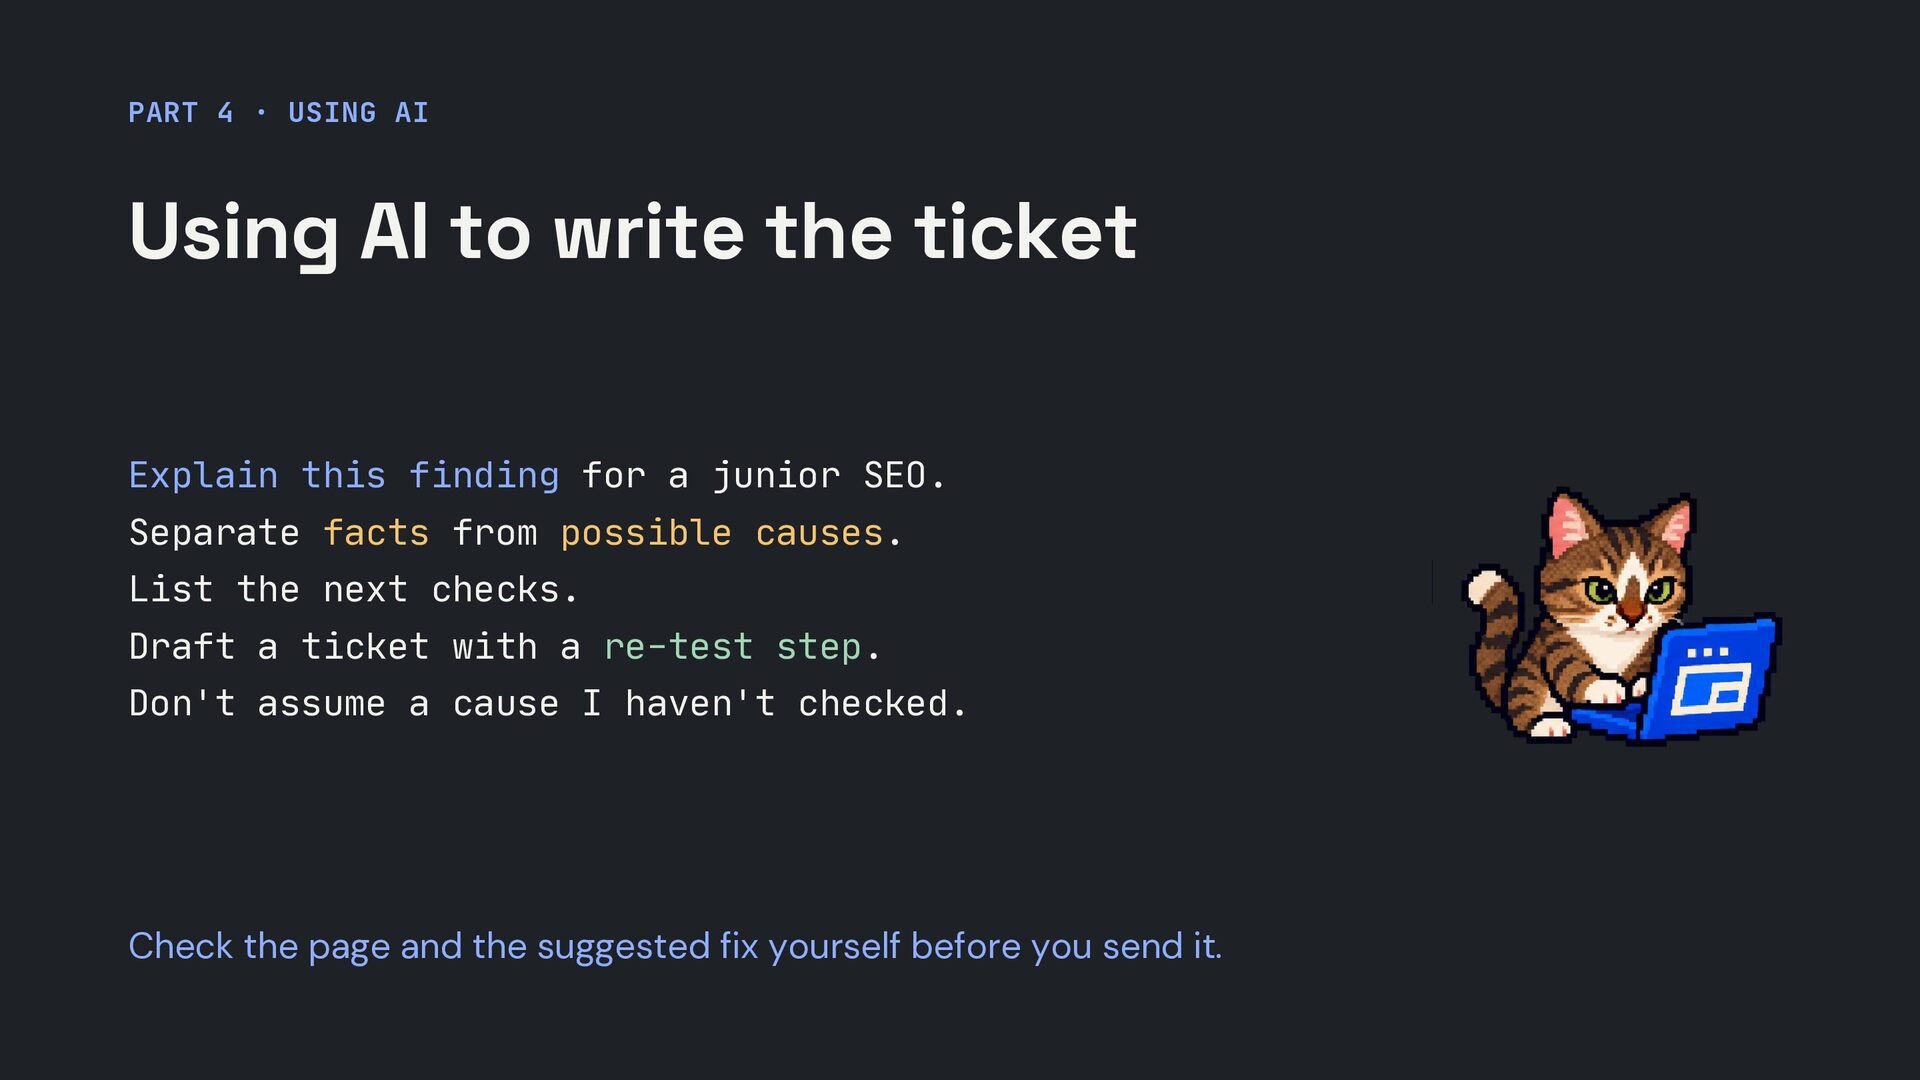
ticket Explain this finding for a junior SEO. Separate facts from possible causes. List the next checks. Draft a ticket with a re-test step. Don't assume a cause I haven't checked. Check the page and the suggested fix yourself before you send it.
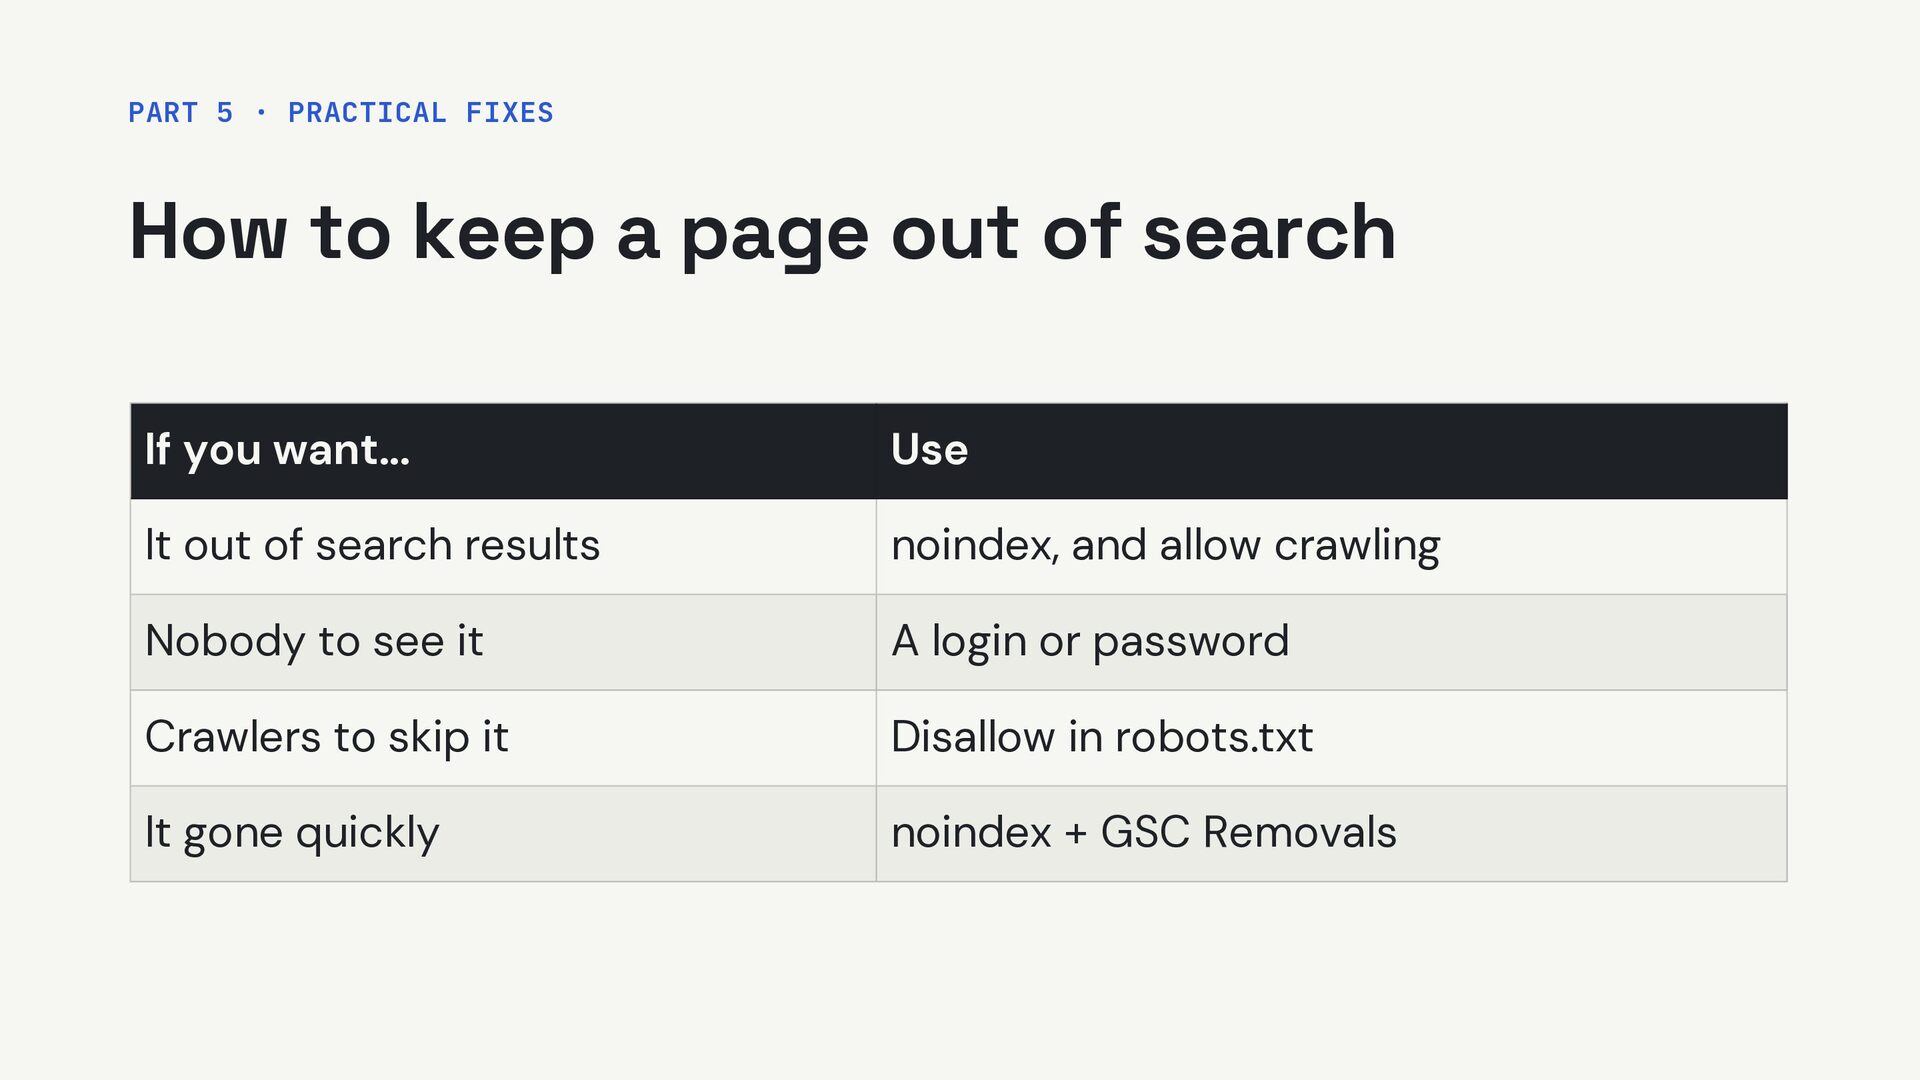
out of search If you want... Use It out of search results noindex, and allow crawling Nobody to see it A login or password Crawlers to skip it Disallow in robots.txt It gone quickly noindex + GSC Removals
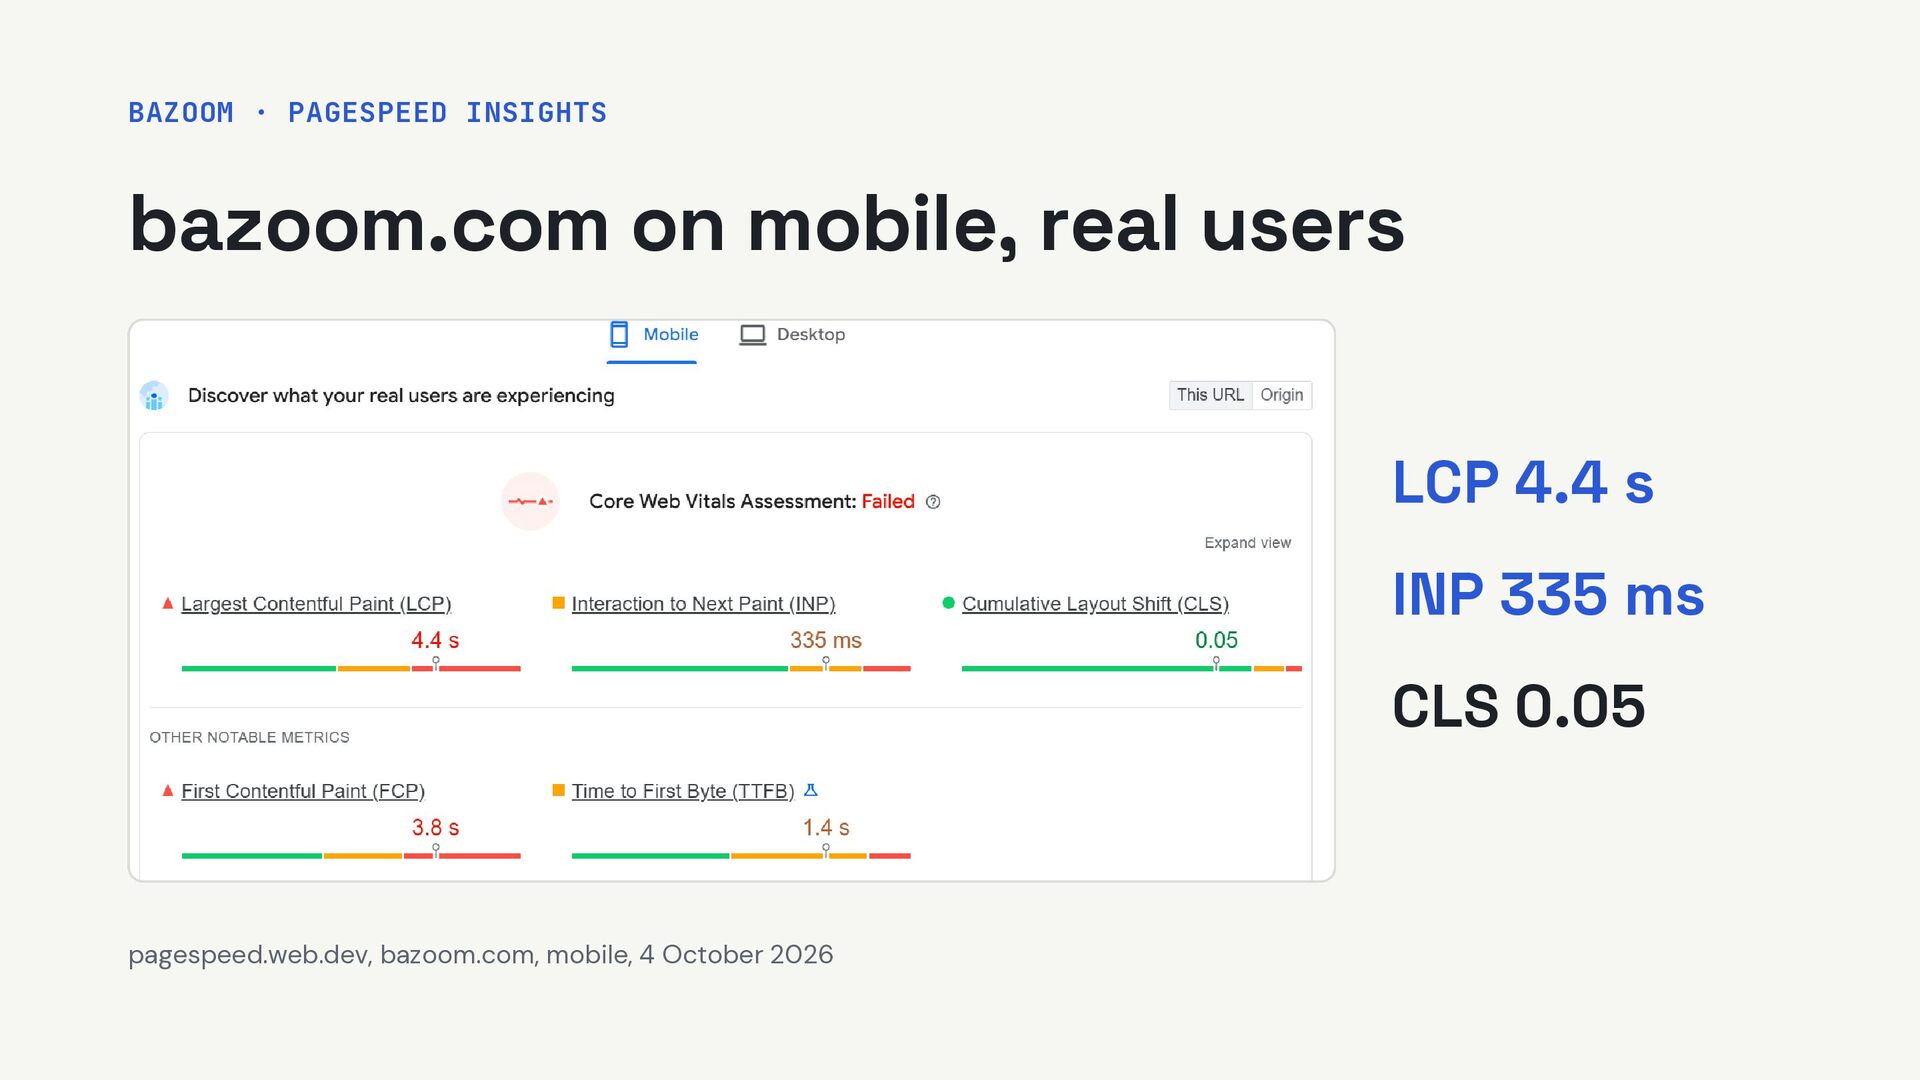
Crawling Mondays · Aleyda's video tips Google Search Central · the source docs Screaming Frog user guide · every tab explained Core Updates · Mark Williams-Cook's newsletter Gus Pelogia on SEL · tickets, testing, product Bazoom data: Ahrefs Site Audit 1 Oct 2026, Search Console Jul to Oct 2026, PageSpeed Insights 4 Oct 2026 Search Central Live Deep Dive 2026, latest Google insights on Crawling, Rendering and Indexing


 tamaranovitovic
 samtorres
 chrisleverseo
 tasky_ai
 giuliapanozzo
 metehanyesilyurt
 athenseo
 cargoodrich
 samanyougarg
 c_j_ridley
 kevinki
 pelogia
 joshbly
 kimpetersen
 lindahogenes
 nwiizo
 eileencodes
 jacobian
 axbom
 addyosmani
 ryanjones
 sugarenia
 katarinadahlin
 tonyrice