Share
Embed
Scale-out ccNUMA [EuroSys'18]
These are the slides from eurosys'18 talk of paper
"Scale-Out ccNUMA: Exploiting Skew with Strongly Consistent Caching"
paper link: http://homepages.inf.ed.ac.uk/vnagaraj/papers/eurosys18.pdf
Antonios Katsarakis
April 23, 2018
Transcript
47 slides
-
Scale-Out ccNUMA: Exploiting Skew with Strongly Consistent Caching Antonios Katsarakis*,
Vasilis Gavrielatos*, A. Joshi, N. Oswald, B. Grot, V. Nagarajan The University of Edinburgh This work was supported by EPSRC, ARM and Microsoft through their PhD Fellowship Programs *The first two authors equally contribute to this work -
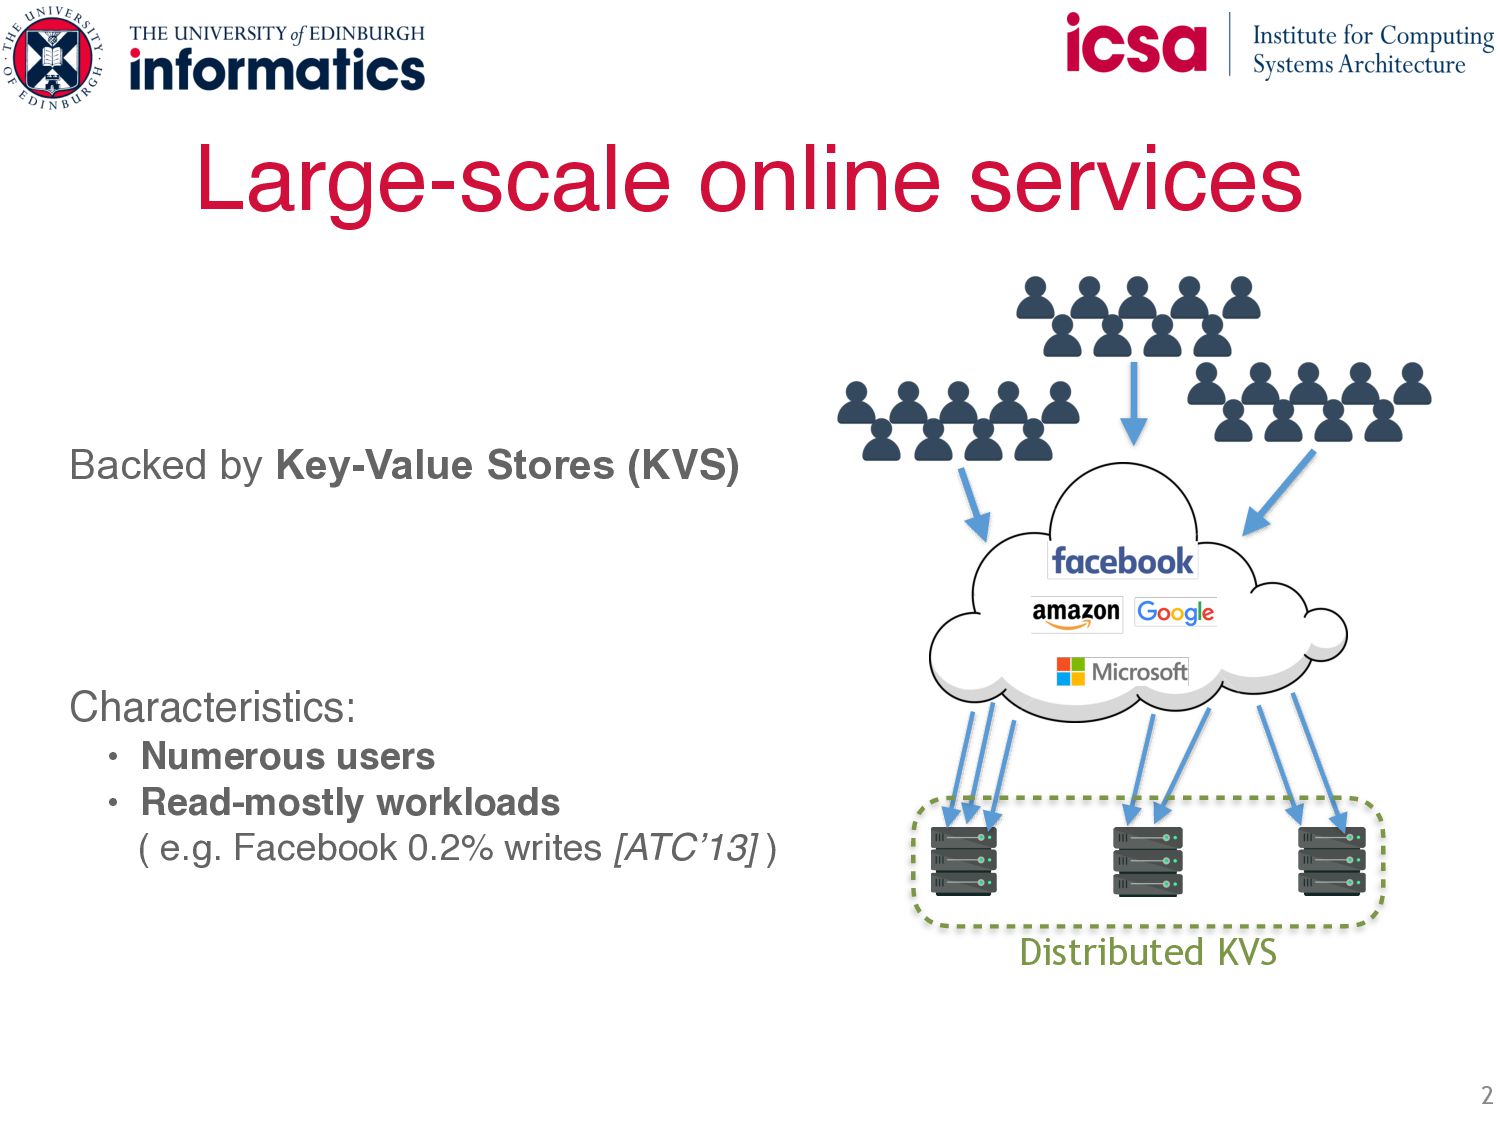
Large-scale online services 2 Backed by Key-Value Stores (KVS) Characteristics:
• Numerous users • Read-mostly workloads ( e.g. Facebook 0.2% writes [ATC’13] ) Distributed KVS -
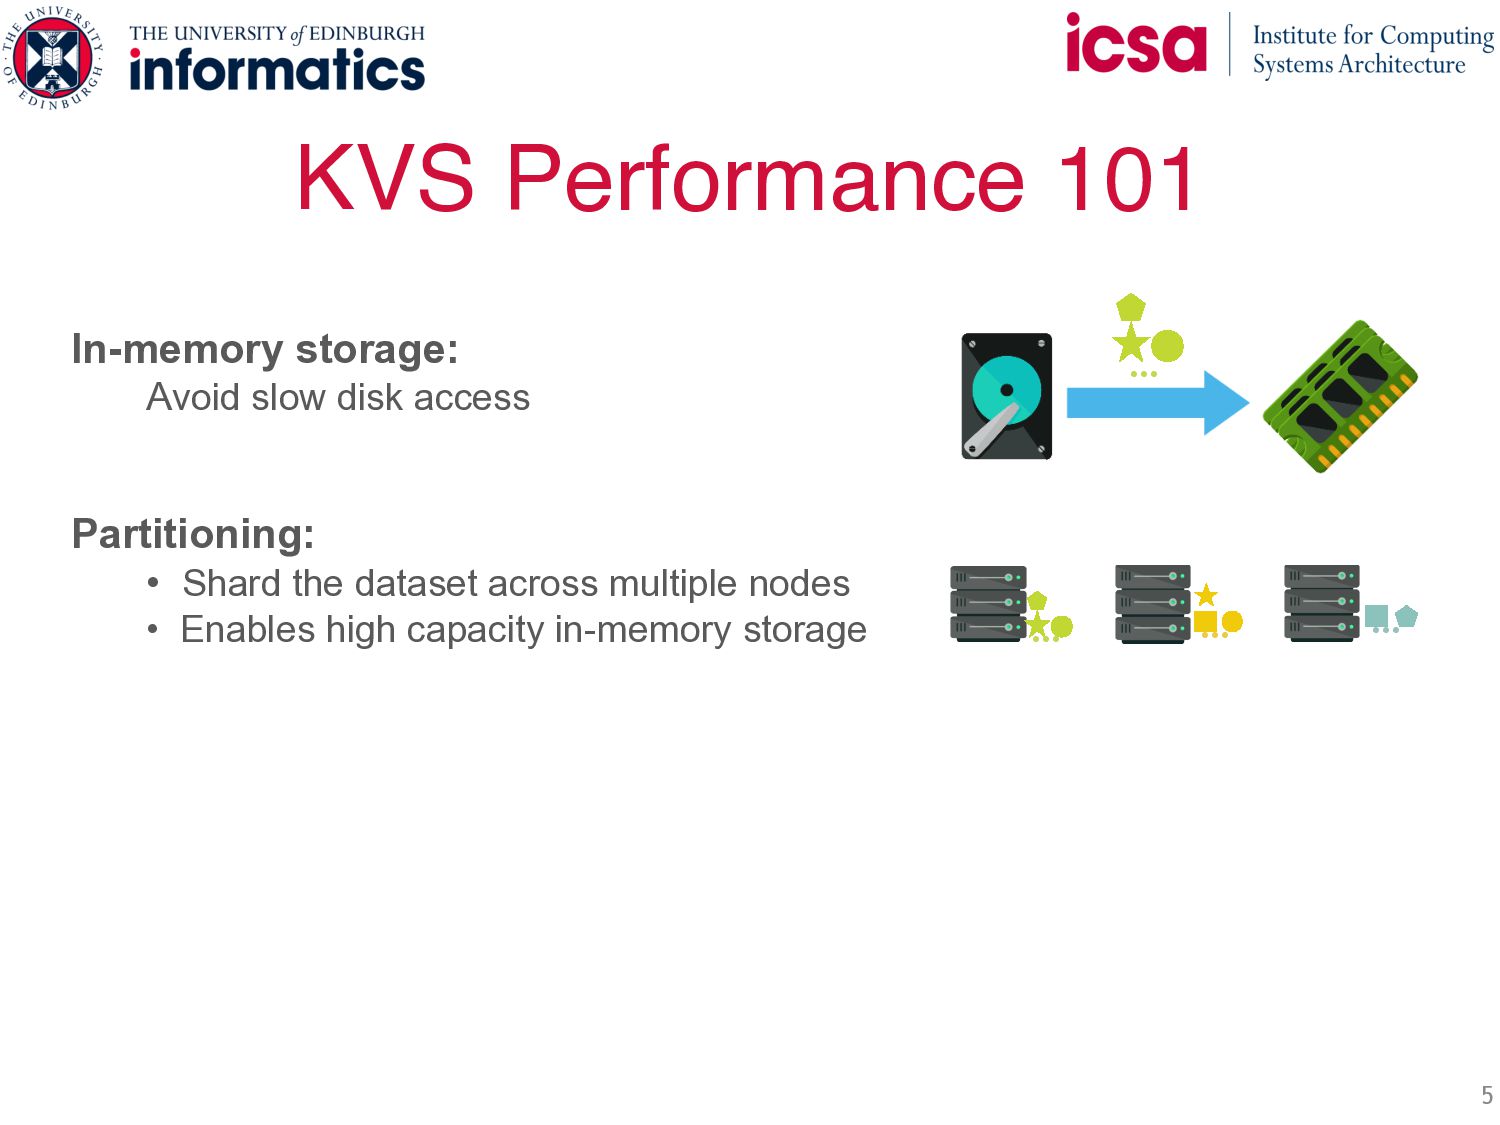
… … … … KVS Performance 101 5 In-memory storage:
Avoid slow disk access Partitioning: • Shard the dataset across multiple nodes • Enables high capacity in-memory storage -
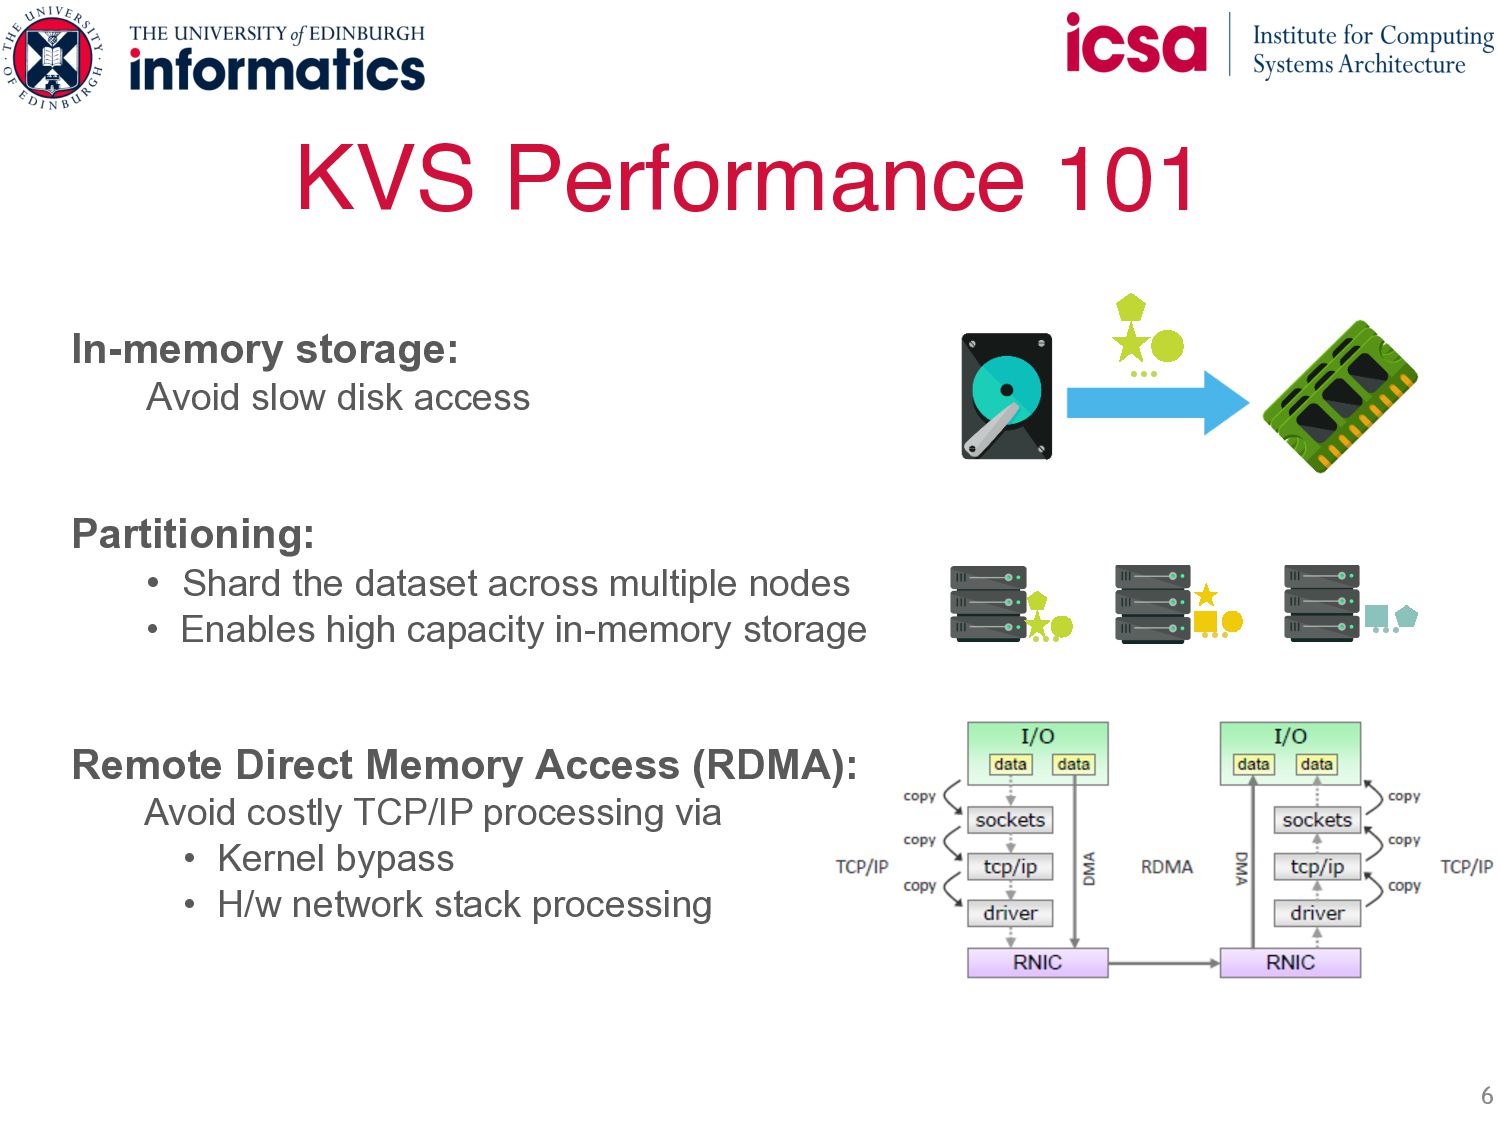
… … … … KVS Performance 101 6 In-memory storage:
Avoid slow disk access Partitioning: • Shard the dataset across multiple nodes • Enables high capacity in-memory storage Remote Direct Memory Access (RDMA): Avoid costly TCP/IP processing via • Kernel bypass • H/w network stack processing -
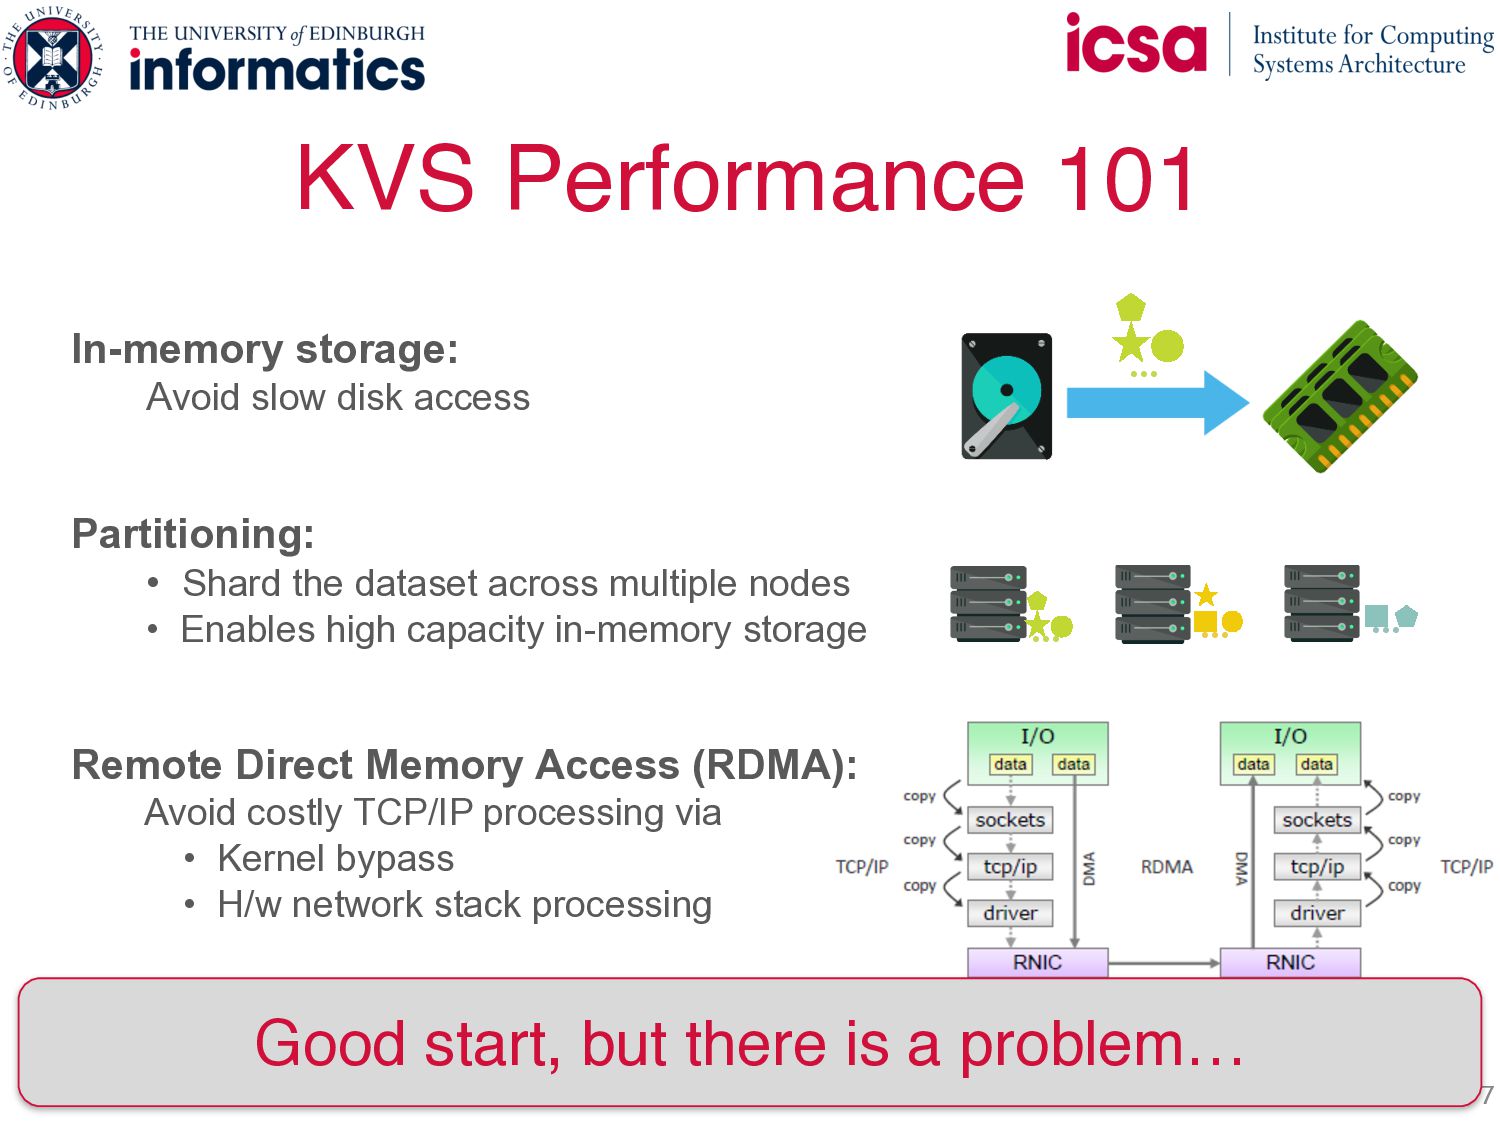
… … … … KVS Performance 101 7 In-memory storage:
Avoid slow disk access Partitioning: • Shard the dataset across multiple nodes • Enables high capacity in-memory storage Remote Direct Memory Access (RDMA): Avoid costly TCP/IP processing via • Kernel bypass • H/w network stack processing Good start, but there is a problem… -
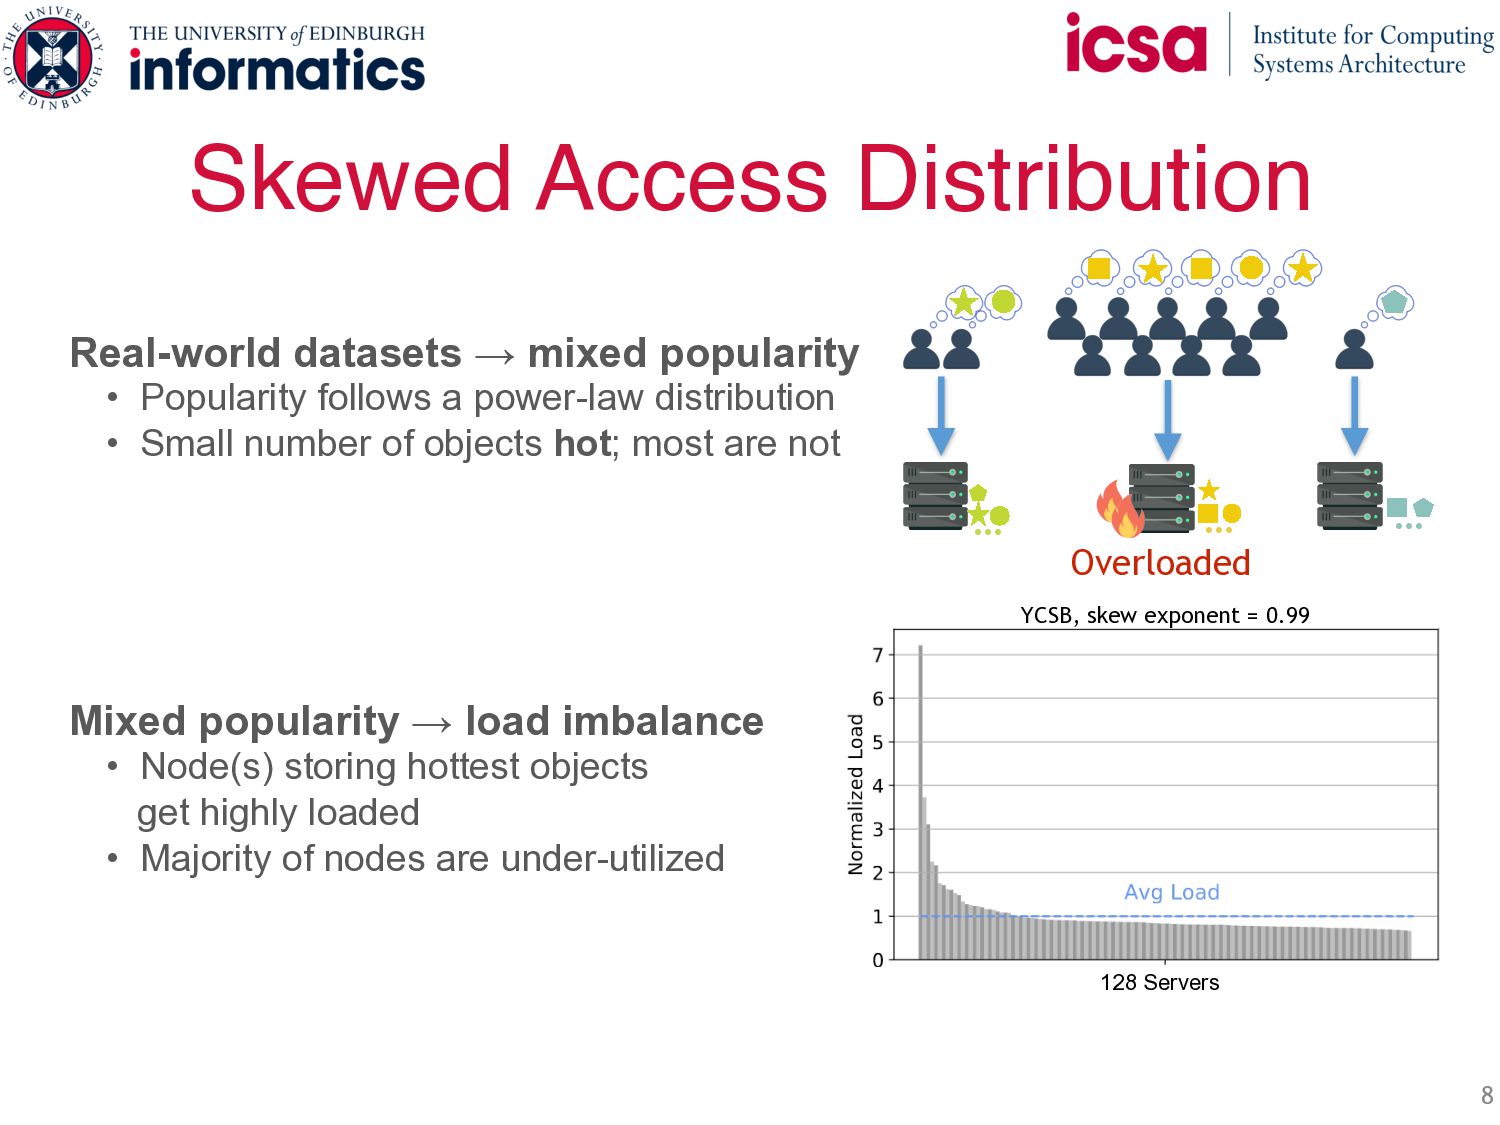
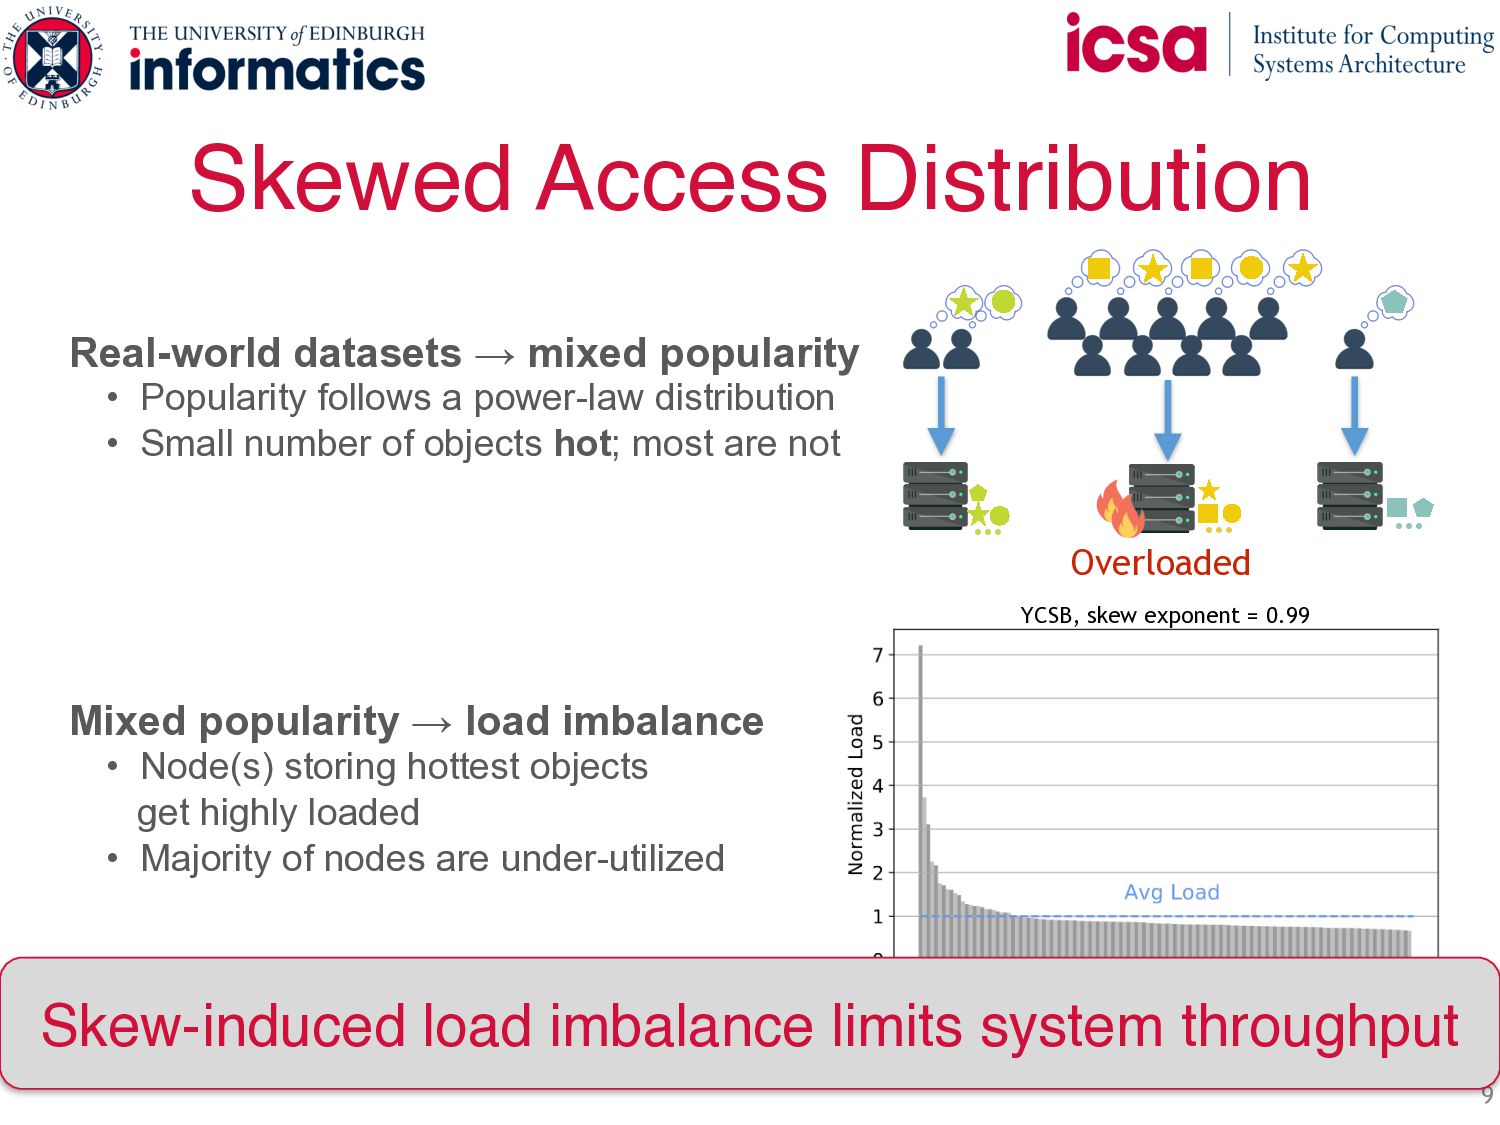
Skewed Access Distribution 8 Real-world datasets → mixed popularity •
Popularity follows a power-law distribution • Small number of objects hot; most are not Mixed popularity → load imbalance • Node(s) storing hottest objects get highly loaded • Majority of nodes are under-utilized 128 Servers … … … Overloaded YCSB, skew exponent = 0.99 -
Skewed Access Distribution 9 Real-world datasets → mixed popularity •
Popularity follows a power-law distribution • Small number of objects hot; most are not Mixed popularity → load imbalance • Node(s) storing hottest objects get highly loaded • Majority of nodes are under-utilized 128 Servers … … … Overloaded YCSB, skew exponent = 0.99 Skew-induced load imbalance limits system throughput -
Centralized cache [SOCC’11, SOSP’17] • Dedicated node resides in front
of the KVS caching hot objects. ◦ Filters the skew with a small cache ◦ Throughput is limited by the single cache Existing Skew Mitigation Techniques 10 … … … ← Cache -
Centralized cache [SOCC’11, SOSP’17] • Dedicated node resides in front
of the KVS caching hot objects. ◦ Filters the skew with a small cache ◦ Throughput is limited by the single cache NUMA abstraction [NSDI’14, SOCC’16] • Uniformly distribute requests to all servers • Remote objects RDMA’ed from home node ◦ Load balance the client requests ◦ No locality → excessive network b/w Most requests require remote access Existing Skew Mitigation Techniques 11 … … … … … … ← Cache -
Centralized cache [SOCC’11, SOSP’17] • Dedicated node resides in front
of the KVS caching hot objects. ◦ Filters the skew with a small cache ◦ Throughput is limited by the single cache NUMA abstraction [NSDI’14, SOCC’16] • Uniformly distribute requests to all servers • Remote objects RDMA’ed from home node ◦ Load balance the client requests ◦ No locality → excessive network b/w Most requests require remote access Existing Skew Mitigation Techniques 12 … … … … … … Can we get the best of both worlds? ← Cache -
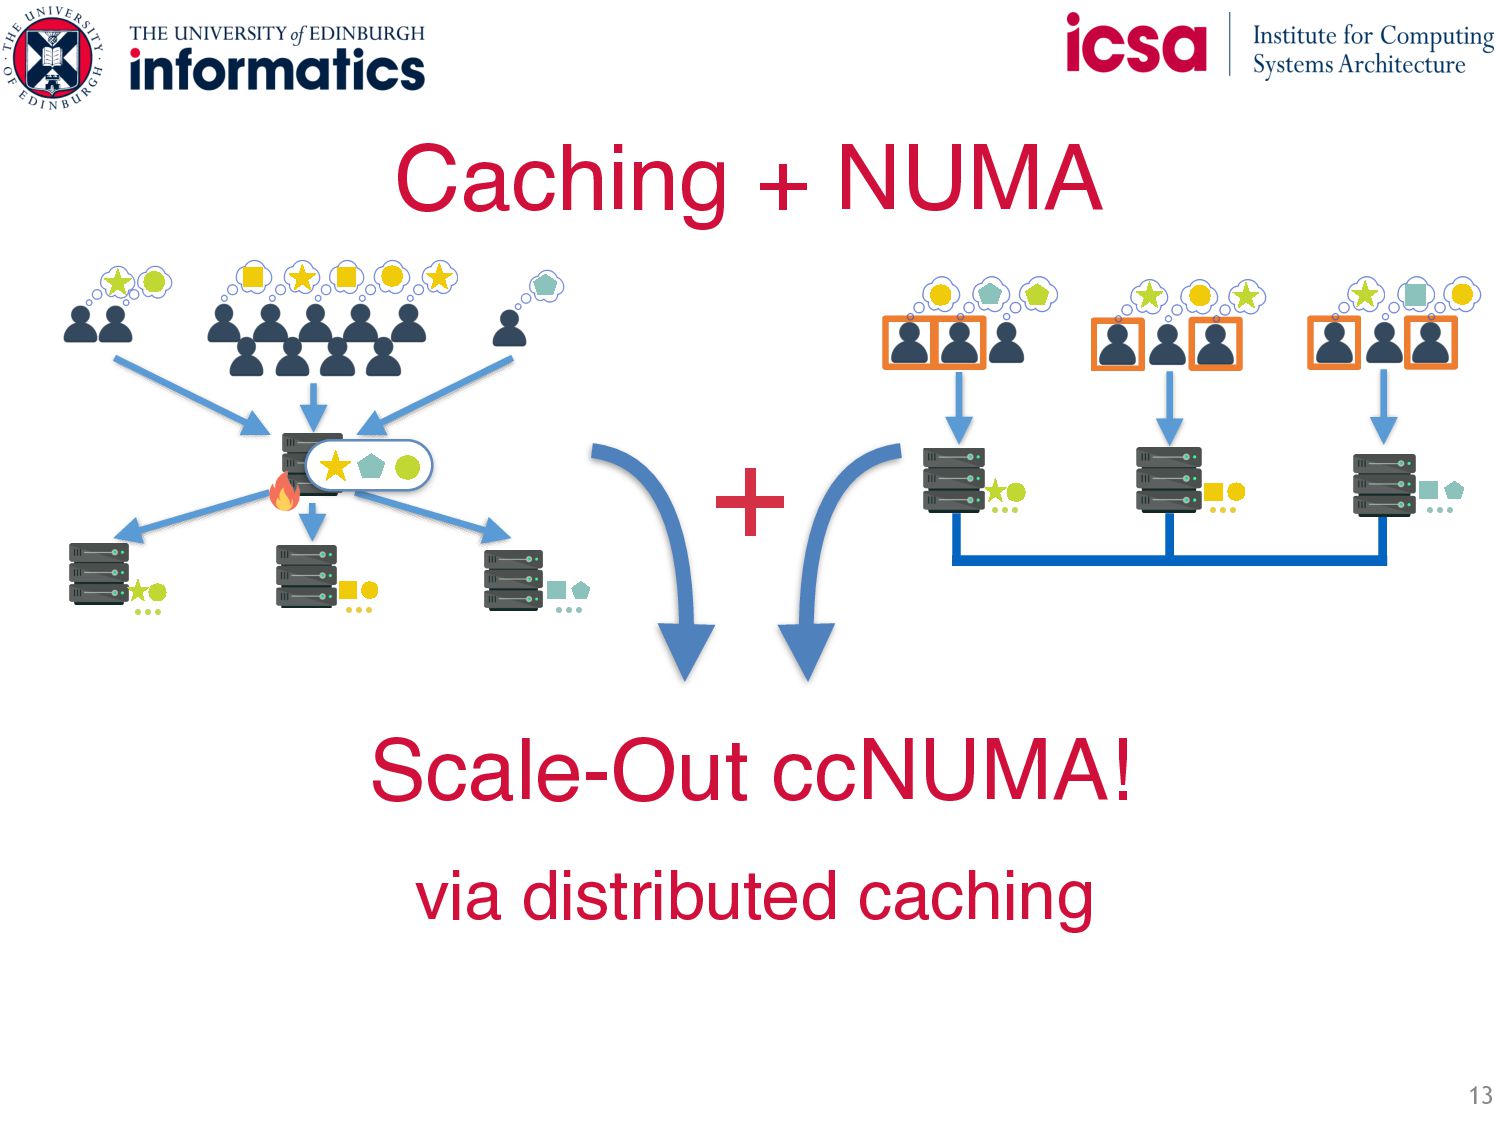
13 Caching + NUMA … … … + Scale-Out ccNUMA!
… … … via distributed caching -
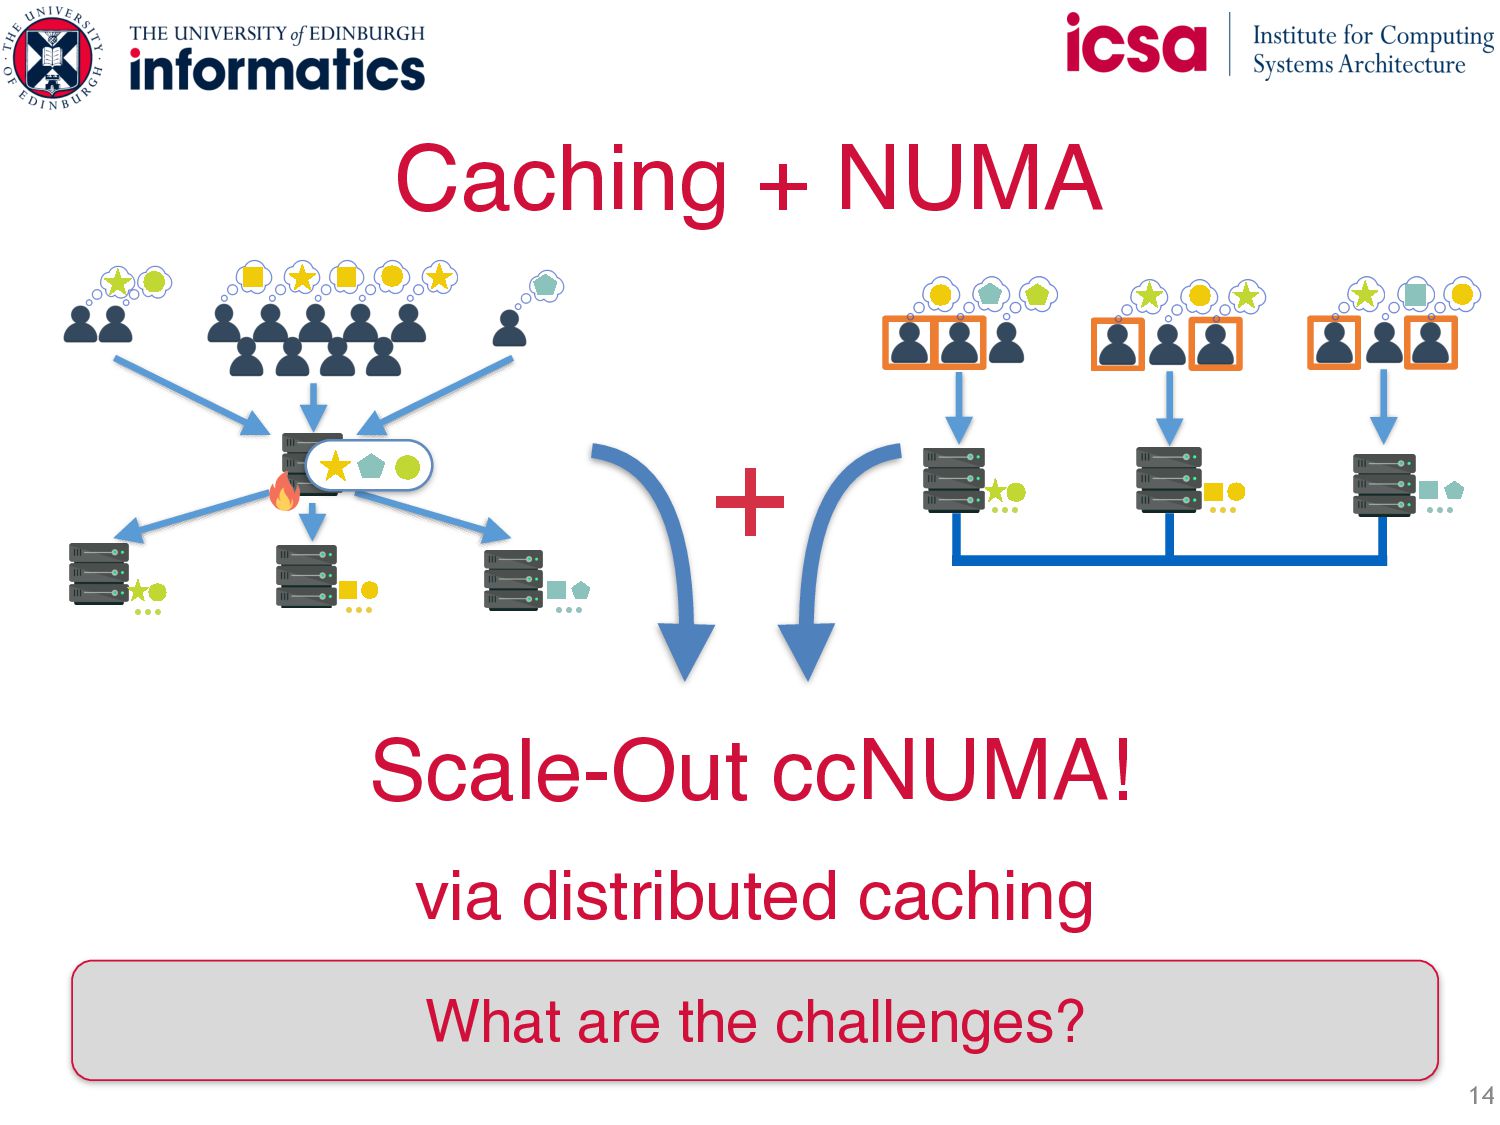
14 Caching + NUMA … … … + Scale-Out ccNUMA!
What are the challenges? … … … via distributed caching -
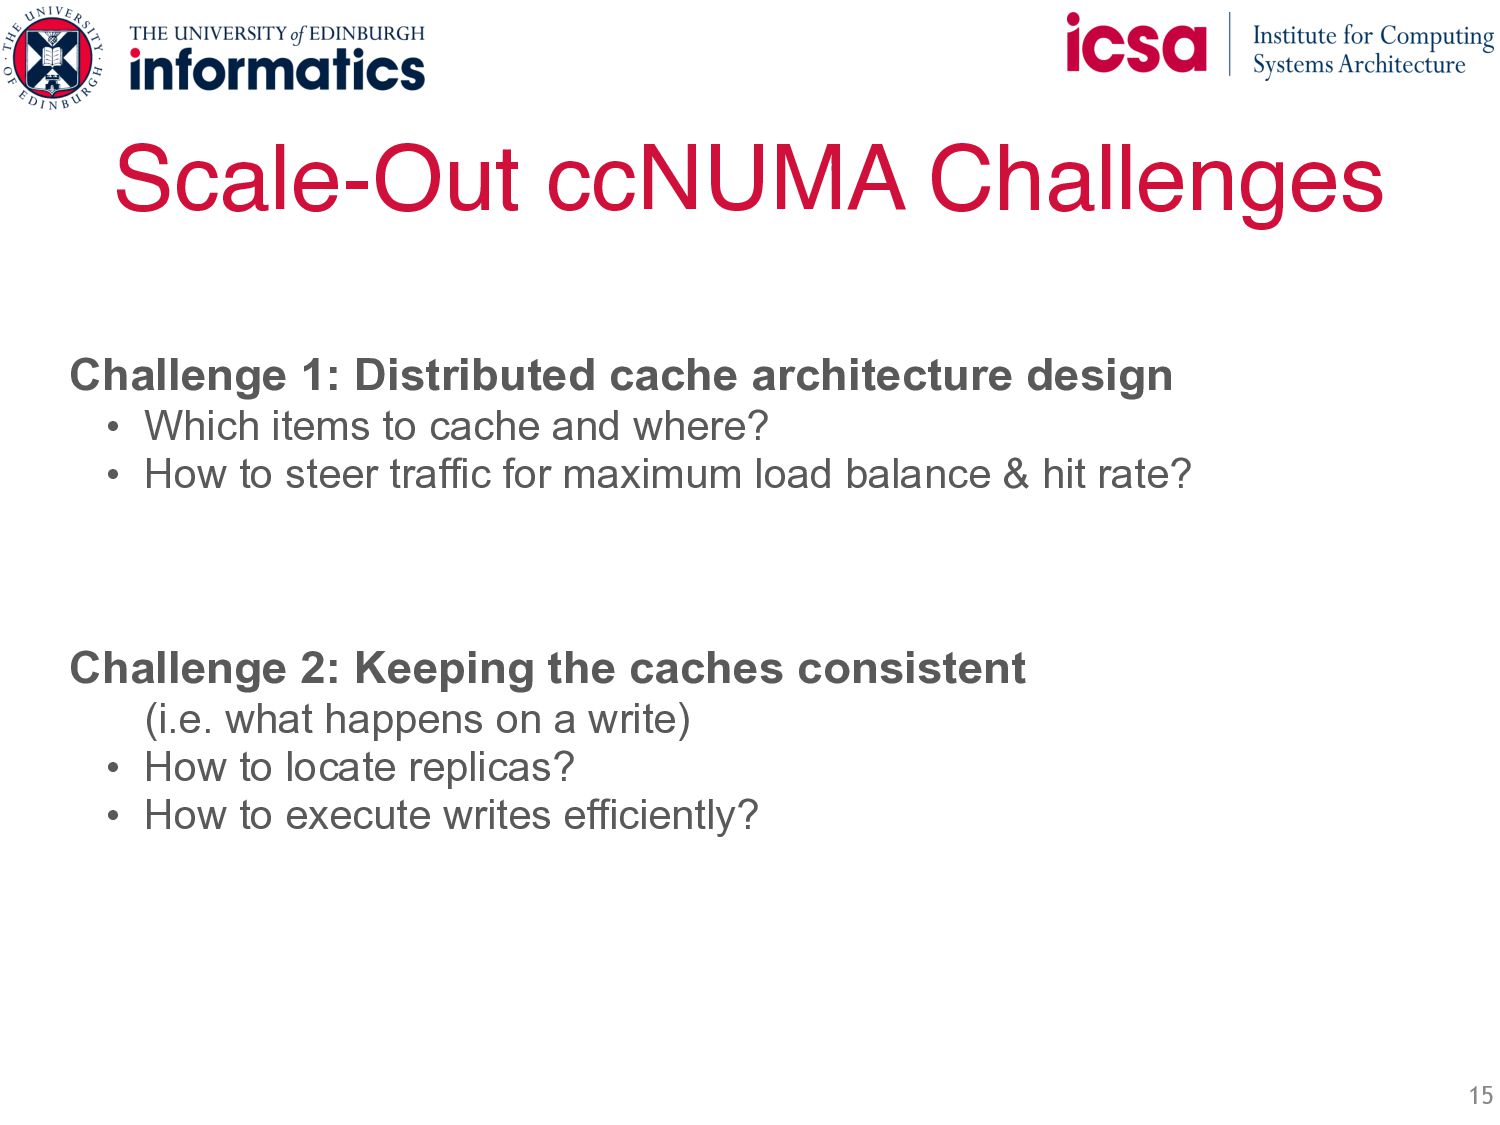
Scale-Out ccNUMA Challenges 15 Challenge 1: Distributed cache architecture design
• Which items to cache and where? • How to steer traffic for maximum load balance & hit rate? Challenge 2: Keeping the caches consistent (i.e. what happens on a write) • How to locate replicas? • How to execute writes efficiently? -
Scale-Out ccNUMA Challenges 16 Challenge 1: Distributed cache architecture design
• Which items to cache and where? • How to steer traffic for maximum load balance & hit rate? Challenge 2: Keeping the caches consistent (i.e. what happens on a write) • How to locate replicas? • How to execute writes efficiently? Solving Challenge 1 with Symmetric Caching -
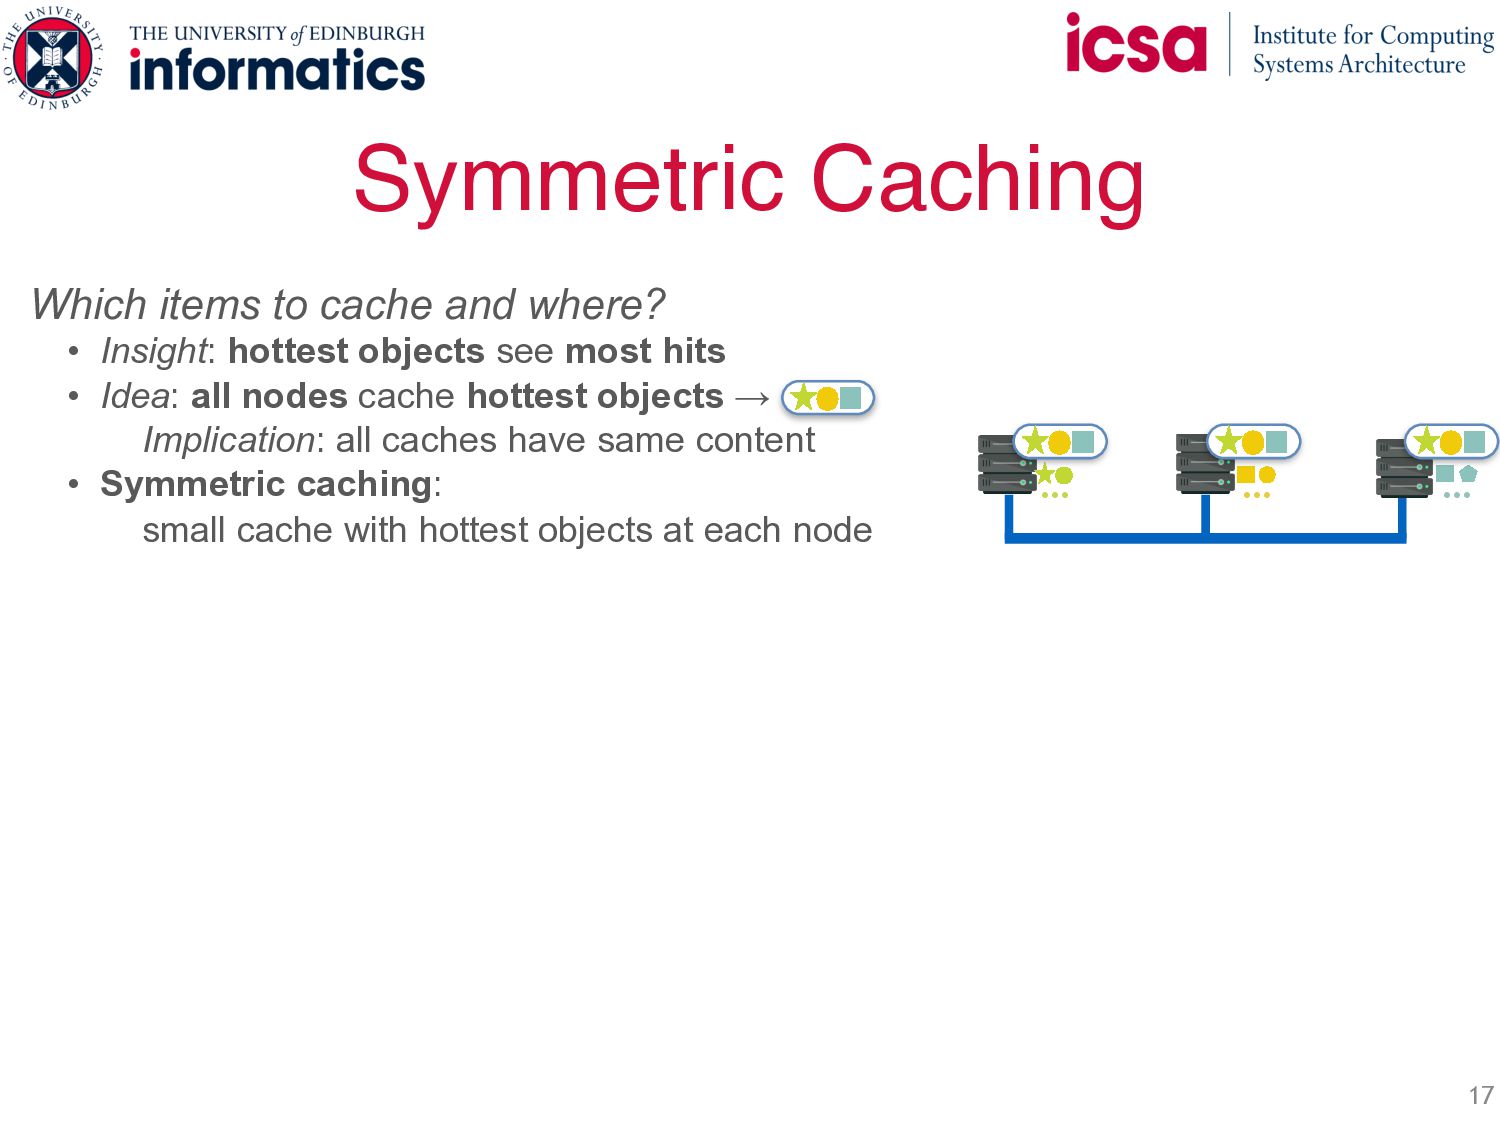
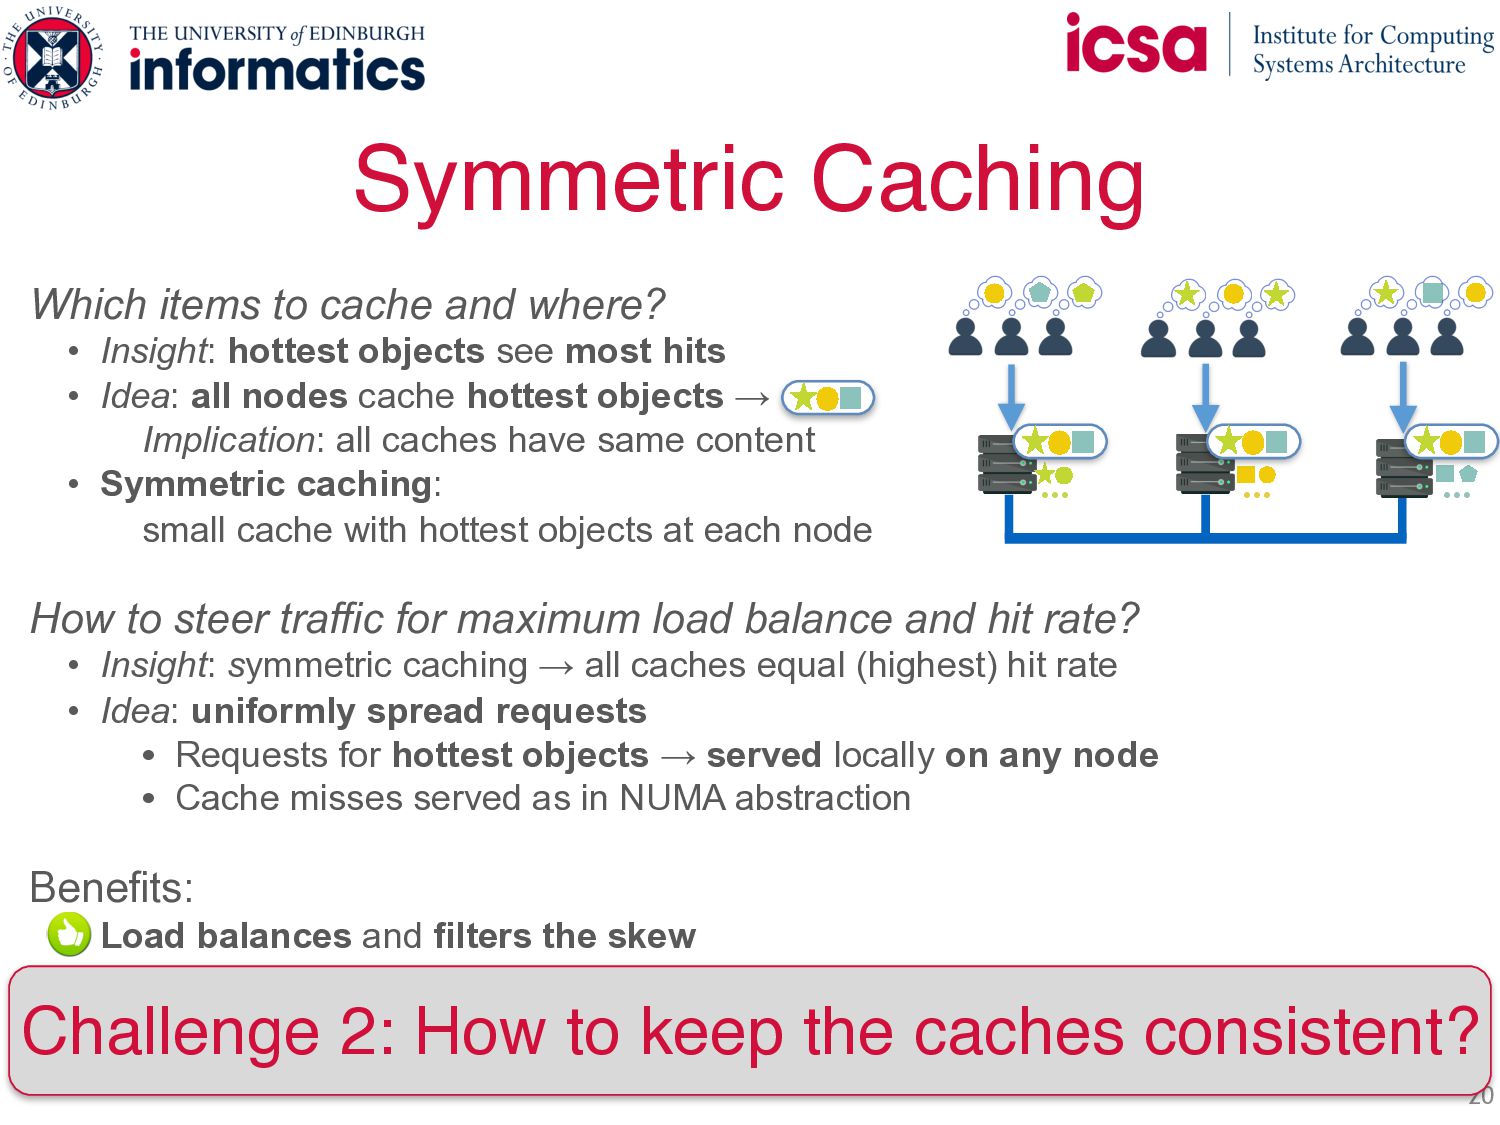
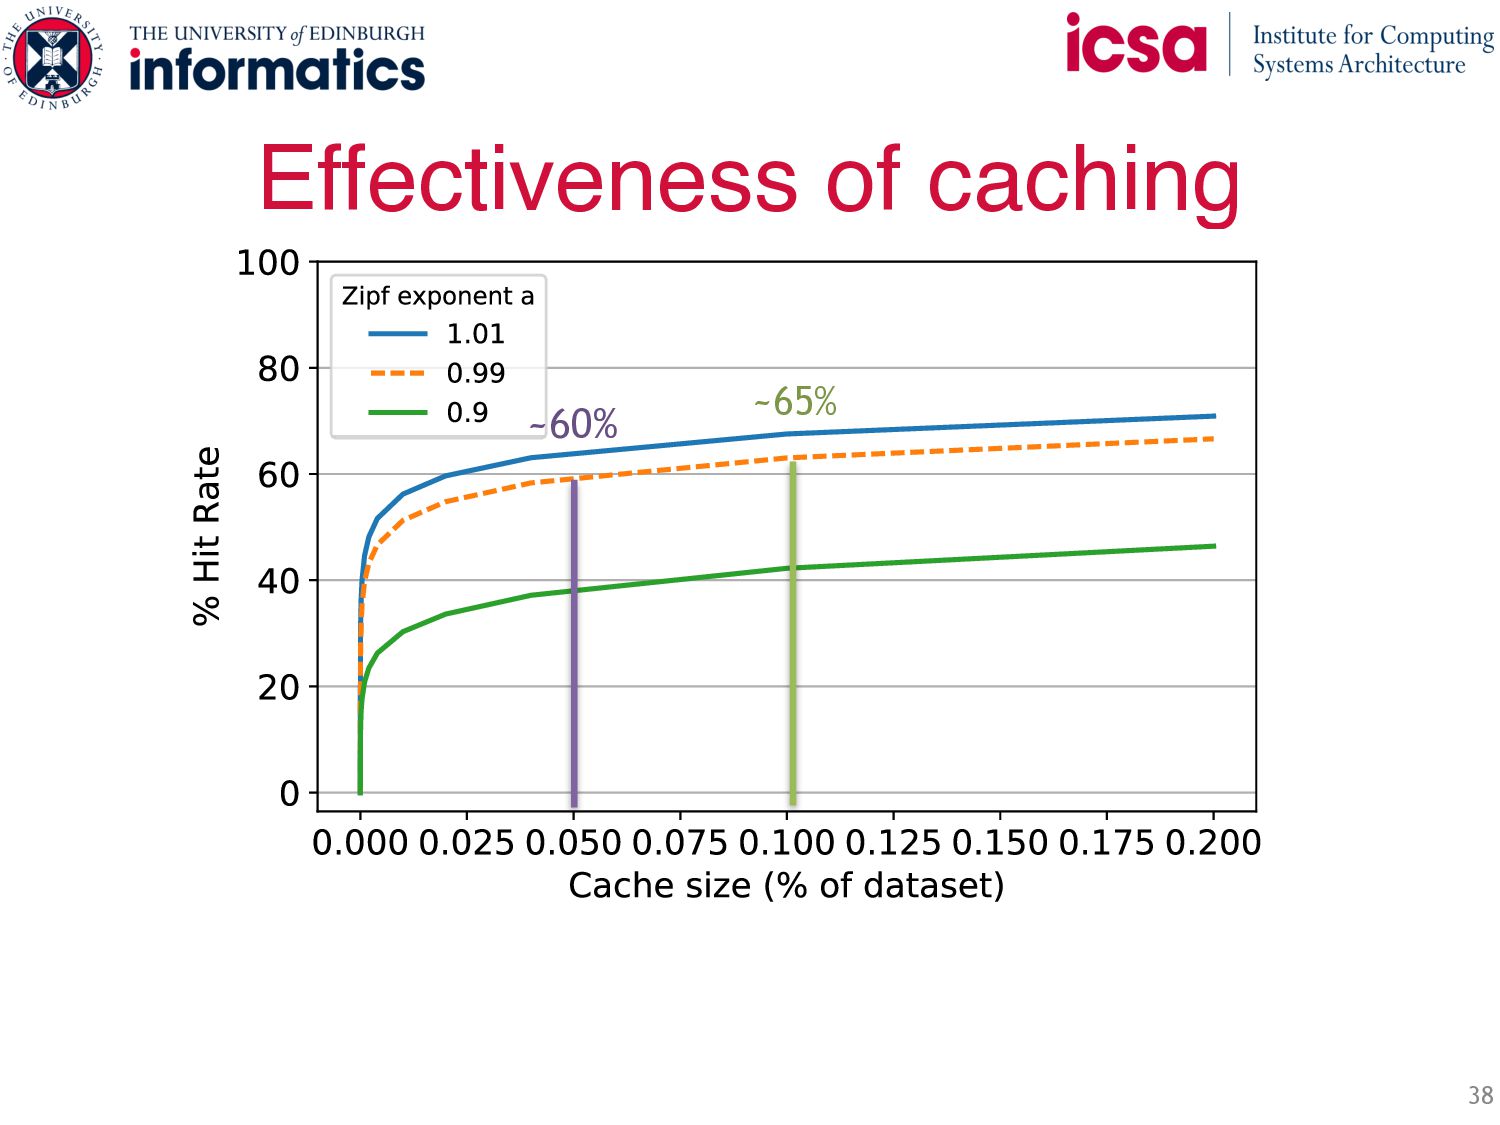
17 Which items to cache and where? • Insight: hottest
objects see most hits • Idea: all nodes cache hottest objects → Implication: all caches have same content • Symmetric caching: small cache with hottest objects at each node How to steer traffic for maximum load balance and hit rate? • Insight: symmetric caching → all caches equal (highest) hit rate • Idea: uniformly spread requests • Requests for hottest objects → served locally on any node • Cache misses served as in NUMA Abstraction Benefits: • Load balances and filters the skew • Throughput scales with number of servers • Less network b/w: most requests are served locally Symmetric Caching … … … -
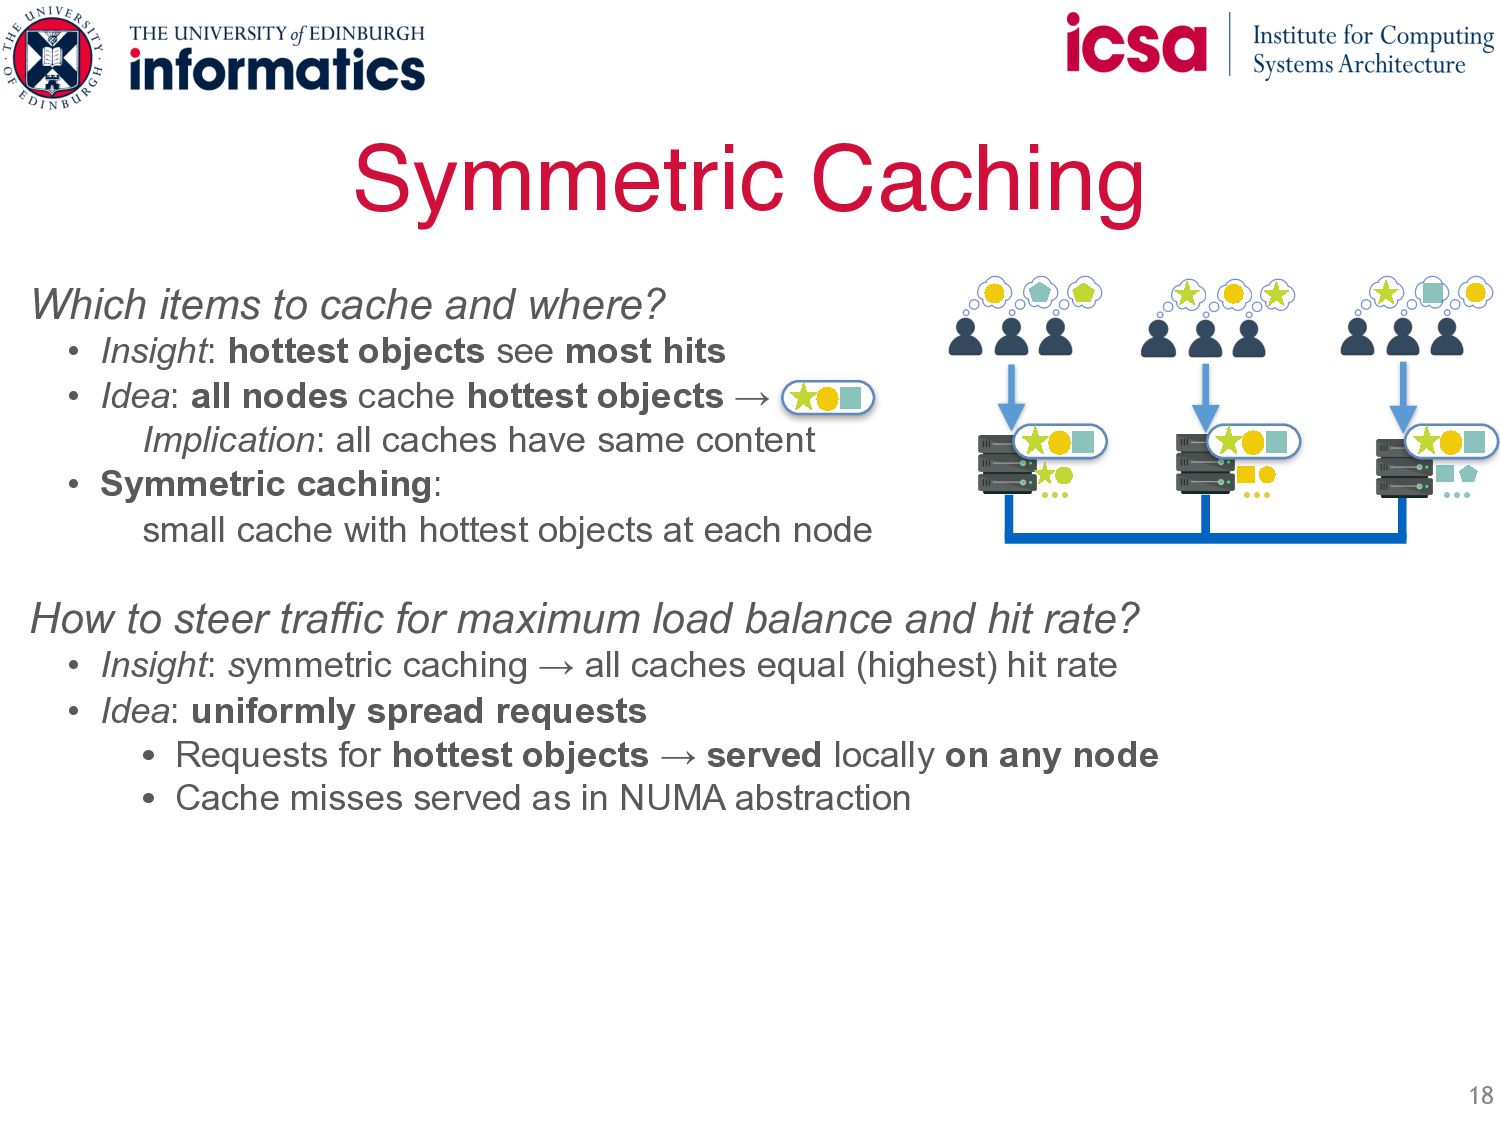
18 Which items to cache and where? • Insight: hottest
objects see most hits • Idea: all nodes cache hottest objects → Implication: all caches have same content • Symmetric caching: small cache with hottest objects at each node How to steer traffic for maximum load balance and hit rate? • Insight: symmetric caching → all caches equal (highest) hit rate • Idea: uniformly spread requests • Requests for hottest objects → served locally on any node • Cache misses served as in NUMA abstraction Benefits: • Load balances and filters the skew • Throughput scales with number of servers • Less network b/w: most requests are served locally Symmetric Caching … … … -
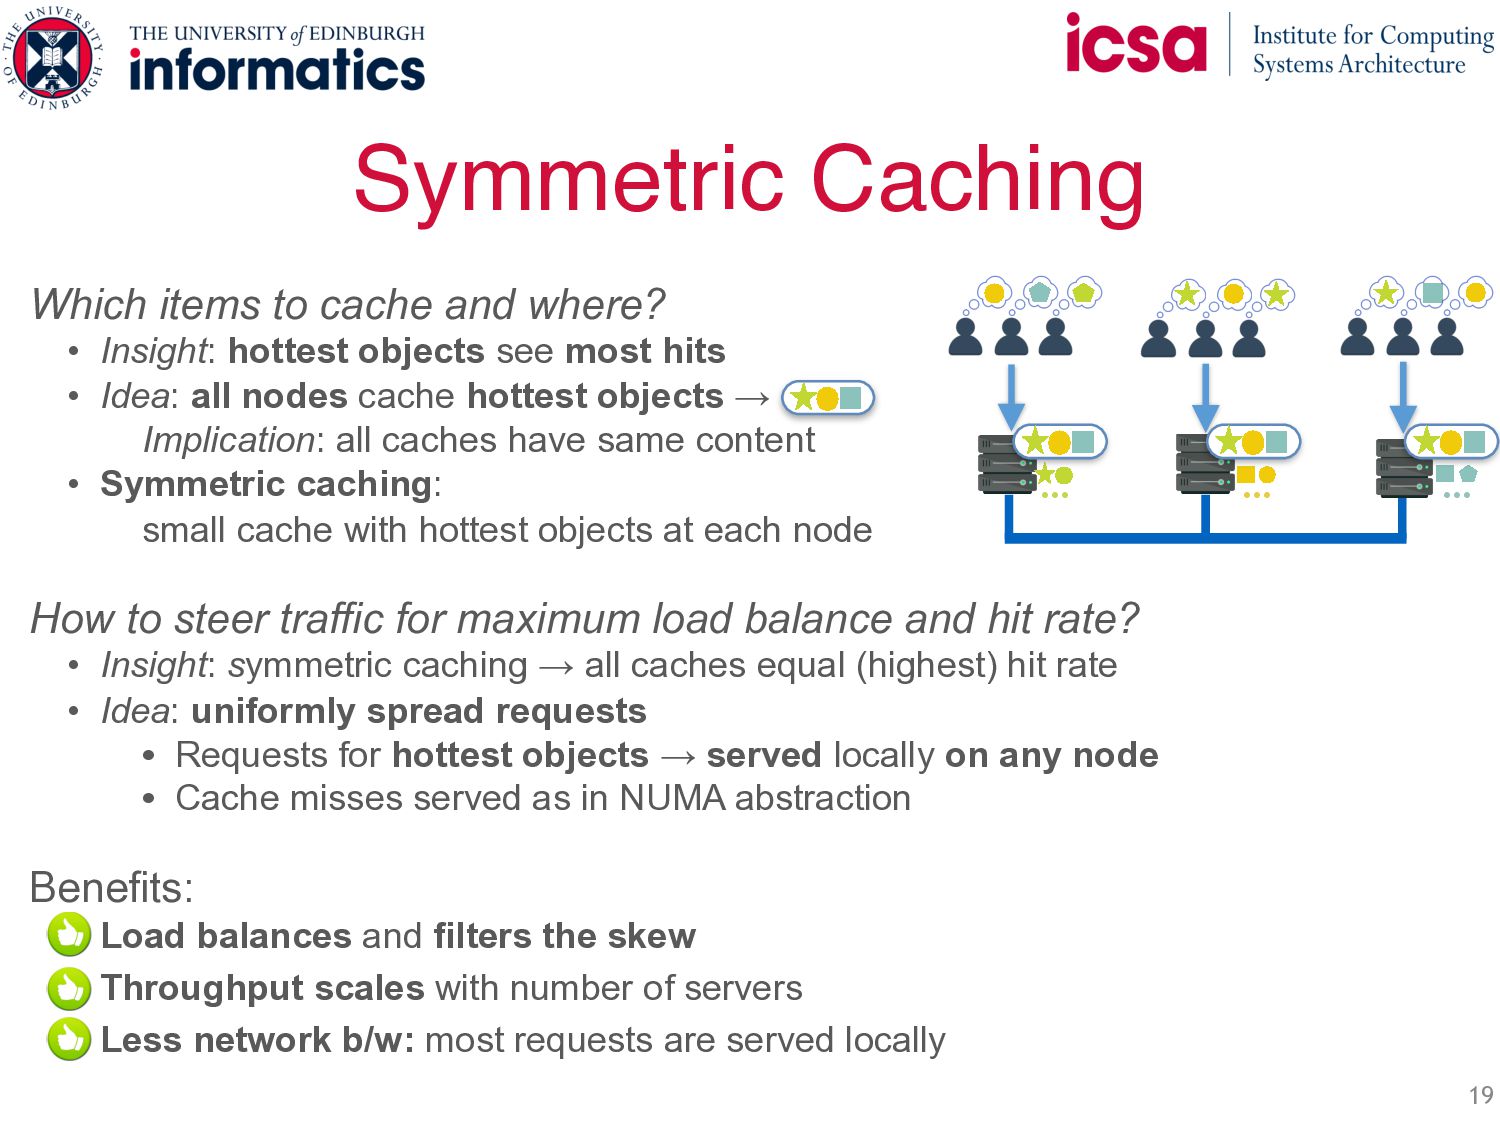
19 Which items to cache and where? • Insight: hottest
objects see most hits • Idea: all nodes cache hottest objects → Implication: all caches have same content • Symmetric caching: small cache with hottest objects at each node How to steer traffic for maximum load balance and hit rate? • Insight: symmetric caching → all caches equal (highest) hit rate • Idea: uniformly spread requests • Requests for hottest objects → served locally on any node • Cache misses served as in NUMA abstraction Benefits: • Load balances and filters the skew • Throughput scales with number of servers • Less network b/w: most requests are served locally Symmetric Caching … … … -
20 Which items to cache and where? • Insight: hottest
objects see most hits • Idea: all nodes cache hottest objects → Implication: all caches have same content • Symmetric caching: small cache with hottest objects at each node How to steer traffic for maximum load balance and hit rate? • Insight: symmetric caching → all caches equal (highest) hit rate • Idea: uniformly spread requests • Requests for hottest objects → served locally on any node • Cache misses served as in NUMA abstraction Benefits: • Load balances and filters the skew • Throughput scales with number of servers • Less network b/w: most requests are served locally Symmetric Caching … … … Challenge 2: How to keep the caches consistent? -
Keeping the caches consistent 21 Requirement: On a write, inform
all replicas of the new value How to locate replicas? - Easy with Symmetric Caching! If object in local cache → all nodes cache it -
Keeping the caches consistent 22 Requirement: On a write, inform
all replicas of the new value How to locate replicas? - Easy with Symmetric Caching! If object in local cache → all nodes cache it -
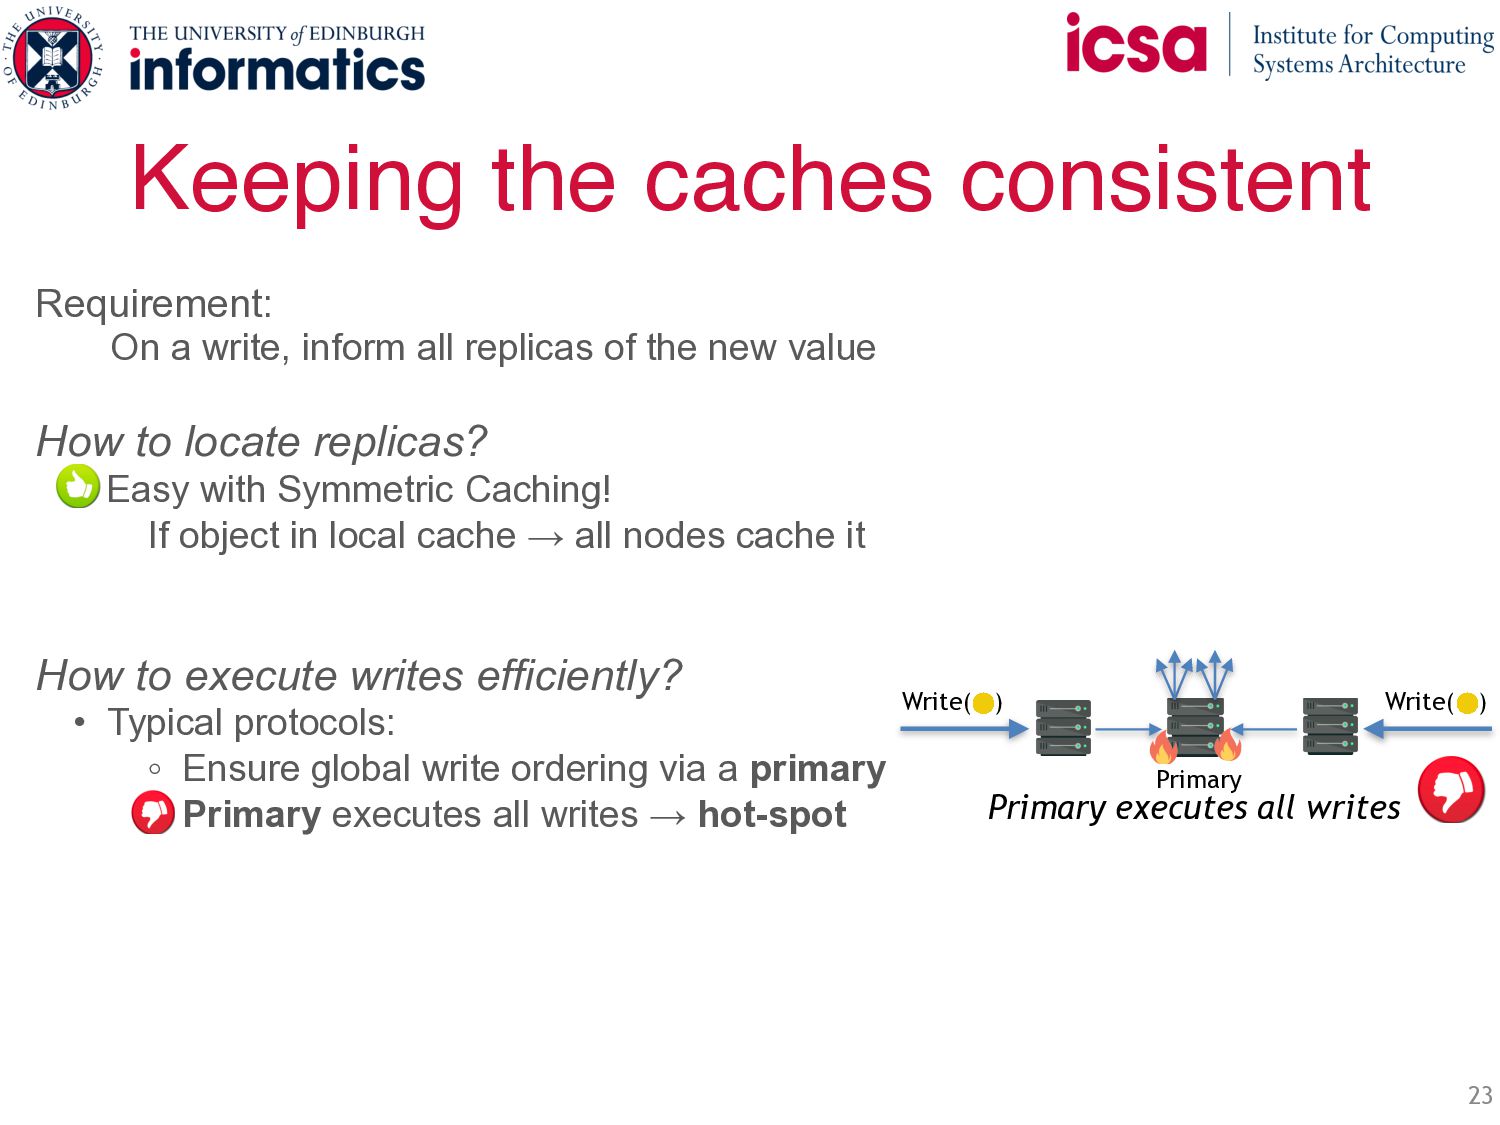
Keeping the caches consistent 23 Requirement: On a write, inform
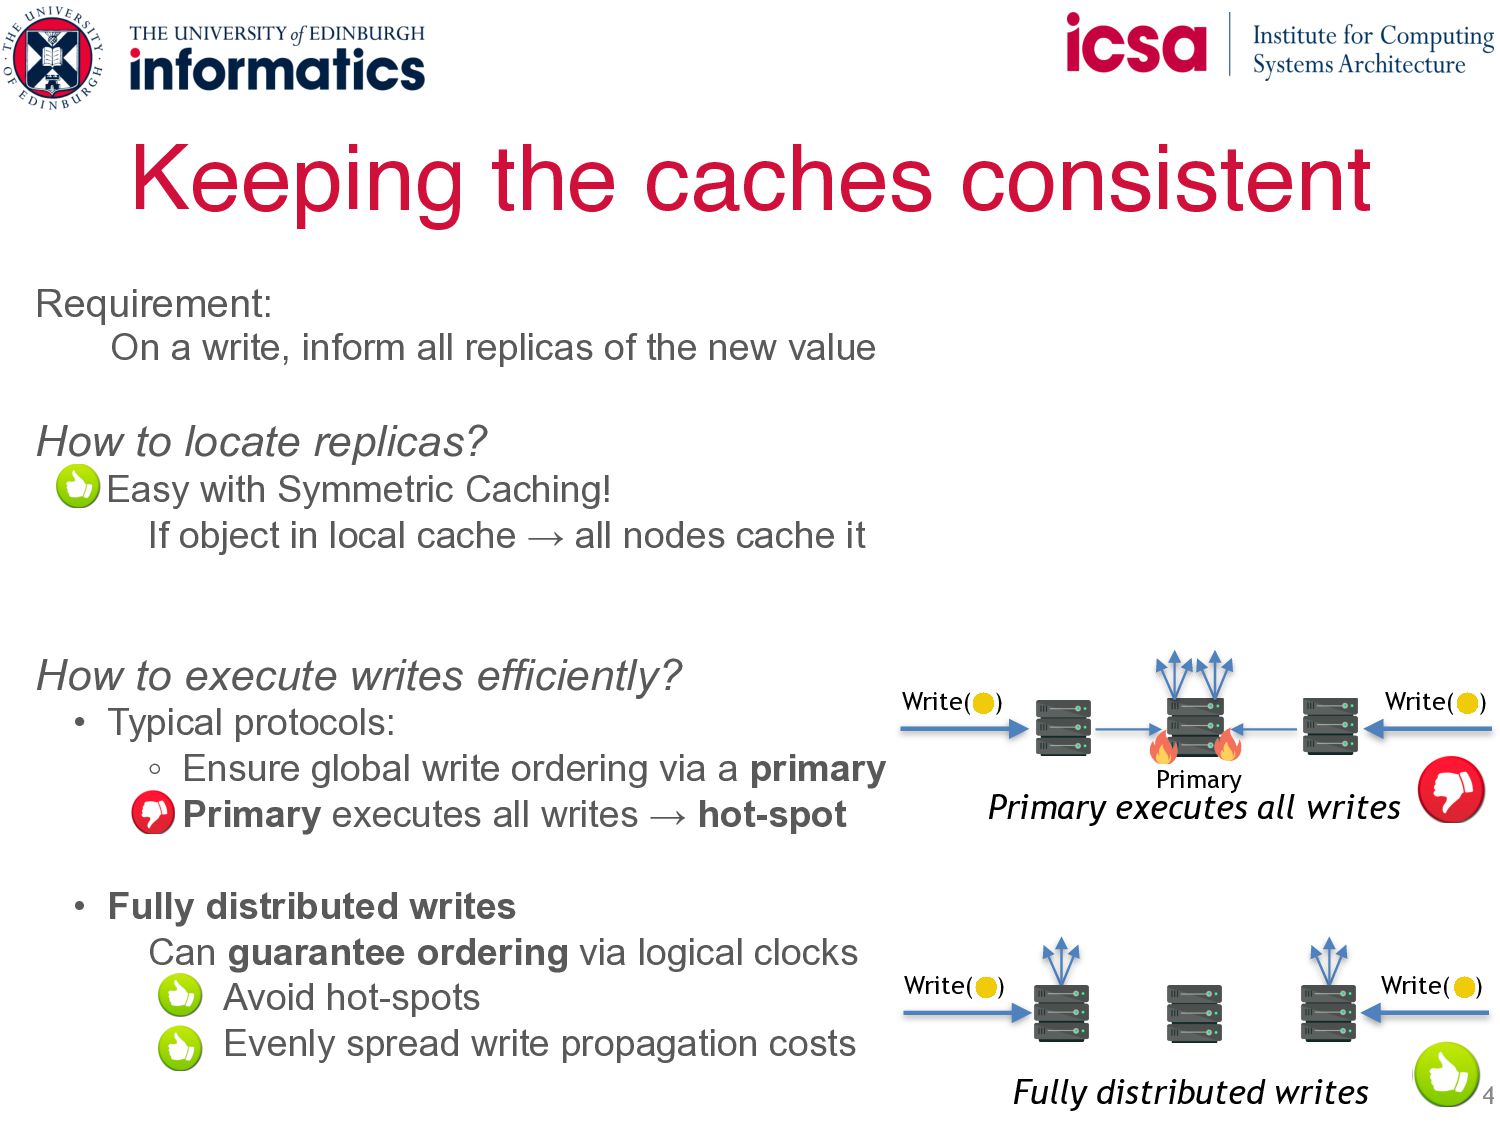
all replicas of the new value How to locate replicas? - Easy with Symmetric Caching! If object in local cache → all nodes cache it How to execute writes efficiently? • Typical protocols: ◦ Ensure global write ordering via a primary ◦ Primary executes all writes → hot-spot Primary executes all writes Write( ) Write( ) Primary -
Keeping the caches consistent 24 Requirement: On a write, inform
all replicas of the new value How to locate replicas? - Easy with Symmetric Caching! If object in local cache → all nodes cache it How to execute writes efficiently? • Typical protocols: ◦ Ensure global write ordering via a primary ◦ Primary executes all writes → hot-spot • Fully distributed writes Can guarantee ordering via logical clocks Avoid hot-spots Evenly spread write propagation costs Primary executes all writes Write( ) Write( ) Primary Fully distributed writes Write( ) Write( ) -
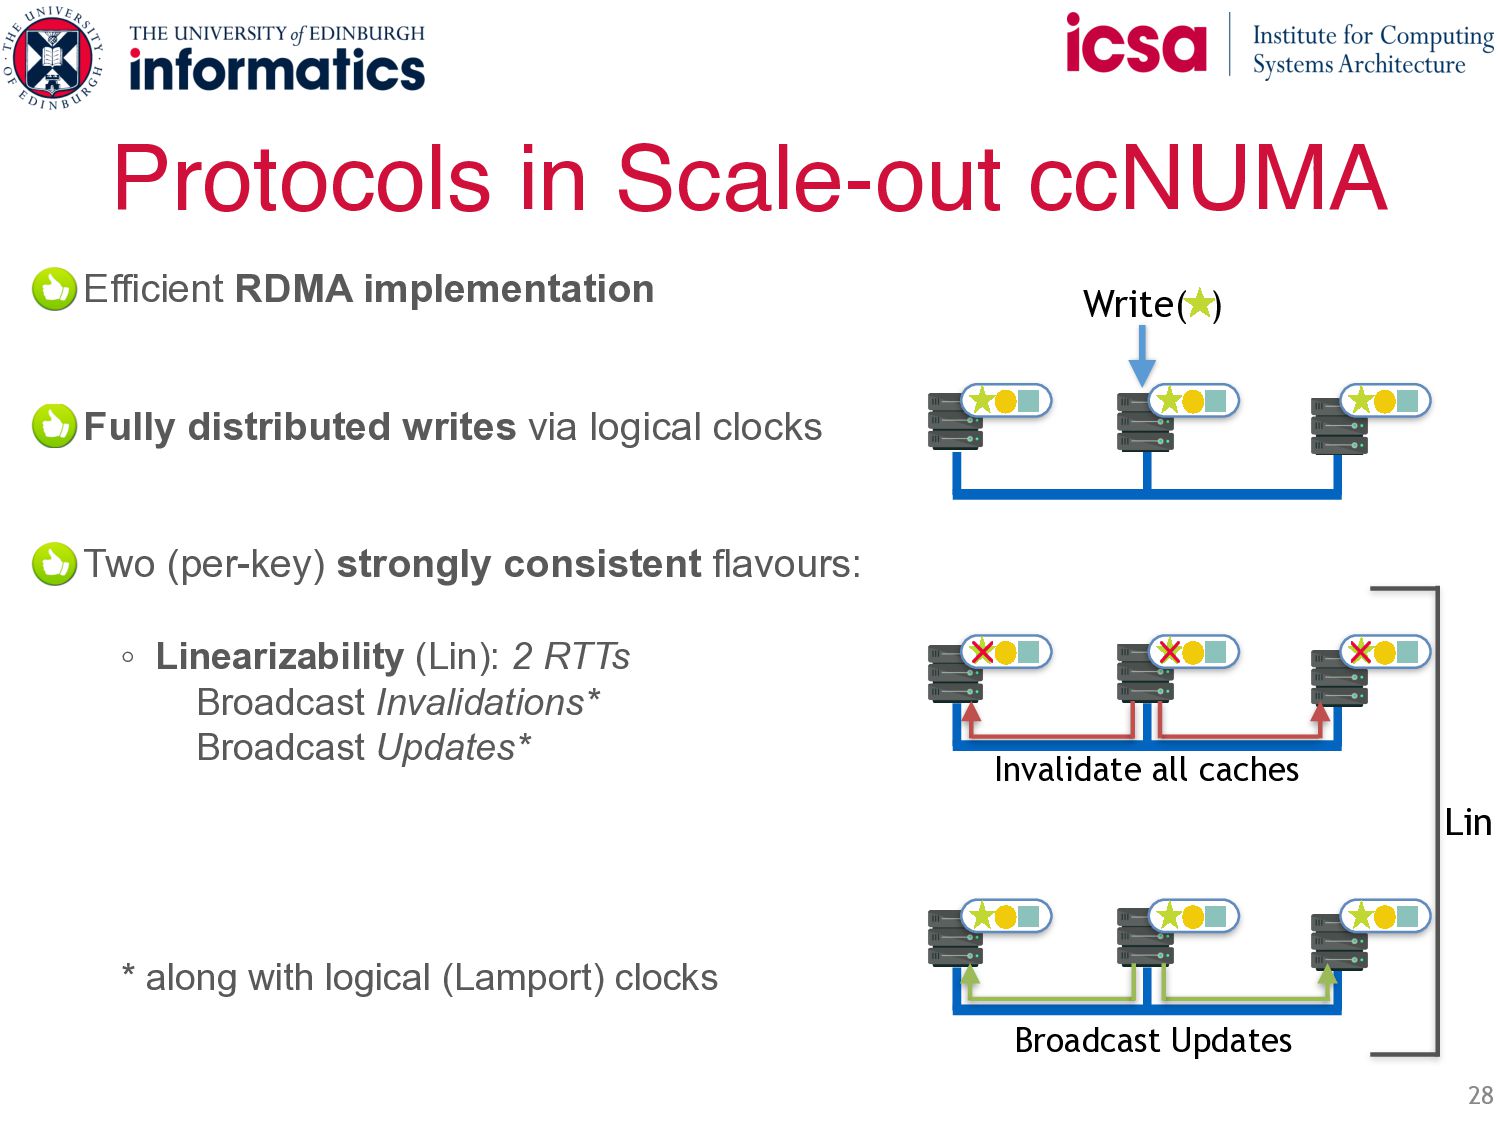
Protocols in Scale-out ccNUMA 25 Efficient RDMA implementation Fully distributed
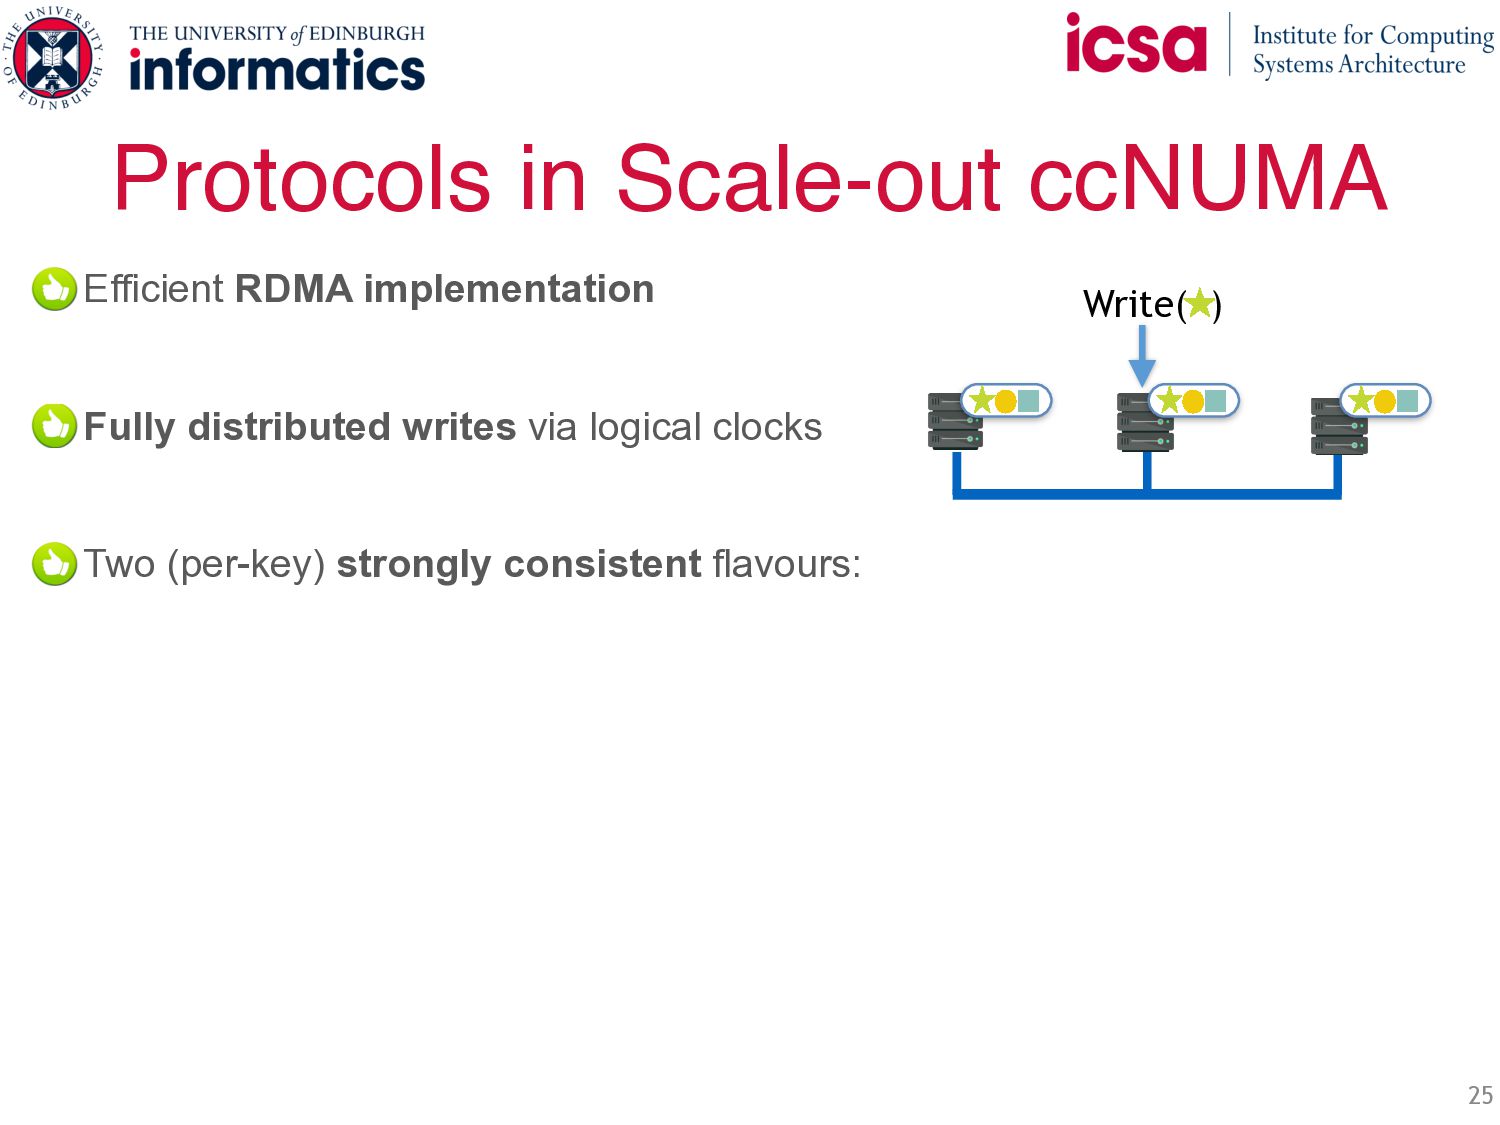
writes via logical clocks Two (per-key) strongly consistent flavours: Write( ) -
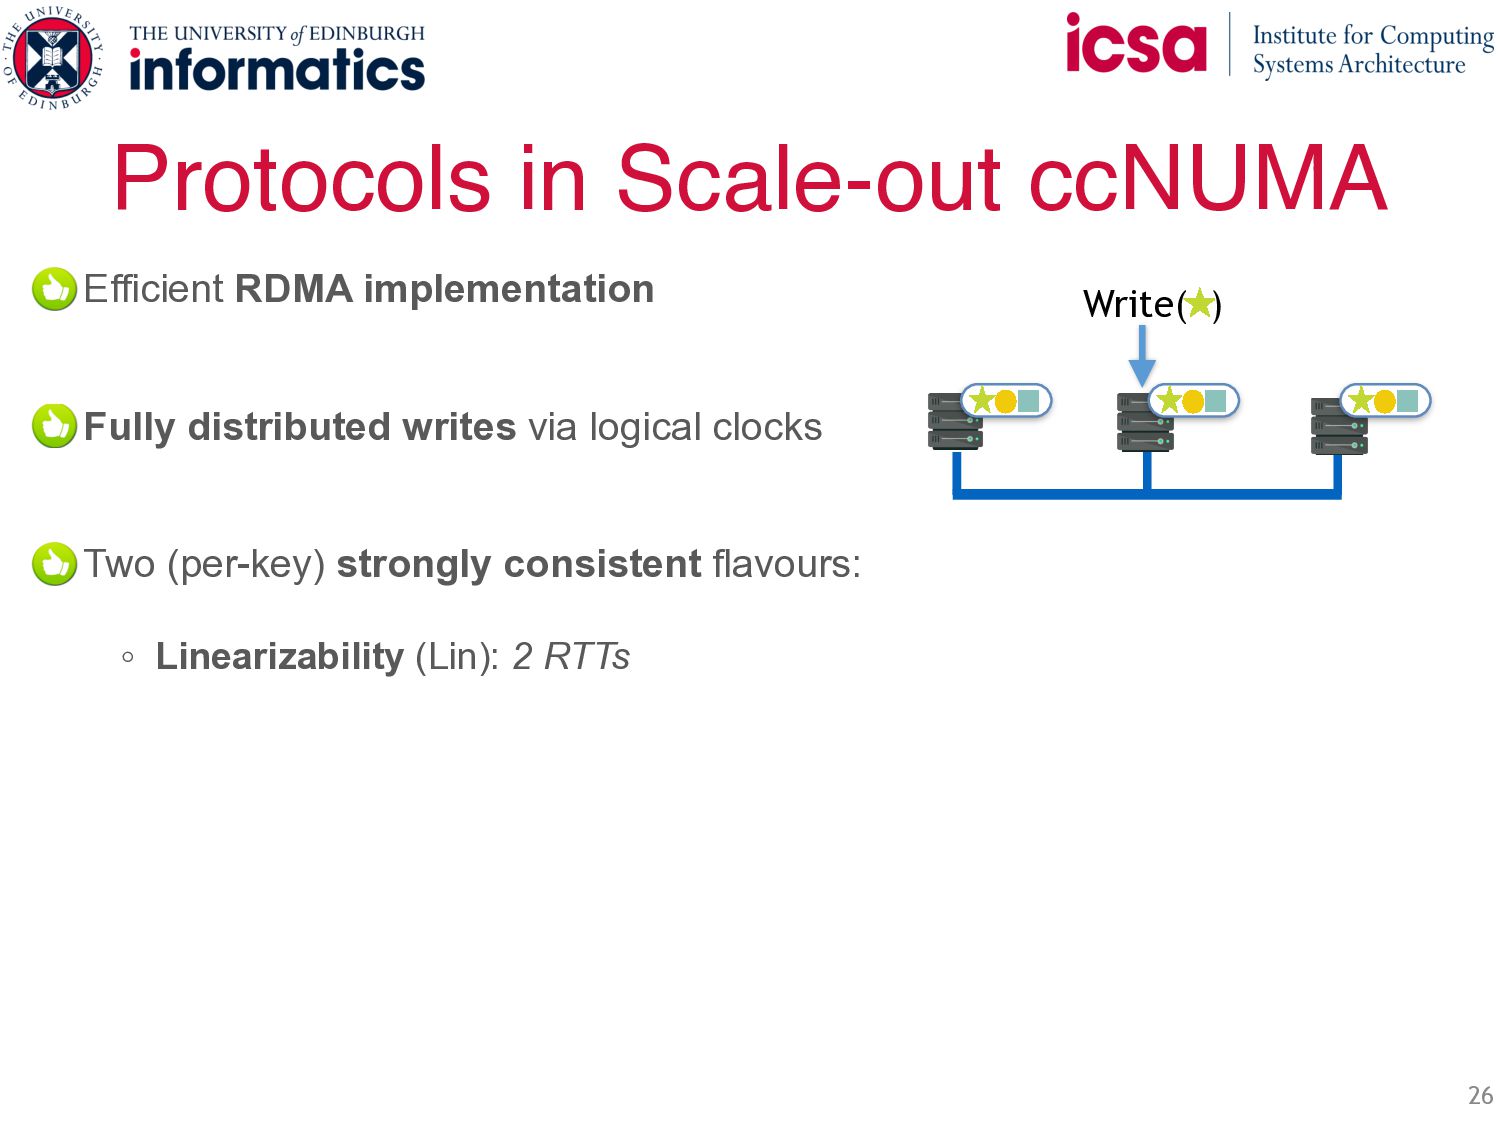
Protocols in Scale-out ccNUMA 26 Efficient RDMA implementation Fully distributed
writes via logical clocks Two (per-key) strongly consistent flavours: ◦ Linearizability (Lin): 2 RTTs Write( ) -
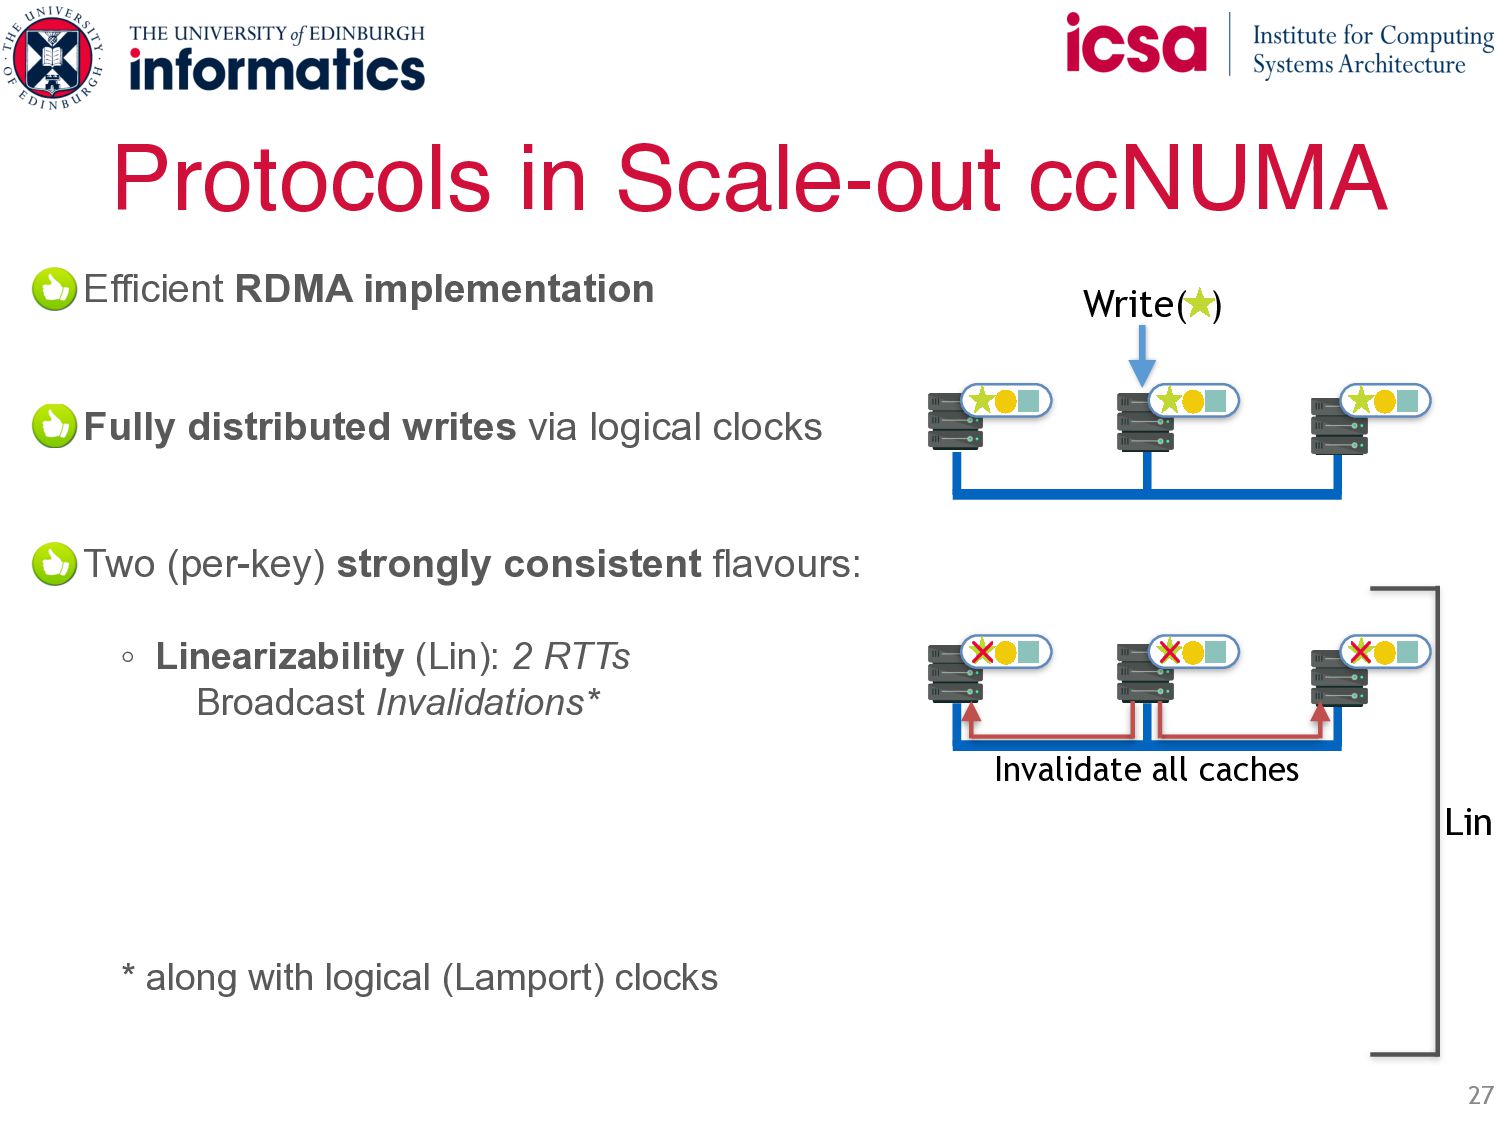
Protocols in Scale-out ccNUMA 27 Efficient RDMA implementation Fully distributed
writes via logical clocks Two (per-key) strongly consistent flavours: ◦ Linearizability (Lin): 2 RTTs Broadcast Invalidations* * along with logical (Lamport) clocks Lin Invalidate all caches Write( ) -
Protocols in Scale-out ccNUMA 28 Efficient RDMA implementation Fully distributed
writes via logical clocks Two (per-key) strongly consistent flavours: ◦ Linearizability (Lin): 2 RTTs Broadcast Invalidations* Broadcast Updates* * along with logical (Lamport) clocks Lin Invalidate all caches Write( ) Broadcast Updates -
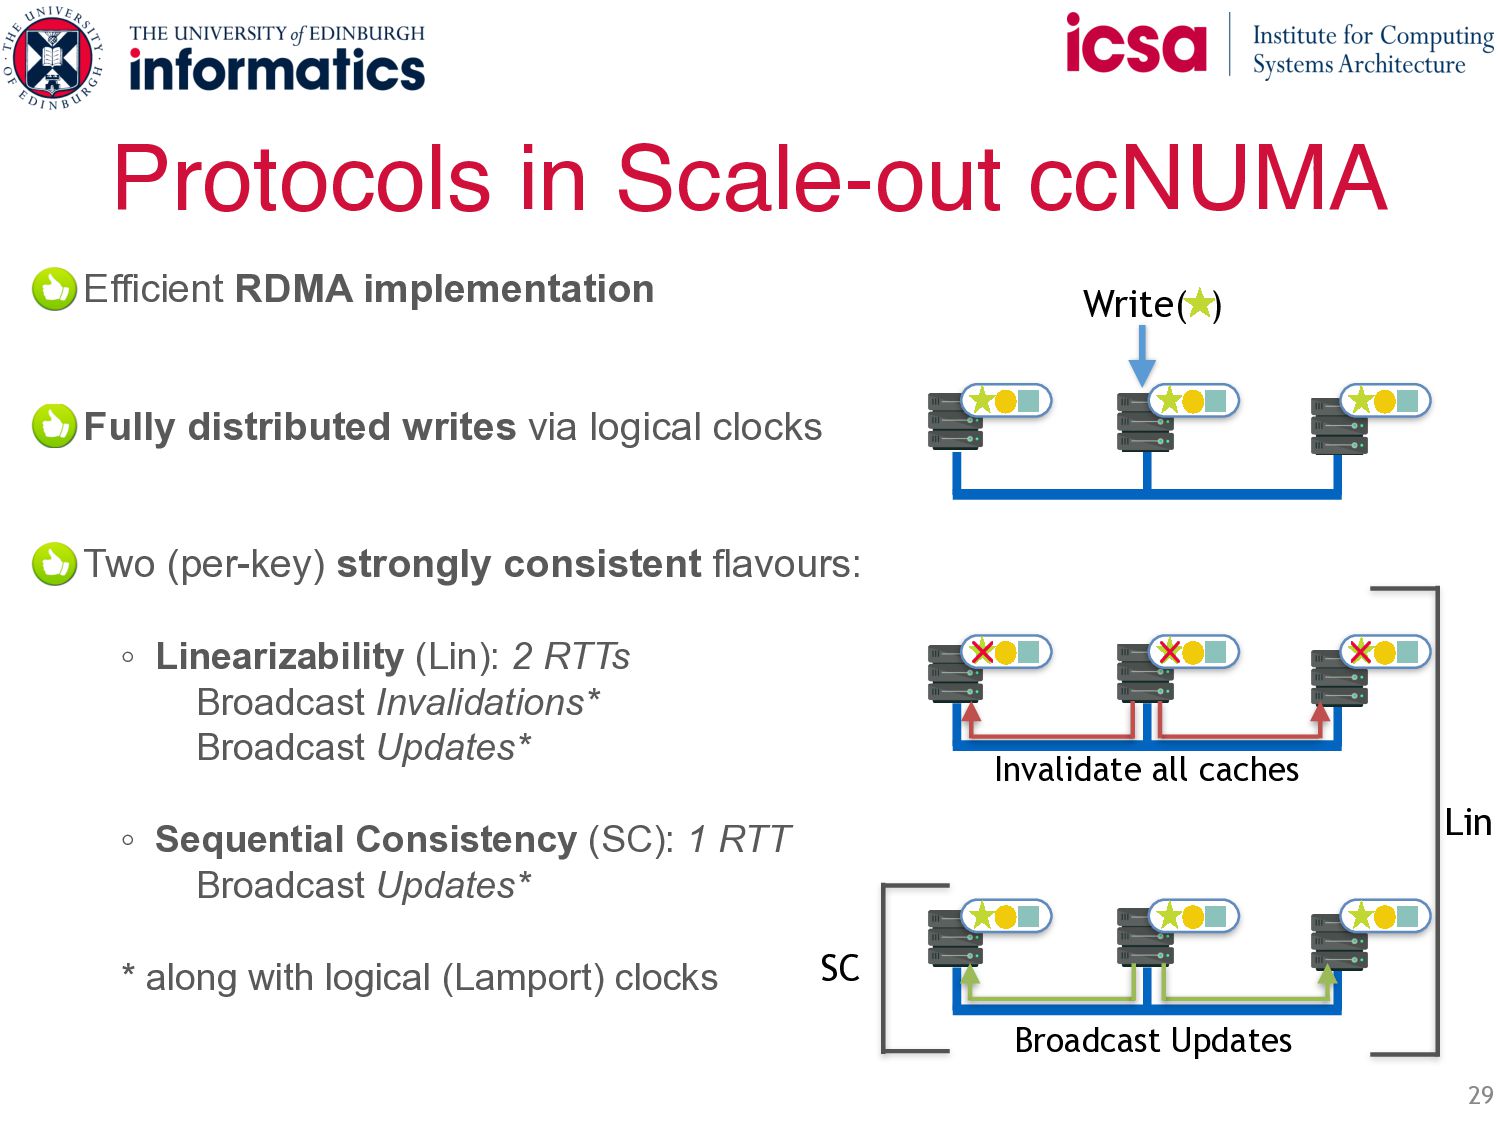
Protocols in Scale-out ccNUMA 29 Efficient RDMA implementation Fully distributed
writes via logical clocks Two (per-key) strongly consistent flavours: ◦ Linearizability (Lin): 2 RTTs Broadcast Invalidations* Broadcast Updates* ◦ Sequential Consistency (SC): 1 RTT Broadcast Updates* * along with logical (Lamport) clocks Lin SC Invalidate all caches Write( ) Broadcast Updates -
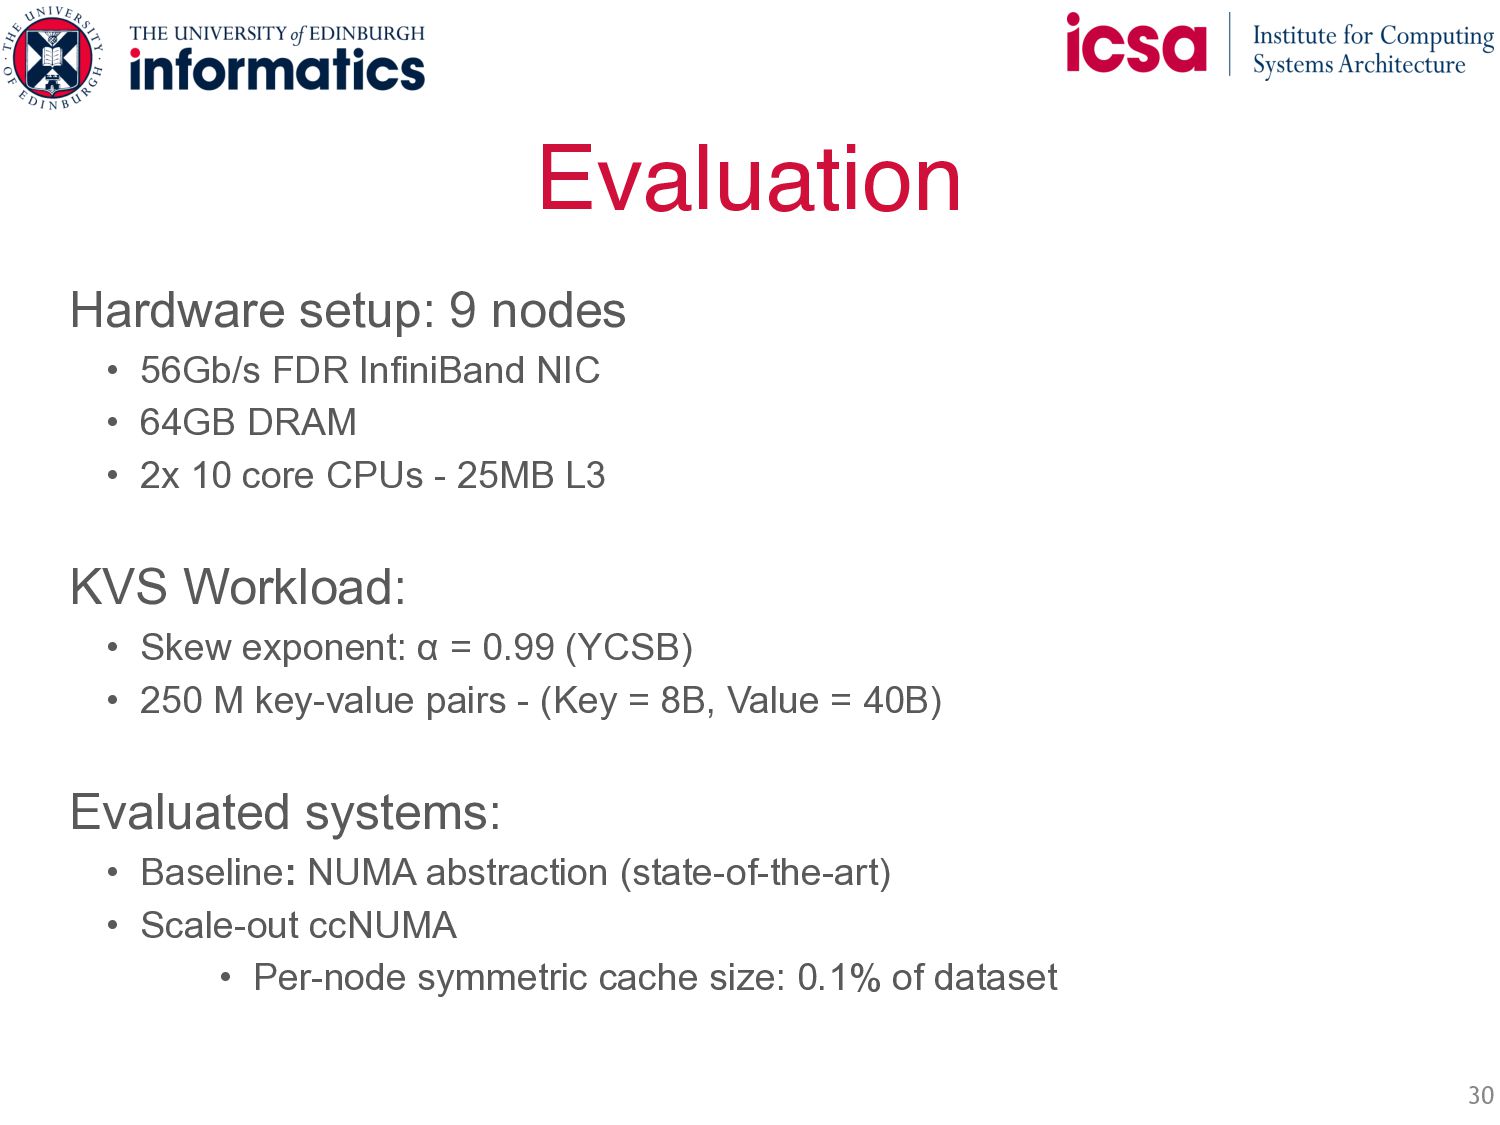
Evaluation 30 Hardware setup: 9 nodes • 56Gb/s FDR InfiniBand
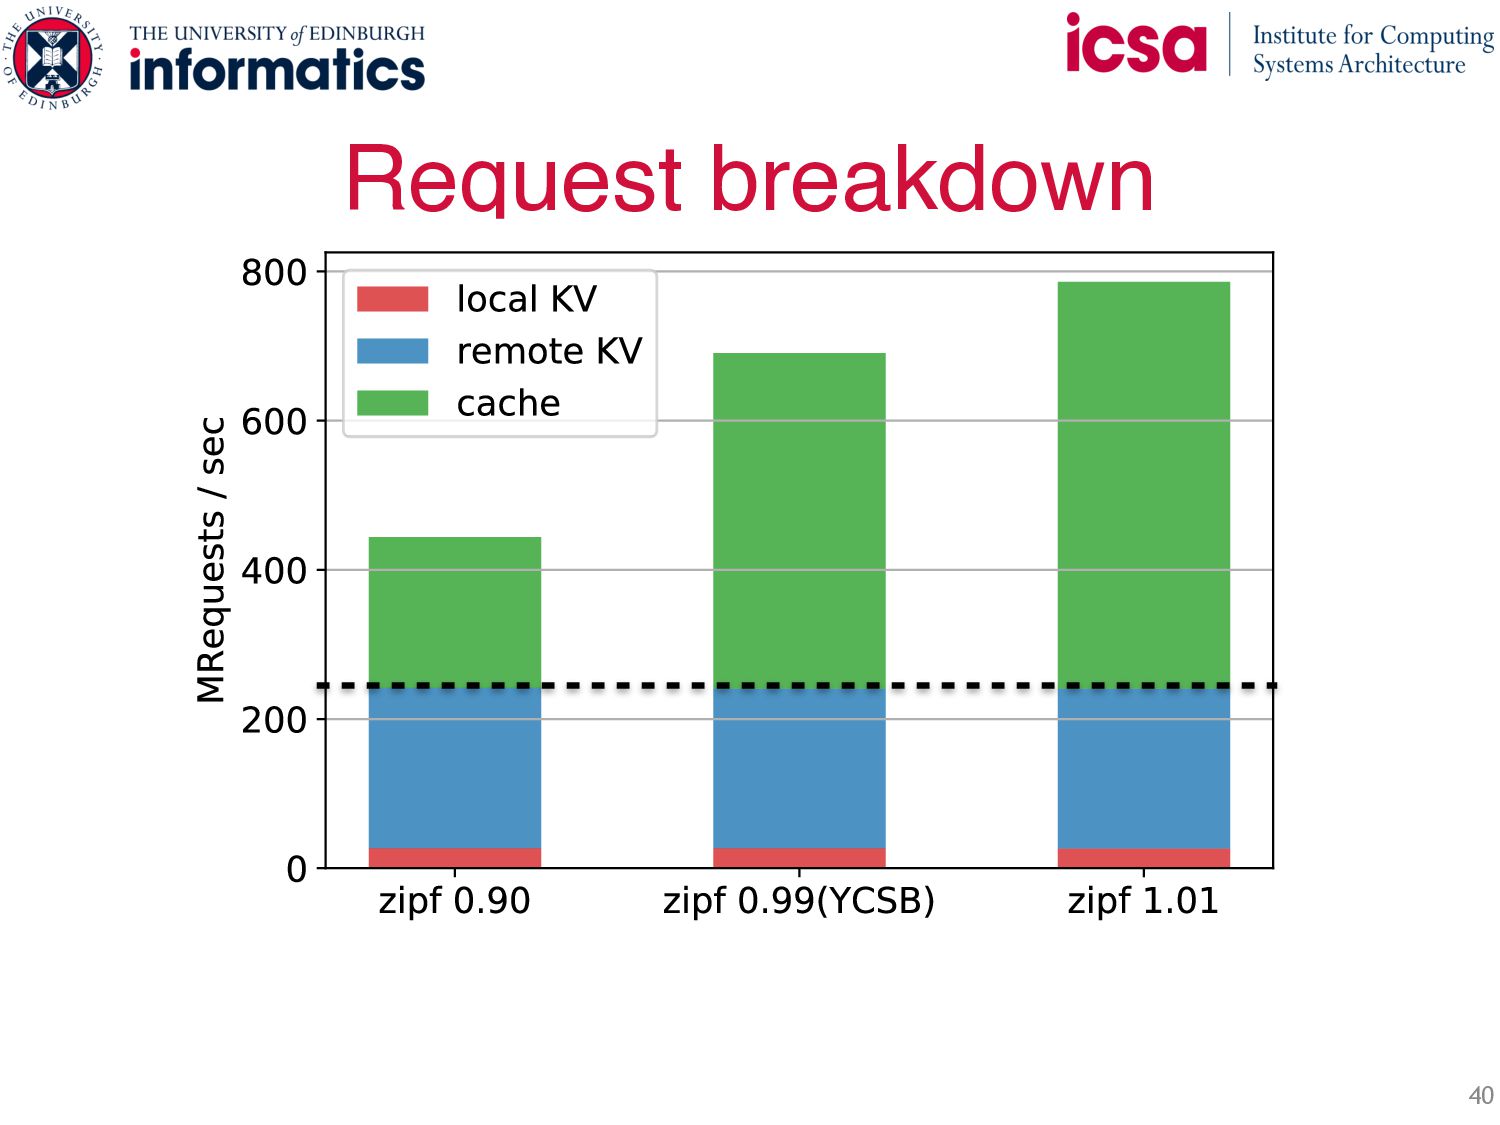
NIC • 64GB DRAM • 2x 10 core CPUs - 25MB L3 KVS Workload: • Skew exponent: α = 0.99 (YCSB) • 250 M key-value pairs - (Key = 8B, Value = 40B) Evaluated systems: • Baseline: NUMA abstraction (state-of-the-art) • Scale-out ccNUMA • Per-node symmetric cache size: 0.1% of dataset -
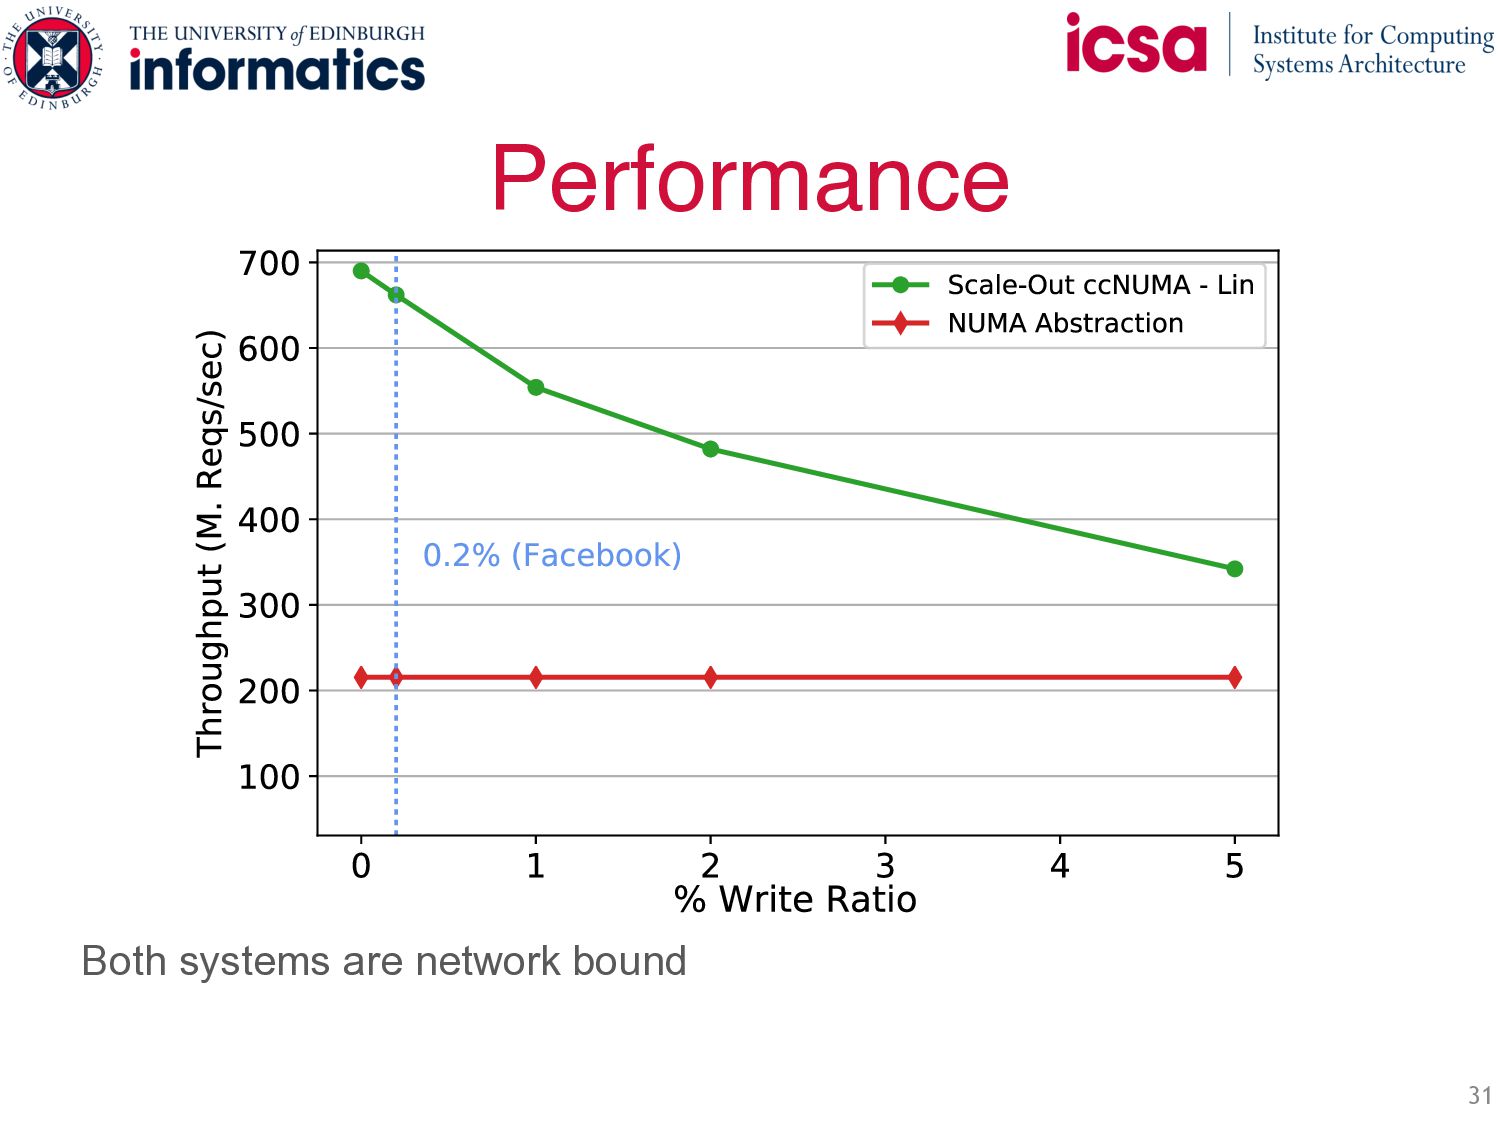
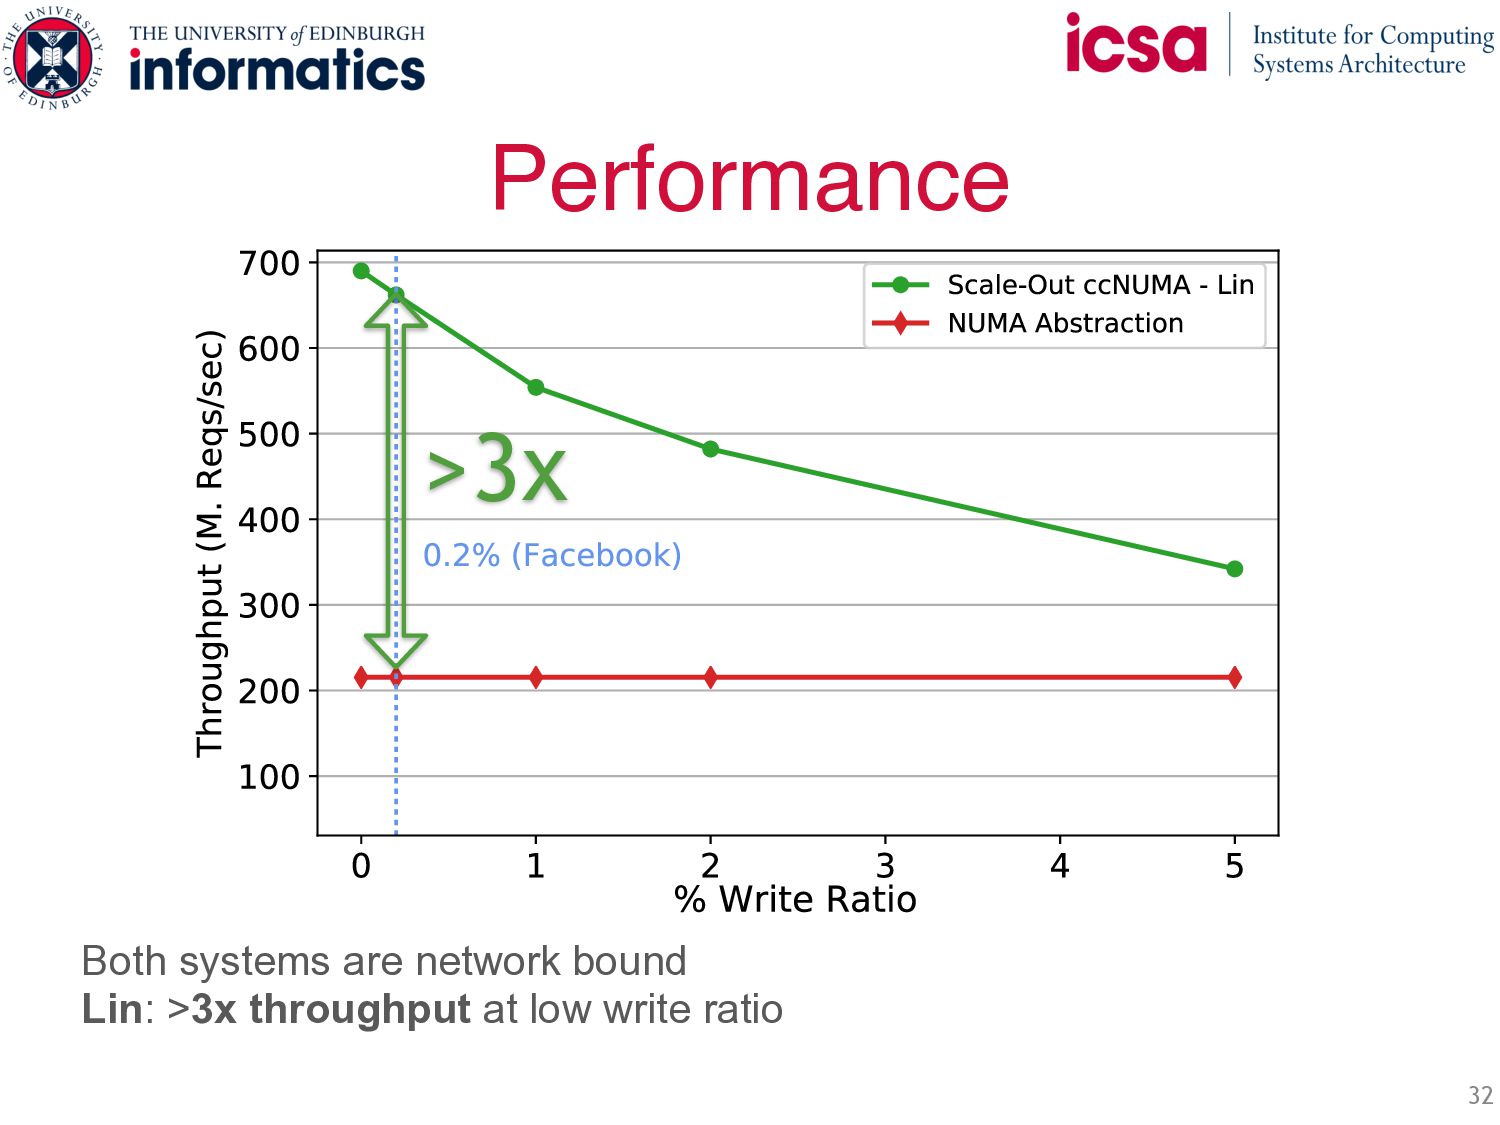
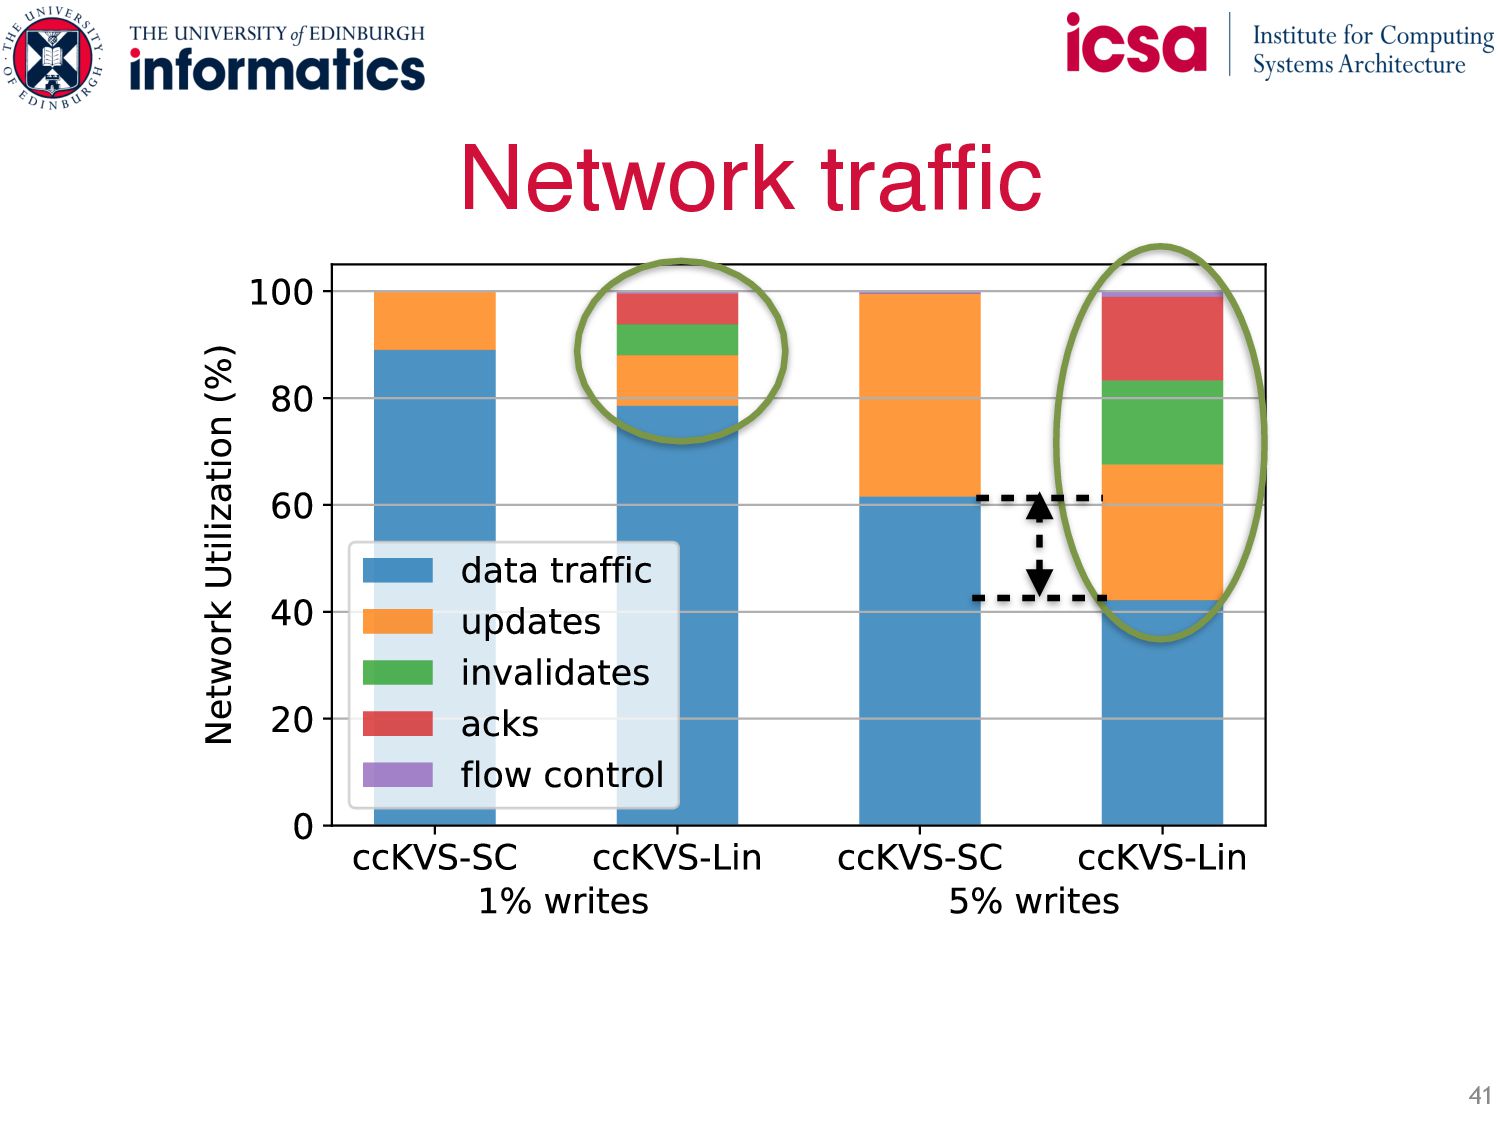
Performance 32 >3χ Both systems are network bound Lin: >3x
throughput at low write ratio -
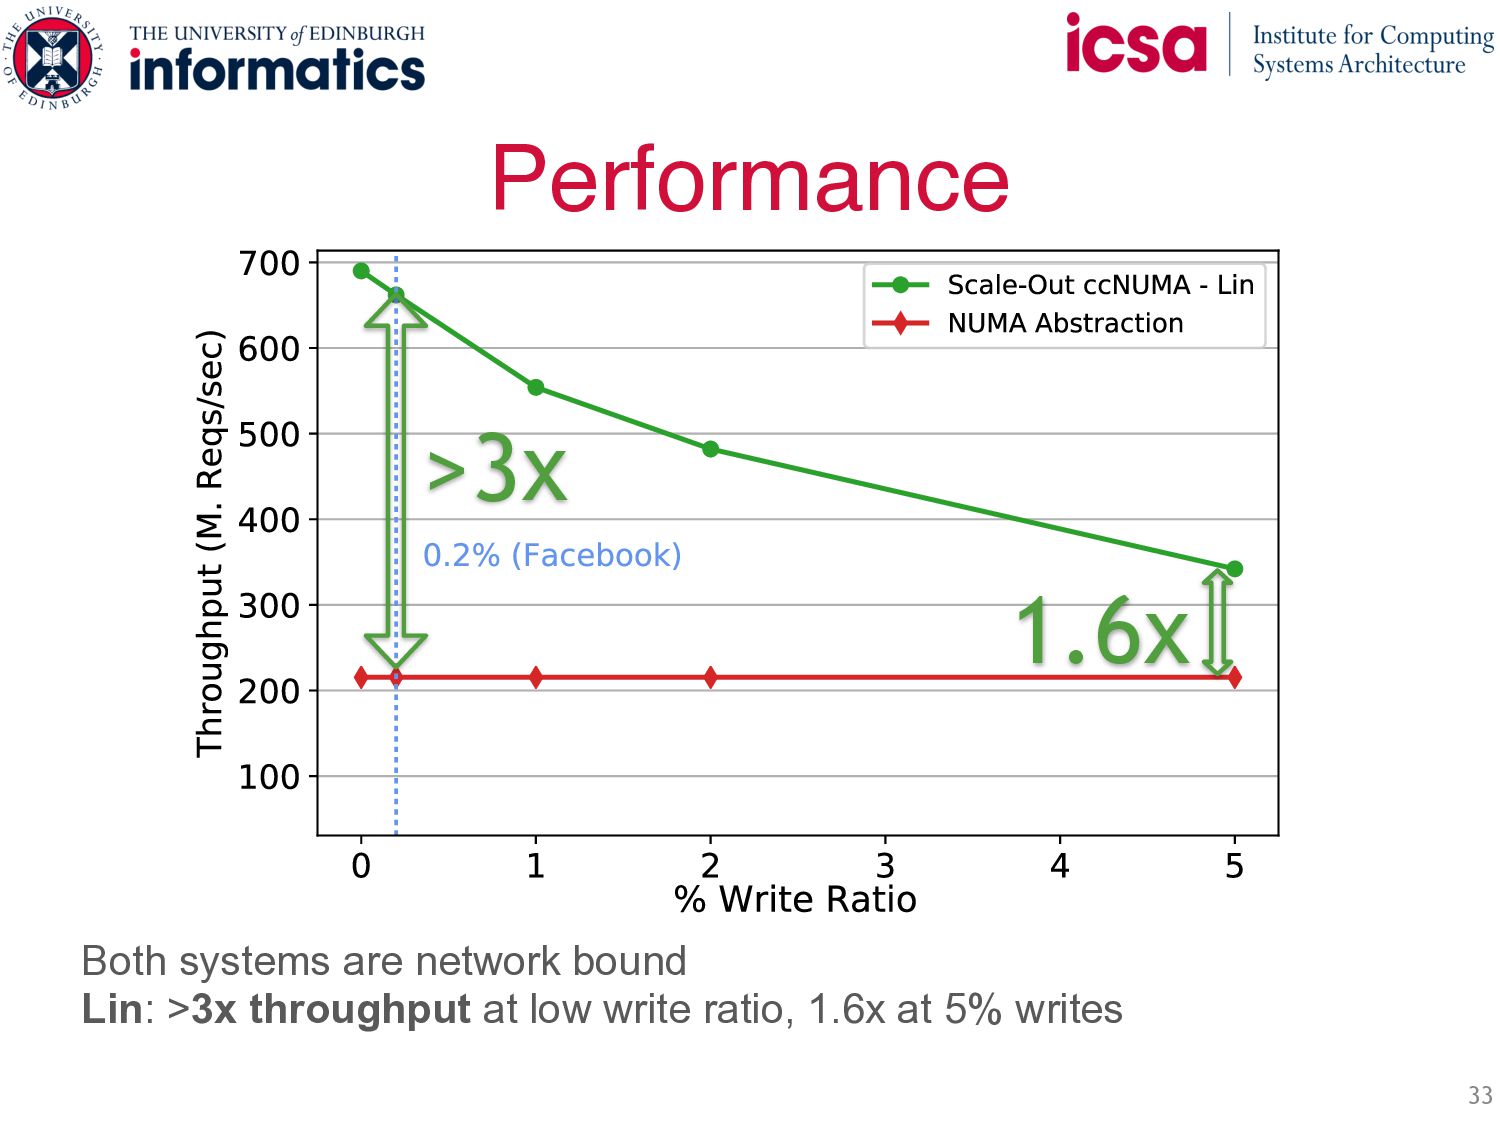
Performance 33 >3χ 1.6χ Both systems are network bound Lin:
>3x throughput at low write ratio, 1.6x at 5% writes -
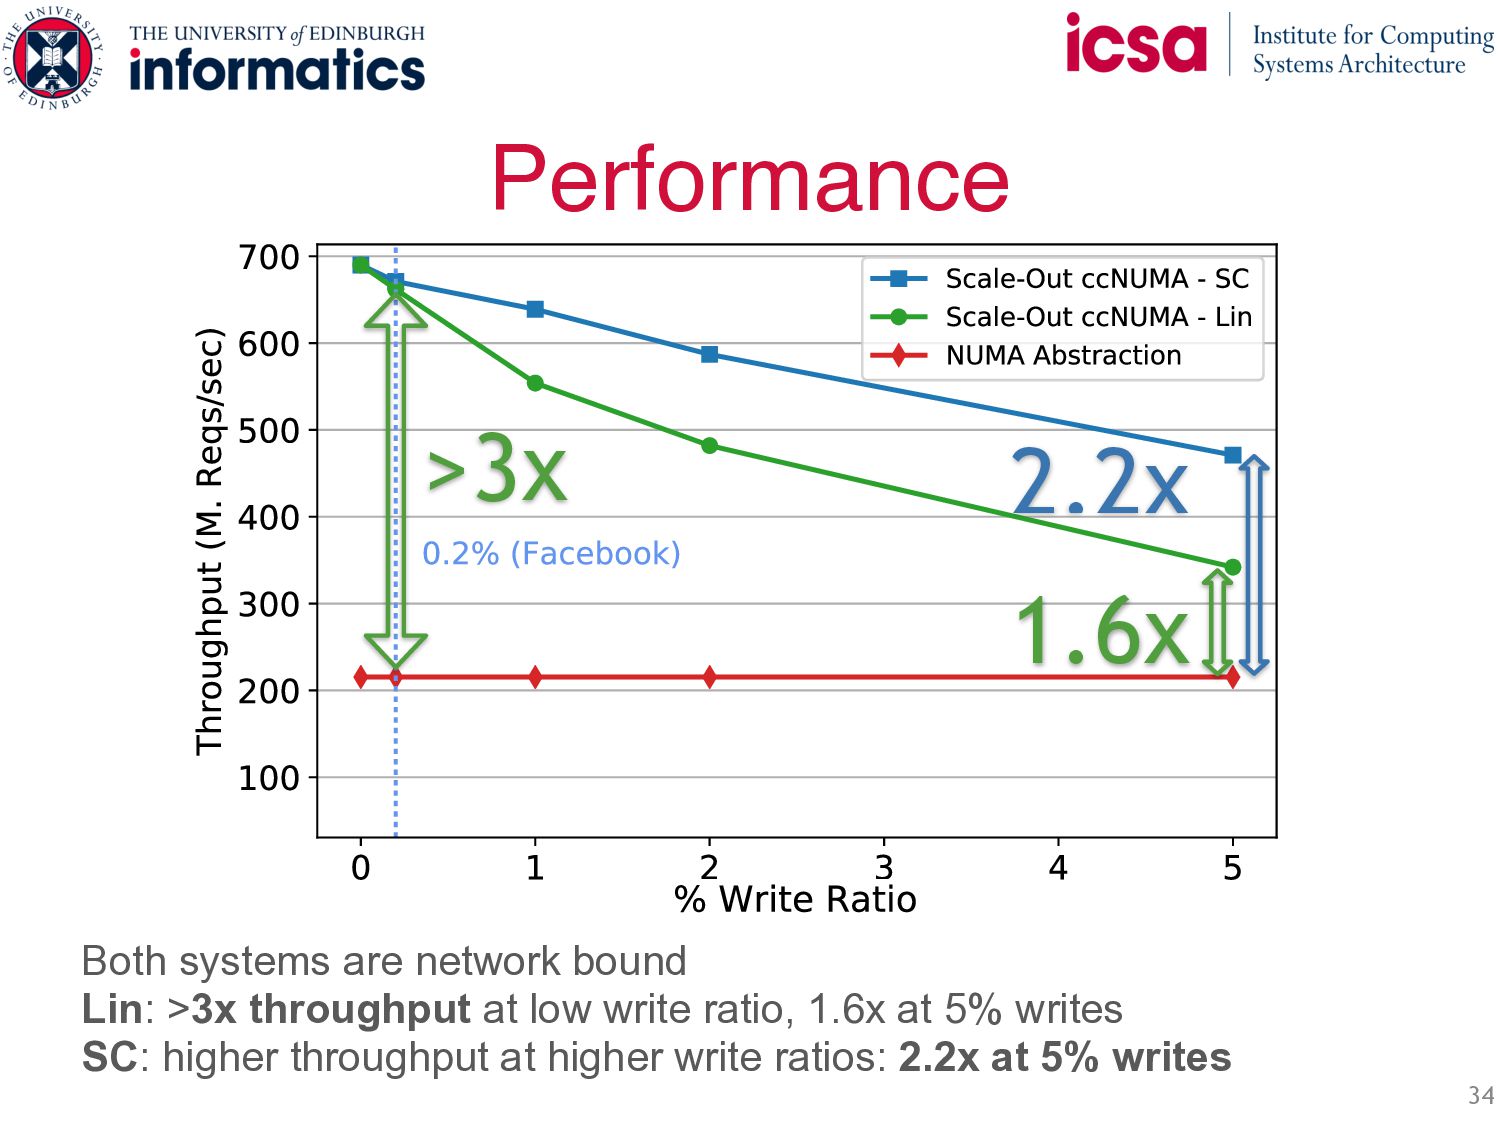
2.2χ Performance 34 Both systems are network bound Lin: >3x
throughput at low write ratio, 1.6x at 5% writes SC: higher throughput at higher write ratios: 2.2x at 5% writes >3χ 1.6χ -
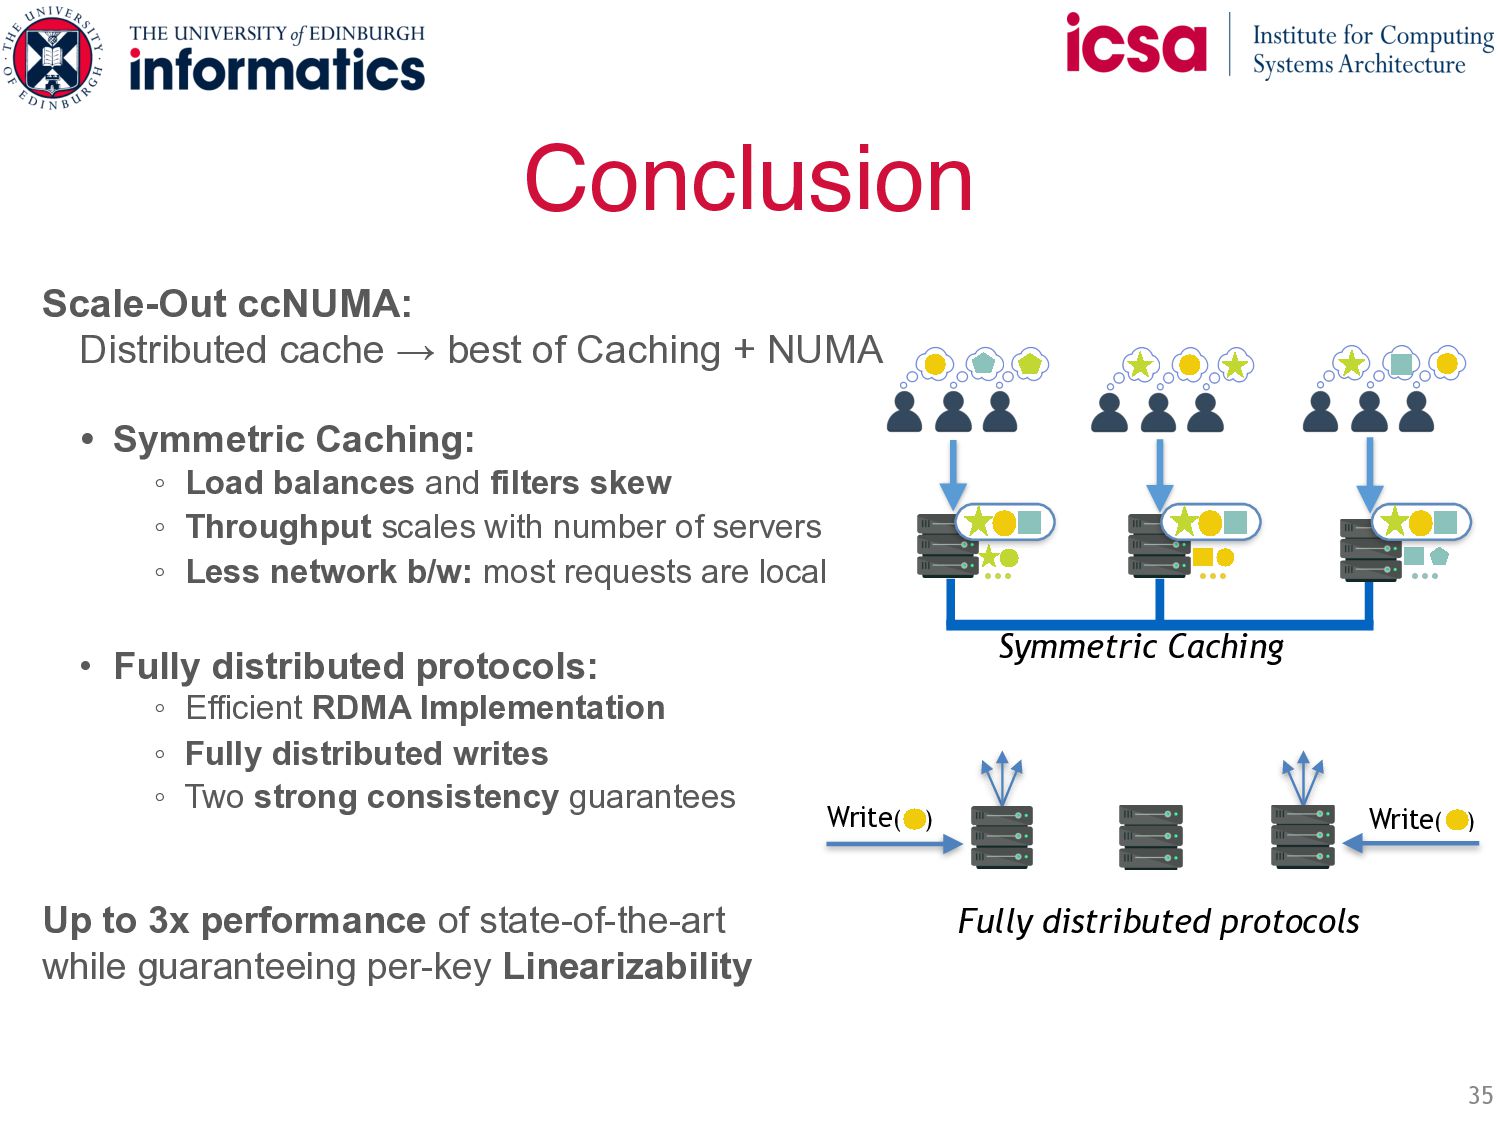
Conclusion 35 Scale-Out ccNUMA: Distributed cache → best of Caching
+ NUMA • Symmetric Caching: ◦ Load balances and filters skew ◦ Throughput scales with number of servers ◦ Less network b/w: most requests are local • Fully distributed protocols: ◦ Efficient RDMA Implementation ◦ Fully distributed writes ◦ Two strong consistency guarantees Up to 3x performance of state-of-the-art while guaranteeing per-key Linearizability Symmetric Caching Fully distributed protocols Write( ) Write( ) … … … -
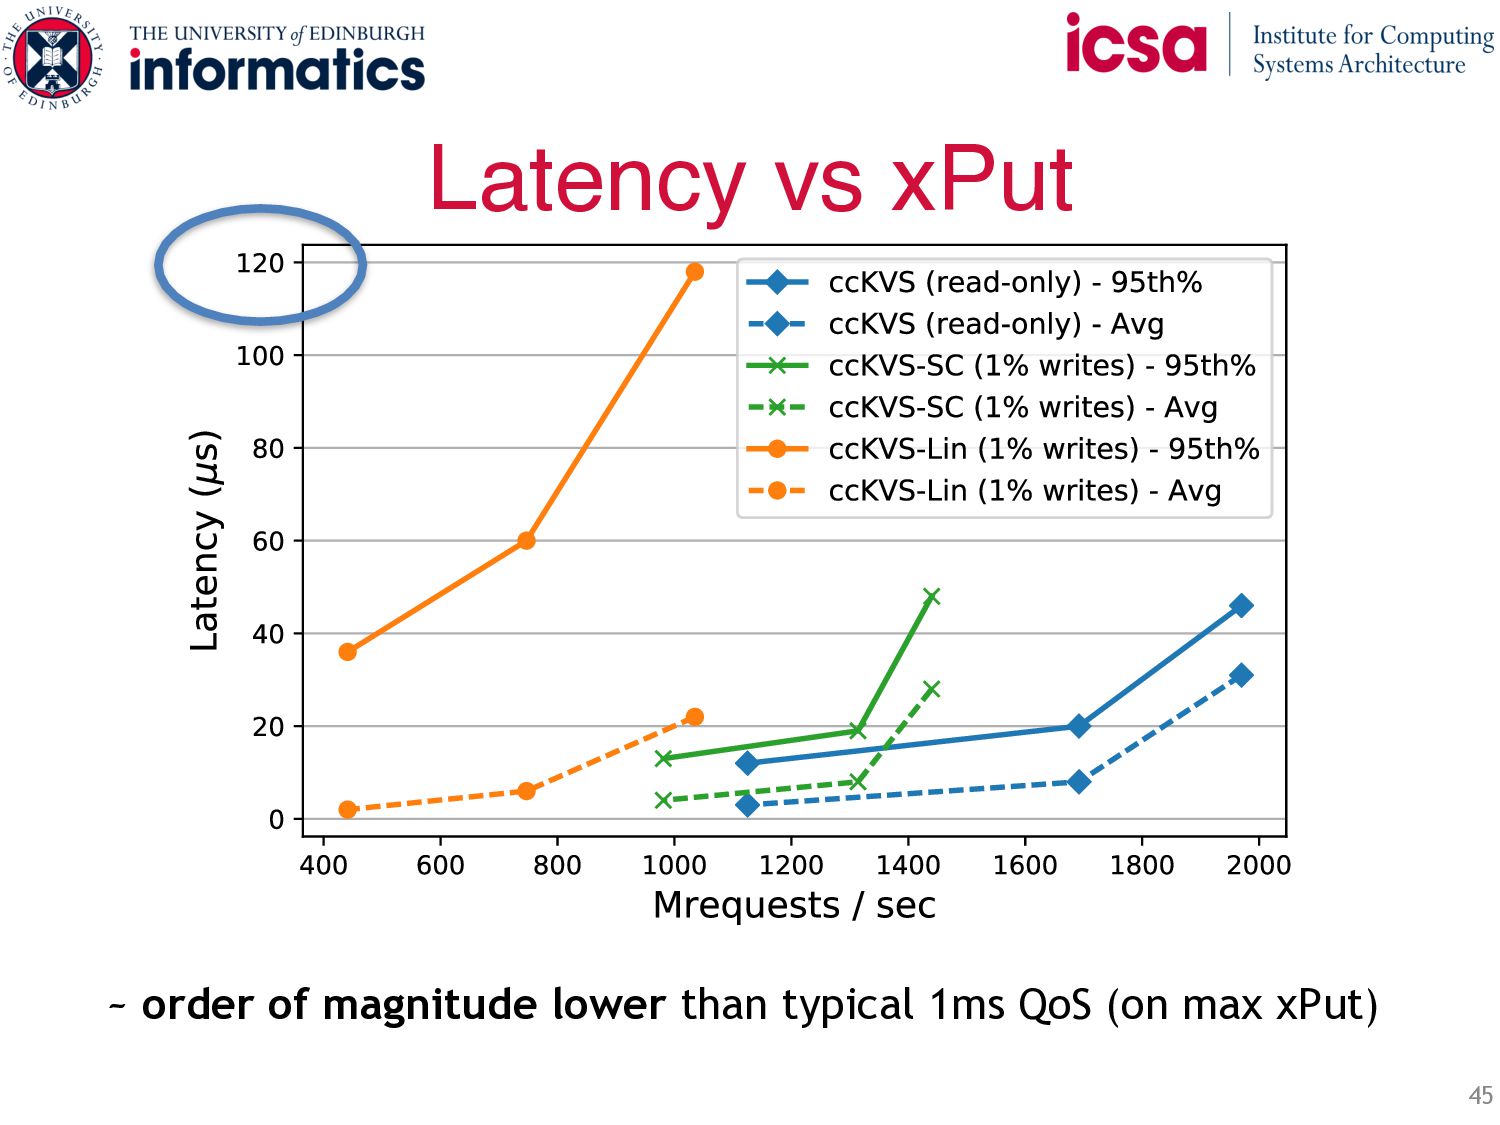
Latency vs xPut 45 ~ order of magnitude lower than
typical 1ms QoS (on max xPut)