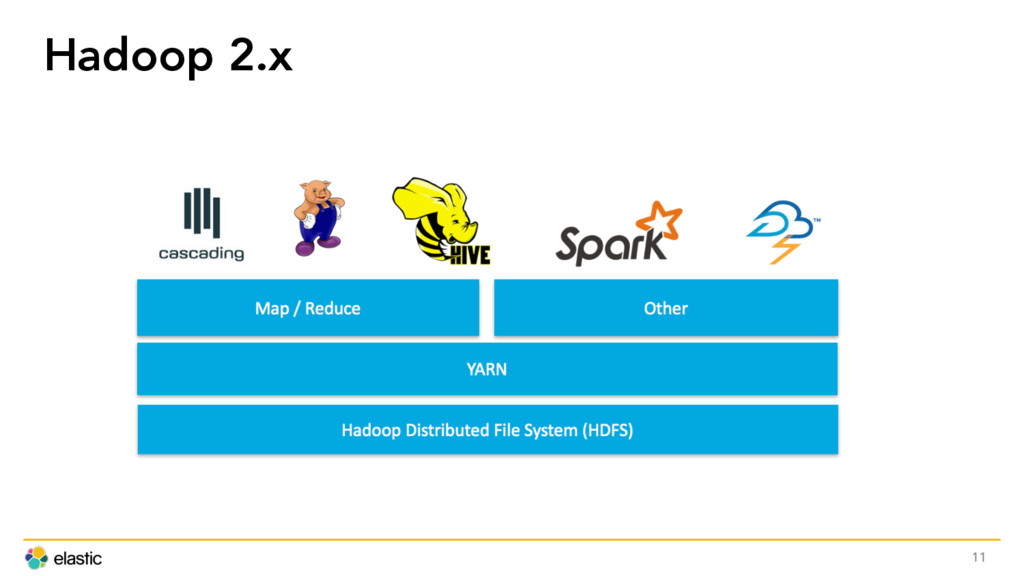
processing any and all data • Schema on read • Batch and Streaming, Multiple engines to analyze data • Powerful + Highly customizable programming frameworks • The ’Data lake’ paradigm • Cost effective 12
HDFS is sequential read/write • Indexing data for fast access and search • Tight integrations into real-time visualization • Easy real-time • Simple developer friendly APIs except Apache Spark 13
is sequential read/write • Indexing data for fast access and search • Tight integrations into real-time visualization • Easy real-time • Simple developer friendly APIs except Apache Spark 14
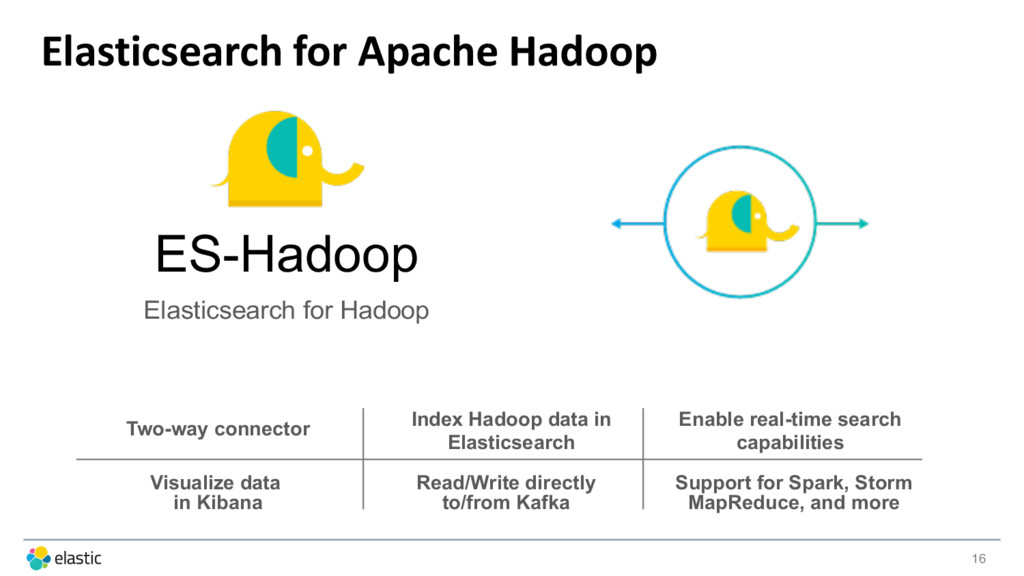
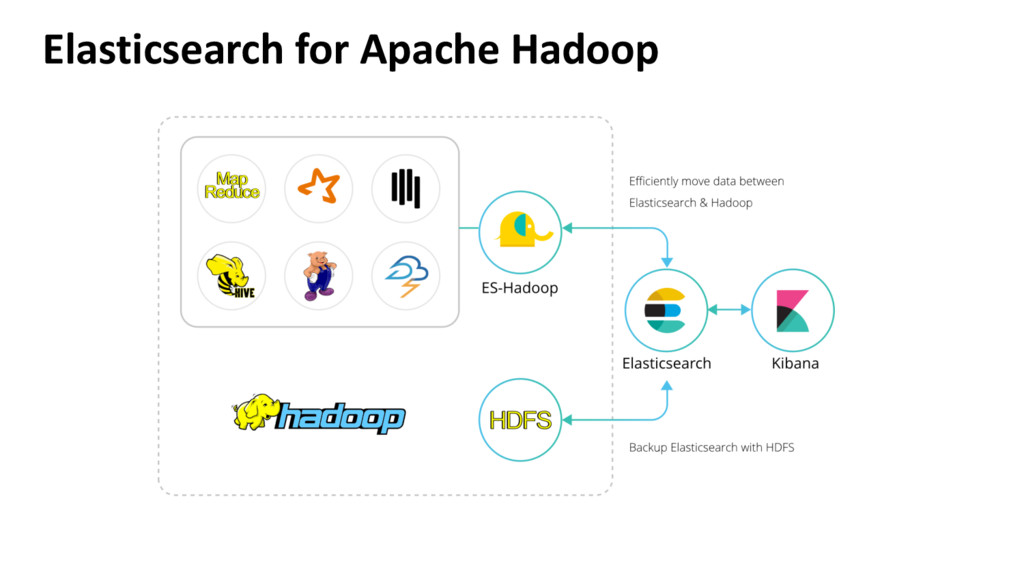
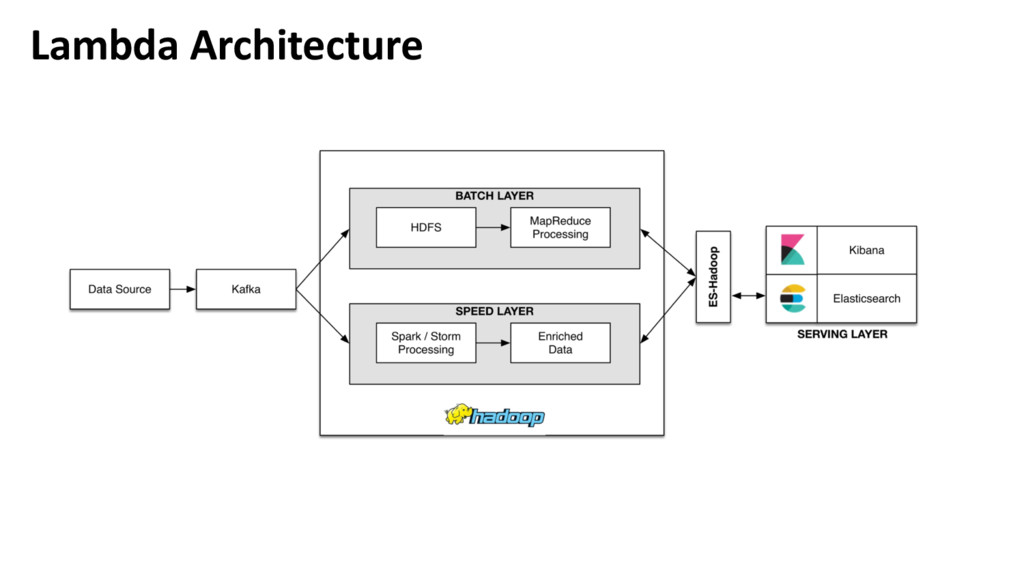
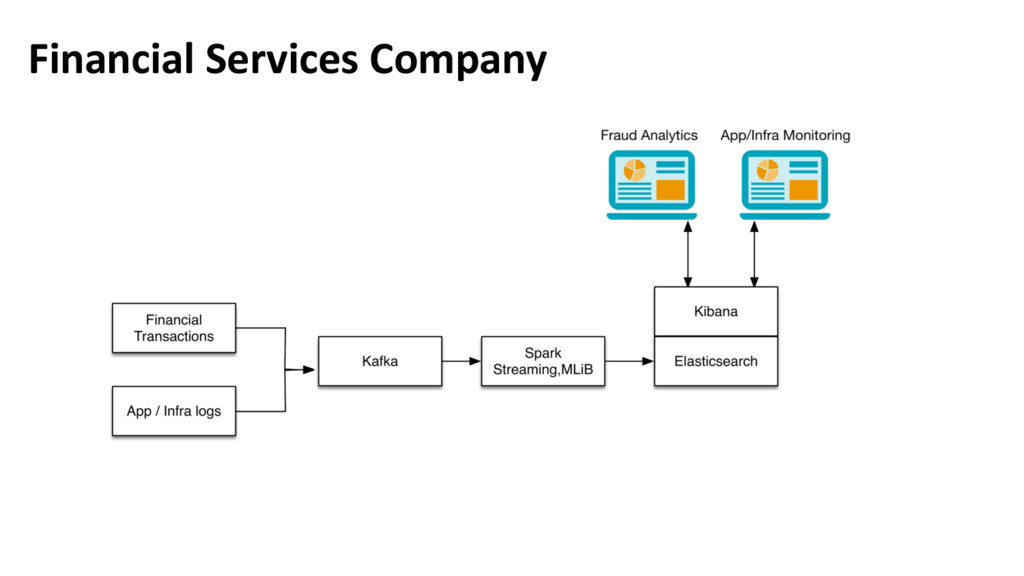
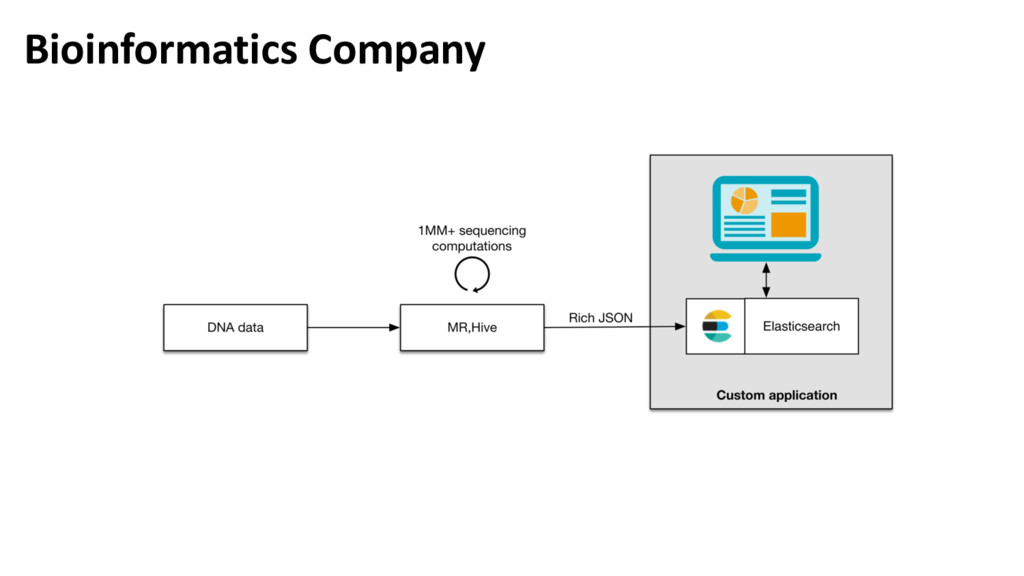
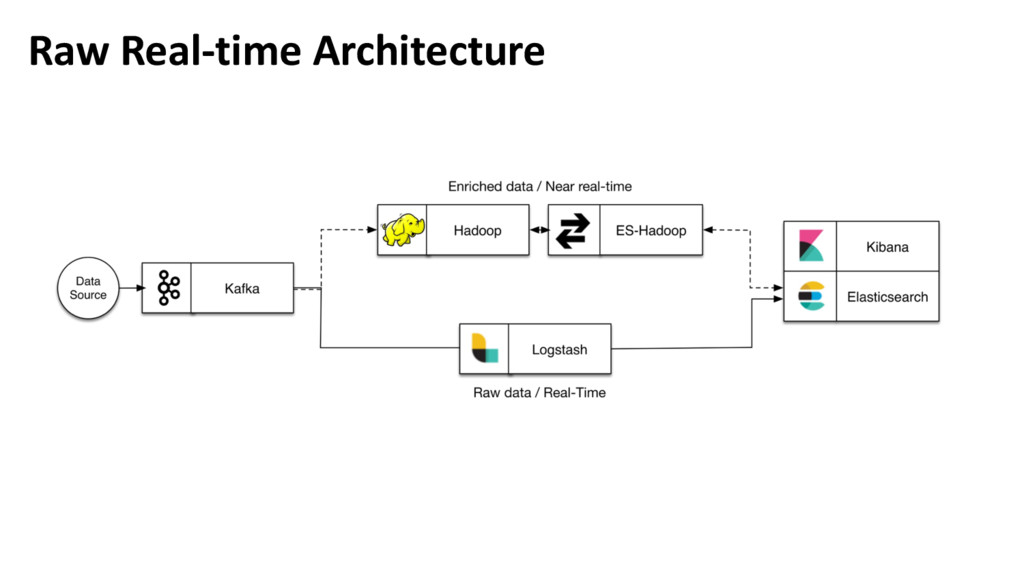
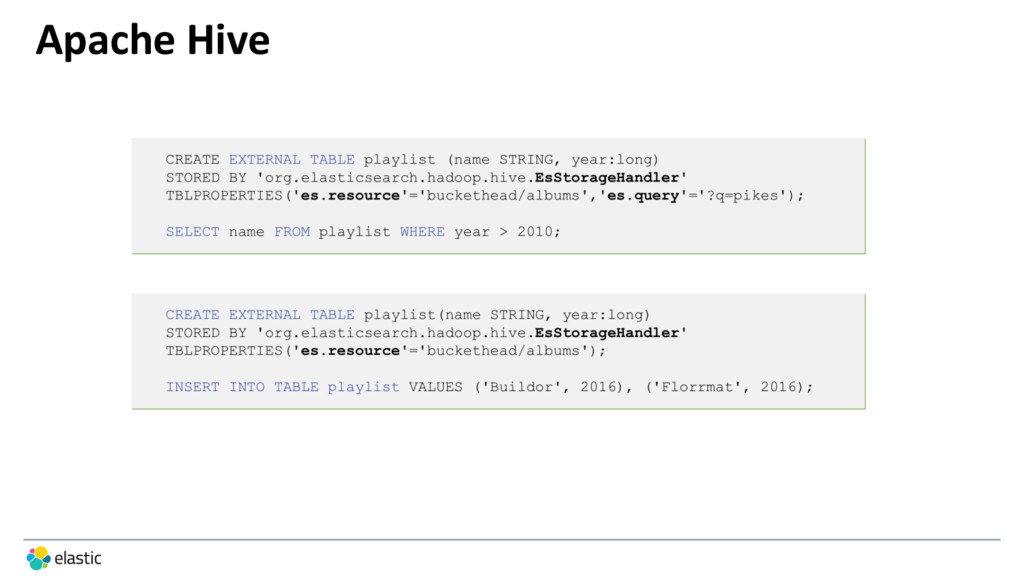
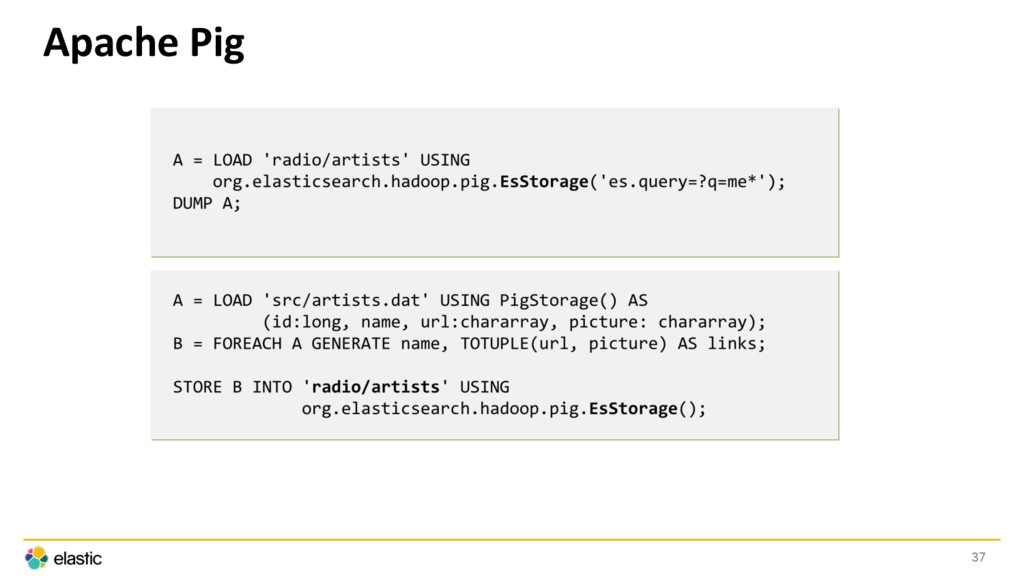
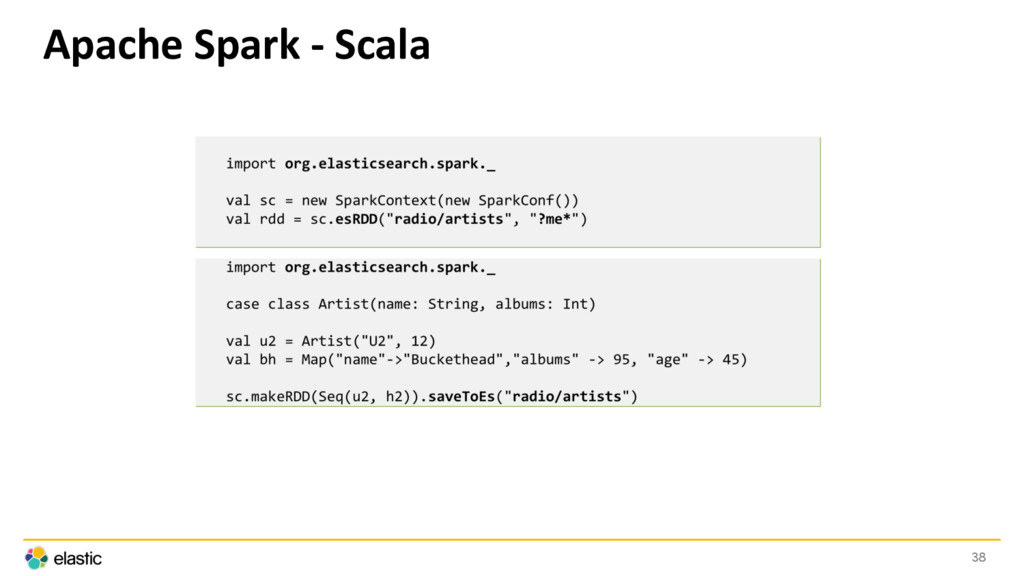
in Elasticsearch Enable real-time search capabilities Visualize data in Kibana Read/Write directly to/from Kafka Support for Spark, Storm MapReduce, and more Elasticsearch for Apache Hadoop
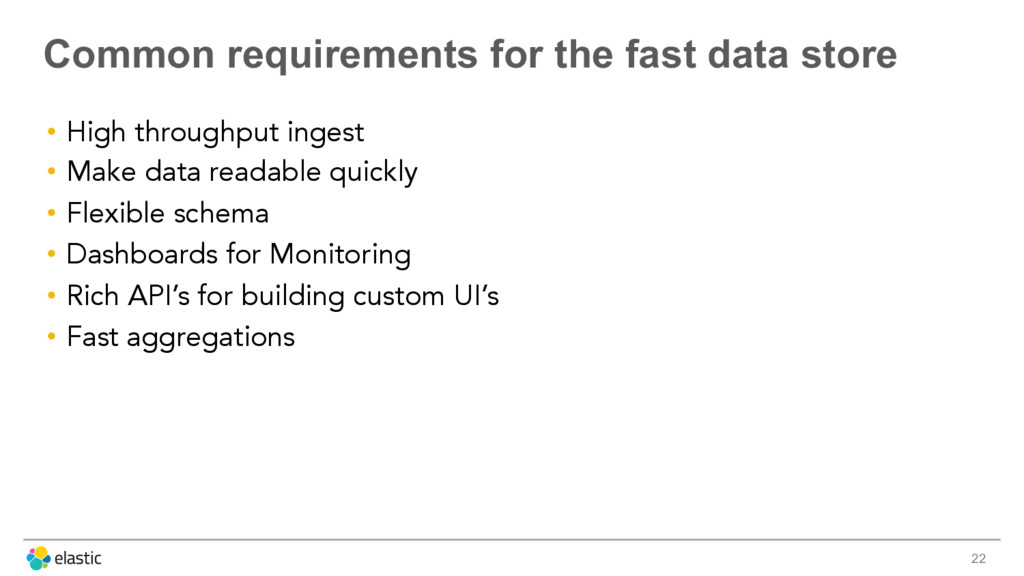
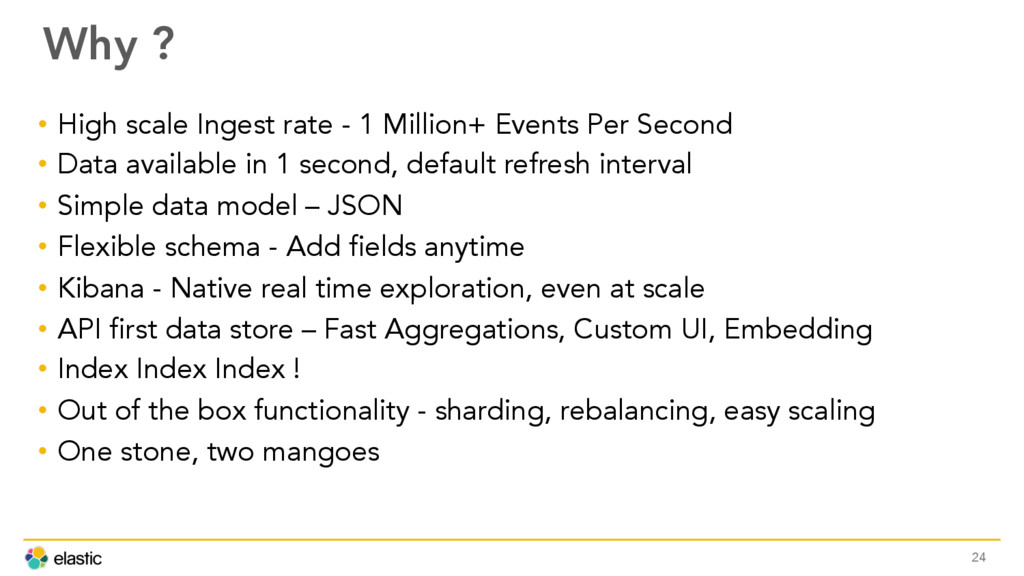
Events Per Second • Data available in 1 second, default refresh interval • Simple data model – JSON • Flexible schema - Add fields anytime • Kibana - Native real time exploration, even at scale • API first data store – Fast Aggregations, Custom UI, Embedding • Index Index Index ! • Out of the box functionality - sharding, rebalancing, easy scaling • One stone, two mangoes 24


 anoops
 yuuuuuuu168
 raspython3
 riyaamemiya
 akitoshiga
 occhi
 puhitaku
 daidaidai
 kworkdev
 kentapapa
 oikon48
 terurou
 ivry_presentationmaterials
 nwiizo
 katarinadahlin
 ivargrimstad
 baasie
 letsgokoyo
 palkan
 tmiket
 inesmontani
 eileencodes
 morganepeng
 addyosmani
 chriscoyier