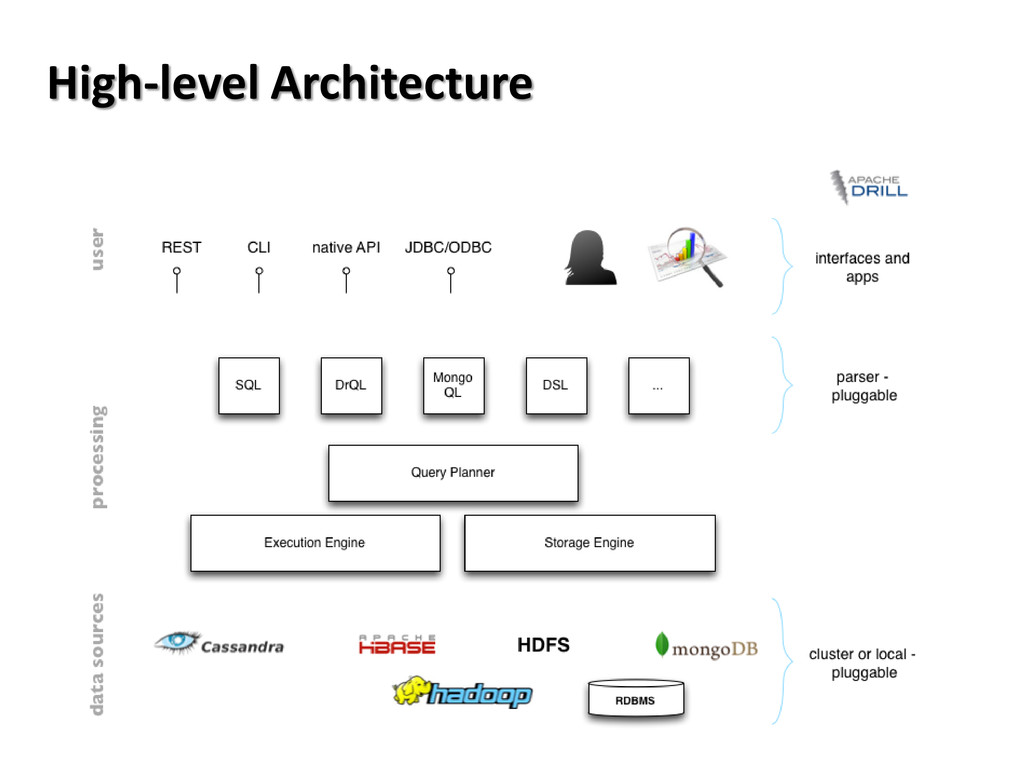
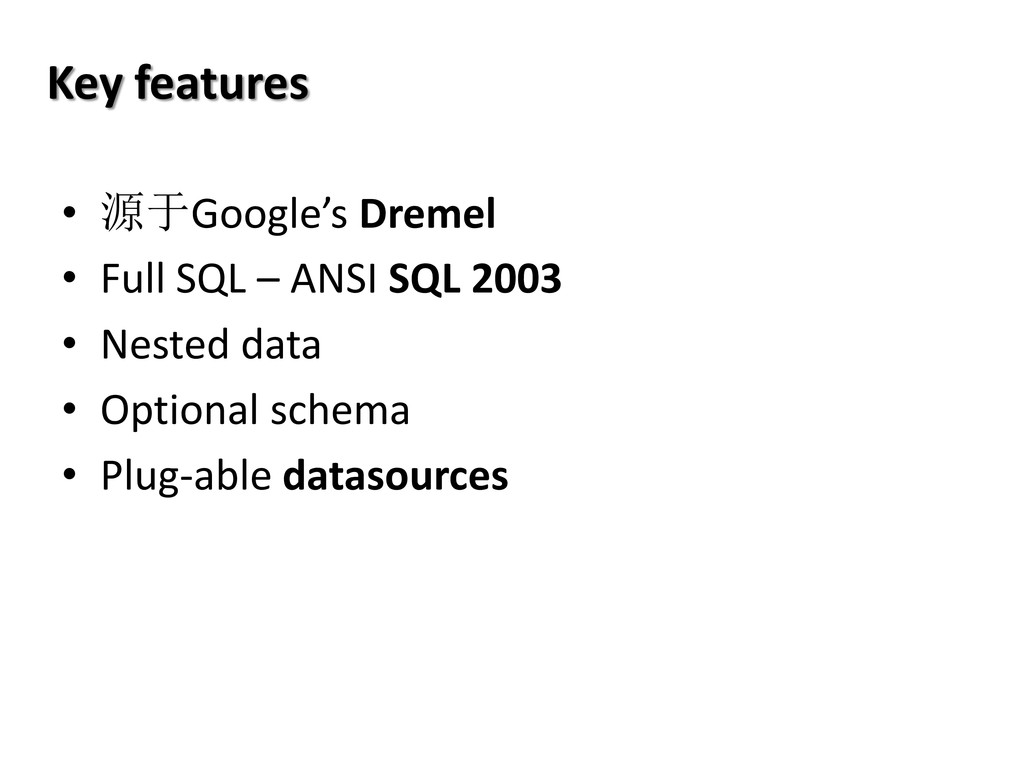
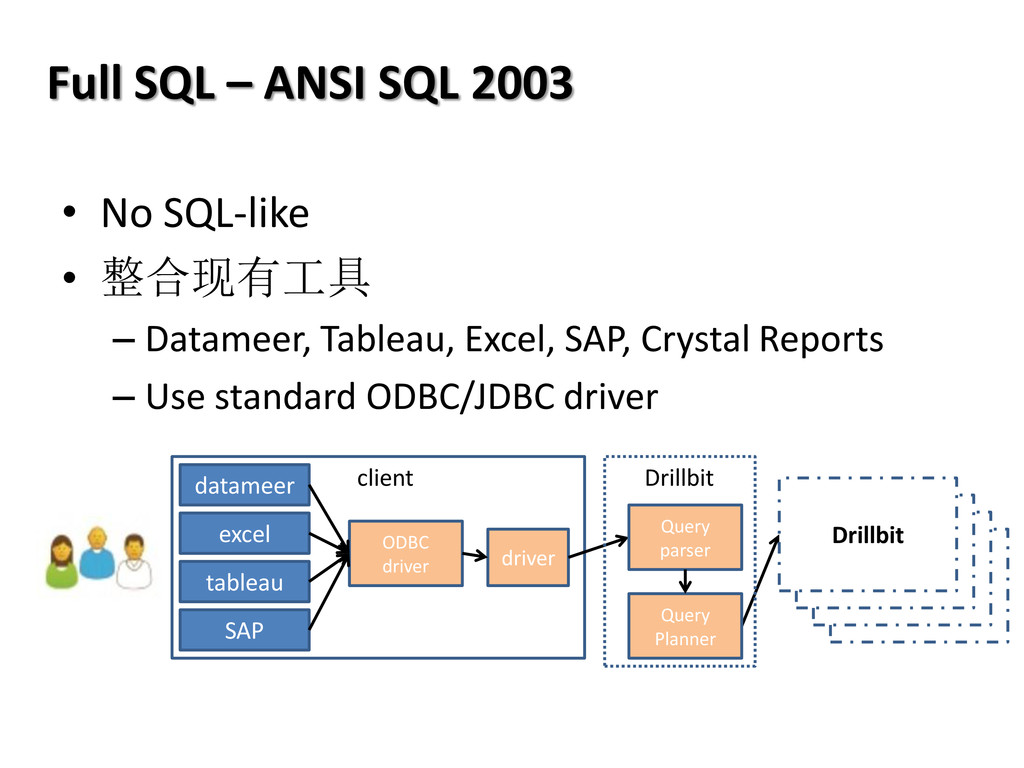
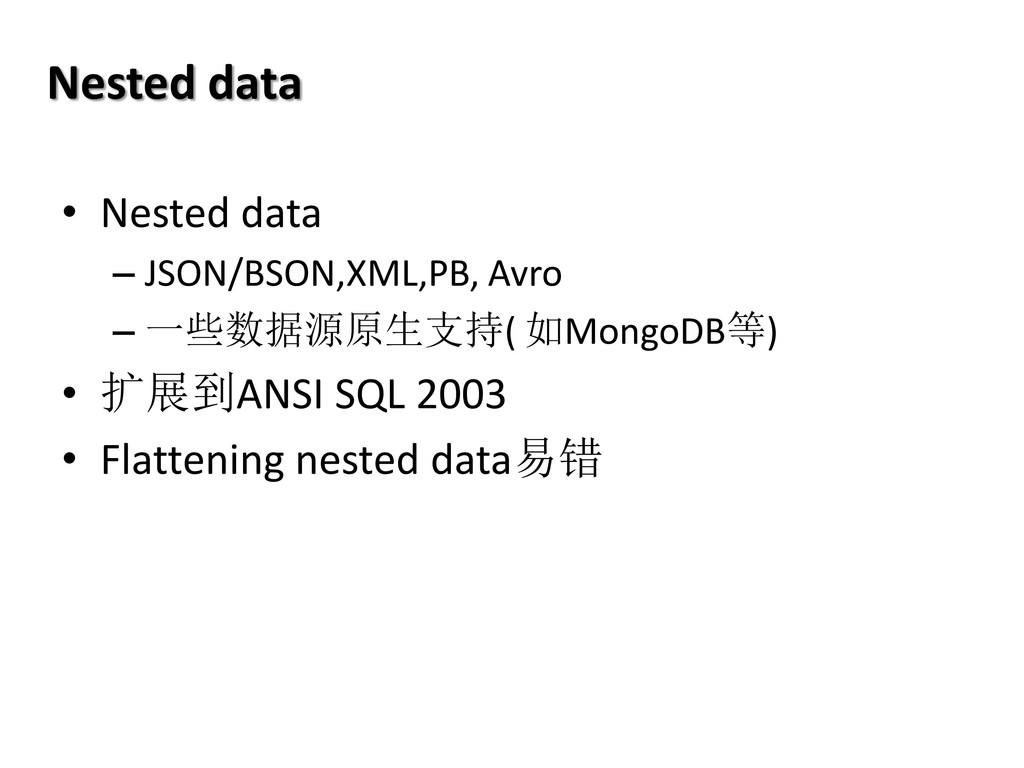
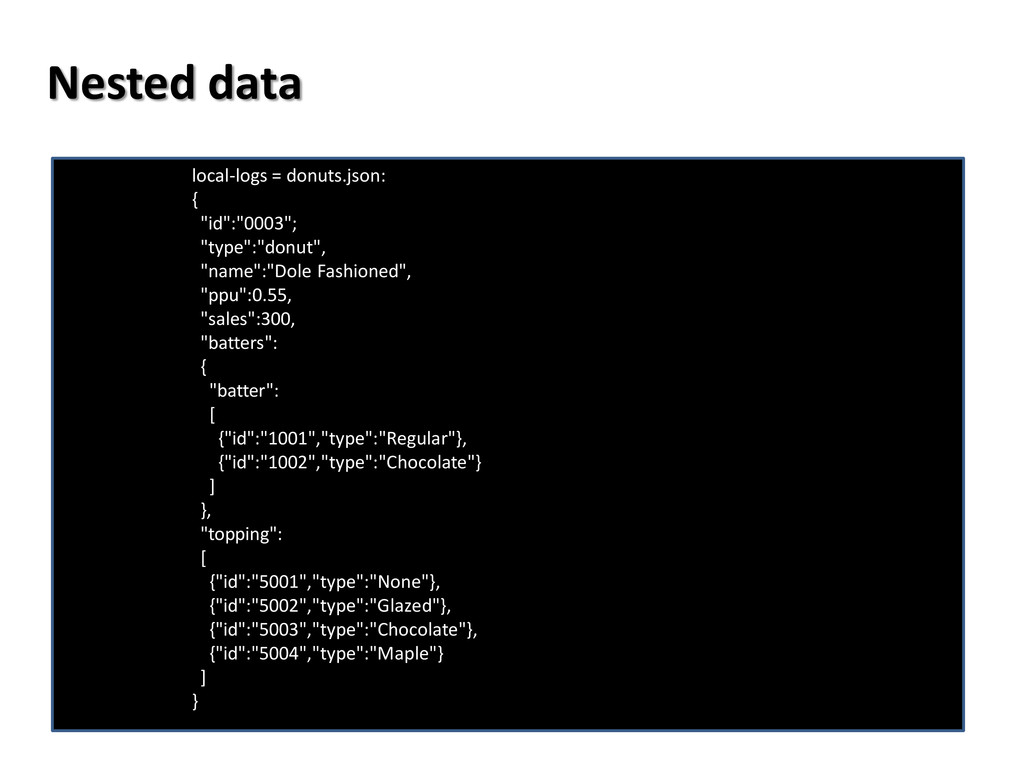
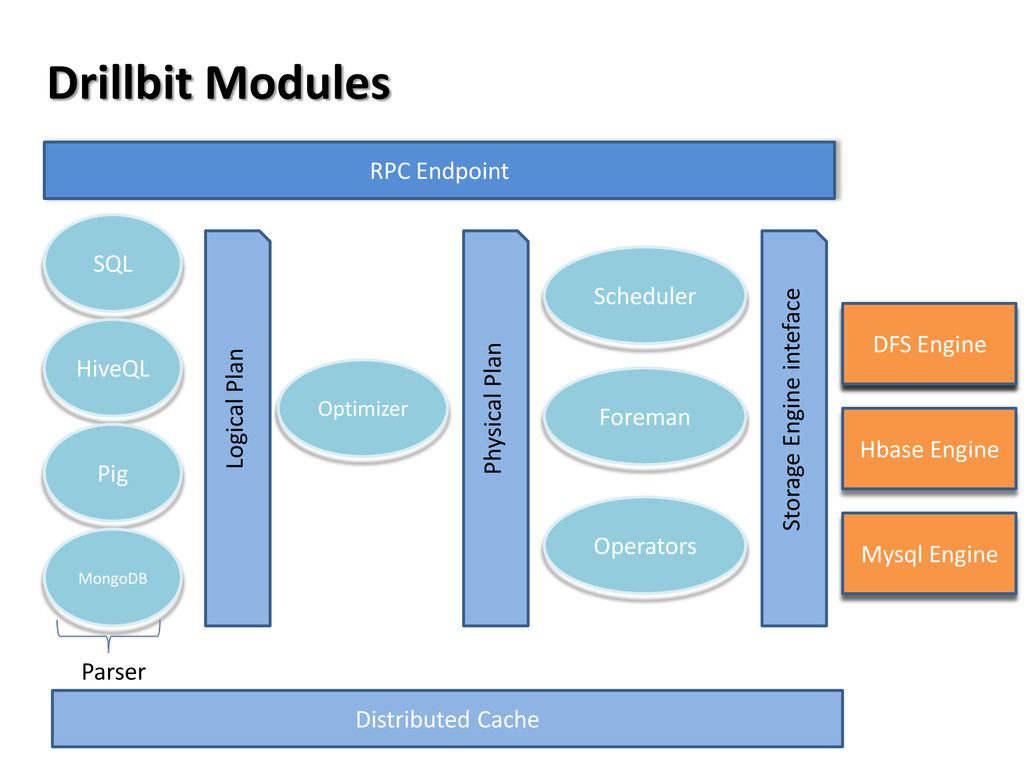
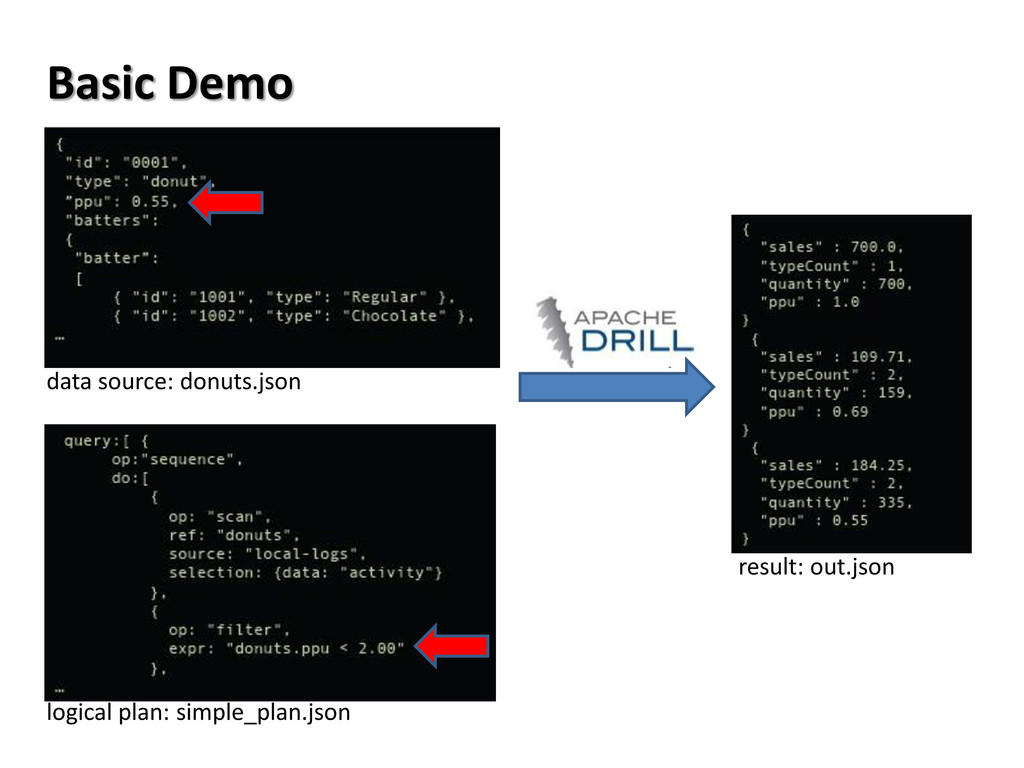
latency ad-hoc queries to many different data sources, including nested data. Inspired by Google's Dremel, Drill is designed to scale to 10,000 servers and query petabytes of data in seconds. Flexible and Extensible Architecture Well-documented APIs and interface allow for fast additions of new data sources and file formats. New query languages and operators are also easy to add to Drill.
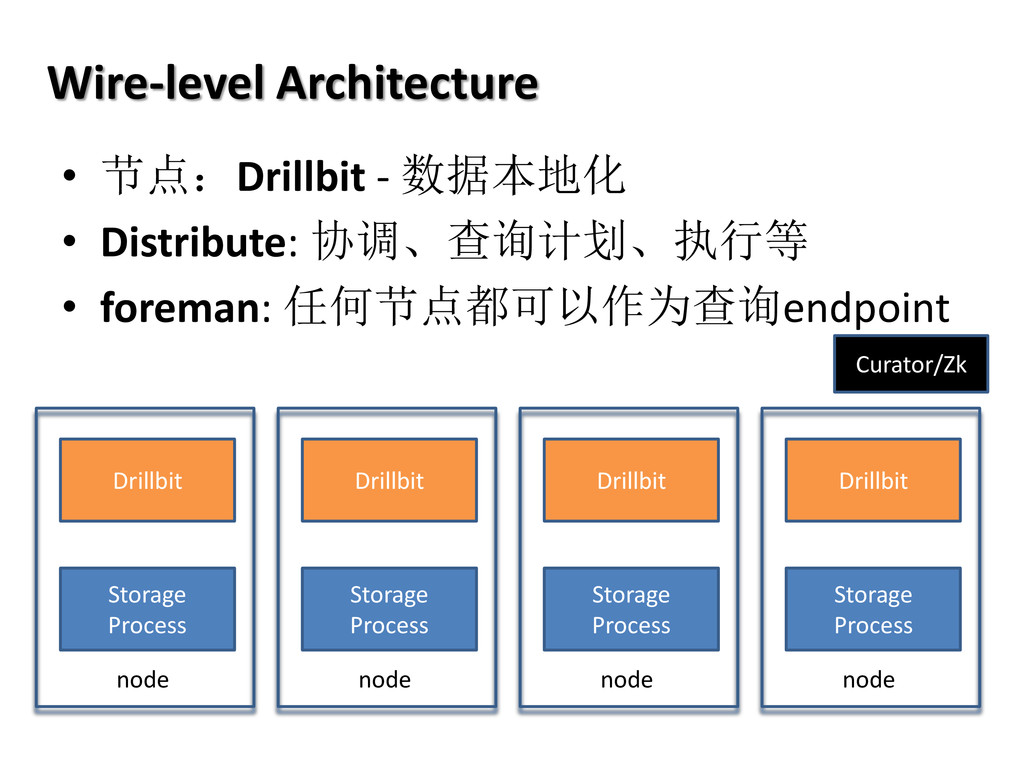
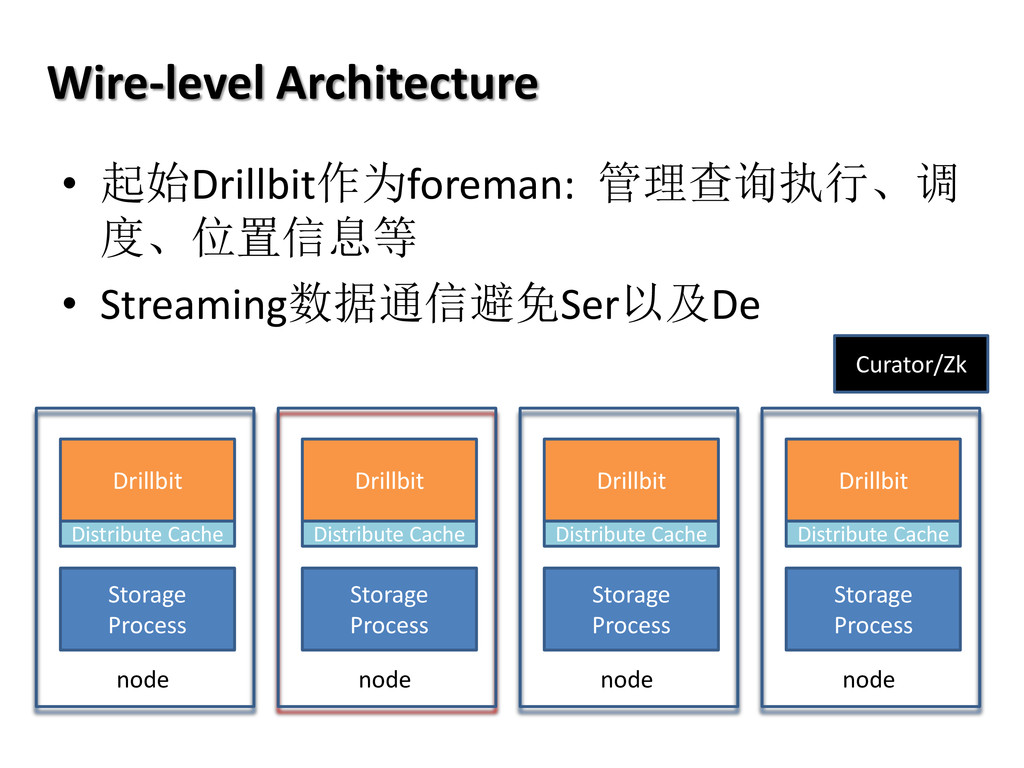
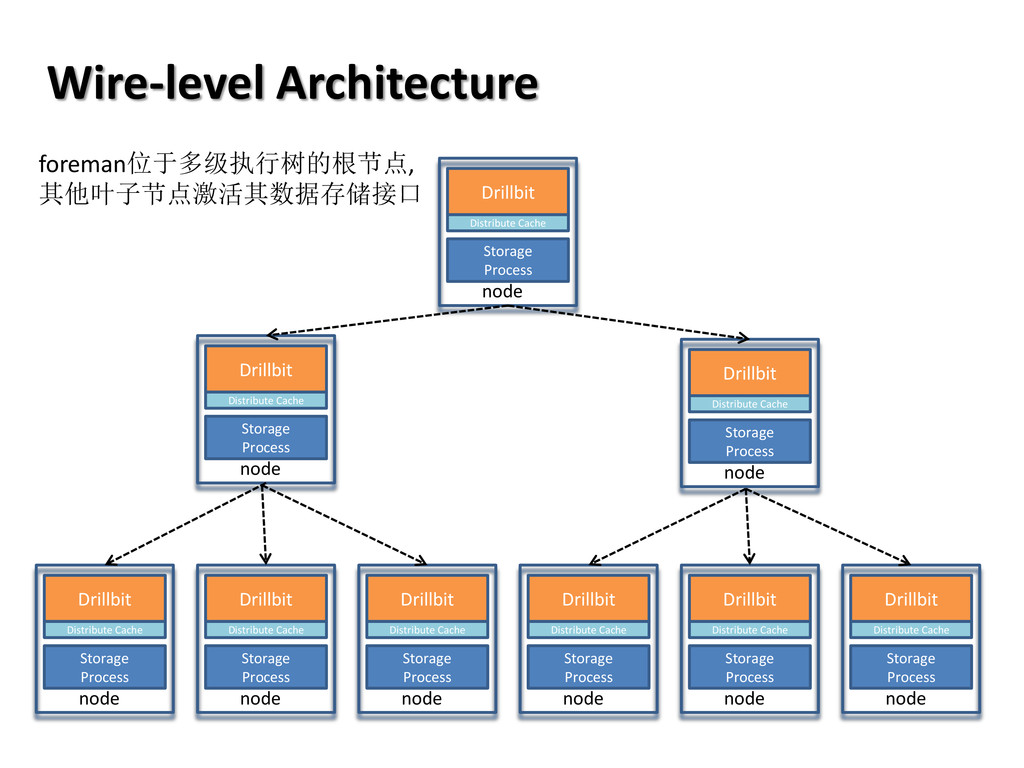
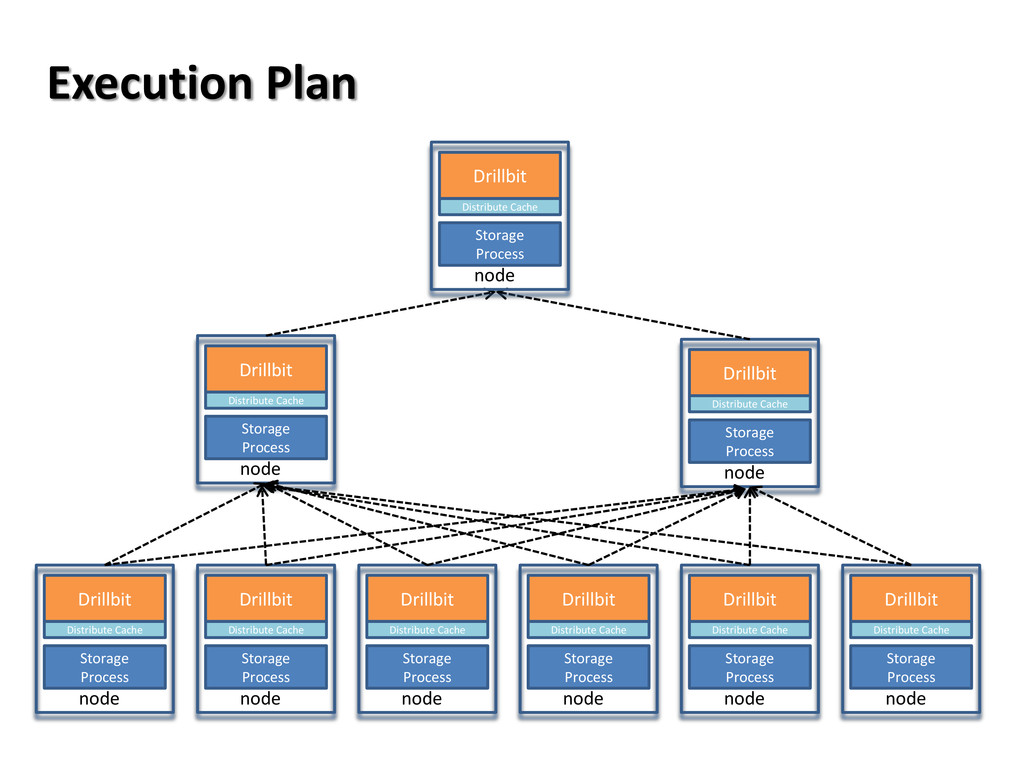
Drillbit Storage Process node Drillbit Storage Process node Drillbit Storage Process node Drillbit Storage Process node Curator/Zk Wire-level Architecture
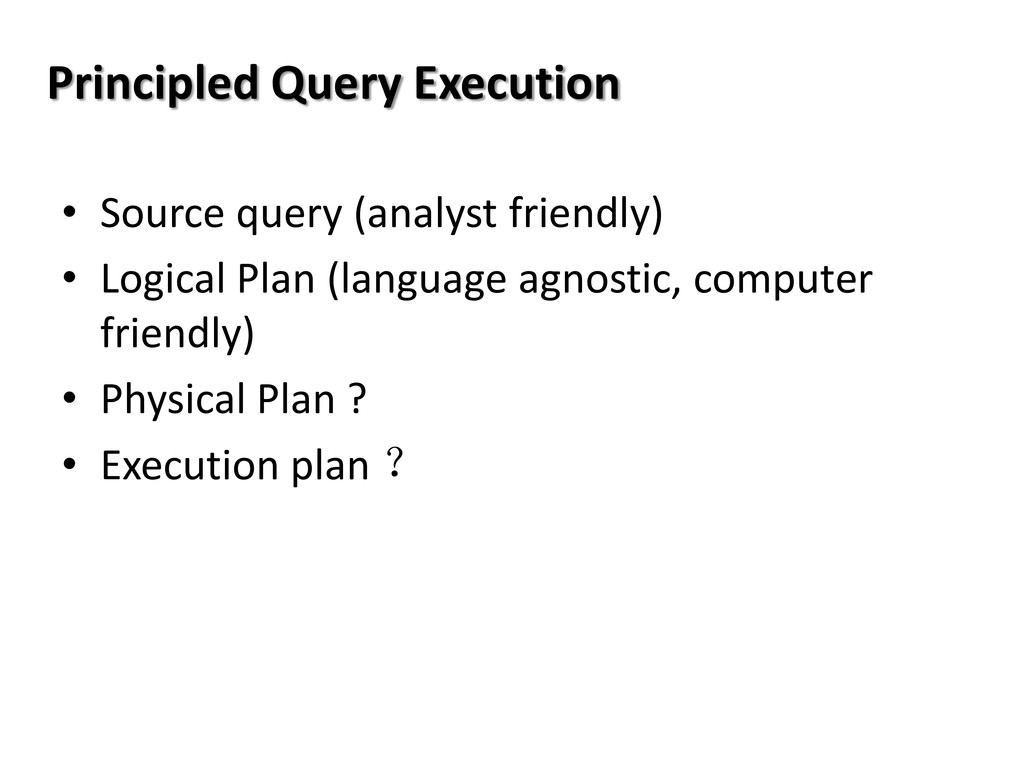
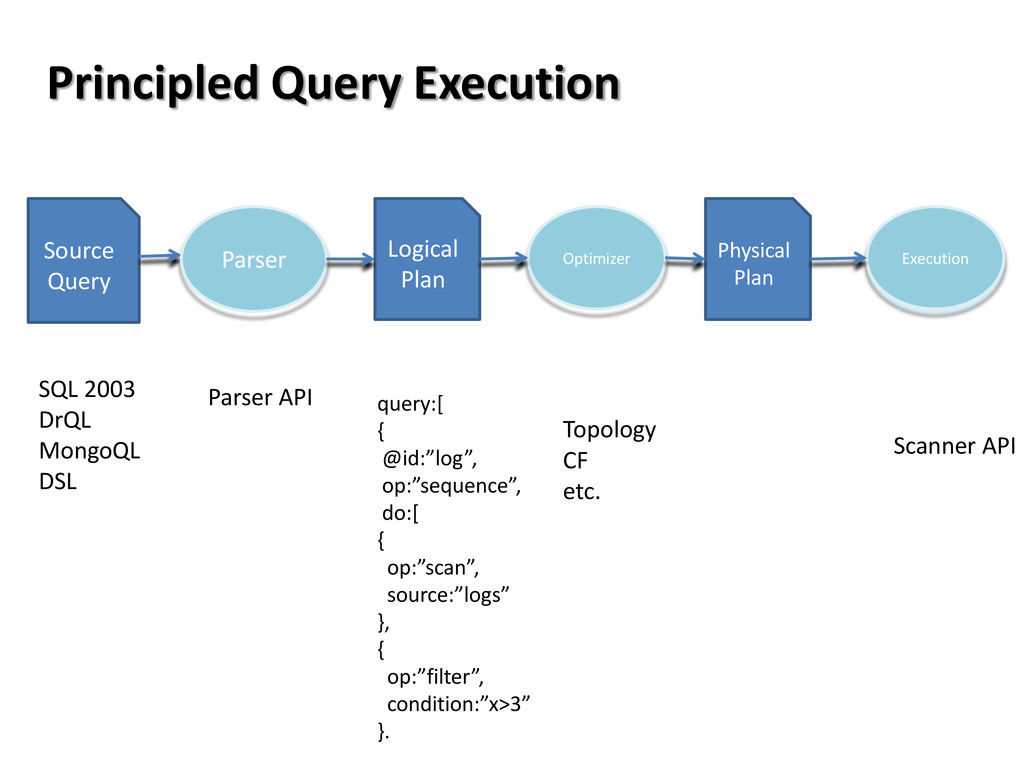
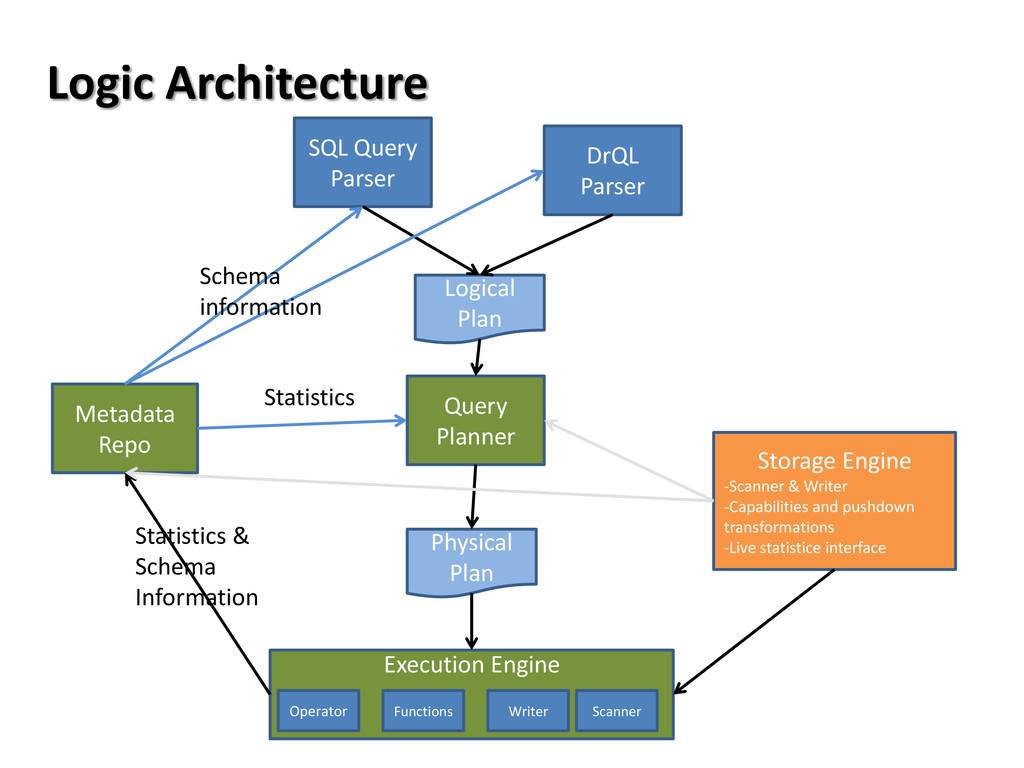
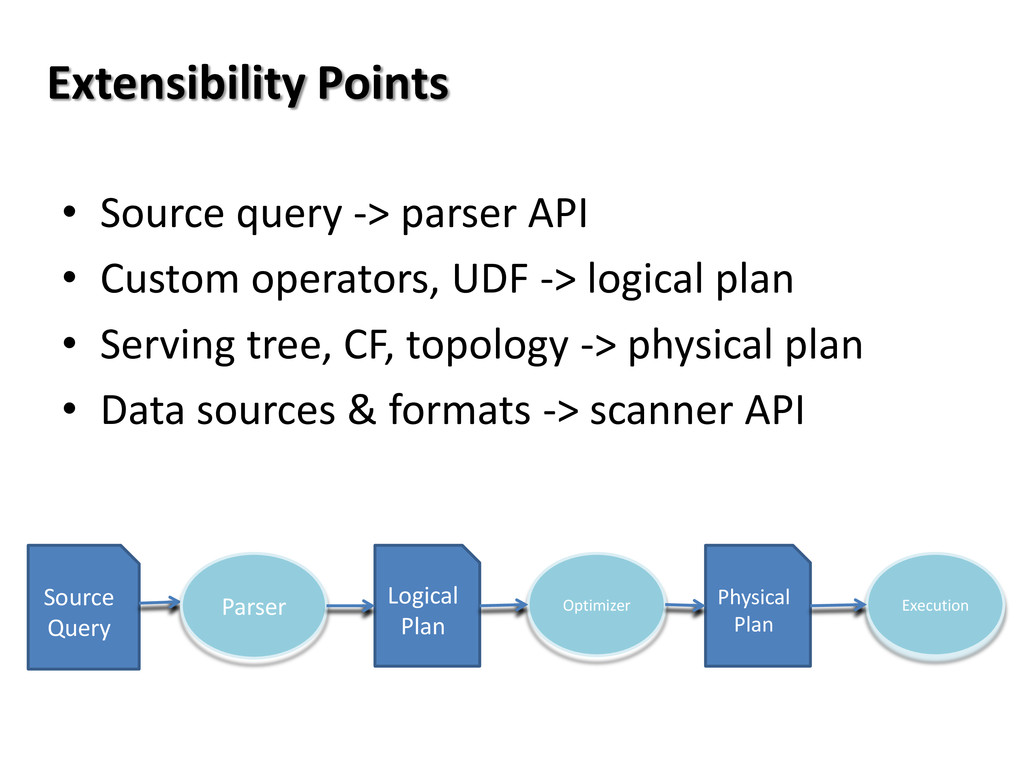
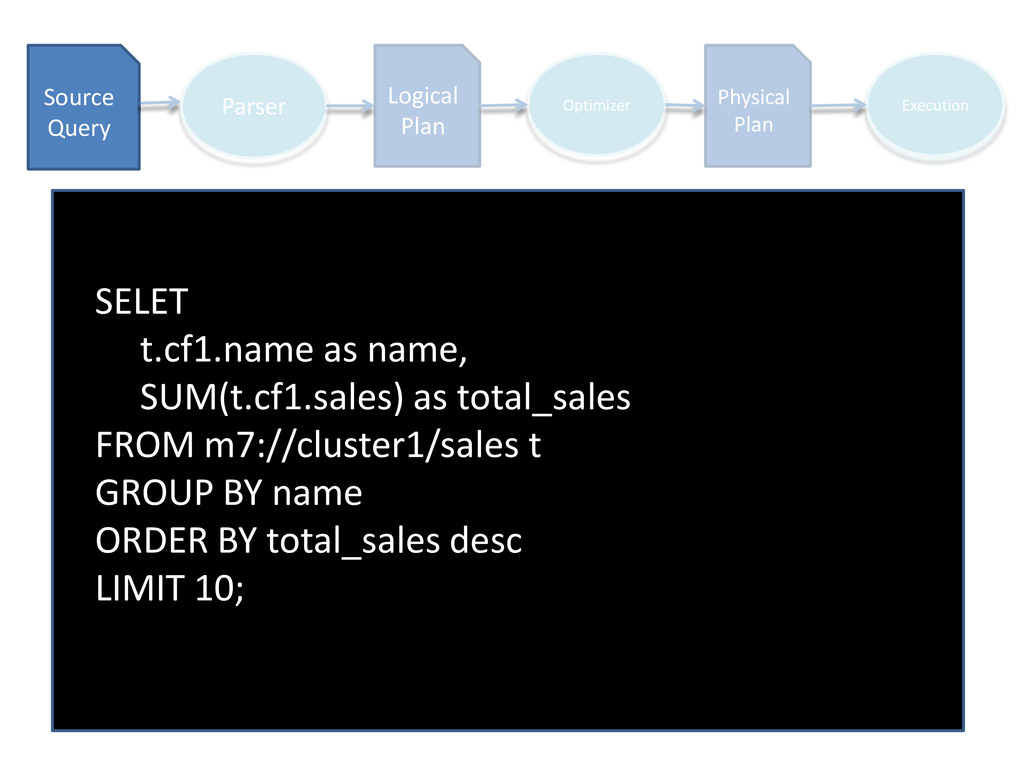
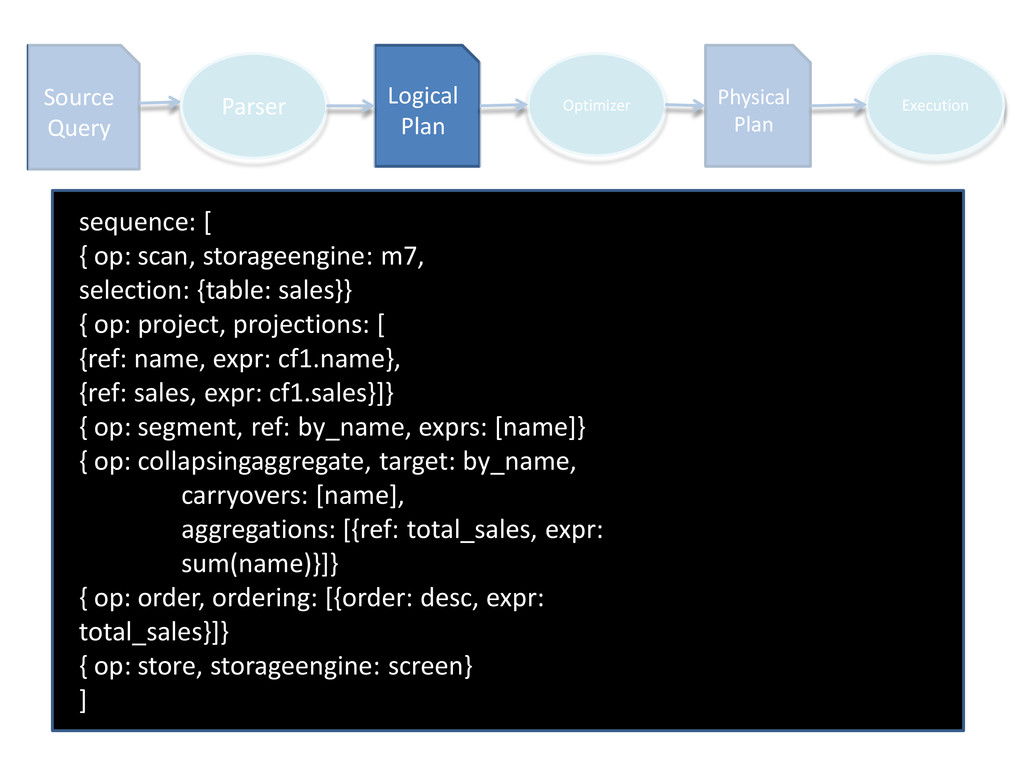
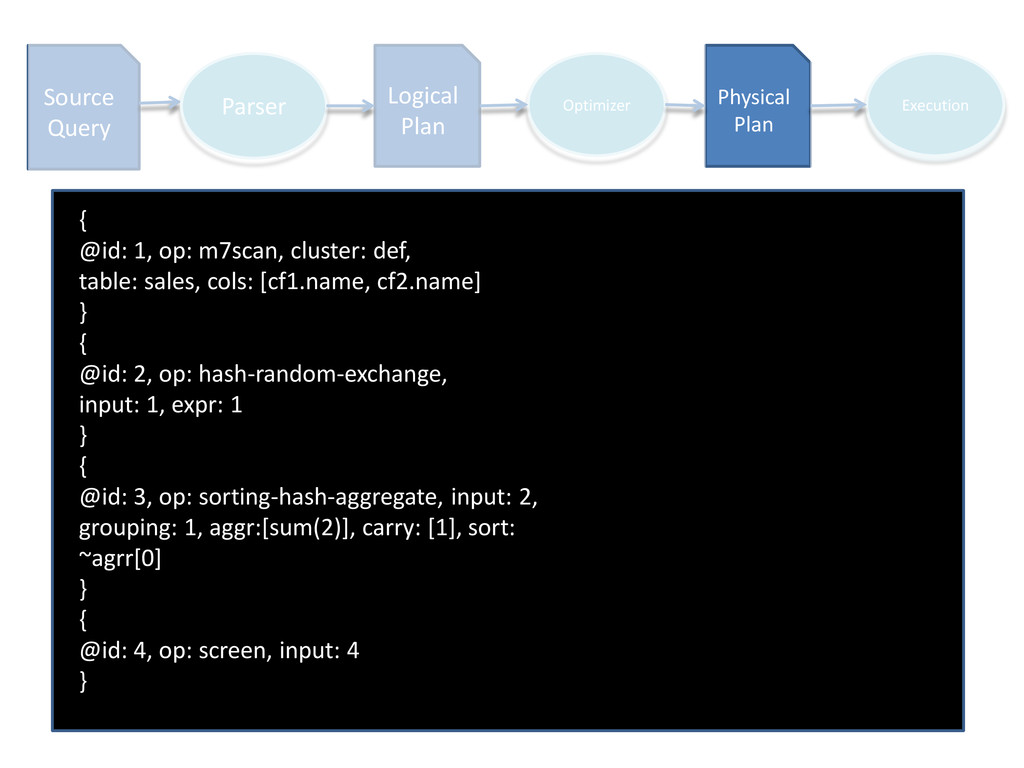
-> logical plan • Serving tree, CF, topology -> physical plan • Data sources & formats -> scanner API Source Query Parser Logical Plan Optimizer Physical Plan Execution Extensibility Points
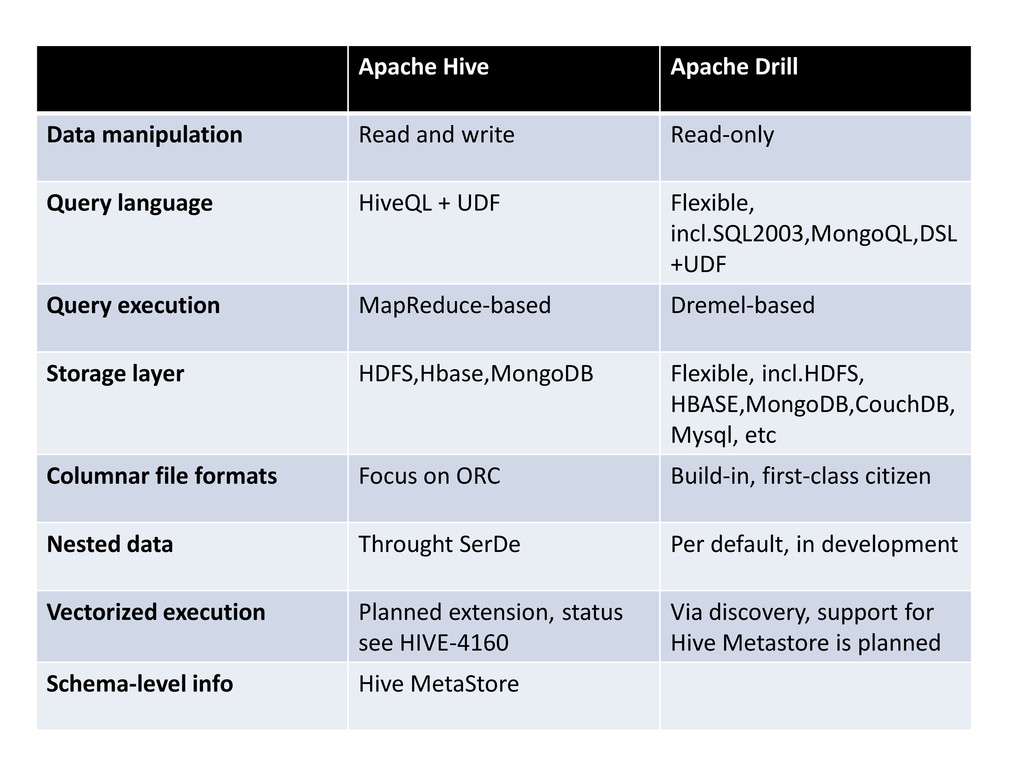
Query language HiveQL + UDF Flexible, incl.SQL2003,MongoQL,DSL +UDF Query execution MapReduce-based Dremel-based Storage layer HDFS,Hbase,MongoDB Flexible, incl.HDFS, HBASE,MongoDB,CouchDB, Mysql, etc Columnar file formats Focus on ORC Build-in, first-class citizen Nested data Throught SerDe Per default, in development Vectorized execution Planned extension, status see HIVE-4160 Via discovery, support for Hive Metastore is planned Schema-level info Hive MetaStore
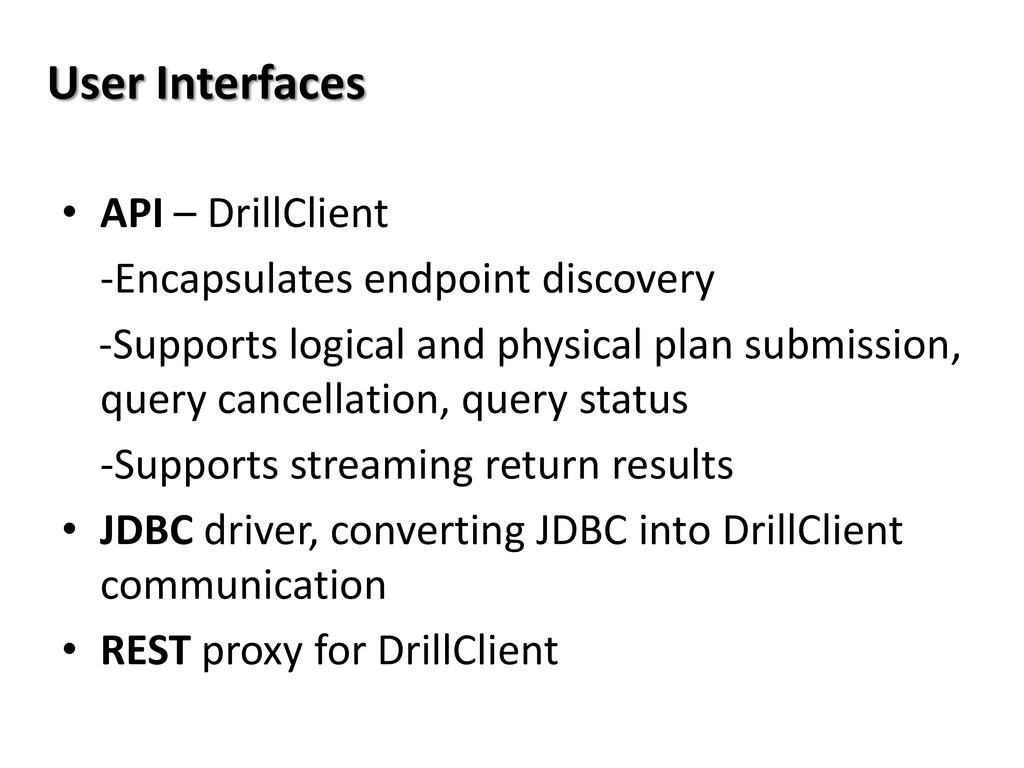
physical plan submission, query cancellation, query status -Supports streaming return results • JDBC driver, converting JDBC into DrillClient communication • REST proxy for DrillClient User Interfaces
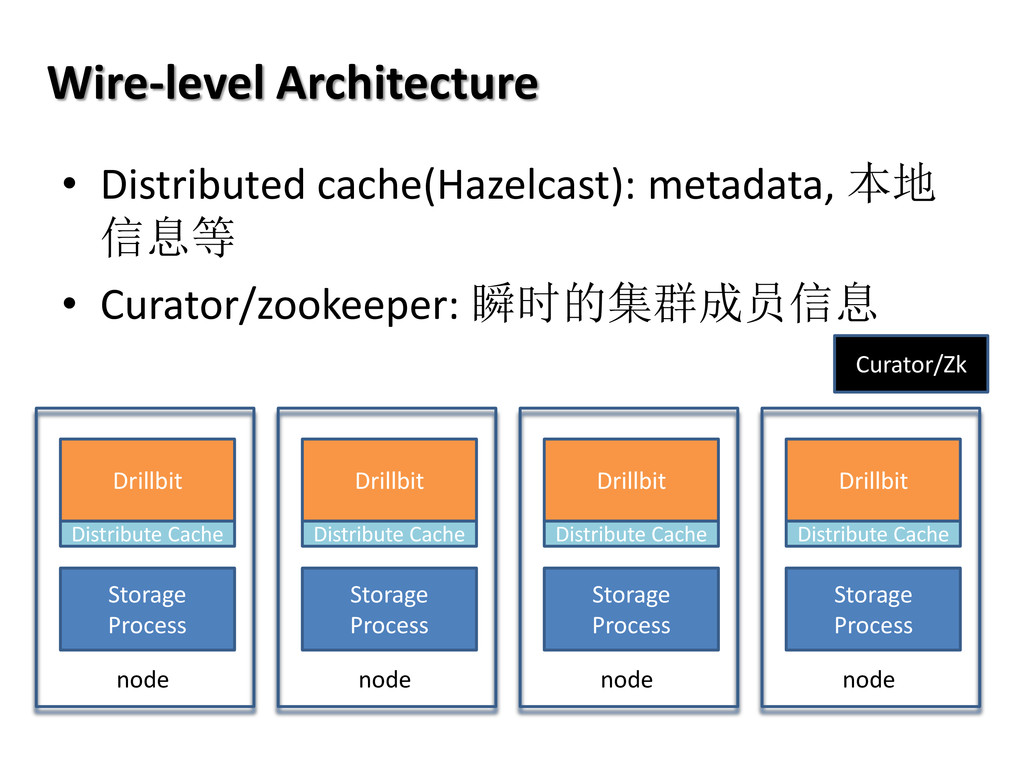
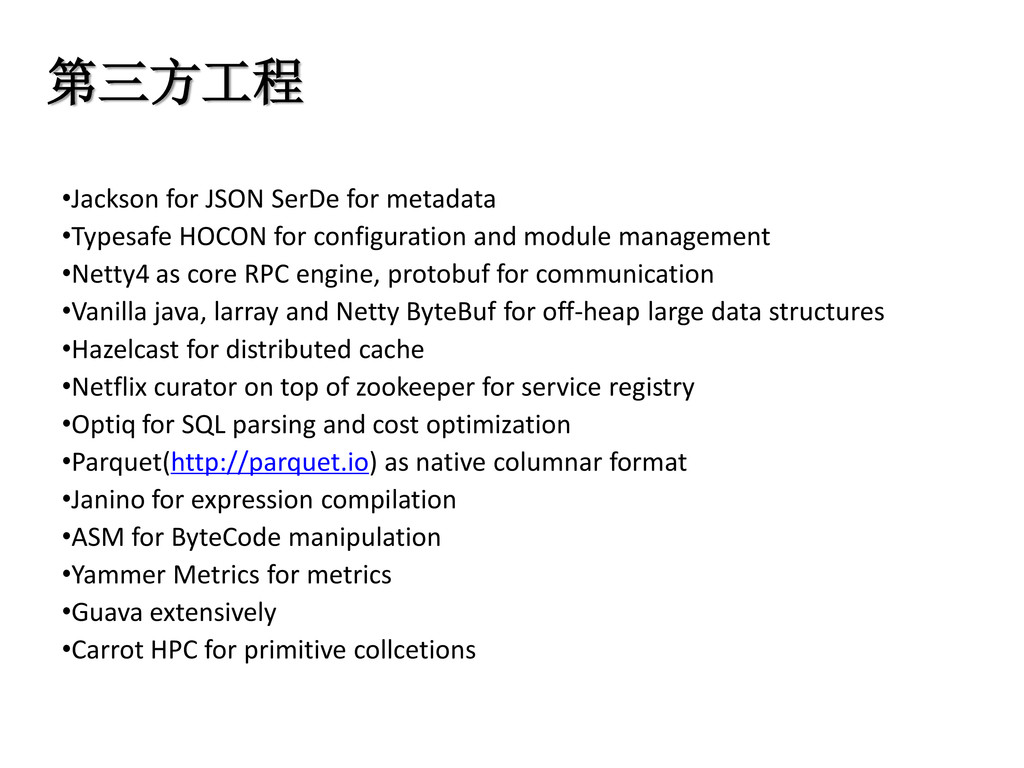
configuration and module management •Netty4 as core RPC engine, protobuf for communication •Vanilla java, larray and Netty ByteBuf for off-heap large data structures •Hazelcast for distributed cache •Netflix curator on top of zookeeper for service registry •Optiq for SQL parsing and cost optimization •Parquet(http://parquet.io) as native columnar format •Janino for expression compilation •ASM for ByteCode manipulation •Yammer Metrics for metrics •Guava extensively •Carrot HPC for primitive collcetions


 namiki64
 yut0naga1_fa
 jozono
 4o1sobblue
 camiha
 oikon48
 rfdnxbro
 grimoh
 nttcom
 greenmidori
 kizawa2020
 bitkey
 lynnandtonic
 greggifford
 schlessera
 mfonobong
 aleyda
 holman
 jonyablonski
 productmarketing
 rkaga
 marcelosomers
 helenjbeal