Share
Dataflows: The abstraction that powers the Big Data technology by RAÚL CASTRO FERNÁNDEZ at Big Data Spain 2014
Dataflows are an omnipresent abstraction across many big data technologies due to its suitability for representing programs in a way that is easy to parallelize. All dataflow models---such as those of Spark or MapReduce---are stateless, which facilitates achieving fault tolerance, a crucial property when running at large-scale. However, this stateless dataflow models have a negative impact on the programming models they expose, which need to adapt to match the stateless nature of the underlying platforms. With the “democratization of data”, different types of users with different skills want answers from their big datasets, but sometimes they lack the skills required to write programs adapted to these specific frameworks: A familiar programming model becomes crucial to open big data value to a broader set of users.
Big Data Spain
Transcript
74 slides
-
THE ABSTRACTION THAT POWERS THE BIG DATA RAÚL CASTRO FERNÁNDEZ
COMPUTER SCIENCE PHD STUDENT IMPERIAL COLLEGE -
Data!ows: The Abstraction that Powers Big Data Raul Castro Fernandez
Imperial College London [email protected] @raulcfernandez -
3 Developers and DBAs are no longer the only
ones genera:ng, processing and analyzing data. Democratization of Data -
4 Decision makers, domain scien:sts, applica:on users, journalists,
crowd workers, and everyday consumers, sales, marke:ng… Democratization of Data Developers and DBAs are no longer the only ones genera:ng, processing and analyzing data. -
6 + Everyone has data + Many have
interes:ng ques:ons -
7 + Everyone has data + Many have
interes:ng ques:ons -‐ Not everyone knows how to analyze it -
8 + Everyone has data + Many have
interes:ng ques:ons -‐ Not everyone knows how to analyze it -
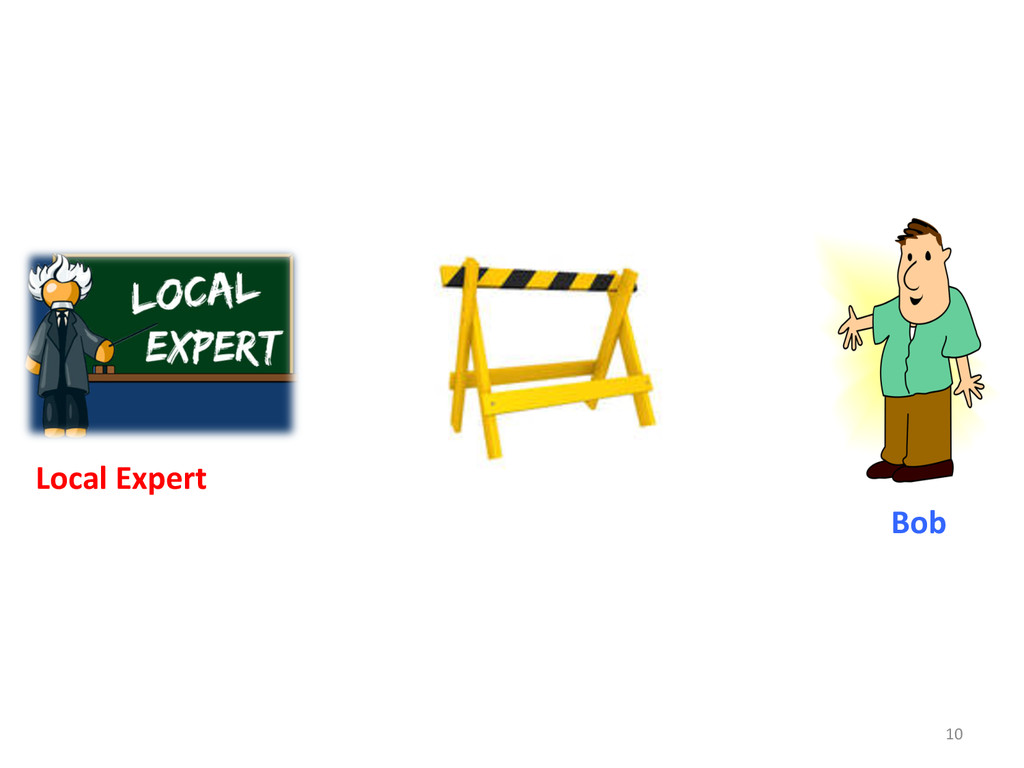
11 Bob Local Expert -‐ Barrier of
human communica:on -‐ Barrier of professional rela:ons -
12 Bob Local Expert -‐ Barrier of
human communica:on -‐ Barrier of professional rela:ons The limits of my language mean the limits of my world. Ludwig WiWgenstein “Tractatus Logico-‐Philosophicus 1922” -
13 First step to democra:ze Big Data: to
offer a familiar programming interface -
• Mo>va>on • SDG: Stateful Dataflow Graphs •
Handling distributed state in SDGs • Transla:ng Java programs to SDGs • Checkpoint-‐based fault tolerance for SDGs • Experimental evalua:on 14 Outline ? ? -
Mutable State in a Recommender System 15 Matrix userItem
= new Matrix(); Matrix coOcc = new Matrix(); Item-‐A Item-‐B User-‐A 4 5 User-‐B 0 5 Item-‐A Item-‐B Item-‐A 1 1 Item-‐B 1 2 User-‐Item matrix (UI) Co-‐Occurrence matrix (CO) -
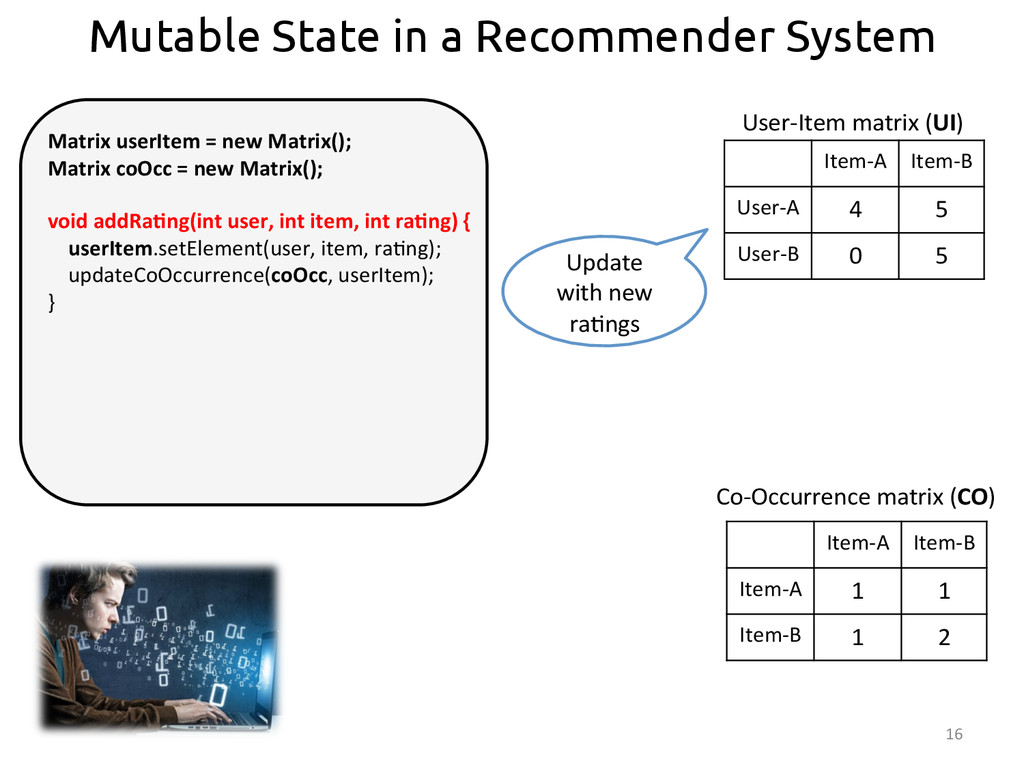
Mutable State in a Recommender System 16 Matrix userItem
= new Matrix(); Matrix coOcc = new Matrix(); void addRa>ng(int user, int item, int ra>ng) { userItem.setElement(user, item, ra:ng); updateCoOccurrence(coOcc, userItem); } Item-‐A Item-‐B User-‐A 4 5 User-‐B 0 5 Item-‐A Item-‐B Item-‐A 1 1 Item-‐B 1 2 User-‐Item matrix (UI) Co-‐Occurrence matrix (CO) Update with new ra:ngs -
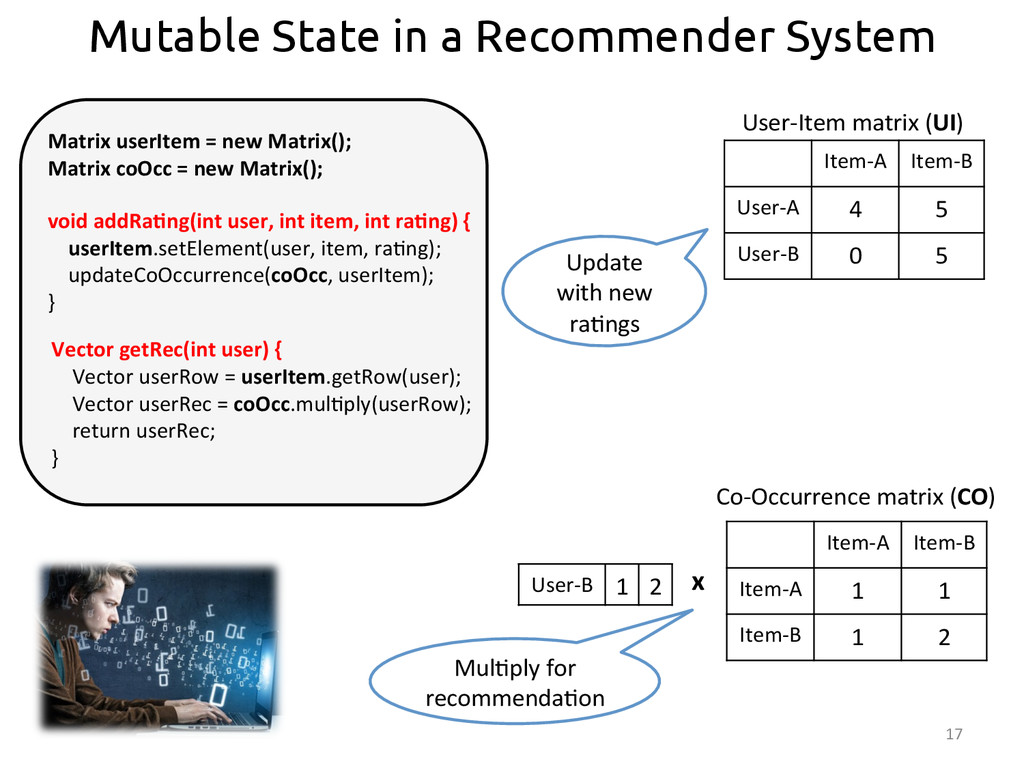
Mutable State in a Recommender System 17 Matrix userItem
= new Matrix(); Matrix coOcc = new Matrix(); void addRa>ng(int user, int item, int ra>ng) { userItem.setElement(user, item, ra:ng); updateCoOccurrence(coOcc, userItem); } Vector getRec(int user) { Vector userRow = userItem.getRow(user); Vector userRec = coOcc.mul:ply(userRow); return userRec; } Item-‐A Item-‐B User-‐A 4 5 User-‐B 0 5 Item-‐A Item-‐B Item-‐A 1 1 Item-‐B 1 2 User-‐Item matrix (UI) Co-‐Occurrence matrix (CO) Update with new ra:ngs Mul:ply for recommenda:on User-‐B 1 2 x -
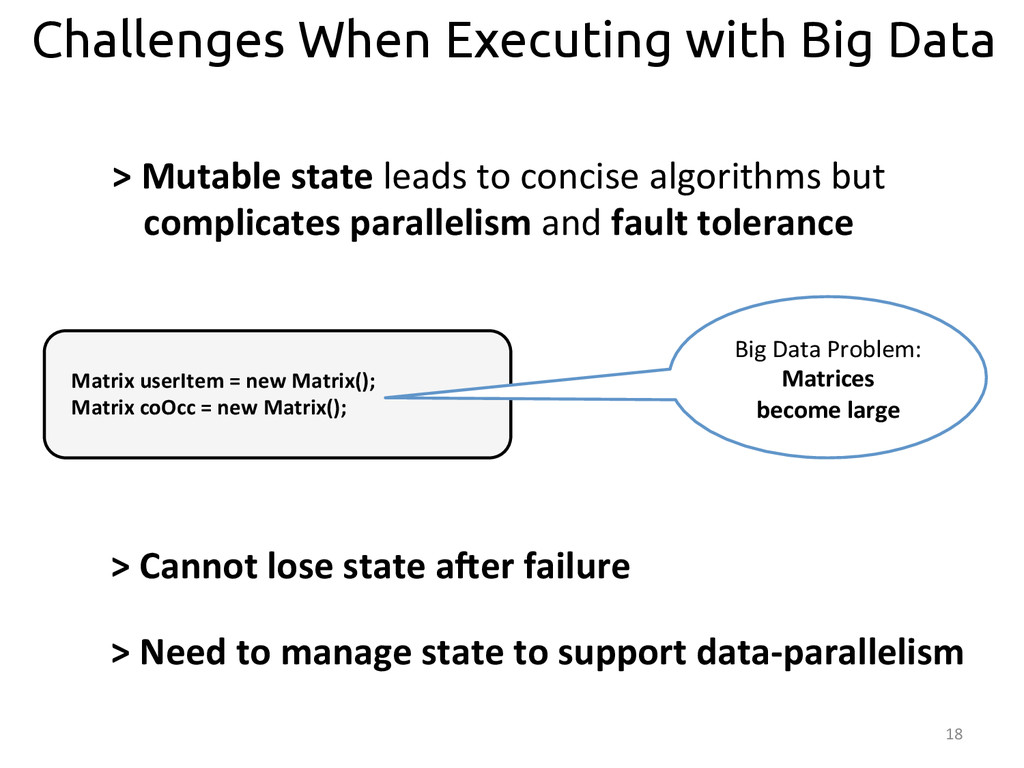
18 Challenges When Executing with Big Data Big Data
Problem: Matrices become large > Mutable state leads to concise algorithms but complicates parallelism and fault tolerance Matrix userItem = new Matrix(); Matrix coOcc = new Matrix(); > Cannot lose state aRer failure > Need to manage state to support data-‐parallelism -
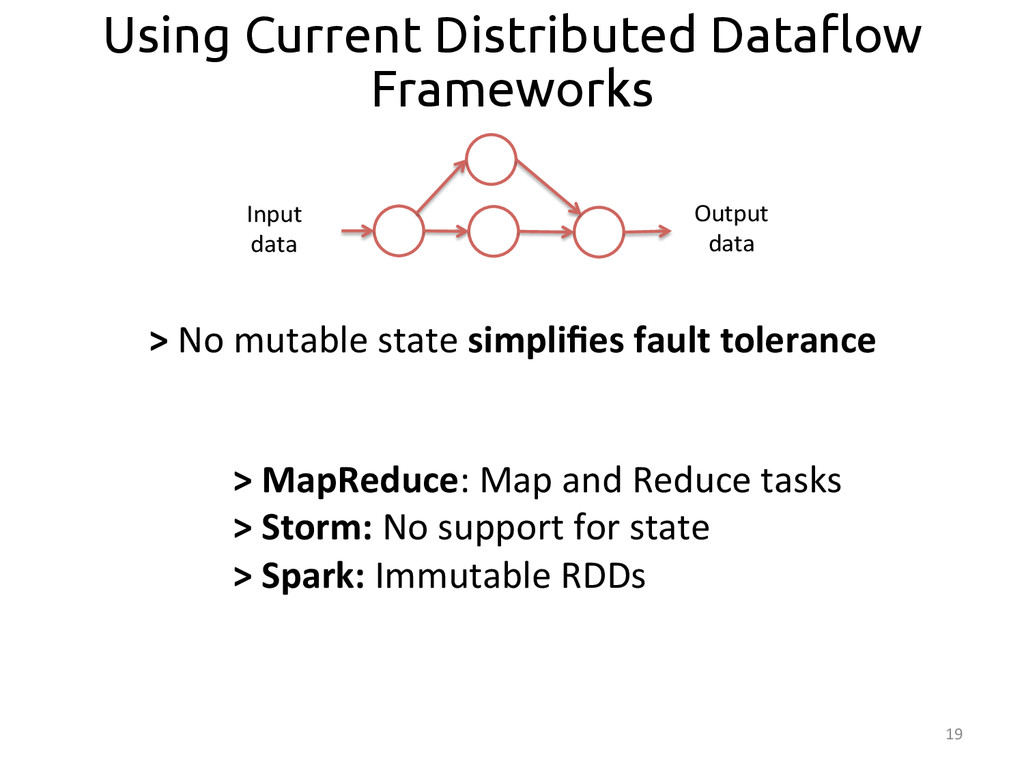
19 Using Current Distributed Data"ow Frameworks Input data
Output data > No mutable state simplifies fault tolerance > MapReduce: Map and Reduce tasks > Storm: No support for state > Spark: Immutable RDDs -
20 > Programming distributed dataflow graphs requires learning
new programming models Imperative Big Data Processing -
21 Our Goal: Run Java programs with mutable
state but with performance and fault tolerance of distributed dataflow systems > Programming distributed dataflow graphs requires learning new programming models Imperative Big Data Processing -
22 > @Annota>ons help with transla>on from Java to
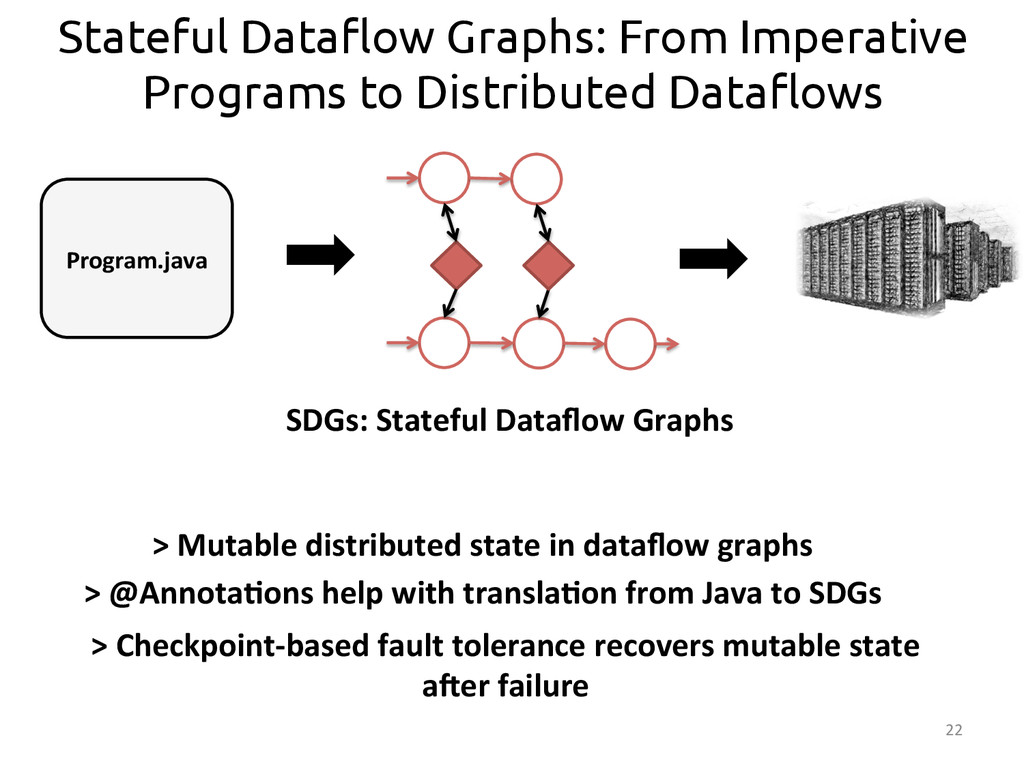
SDGs > Mutable distributed state in dataflow graphs Stateful Data"ow Graphs: From Imperative Programs to Distributed Data"ows Program.java SDGs: Stateful Dataflow Graphs > Checkpoint-‐based fault tolerance recovers mutable state aRer failure -
• Mo:va:on • SDG: Stateful Dataflow Graphs •
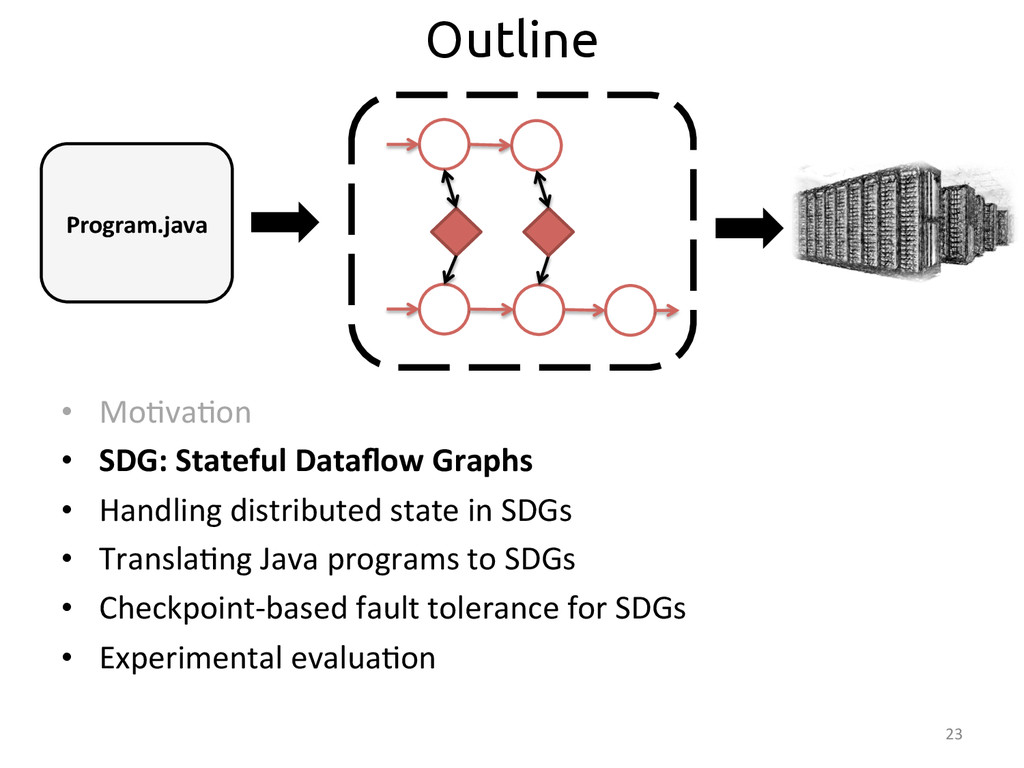
Handling distributed state in SDGs • Transla:ng Java programs to SDGs • Checkpoint-‐based fault tolerance for SDGs • Experimental evalua:on 23 Outline Program.java -
SDG: Data, State and Computation > SDGs separate data and
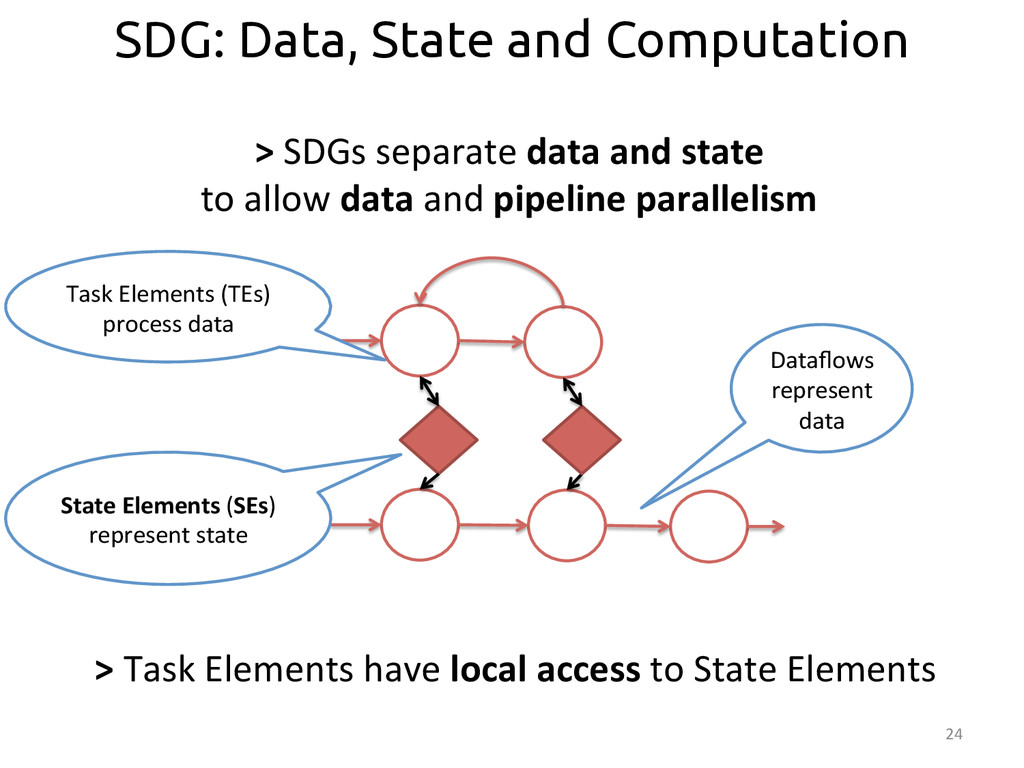
state to allow data and pipeline parallelism 24 Task Elements (TEs) process data State Elements (SEs) represent state Dataflows represent data > Task Elements have local access to State Elements -
State Elements support two abstrac:ons for distributed mutable state
– Par>>oned SEs: task elements always access state by key – Par>al SEs: task elements can access complete state 25 Distributed Mutable State -
26 Distributed Mutable State: Partitioned SEs Dataflow routed according
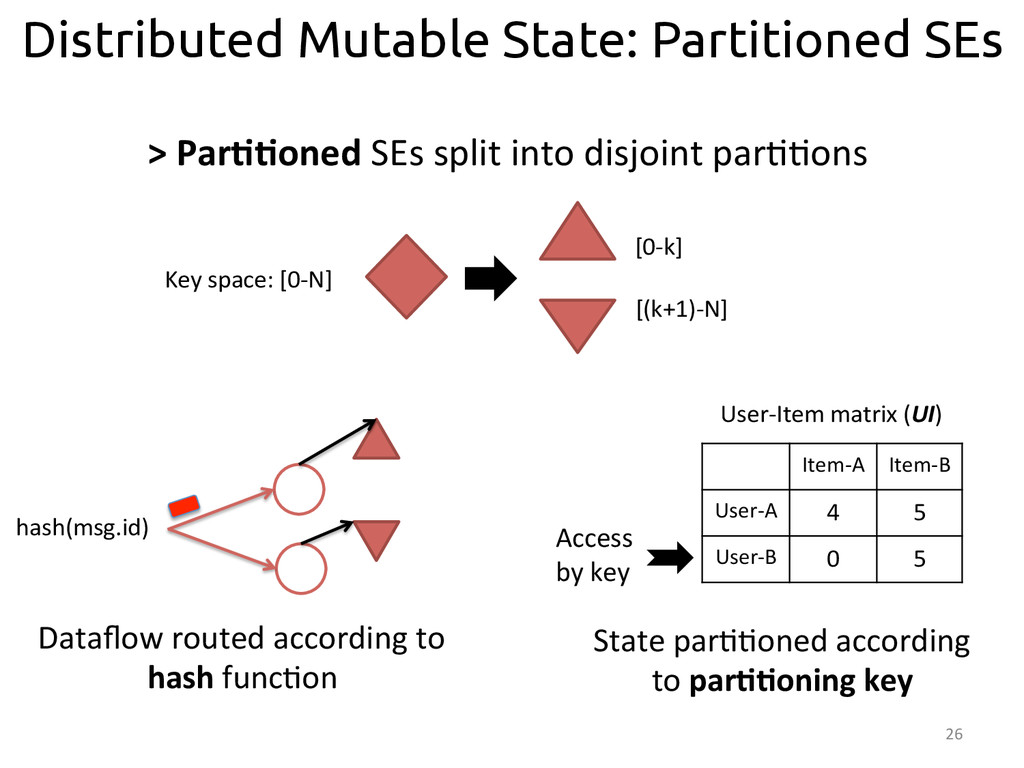
to hash func:on Item-‐A Item-‐B User-‐A 4 5 User-‐B 0 5 Access by key State par::oned according to par>>oning key > Par>>oned SEs split into disjoint par::ons User-‐Item matrix (UI) hash(msg.id) Key space: [0-‐N] [0-‐k] [(k+1)-‐N] -
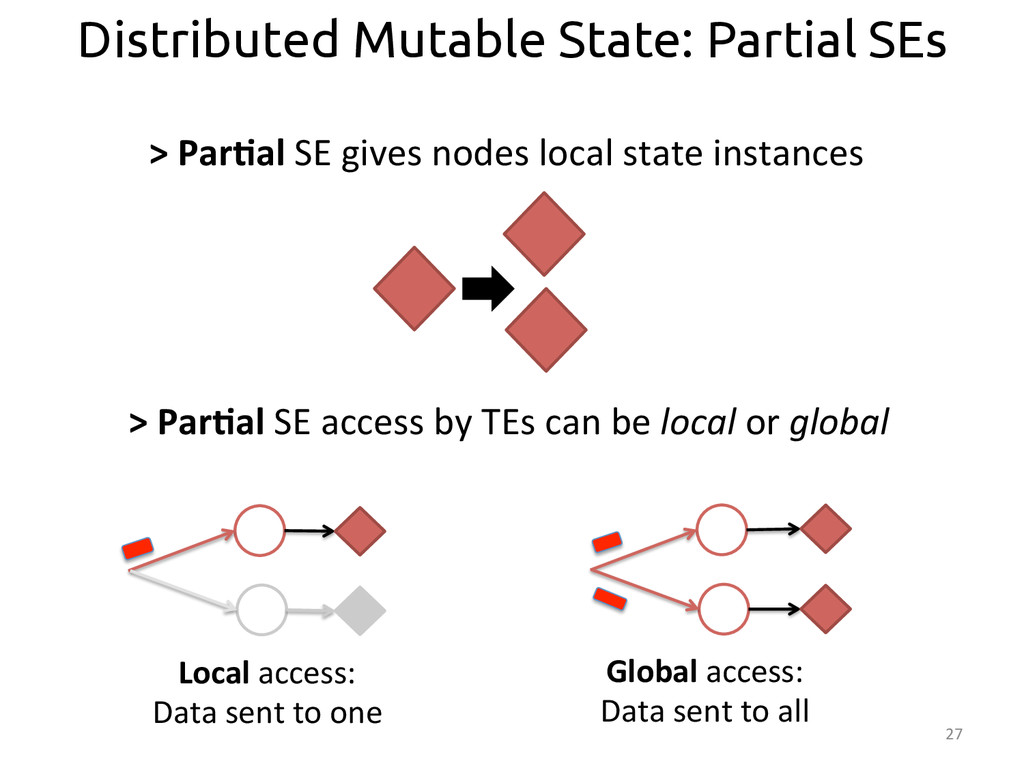
27 Distributed Mutable State: Partial SEs Local access:
Data sent to one Global access: Data sent to all > Par>al SE gives nodes local state instances > Par>al SE access by TEs can be local or global -
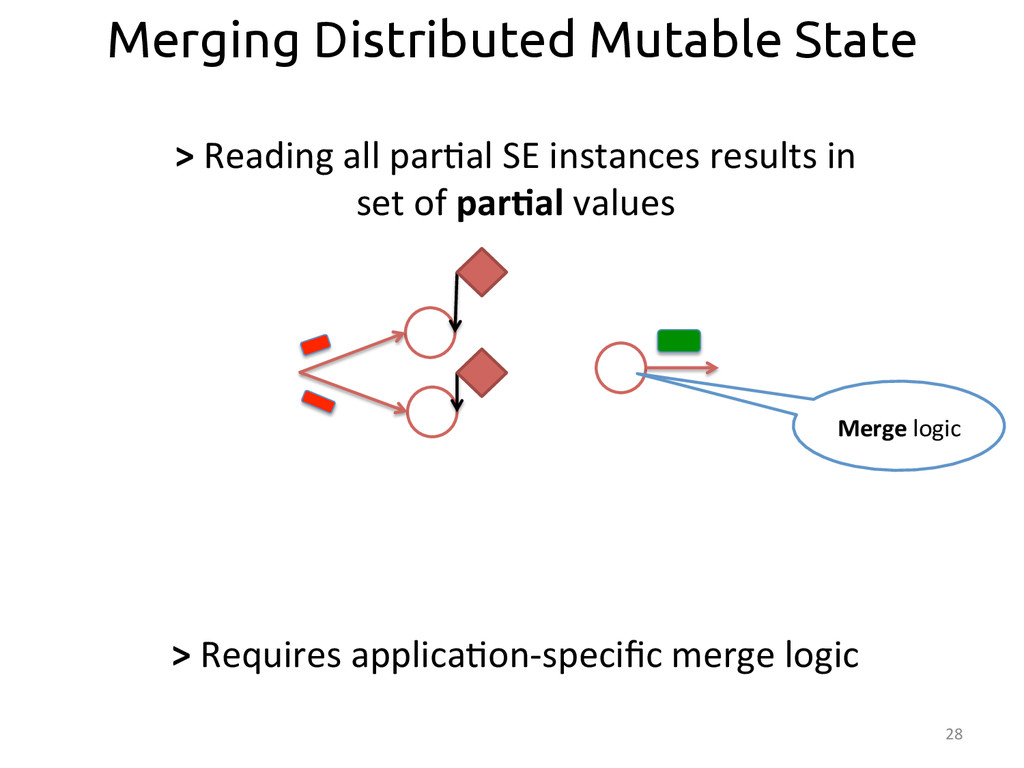
28 Merging Distributed Mutable State Merge logic >
Requires applica:on-‐specific merge logic > Reading all par:al SE instances results in set of par>al values -
29 Merging Distributed Mutable State Mul:ple par:al values
Merge logic > Requires applica:on-‐specific merge logic > Reading all par:al SE instances results in set of par>al values -
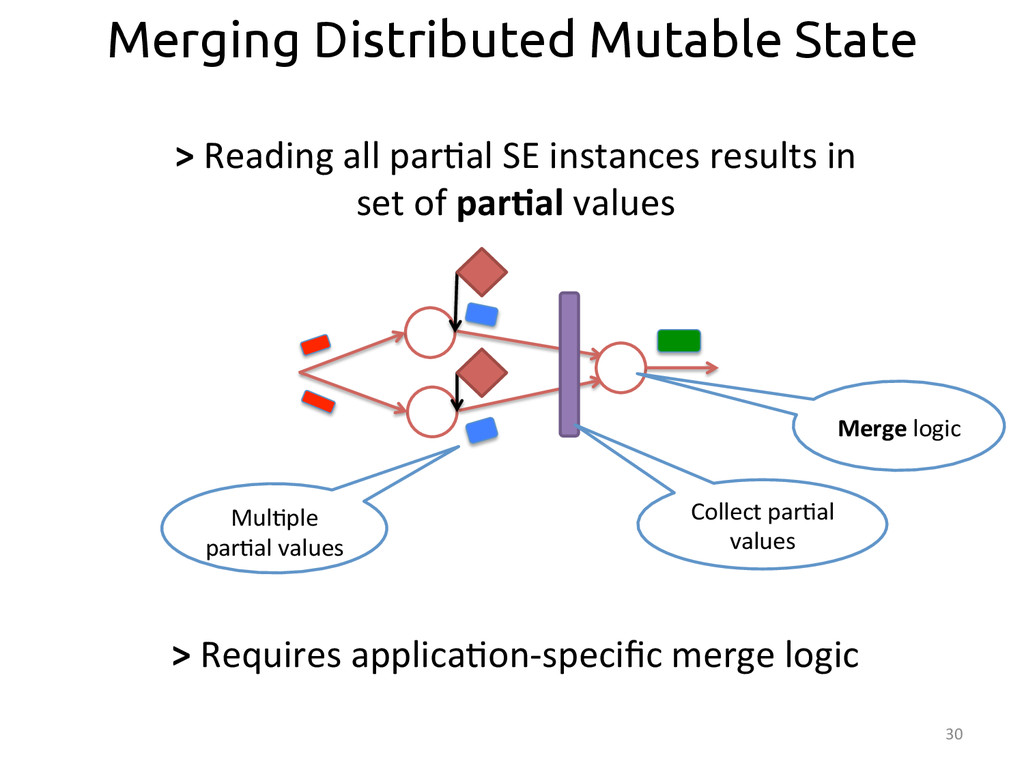
30 Merging Distributed Mutable State Mul:ple par:al values
Collect par:al values Merge logic > Requires applica:on-‐specific merge logic > Reading all par:al SE instances results in set of par>al values -
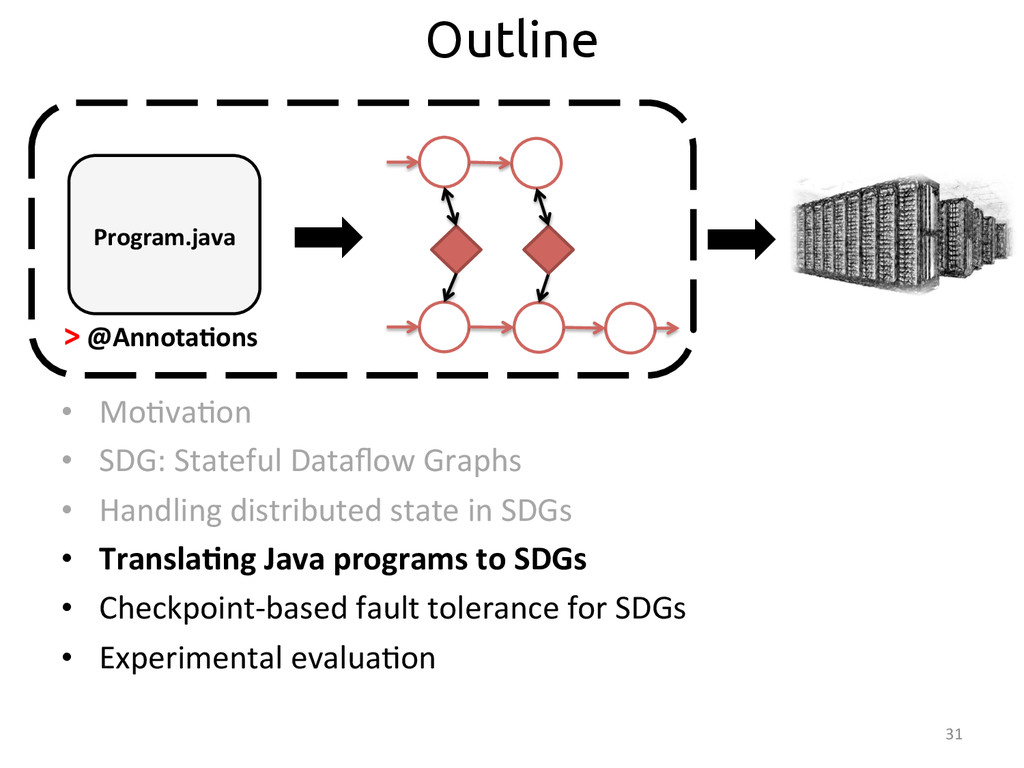
31 Outline > @Annota>ons • Mo:va:on •
SDG: Stateful Dataflow Graphs • Handling distributed state in SDGs • Transla>ng Java programs to SDGs • Checkpoint-‐based fault tolerance for SDGs • Experimental evalua:on Program.java -
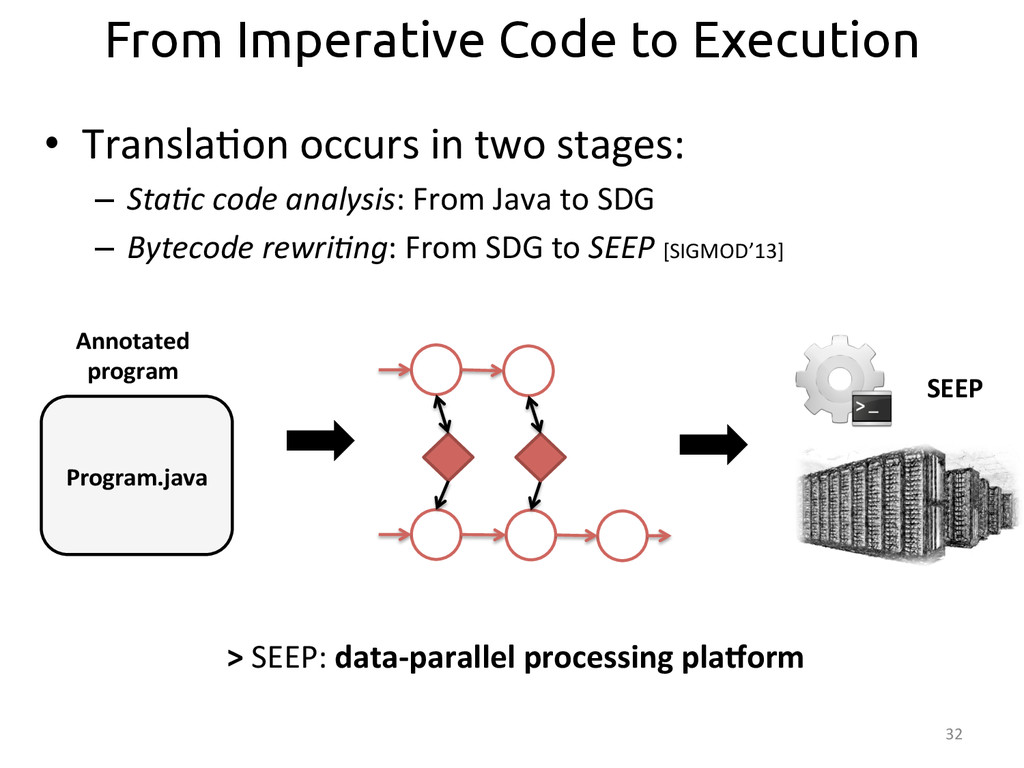
32 From Imperative Code to Execution SEEP Annotated
program > SEEP: data-‐parallel processing plaborm • Transla:on occurs in two stages: – Sta<c code analysis: From Java to SDG – Bytecode rewri<ng: From SDG to SEEP [SIGMOD’13] Program.java -
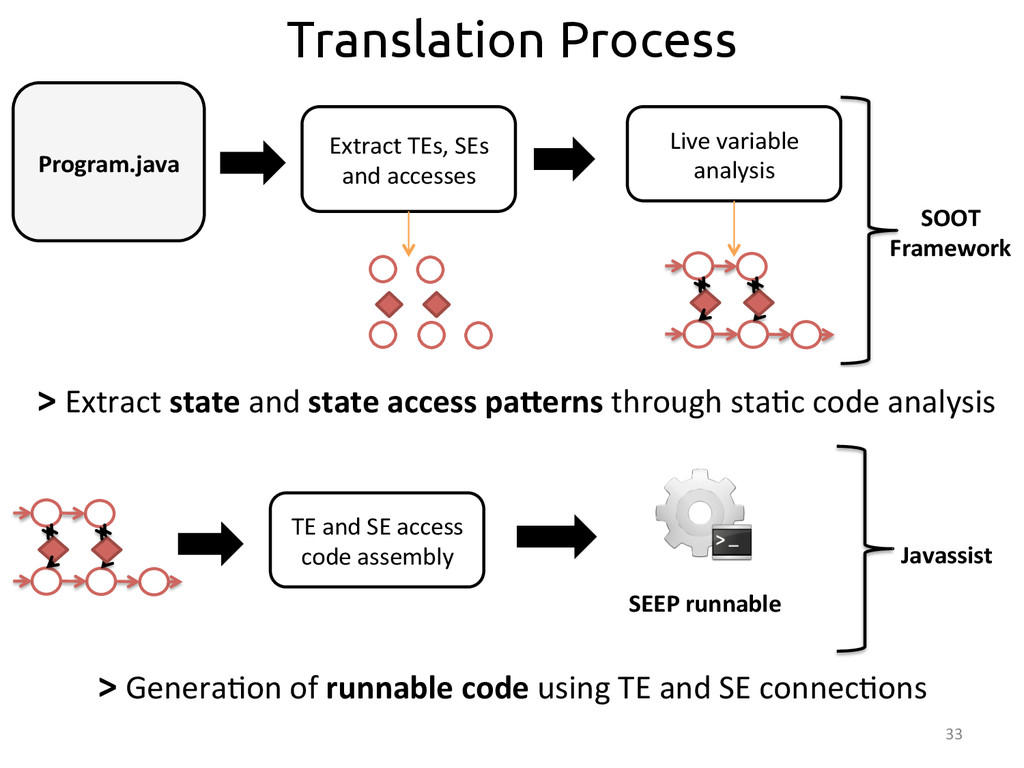
Program.java 33 Extract TEs, SEs and accesses
Live variable analysis TE and SE access code assembly SEEP runnable SOOT Framework Javassist > Extract state and state access paderns through sta:c code analysis > Genera:on of runnable code using TE and SE connec:ons Translation Process -
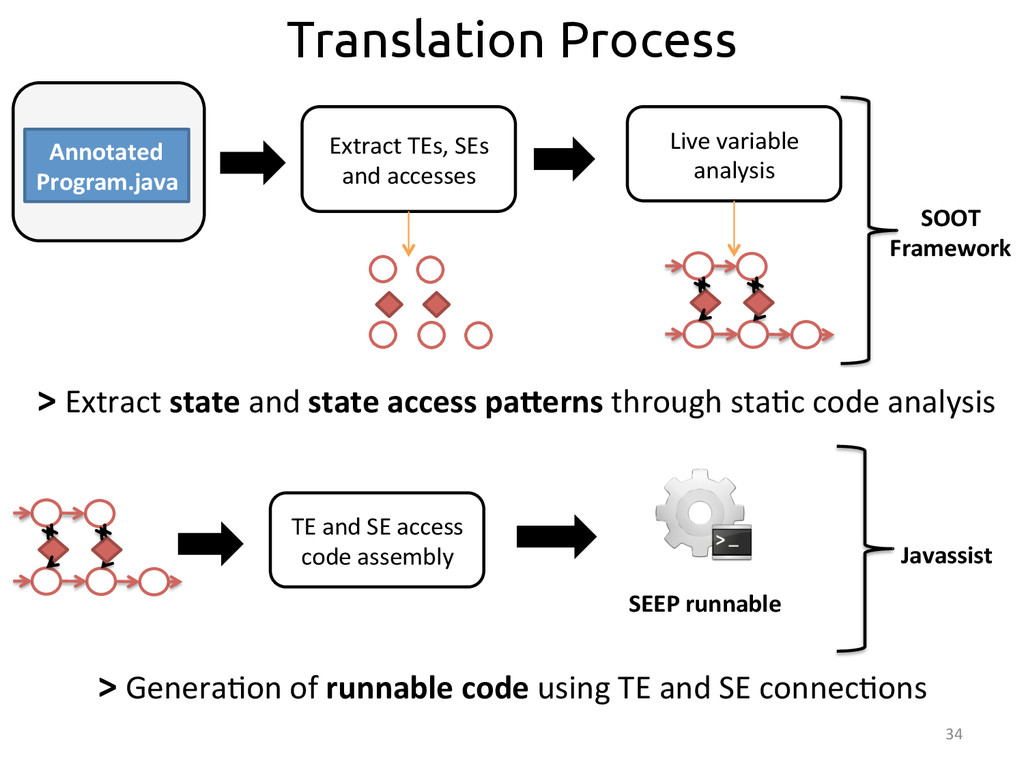
Program.java 34 Extract TEs, SEs and accesses
Live variable analysis TE and SE access code assembly SEEP runnable SOOT Framework Javassist > Extract state and state access paderns through sta:c code analysis > Genera:on of runnable code using TE and SE connec:ons Translation Process Annotated Program.java -
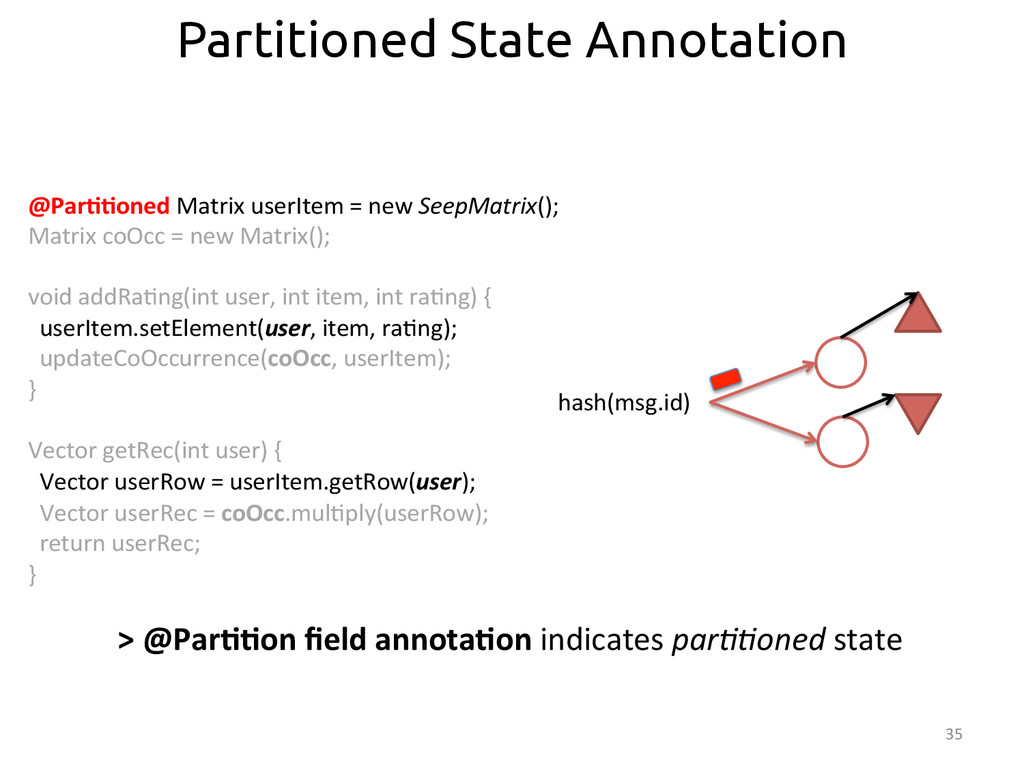
35 @Par>>oned Matrix userItem = new SeepMatrix(); Matrix
coOcc = new Matrix(); void addRa:ng(int user, int item, int ra:ng) { userItem.setElement(user, item, ra:ng); updateCoOccurrence(coOcc, userItem); } Vector getRec(int user) { Vector userRow = userItem.getRow(user); Vector userRec = coOcc.mul:ply(userRow); return userRec; } Partitioned State Annotation > @Par>>on field annota>on indicates par<<oned state hash(msg.id) -
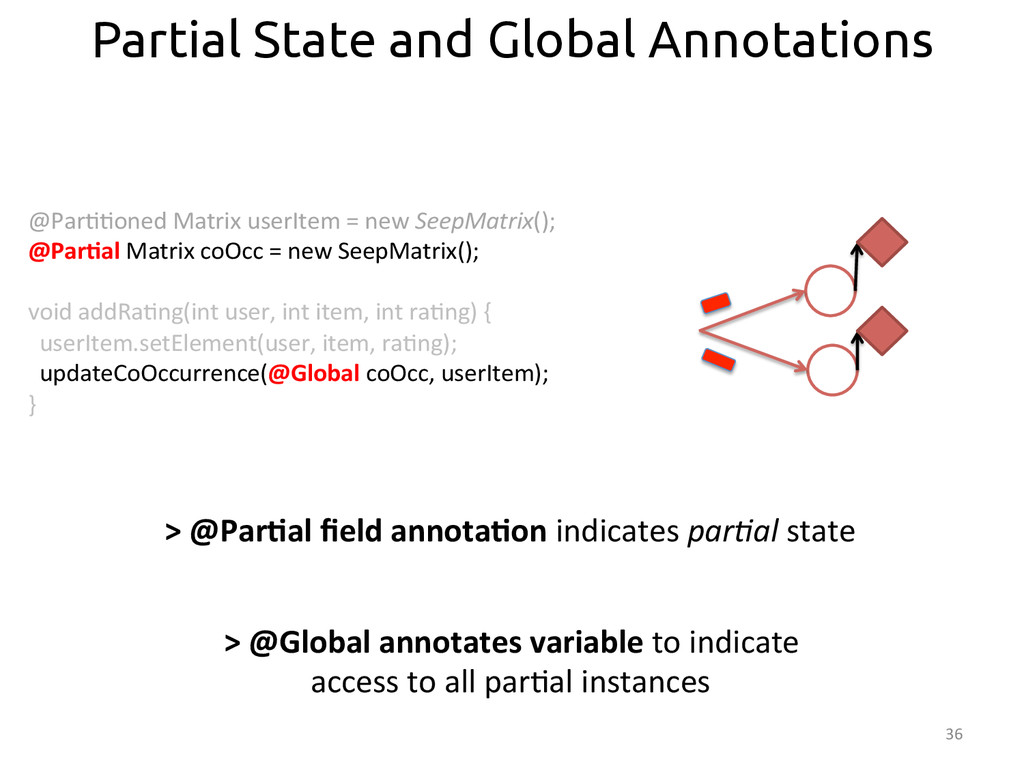
36 @Par::oned Matrix userItem = new SeepMatrix(); @Par>al
Matrix coOcc = new SeepMatrix(); void addRa:ng(int user, int item, int ra:ng) { userItem.setElement(user, item, ra:ng); updateCoOccurrence(@Global coOcc, userItem); } Partial State and Global Annotations > @Global annotates variable to indicate access to all par:al instances > @Par>al field annota>on indicates par<al state -
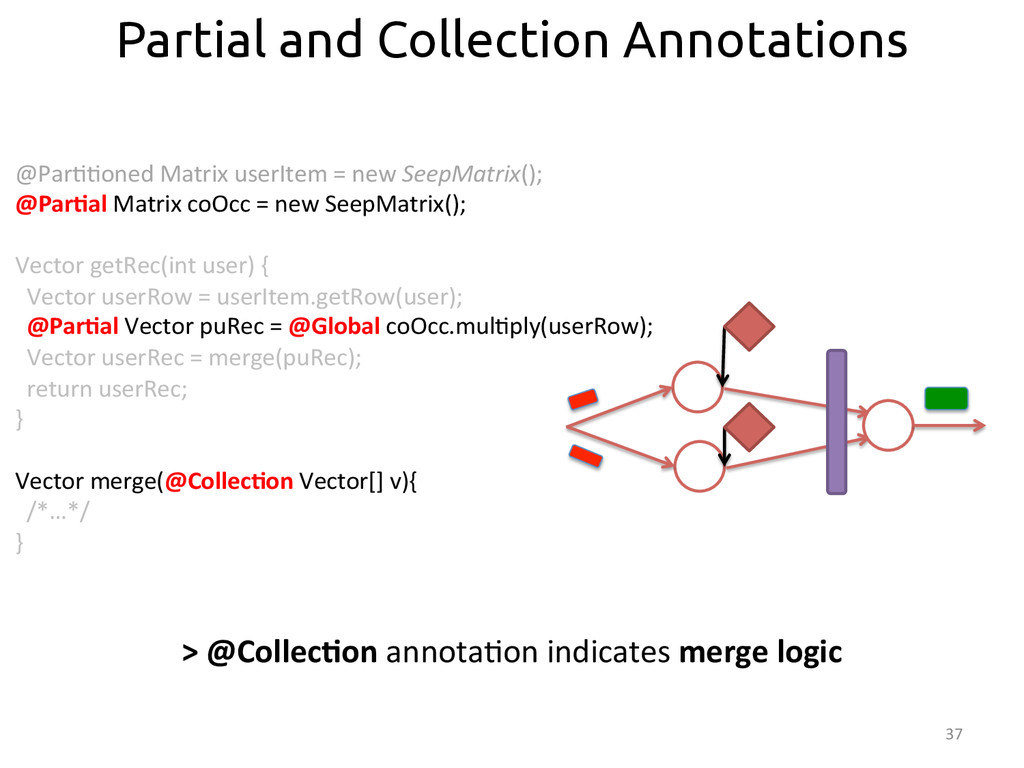
37 @Par::oned Matrix userItem = new SeepMatrix(); @Par>al
Matrix coOcc = new SeepMatrix(); Vector getRec(int user) { Vector userRow = userItem.getRow(user); @Par>al Vector puRec = @Global coOcc.mul:ply(userRow); Vector userRec = merge(puRec); return userRec; } Vector merge(@Collec>on Vector[] v){ /*…*/ } Partial and Collection Annotations > @Collec>on annota:on indicates merge logic -
38 Outline > Failures • Mo:va:on •
SDG: Stateful Dataflow Graphs • Handling distributed state in SDGs • Transla:ng Java programs to SDGs • Checkpoint-‐Based fault tolerance for SDGs • Experimental evalua:on Program.java -
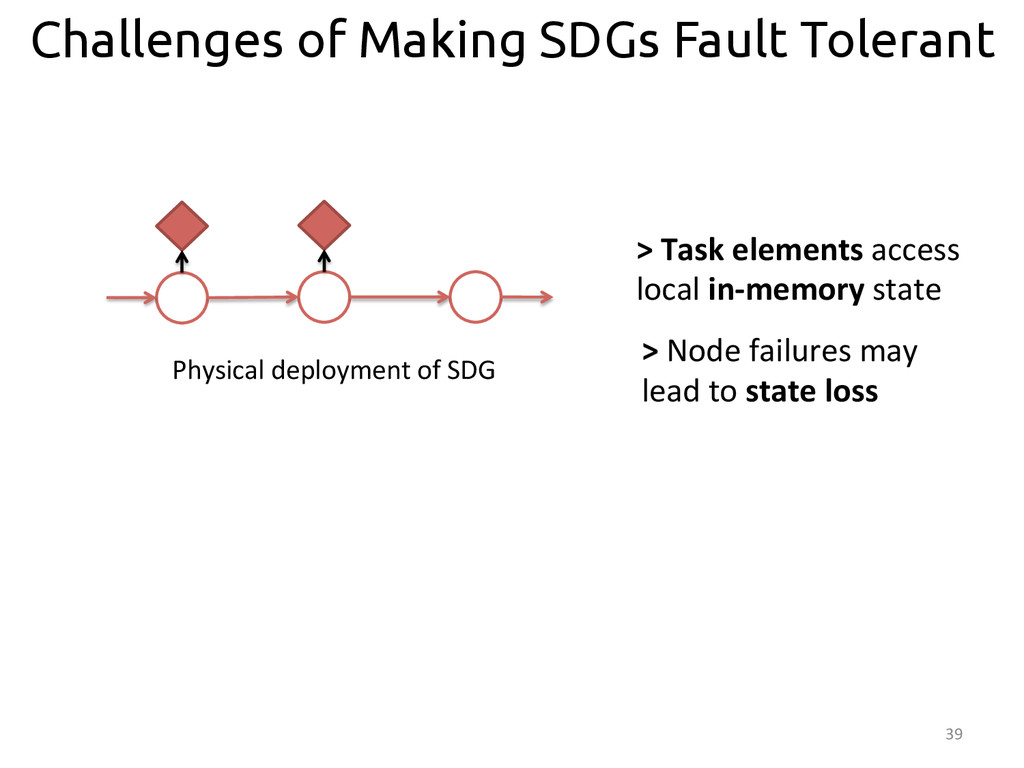
39 Challenges of Making SDGs Fault Tolerant Physical deployment
of SDG > Node failures may lead to state loss > Task elements access local in-‐memory state -
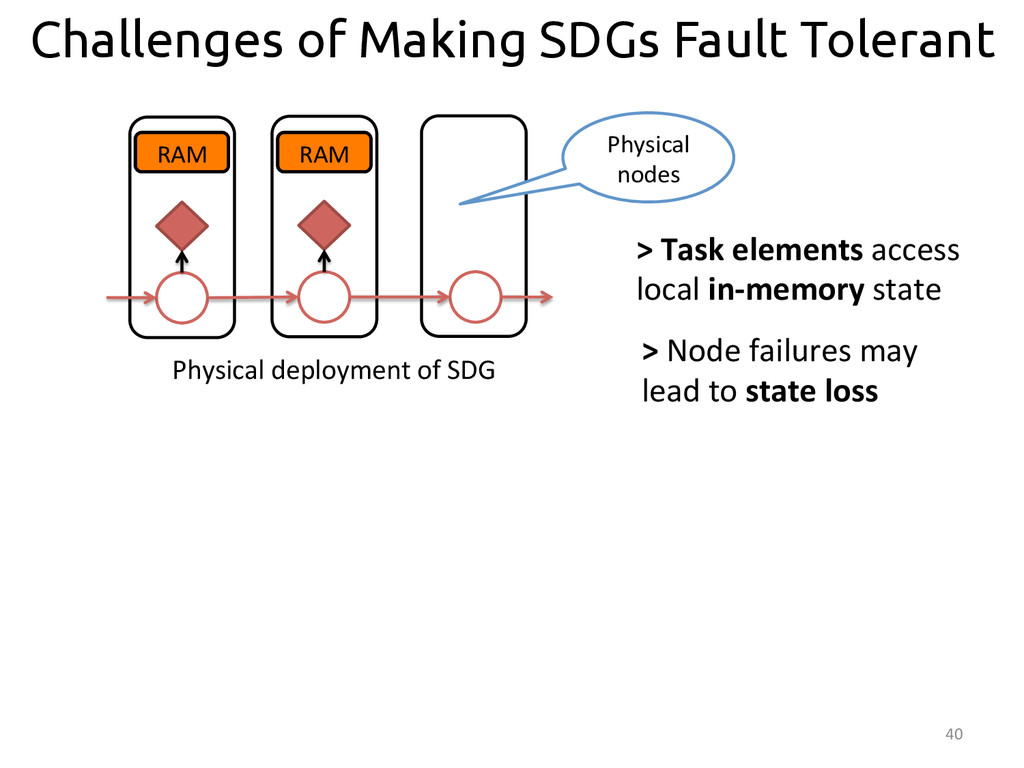
40 Challenges of Making SDGs Fault Tolerant RAM
RAM Physical deployment of SDG > Node failures may lead to state loss > Task elements access local in-‐memory state Physical nodes -
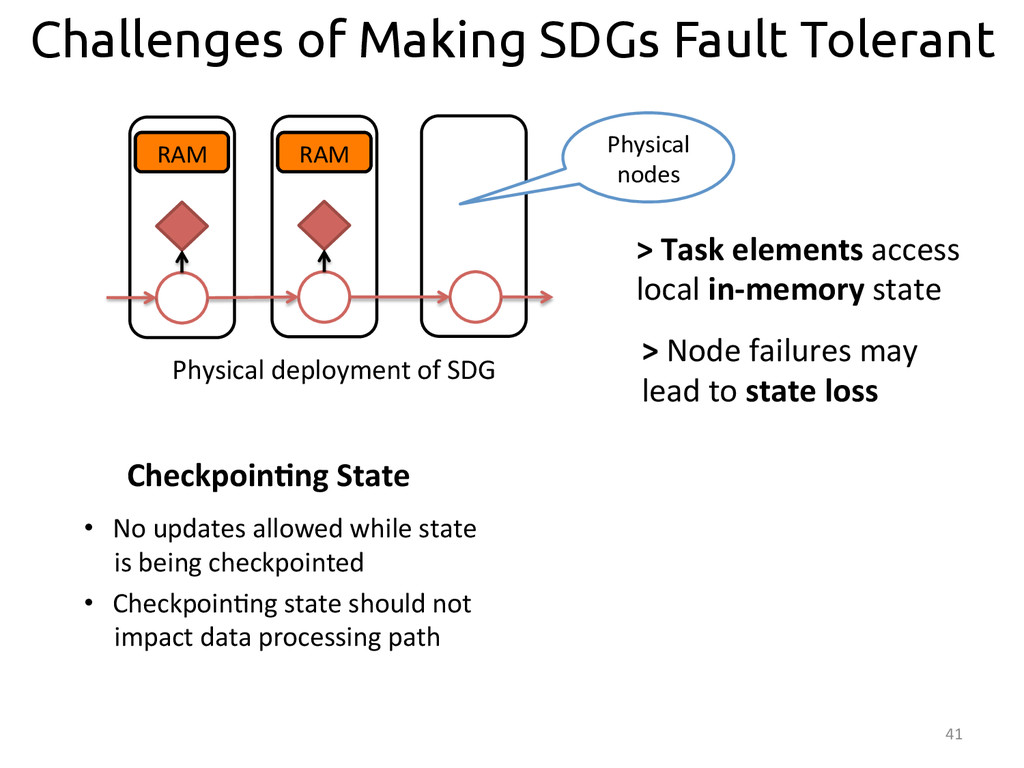
41 RAM RAM Physical deployment of SDG
> Node failures may lead to state loss Checkpoin>ng State • No updates allowed while state is being checkpointed • Checkpoin:ng state should not impact data processing path > Task elements access local in-‐memory state Physical nodes Challenges of Making SDGs Fault Tolerant -
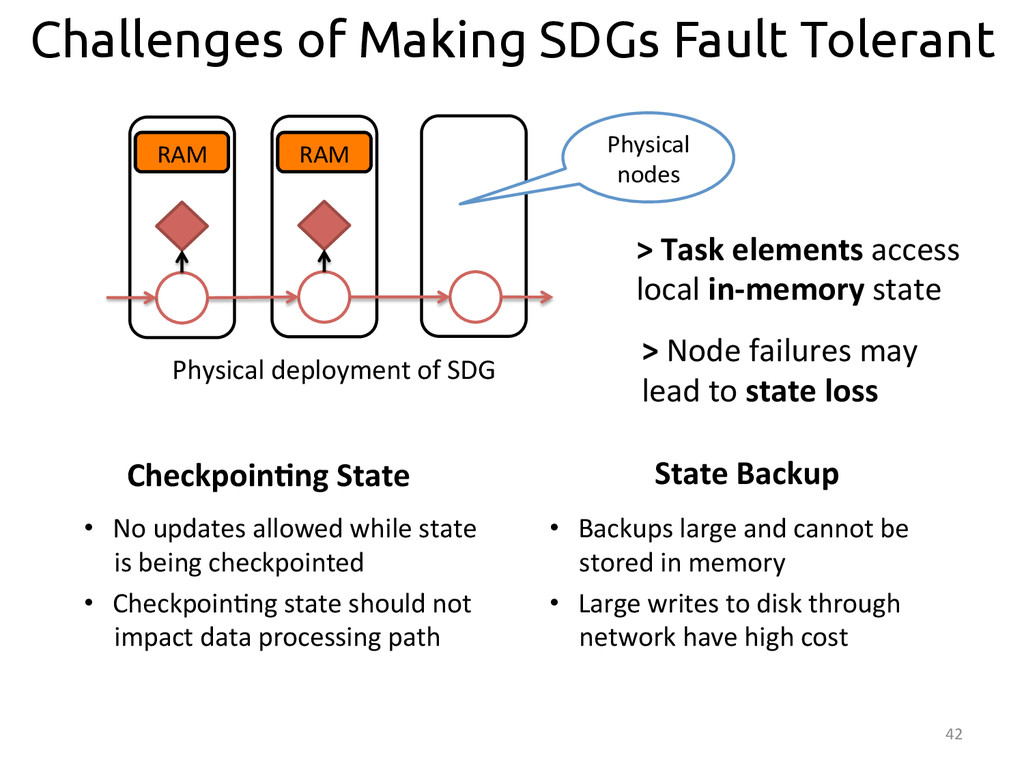
42 RAM RAM Physical deployment of SDG
• Backups large and cannot be stored in memory • Large writes to disk through network have high cost State Backup > Node failures may lead to state loss Checkpoin>ng State • No updates allowed while state is being checkpointed • Checkpoin:ng state should not impact data processing path > Task elements access local in-‐memory state Physical nodes Challenges of Making SDGs Fault Tolerant -
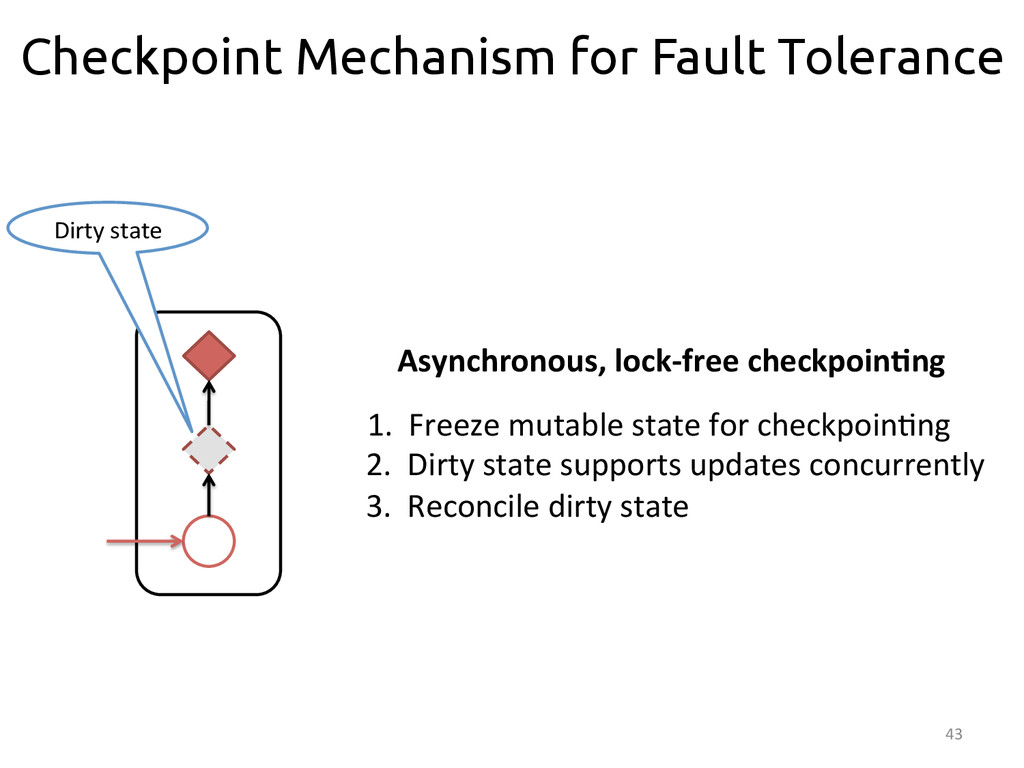
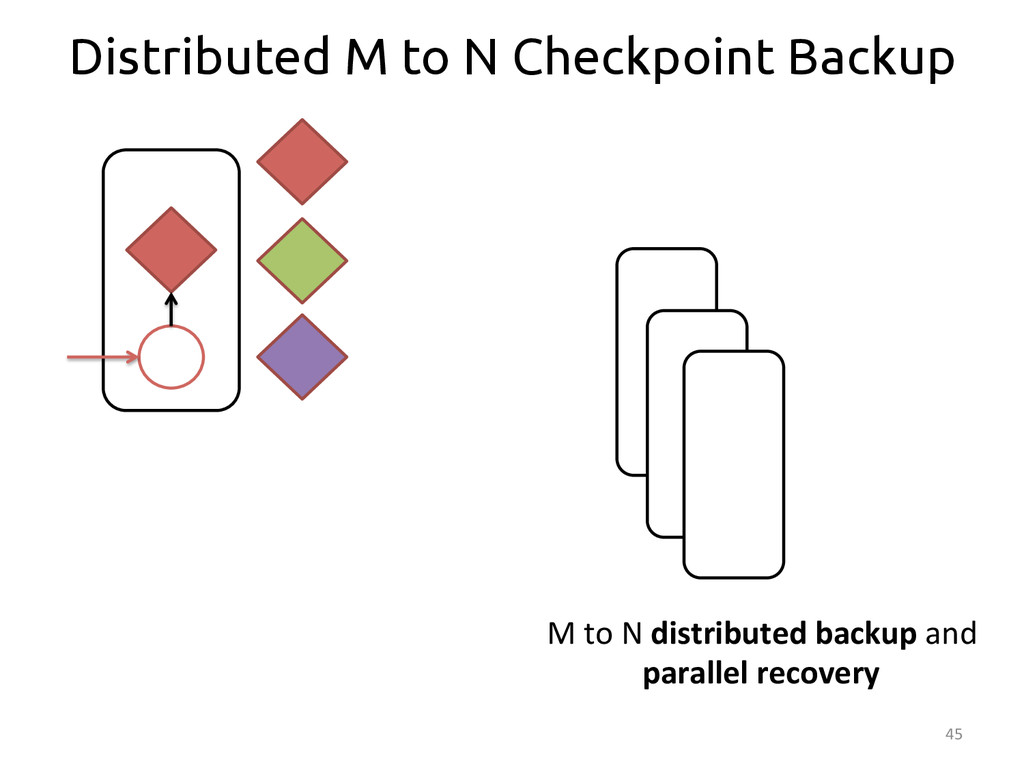
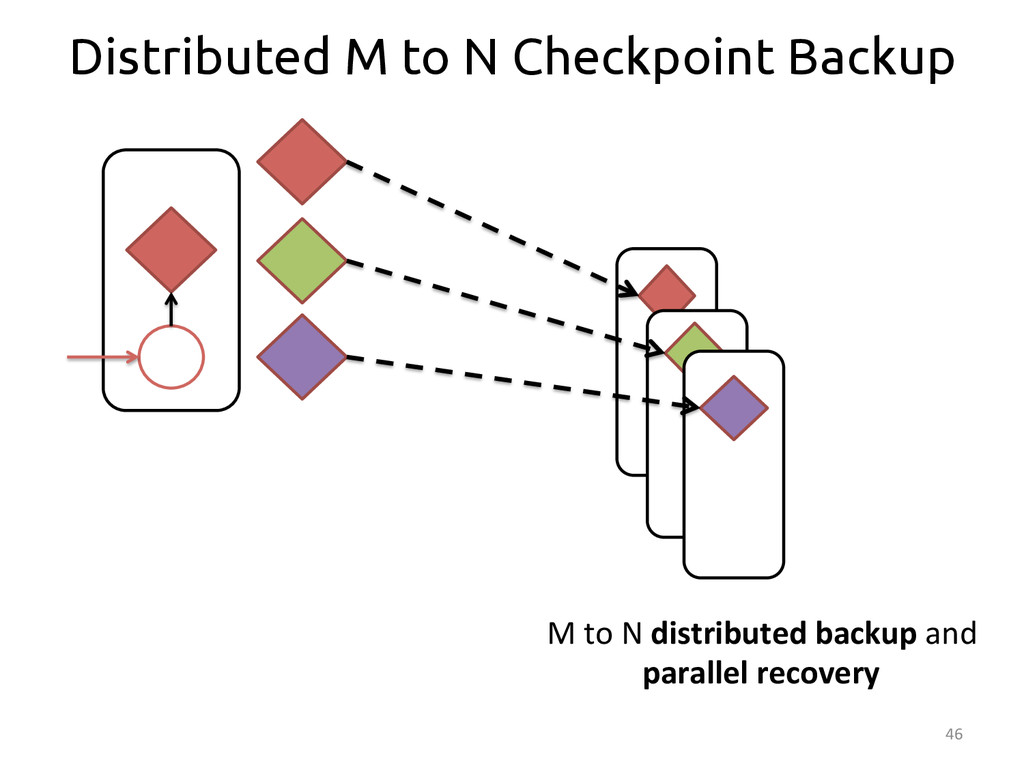
43 Checkpoint Mechanism for Fault Tolerance 1. Freeze mutable
state for checkpoin:ng 2. Dirty state supports updates concurrently 3. Reconcile dirty state Asynchronous, lock-‐free checkpoin>ng Dirty state -
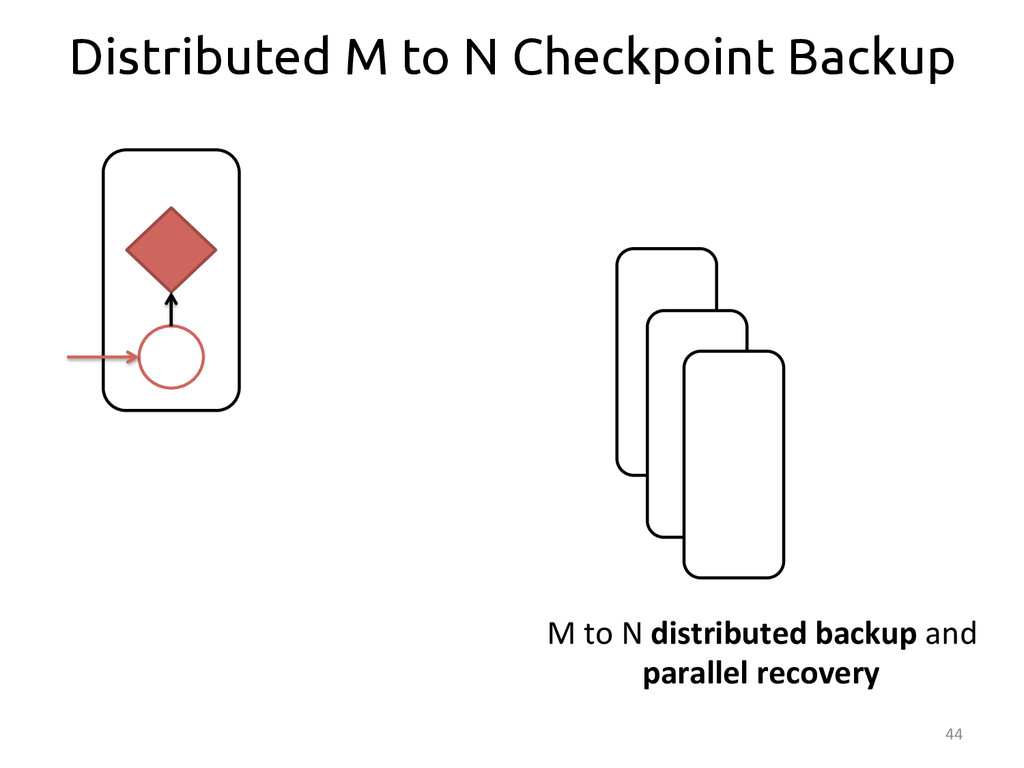
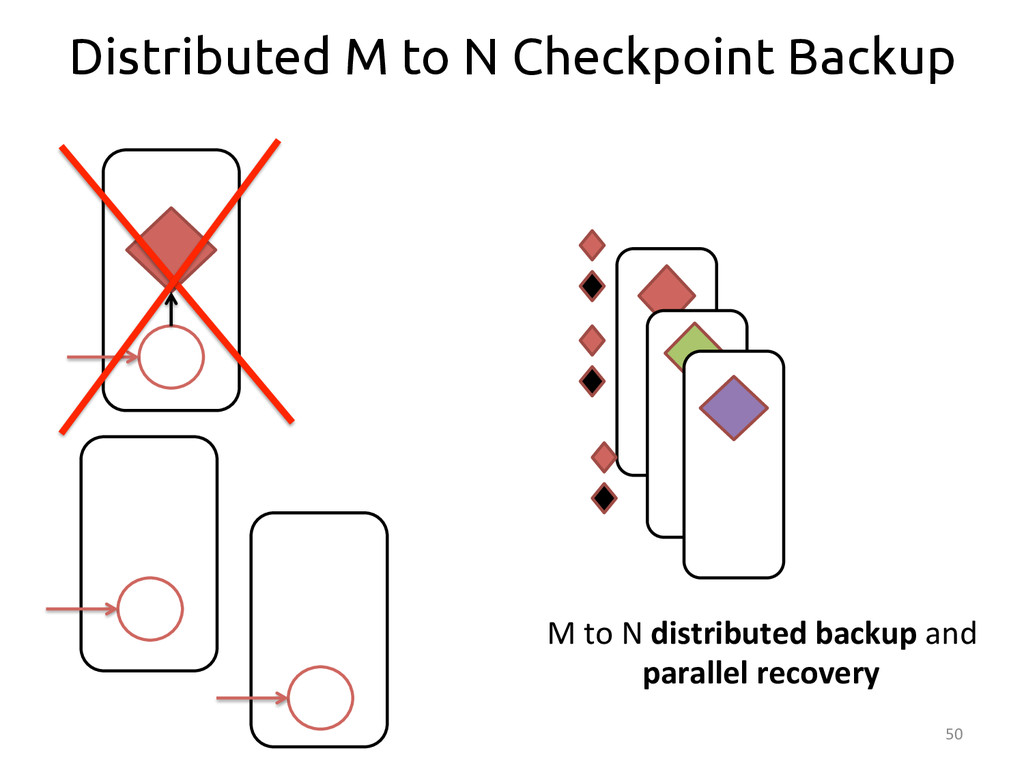
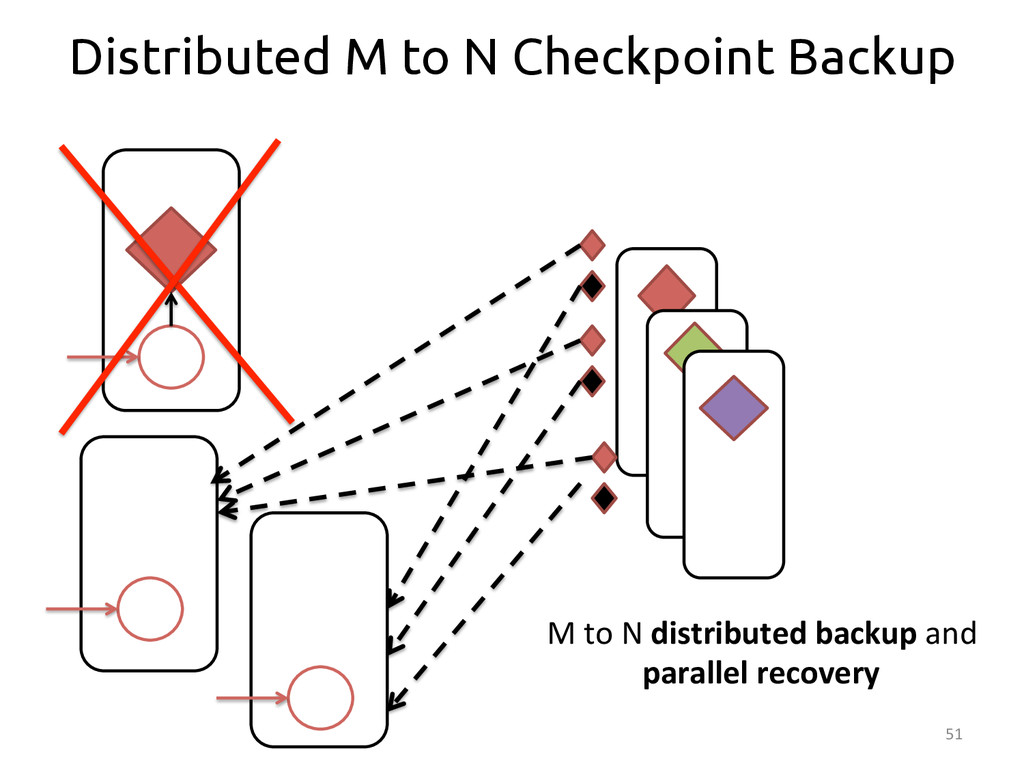
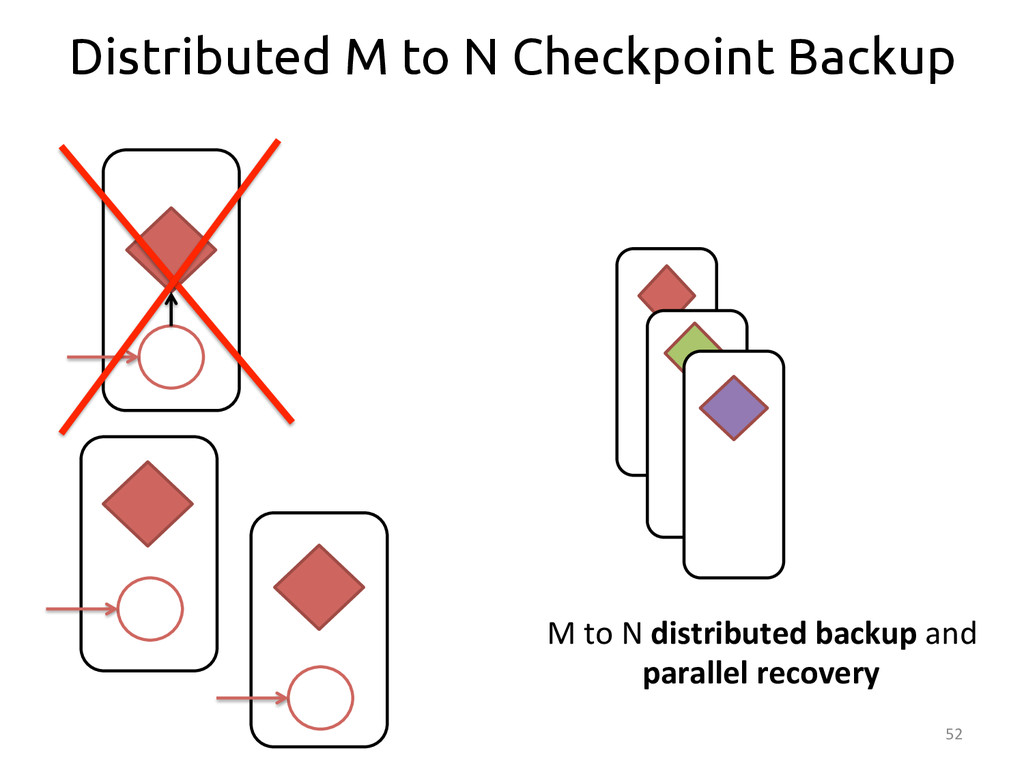
44 Distributed M to N Checkpoint Backup M to
N distributed backup and parallel recovery -
45 Distributed M to N Checkpoint Backup M to
N distributed backup and parallel recovery -
46 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
47 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
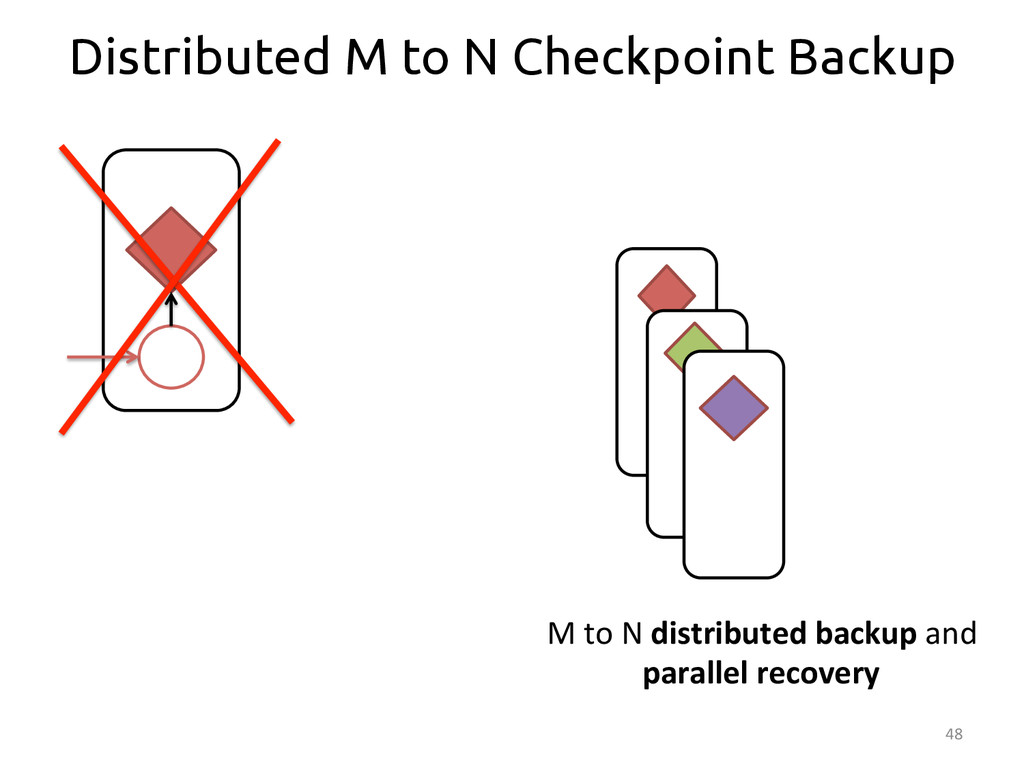
48 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
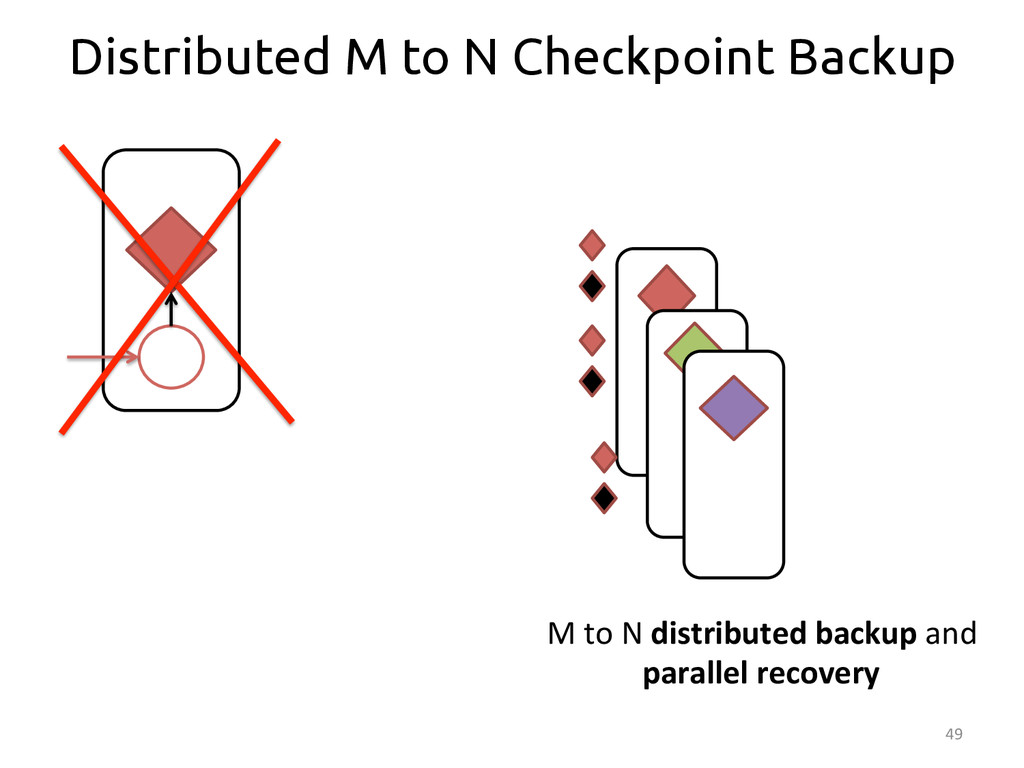
49 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
50 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
51 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
52 M to N distributed backup and parallel
recovery Distributed M to N Checkpoint Backup -
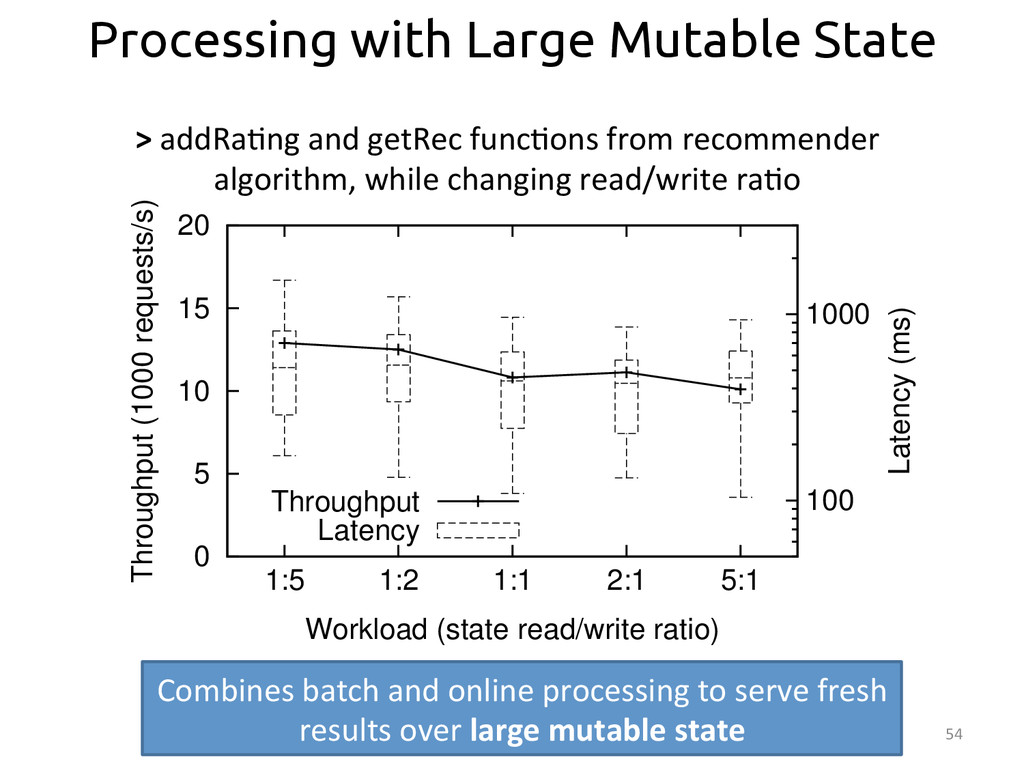
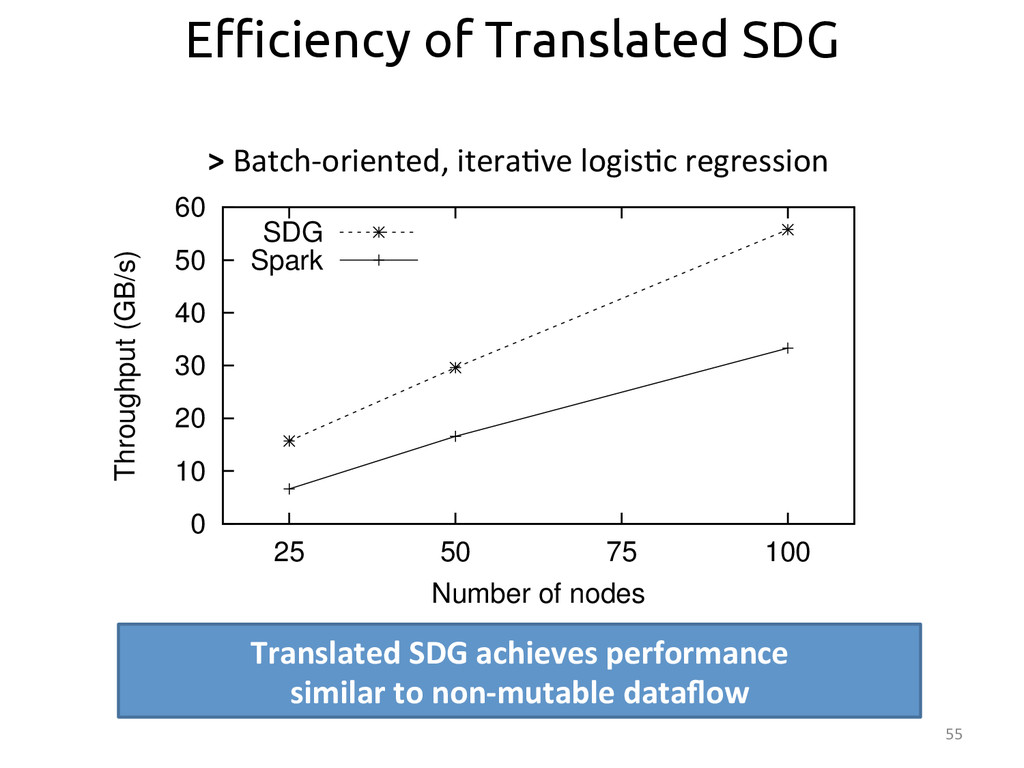
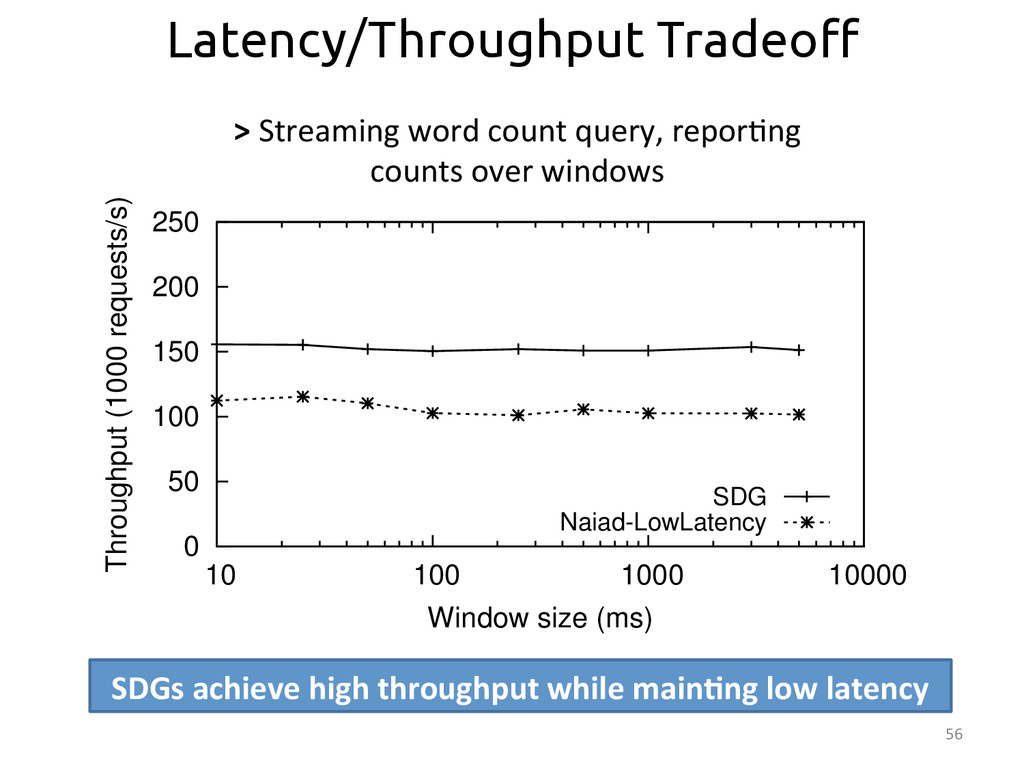
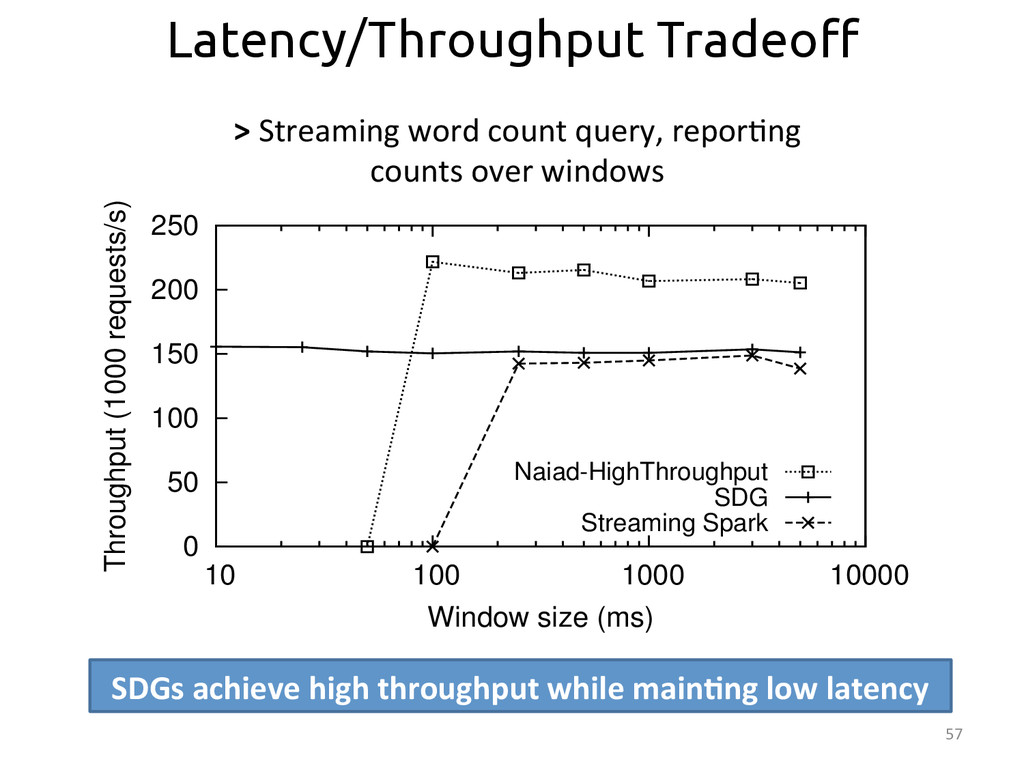
How does mutable state impact performance? How efficient are
translated SDGs? What is the throughput/latency trade-‐off? Experimental set-‐up: – Amazon EC2 (c1 and m1 xlarge instances) – Private cluster (4-‐core 3.4 GHz Intel Xeon servers with 8 GB RAM ) – Sun Java 7, Ubuntu 12.04, Linux kernel 3.10 53 Evaluation of SDG Performance -
54 0 5 10 15 20 1:5 1:2 1:1
2:1 5:1 100 1000 Throughput (1000 requests/s) Latency (ms) Workload (state read/write ratio) Throughput Latency Combines batch and online processing to serve fresh results over large mutable state Processing with Large Mutable State > addRa:ng and getRec func:ons from recommender algorithm, while changing read/write ra:o -
55 0 10 20 30 40 50 60 25
50 75 100 Throughput (GB/s) Number of nodes SDG Spark Translated SDG achieves performance similar to non-‐mutable dataflow > Batch-‐oriented, itera:ve logis:c regression E#ciency of Translated SDG -
56 SDGs achieve high throughput while main>ng low latency
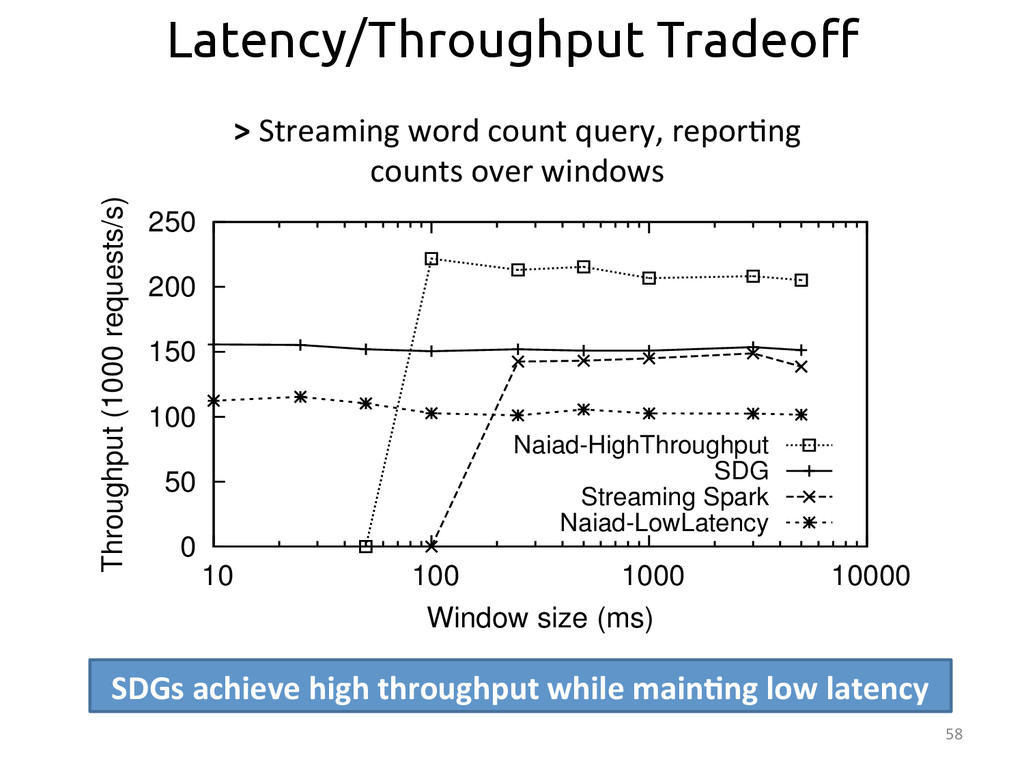
Latency/Throughput Tradeo$ > Streaming word count query, repor:ng counts over windows 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) SDG Naiad-LowLatency -
57 SDGs achieve high throughput while main>ng low latency
Latency/Throughput Tradeo$ > Streaming word count query, repor:ng counts over windows 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) SDG Naiad-LowLatency 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) Naiad-HighThroughput SDG Streaming Spark -
58 SDGs achieve high throughput while main>ng low latency
Latency/Throughput Tradeo$ > Streaming word count query, repor:ng counts over windows 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) SDG Naiad-LowLatency 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) Naiad-HighThroughput SDG Streaming Spark 0 50 100 150 200 250 10 100 1000 10000 Throughput (1000 requests/s) Window size (ms) Naiad-HighThroughput SDG Streaming Spark Naiad-LowLatency -
Running Java programs with the performance of current distributed
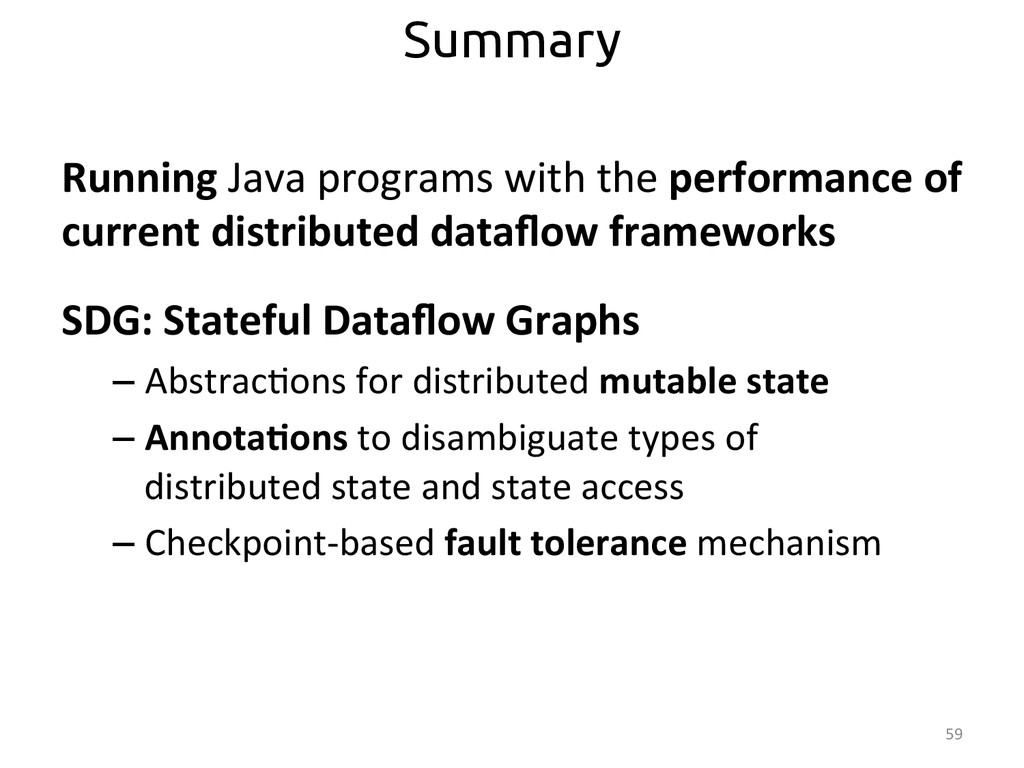
dataflow frameworks SDG: Stateful Dataflow Graphs – Abstrac:ons for distributed mutable state – Annota>ons to disambiguate types of distributed state and state access – Checkpoint-‐based fault tolerance mechanism 59 Summary -
Running Java programs with the performance of current distributed
dataflow frameworks SDG: Stateful Dataflow Graphs – Abstrac:ons for distributed mutable state – Annota>ons to disambiguate types of distributed state and state access – Checkpoint-‐based fault tolerance mechanism 60 Summary Thank you! Any Ques>ons? @raulcfernandez [email protected] hEps://github.com/lsds/Seep/ hEps://github.com/raulcf/SEEPng/ -
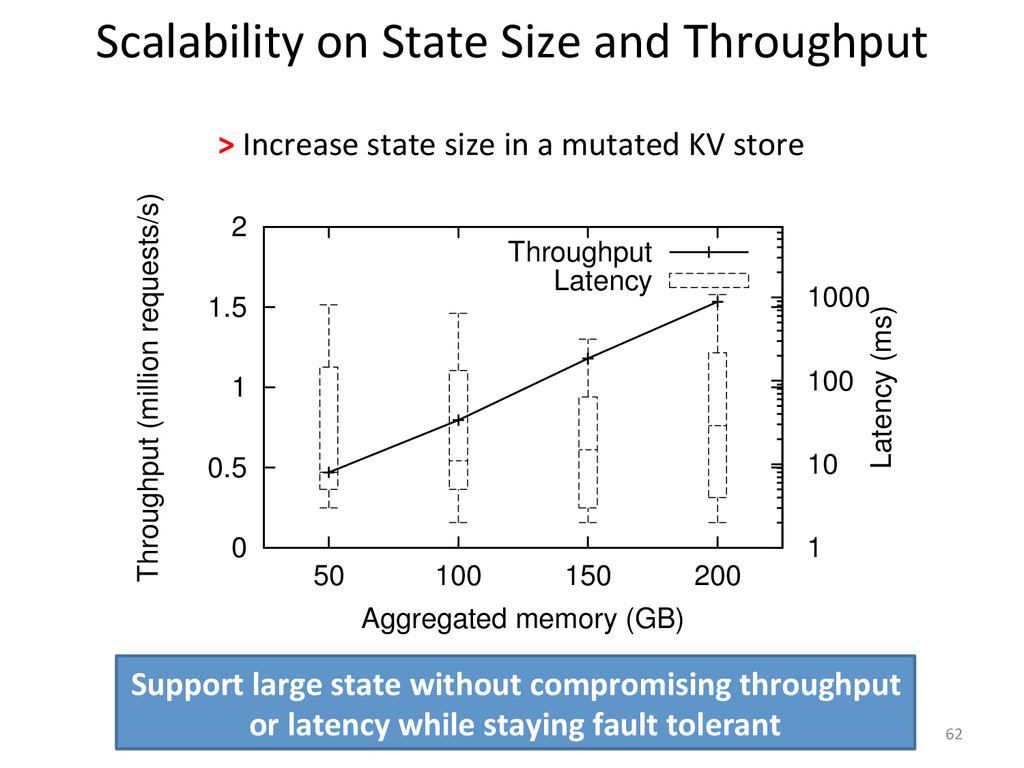
62 0 0.5 1 1.5 2 50 100 150
200 1 10 100 1000 Throughput (million requests/s) Latency (ms) Aggregated memory (GB) Throughput Latency Support large state without compromising throughput or latency while staying fault tolerant Scalability on State Size and Throughput > Increase state size in a mutated KV store -
63 Itera:on in SDG > Local itera>on supported
by one node > Itera>on across TEs requires cycle in the dataflow -
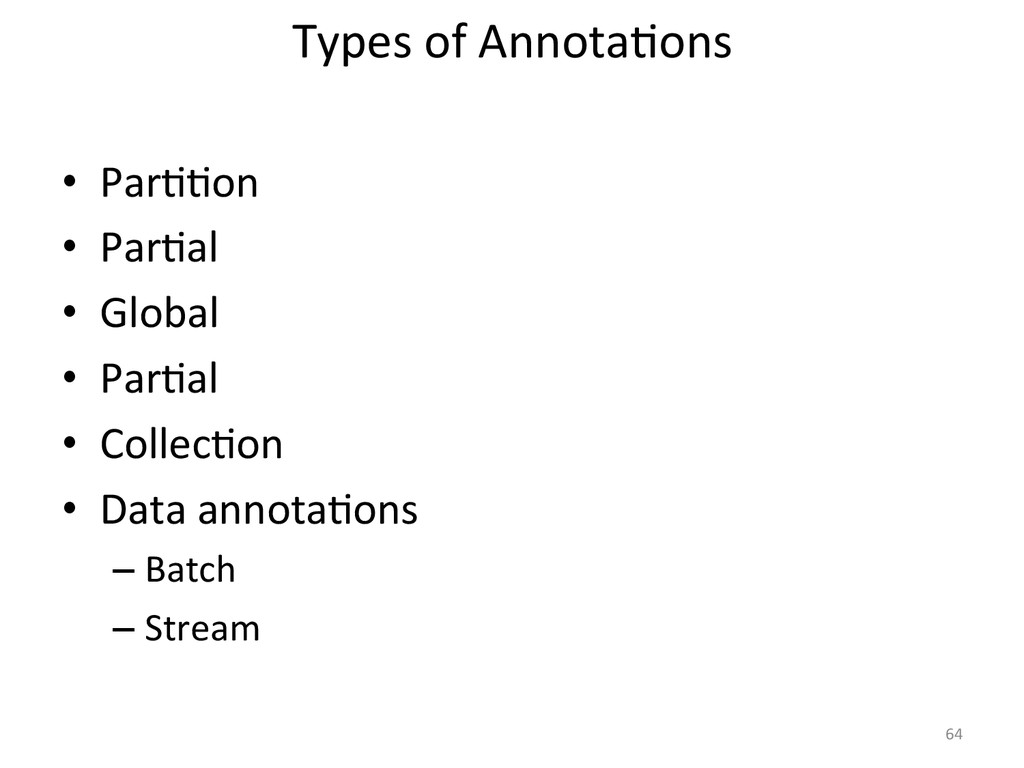
• Par::on • Par:al • Global •
Par:al • Collec:on • Data annota:ons – Batch – Stream 64 Types of Annota:ons -
Overhead of SDG Fault Tolerance 65 1 10
100 1000 10000 No FT 1 2 3 4 5 Latency (ms) State size (GB) 1 10 100 1000 2 4 6 8 10 No FT Latency (ms) Checkpoint frequency (s) Fault Tolerance mechanism impact on performance and latency is small. State size and checkpoin>ng Frequency do not affect the performance -
66 0 2 4 6 8 10 10 100
1000 2000 0 20 40 60 80 100 Throughput (10,000 requests/s) Latency (ms) Aggregated memory (MB) SDG Naiad-NoDisk Naiad-Disk SDG (latency) Naiad-NoDisk (latency) Fault Tolerance Overhead -
0 5 10 15 20 25 30 35 40 1
2 4 Recovery time (s) State size (GB) 1-to-1 recovery 2-to-1 recovery 1-to-2 recovery 2-to-2 recovery 67 Recovery Times -
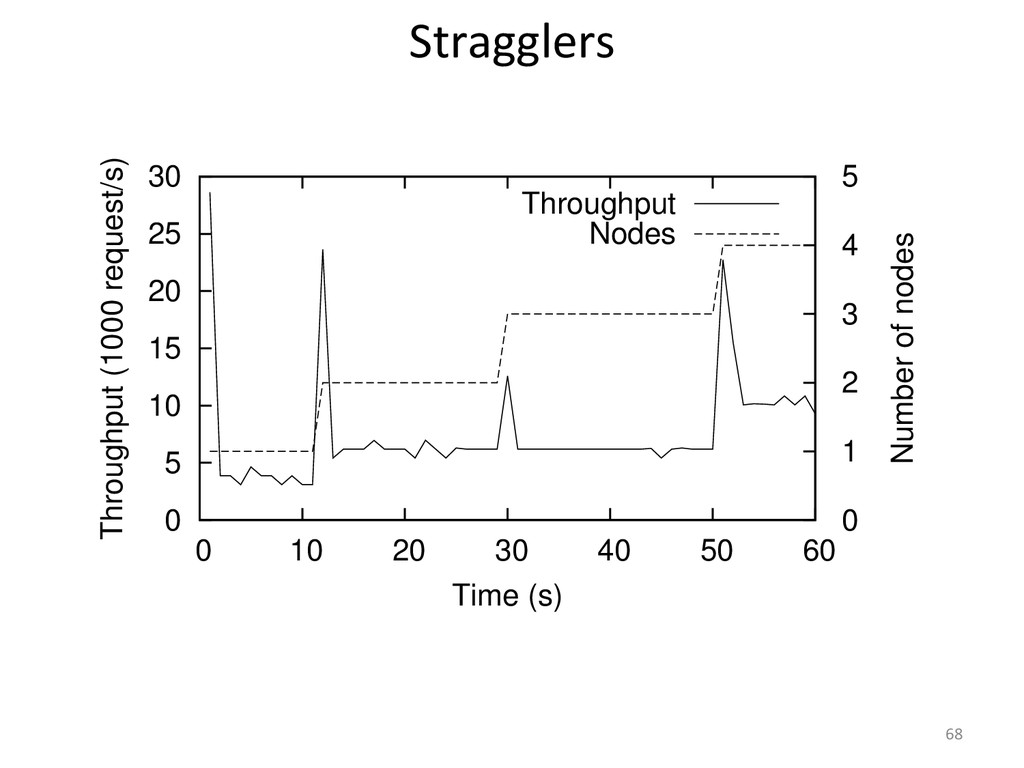
68 0 5 10 15 20 25 30 0
10 20 30 40 50 60 0 1 2 3 4 5 Throughput (1000 request/s) Number of nodes Time (s) Throughput Nodes Stragglers -
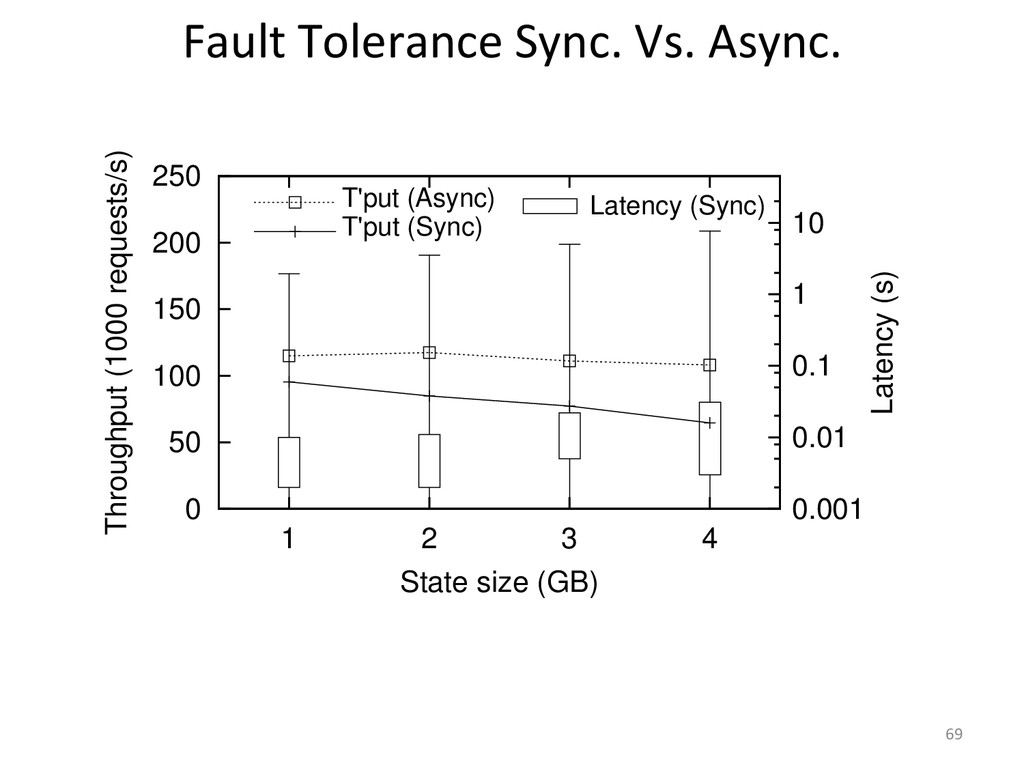
69 0 50 100 150 200 250 1 2
3 4 0.001 0.01 0.1 1 10 Throughput (1000 requests/s) Latency (s) State size (GB) T'put (Sync) Latency (Sync) T'put (Async) Fault Tolerance Sync. Vs. Async. -
System Large State Mutable State Low Latency
Itera>on MapReduce n/a n/a No No Spark n/a n/a No Yes Storm n/a n/a Yes No Naiad No Yes Yes Yes SDG Yes Yes Yes Yes 70 Comparison to State-‐of-‐the-‐Art SDGs are first stateful fault tolerant model; enabling execu:on of impera:ve code with explicit state -
71 Characteris:cs of SDGs > Run>me Data Parallelism
(elas>city) > Support for Cyclic Graphs > Low Latency Adapta:on to varying workloads and mechanism against stragglers Efficiently represent itera:ve algorithms Pipelining tasks decreases latency -
72 Bob Local Expert Hi, I have
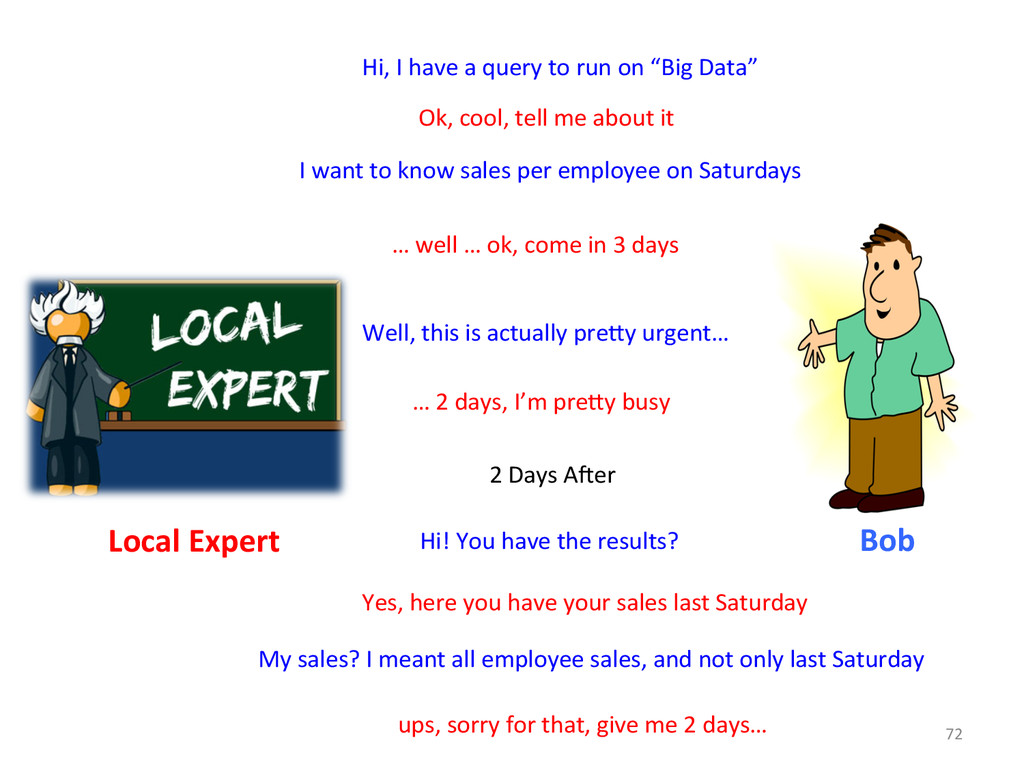
a query to run on “Big Data” Ok, cool, tell me about it I want to know sales per employee on Saturdays … well … ok, come in 3 days Well, this is actually preWy urgent… … 2 days, I’m preWy busy 2 Days Ayer Hi! You have the results? Yes, here you have your sales last Saturday My sales? I meant all employee sales, and not only last Saturday ups, sorry for that, give me 2 days…