Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Efficient solution integrating Spark & Cassandr...

Efficient solution integrating Spark & Cassandra by ALVARO AGEA & LUCA ROSELLINI Big Data Spain 2013

Integrating C* and Spark gives us a system that combines the best of both worlds. The goal of this integration is to obtain a better result than using Spark over HDFS because Cassandra´s philosophy is much closer to RDD's philosophy than what HDFS is.

Session presented at Big Data Spain 2013 Conference
7th Nov 2013
Kinépolis Madrid
http://www.bigdataspain.org
Event promoted by: http://www.paradigmatecnologico.com
Abstract: http://www.bigdataspain.org/2013/conference/an-efficient-data-mining-solution-by-integrating-spark-and-cassandra

Big Data Spain

November 15, 2013

Transcript

39 slides
  1. Stratio Deep An efficient data mining solution “Two and two
    are four? Sometimes… Sometimes they are five.” G. Orwell #StratioB
  2. Goals • Why do you need Cassandra? • What is

    the problem? • Why do you need Spark? • How do they work together? #StratioB
  3. Cassandra #StratioB • Based on DynamoDB… • Replication, Key/Value, P2P
    • And based on Big Table… • Column oriented
  4. New query “I need to find all the reference to

    the domain ACME. I need the answer by Friday.” #StratioB
  5. Problem Cassandra is not well suited to resolved this type

    of queries You need to design the schema with the query in mind #StratioB
  6. What options do we have? • Run Hive Query on

    top of C* • Write an ETL script and load data into another DB • Clone the cluster #StratioB
  7. What options do we have? Run Hive Query on top

    of C* Write ETL scripts and load into another DB Clone the cluster #StratioB
  8. And now… what can we do? “We can't solve problems

    by using the same kind of thinking we used when we created them” #StratioB Albert Einstein
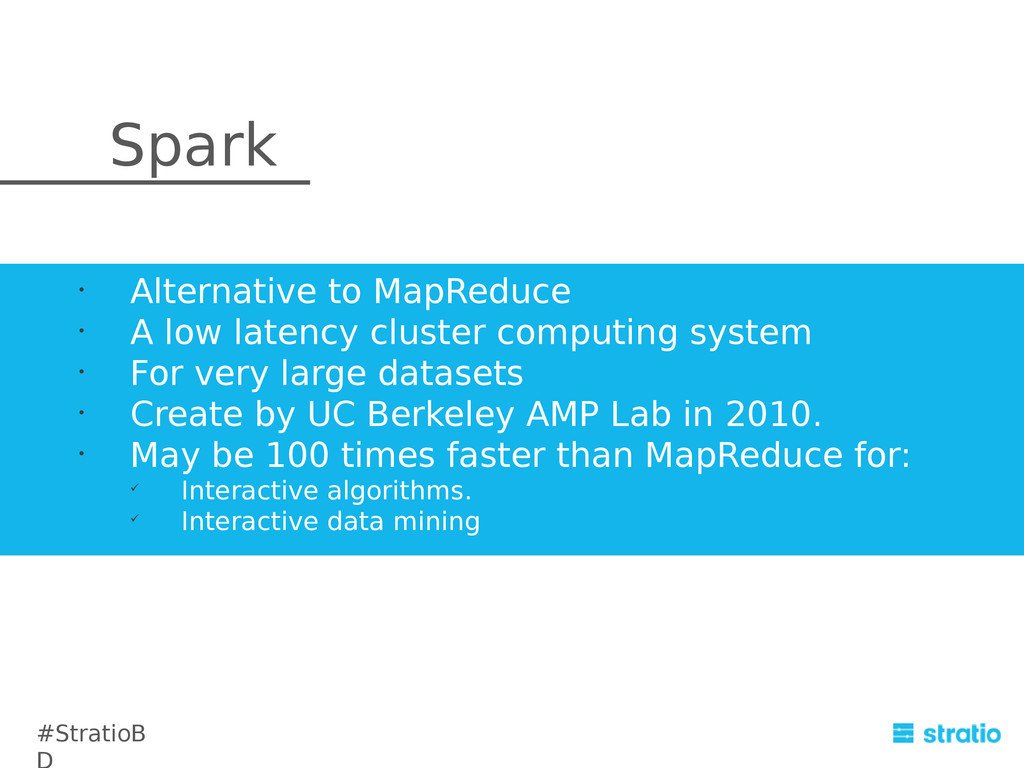
  9. • Alternative to MapReduce • A low latency cluster computing

    system • For very large datasets • Create by UC Berkeley AMP Lab in 2010. • May be 100 times faster than MapReduce for:  Interactive algorithms.  Interactive data mining Spark #StratioB
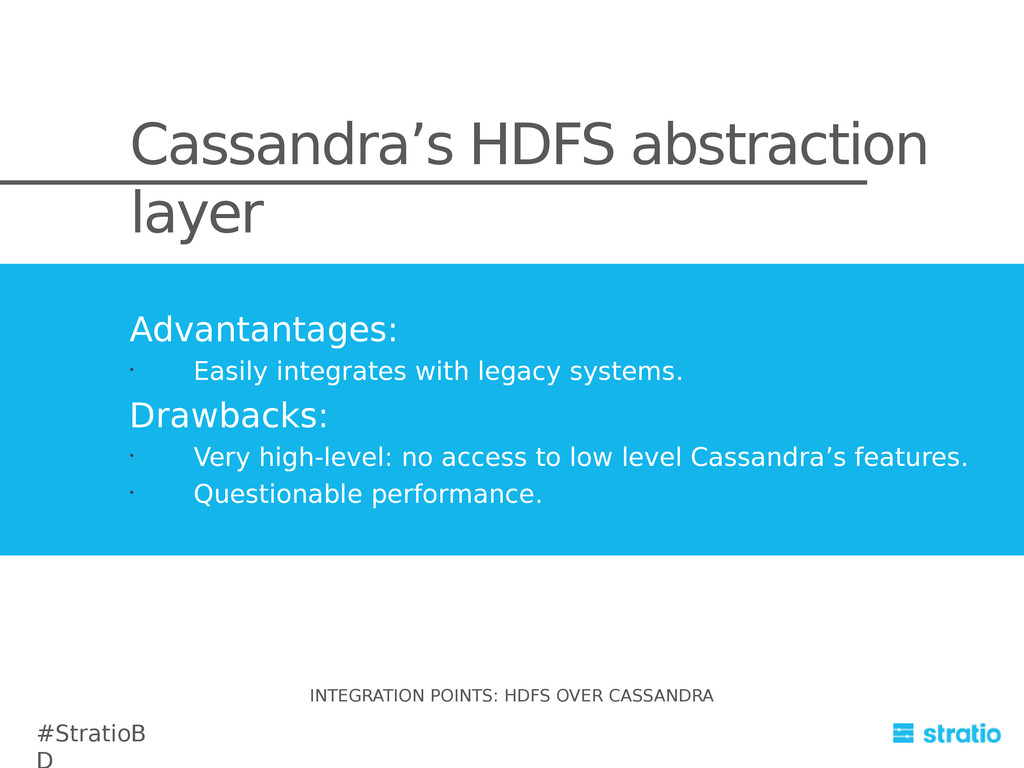
  10. Cassandra’s HDFS abstraction layer Advantantages: • Easily integrates with legacy

    systems. Drawbacks: • Very high-level: no access to low level Cassandra’s features. • Questionable performance. INTEGRATION POINTS: HDFS OVER CASSANDRA #StratioB
  11. Cassandra’s Hadoop Interface • Thrift protocol • CQL3 (our implementation)

     Uses the novel Cassandra’s CqlPagingInputFormat INTEGRATION POINTS: HDFS OVER CASSANDRA #StratioB
  12. • Supports CQL3 features • Respects data locality • Good

    compromise between performance / implementation complexity CQL3 Integration INTEGRATION POINTS: CASSANDRA’S HADOOP INTERFACE – CQL3 #StratioB
  13. CQL3 Integration (II) Provides a Java friendly API: • Developers

    map Column Families to custom serializable POJOs • StratioDeep wraps the complexity of performing Spark calculations directly over the user provided POJOs. INTEGRATION POINTS: CASSANDRA’S HADOOP INTERFACE – CQL3 #StratioB
  14. Drawbacks: • Still not preforming as well as we’d like

     Uses Cassandra’s Hadoop Interface • No analyst-friendly interface:  No SQL-like query features CQL3 Integration (III) INTEGRATION POINTS: CASSANDRA’S HADOOP INTERFACE – CQL3 #StratioB
  15. Bring the integration to another level: • Dump Cassandra’s Hadoop

    Interface • Direct access to Cassandra’s SSTable(s) files. • Extend Cassandra’s CQL3 to make use of Spark’s distributed data processing power Future extensions What are we currently working on? #StratioB

More Decks by Big Data Spain

Other Decks in Technology