Share
Embed
Human-in-the-loop: a design pattern for managing teams which leverage ML by Paco Nathan at Big Data Spain 2017
Human-in-the-loop is an approach which has been used for simulation, training, UX mockups, etc.
Big Data Spain Conference
16th -17th November - Kinépolis Madrid

Big Data Spain
November 22, 2017
Transcript
50 slides
-
Human-‐in-‐a-‐loop: design pattern for managing teams that leverage ML
Paco Nathan @pacoid Director, Learning Group @ O’Reilly Media Big Data Spain, Madrid 2017-‐11-‐16 slides: goo.gl/ba85nF -
Framing Imagine having a mostly-‐automated system where people and
machines collaborate together… May sound a bit Sci-‐Fi, though arguably commonplace. One challenge is whether we can advance beyond just handling rote tasks. Instead of simply running code libraries, can machines make difficult decisions, exercise judgement in complex situations? Can we build systems in which people who aren’t AI experts can “teach” machines to perform complex work – based on examples, not code? -
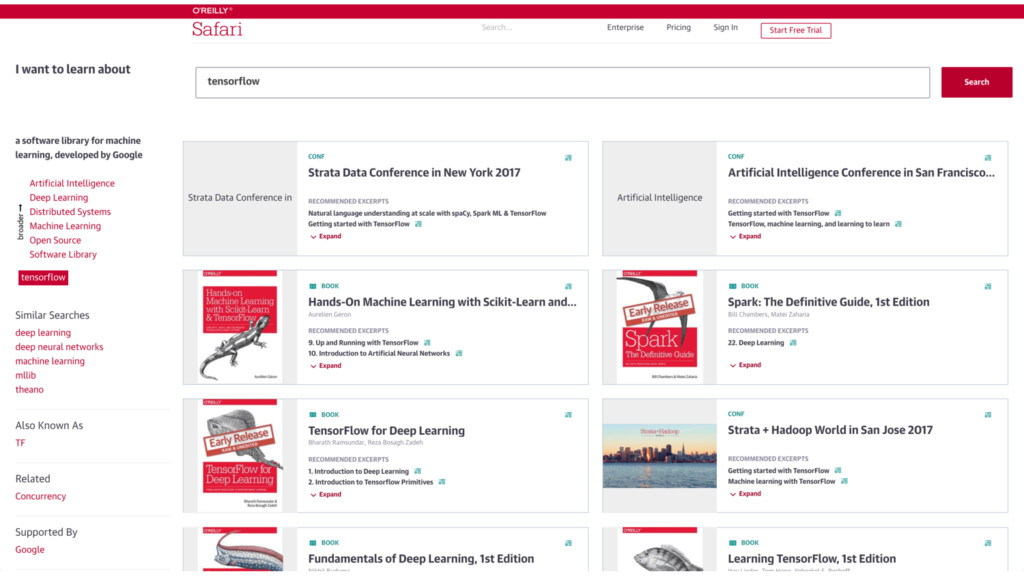
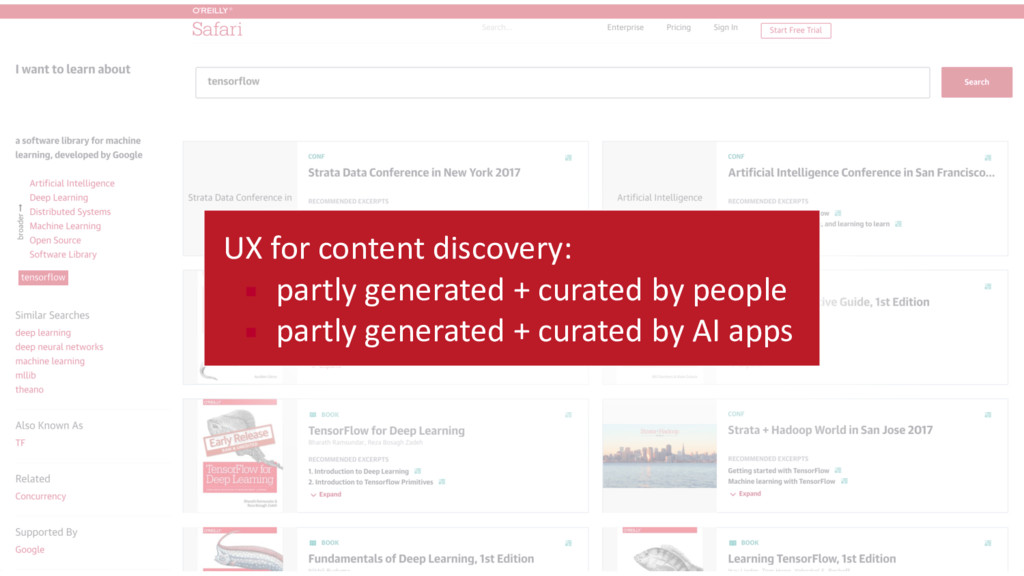
UX for content discovery: ▪ partly generated + curated
by people ▪ partly generated + curated by AI apps -
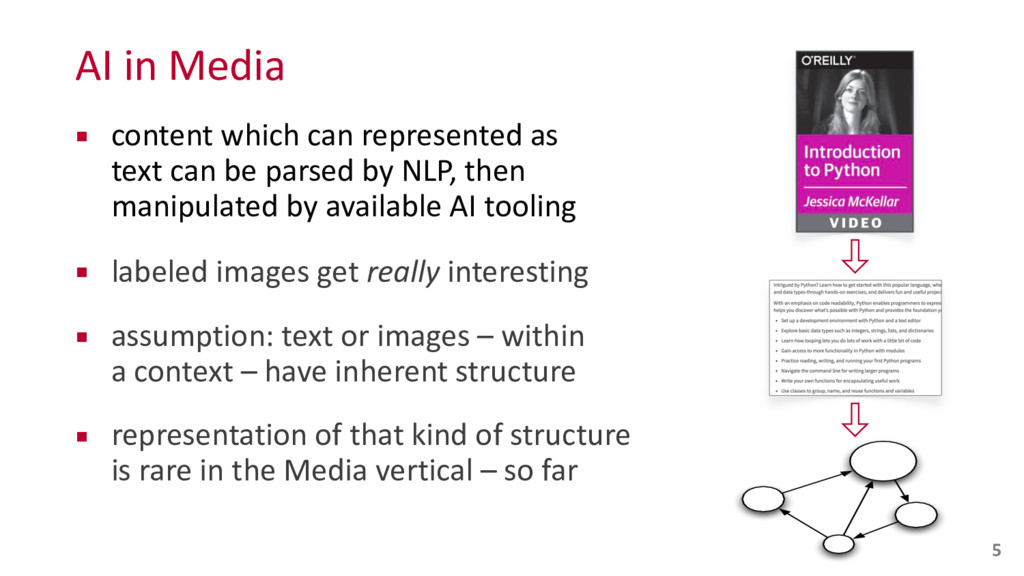
AI in Media ▪ content which can represented as
text can be parsed by NLP, then manipulated by available AI tooling ▪ labeled images get really interesting ▪ assumption: text or images – within a context – have inherent structure ▪ representation of that kind of structure is rare in the Media vertical – so far 5 -
{"graf": [[21, "let", "let", "VB", 1, 48], [0, "'s", "'s",
"PRP", 0, 49], "take", "take", "VB", 1, 50], [0, "a", "a", "DT", 0, 51], [23, "look", "l "NN", 1, 52], [0, "at", "at", "IN", 0, 53], [0, "a", "a", "DT", 0, 54], [ "few", "few", "JJ", 1, 55], [25, "examples", "example", "NNS", 1, 56], [0 "often", "often", "RB", 0, 57], [0, "when", "when", "WRB", 0, 58], [11, "people", "people", "NNS", 1, 59], [2, "are", "be", "VBP", 1, 60], [26, " "first", "JJ", 1, 61], [27, "learning", "learn", "VBG", 1, 62], [0, "abou "about", "IN", 0, 63], [28, "Docker", "docker", "NNP", 1, 64], [0, "they" "they", "PRP", 0, 65], [29, "try", "try", "VBP", 1, 66], [0, "and", "and" 0, 67], [30, "put", "put", "VBP", 1, 68], [0, "it", "it", "PRP", 0, 69], "in", "in", "IN", 0, 70], [0, "one", "one", "CD", 0, 71], [0, "of", "of", 0, 72], [0, "a", "a", "DT", 0, 73], [24, "few", "few", "JJ", 1, 74], [31, "existing", "existing", "JJ", 1, 75], [18, "categories", "category", "NNS 76], [0, "sometimes", "sometimes", "RB", 0, 77], [11, "people", "people", 1, 78], [9, "think", "think", "VBP", 1, 79], [0, "it", "it", "PRP", 0, 80 "'s", "be", "VBZ", 1, 81], [0, "a", "a", "DT", 0, 82], [32, "virtualizati "virtualization", "NN", 1, 83], [19, "tool", "tool", "NN", 1, 84], [0, "l "like", "IN", 0, 85], [33, "VMware", "vmware", "NNP", 1, 86], [0, "or", " "CC", 0, 87], [34, "virtualbox", "virtualbox", "NNP", 1, 88], [0, "also", "also", "RB", 0, 89], [35, "known", "know", "VBN", 1, 90], [0, "as", "as" 0, 91], [0, "a", "a", "DT", 0, 92], [36, "hypervisor", "hypervisor", "NN" 93], [0, "these", "these", "DT", 0, 94], [2, "are", "be", "VBP", 1, 95], "tools", "tool", "NNS", 1, 96], [0, "which", "which", "WDT", 0, 97], [2, "be", "VBP", 1, 98], [37, "emulating", "emulate", "VBG", 1, 99], [38, "hardware", "hardware", "NN", 1, 100], [0, "for", "for", "IN", 0, 101], [ "virtual", "virtual", "JJ", 1, 102], [40, "software", "software", "NN", 1 103]], "id": "001.video197359", "sha1": "4b69cf60f0497887e3776619b922514f2e5b70a8"} AI in Media 6 {"count": 2, "ids": [32, 19], "pos": "np", "rank": 0.0194, "text": "virtualization tool"} {"count": 2, "ids": [40, 69], "pos": "np", "rank": 0.0117, "text": "software applications"} {"count": 4, "ids": [38], "pos": "np", "rank": 0.0114, "text": "hardware"} {"count": 2, "ids": [33, 36], "pos": "np", "rank": 0.0099, "text": "vmware hypervisor"} {"count": 4, "ids": [28], "pos": "np", "rank": 0.0096, "text": "docker"} {"count": 4, "ids": [34], "pos": "np", "rank": 0.0094, "text": "virtualbox"} {"count": 10, "ids": [11], "pos": "np", "rank": 0.0049, "text": "people"} {"count": 4, "ids": [37], "pos": "vbg", "rank": 0.0026, "text": "emulating"} {"count": 2, "ids": [27], "pos": "vbg", "rank": 0.0016, "text": "learning"} Transcript: let's take a look at a few examples often when people are first learning about Docker they try and put it in one of a few existing categories sometimes people think it's a virtualization tool like VMware or virtualbox also known as a hypervisor these are tools which are emulating hardware for virtual software Confidence: 0.973419129848 39 KUBERNETES 0.8747 coreos 0.8624 etcd 0.8478 DOCKER CONTAINERS 0.8458 mesos 0.8406 DOCKER 0.8354 DOCKER CONTAINER 0.8260 KUBERNETES CLUSTER 0.8258 docker image 0.8252 EC2 0.8210 docker hub 0.8138 OPENSTACK orm:Docker a orm:Vendor; a orm:Container; a orm:Open_Source; a orm:Commercial_Software; owl:sameAs dbr:Docker_%28software%29; skos:prefLabel "Docker"@en; -
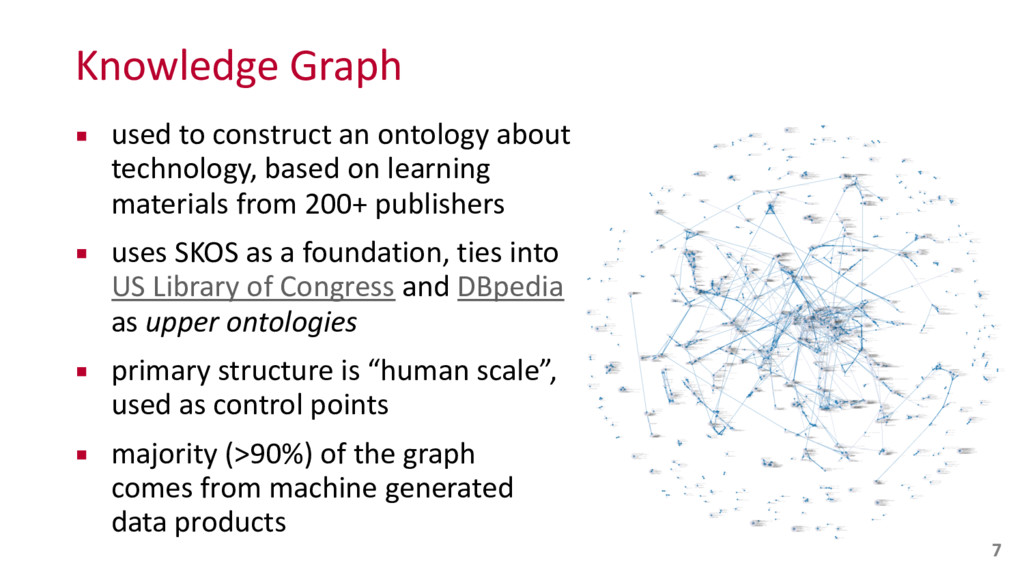
Knowledge Graph ▪ used to construct an ontology about
technology, based on learning materials from 200+ publishers ▪ uses SKOS as a foundation, ties into US Library of Congress and DBpedia as upper ontologies ▪ primary structure is “human scale”, used as control points ▪ majority (>90%) of the graph comes from machine generated data products 7 -
AI is real, but why now? ▪ Big Data: machine
data (1997-‐ish) ▪ Big Compute: cloud computing (2006-‐ish) ▪ Big Models: deep learning (2009-‐ish) The confluence of three factors created a business environment where AI could become mainstream What else is needed? 8 -
Machine learning supervised ML: ▪ take a dataset where
each element has a label ▪ train models on a portion of the data to predict the labels, then evaluate on the holdout ▪ deep learning is a popular example, but only if you have lots of labeled training data available -
Machine learning unsupervised ML: ▪ run lots of unlabeled
data through an algorithm to detect “structure” or embedding ▪ for example, clustering algorithms such as K-‐means ▪ unsupervised approaches for AI are an open research question -
Active learning special case of semi-‐supervised ML: ▪ send
difficult decisions/edge cases to experts; let algorithms handle routine decisions (automation) ▪ works well in use cases which have lots of inexpensive, unlabeled data ▪ e.g., abundance of content to be classified, where the cost of labeling is the expense -
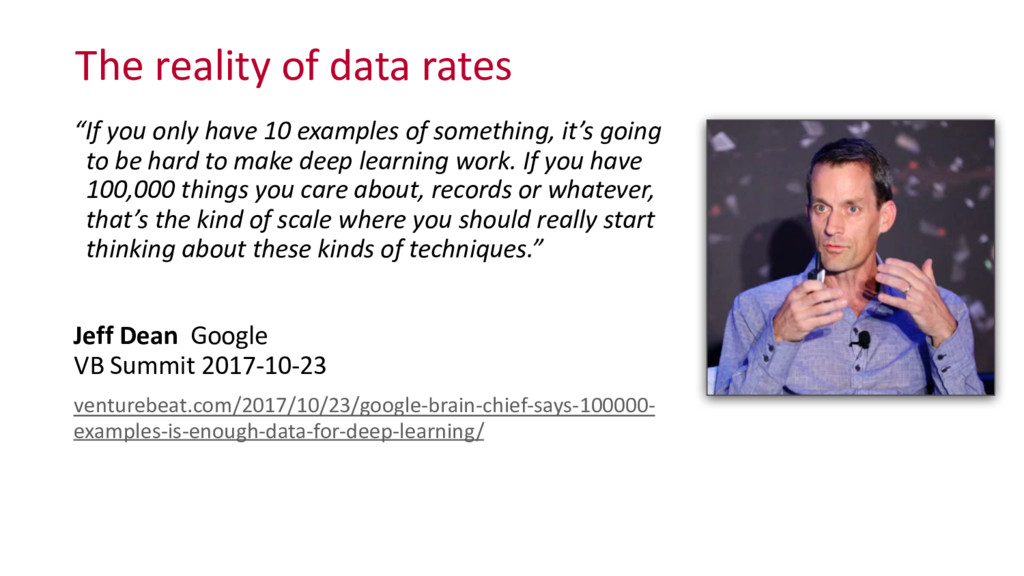
The reality of data rates “If you only have 10
examples of something, it’s going to be hard to make deep learning work. If you have 100,000 things you care about, records or whatever, that’s the kind of scale where you should really start thinking about these kinds of techniques.” Jeff Dean Google VB Summit 2017-‐10-‐23 venturebeat.com/2017/10/23/google-‐brain-‐chief-‐says-‐100000-‐ examples-‐is-‐enough-‐data-‐for-‐deep-‐learning/ -
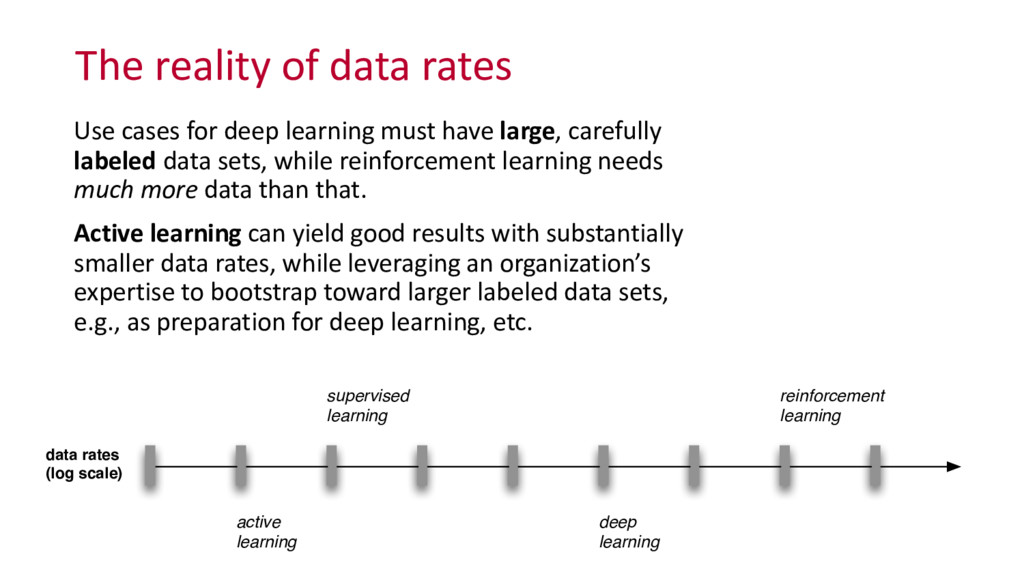
The reality of data rates Use cases for deep learning
must have large, carefully labeled data sets, while reinforcement learning needs much more data than that. Active learning can yield good results with substantially smaller data rates, while leveraging an organization’s expertise to bootstrap toward larger labeled data sets, e.g., as preparation for deep learning, etc. reinforcement learning supervised learning active learning deep learning data rates (log scale) -
Active learning Real-‐World Active Learning: Applications and Strategies for
Human-‐in-‐the-‐Loop Machine Learning radar.oreilly.com/2015/02/human-‐in-‐the-‐loop-‐ machine-‐learning.html Ted Cuzzillo O’Reilly Media, 2015-‐02-‐05 Develop a policy for how human experts select exemplars: ▪ bias toward labels most likely to influence the classifier ▪ bias toward ensemble disagreement ▪ bias toward denser regions of training data 17 -
Active learning Active learning and transfer learning safaribooksonline.com/library/view/oreilly-‐ artificial-‐intelligence/9781491985250/ video314919.html
Luke Biewald CrowdFlower The AI Conf, 2017-‐09-‐17 breakthroughs lag algorithm invention, waiting for “killer data set” to emerge, often decade+ 18 -
Design pattern: Human-‐in-‐the-‐loop Building a business that combines human experts
and data science oreilly.com/ideas/building-‐a-‐business-‐that-‐ combines-‐human-‐experts-‐and-‐data-‐science-‐2 Eric Colson StitchFix O’Reilly Data Show, 2016-‐01-‐28 “what machines can’t do are things around cognition, things that have to do with ambient information, or appreciation of aesthetics, or even the ability to relate to another human” 19 -
Design pattern: Human-‐in-‐the-‐loop Strategies for integrating people and machine
learning in online systems safaribooksonline.com/library/view/oreilly-‐ artificial-‐intelligence/9781491976289/ video311857.html Jason Laska Clara Labs The AI Conf, 2017-‐06-‐29 how to create a two-‐sided marketplace where machines and people compete on a spectrum of relative expertise and capabilities 20 -
Design pattern: Human-‐in-‐the-‐loop Building human-‐assisted AI applications oreilly.com/ideas/building-‐human-‐ assisted-‐ai-‐applications Adam
Marcus B12 O’Reilly Data Show, 2016-‐08-‐25 Orchestra: a platform for building human-‐ assisted AI applications, e.g., to create business websites https://github.com/b12io/orchestra example http://www.coloradopicked.com/ 21 -
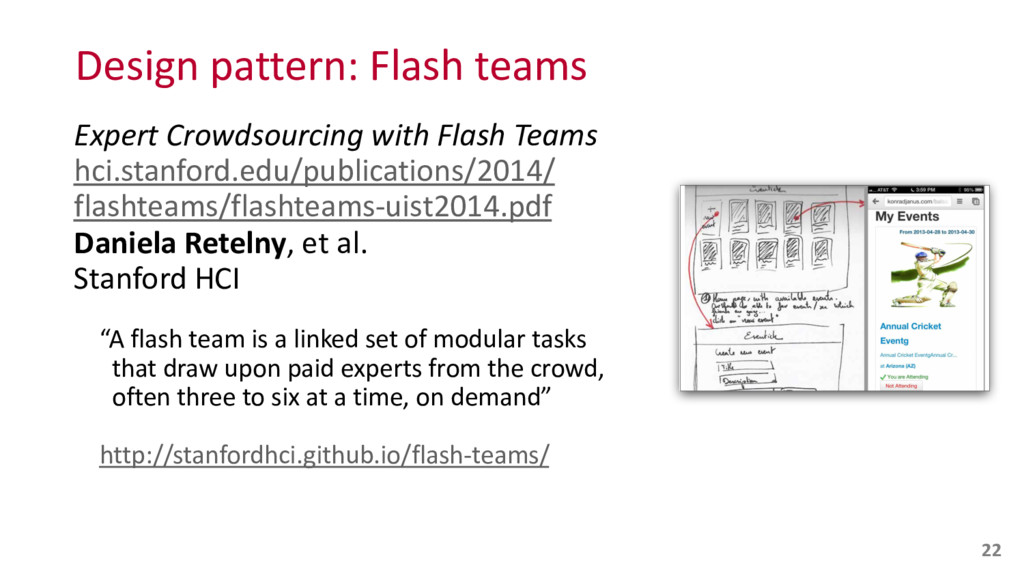
Design pattern: Flash teams Expert Crowdsourcing with Flash Teams hci.stanford.edu/publications/2014/
flashteams/flashteams-‐uist2014.pdf Daniela Retelny, et al. Stanford HCI “A flash team is a linked set of modular tasks that draw upon paid experts from the crowd, often three to six at a time, on demand” http://stanfordhci.github.io/flash-‐teams/ 22 -
Weak supervision / Data programming Creating large training data sets
quickly oreilly.com/ideas/creating-‐large-‐training-‐ data-‐sets-‐quickly Alex Ratner Stanford O’Reilly Data Show, 2017-‐06-‐08 Snorkel: “weak supervision” and “data programming” as another instance of human-‐in-‐the-‐loop github.com/HazyResearch/snorkel conferences.oreilly.com/strata/strata-‐ny/public/ schedule/detail/61849 23 -
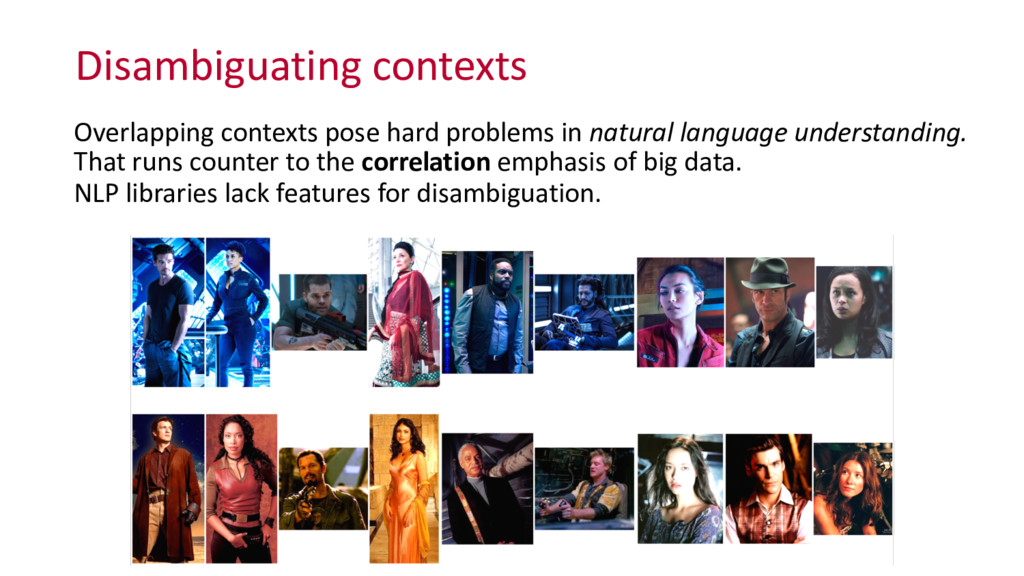
Disambiguating contexts Overlapping contexts pose hard problems in natural language
understanding. That runs counter to the correlation emphasis of big data. NLP libraries lack features for disambiguation. -
Disambiguating contexts 27 Suppose someone publishes a book which uses
the term `IOS`: are they talking about an operating system for an Apple iPhone, or about an operating system for a Cisco router? We handle lots of content about both. Disambiguating those contexts is important for good UX in personalized learning. In other words, how do machines help people distinguish that content within search? Potentially a good case for deep learning, except for the lack of labeled data at scale. -
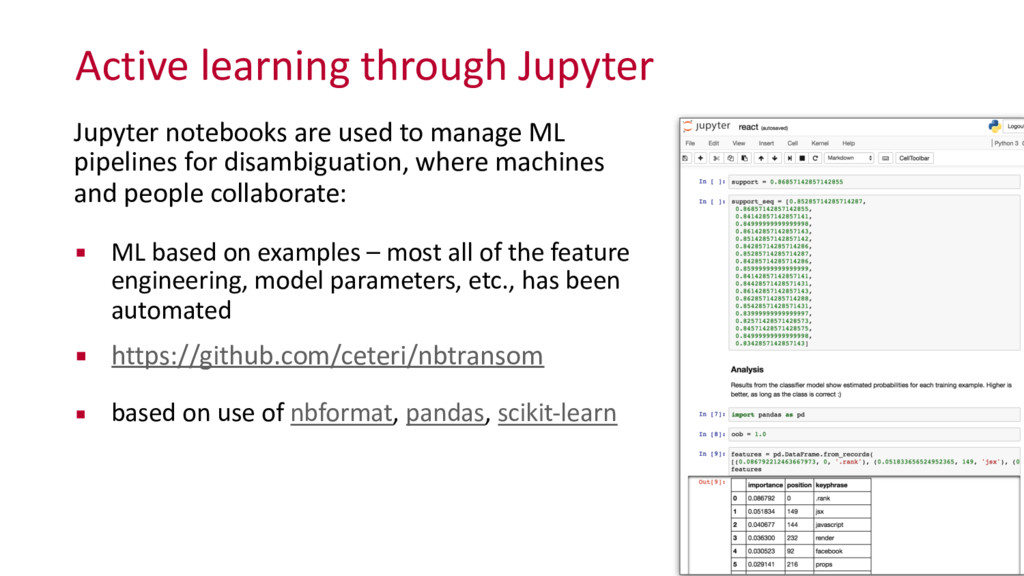
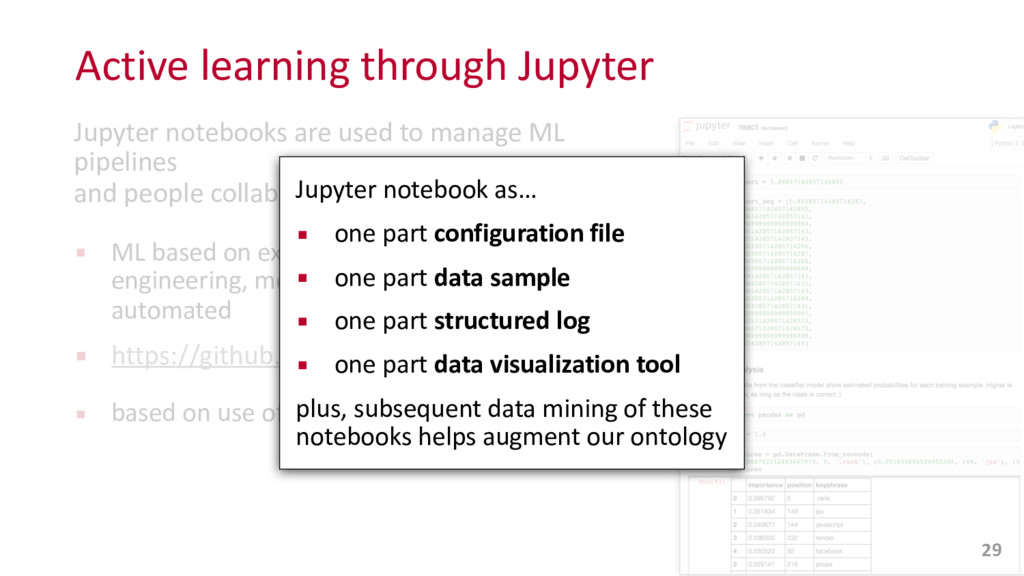
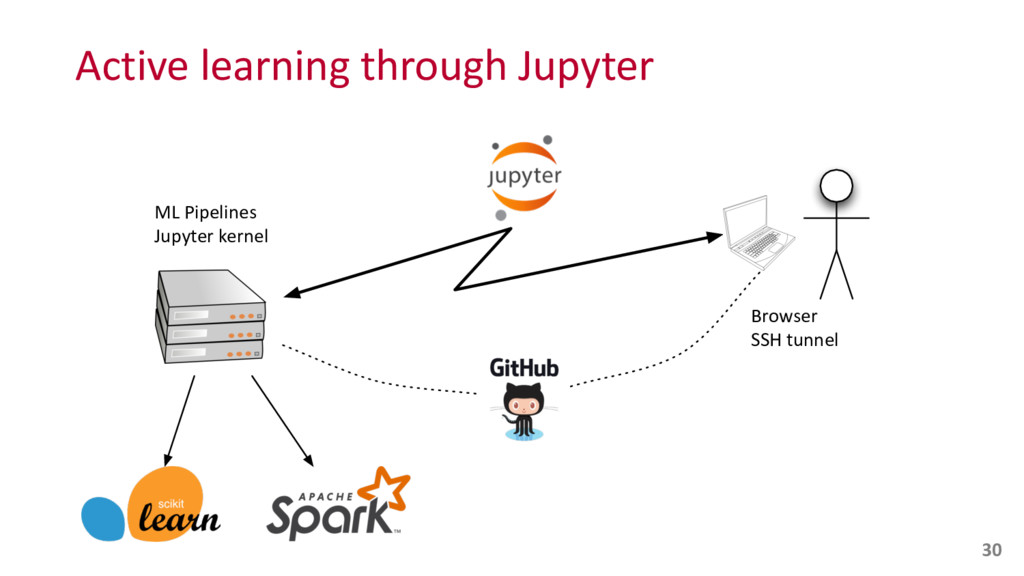
Active learning through Jupyter 28 Jupyter notebooks are used to
manage ML pipelines for disambiguation, where machines and people collaborate: ▪ ML based on examples – most all of the feature engineering, model parameters, etc., has been automated ▪ https://github.com/ceteri/nbtransom ▪ based on use of nbformat, pandas, scikit-‐learn -
Active learning through Jupyter 29 Jupyter notebooks are used to
manage ML pipelines and people collaborate: ▪ ML based on examples – most all of the feature engineering, model parameters, etc., has been automated ▪ https://github.com/ceteri/nbtransom ▪ based on use of Jupyter notebook as… ▪ one part configuration file ▪ one part data sample ▪ one part structured log ▪ one part data visualization tool plus, subsequent data mining of these notebooks helps augment our ontology -
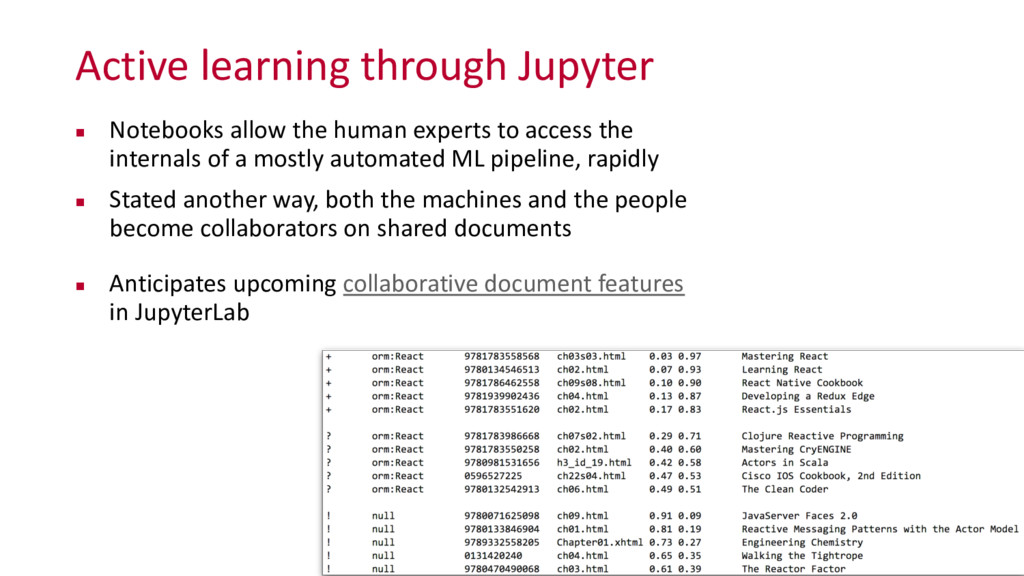
Active learning through Jupyter ▪ Notebooks allow the human experts
to access the internals of a mostly automated ML pipeline, rapidly ▪ Stated another way, both the machines and the people become collaborators on shared documents ▪ Anticipates upcoming collaborative document features in JupyterLab -
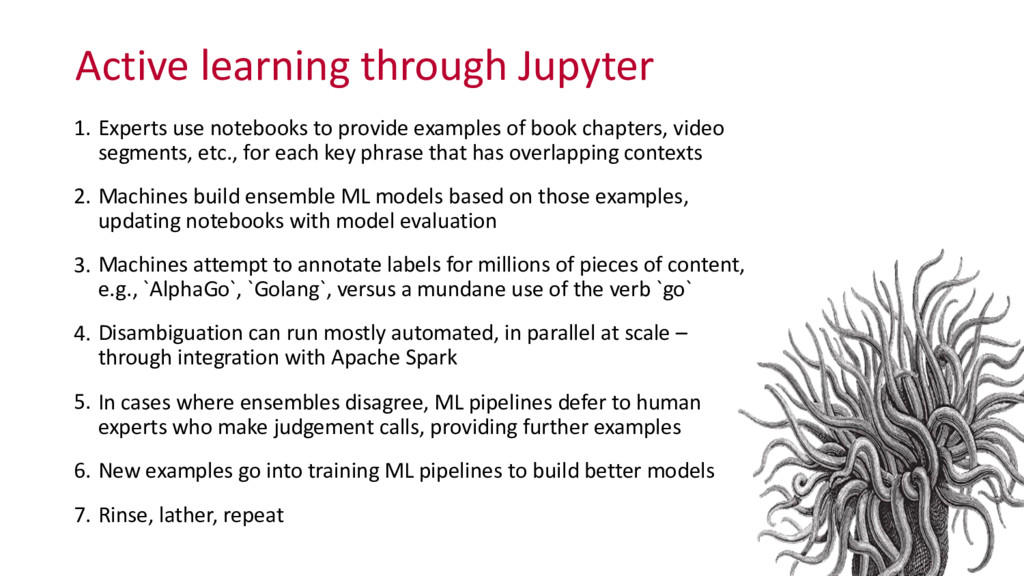
Active learning through Jupyter 1. Experts use notebooks to provide
examples of book chapters, video segments, etc., for each key phrase that has overlapping contexts 2. Machines build ensemble ML models based on those examples, updating notebooks with model evaluation 3. Machines attempt to annotate labels for millions of pieces of content, e.g., `AlphaGo`, `Golang`, versus a mundane use of the verb `go` 4. Disambiguation can run mostly automated, in parallel at scale – through integration with Apache Spark 5. In cases where ensembles disagree, ML pipelines defer to human experts who make judgement calls, providing further examples 6. New examples go into training ML pipelines to build better models 7. Rinse, lather, repeat -
Nuances ▪ No Free Lunch theorem: it is better to
err on the side of less false positives / more false negatives in use cases about learning materials ▪ Employ a bias toward exemplars policy, i.e., those most likely to influence the classifier ▪ Potentially, “AI experts” may be Customer Service staff who review edge cases within search results or recommended content – as an integral part of our UX – then re-‐train the ML pipelines through examples -
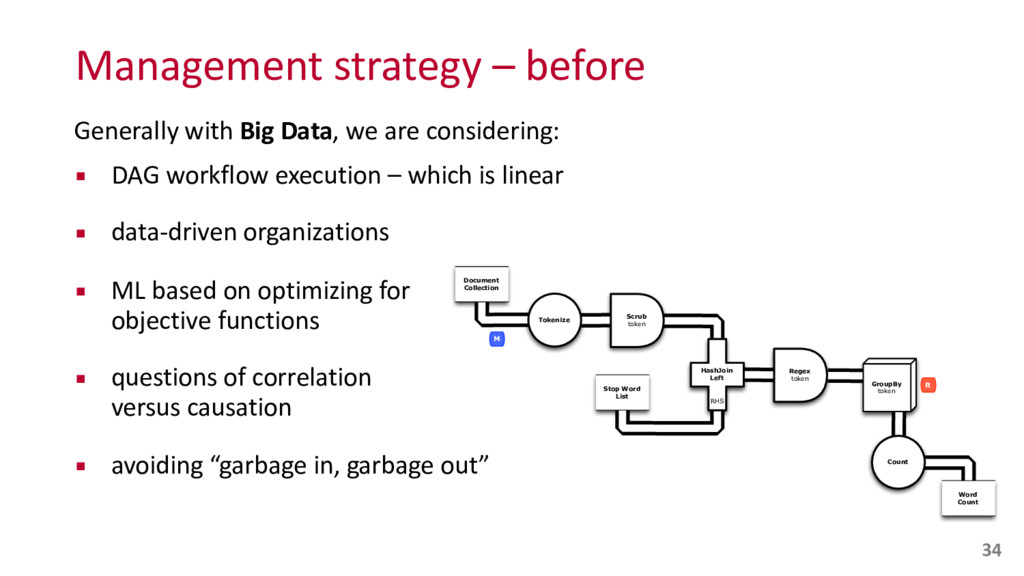
Management strategy – before Generally with Big Data, we are
considering: ▪ DAG workflow execution – which is linear ▪ data-‐driven organizations ▪ ML based on optimizing for objective functions ▪ questions of correlation versus causation ▪ avoiding “garbage in, garbage out” Scrub token Document Collection Tokenize Word Count GroupBy token Count Stop Word List Regex token HashJoin Left RHS M R 34 -
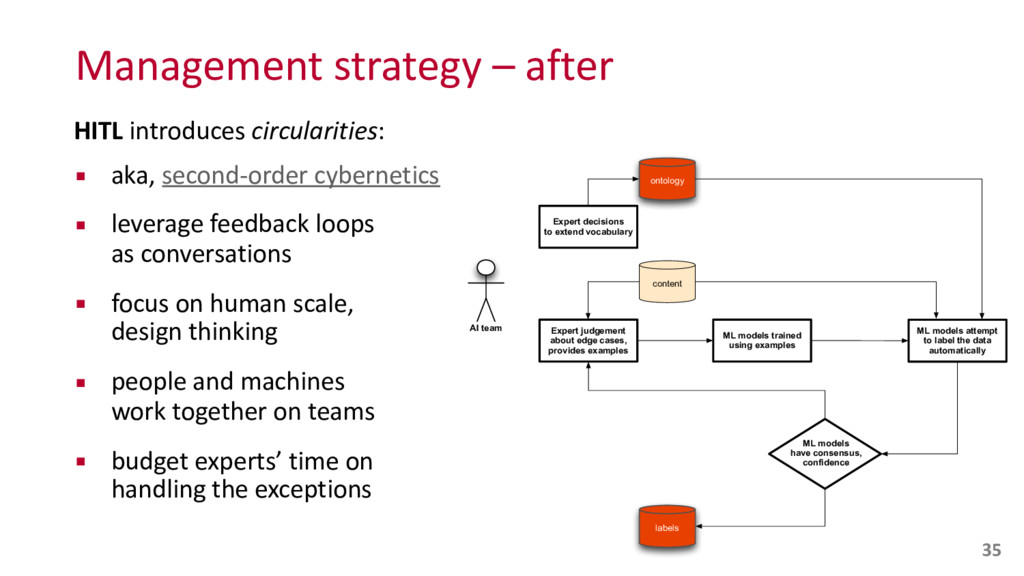
Management strategy – after HITL introduces circularities: ▪ aka,
second-‐order cybernetics ▪ leverage feedback loops as conversations ▪ focus on human scale, design thinking ▪ people and machines work together on teams ▪ budget experts’ time on handling the exceptions AI team content ontology ML models attempt to label the data automatically Expert judgement about edge cases, provides examples ML models trained using examples Expert decisions to extend vocabulary ML models have consensus, confidence labels 35 -
Essential takeaway idea: Depending on the organization, key ingredients
needed to enable effective AI apps may come from non-‐traditional “tech” sources … In other words, based on human-‐in-‐the-‐loop design pattern, AI expertise may emerge from your Sales, Marketing, and Customer Service teams – which have crucial insights about your customers’ needs. -
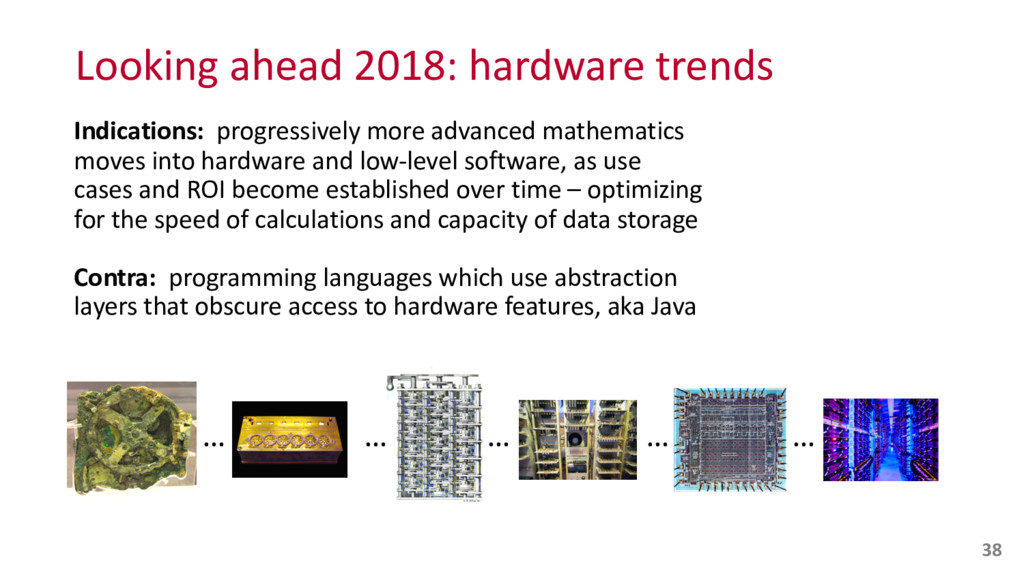
Looking ahead 2018: hardware trends Indications: progressively more advanced
mathematics moves into hardware and low-‐level software, as use cases and ROI become established over time – optimizing for the speed of calculations and capacity of data storage Contra: programming languages which use abstraction layers that obscure access to hardware features, aka Java 38 … … … … … -
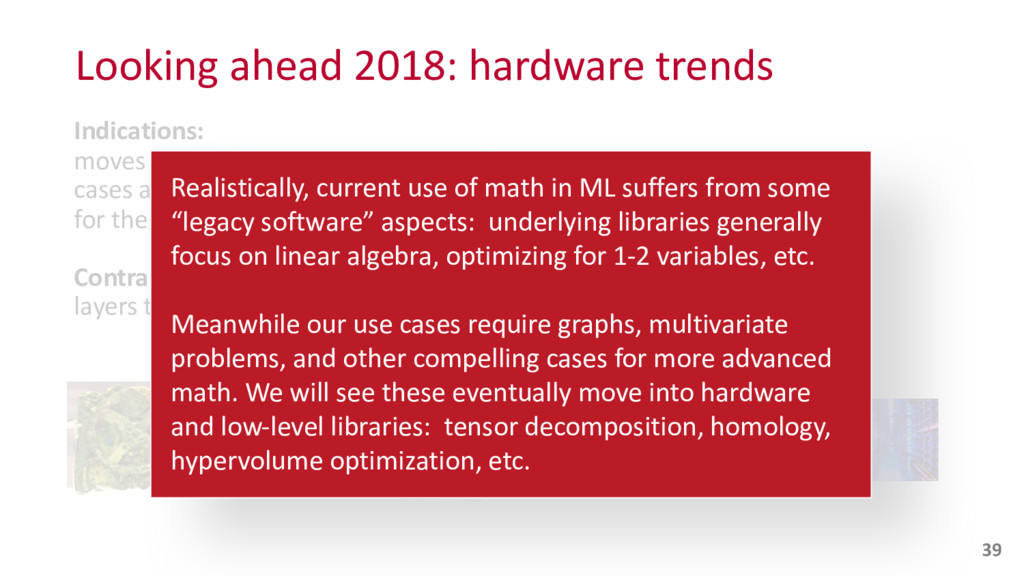
Indications: moves into hardware and low-‐level software, as use
cases and ROI become established over time – optimizing for the speed of calculations and capacity of data storage Contra: layers that obscure access to hardware features, aka Java Looking ahead 2018: hardware trends 39 … … … … … Realistically, current use of math in ML suffers from some “legacy software” aspects: underlying libraries generally focus on linear algebra, optimizing for 1-‐2 variables, etc. Meanwhile our use cases require graphs, multivariate problems, and other compelling cases for more advanced math. We will see these eventually move into hardware and low-‐level libraries: tensor decomposition, homology, hypervolume optimization, etc. -
Looking ahead 2018: software trends Indications: cognitive subsystems progressively
becoming automated, e.g., sensory perception, pattern recognition, decisions, gaming, mimicry, optimization, knowledge representation, language, complex movements, planning, scheduling, etc. Contra: merely incremental changes for practices in software engineering and product management – within the context of AI apps – which has suffered from being too“linear” 40 -
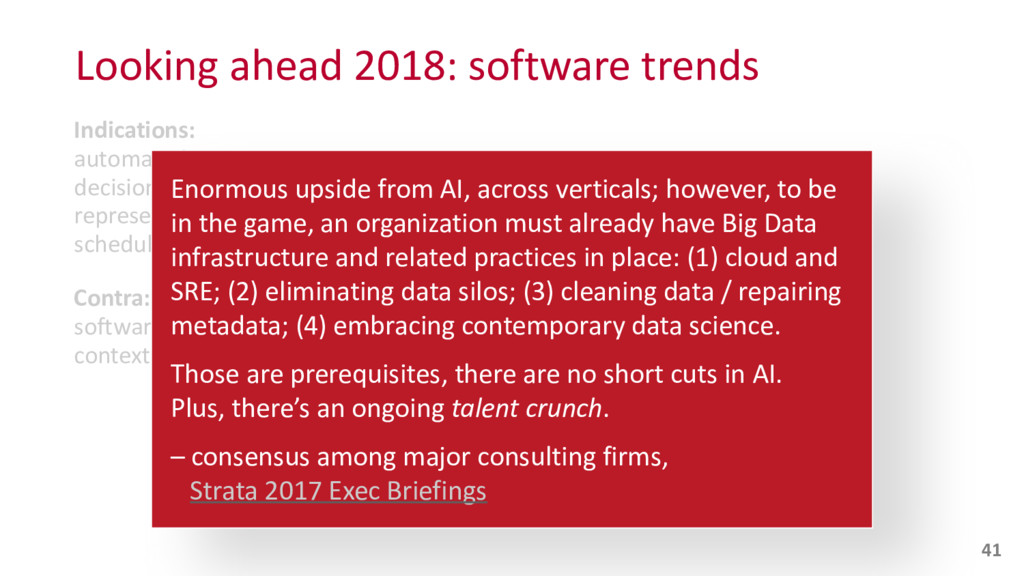
Indications: automated, e.g., sensory perception, pattern recognition, decisions, gaming,
mimicry, optimization, knowledge representation, language, complex movements, planning, scheduling, etc. Contra: software engineering and product management – within the context of AI apps – which has Looking ahead 2018: software trends 41 Enormous upside from AI, across verticals; however, to be in the game, an organization must already have Big Data infrastructure and related practices in place: (1) cloud and SRE; (2) eliminating data silos; (3) cleaning data / repairing metadata; (4) embracing contemporary data science. Those are prerequisites, there are no short cuts in AI. Plus, there’s an ongoing talent crunch. – consensus among major consulting firms, Strata 2017 Exec Briefings -
Looking ahead 2018: people trends Indications: organizations embracing circularities,
focused on optimizing for fitness functions (populations of priorities, longer-‐term ROI) in lieu of optimizing for objective functions (singular goals, linear cognition, short-‐term ROI) Contra: conflict defined by “confident personalities vs. confidence intervals”, see goo.gl/GPYZ6v 42 -
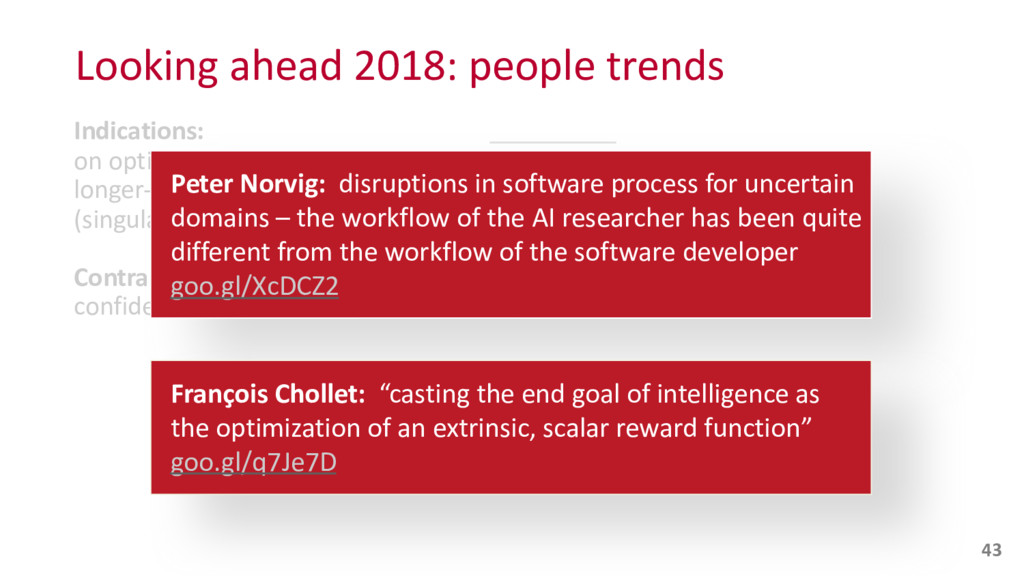
Indications: on optimizing for longer-‐term ROI) in lieu of
optimizing for (singular goals, linear cognition, short-‐term ROI) Contra: confidence intervals”, see Looking ahead 2018: people trends 43 Peter Norvig: disruptions in software process for uncertain domains – the workflow of the AI researcher has been quite different from the workflow of the software developer goo.gl/XcDCZ2 François Chollet: “casting the end goal of intelligence as the optimization of an extrinsic, scalar reward function” goo.gl/q7Je7D -
Summary Ahead in AI: hardware advances force abrupt changes
in software practices – which has lagged due to lack of infrastructure, data quality, outdated process, etc. HITL (active learning) as management strategy for AI addresses broad needs across industry, especially for enterprise organizations. Big Team begins to take its place in the formula Big Data + Big Compute + Big Models. -
Summary The “game” is not to replace people – instead
it is about leveraging AI to augment staff, so that organizations can retain people with valuable domain expertise, making their contributions and experience even more vital. This is a personal opinion, which does not necessarily reflect the views of my employer. However, the views of my employer… -
Strata Data SG, Dec 4-‐7 SJ, Mar 5-‐8 UK,
May 21-‐24 CN, Jul 12-‐15 The AI Conf CN Apr 10-‐13 NY, Apr 29-‐May 2 SF, Sep 4-‐7 UK, Oct 8-‐11 JupyterCon NY, Aug 21-‐24 OSCON PDX, Jul 16-‐19, 2018 47 -
48 Get Started with NLP in Python Just Enough
Math Building Data Science Teams Hylbert-‐Speys How Do You Learn? updates, reviews, conference summaries… liber118.com/pxn/ @pacoid
 bigdataspain
 ykimi
 ymotongpoo
 tsukuboshi
 sat
 csswizardry
 wind111
 shumpei3
 endonanana
 imuta
 inesmontani
 kasada
 munenick
 mongodb
 reverentgeek
 katarinadahlin
 tammyeverts
 jakevdp
 katiecoart
 lcolladotor
 kneath
 skipperchong
 tapps
 addyosmani
 dougneiner
![{"graf": [[21, "let", "let", "VB", 1, 48], [0, "'s", "'s",](https://files.speakerdeck.com/presentations/88fea2b1b7f14625a5f32726ee1a7bff/slide_6.jpg)