Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Java Unicode NCR 處理
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
Brian Hsu
January 03, 2013
Programming
460
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Java Unicode NCR 處理
Java 中 Unicode NCR 的轉換與處理
Brian Hsu
January 03, 2013
Transcript
20 slides
Unicode NCR 處理 BrianHsu
[email protected]
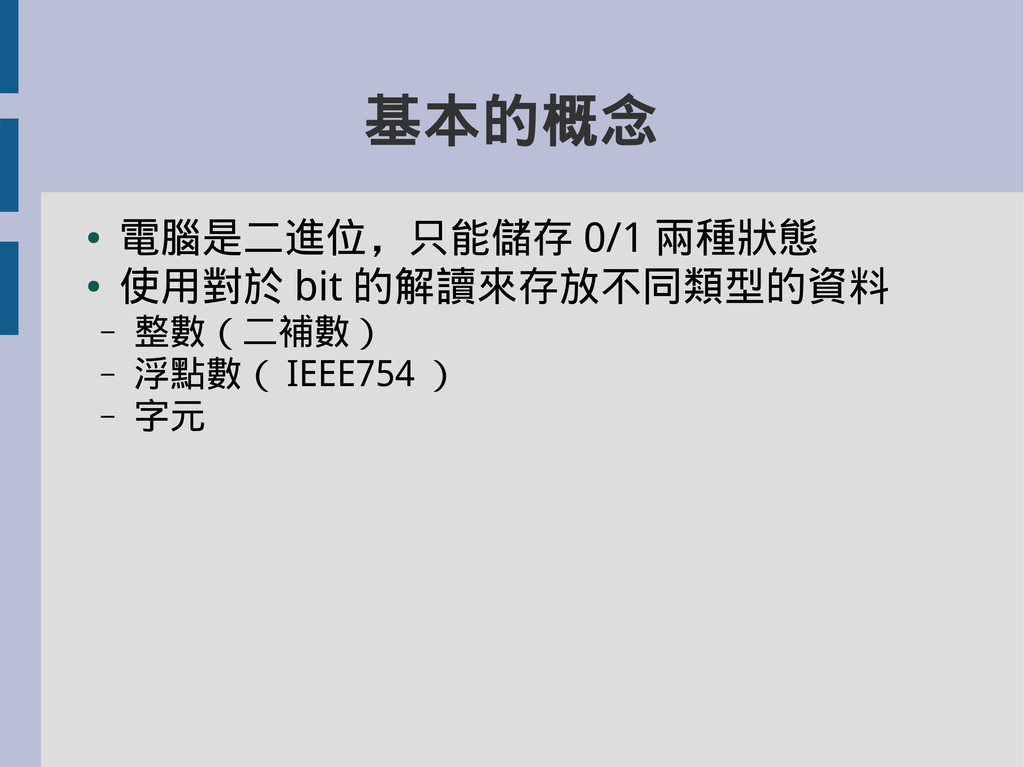
基本的概念 • 電腦是二進位,只能儲存 0/1 兩種狀態 • 使用對於 bit 的解讀來存放不同類型的資料 –
整數(二補數) – 浮點數( IEEE754 ) – 字元
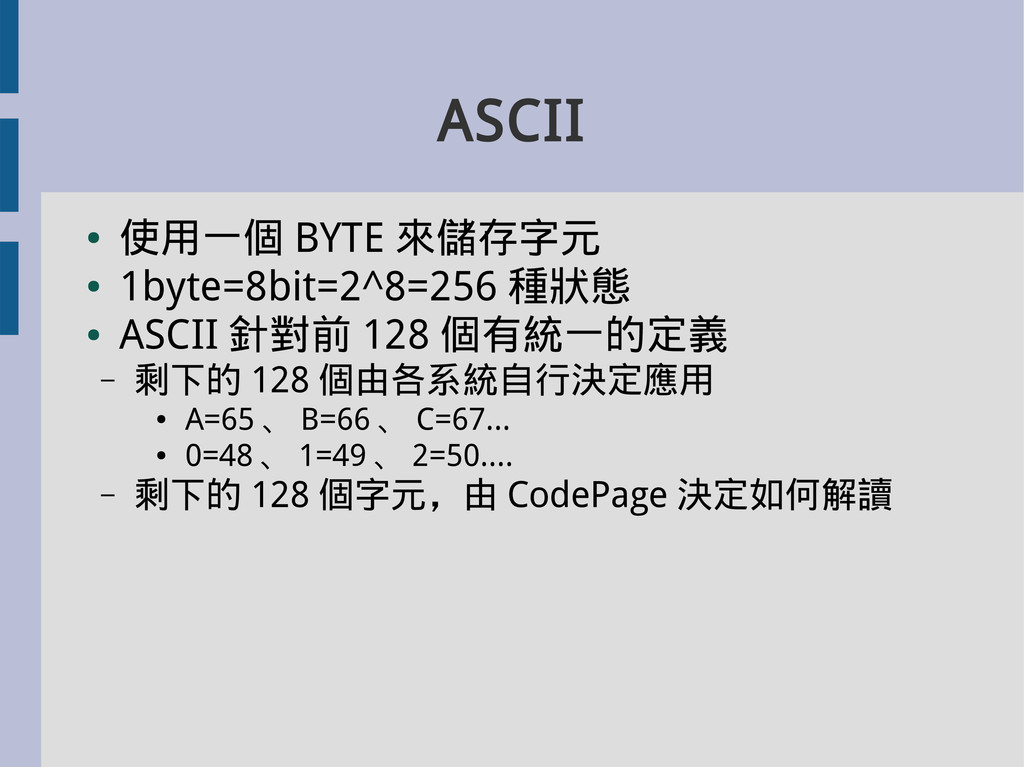
ASCII • 使用一個 BYTE 來儲存字元 • 1byte=8bit=2^8=256 種狀態 • ASCII
針對前 128 個有統一的定義 – 剩下的 128 個由各系統自行決定應用 • A=65 、 B=66 、 C=67... • 0=48 、 1=49 、 2=50.... – 剩下的 128 個字元,由 CodePage 決定如何解讀
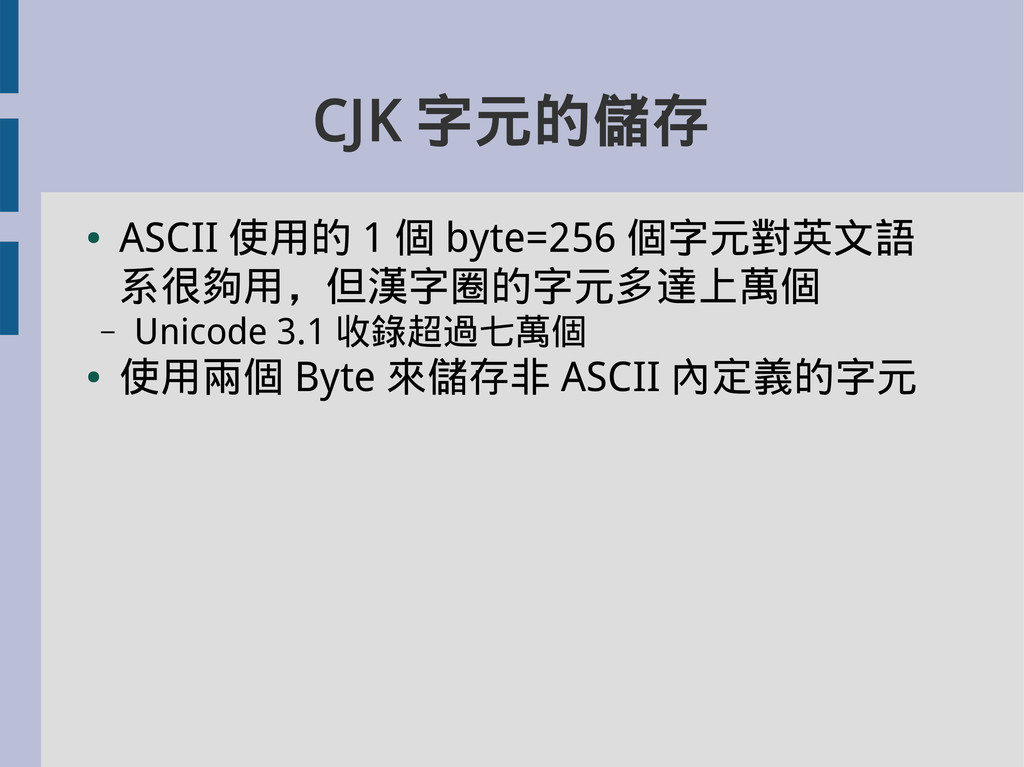
CJK 字元的儲存 • ASCII 使用的 1 個 byte=256 個字元對英文語 系很夠用,但漢字圈的字元多達上萬個
– Unicode 3.1 收錄超過七萬個 • 使用兩個 Byte 來儲存非 ASCII 內定義的字元
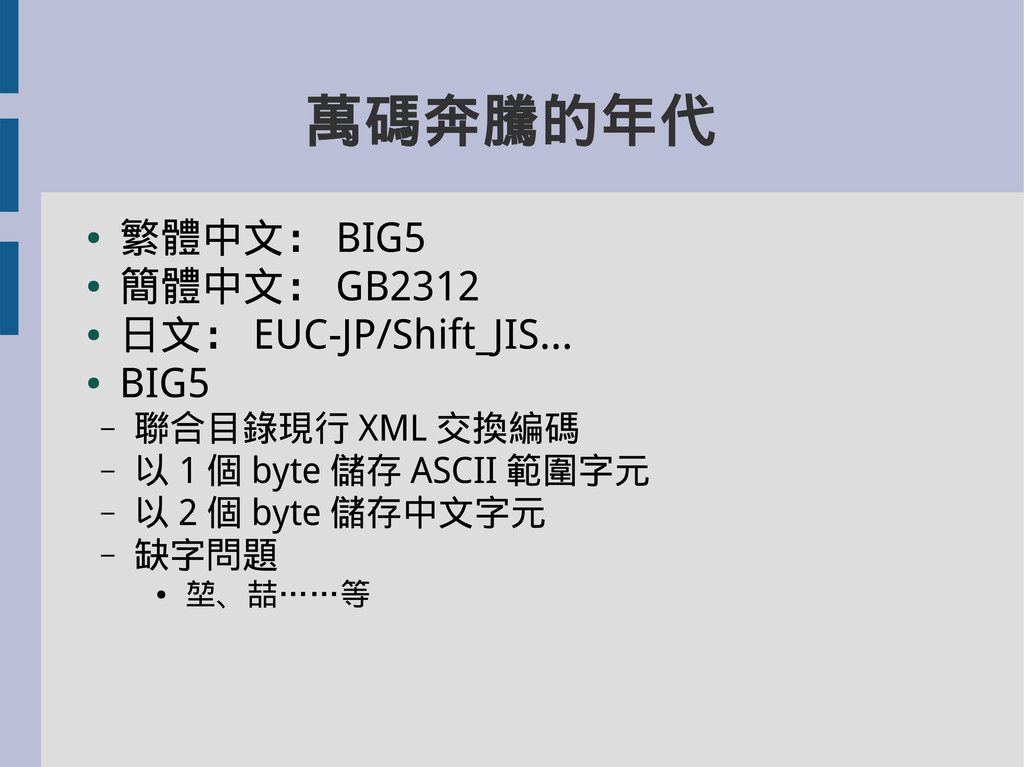
萬碼奔騰的年代 • 繁體中文: BIG5 • 簡體中文: GB2312 • 日文: EUC-JP/Shift_JIS...
• BIG5 – 聯合目錄現行 XML 交換編碼 – 以 1 個 byte 儲存 ASCII 範圍字元 – 以 2 個 byte 儲存中文字元 – 缺字問題 • 堃、喆……等
Unicode 編碼
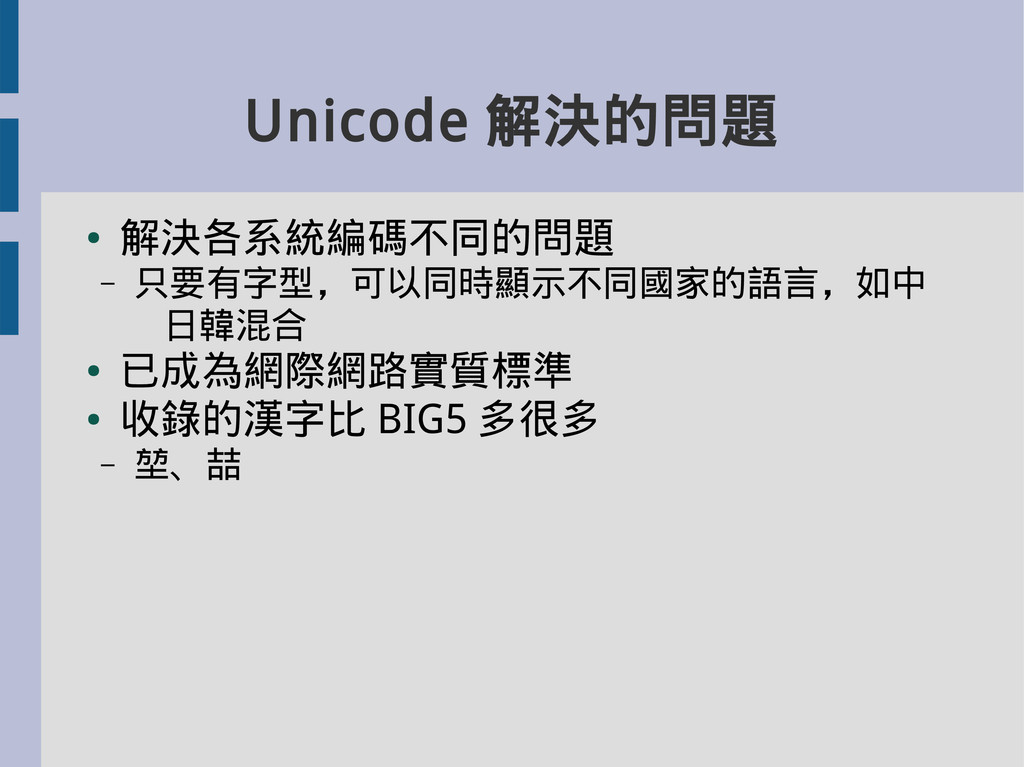
Unicode 解決的問題 • 解決各系統編碼不同的問題 – 只要有字型,可以同時顯示不同國家的語言,如中 日韓混合 • 已成為網際網路實質標準 •
收錄的漢字比 BIG5 多很多 – 堃、喆
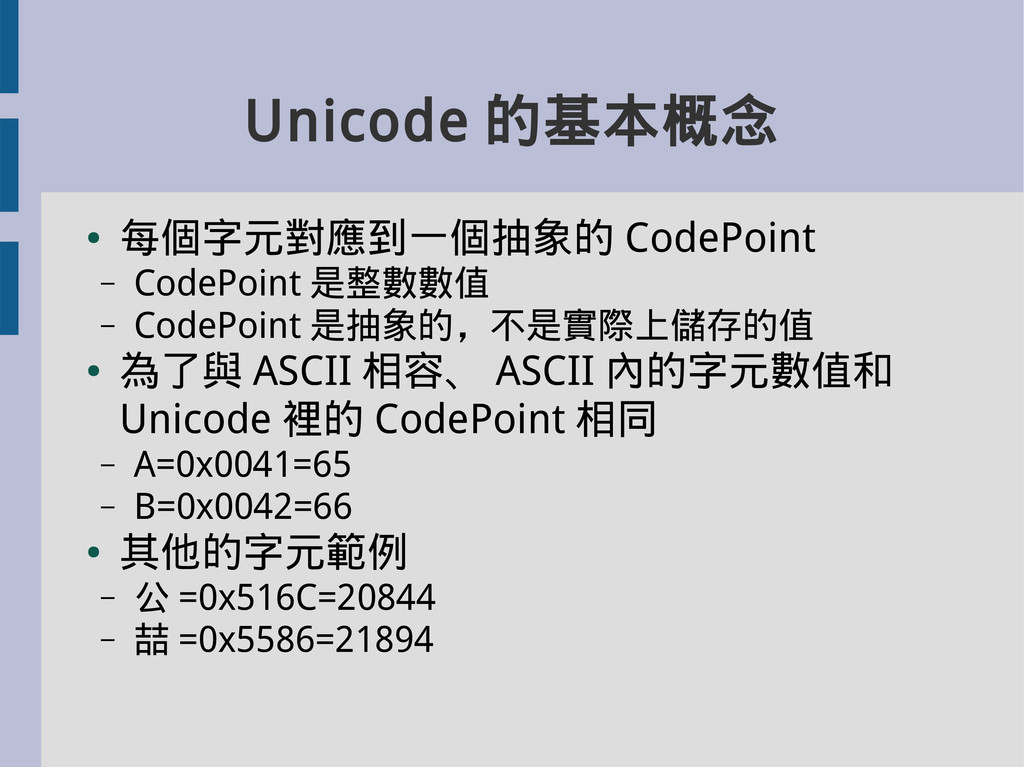
Unicode 的基本概念 • 每個字元對應到一個抽象的 CodePoint – CodePoint 是整數數值 – CodePoint
是抽象的,不是實際上儲存的值 • 為了與 ASCII 相容、 ASCII 內的字元數值和 Unicode 裡的 CodePoint 相同 – A=0x0041=65 – B=0x0042=66 • 其他的字元範例 – 公 =0x516C=20844 – 喆 =0x5586=21894
沒有 「儲存為 Unicode 」 這種事!!
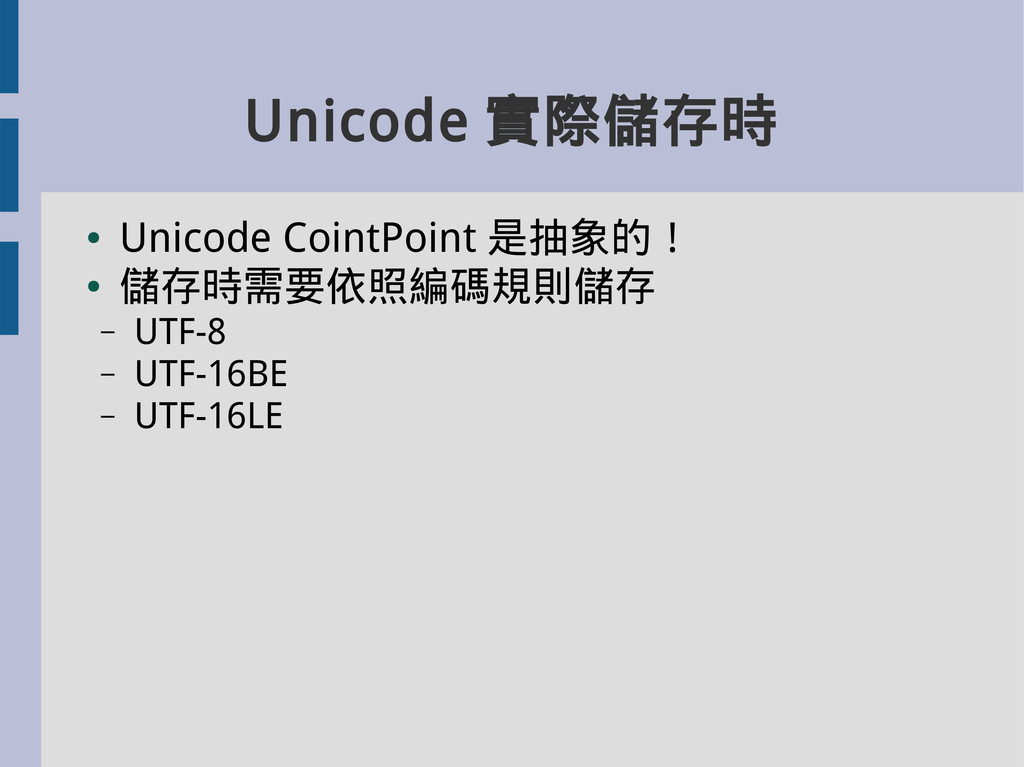
Unicode 實際儲存時 • Unicode CointPoint 是抽象的! • 儲存時需要依照編碼規則儲存 – UTF-8
– UTF-16BE – UTF-16LE
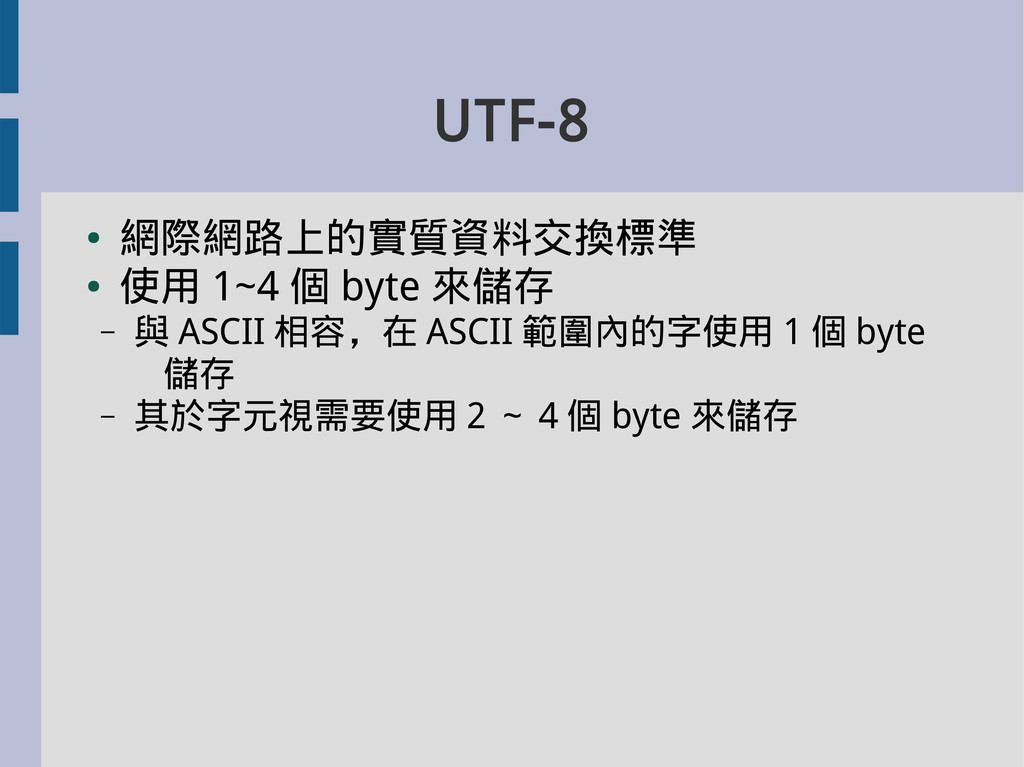
UTF-8 • 網際網路上的實質資料交換標準 • 使用 1~4 個 byte 來儲存 –
與 ASCII 相容,在 ASCII 範圍內的字使用 1 個 byte 儲存 – 其於字元視需要使用2~4個 byte 來儲存
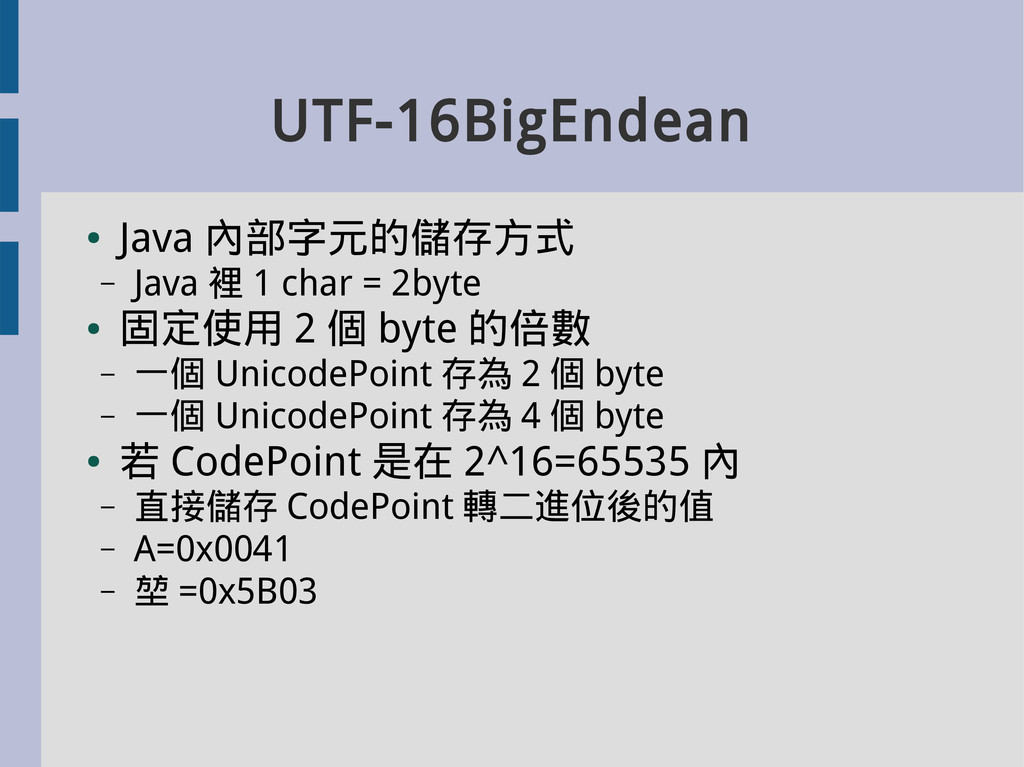
UTF-16BigEndean • Java 內部字元的儲存方式 – Java 裡 1 char =
2byte • 固定使用 2 個 byte 的倍數 – 一個 UnicodePoint 存為 2 個 byte – 一個 UnicodePoint 存為 4 個 byte • 若 CodePoint 是在 2^16=65535 內 – 直接儲存 CodePoint 轉二進位後的值 – A=0x0041 – 堃 =0x5B03
UTF-16BigEndean • 若字元的 CodePoint 超過 65535 • 使用兩個 Byte 表示
– 並非直接對應 CodePoint ,需經過編碼 – 編碼過後的第一個 Byte 必定為 HighSurrogate 範圍 內 (0xD800–0xDBFF) – 言㐌 • CodePoint 0x279A7 • 實際編碼 – 0xD85E 0xDDA7
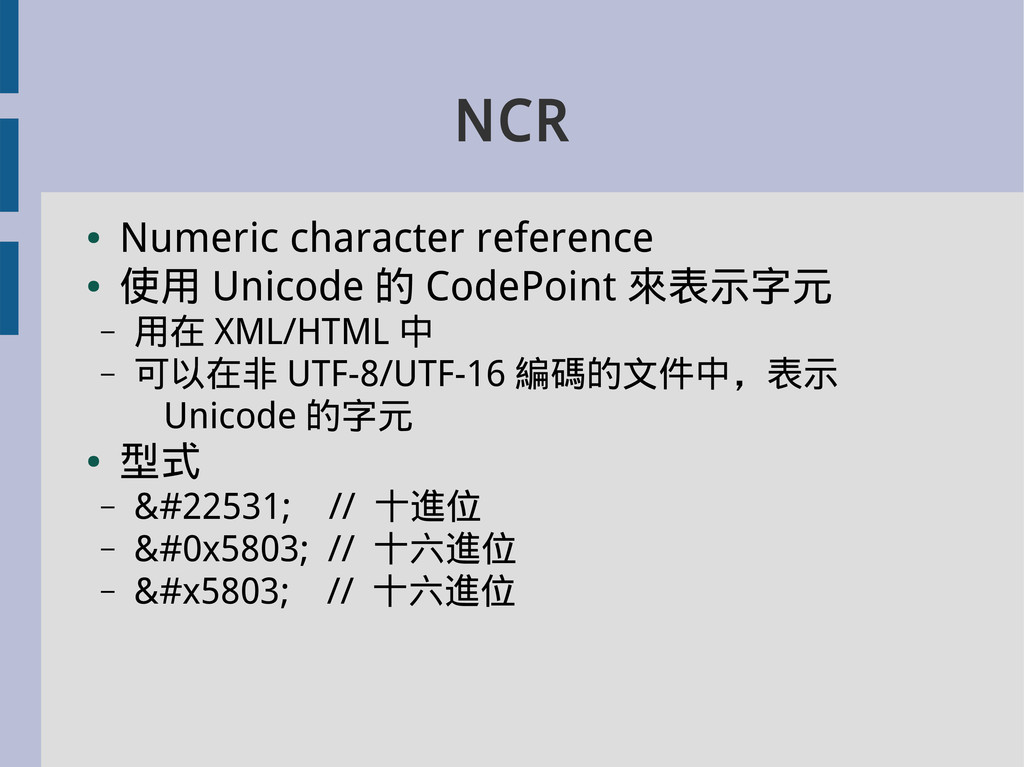
NCR • Numeric character reference • 使用 Unicode 的 CodePoint
來表示字元 – 用在 XML/HTML 中 – 可以在非 UTF-8/UTF-16 編碼的文件中,表示 Unicode 的字元 • 型式 – 堃 // 十進位 – �x5803; // 十六進位 – 堃 // 十六進位
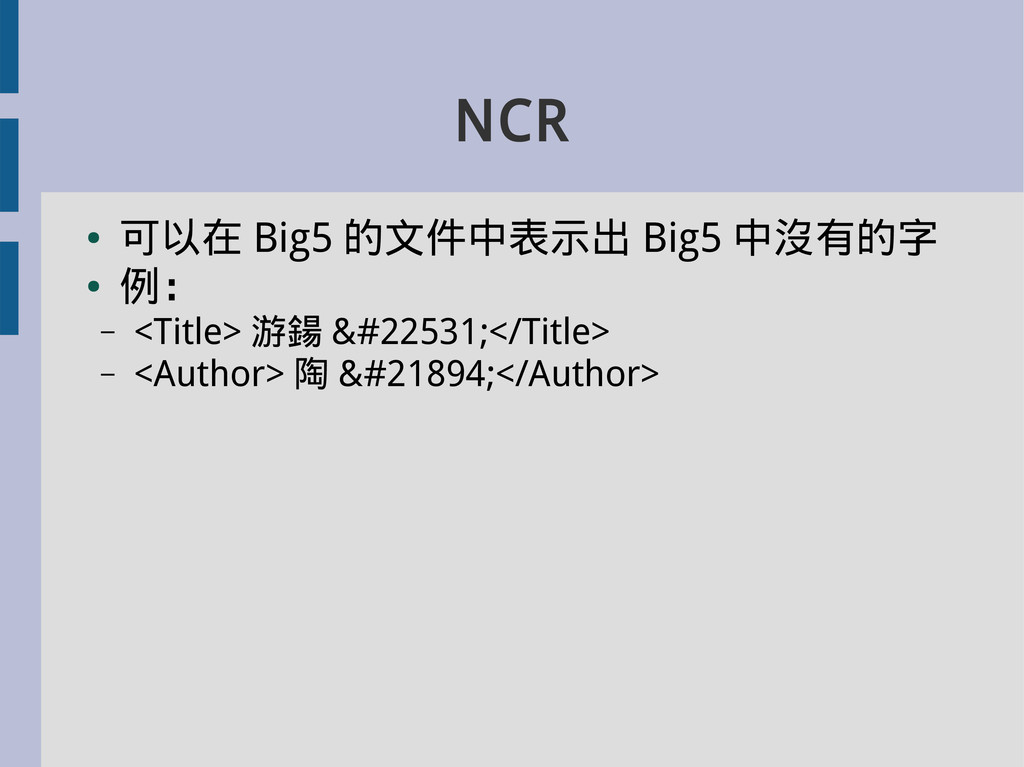
NCR • 可以在 Big5 的文件中表示出 Big5 中沒有的字 • 例: –
<Title> 游鍚 堃</Title> – <Author> 陶 喆</Author>
從 NCR 轉回 UTF-16 • 不要自己做! • 光是 CodePoint 在
65535 以上字元編碼就很 麻煩而且容易出錯 • 使用 Apache Commons Language 函式庫 – JAR檔連結 – JavaDoc API
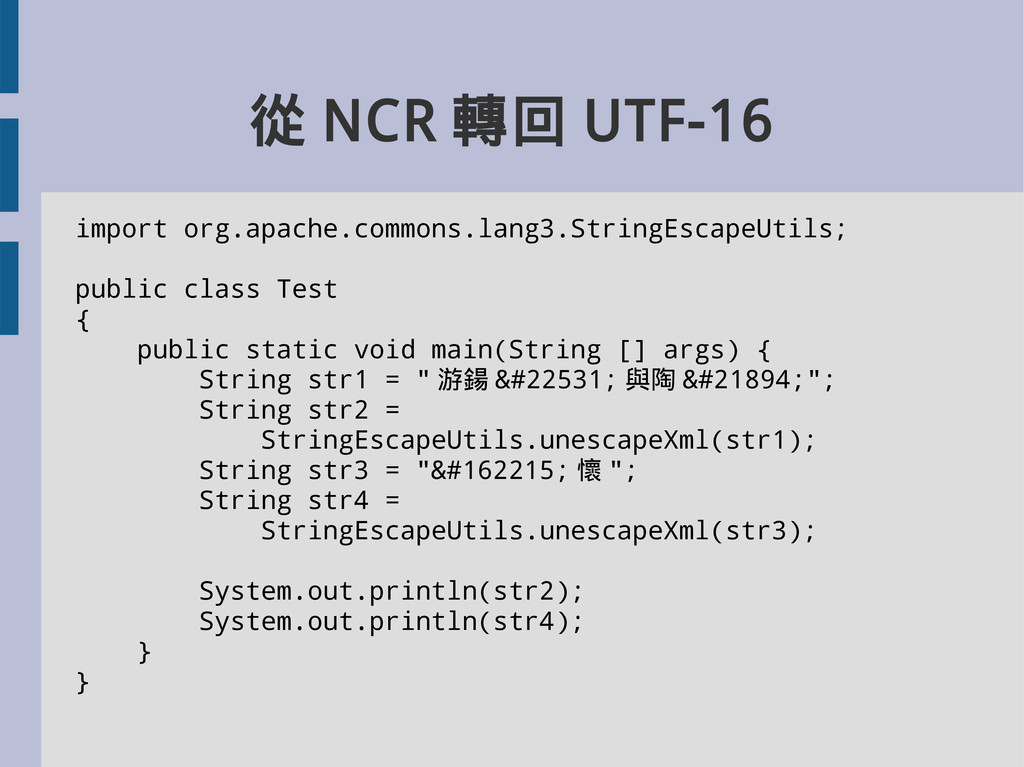
從 NCR 轉回 UTF-16 import org.apache.commons.lang3.StringEscapeUtils; public class Test {
public static void main(String [] args) { String str1 = " 游鍚 堃 與陶 喆"; String str2 = StringEscapeUtils.unescapeXml(str1); String str3 = "𧦧 懷 "; String str4 = StringEscapeUtils.unescapeXml(str3); System.out.println(str2); System.out.println(str4); } }
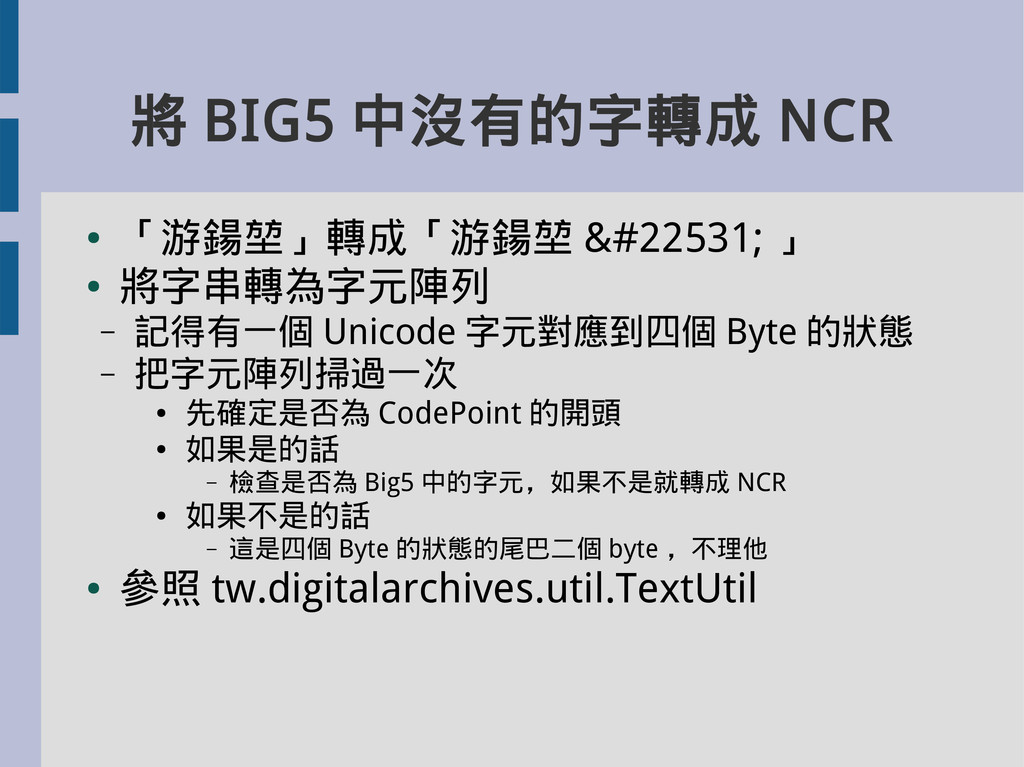
將 BIG5 中沒有的字轉成 NCR • 「游鍚堃」轉成「游鍚堃 堃 」 • 將字串轉為字元陣列
– 記得有一個 Unicode 字元對應到四個 Byte 的狀態 – 把字元陣列掃過一次 • 先確定是否為 CodePoint 的開頭 • 如果是的話 – 檢查是否為 Big5 中的字元,如果不是就轉成 NCR • 如果不是的話 – 這是四個 Byte 的狀態的尾巴二個 byte ,不理他 • 參照 tw.digitalarchives.util.TextUtil
將 BIG5 中沒有的字轉成 NCR import tw.digitalarchives.util.TextUtil; public class Test {
public static void main(String [] args) { String str1 = " 游鍚堃與陶喆 "; String str2 = " 懷 "; String str3 = TextUtil.normalizeString(str1); String str4 = TextUtil.normalizeString(str2); System.out.println(str3); System.out.println(str4); } }
參考資料 • Unicode Code Point列表 • Unicode Code Point查詢
More Decks by Brian Hsu
See All by Brian Hsu
我如何停止憂慮並愛上 Non-MVC Web Framework @ OSDC.tw 2013
brianhsu
6
3.4k
數位典藏聯合目錄搜尋引擎模組
brianhsu
0
230
Java XML Processing
brianhsu
0
96
如何在 Java App 中導入 Scala @ JavaTWO 2011
brianhsu
1
160
[LT] 自由軟體讓你五分鐘上新聞 @ OSDC.tw 2011
brianhsu
1
120
ScalaTest-連貓都會的單元測試與 BDD @ COSCUP 2010
brianhsu
0
320
Introduction to Scala @ TWJUG 2010/07
brianhsu
1
200
Programming Android Application in Scala @ OSDC.tw 2010
brianhsu
1
140
Other Decks in Programming
See All in Programming
DroidKnights 2026 Android A2UI Jetpack Compose 기반의 안전한 AI UI 렌더링 - 박제창
itsmedreamwalker
1
250
Secure Your Coding Agent Like It’s Malware (v1.5) 🇬🇧 @Code.talks 2026
richargh
0
190
小さなアプリを作って公開するまで
onozaty
0
210
AI Augmentation Techniques with Liberty
ivargrimstad
1
530
Kawaiicon: Kubernetes, it's no longer cool, but let's secure it anyway!
barnbarn
0
140
オーケストレーション記述言語 Katari
yukikurage
0
270
Growing PicoRuby's Ecosystem on ESP32
yuuu
2
150
Getting Started with Vibe Coding
miccheng
0
240
なぜ私たちは「現時点では」KMPの導入を見送ったのか
chigichan24
1
310
あなたの await、OS まで届いてる? strace で覗く JavaScript の非同期
hasutosasaki
1
2.4k
protojson における文字化けの扱い
kazuki1023
0
450
Proxmox x Talos Linux x Terraform で実現するなんかいい感じの Kubernetes クラスタ / A Sleek Kubernetes Cluster Powered by Proxmox, Talos Linux, and Terraform
nnaka2992
0
270
Featured
See All Featured
A Tale of Four Properties
chriscoyier
163
24k
Docker and Python
trallard
47
4.3k
What the history of the web can teach us about the future of AI
inesmontani
PRO
3
820
Navigating Algorithm Shifts & AI Overviews - #SMXNext
aleyda
1
1.7k
Marketing Yourself as an Engineer | Alaka | Gurzu
gurzu
0
390
Noah Learner - AI + Me: how we built a GSC Bulk Export data pipeline
techseoconnect
PRO
0
490
Sam Torres - BigQuery for SEOs
techseoconnect
PRO
0
620
Exploring the Power of Turbo Streams & Action Cable | RailsConf2023
kevinliebholz
37
6.7k
The Cult of Friendly URLs
andyhume
79
7.1k
Gemini Prompt Engineering: Practical Techniques for Tangible AI Outcomes
mfonobong
2
640
Building Flexible Design Systems
yeseniaperezcruz
330
41k
For a Future-Friendly Web
brad_frost
184
11k


 brianhsu
 itsmedreamwalker
 richargh
 onozaty
 ivargrimstad
 barnbarn
 yukikurage
 yuuu
 miccheng
 chigichan24
 hasutosasaki
 kazuki1023
 nnaka2992
 chriscoyier
 trallard
 inesmontani
 aleyda
 gurzu
 techseoconnect
 kevinliebholz
 andyhume
 mfonobong
 yeseniaperezcruz
 brad_frost