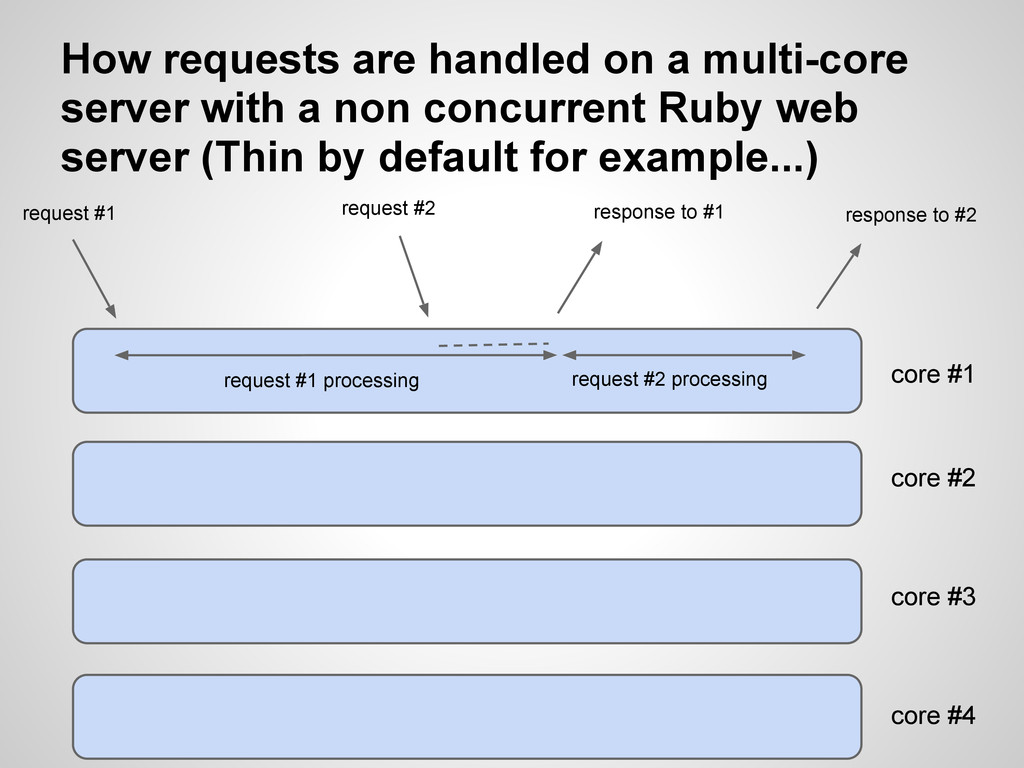
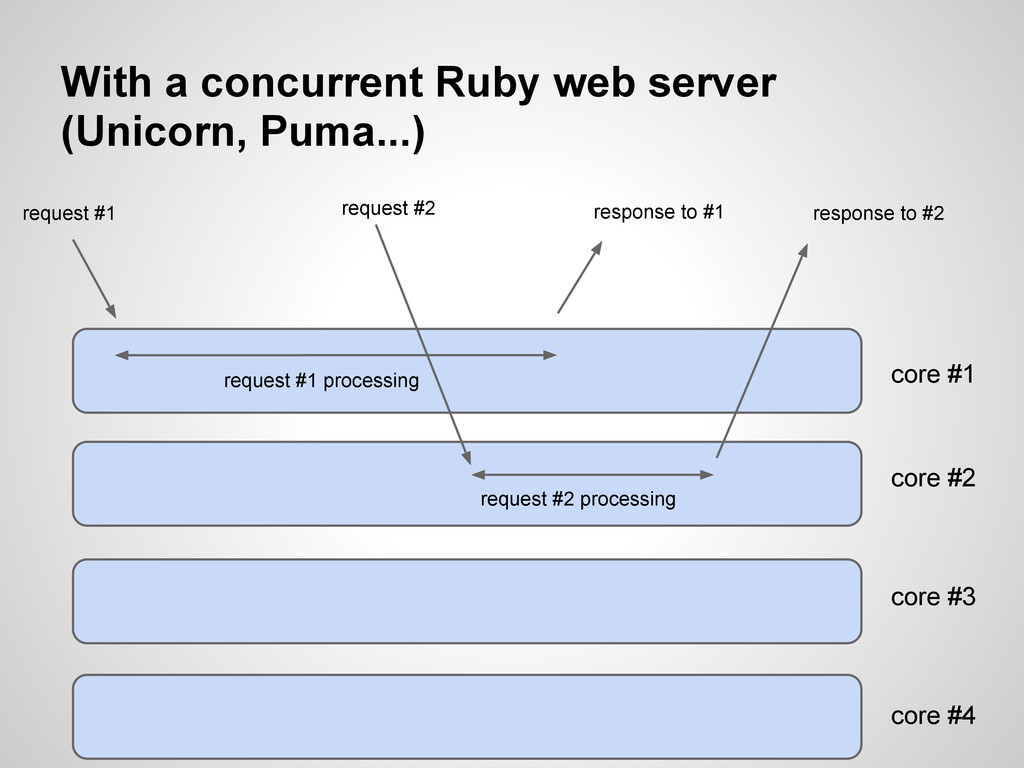
non concurrent Ruby web server (Thin by default for example...) core #1 request #1 processing request #1 response to #1 request #2 request #2 processing response to #2 core #2 core #3 core #4
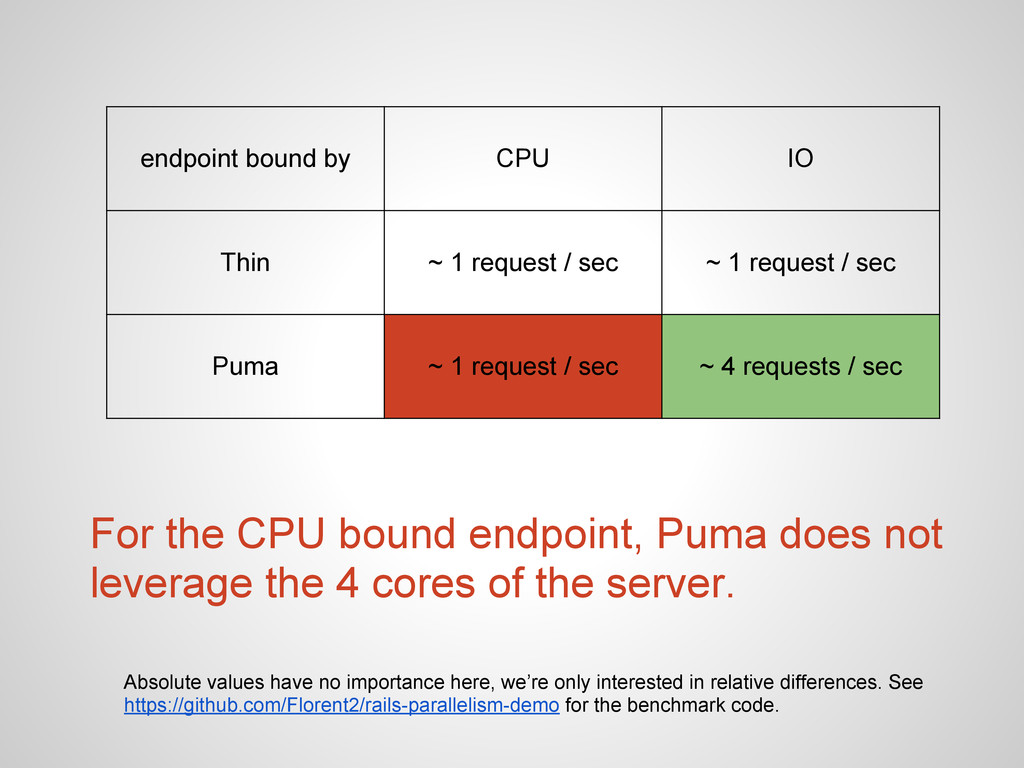
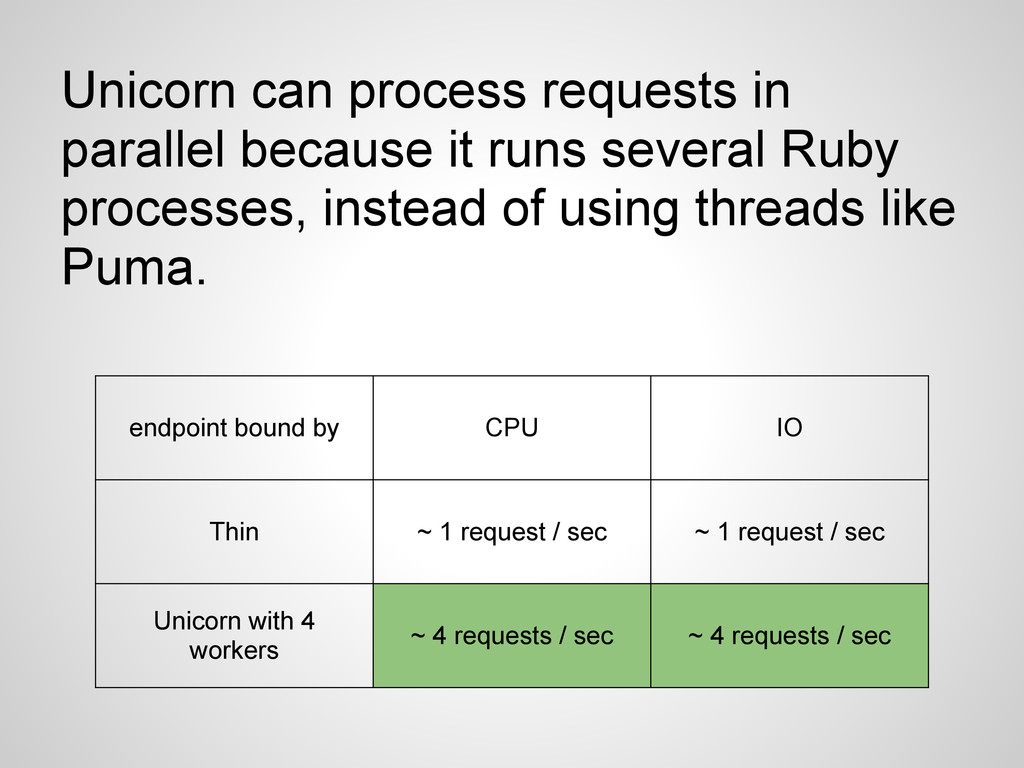
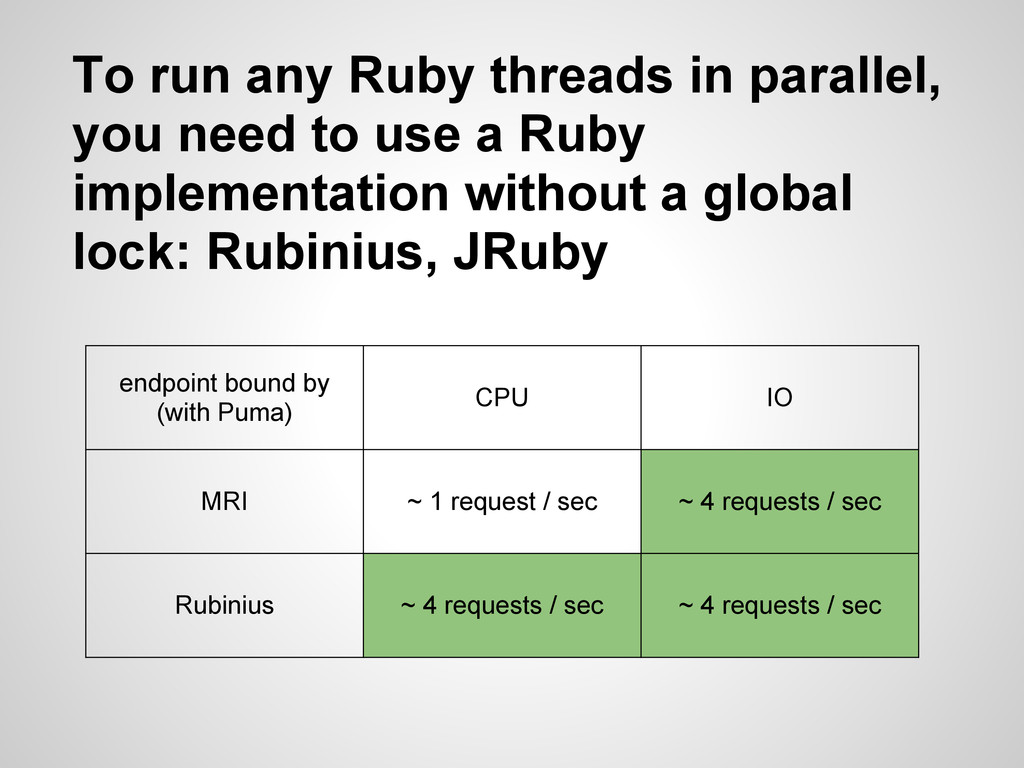
sec ~ 1 request / sec Puma ~ 1 request / sec ~ 4 requests / sec For the CPU bound endpoint, Puma does not leverage the 4 cores of the server. Absolute values have no importance here, we’re only interested in relative differences. See https://github.com/Florent2/rails-parallelism-demo for the benchmark code.
of the server (PI number calculation, video processing...) IO bound: code execution is bound by the IO capabilities of the server (processing data from disk, requesting over a network...) Also: memory bound, cache bound
CPU bound endpoint? We were using MRI (the default Ruby implementation). MRI has the GIL (Global Interpreter Lock): A MRI process can not run threads in parallel, except on blocking IO.
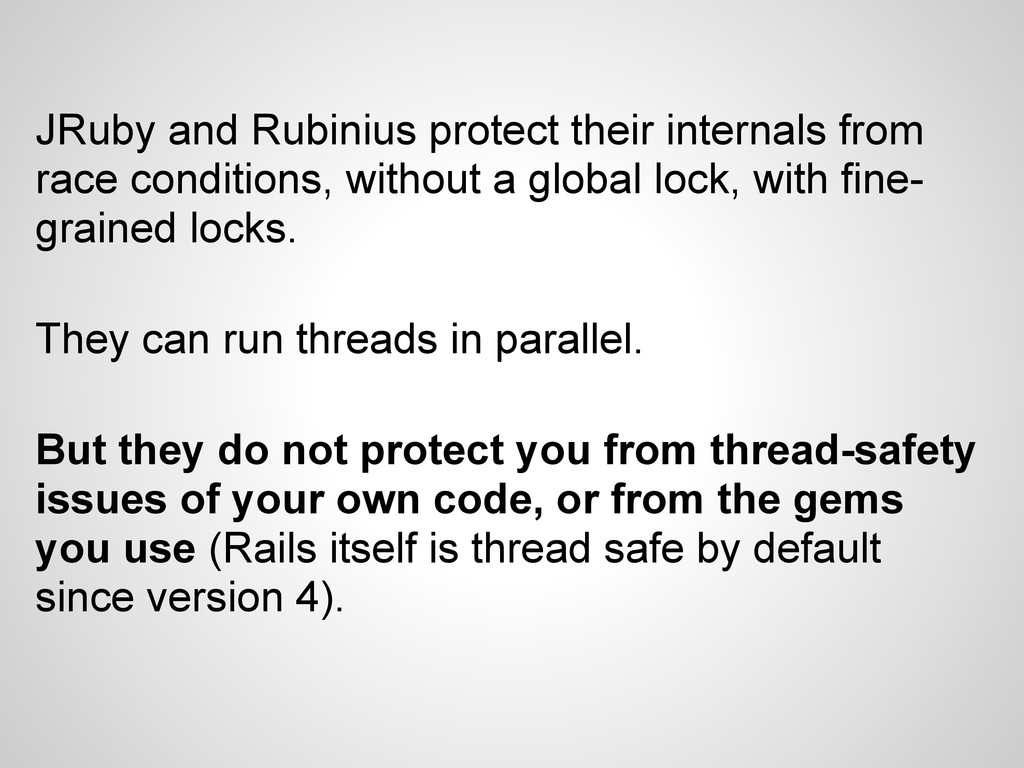
a global lock, with fine- grained locks. They can run threads in parallel. But they do not protect you from thread-safety issues of your own code, or from the gems you use (Rails itself is thread safe by default since version 4).
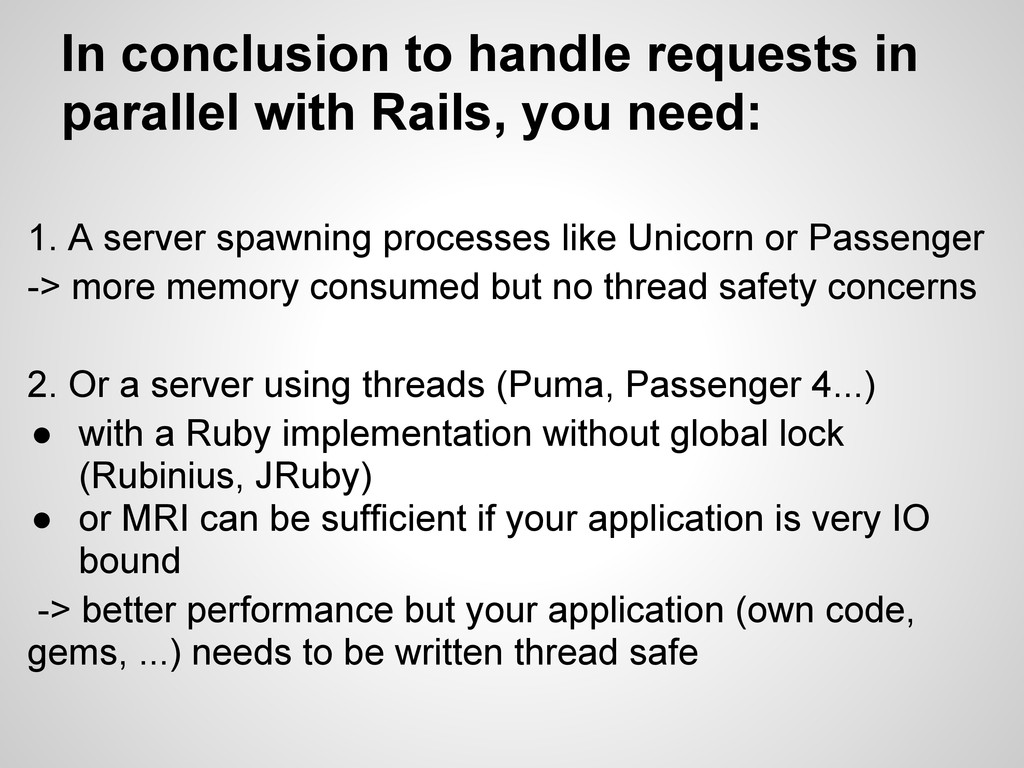
more memory consumed but no thread safety concerns 2. Or a server using threads (Puma, Passenger 4...) • with a Ruby implementation without global lock (Rubinius, JRuby) • or MRI can be sufficient if your application is very IO bound -> better performance but your application (own code, gems, ...) needs to be written thread safe In conclusion to handle requests in parallel with Rails, you need:


 florent2
 kinakomoti321
 rkaga
 yahir0
 ochtum
 sodainc
 seosoft
 koukimiura
 yosuke_furukawa
 quramy
 slobodan
 akihisaikeda
 ivargrimstad
 chriscoyier
 cargoodrich
 cassininazir
 popppiees
 geoffreycrofte
 morganepeng
 rasmusluckow
 marcoroth
 jonrohan
 bcantrill
 addyosmani
 reverentgeek