Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Matrix Multiplication
Search
Moro
November 14, 2018
Programming
18
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Matrix Multiplication
Parallel Computing in Shared Memory using OpenMP - Matrix Multiplication problem.
Moro
November 14, 2018
More Decks by Moro
See All by Moro
MockK and Truth - Unit Tests - Android
gabrielbmoro
0
160
More Accessible Apps - Android
gabrielbmoro
0
13
Variables and Tips - Android
gabrielbmoro
0
14
Migrating an Existing App to Compose - Android
gabrielbmoro
0
18
Recycler View and Performance - Android
gabrielbmoro
0
20
Repository Pattern and Productivity - Android
gabrielbmoro
0
17
What is new in Android Jetpack?
gabrielbmoro
0
27
List Users - Android
gabrielbmoro
0
14
Working with Collections - Kotlin
gabrielbmoro
0
19
Other Decks in Programming
See All in Programming
Herb in Rails 8.2: Your ERB views, now HTML-aware @ Rails World 2026, Austin, Texas
marcoroth
0
220
作れる、でも消せるか?──安全に「枯らして消す」機能削除術 / Drain, Then Delete
chobishiba
2
660
golang-bob.pdf
iwatsukayura
0
130
APNsからLive Activityを開始する話
yumnumm
0
170
Rでドレミ/Do-Re-Mi_with_R
florets1
0
130
ActionController meets Protocol Buffers
sorah
0
520
自サークルのIdPからログアウトできるようになるまで
taiseiue
1
140
Long Living Tokens, Die, Die, Die! (or: The One Ring is Banned in Modern)
sylph01
0
300
すこし踏み込む CancellationToken
htkym
2
1.7k
AmebaブログはKMPから卒業します
kmars0605
0
190
Augmenting AI with the Power of Jakarta EE
ivargrimstad
0
190
S3 TablesのIcebergデータに、AIエージェントからアクセスしてみた / 20261016developersio2026joetsu-accessing-iceberg-in-s3tables-via-agent
kasacchiful
PRO
0
150
Featured
See All Featured
Agile Leadership in an Agile Organization
kimpetersen
PRO
0
280
Navigating Algorithm Shifts & AI Overviews - #SMXNext
aleyda
1
1.7k
The Power of CSS Pseudo Elements
geoffreycrofte
82
6.6k
sira's awesome portfolio website redesign presentation
elsirapls
0
460
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
620
Building an army of robots
kneath
307
47k
Fight the Zombie Pattern Library - RWD Summit 2016
marcelosomers
234
18k
Understanding Cognitive Biases in Performance Measurement
bluesmoon
32
3.1k
Why You Should Never Use an ORM
jnunemaker
PRO
61
10k
[Rails World 2026] Durable orchestration on Rails: from continuation to workflow
palkan
1
750
Designing for Performance
lara
612
70k
Game over? The fight for quality and originality in the time of robots
wayneb77
1
300
Transcript
Matrix Multiplication Parallel Computing in Shared Memory using OpenMP Gabriel
Moro - KNOWLEDGE TRANSFER - KT, Porto Alegre - November 2018
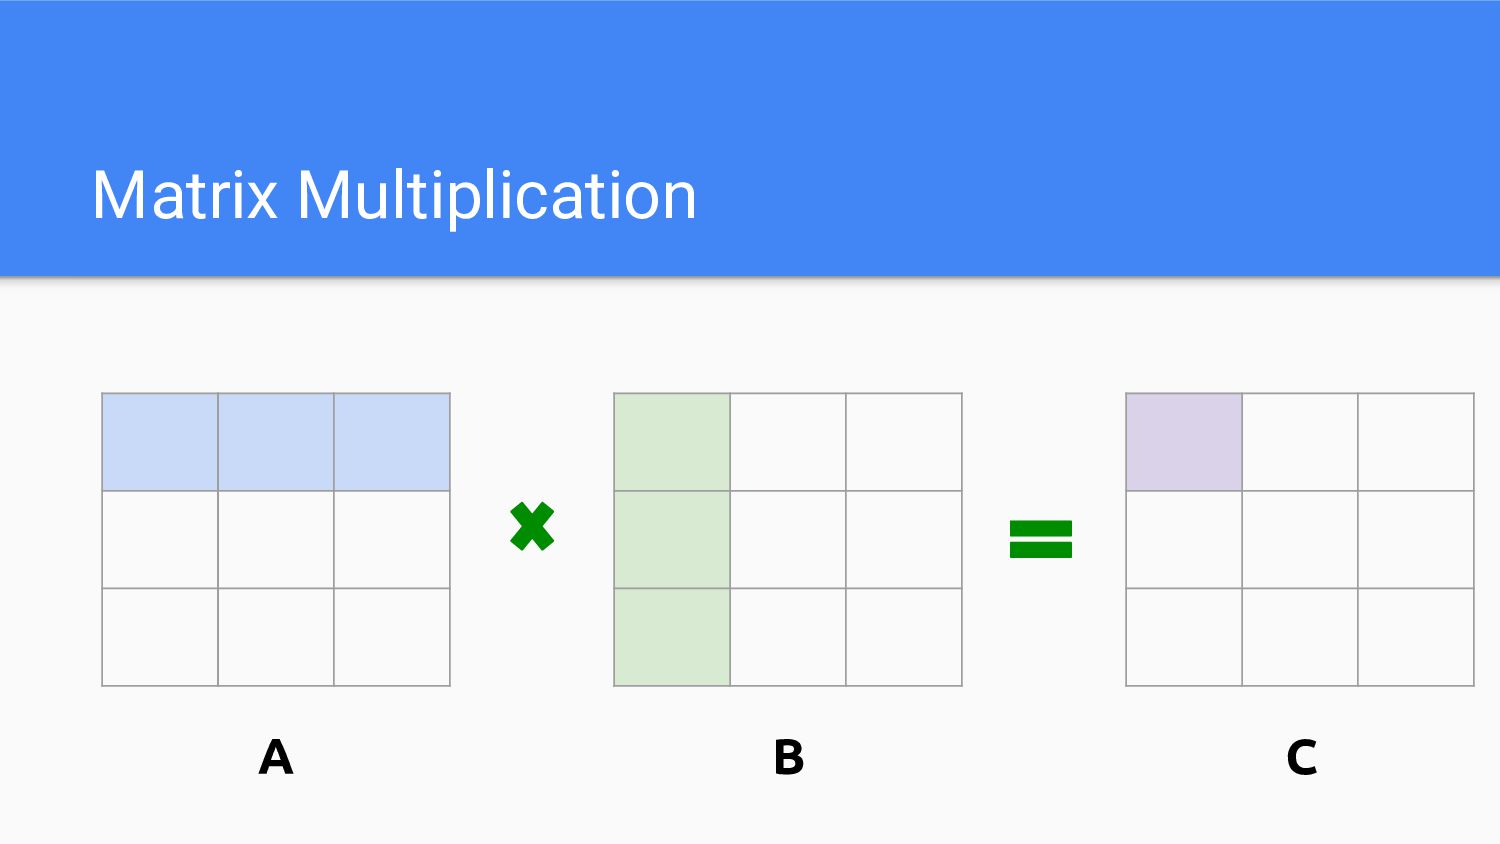
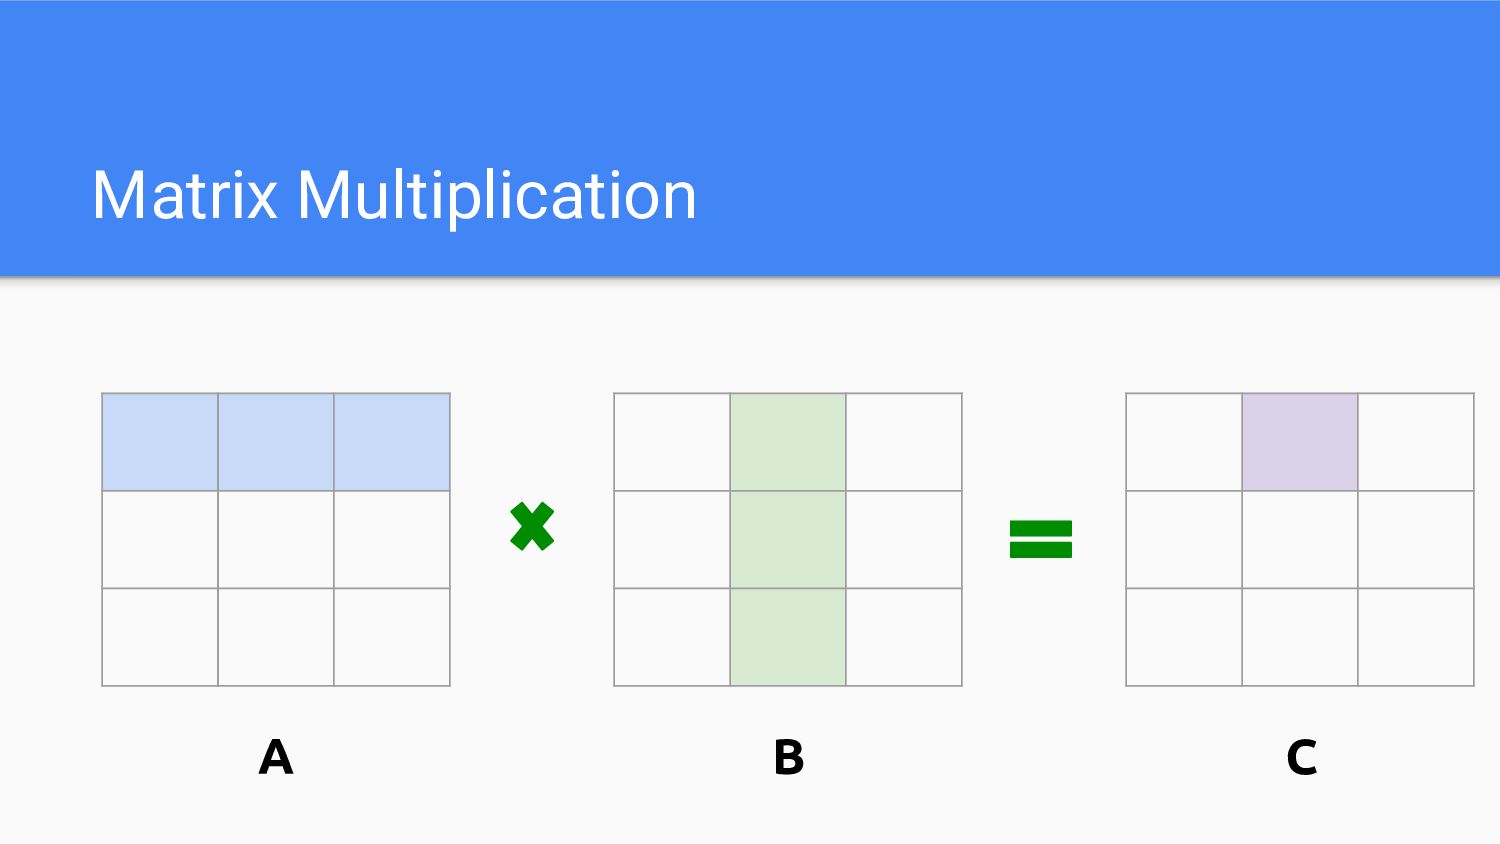
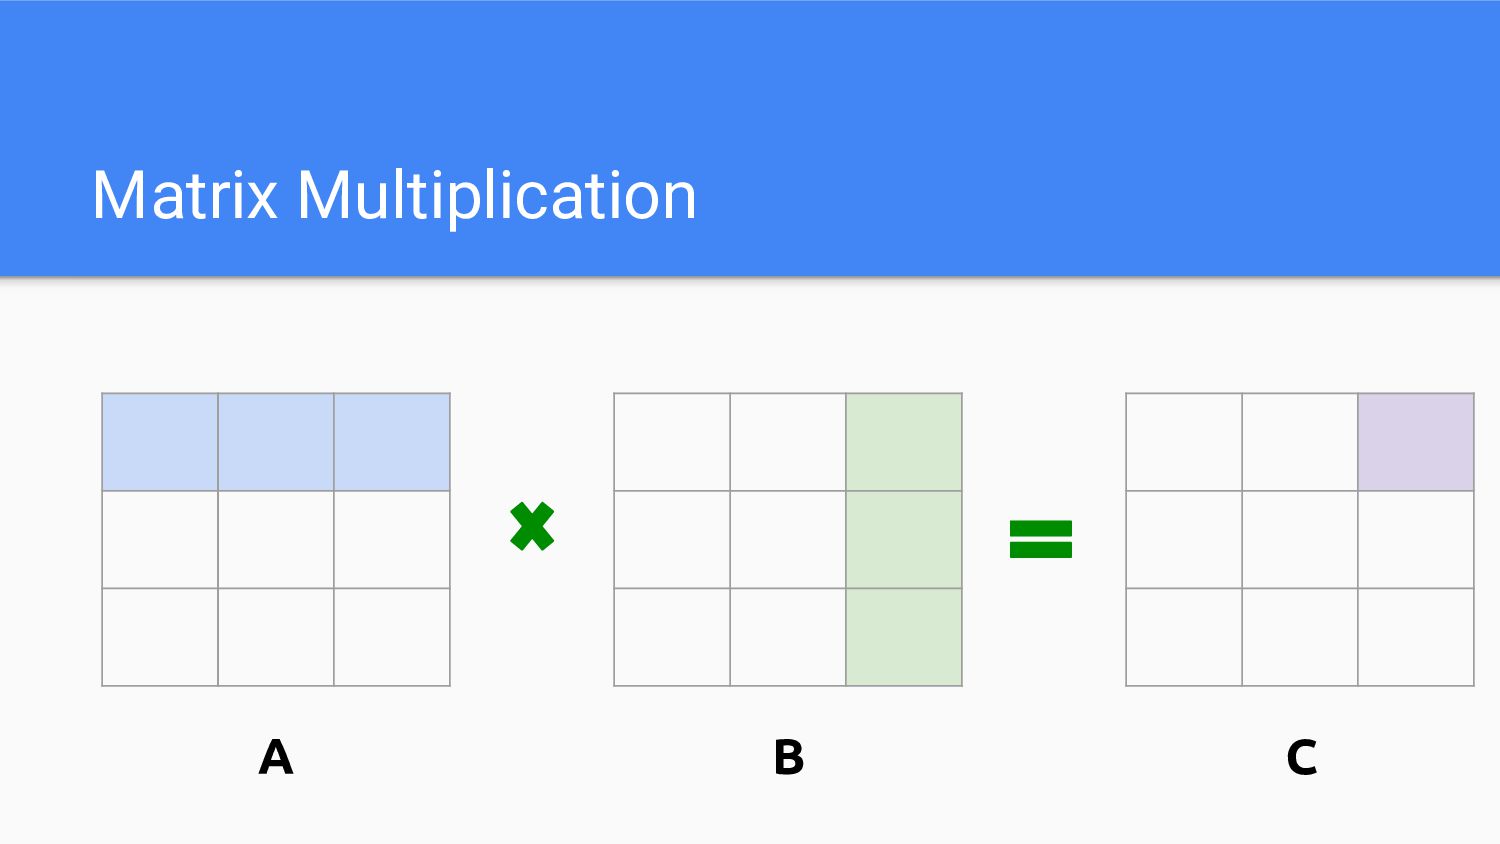
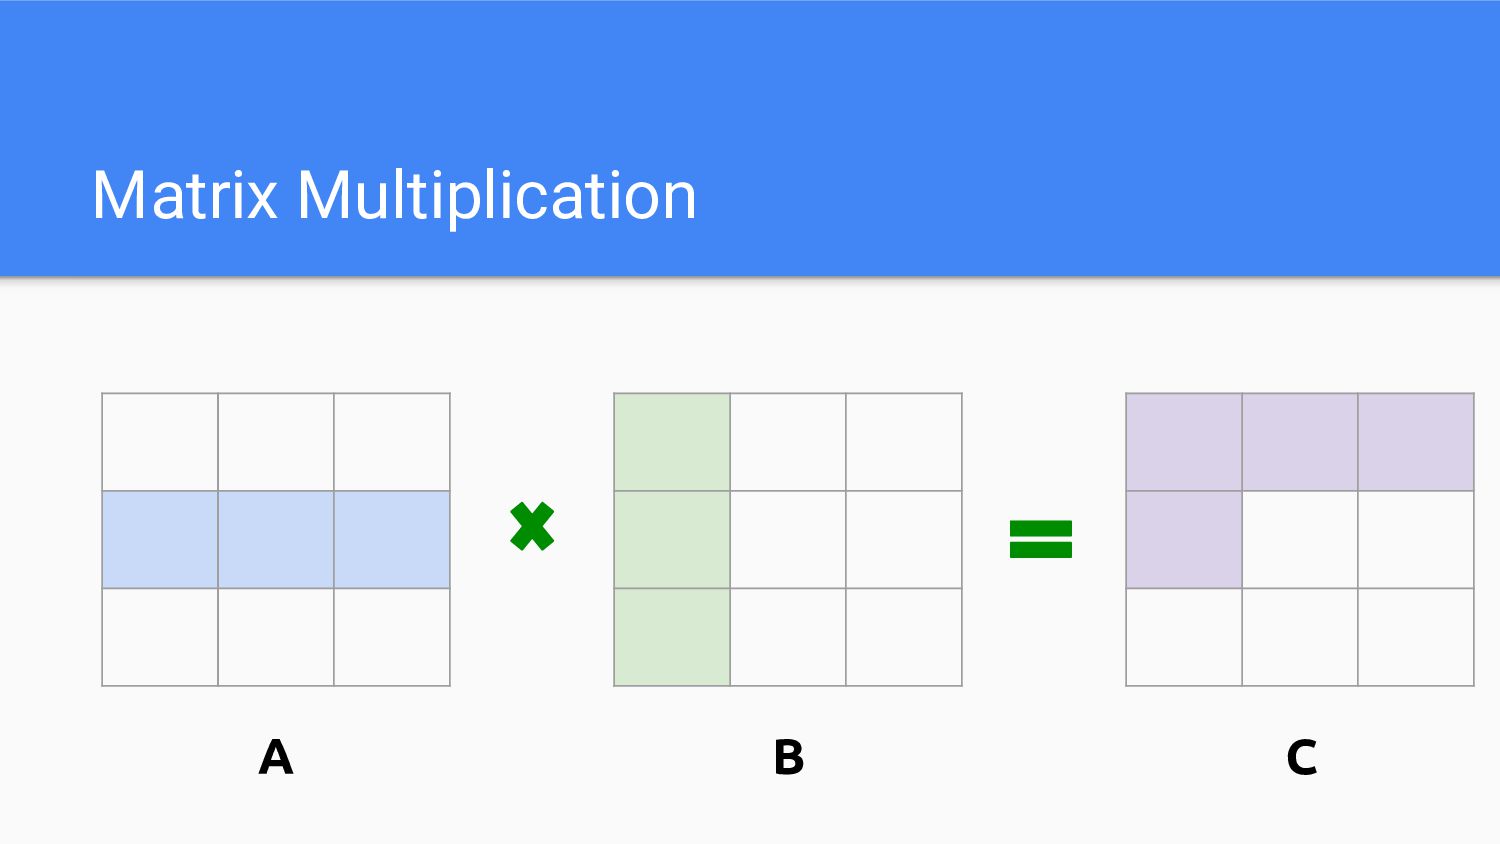
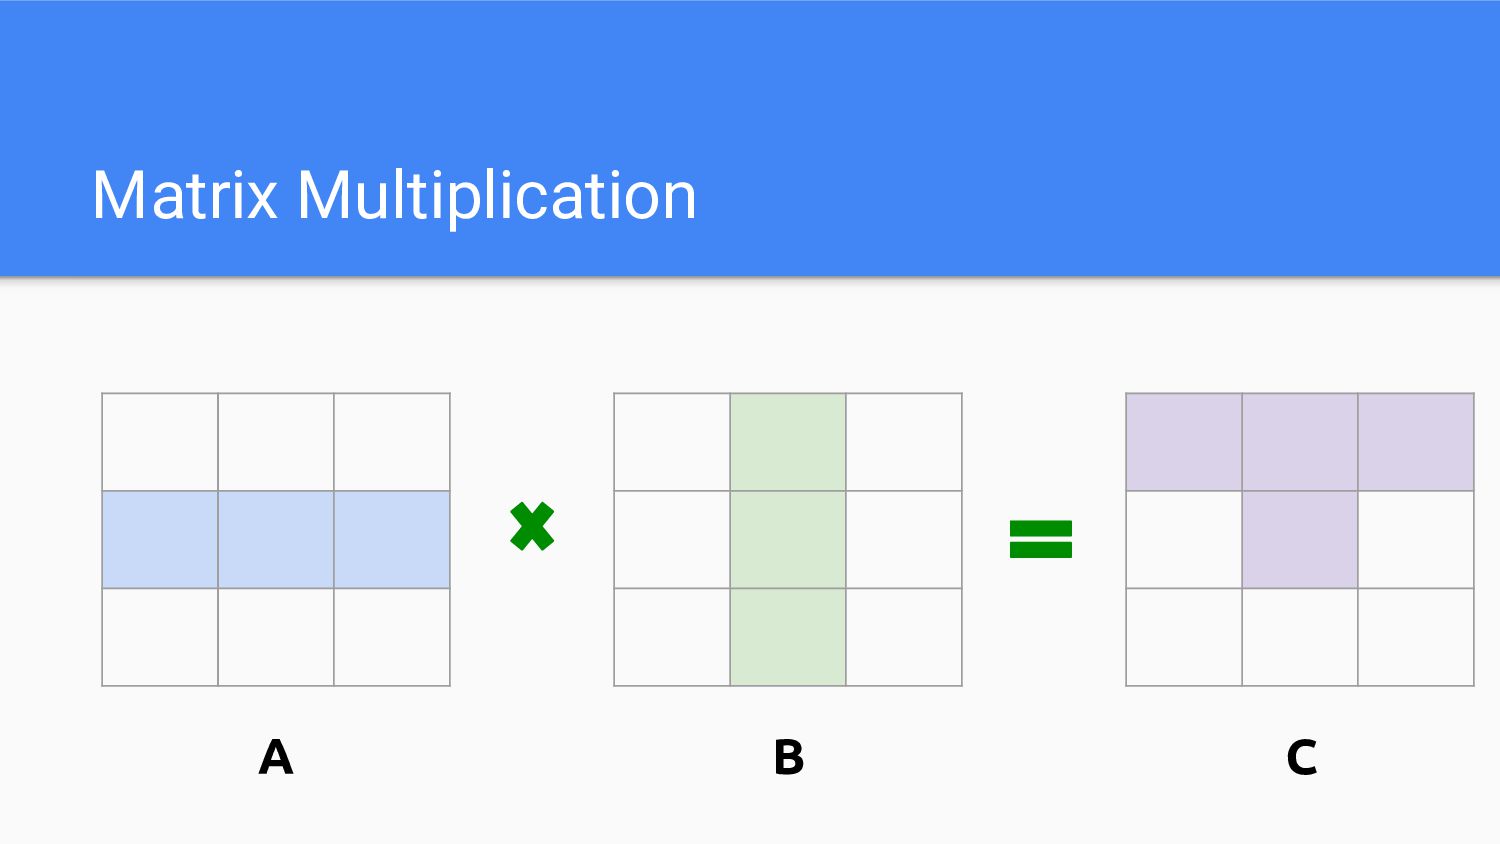
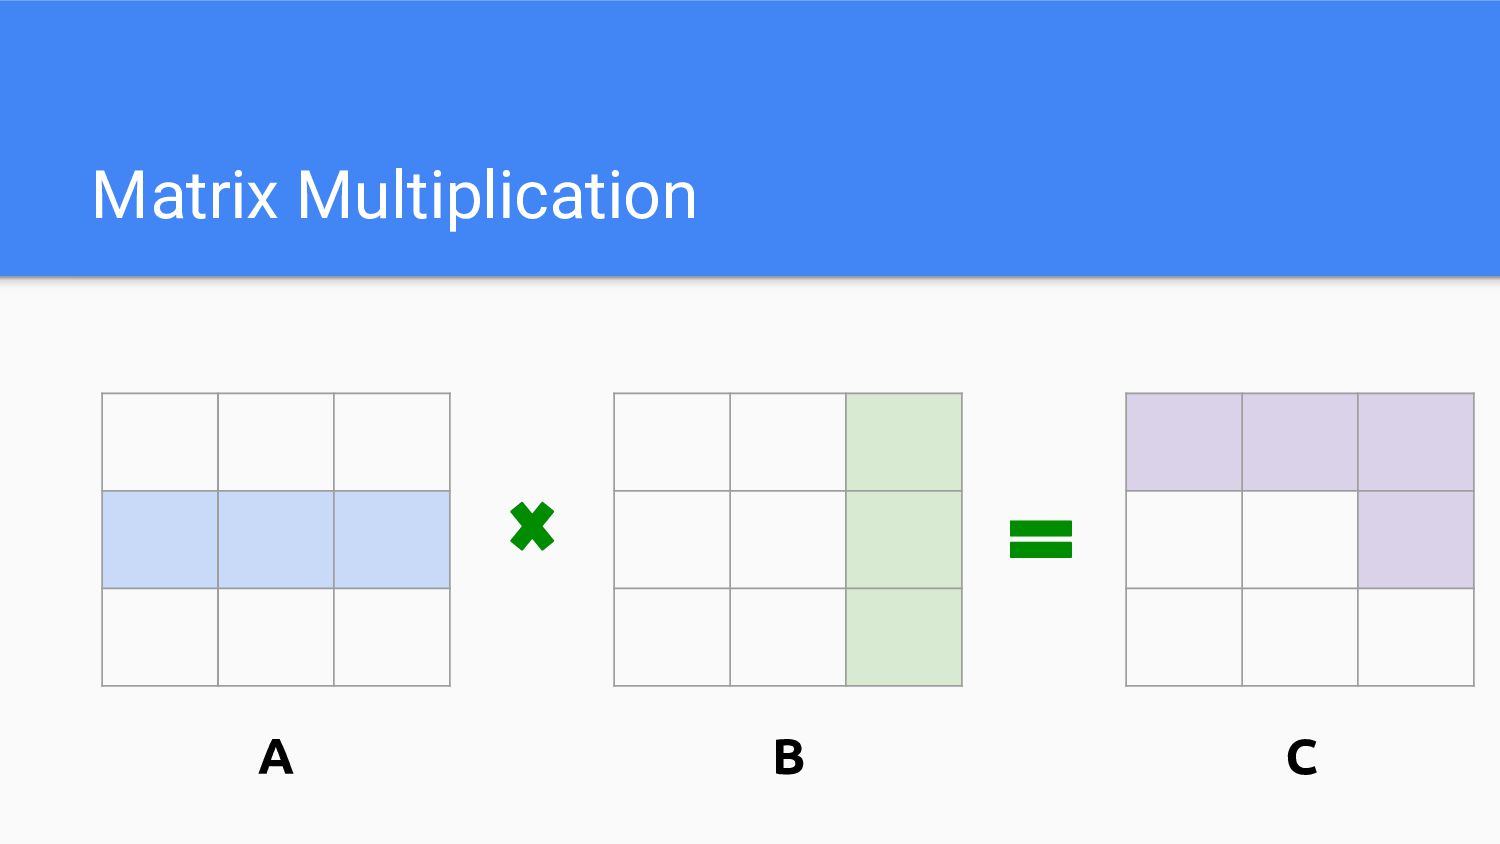
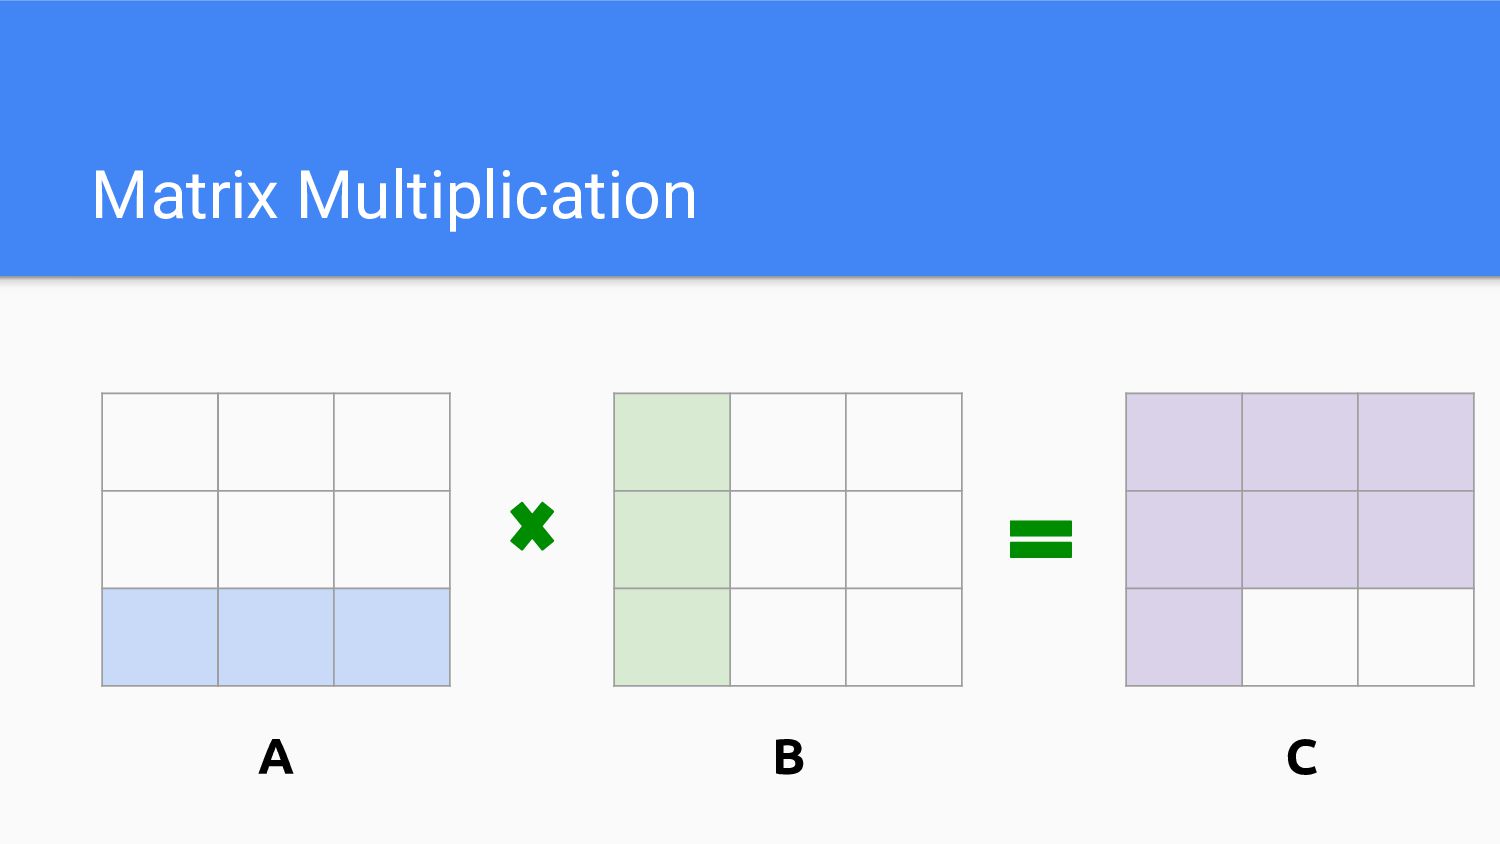
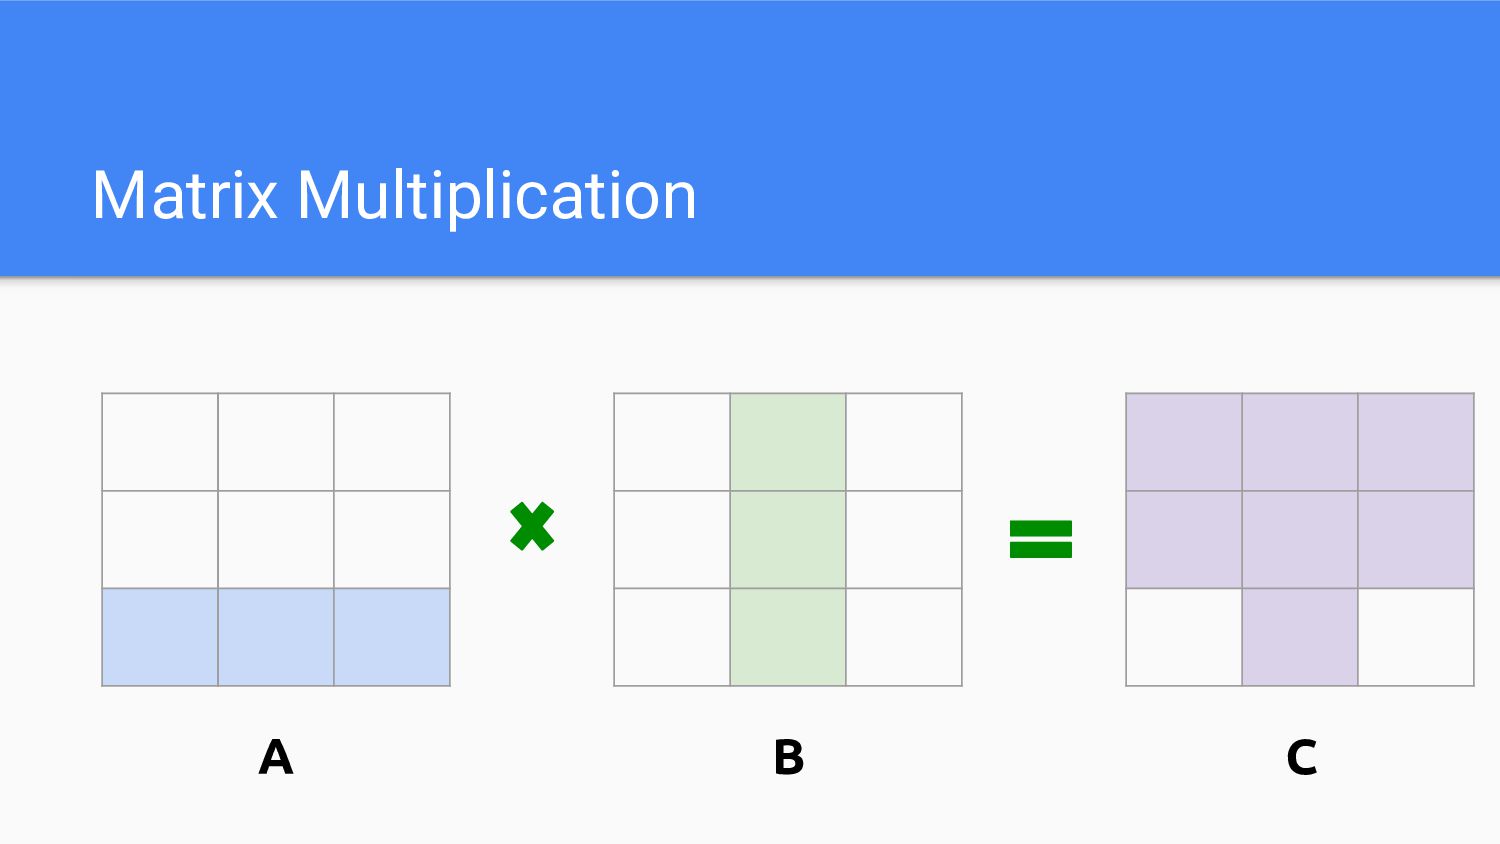
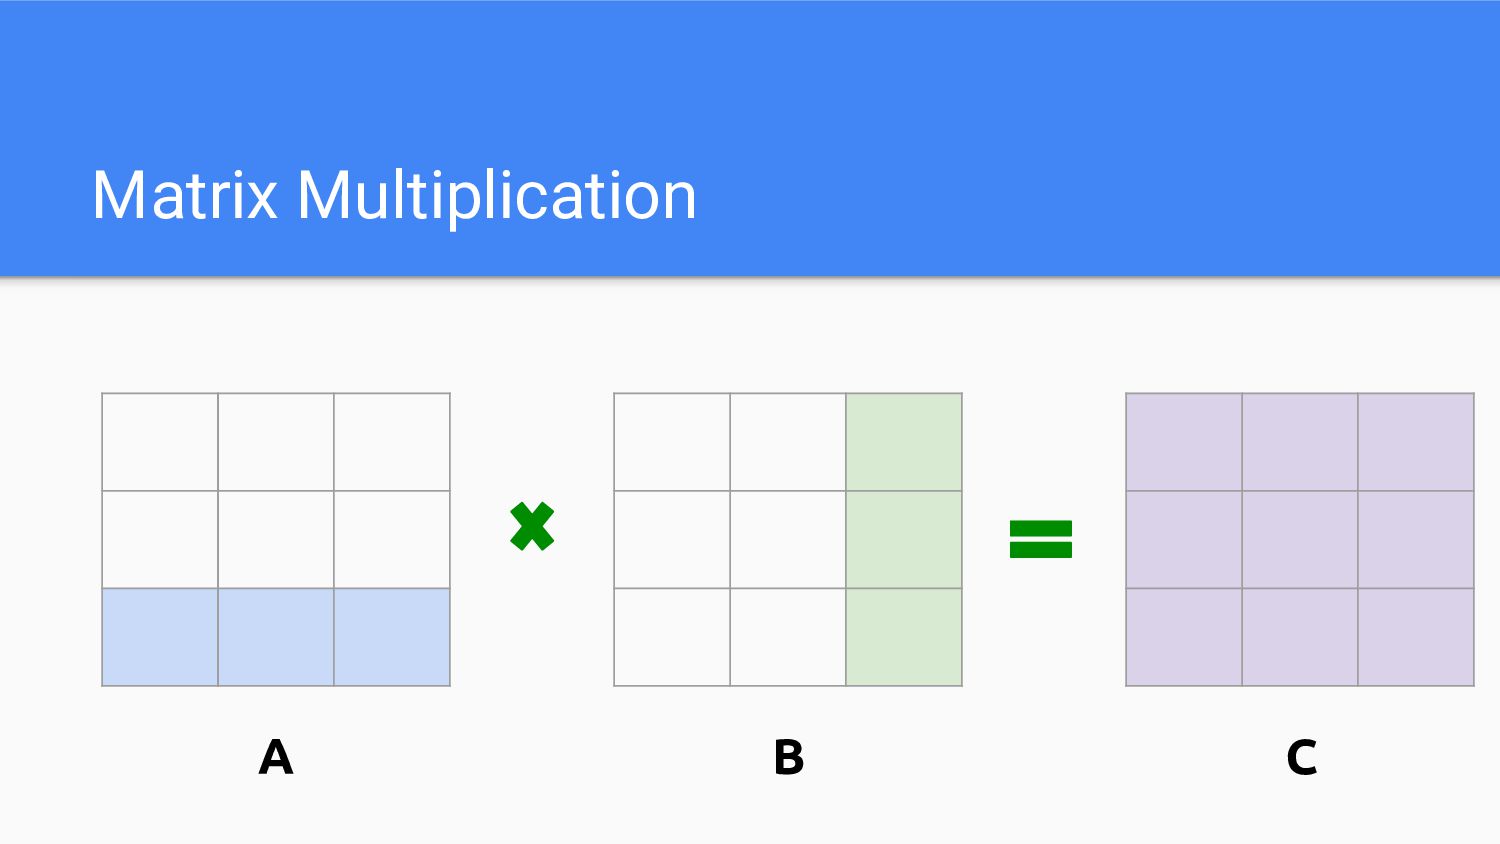
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Matrix Multiplication A B C
Ways to improve the performance to this algorithm - Algorithm
complexity - Parallelism
Ways to improve the performance to this algorithm - Algorithm
complexity - Parallelism
Ways to improve the performance to this algorithm - Algorithm
complexity - Parallelism - Shared Memory - Distributed Memory
Ways to improve the performance to this algorithm - Algorithm
complexity - Parallelism - Shared Memory - Distributed Memory
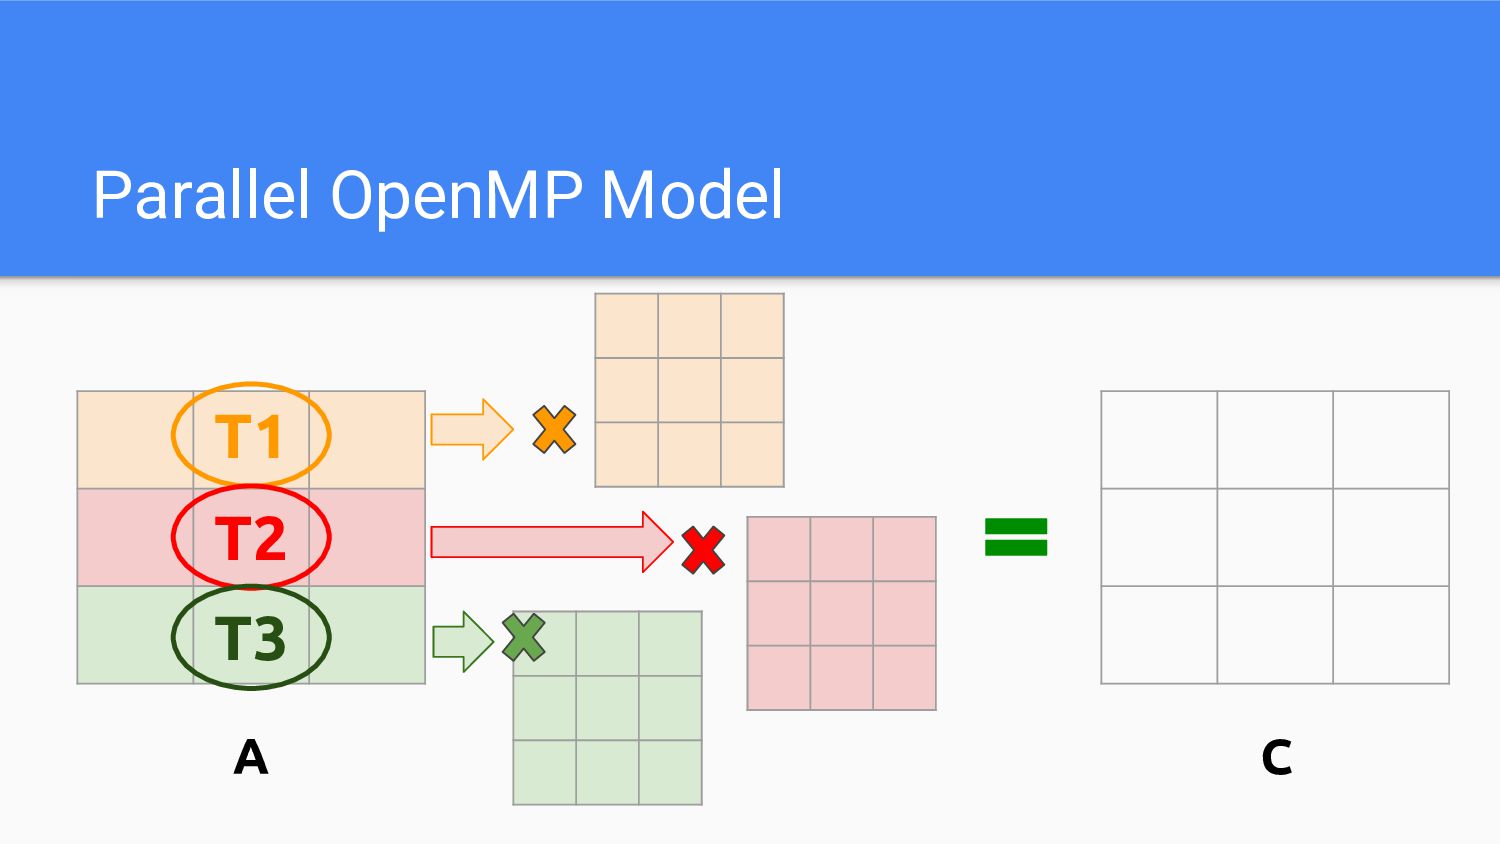
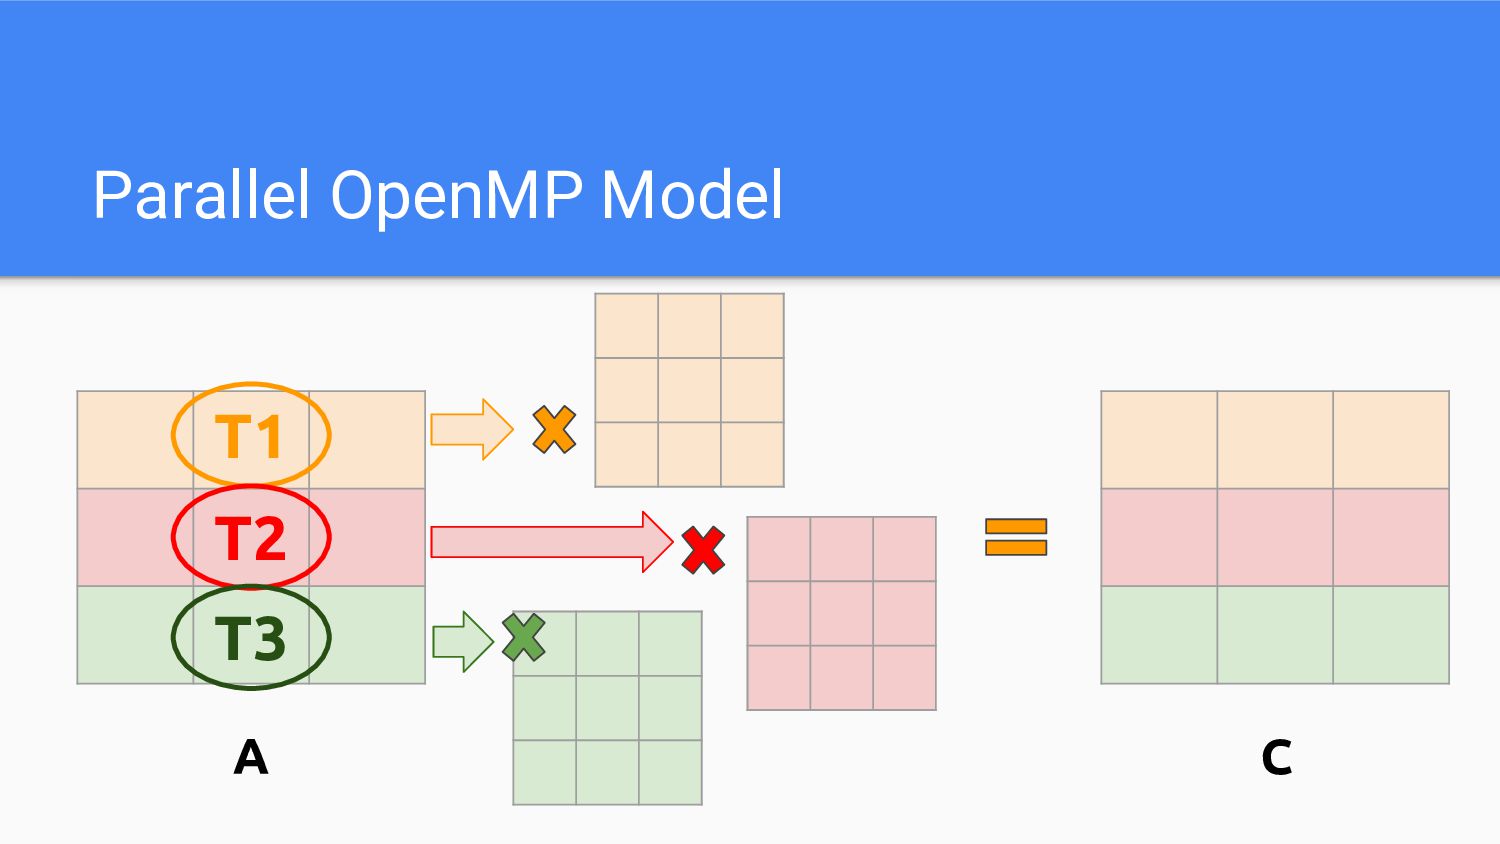
Parallel OpenMP Model A C T1 T2 T3
Parallel OpenMP Model A C T1 T2 T3
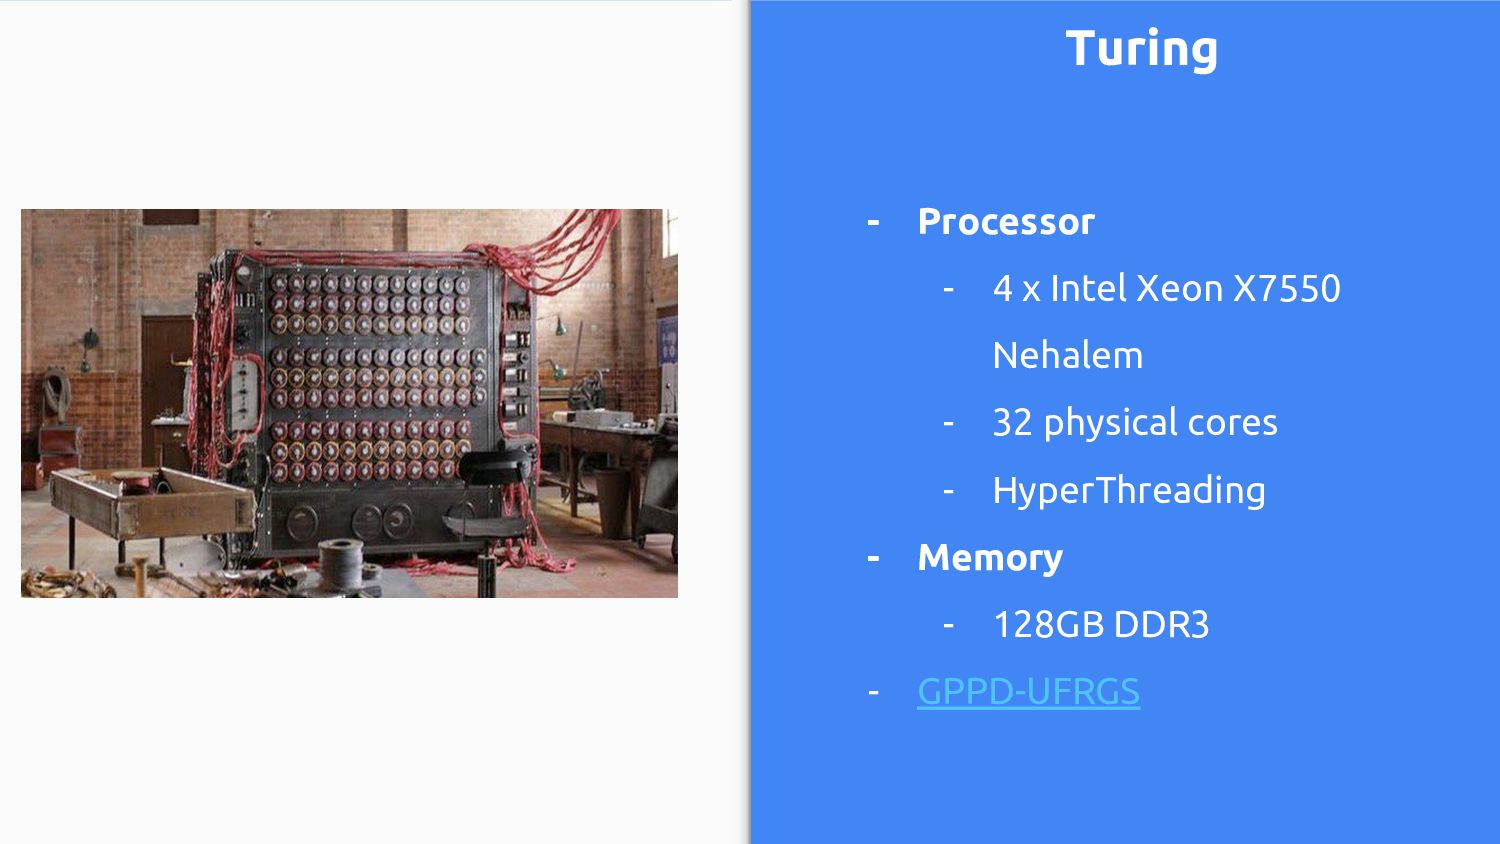
Turing - Processor - 4 x Intel Xeon X7550 Nehalem
- 32 physical cores - HyperThreading - Memory - 128GB DDR3 - GPPD-UFRGS
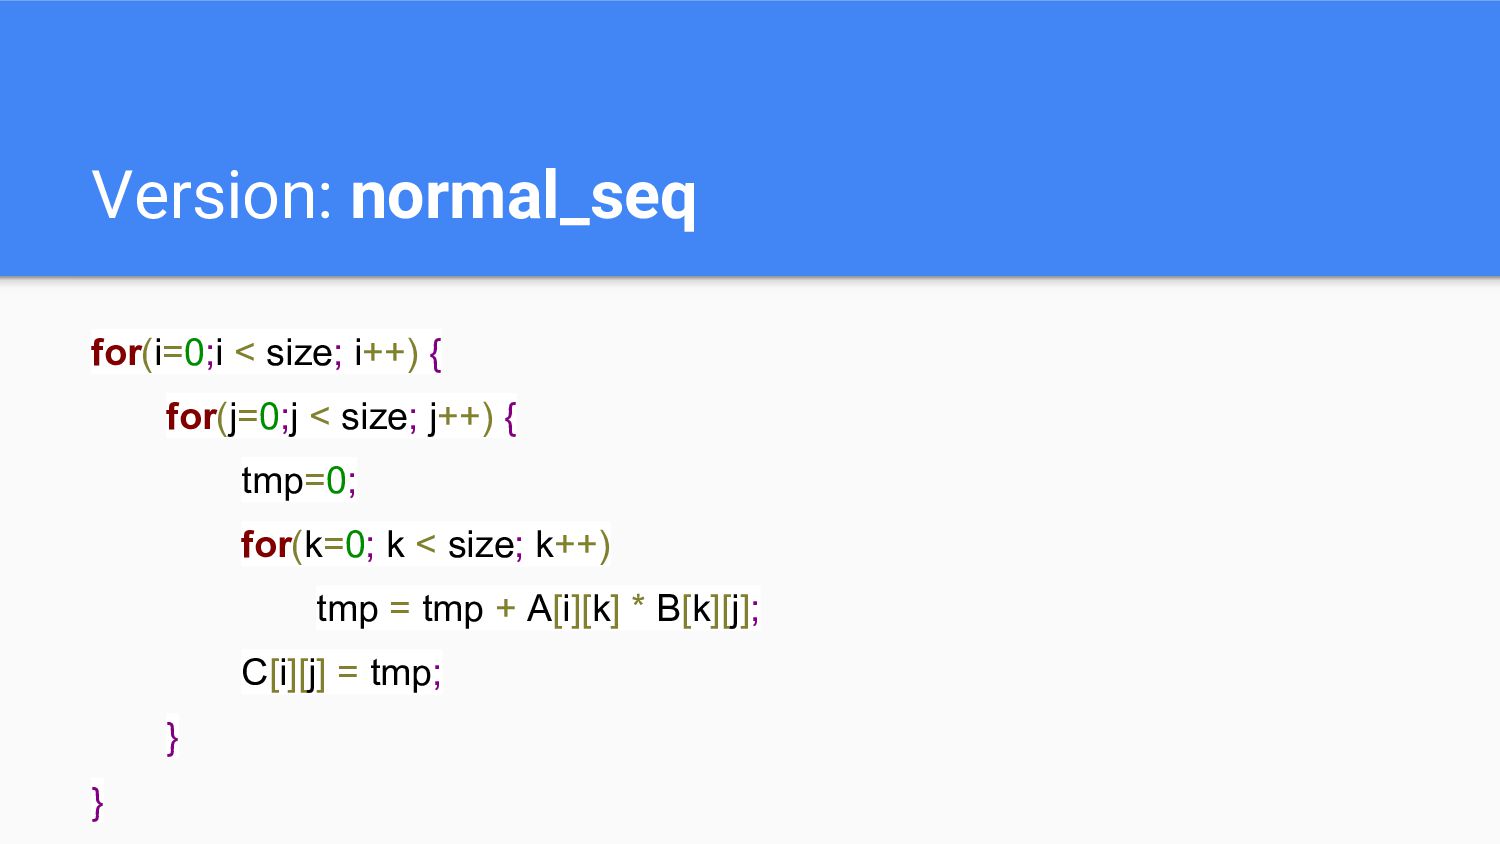
Version: normal_seq for(i=0;i < size; i++) { for(j=0;j < size;
j++) { tmp=0; for(k=0; k < size; k++) tmp = tmp + A[i][k] * B[k][j]; C[i][j] = tmp; } }
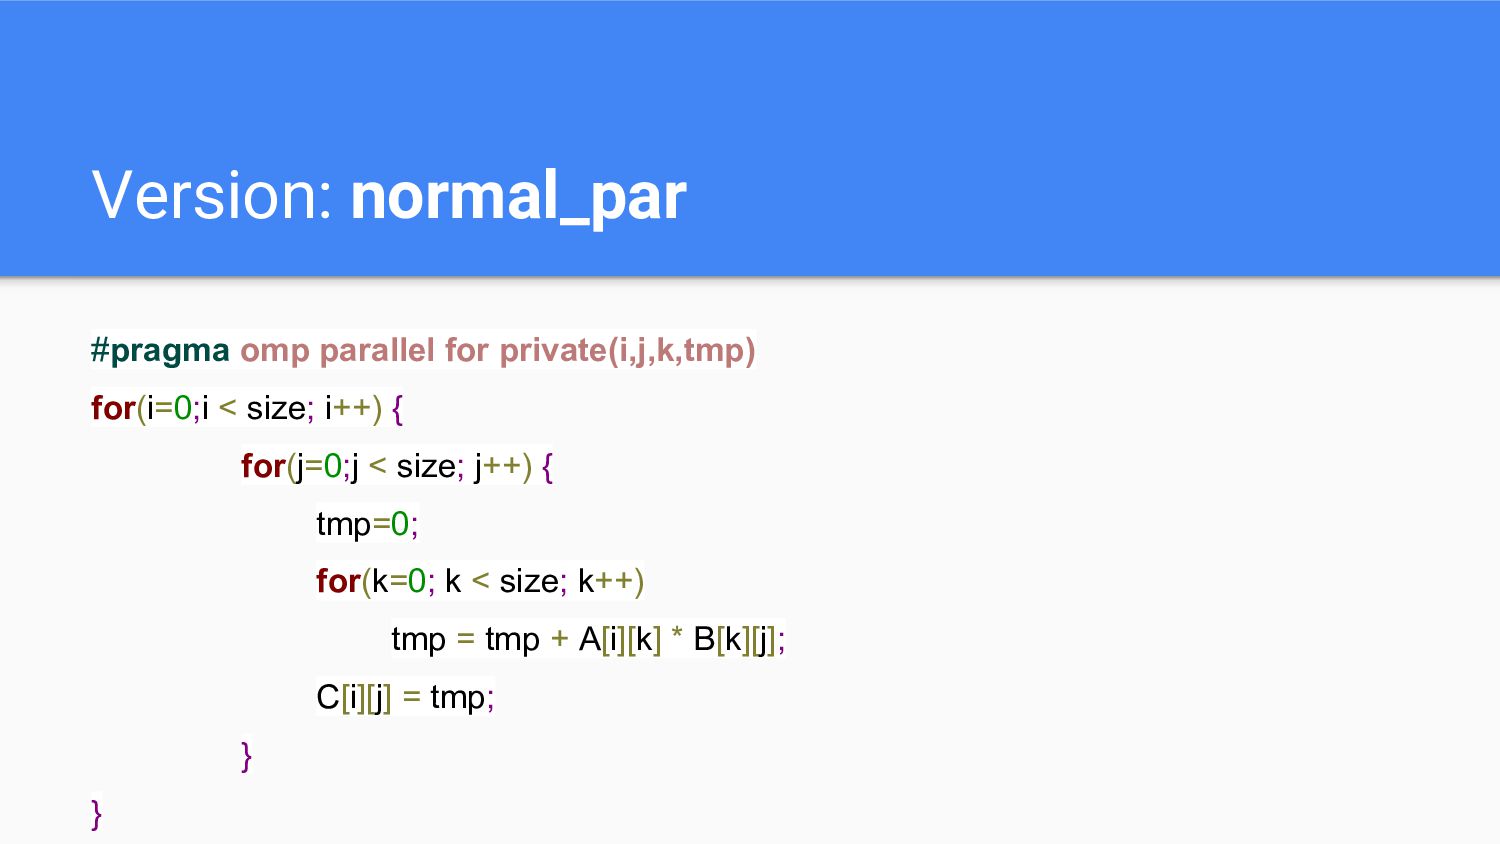
Version: normal_par #pragma omp parallel for private(i,j,k,tmp) for(i=0;i < size;
i++) { for(j=0;j < size; j++) { tmp=0; for(k=0; k < size; k++) tmp = tmp + A[i][k] * B[k][j]; C[i][j] = tmp; } }
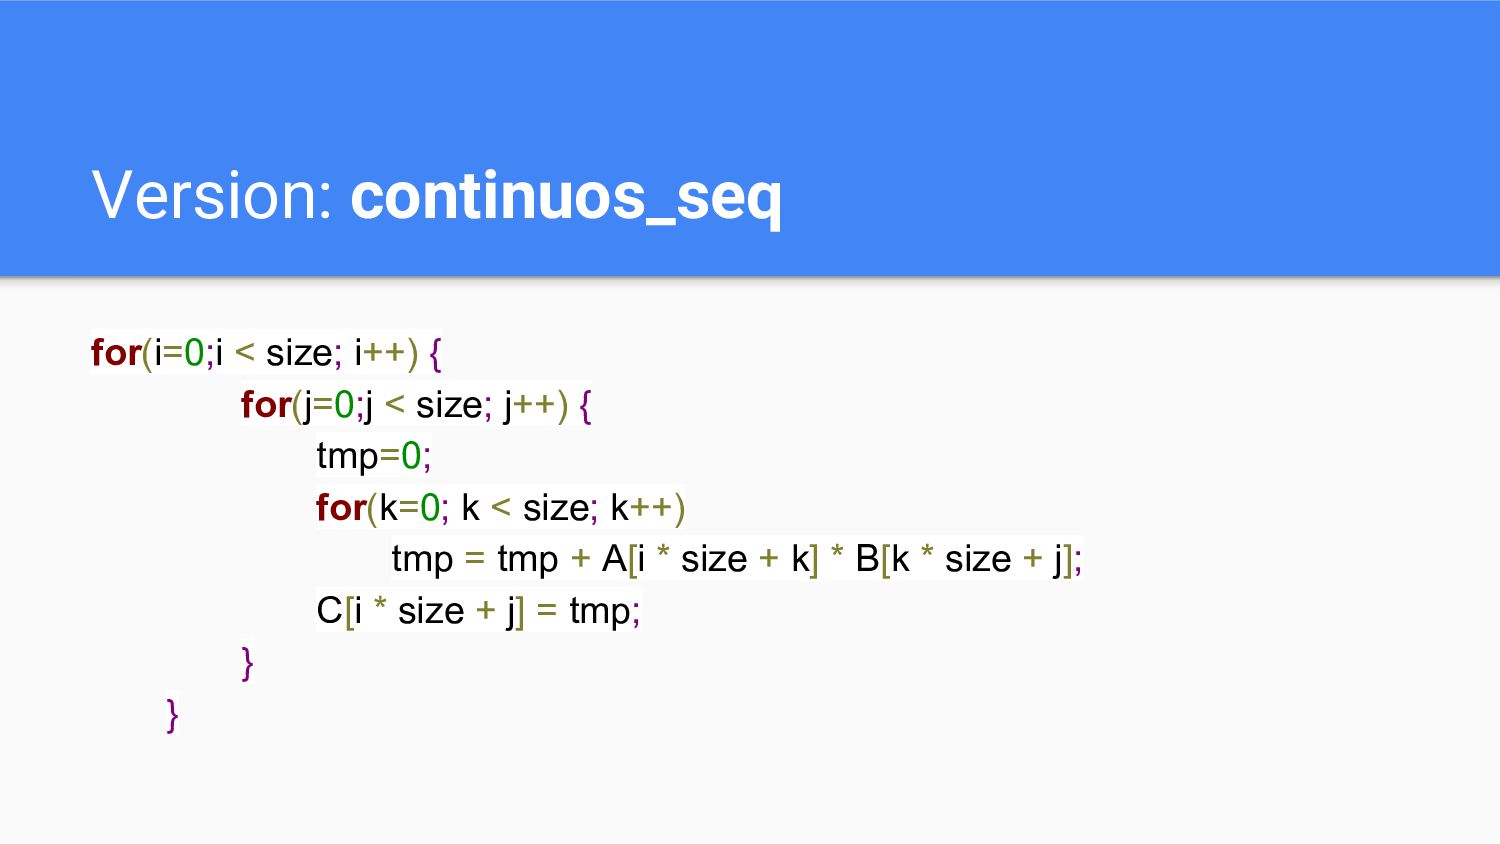
Version: continuos_seq for(i=0;i < size; i++) { for(j=0;j < size;
j++) { tmp=0; for(k=0; k < size; k++) tmp = tmp + A[i * size + k] * B[k * size + j]; C[i * size + j] = tmp; } }
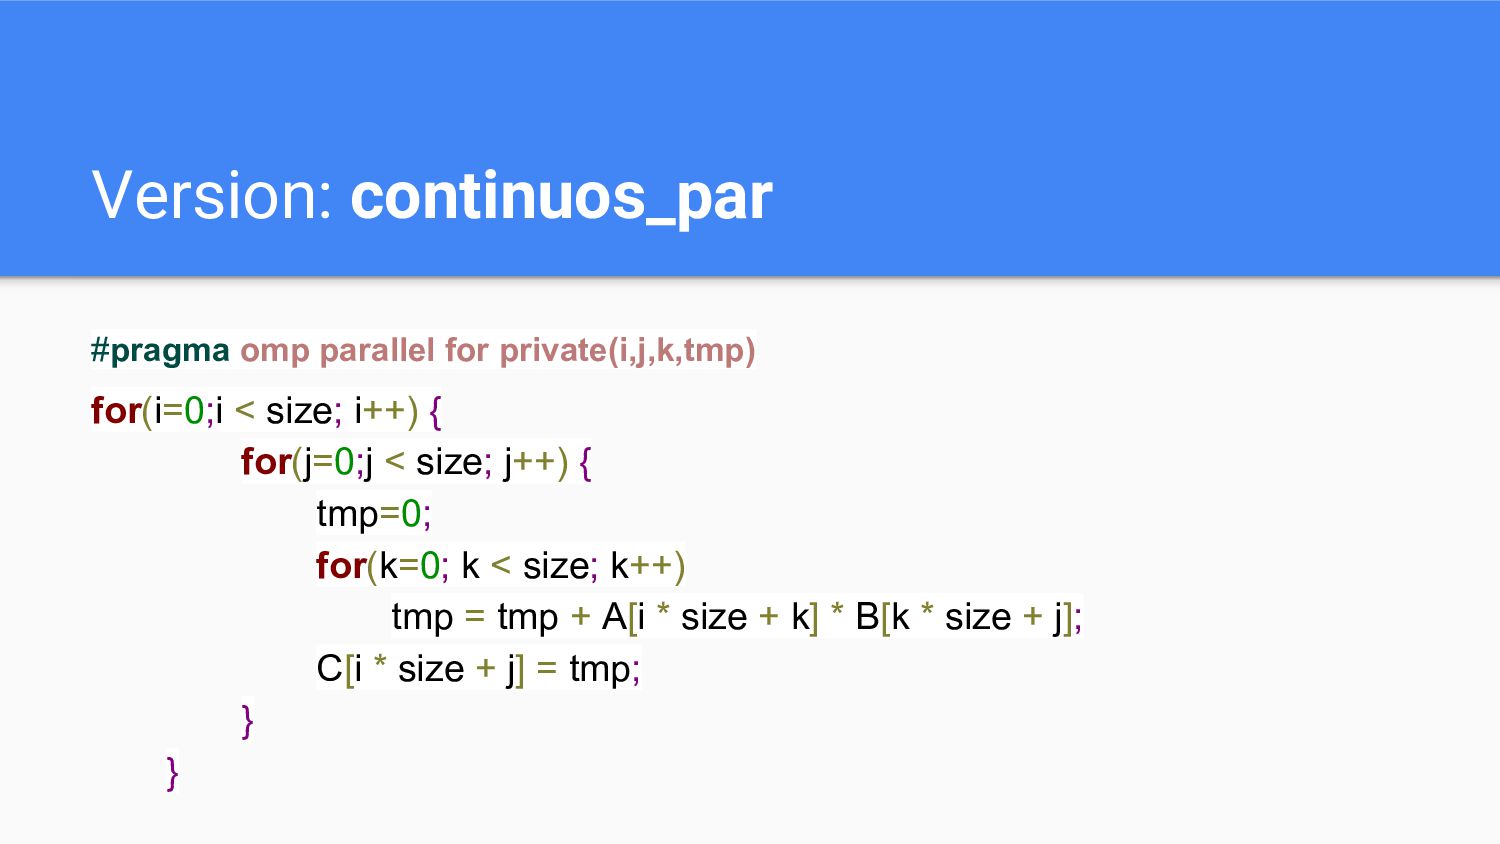
Version: continuos_par #pragma omp parallel for private(i,j,k,tmp) for(i=0;i < size;
i++) { for(j=0;j < size; j++) { tmp=0; for(k=0; k < size; k++) tmp = tmp + A[i * size + k] * B[k * size + j]; C[i * size + j] = tmp; } }
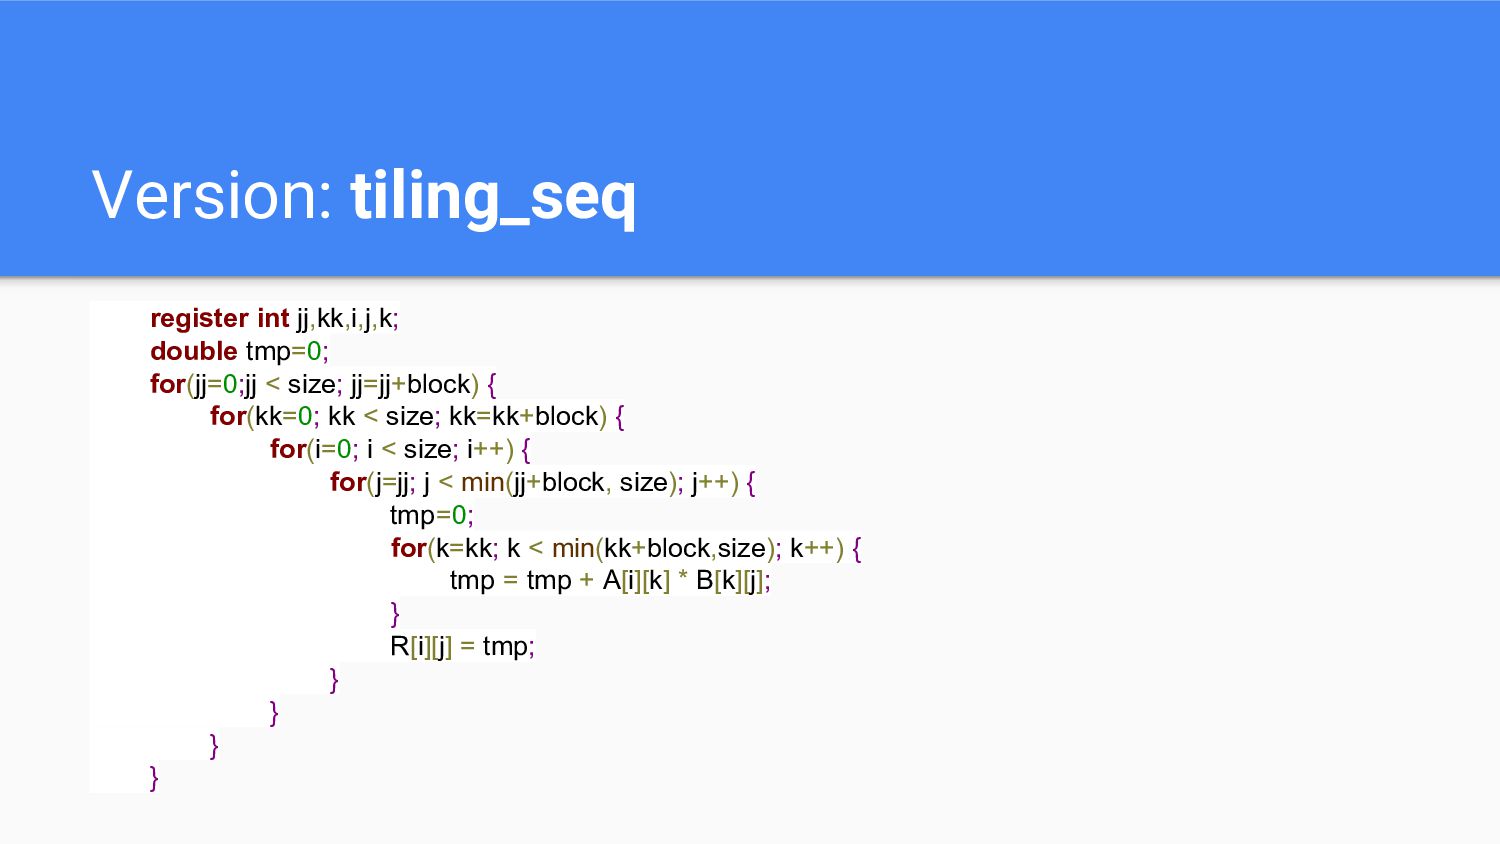
Version: tiling_seq register int jj,kk,i,j,k; double tmp=0; for(jj=0;jj < size;
jj=jj+block) { for(kk=0; kk < size; kk=kk+block) { for(i=0; i < size; i++) { for(j=jj; j < min(jj+block, size); j++) { tmp=0; for(k=kk; k < min(kk+block,size); k++) { tmp = tmp + A[i][k] * B[k][j]; } R[i][j] = tmp; } } } }
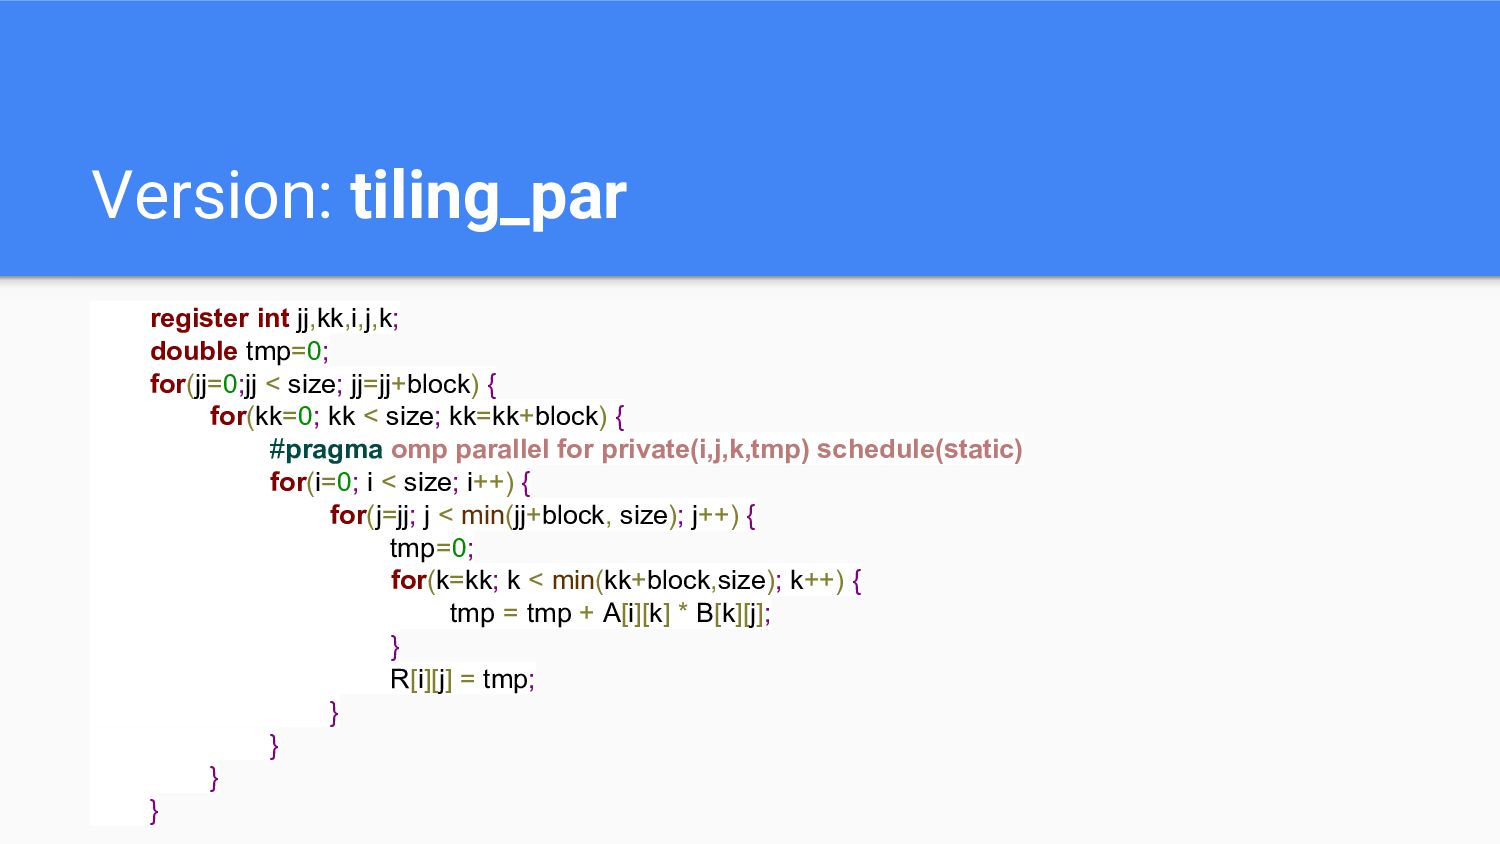
Version: tiling_par register int jj,kk,i,j,k; double tmp=0; for(jj=0;jj < size;
jj=jj+block) { for(kk=0; kk < size; kk=kk+block) { #pragma omp parallel for private(i,j,k,tmp) schedule(static) for(i=0; i < size; i++) { for(j=jj; j < min(jj+block, size); j++) { tmp=0; for(k=kk; k < min(kk+block,size); k++) { tmp = tmp + A[i][k] * B[k][j]; } R[i][j] = tmp; } } } }
Links - Top 500: https://www.top500.org/lists/2018/11/ - Green 500: https://www.top500.org/green500/lists/2018/11/ -
NAS Parallel Benchmark: https://www.nas.nasa.gov/publications/npb.html
Thanks! https://github.com/tido4410/knowledge-transfer-gbmoro.git Gabriel Moro - Matrix Multiplication - OpenMP -
KT, Porto Alegre - November 2018


 gabrielbmoro
 marcoroth
 chobishiba
 iwatsukayura
 yumnumm
 florets1
 sorah
 taiseiue
 sylph01
 htkym
 kmars0605
 ivargrimstad
 kasacchiful
 kimpetersen
 aleyda
 geoffreycrofte
 elsirapls
 konakalab
 kneath
 marcelosomers
 bluesmoon
 jnunemaker
 palkan
 lara
 wayneb77