Share
Embed
Mongo and Ops
gamechanger
August 21, 2012
Transcript
8 slides
-
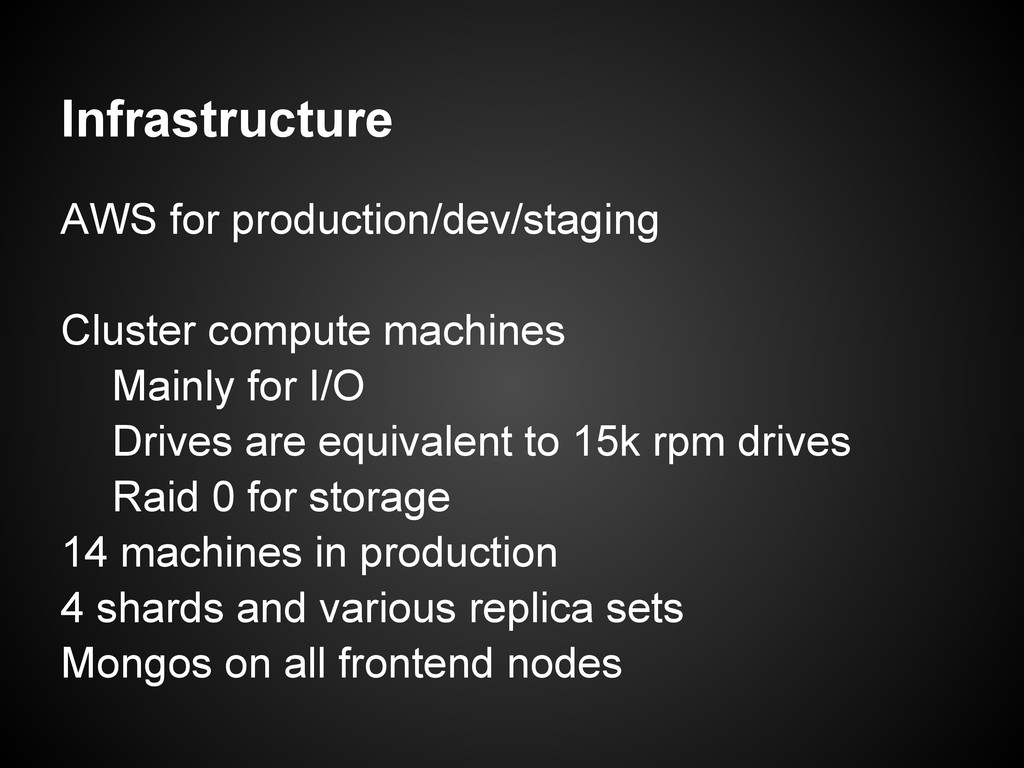
Infrastructure AWS for production/dev/staging Cluster compute machines Mainly for I/O
Drives are equivalent to 15k rpm drives Raid 0 for storage 14 machines in production 4 shards and various replica sets Mongos on all frontend nodes -
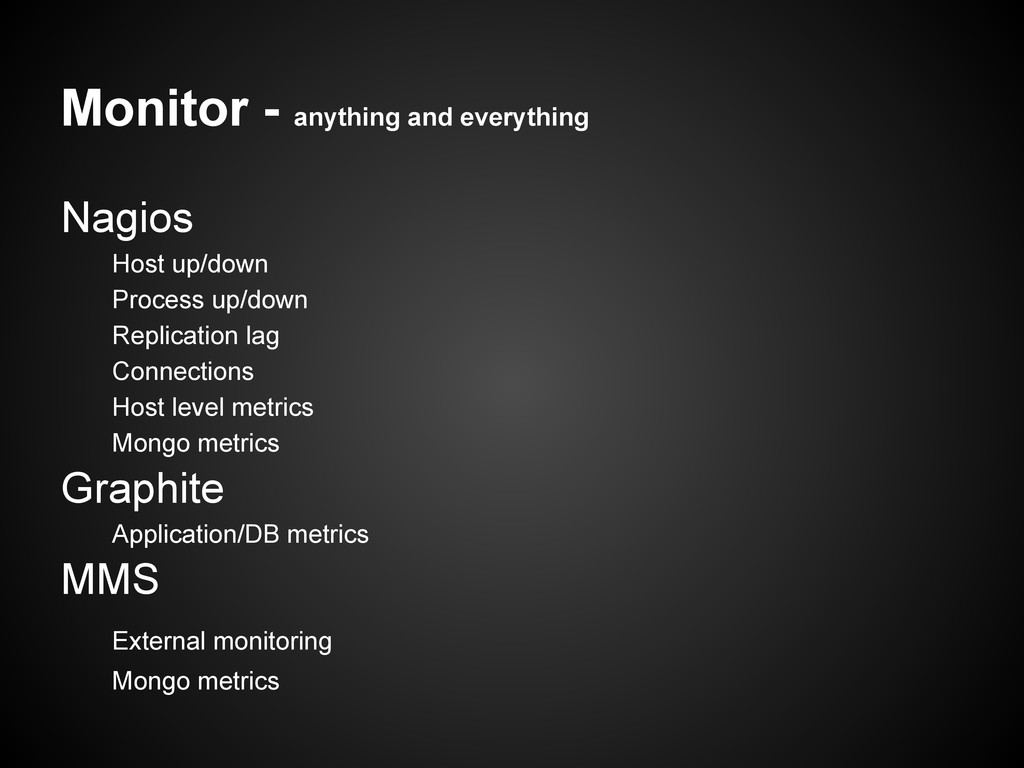
Monitor - anything and everything Nagios Host up/down Process up/down
Replication lag Connections Host level metrics Mongo metrics Graphite Application/DB metrics MMS External monitoring Mongo metrics -
Backups and DR 2 replicas of each shard for redundancy.
3rd replica node for backups. Set to priority 0 Backup node is EBS based Over 2 TB of data in mongo EBS snapshots for backups Snapshot every few hours -
Configuration management Use chef to build/manage servers. Using opscode's hosted
chef server offering. Cookbooks are divided up into various small modules. base, mongodb knife for provisioning/bootstrapping data bags for user management -
Optimizations Raid 0 on 2 drives for CC machines and
8 drives on ebs machines. blockdev read ahead optimizations on ebs volumes. # of open files bumped to 32k small tcp_keepalive_time on clients (300) -
Lessons learned • EBS is slow for primary/secondary mongodb operations
but great for snapshots. • Nodes in AWS can disappear quite frequently, make sure they are disposable. • Mongodump doesn't really work well for large sharded databases. Takes too long to dump and ship to s3, can't ship files larger than 5gb to s3. • Keep an eye out for write lock %