servers Our server software: ► Runs on customer servers, in cloud and on edge nodes. ► Runs on Windows, Mac, Several Linuxes. ► Is tightly coupled to the OS it runs on. ► Is usually soft real time.
Mac and Linuxes ► Reasonable memory footprint ► Fast enough for soft real time ► Simple language. Good for writing complex software. ► Fast development cycles ► Libraries for common needs. String processing, networking, crypto, graphics, etc ► Libraries follow simplicity of base language.
protocol ► Widely used ► Basis of CUPS, the printing subsystem on Mac and Unix ► Basis of AirPrint, the native printing on iOS devices ► Needs a directory service, typically DNS or mDNS ► Uses PDF as internal print document format
PDFs. Full text search of the documents can help customers in several ways: ► Print alerts: Search for a fixed term in each document before it is printed. ► Print archive search: Search over all user’s documents. Present her with a list and allow her to print selected documents or pages ► Qrdoc Program: Adds a QR code to documents. Readers of the paper document access the digital copy by scanning the QR code.
to text. 2. Do full text search on PDF. Get top matches 3. Find page number and location of matches in PDFs. 4. Mark up PDF pages. 5. Optionally rasterize PDF pages to PNG at specified PPI.
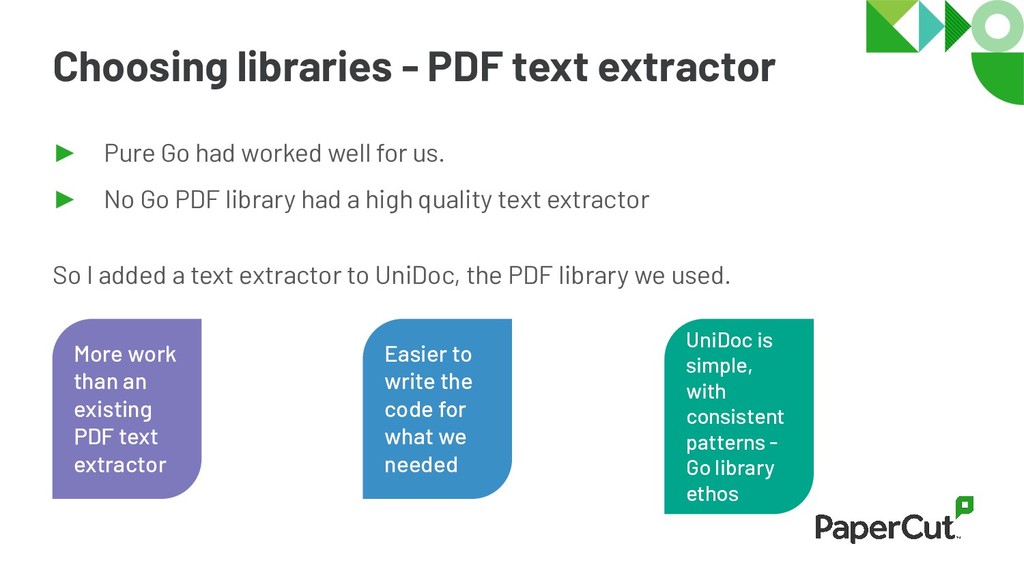
worked well for us. ► No Go PDF library had a high quality text extractor So I added a text extractor to UniDoc, the PDF library we used. Insert more and more info Easier to write the code for what we needed More work than an existing PDF text extractor UniDoc is simple, with consistent patterns - Go library ethos
worked well for us. ► bleve looked simple and clean. ► Simpler and less history than Lucene. ► Had all the features we needed. We didn’t need many. ► We still think Lucene is great.
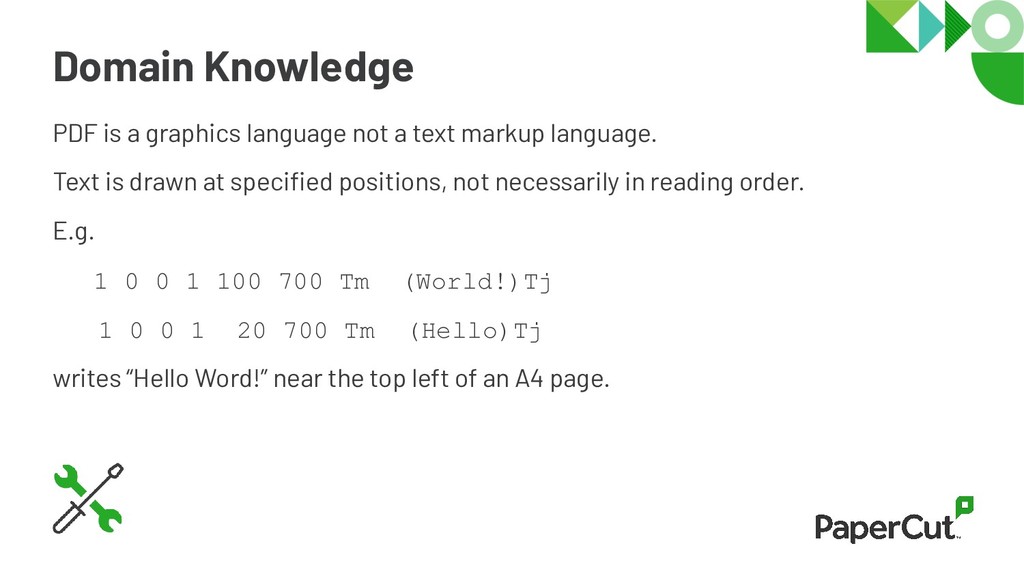
markup language. Text is drawn at specified positions, not necessarily in reading order. E.g. 1 0 0 1 100 700 Tm (World!)Tj 1 0 0 1 20 700 Tm (Hello)Tj writes “Hello Word!” near the top left of an A4 page.
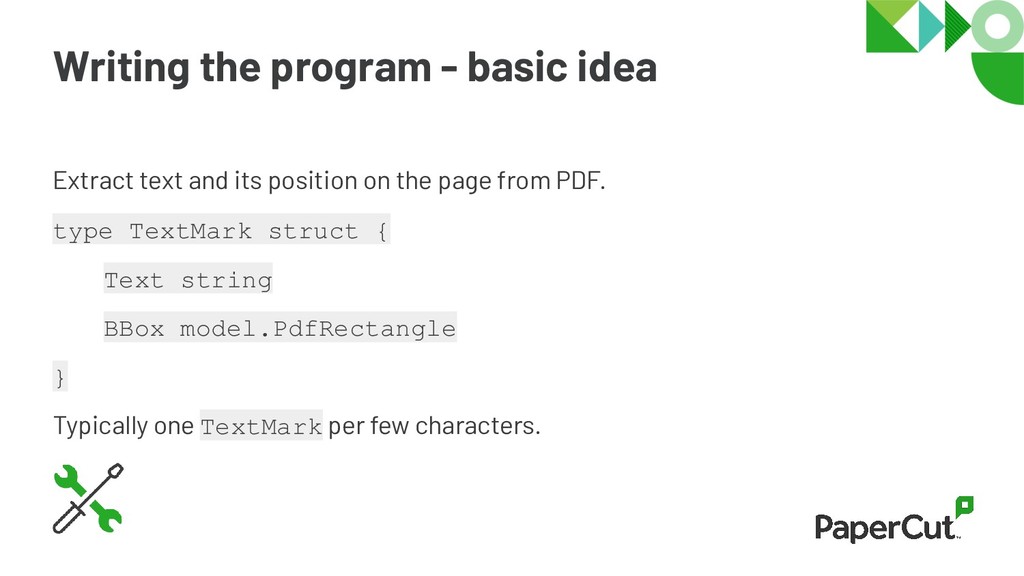
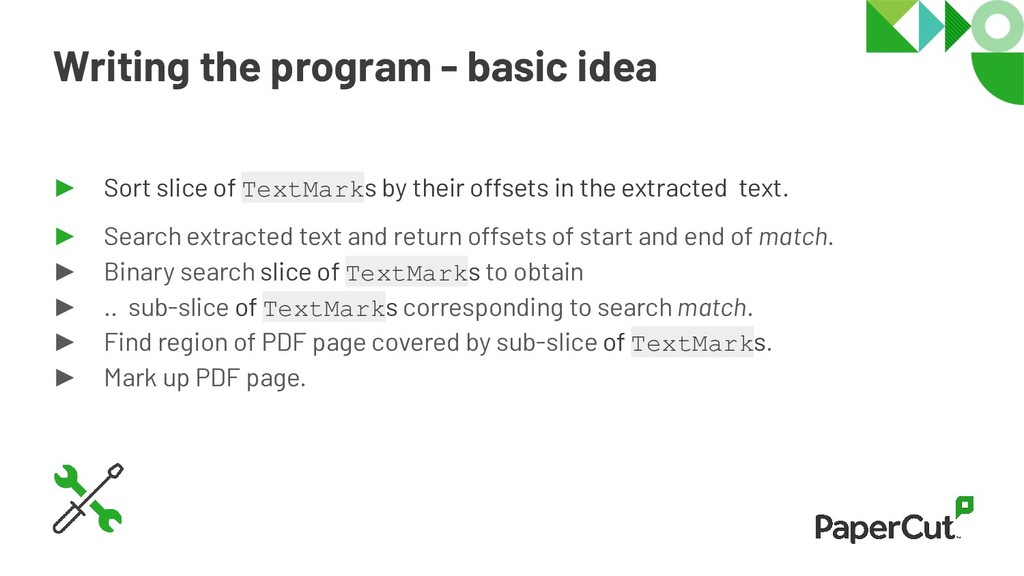
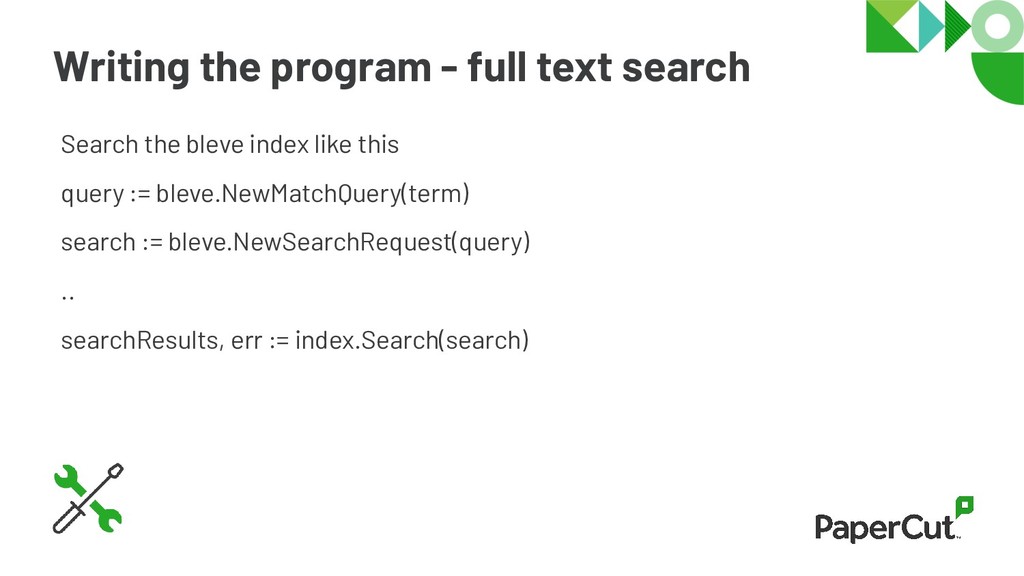
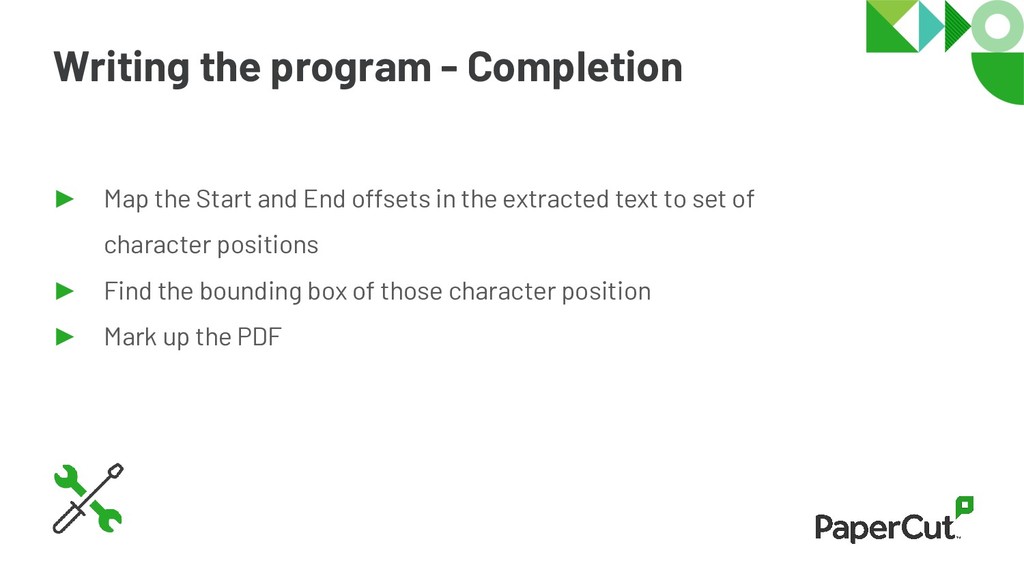
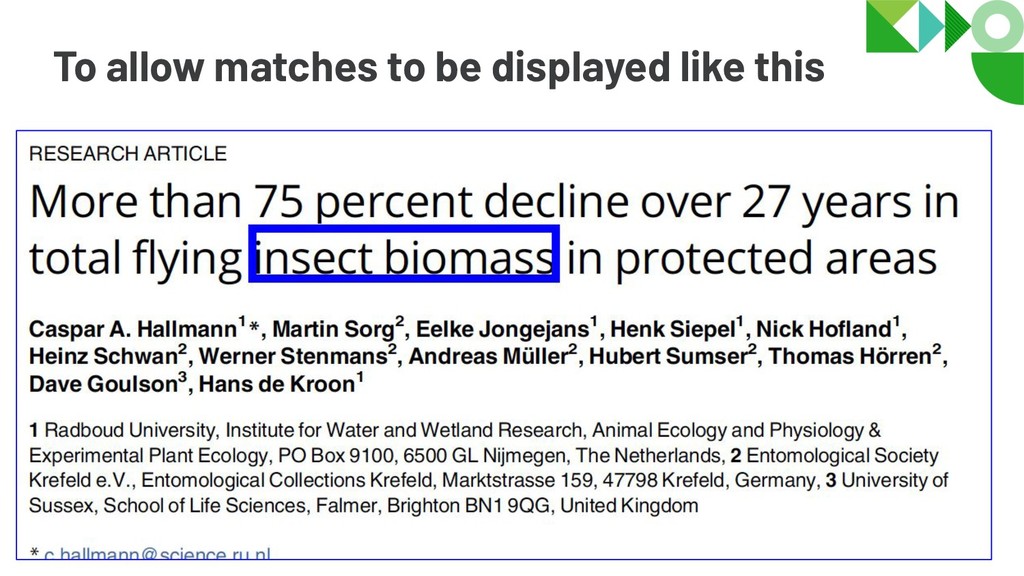
TextMarks by their offsets in the extracted text. ► Search extracted text and return offsets of start and end of match. ► Binary search slice of TextMarks to obtain ► .. sub-slice of TextMarks corresponding to search match. ► Find region of PDF page covered by sub-slice of TextMarks. ► Mark up PDF page.
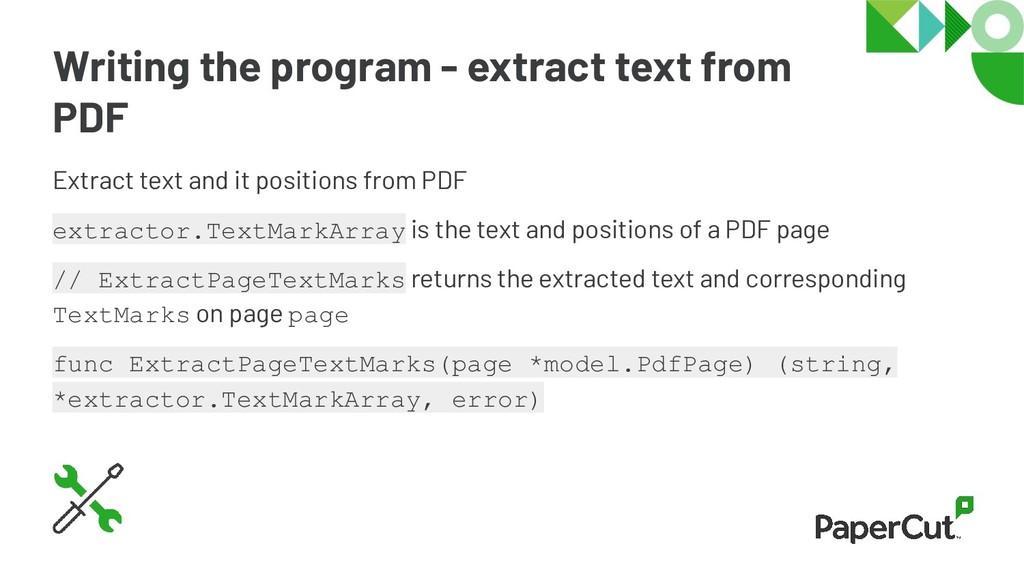
and it positions from PDF extractor.TextMarkArray is the text and positions of a PDF page // ExtractPageTextMarks returns the extracted text and corresponding TextMarks on page page func ExtractPageTextMarks(page *model.PdfPage) (string, *extractor.TextMarkArray, error)
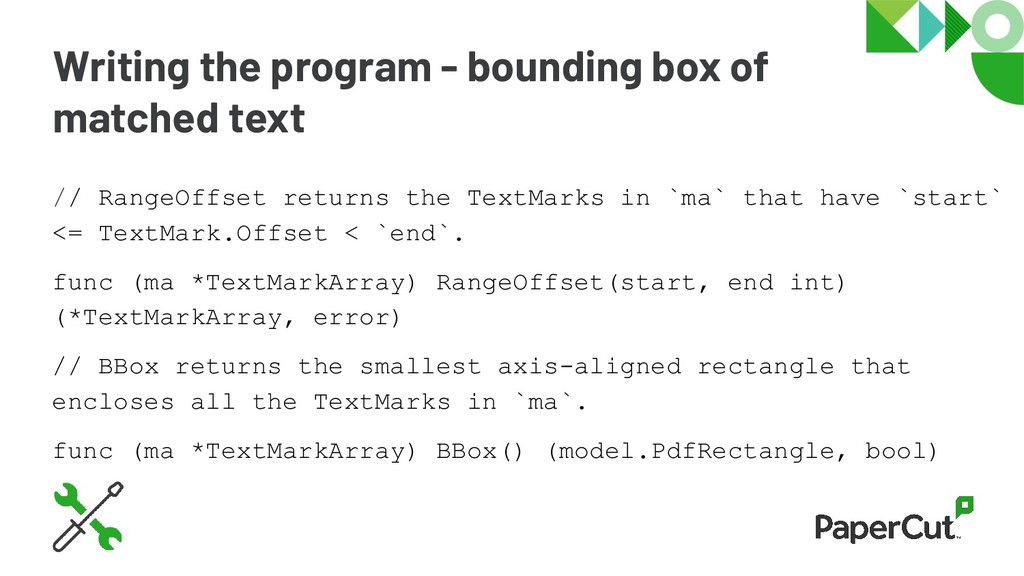
RangeOffset returns the TextMarks in `ma` that have `start` <= TextMark.Offset < `end`. func (ma *TextMarkArray) RangeOffset(start, end int) (*TextMarkArray, error) // BBox returns the smallest axis-aligned rectangle that encloses all the TextMarks in `ma`. func (ma *TextMarkArray) BBox() (model.PdfRectangle, bool)
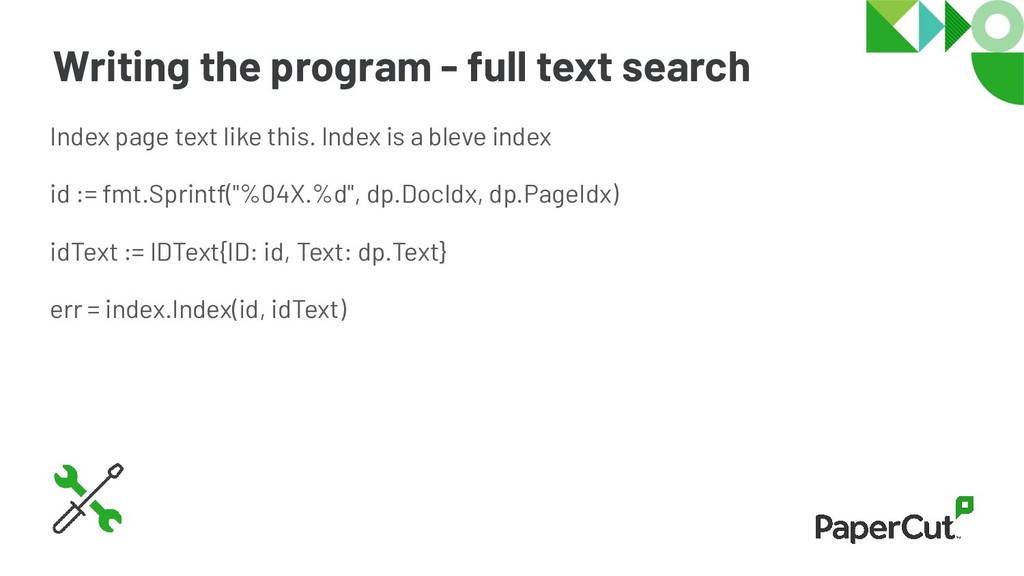
like this. Index is a bleve index id := fmt.Sprintf("%04X.%d", dp.DocIdx, dp.PageIdx) idText := IDText{ID: id, Text: dp.Text} err = index.Index(id, idText)
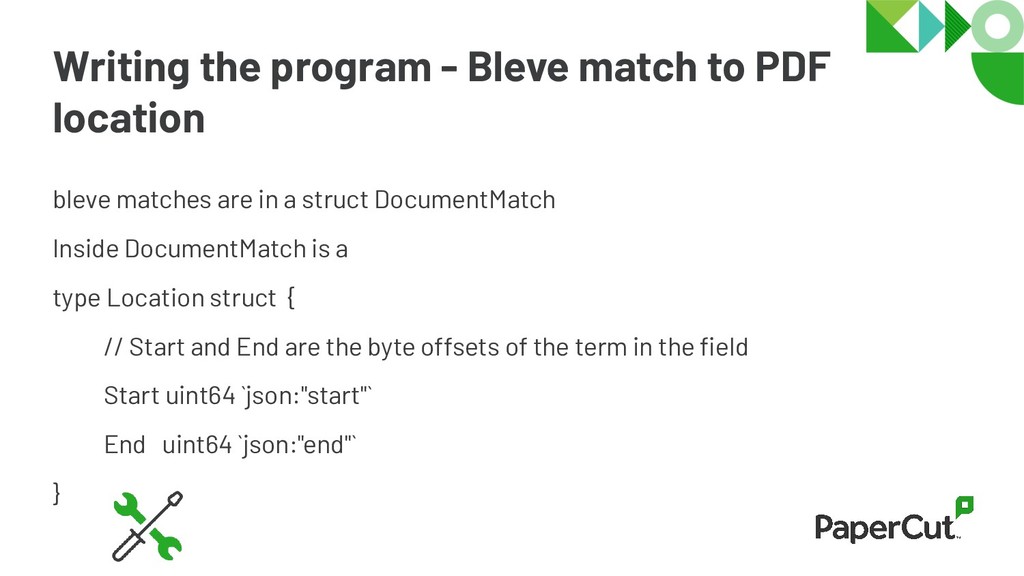
matches are in a struct DocumentMatch Inside DocumentMatch is a type Location struct { // Start and End are the byte offsets of the term in the field Start uint64 `json:"start"` End uint64 `json:"end"` }


 gopherconau
 n_takehata
 kinopeee
 gonta
 rshindo
 andpad
 utakaha
 shihochan
 skydoves
 oku053
 iwatsukayura
 lynnswap
 florets1
 eileencodes
 aleyda
 nwiizo
 rasagy
 tammyeverts
 kristinabergwall1
 427marketing
 brad_frost
 portentint
 reverentgeek
 inesmontani