Upgrade to Pro — share decks privately, control downloads, hide ads and more …

AI-Aware Traffic Management: Scaling Inference ...

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →

AI-Aware Traffic Management: Scaling Inference with Istio Ambient Mesh

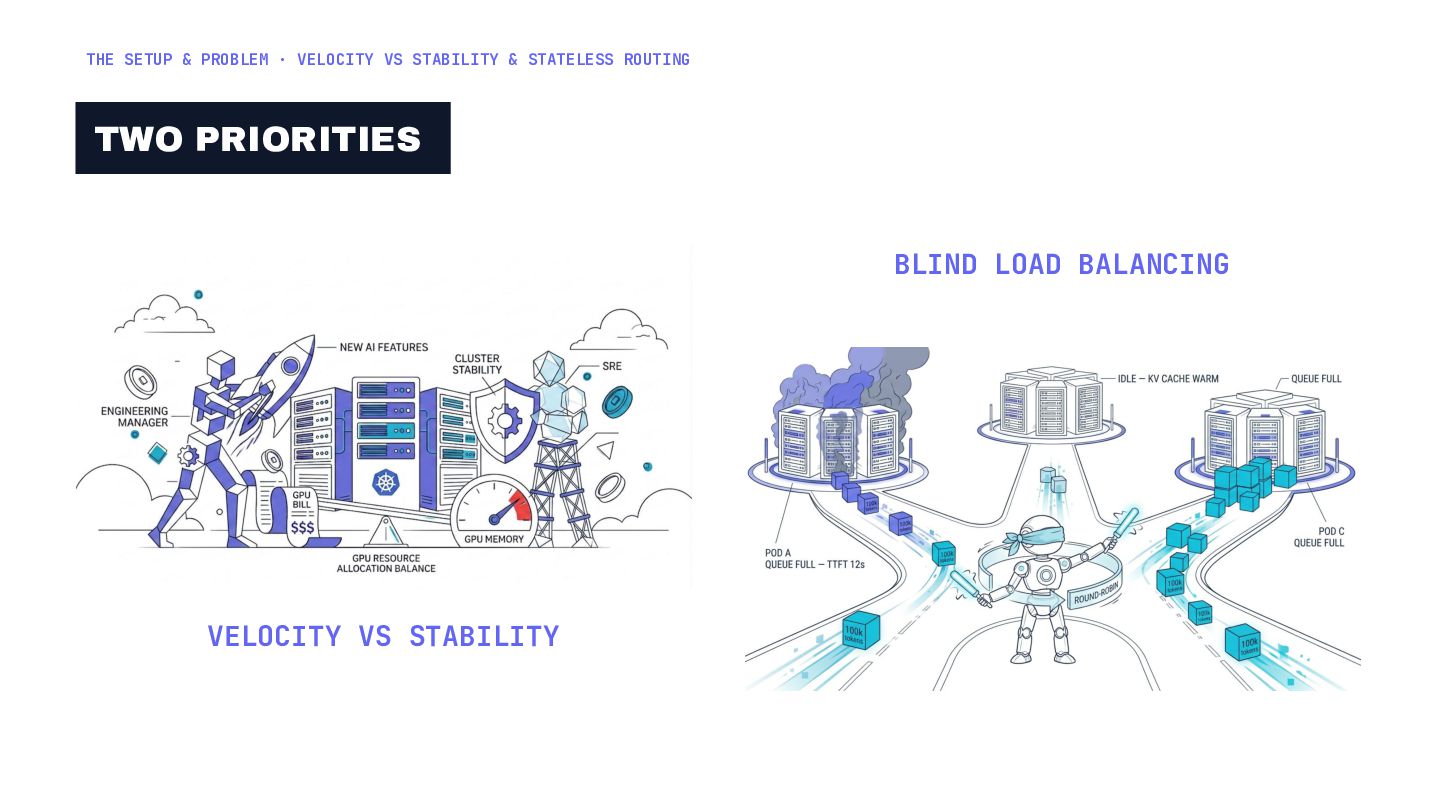
When rolling out AI inference and agentic workflows, a natural tension emerges between product velocity and platform stability. Engineering Managers push to ship LLM features quickly while keeping premium GPU cloud spend under control, while SREs face an operational nightmare. Traditional round-robin load balancers blindly send massive token requests to already choking GPU pods. Securing this traffic typically requires Envoy sidecars, which steal precious memory and CPU from the GPU nodes running the LLMs.

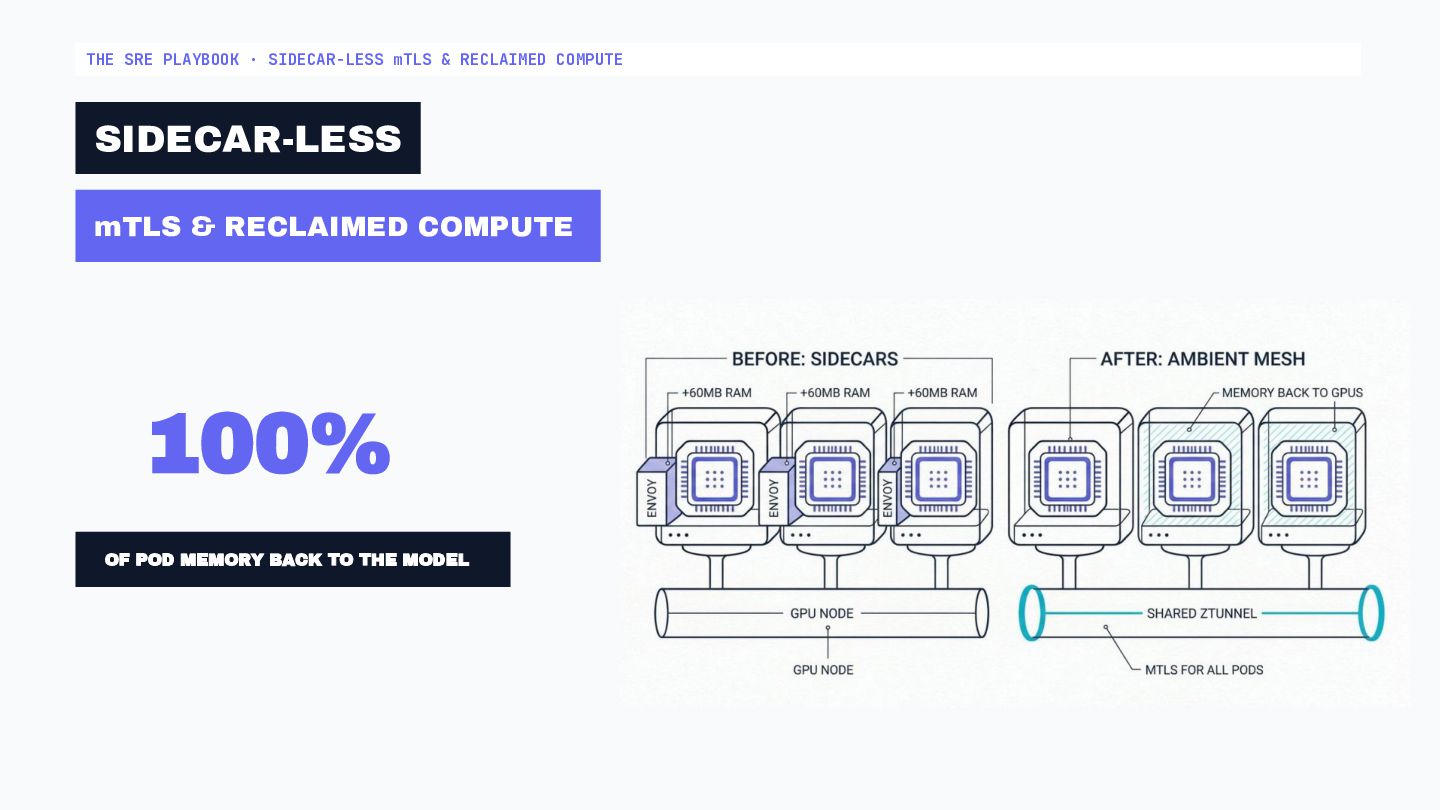
In this dual-perspective session, an Engineering Manager and SRE will debate and dissect the realities of scaling AI infrastructure. We will show how to resolve the velocity versus control paradox by treating AI workloads as first-class citizens in the mesh. We will demonstrate Istio Ambient Mesh ztunnels for sidecar-less mTLS, pushing L7 processing to Waypoint proxies on standard CPU nodes and reclaiming compute for GPUs.

Hannah Olukoye

November 11, 2026

Transcript

12 slides
  1. ISTIO DAY · KUBECON + CLOUDNATIVECON NA 2026 AI-AWARE TRAFFIC

    MANAGEMENT Scaling Inference with Istio Ambient Mesh Hannah Olukoye Mofesola Babalola ENGINEERING MANAGER STAFF SRE
  2. THE SETUP & PROBLEM · VELOCITY VS STABILITY & STATELESS

    ROUTING TWO PRIORITIES BLIND LOAD BALANCING VELOCITY VS STABILITY
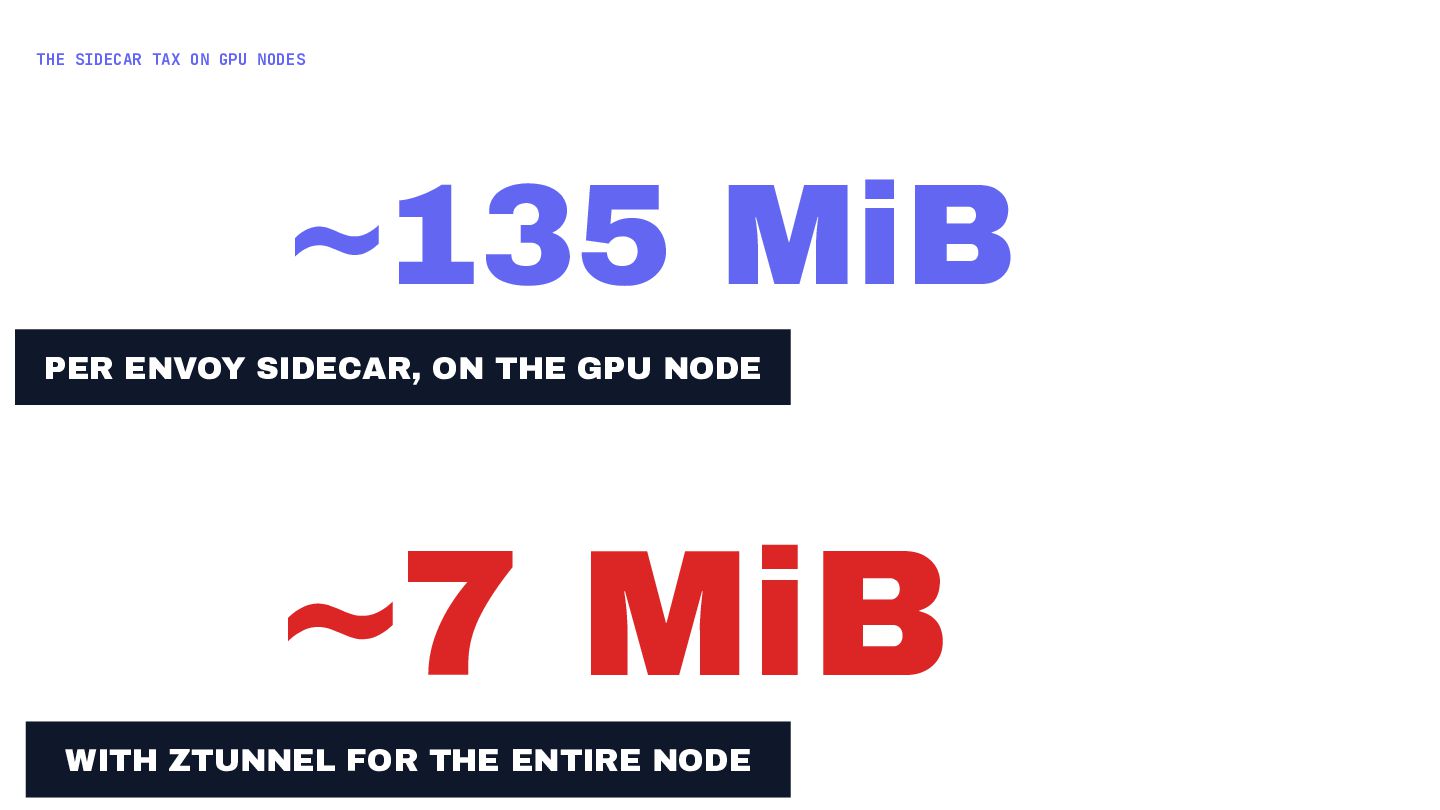
  3. THE SIDECAR TAX ON GPU NODES ~135 MiB PER ENVOY

    SIDECAR, ON THE GPU NODE ~7 MiB WITH ZTUNNEL FOR THE ENTIRE NODE
  4. THE SRE PLAYBOOK · SIDECAR-LESS mTLS & RECLAIMED COMPUTE SIDECAR-LESS

    mTLS & RECLAIMED COMPUTE 100% OF POD MEMORY BACK TO THE MODEL
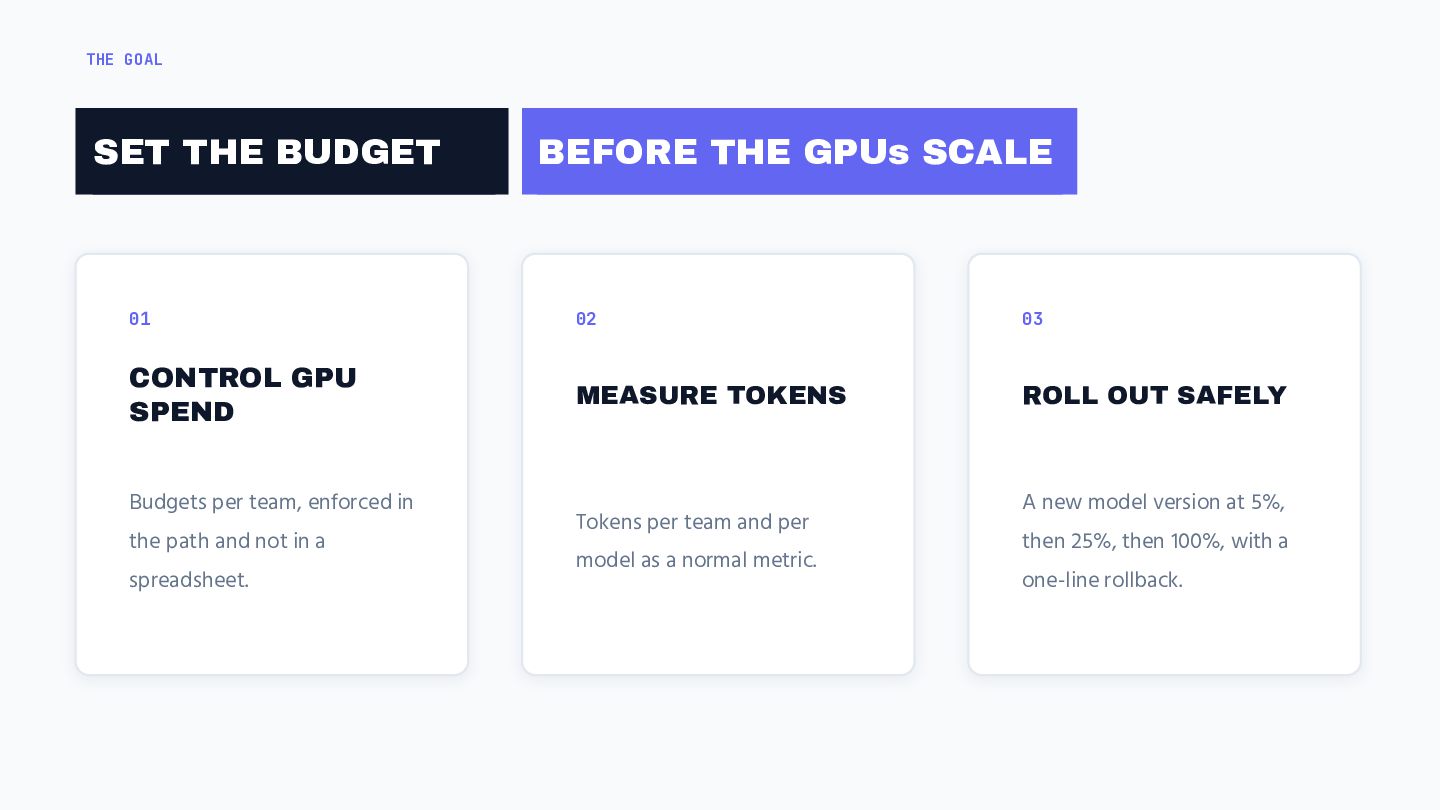
  5. THE GOAL SET THE BUDGET BEFORE THE GPUs SCALE 01

    02 03 CONTROL GPU SPEND MEASURE TOKENS ROLL OUT SAFELY Budgets per team, enforced in the path and not in a spreadsheet. Tokens per team and per model as a normal metric. A new model version at 5%, then 25%, then 100%, with a one-line rollback.
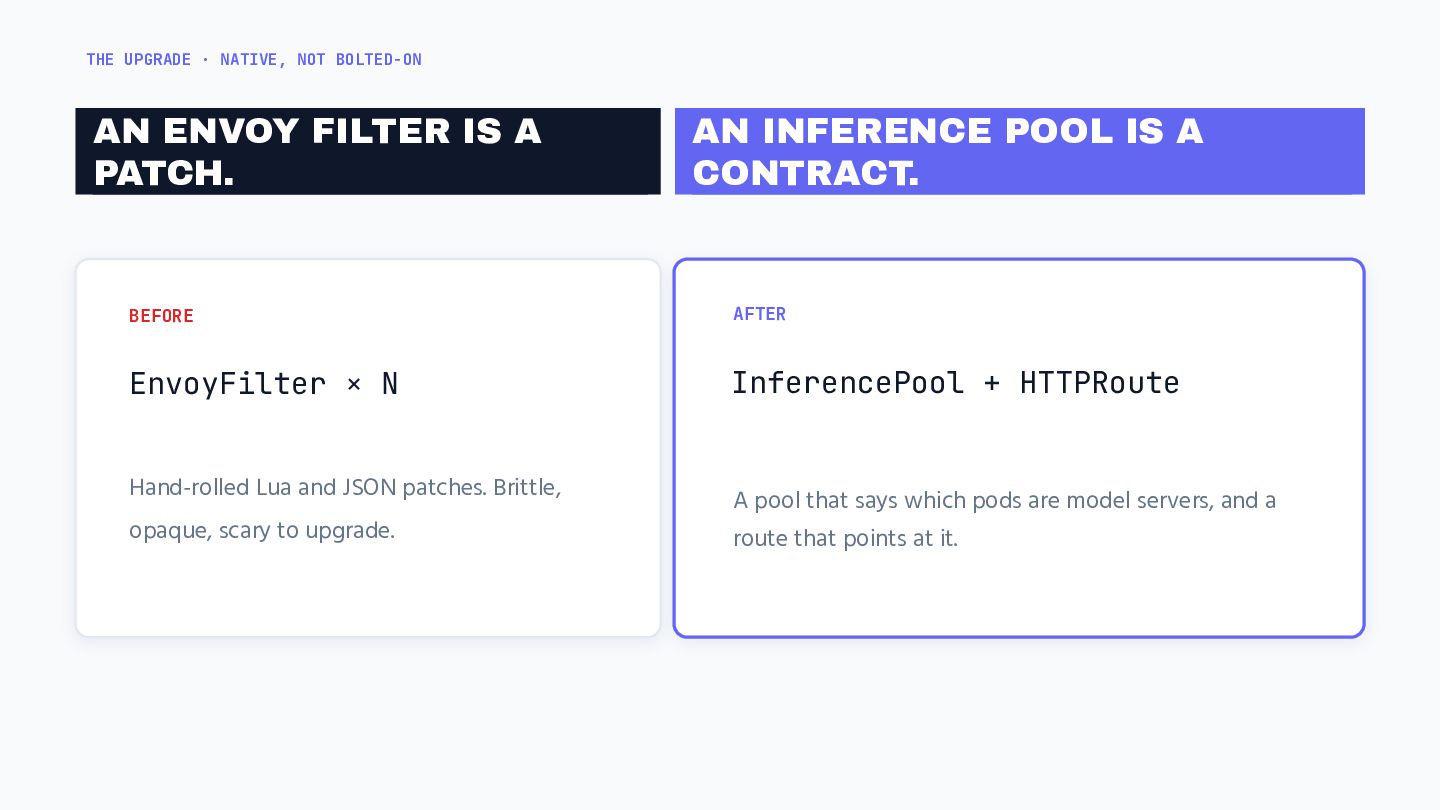
  6. THE UPGRADE · NATIVE, NOT BOLTED-ON AN ENVOY FILTER IS

    A PATCH. AN INFERENCE POOL IS A CONTRACT. BEFORE AFTER EnvoyFilter × N InferencePool + HTTPRoute Hand-rolled Lua and JSON patches. Brittle, opaque, scary to upgrade. A pool that says which pods are model servers, and a route that points at it.
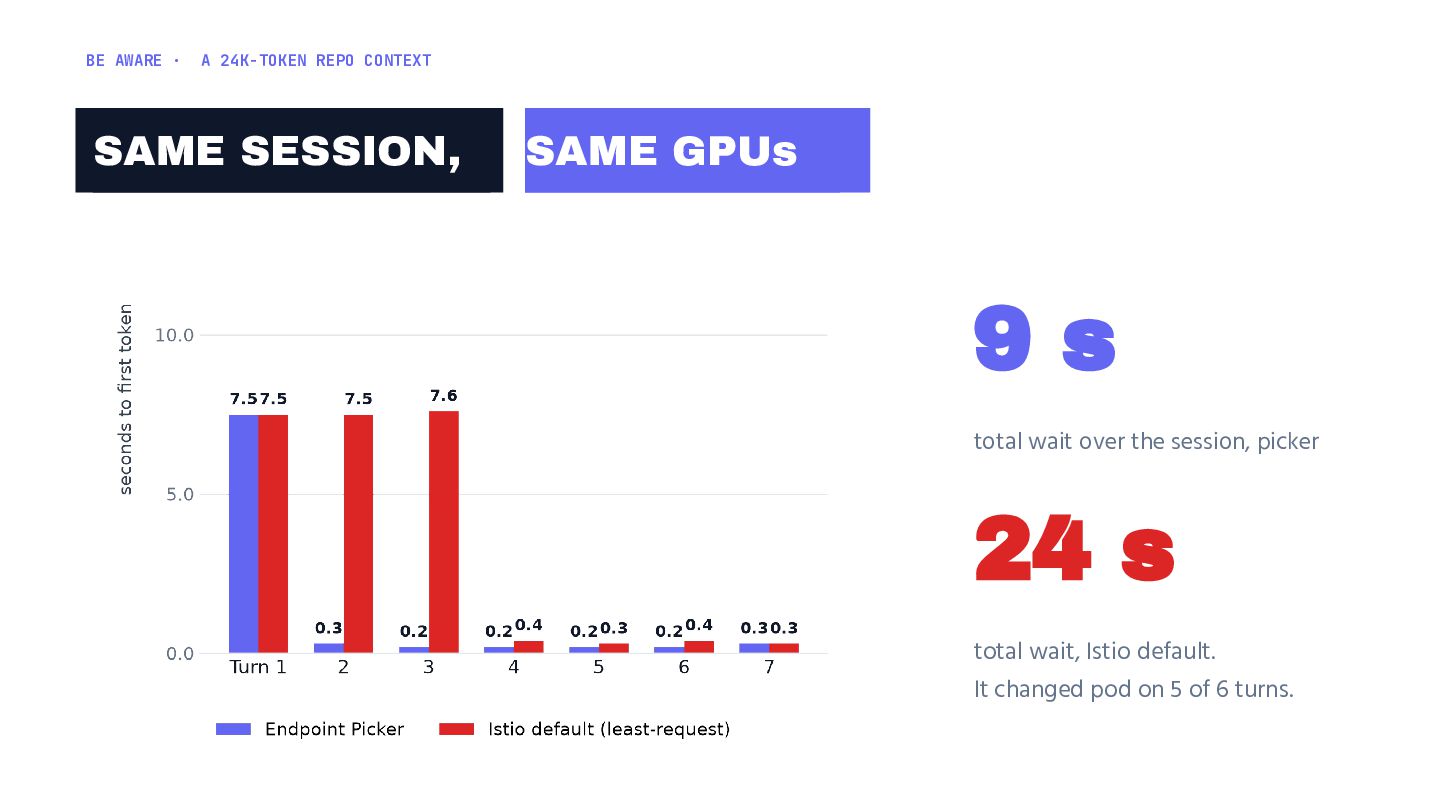
  7. BE AWARE · A 24K-TOKEN REPO CONTEXT SAME SESSION, SAME

    GPUs 9s total wait over the session, picker 24 s total wait, Istio default. It changed pod on 5 of 6 turns.
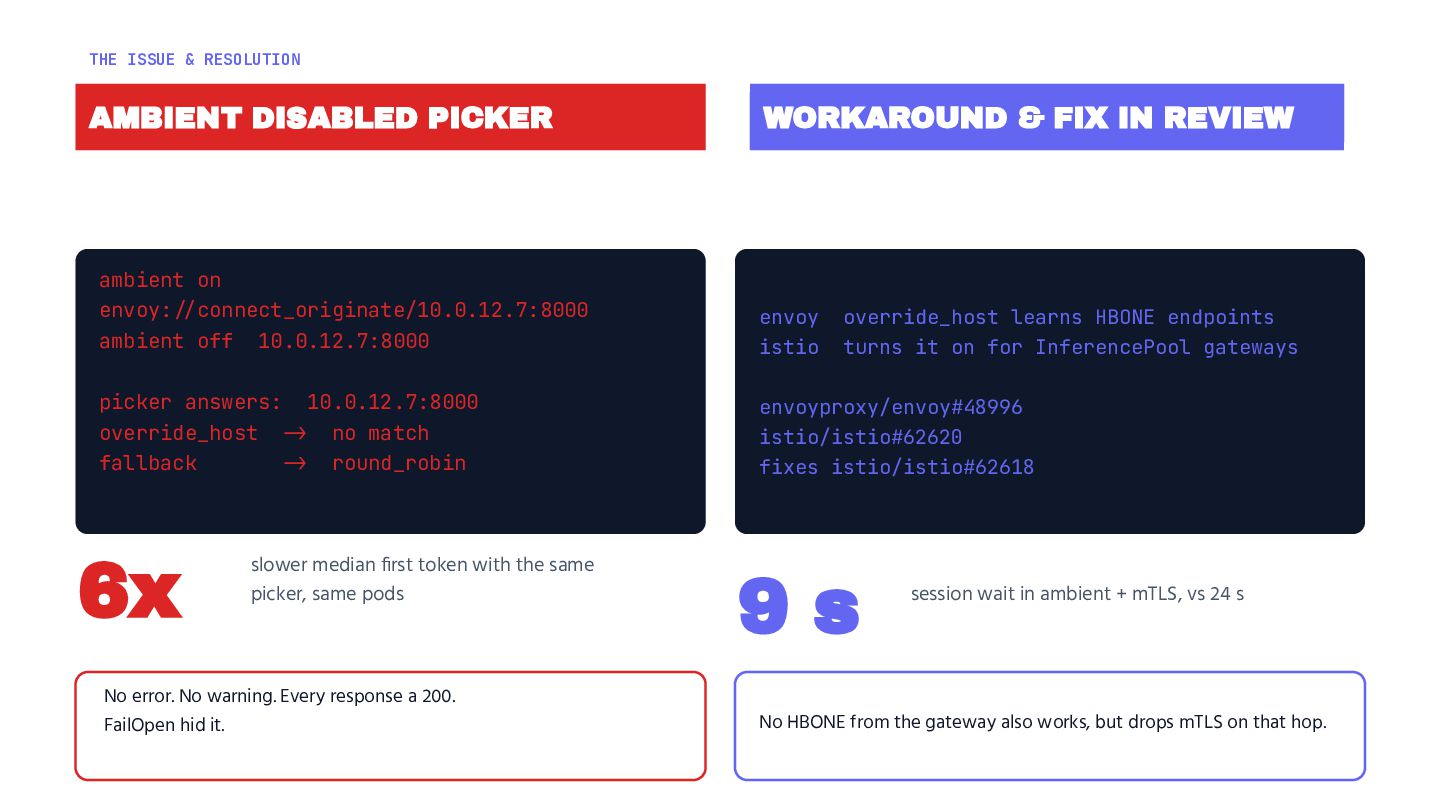
  8. THE ISSUE & RESOLUTION AMBIENT DISABLED PICKER WORKAROUND & FIX

    IN REVIEW ambient on envoy:-/connect_originate/10.0.12.7:8000 ambient off 10.0.12.7:8000 envoy istio picker answers: 10.0.12.7:8000 override_host -> no match fallback -> round_robin 6x slower median first token with the same picker, same pods No error. No warning. Every response a 200. FailOpen hid it. override_host learns HBONE endpoints turns it on for InferencePool gateways envoyproxy/envoy#48996 istio/istio#62620 fixes istio/istio#62618 9s session wait in ambient + mTLS, vs 24 s No HBONE from the gateway also works, but drops mTLS on that hop.
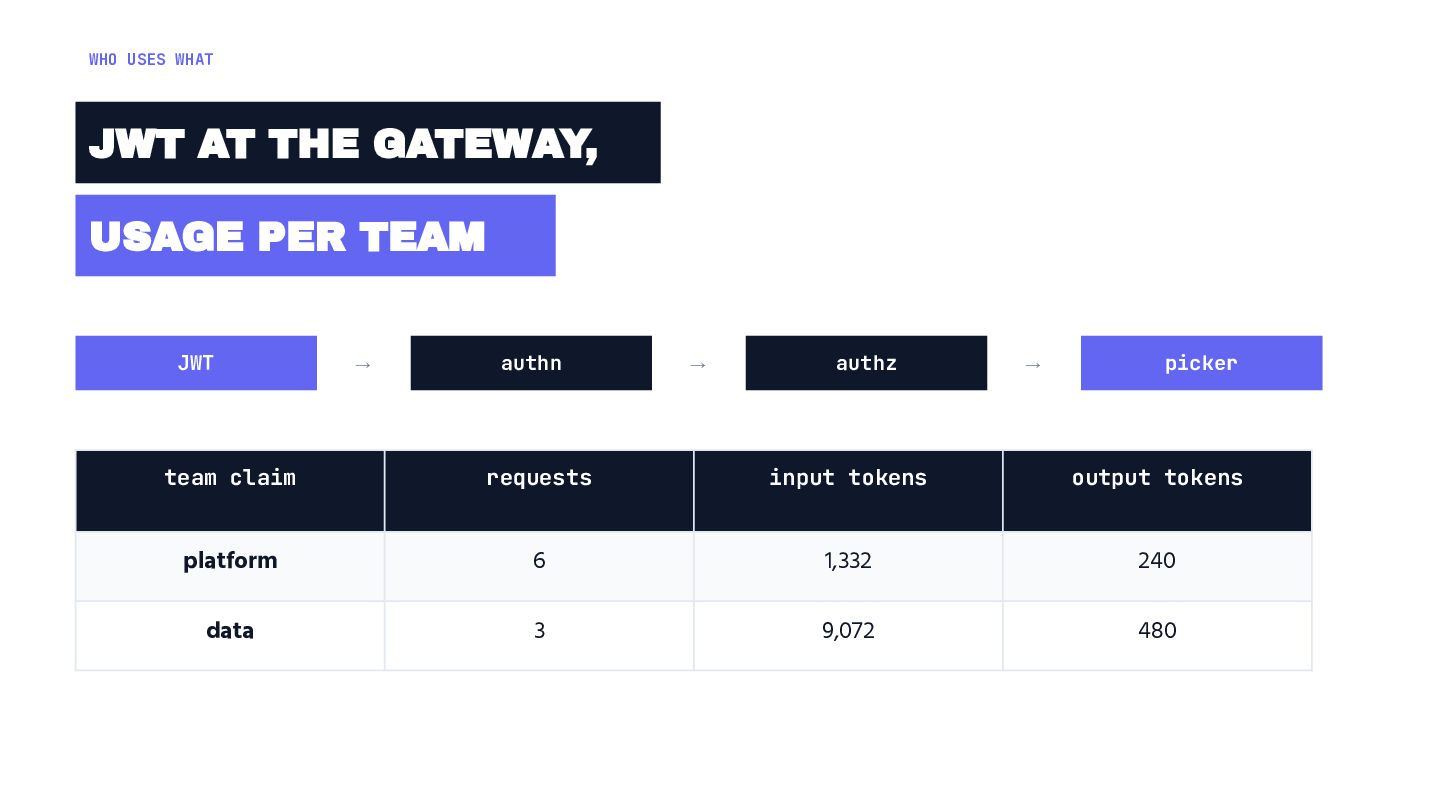
  9. WHO USES WHAT JWT AT THE GATEWAY, USAGE PER TEAM

    JWT → authn → authz → picker team claim requests input tokens output tokens platform 6 1,332 240 data 3 9,072 480
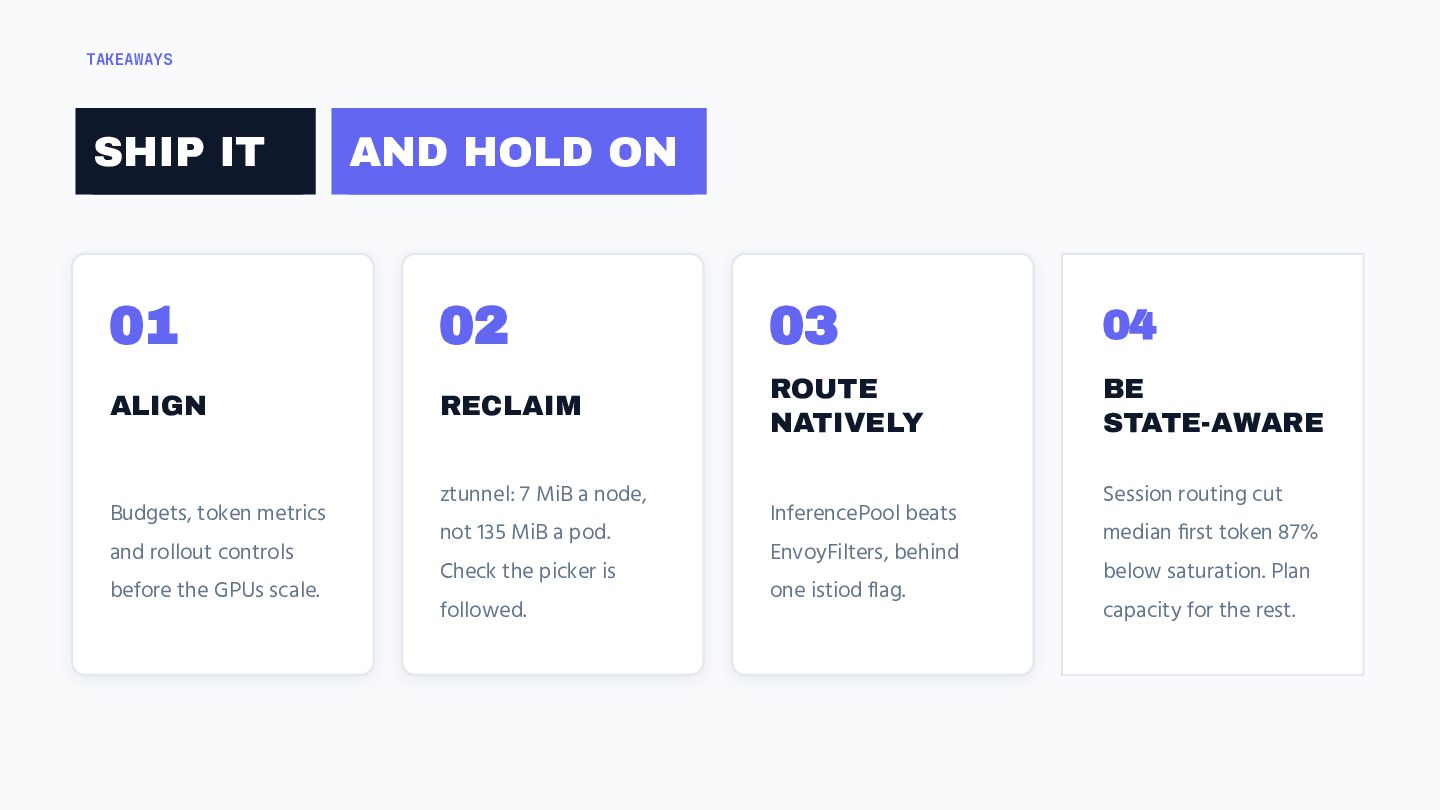
  10. TAKEAWAYS SHIP IT AND HOLD ON 01 02 03 04

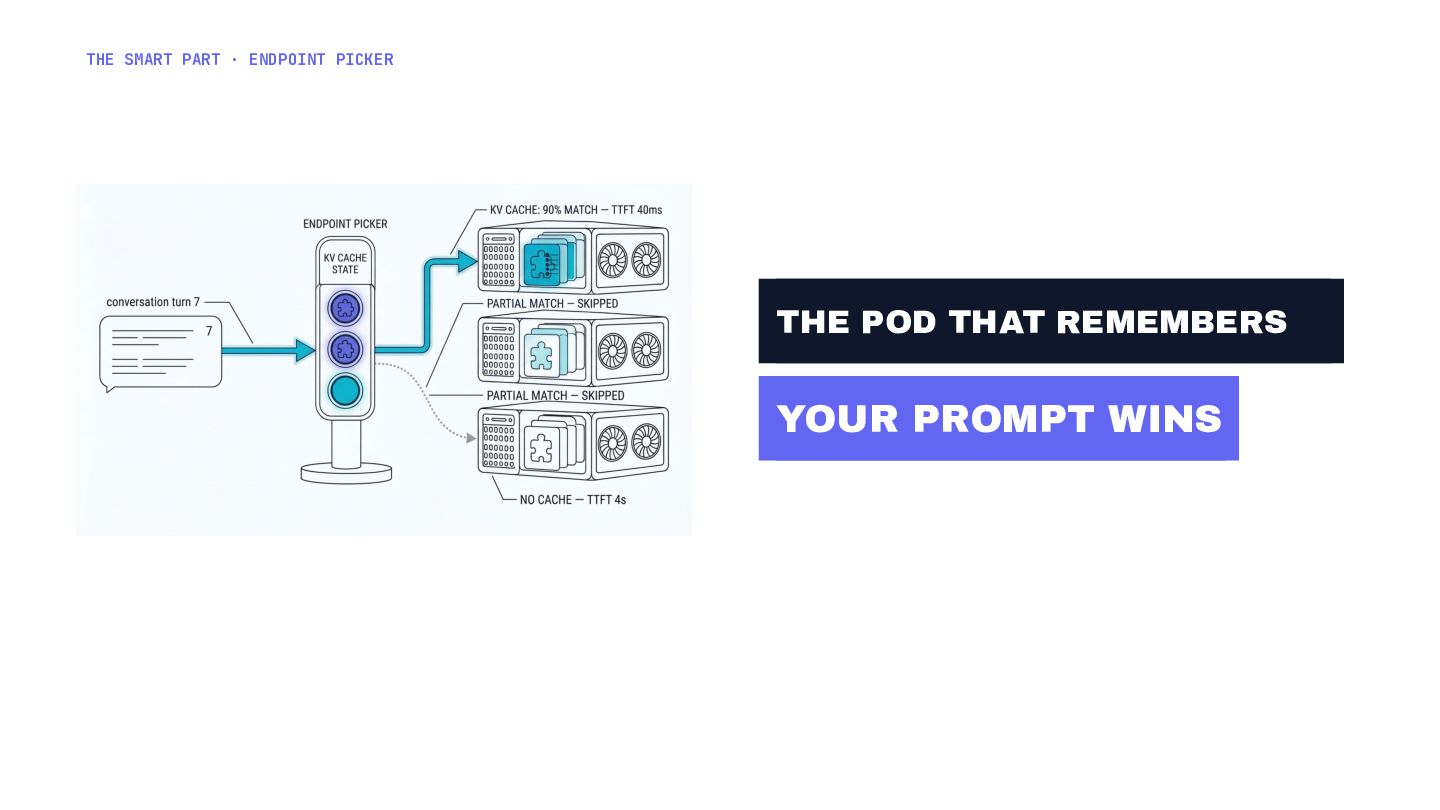
    ALIGN RECLAIM ROUTE NATIVELY BE STATE-AWARE Budgets, token metrics and rollout controls before the GPUs scale. ztunnel: 7 MiB a node, not 135 MiB a pod. Check the picker is followed. InferencePool beats EnvoyFilters, behind one istiod flag. Session routing cut median first token 87% below saturation. Plan capacity for the rest.
  11. ISTIO DAY · KUBECON + CLOUDNATIVECON NA 2026 THANK YOU

    Scan QR code for feedback, Link to Slides and Resources

More Decks by Hannah Olukoye

Other Decks in Technology