Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Database Integration to Improve Accessibility t...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Tazro Inutano Ohta
July 04, 2014
Science
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Database Integration to Improve Accessibility to Public High-throughput Sequencing Data
A Presentation at National Institute of Genetics, Japan Retreat 2014
Tazro Inutano Ohta
July 04, 2014
More Decks by Tazro Inutano Ohta
See All by Tazro Inutano Ohta
Yevis: System to support building a workflow registry with automated quality control
inutano
0
160
Standardization of biological sample information database
inutano
0
120
Describe data analysis workflow with workflow languages
inutano
5
6.3k
Container virtualization technologies and workflow languages improve portability and reproducibility of data analysis environment
inutano
3
400
次世代シーケンサーによるメタゲノム解析:桜の花びらに付着した環境DNAを解析する
inutano
0
140
Workflows that run everywhere and where to run them
inutano
0
220
The Sequence Read Archive search system to make use of public high-throughput sequencing data
inutano
0
340
Improve portability of bioinformatics software across HPC and cloud infrastructures
inutano
1
160
Container, Cloud, and HPC
inutano
0
220
Other Decks in Science
See All in Science
AlgorithAlgorihms for Decision Making
mickey_kubo
0
170
言葉をはかる:テキストマイニング入門①講義編
satocos135
0
270
[Relay webinaire eBIS actu n°16] Conclusion
institutdelelevage
PRO
0
200
[NLP2026 参加報告会] AI for Science まとめ / NLP2026
lychee1223
0
2k
データベース09: 実体関連モデル上の一貫性制約
trycycle
PRO
0
1.9k
Conwayの法則を"ちゃんと"使うために — 原典でConwayは何を言っていたのか
bonotake
10
7.5k
20260410_SystemsThinking
takusamar
1
160
JSAI2026企画セッションKS-14 インタビュー集『⼈⼯知能と哲学と四つの問い』が提起する⼈⼯知能のこれからの課題 趣旨説明 / JSAI2026 Special Session: A Collection of Interviews, “Artificial Intelligence, Philosophy, and Four Questions”
ykiyota
0
470
コーヒー豆様核 (Coffee-bean nuclei) における形態学的サブタイピングと精選・焙煎特性の同定
jagupath
PRO
0
210
機械学習 - K近傍法 & 機械学習のお作法
trycycle
PRO
1
1.7k
生成AIが科学とRAにもたらしていること:メタサイエンスの視点から
rmaruy
0
140
[Relay webinaire eBIS actu n°16] Sélection pour la vitalité des jeunes bovins allaitants et laitiers
institutdelelevage
PRO
0
270
Featured
See All Featured
We Analyzed 250 Million AI Search Results: Here's What I Found
joshbly
2
2k
Claude Code のすすめ
schroneko
67
230k
Jess Joyce - The Pitfalls of Following Frameworks
techseoconnect
PRO
1
450
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Producing Creativity
orderedlist
PRO
348
41k
SEO for Brand Visibility & Recognition
aleyda
0
4.8k
The Power of CSS Pseudo Elements
geoffreycrofte
82
6.6k
What Being in a Rock Band Can Teach Us About Real World SEO
427marketing
0
1.1k
Context Engineering - Making Every Token Count
addyosmani
9
1.2k
Prompt Engineering for Job Search
mfonobong
0
520
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
730
Public Speaking Without Barfing On Your Shoes - THAT 2023
reverentgeek
1
600
Transcript
Database Integration to Improve Accessibility to High-Throughput Seq Data
TAZRO OHTA @inutano
None
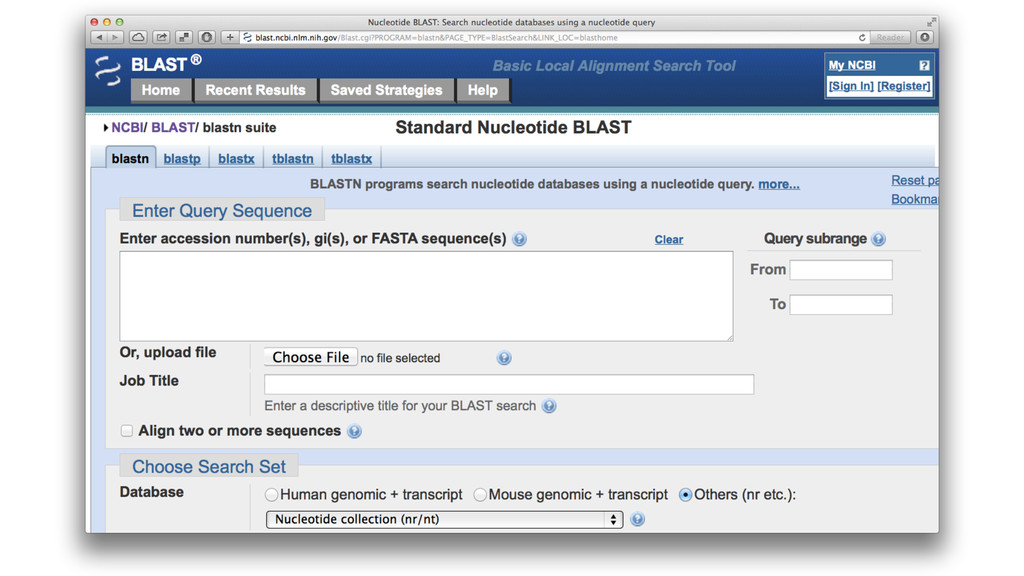
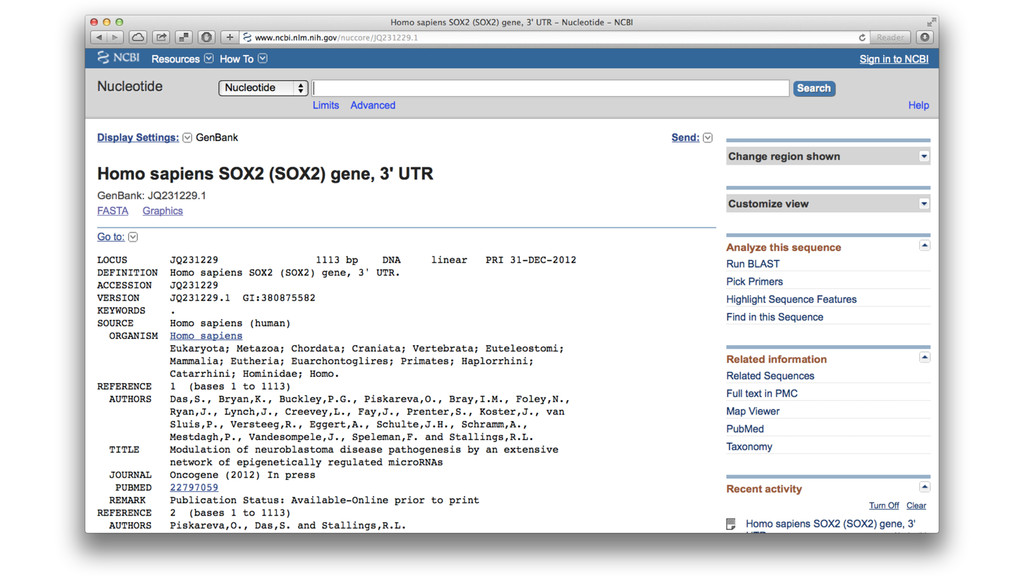
What do you imagine with a term “Database”?
None
None
None
Knowledge Scientific data Experimental data
Knowledge base Database Raw Data repository
Knowledge base Database Raw Data repository
What kind of data? Next-generation is already out there…
We all need Raw data repo for NGS
We’ve already seen WHY WE NEED
None
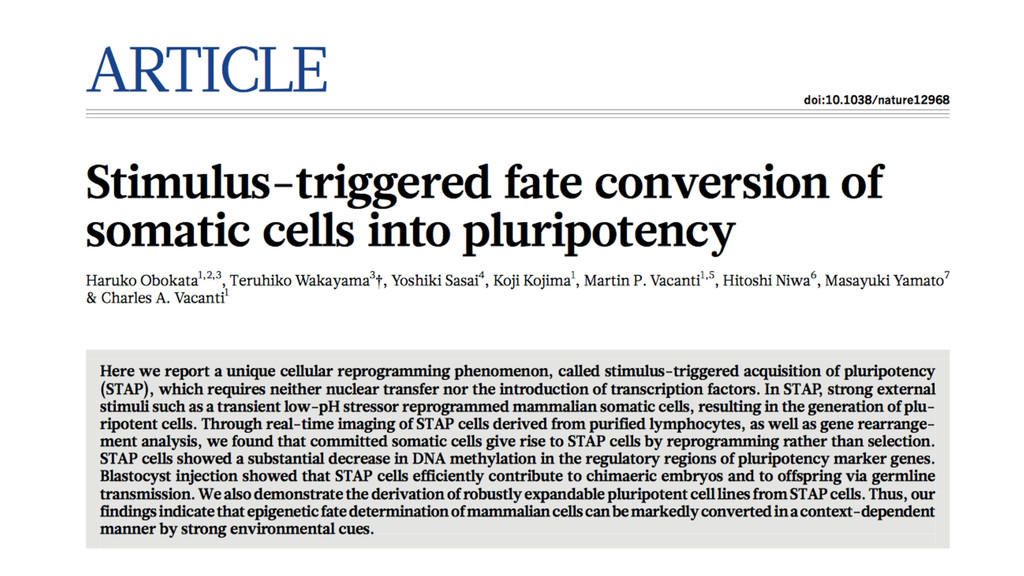
Reproducibility is what makes science fair.
2 things required for data repository is…
1: Reliability Data should be archived correctly, with explicit metadata
2: Accessibility Data should be able to be accessed by anyone, without special trick
1: Reliability needs curation Data should be archived correctly, with
explicit metadata 2: Accessibility needs good interface Data should be able to be accessed by anyone, without special trick
1: Reliability needs curation Data should be archived correctly, with
explicit metadata 2: Accessibility needs good interface Data should be able to be accessed by anyone, without special trick
1: Reliability needs curation Data should be archived correctly, with
explicit metadata 2: Accessibility needs good interface Data should be able to be accessed by anyone, without special trick
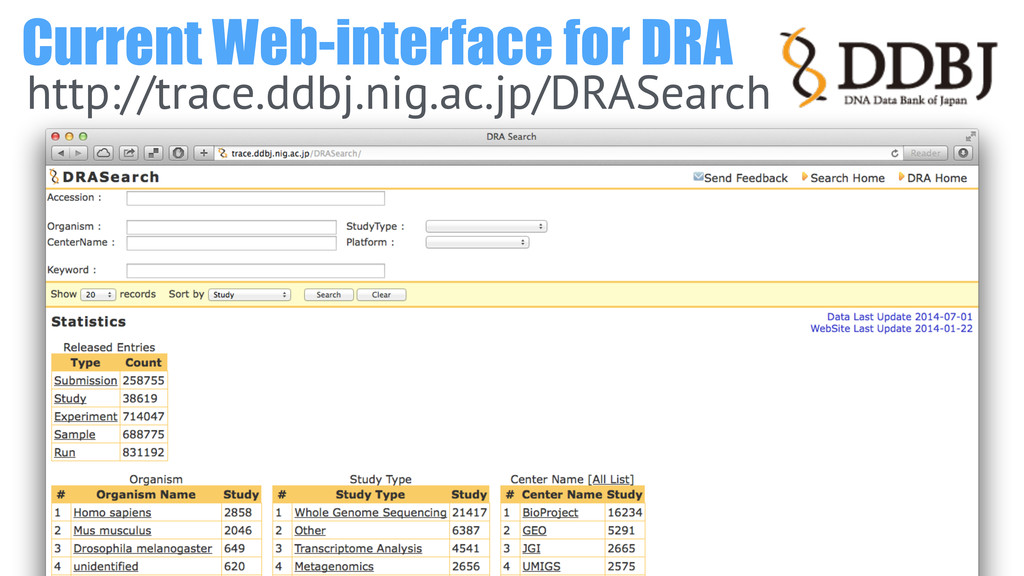
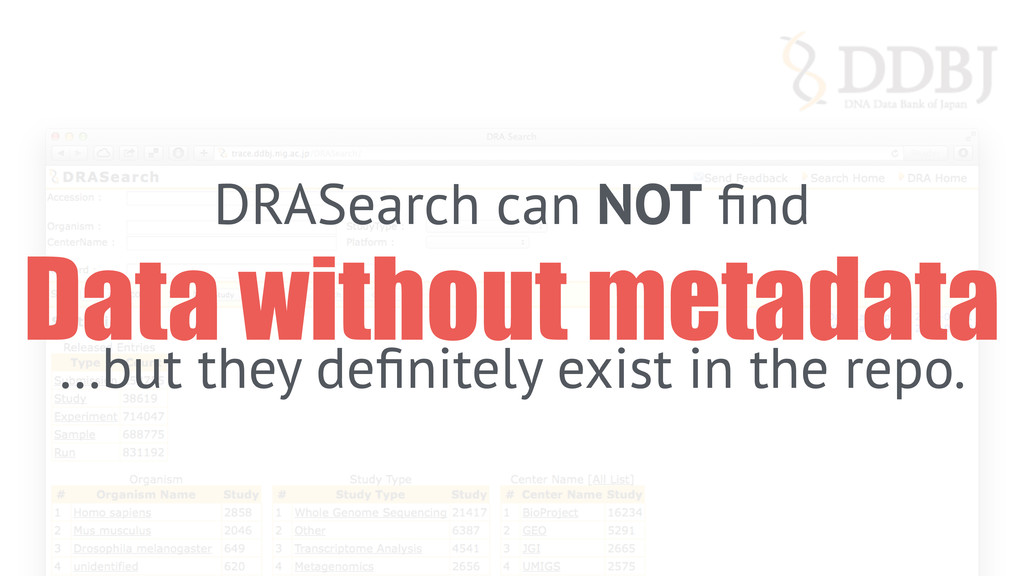
Current Web-interface for DRA http://trace.ddbj.nig.ac.jp/DRASearch
Good: Simple, Fast, and no bugs (!) Challenge: Lack of
metadata caused “NOT FOUND”
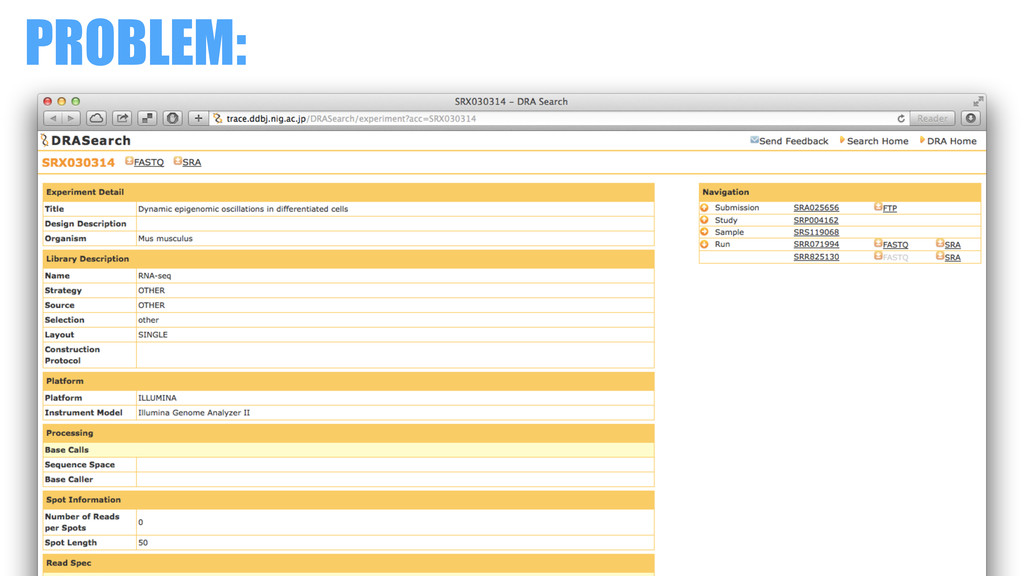
PROBLEM:
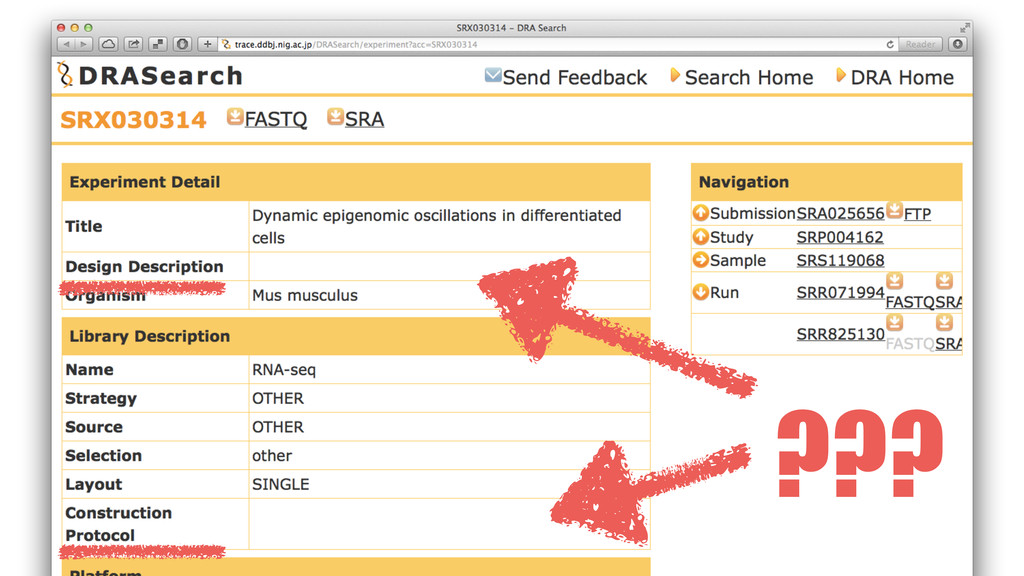
???
DRASearch can NOT find Data without metadata …but they definitely
exist in the repo.
Too many to ask submitters; then we implemented a system
to make metadata rich enough
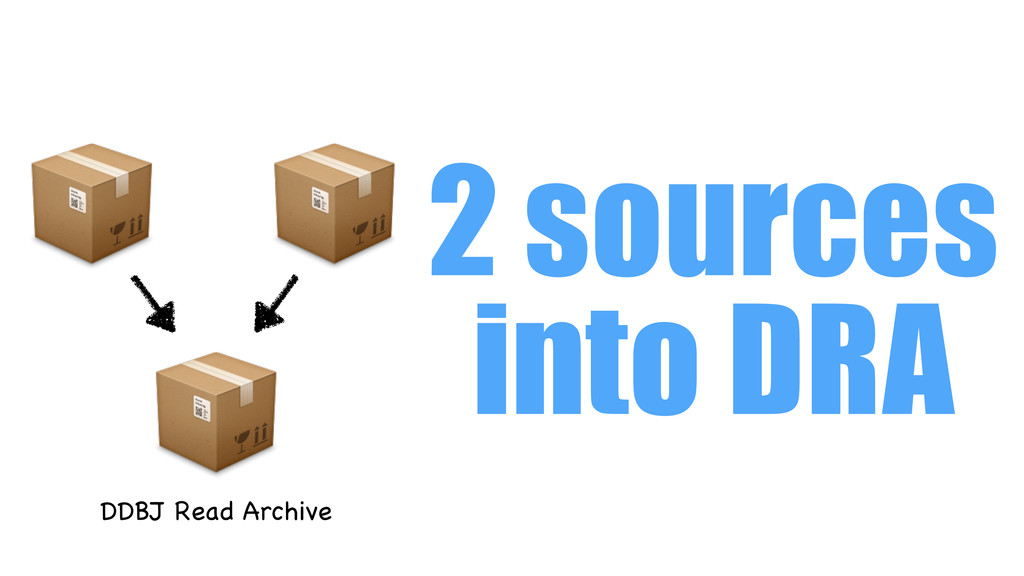
2 sources into DRA DDBJ Read Archive
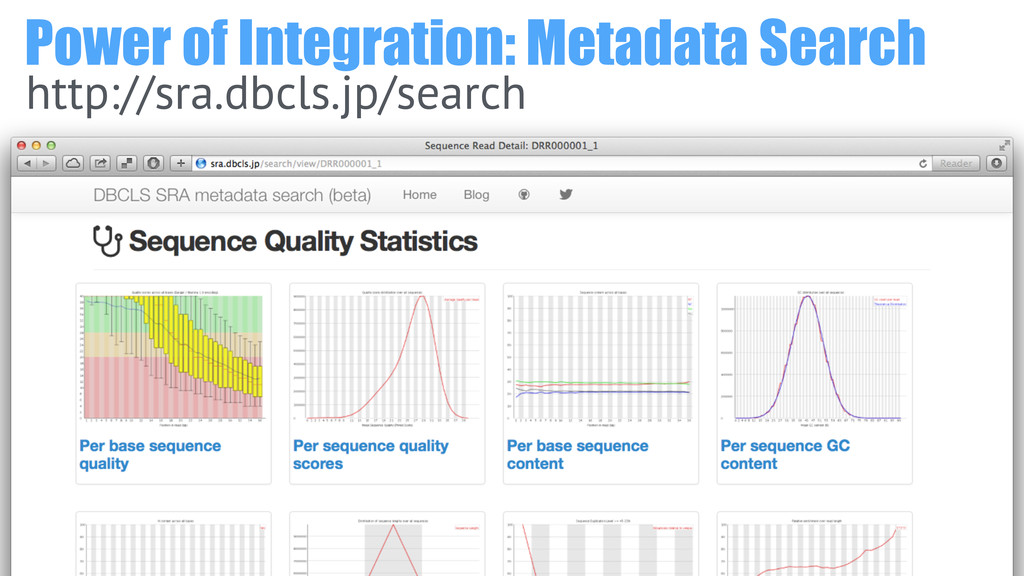
Publications can have details of seq process, Seq Read Quality
can be a source of data quality. DDBJ Read Archive PubMed PMC Extracted Read Quality
And then: integration enables to implement Efficient Data Search
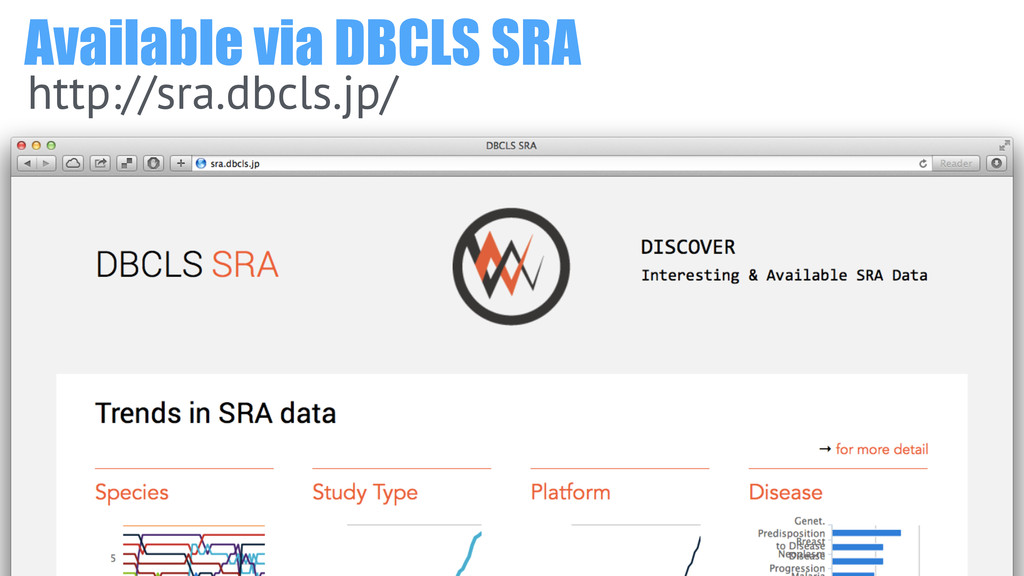
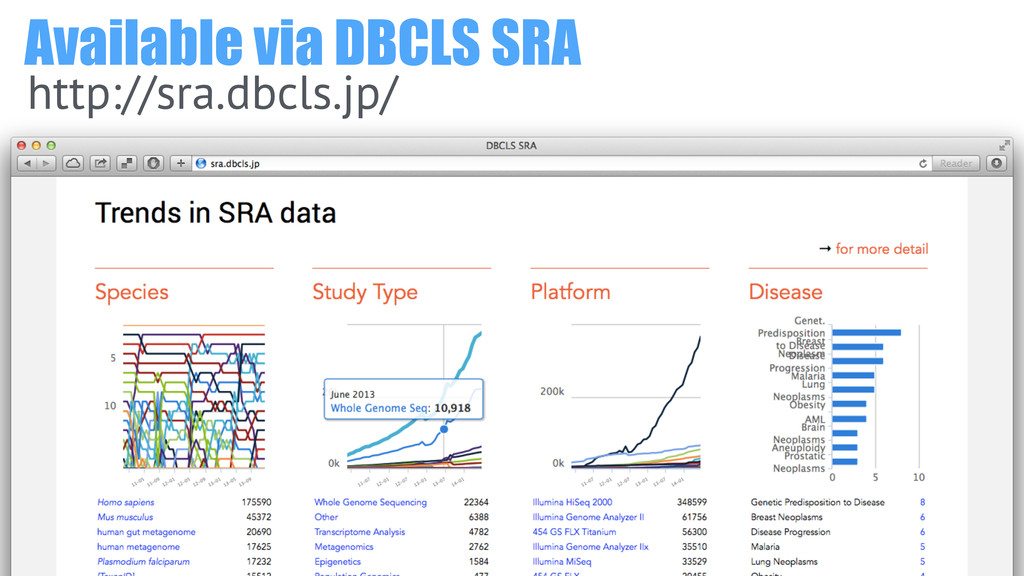
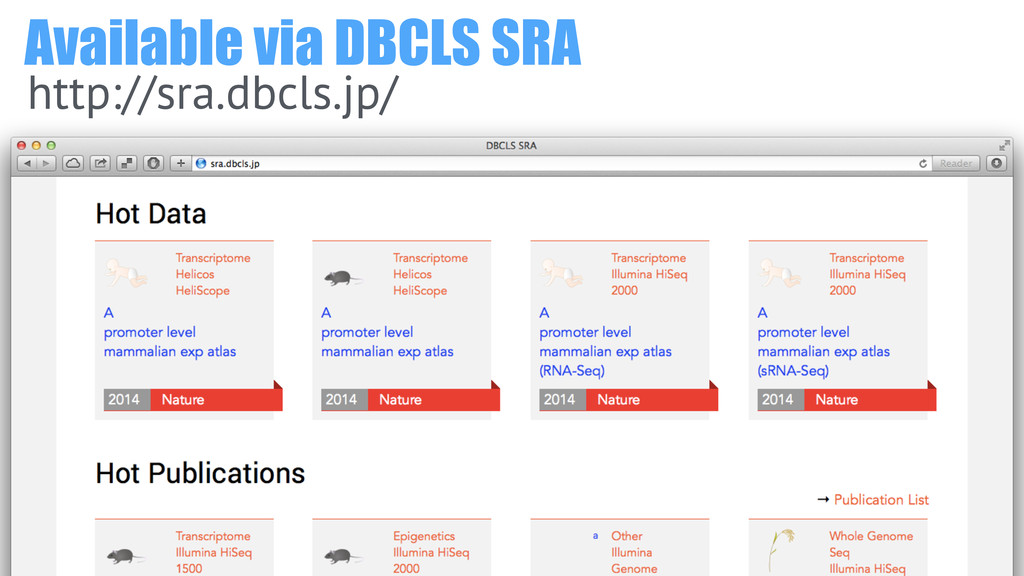
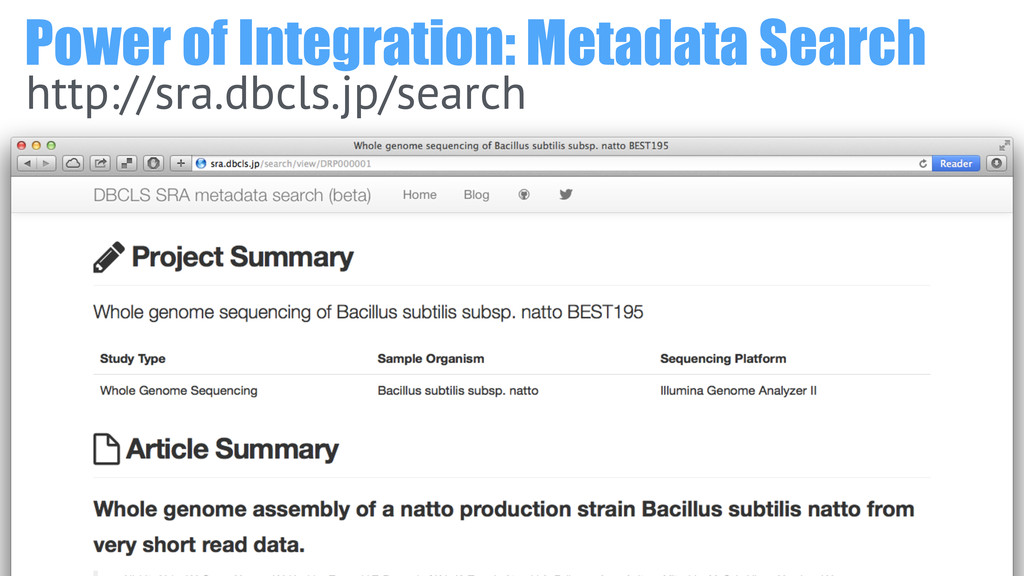
Available via DBCLS SRA http://sra.dbcls.jp/
Available via DBCLS SRA http://sra.dbcls.jp/
Available via DBCLS SRA http://sra.dbcls.jp/
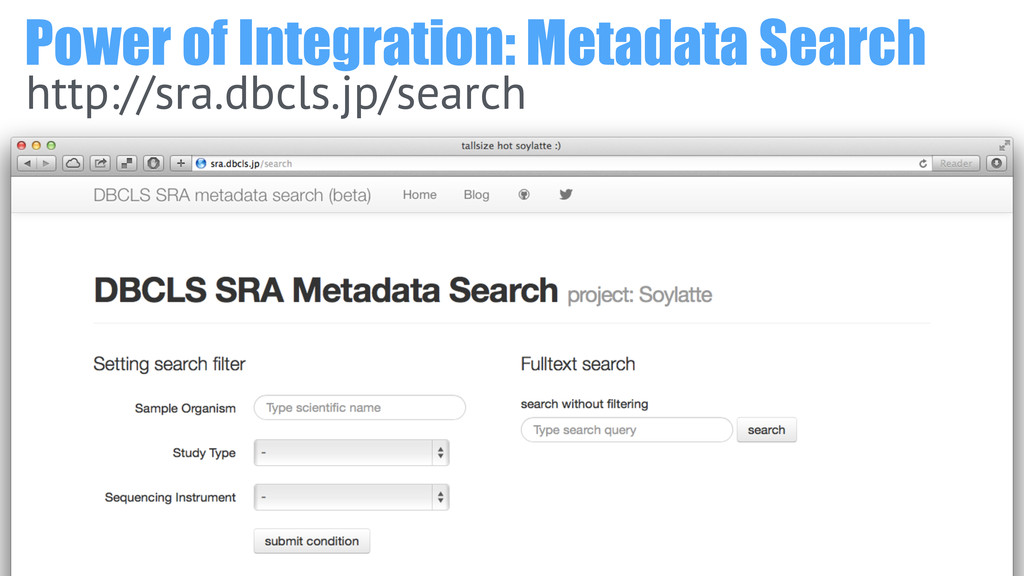
Power of Integration: Metadata Search http://sra.dbcls.jp/search
Power of Integration: Metadata Search http://sra.dbcls.jp/search
Power of Integration: Metadata Search http://sra.dbcls.jp/search
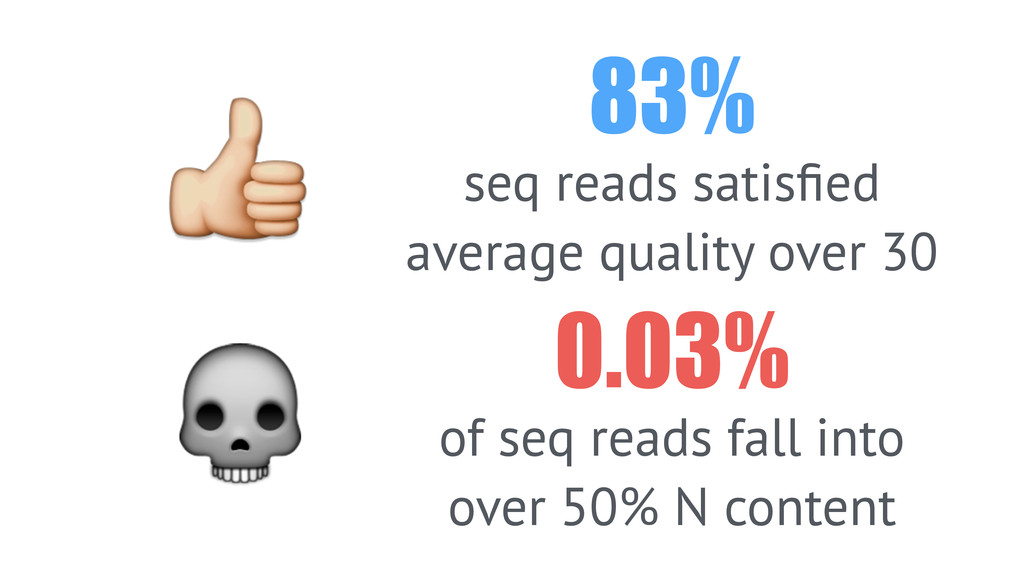
83% seq reads satisfied average quality over 30 0.03% of
seq reads fall into over 50% N content
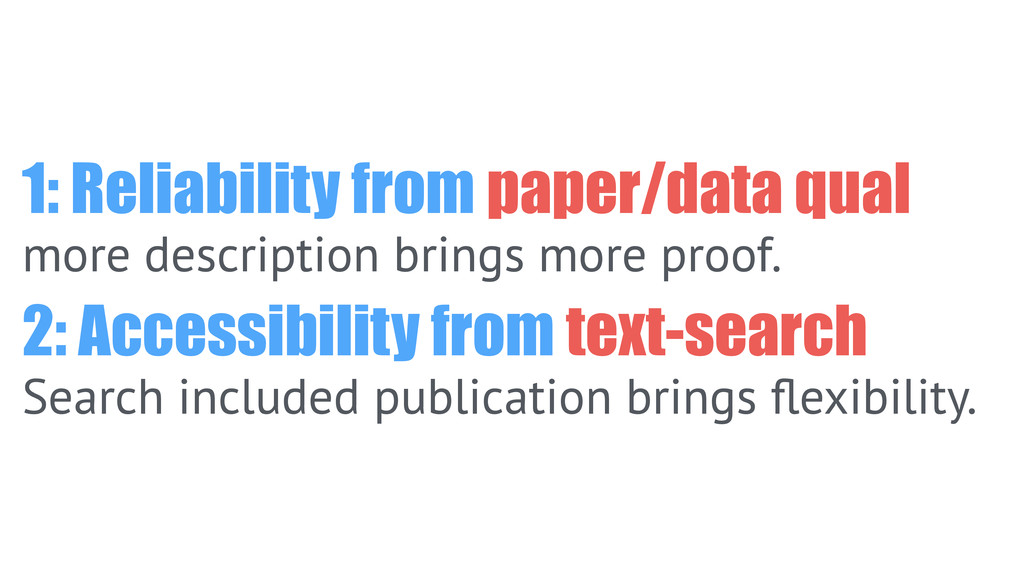
1: Reliability from paper/data qual more description brings more proof.
2: Accessibility from text-search Search included publication brings flexibility.
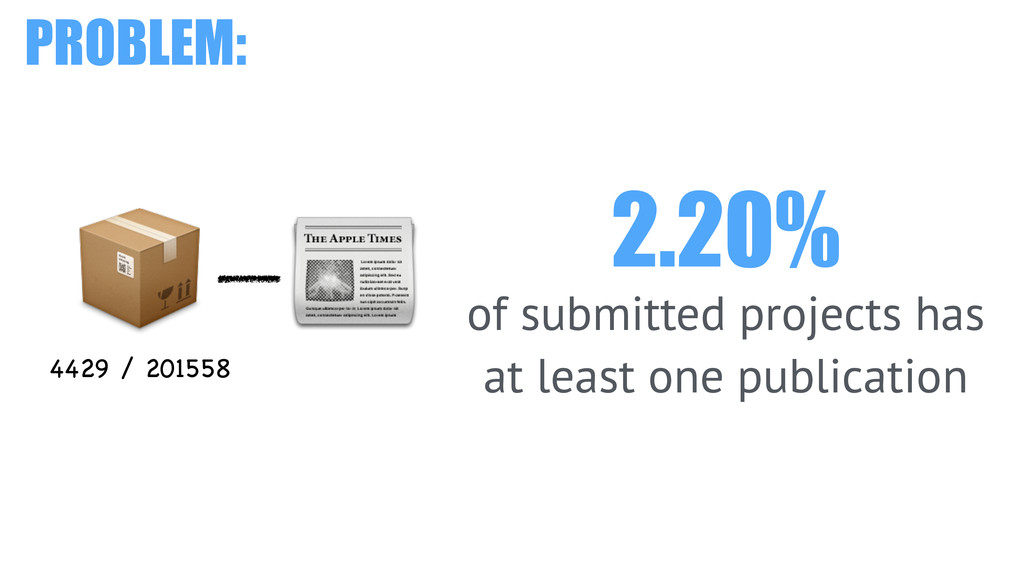
2.20% of submitted projects has at least one publication 4429
/ 201558 PROBLEM:
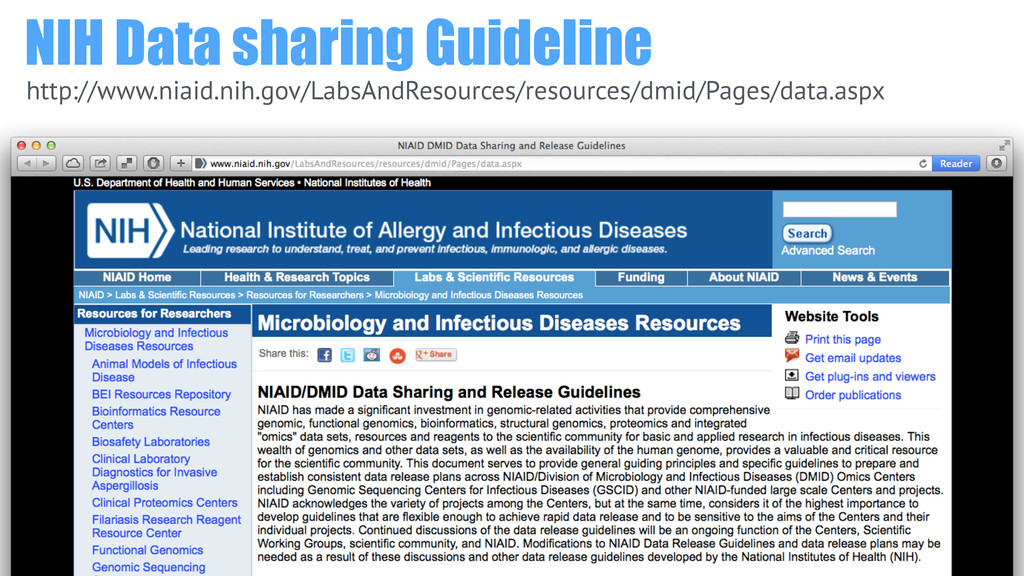
NIH Data sharing Guideline http://www.niaid.nih.gov/LabsAndResources/resources/dmid/Pages/data.aspx
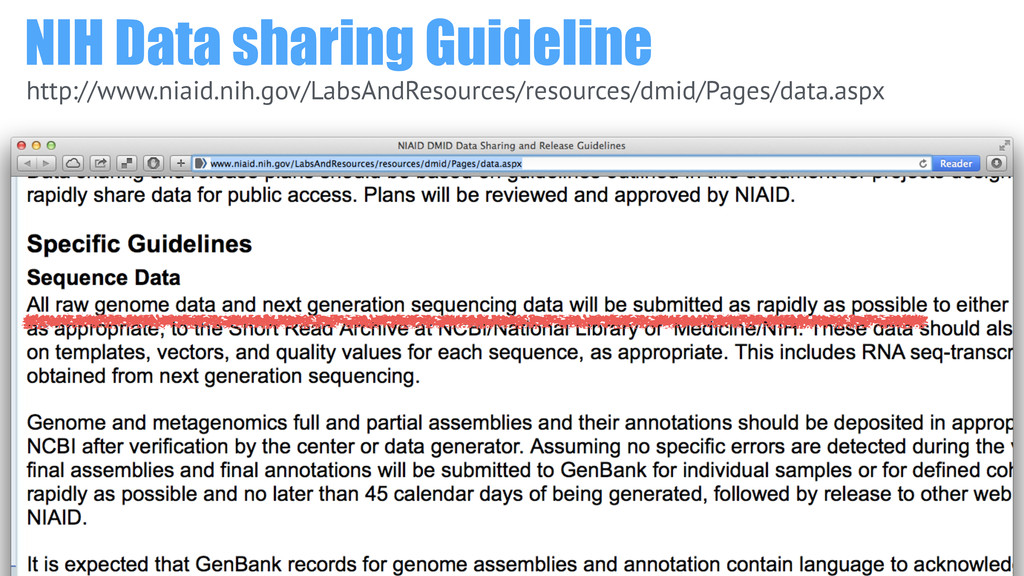
NIH Data sharing Guideline http://www.niaid.nih.gov/LabsAndResources/resources/dmid/Pages/data.aspx
What is Next-step to carry on?
1: Beyond Raw Data Archive is going to handle alignment
data. 2: Analysis Reproducibility Public repo for analysis pipeline is required.
1: Beyond Raw Data Archive is going to handle alignment
data. 2: Analysis Reproducibility Public repo for analysis pipeline is required.
Database is for Biologists not for developers.
Thank you!
[email protected]
http://speakerdeck.com/inutano


 inutano
 mickey_kubo
 satocos135
 institutdelelevage
 lychee1223
 trycycle
 bonotake
 takusamar
 ykiyota
 jagupath
 rmaruy
 joshbly
 schroneko
 techseoconnect
 aarron
 orderedlist
 aleyda
 geoffreycrofte
 427marketing
 addyosmani
 mfonobong
 baasie
 reverentgeek