Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[RSJ26] AnoleVLA: Lightweight Vision-Language-A...
Search
Semantic Machine Intelligence Lab., Keio Univ.
PRO
August 29, 2026
Technology
140
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
Semantic Machine Intelligence Lab., Keio Univ.
PRO
August 29, 2026
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
200
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
170
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
220
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
180
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
210
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
49
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
290
[Journal club] FlashVID: Efficient Video Large Language Models via Training-free Tree-based Spatiotemporal Token Merging
keio_smilab
PRO
0
38
[Journal club] DyCoke: Dynamic Compression of Tokens for Fast Video Large Language Models
keio_smilab
PRO
1
78
Other Decks in Technology
See All in Technology
Omarchy Quattro の日本語設定周り
simosako
2
180
range over func 2年間の軌跡 Issue #56413 はGoのエコシステムをどう変えたか
ryujicre8ive
0
190
OpenTelemetryのメトリクスをCloudWatchに送ってPromQLで見てみた
ota1022
0
150
越境するなら専門用語を使うな高校校歌 / If you wanna cross border, you shouldn't use jargon
vtryo
0
140
20260912_スクフェス三河
kgnkhkr
0
380
山手線を徒歩で一周してわかった、 位置情報アプリは「足」が最強のデバッガー
hinakko
0
160
あるけみー式LTスライド作成術
alchemy1115
1
210
目の前の楽しいが人生を変える - コミュニティの螺旋の歩き方と楽しむコツ / change your life
soudai
PRO
4
610
AIに任せた品質は、誰が見立てるのか - AI時代のテストマネジメント
nakanao
0
200
事業課題から技術的負債に向き合う
sansantech
PRO
2
1.8k
生成AIエージェントを用いた、 手動テスト手順書から自動テストへの 変換手法の検討
magicpod
0
160
すぐできる衛星通信対応 あとは山奥に行くだけ
tatetate55
0
130
Featured
See All Featured
AI: The stuff that nobody shows you
jnunemaker
PRO
10
1k
Product Roadmaps are Hard
iamctodd
55
13k
Testing 201, or: Great Expectations
jmmastey
46
8.3k
Context Engineering - Making Every Token Count
addyosmani
9
1.1k
Conquering PDFs: document understanding beyond plain text
inesmontani
PRO
4
3.1k
Claude Code のすすめ
schroneko
67
230k
Impact Scores and Hybrid Strategies: The future of link building
tamaranovitovic
0
440
The Pragmatic Product Professional
lauravandoore
37
7.4k
Getting science done with accelerated Python computing platforms
jacobtomlinson
2
480
How GitHub (no longer) Works
holman
316
150k
Breaking role norms: Why Content Design is so much more than writing copy - Taylor Woolridge
uxyall
1
410
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
670
Transcript
深層状態空間モデルに基づく 軽量VLAによる物体操作 慶應義塾大学 髙木裕輔 神原元就 八島大地 妹尾幸樹 戸倉健登 杉浦孔明
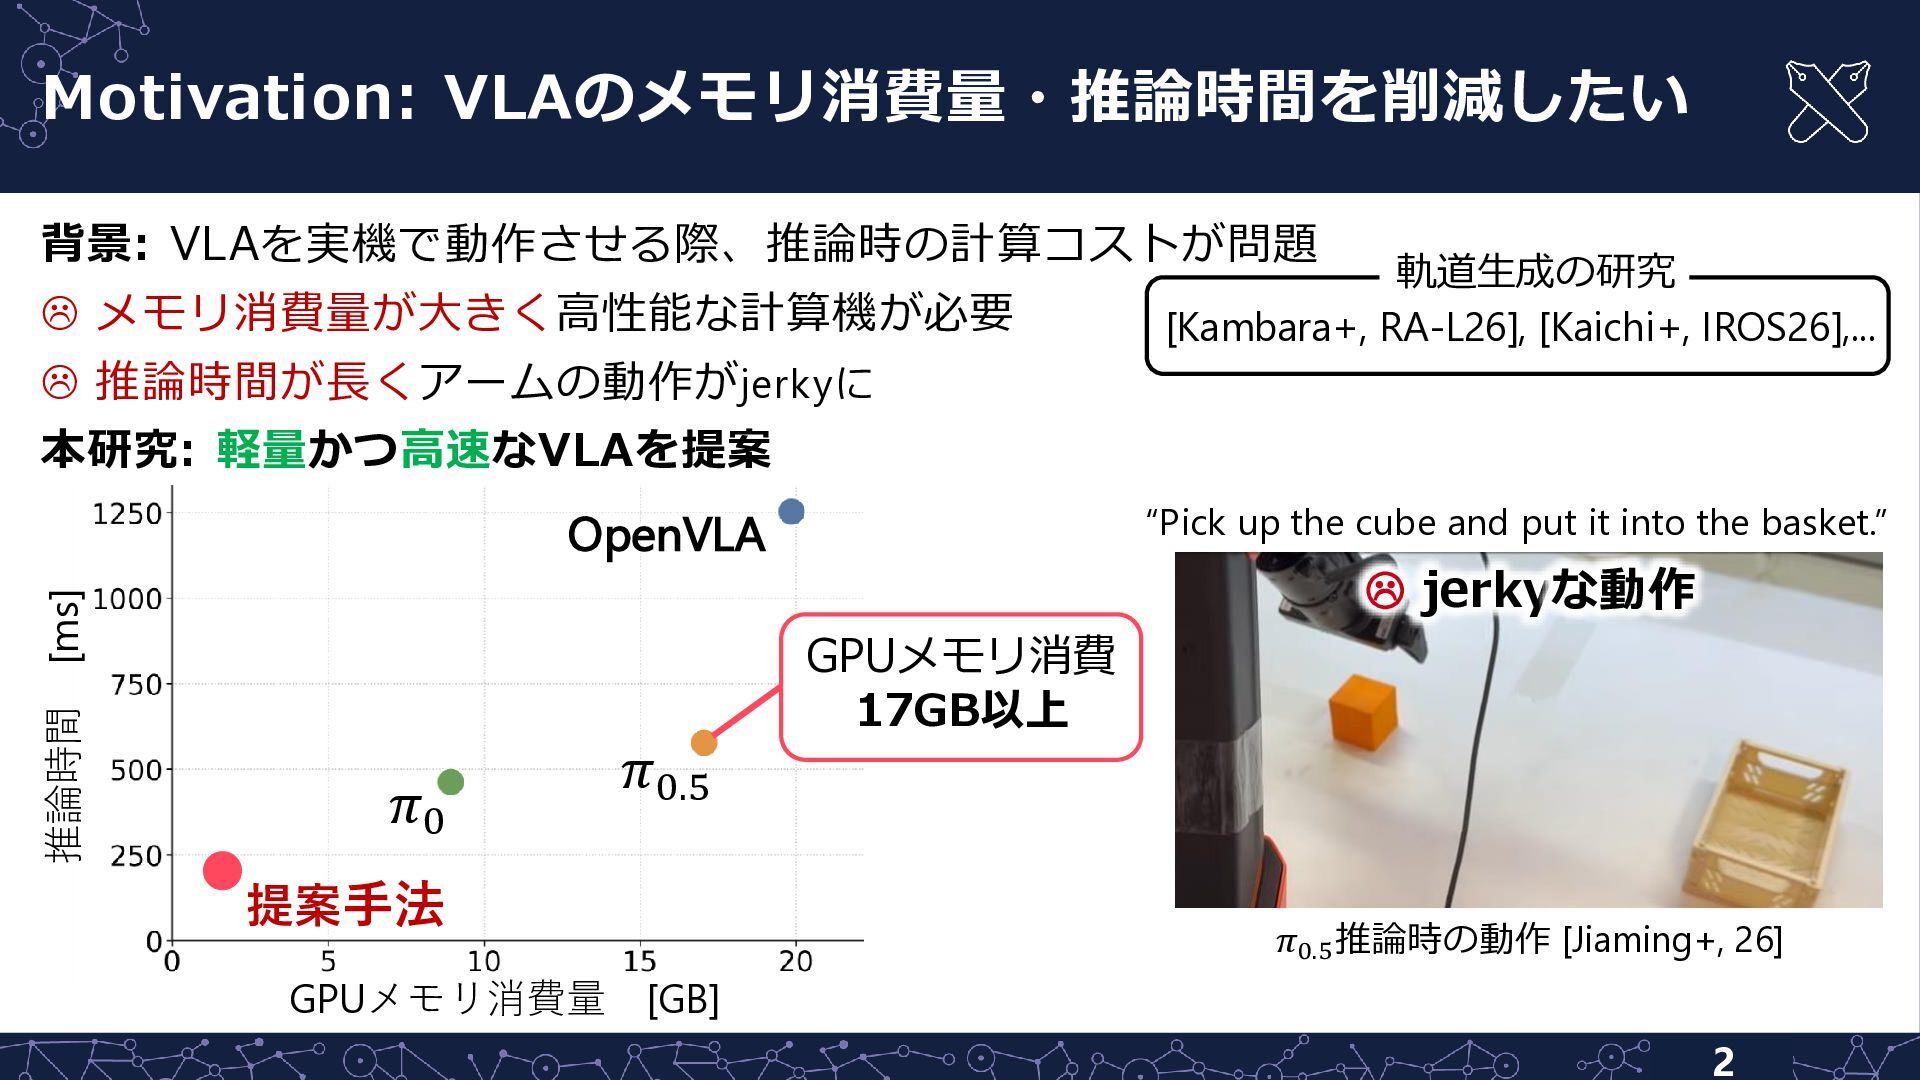
Motivation: VLAのメモリ消費量・推論時間を削減したい 背景: VLAを実機で動作させる際、推論時の計算コストが問題 メモリ消費量が大きく高性能な計算機が必要 軌道生成の研究 [Kambara+, RA-L26], [Kaichi+,
IROS26],... 推論時間が長くアームの動作がjerkyに 本研究: 軽量かつ高速なVLAを提案 “Pick up the cube and put it into the basket.” 推論時間 [ms] OpenVLA jerkyな動作 GPUメモリ消費 17GB以上 𝜋0 𝜋0.5 提案手法 𝜋0.5 推論時の動作 [Jiaming+, 26] GPUメモリ消費量 [GB] 2
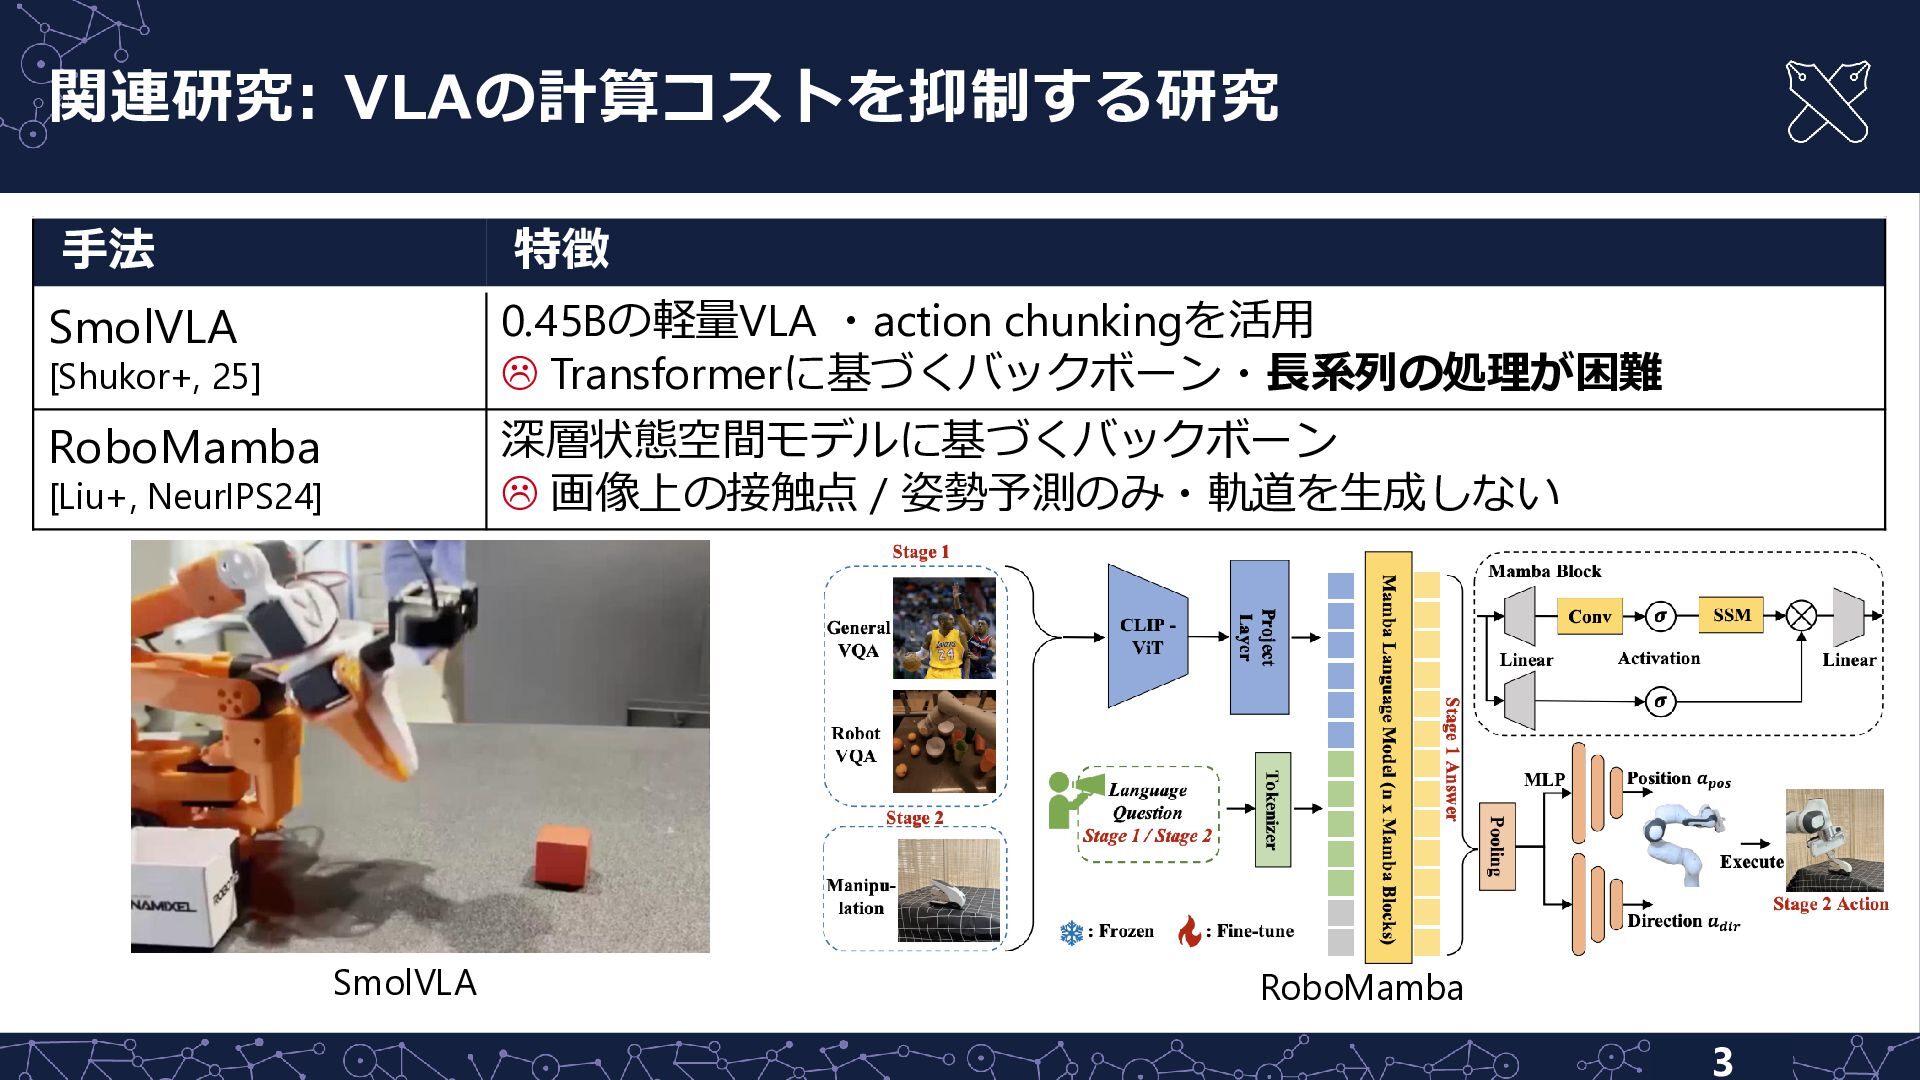
関連研究: VLAの計算コストを抑制する研究 手法 特徴 SmolVLA 0.45Bの軽量VLA ・action chunkingを活用 Transformerに基づくバックボーン・長系列の処理が困難
深層状態空間モデルに基づくバックボーン 画像上の接触点 / 姿勢予測のみ・軌道を生成しない [Shukor+, 25] RoboMamba [Liu+, NeurIPS24] SmolVLA RoboMamba 3
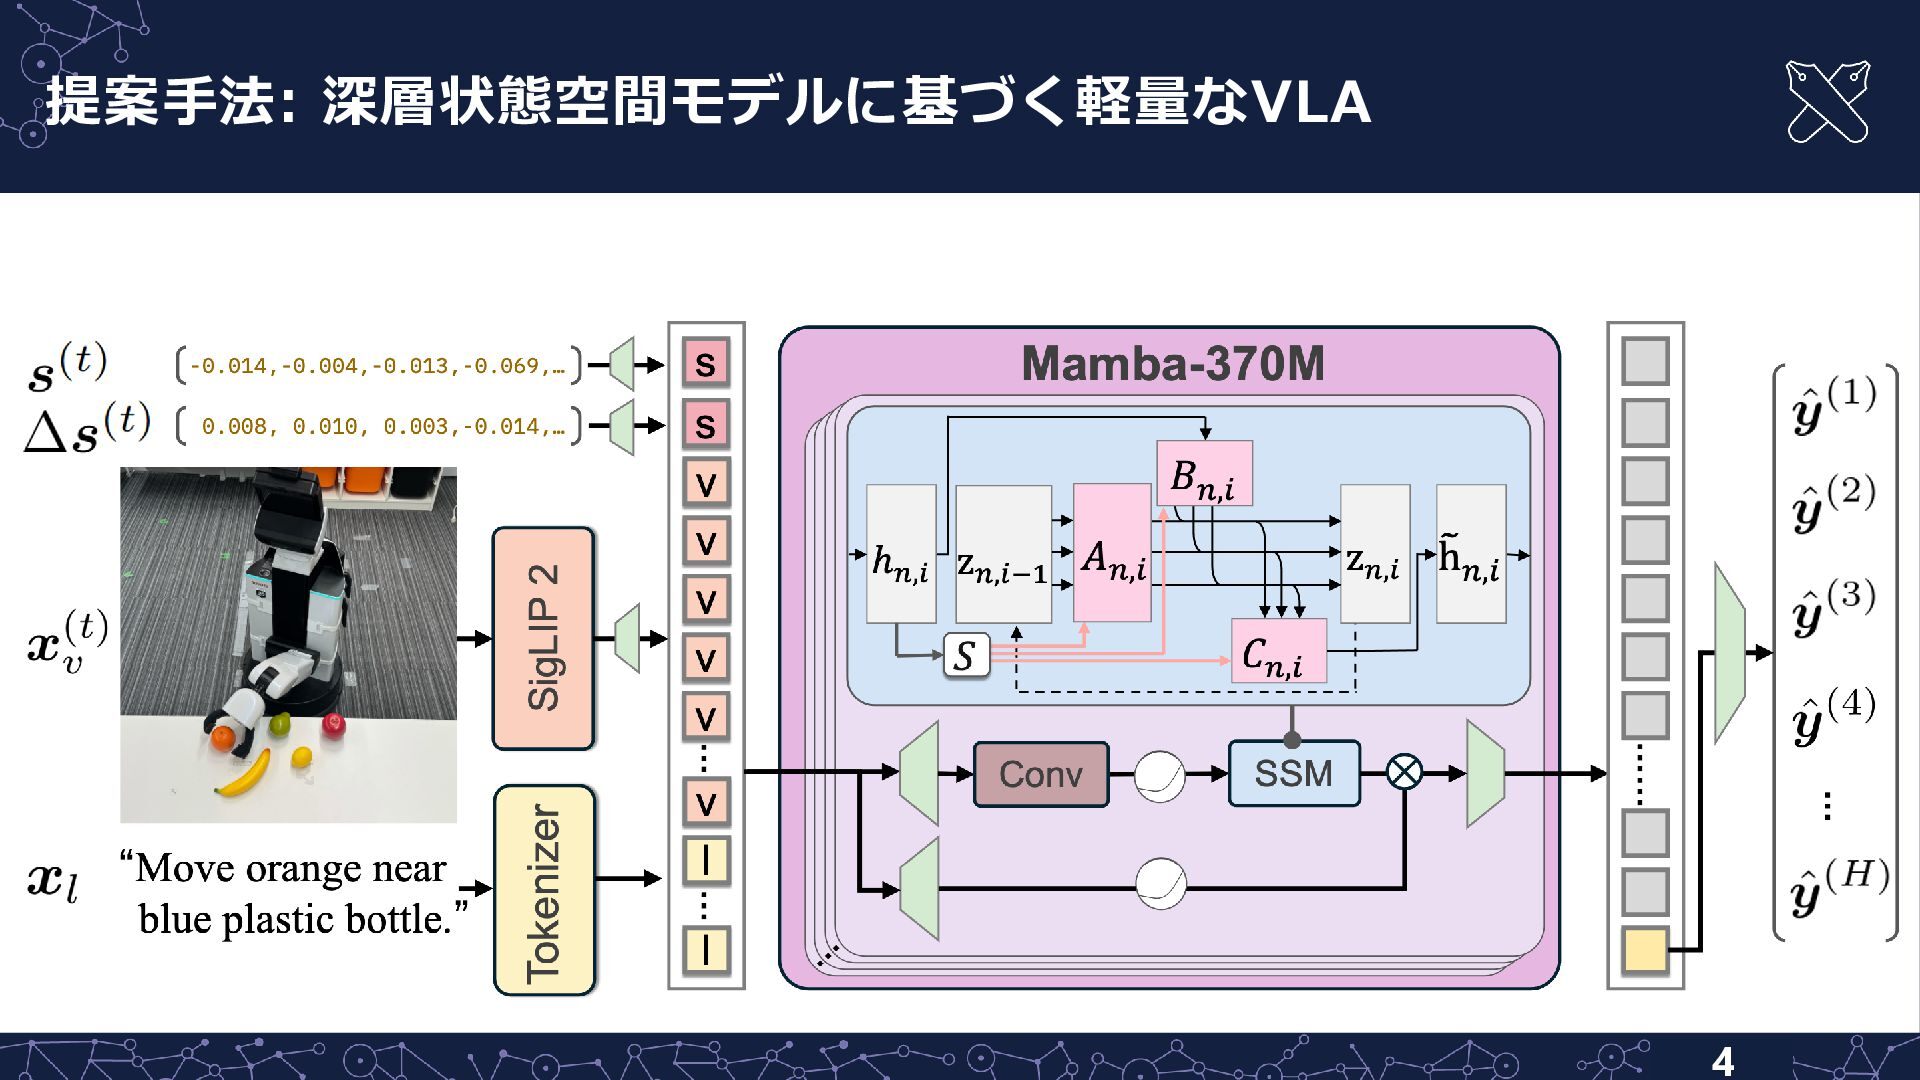
提案手法: 深層状態空間モデルに基づく軽量なVLA 4
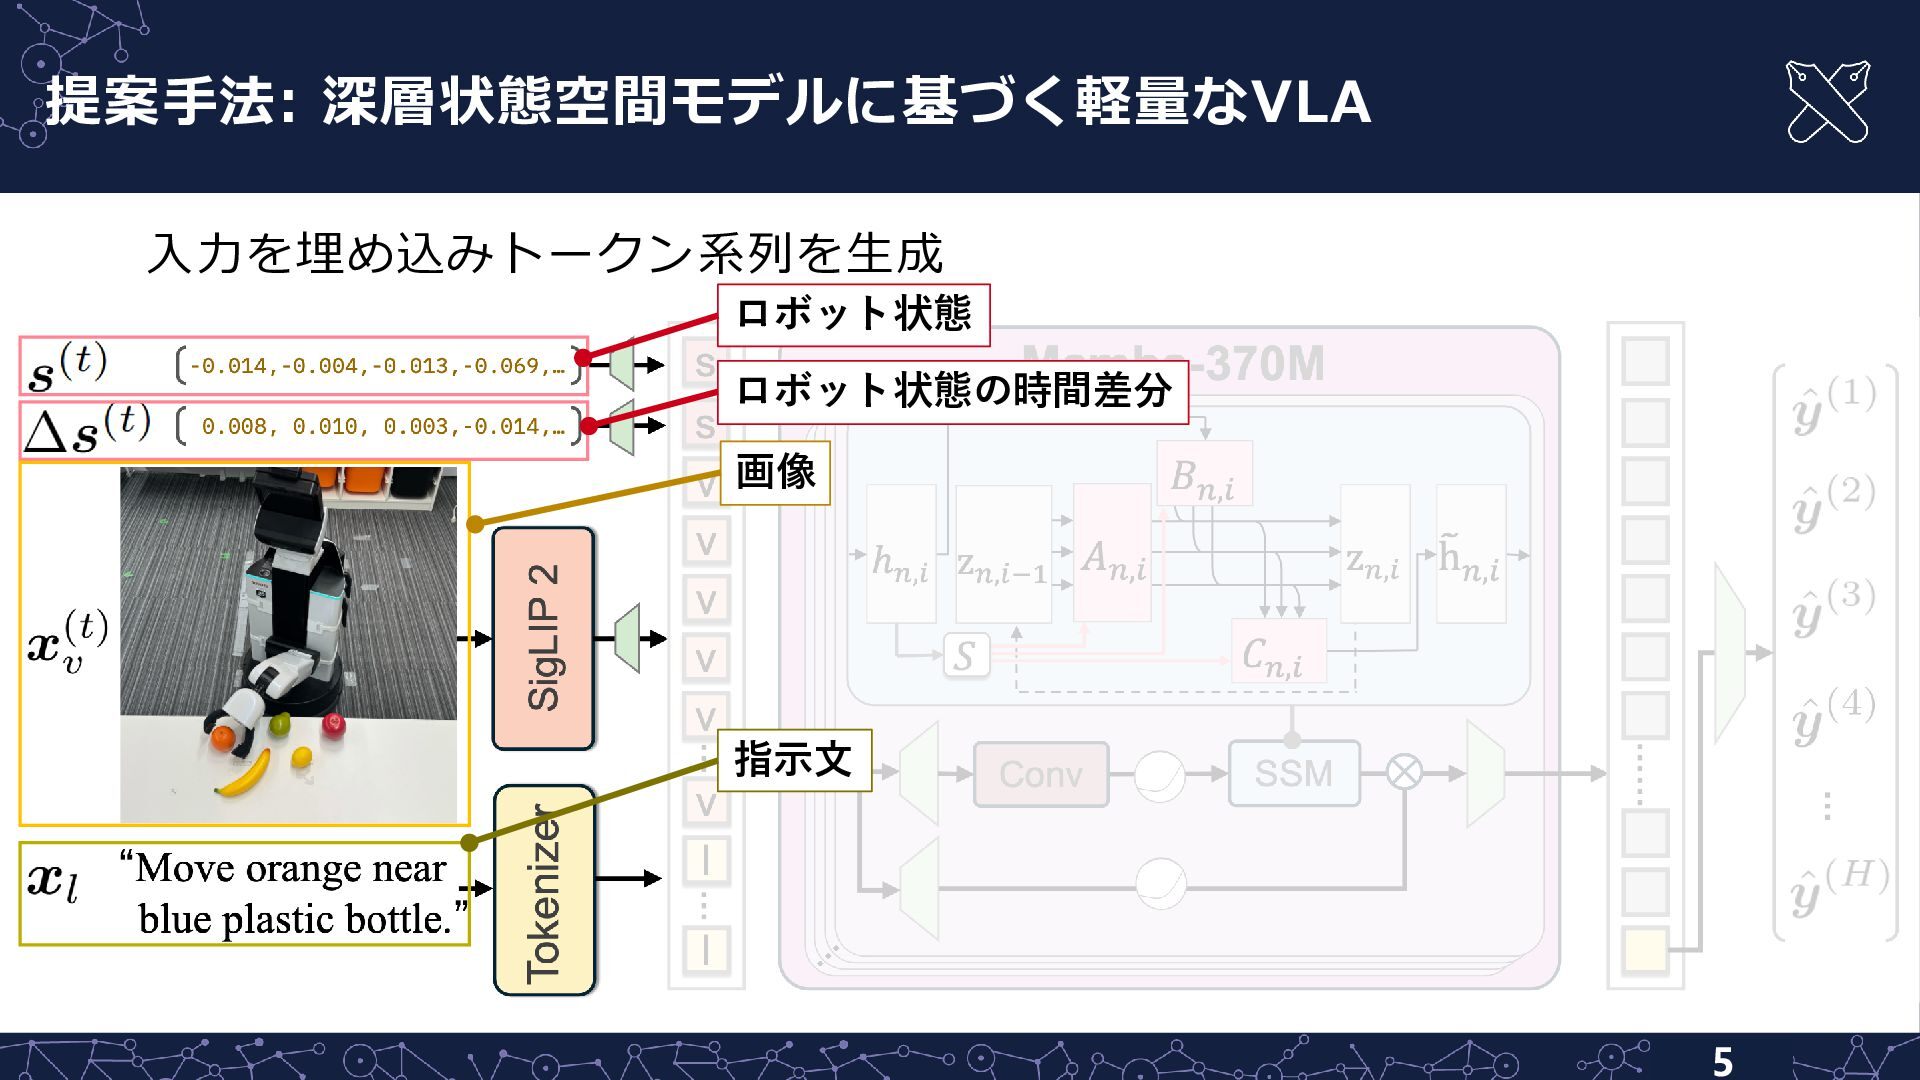
提案手法: 深層状態空間モデルに基づく軽量なVLA 入力を埋め込みトークン系列を生成 ロボット状態 ロボット状態の時間差分 画像 指示文 5
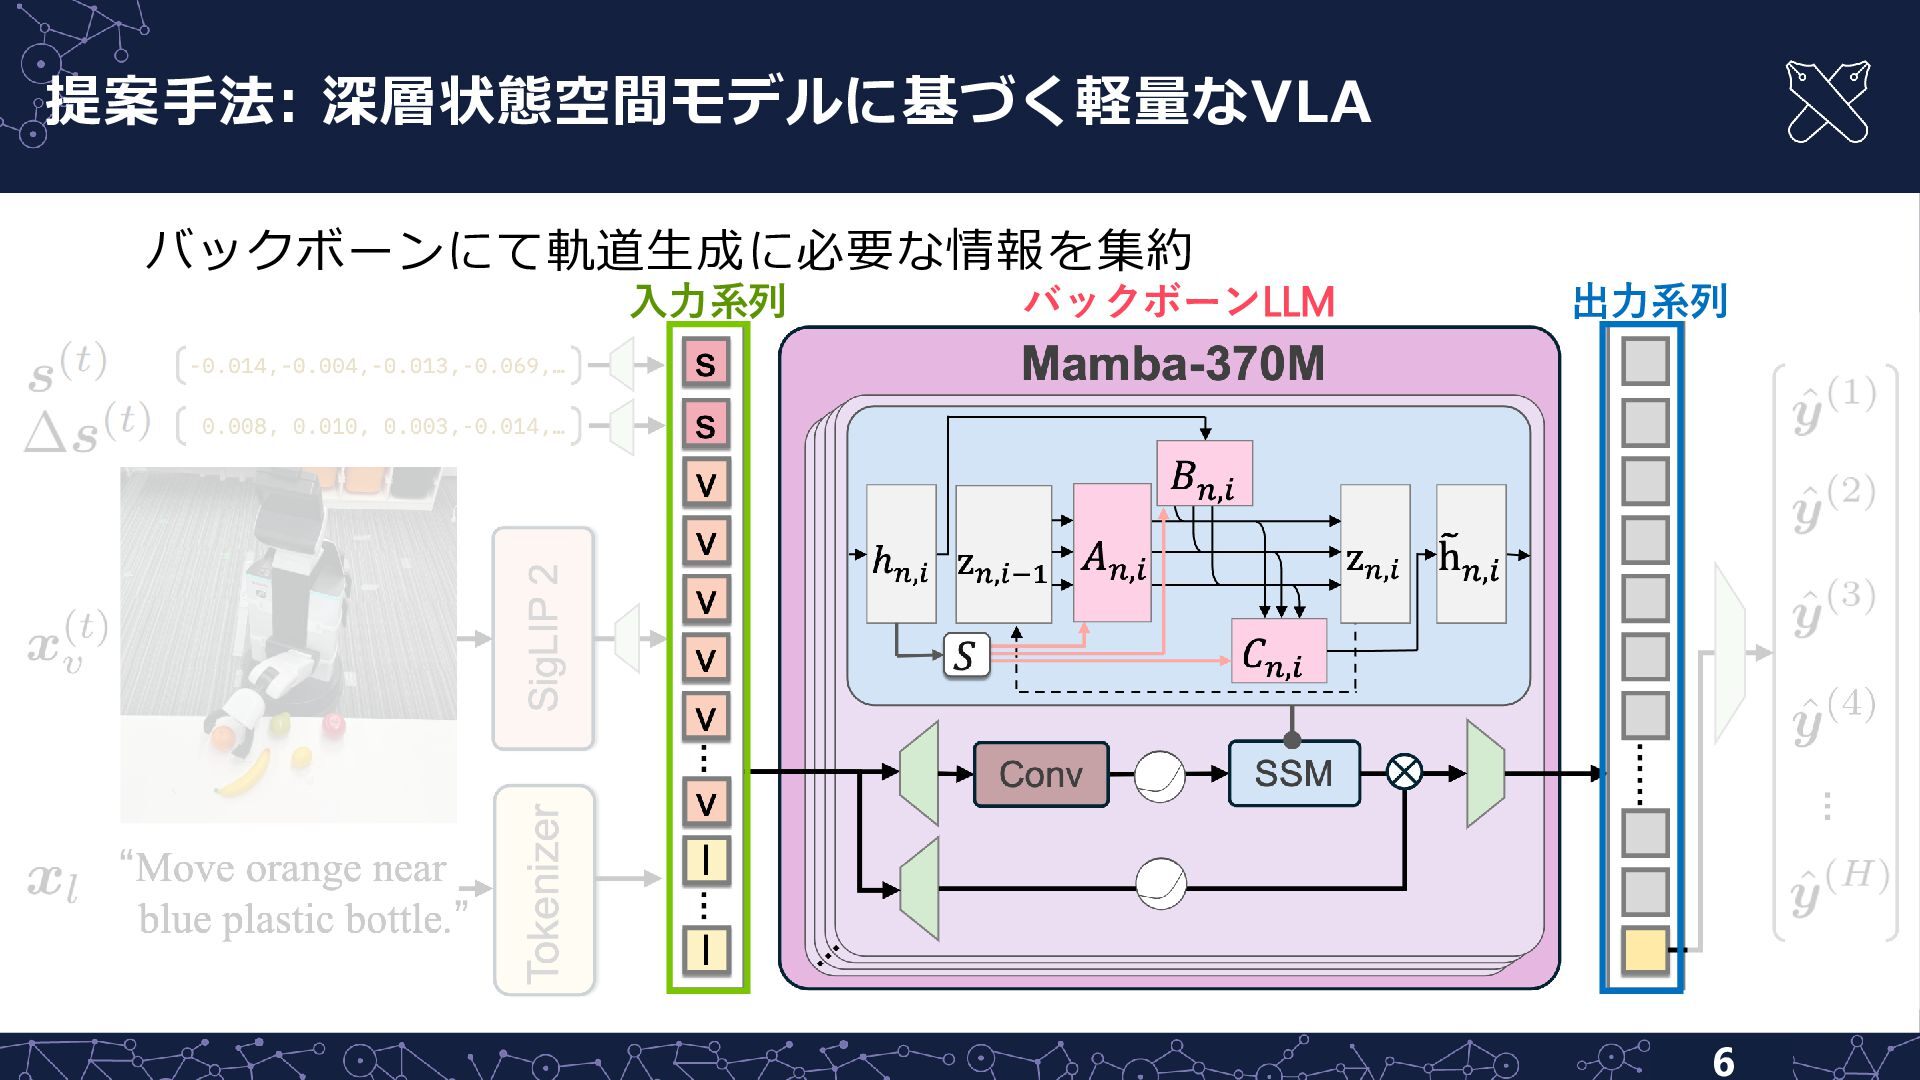
提案手法: 深層状態空間モデルに基づく軽量なVLA バックボーンにて軌道生成に必要な情報を集約 入力系列 バックボーンLLM 出力系列 6
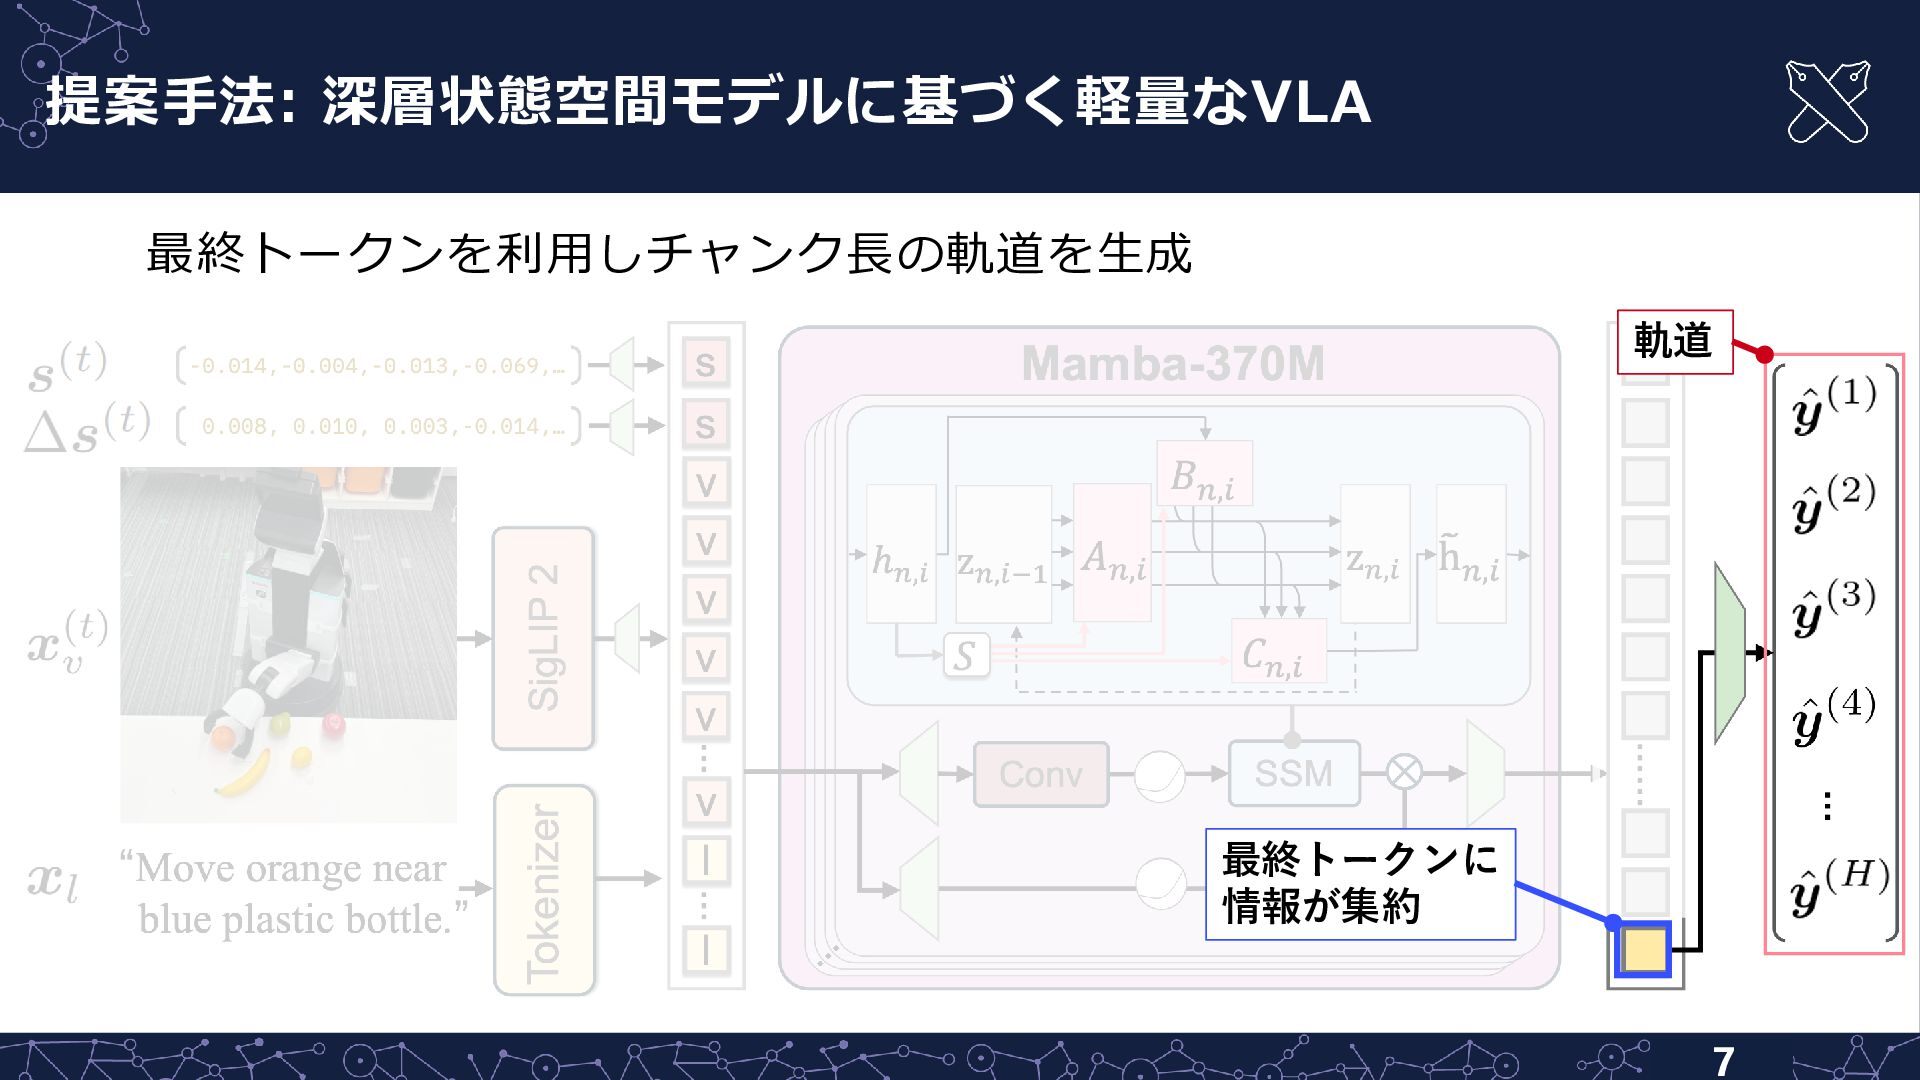
提案手法: 深層状態空間モデルに基づく軽量なVLA 最終トークンを利用しチャンク長の軌道を生成 軌道 最終トークンに 情報が集約 7
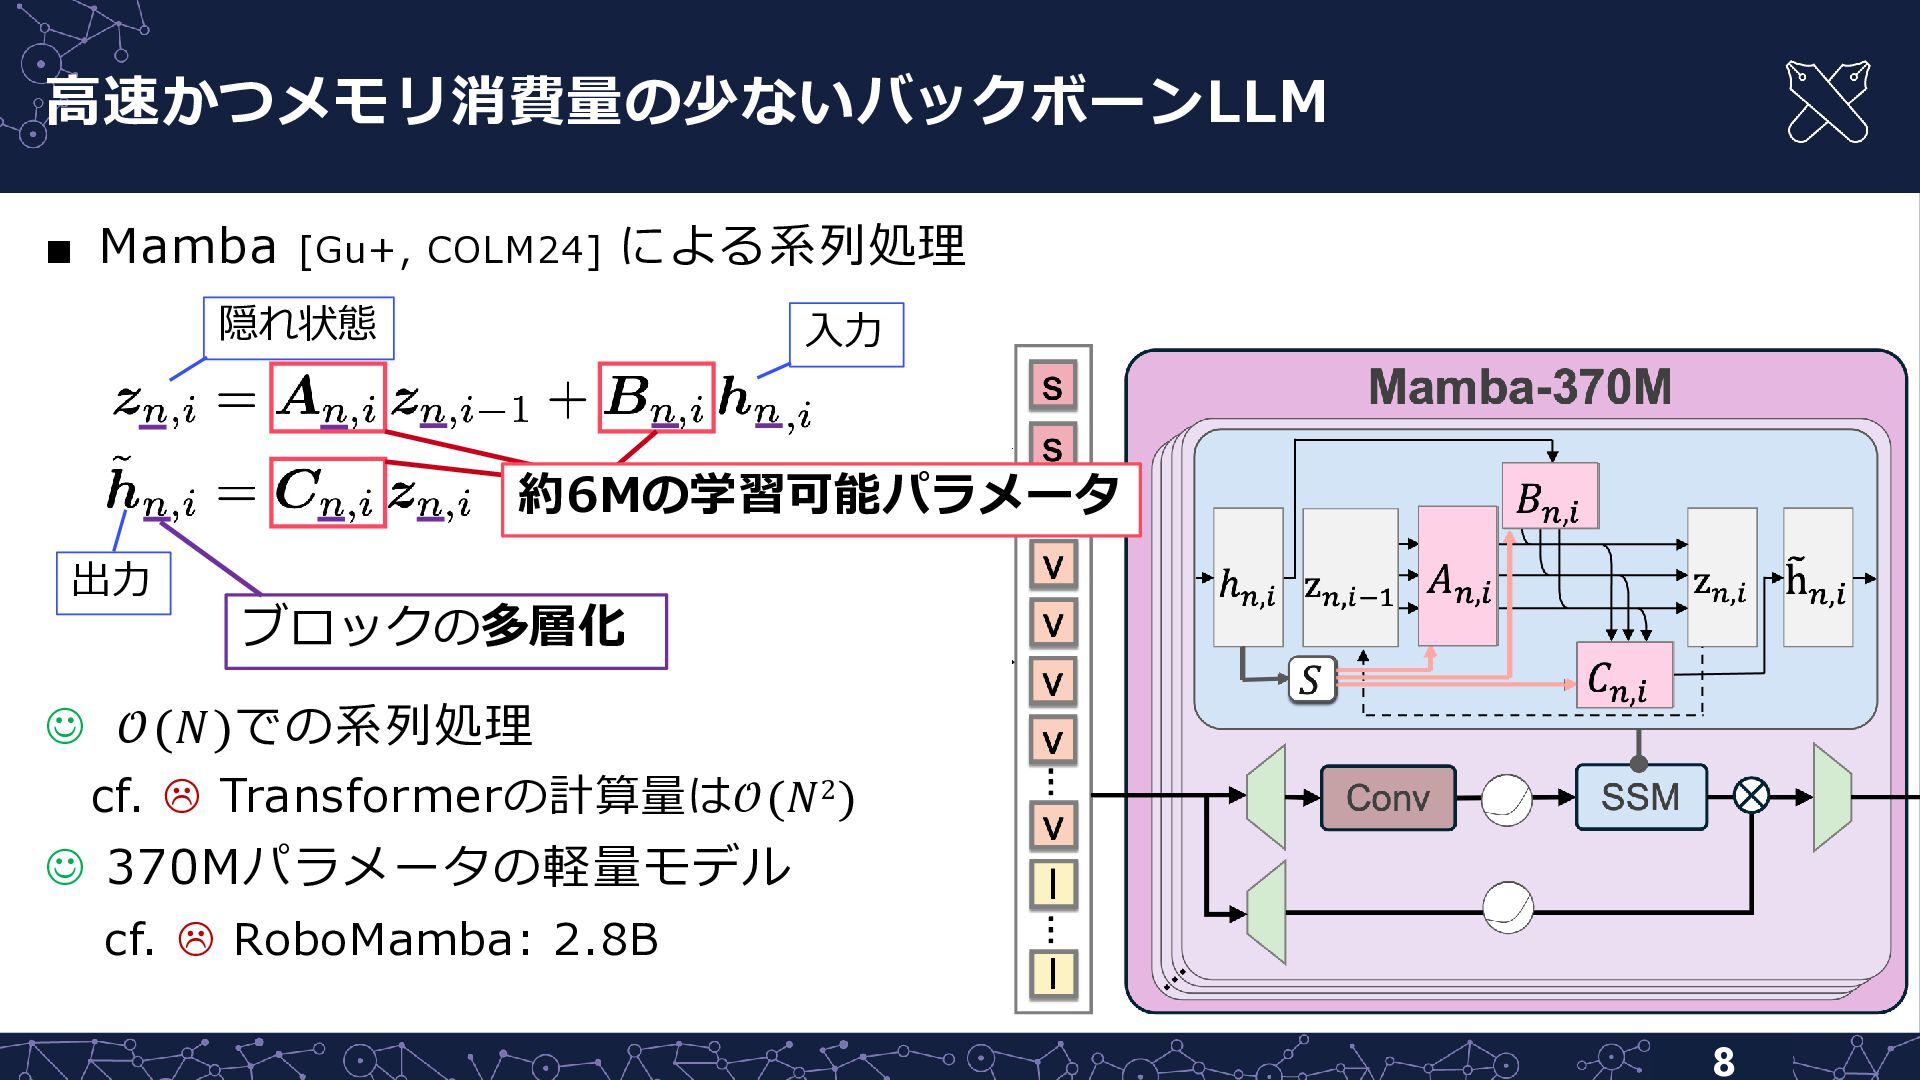
高速かつメモリ消費量の少ないバックボーンLLM ▪ Mamba [Gu+, COLM24] による系列処理 隠れ状態 入力 約6Mの学習可能パラメータ 出力
ブロックの多層化 ☺ 𝒪(𝑁)での系列処理 cf. Transformerの計算量は𝒪(𝑁 2 ) ☺ 370Mパラメータの軽量モデル cf. RoboMamba: 2.8B 8
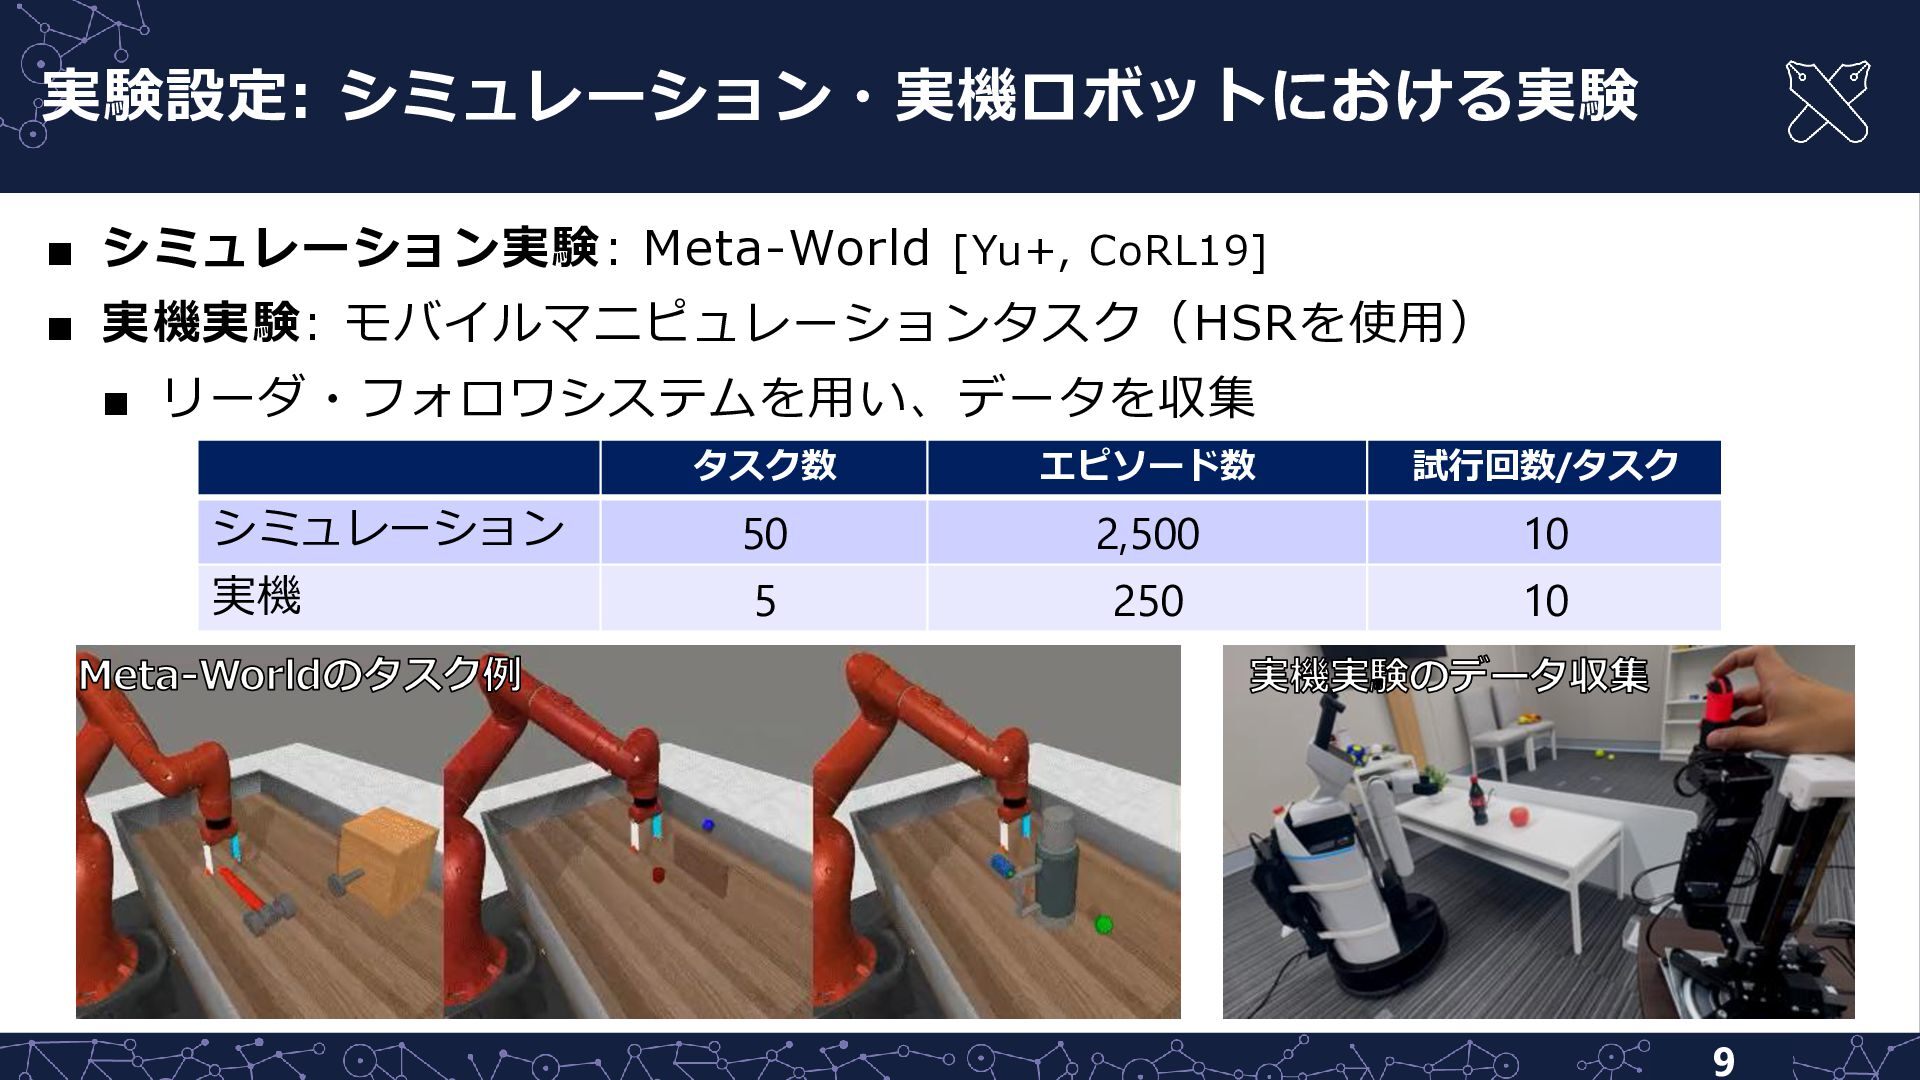
実験設定: シミュレーション・実機ロボットにおける実験 ▪ シミュレーション実験: Meta-World [Yu+, CoRL19] ▪ 実機実験: モバイルマニピュレーションタスク(HSRを使用)
▪ リーダ・フォロワシステムを用い、データを収集 タスク数 エピソード数 試行回数/タスク シミュレーション 50 2,500 10 実機 5 250 10 Meta-Worldのタスク例 実機実験のデータ収集 9
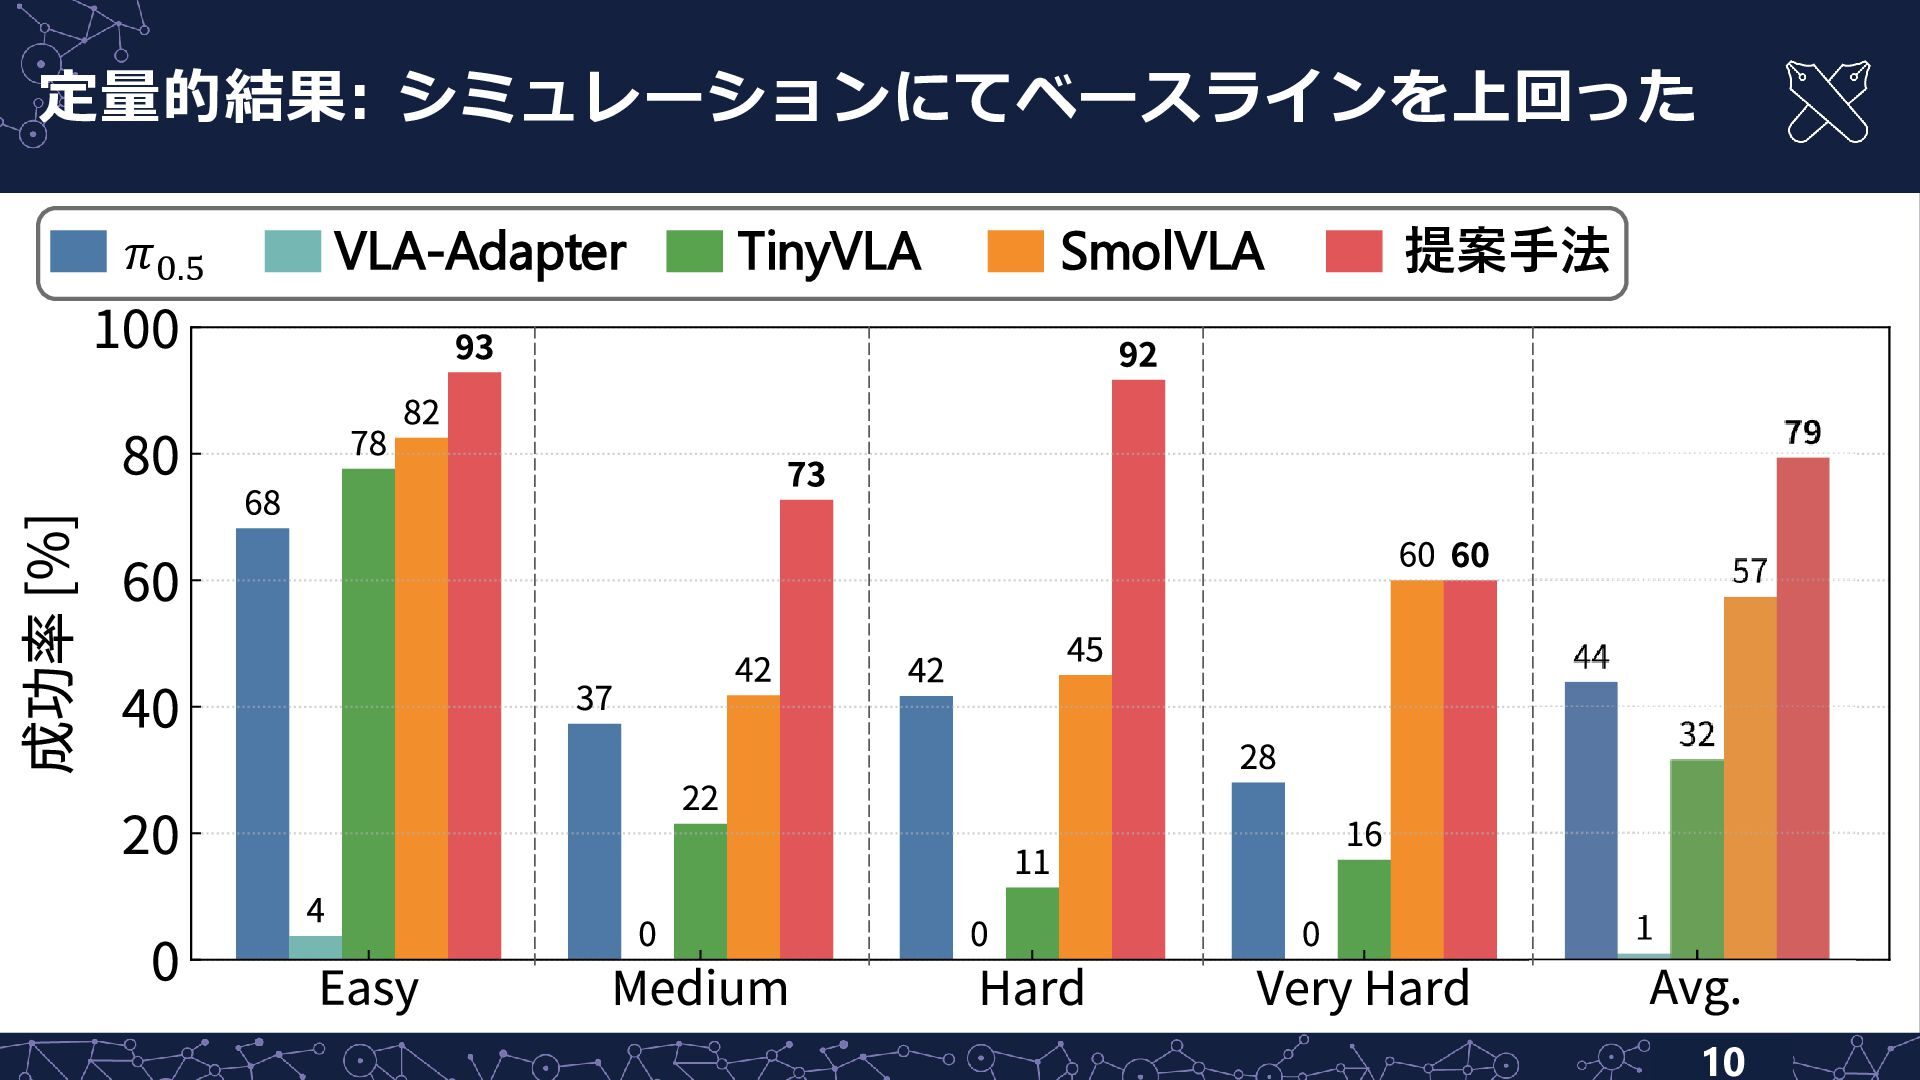
定量的結果: シミュレーションにてベースラインを上回った 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 10
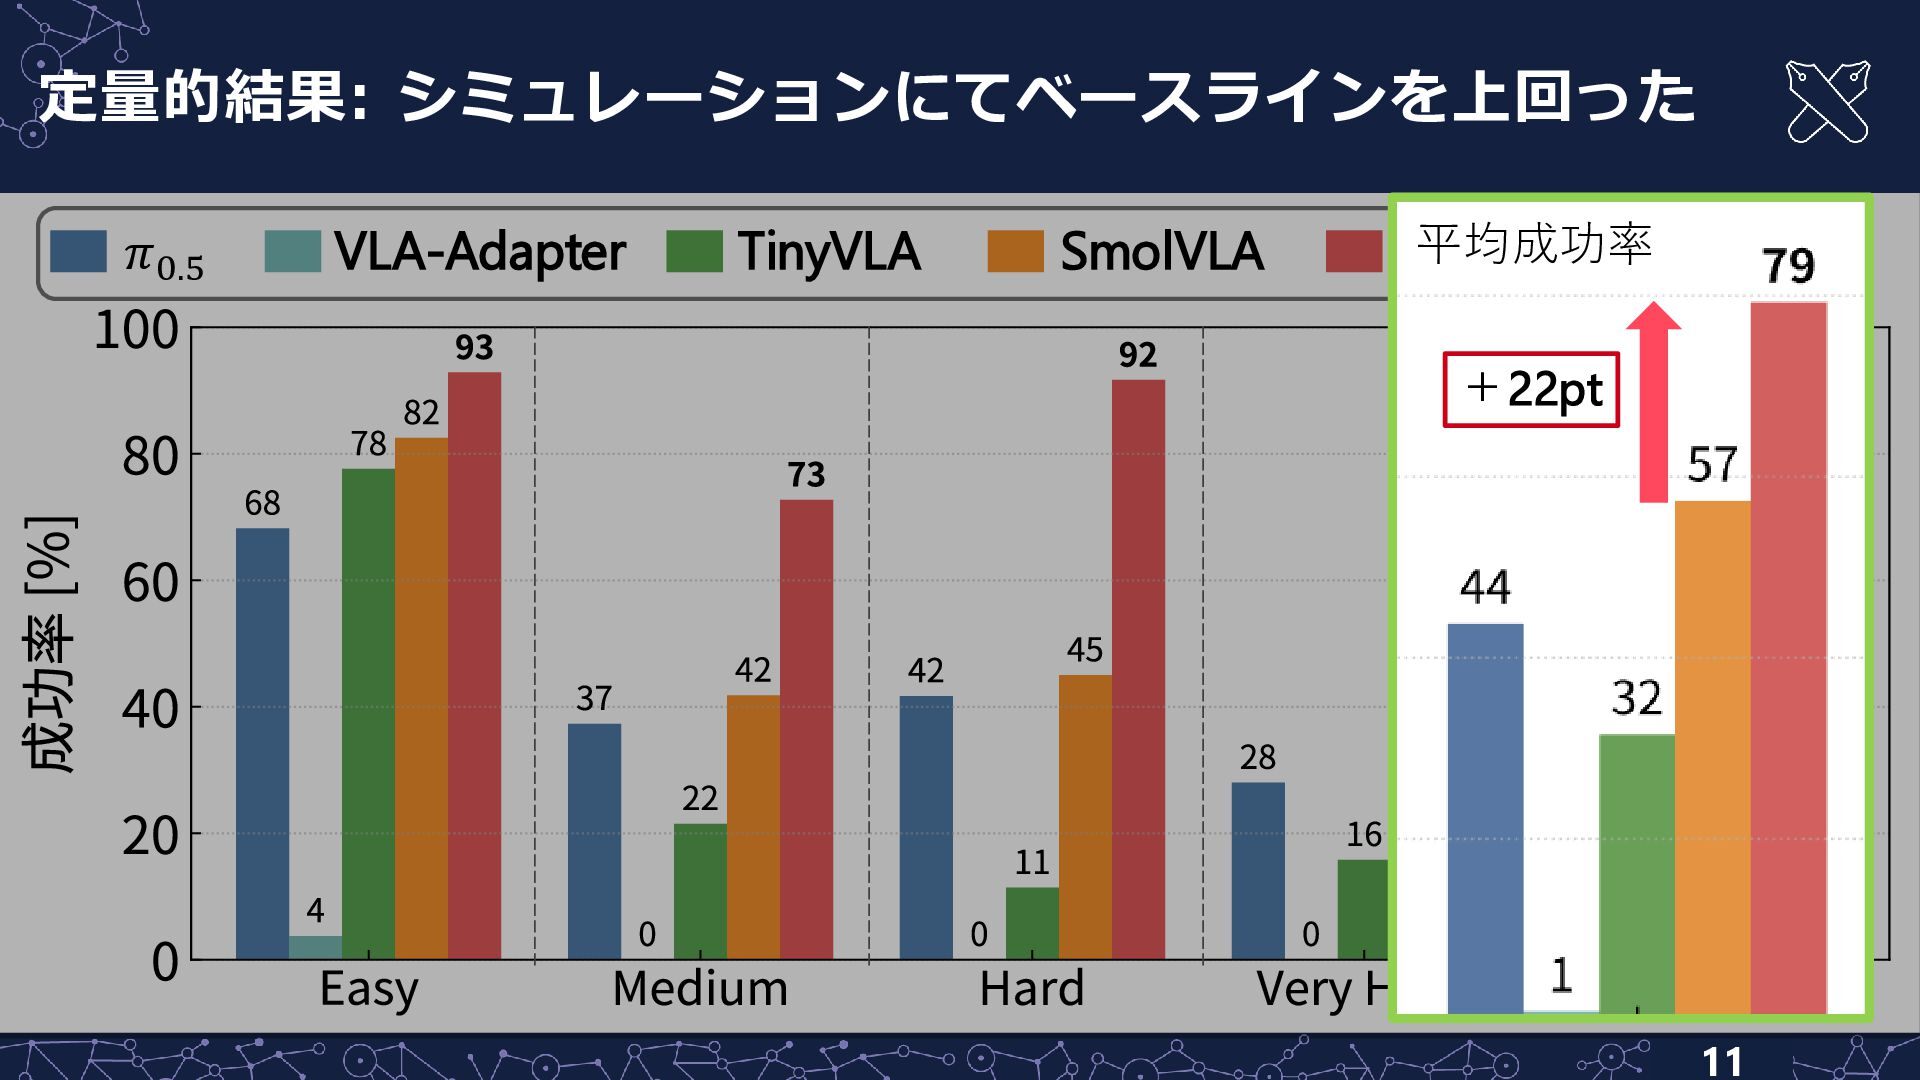
定量的結果: シミュレーションにてベースラインを上回った 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 平均成功率 提案手法 +22pt 11
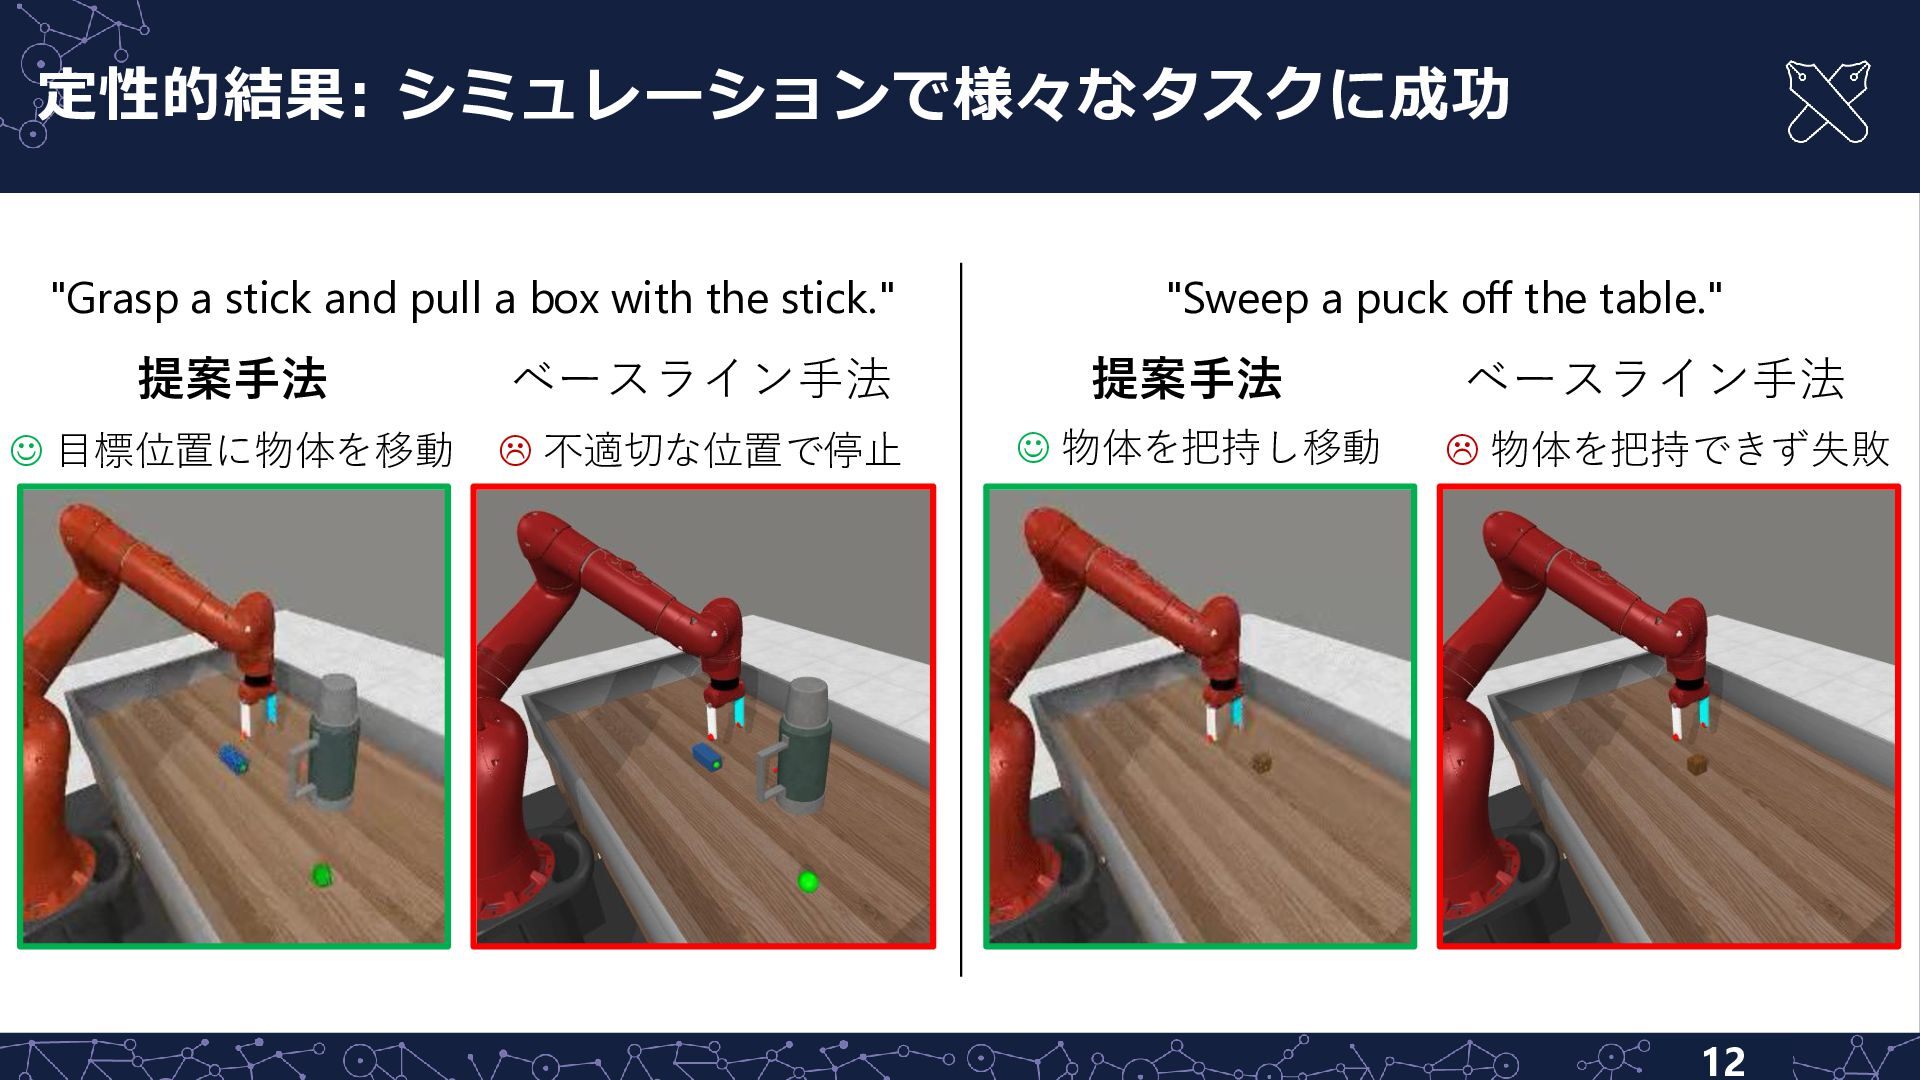
定性的結果: シミュレーションで様々なタスクに成功 "Grasp a stick and pull a box with
the stick." "Sweep a puck off the table." 提案手法 ベースライン手法 提案手法 ベースライン手法 ☺ 目標位置に物体を移動 不適切な位置で停止 ☺ 物体を把持し移動 物体を把持できず失敗 12
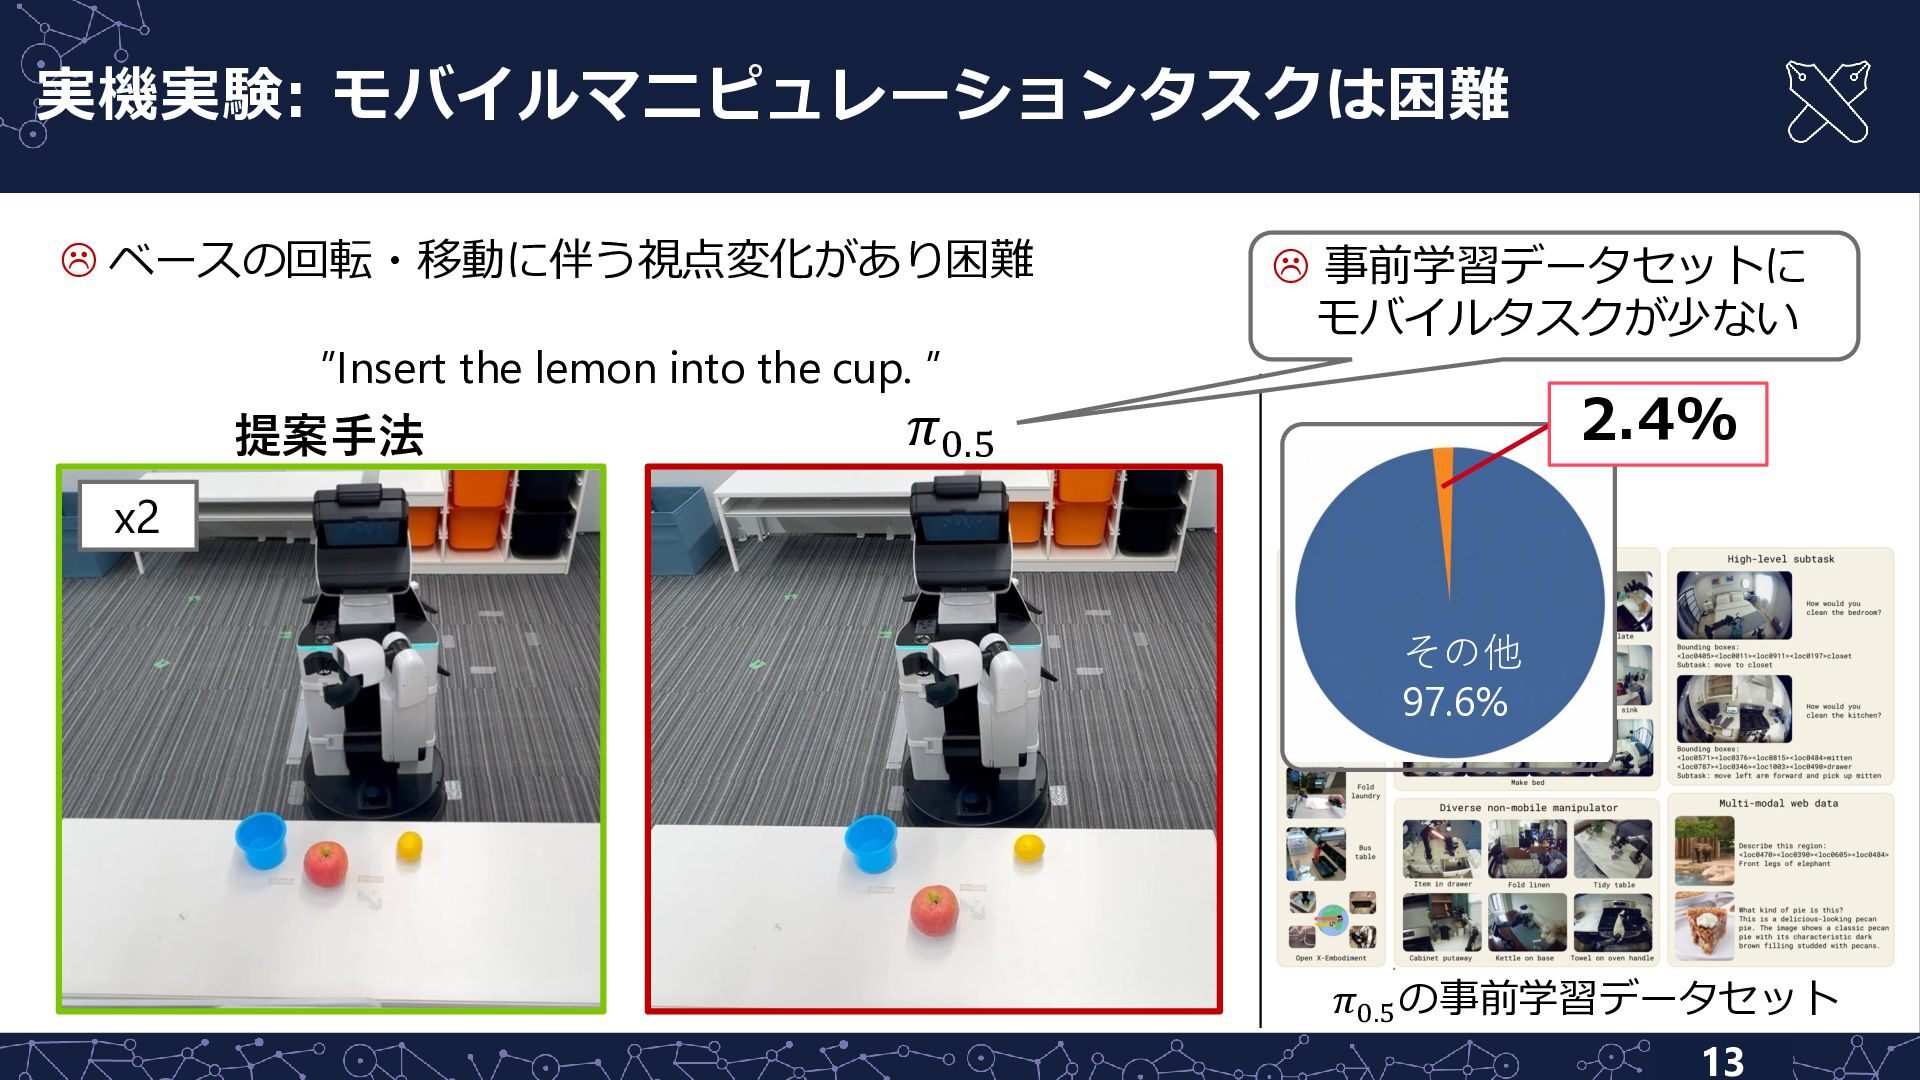
実機実験: モバイルマニピュレーションタスクは困難 ベースの回転・移動に伴う視点変化があり困難 ”Insert the lemon into the cup.
” 提案手法 事前学習データセットに モバイルタスクが少ない 2.4% 𝜋0.5 x2 その他 97.6% 𝜋0.5 の事前学習データセット 13
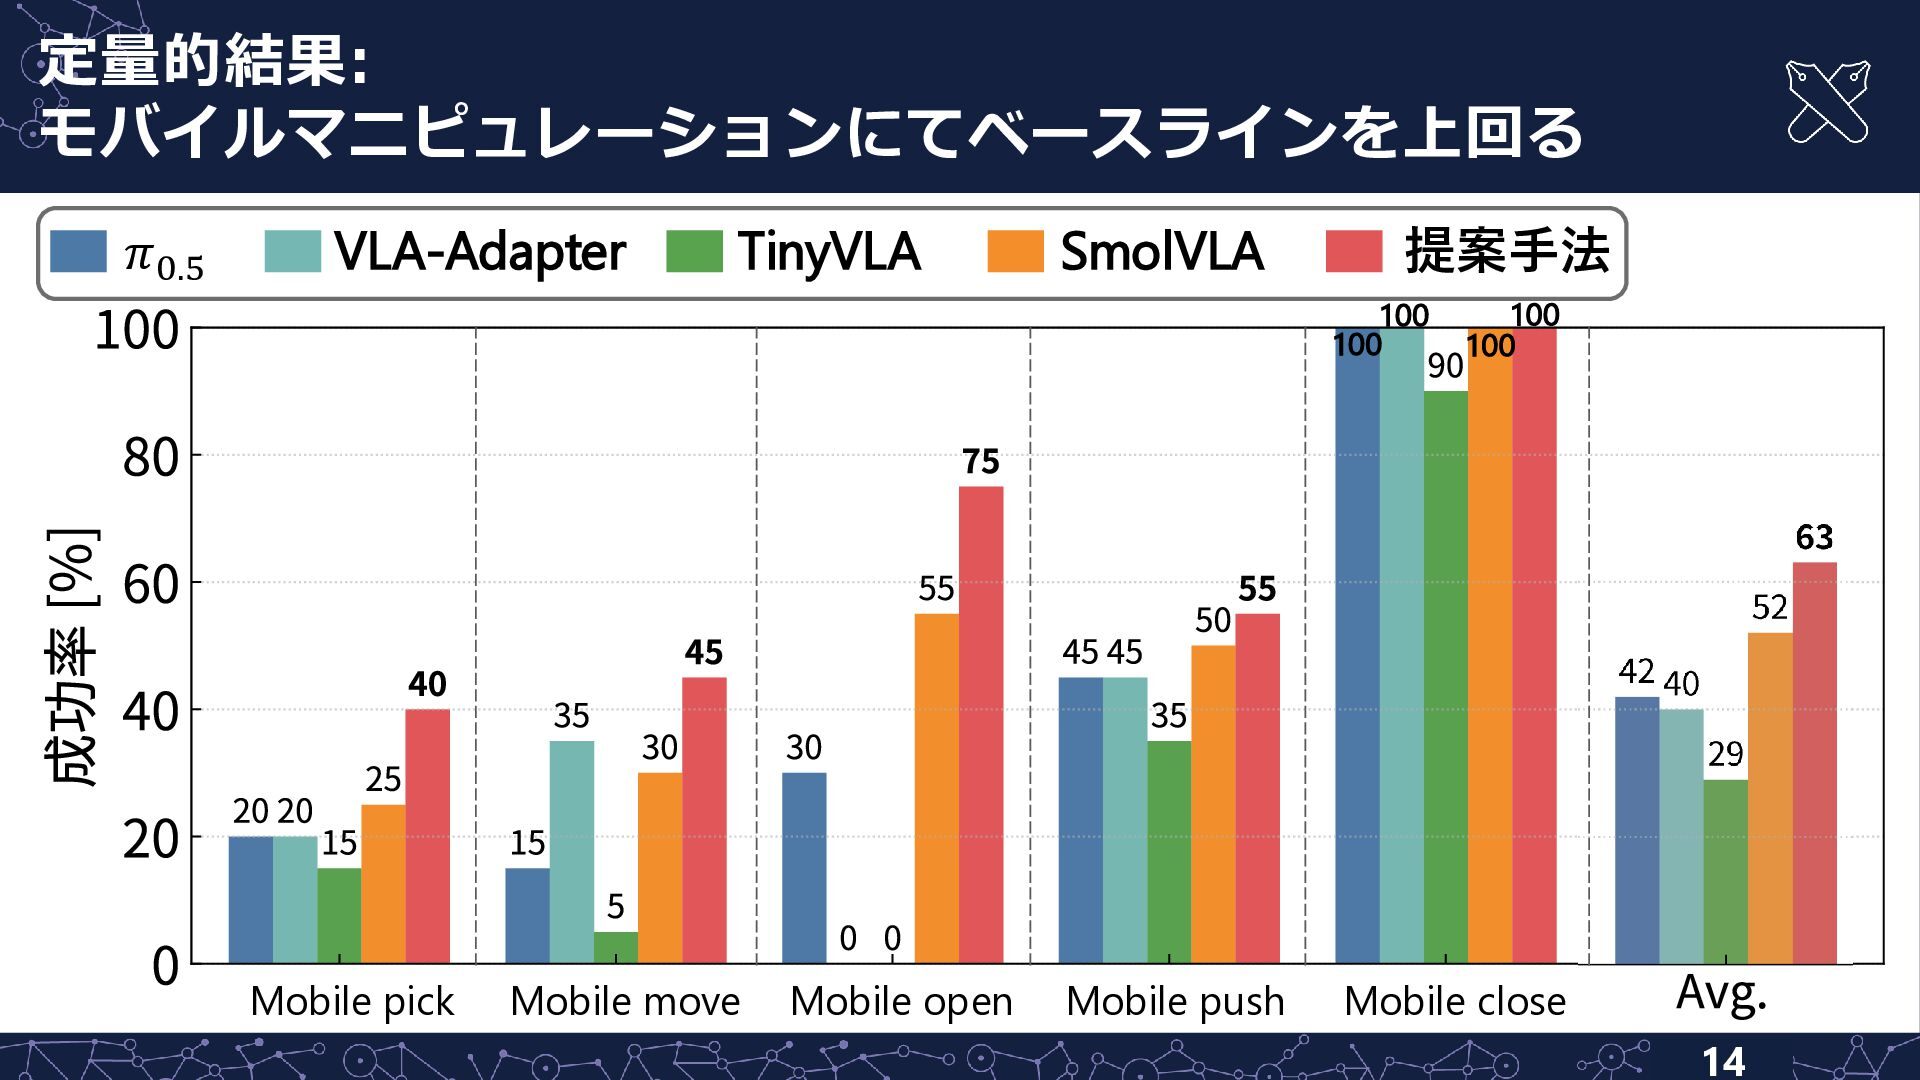
定量的結果: モバイルマニピュレーションにてベースラインを上回る 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 100 100 Mobile
pick Mobile move Mobile open Mobile push 100 100 Mobile close 14
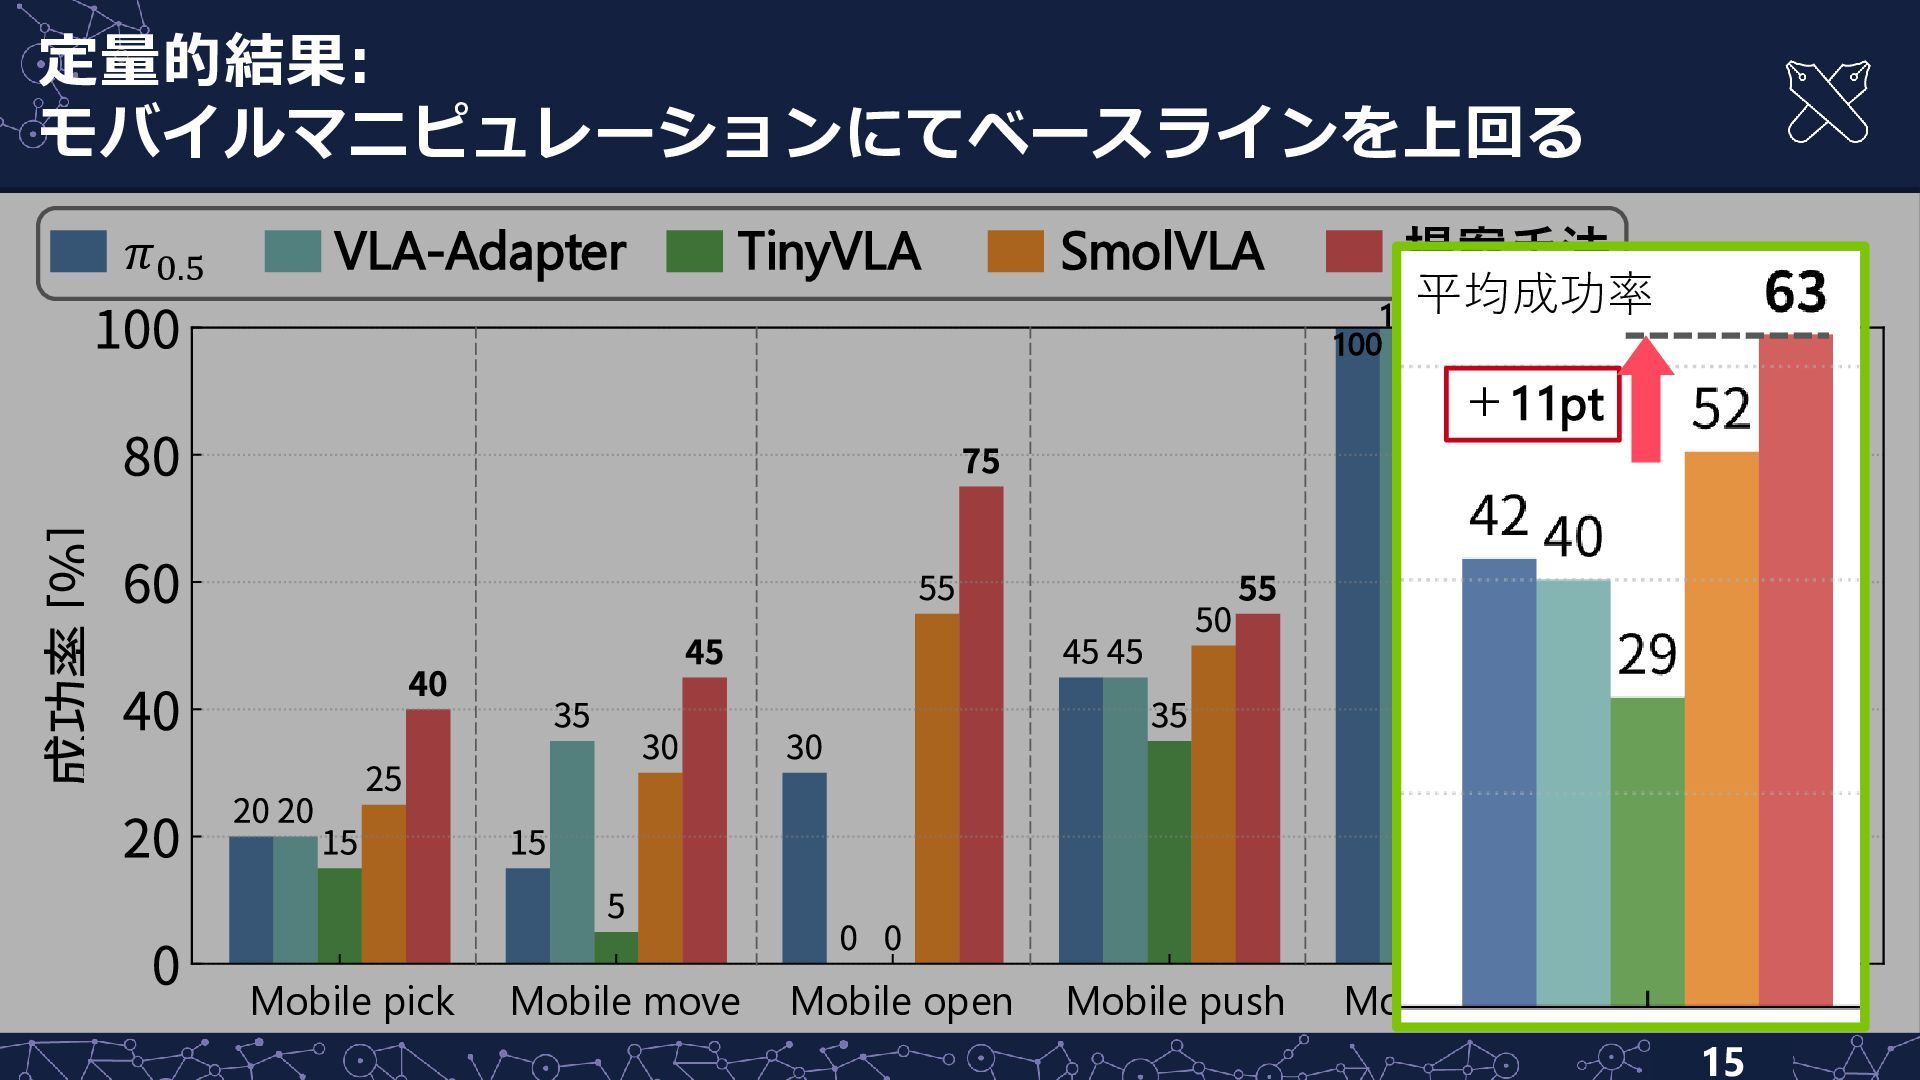
定量的結果: モバイルマニピュレーションにてベースラインを上回る 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 100 100平均成功率 100
100 +11pt Mobile pick Mobile move Mobile open Mobile push Mobile close 15
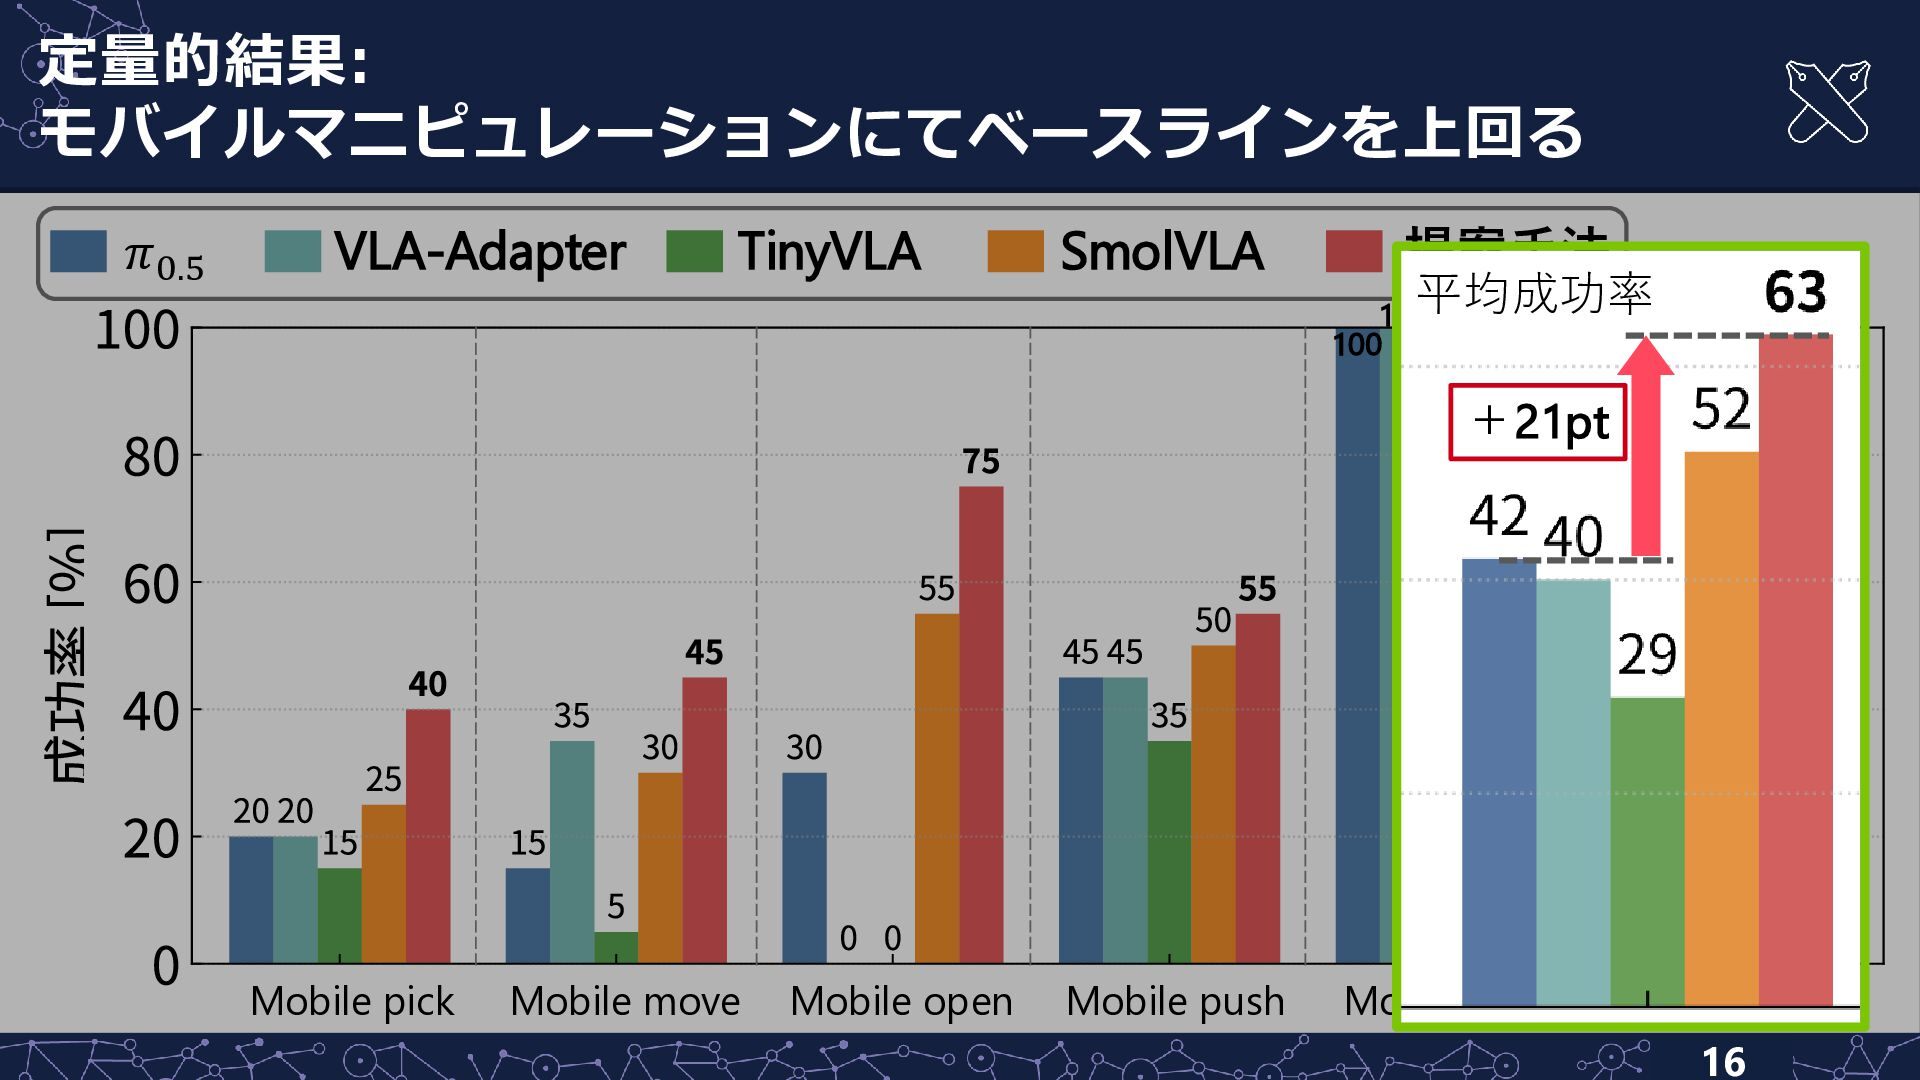
定量的結果: モバイルマニピュレーションにてベースラインを上回る 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 100 100平均成功率 100
100 +21pt Mobile pick Mobile move Mobile open Mobile push Mobile close 16
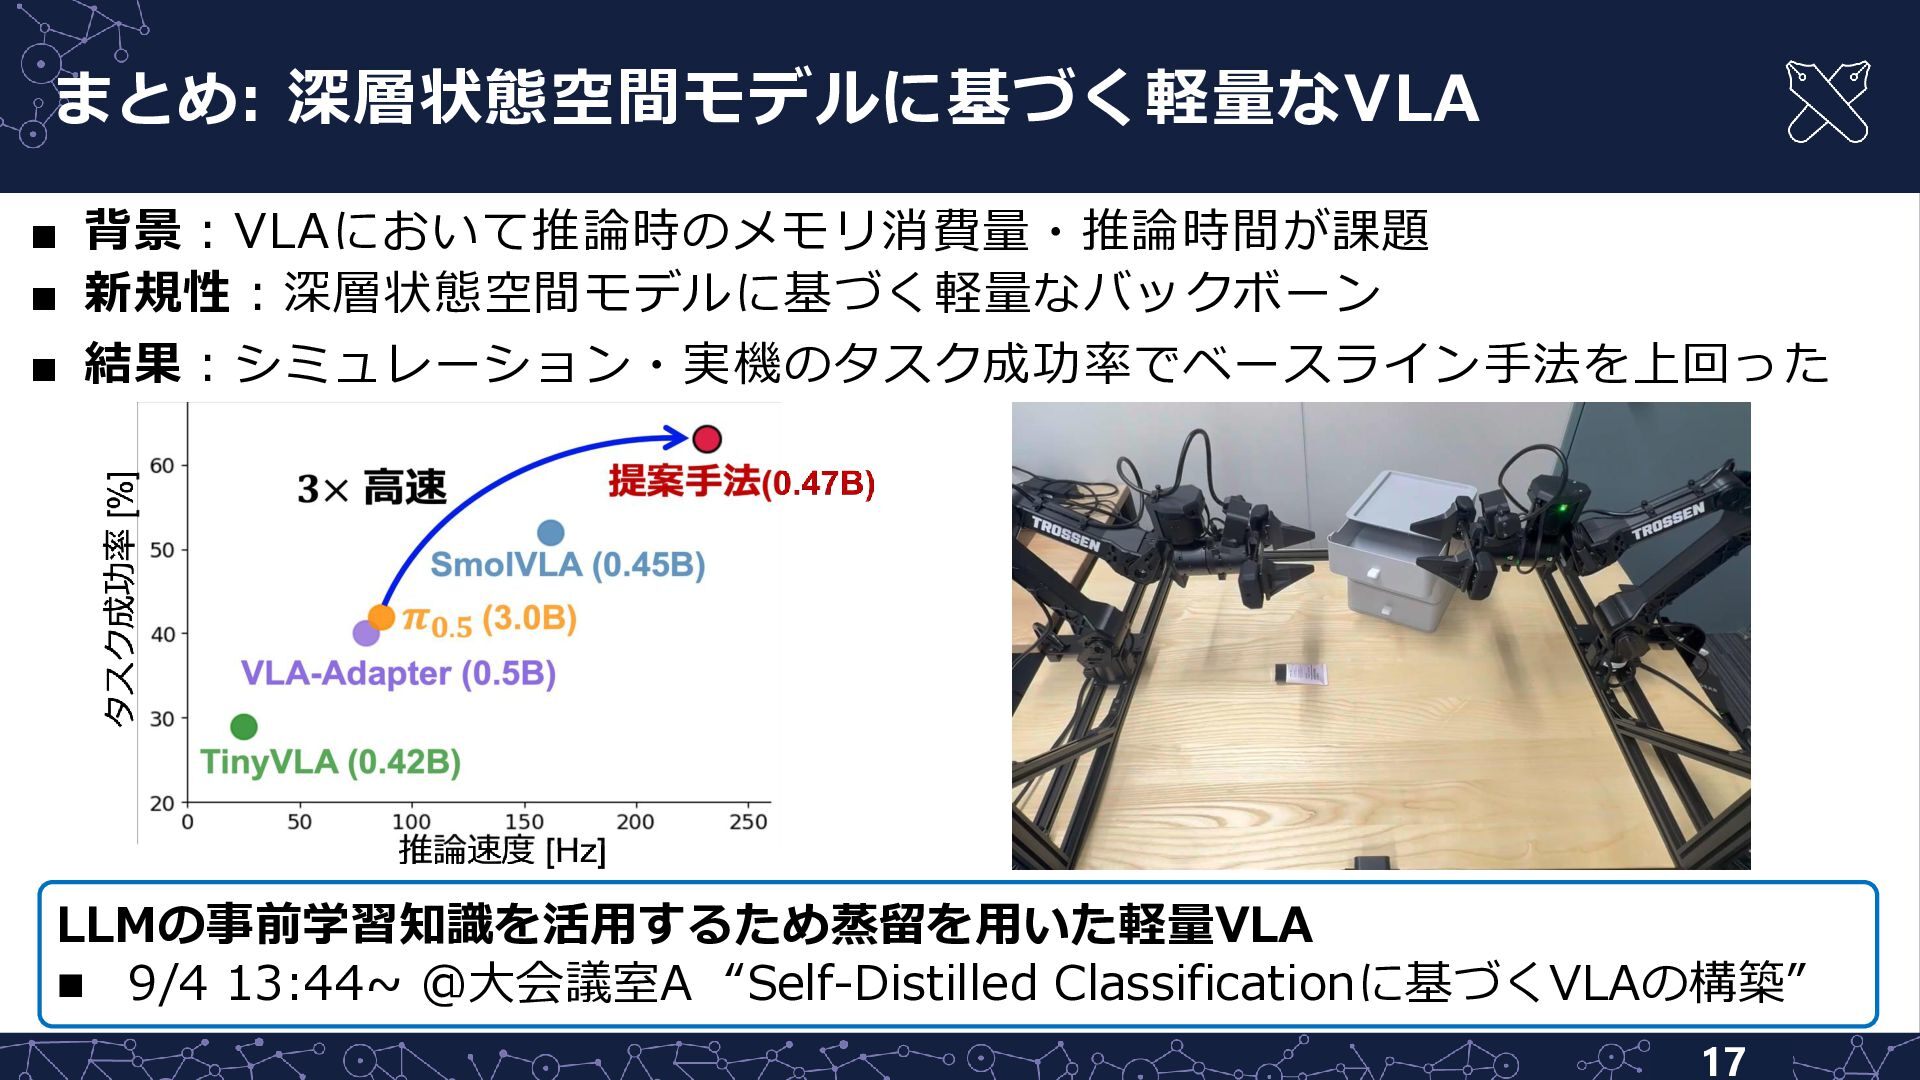
まとめ: 深層状態空間モデルに基づく軽量なVLA ▪ 背景:VLAにおいて推論時のメモリ消費量・推論時間が課題 ▪ 新規性:深層状態空間モデルに基づく軽量なバックボーン ▪ 結果:シミュレーション・実機のタスク成功率でベースライン手法を上回った LLMの事前学習知識を活用するため蒸留を用いた軽量VLA ◼
9/4 13:44~ @大会議室A “Self-Distilled Classificationに基づくVLAの構築” 17
Appendix
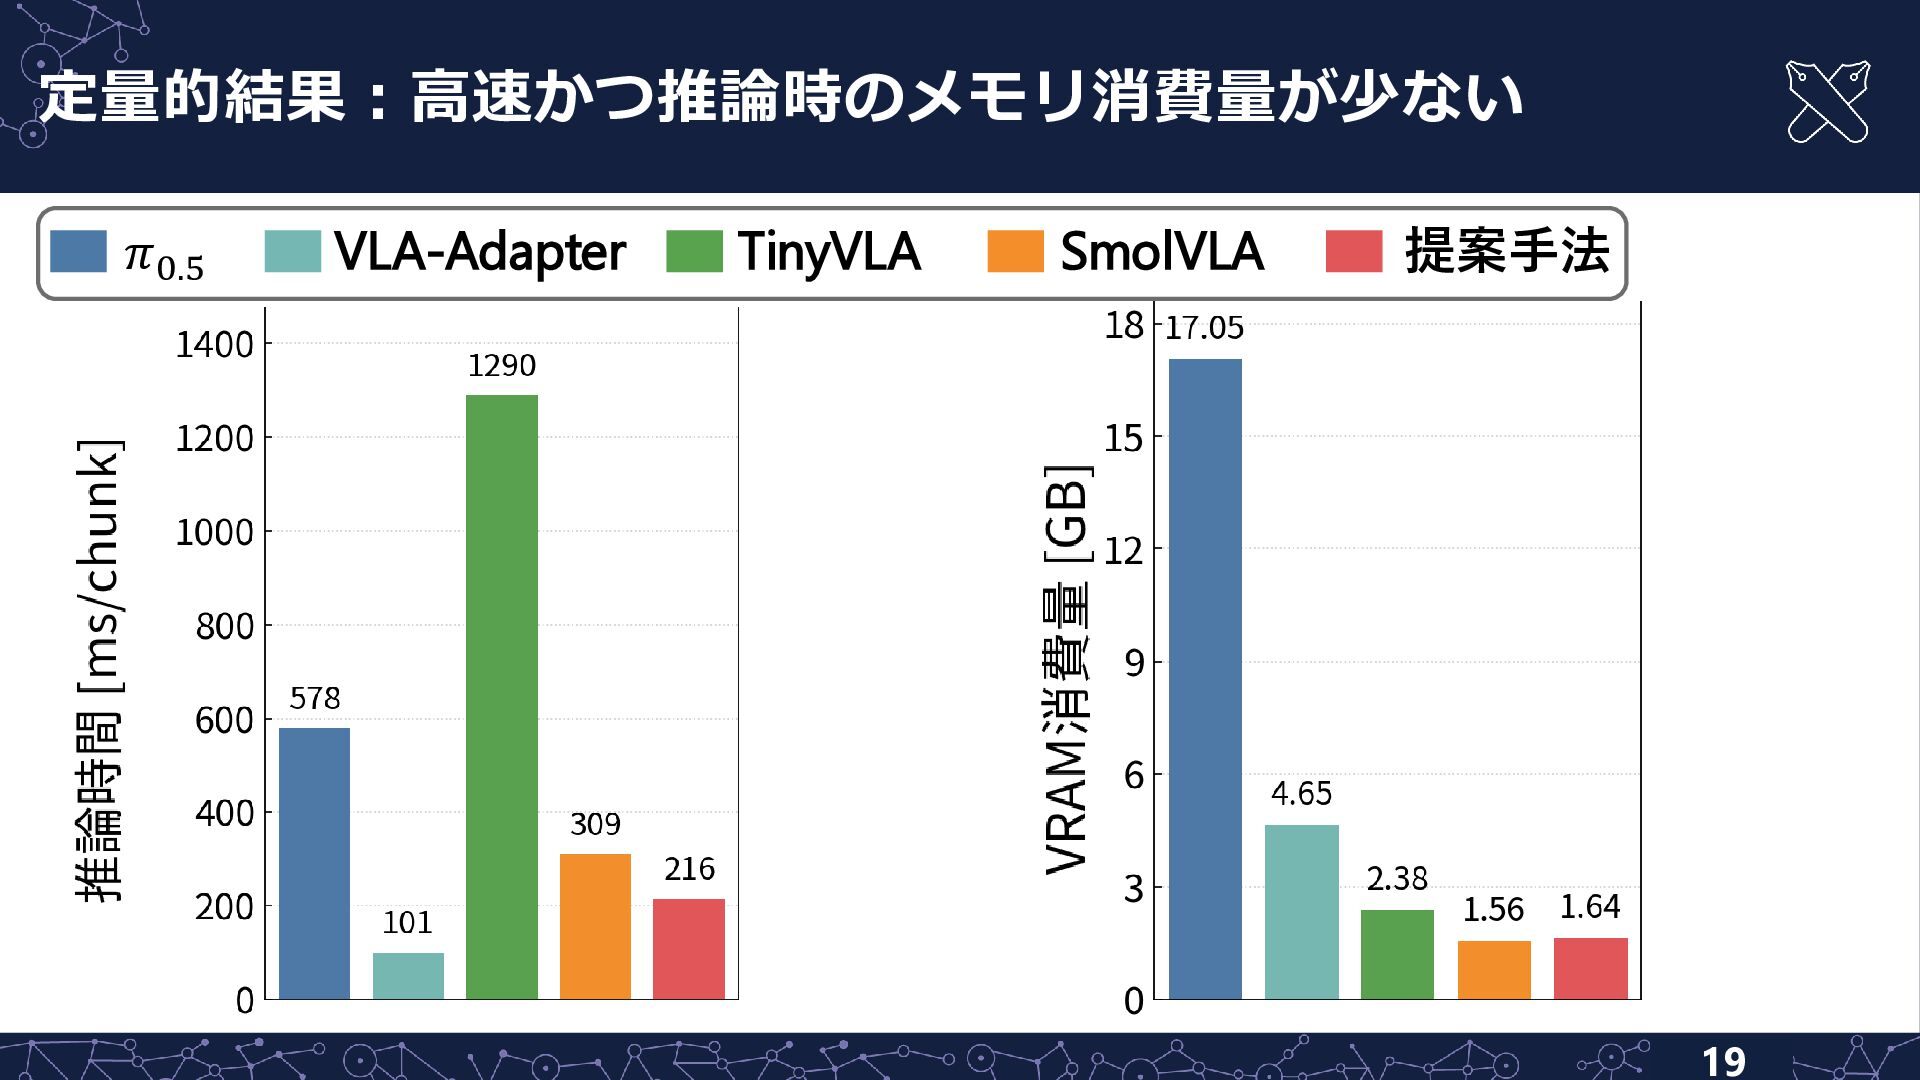
定量的結果:高速かつ推論時のメモリ消費量が少ない 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 19
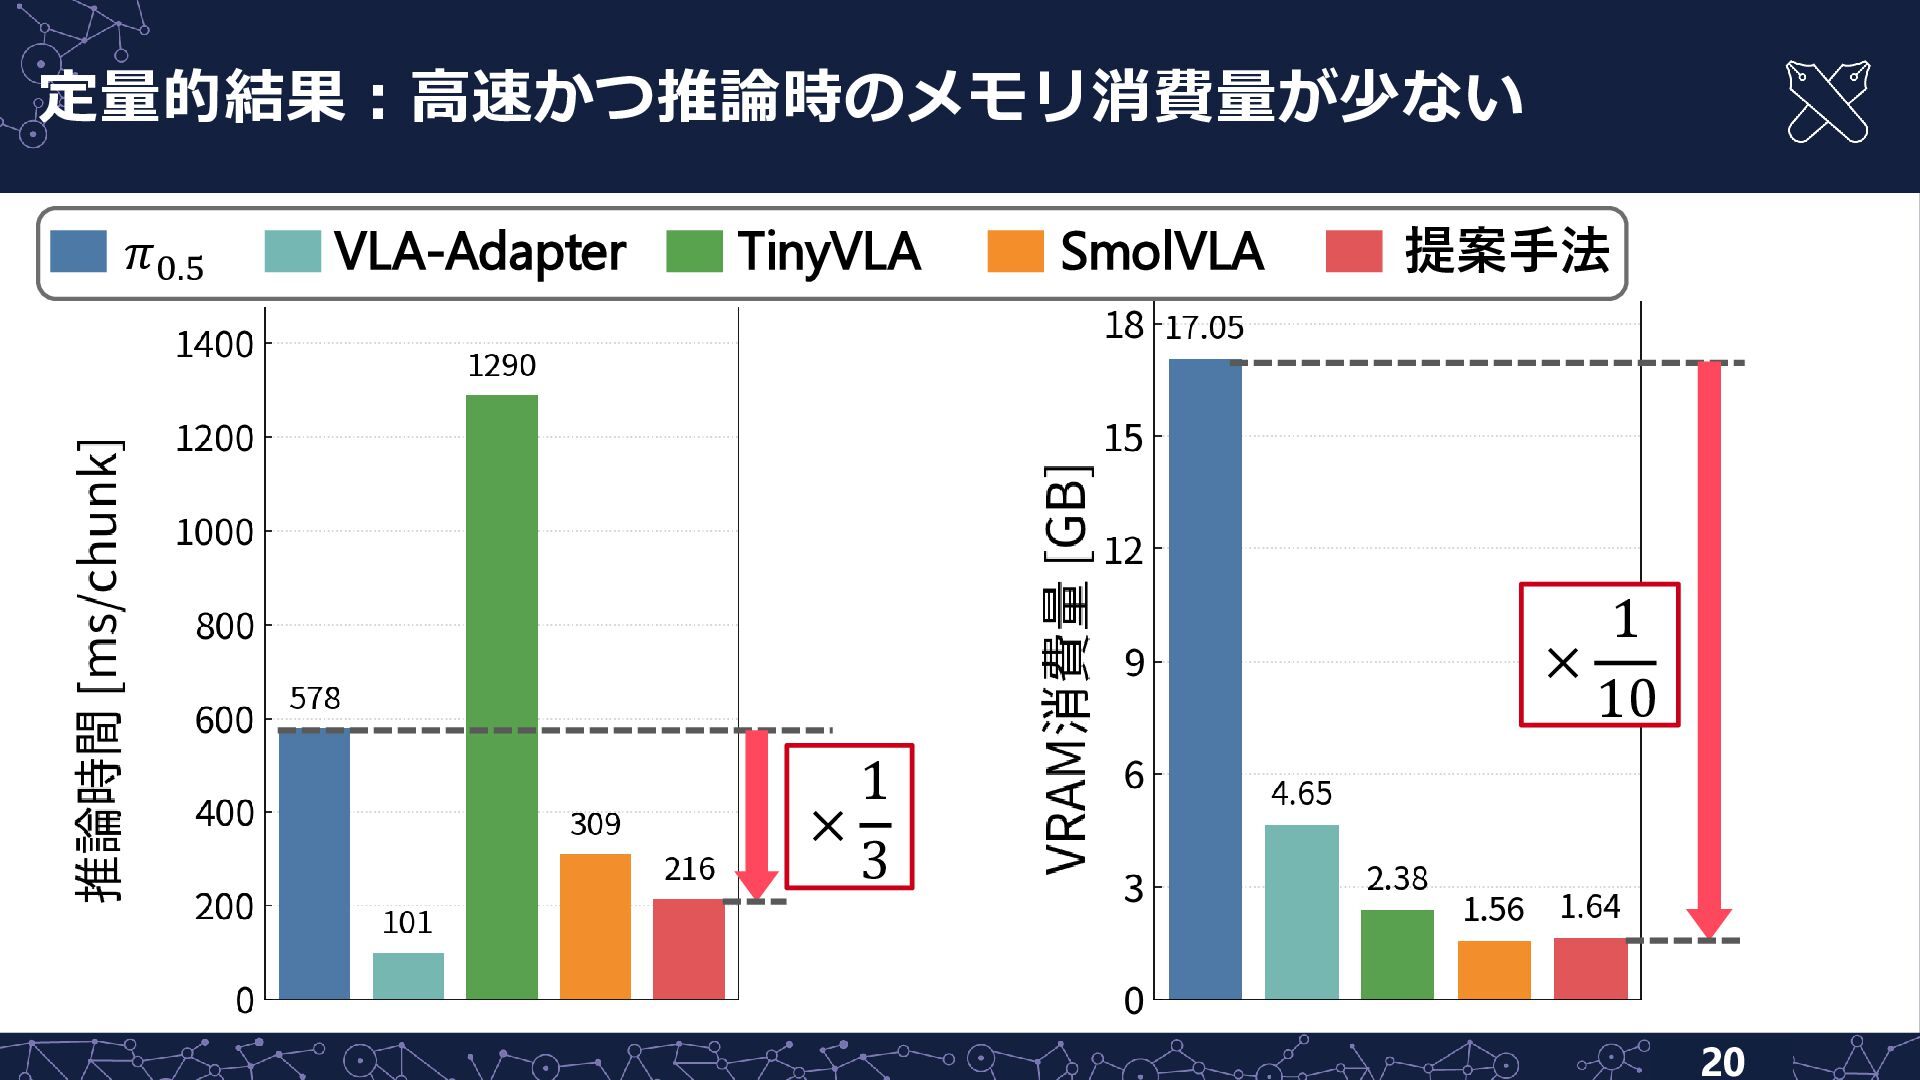
定量的結果:高速かつ推論時のメモリ消費量が少ない 𝜋0.5 VLA-Adapter TinyVLA SmolVLA 提案手法 1 × 10 1
× 3 20
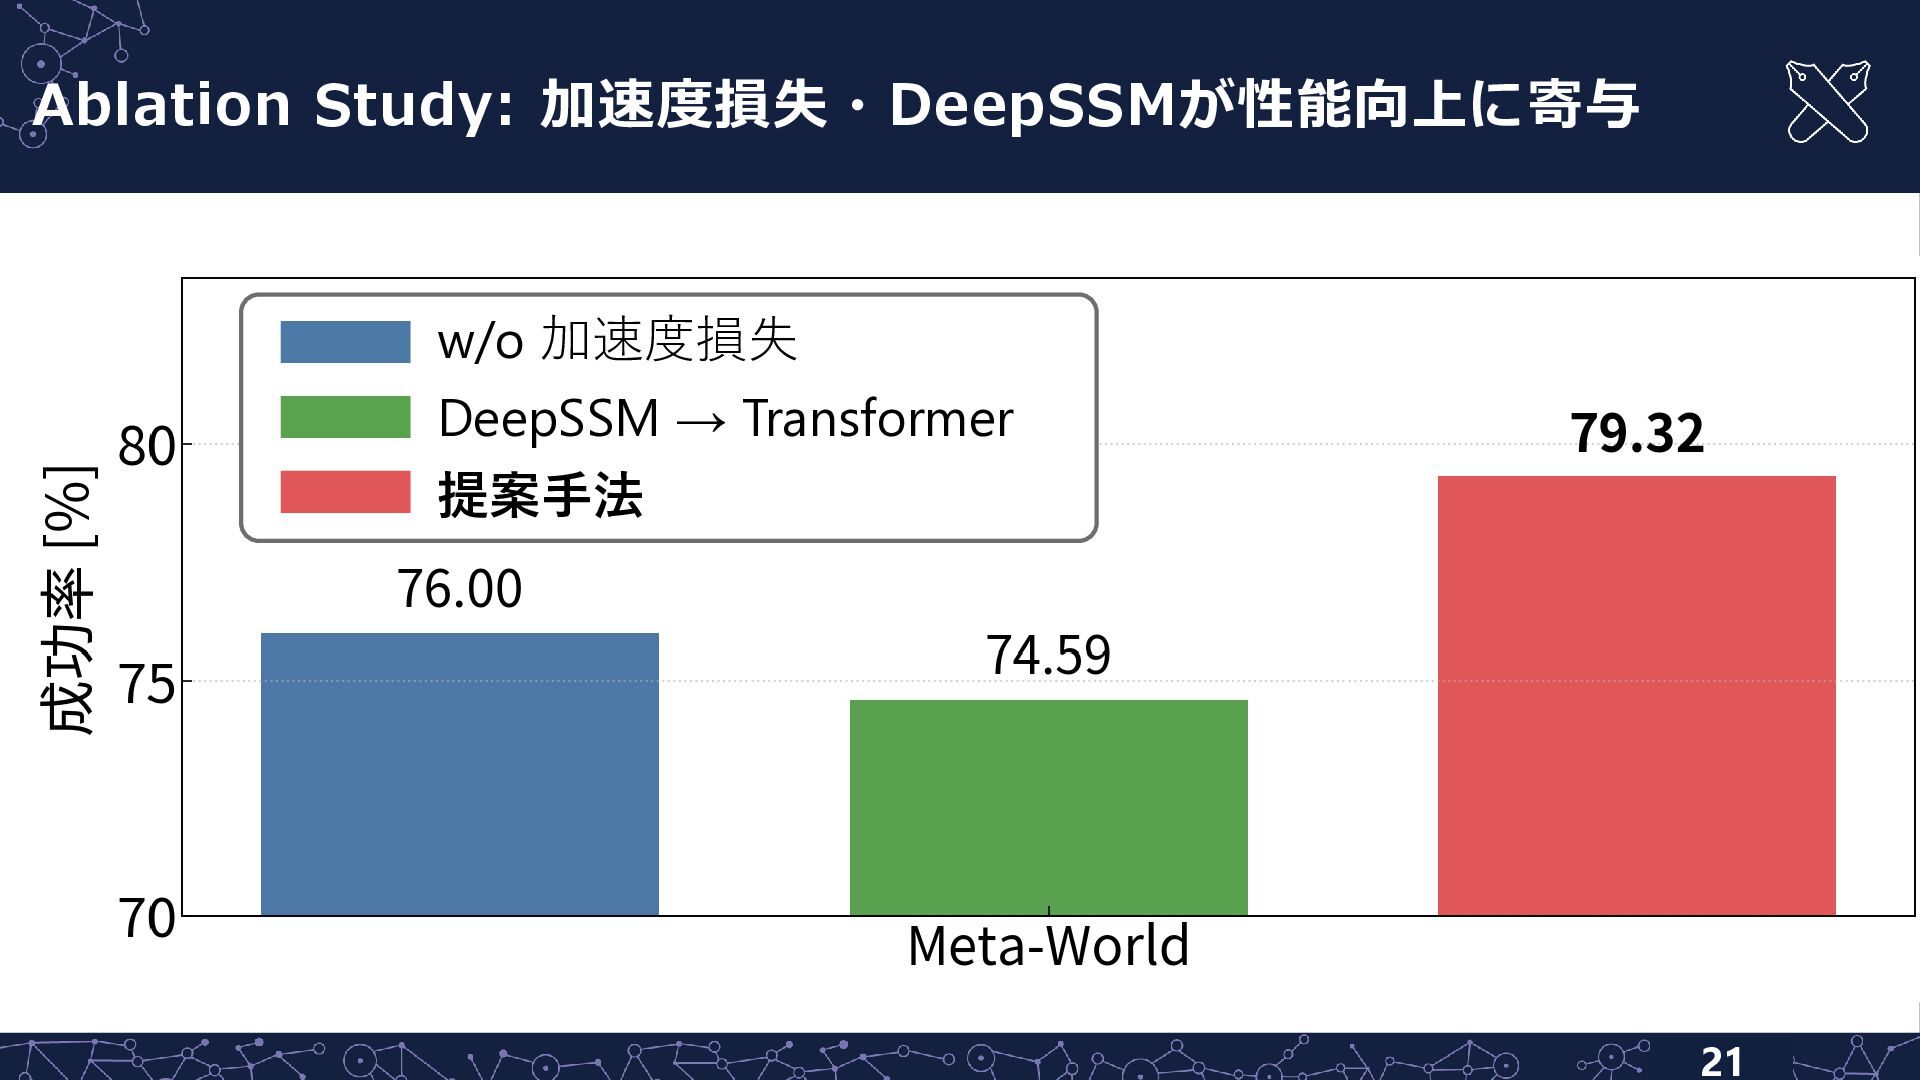
Ablation Study: 加速度損失・DeepSSMが性能向上に寄与 w/o 加速度損失 DeepSSM → Transformer 提案手法 21
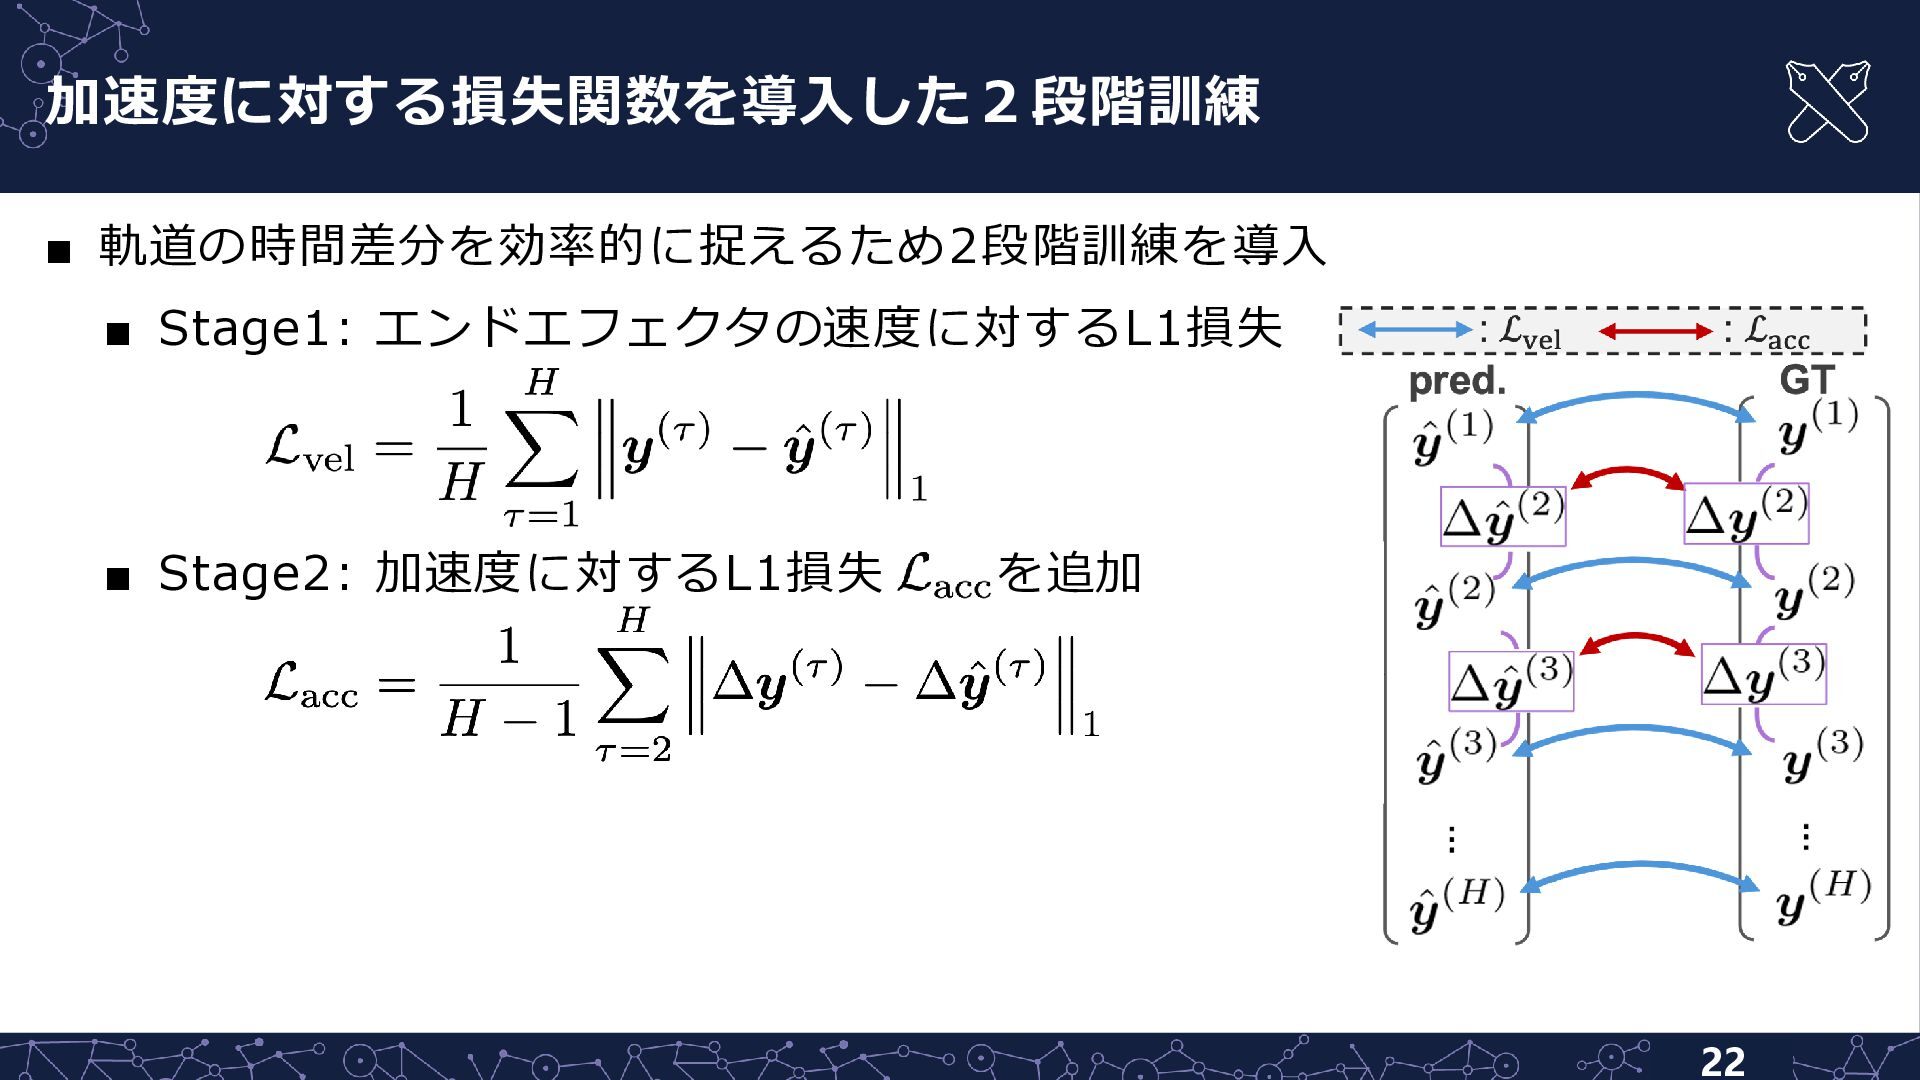
加速度に対する損失関数を導入した2段階訓練 ▪ 軌道の時間差分を効率的に捉えるため2段階訓練を導入 ▪ Stage1: エンドエフェクタの速度に対するL1損失 ▪ Stage2: 加速度に対するL1損失. .
を追加 22
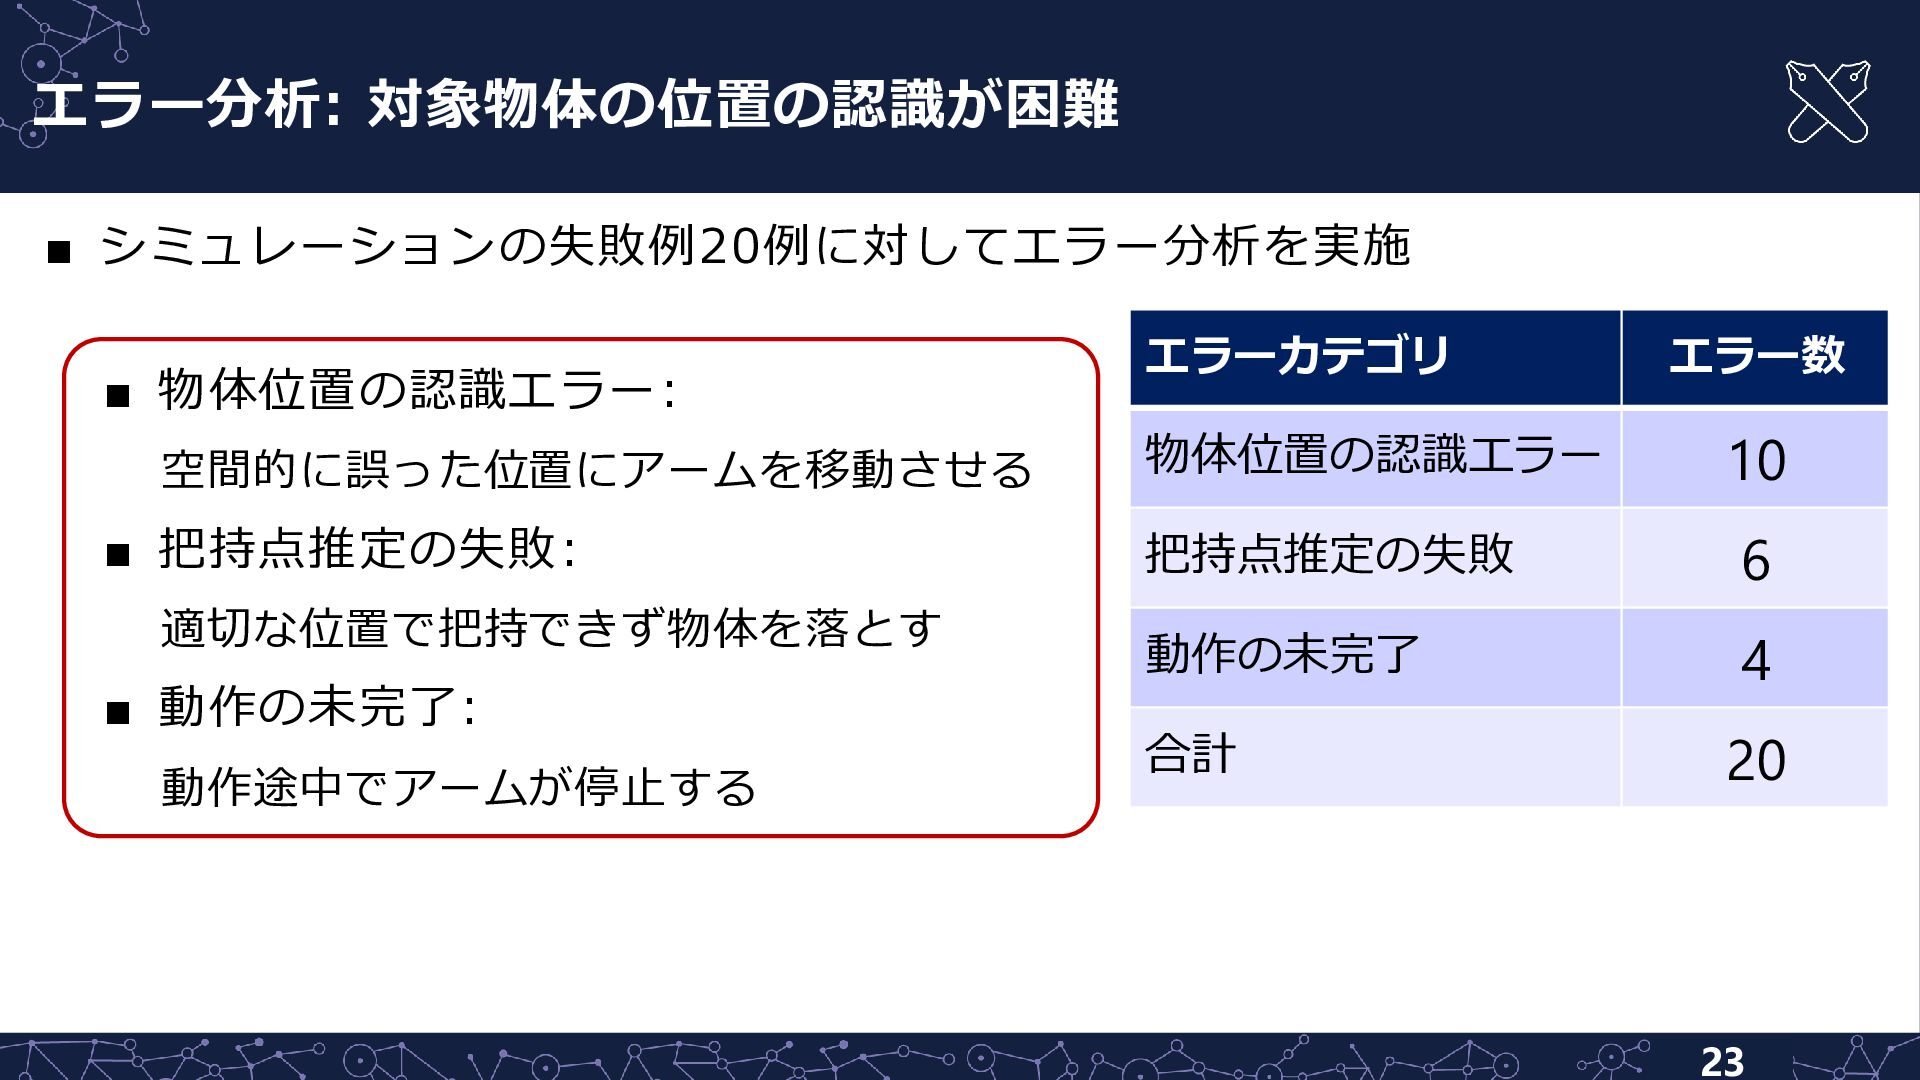
エラー分析: 対象物体の位置の認識が困難 ▪ シミュレーションの失敗例20例に対してエラー分析を実施 ▪ 物体位置の認識エラー: 空間的に誤った位置にアームを移動させる ▪ 把持点推定の失敗: 適切な位置で把持できず物体を落とす
▪ 動作の未完了: 動作途中でアームが停止する エラーカテゴリ エラー数 物体位置の認識エラー 10 把持点推定の失敗 6 動作の未完了 4 合計 20 23
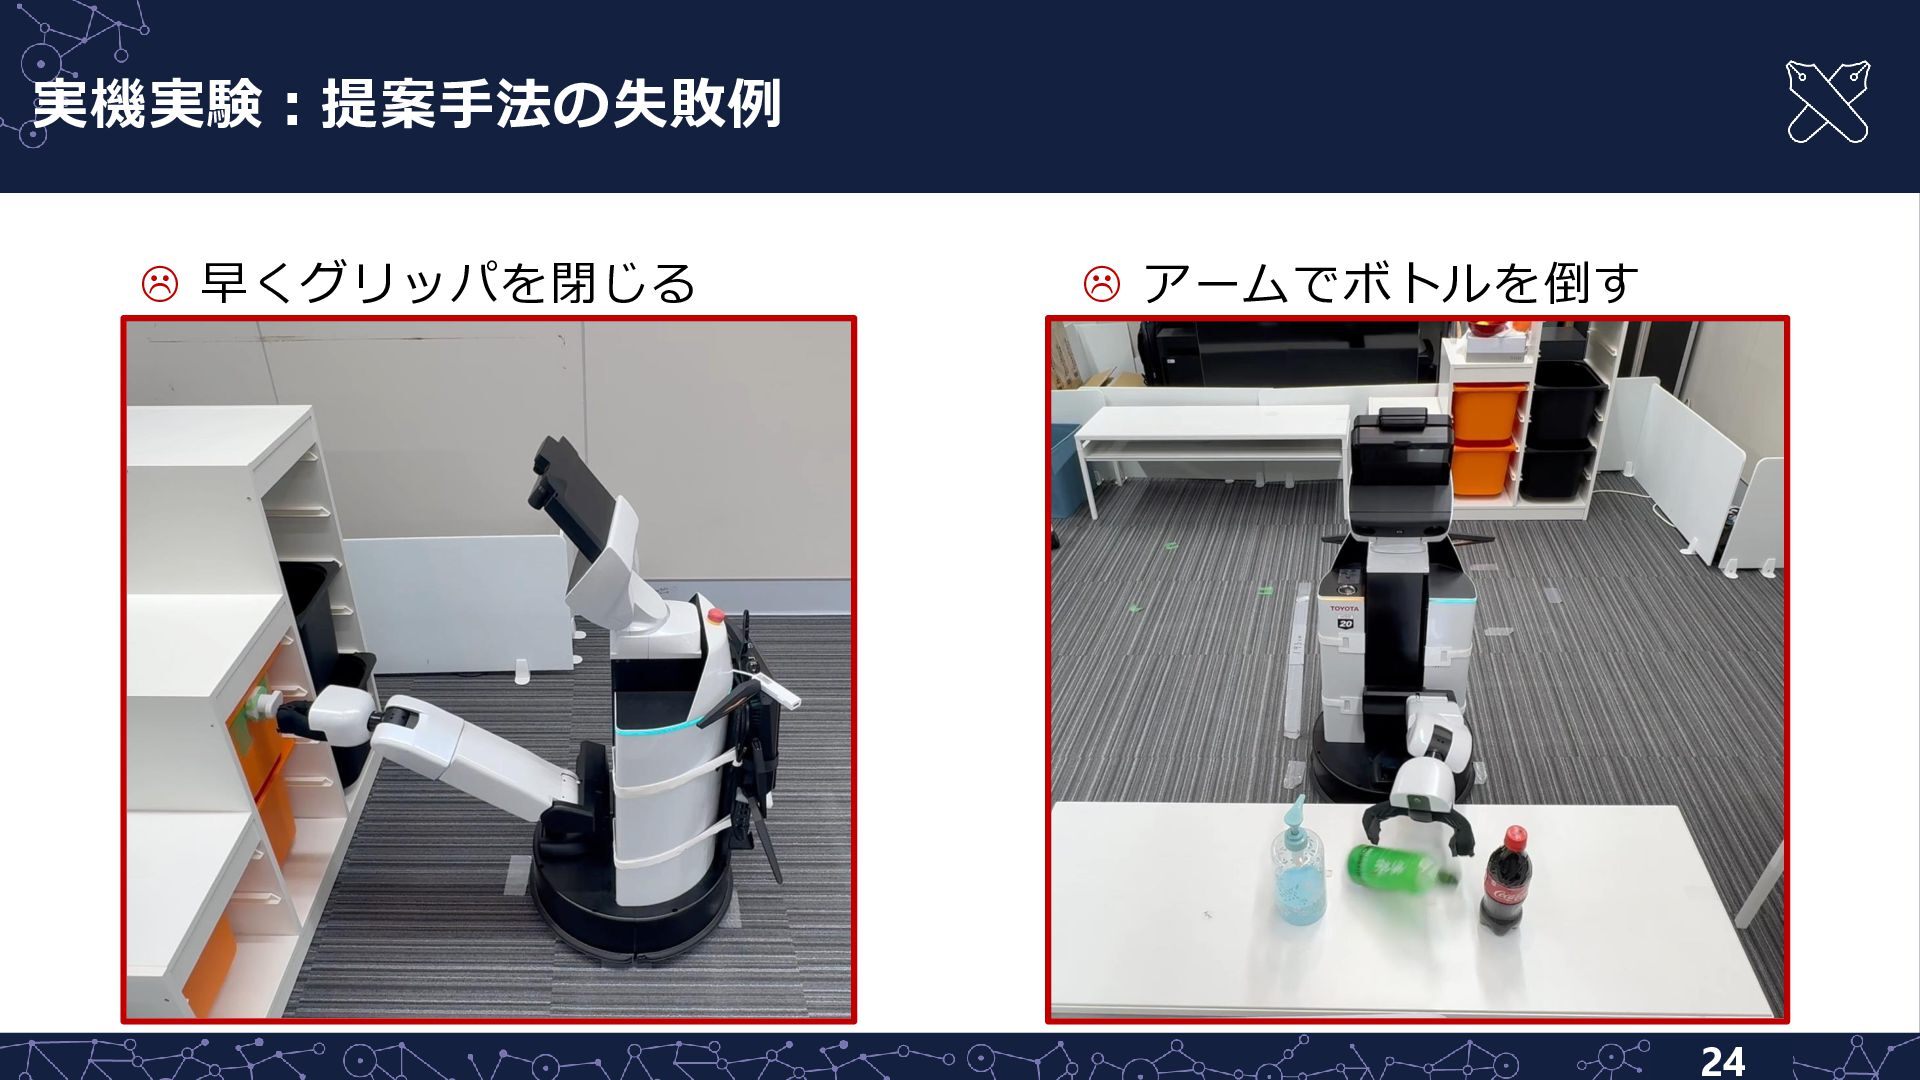
実機実験:提案手法の失敗例 早くグリッパを閉じる アームでボトルを倒す 24


 keio_smilab
 simosako
 ryujicre8ive
 ota1022
 vtryo
 kgnkhkr
 hinakko
 alchemy1115
 soudai
 nakanao
 sansantech
 magicpod
 tatetate55
 jnunemaker
 iamctodd
 jmmastey
 addyosmani
 inesmontani
 schroneko
 tamaranovitovic
 lauravandoore
 jacobtomlinson
 holman
 uxyall
 techseoconnect