Share
Embed
Making a strong and robust deep model by simple but effective data augmentation.
Sangdoo Yun
NAVER AI Research / OCR Research Scientist
https://linedevday.linecorp.com/jp/2019/sessions/F1-1
LINE DevDay 2019
November 20, 2019
Transcript
69 slides
-
2019 DevDay Making a Strong and Robust Deep Model by
Simple but Effective Data Augmentation. > Sangdoo Yun > NAVER AI Research / OCR Research Scientist -
This Talk Presents > How to solve computer vision tasks
using deep models. > Ways to train better and stronger deep models. Disclaimer: this talk does not include detailed mathematics and proof -
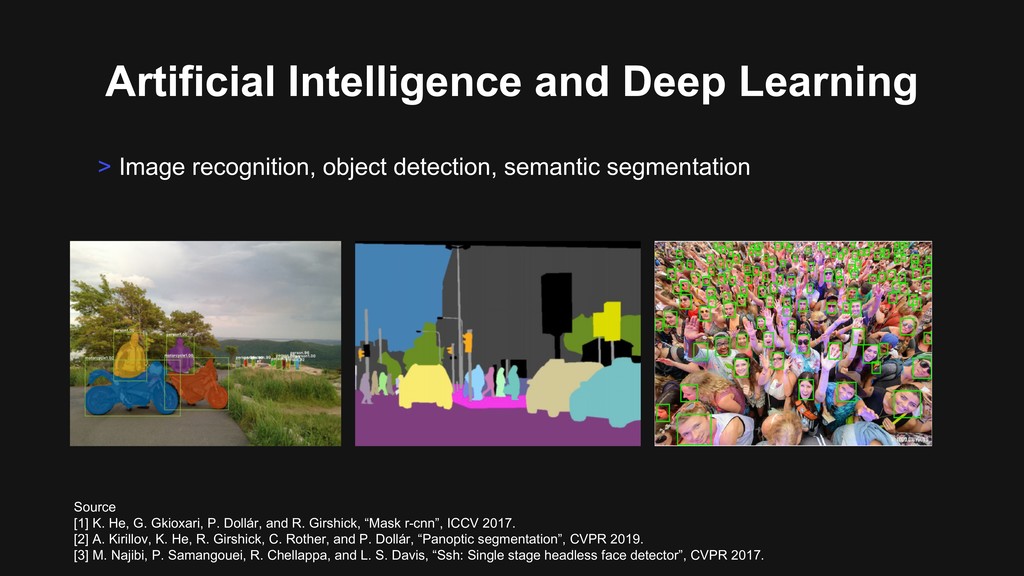
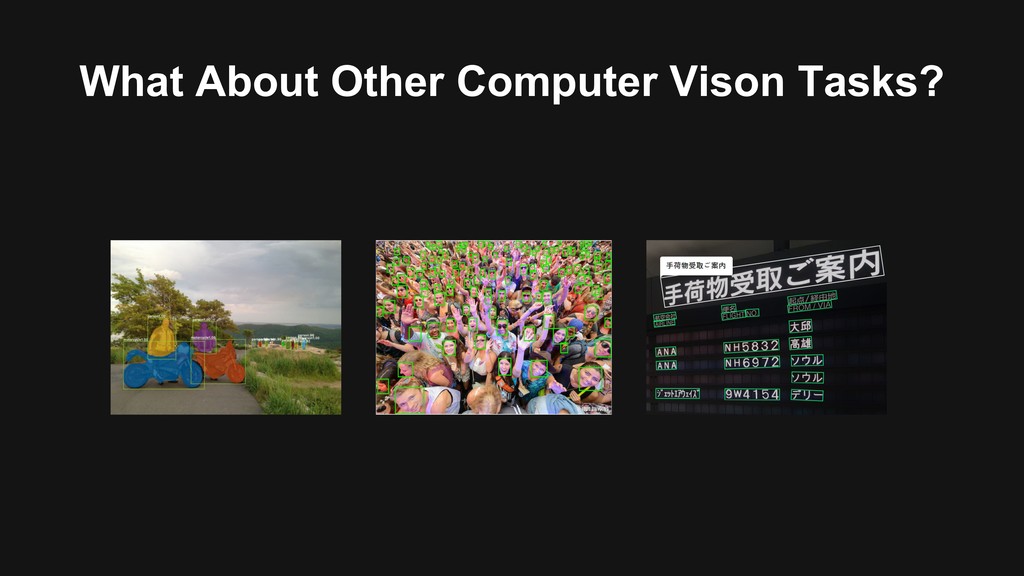
Artificial Intelligence and Deep Learning > Image recognition, object detection,
semantic segmentation Source [1] K. He, G. Gkioxari, P. Dollár, and R. Girshick, “Mask r-cnn”, ICCV 2017. [2] A. Kirillov, K. He, R. Girshick, C. Rother, and P. Dollár, “Panoptic segmentation”, CVPR 2019. [3] M. Najibi, P. Samangouei, R. Chellappa, and L. S. Davis, “Ssh: Single stage headless face detector”, CVPR 2017. -
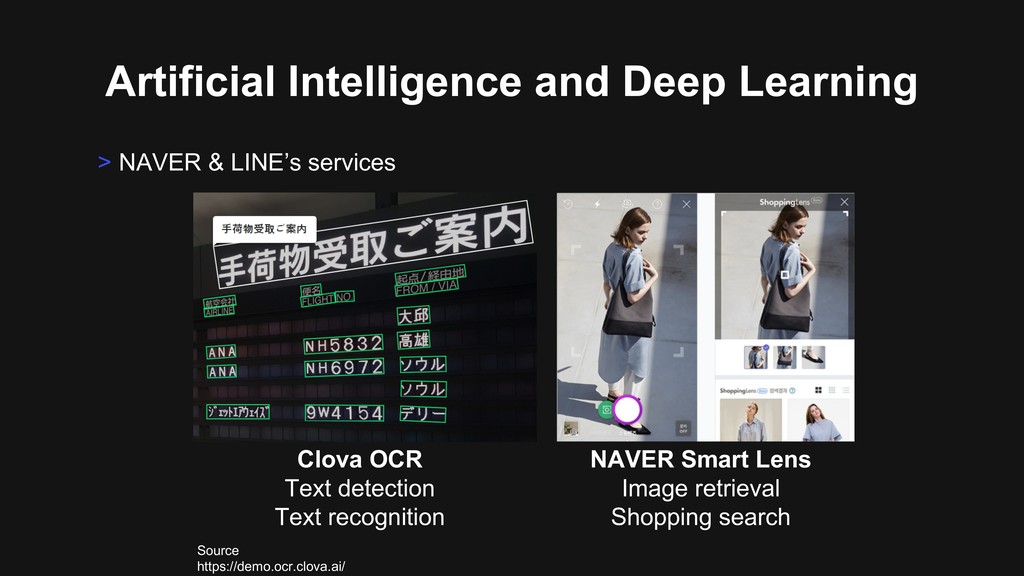
Artificial Intelligence and Deep Learning > NAVER & LINE’s services
Clova OCR Text detection Text recognition Source https://demo.ocr.clova.ai/ NAVER Smart Lens Image retrieval Shopping search -
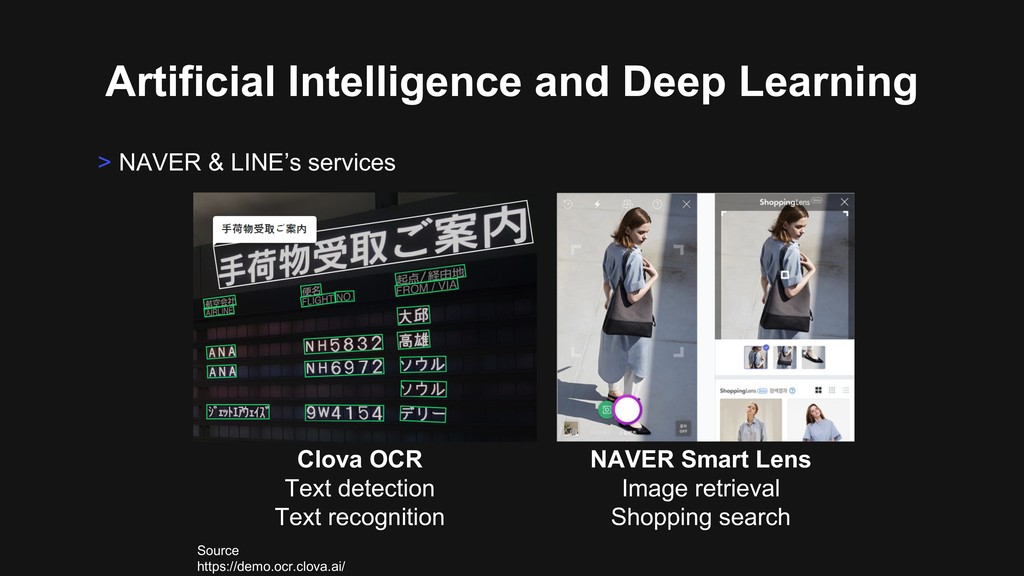
Artificial Intelligence and Deep Learning > NAVER & LINE’s services
Clova OCR Text detection Text recognition Source https://demo.ocr.clova.ai/ NAVER Smart Lens Image retrieval Shopping search -
Agenda > Deep CNN-based Image Recognition > Beyond Image Recognition:
Applying to My Own Tasks > A Simple and Effective Training Strategy -
Agenda > Deep CNN-based Image Recognition > Beyond Image Recognition:
Applying to My Own Tasks > A Simple and Effective Training Strategy -
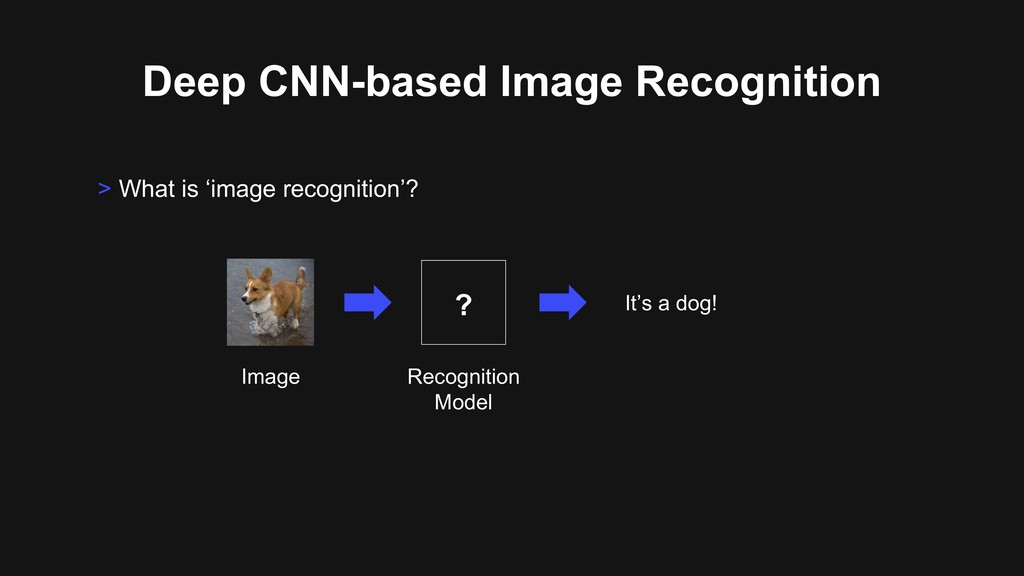
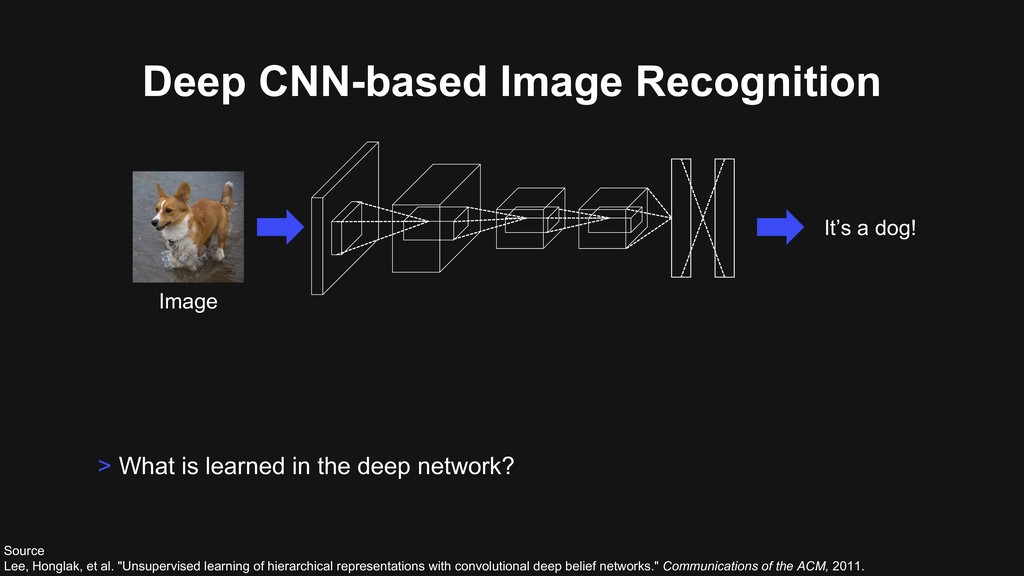
Deep CNN-based Image Recognition > What is ‘image recognition’? Image
Recognition Model It’s a dog! ? -
Deep CNN-based Image Recognition > We need lots of ‘training
data’ to teach a model Dog Cat Car ? Recognition Model -
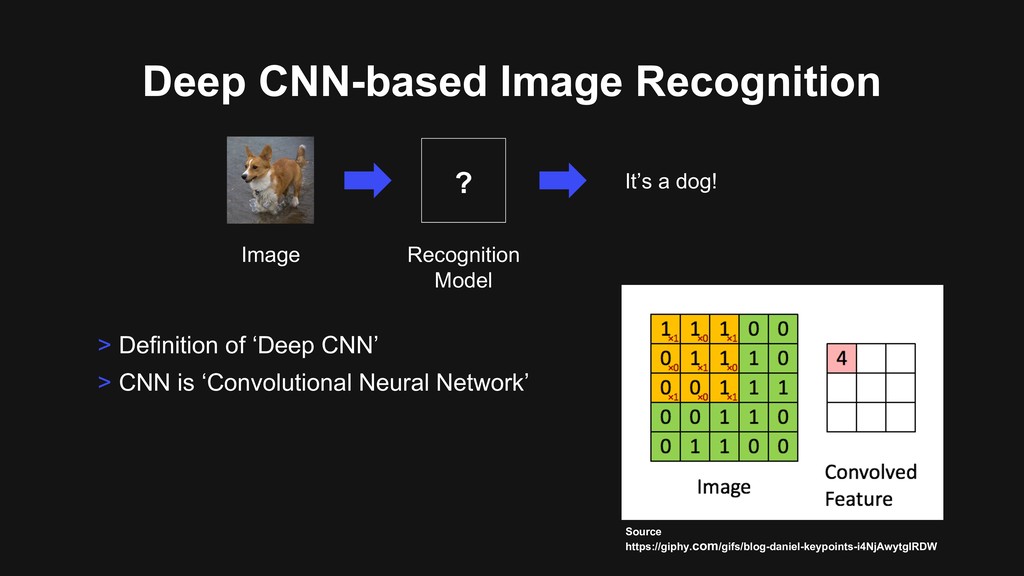
Deep CNN-based Image Recognition > Definition of ‘Deep CNN’ >
CNN is ‘Convolutional Neural Network’ Image Recognition Model It’s a dog! ? Source https://giphy.com/gifs/blog-daniel-keypoints-i4NjAwytgIRDW -
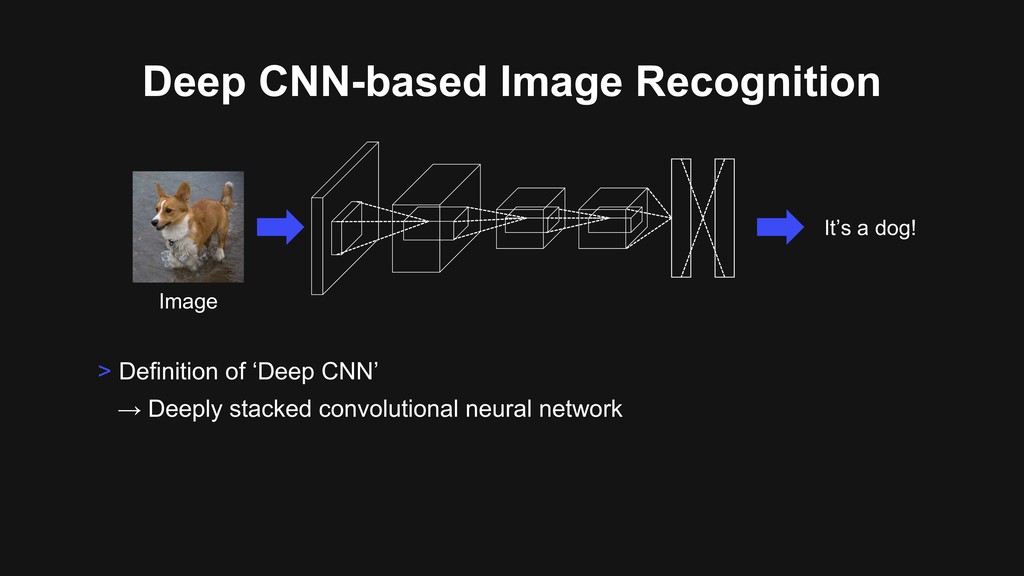
Deep CNN-based Image Recognition > Definition of ‘Deep CNN’ →
Deeply stacked convolutional neural network Image It’s a dog! -
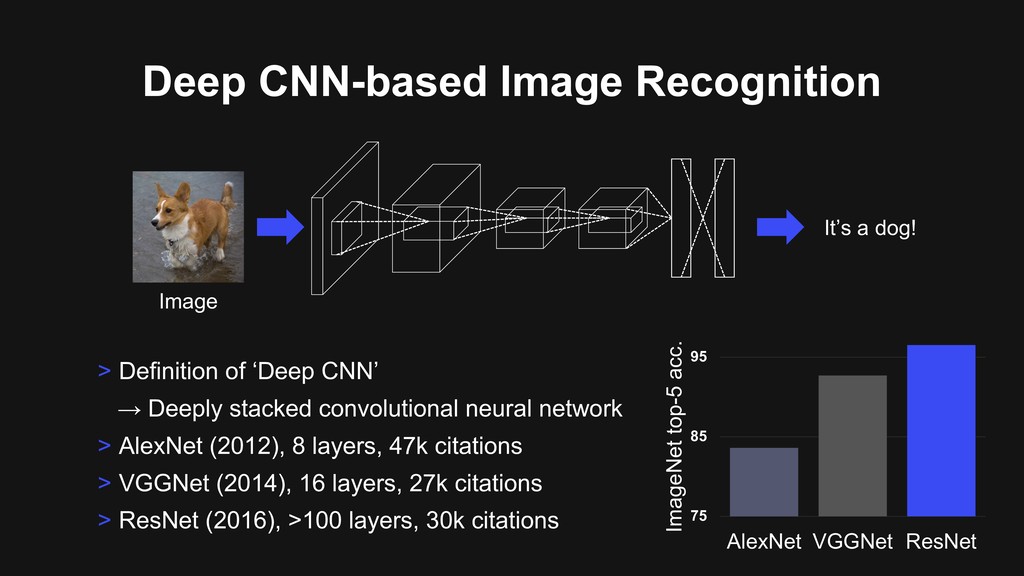
Deep CNN-based Image Recognition > Definition of ‘Deep CNN’ →
Deeply stacked convolutional neural network > AlexNet (2012), 8 layers, 47k citations > VGGNet (2014), 16 layers, 27k citations > ResNet (2016), >100 layers, 30k citations It’s a dog! Image 75 85 95 AlexNet VGGNet ResNet ImageNet top-5 acc. -
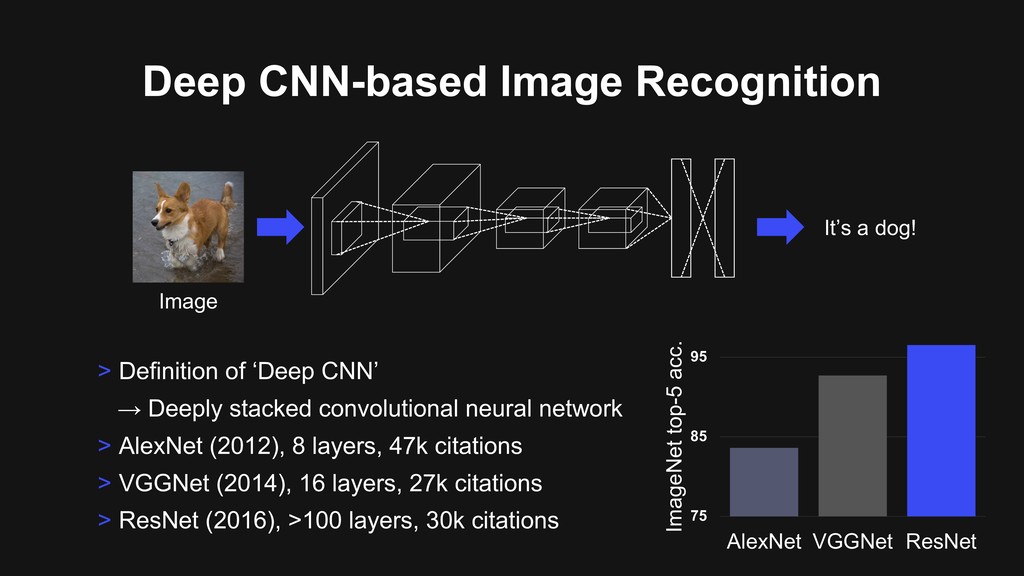
Deep CNN-based Image Recognition > Definition of ‘Deep CNN’ →
Deeply stacked convolutional neural network > AlexNet (2012), 8 layers, 47k citations > VGGNet (2014), 16 layers, 27k citations > ResNet (2016), >100 layers, 30k citations It’s a dog! Image 75 85 95 AlexNet VGGNet ResNet ImageNet top-5 acc. -
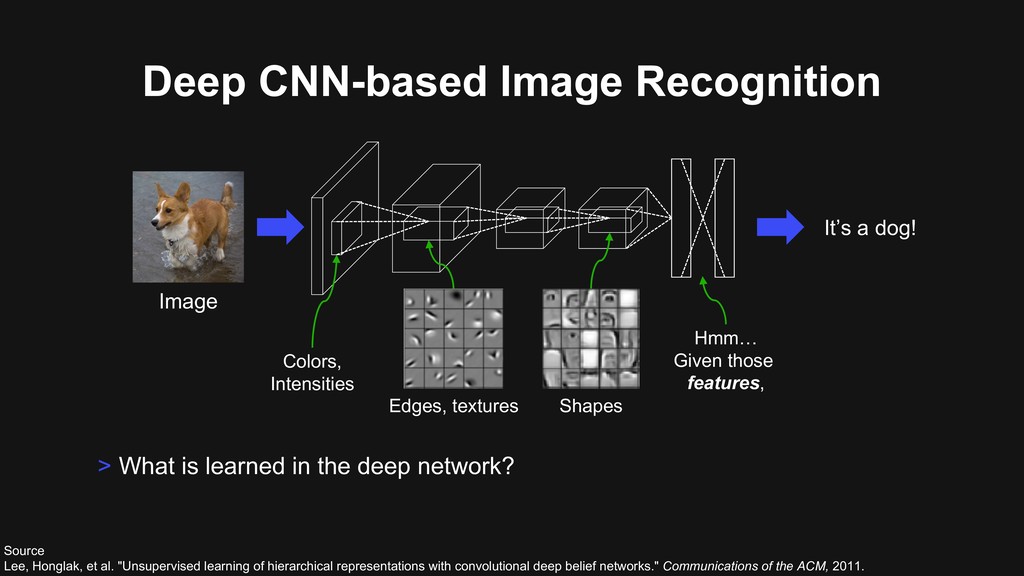
Deep CNN-based Image Recognition > What is learned in the
deep network? It’s a dog! Source Lee, Honglak, et al. "Unsupervised learning of hierarchical representations with convolutional deep belief networks." Communications of the ACM, 2011. Image -
Deep CNN-based Image Recognition > What is learned in the
deep network? It’s a dog! Edges, textures Shapes Colors, Intensities Hmm… Given those features, Source Lee, Honglak, et al. "Unsupervised learning of hierarchical representations with convolutional deep belief networks." Communications of the ACM, 2011. Image -
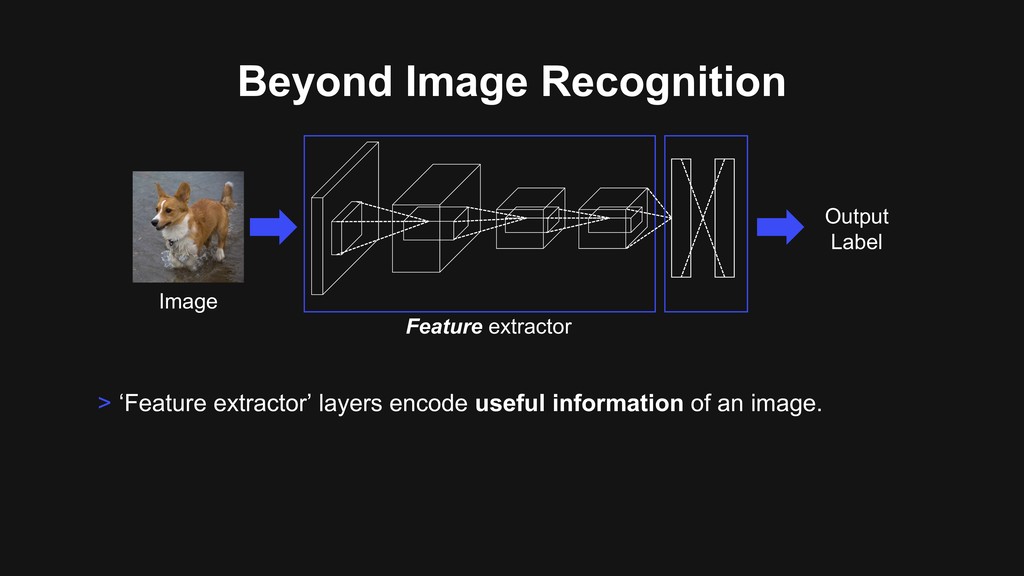
Beyond Image Recognition > ‘Feature extractor’ layers encode useful information
of an image. Output Label Feature extractor Image -
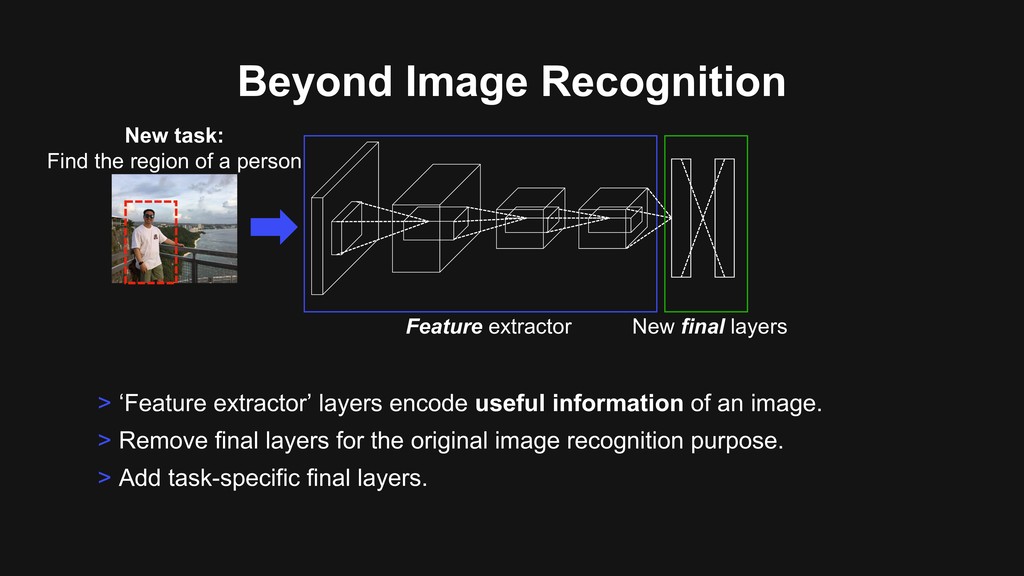
Beyond Image Recognition > ‘Feature extractor’ layers encode useful information
of an image. > Remove final layers for the original image recognition purpose. > Add task-specific final layers. Feature extractor New final layers New task: Find the region of a person -
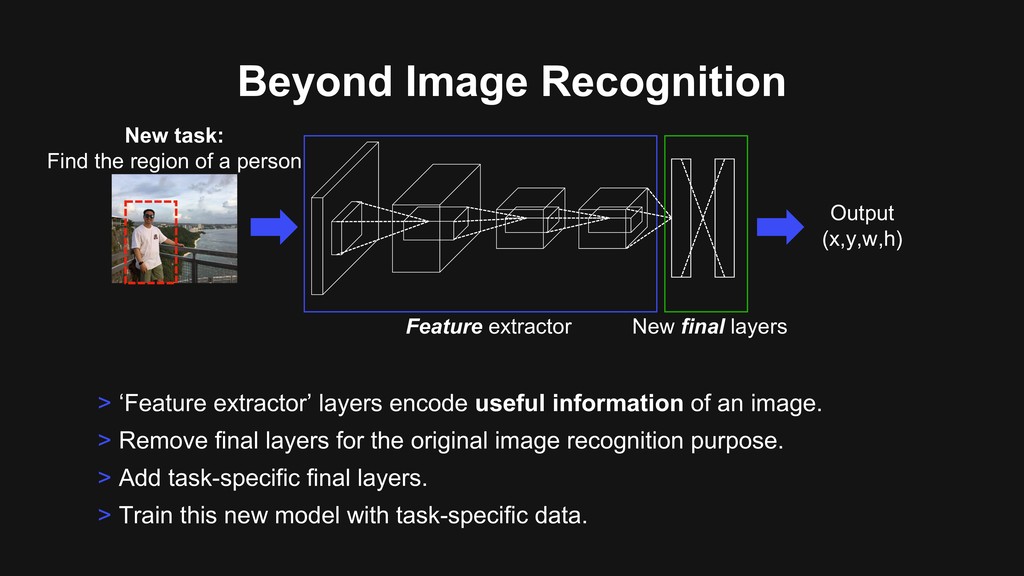
Beyond Image Recognition > ‘Feature extractor’ layers encode useful information
of an image. > Remove final layers for the original image recognition purpose. > Add task-specific final layers. > Train this new model with task-specific data. Feature extractor New final layers New task: Find the region of a person Output (x,y,w,h) -
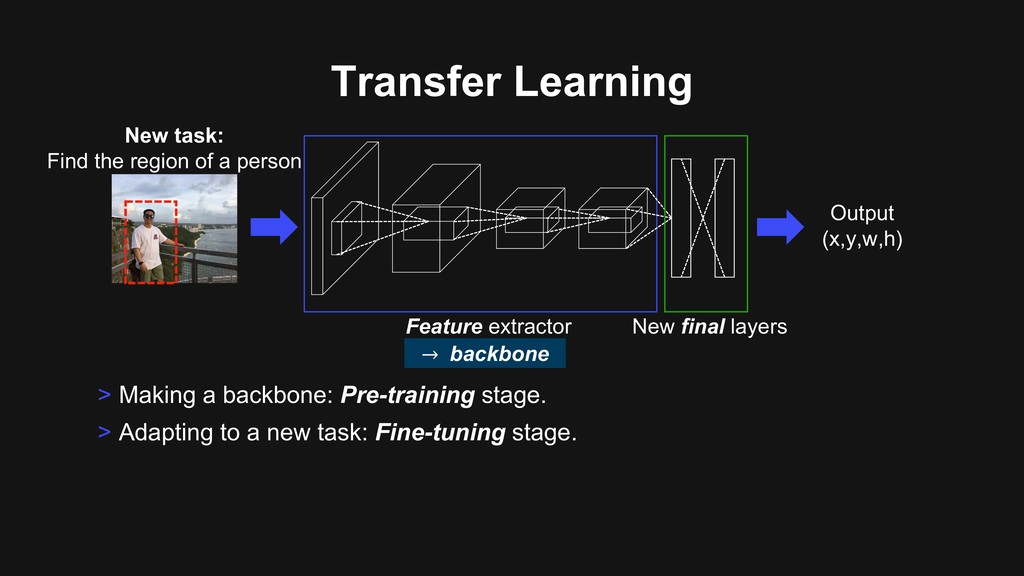
Transfer Learning > Making a backbone: Pre-training stage. > Adapting
to a new task: Fine-tuning stage. Feature extractor New final layers New task: Find the region of a person Output (x,y,w,h) → backbone -
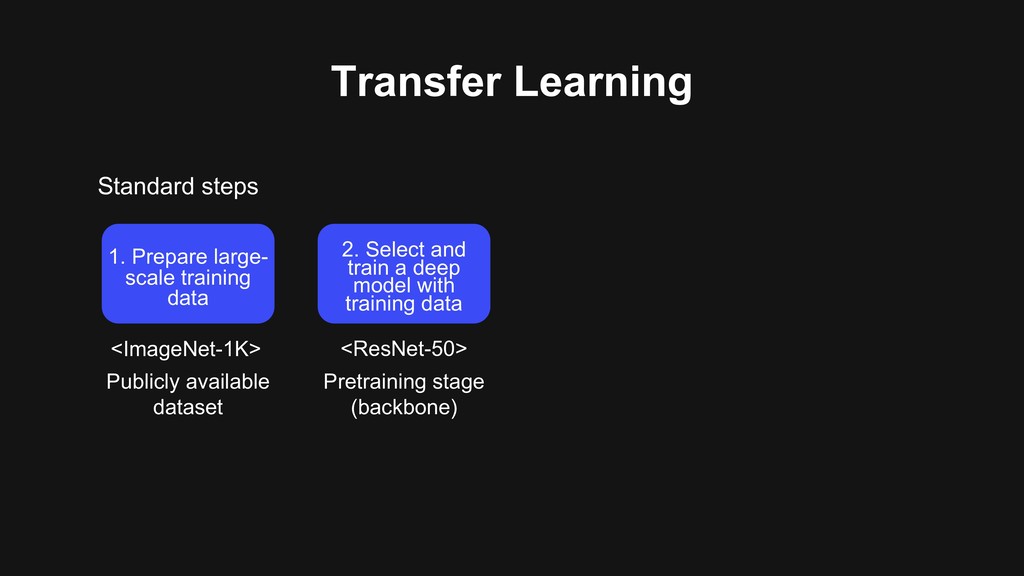
Transfer Learning Standard steps 1. Prepare large- scale training data
2. Select and train a deep model with training data <ImageNet-1K> <ResNet-50> Pretraining stage (backbone) Publicly available dataset -
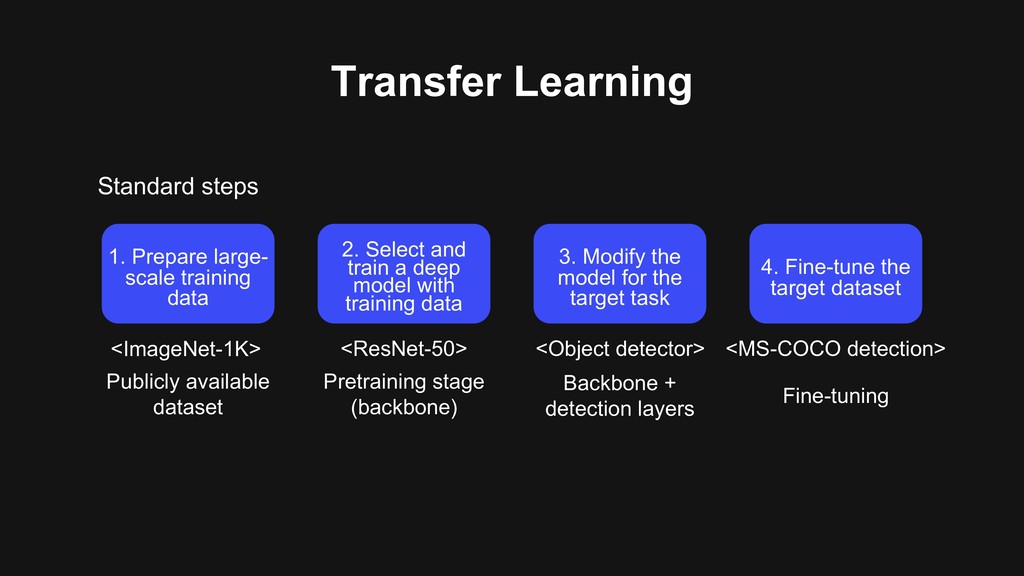
Transfer Learning Standard steps 1. Prepare large- scale training data
2. Select and train a deep model with training data 3. Modify the model for the target task 4. Fine-tune the target dataset <ImageNet-1K> <Object detector> <ResNet-50> <MS-COCO detection> Pretraining stage (backbone) Publicly available dataset Backbone + detection layers Fine-tuning -
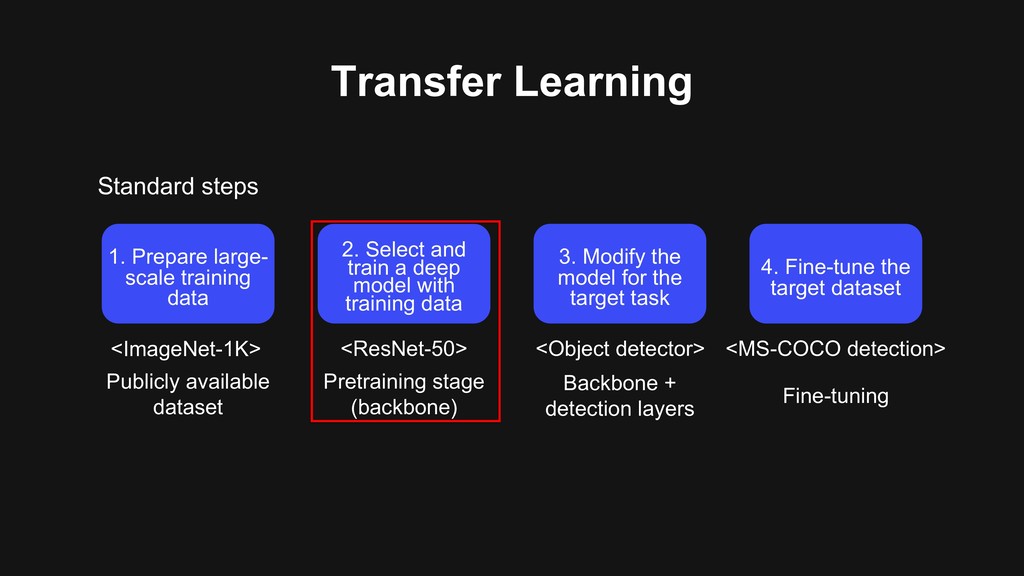
Transfer Learning Standard steps 1. Prepare large- scale training data
2. Select and train a deep model with training data 3. Modify the model for the target task 4. Fine-tune the target dataset <ImageNet-1K> <Object detector> <ResNet-50> <MS-COCO detection> Pretraining stage (backbone) Publicly available dataset Backbone + detection layers Fine-tuning -
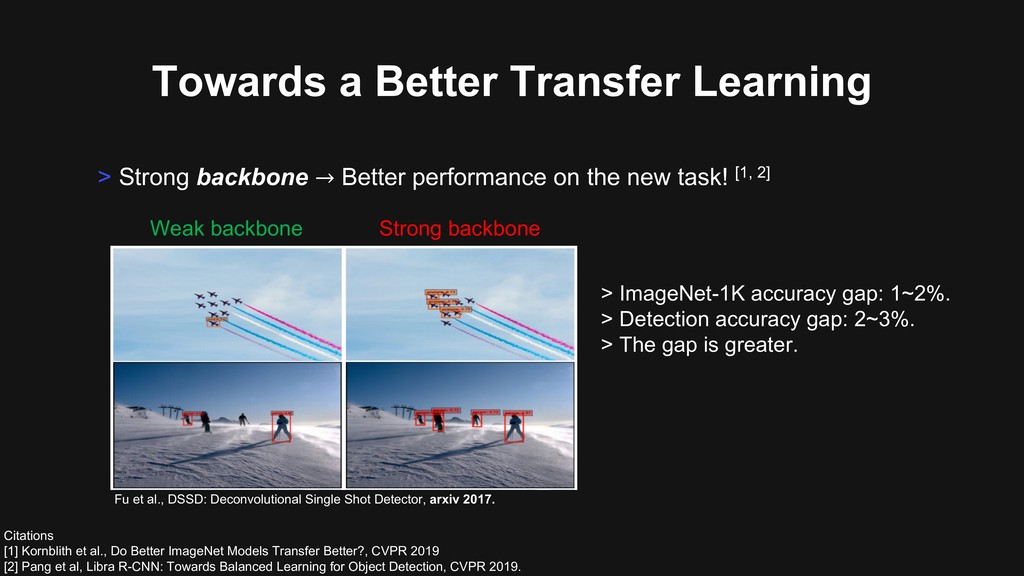
Towards a Better Transfer Learning > Strong backbone → Better
performance on the new task! [1, 2] -
Towards a Better Transfer Learning > Strong backbone → Better
performance on the new task! [1, 2] Citations [1] Kornblith et al., Do Better ImageNet Models Transfer Better?, CVPR 2019 [2] Pang et al, Libra R-CNN: Towards Balanced Learning for Object Detection, CVPR 2019. Weak backbone Strong backbone > ImageNet-1K accuracy gap: 1~2%. > Detection accuracy gap: 2~3%. > The gap is greater. Fu et al., DSSD: Deconvolutional Single Shot Detector, arxiv 2017. -
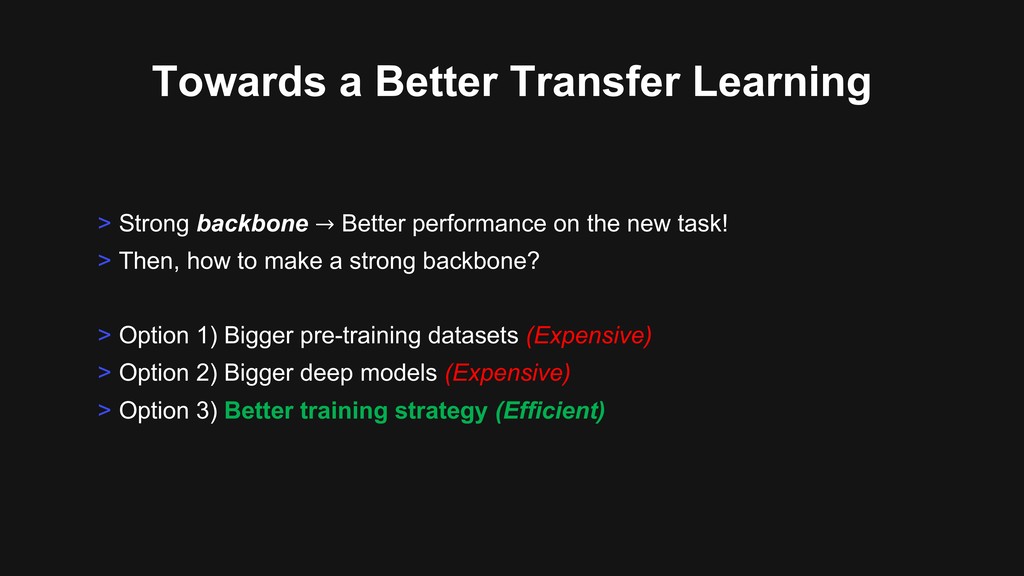
Towards a Better Transfer Learning > Strong backbone → Better
performance on the new task! > Then, how to make a strong backbone? -
Towards a Better Transfer Learning > Strong backbone → Better
performance on the new task! > Then, how to make a strong backbone? > Option 1) Bigger pre-training datasets (Expensive) > Option 2) Bigger deep models (Expensive) -
Towards a Better Transfer Learning > Strong backbone → Better
performance on the new task! > Then, how to make a strong backbone? > Option 1) Bigger pre-training datasets (Expensive) > Option 2) Bigger deep models (Expensive) > Option 3) Better training strategy (Efficient) -
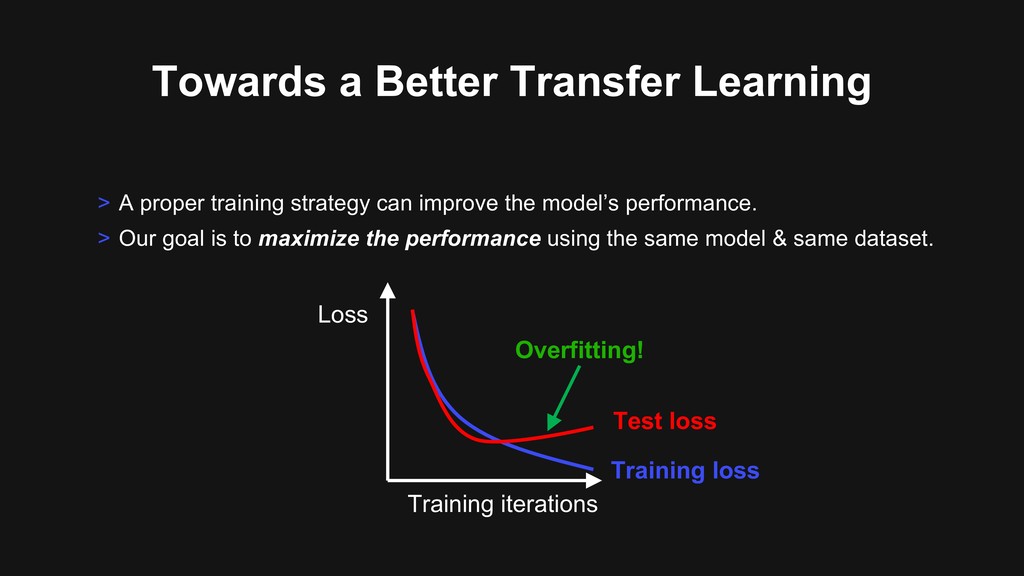
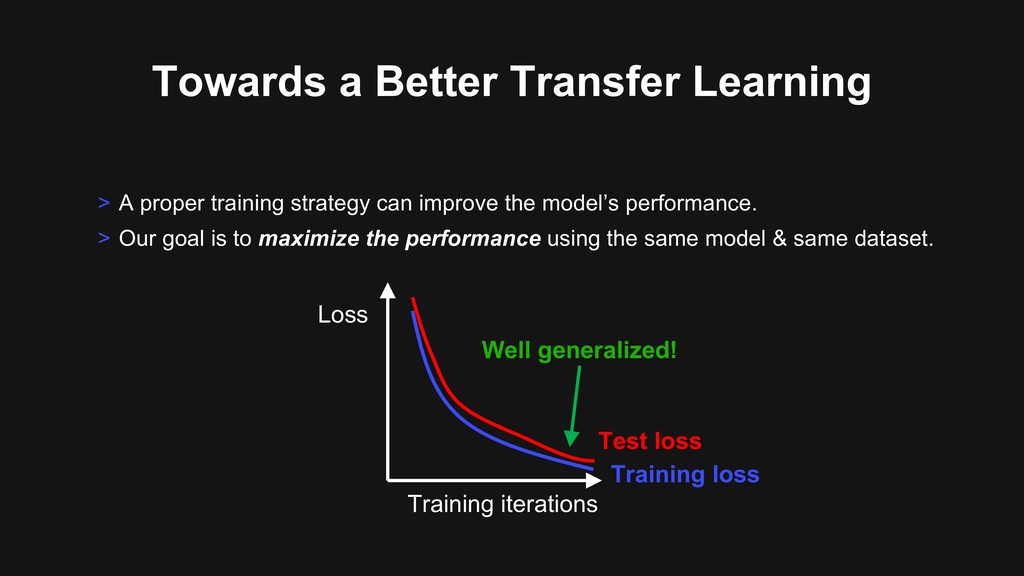
Towards a Better Transfer Learning > A proper training strategy
can improve the model’s performance. > Our goal is to maximize the performance using the same model & same dataset. -
Towards a Better Transfer Learning > A proper training strategy
can improve the model’s performance. > Our goal is to maximize the performance using the same model & same dataset. Loss Training iterations Training loss Test loss Overfitting! -
Towards a Better Transfer Learning > A proper training strategy
can improve the model’s performance. > Our goal is to maximize the performance using the same model & same dataset. Loss Training iterations Training loss Test loss Well generalized! -
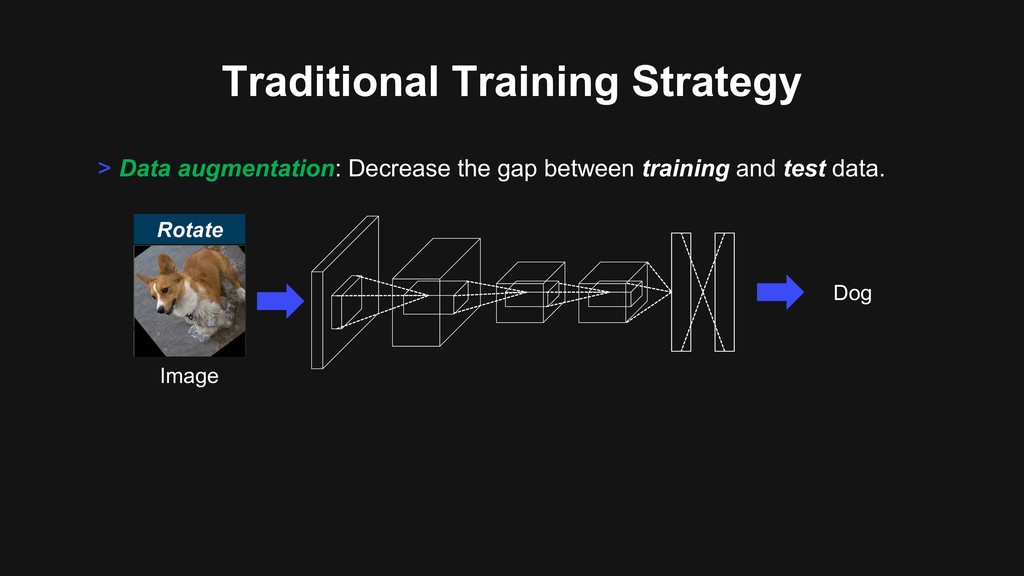
> Data augmentation: Decrease the gap between training and test
data. Image Dog Flip Resize Traditional Training Strategy Rotate -
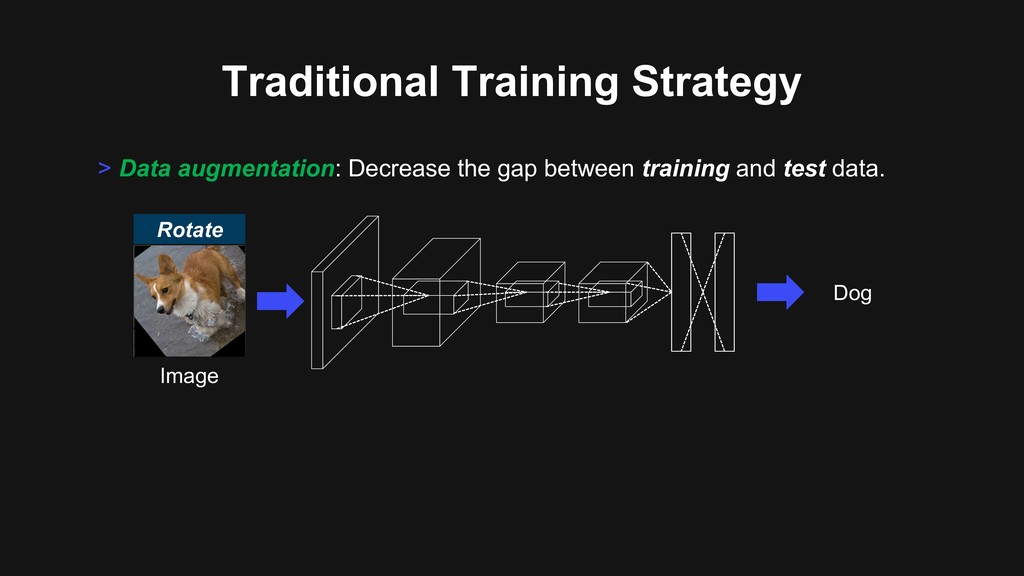
> Data augmentation: Decrease the gap between training and test
data. Image Dog Flip Resize Traditional Training Strategy Rotate -
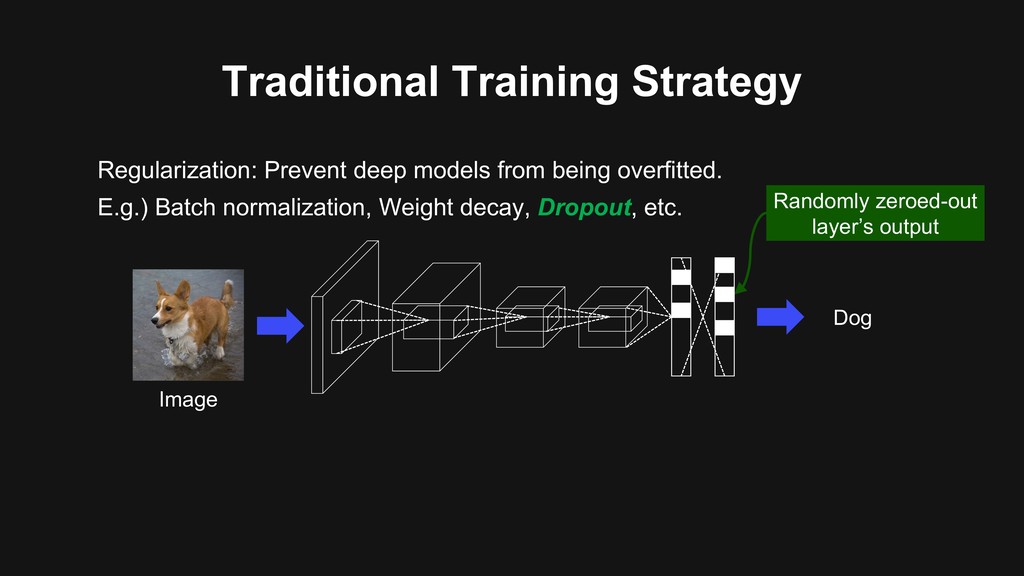
Regularization: Prevent deep models from being overfitted. E.g.) Batch normalization,
Weight decay, Dropout, etc. Traditional Training Strategy -
Regularization: Prevent deep models from being overfitted. E.g.) Batch normalization,
Weight decay, Dropout, etc. Dog Randomly zeroed-out layer’s output Traditional Training Strategy Image -
Image Regional Dropout strategy “Cutout” [1, 2]: randomly remove image
regions Recent works [1] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. [2] Zhong et al., “Random erasing data augmentation”, arXiv 2017. Dog -
Image Regional Dropout strategy “Cutout” [1, 2]: randomly remove image
regions Recent works [1] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. [2] Zhong et al., “Random erasing data augmentation”, arXiv 2017. Dog → make “occlusion-robust” backbone ✓ Good generalization ability ✘ Cannot utilize full image regions -
Recent works Image Dog > Mixup[1] regularization Cat Dog 0.5
Cat 0.5 [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. -
Dog 0.5 Cat 0.5 Recent works Image > Mixup[1] regularization
→ make backbone robust to uncertain samples ✓ Good generalization ability ✓ Use full image region ✘ Locally unrealistic image [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. -
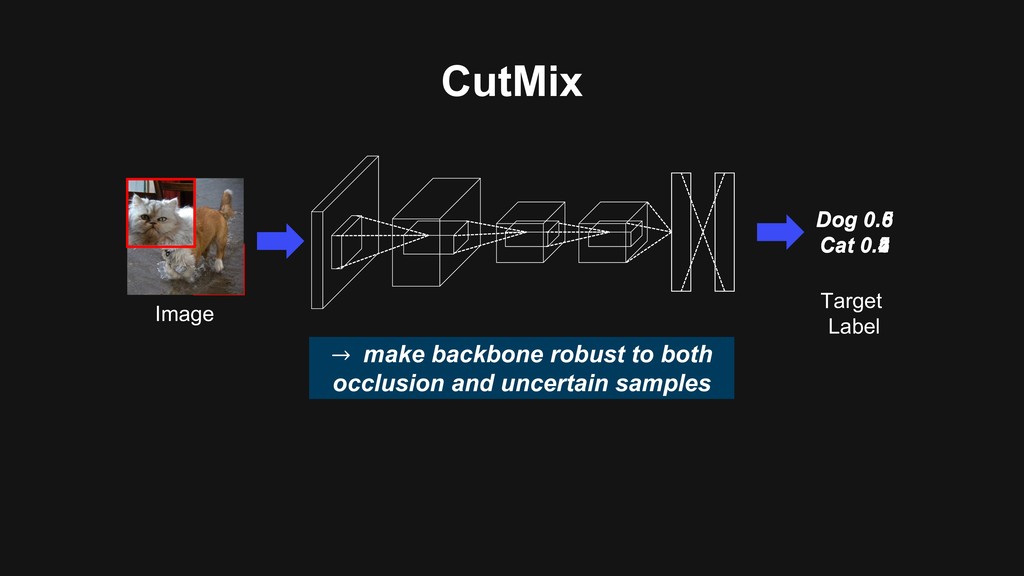
CutMix Dog 1.0 Target Label Input Image Dog 0.5 Cat
0.5 Label is decided by the pixel ratio of each image Cut Paste Cat 1.0 -
CutMix Image Dog 0.6 Cat 0.4 → make backbone robust
to both occlusion and uncertain samples Dog 0.8 Cat 0.2 Target Label Dog 0.5 Cat 0.5 -
CutMix: Regularization Strategy to Train Strong Classifiers with Localizable Features
Sangdoo Yun Clova AI Naver Dongyoon Han Clova AI Naver Seong Joon Oh Clova AI LINE+ Sanghyuk Chun Clova AI Naver Junsuk Choe* Yonsei University Youngjoon Yoo Clova AI Naver * Intern at Clova. Presented at ICCV 2019, Korea -
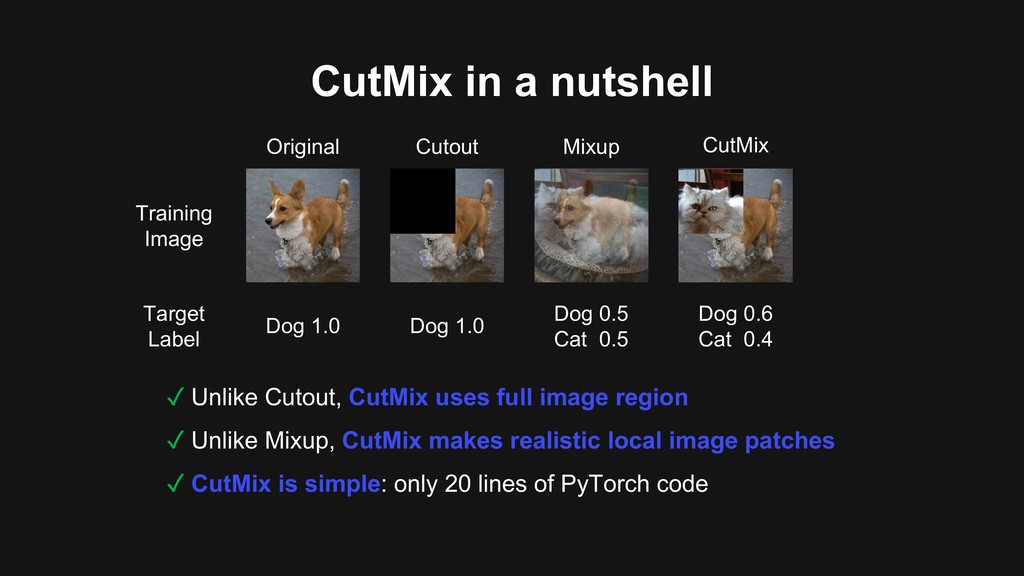
CutMix in a nutshell Original Cutout Mixup Training Image Target
Label Dog 1.0 Dog 1.0 Dog 0.5 Cat 0.5 CutMix Dog 0.6 Cat 0.4 ✓ Unlike Cutout, CutMix uses full image region ✓ Unlike Mixup, CutMix makes realistic local image patches ✓ CutMix is simple: only 20 lines of PyTorch code -
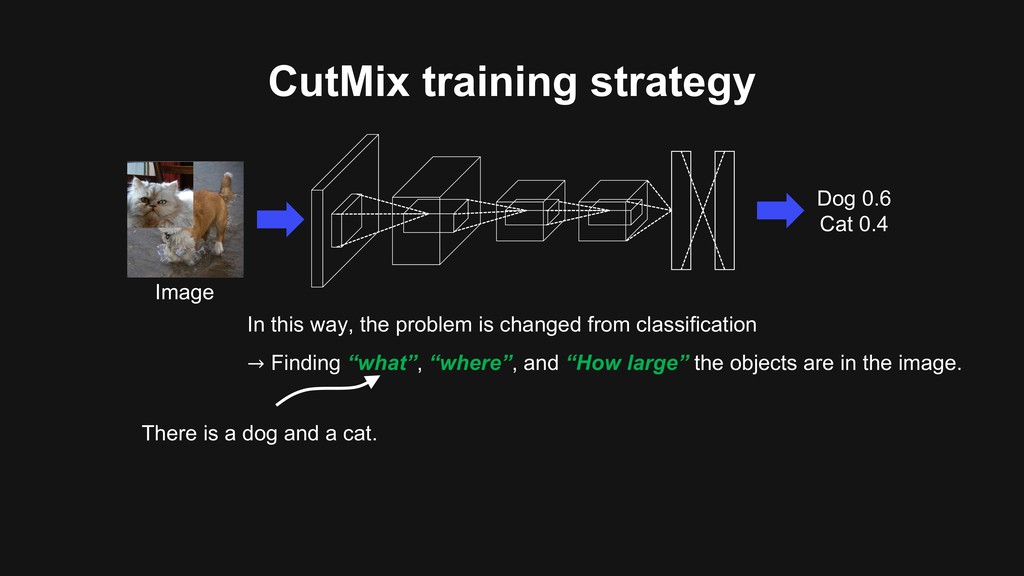
CutMix training strategy Image Dog 0.6 Cat 0.4 In this
way, the problem is changed from classification → Finding “what”, “where”, and “How large” the objects are in the image. There is a dog and a cat. -
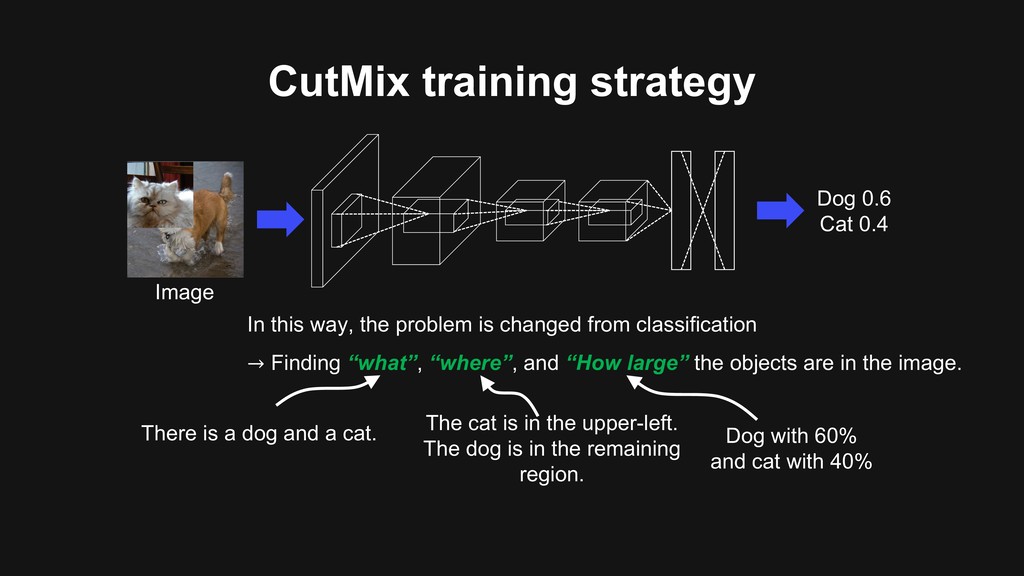
CutMix training strategy Image Dog 0.6 Cat 0.4 In this
way, the problem is changed from classification → Finding “what”, “where”, and “How large” the objects are in the image. There is a dog and a cat. The cat is in the upper-left. The dog is in the remaining region. Dog with 60% and cat with 40% -
What does the model learn with CutMix? [1] Zhou et
al., Learning Deep Features for Discriminative Localization, CVPR 2016. Heatmap visualization[1]: Where does the model recognize the object? -
What does the model learn with CutMix? [1] Zhou et
al., Learning Deep Features for Discriminative Localization, CVPR 2016. Heatmap visualization[1]: Where does the model recognize the object? Heatmap of St. Bernard Heatmap of Poodle -
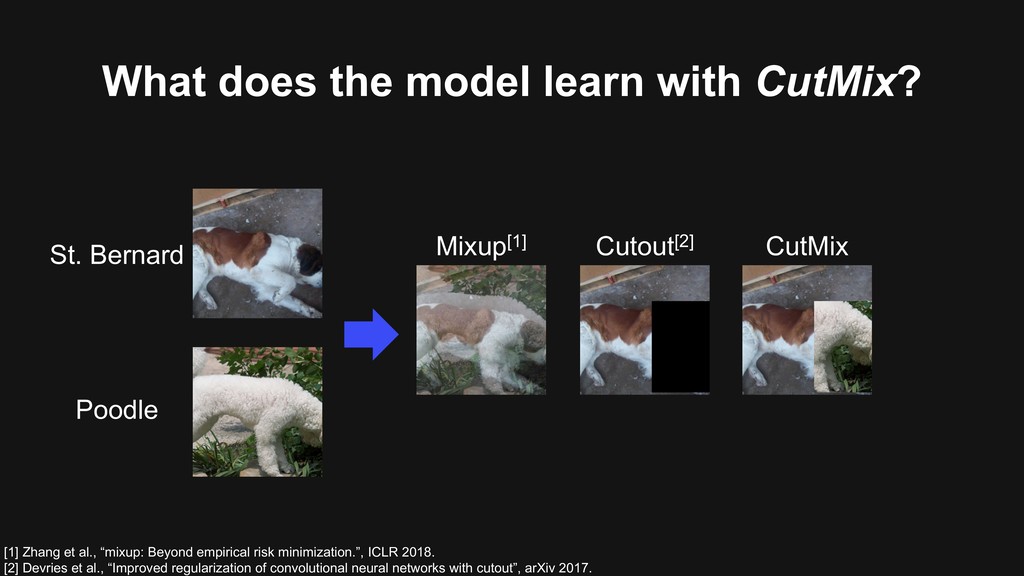
What does the model learn with CutMix? St. Bernard Poodle
Mixup[1] Cutout[2] CutMix [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Cutout[2] CutMix Heatmap
of St. Bernard [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Cutout[2] CutMix Heatmap
of St. Bernard Heatmap of Poodle [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Mixup[1] CutMix Heatmap
of St. Bernard [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Mixup[1] CutMix Heatmap
of St. Bernard Heatmap of Poodle [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Mixup[1] CutMix Heatmap
of St. Bernard Heatmap of Poodle [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
What does the model learn with CutMix? Mixup[1] Cutout[2] CutMix
Heatmap of St. Bernard Heatmap of Poodle [1] Zhang et al., “mixup: Beyond empirical risk minimization.”, ICLR 2018. [2] Devries et al., “Improved regularization of convolutional neural networks with cutout”, arXiv 2017. -
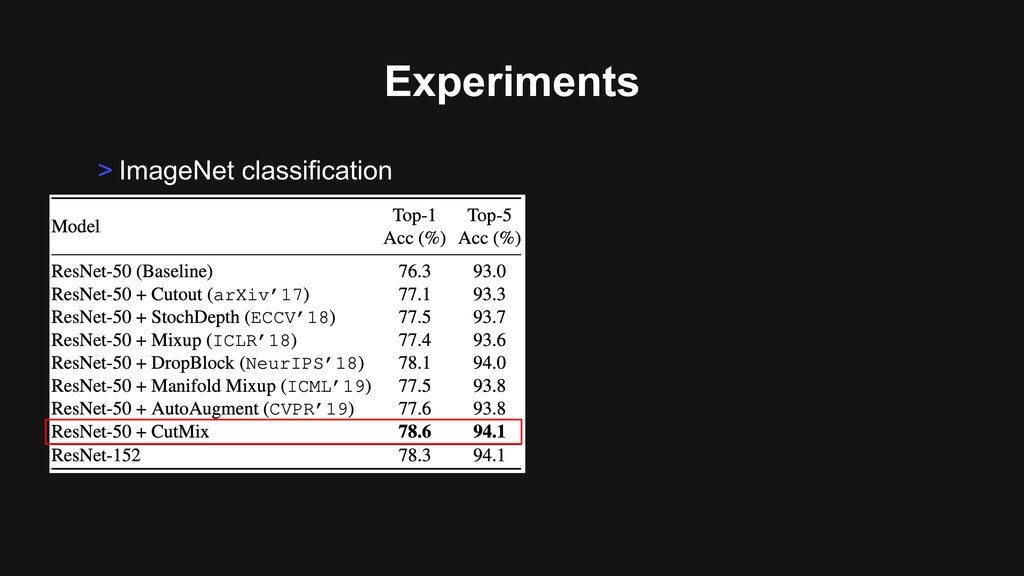
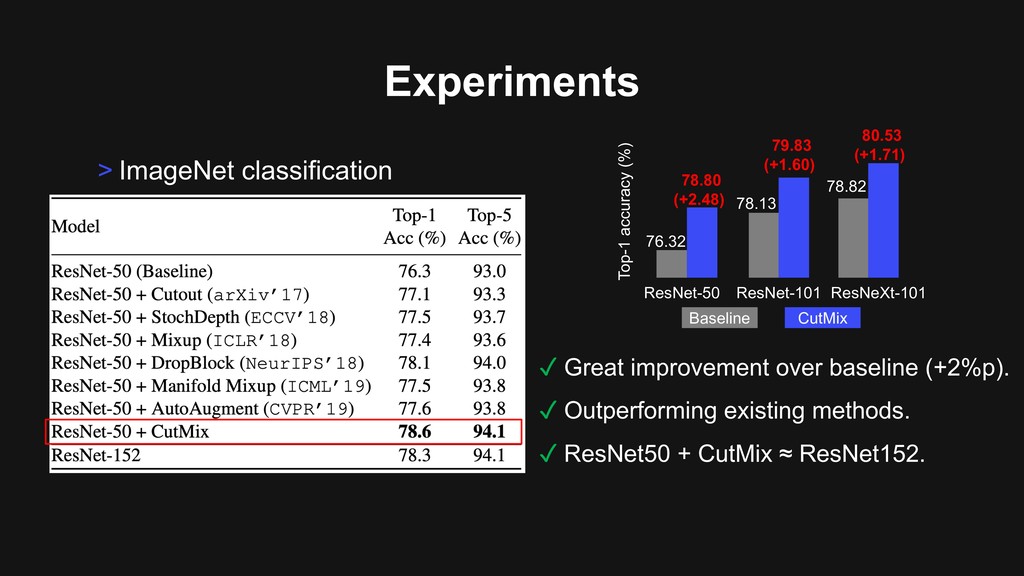
> ImageNet classification Experiments ✓ Great improvement over baseline (+2%p).
✓ Outperforming existing methods. ✓ ResNet50 + CutMix ≈ ResNet152. ResNeXt-101 ResNet-50 ResNet-101 76.32 78.80 (+2.48) 78.13 79.83 (+1.60) 78.82 80.53 (+1.71) Top-1 accuracy (%) Baseline CutMix -
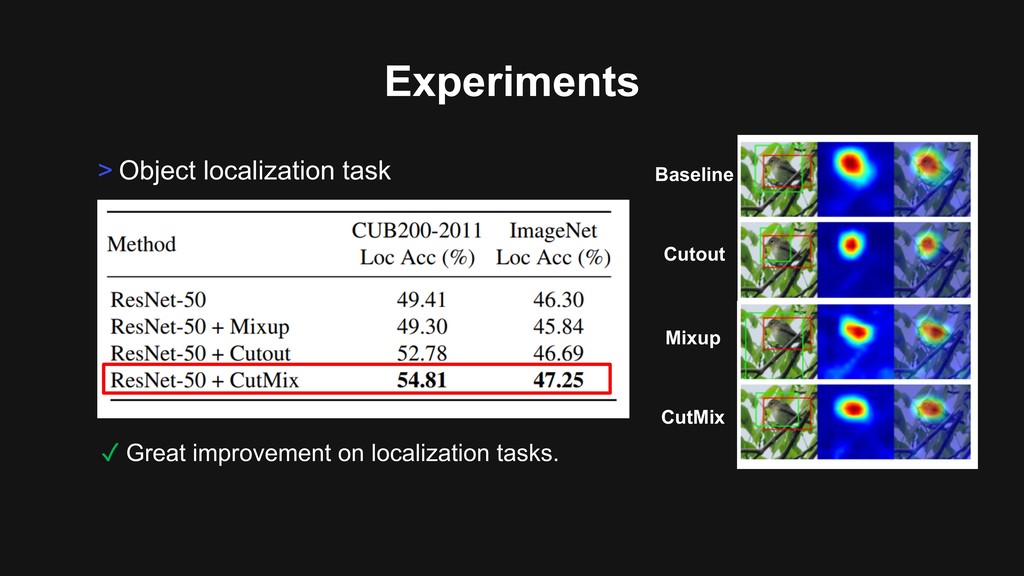
> Object localization task Experiments ✓ Great improvement on localization
tasks. Baseline Cutout Mixup CutMix -
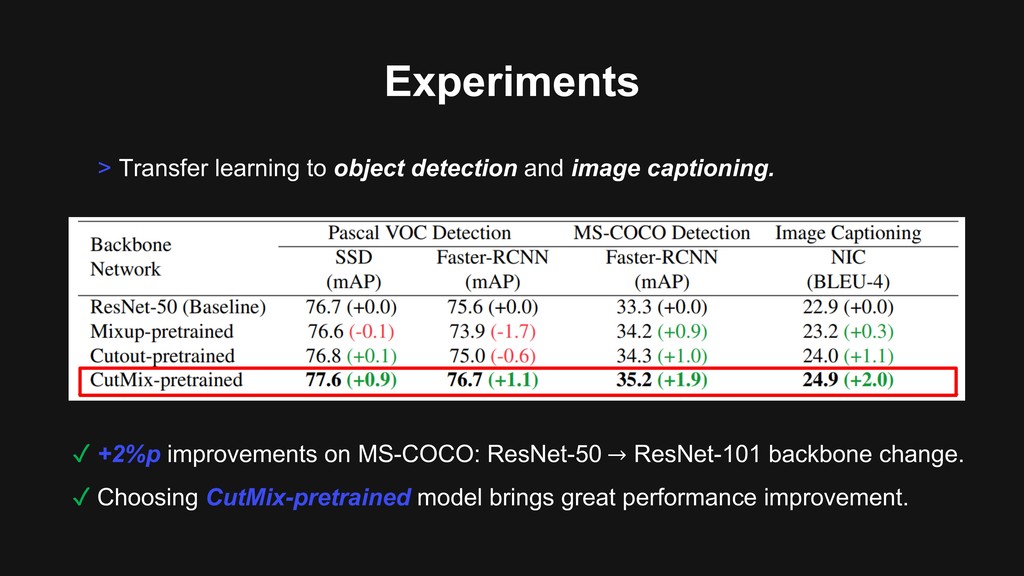
> Transfer learning to object detection and image captioning. Experiments
Ren et al., Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks, NIPS 2015. Karpathy et el., Deep Visual-Semantic Alignments for Generating Image Descriptions, CVPR 2015. -
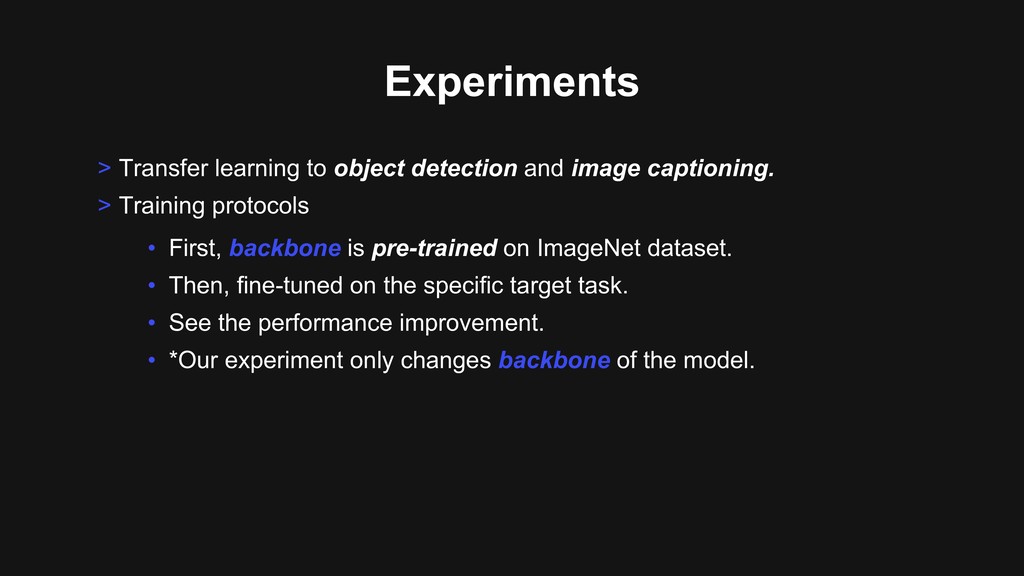
> Transfer learning to object detection and image captioning. >
Training protocols Experiments • First, backbone is pre-trained on ImageNet dataset. • Then, fine-tuned on the specific target task. • See the performance improvement. • *Our experiment only changes backbone of the model. -
Experiments > Transfer learning to object detection and image captioning.
✓ +2%p improvements on MS-COCO: ResNet-50 → ResNet-101 backbone change. ✓ Choosing CutMix-pretrained model brings great performance improvement. -
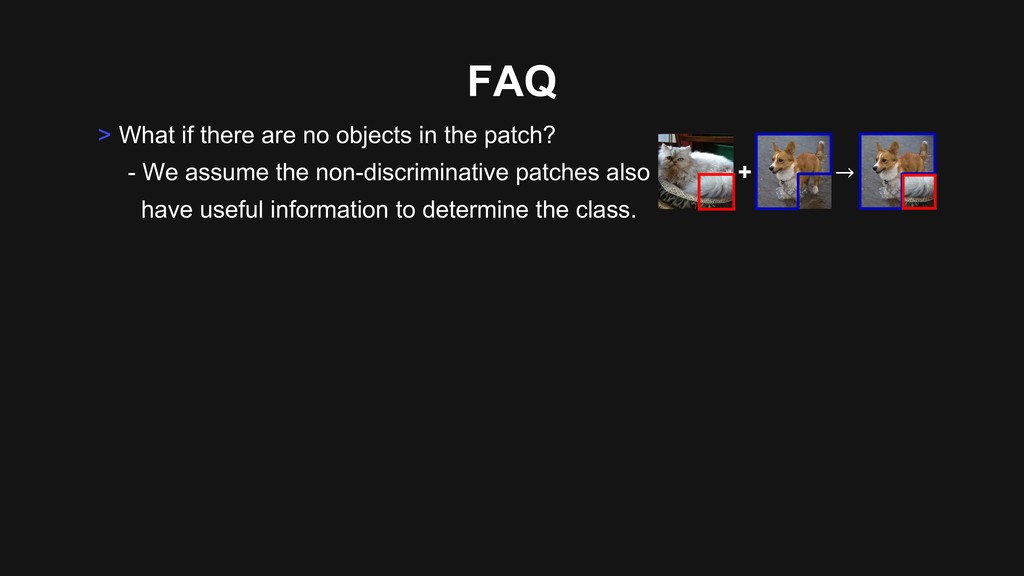
> What if there are no objects in the patch?
- We assume the non-discriminative patches also have useful information to determine the class. FAQ + → -
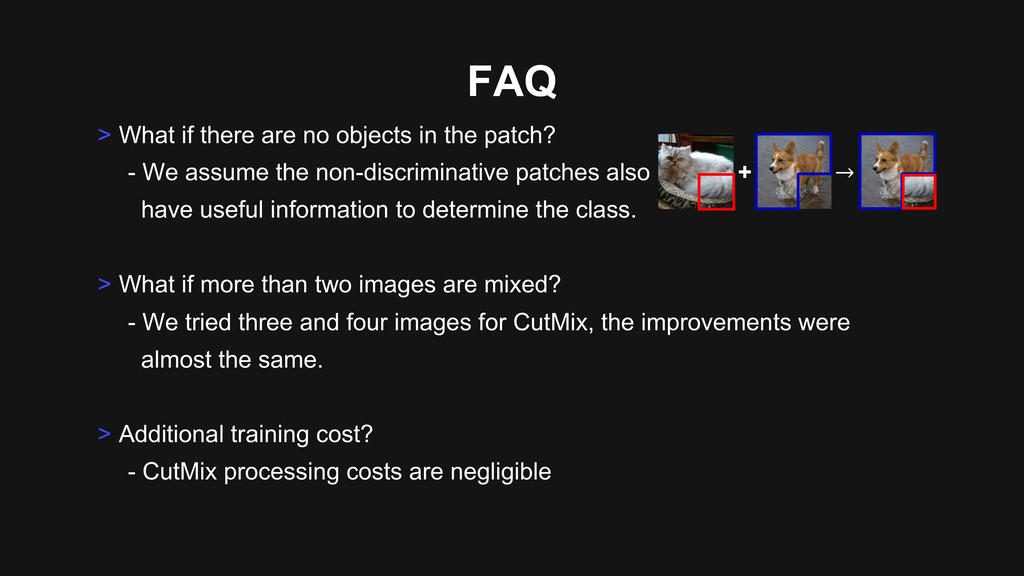
> What if there are no objects in the patch?
- We assume the non-discriminative patches also have useful information to determine the class. > What if more than two images are mixed? - We tried three and four images for CutMix, the improvements were almost the same. > Additional training cost? - CutMix processing costs are negligible FAQ + → -
Conclusion > Training a strong classifier is important for many
computer vision tasks. -
Conclusion > Training a strong classifier is important for many
computer vision tasks. > Need to train a strong and robust classifier → Apply CutMix regularizer to your classifier. > Need a better pre-trained model for transfer learning → Download our CutMix-pretrained model. > Visit our website (codes & models): https://github.com/clovaai/CutMix-PyTorch