Share
Embed
Transcript
51 slides
-
Agenda 1. Issue 2. Gathering Statistics 3. Injecting Custom Optimization
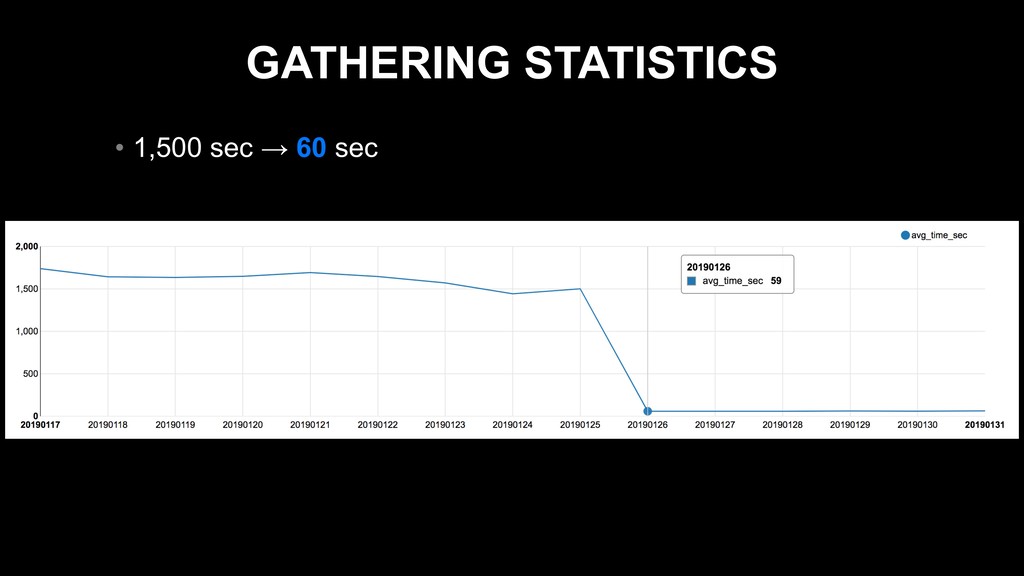
Rules 4. Cost-based Optimizer -
Agenda 1. Issue 2. Gathering Statistics 3. Injecting Custom Optimization
Rules 4. Cost-based Optimizer -
Users / Day 1,300+ Spark Apps / Day 7,000+ Spark
Jobs / Day 200+ USAGE -
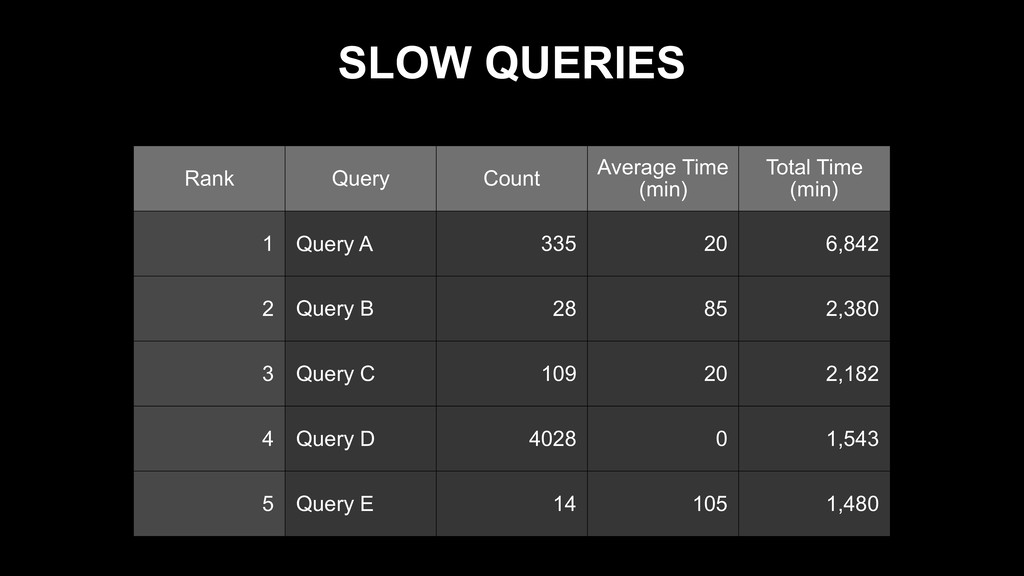
SLOW QUERIES Rank Query Count Average Time (min) Total Time
(min) 1 Query A 335 20 6,842 2 Query B 28 85 2,380 3 Query C 109 20 2,182 4 Query D 4028 0 1,543 5 Query E 14 105 1,480 -
IMPACTS • Speed of data analysis and decision making •
Usage efficiency of computing resources -
CHALLENGES FOR END USERS • Acquiring knowledge and skills of
data engineering • Taking care of queries’ performances • Changing queries and tables in the production environment -
Agenda 1. Issue 2. Gathering Statistics 3. Injecting Custom Optimization
Rules 4. Cost-based Optimizer -
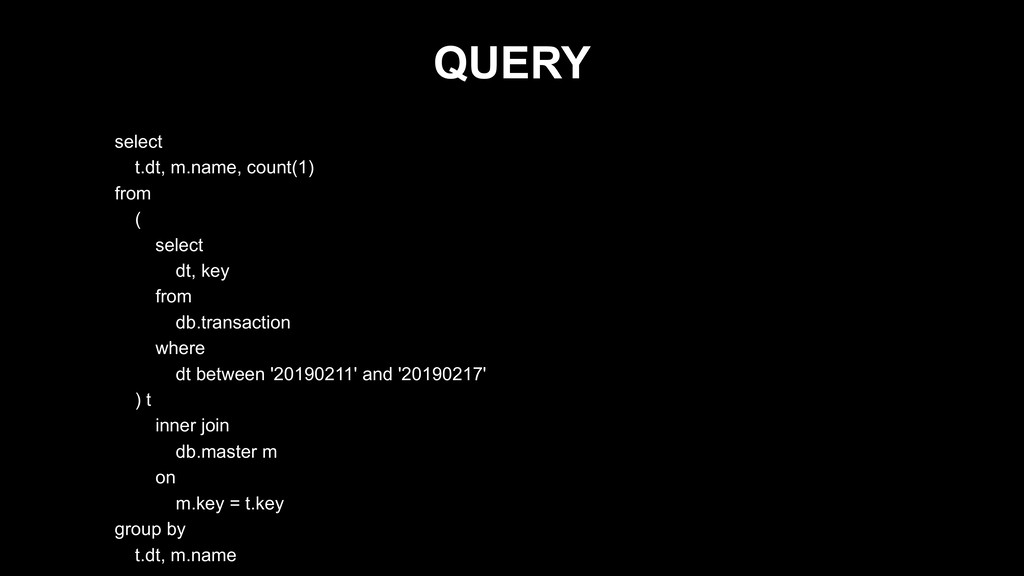
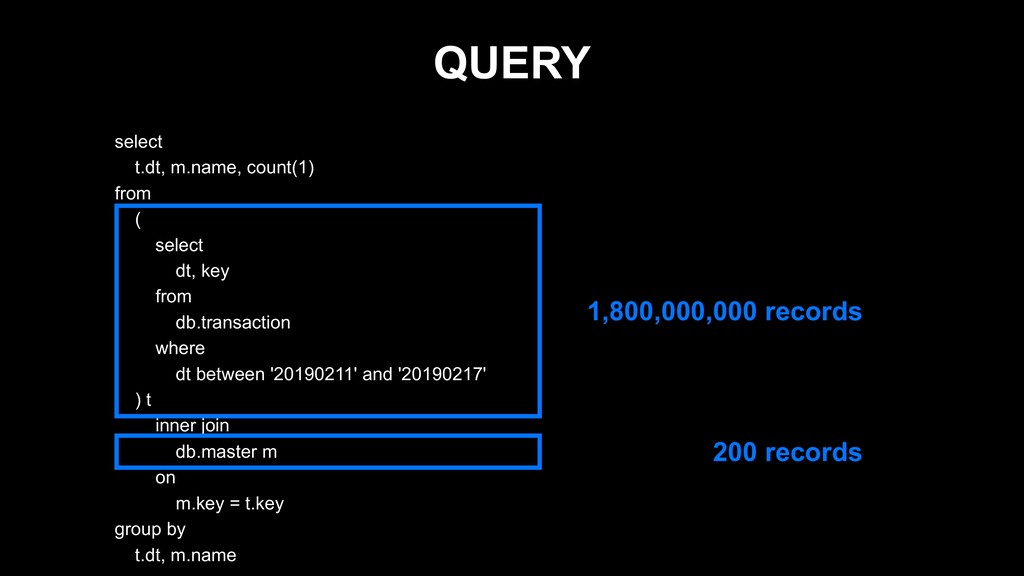
QUERY select t.dt, m.name, count(1) from ( select dt, key
from db.transaction where dt between '20190211' and '20190217' ) t inner join db.master m on m.key = t.key group by t.dt, m.name -
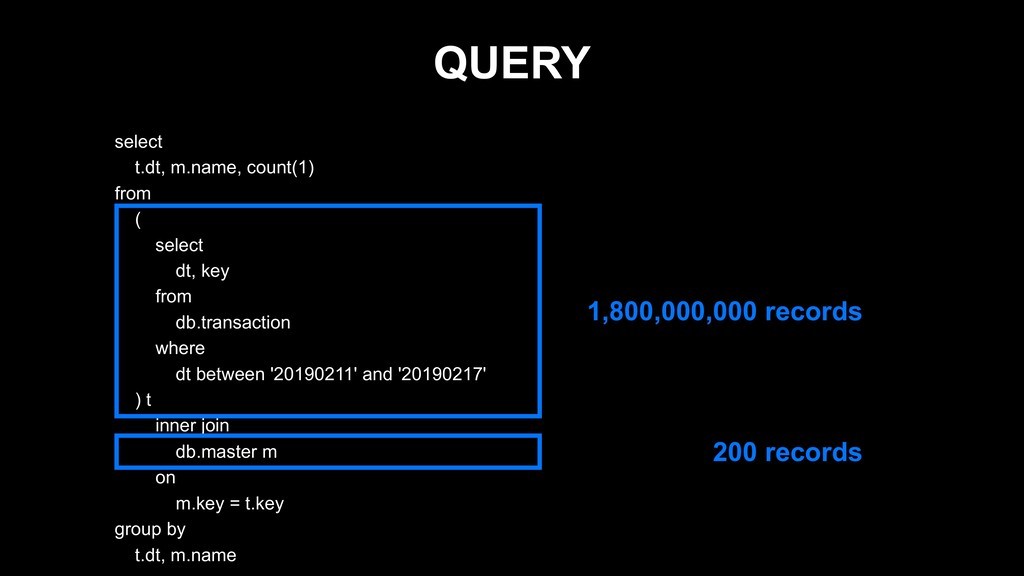
QUERY select t.dt, m.name, count(1) from ( select dt, key
from db.transaction where dt between '20190211' and '20190217' ) t inner join db.master m on m.key = t.key group by t.dt, m.name 1,800,000,000 records 200 records -
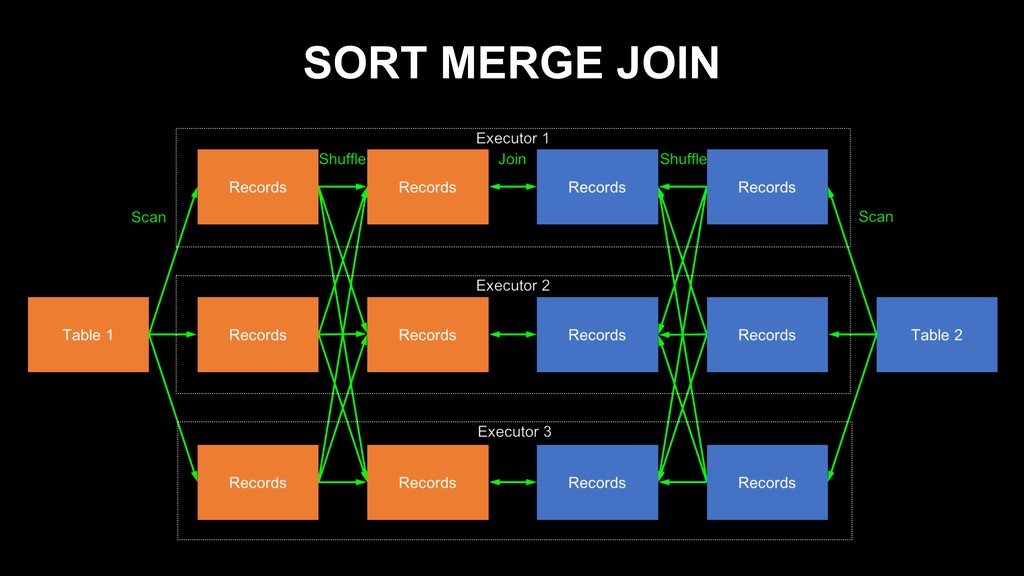
PHYSICAL PLAN *(6) HashAggregate(keys=[dt#958, name#970], functions=[count(1)]) +- Exchange hashpartitioning(dt#958, name#970,
200) +- *(5) HashAggregate(keys=[dt#958, name#970], functions=[partial_count(1)]) +- *(5) Project [dt#958, name#970] +- *(5) SortMergeJoin [key#937], [key#960], Inner :- *(2) Sort [key#937 ASC NULLS FIRST], false, 0 : +- Exchange hashpartitioning(key#937, 200) : +- *(1) Project [dt#958, key#937] : +- *(1) Filter isnotnull(key#937) : +- *(1) FileScan orc transaction[key#937,dt#958] Batched: true, Format: ORC, Location:… +- *(4) Sort [key#960 ASC NULLS FIRST], false, 0 +- Exchange hashpartitioning(key#960, 200) +- *(3) Project [key#960, name#970] +- *(3) Filter isnotnull(key#960) +- *(3) FileScan orc master[key#960,name#970] Batched: true, Format: ORC, Location:… -
QUERY select t.dt, m.name, count(1) from ( select dt, key
from db.transaction where dt between '20190211' and '20190217' ) t inner join db.master m on m.key = t.key group by t.dt, m.name 1,800,000,000 records 200 records -
PHYSICAL PLAN *(6) HashAggregate(keys=[dt#958, name#970], functions=[count(1)]) +- Exchange hashpartitioning(dt#958, name#970,
200) +- *(5) HashAggregate(keys=[dt#958, name#970], functions=[partial_count(1)]) +- *(5) Project [dt#958, name#970] +- *(5) SortMergeJoin [key#937], [key#960], Inner :- *(2) Sort [key#937 ASC NULLS FIRST], false, 0 : +- Exchange hashpartitioning(key#937, 200) : +- *(1) Project [dt#958, key#937] : +- *(1) Filter isnotnull(key#937) : +- *(1) FileScan orc db.transaction[key#937,dt#958] Batched: true, Format: ORC +- *(4) Sort [key#960 ASC NULLS FIRST], false, 0 +- Exchange hashpartitioning(key#960, 200) +- *(3) Project [key#960, name#970] +- *(3) Filter isnotnull(key#960) +- *(3) FileScan orc db.master[key#960,name#970] Batched: true, Format: ORC -
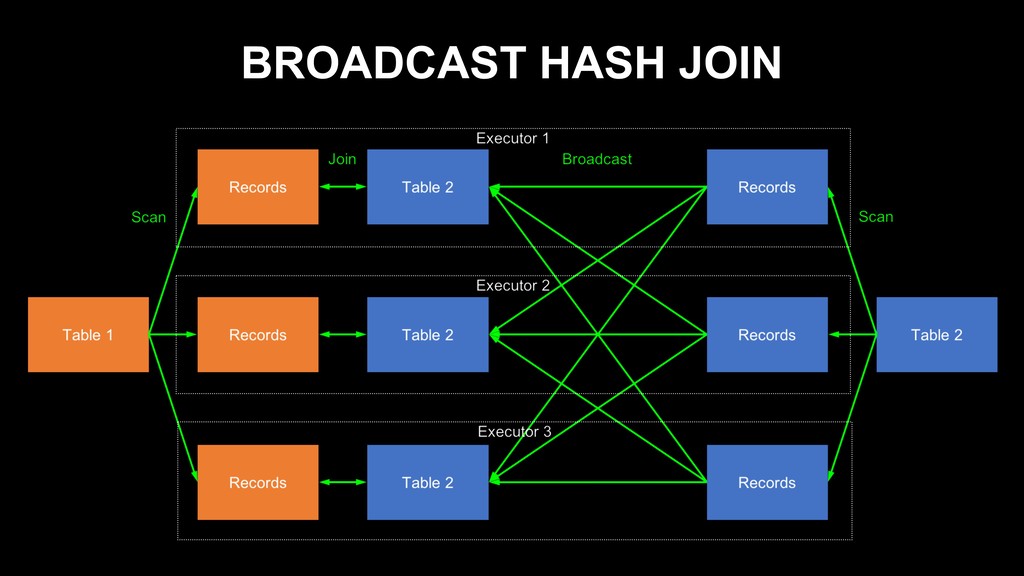
PHYSICAL PLAN *(3) HashAggregate(keys=[dt#149, name#161], functions=[count(1)]) +- Exchange hashpartitioning(dt#149, name#161,
200) +- *(2) HashAggregate(keys=[dt#149, name#161], functions=[partial_count(1)]) +- *(2) Project [dt#149, name#161] +- *(2) BroadcastHashJoin [key#128], [key#151], Inner, BuildRight :- *(2) Project [dt#149, key#128] : +- *(2) Filter isnotnull(key#128) : +- *(2) FileScan orc db.transaction[key#128,dt#149] Batched: true, Format:… +- BroadcastExchange HashedRelationBroadcastMode(List(input[0, string, true])) +- *(1) Project [key#151, name#161] +- *(1) Filter isnotnull(key#151) +- *(1) FileScan orc db.master[key#151,name#161] Batched: true, Format:… -
Agenda 1. Issue 2. Gathering Statistics 3. Injecting Custom Optimization
Rules 4. Cost-based Optimizer -
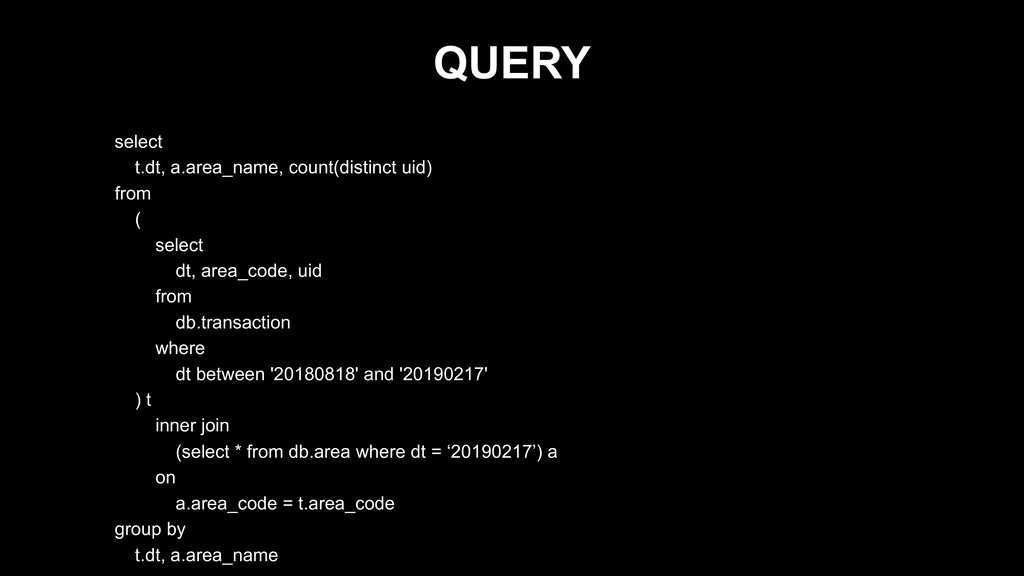
QUERY select t.dt, a.area_name, count(distinct uid) from ( select dt,
area_code, uid from db.transaction where dt between '20180818' and '20190217' ) t inner join (select * from db.area where dt = ‘20190217’) a on a.area_code = t.area_code group by t.dt, a.area_name -
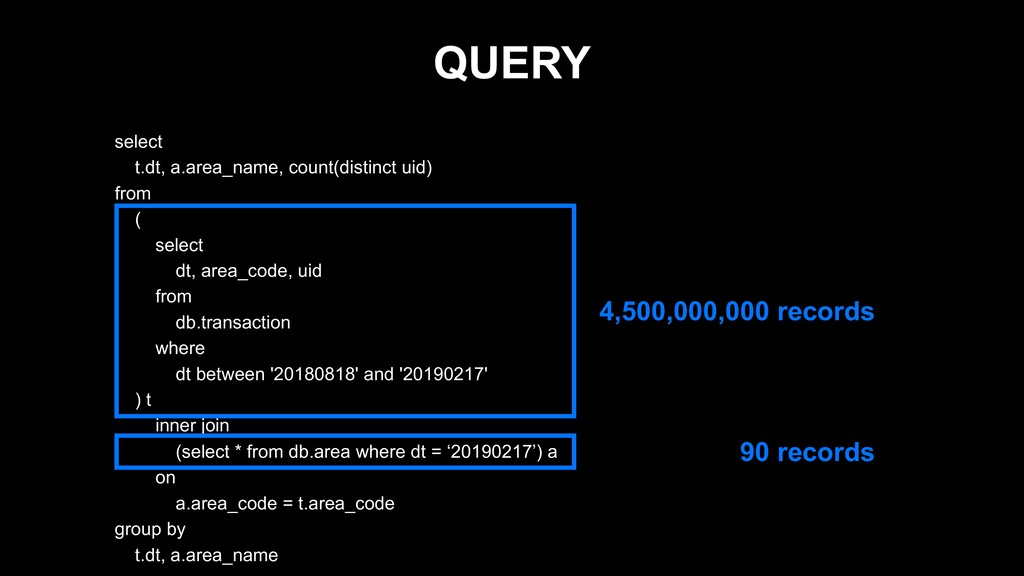
QUERY select t.dt, a.area_name, count(distinct uid) from ( select dt,
area_code, uid from db.transaction where dt between '20180818' and '20190217' ) t inner join (select * from db.area where dt = ‘20190217’) a on a.area_code = t.area_code group by t.dt, a.area_name 4,500,000,000 records 90 records -
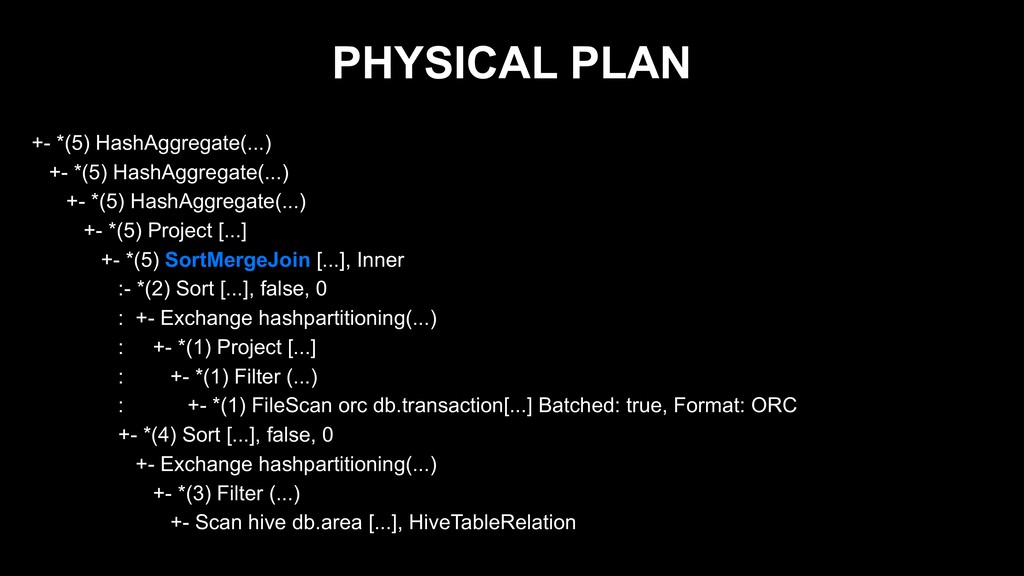
PHYSICAL PLAN +- *(5) HashAggregate(...) +- *(5) HashAggregate(...) +- *(5)
HashAggregate(...) +- *(5) Project [...] +- *(5) SortMergeJoin [...], Inner :- *(2) Sort [...], false, 0 : +- Exchange hashpartitioning(...) : +- *(1) Project [...] : +- *(1) Filter (...) : +- *(1) FileScan orc db.transaction[...] Batched: true, Format: ORC +- *(4) Sort [...], false, 0 +- Exchange hashpartitioning(...) +- *(3) Filter (...) +- Scan hive db.area [...], HiveTableRelation -
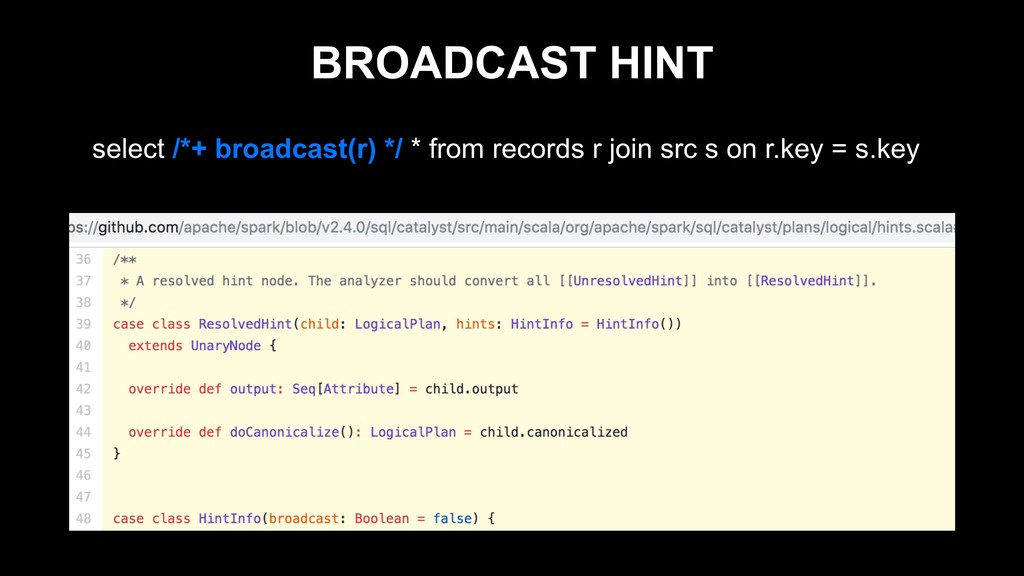
BROADCAST HINT select /*+ broadcast(r) */ * from records r
join src s on r.key = s.key -
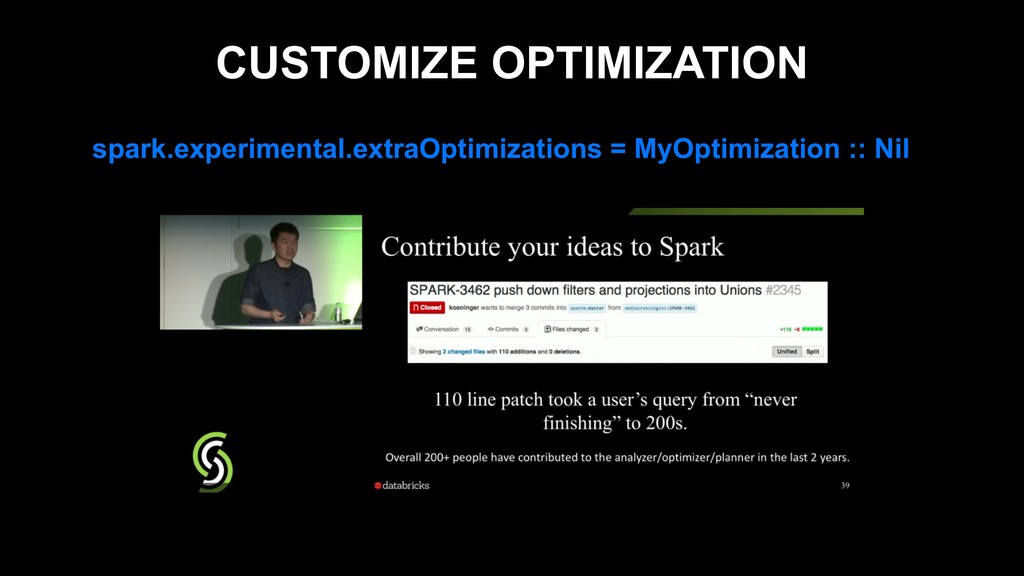
CUSTOMIZE OPTIMIZATION object InsertBroadcastHints extends Rule[LogicalPlan] { val targets =
Map(("db", "area") -> "dt") override def apply(plan: LogicalPlan): LogicalPlan = plan transform { case join: Join if isSelectFromTarget(join.left) => join.copy(left = ResolvedHint(join.left, HintInfo(true))) case join: Join if isSelectFromTarget(join.right) => join.copy(right = ResolvedHint(join.right, HintInfo(true))) } private def isSelectFromTarget(plan: LogicalPlan): Boolean = plan match { case p: Project => p.child match { case f: Filter => f.child match { case rel: HiveTableRelation => targets.get(rel.tableMeta.database, rel.tableMeta.identifier.table) match { case Some(pt) => isFilteredByLiteral(f.condition, pt) case None => false } … } private def isFilteredByLiteral(expr: Expression, pt: String): Boolean = ... } spark.experimental.extraOptimizations = InsertBroadcastHints :: Nil -
OPTIMIZED LOGICAL PLAN Aggregate [...] +- Project [...] +- Join
Inner, (...) :- Project [...] : +- Filter (...) : +- Relation[...] orc +- ResolvedHint (broadcast) +- Project [...] +- Filter (...) +- HiveTableRelation `db`.`area`, ... -
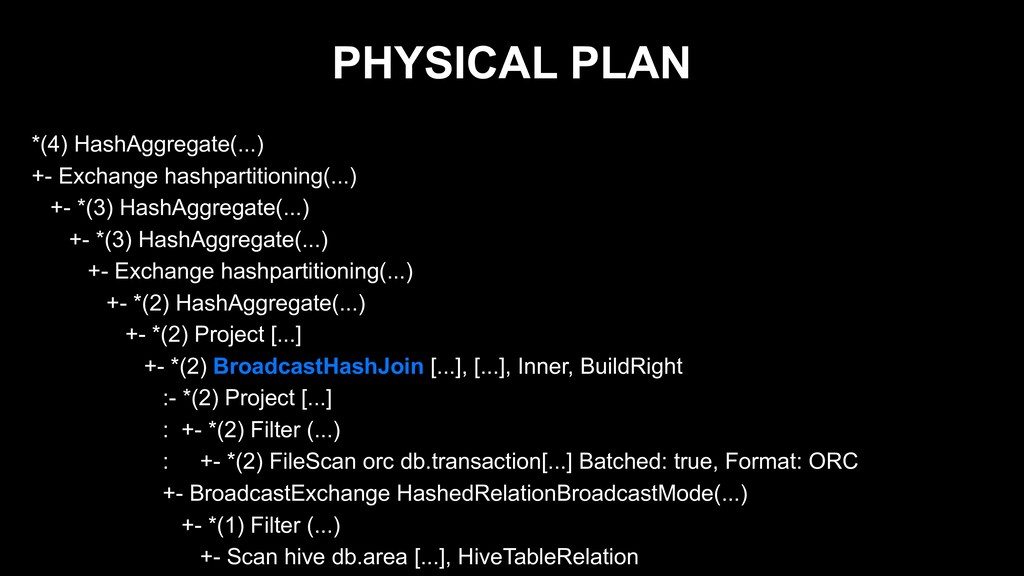
PHYSICAL PLAN *(4) HashAggregate(...) +- Exchange hashpartitioning(...) +- *(3) HashAggregate(...)
+- *(3) HashAggregate(...) +- Exchange hashpartitioning(...) +- *(2) HashAggregate(...) +- *(2) Project [...] +- *(2) BroadcastHashJoin [...], [...], Inner, BuildRight :- *(2) Project [...] : +- *(2) Filter (...) : +- *(2) FileScan orc db.transaction[...] Batched: true, Format: ORC +- BroadcastExchange HashedRelationBroadcastMode(...) +- *(1) Filter (...) +- Scan hive db.area [...], HiveTableRelation -
Agenda 1. Issue 2. Gathering Statistics 3. Injecting Custom Optimization
Rules 4. Cost-based Optimizer -
COST-BASED OPTIMIZATION • Apache Spark 2.2.0~ • Statistics, Cost •
Advanced Optimizations 1. Broadcast Hash Join Based on Column Statistics 2. Join Reordering -
COST-BASED OPTIMIZATION • Apache Spark 2.2.0~ • Statistics, Cost •
Advanced Optimizations 1. Broadcast Hash Join Based on Column Statistics 2. Join Reordering -
QUERY select a.* from db.a inner join db.b on a.id
= b.id inner join db.c on b.key = c.key -
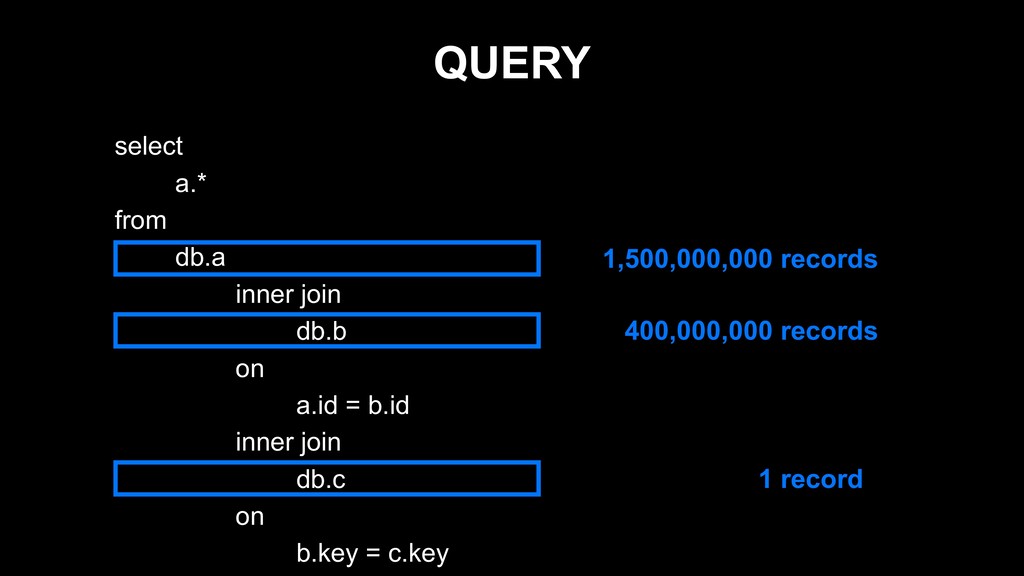
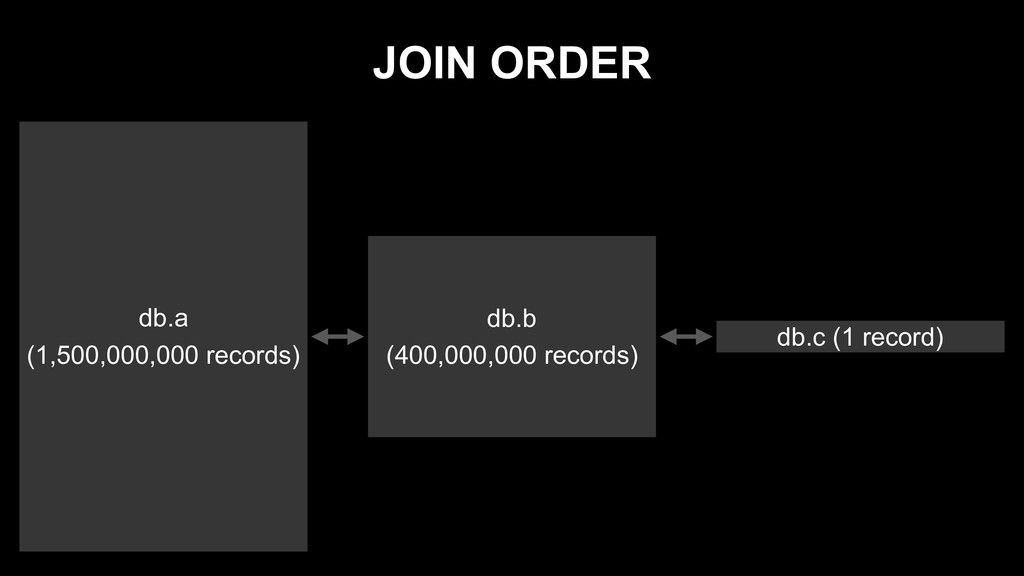
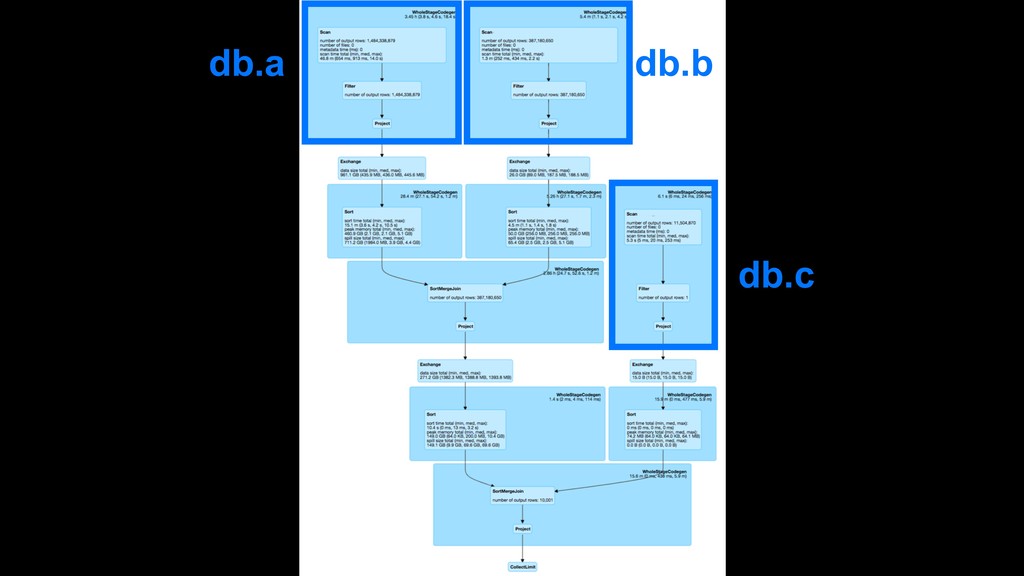
QUERY select a.* from db.a inner join db.b on a.id
= b.id inner join db.c on b.key = c.key 1,500,000,000 records 400,000,000 records 1 records -
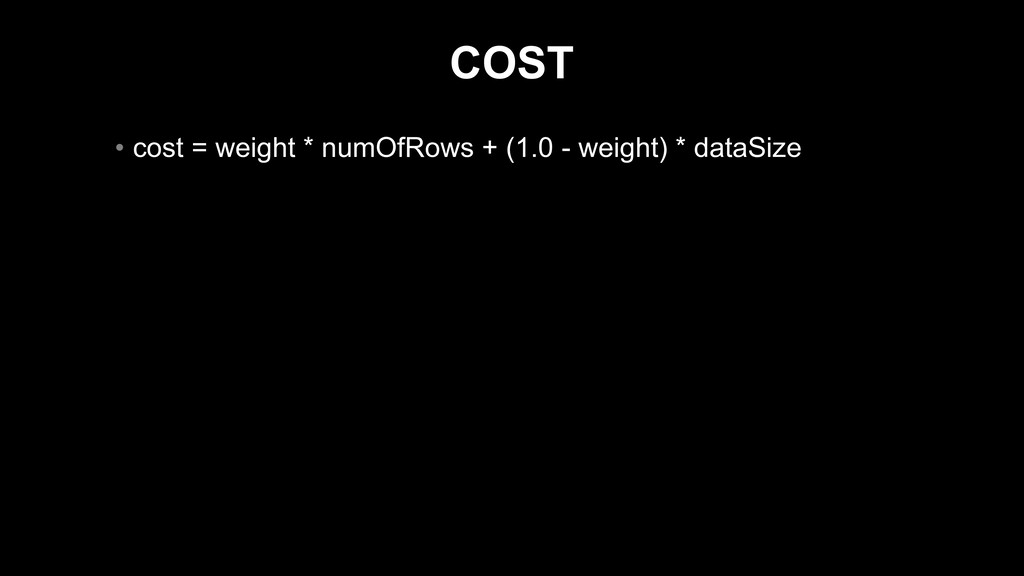
COST • cost = weight * numOfRows + (1.0 -
weight) * dataSize