Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Real-time Analytics with Spark

Real-time Analytics with Spark

Big Data meets a small startup. Presented at the Galway Data Meetup.

Experiences from deploying a scalable data analytics infrastructure in the cloud, using Spark, Kafka, Cassandra, MongoDB and Node.js
You will also find a short overview of Spark, some code examples, and useful tips for running Spark Streaming in Production.

Avatar for Maciej Dabrowski

Maciej Dabrowski

February 03, 2015

More Decks by Maciej Dabrowski

Other Decks in Technology

Transcript

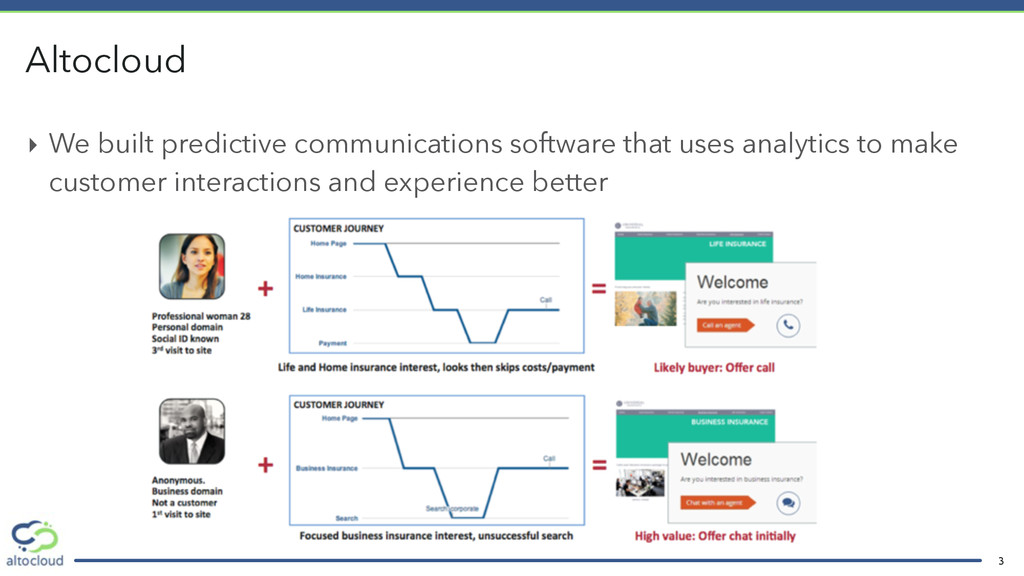
  1. ‣ We built predictive communications software that uses analytics to

    make customer interactions and experience better Altocloud 3
  2. 5

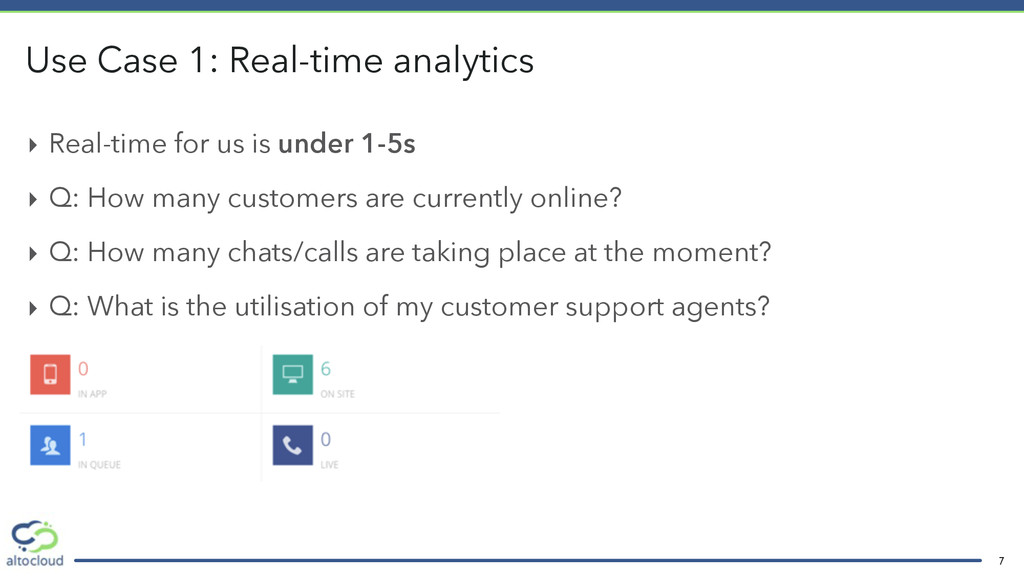
  3. ‣ Real-time for us is under 1-5s ‣ Q: How

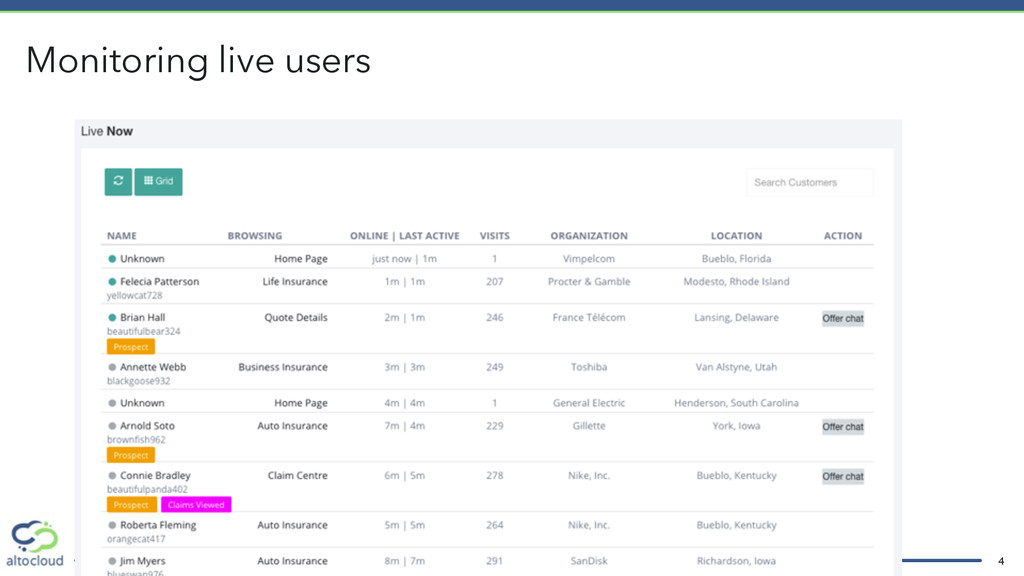
    many customers are currently online? ‣ Q: How many chats/calls are taking place at the moment? ‣ Q: What is the utilisation of my customer support agents? Use Case 1: Real-time analytics 7
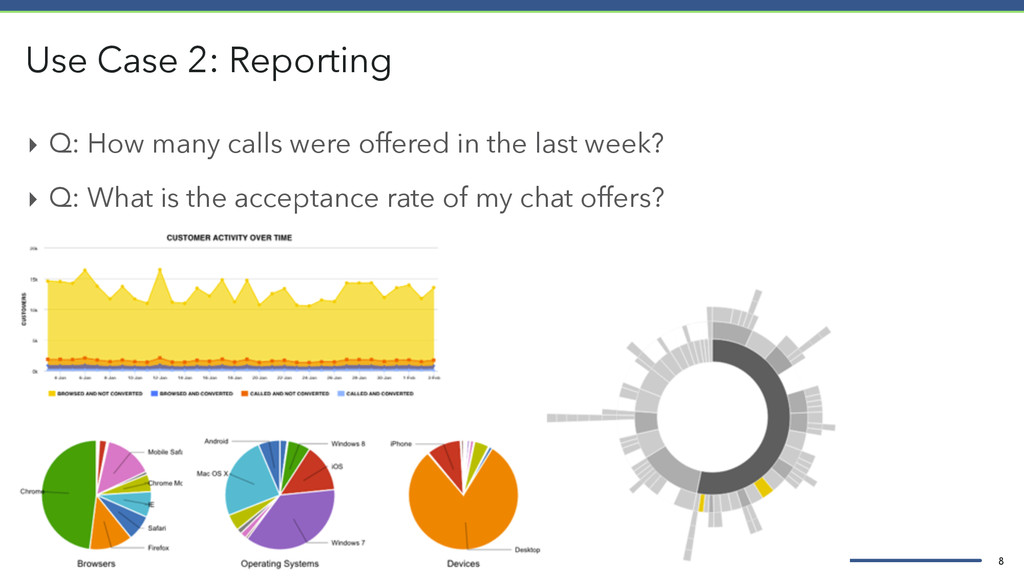
  4. ‣ Q: How many calls were offered in the last

    week? ‣ Q: What is the acceptance rate of my chat offers? Use Case 2: Reporting 8
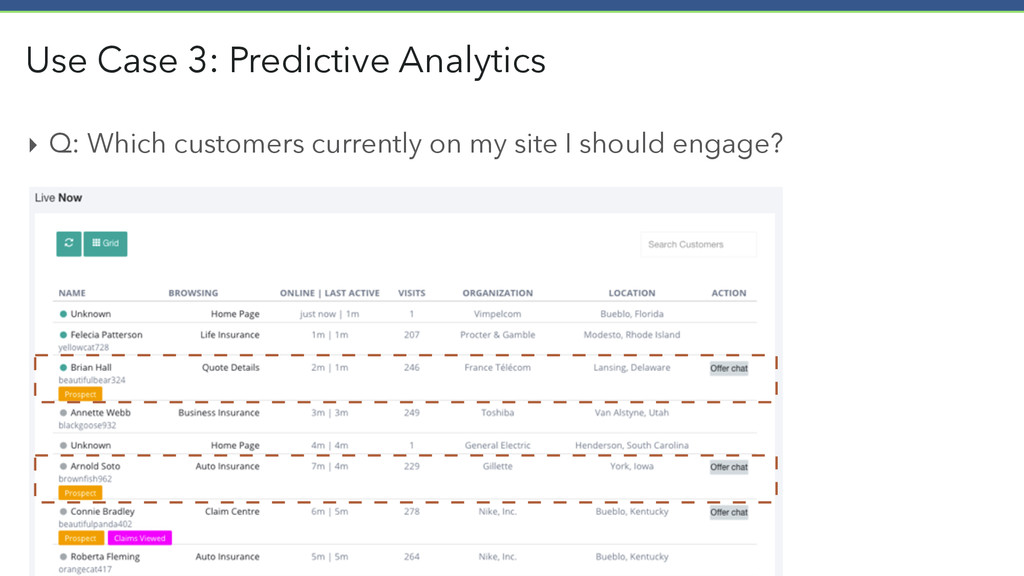
  5. ‣ Q: Which customers currently on my site I should

    engage? Use Case 3: Predictive Analytics 9
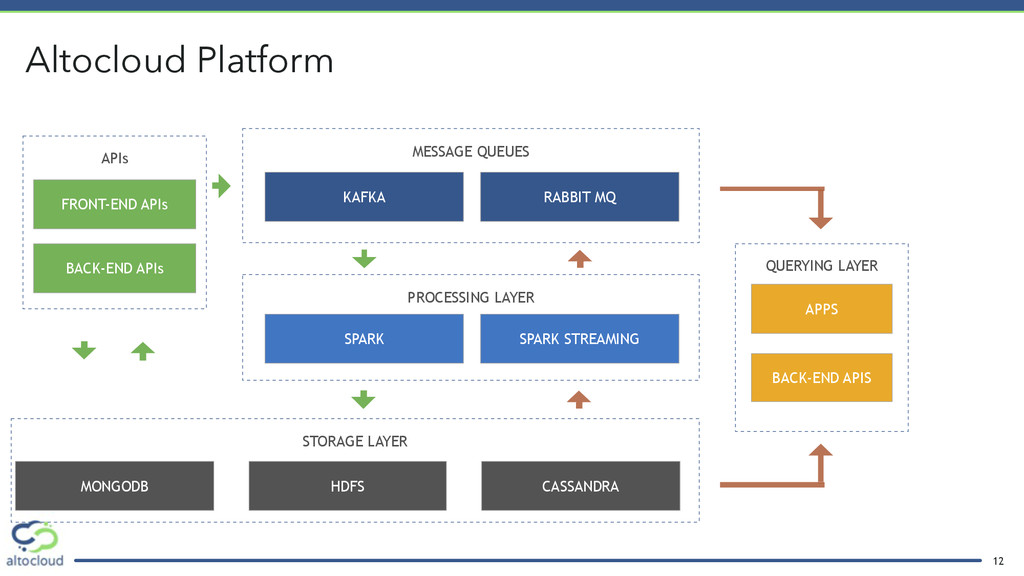
  6. APIs QUERYING LAYER STORAGE LAYER PROCESSING LAYER Altocloud Platform 12

    MESSAGE QUEUES FRONT-END APIs KAFKA SPARK RABBIT MQ CASSANDRA SPARK STREAMING HDFS BACK-END APIS APPS BACK-END APIs MONGODB
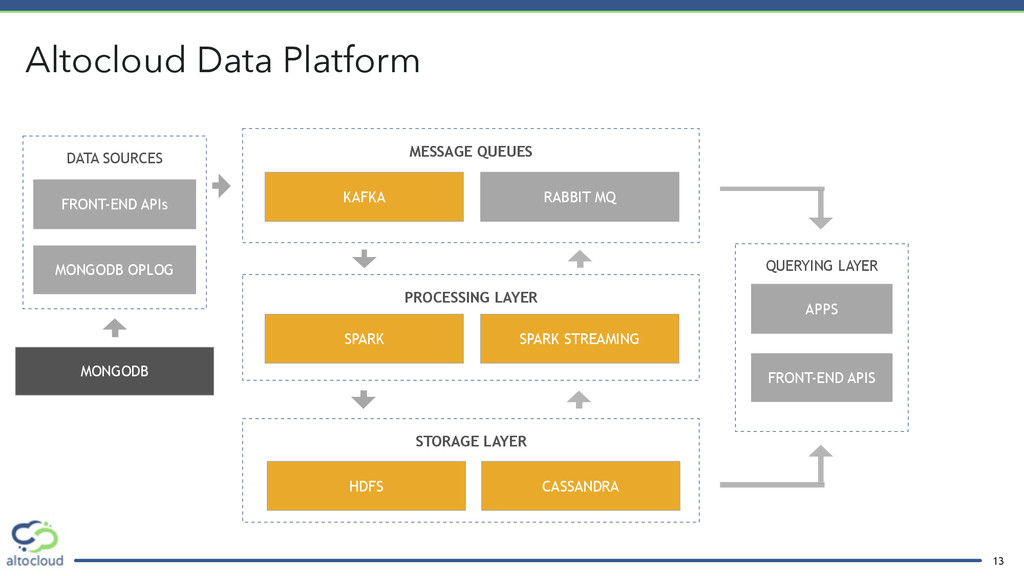
  7. DATA SOURCES QUERYING LAYER STORAGE LAYER PROCESSING LAYER Altocloud Data

    Platform 13 MESSAGE QUEUES FRONT-END APIs KAFKA MONGODB OPLOG SPARK RABBIT MQ CASSANDRA SPARK STREAMING HDFS FRONT-END APIS APPS MONGODB
  8. ‣ One code base for streaming and batch processing ‣

    Rich API in Scala/Python/Java ‣ Fast for iterative algorithms (important for ML) ‣ Growing community ‣ The concept of a micro-batch ‣ Nicely integrates with Kafka and Cassandra ‣ Fairly easy setup Why Spark 14
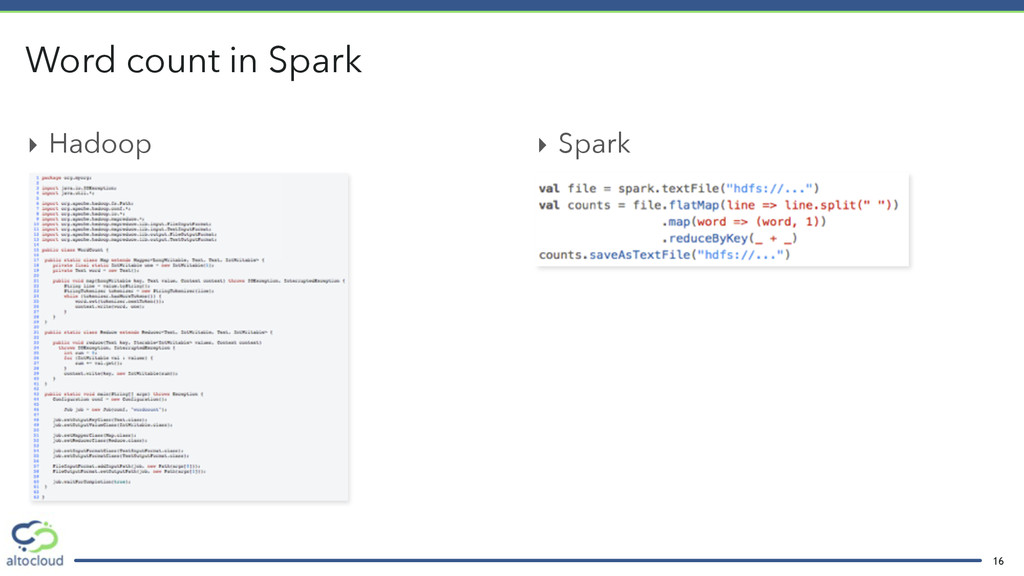
  9. ‣ Hadoop ! ! ! ! ! ! ‣ Spark

    Word count in Spark 16
  10. ‣ Example: user event aggregation stored in Cassandra ‣ Still

    much better than Hadoop! What about something more useful? 17
  11. ‣ User activity is an input (e.g. page view) ‣

    Users for multiple businesses online ‣ Scale 100s to 100 000s activities per second ‣ Response time under 5s ‣ A perfect use case for spark streaming Counting users currently online 18
  12. ‣ Pub-sub message broker ‣ Fast: 100s MBs /s on

    a single broker ‣ Scalable: partitioned data streams ‣ Durable: messages persisted and replicated ‣ Distributed: Strong durability with and fault-tolerance ‣ Downside: requires ZooKeeper ! see https://kafka.apache.org Data source: Kafka 19
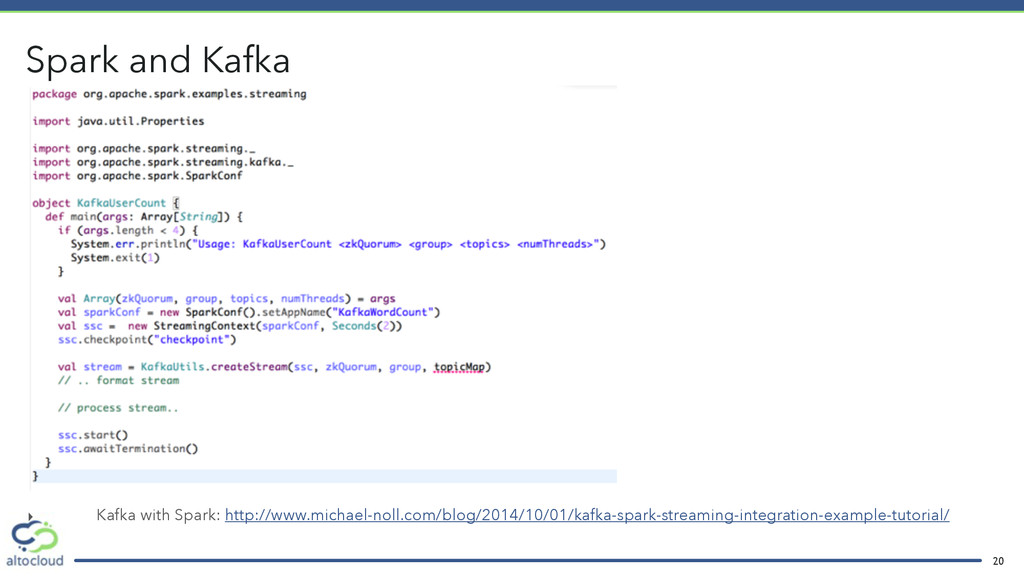
  13. ! ! ! ! ! ! ! ‣ Kafka with

    Spark: http://www.michael-noll.com/blog/2014/10/01/kafka-spark-streaming-integration-example-tutorial/ Spark and Kafka 20
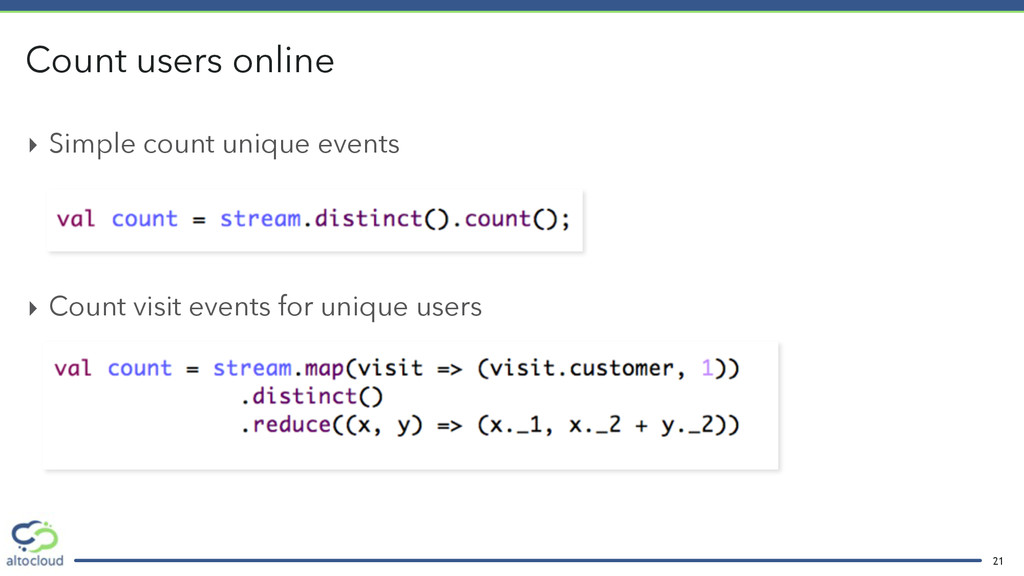
  14. ‣ Simple count unique events ! ! ‣ Count visit

    events for unique users Count users online 21
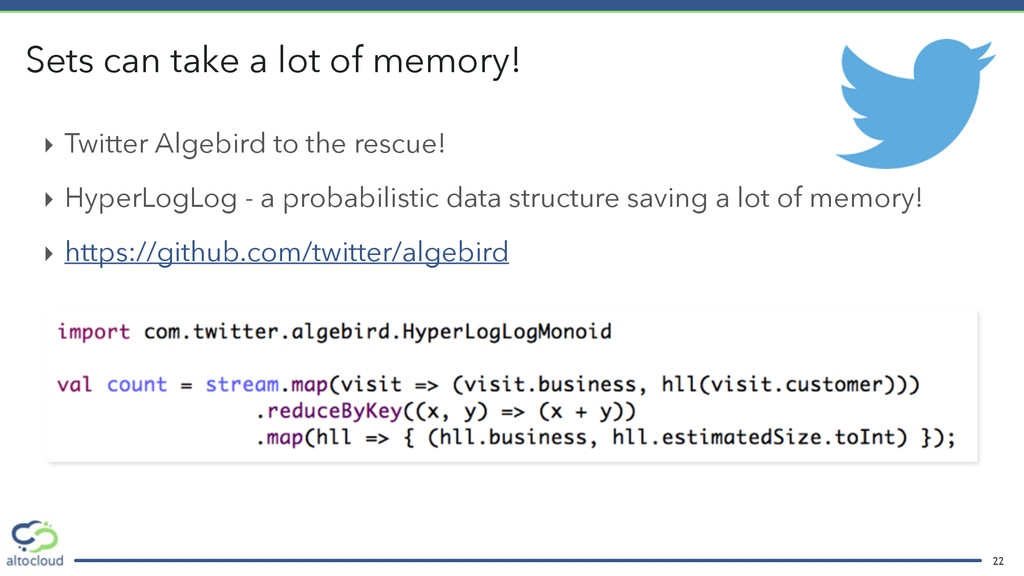
  15. ‣ Twitter Algebird to the rescue! ‣ HyperLogLog - a

    probabilistic data structure saving a lot of memory! ‣ https://github.com/twitter/algebird Sets can take a lot of memory! 22
  16. ‣ Easy to setup ‣ High availability - no master

    ‣ Great performance ‣ CQL - SQL like querying ‣ Great support and bug-free drivers from Datastax ‣ Key: Design your schema around queries; ! ! see https://cassandra.apache.org Storing your results 23
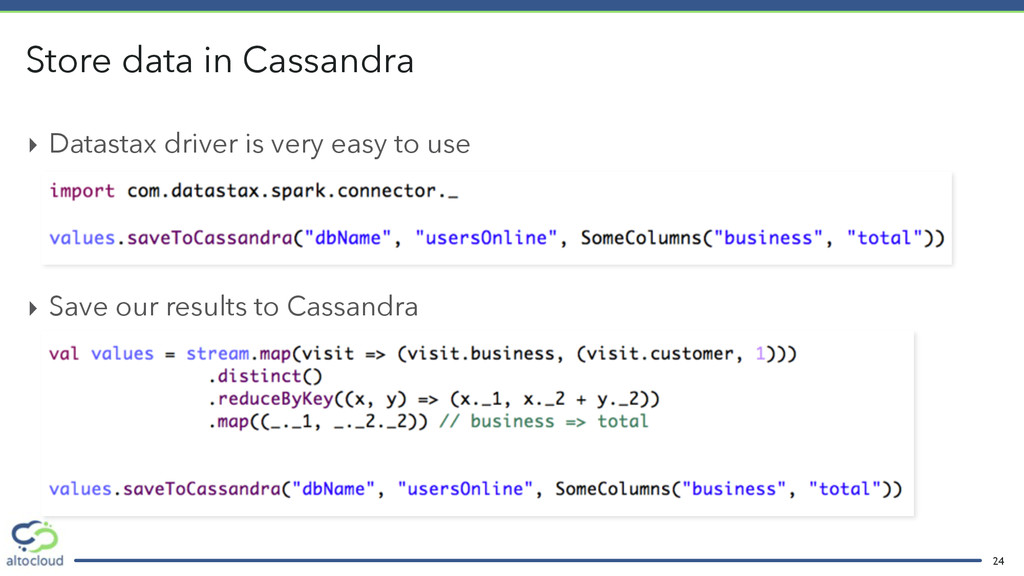
  17. ‣ Datastax driver is very easy to use ! !

    ‣ Save our results to Cassandra Store data in Cassandra 24
  18. ‣ Spark streaming job performs two major tasks: • data

    processing • data receiving ‣ Receiver always takes one core ‣ Technically, you need 2N cores to run N streaming jobs ‣ Not a big deal in production, what about testing? Spark streaming 26
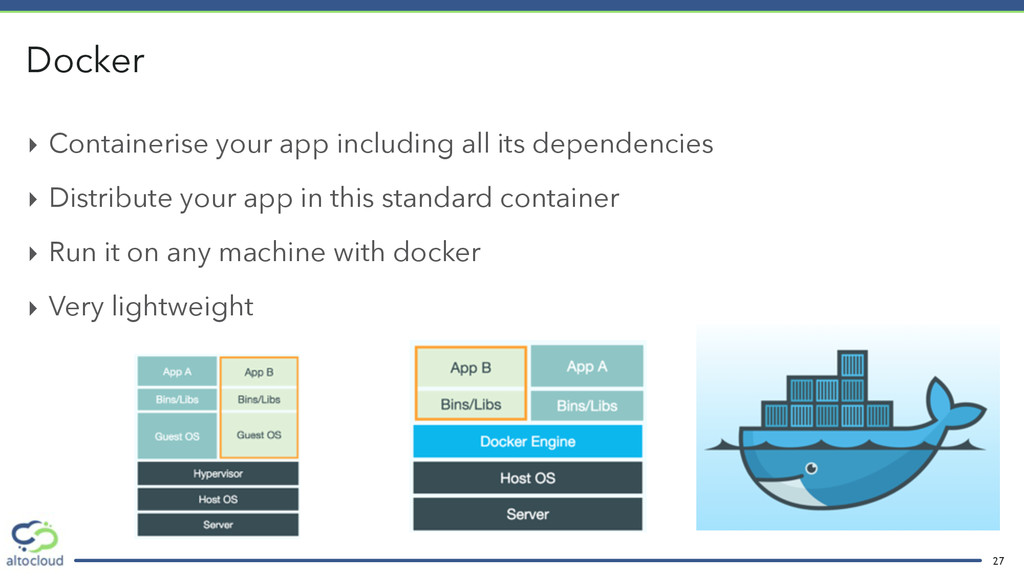
  19. ‣ Containerise your app including all its dependencies ‣ Distribute

    your app in this standard container ‣ Run it on any machine with docker ‣ Very lightweight Docker 27
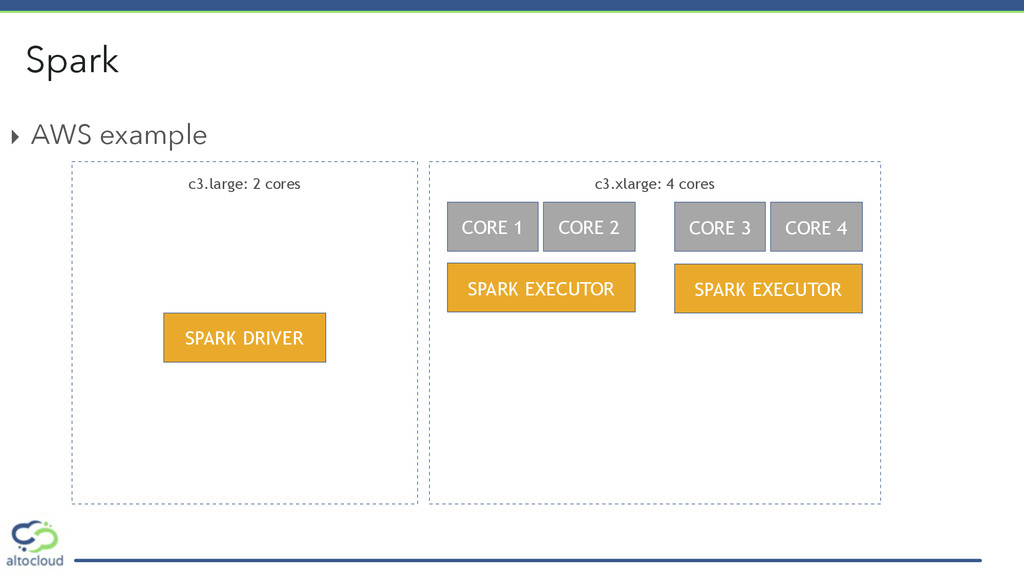
  20. c3.xlarge: 4 cores ‣ AWS example Spark SPARK EXECUTOR c3.large:

    2 cores SPARK DRIVER SPARK EXECUTOR CORE 1 CORE 2 CORE 3 CORE 4
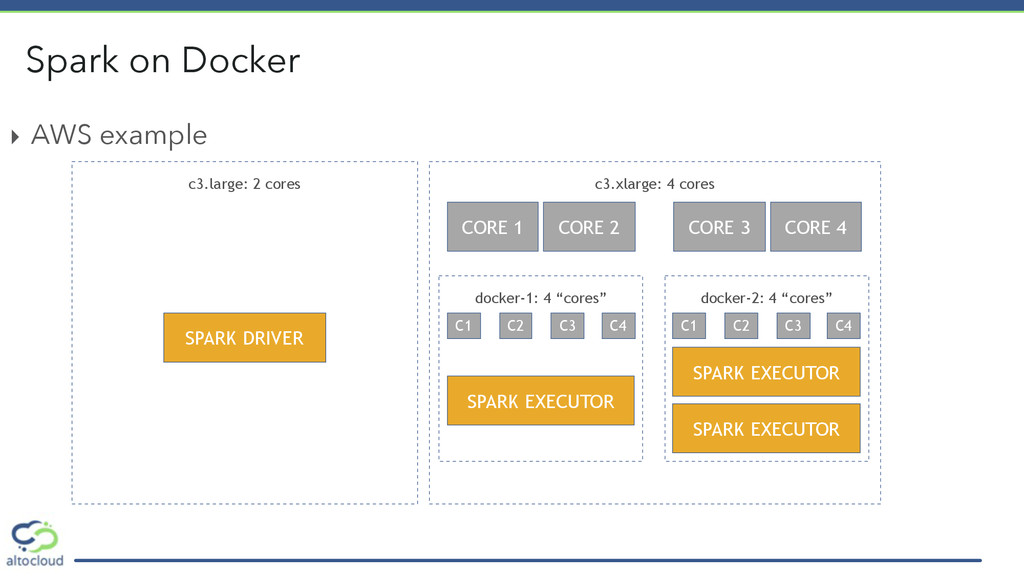
  21. c3.xlarge: 4 cores ‣ AWS example Spark on Docker c3.large:

    2 cores SPARK DRIVER CORE 1 CORE 2 CORE 3 CORE 4 docker-1: 4 “cores” SPARK EXECUTOR C1 C2 C4 C3 docker-2: 4 “cores” SPARK EXECUTOR C1 C2 C4 C3 SPARK EXECUTOR
  22. ‣ Spark Streaming is fast to deploy but tuning is

    VERY important ‣ The lower the number of tasks, the better (in general) ‣ When reading from Kafka make sure that you configure blockingInterval ‣ optimize your jobs when possible - similar jobs can be sometimes merged ‣ persist your data from workers, NOT the driver Spark Streaming 30
  23. ‣ OLAP-type queries using Spark SQL ‣ More advanced performance

    testing ‣ Detailed unit testing ‣ More batch jobs Where do we go from here? 31
  24. ‣ Spark Documentation ‣ Reference application: http://github.com/killrweather/killrweather ‣ Productionalizing Spark

    Streaming ‣ Spark and Kafka ‣ Docker ‣ Free Hadoop Training from MapR ‣ Free edX course on Spark Resources 32