Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Big Data Analytics - an overview

Big Data Analytics - an overview

A high level overview of Big Data Analytics presented to the NUIG final year students.

Avatar for Maciej Dabrowski

Maciej Dabrowski

March 09, 2015

More Decks by Maciej Dabrowski

Other Decks in Education

Transcript

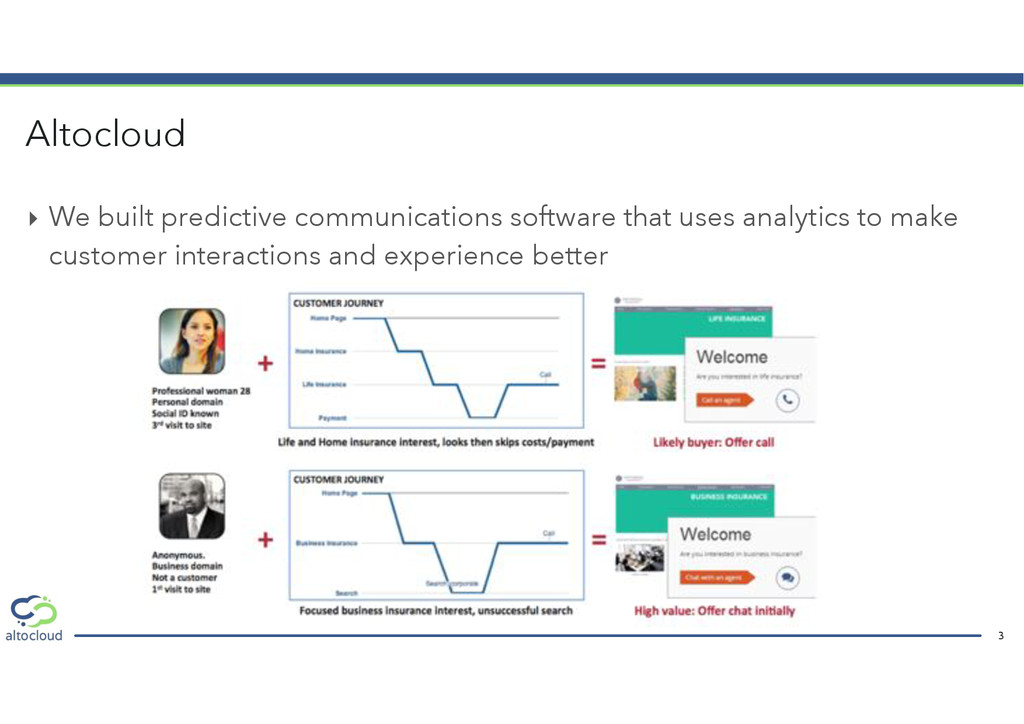
  1. ‣ We built predictive communications software that uses analytics to

    make customer interactions and experience better Altocloud 3
  2. 5

  3. 17

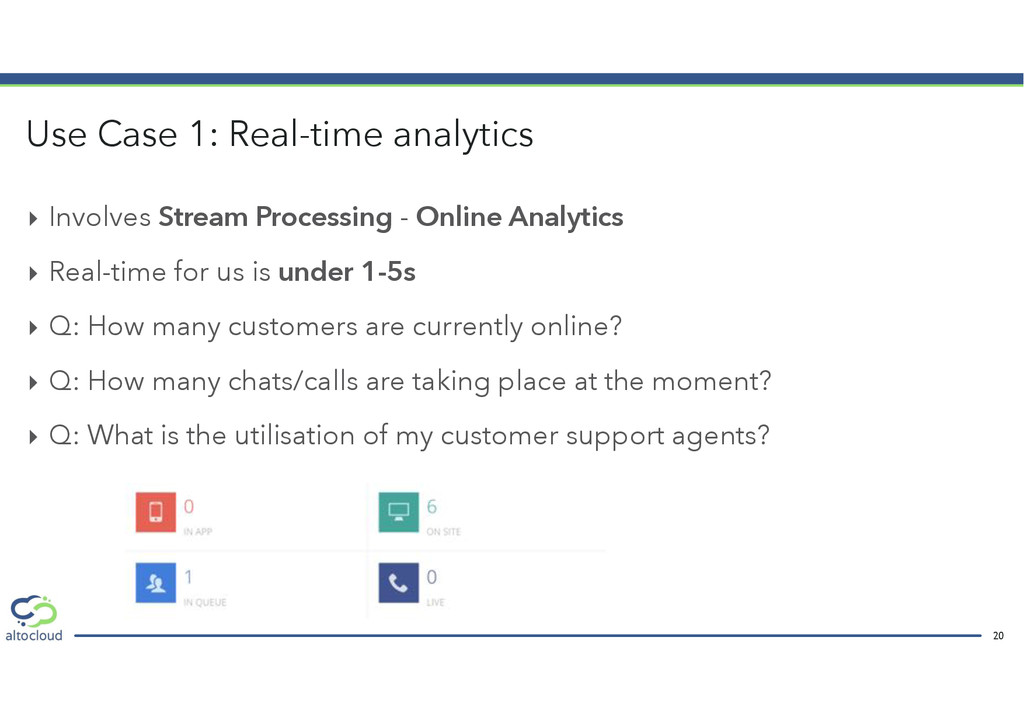
  4. ‣ Involves Stream Processing - Online Analytics ‣ Real-time for

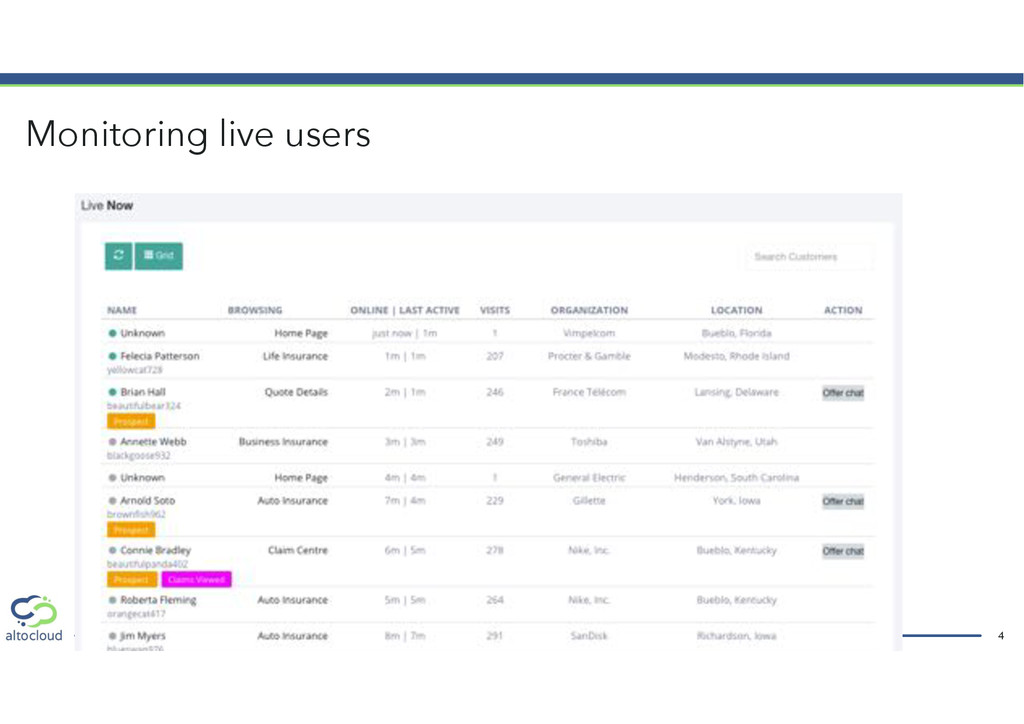
    us is under 1-5s ‣ Q: How many customers are currently online? ‣ Q: How many chats/calls are taking place at the moment? ‣ Q: What is the utilisation of my customer support agents? Use Case 1: Real-time analytics 20
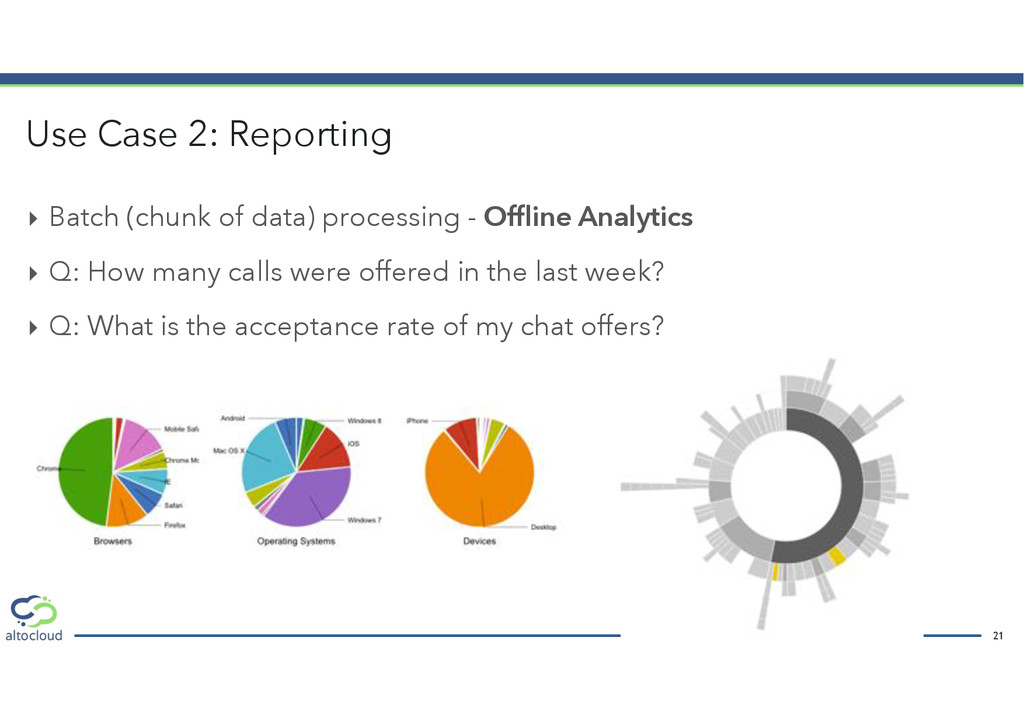
  5. ‣ Batch (chunk of data) processing - Offline Analytics ‣

    Q: How many calls were offered in the last week? ‣ Q: What is the acceptance rate of my chat offers? Use Case 2: Reporting 21
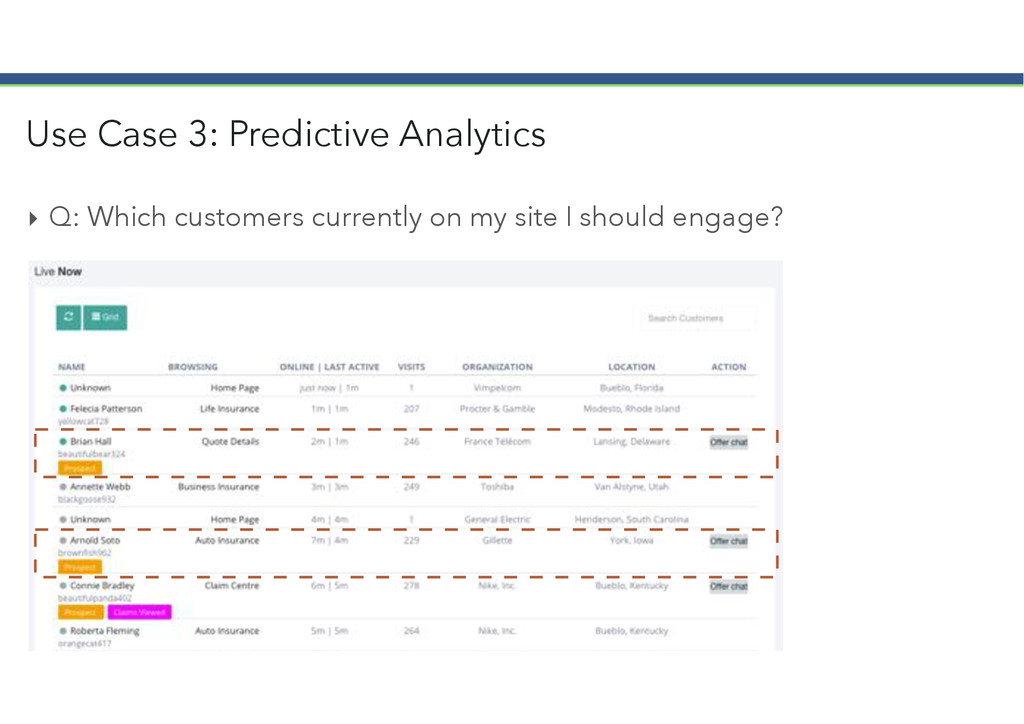
  6. ‣ Q: Which customers currently on my site I should

    engage? Use Case 3: Predictive Analytics 22
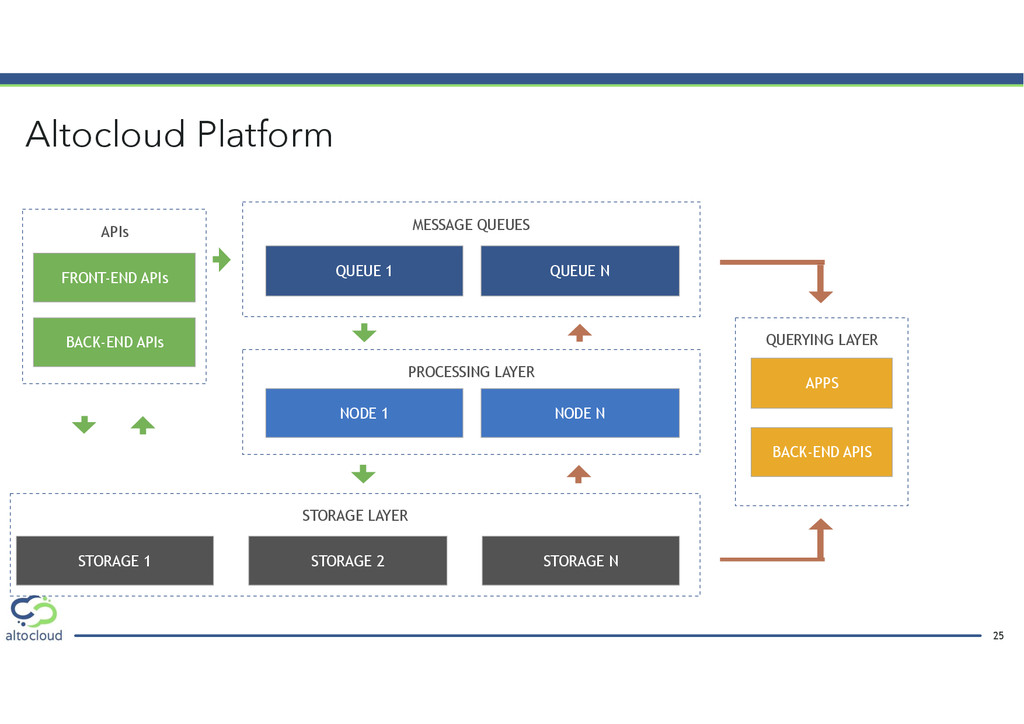
  7. APIs QUERYING LAYER STORAGE LAYER PROCESSING LAYER Altocloud Platform 25

    MESSAGE QUEUES FRONT-END APIs QUEUE 1 NODE 1 QUEUE N STORAGE N NODE N STORAGE 2 BACK-END APIS APPS BACK-END APIs STORAGE 1
  8. 26

  9. ‣ Document store ‣ Using JSON as format ‣ No

    Schema ‣ Easy to setup ‣ Scales through replication and sharing ‣ Commercial support through 10gen.com MongoDB 28
  10. ‣ Columnar store ‣ Easy to setup ‣ High availability

    - no master ‣ Great performance ‣ CQL - SQL like querying ‣ Great support and bug-free drivers from Datastax ‣ Key: Design your schema around queries; see https://cassandra.apache.org Cassandra 29
  11. ‣ Pub-sub message broker ‣ Fast: 100s MBs /s on

    a single broker ‣ Scalable: partitioned data streams ‣ Durable: messages persisted and replicated ‣ Distributed: Strong durability with and fault-tolerance ‣ Downside: requires ZooKeeper ‣ Very simple - great at scale, requires more client-side logic see https://kafka.apache.org Kafka 30
  12. ‣ Robust messaging queue ‣ Provides advanced routing mechanisms ‣

    Supported on all major platforms ‣ Fairly easy to scale through clustering ‣ Good support ‣ More functionality comes at a cost of lower performance than Kafka Rabbit MQ 31
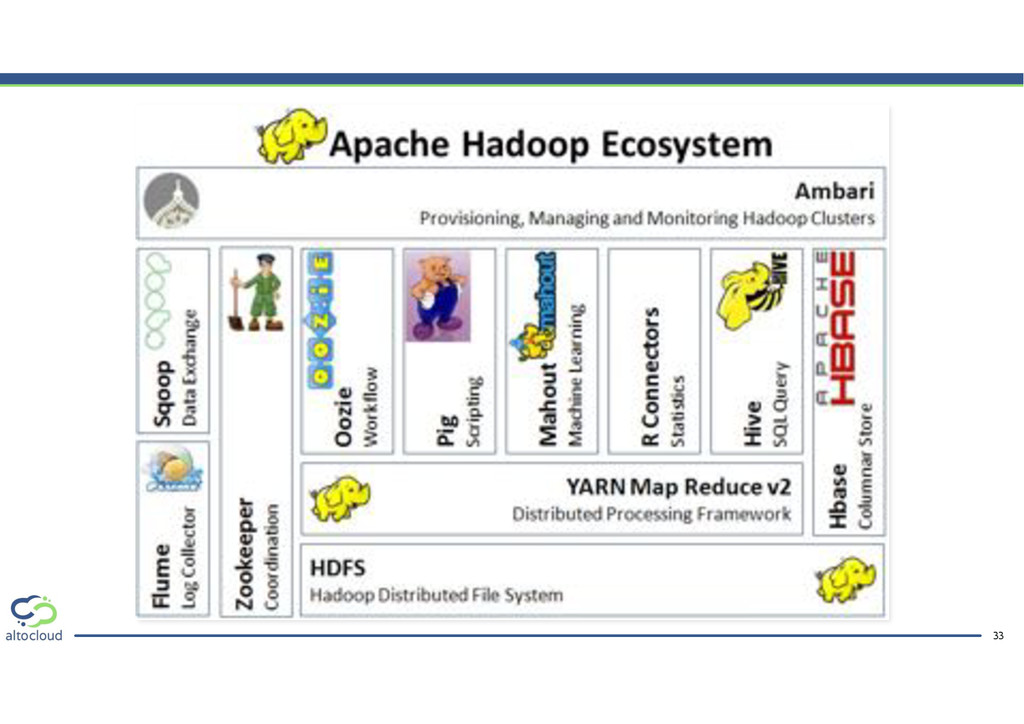
  13. ‣ Set of tools and algorithms for batch processing using

    Map Reduce ‣ Hadoop Distributed File System (HDFS) ‣ YARN - resource scheduler ‣ Map Reduce - a programming model (probably originating from Google) Hadoop 32
  14. 33

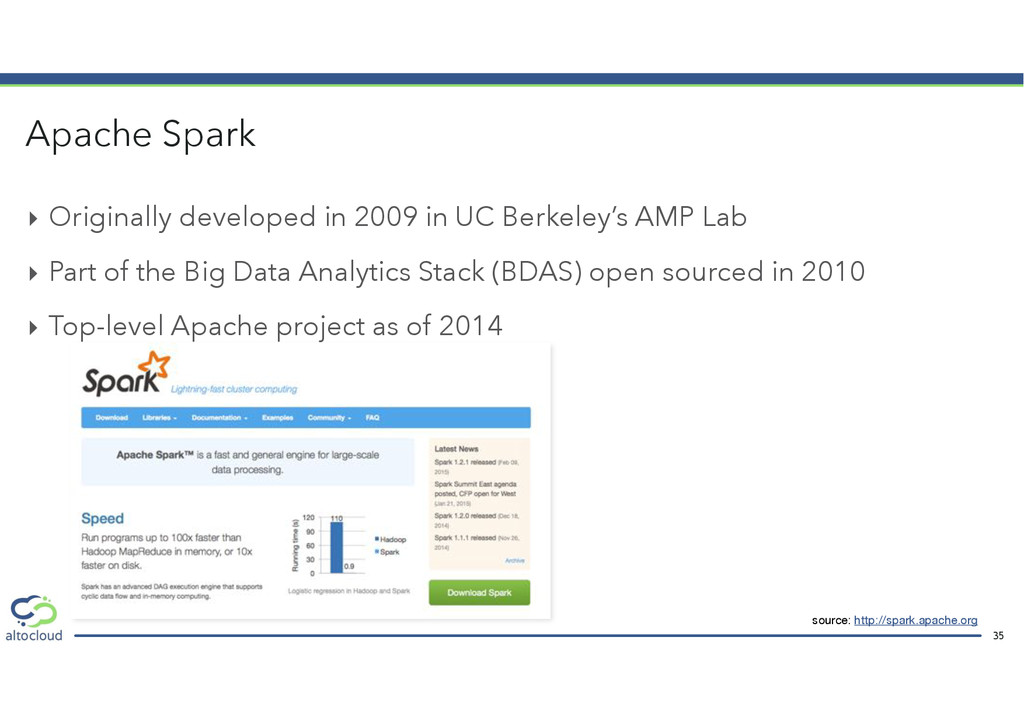
  15. ‣ Originally developed in 2009 in UC Berkeley’s AMP Lab

    ‣ Part of the Big Data Analytics Stack (BDAS) open sourced in 2010 ‣ Top-level Apache project as of 2014 Apache Spark 35 source: http://spark.apache.org
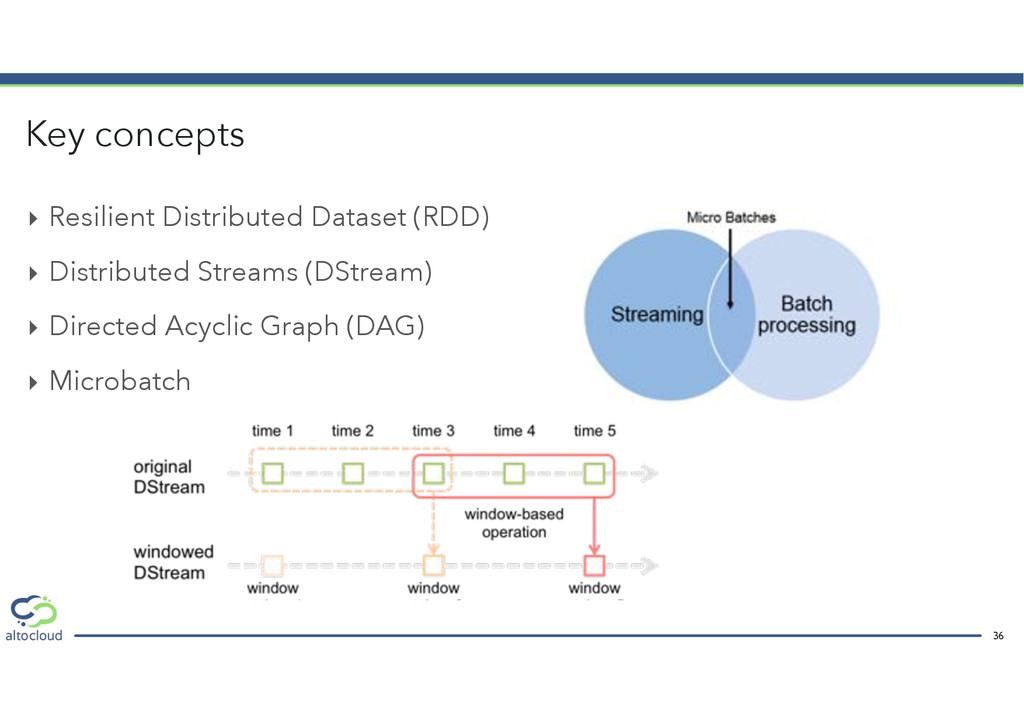
  16. ‣ Resilient Distributed Dataset (RDD) ‣ Distributed Streams (DStream) ‣

    Directed Acyclic Graph (DAG) ‣ Microbatch Key concepts 36
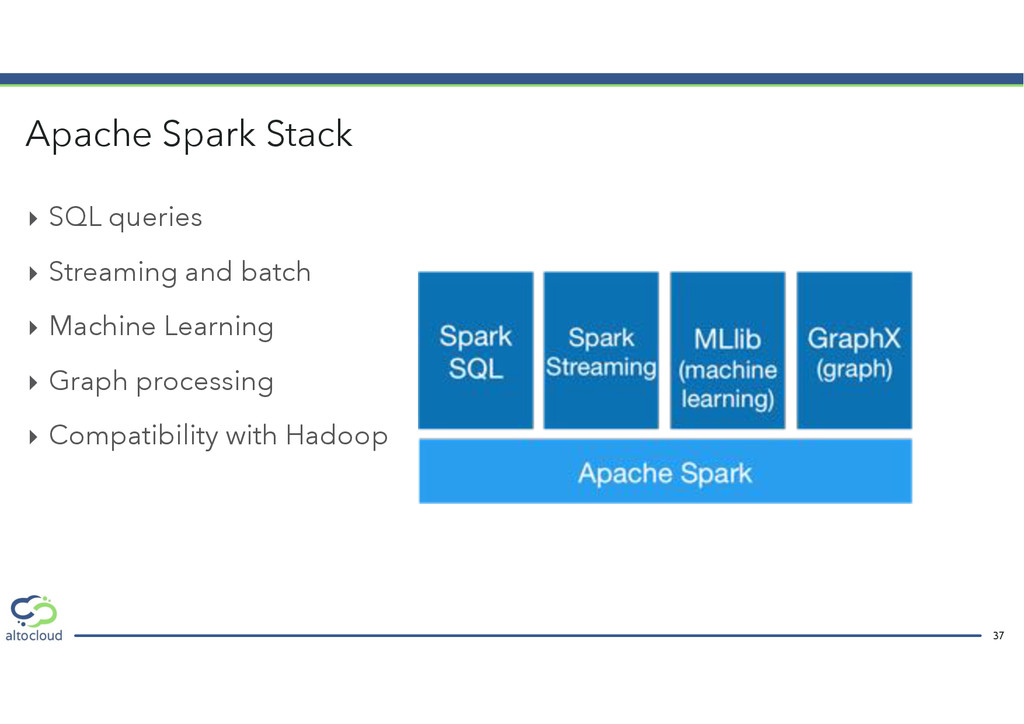
  17. ‣ SQL queries ‣ Streaming and batch ‣ Machine Learning

    ‣ Graph processing ‣ Compatibility with Hadoop Apache Spark Stack 37
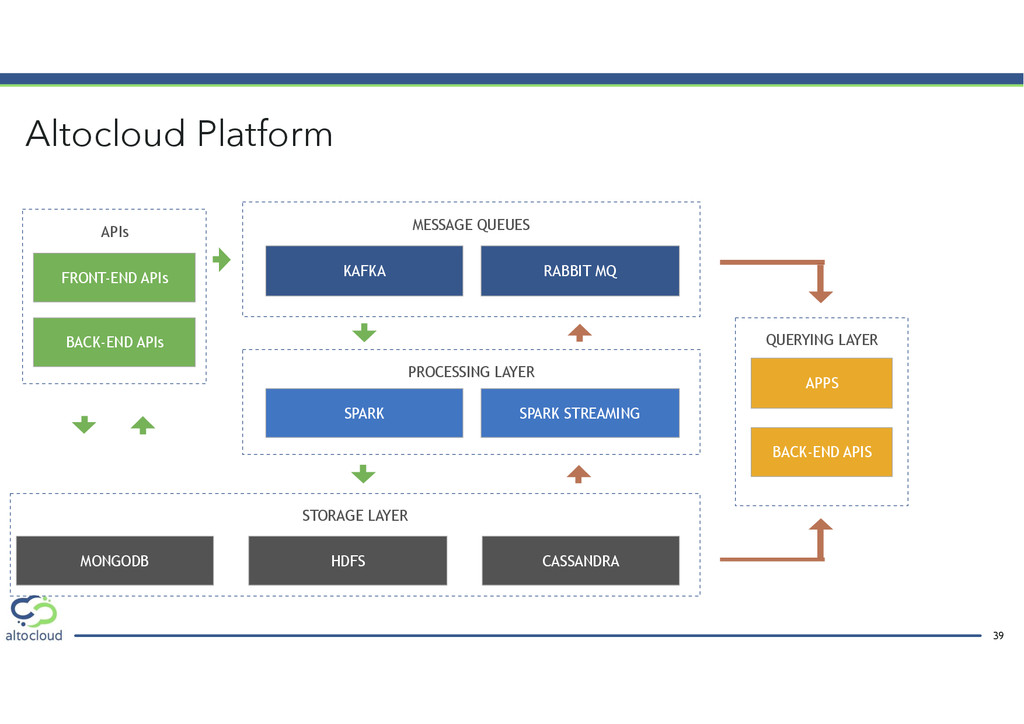
  18. APIs QUERYING LAYER STORAGE LAYER PROCESSING LAYER Altocloud Platform 39

    MESSAGE QUEUES FRONT-END APIs KAFKA SPARK RABBIT MQ CASSANDRA SPARK STREAMING HDFS BACK-END APIS APPS BACK-END APIs MONGODB
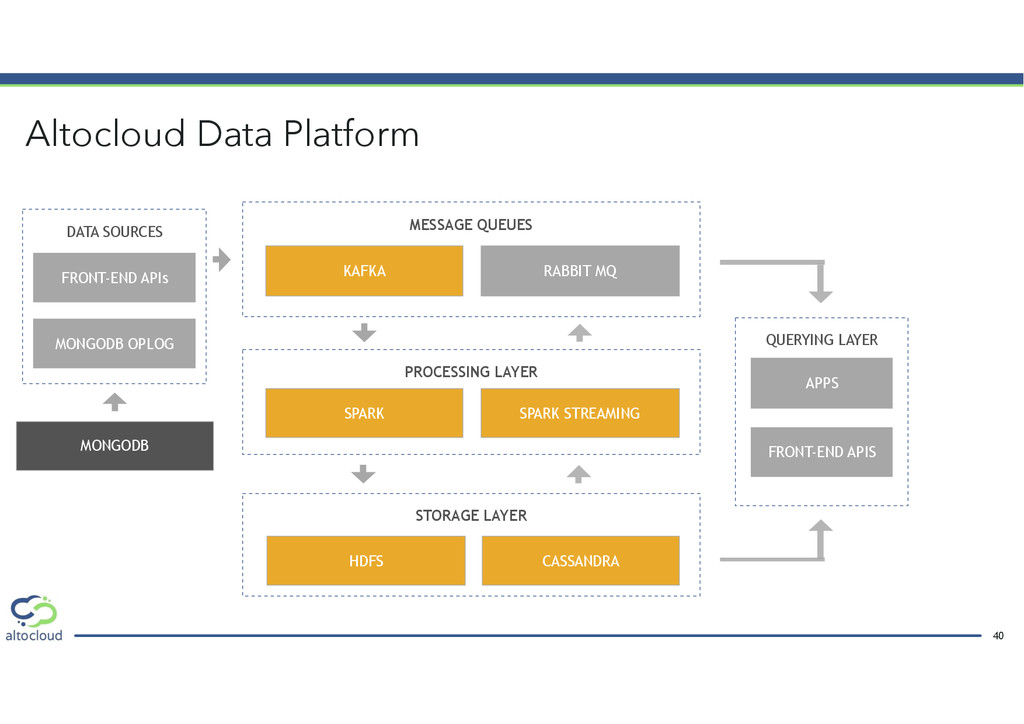
  19. DATA SOURCES QUERYING LAYER STORAGE LAYER PROCESSING LAYER Altocloud Data

    Platform 40 MESSAGE QUEUES FRONT-END APIs KAFKA MONGODB OPLOG SPARK RABBIT MQ CASSANDRA SPARK STREAMING HDFS FRONT-END APIS APPS MONGODB
  20. ‣ One code base for streaming and batch processing ‣

    Rich API in Scala/Python/Java ‣ Fast for iterative algorithms (important for ML) ‣ Growing community ‣ The concept of a micro-batch ‣ Nicely integrates with Kafka and Cassandra ‣ Fairly easy setup Why Spark 41
  21. ‣ User activity is an input (e.g. page view) ‣

    Users for multiple businesses online ‣ Scale 100s to 100 000s activities per second ‣ Response time under 5s ‣ A perfect use case for spark streaming Counting users currently online 43
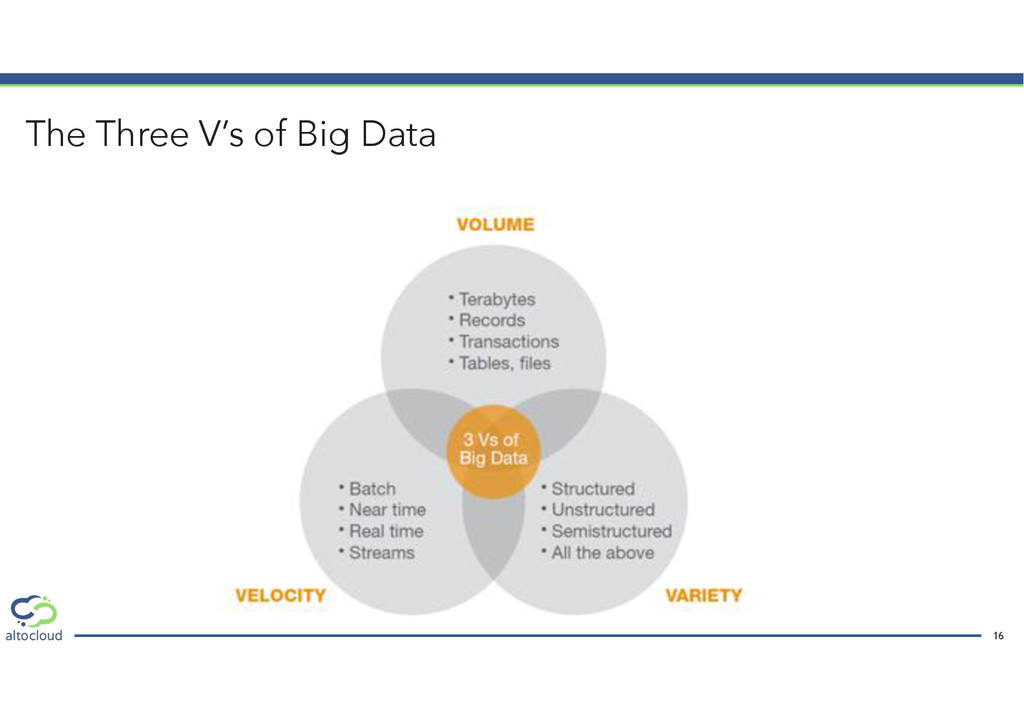
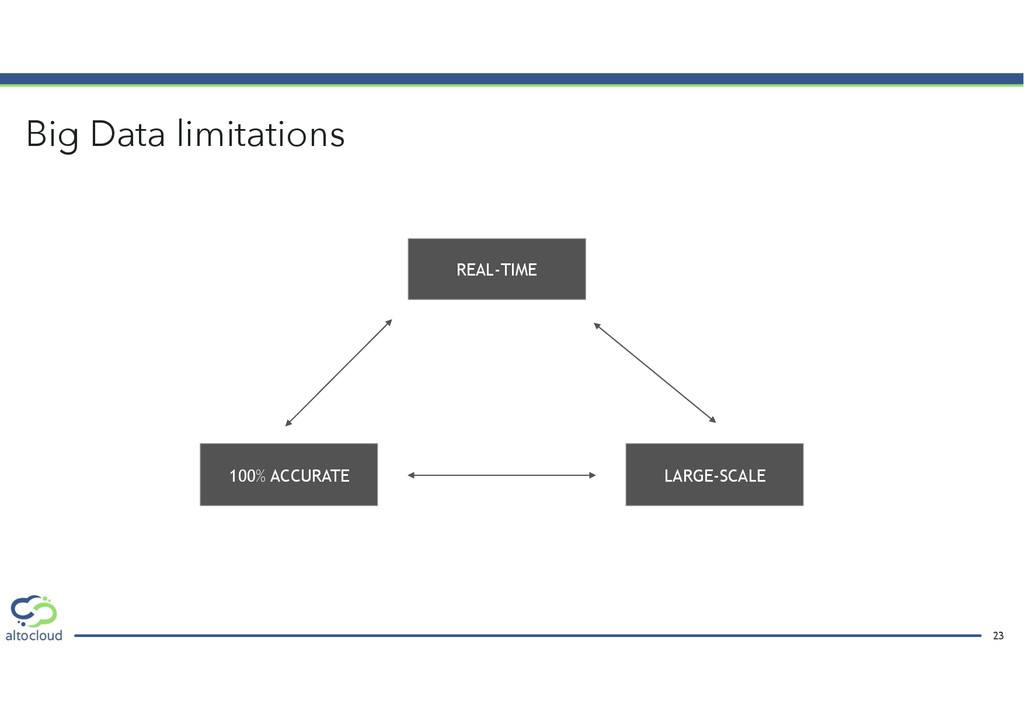
  22. ‣ Big Data Concepts • Data features, 3 Vs, Big

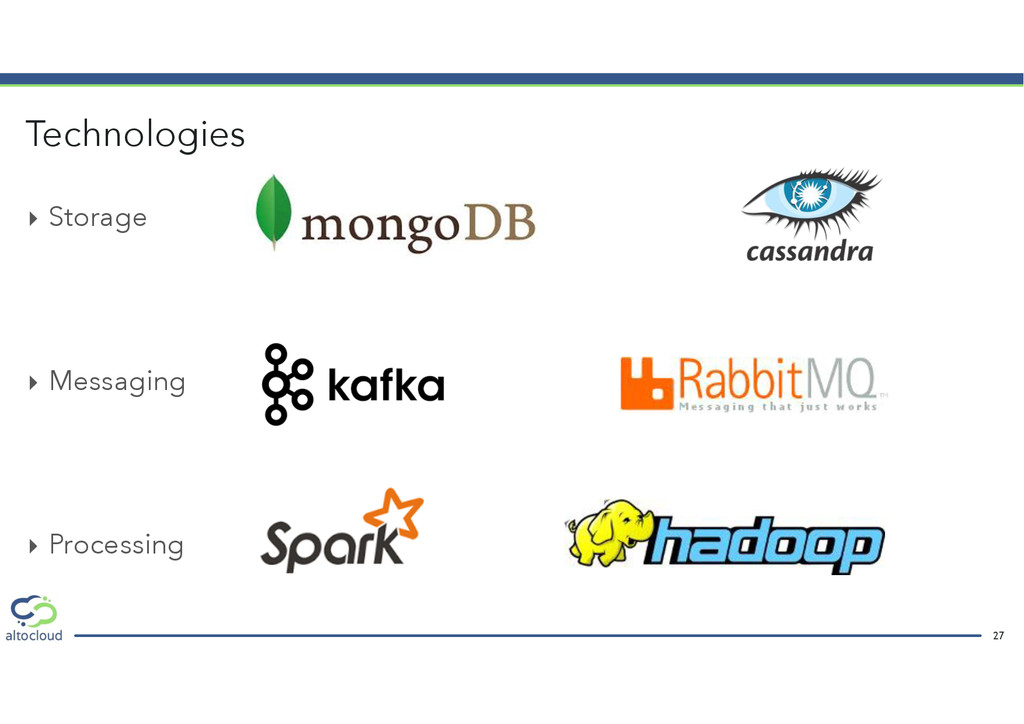
    Data limitations ‣ Analytics Use Cases • Real-time, reporting, predictive, streaming vs. batch ‣ Technologies • Storage (MongoDB, Cassandra), Messaging (Kafka, RabbitMQ), Processing (Hadoop, Spark) Recap 44
  23. ‣ Streaming raw sensor data ‣ Real-time processing ‣ Both

    small and large volume Future - Internet of Things 45 source: https://www.mapr.com/blog/key-requirements-iot-data-platform
  24. ‣ Spark Documentation ‣ Reference application: http://github.com/killrweather/killrweather ‣ Productionalizing Spark

    Streaming ‣ Spark and Kafka ‣ Docker ‣ Free Hadoop Training from MapR ‣ Free edX course on Spark ‣ IoT: http://cdn.oreillystatic.com/en/assets/1/event/120/Opportunities%20and%20Challenges %20of%20Data%20Processing%20in%20the%20Internet%20of%20Things%20_IoT_ %20Presentation.pdf Resources 46