Share
Embed
David Eyers - University of Otago, New Zealand
"Multicore CPUs: power vs. energy considerations in Cloud Computing workloads"

Multicore World
July 17, 2012
Transcript
17 slides
-
Multicore CPUs: power vs. energy considerations in Cloud Computing workloads
David Eyers ([email protected]) Presenting work by Jason Mair and the Otago Systems Research Group -
Motivation • Can productively interlink the benefits of: – Multicore
Computing, – Green Computing, and – Cloud Computing • We want to investigate power consumption tradeoffs against execution time for a workload of discrete tasks submitted to a multicore server • Multicore (WLOG manycore) provides a very different landscape from conventional, serial processors – We aim to optimise scheduling for different workloads 2 -
Talk outline • Motivation and background • Green metrics •
Power versus energy • Multicore scheduling options • Experimental results • Future work • Conclusions 3 -
Green: Cloud & Multicore • Better energy efficiency in computing:
– large-scale: cloud computing, small-scale: multicore CPUs • Cloud-based server consolidation can clearly save energy – plus economies of scale regarding all types of infrastructure • Multicore has reversed previous decades’ trend – Parallelism, and increasingly distribution, are a part of almost all computer CPU architectures – This community knows that, of course! – Still challenges regarding support for multicore CPUs in the designs of common programming languages and operating systems. 4 -
Emphasis: green energy metrics • Green computing unsurprisingly focuses on
power – Instead, our research focuses on maximising the total energy savings recouped over the completion of a set of computing jobs – Developing CPUs that require less power does not necessarily guarantee improved energy efficiency for a given set of tasks – (but it’s still a good idea!) – Our work makes heavy use of Dynamic Voltage and Frequency Scaling (DVFS) in order to optimise overall energy usage • Common green computing metric: Performance per Watt – We introduce other metrics: Speedup per Watt (SPW), Power per Speedup (PPS) and Energy per Target (EPT) 5 -
Power/energy in cloud context? • Explore two key aspects of
Cloud Computing workloads: – Novel scheduling policies that may employ periods of higher power usage in order to produce lower overall energy consumption – Take advantage of the particular processing consolidation options that multicore CPUs can provide • Take-away from Zhiyi’s presentation yesterday: want workload knowledge for job scheduling – Can change the total execution time of those jobs, and thus facilitate overall energy savings – Cloud Computing environments likely to provide heterogeneity of jobs, scale of server numbers and appropriate limits of job queue sizes to make effective use of energy-aware scheduling schemes 6 -
Burning power to save energy • A key idea: evoke
fable of race between Tortoise and Hare – Hare is high power, tortoise low power, similar overall energy – Both Hare and Tortoise provide useful scheduling approaches that are optimal for different types of workload • However, race-to-sleep approaches have requirements: – Rate of job arrival cannot depend on the service rate – Must be a mechanism to recoup short-term energy cost • Must be time available, and energy savings to be gained from switching CPU into aggressive power-saving mode – Need to consider delays between power-saving states 7 -
Unique MC scheduling options • Need discrete tasks/jobs, and ideally
intra-job parallelism • Power-aware scheduler can consider combinations of inter-application or intra-application parallelism applied to the jobs—also referred to as ‘exclusive’ and ‘sharing’ policies respectively in our research – cores can be used to run different jobs in parallel – ... or cores can be used to run a job’s many threads in parallel – (or some intermediate combination of these two extremes) – Scheduler can apply DVFS alter the instantaneous power properties of the overall CPU, and in most cases of the individual cores too. 8 -
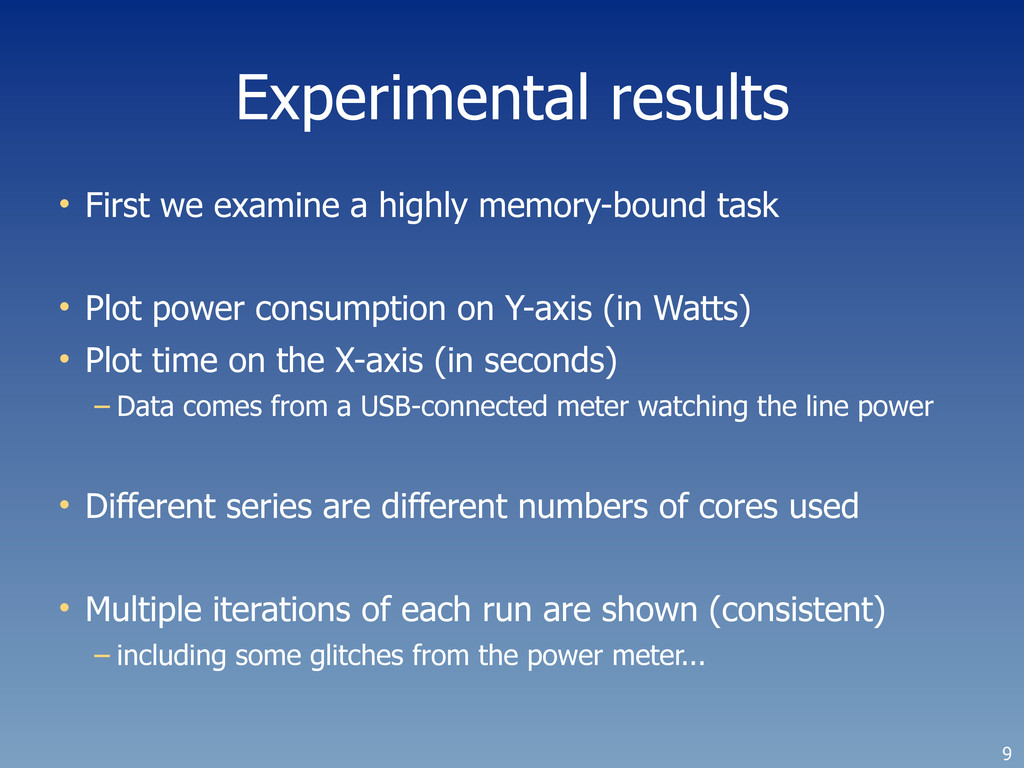
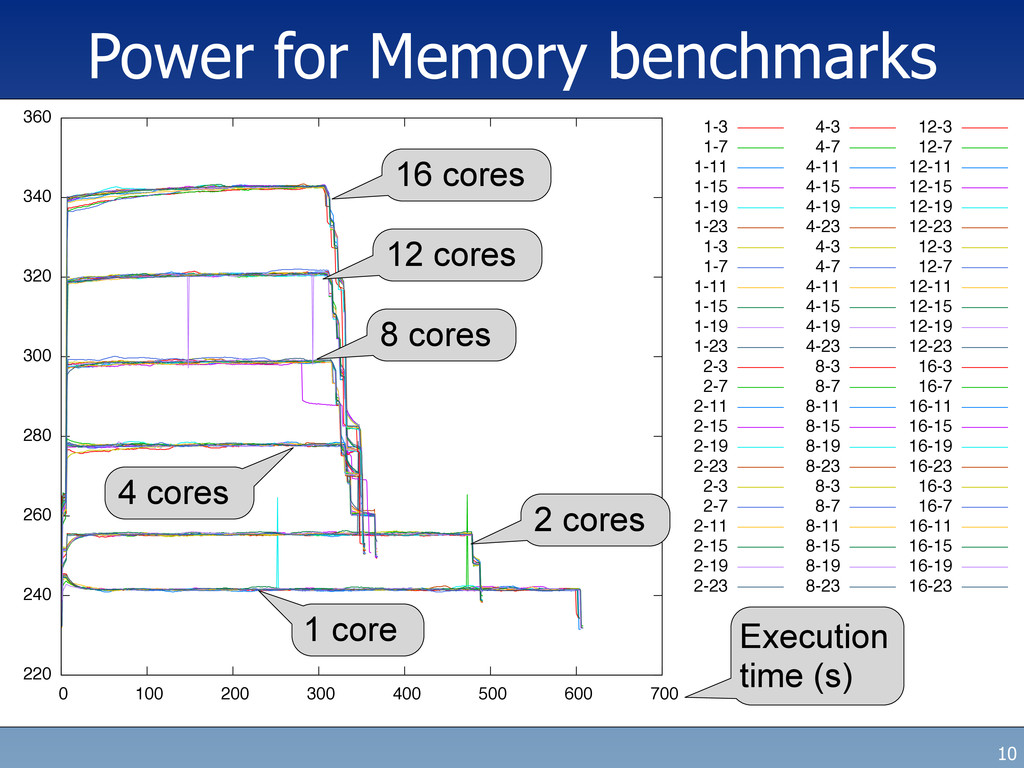
Experimental results • First we examine a highly memory-bound task
• Plot power consumption on Y-axis (in Watts) • Plot time on the X-axis (in seconds) – Data comes from a USB-connected meter watching the line power • Different series are different numbers of cores used • Multiple iterations of each run are shown (consistent) – including some glitches from the power meter... 9 -
Power for Memory benchmarks 10 220 240 260 280 300
320 340 360 0 100 200 300 400 500 600 700 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 4-3 4-7 4-11 4-15 4-19 4-23 4-3 4-7 4-11 4-15 4-19 4-23 8-3 8-7 8-11 8-15 8-19 8-23 8-3 8-7 8-11 8-15 8-19 8-23 12-3 12-7 12-11 12-15 12-19 12-23 12-3 12-7 12-11 12-15 12-19 12-23 16-3 16-7 16-11 16-15 16-19 16-23 16-3 16-7 16-11 16-15 16-19 16-23 16 cores 12 cores 8 cores 4 cores 2 cores 1 core Execution time (s) -
Power for Memory benchmarks 11 220 240 260 280 300
320 340 360 0 100 200 300 400 500 600 700 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 4-3 4-7 4-11 4-15 4-19 4-23 4-3 4-7 4-11 4-15 4-19 4-23 8-3 8-7 8-11 8-15 8-19 8-23 8-3 8-7 8-11 8-15 8-19 8-23 12-3 12-7 12-11 12-15 12-19 12-23 12-3 12-7 12-11 12-15 12-19 12-23 16-3 16-7 16-11 16-15 16-19 16-23 16-3 16-7 16-11 16-15 16-19 16-23 220 230 240 250 260 270 280 290 300 0 100 200 300 400 500 600 700 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 4-3 4-7 4-11 4-15 4-19 4-23 4-3 4-7 4-11 4-15 4-19 4-23 8-3 8-7 8-11 8-15 8-19 8-23 8-3 8-7 8-11 8-15 8-19 8-23 12-3 12-7 12-11 12-15 12-19 12-23 12-3 12-7 12-11 12-15 12-19 12-23 16-3 16-7 16-11 16-15 16-19 16-23 16-3 16-7 16-11 16-15 16-19 16-23 200 210 220 230 240 250 260 270 0 100 200 300 400 500 600 700 800 900 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 4-3 4-7 4-11 4-15 4-19 4-23 4-3 4-7 4-11 4-15 4-19 4-23 8-3 8-7 8-11 8-15 8-19 8-23 8-3 8-7 8-11 8-15 8-19 8-23 12-3 12-7 12-11 12-15 12-19 12-23 12-3 12-7 12-11 12-15 12-19 12-23 16-3 16-7 16-11 16-15 16-19 16-23 16-3 16-7 16-11 16-15 16-19 16-23 200 210 220 230 240 250 260 270 0 200 400 600 800 1000 1200 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 4-3 4-7 4-11 4-15 4-19 4-23 4-3 4-7 4-11 4-15 4-19 4-23 8-3 8-7 8-11 8-15 8-19 8-23 8-3 8-7 8-11 8-15 8-19 8-23 12-3 12-7 12-11 12-15 12-19 12-23 12-3 12-7 12-11 12-15 12-19 12-23 16-3 16-7 16-11 16-15 16-19 16-23 16-3 16-7 16-11 16-15 16-19 16-23 2.5GHz 1.8GHz 1.3GHz 0.8GHz -
Analysis • Care about deadline, but want to save power?
• Best in this case to run on only four cores – Leaves 12 cores to do other work (or go to low power) – Time is about 60% of the time taken by one core – Takes about 62% of the energy compared to one core – However, what do I mean by this case? • Memory micro-benchmark stresses whole RAM hierarchy – Note that we are seeing AMD NUMA effect here: • Optimal to use all cores on one die – While not unsurprising (considering NUMA) we still need to know what the actual difference is! 12 -
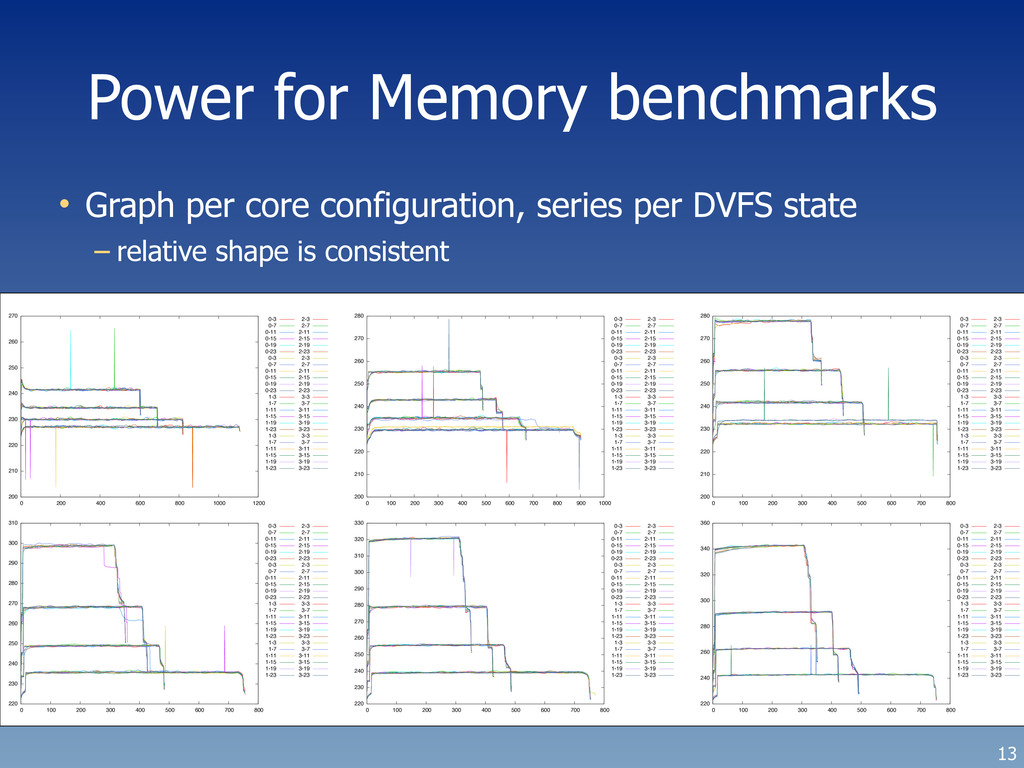
Power for Memory benchmarks 13 200 210 220 230 240
250 260 270 280 0 100 200 300 400 500 600 700 800 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 220 230 240 250 260 270 280 290 300 310 0 100 200 300 400 500 600 700 800 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 220 230 240 250 260 270 280 290 300 310 320 330 0 100 200 300 400 500 600 700 800 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 220 240 260 280 300 320 340 360 0 100 200 300 400 500 600 700 800 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 200 210 220 230 240 250 260 270 0 200 400 600 800 1000 1200 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 200 210 220 230 240 250 260 270 280 0 100 200 300 400 500 600 700 800 900 1000 0-3 0-7 0-11 0-15 0-19 0-23 0-3 0-7 0-11 0-15 0-19 0-23 1-3 1-7 1-11 1-15 1-19 1-23 1-3 1-7 1-11 1-15 1-19 1-23 2-3 2-7 2-11 2-15 2-19 2-23 2-3 2-7 2-11 2-15 2-19 2-23 3-3 3-7 3-11 3-15 3-19 3-23 3-3 3-7 3-11 3-15 3-19 3-23 • Graph per core configuration, series per DVFS state – relative shape is consistent -
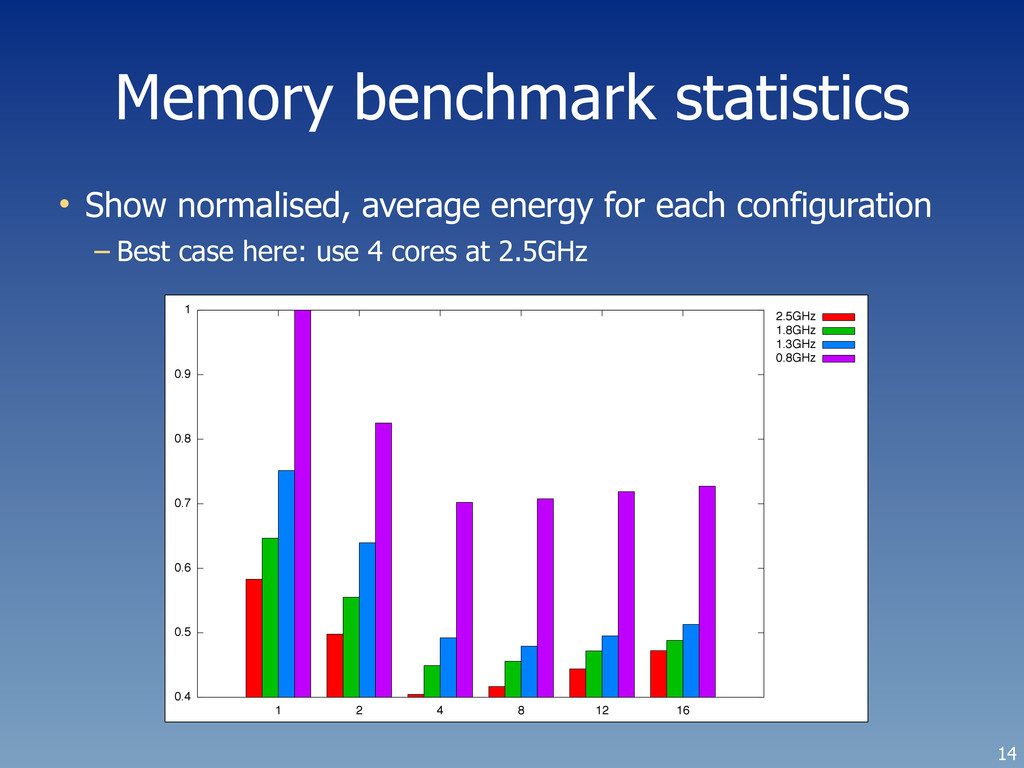
Memory benchmark statistics 14 • Show normalised, average energy for
each configuration – Best case here: use 4 cores at 2.5GHz 0.4 0.5 0.6 0.7 0.8 0.9 1 1 2 4 8 12 16 2.5GHz 1.8GHz 1.3GHz 0.8GHz -
Take-away message • Behaviour of a given machine is not
entirely predictable – ... but it is easy to measure the results of scheduling decisions • Just looked at the memory micro-benchmark in this talk – Also have a CPU-heavy micro-benchmark – ... and a set of less extreme benchmarks • Our methodology for optimising against a given workload can be applied easily – ongoing work to filter the data to collect, and simplify the analysis 15 -
Future work • Characterising workloads dynamically – Zhiyi talked yesterday
about dynamic task characterisation for asymmetric multicore – Similar approaches work for energy-efficient multicore scheduling – e.g. memory versus CPU-bound implies different scheduling • More kit! Results are dependent on the machine at hand – ... although the methodology generalises – Buying 64-core machine later this year (4x 16-core) – Anyone have any spare 256-core machines they want to lend us? 16 -
Conclusions • Multicore provides a middle-ground between power optimisation at
a per-node level and a serial CPU speed – Complexities from fundamental machine architecture (e.g. NUMA) • Experimental results: saving power does not necessarily reduce energy use for discrete jobs with deadlines. • Our energy-aware scheduling benefits are greatly amplified by multicore CPUs, and apply to cloud workloads • Questions? 17
 multicoreworld
 analokmaus
 anikisencyo
 ishiirikie
 rikkabotan7
 ept
 institutdelelevage
 satai
 hellosct1
 ivargrimstad
 csswizardry
 aleyda
 jlugia
 jcasabona
 tessaabrams
 greggifford
 akosma
 livdayseo
 hatefulcrawdad
 nmsamuel