Share
Embed
文献紹介:HMM Parameter Learning for Japanese Morphological Analyzer
Van Hai
April 25, 2017
Transcript
15 slides
-
1 文献紹介 (2017.04.25) 長岡技術科学大学 自然言語処理 Nguyen Van Hai HMM Parameter
Learning for Japanese Morphological Analyzer Koichi Takeuchi and Yuji Matsumoto Graduate School of Information Science Nara Institute of Science and Technology {kouit-t, matsu}@is.aist-nara.ac.jp 情報処理学会論文誌 , Vol38, No.3 -
2 Introduction • Apply Hidden Markov Model (HMM) to parameter
learning for Japanese Morphological Analyzer. • Measure the effect of two information sources: – The initial value of parameters – Some grammatical constraints that hold in Japanese sentences • The final result gives that total performance of the HMM-based parameter achieves almost the same level -
3 Previous Works • Statistical method: – Church use trigram
probabilities from tagged Brown corpus and achieved over 95% precision in English Part-of-speech tagging. – Cutting used HMM to estimate probability parameters for the tagger and achieved 96% precision. – Chang and Chen applied HMM to part-of-speech tagging of Chinese • -
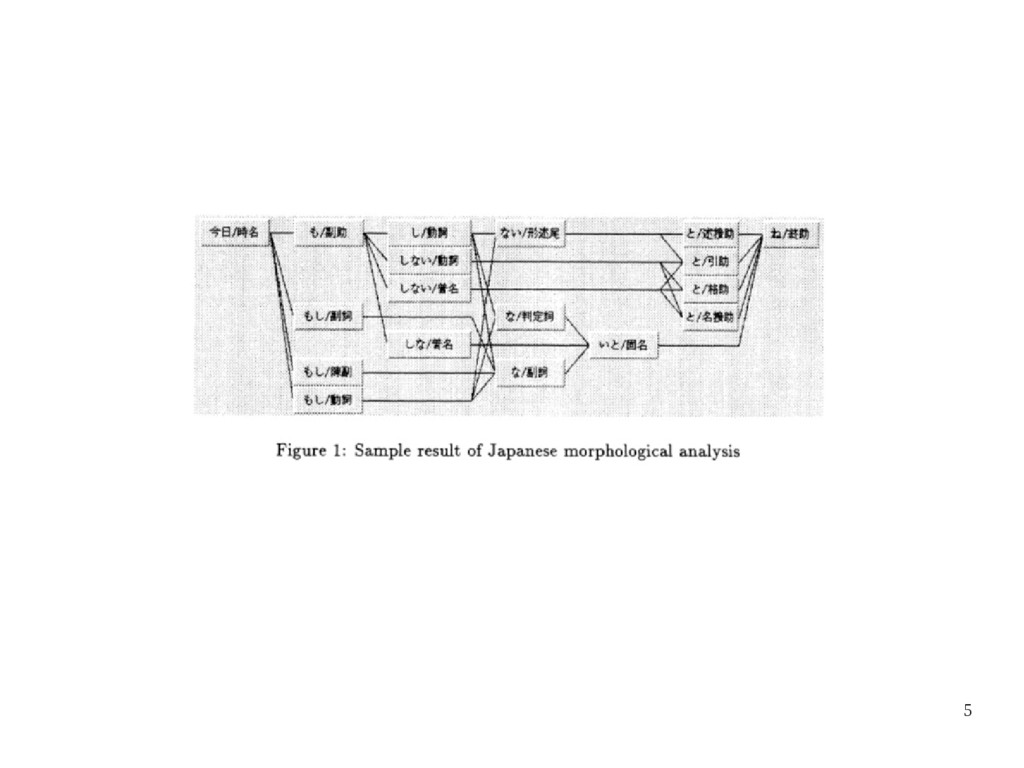
4 JUMAN Morphological Analyzer • JUMAN was developed at NAIST
and Kyoto University: – Lexical entries cost – Connectivity of adjacent parts-of-speech • The result of an analysis is a lattice-lie structure of word, of which the path with the least total cost is selected as the most plausible answer. • performance of the JUMAN system is 93% 95% accuracy -
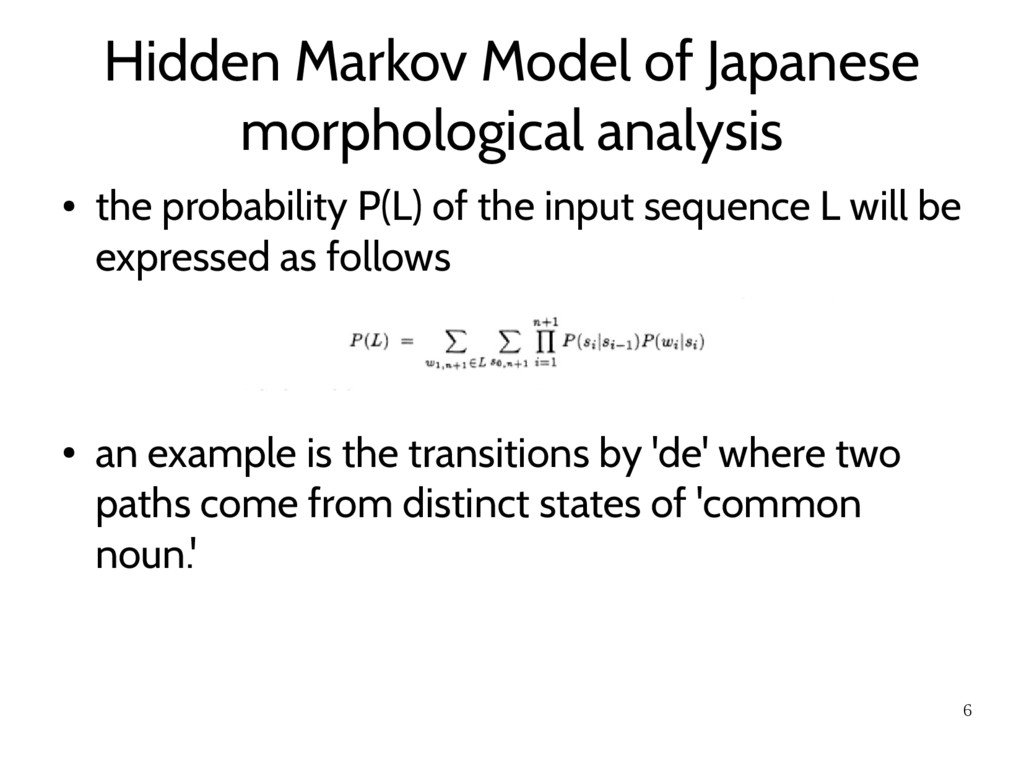
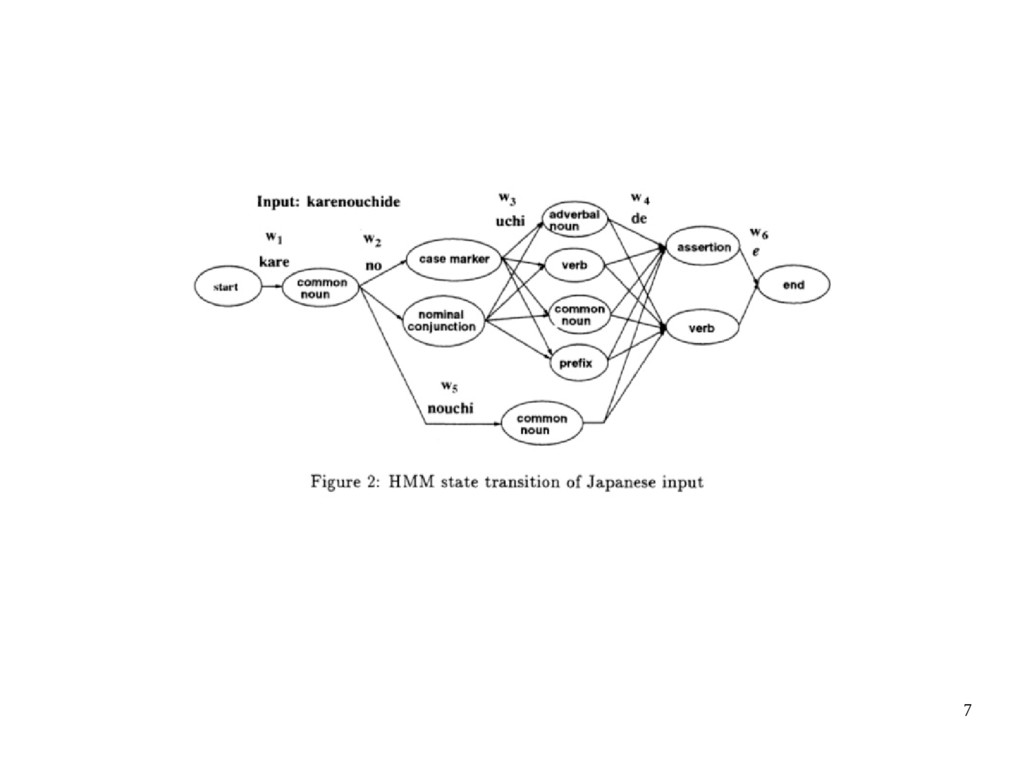
6 Hidden Markov Model of Japanese morphological analysis • the
probability P(L) of the input sequence L will be expressed as follows • an example is the transitions by 'de' where two paths come from distinct states of 'common noun.' -
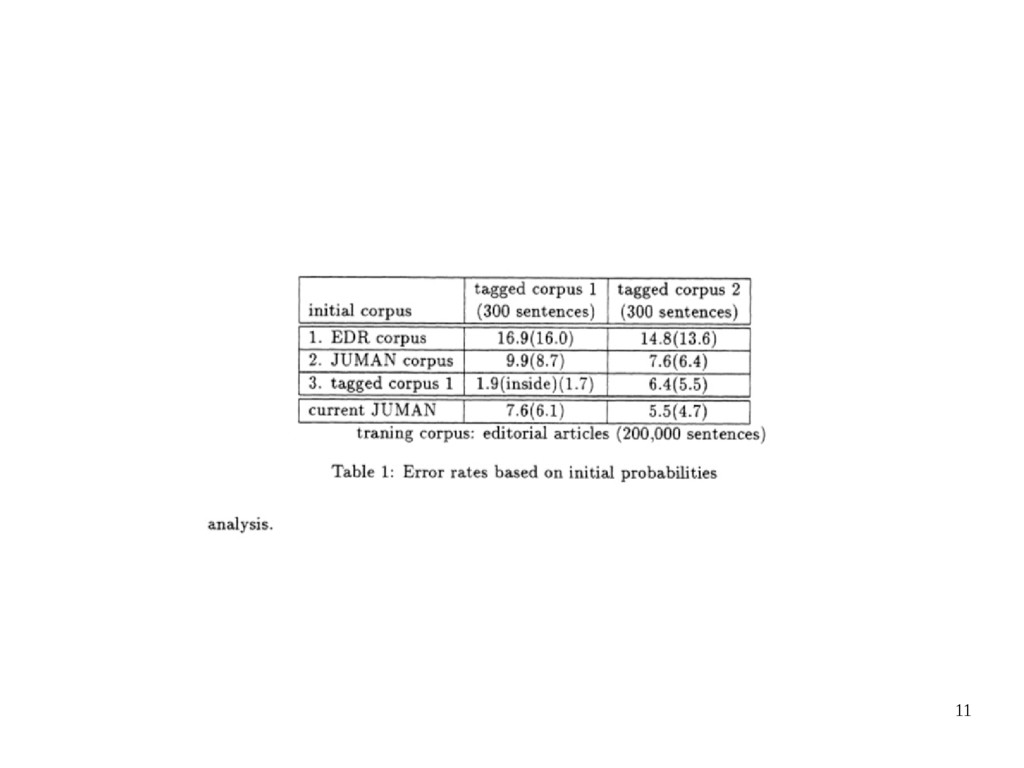
9 HMM parameter Learning • The result of HMM parameter
learning with Japanese newspaper editorial articles give the accuracy of lower than 20%. – Japanese texts do not specify word boundaries • improve the learning performance – the initial probabilities – grammatical constraints -
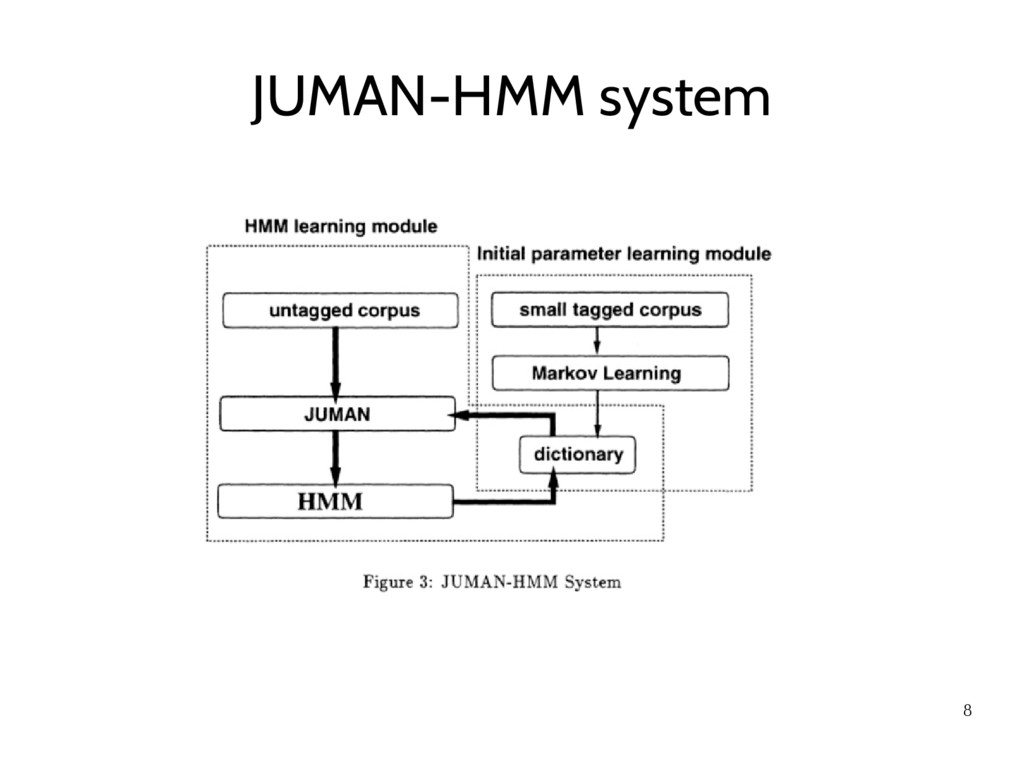
10 Effect of initial probability • Initial probabilities of transitions
and word occurrences are easily obtainable if there is a large scale tagged corpus – EDR tagged corpus – Asahi Newspaper editorial articles tagged by JUMAN system (65,000 sentences) – Manually tagged editorial articles (300 sentences) -
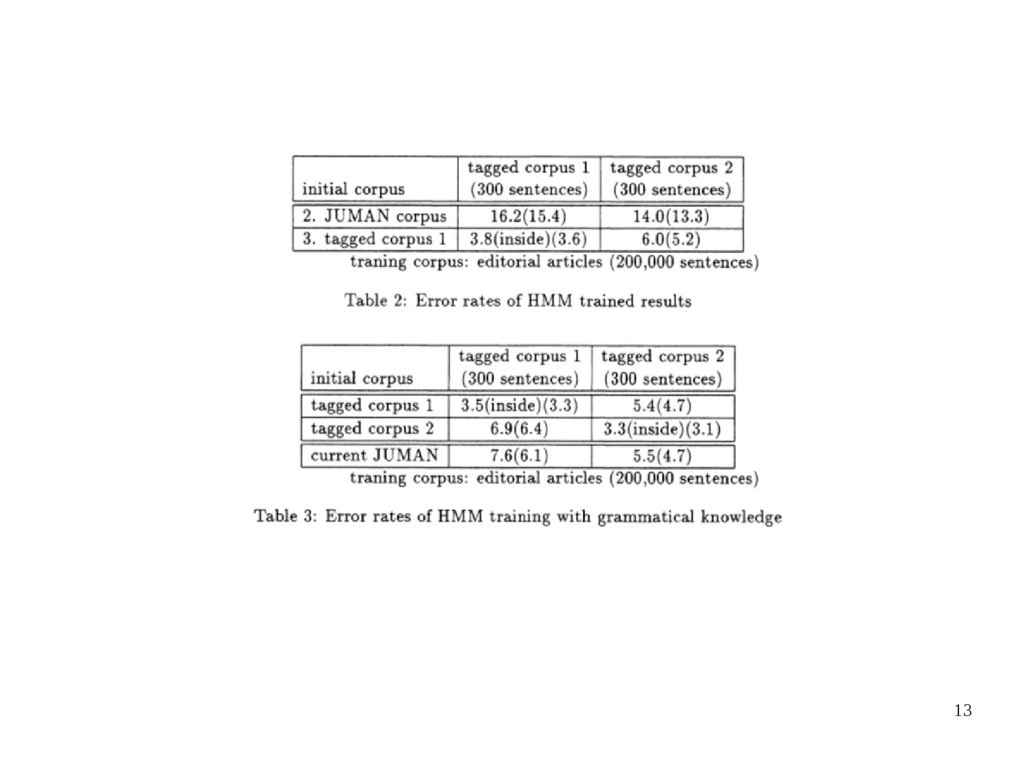
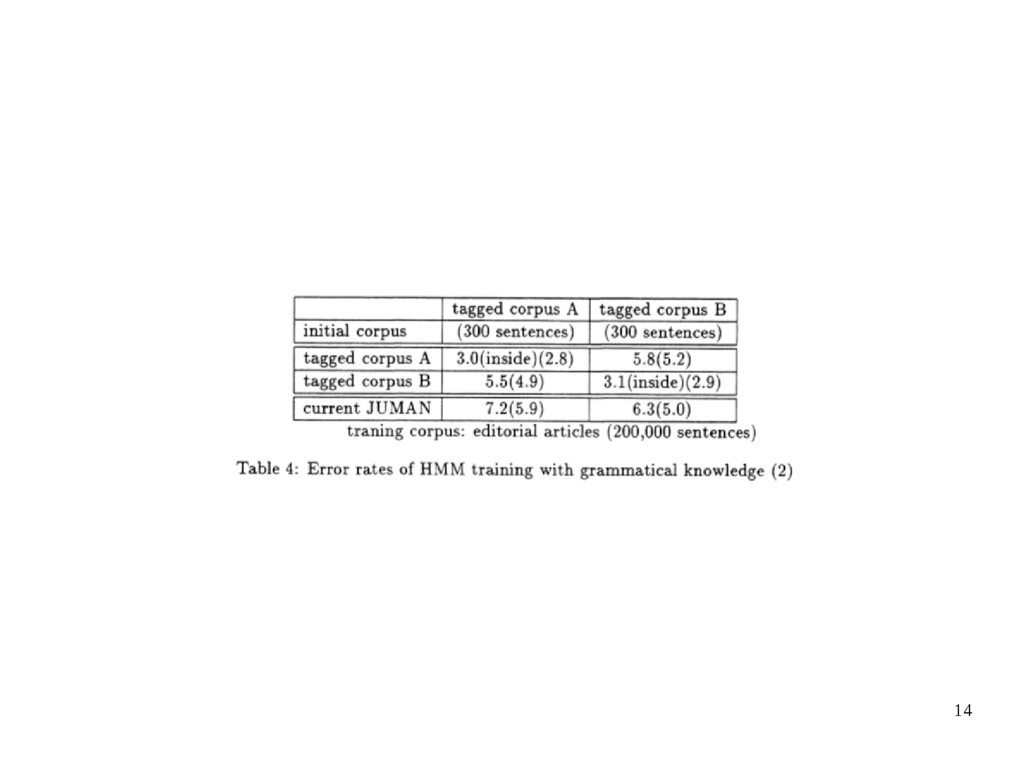
12 Incorporating grammatical knowledge • HMM learned probabilities allow some
grammatically unacceptable connections: – a prefix precedes a postfix – a stem of a verb precedes a non-inflectional suffix • unacceptable connections (about 15 rules) by fixing the probabilities of those adjacent occurrences to zero probability -
15 Conclusions • applying HMM parameter learning to Japanese morphological
analyzer • the initial probabilities and grammatical knowledge perform improving the results of HMM parameter learning