Share
Embed
文献紹介:A Supervised Learning Approach to Automatic Synonym Identification based on Distributional Features
Van Hai
April 04, 2016
Transcript
11 slides
-
1 文献紹介 (2016.04.04) 長岡技術科学大学 自然言語処理 Nguyen Van Hai A Supervised
Learning Approach to Automatic Synonym Identification based on Distributional Features Masato Higiwara Graduate School of Information Science Nagoya University Proceedings of the ACL-08: HLT Student Research Workshop (Companion Volume), p1-6, Columbus, June 2008. -
2 Abstract • Distribution similarity been used to capture the
semantic relatedness of word in NLP tasks. • This paper use a novel approach to synonym identification based on supervised learning and distributional features. • The F1 of this evaluation experiment increase over 120%, compared with the conventional classification. -
3 Introduction • Distribution similarity representations the relatedness of two
words by the commonality of context. • Syntactic pattern such as “such X as Y” and “Y and other X”, and extract hyponym relation of X and Y. • This paper , they re-formalize synonym acquisition as a classification which classifies word pairs into synonym/non-synonym. -
4 Distribution features • Adopt dependency structure as the context
of words. • RASP Toolkit 2 (Briscoe et at., 2006) is used to extract word relations. • RASP outputs the extracted dependency structure as n-ray relations as follows: -
6 Distribution features • Extract the set of co-occurrences of
stemmed word and context. • Using co-occurrences extracted, they define distribution features • The feature value is calculated as the sum of two corresponding pointwise mutual information weight. -
7 Pattern-based Features • Define as the concatenation of the
words and relations which are on the dependency path. • In the experiment, they limited the maximim length of syntactic path to five. • Define and calculate the pattern based feature, which corresponds to the syntactic pattern. -
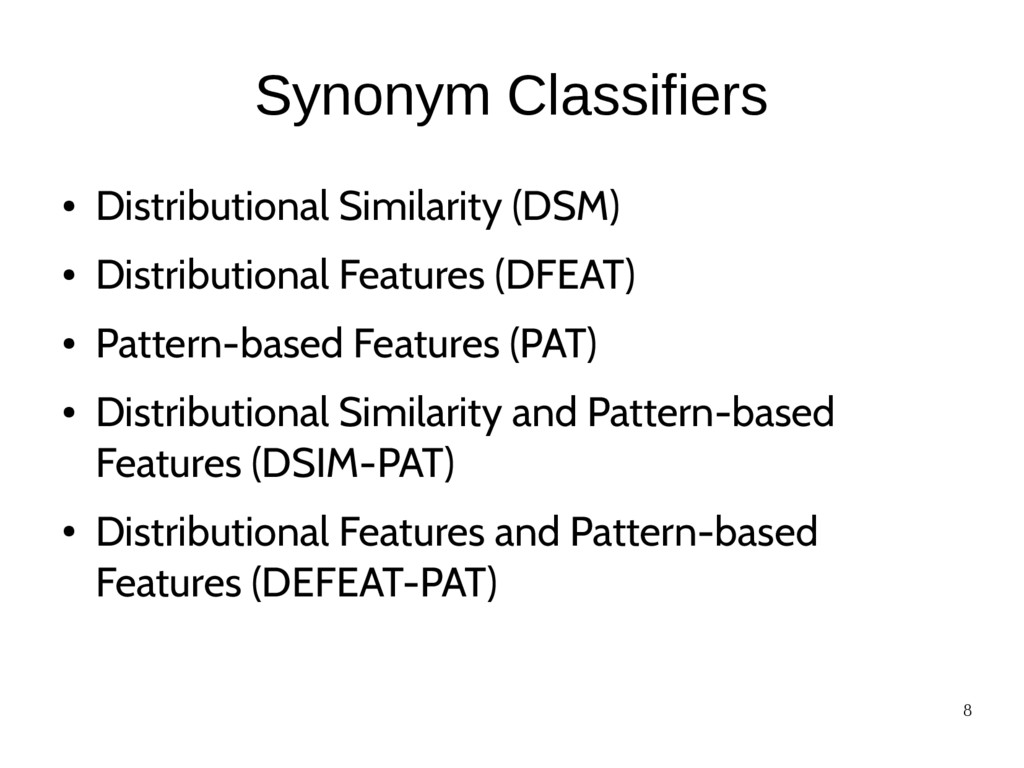
8 Synonym Classifiers • Distributional Similarity (DSM) • Distributional Features
(DFEAT) • Pattern-based Features (PAT) • Distributional Similarity and Pattern-based Features (DSIM-PAT) • Distributional Features and Pattern-based Features (DEFEAT-PAT) -
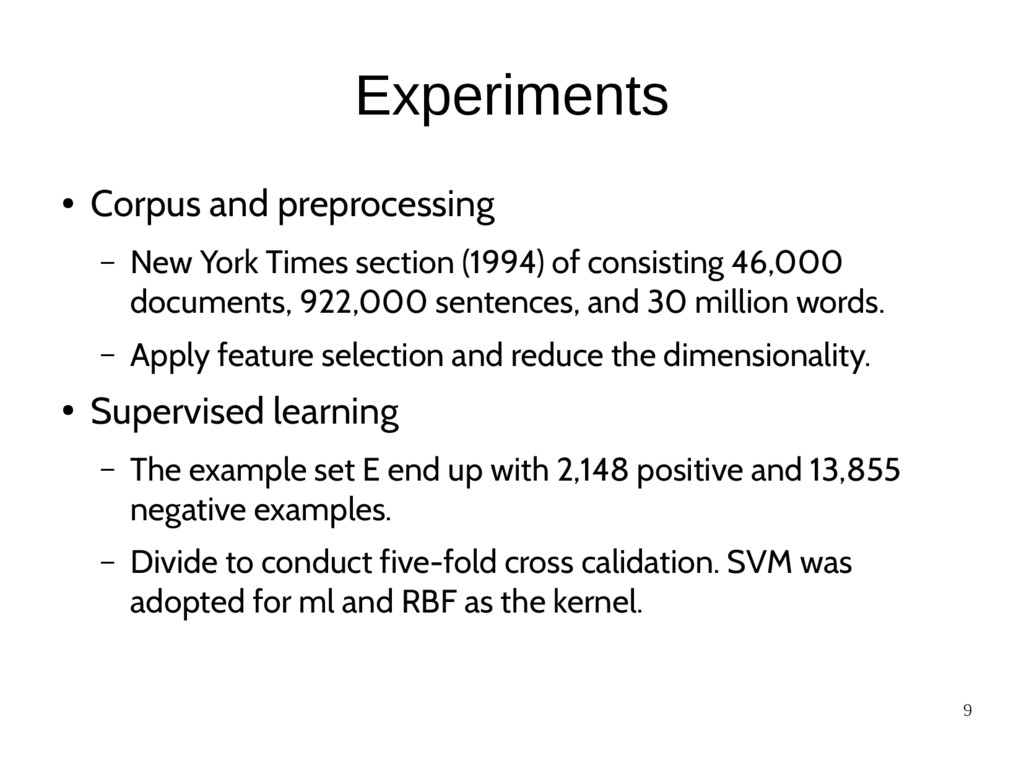
9 Experiments • Corpus and preprocessing – New York Times
section (1994) of consisting 46,000 documents, 922,000 sentences, and 30 million words. – Apply feature selection and reduce the dimensionality. • Supervised learning – The example set E end up with 2,148 positive and 13,855 negative examples. – Divide to conduct five-fold cross calidation. SVM was adopted for ml and RBF as the kernel. -
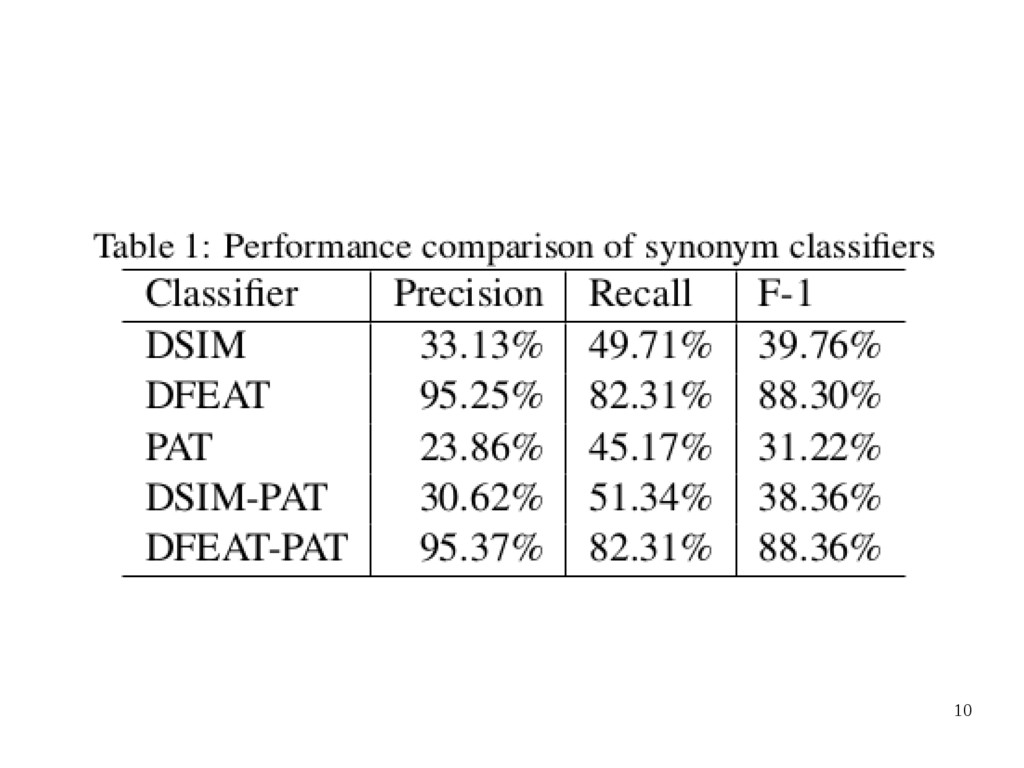
11 Experiments • DFEAT over DSIM- over 120% increase of
F1 • Performance PAT was the lowest, reflect synonym pairs occur in the same sentence makes the identification using syntactic patten more difficult