Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Making DISQUS Realtime

Adam
July 05, 2012

Making DISQUS Realtime

tl;dr: #Python #Architecture #Scalability #DISQUS

What does it take to add realtime functionality to a truly “web scale” app. The result is the DISQUS realtime system, a highly concurrent system for allowing web clients to subscribe to arbitrary events in the DISQUS infrastructure.

Adam

July 05, 2012

Transcript

41 slides
  1. Adam Hitchcock @NorthIsUp Making DISQUS Realtime Thursday, March 21, 13

    suposed to be and advanced talk, but i don’t know what that means (i assume you know some thing)...so I hope this doesn’t bore anybody. - I HATE LONG TALKS, OPEN SPACE. - I TALK FAST, if you can’t understand me please tell me to slow down
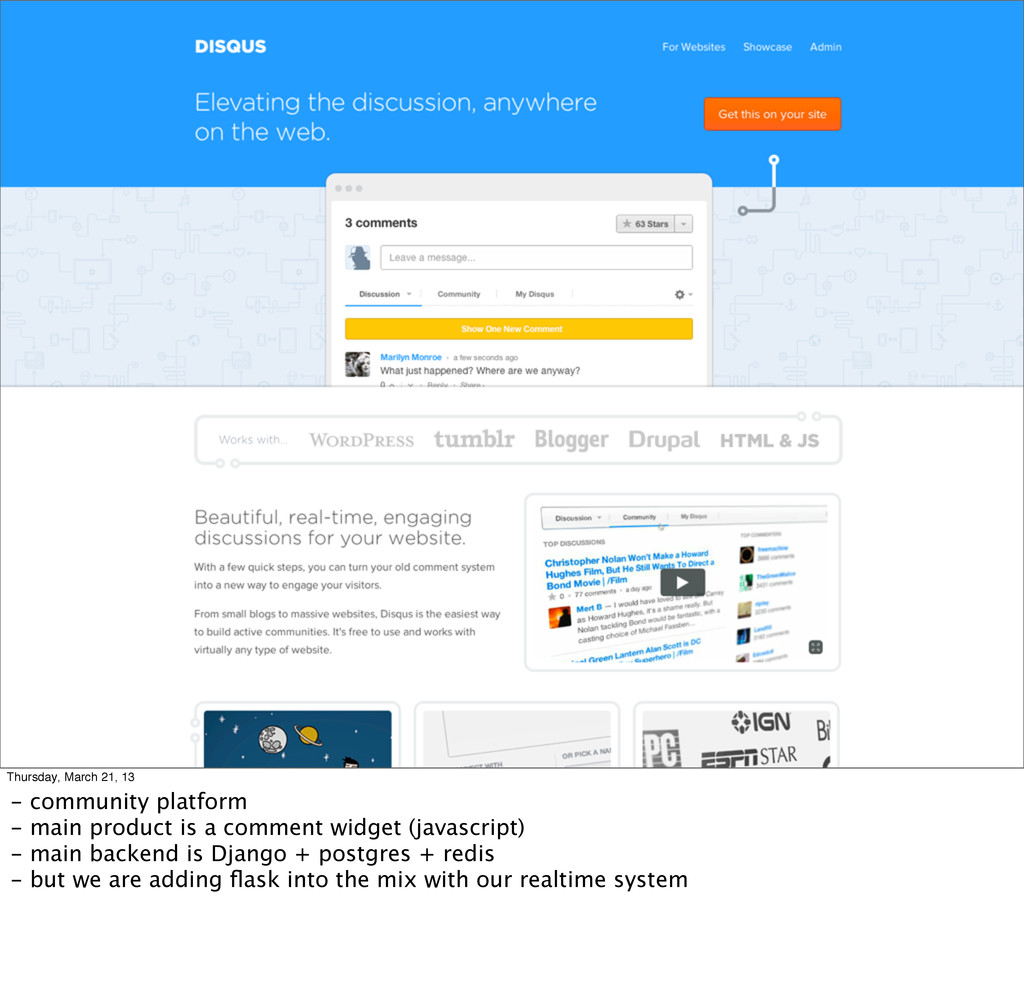
  2. Thursday, March 21, 13 - community platform - main product

    is a comment widget (javascript) - main backend is Django + postgres + redis - but we are adding flask into the mix with our realtime system
  3. why do realtime? ๏ getting new data to the user

    asap ๏ increased engagement ๏ looks awesome ๏ we can sell it Thursday, March 21, 13 We define this as ‘less than 10 seconds’ but my goal was less than one.
  4. how many of you currently have a realtime component? Thursday,

    March 21, 13 well, so do we. and try to keep it short, because you are probably smarter than me, and I want to hear what you have to say (@NorthIsUp)
  5. realtime ๏ polls memcache ๏ is kinda #failscale Thursday, March

    21, 13 - we set a per thread key, this key gets polled every five seconds. - problem is... that is is a #failscale
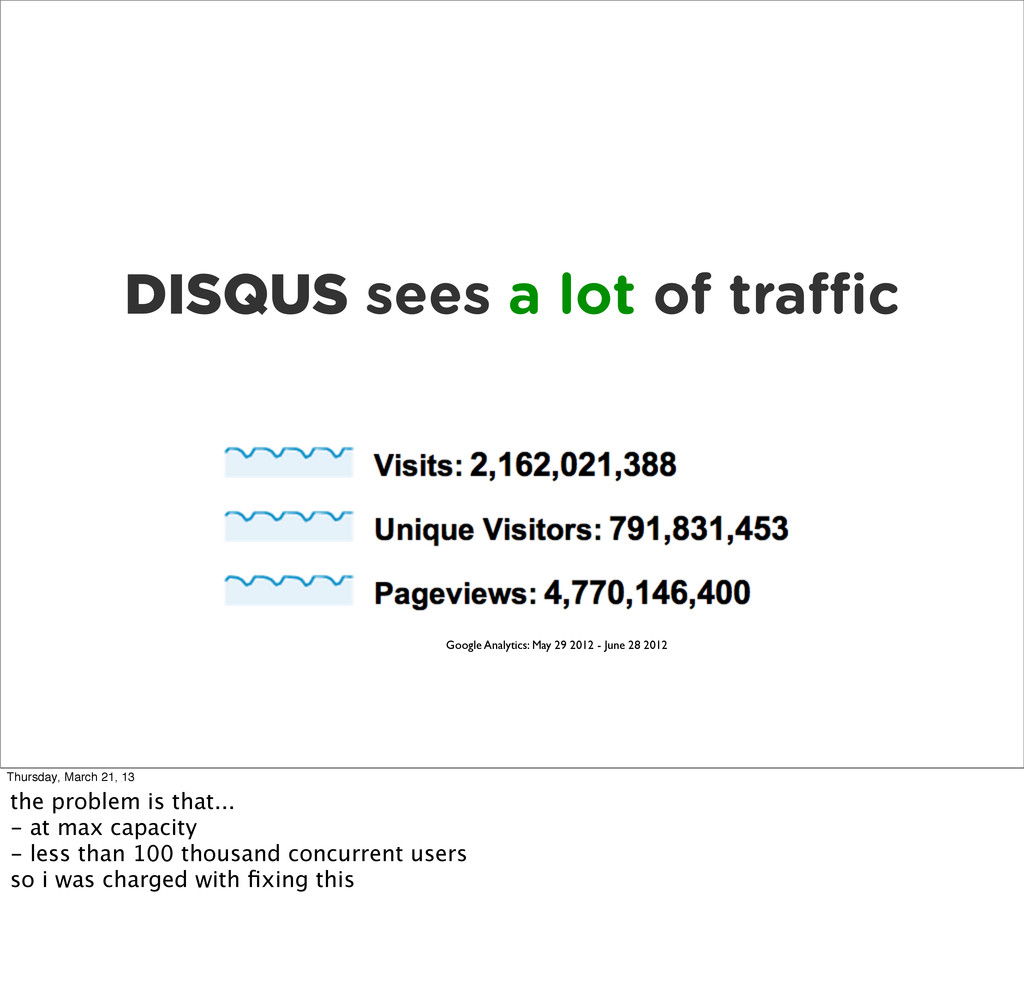
  6. DISQUS sees a lot of tra c Google Analytics: May

    29 2012 - June 28 2012 Thursday, March 21, 13 the problem is that... - at max capacity - less than 100 thousand concurrent users so i was charged with fixing this
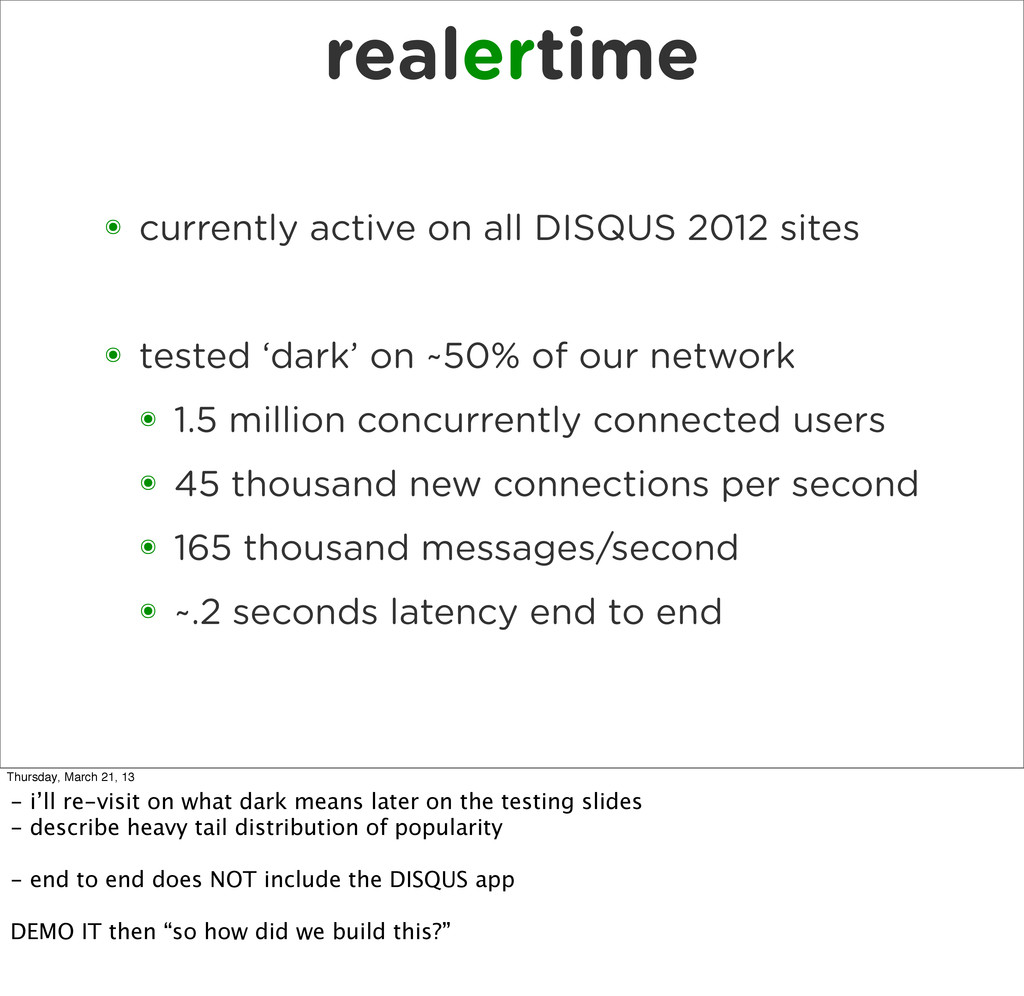
  7. realertime ๏ currently active on all DISQUS 2012 sites ๏

    tested ‘dark’ on ~50% of our network ๏ 1.5 million concurrently connected users ๏ 45 thousand new connections per second ๏ 165 thousand messages/second ๏ ~.2 seconds latency end to end Thursday, March 21, 13 - i’ll re-visit on what dark means later on the testing slides - describe heavy tail distribution of popularity - end to end does NOT include the DISQUS app DEMO IT then “so how did we build this?”
  8. technology ๏ gevent ๏ gunicorn ๏ flask ๏ thoonk (a

    queue built on redis) ๏ redis ๏ nginx ๏ haproxy Thursday, March 21, 13 pubsub == redis thoonk == queues thoonk (each message is delivered to only one subscriber)
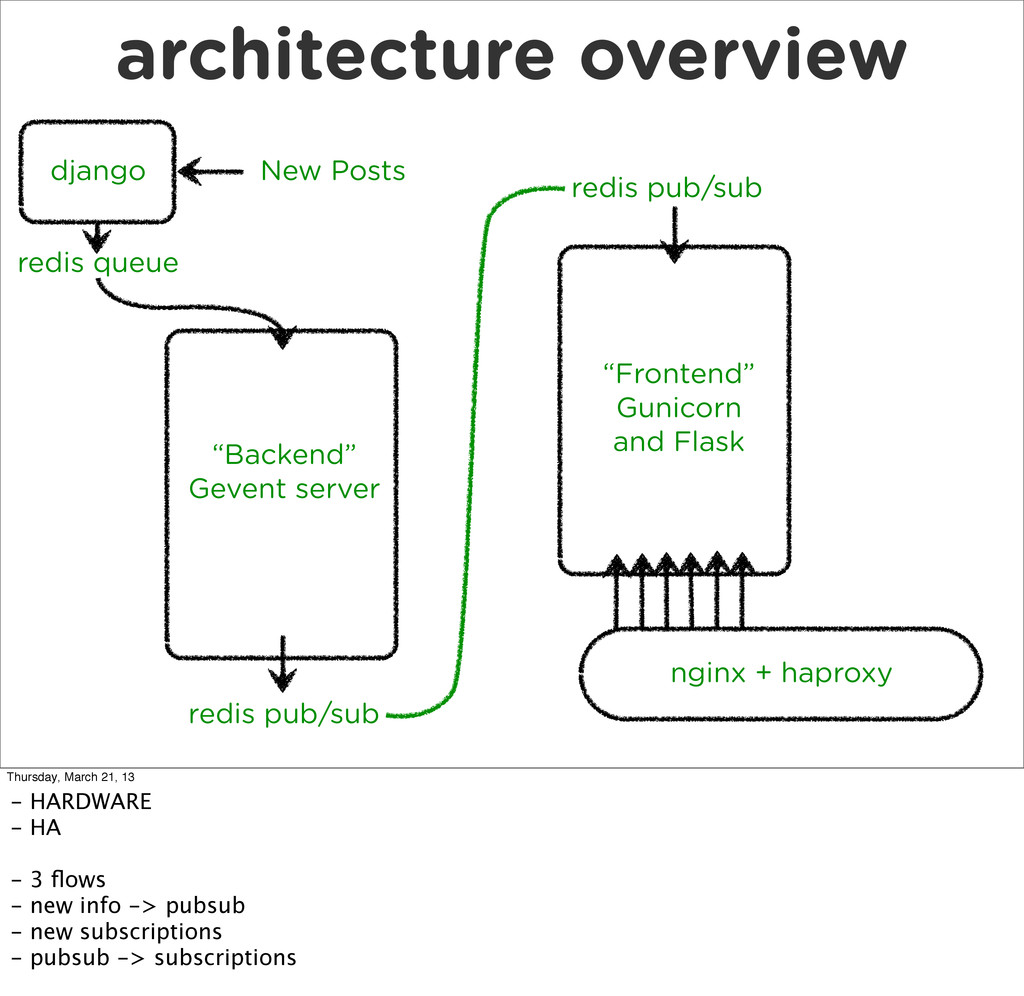
  9. architecture overview redis pub/sub redis queue “Frontend” Gunicorn and Flask

    “Backend” Gevent server New Posts django redis pub/sub nginx + haproxy Thursday, March 21, 13 - HARDWARE - HA - 3 flows - new info -> pubsub - new subscriptions - pubsub -> subscriptions
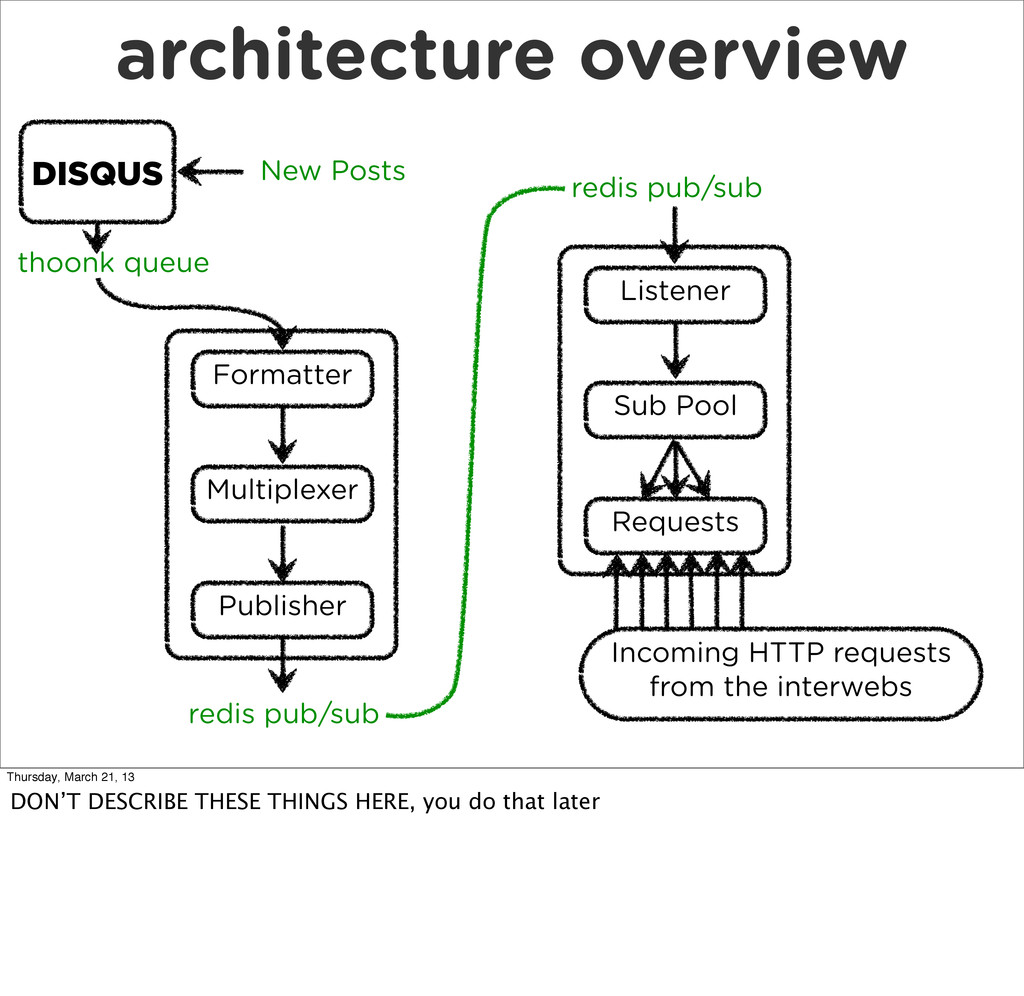
  10. architecture overview DISQUS Formatter Multiplexer Publisher Listener Sub Pool Requests

    Incoming HTTP requests from the interwebs redis pub/sub thoonk queue New Posts redis pub/sub Thursday, March 21, 13 DON’T DESCRIBE THESE THINGS HERE, you do that later
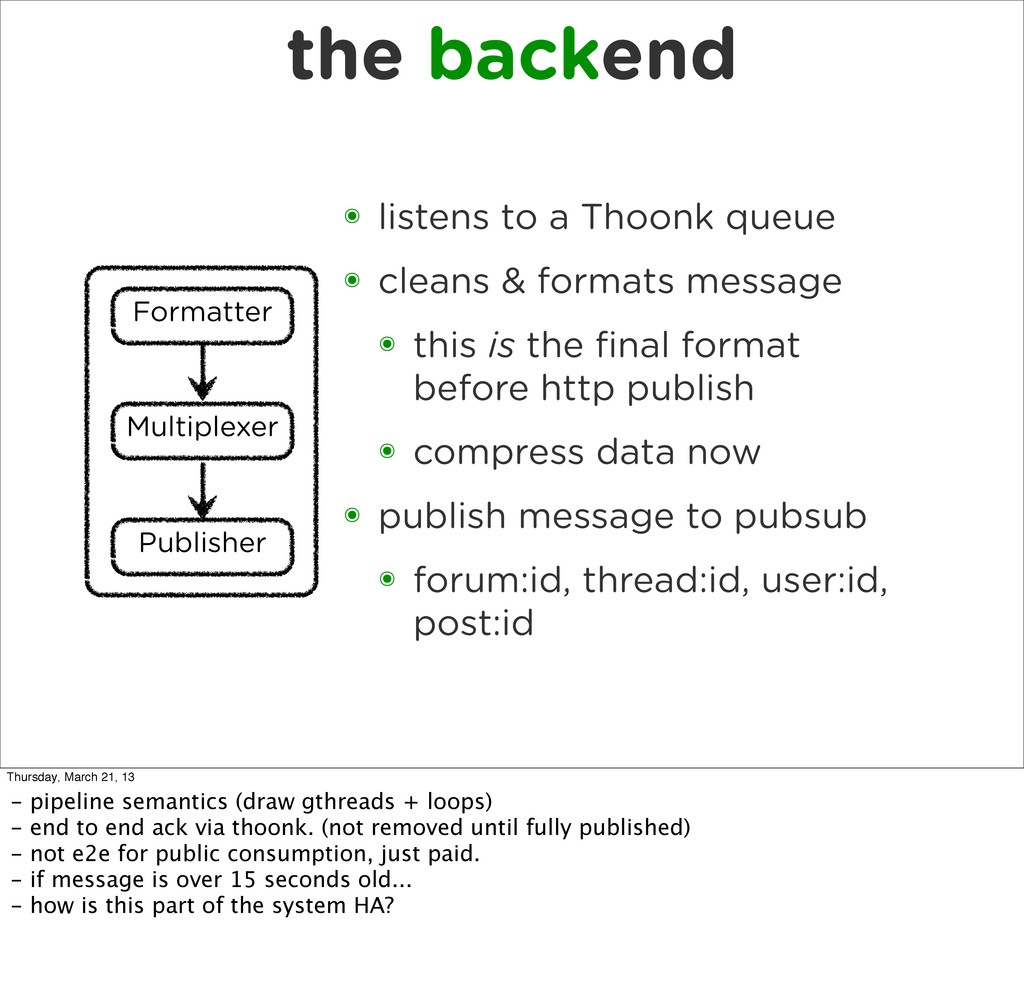
  11. the backend ๏ listens to a Thoonk queue ๏ cleans

    & formats message ๏ this is the final format before http publish ๏ compress data now ๏ publish message to pubsub ๏ forum:id, thread:id, user:id, post:id Formatter Multiplexer Publisher Thursday, March 21, 13 - pipeline semantics (draw gthreads + loops) - end to end ack via thoonk. (not removed until fully published) - not e2e for public consumption, just paid. - if message is over 15 seconds old... - how is this part of the system HA?
  12. the backend ๏ average processing time is ~0.2 seconds ๏

    queue maintenance ๏ ACK timeouts (5 secondsish) Thursday, March 21, 13 HA before maintenance zookeeper
  13. random redis lessons ๏ separate pub/sub and non pub/sub redis

    usage by physical node ๏ transactions can be prickly Thursday, March 21, 13 transactions can trip you up, atomic is good, but they are way more expensive
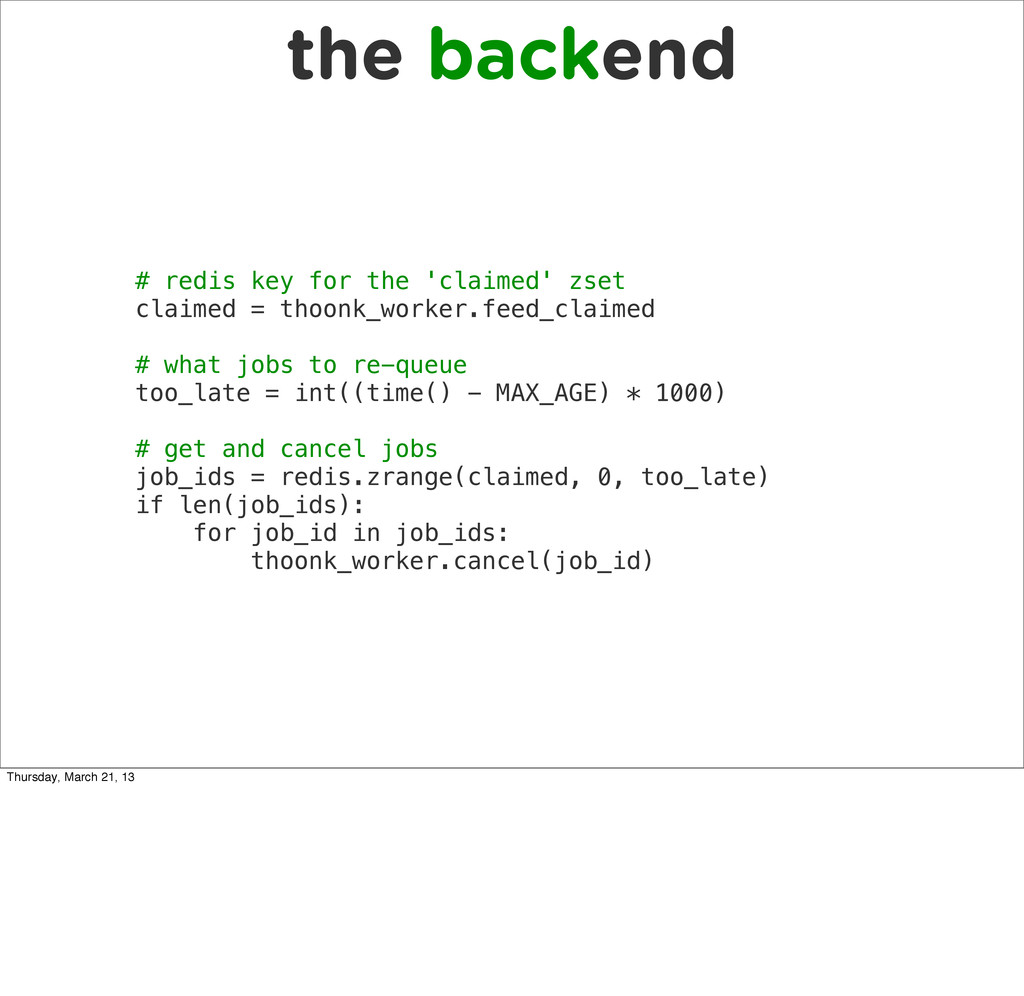
  14. the backend # redis key for the 'claimed' zset claimed

    = thoonk_worker.feed_claimed # what jobs to re-queue too_late = int((time() - MAX_AGE) * 1000) # get and cancel jobs job_ids = redis.zrange(claimed, 0, too_late) if len(job_ids): for job_id in job_ids: thoonk_worker.cancel(job_id) Thursday, March 21, 13
  15. gevent is nice # the code is too big to

    show here, so just import it # http://bitly.com/geventspawn from realertime.lib.spawn import Watchdog from realertime.lib.spawn import TimeSensitiveBackoff Thursday, March 21, 13 - /lots/ of greenlets, need a way to manage them NAY! manage themselves - sleep(0)
  16. the frontend ๏ needs to be fast! ๏ pools redis

    connections ๏ routes messages from pubsub to http Thursday, March 21, 13 how is this part of the system HA?
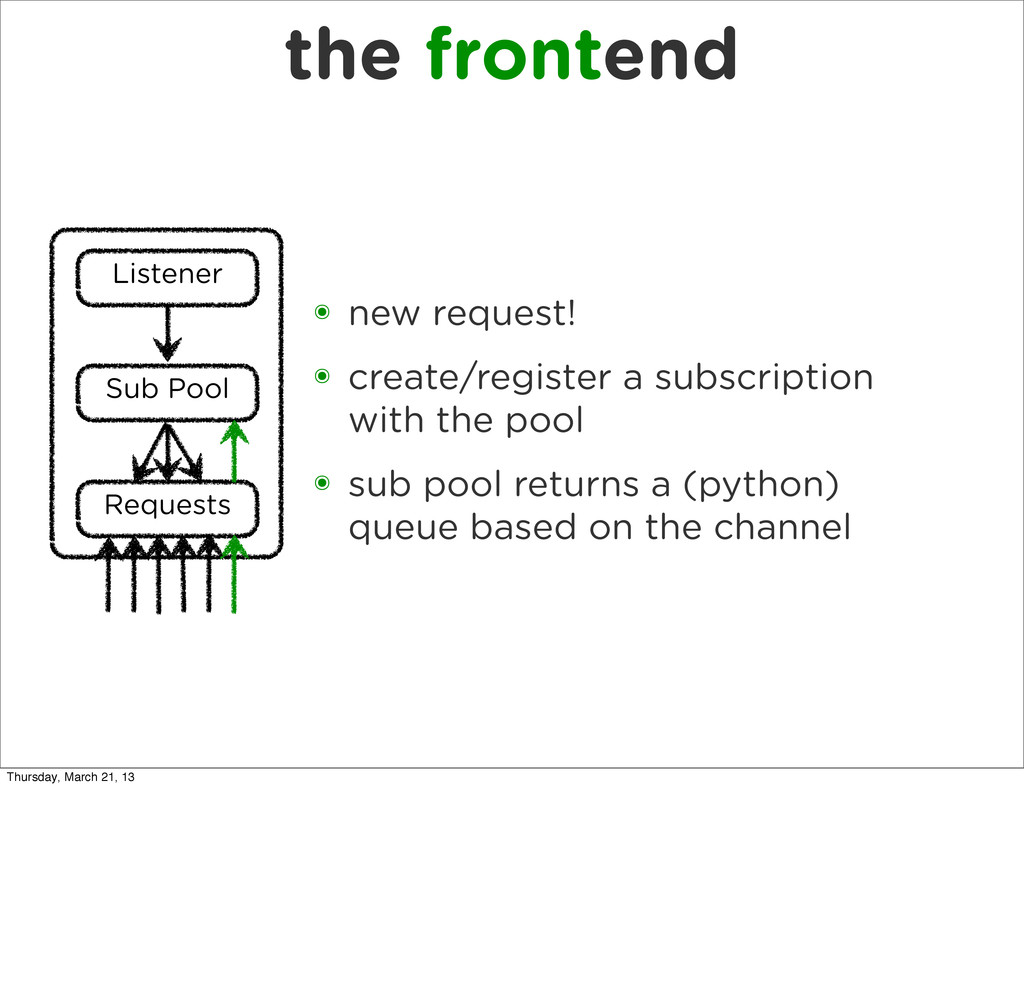
  17. the frontend ๏ new request! ๏ create/register a subscription with

    the pool ๏ sub pool returns a (python) queue based on the channel Listener Sub Pool Requests Thursday, March 21, 13
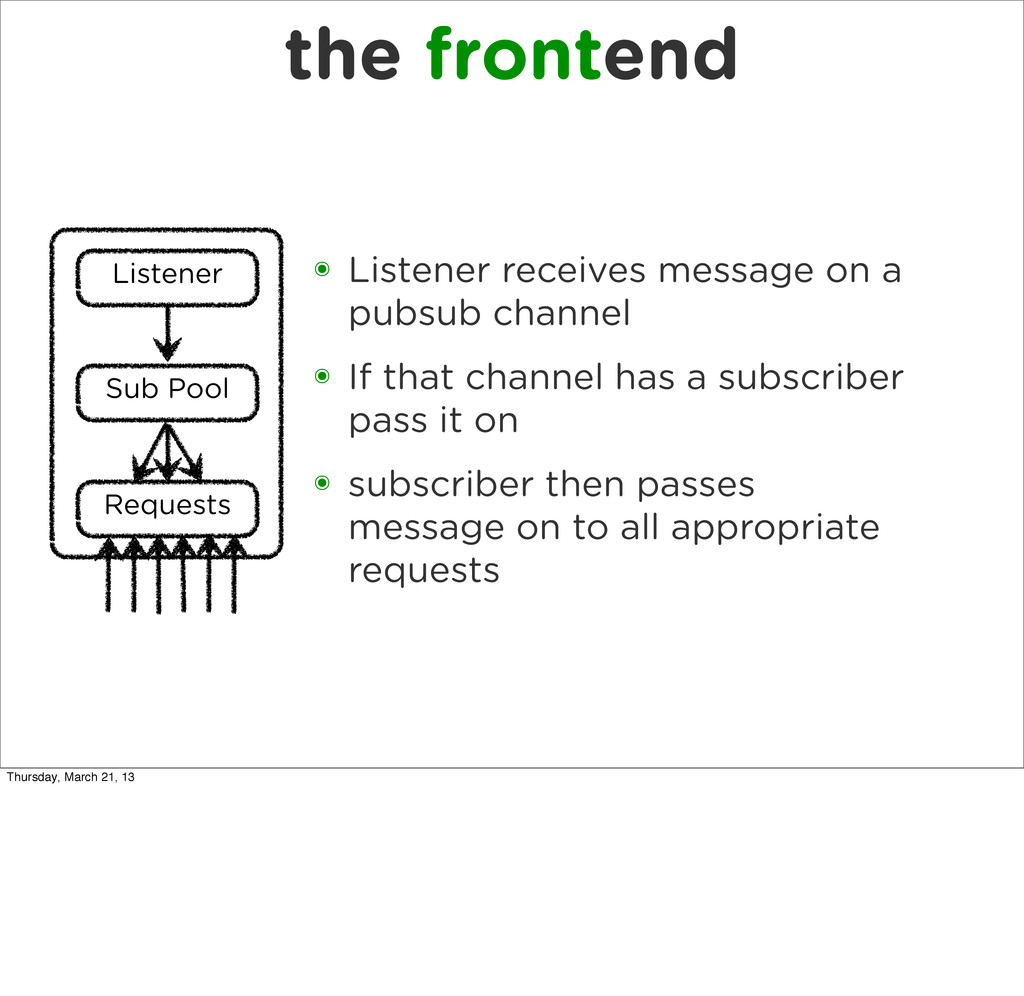
  18. the frontend ๏ Listener receives message on a pubsub channel

    ๏ If that channel has a subscriber pass it on ๏ subscriber then passes message on to all appropriate requests Listener Sub Pool Requests Thursday, March 21, 13
  19. long pollingish ๏ long held http connection ๏ stream JSON

    over this http connection Thursday, March 21, 13 long held, because why close it? you just put all that work into opening it! Why not websockets? - standard was still in flux when we started - http is maximum compatibility - we are going to add support in v2 - our problem does not require a symmetric communication pipe
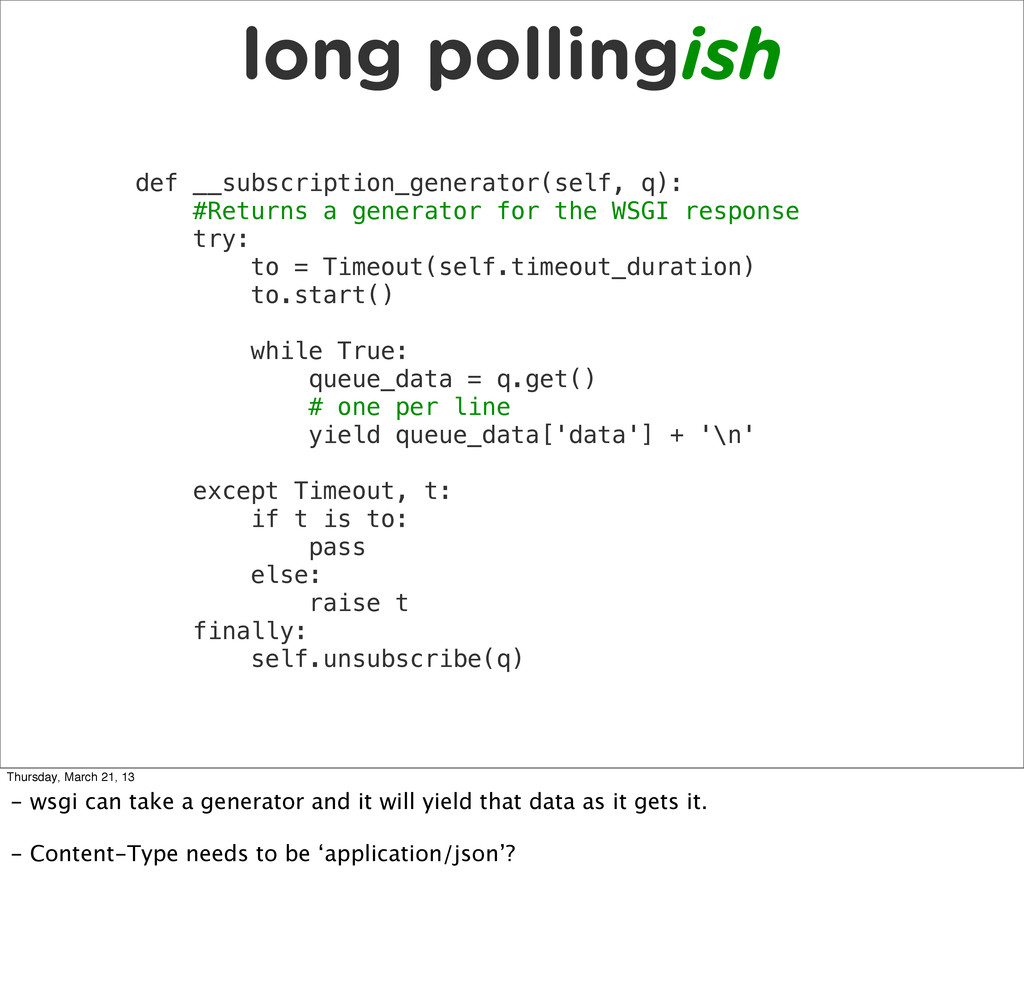
  20. long pollingish def __subscription_generator(self, q): #Returns a generator for the

    WSGI response try: to = Timeout(self.timeout_duration) to.start() while True: queue_data = q.get() # one per line yield queue_data['data'] + '\n' except Timeout, t: if t is to: pass else: raise t finally: self.unsubscribe(q) Thursday, March 21, 13 - wsgi can take a generator and it will yield that data as it gets it. - Content-Type needs to be ‘application/json’?
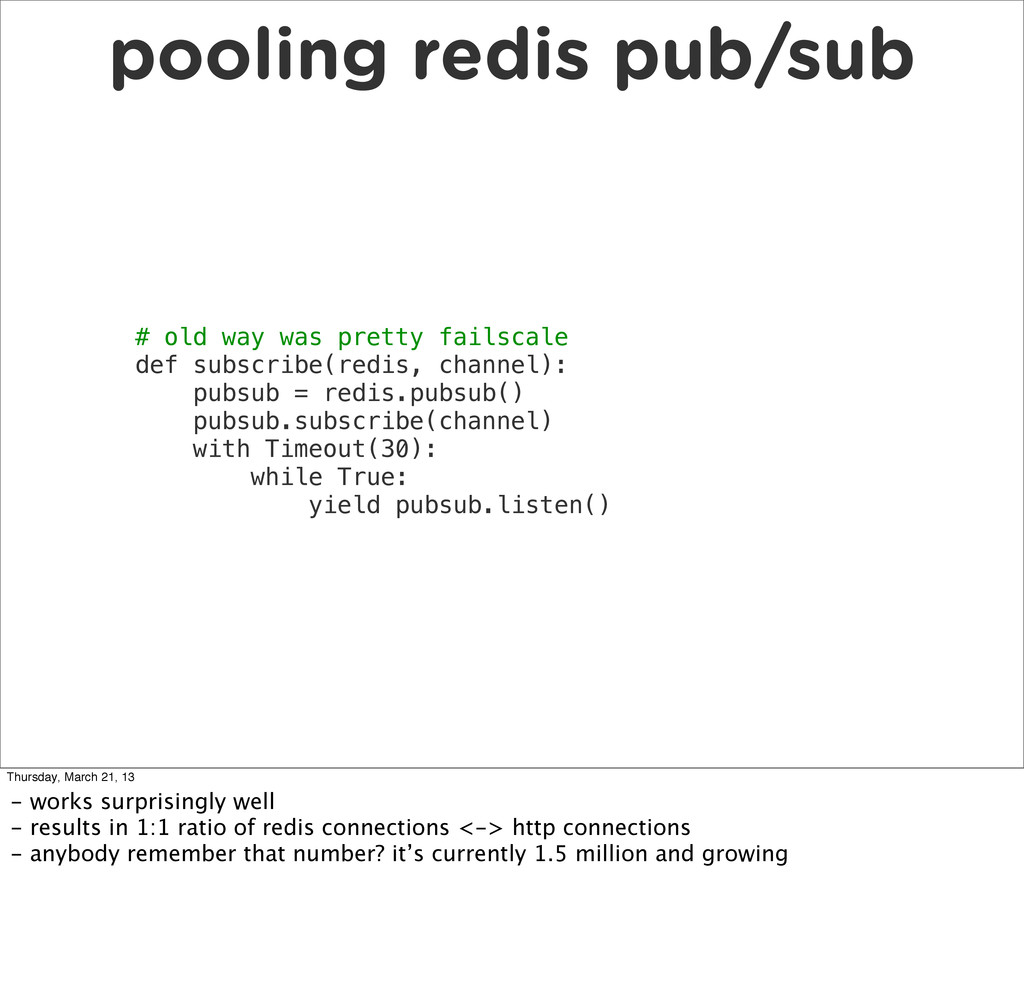
  21. pooling redis pub/sub # old way was pretty failscale def

    subscribe(redis, channel): pubsub = redis.pubsub() pubsub.subscribe(channel) with Timeout(30): while True: yield pubsub.listen() Thursday, March 21, 13 - works surprisingly well - results in 1:1 ratio of redis connections <-> http connections - anybody remember that number? it’s currently 1.5 million and growing
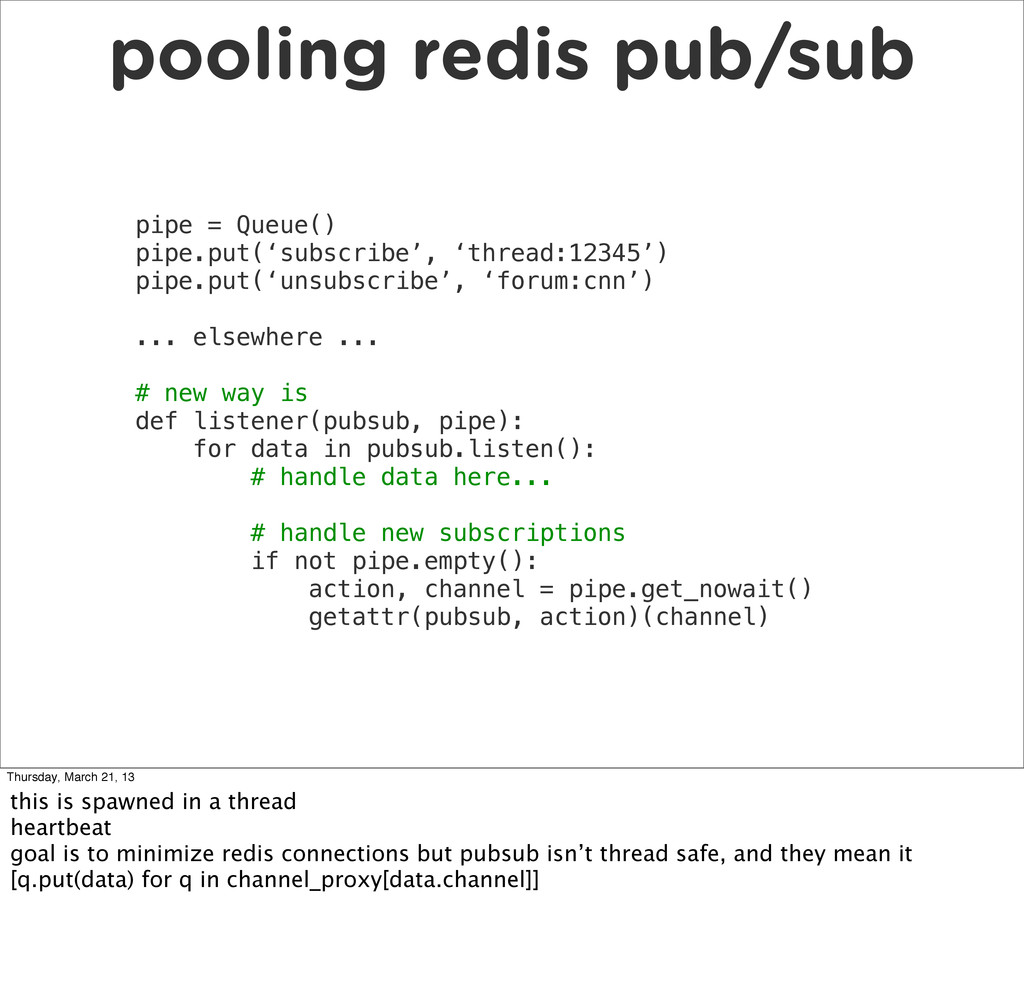
  22. pooling redis pub/sub pipe = Queue() pipe.put(‘subscribe’, ‘thread:12345’) pipe.put(‘unsubscribe’, ‘forum:cnn’)

    ... elsewhere ... # new way is def listener(pubsub, pipe): for data in pubsub.listen(): # handle data here... # handle new subscriptions if not pipe.empty(): action, channel = pipe.get_nowait() getattr(pubsub, action)(channel) Thursday, March 21, 13 this is spawned in a thread heartbeat goal is to minimize redis connections but pubsub isn’t thread safe, and they mean it [q.put(data) for q in channel_proxy[data.channel]]
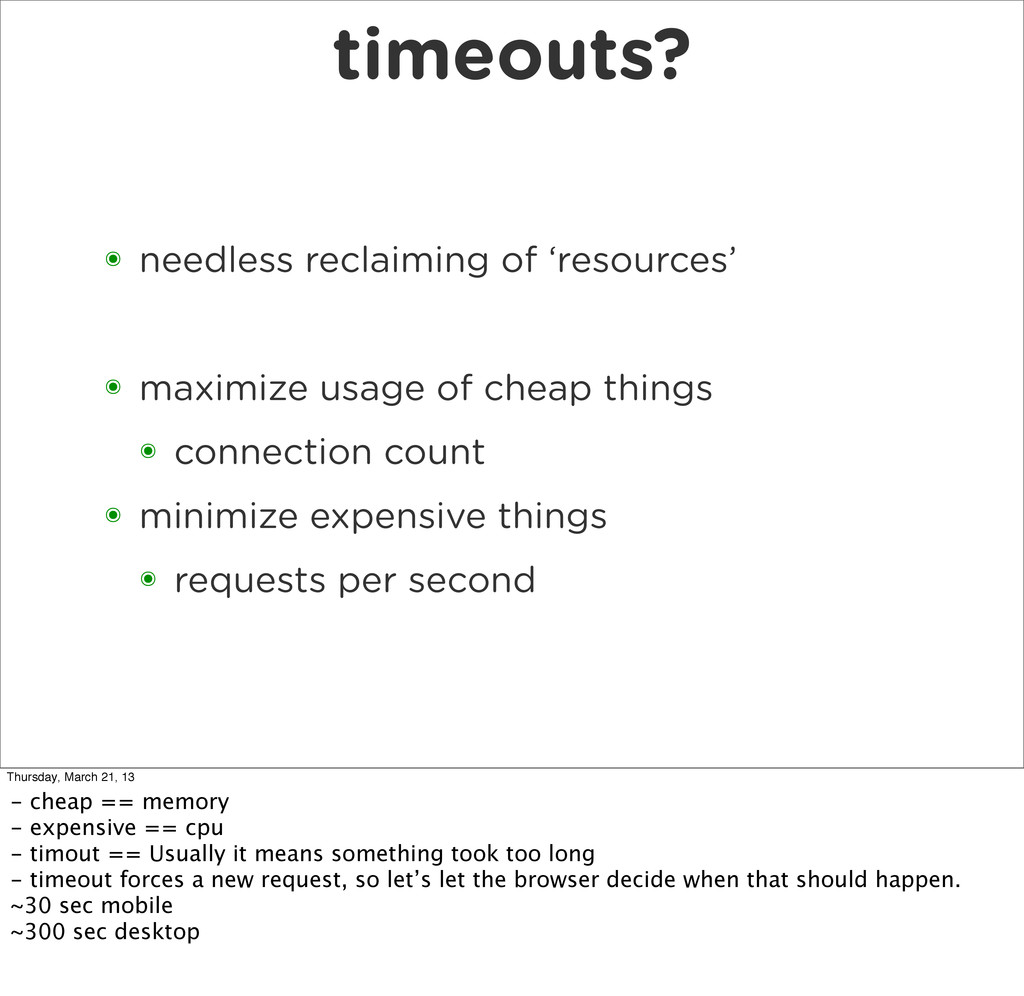
  23. timeouts? ๏ needless reclaiming of ‘resources’ ๏ maximize usage of

    cheap things ๏ connection count ๏ minimize expensive things ๏ requests per second Thursday, March 21, 13 - cheap == memory - expensive == cpu - timout == Usually it means something took too long - timeout forces a new request, so let’s let the browser decide when that should happen. ~30 sec mobile ~300 sec desktop
  24. testing ๏ Darktime ๏ use existing network to loadtest ๏

    (user complaints when it didn’t work...) ๏ Darkesttime ๏ load testing a single thread ๏ have knobs you can twiddle Thursday, March 21, 13
  25. stats ๏ measure all the things! ๏ especially when the

    numbers don’t line up ๏ is hard in distributed systems ๏ try to express things as +1 and -1 if you can ๏ i used scales from greplin “metrics for py” Thursday, March 21, 13 scales! gauges and aggregation
  26. lessons ๏ do hard work early ๏ defer work that

    you might never need ๏ end-to-end acks are good, but expensive ๏ timeouts are not free ๏ greenlets are e ectively free ๏ pubsub is e ectively free Thursday, March 21, 13 - data processing and json formatting done once not 1000x times - gziping done once not 1000x times - defer setting up the work in the generator until as late as possible - ditched e2e acks from the fe, cost way too much
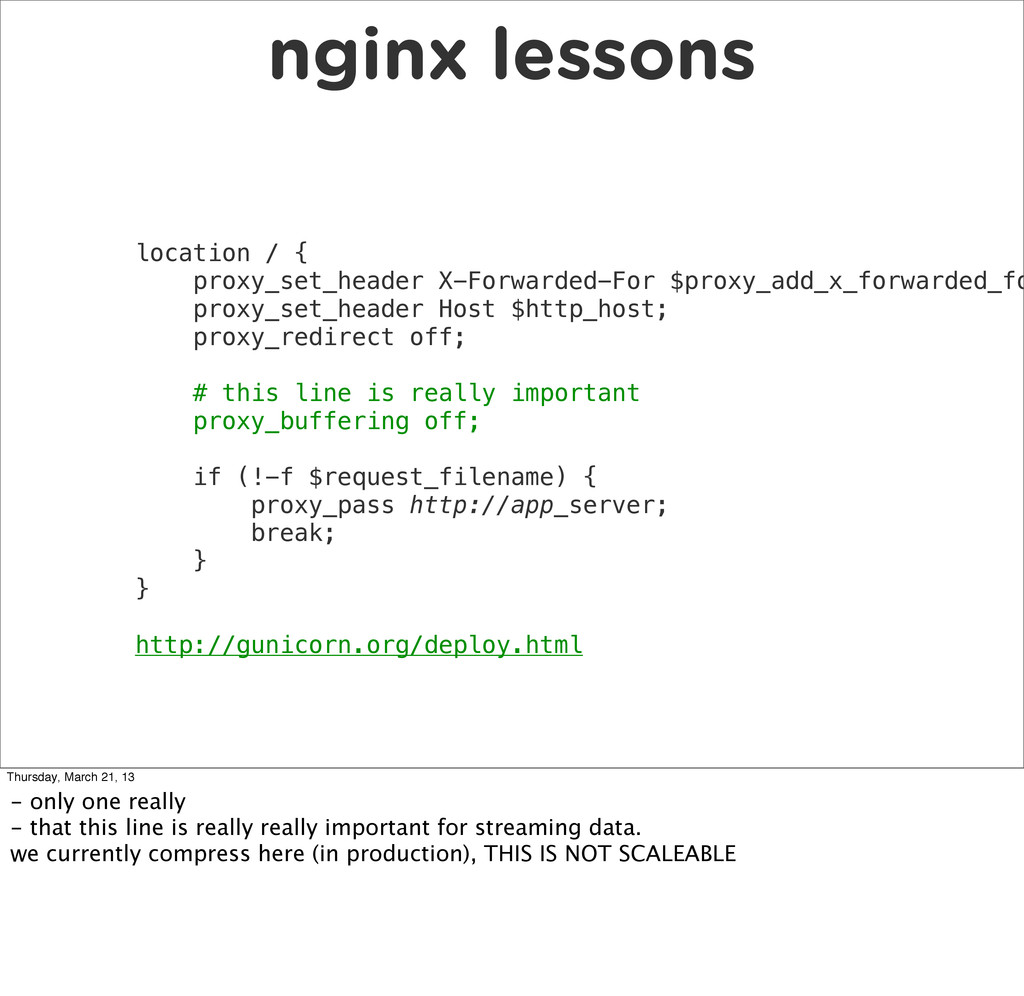
  27. nginx lessons location / { proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_fo proxy_set_header Host

    $http_host; proxy_redirect off; # this line is really important proxy_buffering off; if (!-f $request_filename) { proxy_pass http://app_server; break; } } http://gunicorn.org/deploy.html Thursday, March 21, 13 - only one really - that this line is really really important for streaming data. we currently compress here (in production), THIS IS NOT SCALEABLE
  28. slide full o’ links ๏ Gevent (python coroutines and greenlets)

    http://gevent.org/ ๏ Gunicorn (python pre-fork WSGI server) http://gunicorn.org/ ๏ Thoonk (redis queue) https://github.com/andyet/thoonk.py ๏ Sentry (log aggregation) https://github.com/dcramer/sentry ๏ Scales (in-app metrics) https://github.com/Greplin/scales code.disqus.com Thursday, March 21, 13 Tell me your thoughts! @NorthIsUp
  29. special thanks ๏ the team at DISQUS ๏ especially our

    dev-ops guys ๏ and je who had to review all my code Thursday, March 21, 13 Tell me your thoughts! @NorthIsUp
  30. open questions ๏ best system config for thousands of rps?

    ๏ how to make the front end faster? ๏ something faster than pywsgi? ๏ FapWS? ๏ libevent -> libev? (i.e. gevent 1.0) ๏ dump wsgi for raw sockets? (last resort) ๏ best internal python pub/sub option? Thursday, March 21, 13 Tell me your thoughts! @NorthIsUp

More Decks by Adam

Other Decks in Technology