Upgrade to Pro — share decks privately, control downloads, hide ads and more …

GLAMhack 2026 - Apertus and Public AI Switzerland

GLAMhack 2026 - Apertus and Public AI Switzerland

The 11th edition of our yearly Swiss Open Cultural Data Hackathon (or GLAMhack for short) was hosted by the Stiftung für Kunst, Kultur und Geschichte (SKKG) in Winterthur. This year’s theme is “Hack the Gap – Bridging Analog and Digital Worlds“

For full details, visit https://opendata.ch/events/glamhack2026/

Hackathon results: https://glamhack.vercel.app/

#makeopendata

November 15, 2026

Transcript

25 slides
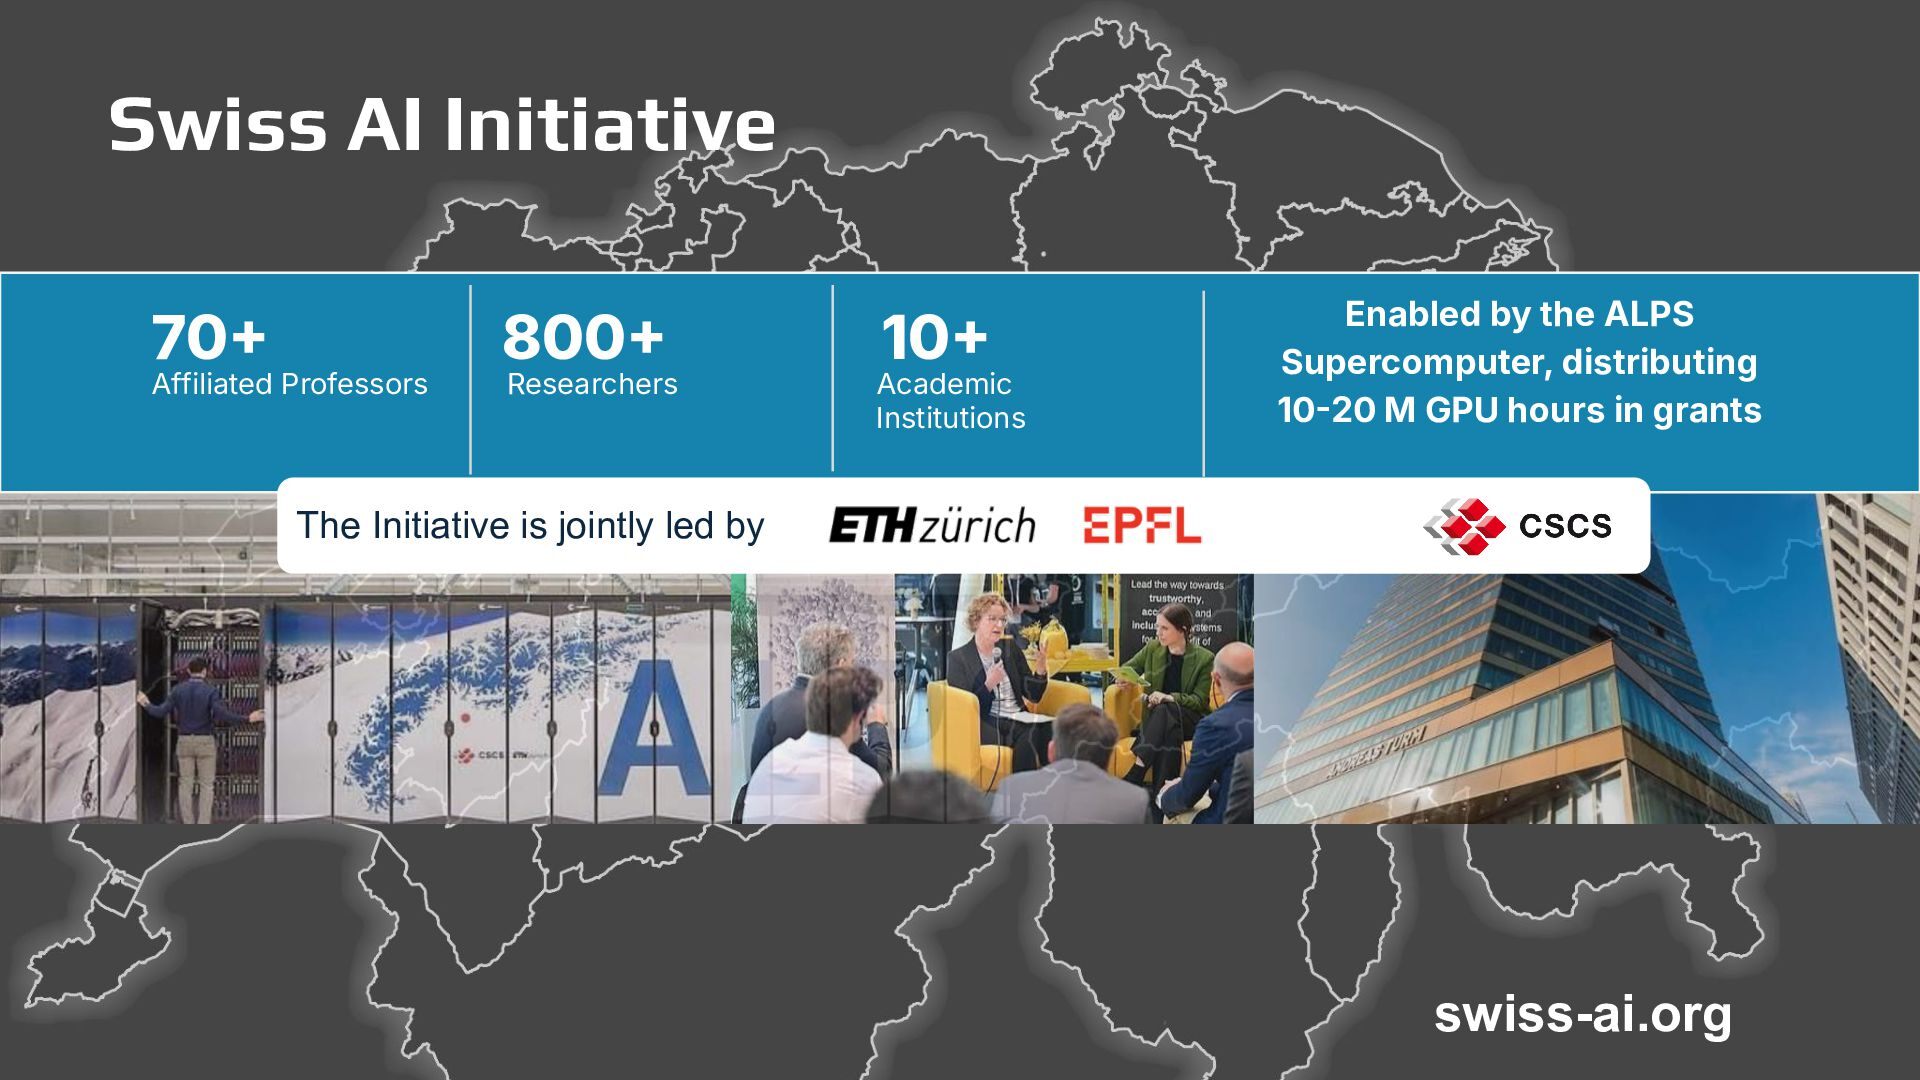
  1. Swiss AI Initiative 70 Affiliated Professors 800 Researchers 10 Academic

    Institutions Enabled by the ALPS Supercomputer, distributing 1020 M GPU hours in grants The Initiative is jointly led by swiss-ai.org
  2. Swiss National Supercomputing Centre CSCS develops and operates high-performance computing

    and data research infrastructure that supports world-class science in Switzerland. 6
  3. Why Build Our Own Models? ➢ Scientific integrity Open reproducibility

    is foundational to science ➢ Deployment integrity On-premise, no lock-in, data under your control 8
  4. Full deployment control Available from cloud providers: Swisscom, Infomaniak, Stepping

    Stone, Phoeniqs, AWS, Azure, Featherless.ai & others Supported for local inference in leading open platforms: vLLM, SGlang, Transformers, llama.cpp*, MLX*, GGUF* (*community) Weights and checkpoints on Hugging Face: For individual deployment and fine-tuning under an Apache 2.0 license 9
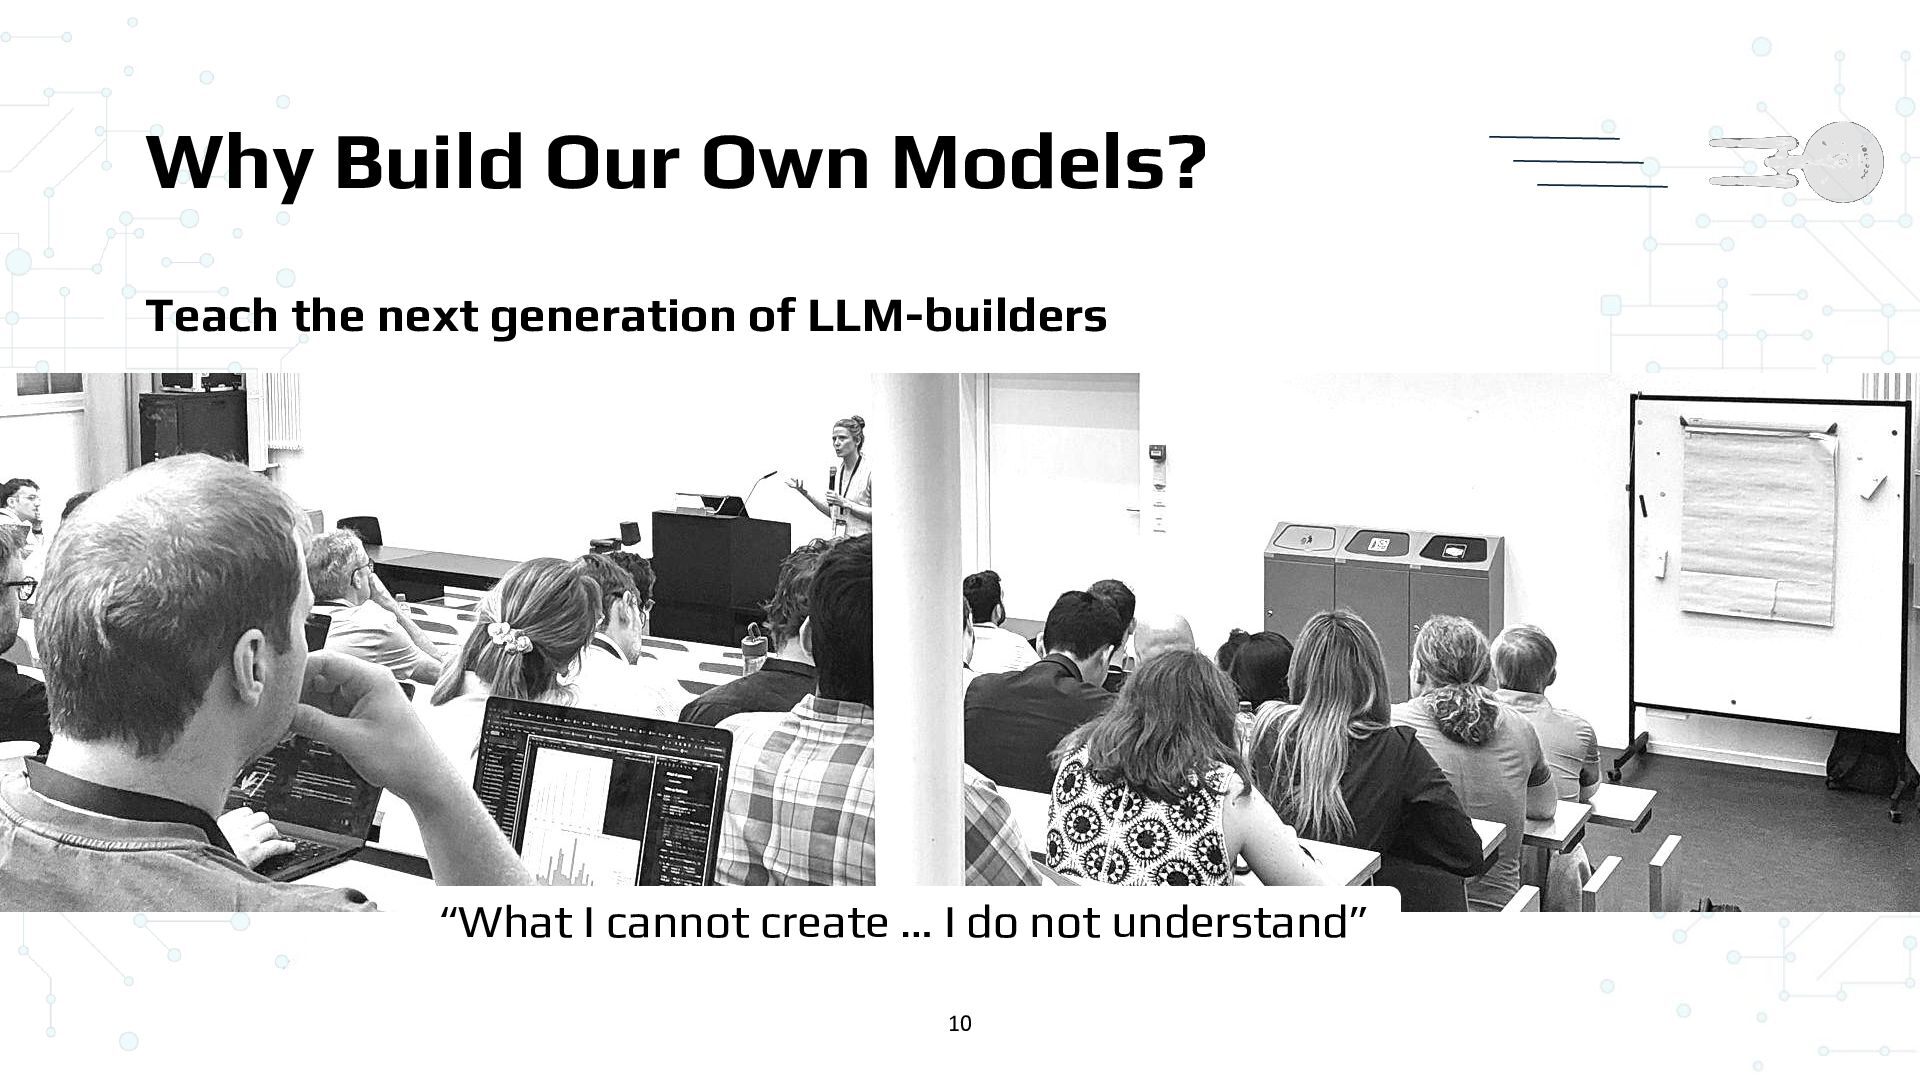
  5. Why Build Our Own Models? Teach the next generation of

    LLM-builders “What I cannot create … I do not understand” 10
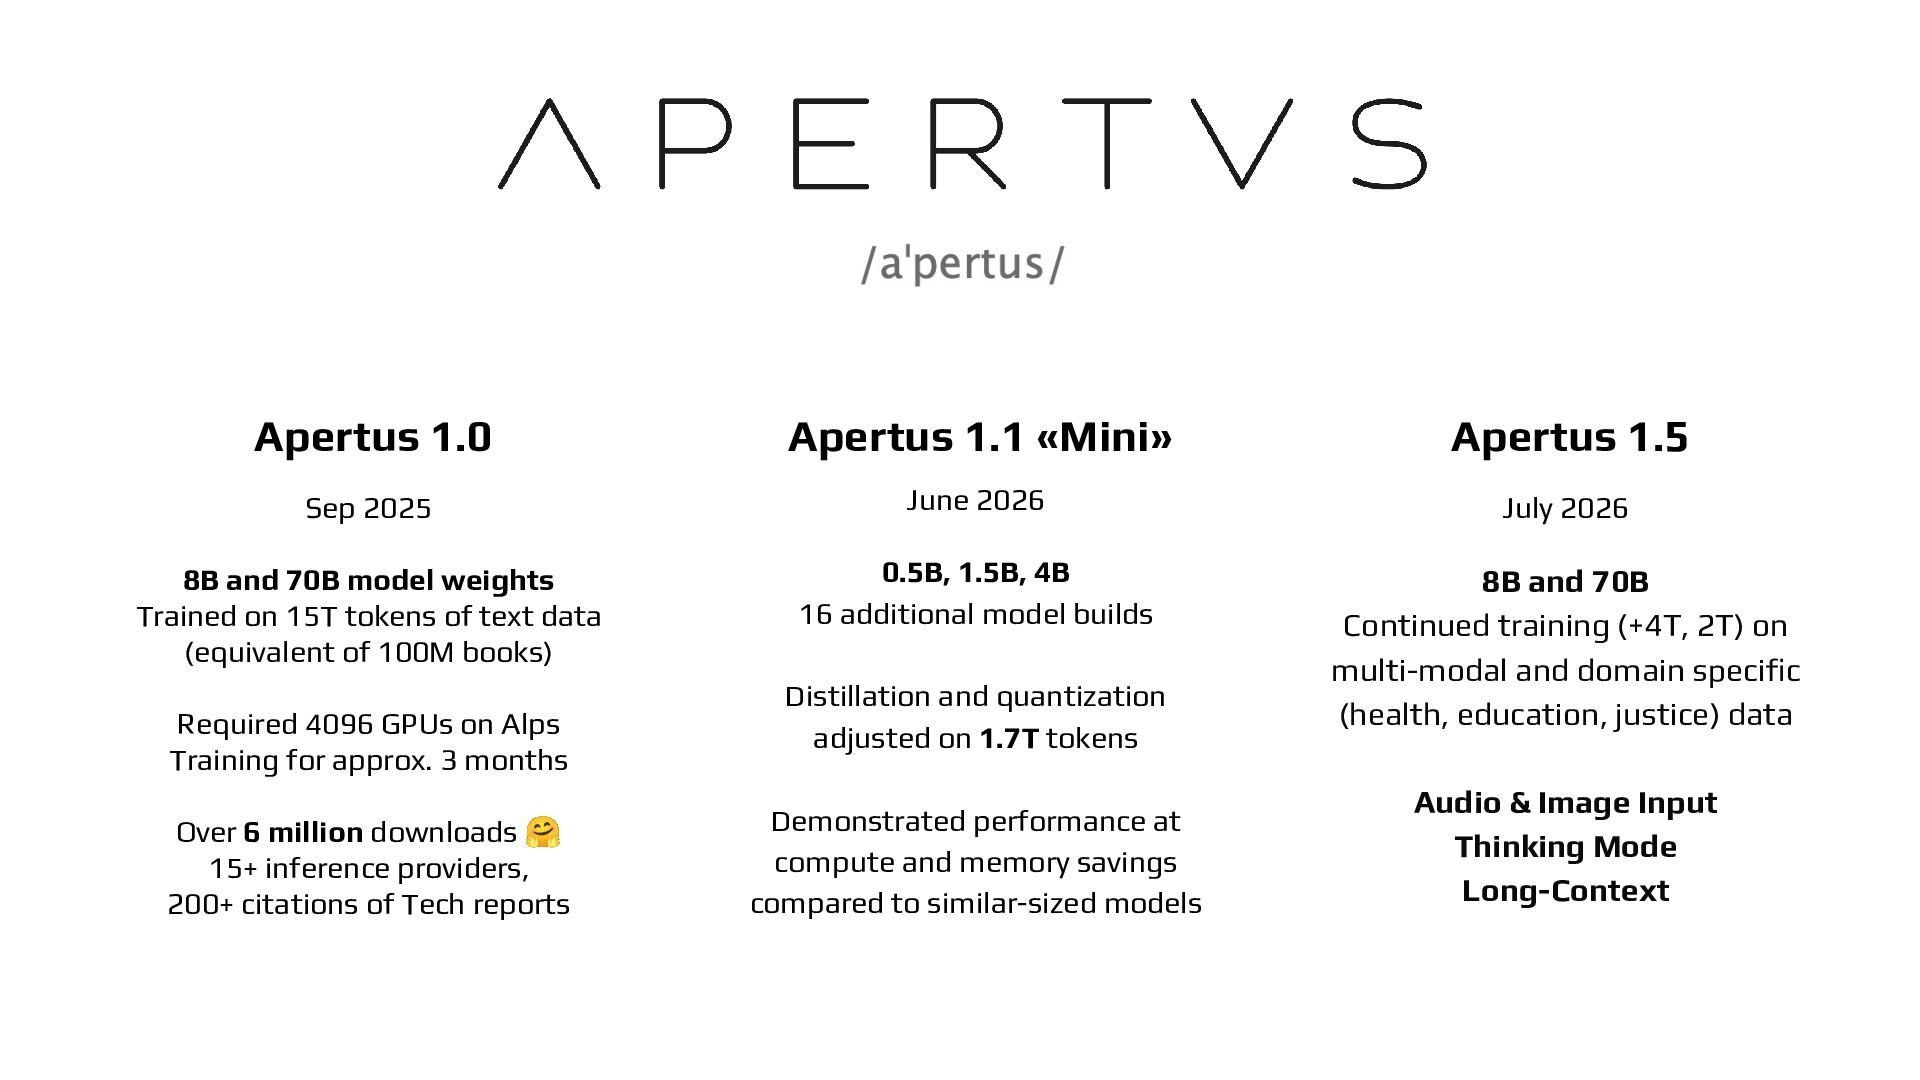
  6. Apertus 1.0 Apertus 1.1 «Mini» Apertus 1.5 Sep 2025 June

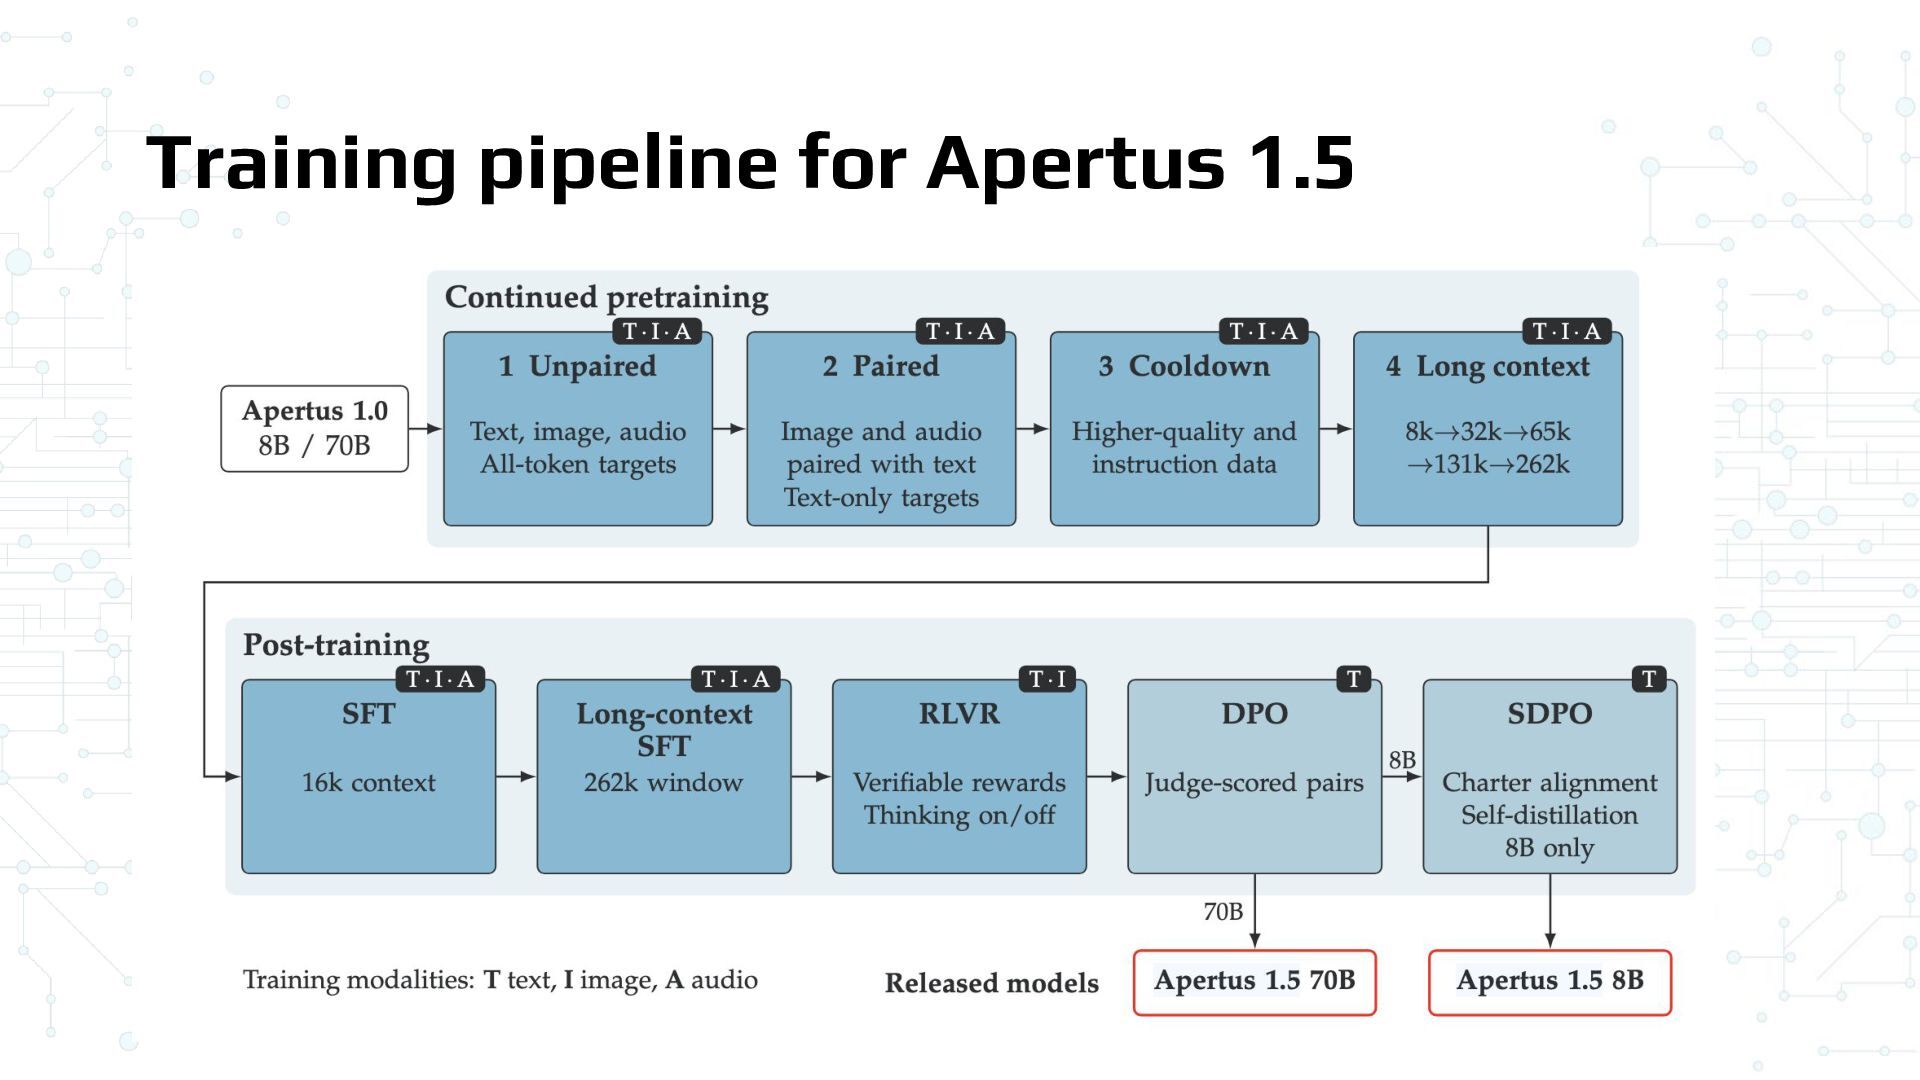
    2026 July 2026 8B and 70B model weights Trained on 15T tokens of text data (equivalent of 100M books) 0.5B, 1.5B, 4B 16 additional model builds 8B and 70B Continued training (+4T, 2T) on multi-modal and domain specific (health, education, justice) data Required 4096 GPUs on Alps Training for approx. 3 months Over 6 million downloads 🤗 15+ inference providers, 200+ citations of Tech reports Distillation and quantization adjusted on 1.7T tokens Demonstrated performance at compute and memory savings compared to similar-sized models Audio & Image Input Thinking Mode Long-Context
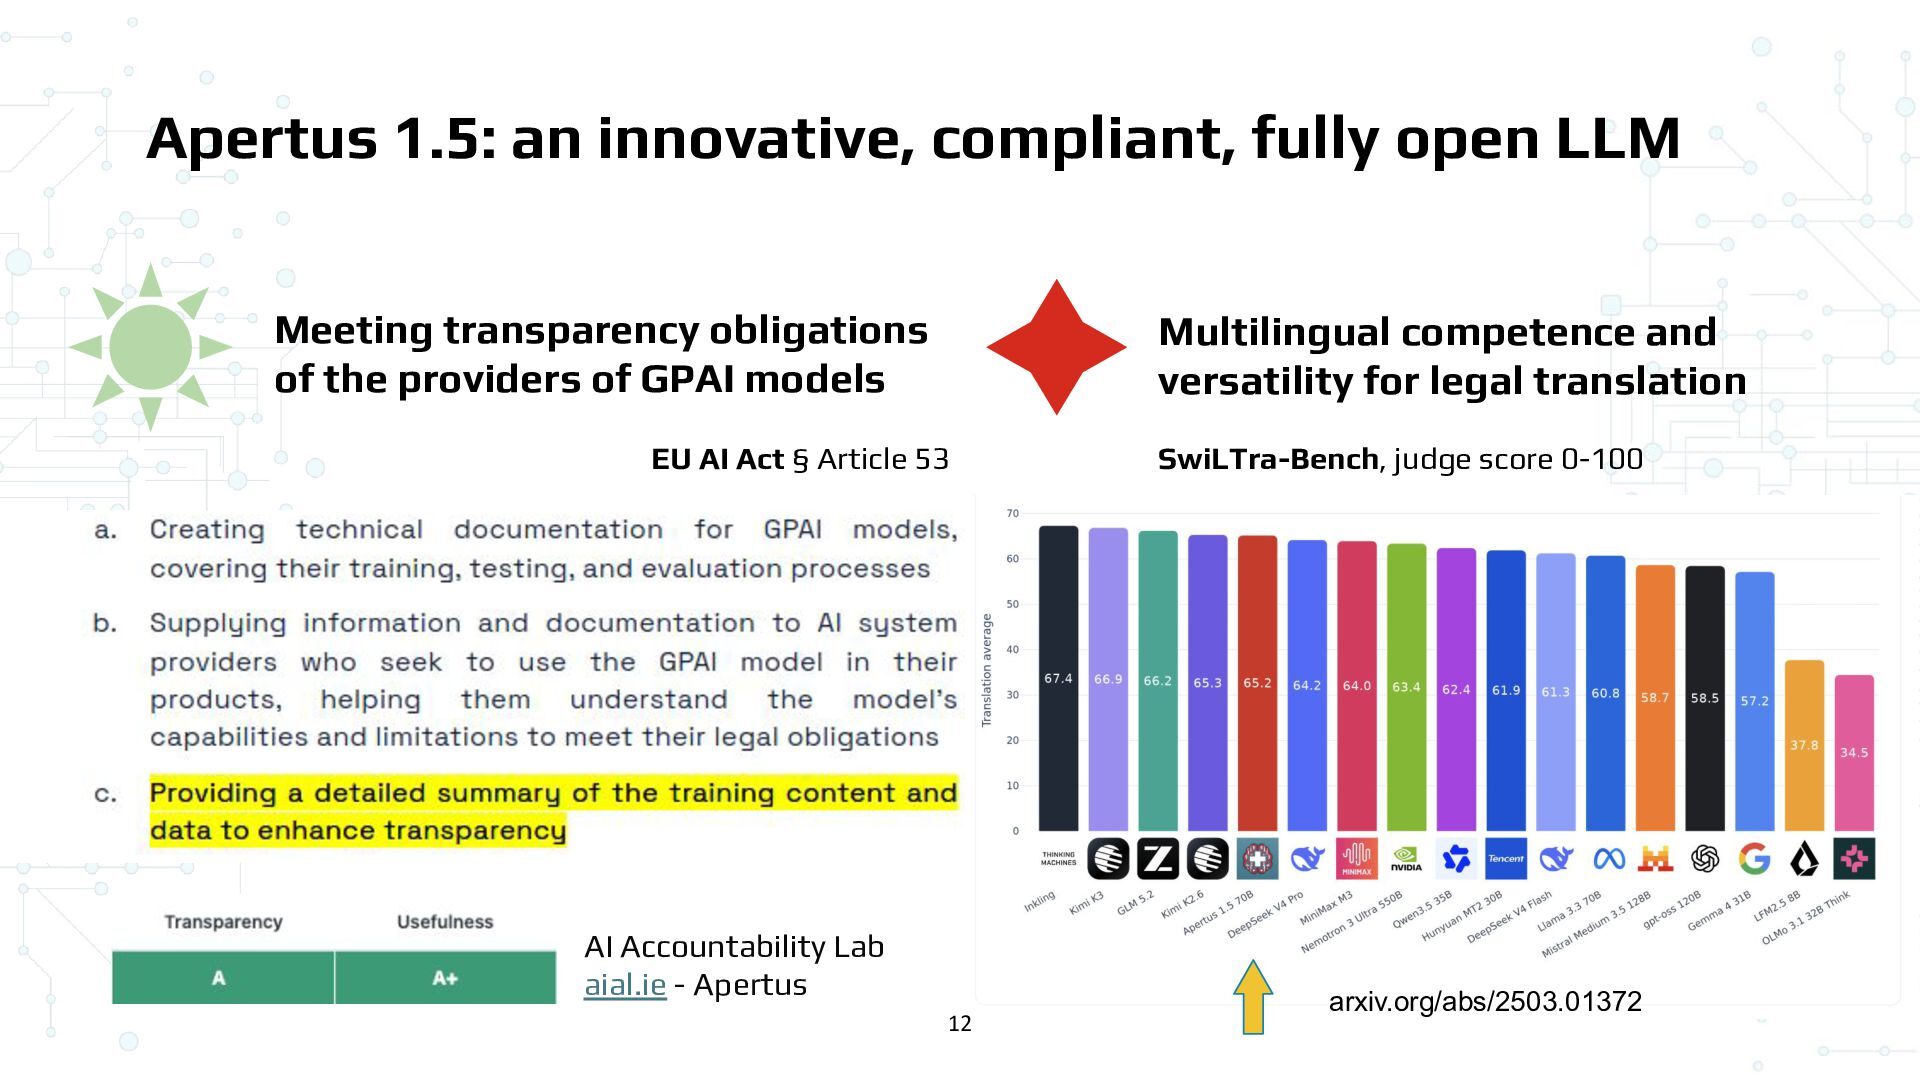
  7. Apertus 1.5: an innovative, compliant, fully open LLM Meeting transparency

    obligations of the providers of GPAI models Multilingual competence and versatility for legal translation EU AI Act § Article 53 AI Accountability Lab aial.ie - Apertus 12 SwiLTra-Bench, judge score 0-100 arxiv.org/abs/2503.01372
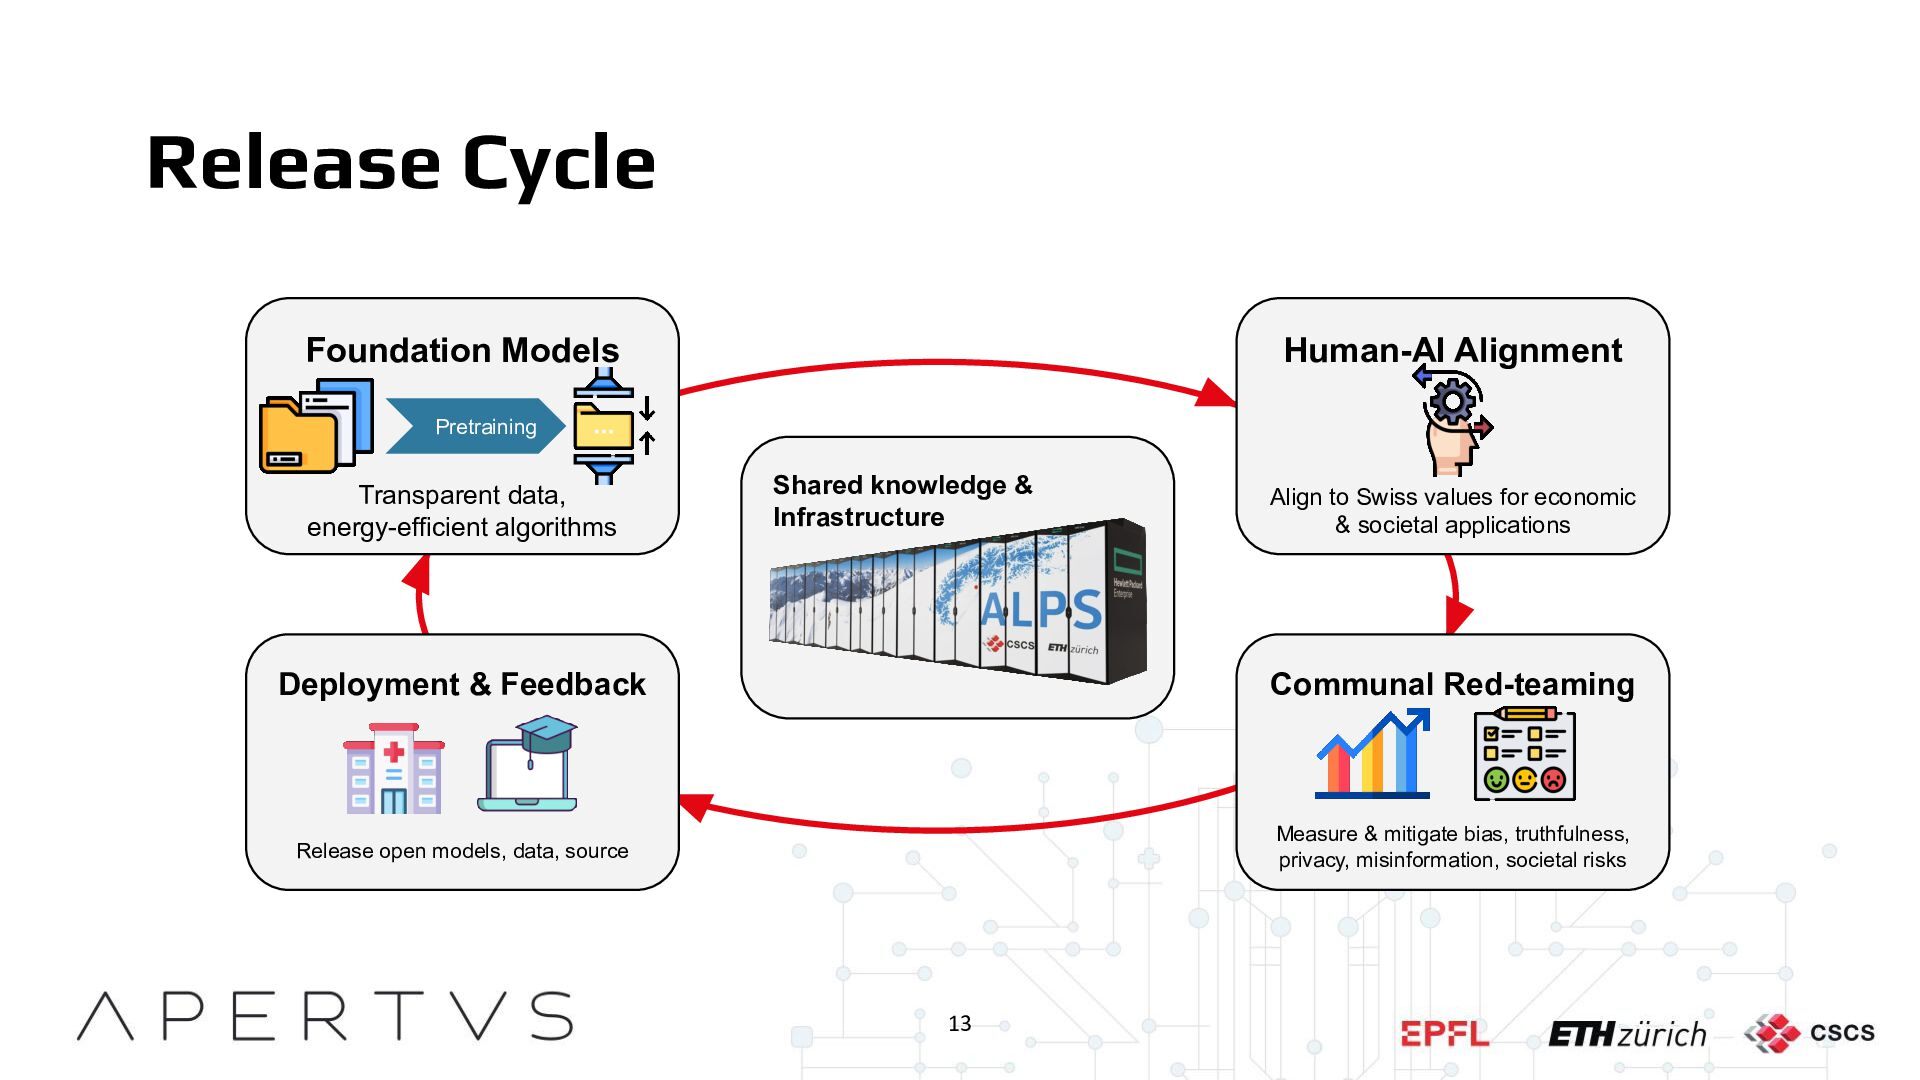
  8. Release Cycle Human-AI Alignment Foundation Models Pretraining Transparent data, energy-efficient

    algorithms Shared knowledge & Infrastructure Align to Swiss values for economic & societal applications Deployment & Feedback Communal Red-teaming Release open models, data, source Measure & mitigate bias, truthfulness, privacy, misinformation, societal risks 13
  9. Apertus 1.5 Continued Pretraining: 8B, 70B Additional high-quality data up-sampling

    for strategic areas, e.g. health, education, justice, for a total of 17T tokens at 70B Multimodality Native audio and image input for transcription and captions. Improved perceptual specificity, longer context window. Reinforcement Learning Improved instruction-following for better tool use, more advanced reasoning capabilities, thinking mode. 15
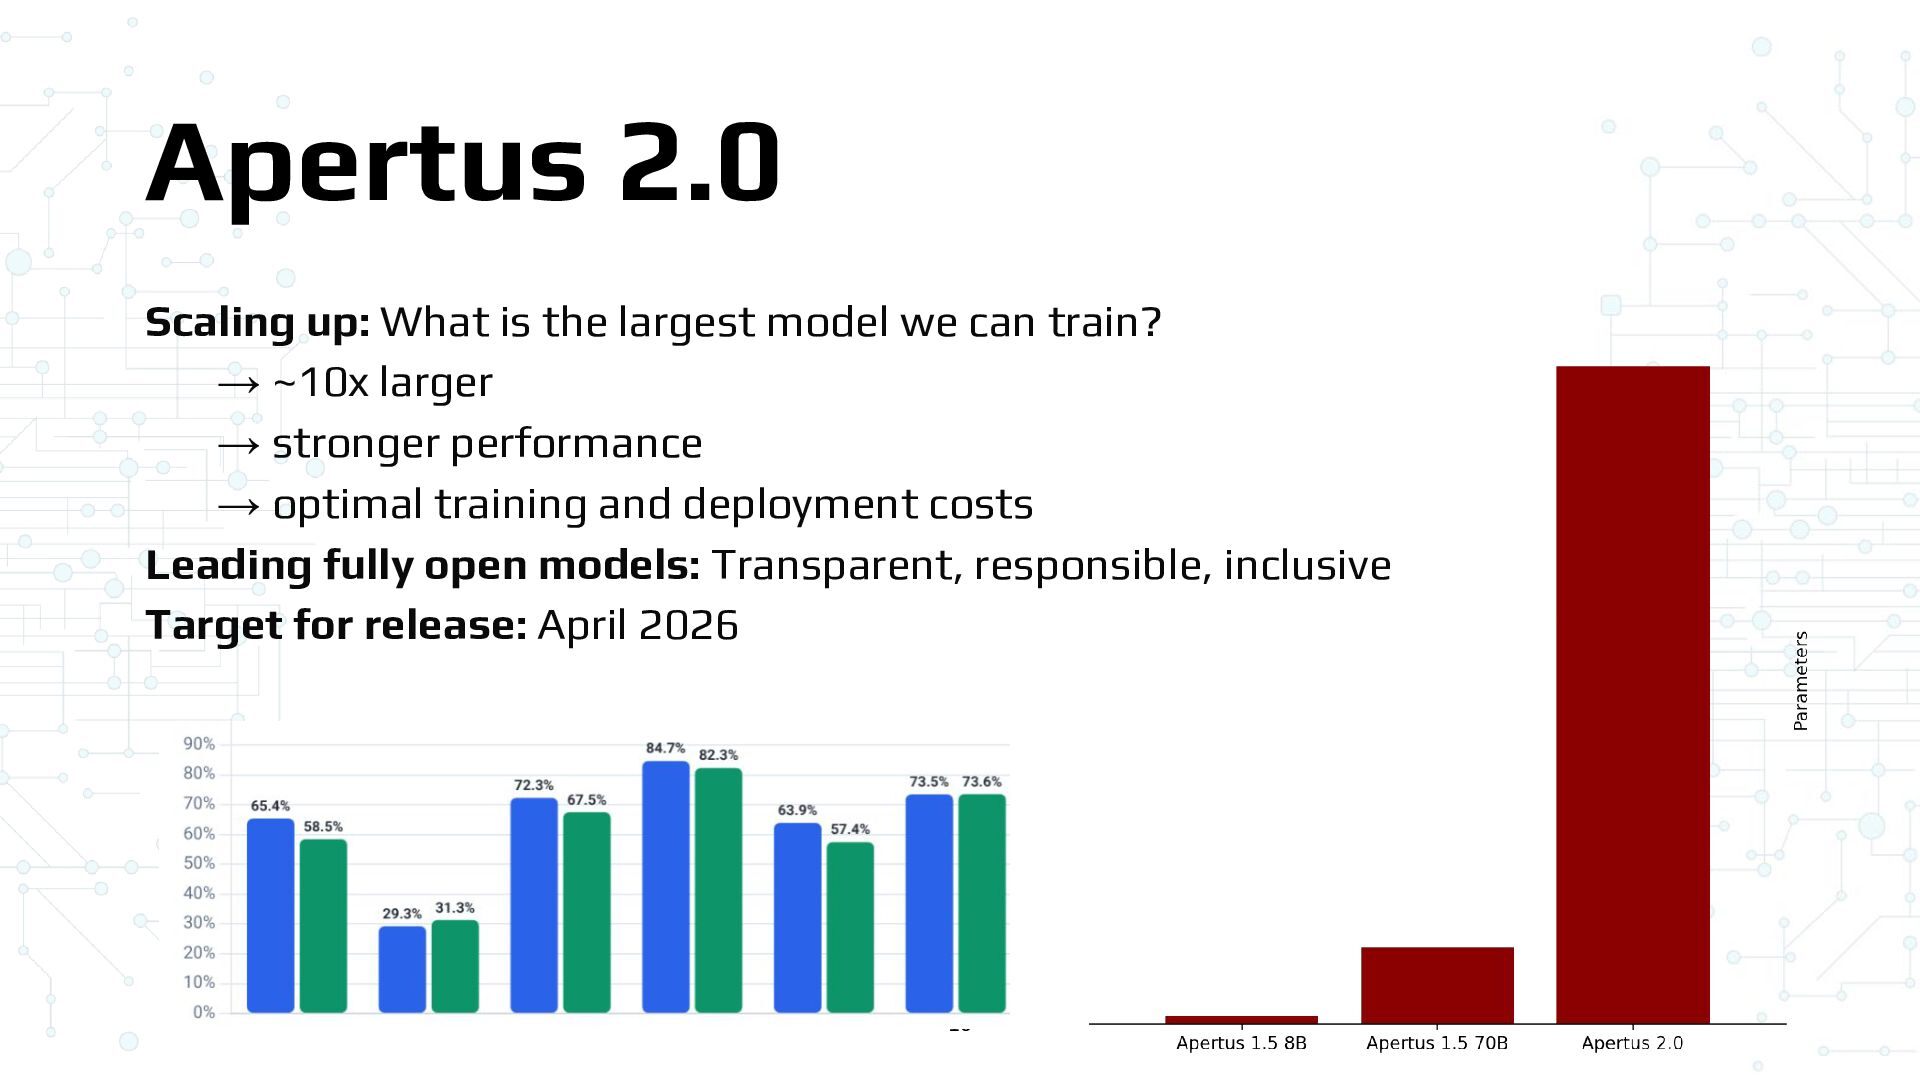
  10. Apertus 2.0 Scaling up: What is the largest model we

    can train? → ~10x larger → stronger performance → optimal training and deployment costs Leading fully open models: Transparent, responsible, inclusive Target for release: April 2026 16

More Decks by #makeopendata

Other Decks in Technology