Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
PyBR12
Search
Patty Vader
October 12, 2016
Programming
75
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
PyBR12
Patty Vader
October 12, 2016
More Decks by Patty Vader
See All by Patty Vader
Python para Machine Learning
pattyvader
0
44
Search Engines using Python and Elasticsearch
pattyvader
0
200
Pygame
pattyvader
0
99
GitHubWTM
pattyvader
0
56
Other Decks in Programming
See All in Programming
HTML-in-Canvasで作る未来のWeb UI表現
clockmaker
5
5.1k
FactoryBotをやめればRSpecは速くなるのか?
yuta_onishi_97
0
270
Rでドレミ/Do-Re-Mi_with_R
florets1
0
130
個人開発者よ、Honoを使え(おじさんver)
tanahiro2010
2
260
すこし踏み込む CancellationToken
htkym
2
1.7k
パスワード再設定メールのURLについて知っておこう
uyuki234
0
160
見えないものを探る要求要件定義に必要な基本的思考 / invisible-requirement-thinking
minodriven
15
8.5k
なぜCTOを降りてFDEを選んだのか?〜なぜプロダクト企業がFDEで顧客の現場に踏み込むのか〜
gonta
1
210
コーディング自動化の次へ。人の介入をゼロにするファクトリーとサポートAIによる実践
timakin
4
3.5k
ソニーのクラウド共通基盤の変遷と AI時代の開発スタイルに合わせた進化 / The Journey of Sony’s Common Cloud Platform and Its Evolution for AI-Native Development
kenjiyoneyama
0
270
気持ちぃ〜角丸 Squircle
ryu1013
0
310
Herb in Rails 8.2: Your ERB views, now HTML-aware @ Kaigi on Rails 2026, Tokyo, Japan
marcoroth
2
220
Featured
See All Featured
Lightning talk: Run Django tests with GitHub Actions
sabderemane
0
300
More Than Pixels: Becoming A User Experience Designer
marktimemedia
3
560
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
360
Utilizing Notion as your number one productivity tool
mfonobong
4
620
How to build an LLM SEO readiness audit: a practical framework
nmsamuel
2
950
Docker and Python
trallard
47
4.2k
Fantastic passwords and where to find them - at NoRuKo
philnash
53
4k
Product Roadmaps are Hard
iamctodd
55
13k
Code Review Best Practice
trishagee
74
20k
Why You Should Never Use an ORM
jnunemaker
PRO
61
10k
The Illustrated Guide to Node.js - THAT Conference 2024
reverentgeek
1
570
Rails Girls Zürich Keynote
gr2m
96
14k
Transcript
Search Engines utilizando Python e Elasticsearch
Apresentação https://spekerdeck.com/pattyvader/pybr12
Projeto Athena https://github.com/pattyvader/athena
Roadmap 1. Busca de documentos 2. Indexação 3. Percorrendo a
web
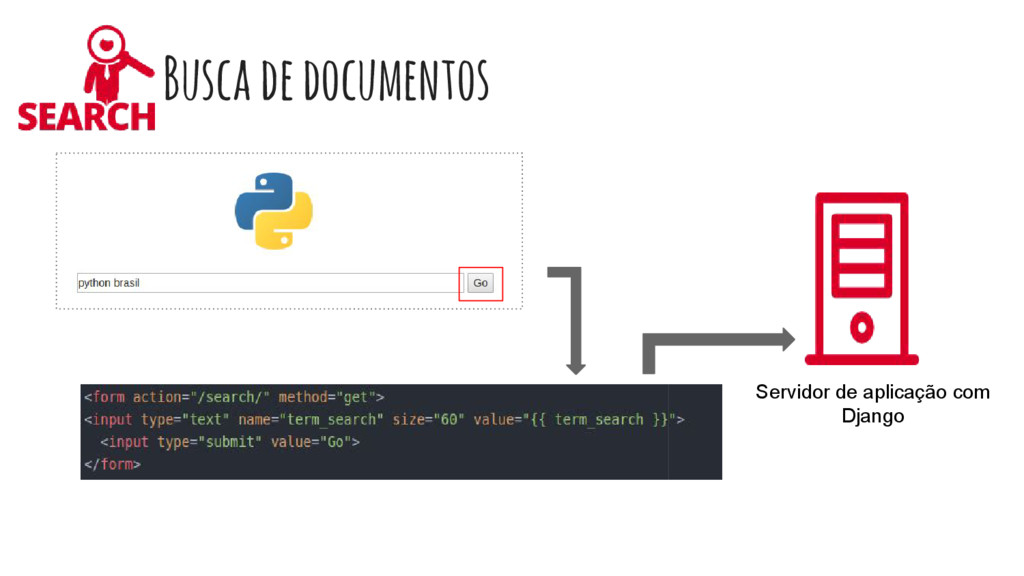
Busca de documentos
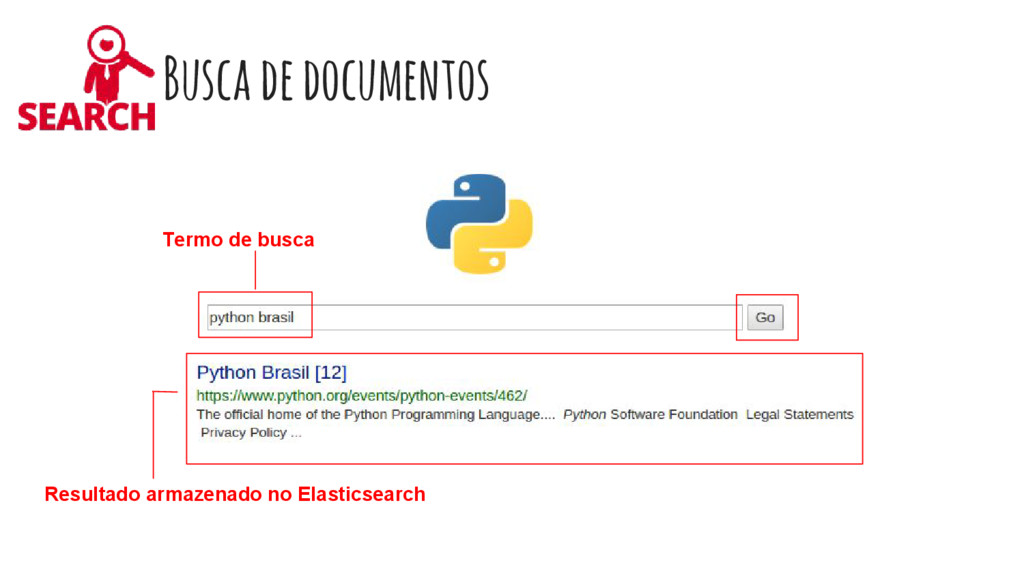
Busca de documentos Resultado armazenado no Elasticsearch Termo de busca
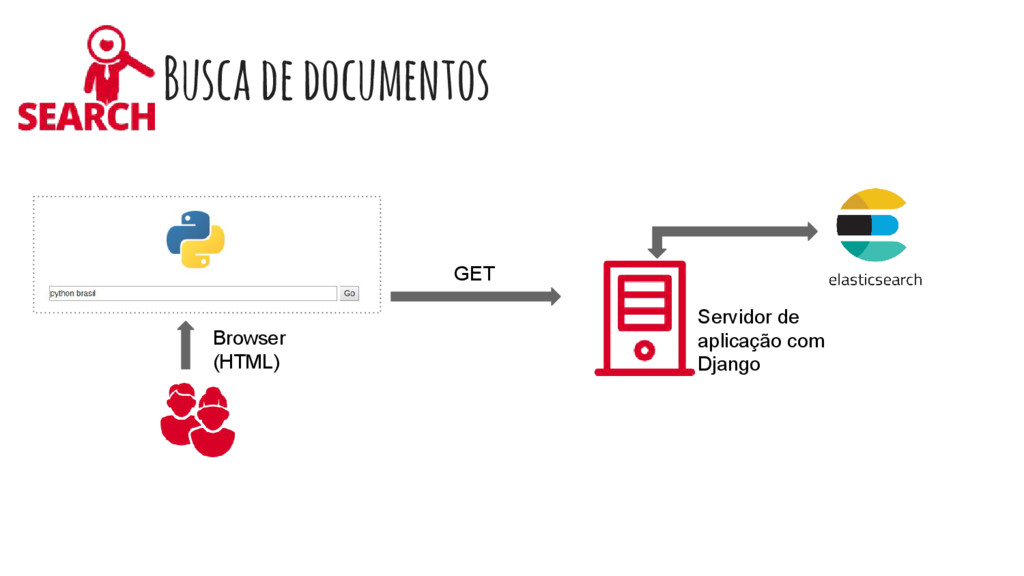
Busca de documentos Servidor de aplicação com Django GET Browser
(HTML)
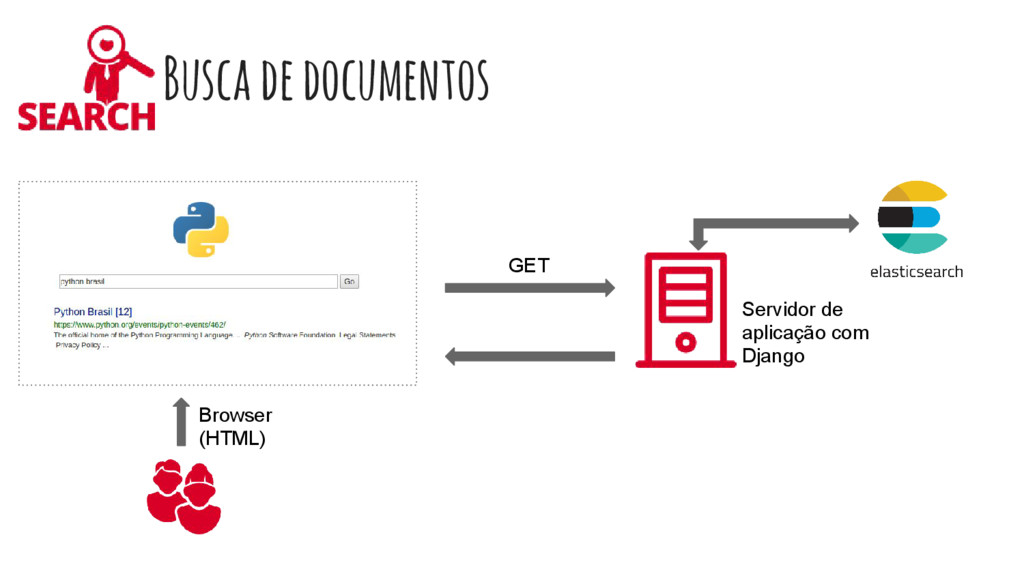
Servidor de aplicação com Django Busca de documentos GET Browser
(HTML)
Busca de documentos . Servidor de aplicação com Django
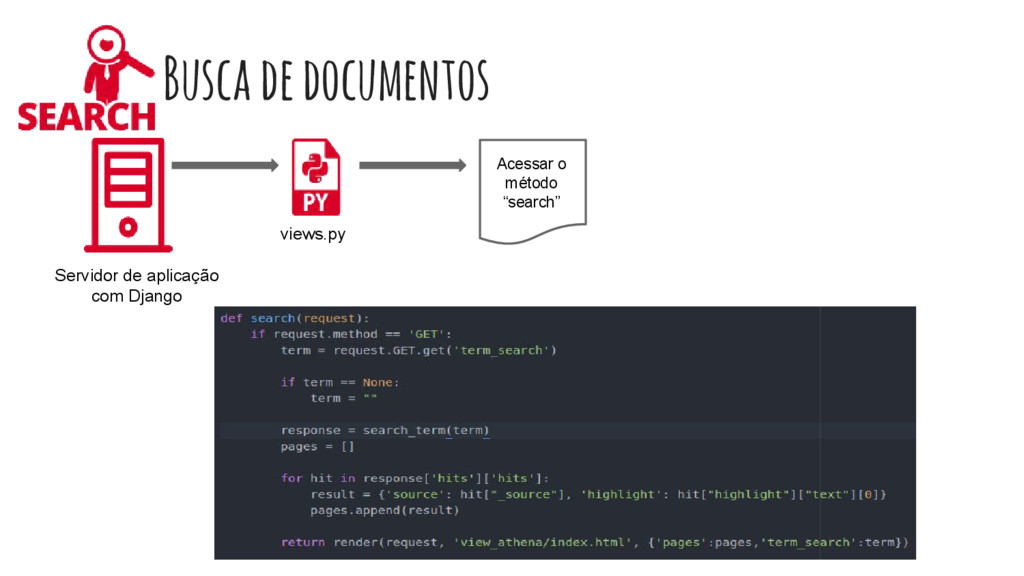
Busca de documentos views.py Acessar o método “search” Servidor de
aplicação com Django
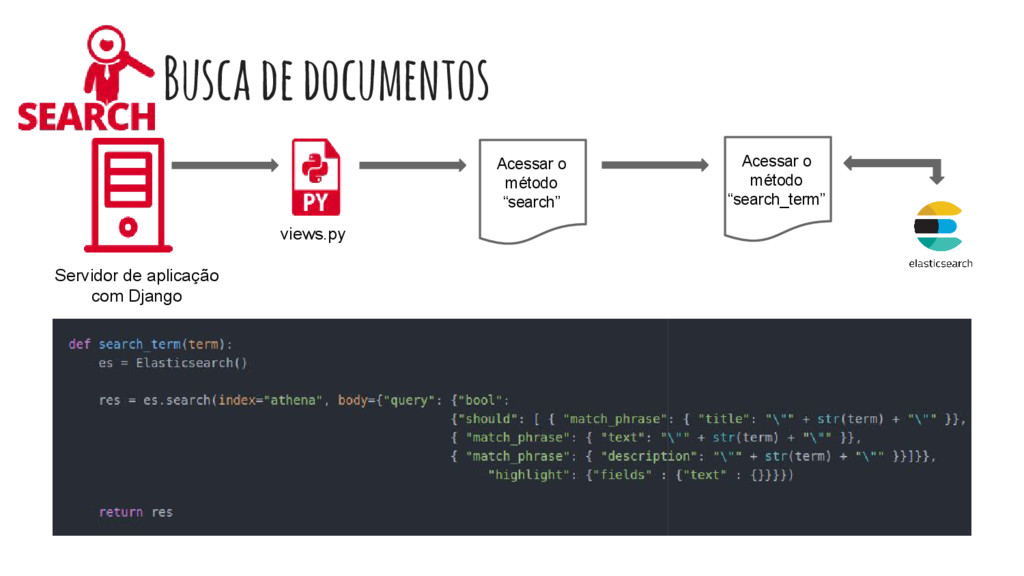
Busca de documentos views.py Acessar o método “search” Acessar o
método “search_term” Servidor de aplicação com Django
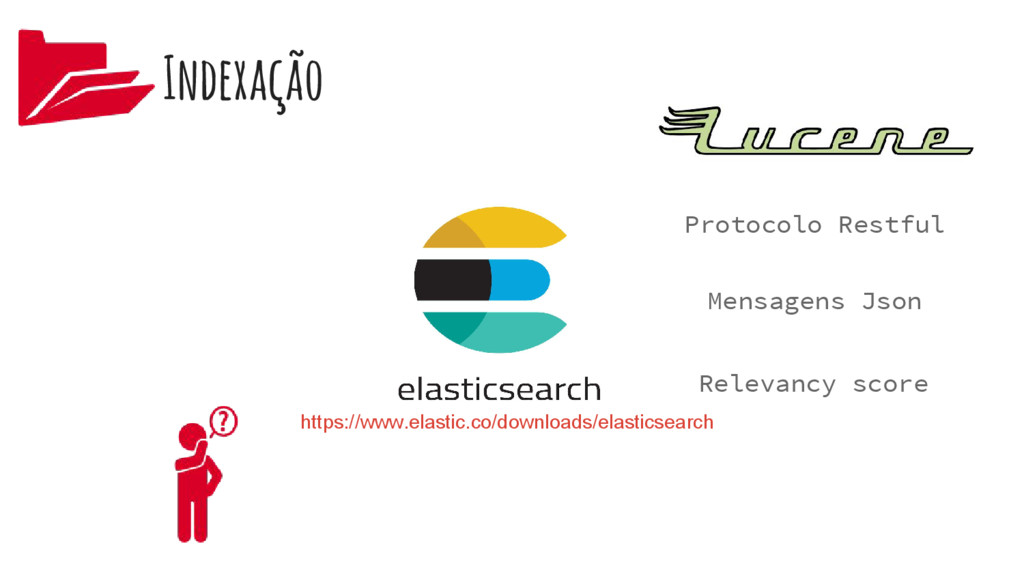
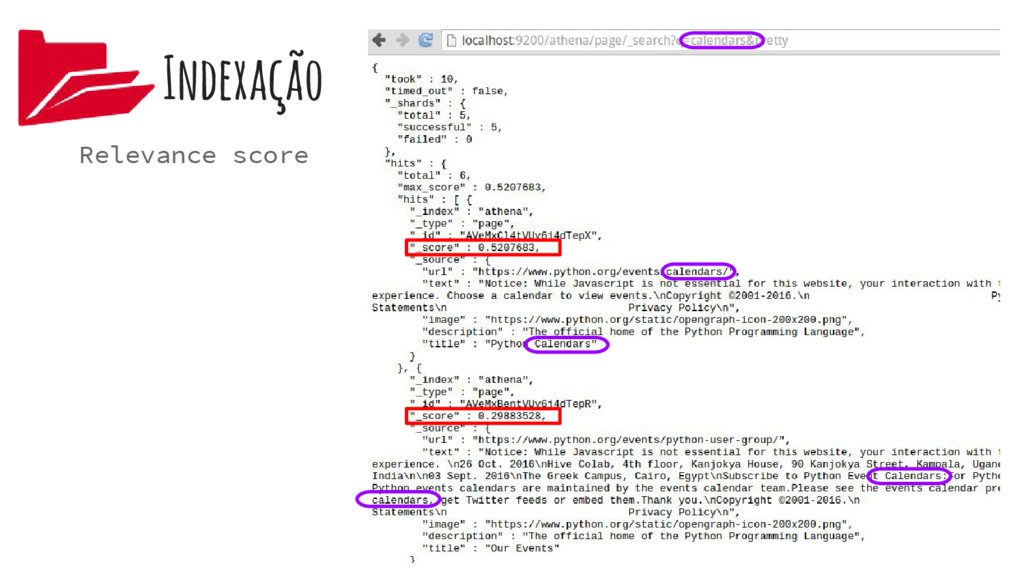
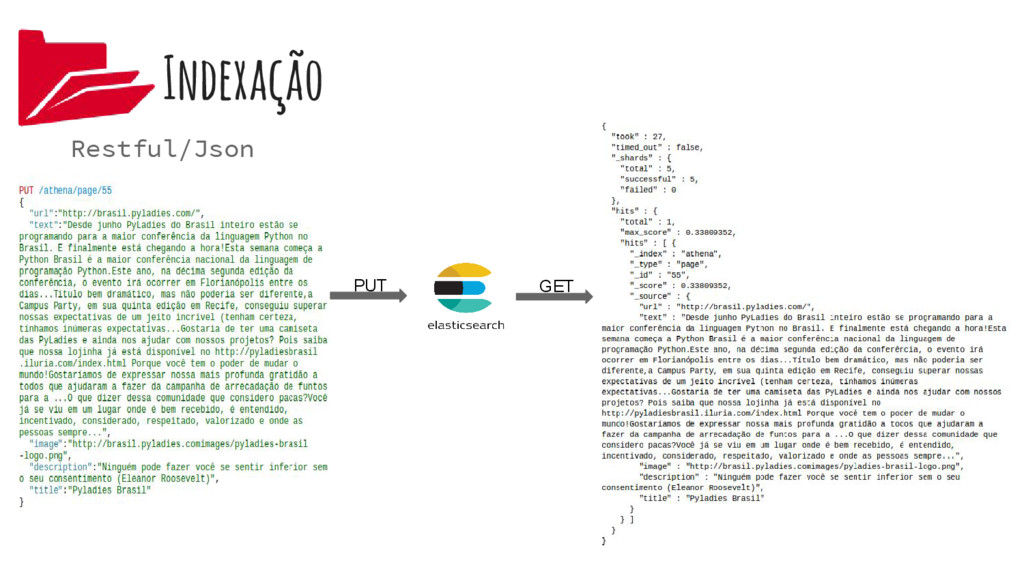
Indexação https://www.elastic.co/downloads/elasticsearch Relevancy score Protocolo Restful Mensagens Json
Indexação Relevance score
Indexação Restful/Json PUT GET
Indexação https://www.elastic.co/use-cases
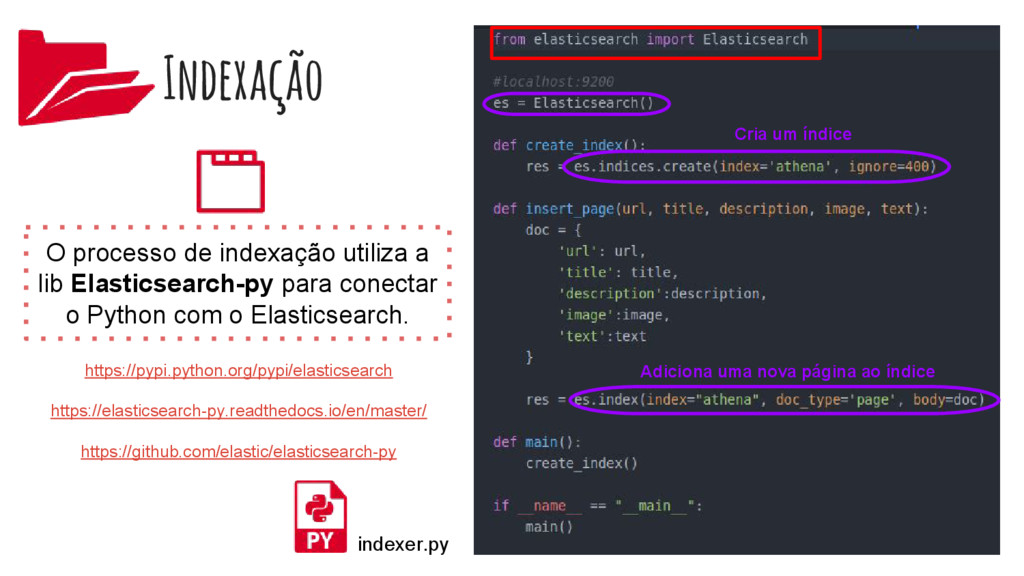
Indexação O processo de indexação utiliza a lib Elasticsearch-py para
conectar o Python com o Elasticsearch. indexer.py https://pypi.python.org/pypi/elasticsearch https://elasticsearch-py.readthedocs.io/en/master/ https://github.com/elastic/elasticsearch-py Cria um índice Adiciona uma nova página ao índice
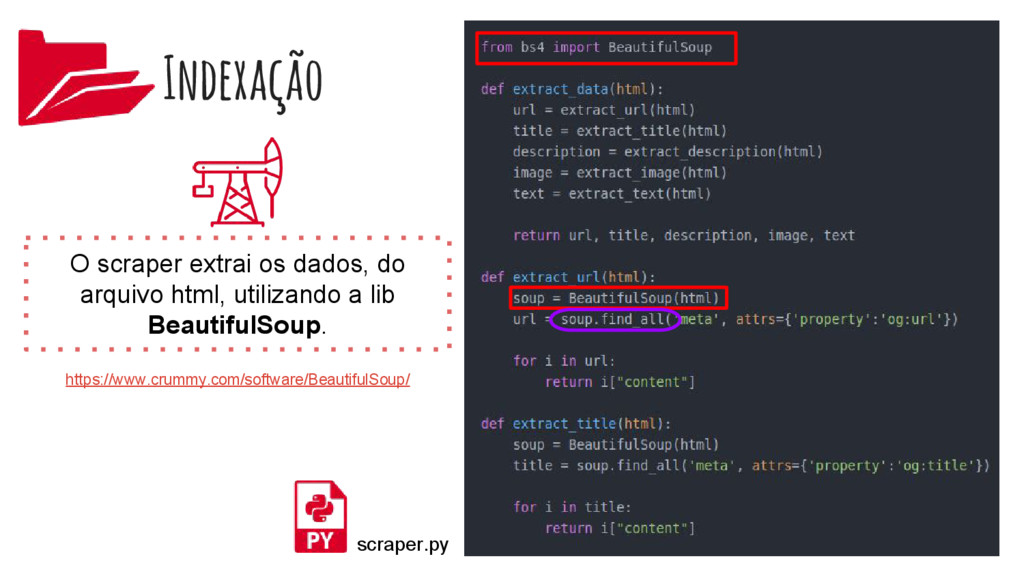
Indexação scraper.py O scraper extrai os dados, do arquivo html,
utilizando a lib BeautifulSoup. https://www.crummy.com/software/BeautifulSoup/
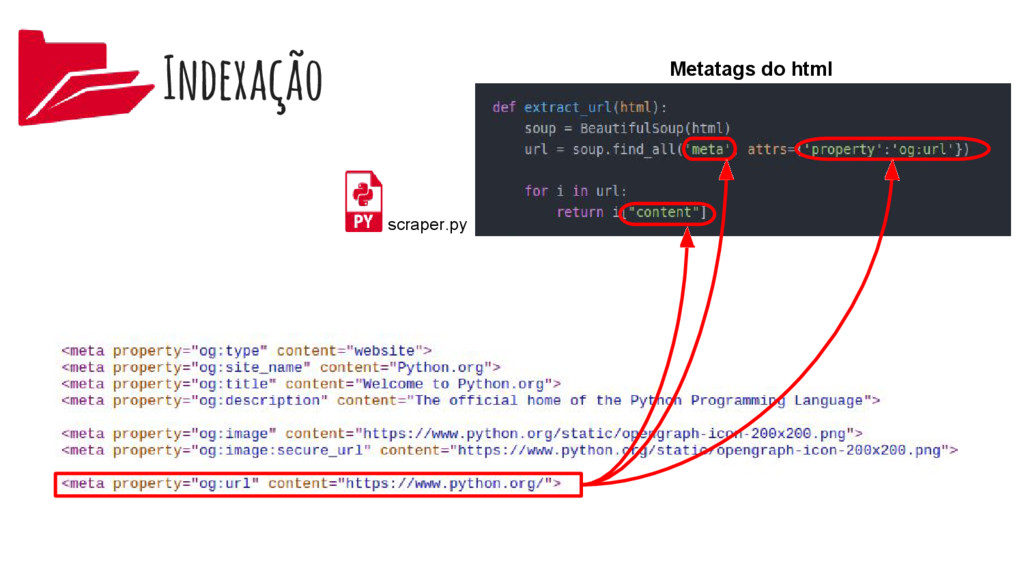
scraper.py Indexação Metatags do html
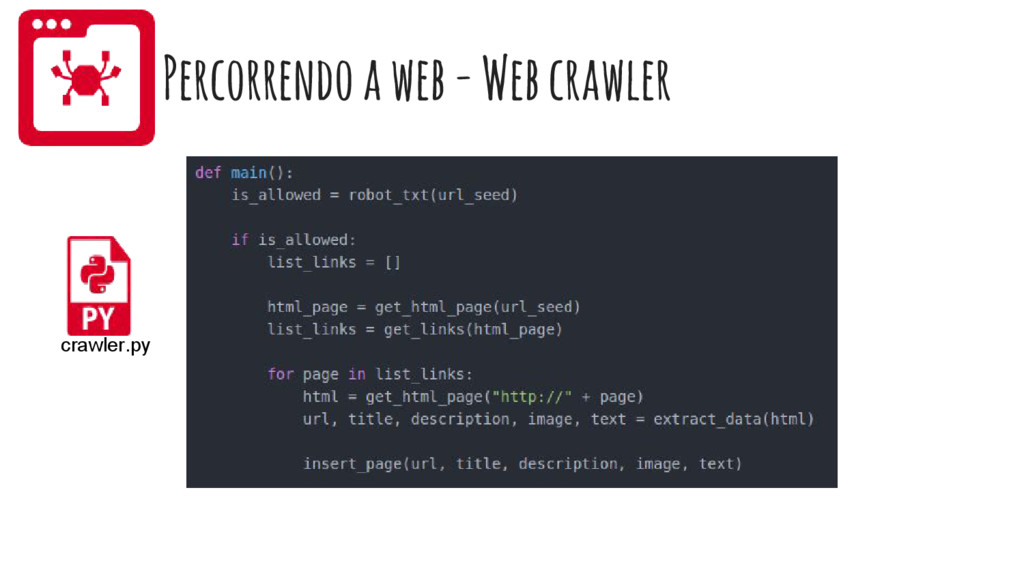
Percorrendo a web - Web crawler crawler.py
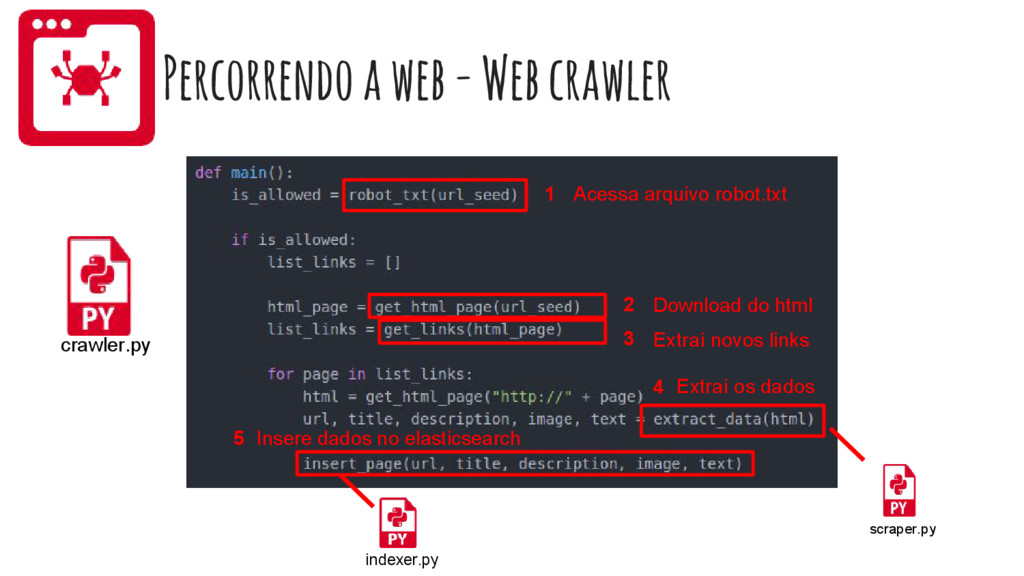
Percorrendo a web - Web crawler 1 3 2 4
5 Acessa arquivo robot.txt Download do html Extraí novos links Extraí os dados Insere dados no elasticsearch indexer.py scraper.py crawler.py
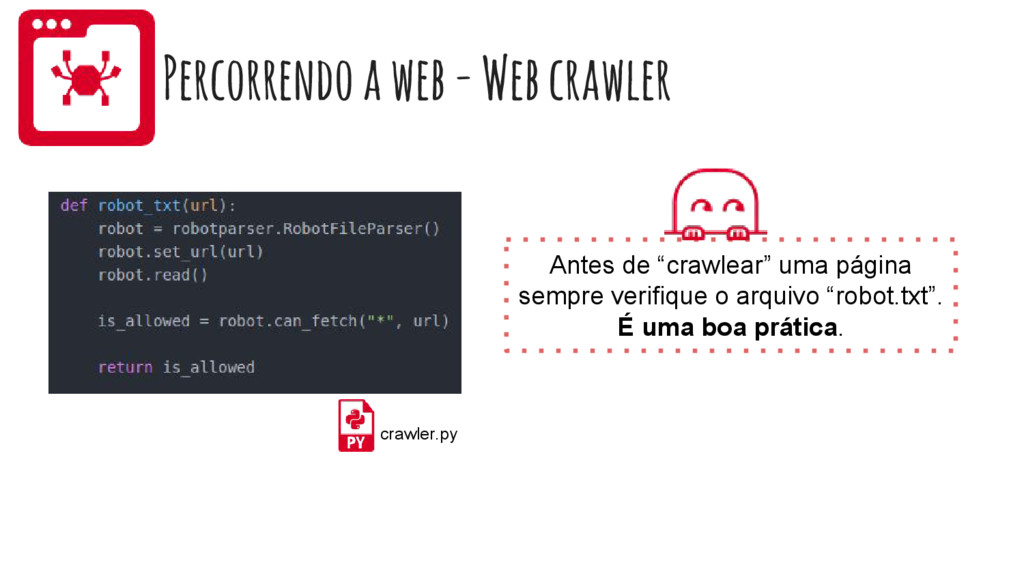
Percorrendo a web - Web crawler Antes de “crawlear” uma
página sempre verifique o arquivo “robot.txt”. É uma boa prática. crawler.py
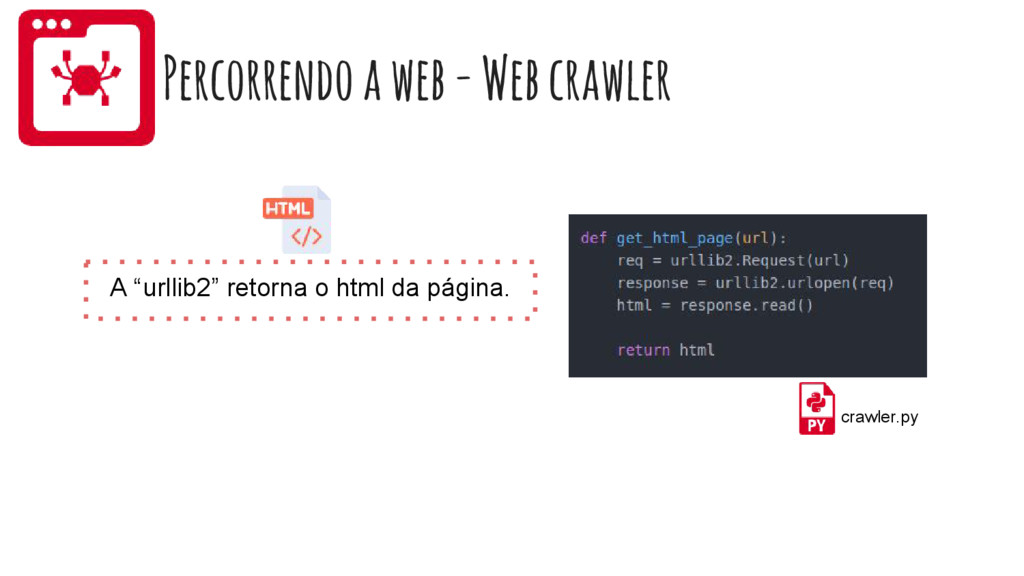
Percorrendo a web - Web crawler A “urllib2” retorna o
html da página. crawler.py
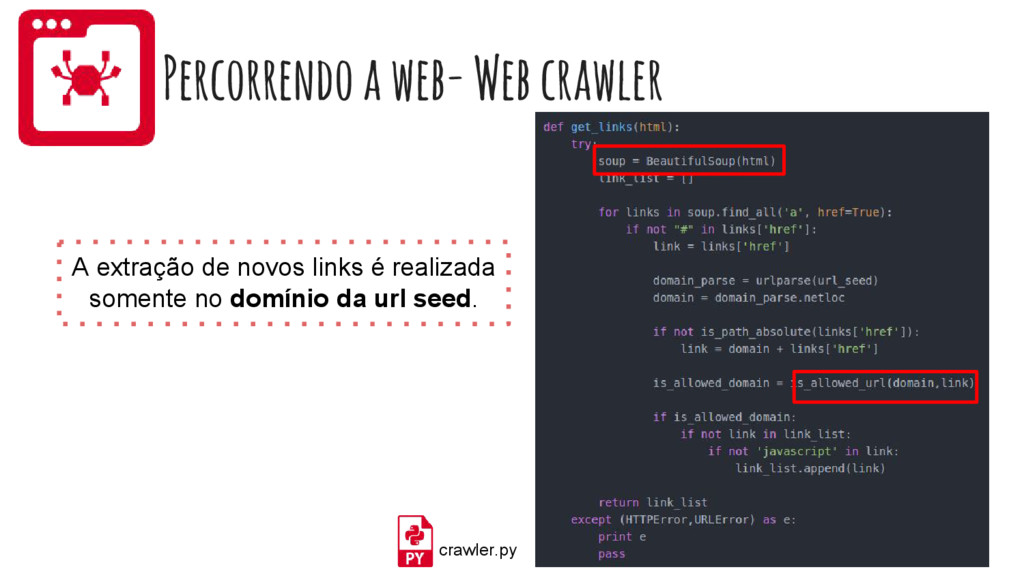
Percorrendo a web- Web crawler crawler.py A extração de novos
links é realizada somente no domínio da url seed.
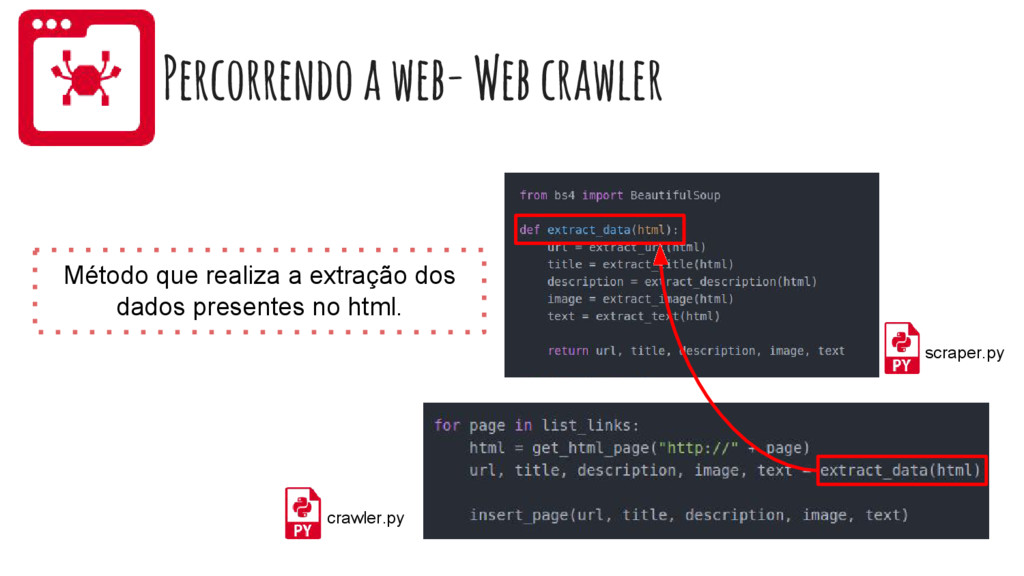
Percorrendo a web- Web crawler Método que realiza a extração
dos dados presentes no html. scraper.py crawler.py
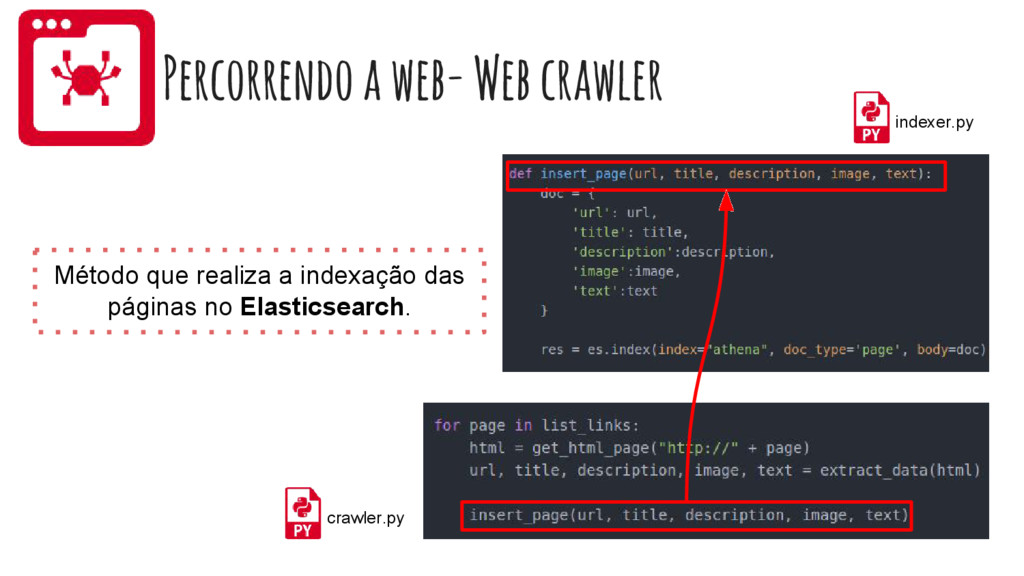
Percorrendo a web- Web crawler Método que realiza a indexação
das páginas no Elasticsearch. indexer.py crawler.py
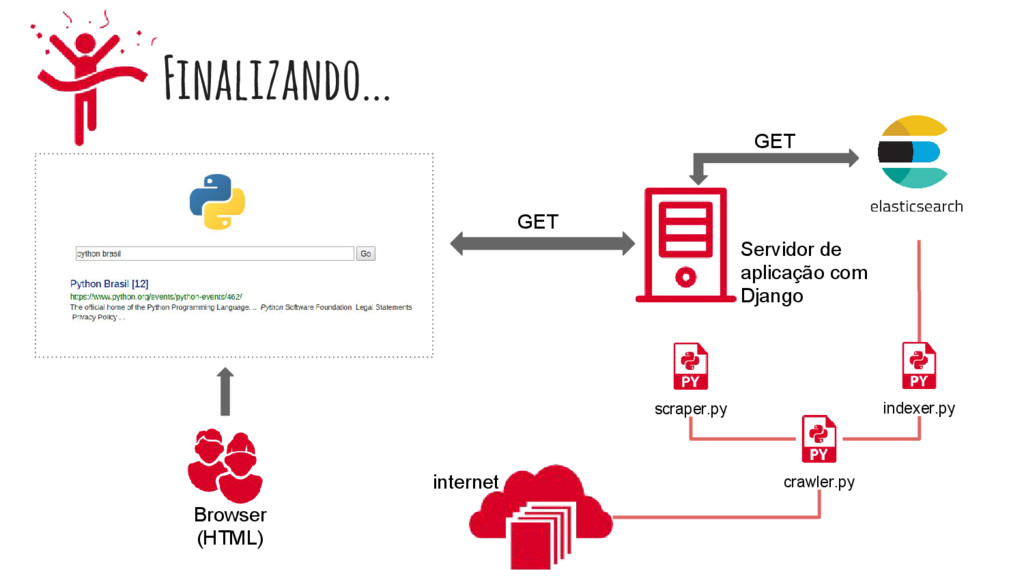
Finalizando... Browser (HTML) GET Servidor de aplicação com Django scraper.py
crawler.py indexer.py GET internet
https://github.com/pattyvader https://br.linkedin.com/in/patricia-regina-18790040 Contato *Designed by Freepik from www.flaticon.com*
[email protected]


 pattyvader
 clockmaker
 yuta_onishi_97
 florets1
 tanahiro2010
 htkym
 uyuki234
 minodriven
 gonta
 timakin
 kenjiyoneyama
 ryu1013
 marcoroth
 sabderemane
 marktimemedia
 helenjbeal
 mfonobong
 nmsamuel
 trallard
 philnash
 iamctodd
 trishagee
 jnunemaker
 reverentgeek
 gr2m