Share
Embed
The Six Principles For Resilient Evolvability
The Six Principles For Resilient Evolvability: Building robust yet flexible shared data applications
Principles to follow when building applications & services which are on different release trains, but have the overlapping dependencies on a shared data set. Also discusses something coined the Data Access Triangle, including Shared Data, Isolated Data and Duplicated Data, and some of the trade-offs of each. Accompanied by an example application on GitHub: https://github.com/pkdone/mongo-resilient-evolvability-demo
@TheDonester

Paul Done
December 01, 2020
Transcript
73 slides
-
Paul Done | Executive Solutions Architect | MongoDB Inc. |
@TheDonester The Six Principles For Resilient Evolvability Building robust yet flexible shared data applications November 2020 -
Software development practices & the way we incrementally deliver new
code to address evolving business needs, are becoming far more fluid & agile... -
...but if we don’t allow for agility in our live
data, to match the flexibility of our modern business logic approaches, solutions will still be resistant to rapid business change -
So, here we will explore techniques to effectively deliver resilient
yet evolvable data-intensive applications -
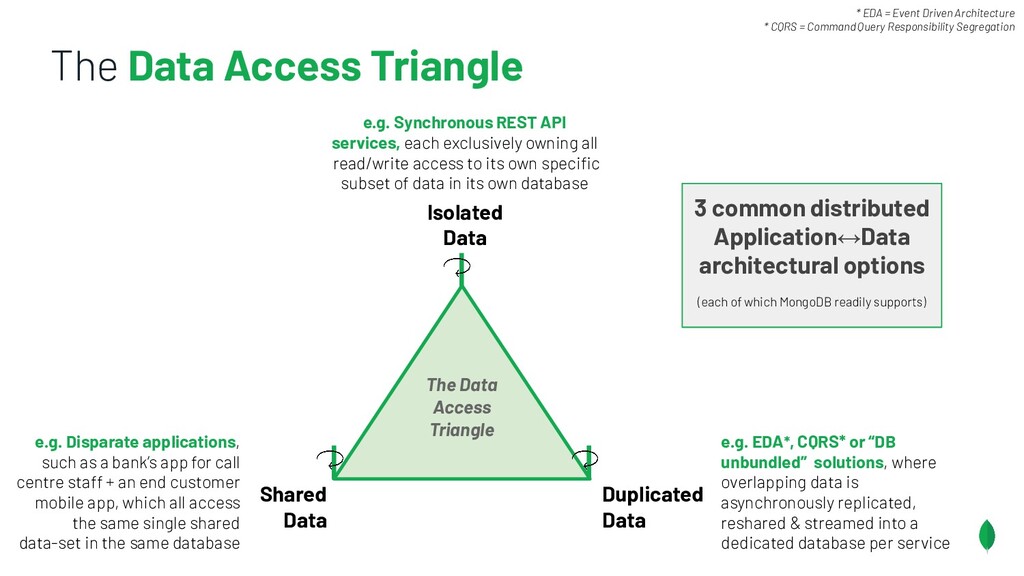
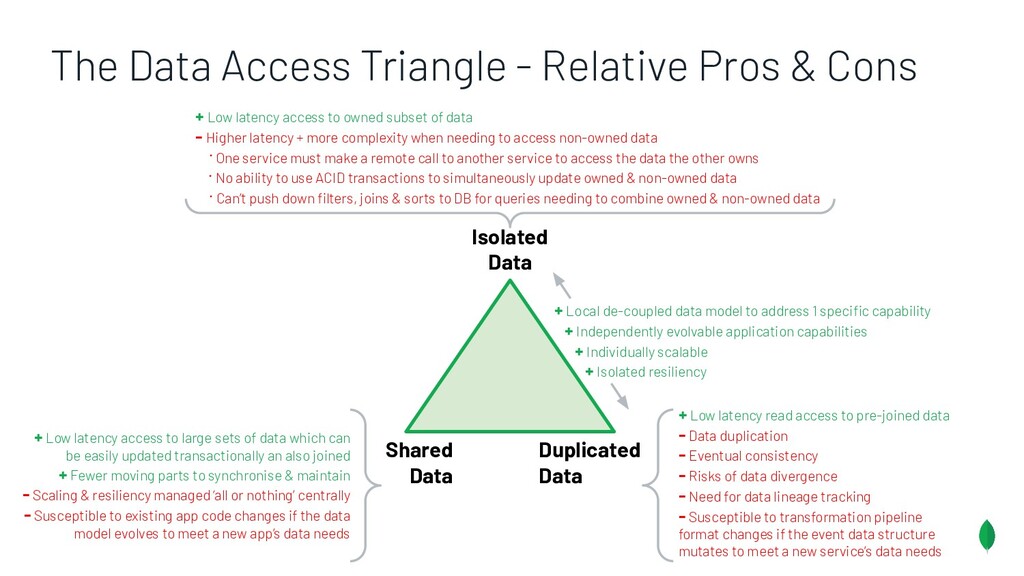
The Data Access Triangle Shared Data Isolated Data Duplicated Data
e.g. Synchronous REST API services, each exclusively owning all read/write access to its own specific subset of data in its own database e.g. EDA*, CQRS* or “DB unbundled” solutions, where overlapping data is asynchronously replicated, reshared & streamed into a dedicated database per service e.g. Disparate applications, such as a bank’s app for call centre staff + an end customer mobile app, which all access the same single shared data-set in the same database * EDA = Event Driven Architecture * CQRS = Command Query Responsibility Segregation 3 common distributed Application↔Data architectural options (each of which MongoDB readily supports) The Data Access Triangle -
Shared Data Isolated Data Duplicated Data + Low latency read
access to pre-joined data - Data duplication - Eventual consistency - Risks of data divergence - Need for data lineage tracking - Susceptible to transformation pipeline format changes if the event data structure mutates to meet a new service’s data needs + Low latency access to owned subset of data - Higher latency + more complexity when needing to access non-owned data . One service must make a remote call to another service to access the data the other owns . No ability to use ACID transactions to simultaneously update owned & non-owned data . Can’t push down filters, joins & sorts to DB for queries needing to combine owned & non-owned data + Low latency access to large sets of data which can be easily updated transactionally an also joined + Fewer moving parts to synchronise & maintain - Scaling & resiliency managed ‘all or nothing’ centrally - Susceptible to existing app code changes if the data model evolves to meet a new app’s data needs + Local de-coupled data model to address 1 specific capability + Independently evolvable application capabilities + Individually scalable + Isolated resiliency The Data Access Triangle - Relative Pros & Cons -
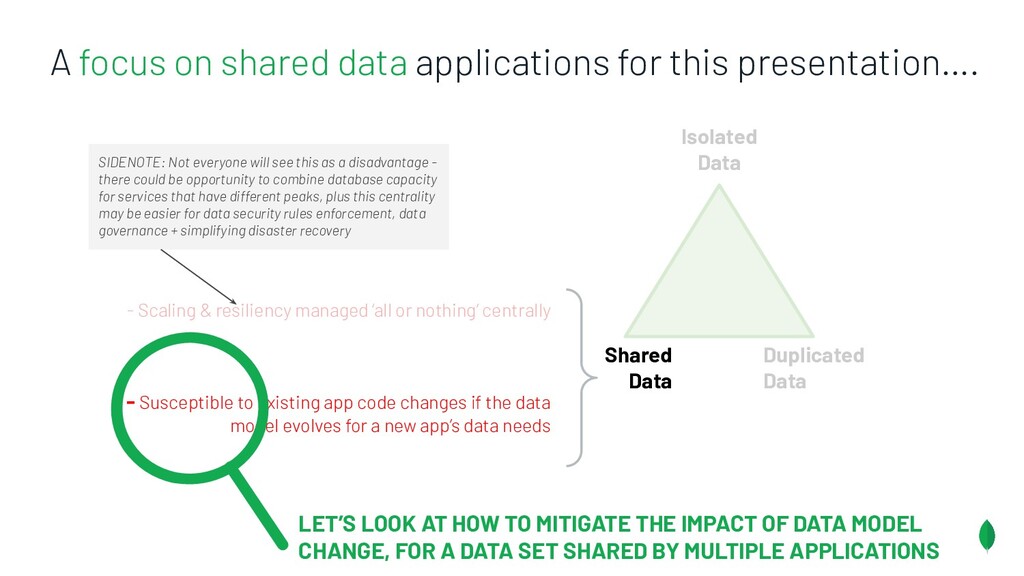
Shared Data Isolated Data Duplicated Data - Scaling & resiliency
managed ‘all or nothing’ centrally - Susceptible to existing app code changes if the data model evolves for a new app’s data needs A focus on shared data applications for this presentation…. LET’S LOOK AT HOW TO MITIGATE THE IMPACT OF DATA MODEL CHANGE, FOR A DATA SET SHARED BY MULTIPLE APPLICATIONS SIDENOTE: Not everyone will see this as a disadvantage - there could be opportunity to combine database capacity for services that have different peaks, plus this centrality may be easier for data security rules enforcement, data governance + simplifying disaster recovery -
Quick Important Note This is NOT a presentation about Monoliths
vs Microservices or relative merits of each ‐ Many principles outlined are applicable to either (or any grey area between) So, this presentation intentionally refers to new pieces of business code as Components, which in reality could be: ‐ A new set of functions added to an application ‐ A new library added to an application ‐ A new standalone microservice ‐ A new standalone service ‐ A new application ‐ A new set of applications -
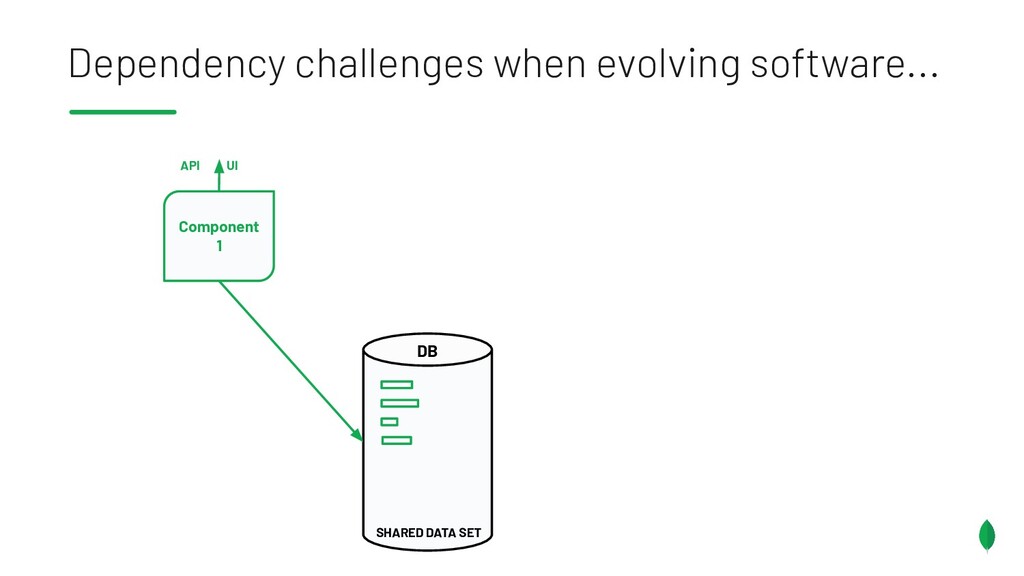
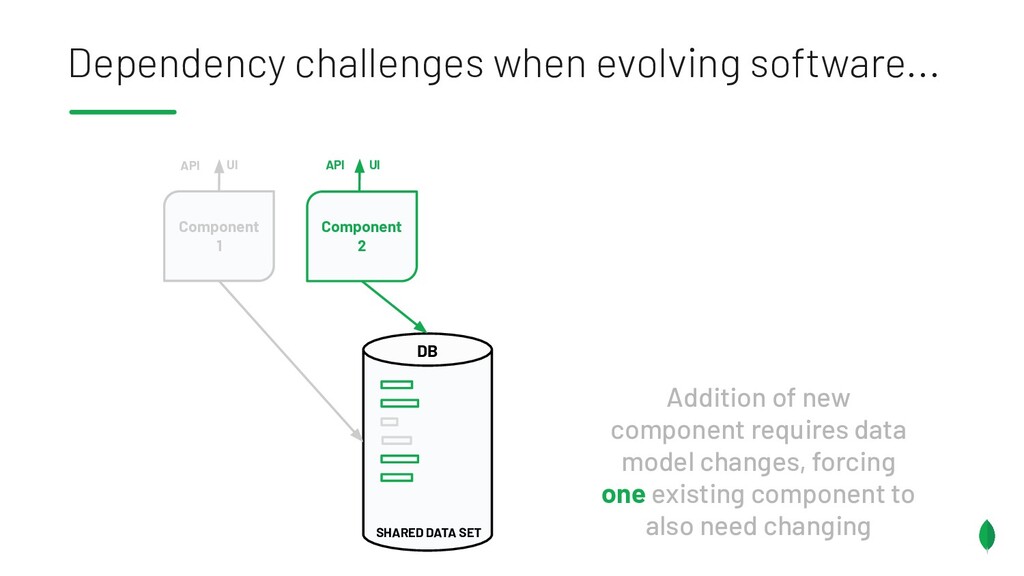
Dependency challenges when evolving software... DB Component 2 API Component
1 API UI UI Addition of new component requires data model changes, forcing one existing component to also need changing SHARED DATA SET -
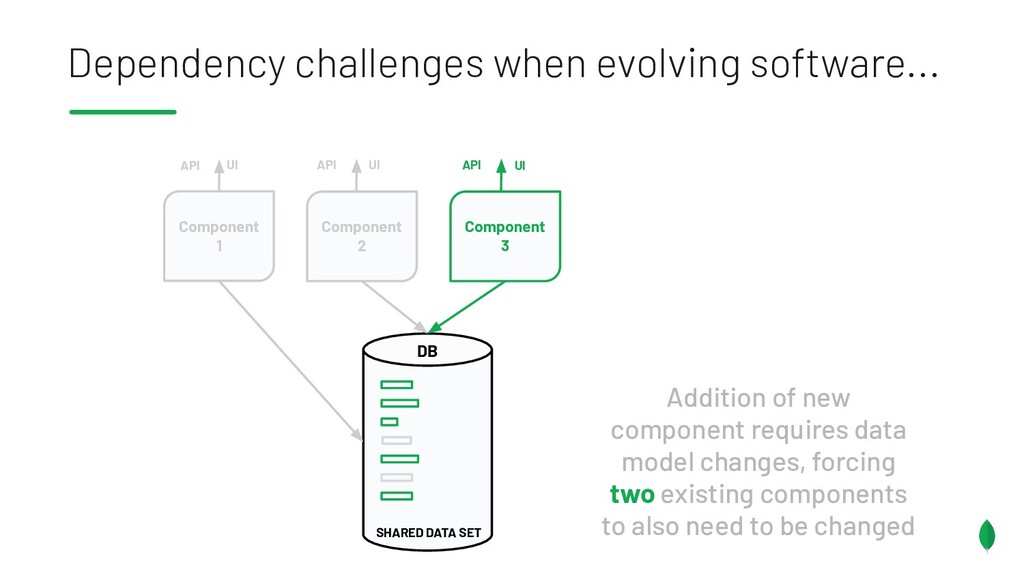
Dependency challenges when evolving software... DB Component 2 API Component
1 API Component 3 API UI UI UI Addition of new component requires data model changes, forcing two existing components to also need to be changed SHARED DATA SET -
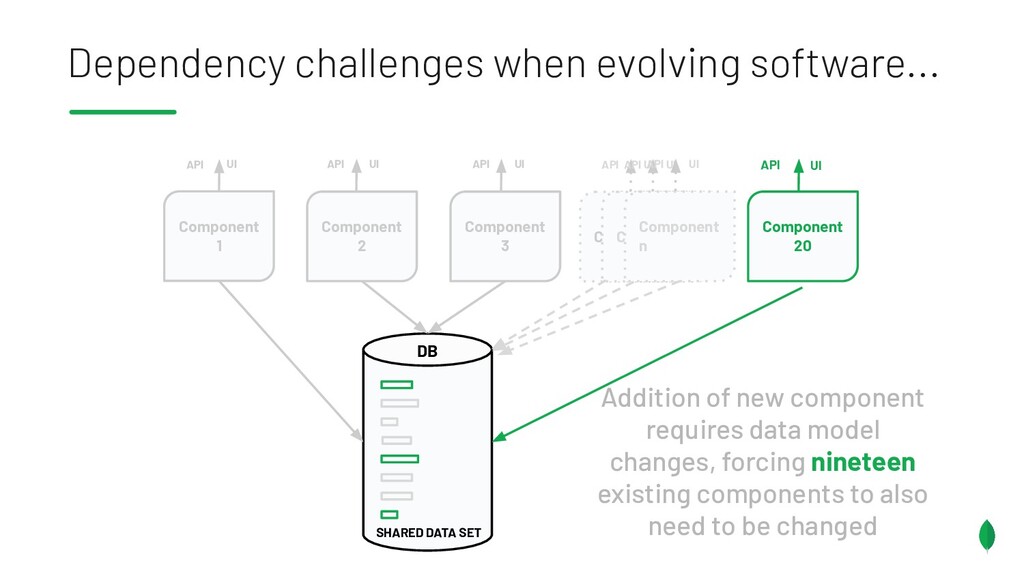
Dependency challenges when evolving software... DB Component 2 API Component
1 API Component 3 API Component 20 API UI UI UI UI Component API UI Component API UI Component n API UI Addition of new component requires data model changes, forcing nineteen existing components to also need to be changed SHARED DATA SET -
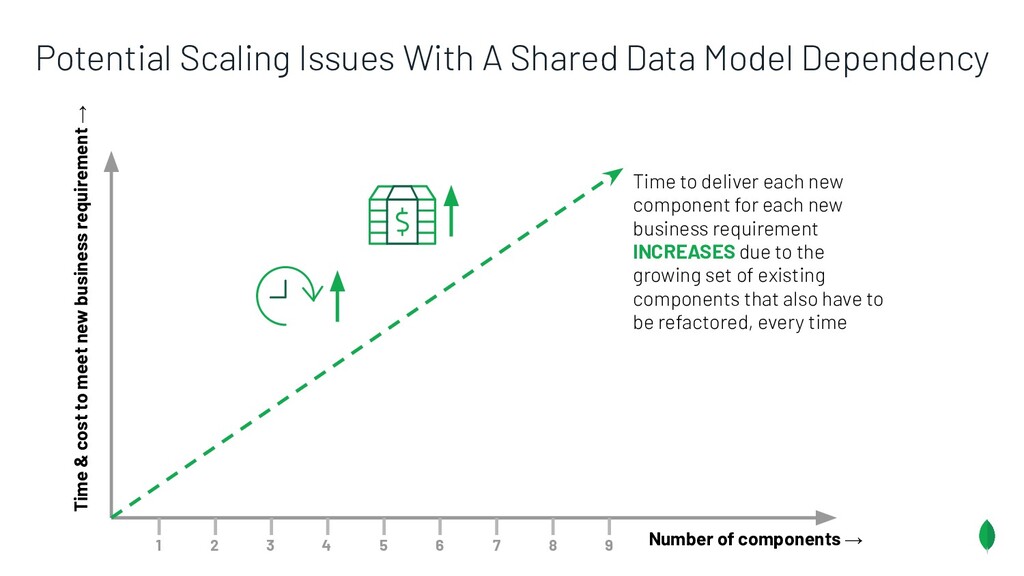
Potential Scaling Issues With A Shared Data Model Dependency Number
of components → Time & cost to meet new business requirement → 1 2 3 4 5 6 7 8 9 Time to deliver each new component for each new business requirement INCREASES due to the growing set of existing components that also have to be refactored, every time -
So, MongoDB already has a flexible data model Isn’t that
enough for software agility? No, it isn’t It is also about application development best practices Hence this talk Almost impossible with RDBMS Even though some RDBMS provide schema versioning, these invariably fall short if modifying the E-R model to include a new 1:M child table & relationship, for example But a DB with a flexible data model, like MongoDB’s, is an essential foundation -
An approach that should apply regardless of programming language, so
let’s test it against the most strict & statically compiled language supported by MongoDB, to be sure... -
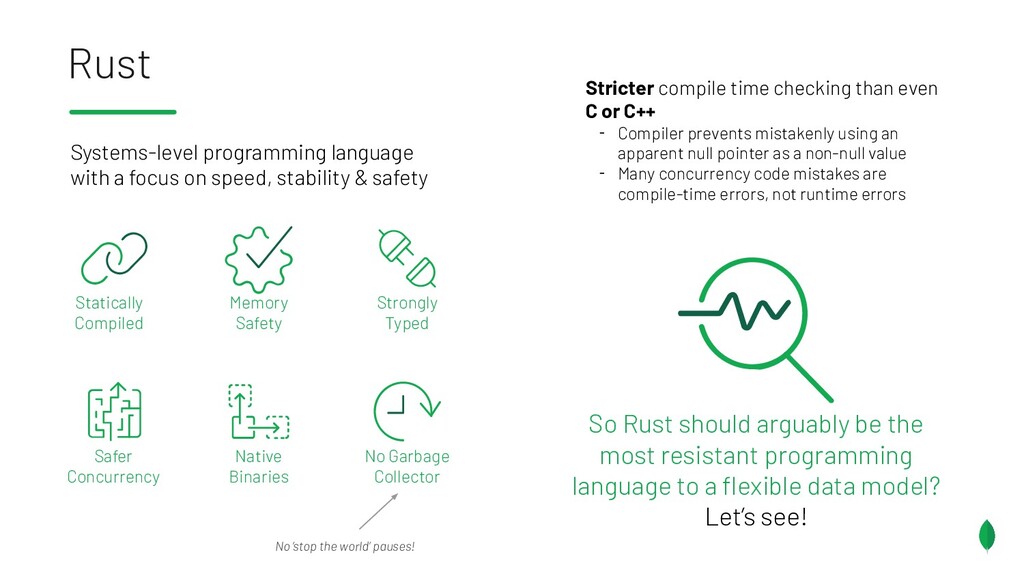
Rust No Garbage Collector Safer Concurrency Strongly Typed Memory Safety
Statically Compiled Systems-level programming language with a focus on speed, stability & safety Native Binaries Stricter compile time checking than even C or C++ ‑ Compiler prevents mistakenly using an apparent null pointer as a non-null value ‑ Many concurrency code mistakes are compile-time errors, not runtime errors So Rust should arguably be the most resistant programming language to a flexible data model? Let’s see! No ‘stop the world’ pauses! -
Also, Rust is unlikely to be well known by most
of you, so is a good way to convey principles that apply to any programming language (you shouldn’t need to know Rust to follow this presentation) -
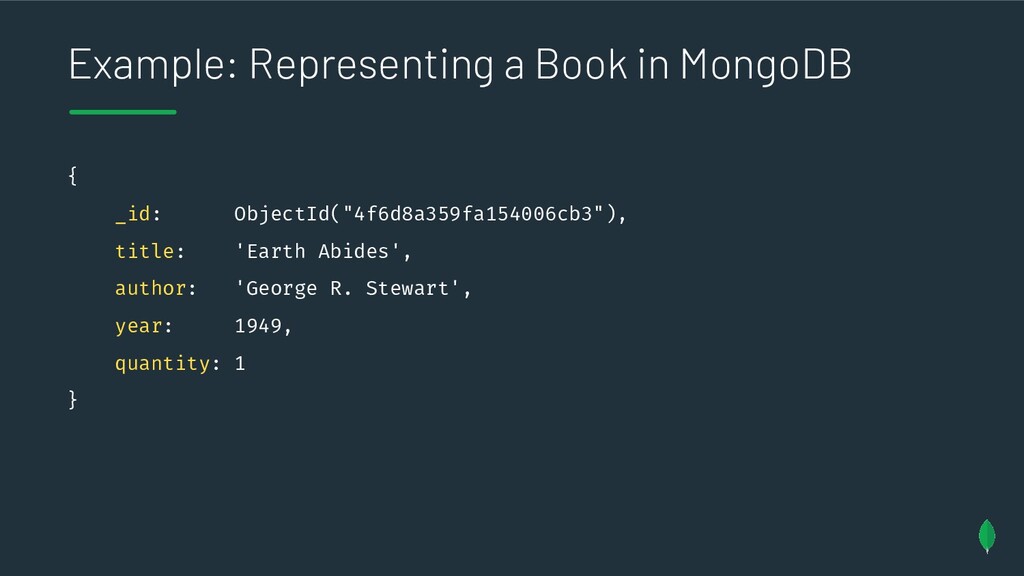
Example: Representing a Book in MongoDB { _id: ObjectId("4f6d8a359fa154006cb3"), title:
'Earth Abides', author: 'George R. Stewart', year: 1949, quantity: 1 } -
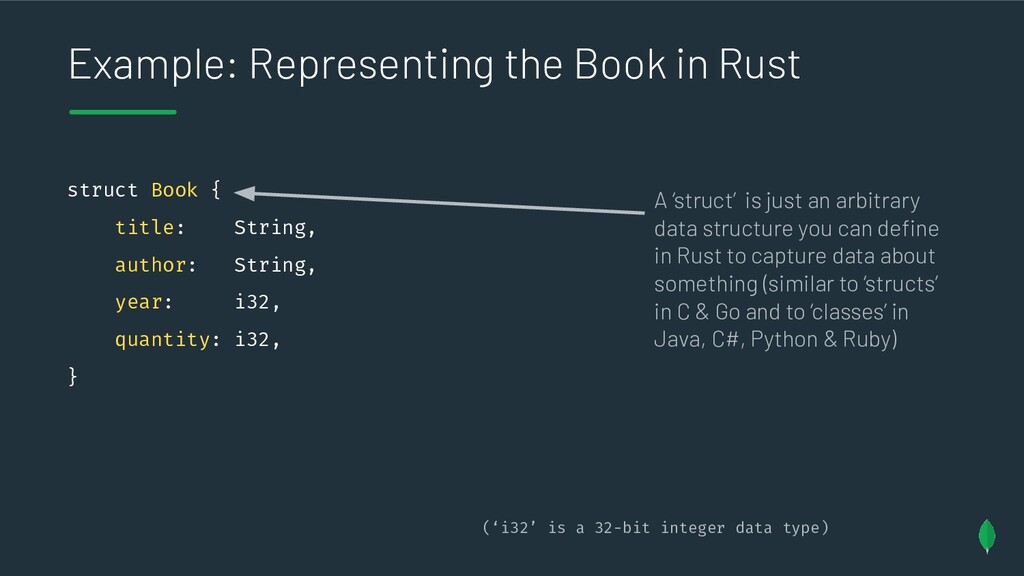
Example: Representing the Book in Rust struct Book { title:
String, author: String, year: i32, quantity: i32, } (‘i32’ is a 32-bit integer data type) A ‘struct’ is just an arbitrary data structure you can define in Rust to capture data about something (similar to ‘structs’ in C & Go and to ‘classes’ in Java, C#, Python & Ruby) -
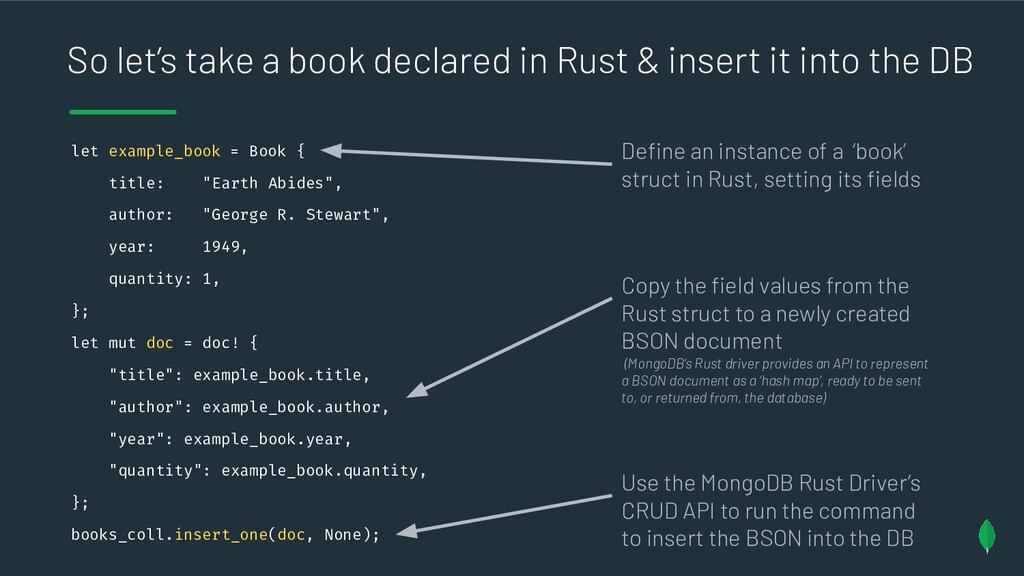
So let’s take a book declared in Rust & insert
it into the DB let example_book = Book { title: "Earth Abides", author: "George R. Stewart", year: 1949, quantity: 1, }; let mut doc = doc! { "title": example_book.title, "author": example_book.author, "year": example_book.year, "quantity": example_book.quantity, }; books_coll.insert_one(doc, None); Define an instance of a ‘book’ struct in Rust, setting its fields Copy the field values from the Rust struct to a newly created BSON document (MongoDB’s Rust driver provides an API to represent a BSON document as a ‘hash map’, ready to be sent to, or returned from, the database) Use the MongoDB Rust Driver’s CRUD API to run the command to insert the BSON into the DB -
But in a MongoDB database collection, a specific field might
not appear in every document (and this point actually conveys information) -
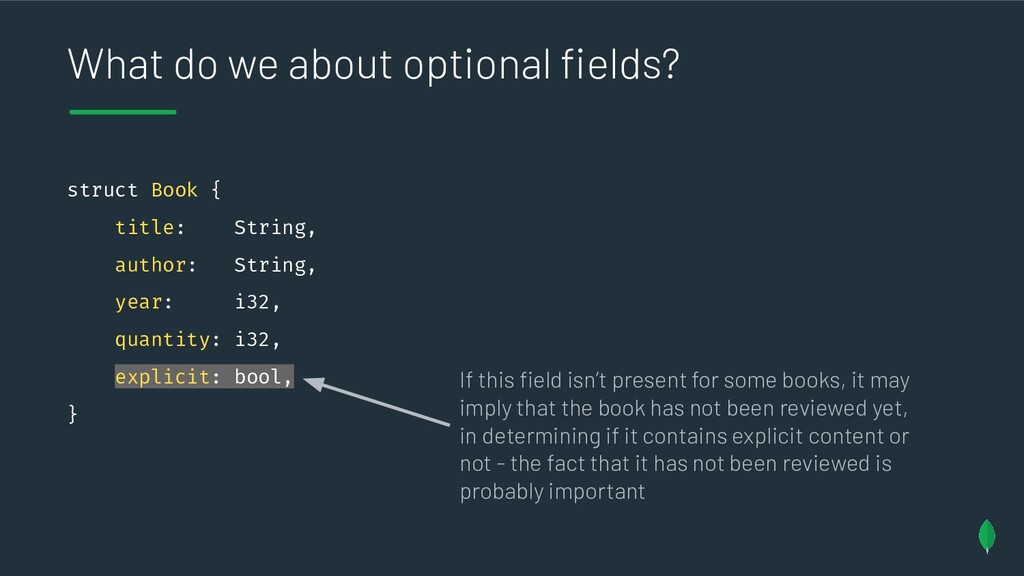
What do we about optional fields? struct Book { title:
String, author: String, year: i32, quantity: i32, explicit: bool, } If this field isn’t present for some books, it may imply that the book has not been reviewed yet, in determining if it contains explicit content or not - the fact that it has not been reviewed is probably important -
Well Rust also has a well used native concept to
convey that a variable may have some value (’Some’) or no value (’None’) - this is called an ’Option’ in Rust -
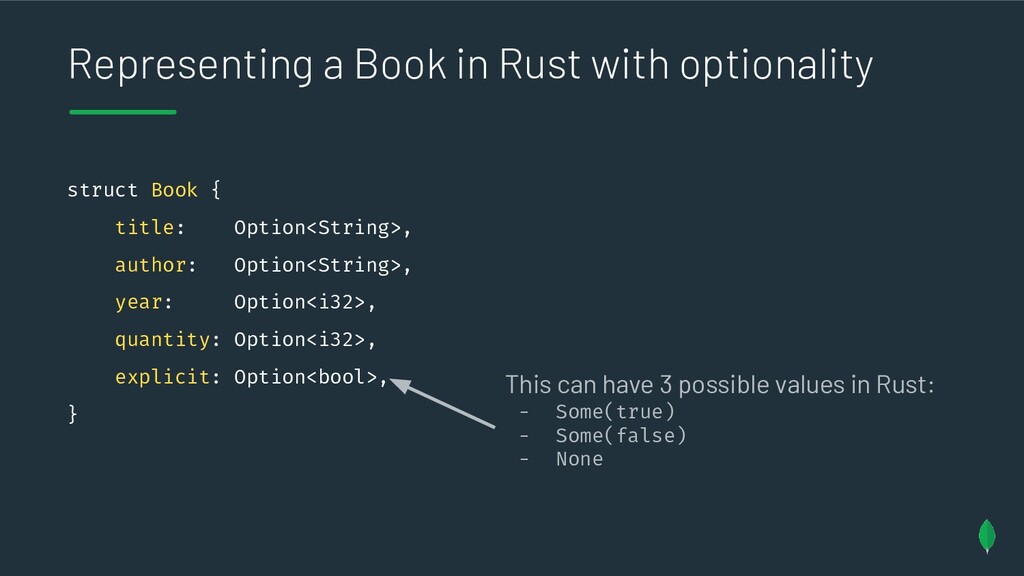
Representing a Book in Rust with optionality struct Book {
title: Option<String>, author: Option<String>, year: Option<i32>, quantity: Option<i32>, explicit: Option<bool>, } This can have 3 possible values in Rust: - Some(true) - Some(false) - None -
So how would we support this optionality in code we
are using to interact with the database? -
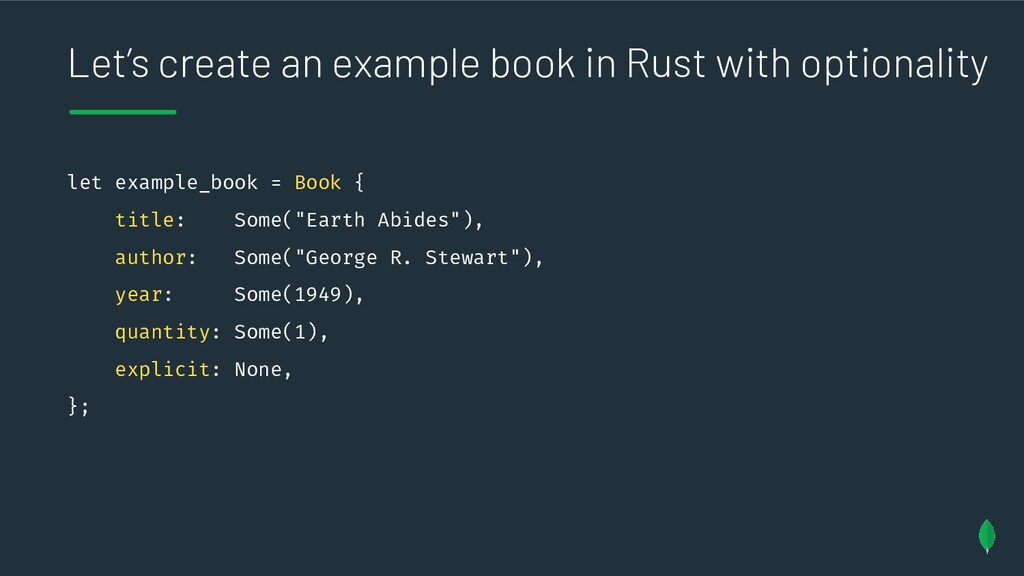
Let’s create an example book in Rust with optionality let
example_book = Book { title: Some("Earth Abides"), author: Some("George R. Stewart"), year: Some(1949), quantity: Some(1), explicit: None, }; -
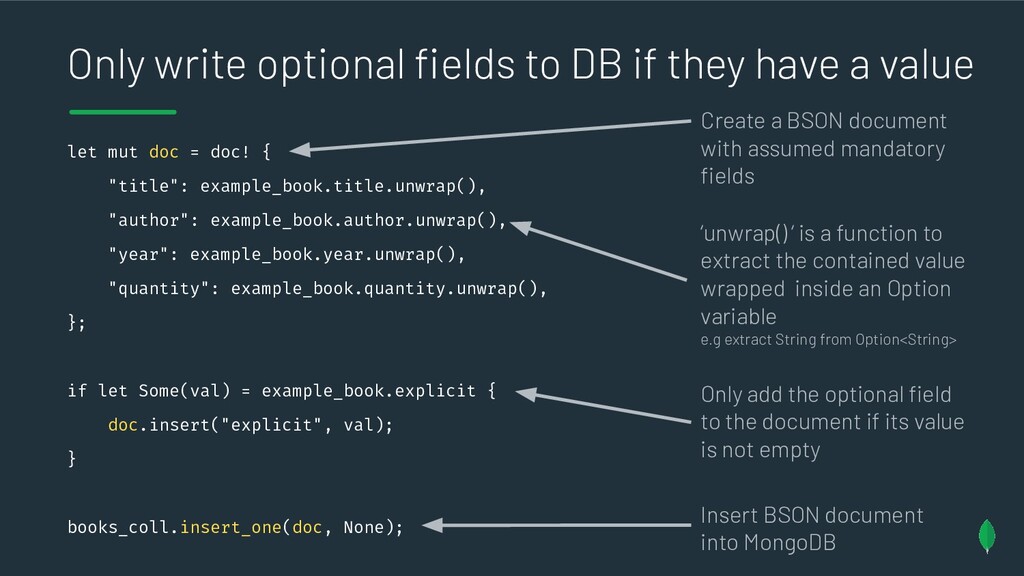
Only write optional fields to DB if they have a
value let mut doc = doc! { "title": example_book.title.unwrap(), "author": example_book.author.unwrap(), "year": example_book.year.unwrap(), "quantity": example_book.quantity.unwrap(), }; if let Some(val) = example_book.explicit { doc.insert("explicit", val); } books_coll.insert_one(doc, None); Only add the optional field to the document if its value is not empty Create a BSON document with assumed mandatory fields Insert BSON document into MongoDB ‘unwrap() ‘ is a function to extract the contained value wrapped inside an Option variable e.g extract String from Option<String> -
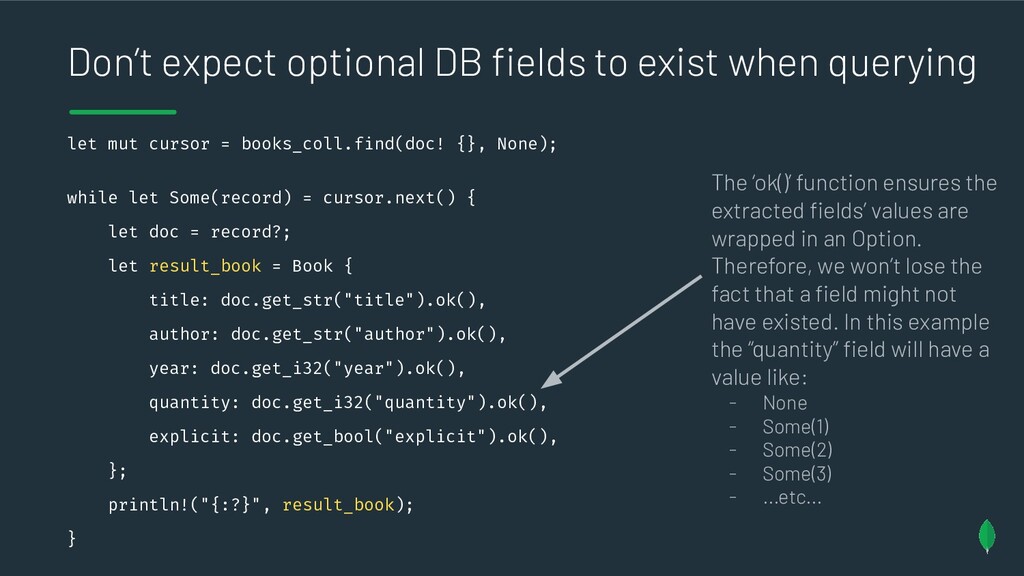
Don’t expect optional DB fields to exist when querying let
mut cursor = books_coll.find(doc! {}, None); while let Some(record) = cursor.next() { let doc = record?; let result_book = Book { title: doc.get_str("title").ok(), author: doc.get_str("author").ok(), year: doc.get_i32("year").ok(), quantity: doc.get_i32("quantity").ok(), explicit: doc.get_bool("explicit").ok(), }; println!("{:?}", result_book); } The ‘ok()’ function ensures the extracted fields’ values are wrapped in an Option. Therefore, we won’t lose the fact that a field might not have existed. In this example the “quantity” field will have a value like: - None - Some(1) - Some(2) - Some(3) - ...etc... -
But what if we want to use a Document Mapper
tool in our code, for convenience, to serialise/deserialise data to/from the DB? -
Document Mapper * Object Relational Mapping tool Translate object definition
to SQL Maps each application object to a set of tables, generating necessary joins Heavyweight abstraction - does a lot Inflexible Data model changes invariably require application code changes ORM a.k.a. Object Document Mapping tool Translate data structure to DB document format Maps each application data structure to a single database record Lightweight abstraction - thin layer Flexible? ...to be determined Do data model changes require application code changes? Not always objects - could be other types of data structures * BE CAREFUL, NOT ALL DOCUMENT MAPPERS ARE CREATED EQUAL -
Serde is a generic Rust framework for efficiently serialising &
deserialising Rust data structures to/from other formats (i.e. it is effectively a Document Mapper) -
Rust structs serialised using Serde #[derive(Serialize, Deserialize)] struct Book {
title: Option<String>, author: Option<String>, year: Option<i32>, quantity: Option<i32>, explicit: Option<bool>, } Rust attributes add additional compile time behaviour & meaning to a data structure - here adding the ability for Serde to automate serializating & deserializing its content To/from: • JSON • Avro • YAML • Pickle • BSON (MongoDB’s document format) • ...many others... -
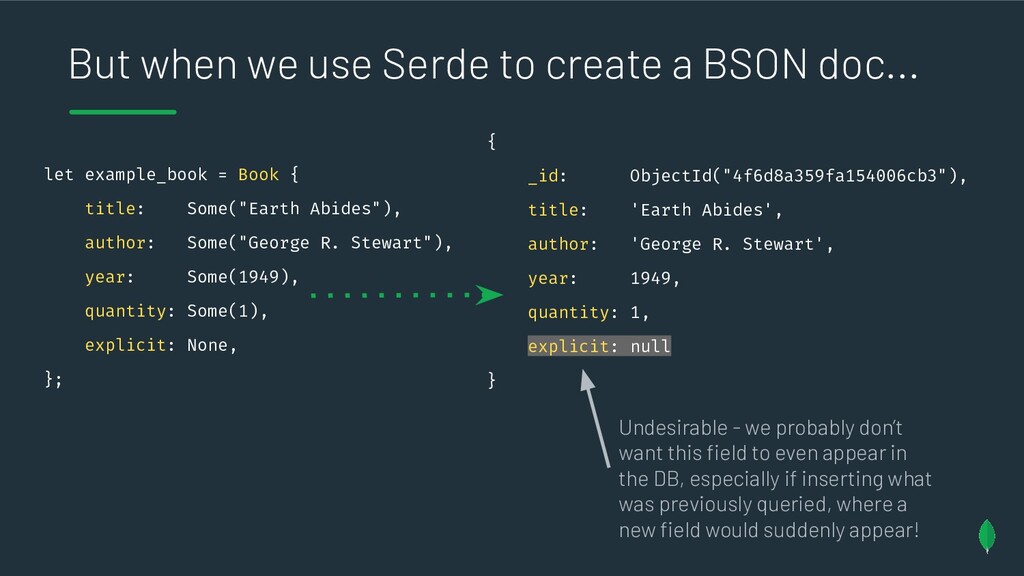
But when we use Serde to create a BSON doc...
let example_book = Book { title: Some("Earth Abides"), author: Some("George R. Stewart"), year: Some(1949), quantity: Some(1), explicit: None, }; { _id: ObjectId("4f6d8a359fa154006cb3"), title: 'Earth Abides', author: 'George R. Stewart', year: 1949, quantity: 1, explicit: null } Undesirable - we probably don’t want this field to even appear in the DB, especially if inserting what was previously queried, where a new field would suddenly appear! -
So we’ve determined that using a Document Mapper is a
problem here? (well actually no we haven’t) -
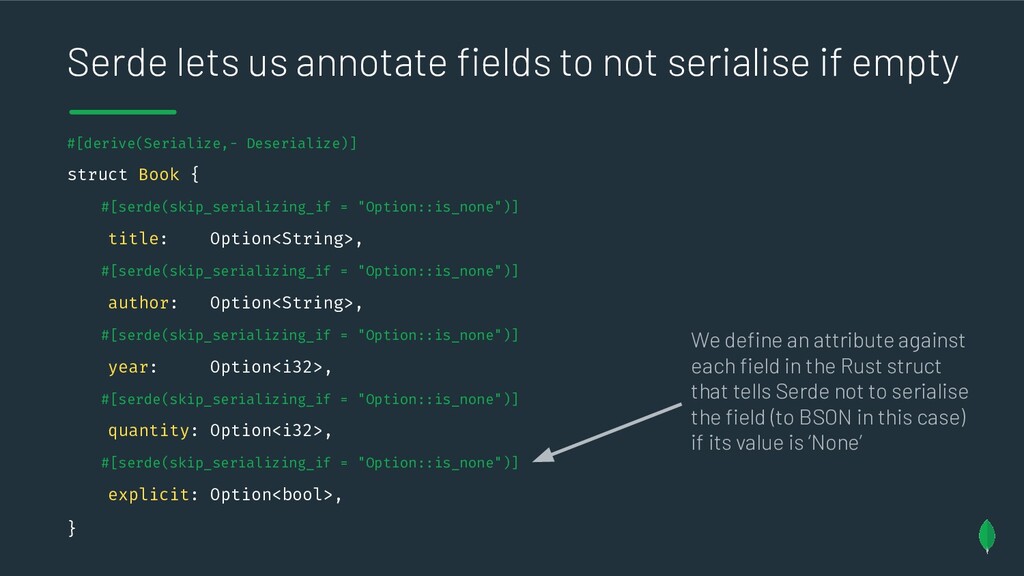
Serde lets us annotate fields to not serialise if empty
#[derive(Serialize,- Deserialize)] struct Book { #[serde(skip_serializing_if = "Option::is_none")] title: Option<String>, #[serde(skip_serializing_if = "Option::is_none")] author: Option<String>, #[serde(skip_serializing_if = "Option::is_none")] year: Option<i32>, #[serde(skip_serializing_if = "Option::is_none")] quantity: Option<i32>, #[serde(skip_serializing_if = "Option::is_none")] explicit: Option<bool>, } We define an attribute against each field in the Rust struct that tells Serde not to serialise the field (to BSON in this case) if its value is ‘None’ -
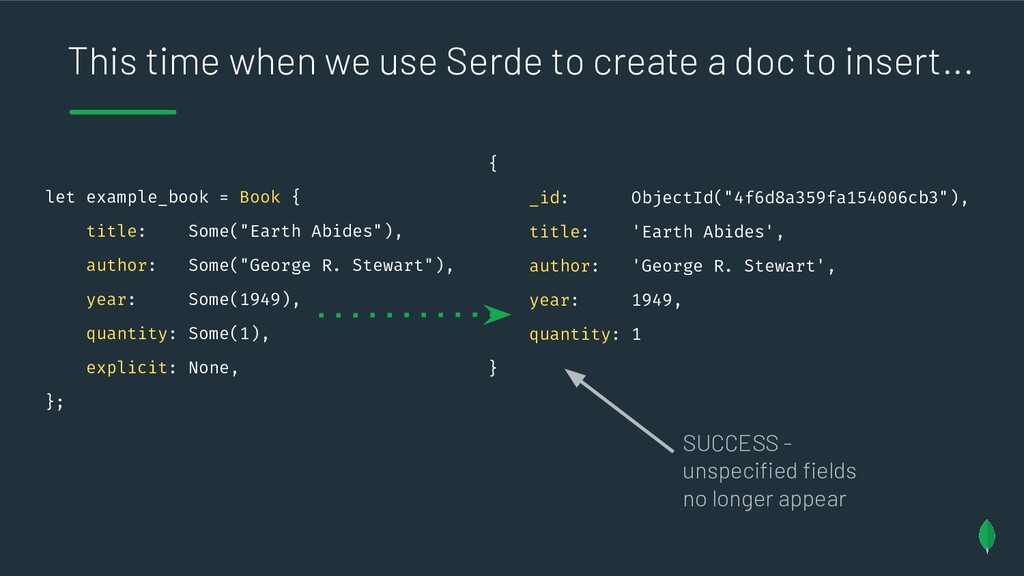
This time when we use Serde to create a doc
to insert... let example_book = Book { title: Some("Earth Abides"), author: Some("George R. Stewart"), year: Some(1949), quantity: Some(1), explicit: None, }; { _id: ObjectId("4f6d8a359fa154006cb3"), title: 'Earth Abides', author: 'George R. Stewart', year: 1949, quantity: 1 } SUCCESS - unspecified fields no longer appear -
However, we should never let a Document Mapper prevent us
from being able to use the power of in-place update operators, when we need them -
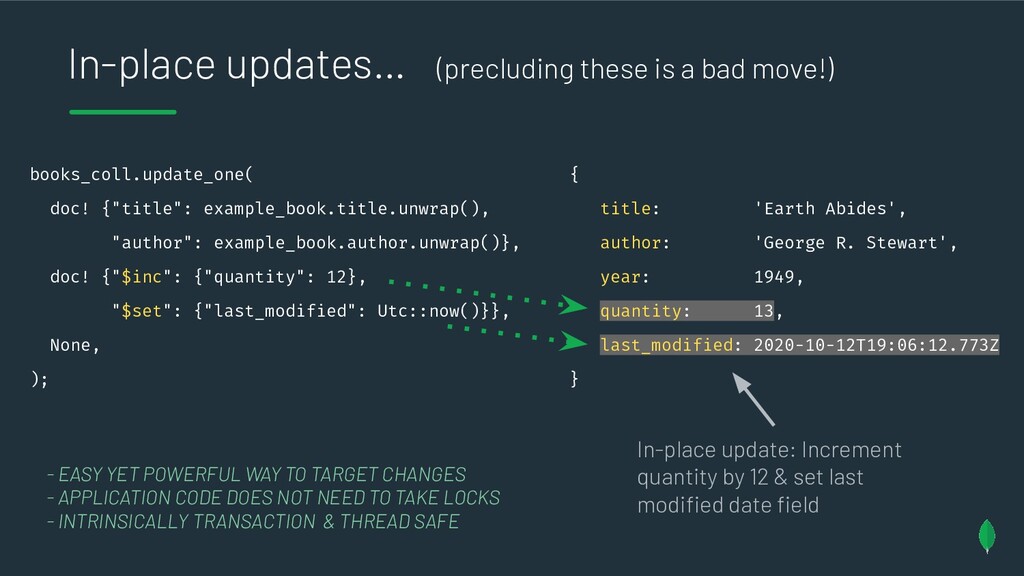
In-place updates… (precluding these is a bad move!) books_coll.update_one( doc!
{"title": example_book.title.unwrap(), "author": example_book.author.unwrap()}, doc! {"$inc": {"quantity": 12}, "$set": {"last_modified": Utc::now()}}, None, ); { title: 'Earth Abides', author: 'George R. Stewart', year: 1949, quantity: 13, last_modified: 2020-10-12T19:06:12.773Z } In-place update: Increment quantity by 12 & set last modified date field - EASY YET POWERFUL WAY TO TARGET CHANGES - APPLICATION CODE DOES NOT NEED TO TAKE LOCKS - INTRINSICALLY TRANSACTION & THREAD SAFE -
Use Document Mappers for Finds & Inserts, by all means,
but never for Updates because you will need the granularity & control to avoid overwriting & losing data written by others -
Resilient Evolvability Principle Only use Document Mappers if they are
NOT ‘all or nothing’ And only if they play nicely with the other five principles -
Resilient Evolvability Principle For Updates, always use in-place operators, changing
targeted fields only Replacing whole documents blows away changes made by other applications -
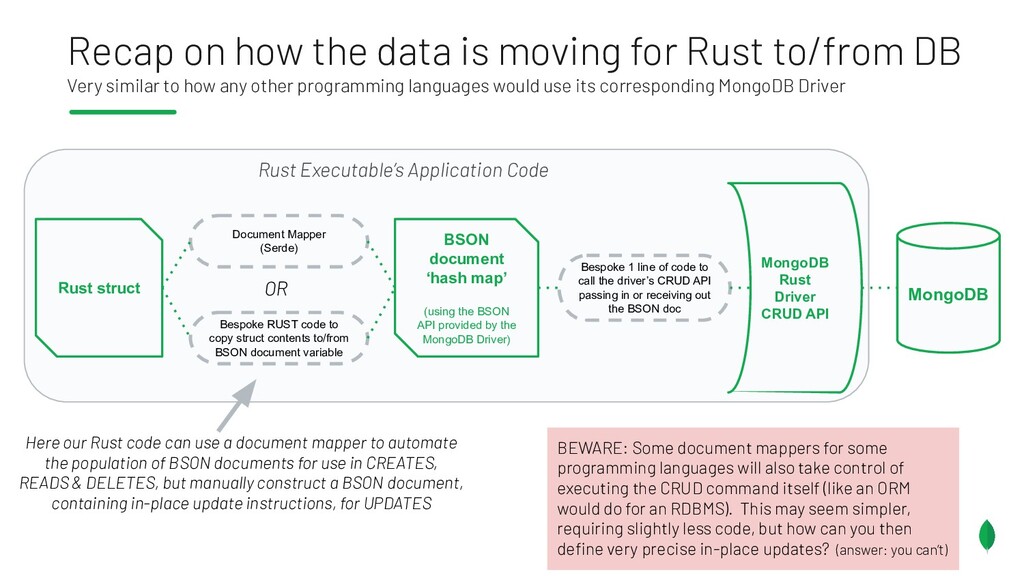
Recap on how the data is moving for Rust to/from
DB Very similar to how any other programming languages would use its corresponding MongoDB Driver MongoDB MongoDB Rust Driver CRUD API BSON document ‘hash map’ (using the BSON API provided by the MongoDB Driver) Bespoke RUST code to copy struct contents to/from BSON document variable Document Mapper (Serde) OR Rust struct Bespoke 1 line of code to call the driver’s CRUD API passing in or receiving out the BSON doc Here our Rust code can use a document mapper to automate the population of BSON documents for use in CREATES, READS & DELETES, but manually construct a BSON document, containing in-place update instructions, for UPDATES Rust Executable’s Application Code BEWARE: Some document mappers for some programming languages will also take control of executing the CRUD command itself (like an ORM would do for an RDBMS). This may seem simpler, requiring slightly less code, but how can you then define very precise in-place updates? (answer: you can’t) -
Right, what if we add a new second component to
meet a new business requirement which needs additions to the data model? -
Our new component will manage 3rd party review scores of
books in the library... -
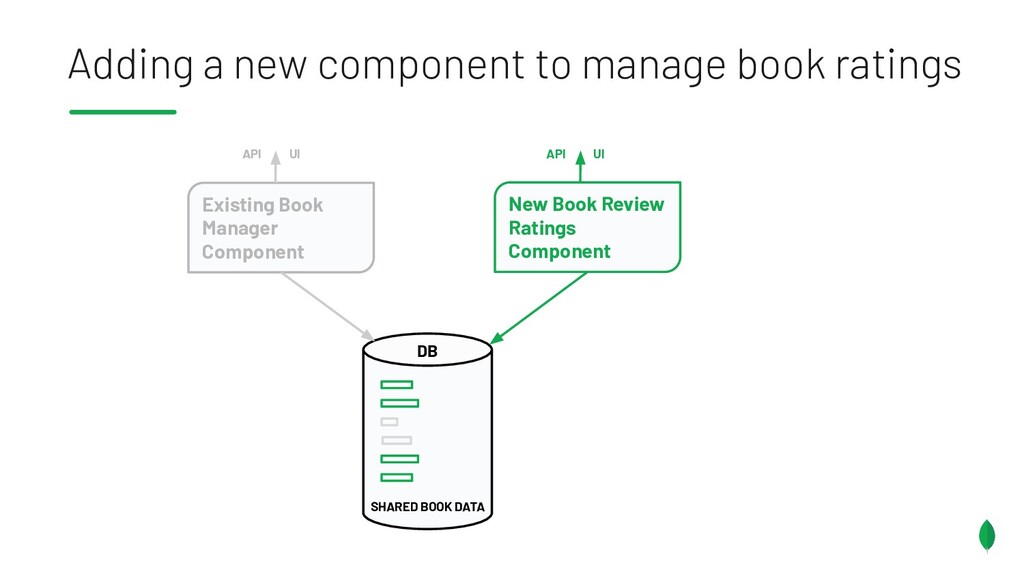
Adding a new component to manage book ratings DB New
Book Review Ratings Component API Existing Book Manager Component API UI UI SHARED BOOK DATA -
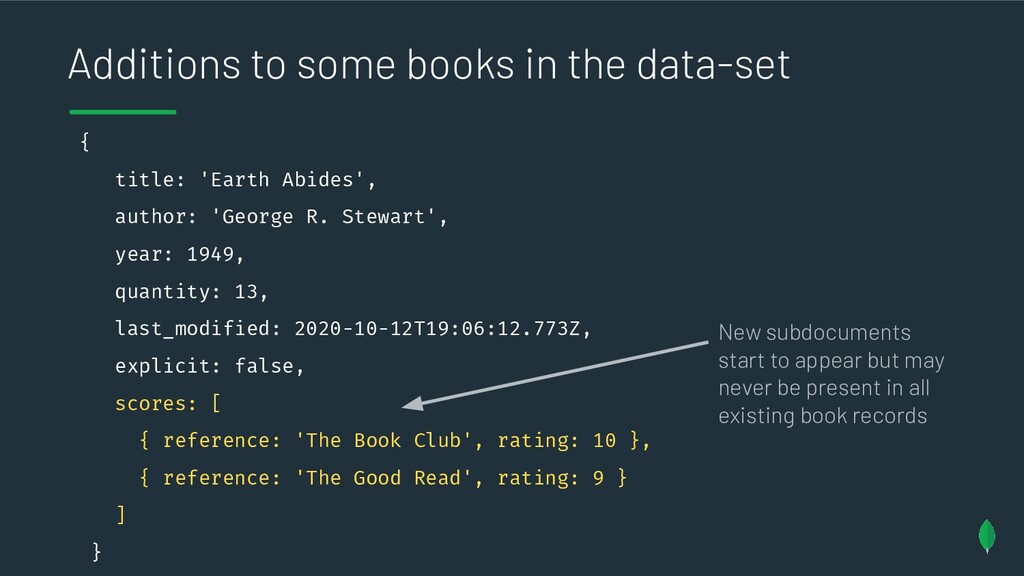
Additions to some books in the data-set { title: 'Earth
Abides', author: 'George R. Stewart', year: 1949, quantity: 13, last_modified: 2020-10-12T19:06:12.773Z, explicit: false, scores: [ { reference: 'The Book Club', rating: 10 }, { reference: 'The Good Read', rating: 9 } ] } New subdocuments start to appear but may never be present in all existing book records -
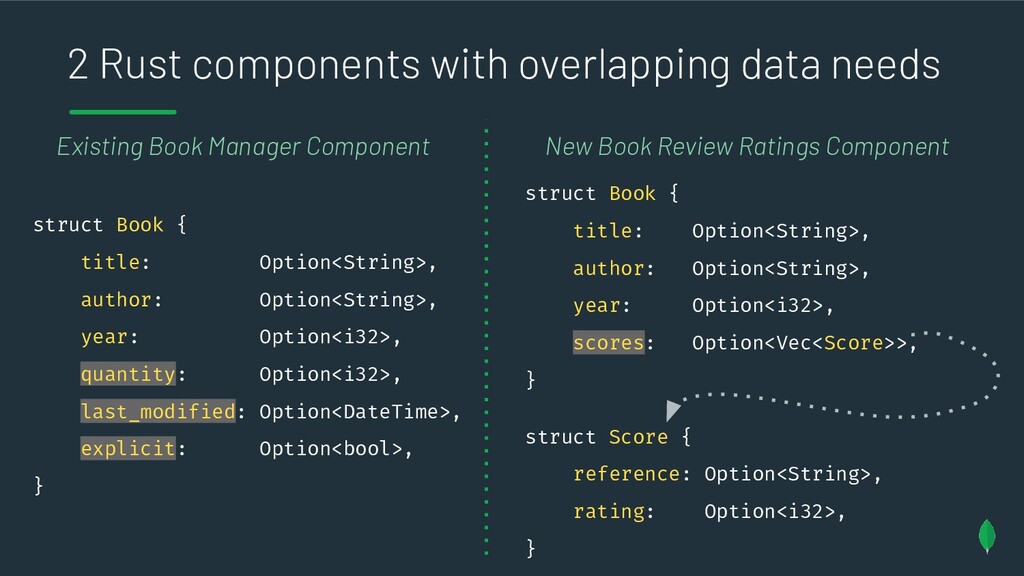
2 Rust components with overlapping data needs struct Book {
title: Option<String>, author: Option<String>, year: Option<i32>, quantity: Option<i32>, last_modified: Option<DateTime>, explicit: Option<bool>, } struct Book { title: Option<String>, author: Option<String>, year: Option<i32>, scores: Option<Vec<Score>>, } struct Score { reference: Option<String>, rating: Option<i32>, } Existing Book Manager Component New Book Review Ratings Component -
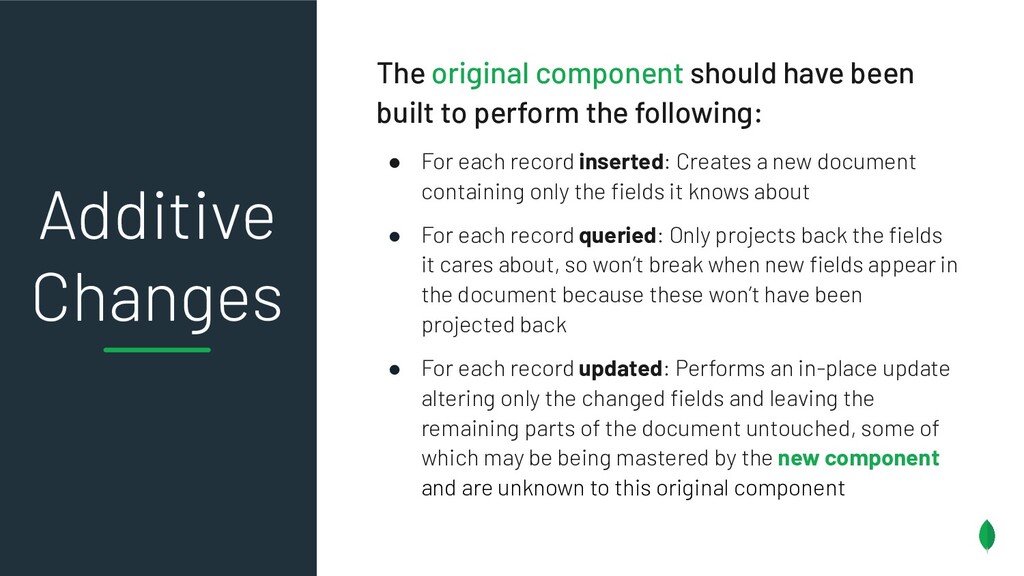
The original component should have been built to perform the
following: • For each record inserted: Creates a new document containing only the fields it knows about • For each record queried: Only projects back the fields it cares about, so won’t break when new fields appear in the document because these won’t have been projected back • For each record updated: Performs an in-place update altering only the changed fields and leaving the remaining parts of the document untouched, some of which may be being mastered by the new component and are unknown to this original component Additive Changes -
So NO changes required to the original component’s code when
the new component and its data model additions are onboarded -
Resilient Evolvability Principle For Finds only ask for fields that
are your concern To support variability & to reduce change dependency -
Ok, what if we need to make a mutative change
to the data model? -
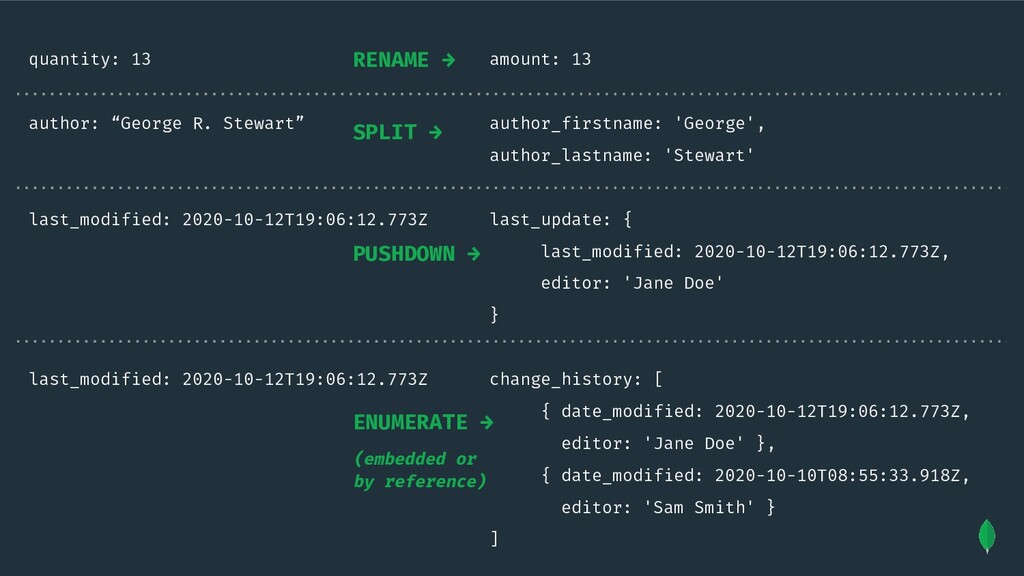
quantity: 13 amount: 13 author: “George R. Stewart” author_firstname: 'George',
author_lastname: 'Stewart' last_modified: 2020-10-12T19:06:12.773Z last_update: { last_modified: 2020-10-12T19:06:12.773Z, editor: 'Jane Doe' } last_modified: 2020-10-12T19:06:12.773Z change_history: [ { date_modified: 2020-10-12T19:06:12.773Z, editor: 'Jane Doe' }, { date_modified: 2020-10-10T08:55:33.918Z, editor: 'Sam Smith' } ] RENAME → PUSHDOWN → ENUMERATE → (embedded or by reference) SPLIT → -
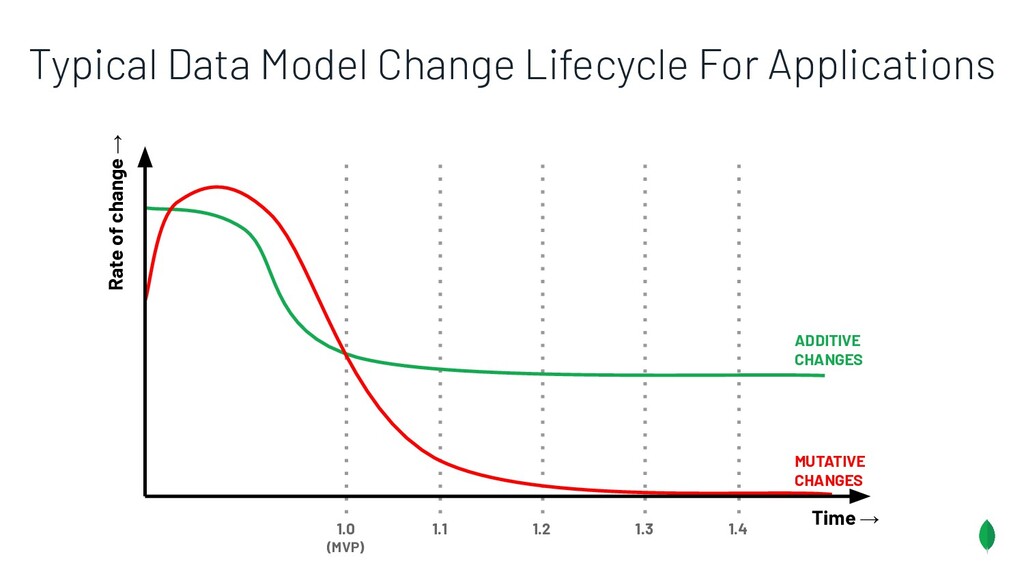
Typical Data Model Change Lifecycle For Applications Time → Rate
of change → 1.0 (MVP) 1.1 1.2 1.3 1.4 ADDITIVE CHANGES MUTATIVE CHANGES -
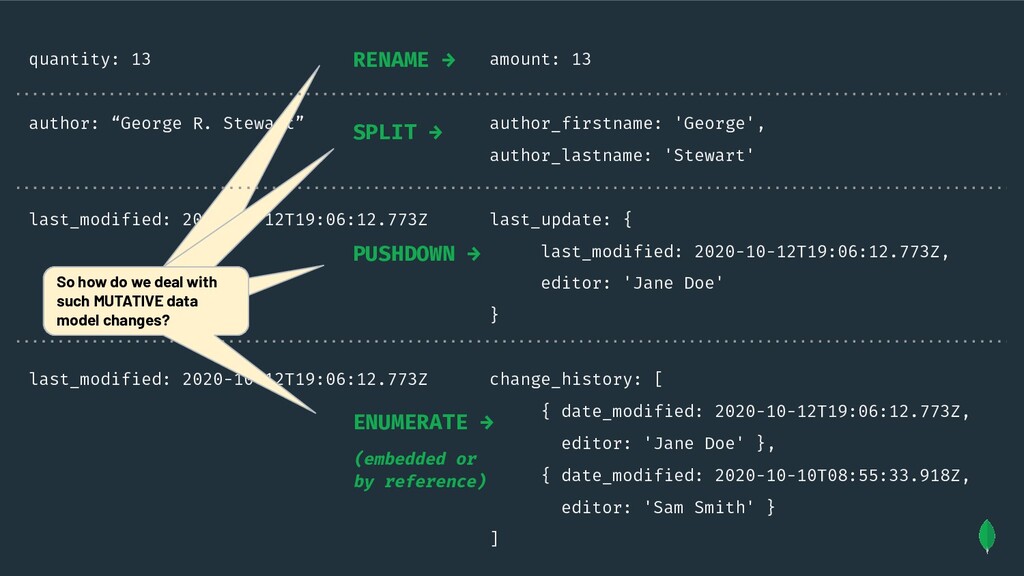
quantity: 13 amount: 13 author: “George R. Stewart” author_firstname: 'George',
author_lastname: 'Stewart' last_modified: 2020-10-12T19:06:12.773Z last_update: { last_modified: 2020-10-12T19:06:12.773Z, editor: 'Jane Doe' } last_modified: 2020-10-12T19:06:12.773Z change_history: [ { date_modified: 2020-10-12T19:06:12.773Z, editor: 'Jane Doe' }, { date_modified: 2020-10-10T08:55:33.918Z, editor: 'Sam Smith' } ] RENAME → PUSHDOWN → ENUMERATE → (embedded or by reference) SPLIT → So how do we deal with such MUTATIVE data model changes? -
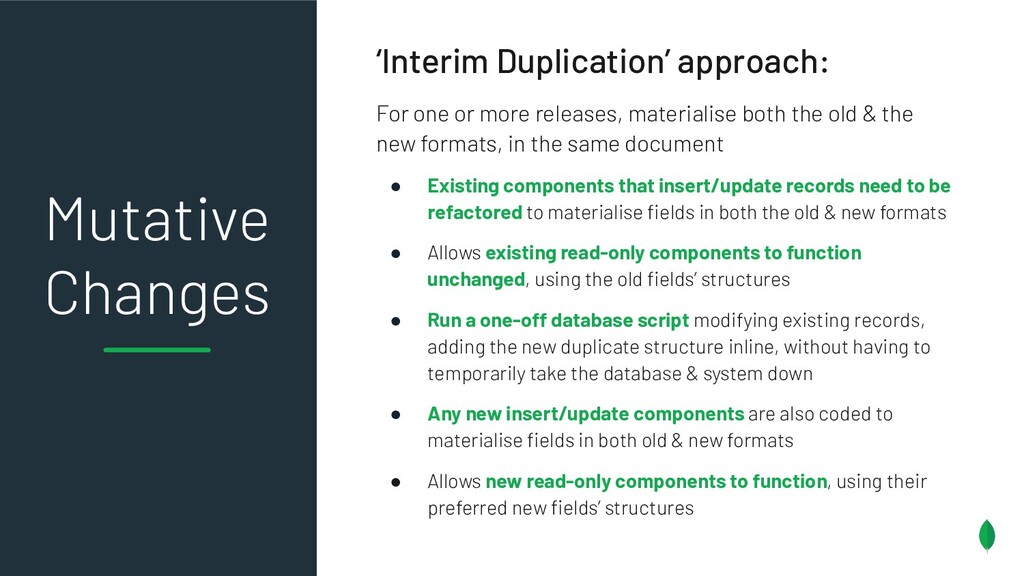
‘Interim Duplication’ approach: For one or more releases, materialise both
the old & the new formats, in the same document • Existing components that insert/update records need to be refactored to materialise fields in both the old & new formats • Allows existing read-only components to function unchanged, using the old fields’ structures • Run a one-off database script modifying existing records, adding the new duplicate structure inline, without having to temporarily take the database & system down • Any new insert/update components are also coded to materialise fields in both old & new formats • Allows new read-only components to function, using their preferred new fields’ structures Mutative Changes -
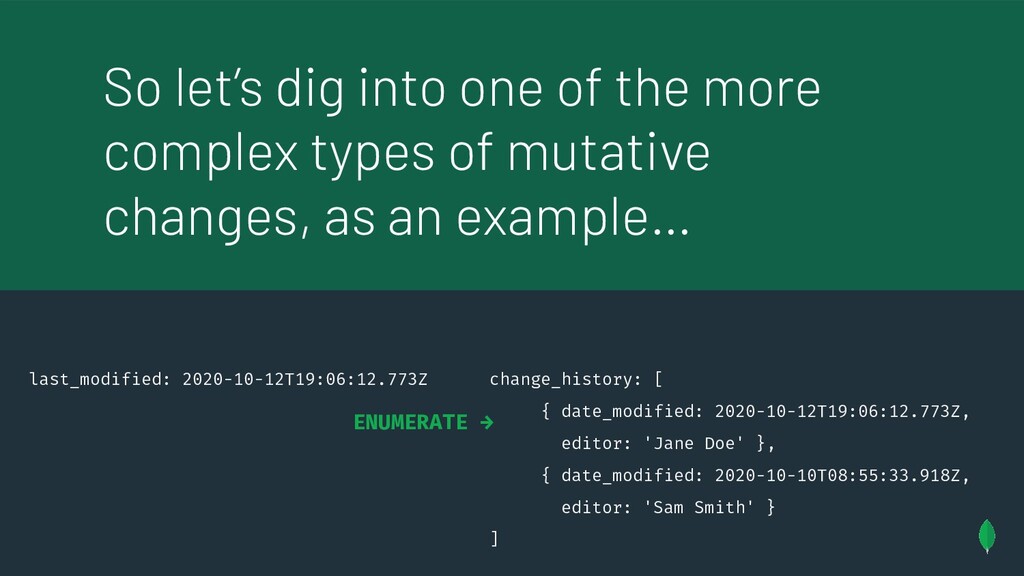
last_modified: 2020-10-12T19:06:12.773Z change_history: [ { date_modified: 2020-10-12T19:06:12.773Z, editor: 'Jane Doe'
}, { date_modified: 2020-10-10T08:55:33.918Z, editor: 'Sam Smith' } ] ENUMERATE → So let’s dig into one of the more complex types of mutative changes, as an example… -
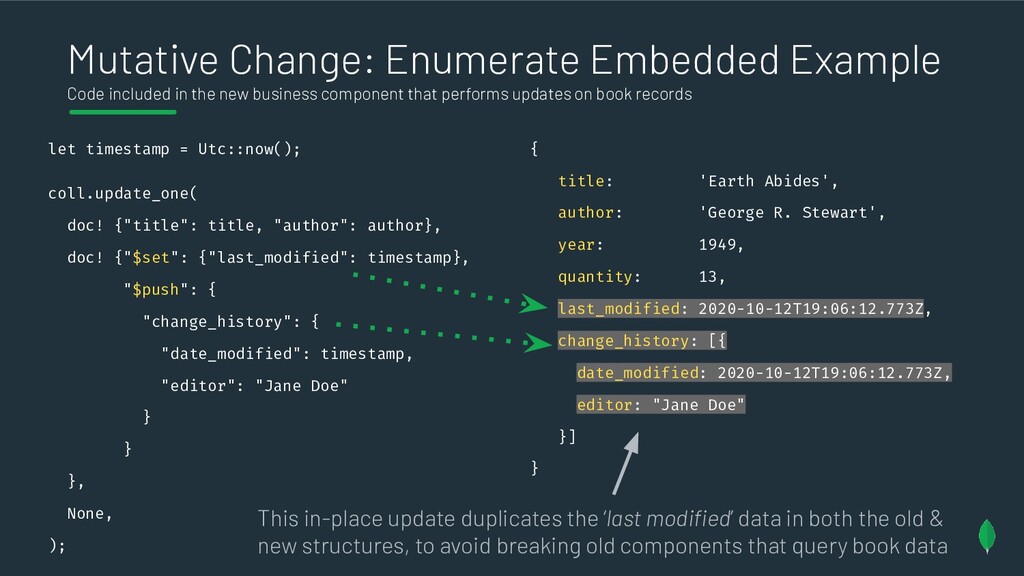
Mutative Change: Enumerate Embedded Example Code included in the new
business component that performs updates on book records let timestamp = Utc::now(); coll.update_one( doc! {"title": title, "author": author}, doc! {"$set": {"last_modified": timestamp}, "$push": { "change_history": { "date_modified": timestamp, "editor": "Jane Doe" } } }, None, ); { title: 'Earth Abides', author: 'George R. Stewart', year: 1949, quantity: 13, last_modified: 2020-10-12T19:06:12.773Z, change_history: [{ date_modified: 2020-10-12T19:06:12.773Z, editor: "Jane Doe" }] } This in-place update duplicates the ‘last modified’ data in both the old & new structures, to avoid breaking old components that query book data -
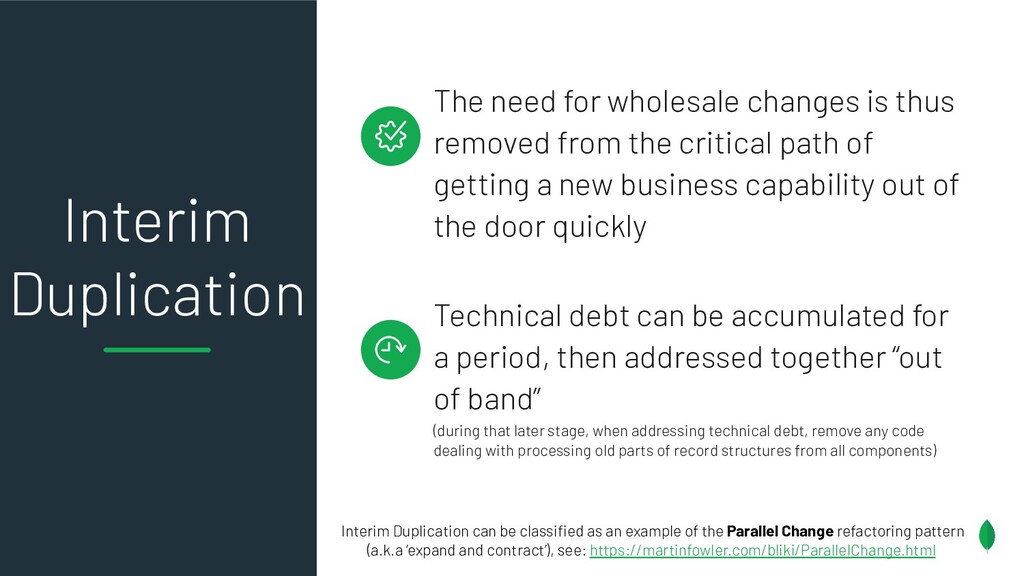
The need for wholesale changes is thus removed from the
critical path of getting a new business capability out of the door quickly Technical debt can be accumulated for a period, then addressed together “out of band” (during that later stage, when addressing technical debt, remove any code dealing with processing old parts of record structures from all components) Interim Duplication Interim Duplication can be classified as an example of the Parallel Change refactoring pattern (a.k.a ‘expand and contract’), see: https://martinfowler.com/bliki/ParallelChange.html -
So by using the ‘Interim Duplication’ approach we reduce the
blast radius of the rarer mutative change occurrences (i.e. a few existing components, but not all, need to change) -
Resilient Evolvability Principle For the rare data model Mutative Changes,
adopt ‘Interim Duplication’ To reduce delaying high priority business requirements -
What about dealing with entity variance in the moment? In
the real world, entities can vary & at times be treated similarly & at other times be used differently -
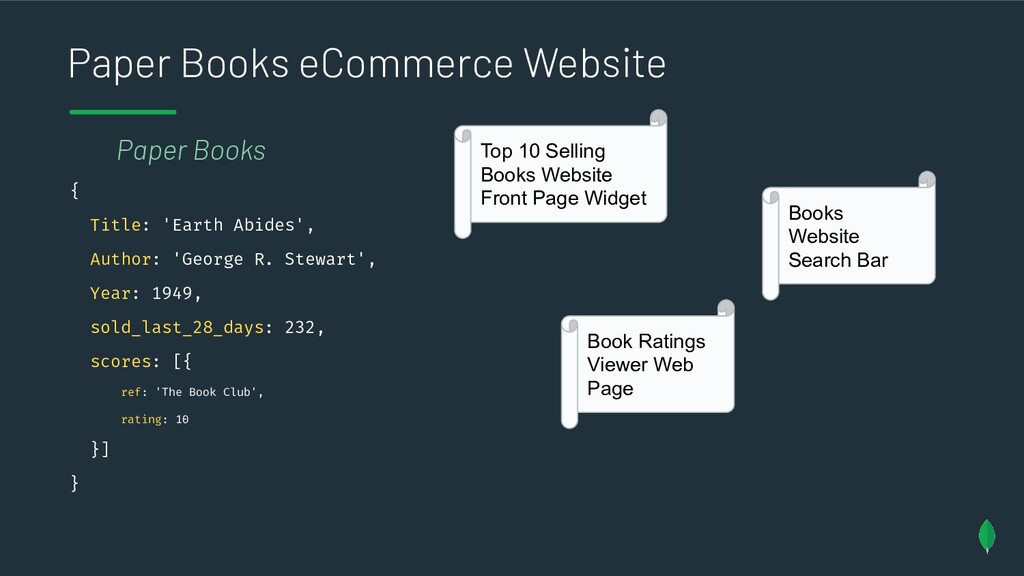
Paper Books eCommerce Website { Title: 'Earth Abides', Author: 'George
R. Stewart', Year: 1949, sold_last_28_days: 232, scores: [{ ref: 'The Book Club', rating: 10 }] } Top 10 Selling Books Website Front Page Widget Books Website Search Bar Book Ratings Viewer Web Page Paper Books -
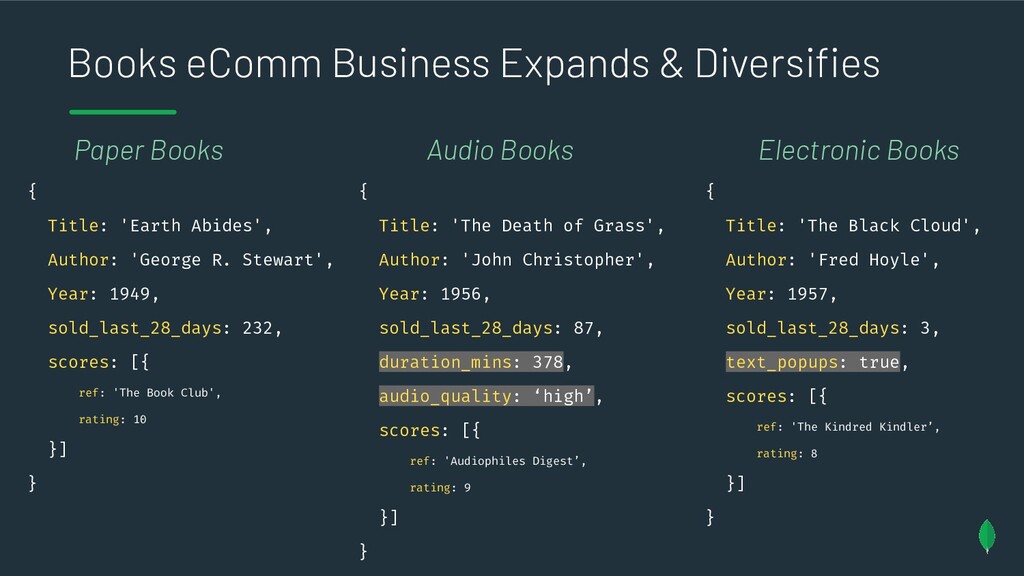
Books eComm Business Expands & Diversifies Paper Books Audio Books
{ Title: 'Earth Abides', Author: 'George R. Stewart', Year: 1949, sold_last_28_days: 232, scores: [{ ref: 'The Book Club', rating: 10 }] } { Title: 'The Death of Grass', Author: 'John Christopher', Year: 1956, sold_last_28_days: 87, duration_mins: 378, audio_quality: ‘high’, scores: [{ ref: 'Audiophiles Digest’, rating: 9 }] } Electronic Books { Title: 'The Black Cloud', Author: 'Fred Hoyle', Year: 1957, sold_last_28_days: 3, text_popups: true, scores: [{ ref: 'The Kindred Kindler’, rating: 8 }] } -
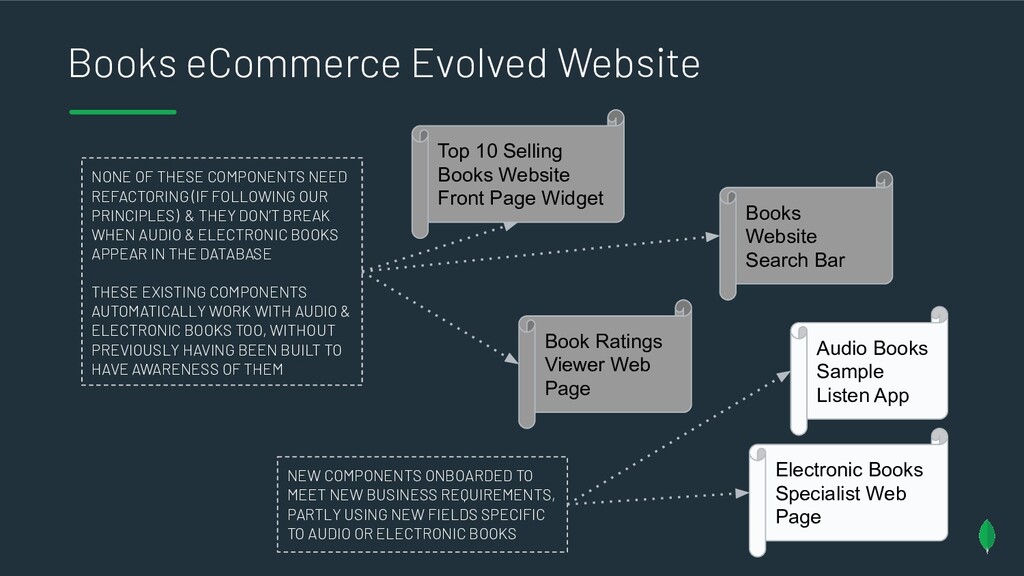
Books eCommerce Evolved Website Top 10 Selling Books Website Front
Page Widget Books Website Search Bar Book Ratings Viewer Web Page NONE OF THESE COMPONENTS NEED REFACTORING (IF FOLLOWING OUR PRINCIPLES) & THEY DON’T BREAK WHEN AUDIO & ELECTRONIC BOOKS APPEAR IN THE DATABASE THESE EXISTING COMPONENTS AUTOMATICALLY WORK WITH AUDIO & ELECTRONIC BOOKS TOO, WITHOUT PREVIOUSLY HAVING BEEN BUILT TO HAVE AWARENESS OF THEM Electronic Books Specialist Web Page Audio Books Sample Listen App NEW COMPONENTS ONBOARDED TO MEET NEW BUSINESS REQUIREMENTS, PARTLY USING NEW FIELDS SPECIFIC TO AUDIO OR ELECTRONIC BOOKS -
So we’ve built components that aren’t brittle and don’t break
when things appear that don’t concern them! -
Resilient Evolvability Principle Facilitate entity variance Because real world entities
do vary, especially when a business evolves & diversifies -
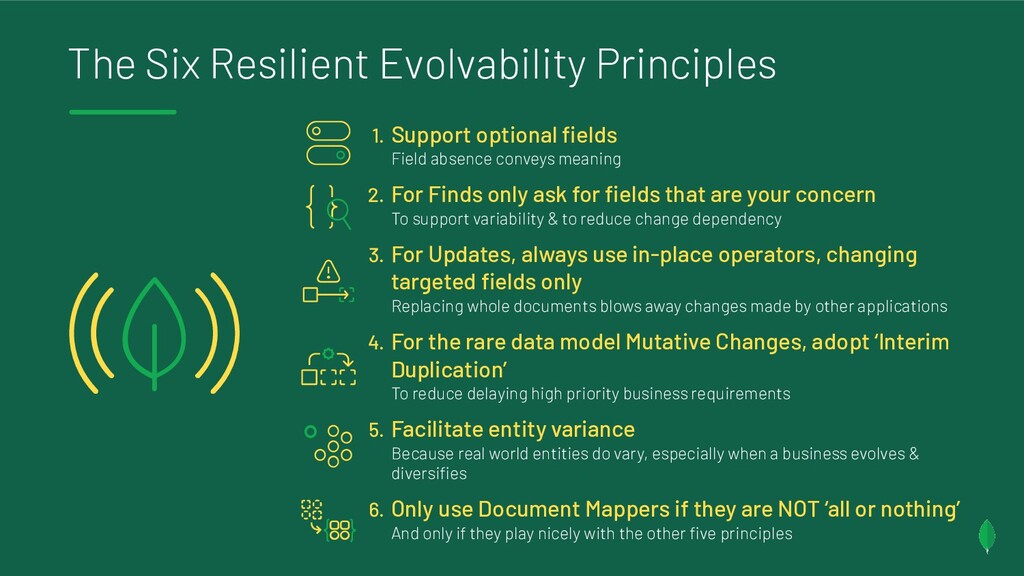
The Six Resilient Evolvability Principles 1. Support optional fields Field
absence conveys meaning 2. For Finds only ask for fields that are your concern To support variability & to reduce change dependency 3. For Updates, always use in-place operators, changing targeted fields only Replacing whole documents blows away changes made by other applications 4. For the rare data model Mutative Changes, adopt ‘Interim Duplication’ To reduce delaying high priority business requirements 5. Facilitate entity variance Because real world entities do vary, especially when a business evolves & diversifies 6. Only use Document Mappers if they are NOT ‘all or nothing’ And only if they play nicely with the other five principles -
Your software will enable varying structured data which embraces, rather
than inhibits, real world requirements Your software won’t break when additive data model changes occur, to rapidly meet new business requirements You will have a process to deal with mutative data model changes, which reduces delays in delivering new business requirements By adopting these principles... -
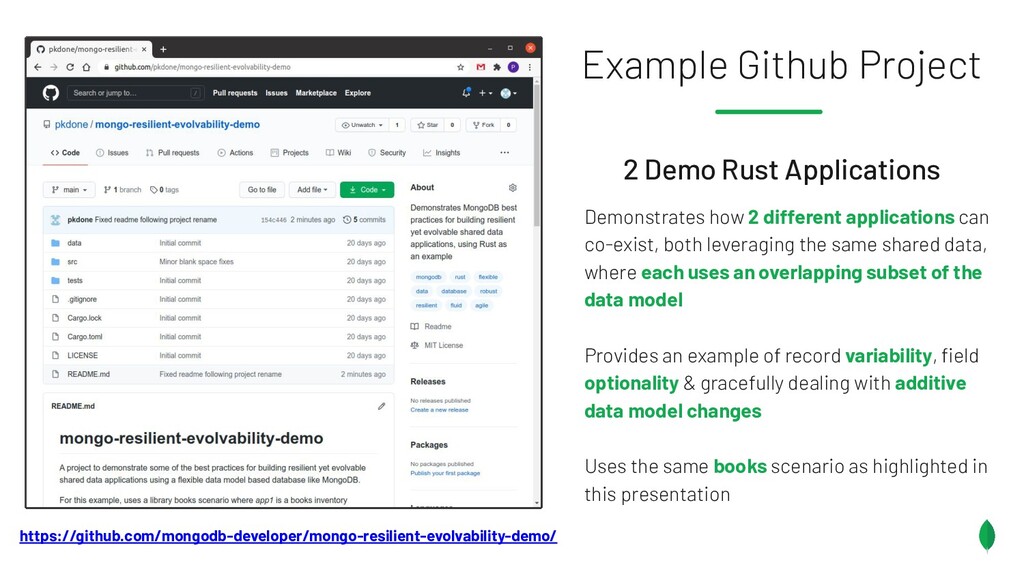
2 Demo Rust Applications Demonstrates how 2 different applications can
co-exist, both leveraging the same shared data, where each uses an overlapping subset of the data model Provides an example of record variability, field optionality & gracefully dealing with additive data model changes Uses the same books scenario as highlighted in this presentation Example Github Project https://github.com/mongodb-developer/mongo-resilient-evolvability-demo/ -
That’s all folks Three people I’d like to thank for
their great feedback & suggested improvements: ‐ Jake McInteer: @jake_144 ‐ Jay Runkel: @jayrunkel ‐ Mark Smith: @Judy2k Paul Done @TheDonester
 pdone
 kamina_zzz
 mktakuya
 hiroaki404
 simas
 yyh_gl
 kinakomoti321
 richargh
 t0yohei
 naruogram
 fuqda
 nasa9084
 katiecoart
 aarron
 pwiseman
 jonoalderson
 scottboms
 codingconduct
 katarinadahlin
 vanstee
 tonyrice
 aki_iinuma
 joshbly
 marketingsoph