Tornado web server internals
Sponsored
·
 SiteGround - Reliable hosting with speed, security, and support you can count on.
→
SiteGround - Reliable hosting with speed, security, and support you can count on.
→

Share
Embed
Tornado web server internals

Praveen Gollakota
August 09, 2012
Transcript
56 slides
-
Tornado Web Server Internals Praveen Gollakota @pgollakota http://shutupandship.com A stroll
into (and out of) the eye of the tornado -
Agenda • Tornado at a glance • Sockets background •
I/O monitoring - select, poll, epoll • Tornado server setup loop • Tornado request - response loop • Tornado vs. Apache -
Tornado • Tornado - a scalable, non-blocking web server. •
Also a minimal Web Application Framework. Written in Python. Open source - Apache V2.0 license. • Originally built by FriendFeed (acquired by Facebook). "The framework is distinct from most mainstream web server frameworks (and certainly most Python frameworks) because it is non- blocking and reasonably fast. Because it is non-blocking and uses epoll or kqueue, it can handle thousands of simultaneous standing connections, which means it is ideal for real-time web services." - Tornado Web Server Home page blurb. -
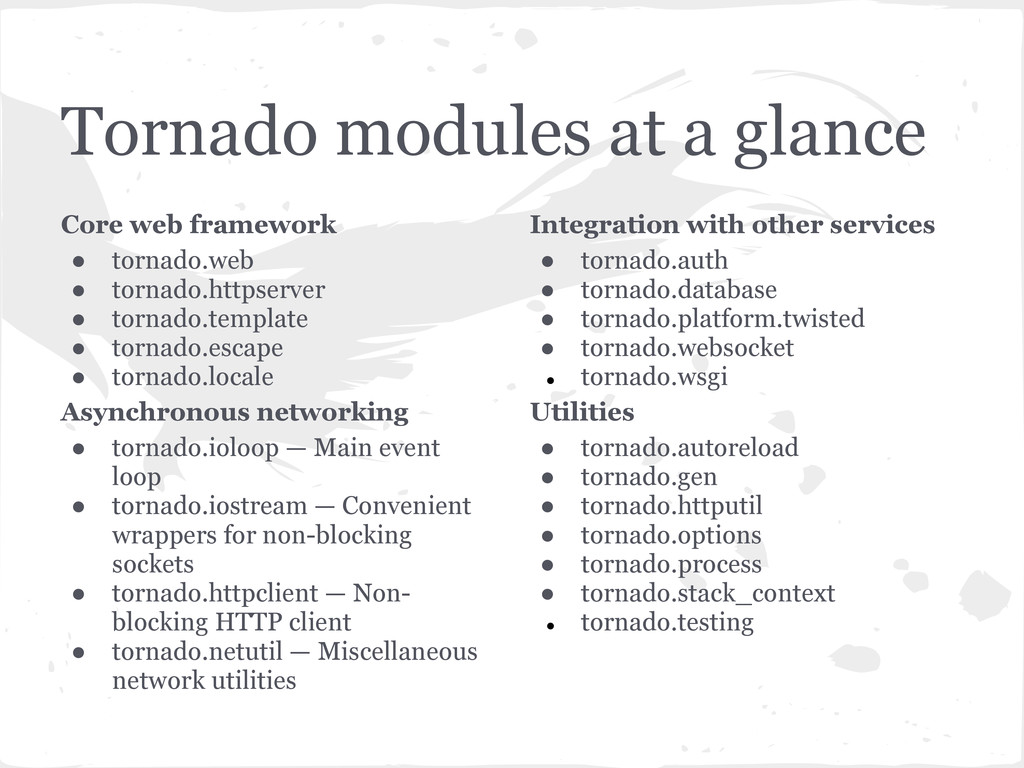
Tornado modules at a glance Integration with other services •
tornado.auth • tornado.database • tornado.platform.twisted • tornado.websocket • tornado.wsgi Utilities • tornado.autoreload • tornado.gen • tornado.httputil • tornado.options • tornado.process • tornado.stack_context • tornado.testing Core web framework • tornado.web • tornado.httpserver • tornado.template • tornado.escape • tornado.locale Asynchronous networking • tornado.ioloop — Main event loop • tornado.iostream — Convenient wrappers for non-blocking sockets • tornado.httpclient — Non- blocking HTTP client • tornado.netutil — Miscellaneous network utilities -
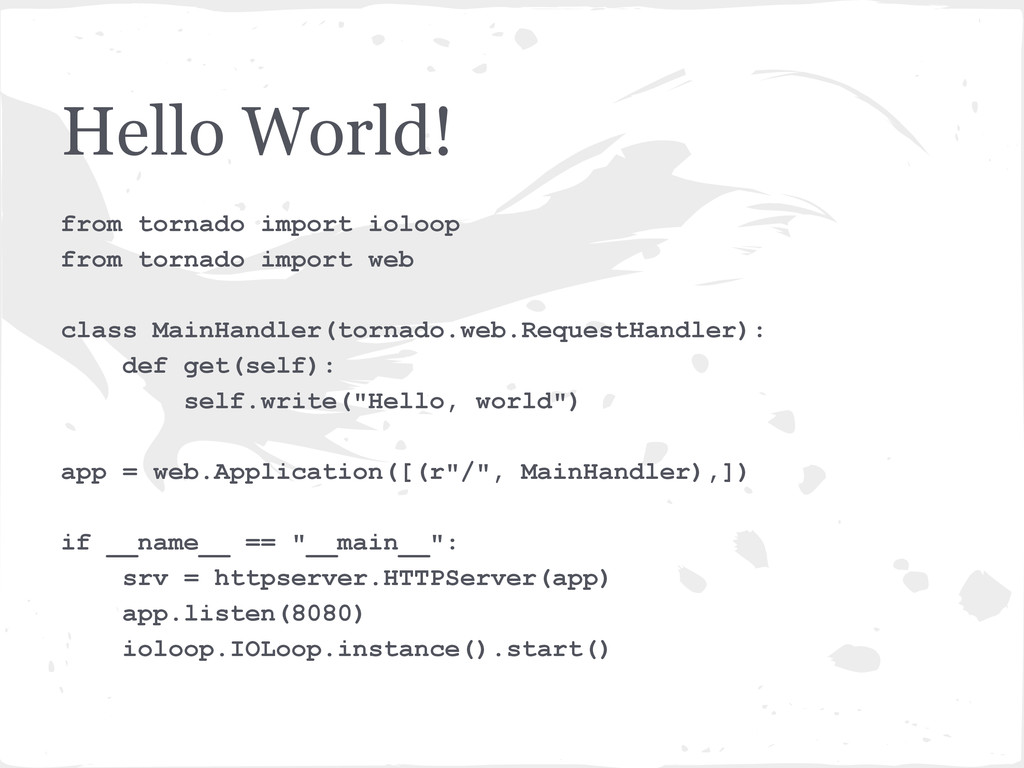
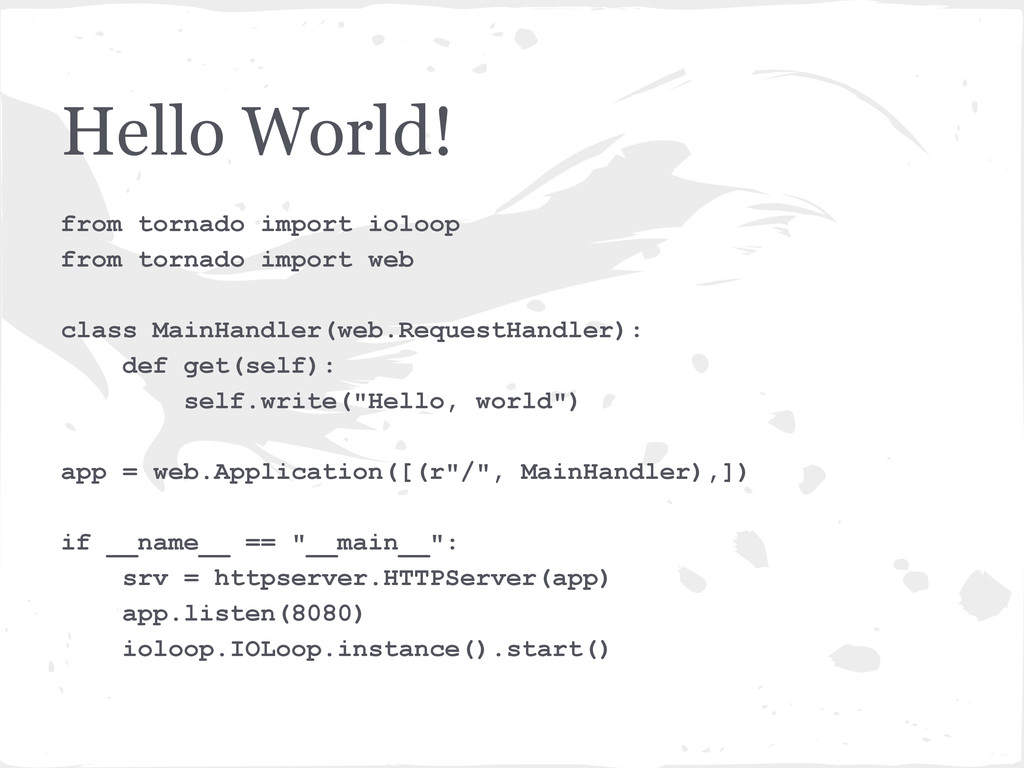
Hello World! from tornado import ioloop from tornado import web
class MainHandler(tornado.web.RequestHandler): def get(self): self.write("Hello, world") app = web.Application([(r"/", MainHandler),]) if __name__ == "__main__": srv = httpserver.HTTPServer(app) app.listen(8080) ioloop.IOLoop.instance().start() -
Our Mission • Analyze "Hello World" application and figure out
what happens at every step of the way. All the way from how the server is setup to how the entire request-response cycle works under the hood. • But first a little bit of background about sockets and poll. -
Sockets • Network protocols are handled through a programming abstraction
known as sockets. Socket is an object similar to a file that allows a program to accept incoming connection, make outgoing connections, and send and receive data. Before two machines can communicate, both must create a socket object. The Python implementation just calls the system sockets API. • For more info $ man socket -
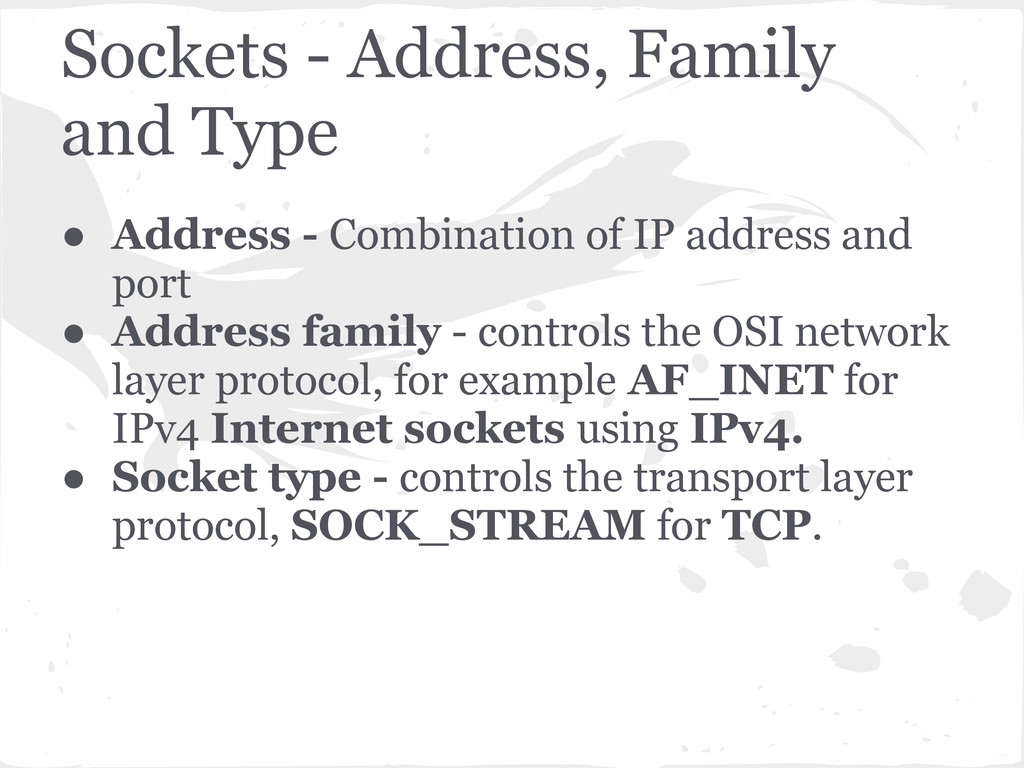
Sockets - Address, Family and Type • Address - Combination
of IP address and port • Address family - controls the OSI network layer protocol, for example AF_INET for IPv4 Internet sockets using IPv4. • Socket type - controls the transport layer protocol, SOCK_STREAM for TCP. -
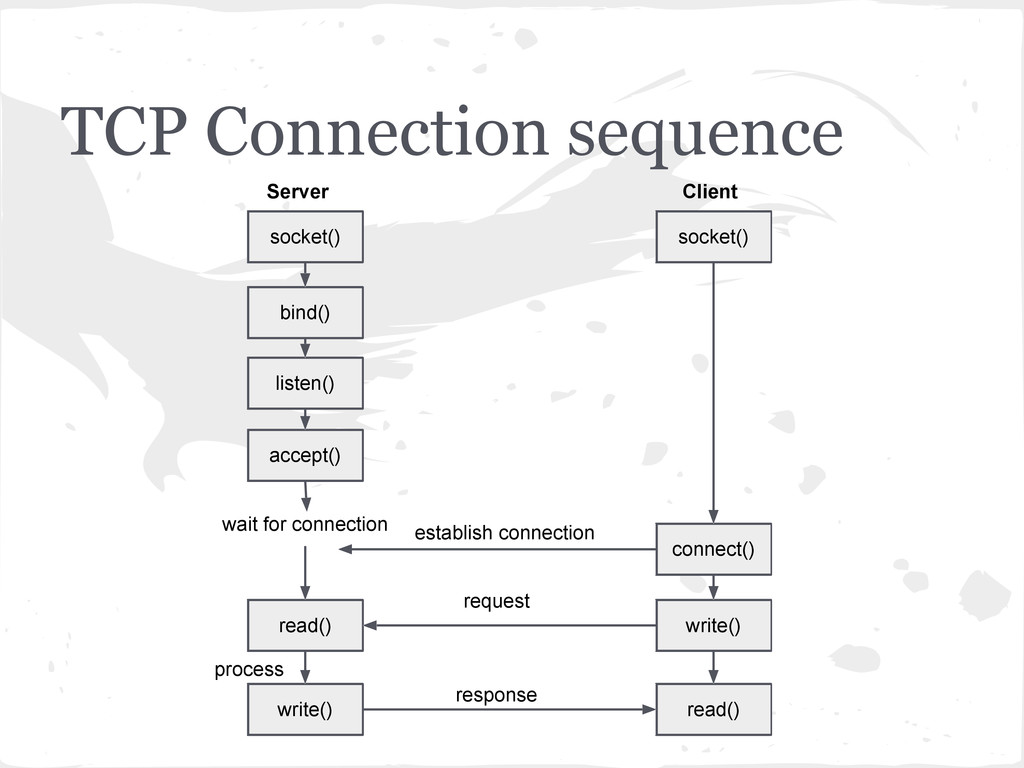
TCP Connection sequence socket() bind() listen() accept() read() write() socket()
connect() write() read() wait for connection establish connection Server Client process response request -
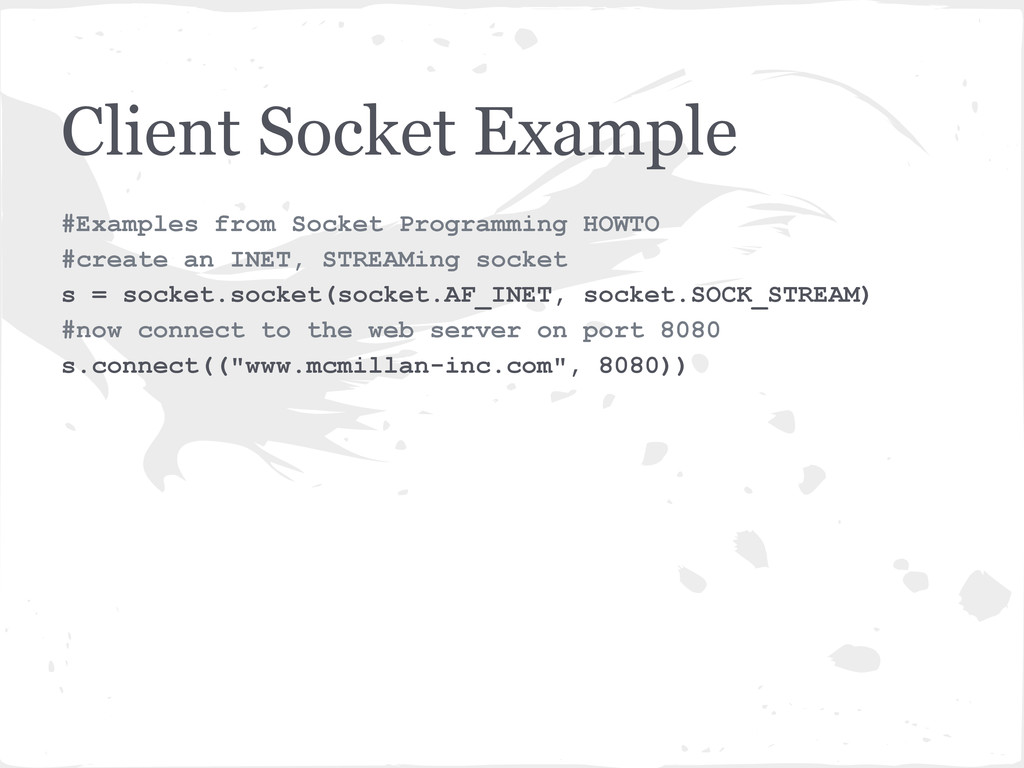
Client Socket Example #Examples from Socket Programming HOWTO #create an
INET, STREAMing socket s = socket.socket(socket.AF_INET, socket.SOCK_STREAM) #now connect to the web server on port 8080 s.connect(("www.mcmillan-inc.com", 8080)) -
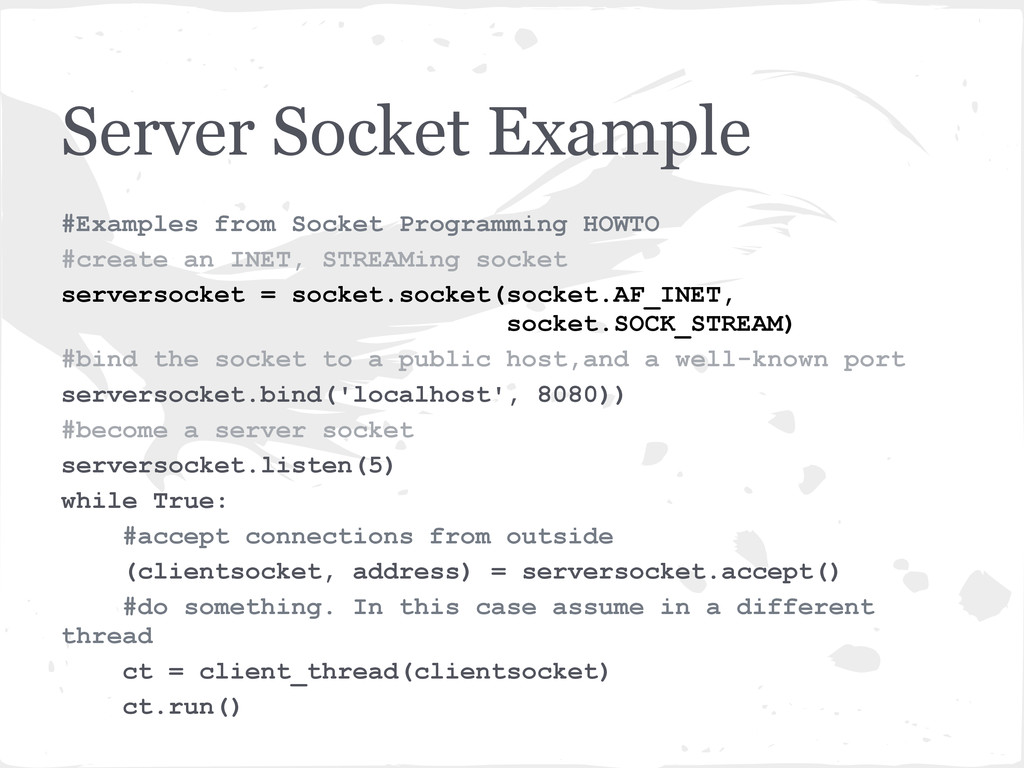
Server Socket Example #Examples from Socket Programming HOWTO #create an
INET, STREAMing socket serversocket = socket.socket(socket.AF_INET, socket.SOCK_STREAM) #bind the socket to a public host,and a well-known port serversocket.bind('localhost', 8080)) #become a server socket serversocket.listen(5) while True: #accept connections from outside (clientsocket, address) = serversocket.accept() #do something. In this case assume in a different thread ct = client_thread(clientsocket) ct.run() -
Server Socket explained “server socket ... doesn’t send any data.
It doesn’t receive any data. It just produces client sockets. Each client socket is created in response to some other client socket doing a connect() to the host and port we’re bound to. As soon as we’ve created that client socket, we go back to listening for more connections. The two clients are free to chat it up - they are using some dynamically allocated port which will be recycled when the conversation ends.” - Gordon McMillan in Socket Programming HOWTO -
Server Socket Loop Three options - • dispatch a thread
to handle client socket • create a new process to handle client socket • Use non-blocking sockets, and mulitplex between our server socket and any active client sockets using select. -
Sockets - Blocking vs. Non- blocking • Blocking sockets -
socket API calls will block indefinitely until the requested action (send, recv, connect or accept) has been performed. • Non-blocking sockets - send, recv, connect and accept can return immediately without having done anything. • In Python, you can use socket. setblocking(0) to make a socket non- blocking. -
Handling non-blocking sockets “You have (of course) a number of
choices. You can check return code and error codes and generally drive yourself crazy. If you don’t believe me, try it sometime. Your app will grow large, buggy and suck CPU. So let’ s skip the brain-dead solutions and do it right. … Use select.” Gordon McMillan - Author of Socket Programming HOWTO & creator of PyInstaller -
References • Socket Programming HOWTO by Gordon McMillan • Python
Module of the Week (PyMOTW) - Socket by Doug Hellmann • Python Essential Reference by David Beazley -
select • A system call - allows a program to
monitor multiple file descriptors, waiting until one or more of the file descriptors become "ready" for some class of I/O operation • More info $ man select • Python’s select() function is a direct interface to the underlying operating system implementation. -
poll • poll() scales better than select(). • poll() -
only requires listing the file descriptors of interest, while select() builds a bitmap, turns on bits for the fds of interest, and then afterward the whole bitmap has to be linearly scanned again. • select() is O(highest file descriptor), while poll() is O(number of file descriptors). -
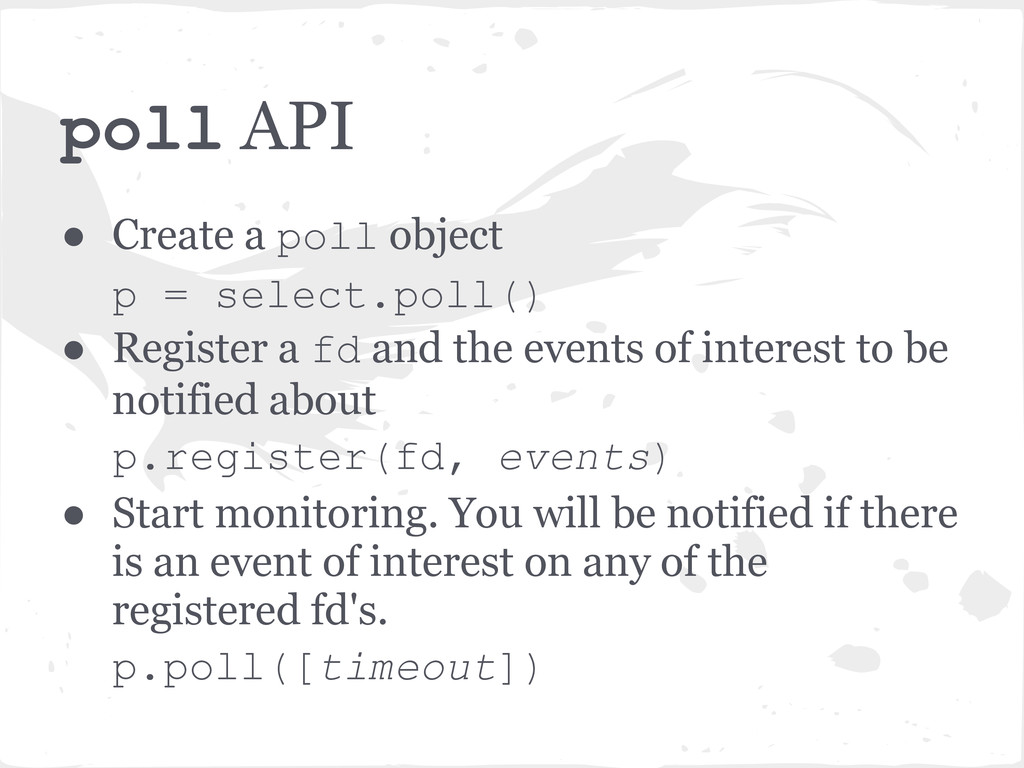
poll API • Create a poll object p = select.poll()
• Register a fd and the events of interest to be notified about p.register(fd, events) • Start monitoring. You will be notified if there is an event of interest on any of the registered fd's. p.poll([timeout]) -
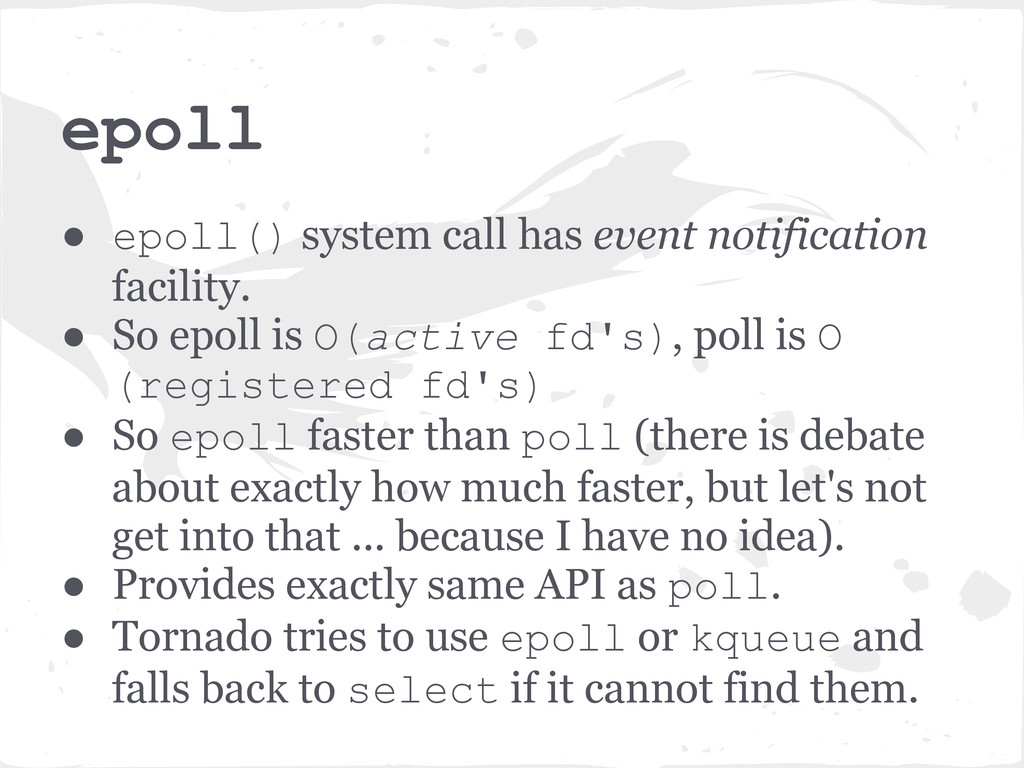
epoll • epoll() system call has event notification facility. •
So epoll is O(active fd's), poll is O (registered fd's) • So epoll faster than poll (there is debate about exactly how much faster, but let's not get into that ... because I have no idea). • Provides exactly same API as poll. • Tornado tries to use epoll or kqueue and falls back to select if it cannot find them. -
References • Python Module of the Week (PyMOTW) - select
by Doug Hellmann • The C10K problem by Dan Kegel • poll, epoll, science, superpoll by Zed Shaw -
Hello World! from tornado import ioloop from tornado import web
class MainHandler(web.RequestHandler): def get(self): self.write("Hello, world") app = web.Application([(r"/", MainHandler),]) if __name__ == "__main__": srv = httpserver.HTTPServer(app) app.listen(8080) ioloop.IOLoop.instance().start() -
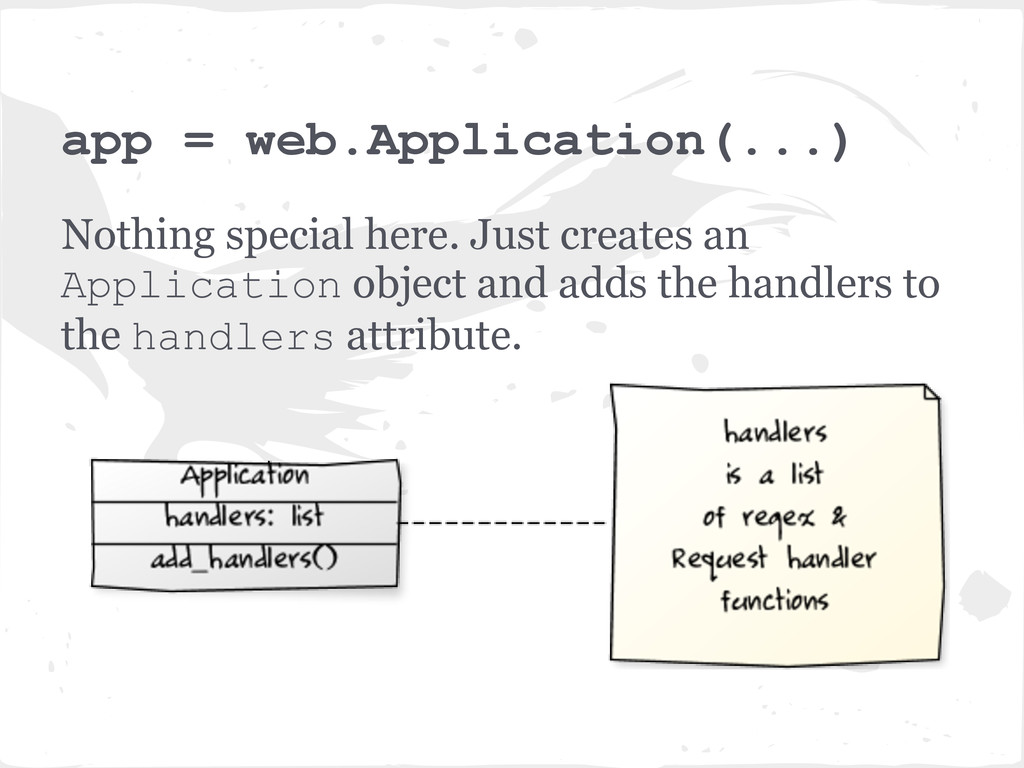
app = web.Application(...) Nothing special here. Just creates an Application
object and adds the handlers to the handlers attribute. -
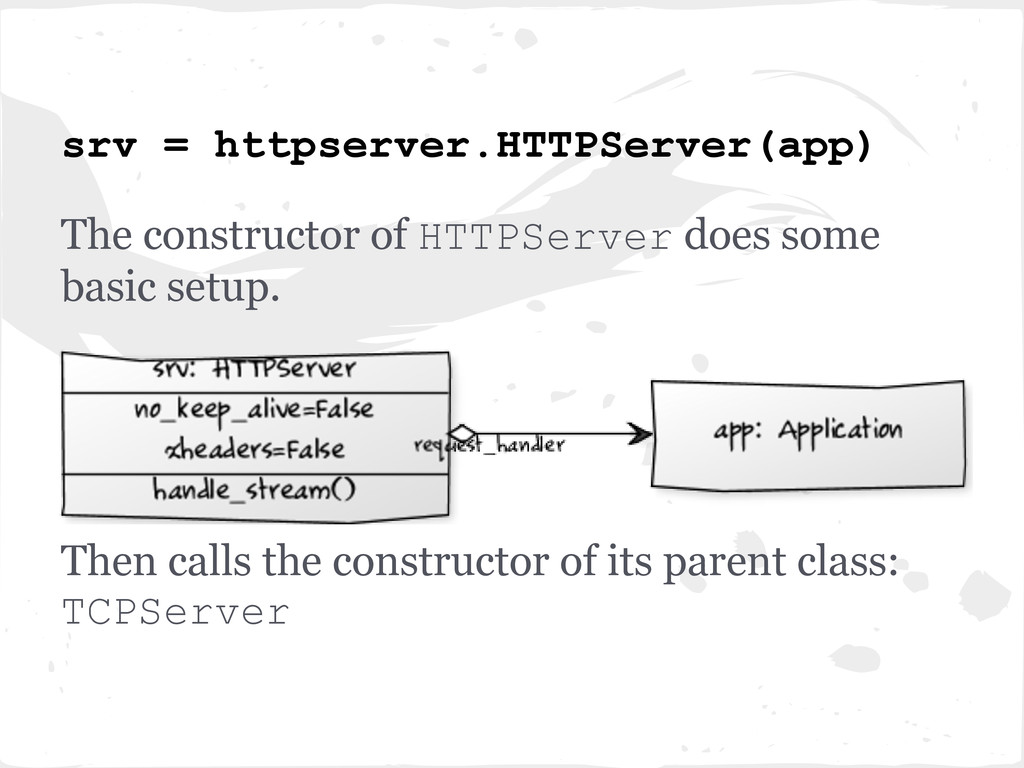
srv = httpserver.HTTPServer(app) The constructor of HTTPServer does some basic
setup. Then calls the constructor of its parent class: TCPServer -
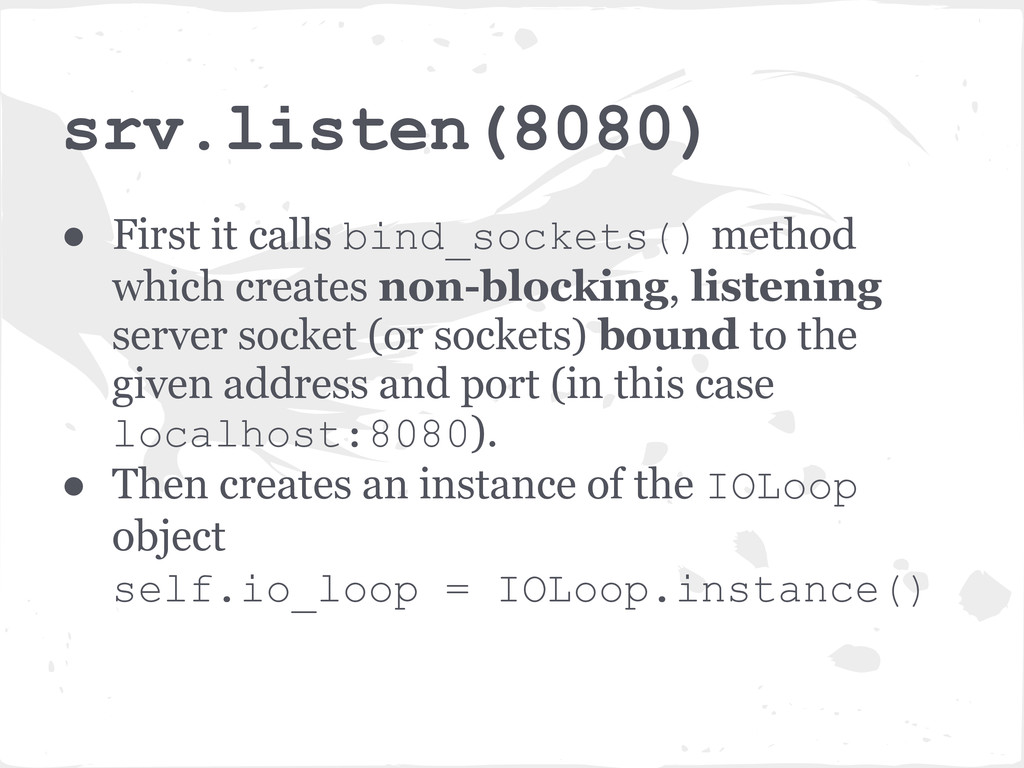
srv.listen(8080) • First it calls bind_sockets() method which creates non-blocking,
listening server socket (or sockets) bound to the given address and port (in this case localhost:8080). • Then creates an instance of the IOLoop object self.io_loop = IOLoop.instance() -
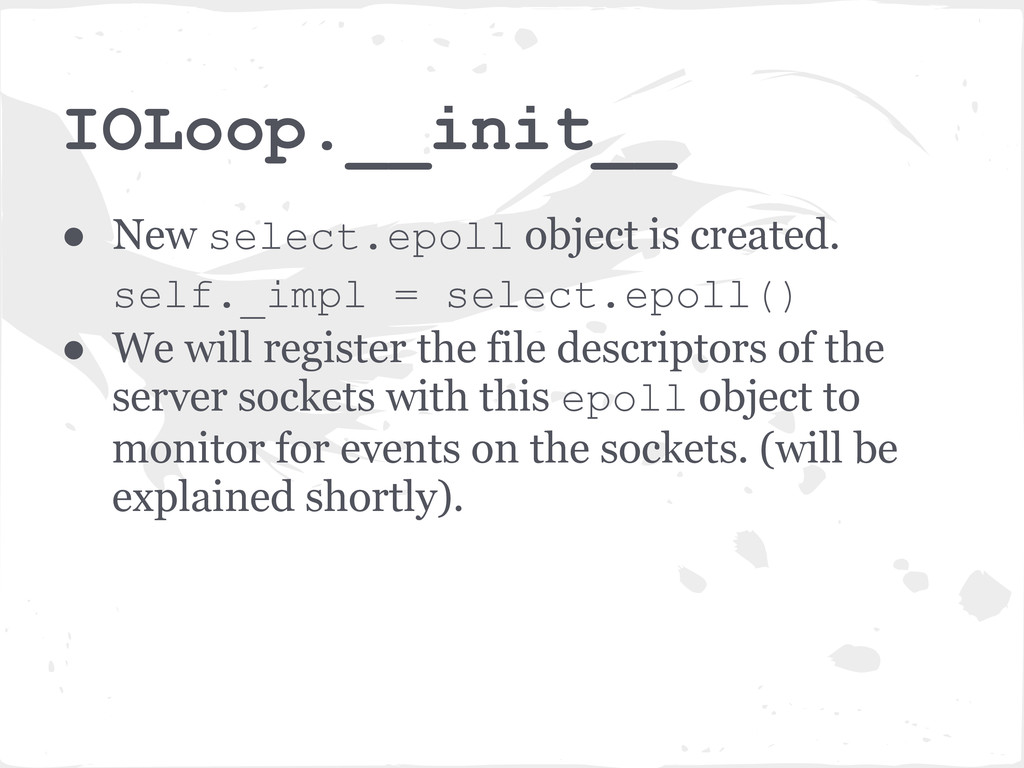
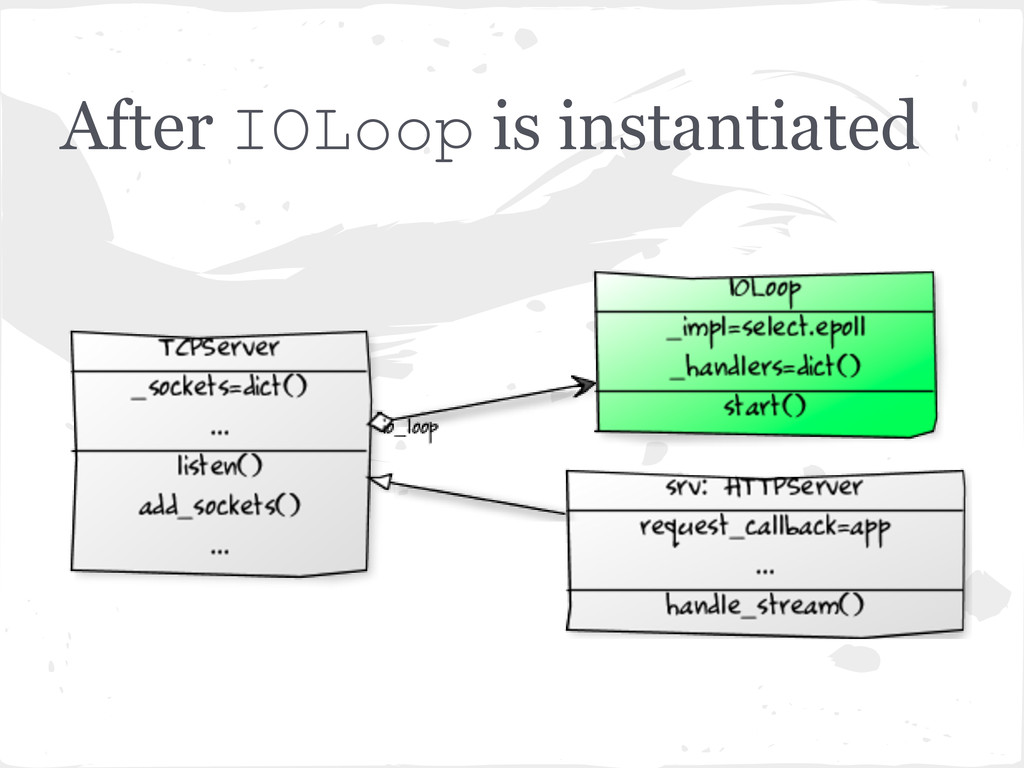
IOLoop.__init__ • New select.epoll object is created. self._impl = select.epoll()
• We will register the file descriptors of the server sockets with this epoll object to monitor for events on the sockets. (will be explained shortly). -
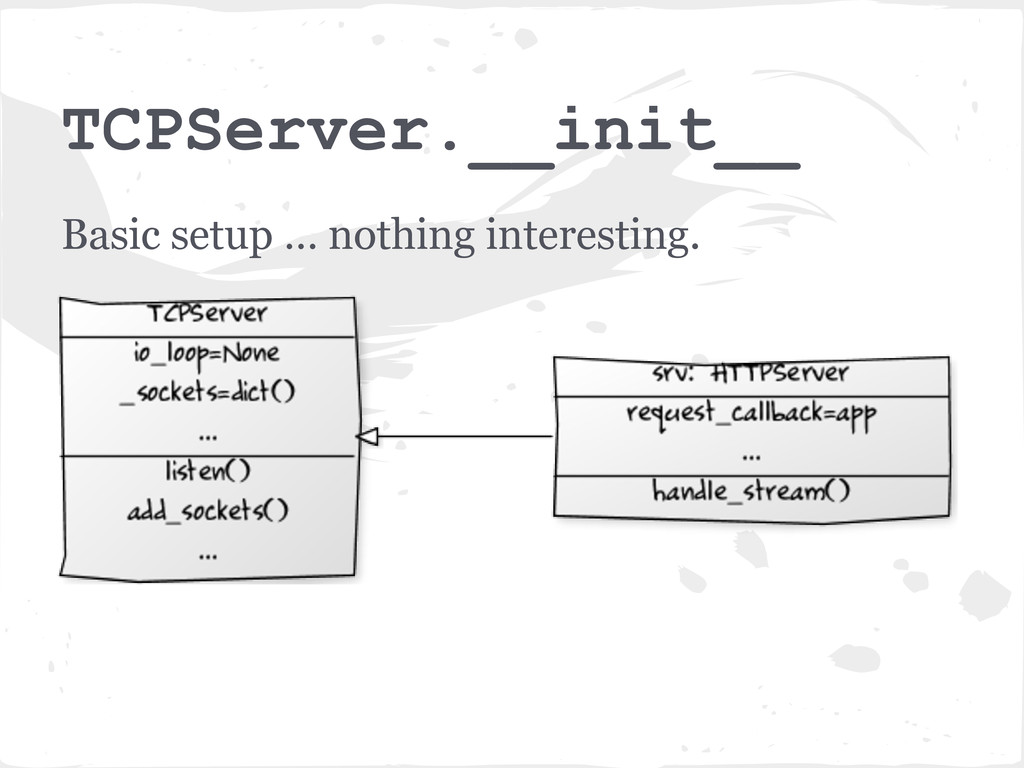
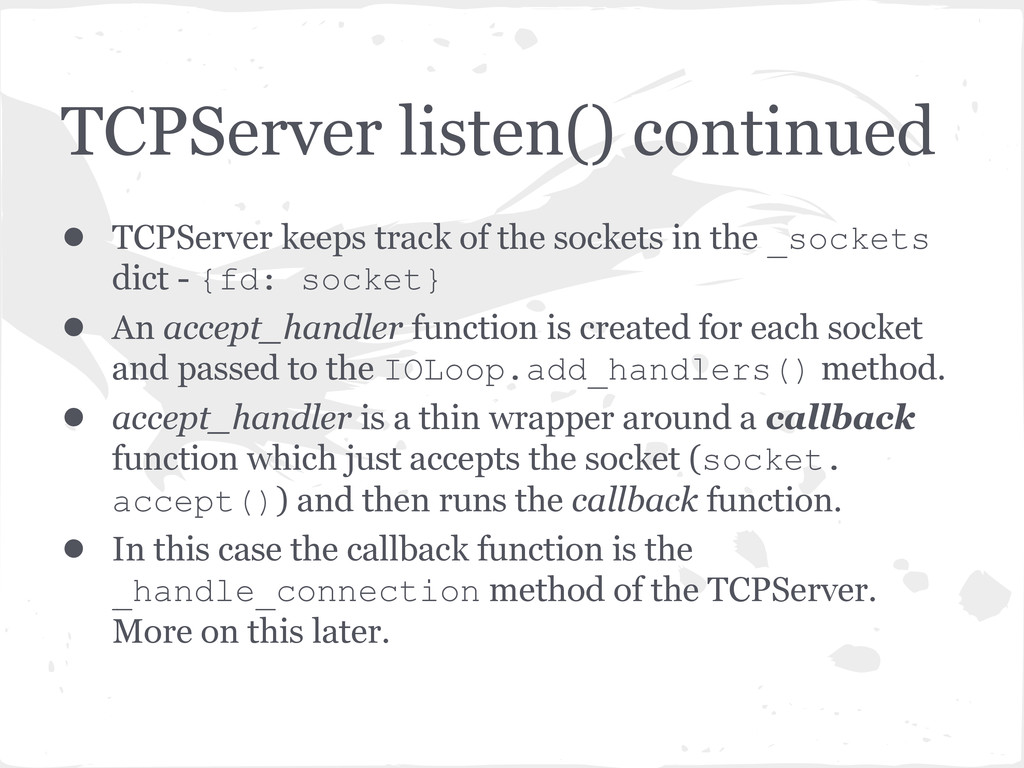
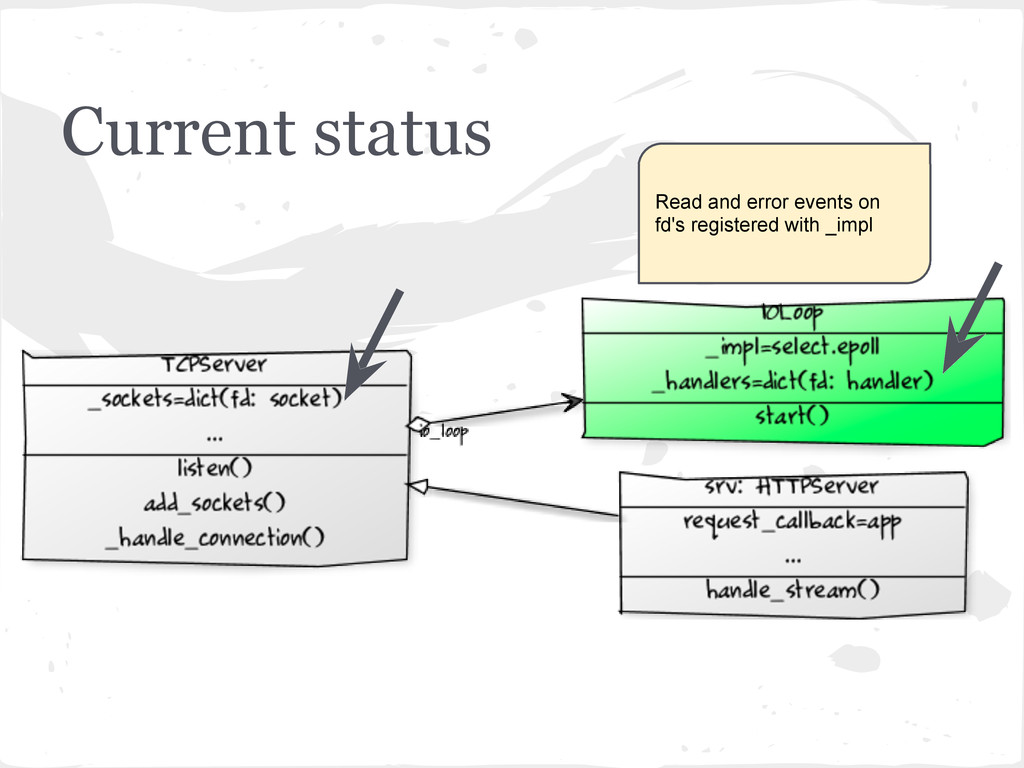
TCPServer listen() continued • TCPServer keeps track of the sockets
in the _sockets dict - {fd: socket} • An accept_handler function is created for each socket and passed to the IOLoop.add_handlers() method. • accept_handler is a thin wrapper around a callback function which just accepts the socket (socket. accept()) and then runs the callback function. • In this case the callback function is the _handle_connection method of the TCPServer. More on this later. -
Adding handlers to IOLoop • Updates ioloop._handlers, with {fd: accept_handler}
to keeps track of which handler function needs to be called when a client tries to establish a connection. • Registers the fd (file descriptor) and data input and error events for the corresponding socket with IOLoop._impl (the epoll object). -
IOLoop.instance() • IOLoop.instance()always returns the same object, no matter how
many times it is called. -
IOLoop.instance().start() • start() method starts the IOLoop. The IOLoop is
the heartbeat and the nerve center of everything. • Continually runs any callback functions, callbacks related to any timeouts, and then runs poll() method on self._impl the epoll object for any new data input events on the socket. • Note: A connect() request from a client is considered as an input event on a server socket. • There is logic in here to send signals to wake up the I/O loop from idle state, ways to run periodic tasks using timeouts etc. which we won't get into. -
What happens when a client connects? • The client socket
connect() is captured by the poll() method in the IOLoop's start() method. • The server runs the accept_handler which accept()'s the connection, then immediately runs the associated callback function. • Remember that accept_handler is a closure that wraps the callback with logic to accept() the connection, so accept_handler knows which callback function to run. • The callback function in this case is _handle_connection method of TCPServer -
TCPServer._handle_connection() • Creates an IOStream object. • IOStream is a
wrapper around non- blocking sockets which provides utilities to read from and write to those sockets. • Then calls HTTPServer.handle_stream (...)and passes it the IOStream object and the client socket address. -
HTTPServer.handle_stream(...) • handle_stream() method creates a HTTPConnection object with our
app as a request_callback. • HTTPConnection handles a connection to an HTTP client and executes HTTP requests. Has methods to parse HTTP headers, bodies, execute callback tasks etc. -
HTTPConnection.__init__() • Reads the headers until "\r\n\r\n" ... delegated to
the IOStream object. self.stream.read_until(b("\r\n\r\n"), self._header_callback) • _header_callback is _on_headers method of HTTPConnection. (We'll get to that in a moment). -
IOStream read • A bunch of redirections to various _read_*
methods. Finally once the headers are read and parsed, invokes _run_callback method. Invokes the socket. recv() methods. • Call back is not executed right away, but added to the IOLoop instance to be called in the next cycle of the IO loop. self.io_loop.add_callback(wrapper) • wrapper is just a wrapper around the callback with some exception handling. Remember, our callback is _on_headers method of HTTPConnection object -
HTTPConnection._on_headers • Creates the appropriate HTTPRequest object (now that we
have parsed the headers). • Then calls the request_callback and passes the HTTPRequest. Remember this? May be you don't after all this ... request_callback is the original app we created. • Whew! Light at the end of the tunnel. Only a couple more steps. -
app.__call__ • Application is a callable object (has the __call__
method. So you can just call an application. • The __call__ method looks at the url in the HTTPRequest and invokes the _execute method of appropriate RequestHandler - the MainHandler in our example. -
RequestHandler._execute • Executes the appropriate HTTP method getattr(self,self.request.method.lower() )(*args, **kwargs)
• In our case get method calls write() and writes the "Hello World" string. • Then calls finish() method which prepares response headers and calls flush() to write the output to the socket and close it. -
Writing the output and closing • RequestHandler.flush() delegates the write()
to the request, which in turn delegates it to the HTTPConnection which in turn delegates it to the IOStream. • IOStream adds this write method to the IOLoop. _callbacks list and the write is executed in turn during the next iteration of IOLoop. • Once everything is done, the socket is closed (unless of course you specify that it stay open). -
Points to note ... • Note that we did fork
a process. • We did not spawn a thread. • Everything happens in just one thread and is multiplexed using epoll.poll() • Callback handlers are run one at a time, in turn, on a single thread. • If a callback task (in the RequestHandler) is long running, for example a database query that takes too long, the other requests which are queued behind will suffer. -
Other things to consider • You can make your request
handler asynchronous, and keep the connection open so that other requests do not suffer. • But you have to close the connection yourself. • See the chat example in the source code. -
Apache - multiple requests • How multiple requests are handled
depends on Multiprocessing mode (MPM). • Two modes ◦ prefork ◦ worker -
prefork MPM • Most commonly used. Is the default mode
in 2.x and only option in 1.3. • The main Apache process will at startup create multiple child processes. When a request is received by the parent process, it will be processed by whichever of the child processes is ready. -
worker MPM • Within each child process there will exist
a number of worker threads. • The request may be processed by a worker thread within a child process which already has other worker threads handling other requests at the same time. -
Apache vs. Tornado • Apache has additional memory overhead of
maintaining the other processes which are essentially idle when the request load is low. Tornado does not have this overhead. • Tornado natively allows you to use websockets. Experimental support in apache with apache-websocket module. • Scalability - There are arguments for both sides. Personally I haven't built anything that cannot be scaled by Apache. So no idea if one is better than the other.
 pgollakota
 110y
 bengo4com
 jirtosterone
 sansantech
 bitkey
 fj_yoshimura_kosuke
 falken
 shumpei3
 grimoh
 tkito
 torounit
 kmiya84377
 cassininazir
 uxyall
 lcolladotor
 addyosmani
 mza
 tenderlove
 jonoalderson
 codingconduct
 iamctodd
 chikuwait
 marcduiker
 paigeccino