Share
Embed

Transcript
58 slides
-
Scaling Data at Slack A Series of Unfortunate Events Ronnie
Chen & Diana Pojar 1 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Ronnie & Diana Data Engineers @ Slack 2 — Kaizen
2016 Scaling Data at Slack | @rondoftw @podiana -
What you think you do 3 — Kaizen 2016 Scaling
Data at Slack | @rondoftw @podiana -
What other people think you do 4 — Kaizen 2016
Scaling Data at Slack | @rondoftw @podiana -
What you actually do 5 — Kaizen 2016 Scaling Data
at Slack | @rondoftw @podiana -
Why are we giving this talk? 6 — Kaizen 2016
Scaling Data at Slack | @rondoftw @podiana -
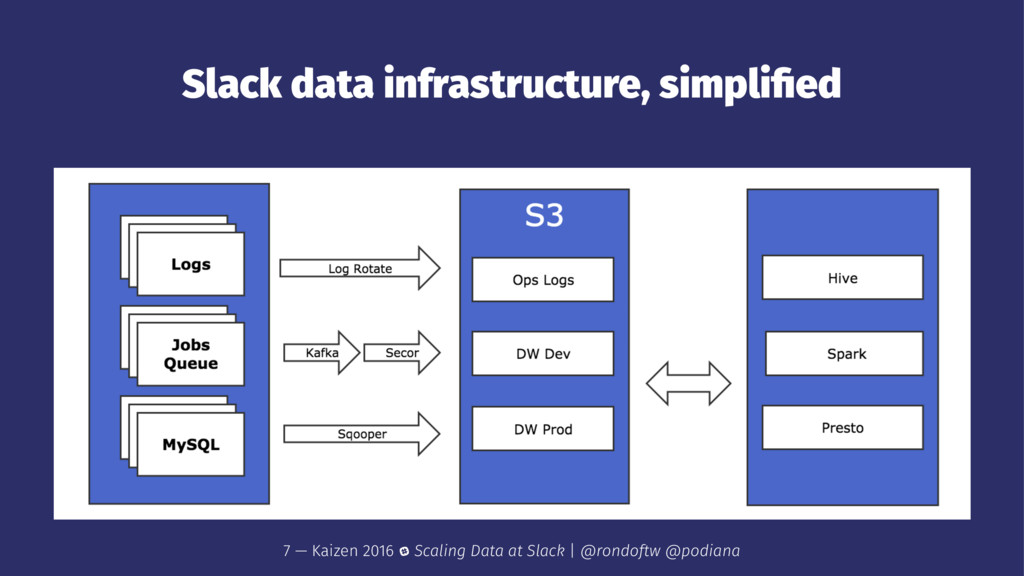
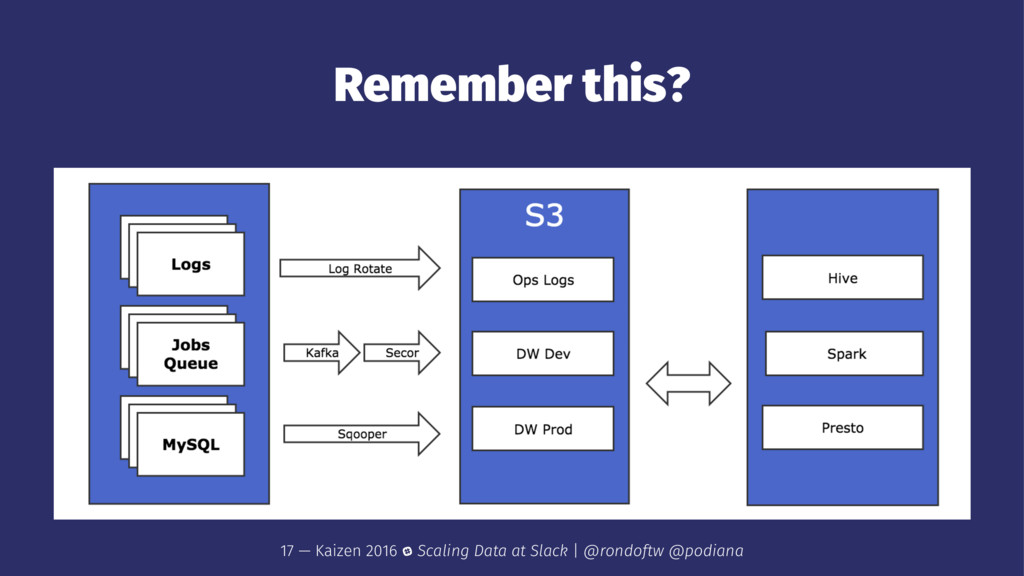
Slack data infrastructure, simplified 7 — Kaizen 2016 Scaling Data
at Slack | @rondoftw @podiana -
Presto → distributed SQL query engine optimized for interactive queries
→ fast/adhoc queries to explore data and get fast answers for a short time range → majority of use is via UI interface vs command line → visualization tools via Mode for making charts and dashboards 8 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Hive → SQL-like queries that are implicitly converted into MapReduce
jobs → suited for ETL pipeline as it can handle larger joins → queries for longer time ranges or bigger datasets because there are no memory constraints → fault-tolerance to stage failures 9 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Spark → used mostly for cleaning up and creating the
different Hive tables for analysts → easier to express some logic in code (! Scala!) and use libraries instead of SQL-like language → multiple knobs to turn to make the jobs more efficient and faster than Hive queries → testable 10 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
AWS EMR → easy to launch cluster that comes already
set up with Presto/Hive/Spark → clusters are ephemeral, we only use it for computation and run our jobs there 11 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
S3 & Hive metastore → everything is stored in a
single place and is accessible by all our dev/prod clusters 12 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
! Thrift ! Parquet → columnar format → query efficiency
→ space efficiency 13 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
This sounds great! 14 — Kaizen 2016 Scaling Data at
Slack | @rondoftw @podiana -
✨The Dream ✨ → Everything can talk to anything else
→ Data is structured and typed → Easy to test and launch in production when ready → Flexibility to choose best processing engine for the job 15 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
! Reality ! → You can write data you can't
read back → You can write data another tool can't read → You can write data that is read the wrong way ! → Have to flatten structured data to keep evolving it → Need to maintain and support interop of all engines 16 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Remember this? 17 — Kaizen 2016 Scaling Data at Slack
| @rondoftw @podiana -
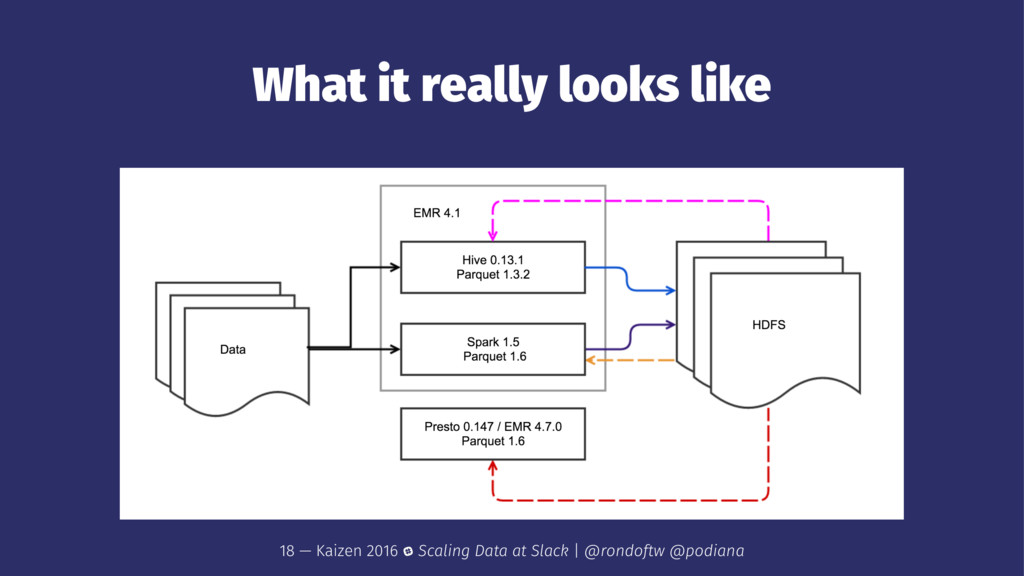
What it really looks like 18 — Kaizen 2016 Scaling
Data at Slack | @rondoftw @podiana -
EMR peculiarities → Hive is forked from official version (0.13)
→ Presto/Spark/Hive versions use conflicting dependencies (parquet) → You're stuck with those versions (no latest features, bug fixes) ! → Missing many useful UDFs from newer versions → Upgrading is not as easy as it seems 19 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Logging data 20 — Kaizen 2016 Scaling Data at Slack
| @rondoftw @podiana -
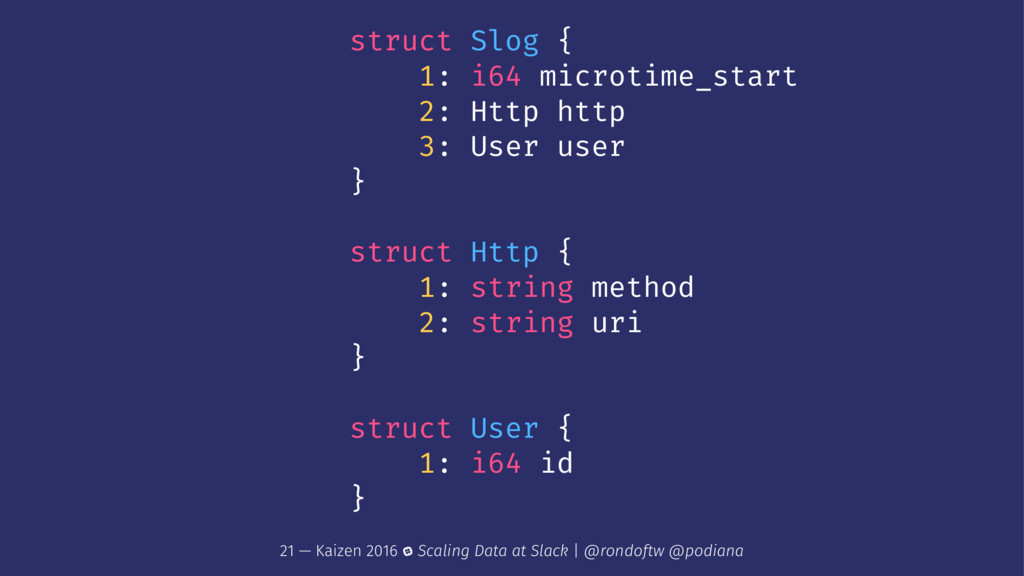
struct Slog { 1: i64 microtime_start 2: Http http 3:
User user } struct Http { 1: string method 2: string uri } struct User { 1: i64 id } 21 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
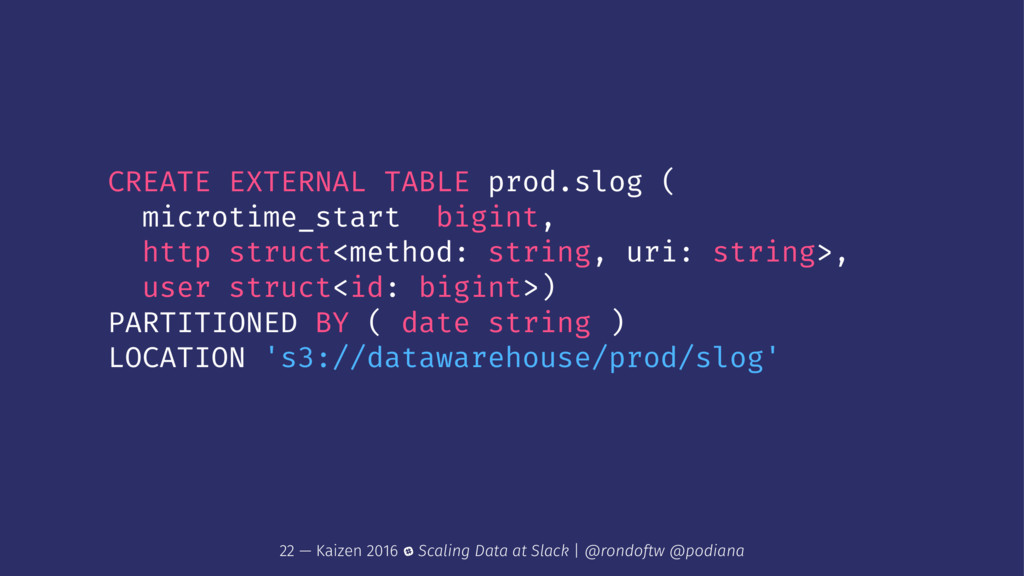
CREATE EXTERNAL TABLE prod.slog ( microtime_start bigint, http struct<method: string,
uri: string>, user struct<id: bigint>) PARTITIONED BY ( date string ) LOCATION 's3://datawarehouse/prod/slog' 22 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
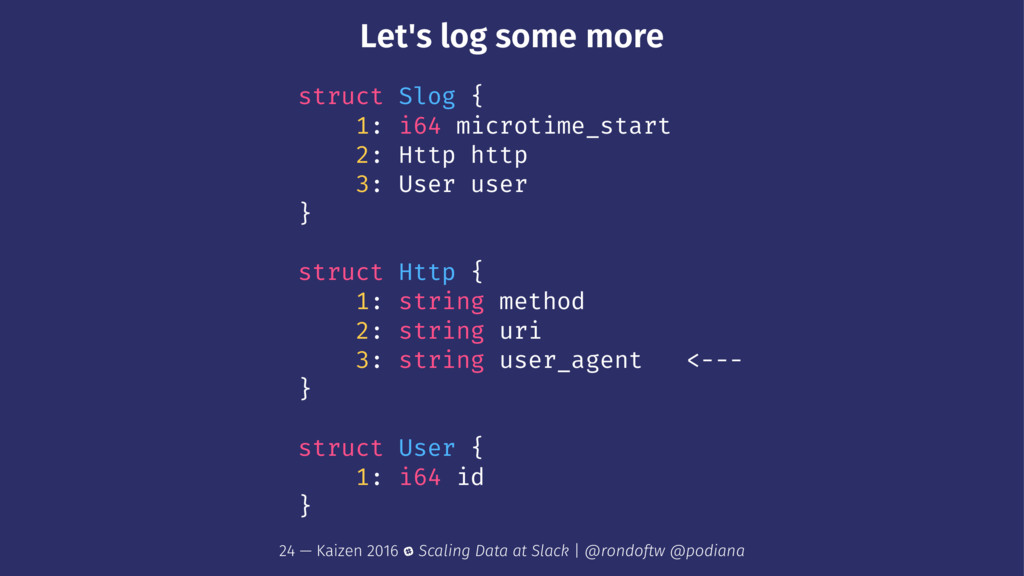
Let's log some more struct Slog { 1: i64 microtime_start
2: Http http 3: User user } struct Http { 1: string method 2: string uri 3: string user_agent <--- } struct User { 1: i64 id } 24 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
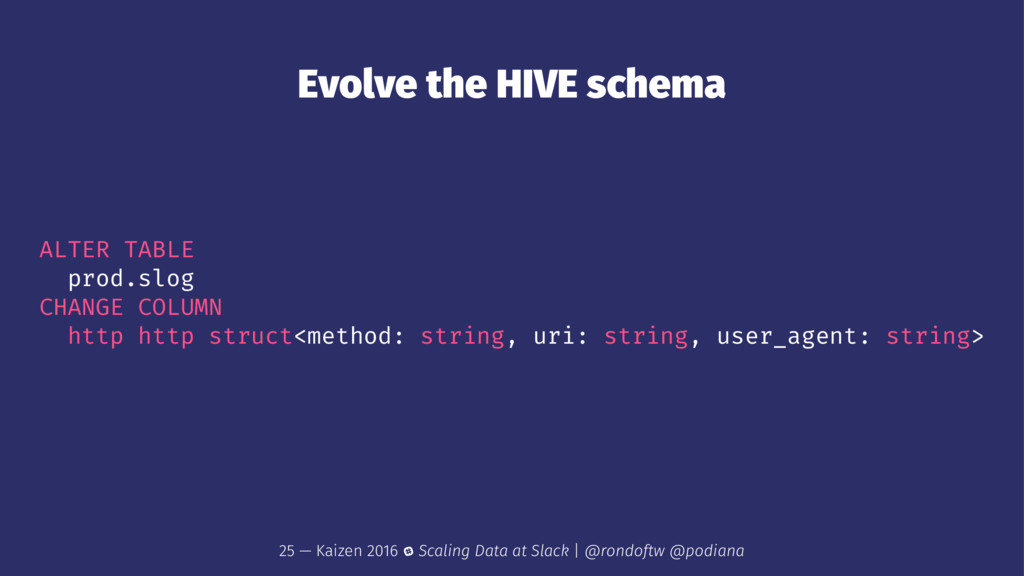
Evolve the HIVE schema ALTER TABLE prod.slog CHANGE COLUMN http
http struct<method: string, uri: string, user_agent: string> 25 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
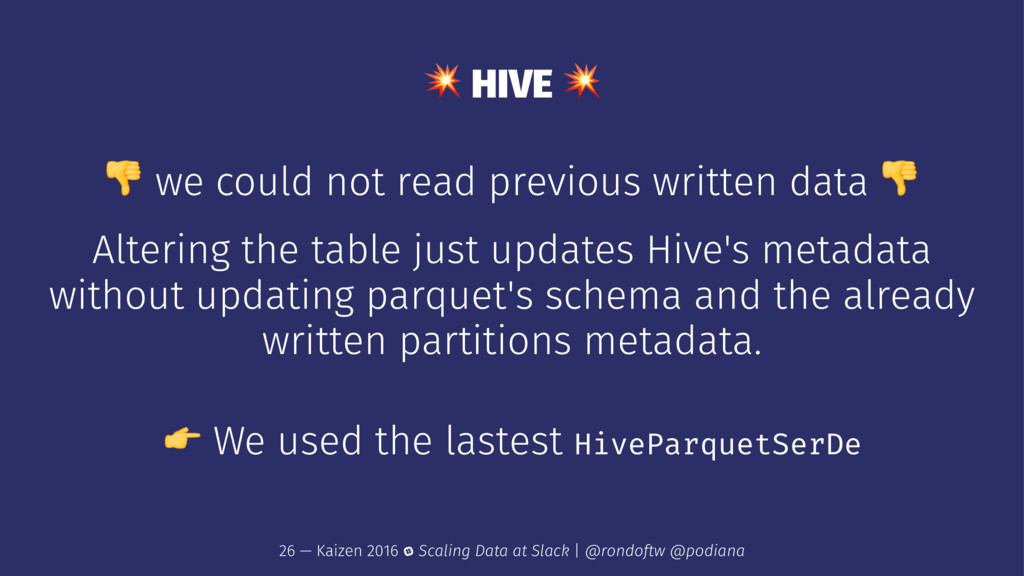
! HIVE ! ! we could not read previous written
data ! Altering the table just updates Hive's metadata without updating parquet's schema and the already written partitions metadata. ! We used the lastest HiveParquetSerDe 26 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
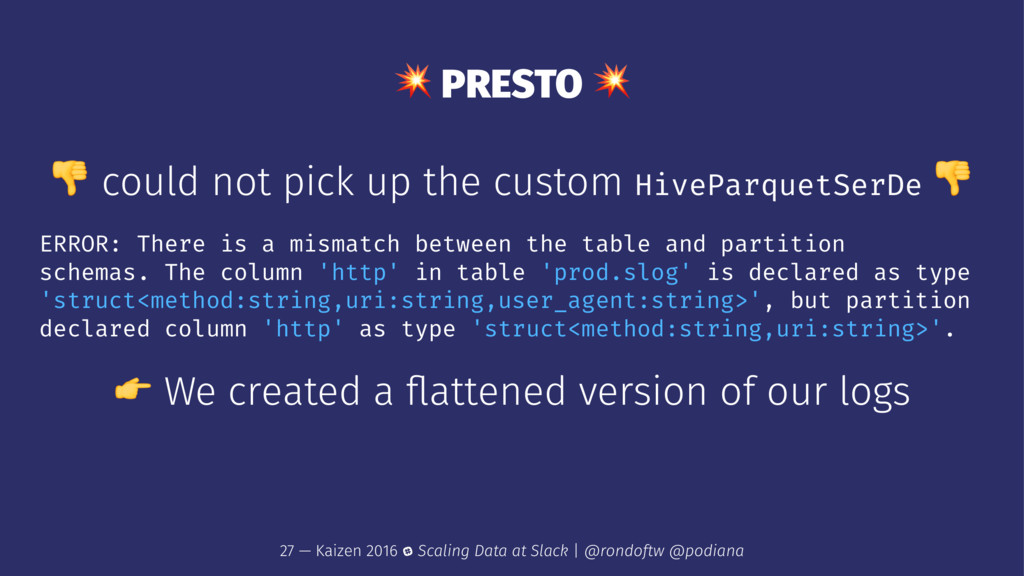
! PRESTO ! ! could not pick up the custom
HiveParquetSerDe ! ERROR: There is a mismatch between the table and partition schemas. The column 'http' in table 'prod.slog' is declared as type 'struct<method:string,uri:string,user_agent:string>', but partition declared column 'http' as type 'struct<method:string,uri:string>'. ! We created a flattened version of our logs 27 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
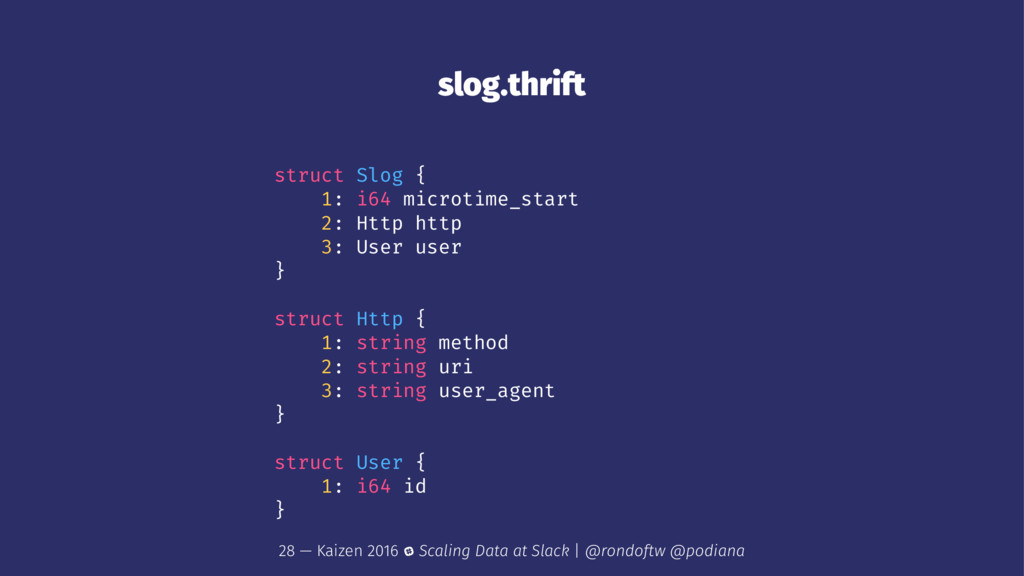
slog.thrift struct Slog { 1: i64 microtime_start 2: Http http
3: User user } struct Http { 1: string method 2: string uri 3: string user_agent } struct User { 1: i64 id } 28 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
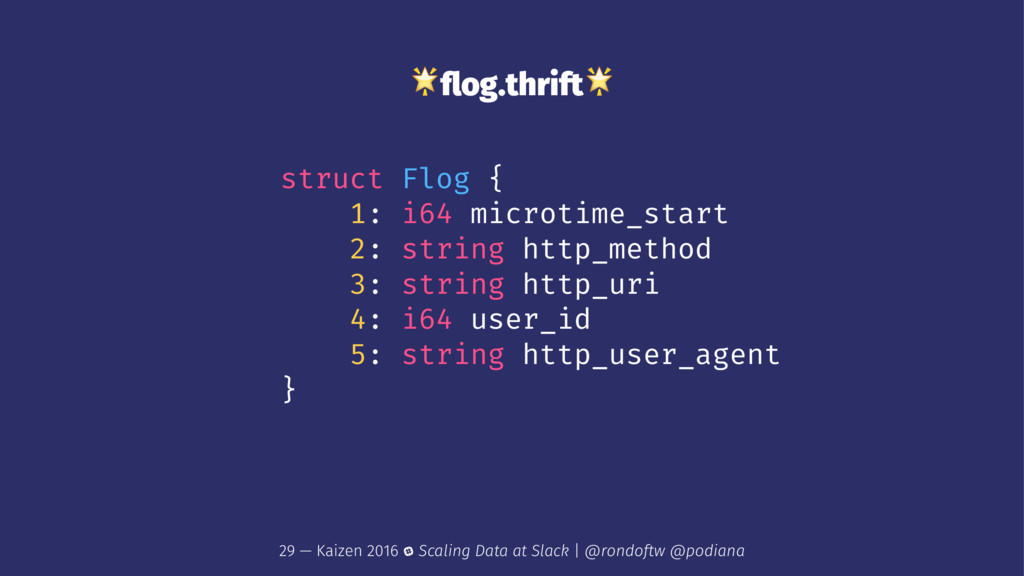
!flog.thrift! struct Flog { 1: i64 microtime_start 2: string http_method
3: string http_uri 4: i64 user_id 5: string http_user_agent } 29 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Processing data 31 — Kaizen 2016 Scaling Data at Slack
| @rondoftw @podiana -
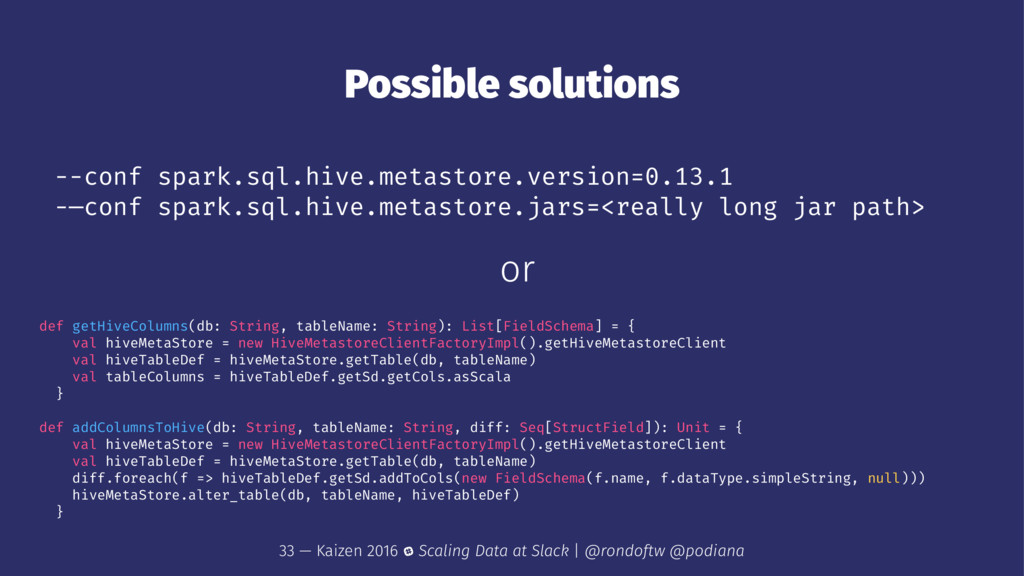
Spark and Hive → EMR Hive metastore version is 0.13.1
→ Spark 1.5 and later ships with a default metastore version of Hive 1.2 ! 32 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Possible solutions --conf spark.sql.hive.metastore.version=0.13.1 -—conf spark.sql.hive.metastore.jars=<really long jar path> or
def getHiveColumns(db: String, tableName: String): List[FieldSchema] = { val hiveMetaStore = new HiveMetastoreClientFactoryImpl().getHiveMetastoreClient val hiveTableDef = hiveMetaStore.getTable(db, tableName) val tableColumns = hiveTableDef.getSd.getCols.asScala } def addColumnsToHive(db: String, tableName: String, diff: Seq[StructField]): Unit = { val hiveMetaStore = new HiveMetastoreClientFactoryImpl().getHiveMetastoreClient val hiveTableDef = hiveMetaStore.getTable(db, tableName) diff.foreach(f => hiveTableDef.getSd.addToCols(new FieldSchema(f.name, f.dataType.simpleString, null))) hiveMetaStore.alter_table(db, tableName, hiveTableDef) } 33 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
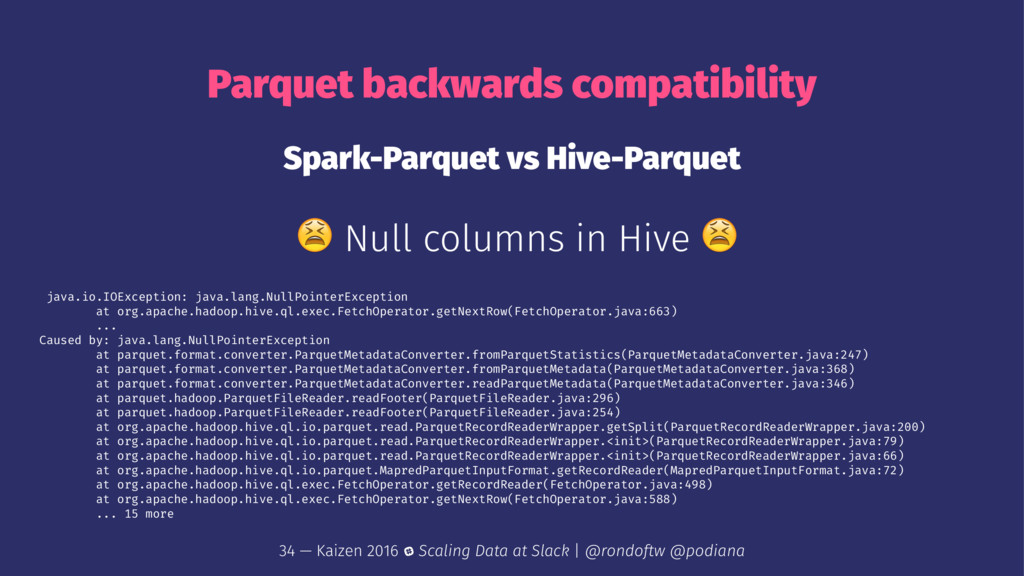
Parquet backwards compatibility Spark-Parquet vs Hive-Parquet ! Null columns in
Hive ! java.io.IOException: java.lang.NullPointerException at org.apache.hadoop.hive.ql.exec.FetchOperator.getNextRow(FetchOperator.java:663) ... Caused by: java.lang.NullPointerException at parquet.format.converter.ParquetMetadataConverter.fromParquetStatistics(ParquetMetadataConverter.java:247) at parquet.format.converter.ParquetMetadataConverter.fromParquetMetadata(ParquetMetadataConverter.java:368) at parquet.format.converter.ParquetMetadataConverter.readParquetMetadata(ParquetMetadataConverter.java:346) at parquet.hadoop.ParquetFileReader.readFooter(ParquetFileReader.java:296) at parquet.hadoop.ParquetFileReader.readFooter(ParquetFileReader.java:254) at org.apache.hadoop.hive.ql.io.parquet.read.ParquetRecordReaderWrapper.getSplit(ParquetRecordReaderWrapper.java:200) at org.apache.hadoop.hive.ql.io.parquet.read.ParquetRecordReaderWrapper.<init>(ParquetRecordReaderWrapper.java:79) at org.apache.hadoop.hive.ql.io.parquet.read.ParquetRecordReaderWrapper.<init>(ParquetRecordReaderWrapper.java:66) at org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat.getRecordReader(MapredParquetInputFormat.java:72) at org.apache.hadoop.hive.ql.exec.FetchOperator.getRecordReader(FetchOperator.java:498) at org.apache.hadoop.hive.ql.exec.FetchOperator.getNextRow(FetchOperator.java:588) ... 15 more 34 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
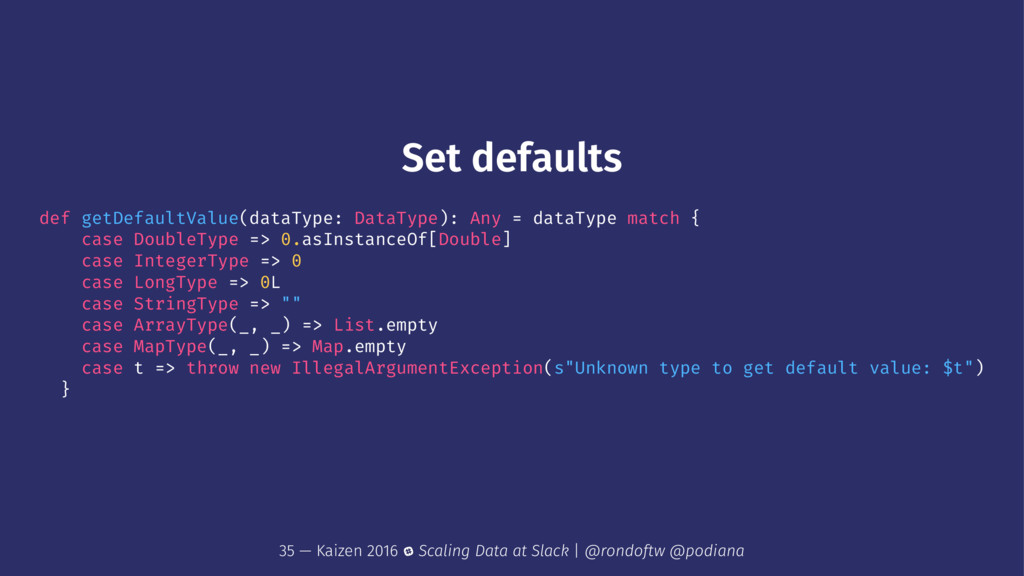
Set defaults def getDefaultValue(dataType: DataType): Any = dataType match {
case DoubleType => 0.asInstanceOf[Double] case IntegerType => 0 case LongType => 0L case StringType => "" case ArrayType(_, _) => List.empty case MapType(_, _) => Map.empty case t => throw new IllegalArgumentException(s"Unknown type to get default value: $t") } 35 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
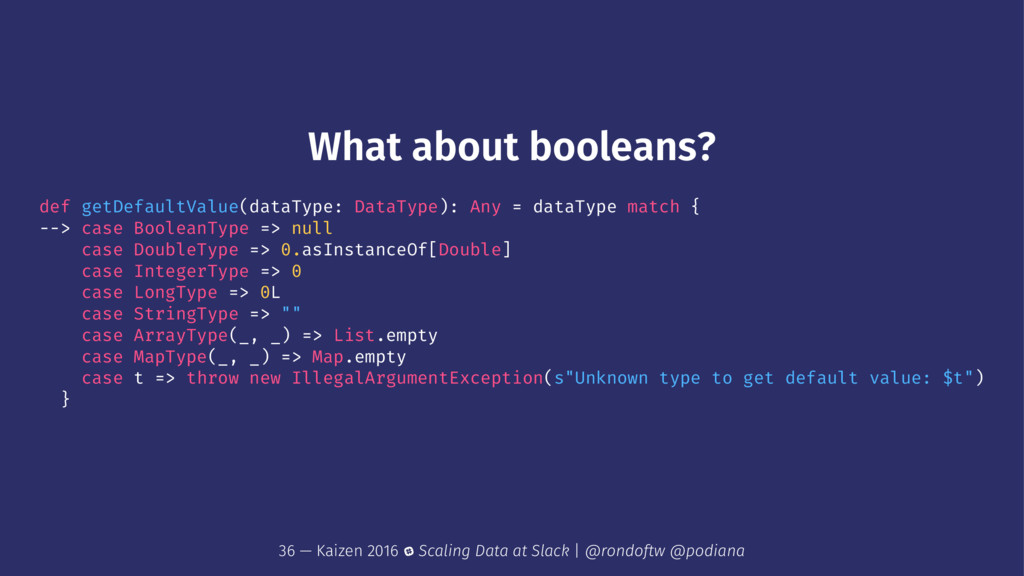
What about booleans? def getDefaultValue(dataType: DataType): Any = dataType match
{ --> case BooleanType => null case DoubleType => 0.asInstanceOf[Double] case IntegerType => 0 case LongType => 0L case StringType => "" case ArrayType(_, _) => List.empty case MapType(_, _) => Map.empty case t => throw new IllegalArgumentException(s"Unknown type to get default value: $t") } 36 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
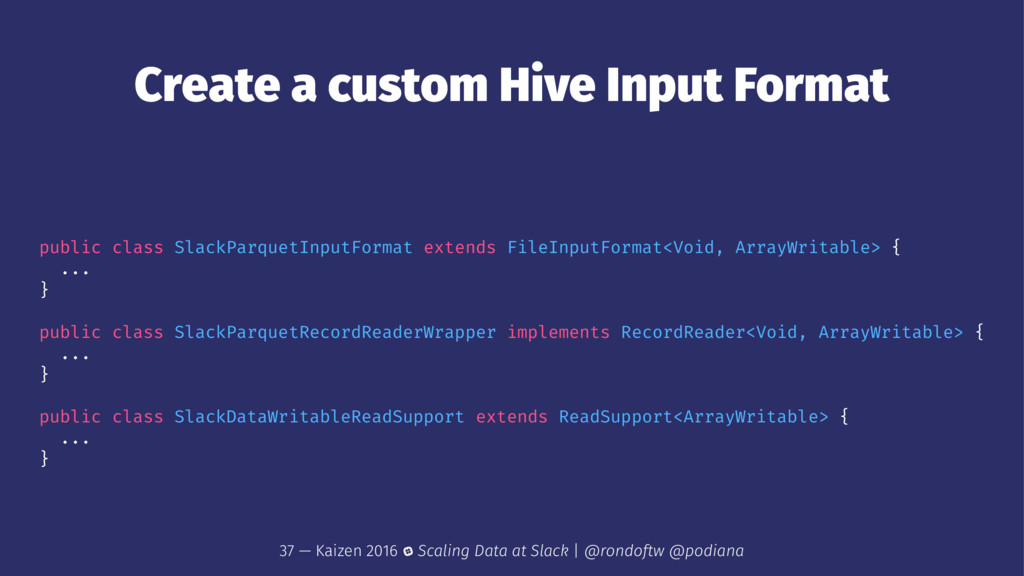
Create a custom Hive Input Format public class SlackParquetInputFormat extends
FileInputFormat<Void, ArrayWritable> { ... } public class SlackParquetRecordReaderWrapper implements RecordReader<Void, ArrayWritable> { ... } public class SlackDataWritableReadSupport extends ReadSupport<ArrayWritable> { ... } 37 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
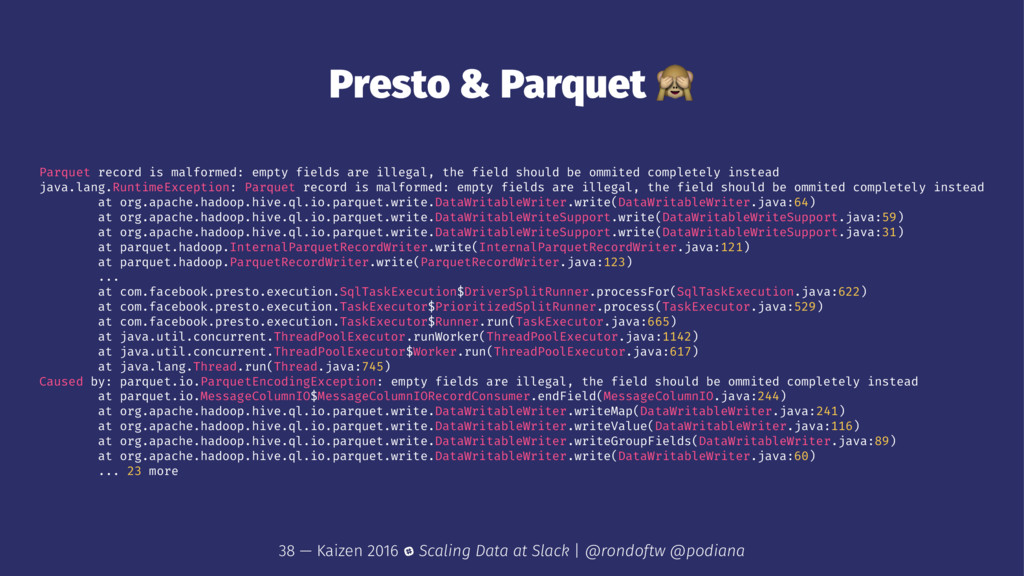
Presto & Parquet ! Parquet record is malformed: empty fields
are illegal, the field should be ommited completely instead java.lang.RuntimeException: Parquet record is malformed: empty fields are illegal, the field should be ommited completely instead at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriter.write(DataWritableWriter.java:64) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriteSupport.write(DataWritableWriteSupport.java:59) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriteSupport.write(DataWritableWriteSupport.java:31) at parquet.hadoop.InternalParquetRecordWriter.write(InternalParquetRecordWriter.java:121) at parquet.hadoop.ParquetRecordWriter.write(ParquetRecordWriter.java:123) ... at com.facebook.presto.execution.SqlTaskExecution$DriverSplitRunner.processFor(SqlTaskExecution.java:622) at com.facebook.presto.execution.TaskExecutor$PrioritizedSplitRunner.process(TaskExecutor.java:529) at com.facebook.presto.execution.TaskExecutor$Runner.run(TaskExecutor.java:665) at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1142) at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:617) at java.lang.Thread.run(Thread.java:745) Caused by: parquet.io.ParquetEncodingException: empty fields are illegal, the field should be ommited completely instead at parquet.io.MessageColumnIO$MessageColumnIORecordConsumer.endField(MessageColumnIO.java:244) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriter.writeMap(DataWritableWriter.java:241) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriter.writeValue(DataWritableWriter.java:116) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriter.writeGroupFields(DataWritableWriter.java:89) at org.apache.hadoop.hive.ql.io.parquet.write.DataWritableWriter.write(DataWritableWriter.java:60) ... 23 more 38 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Presto [HIVE-11625] - Map instances with null keys are not
properly handled for Parquet tables def getDefaultValue(dataType: DataType): Any = dataType match { case BooleanType => null case DoubleType => 0.asInstanceOf[Double] case IntegerType => 0 case LongType => 0L case StringType => "" --> case ArrayType(elemDataType, _) => List(getDefaultValue(elemDataType)) --> case MapType(keyDataType, valueDataType, _) => Map(getDefaultValue(keyDataType) -> getDefaultValue(valueDataType)) case t => throw new IllegalArgumentException(s"Unknown type to get default value: $t") } 39 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
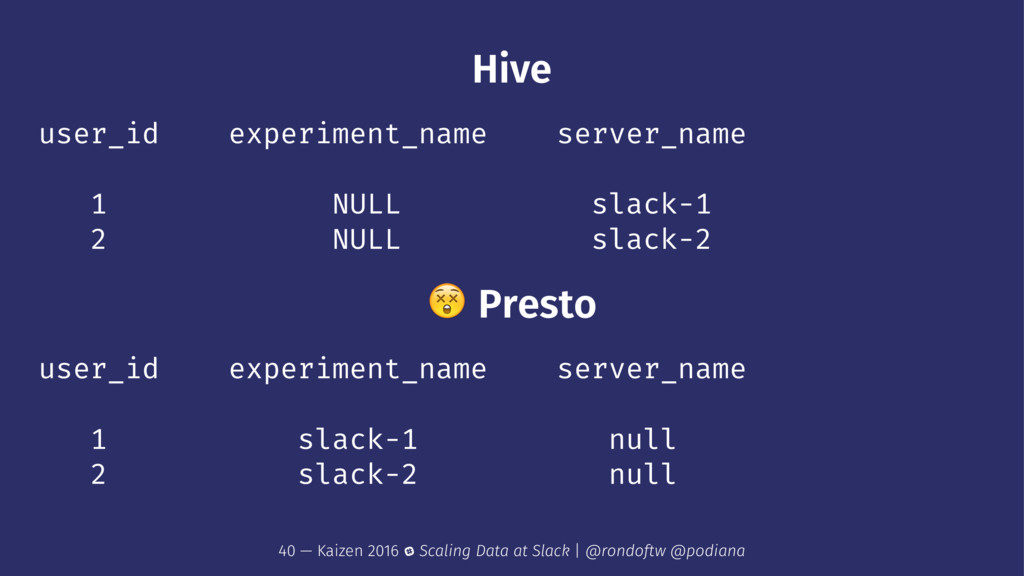
Hive user_id experiment_name server_name 1 NULL slack-1 2 NULL slack-2
! Presto user_id experiment_name server_name 1 slack-1 null 2 slack-2 null 40 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
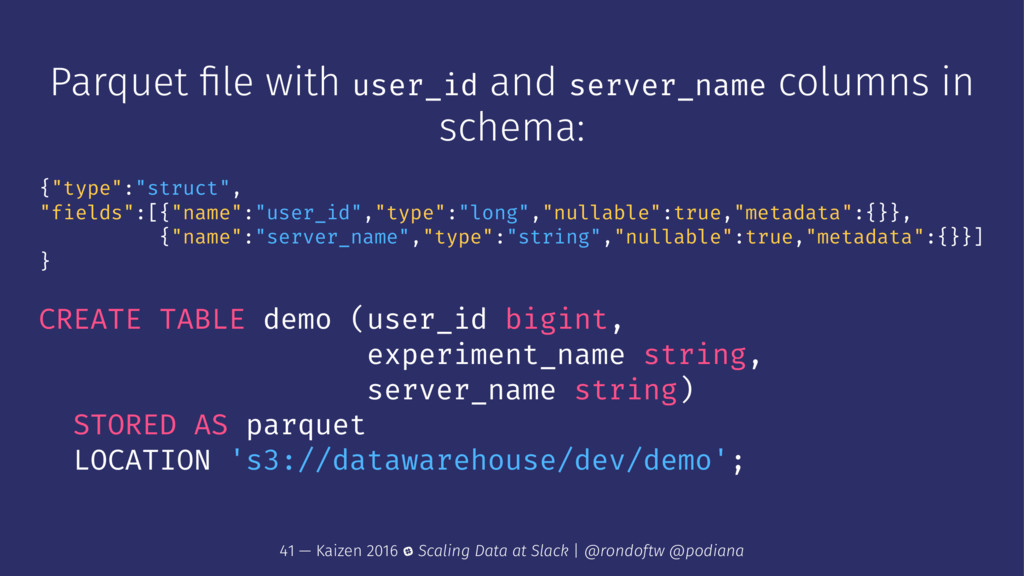
Parquet file with user_id and server_name columns in schema: {"type":"struct",
"fields":[{"name":"user_id","type":"long","nullable":true,"metadata":{}}, {"name":"server_name","type":"string","nullable":true,"metadata":{}}] } CREATE TABLE demo (user_id bigint, experiment_name string, server_name string) STORED AS parquet LOCATION 's3://datawarehouse/dev/demo'; 41 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Presto & column names By default, columns in Parquet files
are accessed by their ordinal position in the Hive table definition. → hive.parquet.use-column-names=true → explicitly write column values so that column shift cannot happen 42 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Leveraging Scala: Option[T] > null Writing custom rich classes to
avoid NPEs implicit class RichRow(val row: Row) { def getOpt[T](fieldName: String): Option[T] = { isNullAt(fieldName) match { case false => Some(row.getAs[T](fieldName)) case true => None } } def getRowOpt(fieldName: String): Option[Row] = getOpt[Row](fieldName) def getStringOpt(fieldName: String): Option[String] = getOpt[String](fieldName) def isNullAt(fieldName: String): Boolean = ! row.schema.schemaContains(fieldName) || row.isNullAt(row.fieldIndex(fieldName)) } 43 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Spark 44 — Kaizen 2016 Scaling Data at Slack |
@rondoftw @podiana -
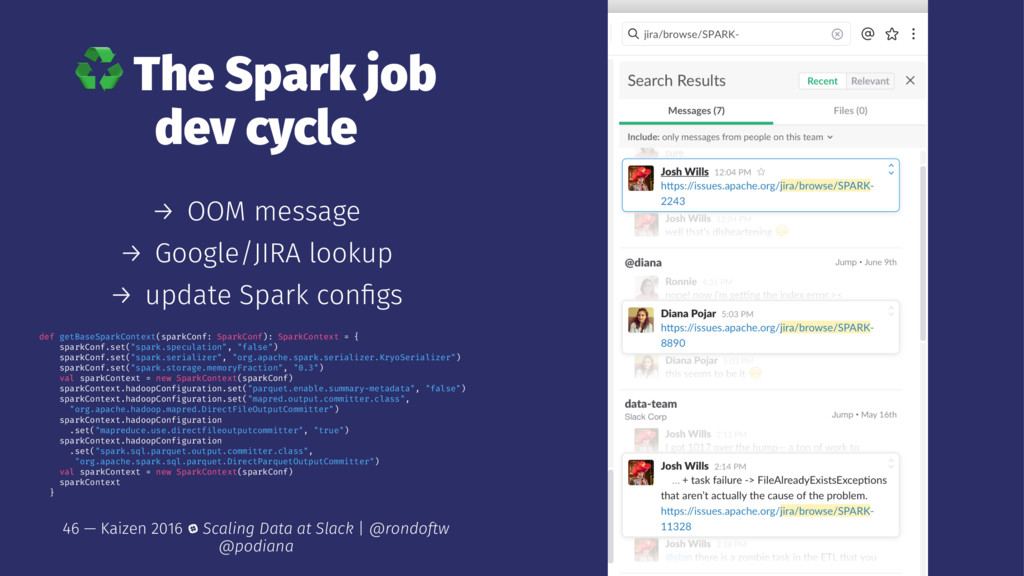
! java.io.IOException: File already exists... [SPARK-11328] - Provide more informative
error message when direct parquet output committer is used and there is a file already exists error. 45 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
♻ The Spark job dev cycle → OOM message →
Google/JIRA lookup → update Spark configs def getBaseSparkContext(sparkConf: SparkConf): SparkContext = { sparkConf.set("spark.speculation", "false") sparkConf.set("spark.serializer", "org.apache.spark.serializer.KryoSerializer") sparkConf.set("spark.storage.memoryFraction", "0.3") val sparkContext = new SparkContext(sparkConf) sparkContext.hadoopConfiguration.set("parquet.enable.summary-metadata", "false") sparkContext.hadoopConfiguration.set("mapred.output.committer.class", "org.apache.hadoop.mapred.DirectFileOutputCommitter") sparkContext.hadoopConfiguration .set("mapreduce.use.directfileoutputcommitter", "true") sparkContext.hadoopConfiguration .set("spark.sql.parquet.output.committer.class", "org.apache.spark.sql.parquet.DirectParquetOutputCommitter") val sparkContext = new SparkContext(sparkConf) sparkContext } 46 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Beware the brute force method ! --driver-memory ☹ --num-executors "
--executor-memory # --partitions $ 47 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
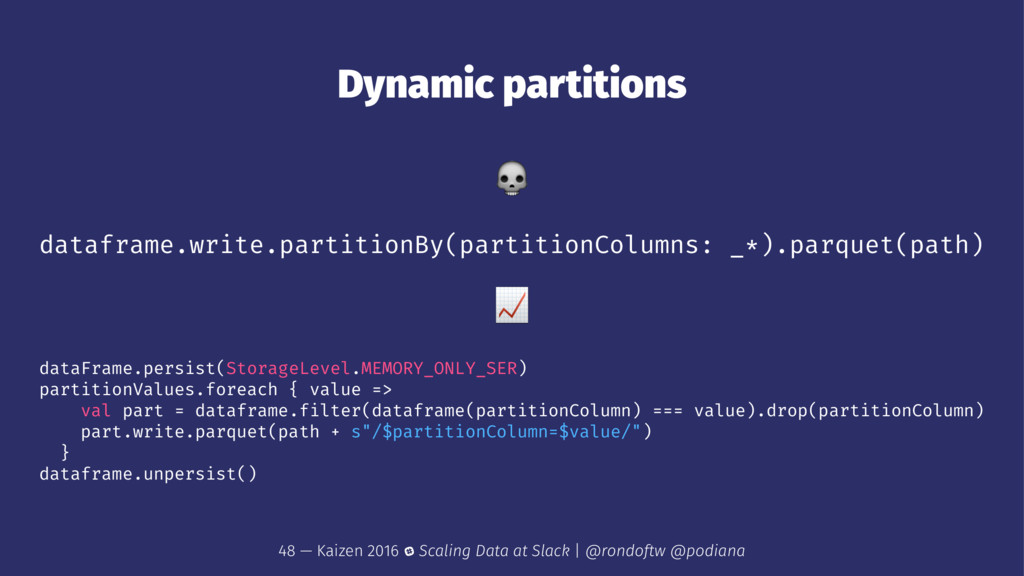
Dynamic partitions ! dataframe.write.partitionBy(partitionColumns: _*).parquet(path) ! dataFrame.persist(StorageLevel.MEMORY_ONLY_SER) partitionValues.foreach { value
=> val part = dataframe.filter(dataframe(partitionColumn) === value).drop(partitionColumn) part.write.parquet(path + s"/$partitionColumn=$value/") } dataframe.unpersist() 48 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Sunshine and roses in data land 49 — Kaizen 2016
Scaling Data at Slack | @rondoftw @podiana -
Let's upgrade EMR 4.1 to 4.7... 50 — Kaizen 2016
Scaling Data at Slack | @rondoftw @podiana -
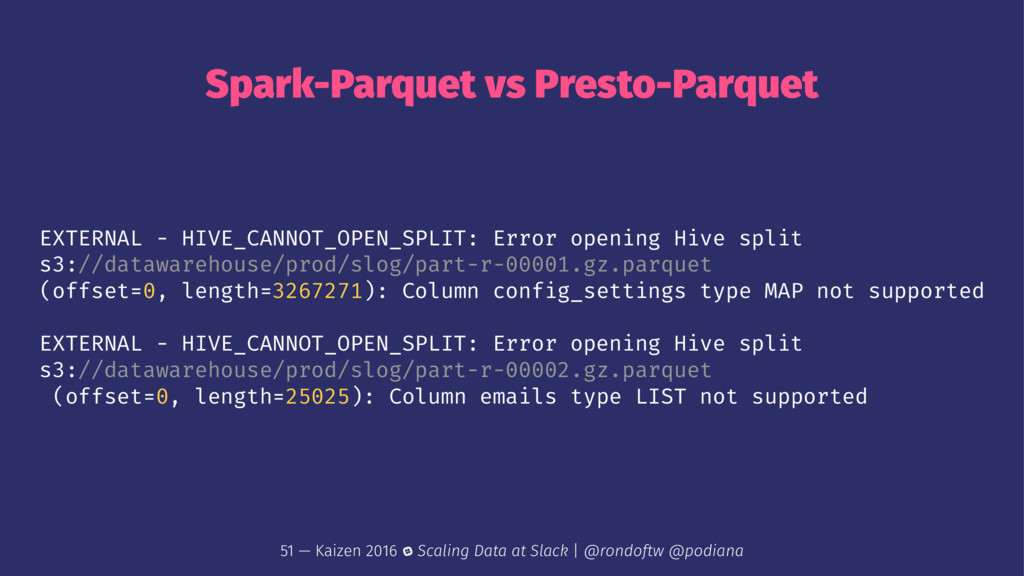
Spark-Parquet vs Presto-Parquet EXTERNAL - HIVE_CANNOT_OPEN_SPLIT: Error opening Hive split
s3://datawarehouse/prod/slog/part-r-00001.gz.parquet (offset=0, length=3267271): Column config_settings type MAP not supported EXTERNAL - HIVE_CANNOT_OPEN_SPLIT: Error opening Hive split s3://datawarehouse/prod/slog/part-r-00002.gz.parquet (offset=0, length=25025): Column emails type LIST not supported 51 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
We just want to read back the data we wrote.
All of it. 52 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
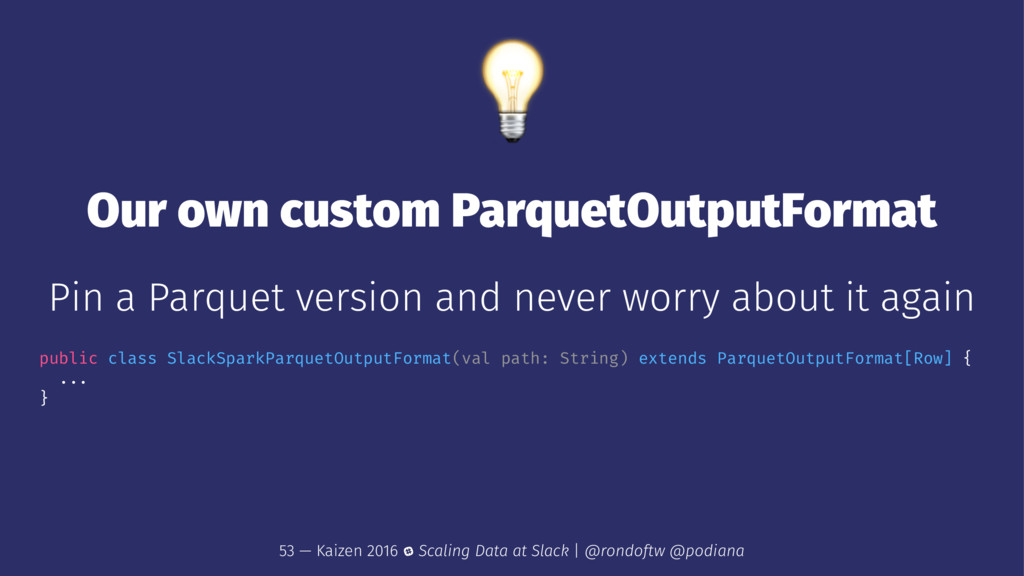
! Our own custom ParquetOutputFormat Pin a Parquet version and
never worry about it again public class SlackSparkParquetOutputFormat(val path: String) extends ParquetOutputFormat[Row] { ... } 53 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
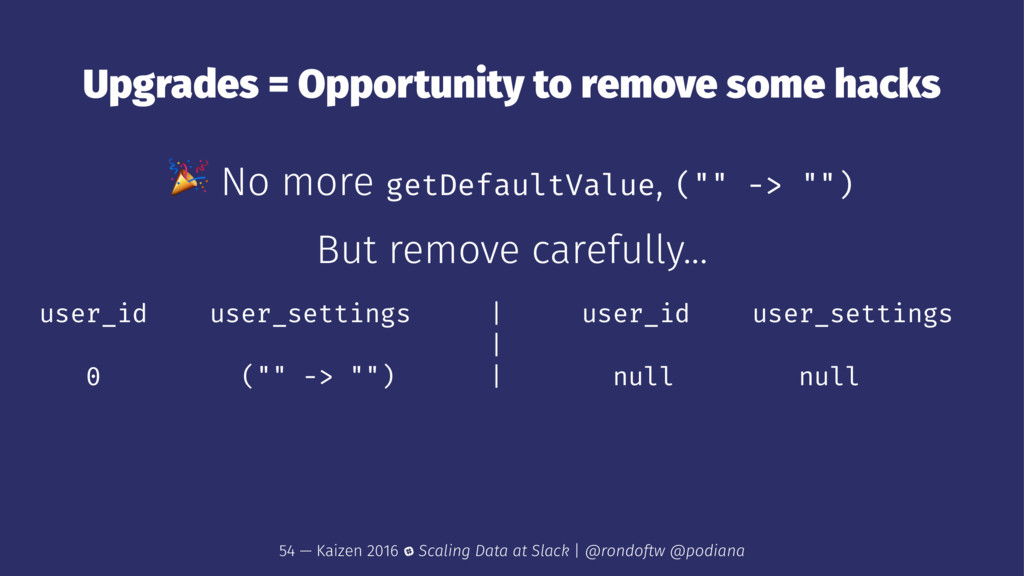
Upgrades = Opportunity to remove some hacks ! No more
getDefaultValue, ("" -> "") But remove carefully... user_id user_settings | user_id user_settings | 0 ("" -> "") | null null 54 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Watch out for unexpected events → Interactions between your tools
are more complicated than they appear → Backwards compatibility isn't always → Consequences from your previous decisions combine in strange ways 55 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Lessons learned ! Structed data & columnar format ! SQL
query engines ! Failing fast ! Never assume backwards compatibility when changing versions 56 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Lessons learned ! Investigation and job tweaking take more time
than writing the code ! If you're not running on premise, look into constraints and interop first ☔ Build for the greatest common factor of features or risk surprises 57 — Kaizen 2016 Scaling Data at Slack | @rondoftw @podiana -
Good luck! Questions? 58 — Kaizen 2016 Scaling Data at
Slack | @rondoftw @podiana
 ronnieftw
 munenick
 rfdnxbro
 k6s4i53rx
 ymotongpoo
 oracle4engineer
 ota1022
 minorun365
 harutiro
 takano0131
 hagino3000
 hatahata021
 imuta
 ryanjones
 axbom
 helmedeiros
 schlessera
 techseoconnect
 bkeepers
 jcasabona
 samanthasiow
 lara
 akosma
 nonsquared
 gr2m