Share
Embed
Algebird : Abstract Algebra for Big Data Analytics.
Devoxx 2014. Antwerp Belgium.
Tools in Action Room 4
Antwerp, Tue 11th Nov. 2014
Sam Bessalah
November 11, 2014
Transcript
51 slides
-
Algebraic Structure “ Set of values, coupled with one or
more finite operations,and a set of laws those operations must obey. “ -
Algebraic Structure “ Set of values, coupled with one or
more finite operations, and a set of laws those operations must obey. “ e.g Sum, Magma, Semigroup, Groups, Monoid, Abelian Group, Semi Lattices, Rings, Monads, etc. -
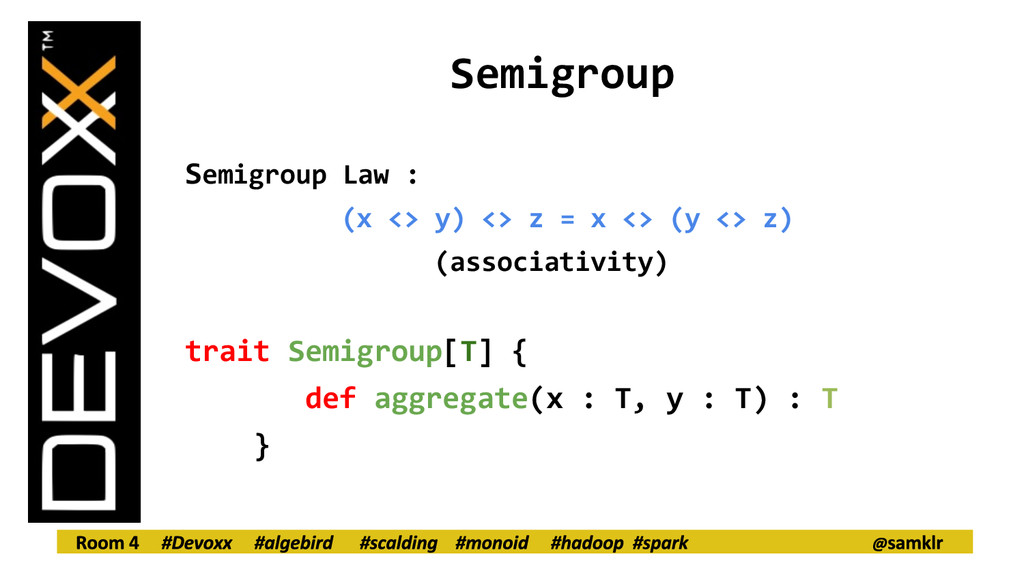
Semigroup Semigroup Law : (x <> y) <> z =
x <> (y <> z) (associativity) -
Semigroup Semigroup Law : (x <> y) <> z =
x <> (y <> z) (associativity) trait Semigroup[T] { def aggregate(x : T, y : T) : T } -
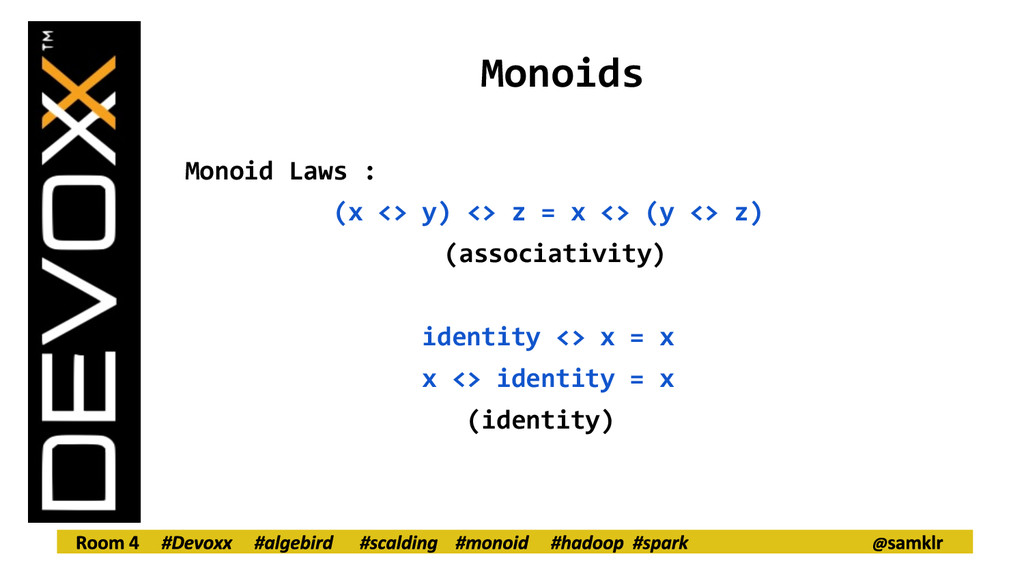
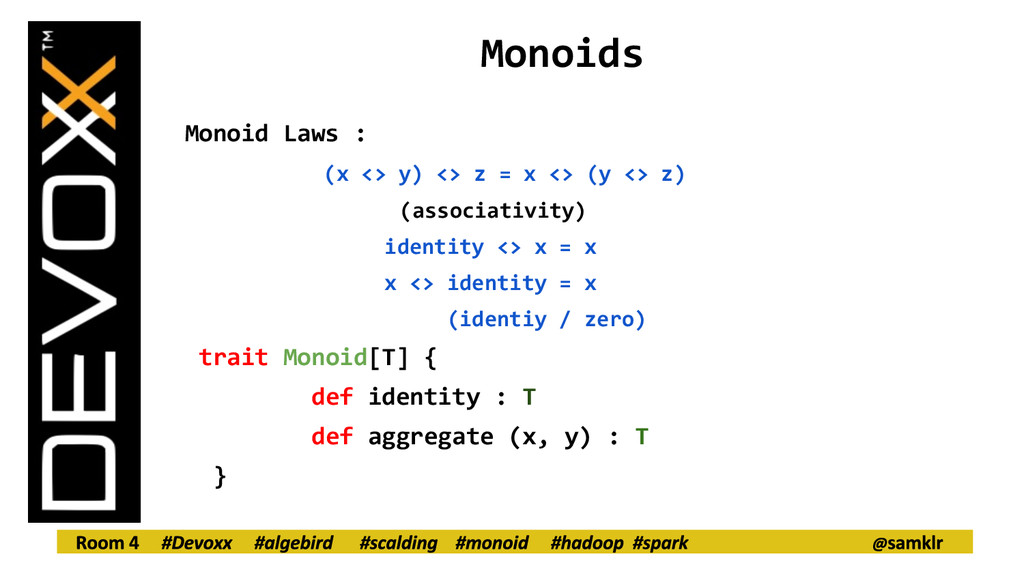
Monoids Monoid Laws : (x <> y) <> z =
x <> (y <> z) (associativity) identity <> x = x x <> identity = x (identity) -
Monoids Monoid Laws : (x <> y) <> z =
x <> (y <> z) (associativity) identity <> x = x x <> identity = x (identiy / zero) trait Monoid[T] { def identity : T def aggregate (x, y) : T } -
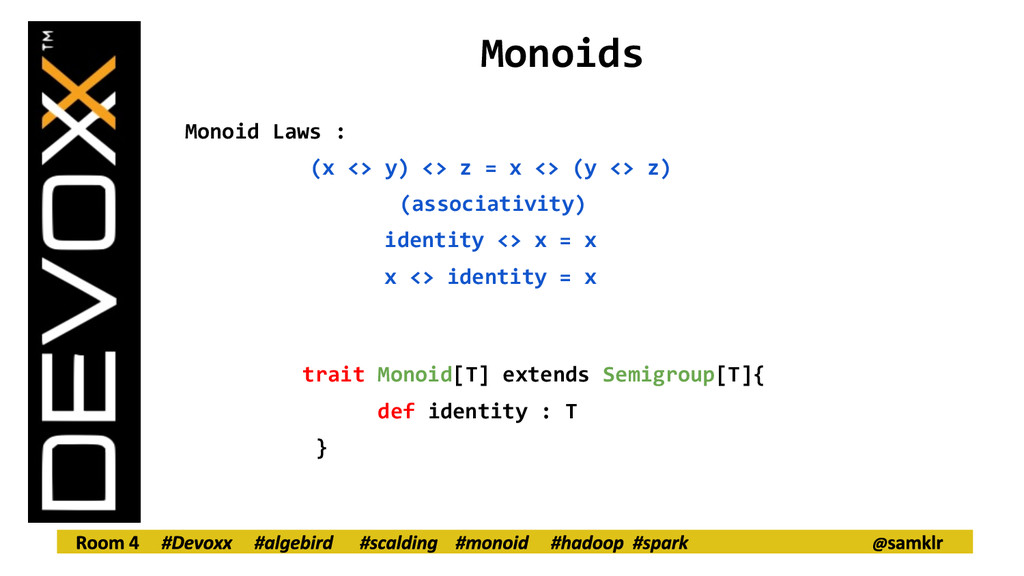
Monoids Monoid Laws : (x <> y) <> z =
x <> (y <> z) (associativity) identity <> x = x x <> identity = x trait Monoid[T] extends Semigroup[T]{ def identity : T } -
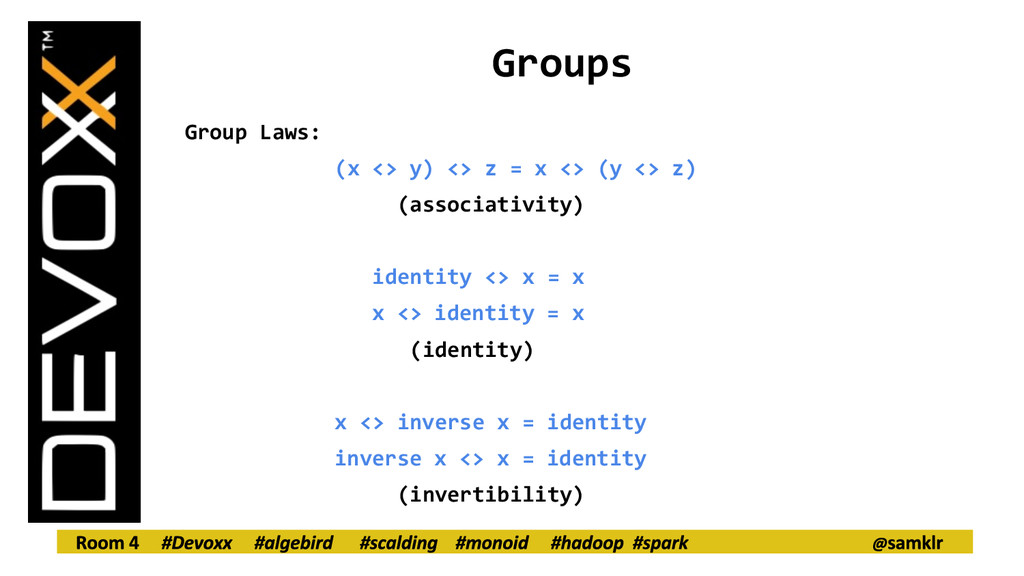
Groups Group Laws: (x <> y) <> z = x
<> (y <> z) (associativity) identity <> x = x x <> identity = x (identity) x <> inverse x = identity inverse x <> x = identity (invertibility) -
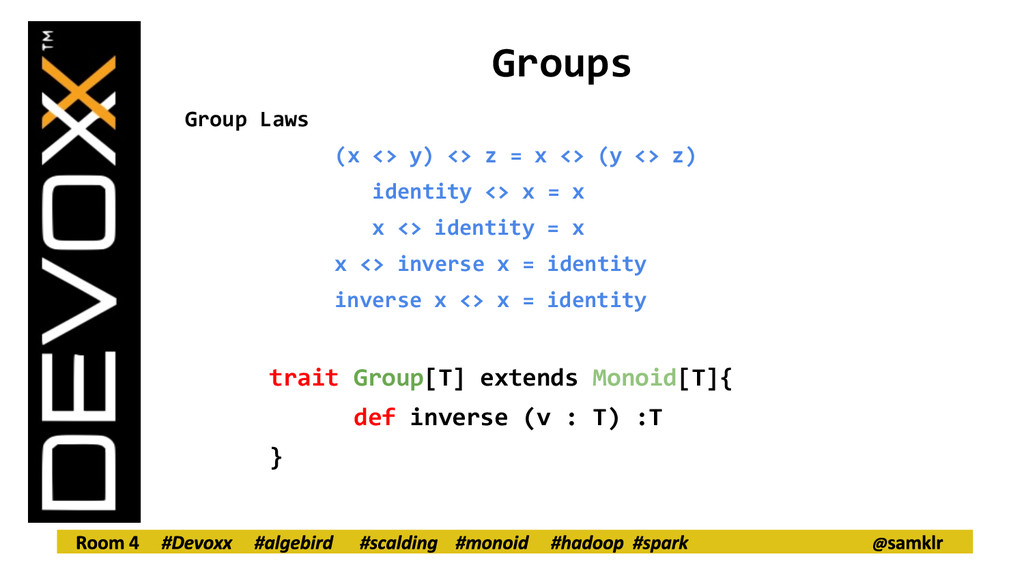
Groups Group Laws (x <> y) <> z = x
<> (y <> z) identity <> x = x x <> identity = x x <> inverse x = identity inverse x <> x = identity trait Group[T] extends Monoid[T]{ def inverse (v : T) :T } -
Many More - Abelian groups (Commutative Sets) - Rings -
Semi Lattices - Ordered Semigroups - Fields .. Many of those are in Algebird …. -
Examples - (a min b) min c = a (b
min c) with Int. - a max ( b max c) = (a max b) max c ** - a or (b or c) = (a or b) or c - a and (b and c) = (a and b) and c - int addition - set union - harmonic sum - Integer mean - Priority queue -
We want to : - Build scalable analytics systems -
Leverage distributed computing to perform aggregation on really large data sets. - A lot of operations in analytics are just sorting and counting at the end of the day -
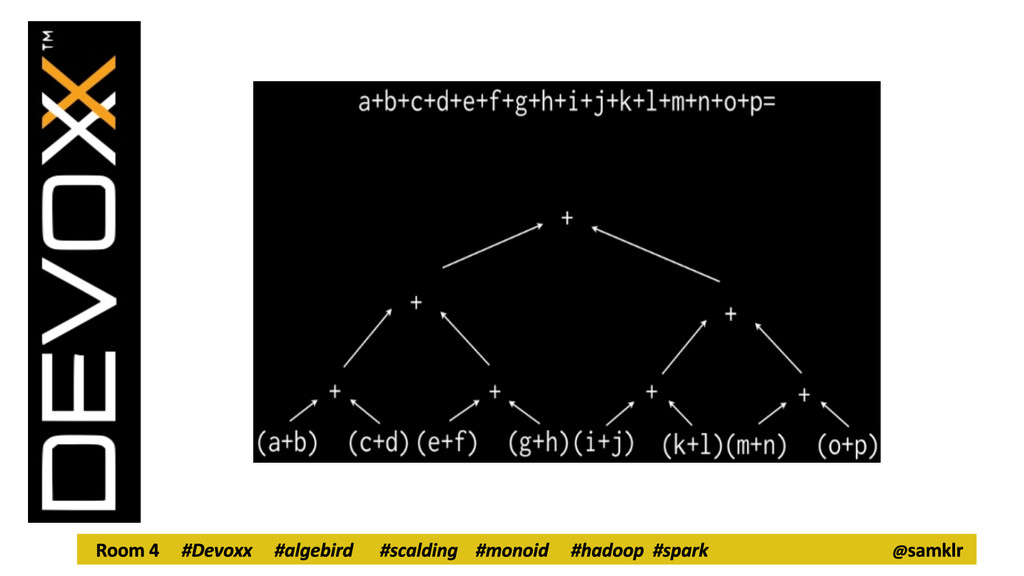
Distributed Computing → Parallellism Associativity enables parallelism Identity means we
can ignore some data Commutativity helps us ignore order -
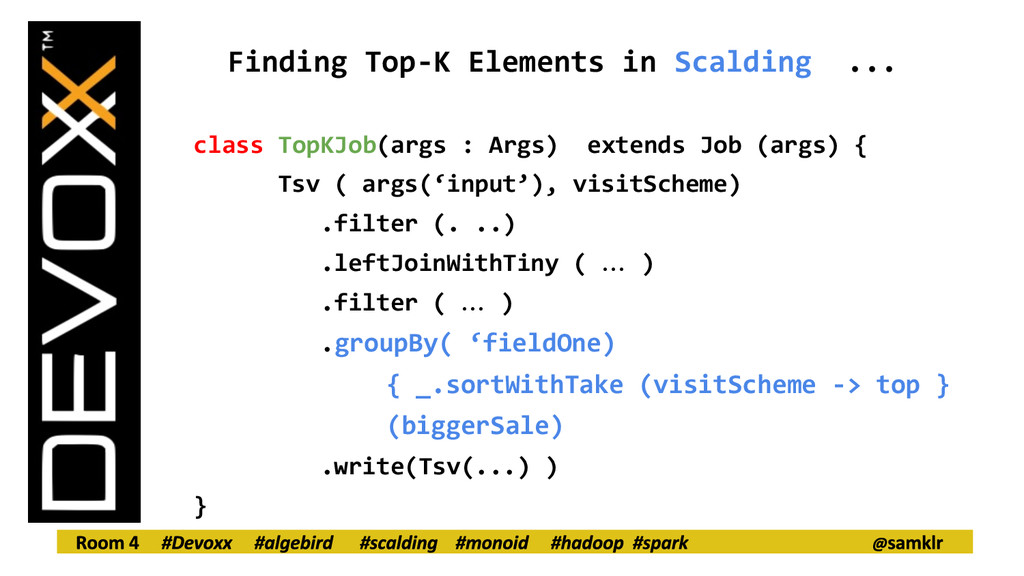
Finding Top-K Elements in Scalding ... class TopKJob(args : Args)
extends Job (args) { Tsv ( args(‘input’), visitScheme) .filter (. ..) .leftJoinWithTiny ( … ) .filter ( … ) .groupBy( ‘fieldOne) { _.sortWithTake (visitScheme -> top } (biggerSale) .write(Tsv(...) ) } -
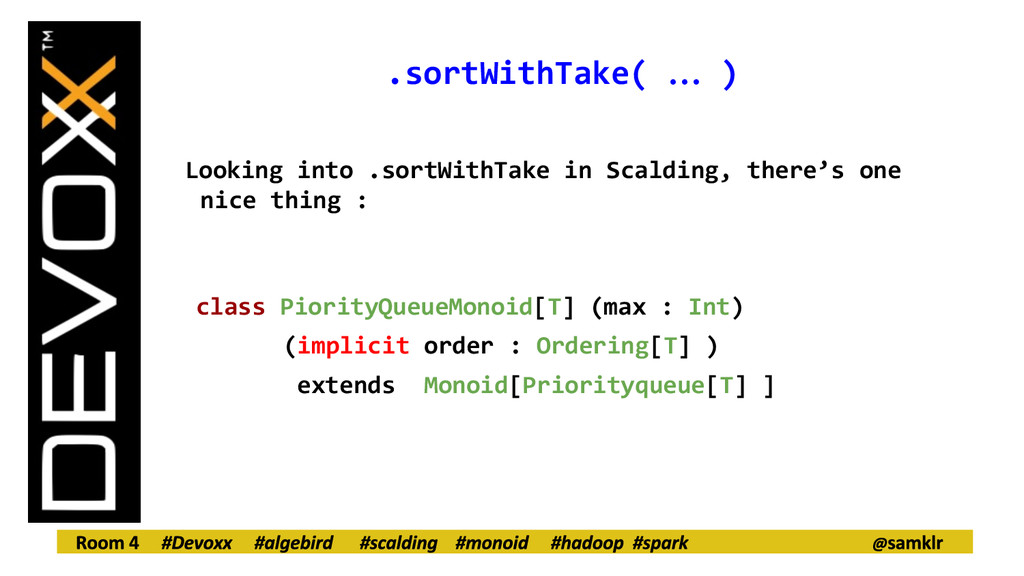
.sortWithTake( … ) Looking into .sortWithTake in Scalding, there’s one
nice thing : class PiorityQueueMonoid[T] (max : Int) (implicit order : Ordering[T] ) extends Monoid[Priorityqueue[T] ] -
class PiorityQueueMonoid[T] (max : Int) (implicit order : Ordering[T] )
extends Monoid[Priorityqueue[T] ] Let’s take a look : PQ1 : 55, 45, 21, 3 PQ2: 100, 80, 40, 3 top-4 (PQ1 U PQ2 ): 100, 80, 55, 45 Priority Queue : Can be empty Two Priority Queues can be “added” in any order Associative + Commutative -
class PiorityQueueMonoid[T] (max : Int) (implicit order : Ordering[T] )
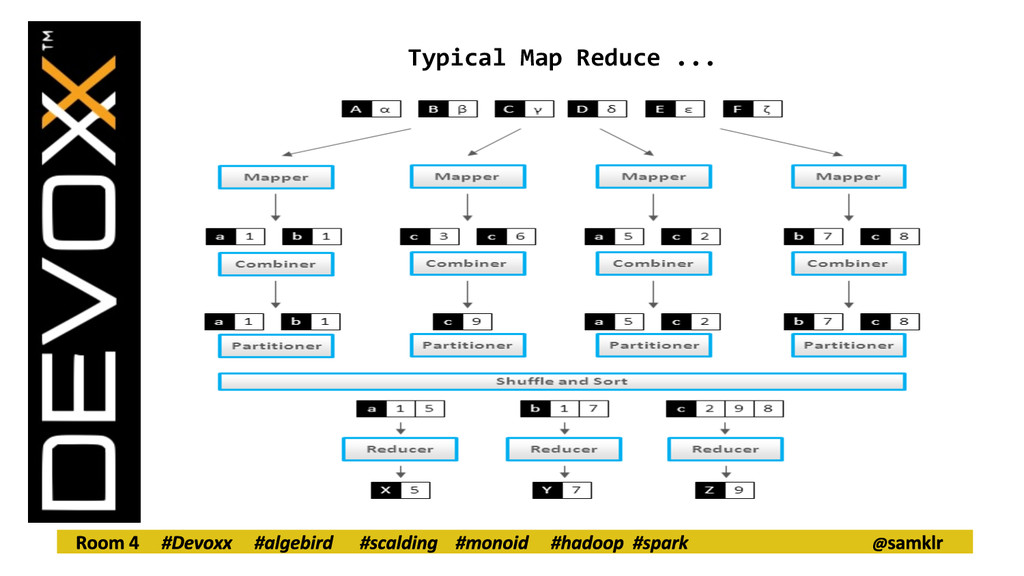
extends Monoid[Priorityqueue[T] ] Let’s take a look : PQ1 : 55, 45, 21, 3 PQ2: 100, 80, 40, 3 top-4 (PQ1 U PQ2 ): 100, 80, 55, 45 Priority Queue : Can be empty Two Priority Queues can be “added” in any order Associative + Commutative Makes Scalding go fast, by doing sorting, filtering and extracting in one single “map” step. -
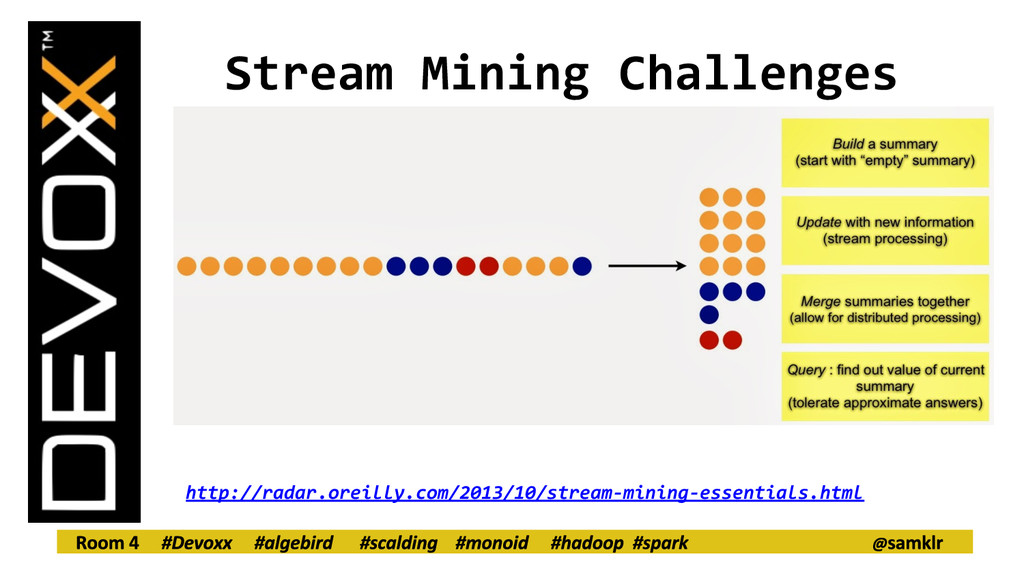
Stream Mining Challenges - Update predictions after each observation -
Single pass : can’t read old data or replay the stream - Full size of the stream often unknown - Limited time for computation per observation - O(1) memory size -
Sketches Probabilistic data structures that store a summary (hashed mostly)of
a data set that would be costly to store in its entirety, thus providing most of the time, sublinear algorithmic properties. E.g Bloom Filters, Counter Sketch, KMV counters, Count Min Sketch, HyperLogLog, Min Hashes -
Bloom filters Approximate data structure for set membership Behaves like
an approximate set BloomFilter.contains(x) => NO | Maybe P(False Positive) > 0 P(False Negative) = 0 -
Internally : Bit Array of fixed size add(x) : for
all element i, b[h(x,i)]=1 contains(x) : TRUE if b[h(x,i)] = = 1 for all i. (Boolean AND => associative) Both are associative => BF can be designed as a Monoid -
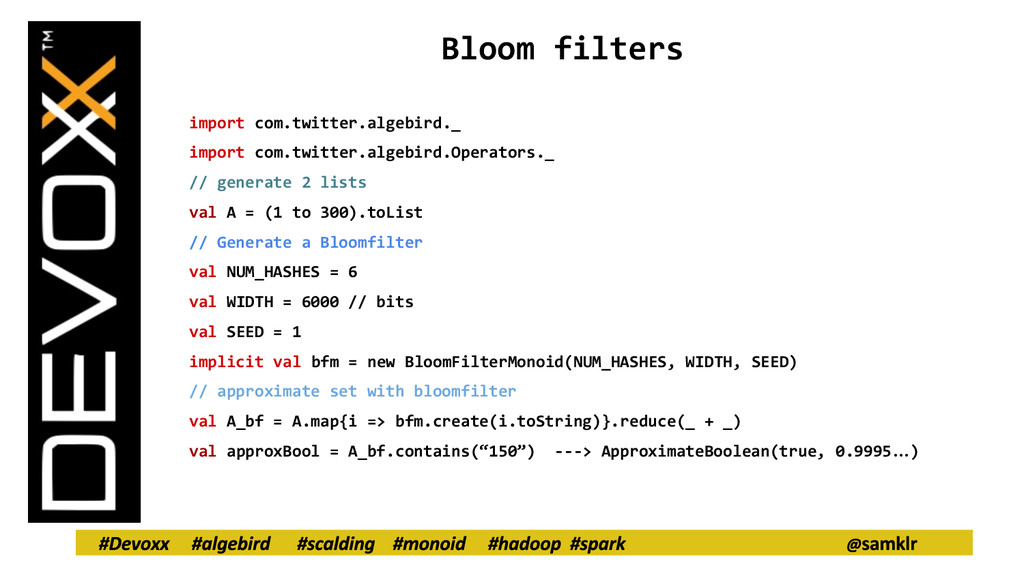
Bloom filters import com.twitter.algebird._ import com.twitter.algebird.Operators._ // generate 2 lists
val A = (1 to 300).toList // Generate a Bloomfilter val NUM_HASHES = 6 val WIDTH = 6000 // bits val SEED = 1 implicit val bfm = new BloomFilterMonoid(NUM_HASHES, WIDTH, SEED) // approximate set with bloomfilter val A_bf = A.map{i => bfm.create(i.toString)}.reduce(_ + _) val approxBool = A_bf.contains(“150”) ---> ApproximateBoolean(true, 0.9995…) -
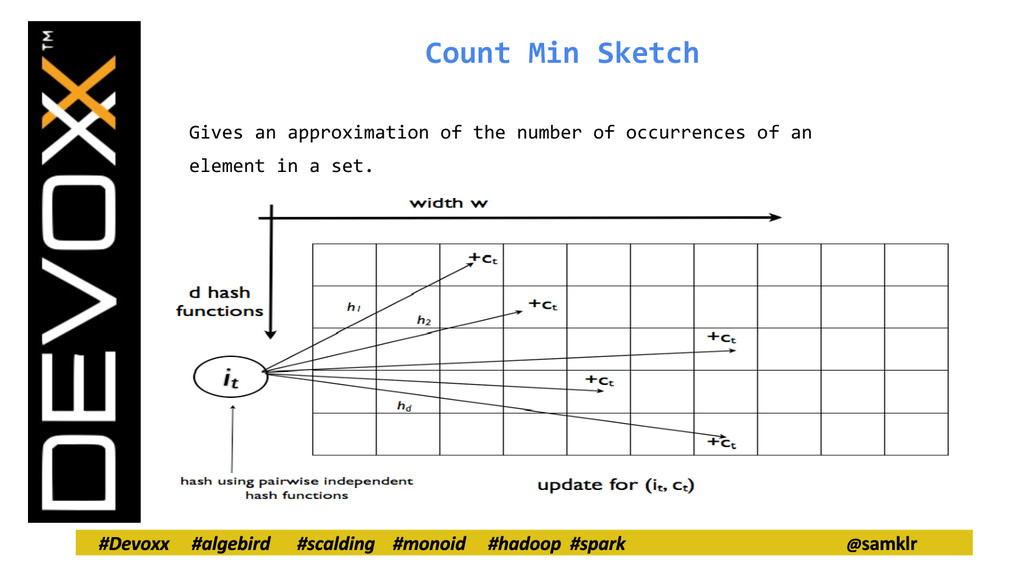
Count Min Sketch Gives an approximation of the number of
occurrences of an element in a set. -
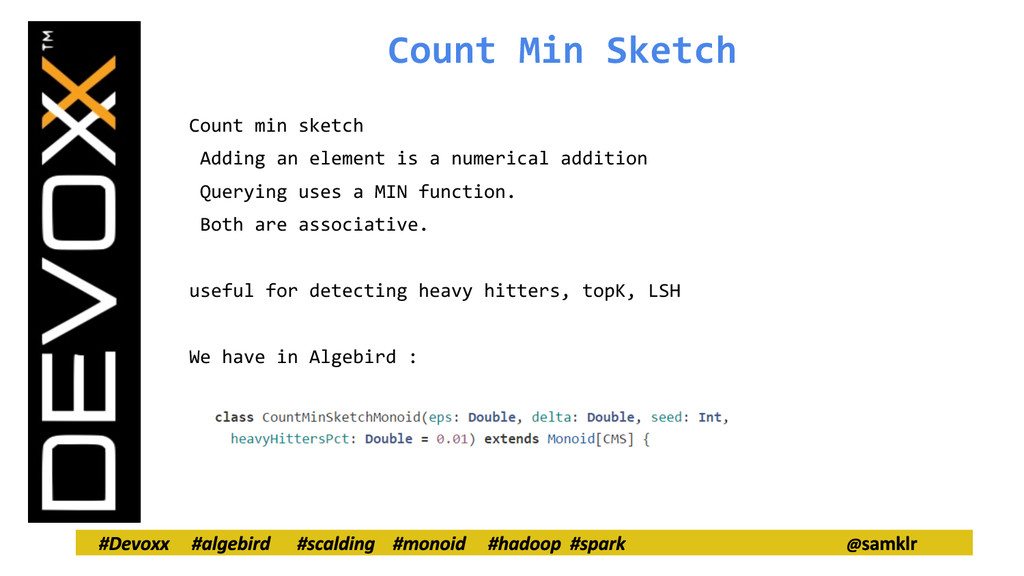
Count Min Sketch Count min sketch Adding an element is
a numerical addition Querying uses a MIN function. Both are associative. useful for detecting heavy hitters, topK, LSH We have in Algebird : -
HyperLogLog Popular sketch for cardinality estimtion. Gives within a probilistic
distribution of an error the number of distinct values in a data set. HLL.size = Approx[Number] Intuition Long runs of trailings 0 in a random bits chain are rare But the more bit chains you look at, the more likely you are to find a long one The longest run of trailing 0-bits seen can be an estimator of the number of unique bit chains observed. -
Adding an element uses a Max and Sum function. Both
are associative and Monoids. (Max is an ordered semigroup in Algebird really) Querying for an element uses an harmonic mean which is a Monoid. In Algebird : -
Many More juicy sketches ... - MinHashes to compute Jaccard
similarity - QTree for quantiles estimation. Neat for anomaly detection. - SpaceSaverMonoid, Awesome to find the approximate most frequent and top K elements. - TopKMonoid - SGD, PriorityQueues, Histograms, etc. -
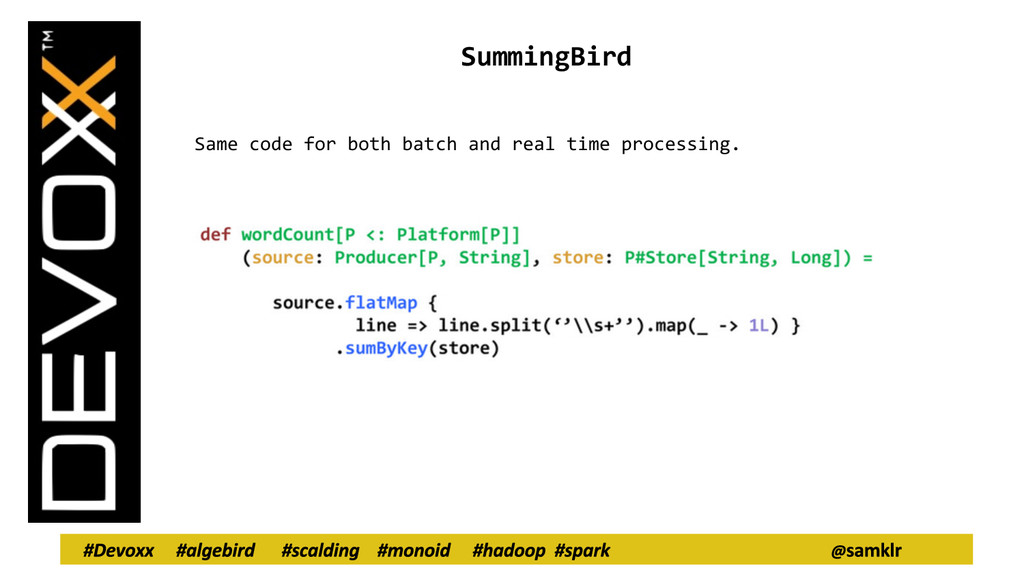
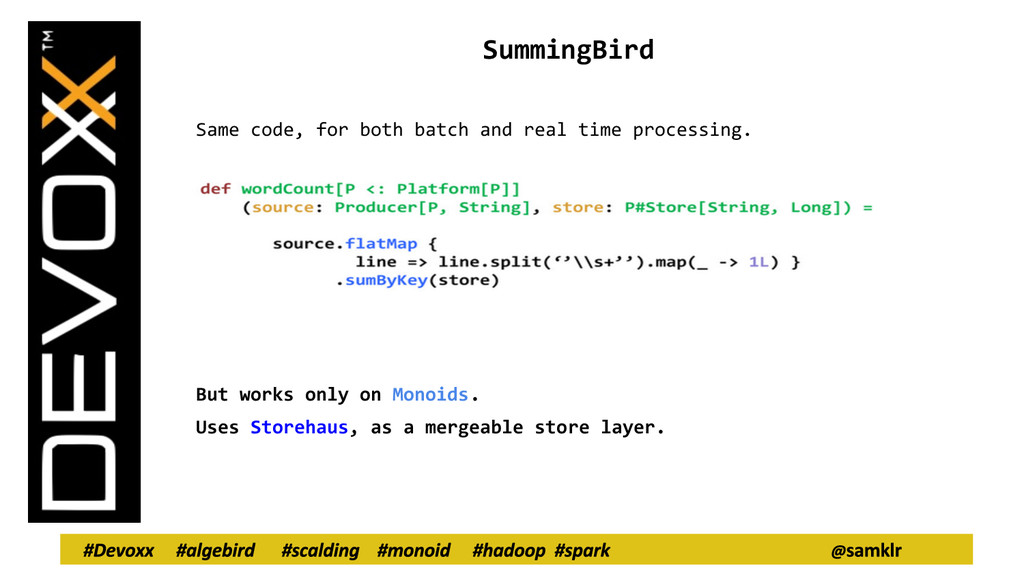
SummingBird Same code, for both batch and real time processing.
But works only on Monoids. Uses Storehaus, as a mergeable store layer. -
-Algebra for analytics by Oscar Boykin (Creator of Algebird) http://speakerdeck.com/johnynek/algebra-for-analytics
- Take a look into HLearn https://github.com/mikeizbicki/HLearn - Great intro into Algebird by Michael Noll http://www.michael-noll.com/blog/2013/12/02/twitter-algebird-monoid- monad-for-large-scala-data-analytics/ -Aggregate Knowledge http://research.neustar.biz/2012/10/25/sketch-of- the-day-hyperloglog-cornerstone-of-a-big-data-infrastructure - Probabilistic data structures for web analytics. http://highlyscalable.wordpress.com/2012/05/01/probabilistic- structures-web-analytics-data-mining/ - http://debasishg.blogspot.fr/2014/01/count-min-sketch-data- structure-for.html - http://infolab.stanford.edu/~ullman/mmds/ch3.pdf Links