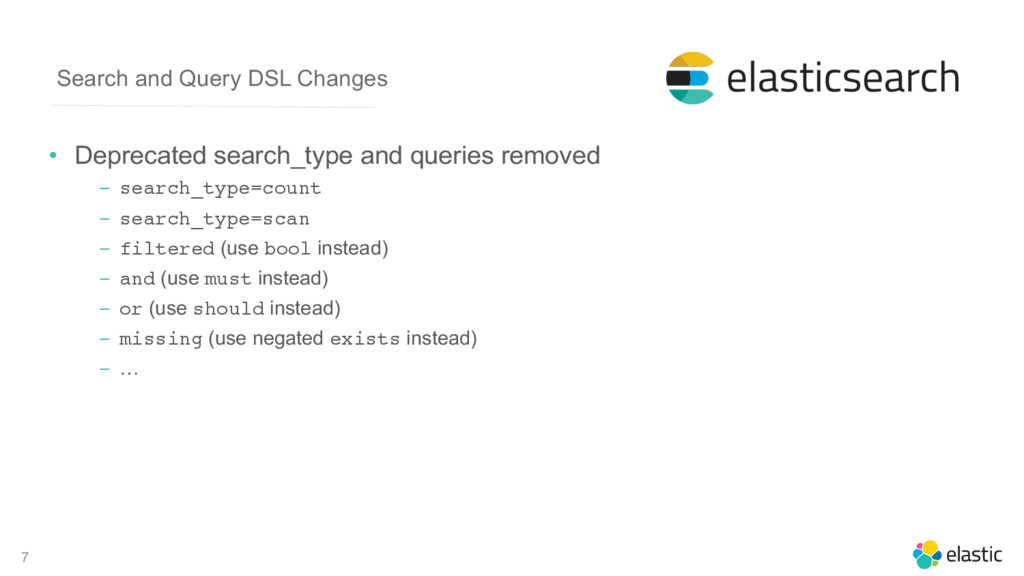
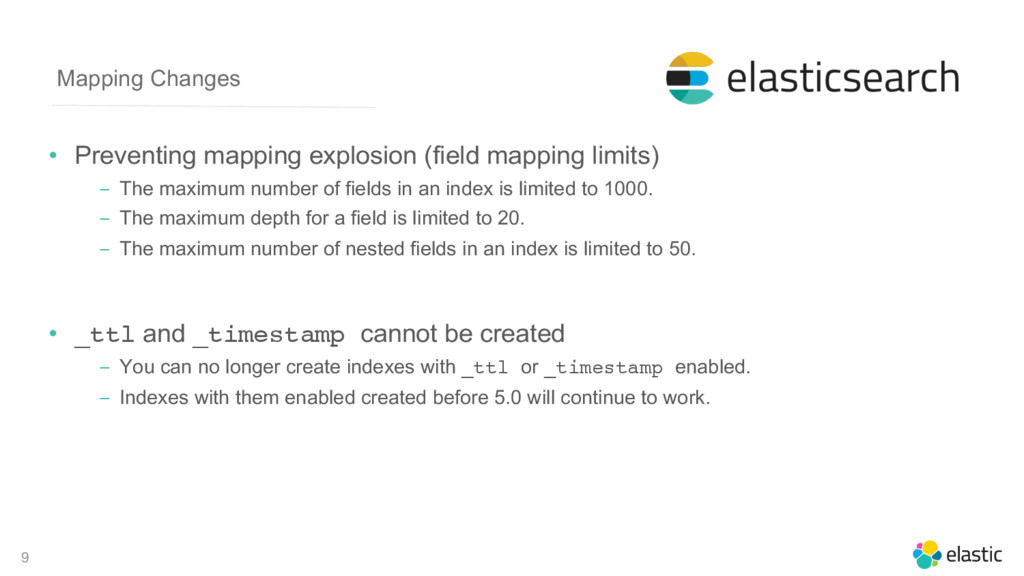
‒ The maximum number of fields in an index is limited to 1000. ‒ The maximum depth for a field is limited to 20. ‒ The maximum number of nested fields in an index is limited to 50. • _ttl and _timestamp cannot be created ‒ You can no longer create indexes with _ttl or _timestamp enabled. ‒ Indexes with them enabled created before 5.0 will continue to work.
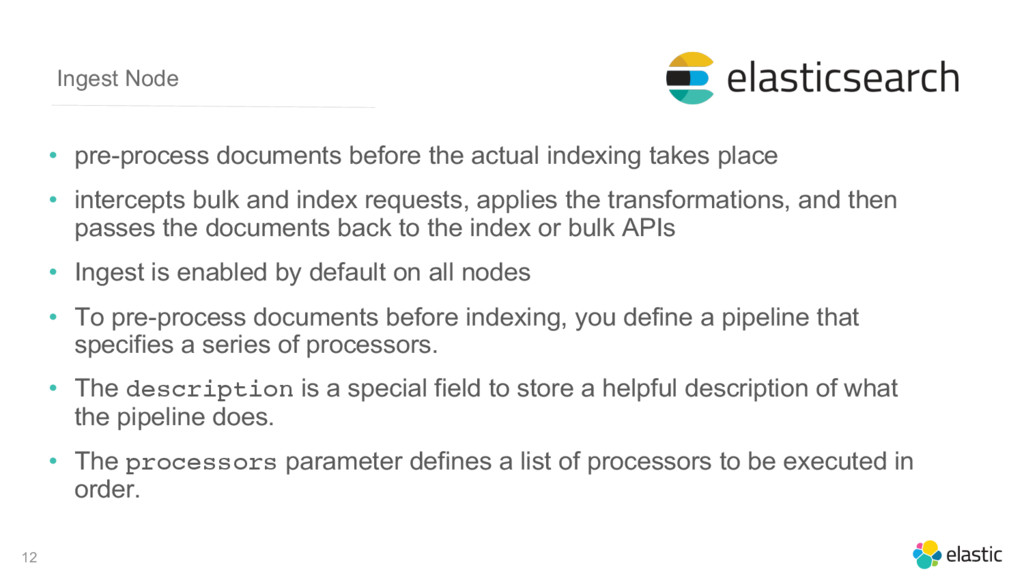
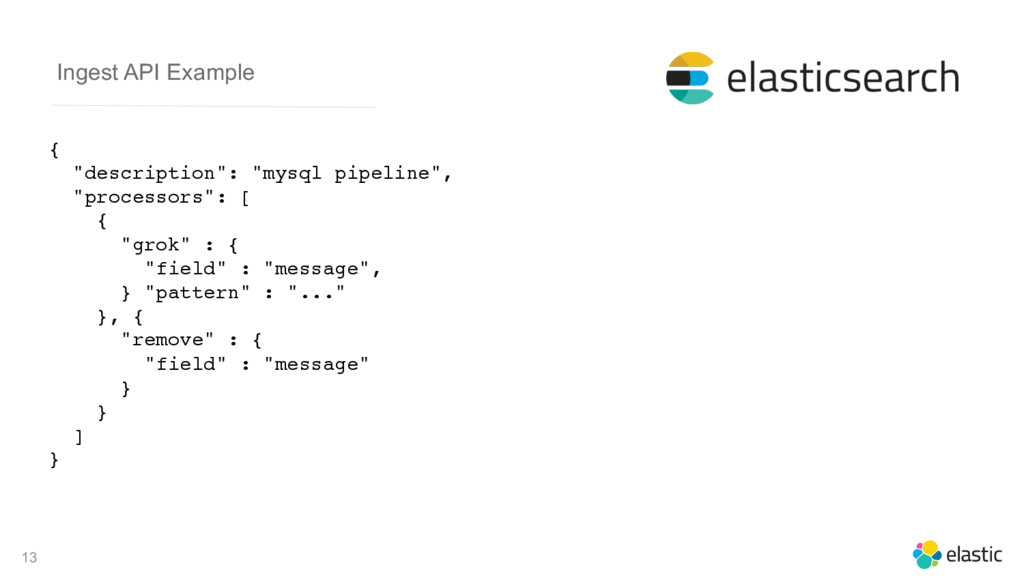
takes place • intercepts bulk and index requests, applies the transformations, and then passes the documents back to the index or bulk APIs • Ingest is enabled by default on all nodes • To pre-process documents before indexing, you define a pipeline that specifies a series of processors. • The description is a special field to store a helpful description of what the pipeline does. • The processors parameter defines a list of processors to be executed in order.
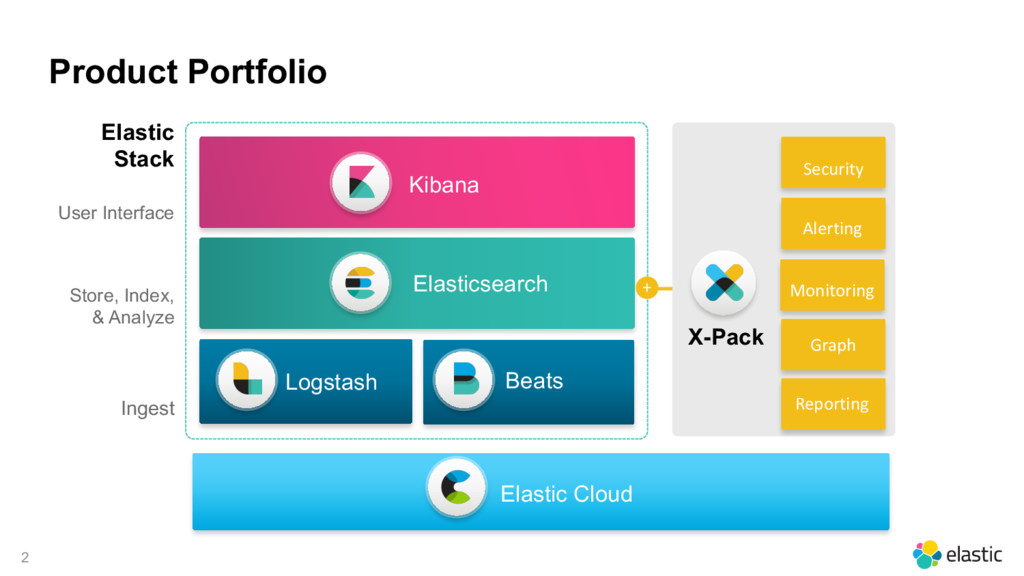
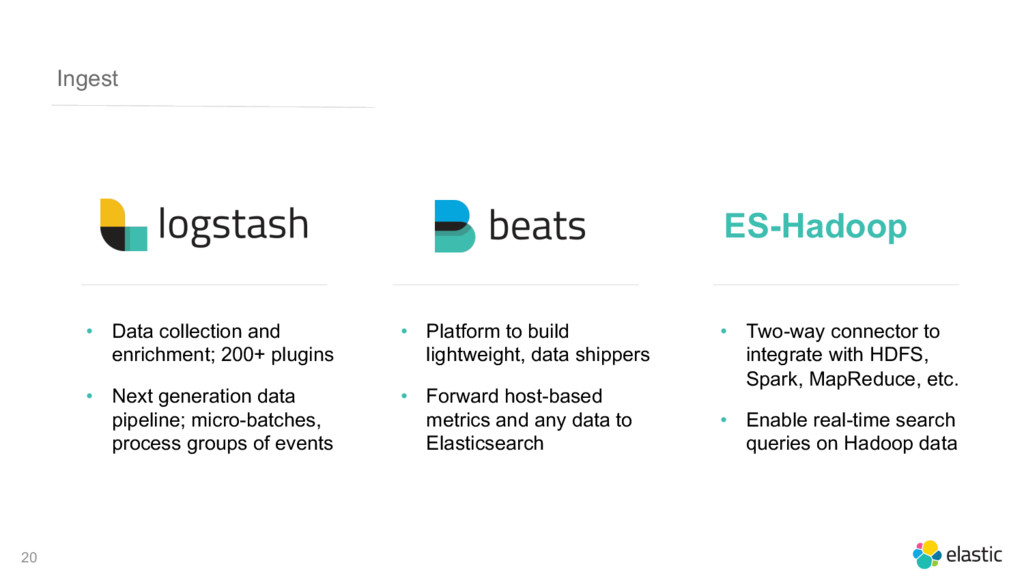
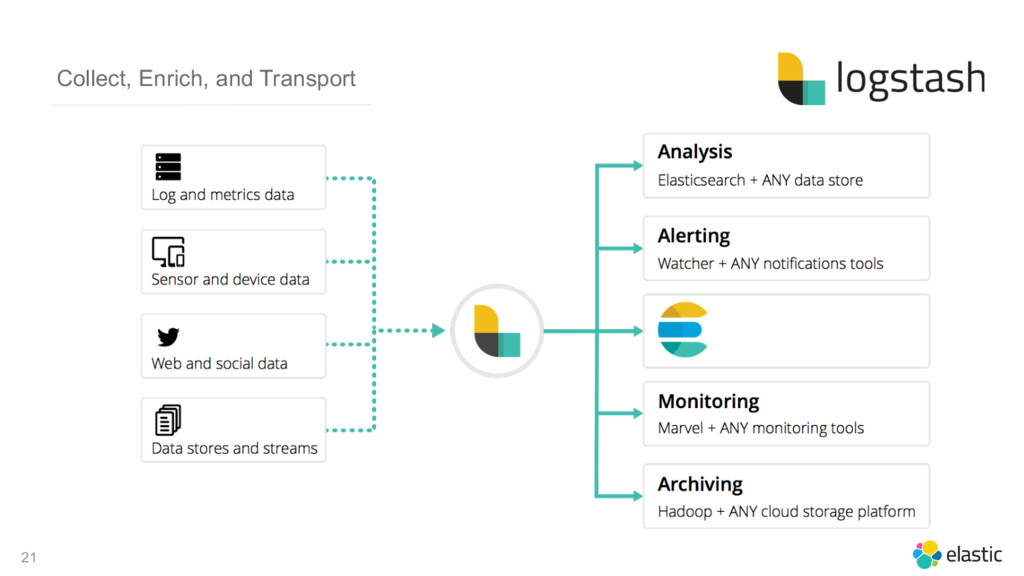
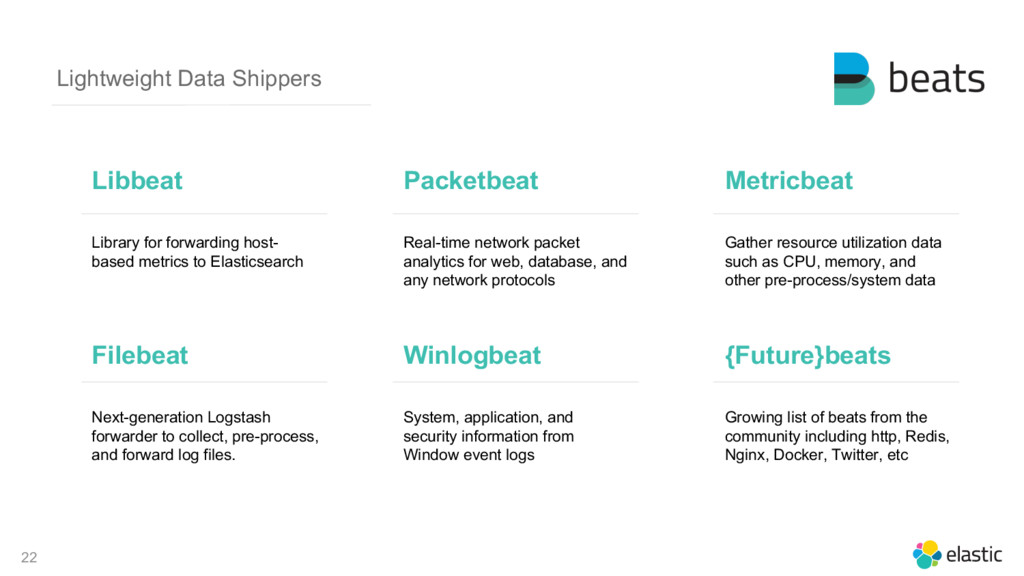
Next generation data pipeline; micro-batches, process groups of events ES-Hadoop • Platform to build lightweight, data shippers • Forward host-based metrics and any data to Elasticsearch • Two-way connector to integrate with HDFS, Spark, MapReduce, etc. • Enable real-time search queries on Hadoop data
to Elasticsearch Libbeat Packetbeat Metricbeat Real-time network packet analytics for web, database, and any network protocols Gather resource utilization data such as CPU, memory, and other pre-process/system data Next-generation Logstash forwarder to collect, pre-process, and forward log files. Filebeat Winlogbeat {Future}beats System, application, and security information from Window event logs Growing list of beats from the community including http, Redis, Nginx, Docker, Twitter, etc


 y0hgi
 kishida
 tmikov2023
 mixplace
 iwiwi
 nokomoro3
 rollbear
 o0h
 uyuki234
 clockmaker
 andpad
 michaelherold
 mlcsv
 rkendrick25
 katiecoart
 ivargrimstad
 rocio
 tammyeverts
 coloredviolet
 scottboms
 jeffersonlam
 427marketing
 rabernat