Share
Embed
Web Scraping Best Practises
Python is a fantastic language for writing web scrapers. There is a large ecosystem of useful projects and a great developer community. However, it can be confusing once you go beyond the simpler scrapers typically covered in tutorials.
In this talk, from EuroPython 2015, we explore some common real-world scraping tasks. You will learn best practises and get a deeper understanding of what tools and techniques can be used and how to deal with the most challenging of web scraping projects.
Shane Evans
July 21, 2015
Transcript
49 slides
-
About Shane • 12y python, 8y scraping • Scrapy, Portia,
Frontera.. • Co-founded Scrapinghub -
Why Scrape? Sources of data -> Internet vast amount of
data APIs - Availability, Limited Data, Throttling, Privacy The web is broken - microdata, microformats, RDFa Endless use cases: monitor prices, leads generation, e- commerce, research, specialized news... -
Badly Written Bots Bots can: • use excessive website resources
• be unreliable • be hard to maintain -
What is Web Scraping A technique of extracting information from
websites includes: • downloading web pages (which may involve crawling - extracting and following links) • Scraping - extracting data from downloaded pages -
Web Scraping Example Our jobs get scraped and posted to
jobs websites the day they are published! How would you build that web scraper? Scrapinghub gets scraped all the time -
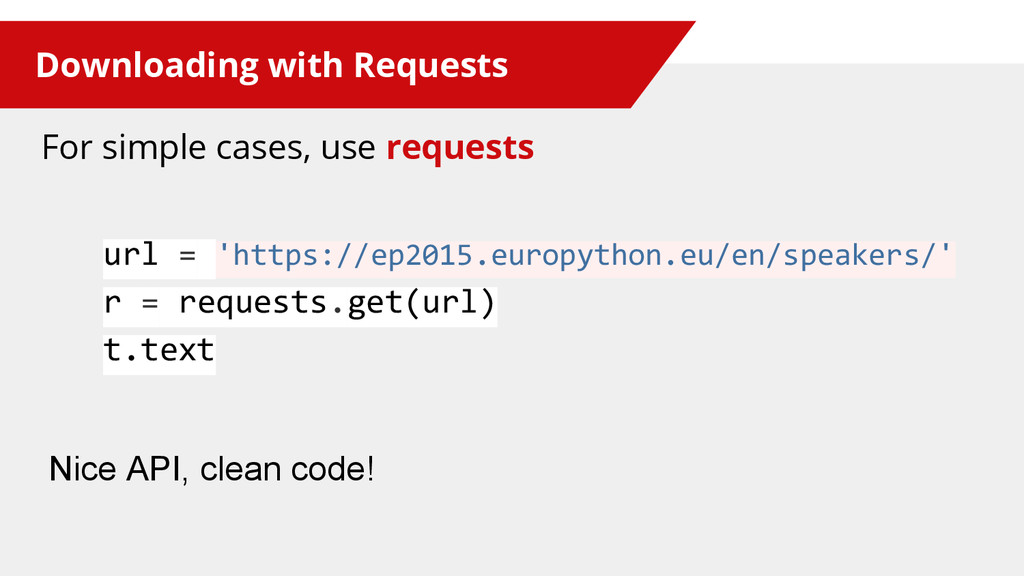
Downloading with Requests For simple cases, use requests url =
'https://ep2015.europython.eu/en/speakers/' r = requests.get(url) t.text Nice API, clean code! -
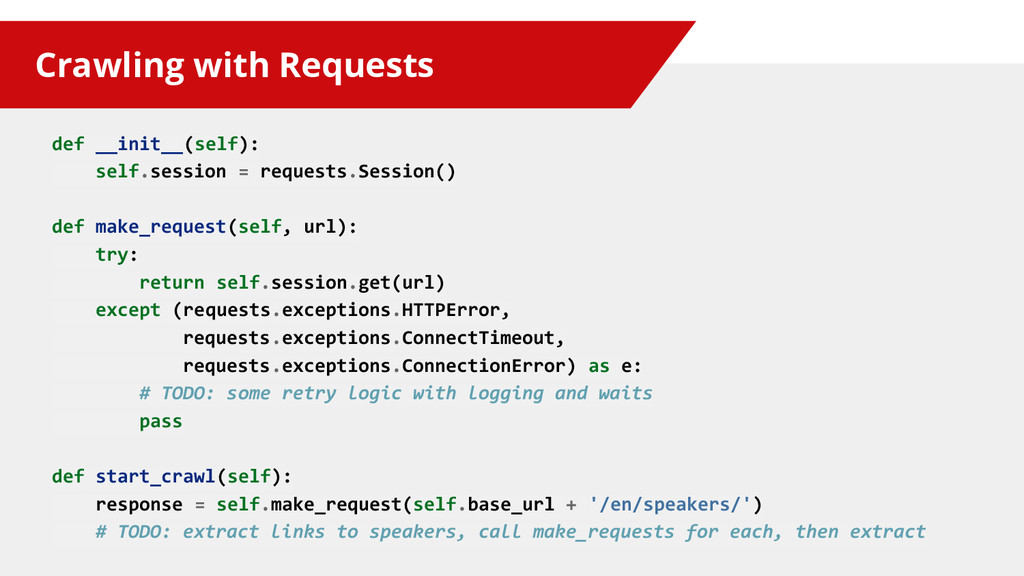
Crawling with Requests def __init__(self): self.session = requests.Session() def make_request(self,
url): try: return self.session.get(url) except (requests.exceptions.HTTPError, requests.exceptions.ConnectTimeout, requests.exceptions.ConnectionError) as e: # TODO: some retry logic with logging and waits pass def start_crawl(self): response = self.make_request(self.base_url + '/en/speakers/') # TODO: extract links to speakers, call make_requests for each, then extract -
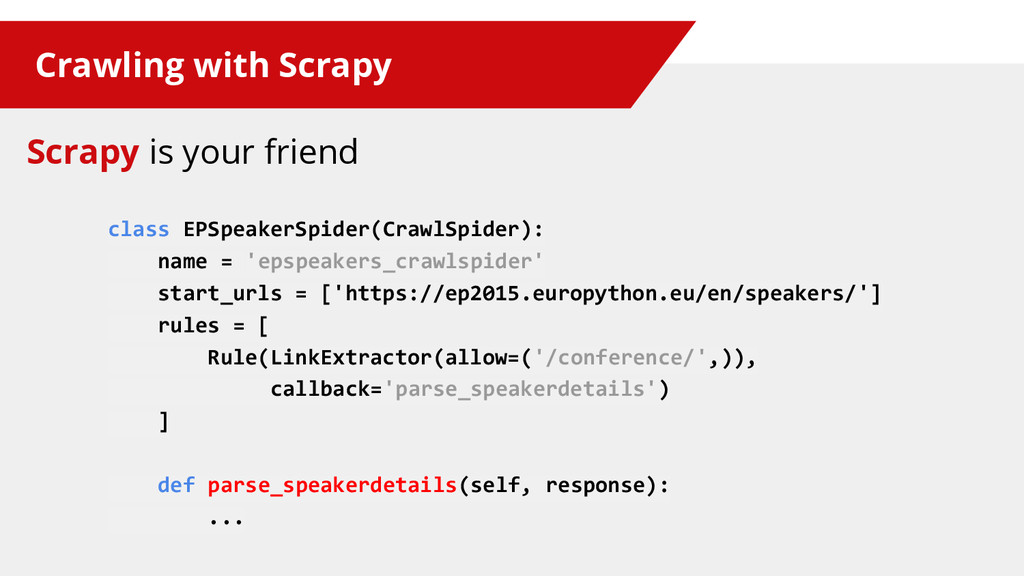
Crawling with Scrapy class EPSpeakerSpider(CrawlSpider): name = 'epspeakers_crawlspider' start_urls =
['https://ep2015.europython.eu/en/speakers/'] rules = [ Rule(LinkExtractor(allow=('/conference/',)), callback='parse_speakerdetails') ] def parse_speakerdetails(self, response): ... Scrapy is your friend -
Crawling Multiple Websites • Separate spiders for each different website
(or crawl logic) • Common logic in appropriate places (middlewares, item loaders, etc.) • lots more: tool support, common patterns, etc. See demo at https://github.com/scrapinghub/pycon-speakers Scrapy encourages best practices for scraping multiple websites: -
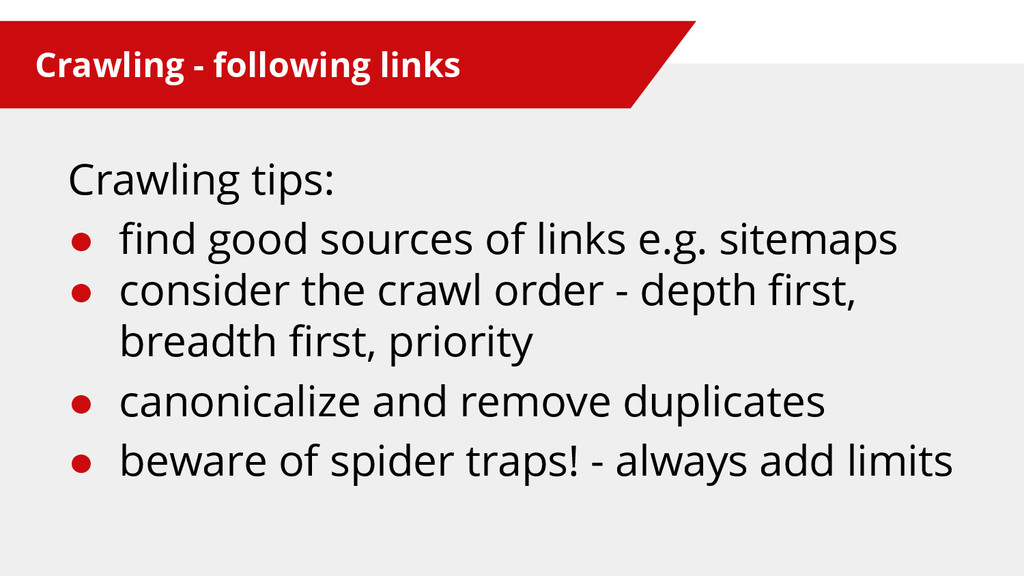
Crawling - following links Crawling tips: • find good sources
of links e.g. sitemaps • consider the crawl order - depth first, breadth first, priority • canonicalize and remove duplicates • beware of spider traps! - always add limits -
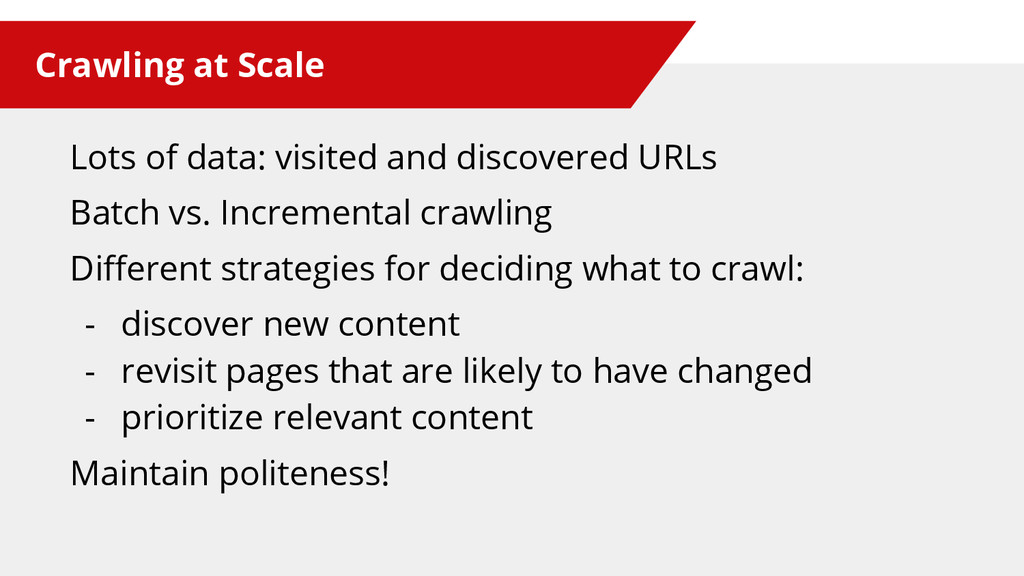
Crawling at Scale Lots of data: visited and discovered URLs
Batch vs. Incremental crawling Different strategies for deciding what to crawl: - discover new content - revisit pages that are likely to have changed - prioritize relevant content Maintain politeness! -
Frontera • open source crawl frontier library, written in python
• python API, or integrated with Scrapy • multiple crawl ordering algorithms (priority, HITS, pagerank, etc.) • configurable back ends: ◦ integrated or distributed ◦ different crawl orderings ◦ sqlite, hbase, etc. • works at scale -
Downloading Summary • requests is a great library for HTTP
• scrapify early, especially if you do any crawling • frontera for advanced URL orderings or larger scale crawling -
Extraction - Standard Library We have a great standard library:
• string handling: slice, split, strip, lower, etc. • regular expressions Usually used with other techniques -
Extraction - HTML Parsers HTML Parsers are the go-to tools
for web scrapers! Useful when data can be extracted via the structure of the HTML document -
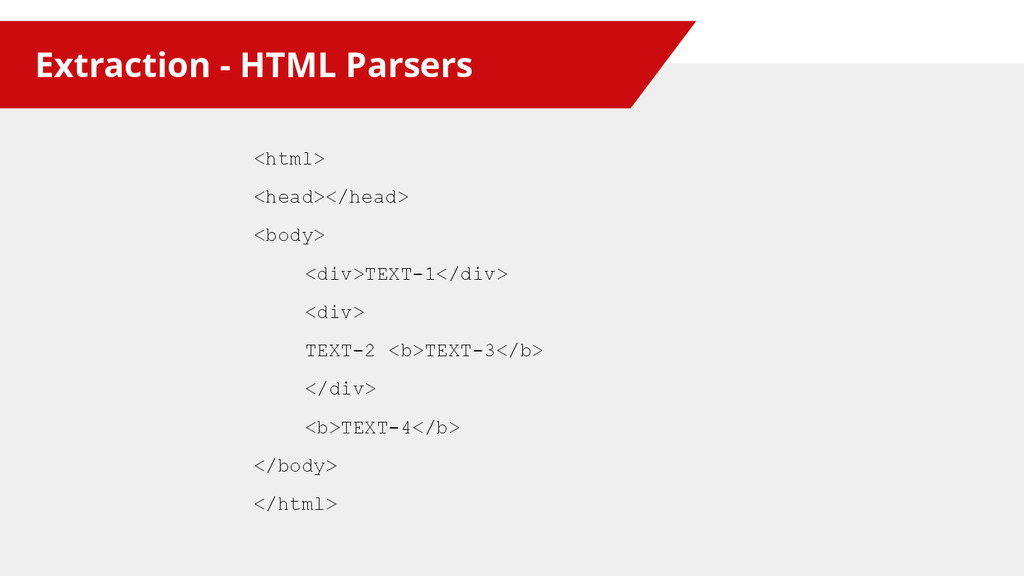
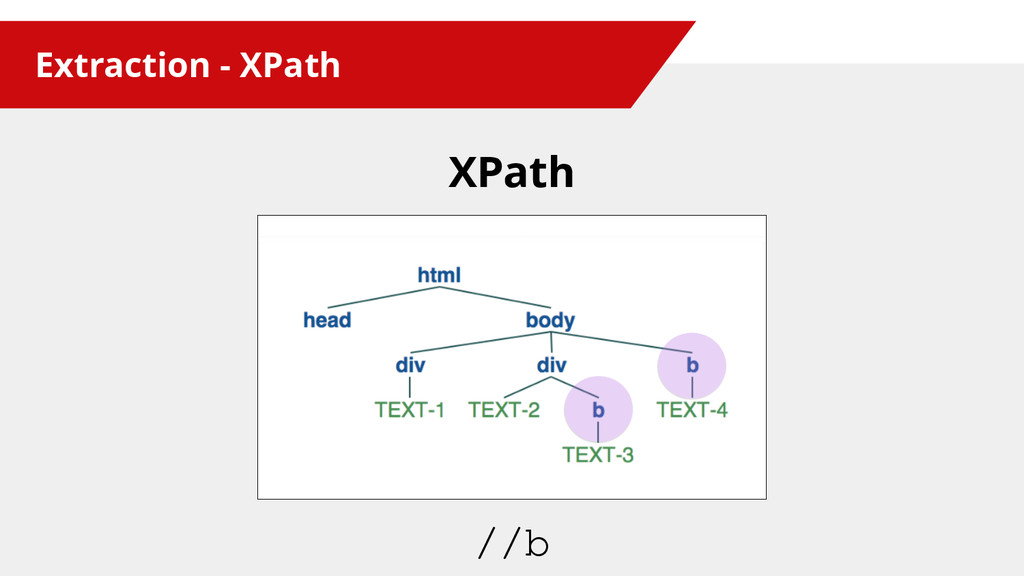
Extraction - HTML Parsers <html> <head></head> <body> <div>TEXT-1</div> <div> TEXT-2
<b>TEXT-3</b> </div> <b>TEXT-4</b> </body> </html> -
Scrapy Selectors name = response.xpath('//section[@class="profile-name"]//h1/text()').extract_first() avatar = response.urljoin(response.xpath('//img[@class="avatar"]/@src').extract_first() for talk
in response.xpath('//div[@class="speaker-talks well"]//li'): talk_title = talk.xpath('.//text()').extract_first() xpath using Scrapy selectors -
BeautifulSoup name = soup.find('section', attrs={'class': 'profile-name'}).h1.text item['avatar'] = self.base_url +
soup.find('img', attrs={'class': 'avatar'})['src'] for talk in soup.find('div', attrs={'class': 'speaker-talks well'}).dl.dd.ul.li: title = talk.text BeautifulSoup uses python objects to interact with the parse tree -
Someone might have solved it! Don’t reinvent the wheel! Lots
of small tools that can make your life easier, for example: • Scrapy loginform fills in login forms • dateparser - parse text dates • webpager helps with pagination -
Visual Data Extraction Portia is a Visual Scraper written in
Python! • train by annotating web pages • run with Scrapy -
Scaling Extraction At scale, use methods that do not require
additional work per website • boilerplate removal - python- goose, readability, justext.. • analyze text with nltk • scikit-learn and scikit-image for classification, feature extraction • webstruct - NER with HTML -
Named Entity Recognition • finds and classifies elements in text
into predefined categories • examples include person names or job titles, organizations, locations, expressions of times, quantities, monetary values, percentages, etc. For English it is often solved using machine learning -
Web Page Annotation Web pages need to be annotated manually
Useful tools include: • https://github.com/xtannier/WebAnnotator • https://gate.ac.uk/ • http://brat.nlplab.org/ -
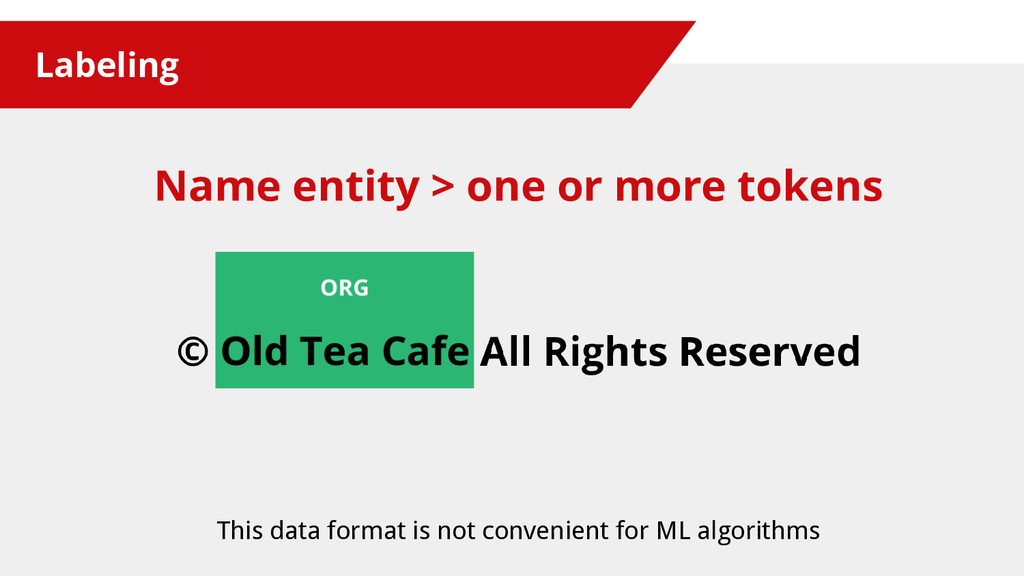
Labeling Name entity > one or more tokens This data
format is not convenient for ML algorithms -
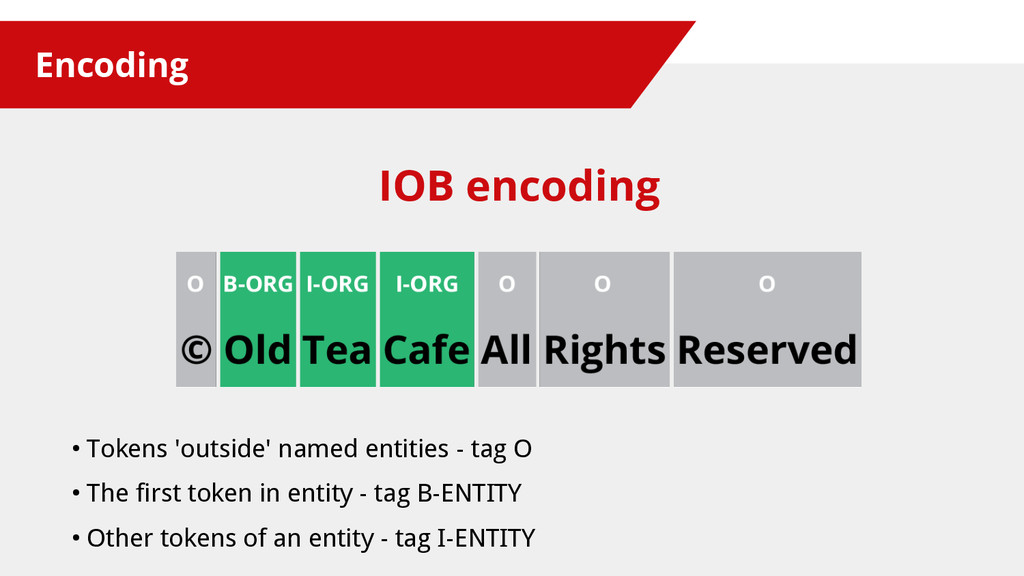
Encoding IOB encoding • Tokens 'outside' named entities - tag
O • The first token in entity - tag B-ENTITY • Other tokens of an entity - tag I-ENTITY -
Classification Task The problem is reduced to a "standard" ML
classification task • Input data - information about tokens (==features) • Output data - named entity label, encoded as IOB • Use a classifier which takes the order of predicted labels into account (Conditional Random Fields is a common choice) -
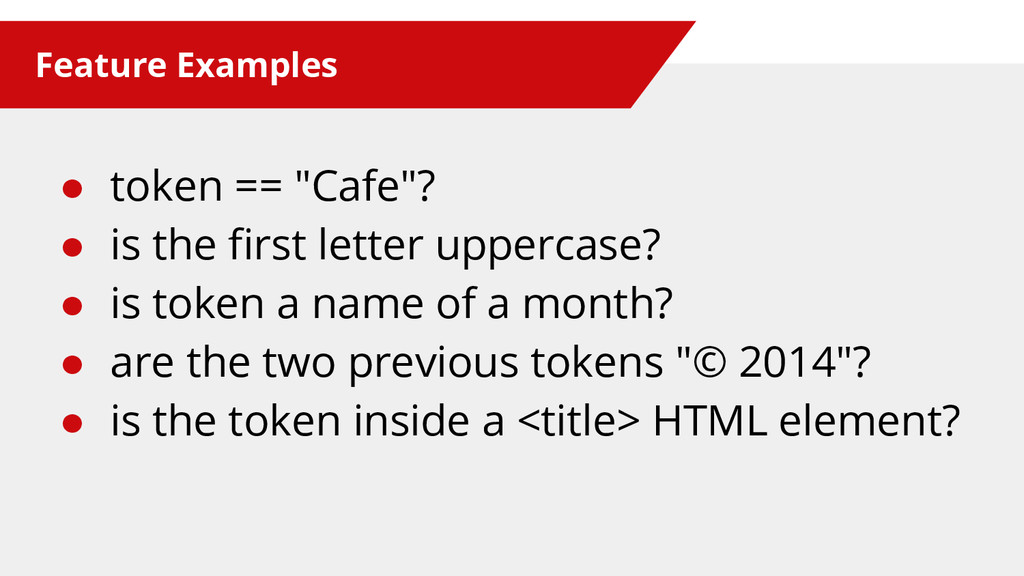
Feature Examples • token == "Cafe"? • is the first
letter uppercase? • is token a name of a month? • are the two previous tokens "© 2014"? • is the token inside a <title> HTML element? -
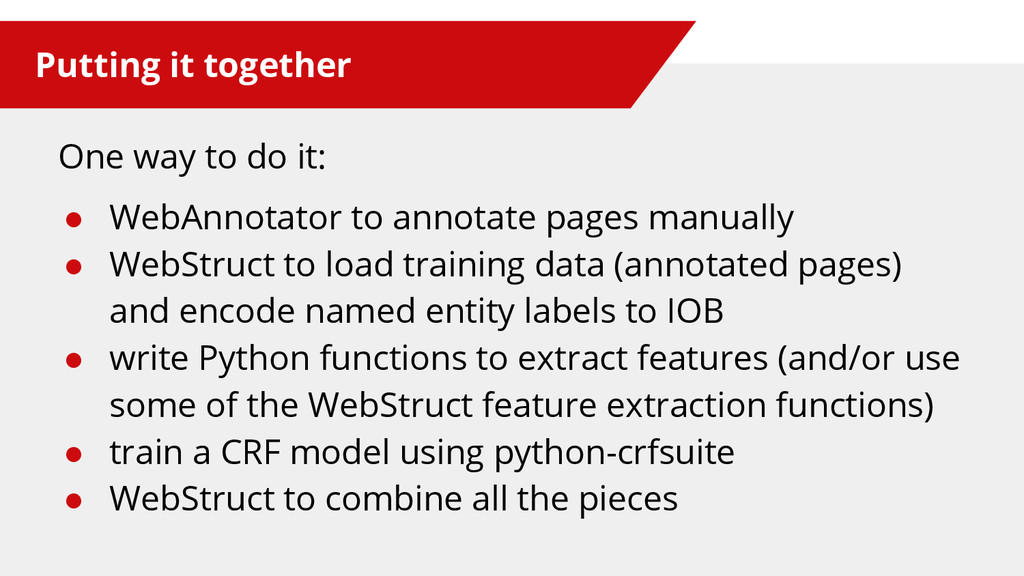
Putting it together One way to do it: • WebAnnotator
to annotate pages manually • WebStruct to load training data (annotated pages) and encode named entity labels to IOB • write Python functions to extract features (and/or use some of the WebStruct feature extraction functions) • train a CRF model using python-crfsuite • WebStruct to combine all the pieces -
Saatchi Global Gallery Guide • Scrape 11k+ gallery websites •
Extract artworks, artist and exhibitions -
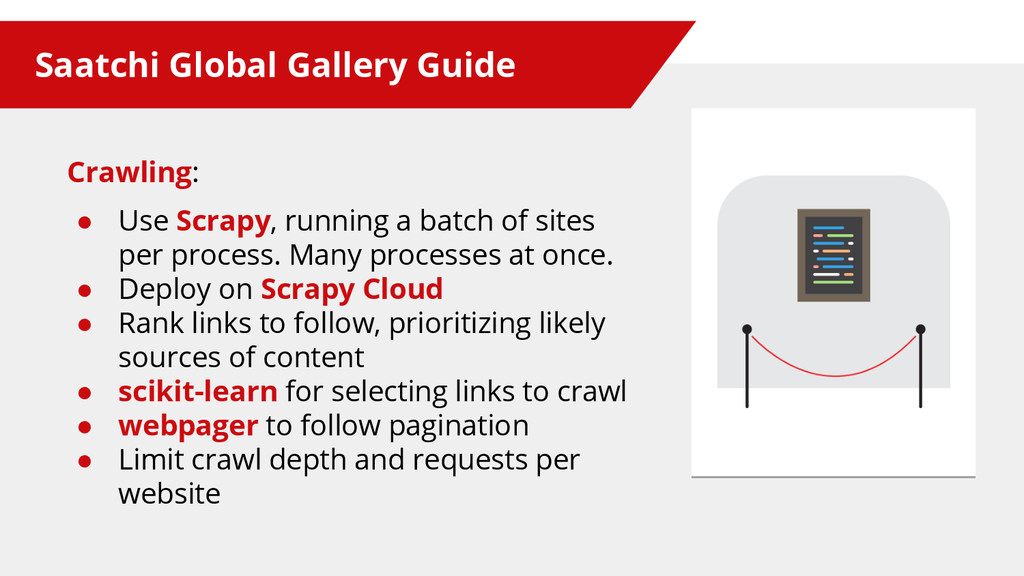
Saatchi Global Gallery Guide Crawling: • Use Scrapy, running a
batch of sites per process. Many processes at once. • Deploy on Scrapy Cloud • Rank links to follow, prioritizing likely sources of content • scikit-learn for selecting links to crawl • webpager to follow pagination • Limit crawl depth and requests per website -
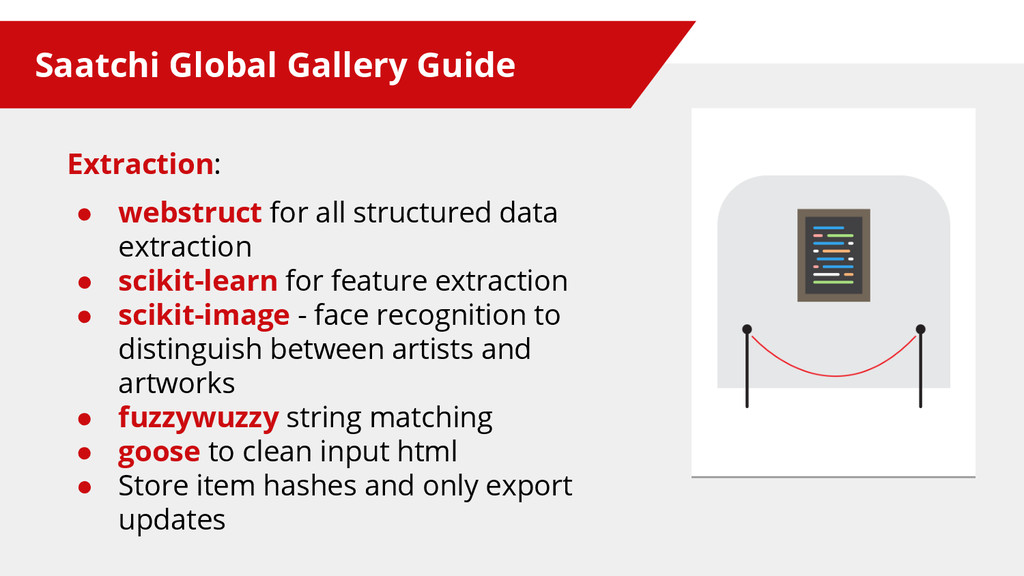
Saatchi Global Gallery Guide Extraction: • webstruct for all structured
data extraction • scikit-learn for feature extraction • scikit-image - face recognition to distinguish between artists and artworks • fuzzywuzzy string matching • goose to clean input html • Store item hashes and only export updates -
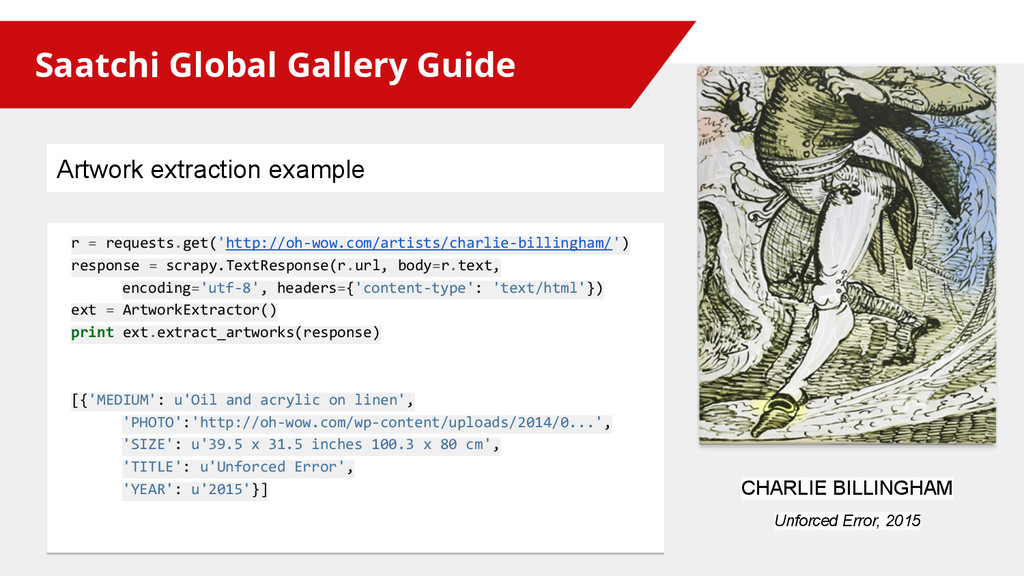
Saatchi Global Gallery Guide r = requests.get('http://oh-wow.com/artists/charlie-billingham/') response = scrapy.TextResponse(r.url,
body=r.text, encoding='utf-8', headers={'content-type': 'text/html'}) ext = ArtworkExtractor() print ext.extract_artworks(response) [{'MEDIUM': u'Oil and acrylic on linen', 'PHOTO':'http://oh-wow.com/wp-content/uploads/2014/0...', 'SIZE': u'39.5 x 31.5 inches 100.3 x 80 cm', 'TITLE': u'Unforced Error', 'YEAR': u'2015'}] CHARLIE BILLINGHAM Unforced Error, 2015 Artwork extraction example -
Saatchi Global Gallery Guide evaluation: • measure accuracy (precision and
recall) • avoid false positives • test everything, improve iteratively -
Web Scraping Challenges Difficulty typically depends on the size of
data, complexity of extracted items and accuracy requirements -
Web Scraping Challenges But getting clean data from the web
is a dirty business! Some things will kill your scraping.. -
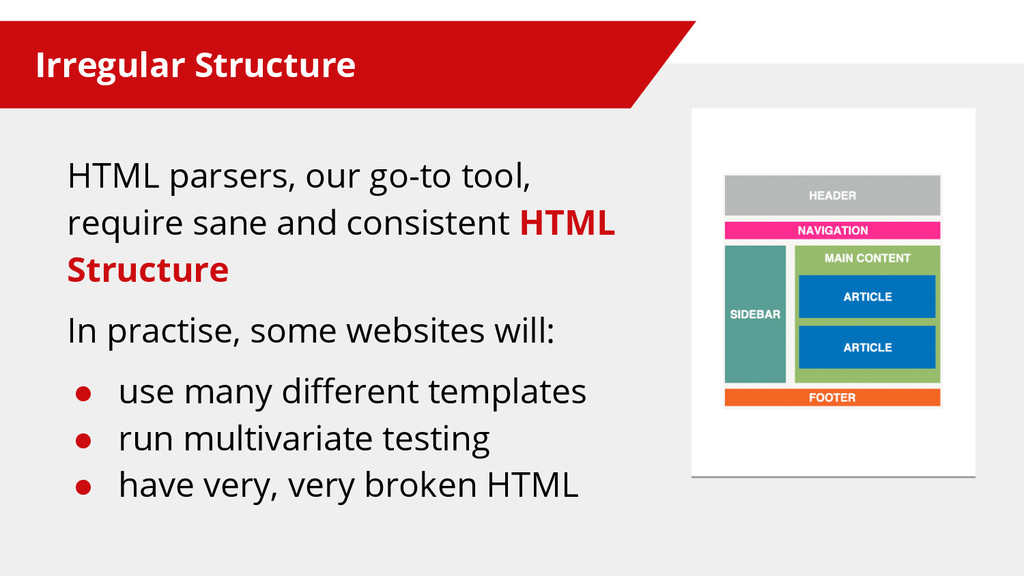
Irregular Structure HTML parsers, our go-to tool, require sane and
consistent HTML Structure In practise, some websites will: • use many different templates • run multivariate testing • have very, very broken HTML -
JavaScript Many sites require JavaScript, or browser rendering, to be
scraped. • Splash is a scriptable browser available via an API. Works well with Scrapy. • Automate web browser interaction with Selenium • Most JS-heavy sites call APIs. You can do that too! use browser tools to inspect • js2xml can make JS easier to parse, sometimes pull data with regexp • Maybe the mobile site is better? -
Proxies • Sometimes need to crawl from a specific location
• Many hosting centres (e.g. EC2) are frequently entirely banned • Privacy can be important • Multiple proxies for sustained reliable crawling e.g. Tor, illuminati, open proxies, private providers and Crawlera -
Ethics • is your web scraping causing harm? • crawl
at a reasonable rate, especially on smaller websites • identify your bot via a user agent • respect robots.txt on broad crawls -
THANK YOU! Shane Evans @shaneaevans Visit our booth Talk to
us at the recruiting session Stick around for the “Dive into Scrapy” talk