Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Reproducible Distributed Experiments on Cloud

Reproducible Distributed Experiments on Cloud

This is a project for creating a reproducible experiment for comparing Apache Flink and Apache Spark
Batch Processing.
https://github.com/karamel-lab/batch-processing-comparison

Avatar for Shelan Perera

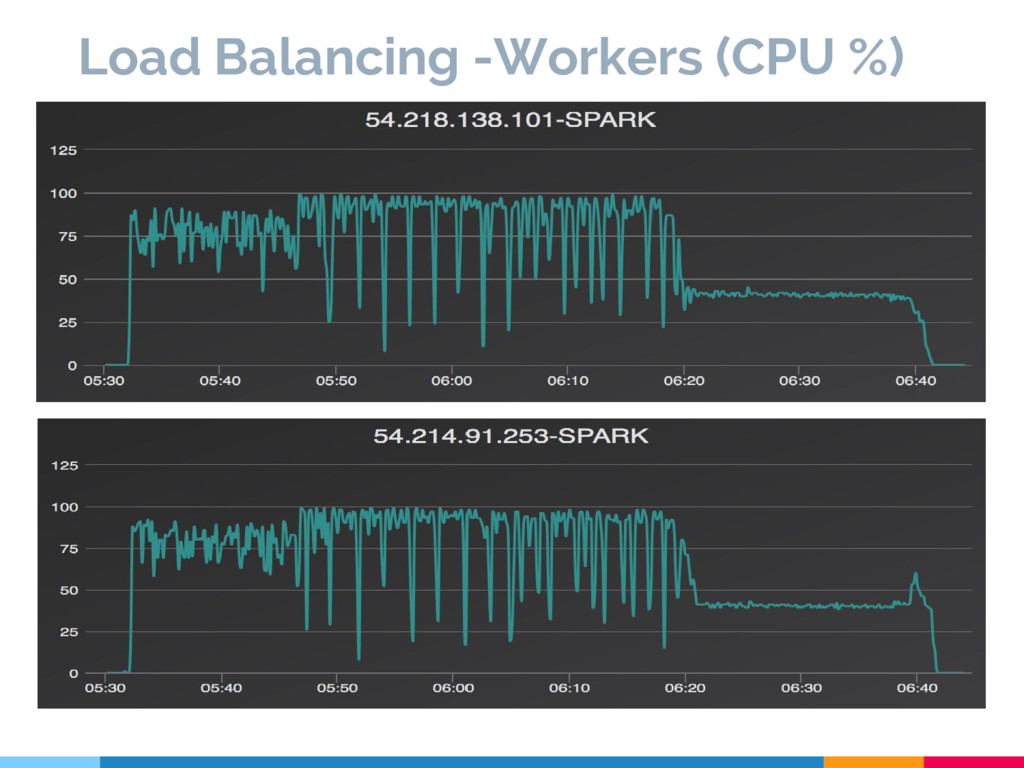
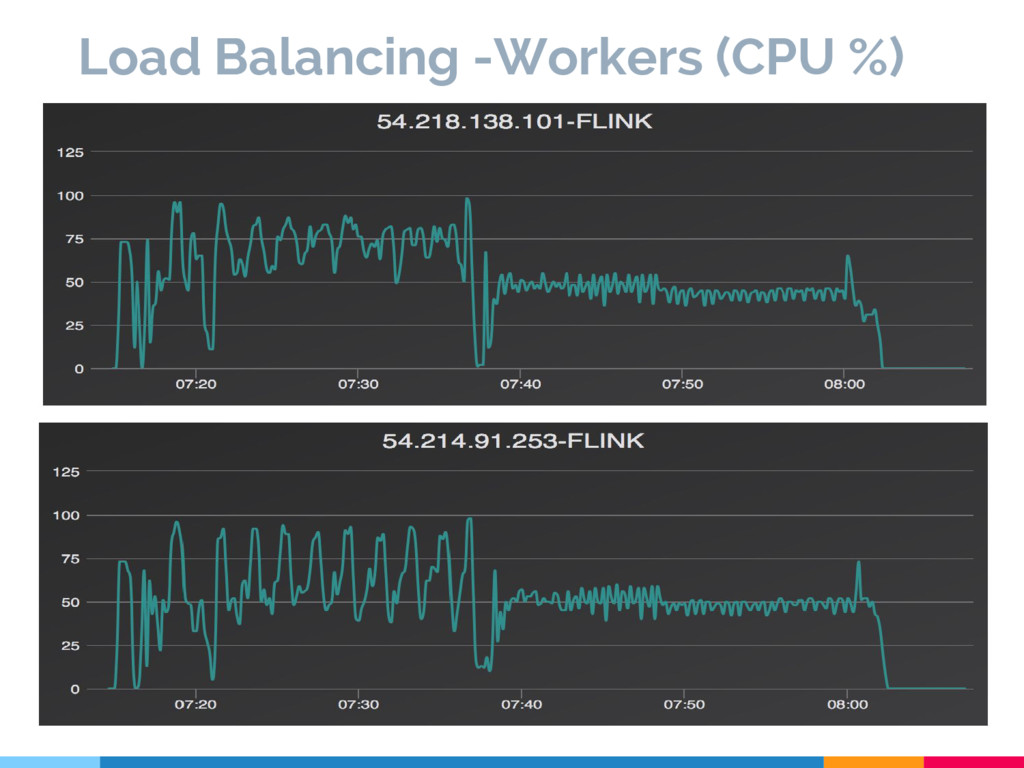
Shelan Perera

February 03, 2016

More Decks by Shelan Perera

Other Decks in Technology

Transcript

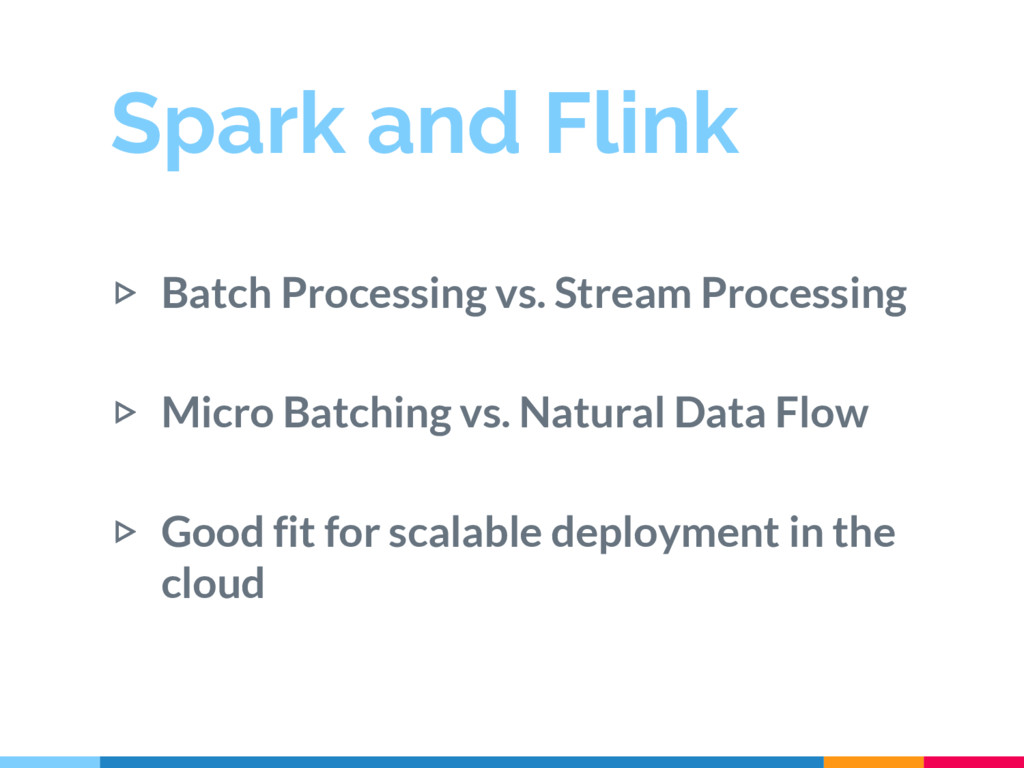
  1. Spark and Flink ▷ Batch Processing vs. Stream Processing ▷

    Micro Batching vs. Natural Data Flow ▷ Good fit for scalable deployment in the cloud
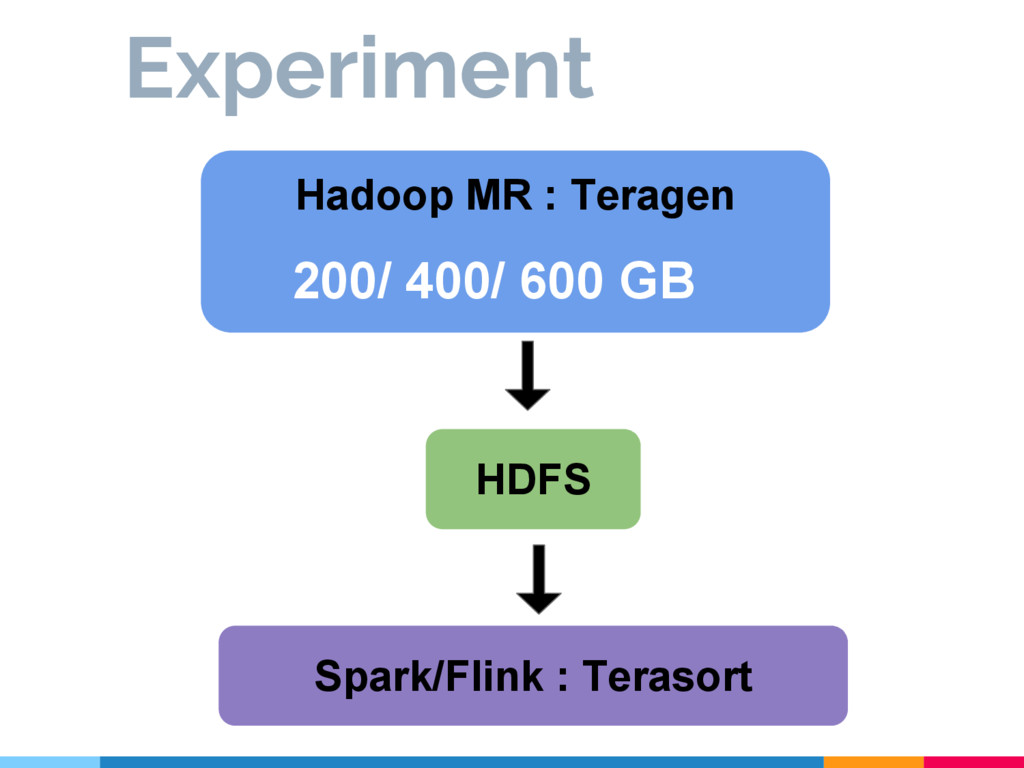
  2. Benchmark - Batch Teragen - To generate data (Hadoop) Terasort

    - Benchmarking Algorithm (Spark, Flink)
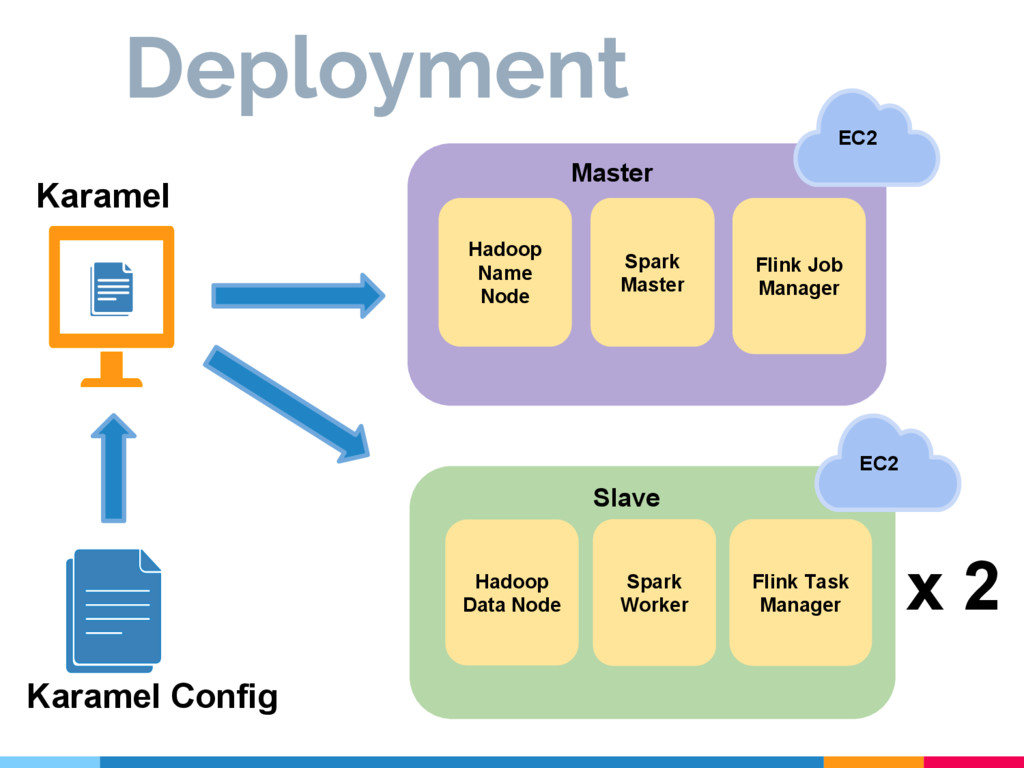
  3. 1 Namenode ⇒ Master (Low processing ) 2 Worker nodes

    ⇒ Slaves (High processing ) Our Deployment
  4. EC2 Slave EC2 Master Deployment Hadoop Name Node Spark Master

    Flink Job Manager Spark Worker Flink Task Manager Hadoop Data Node Karamel x 2 Karamel Config
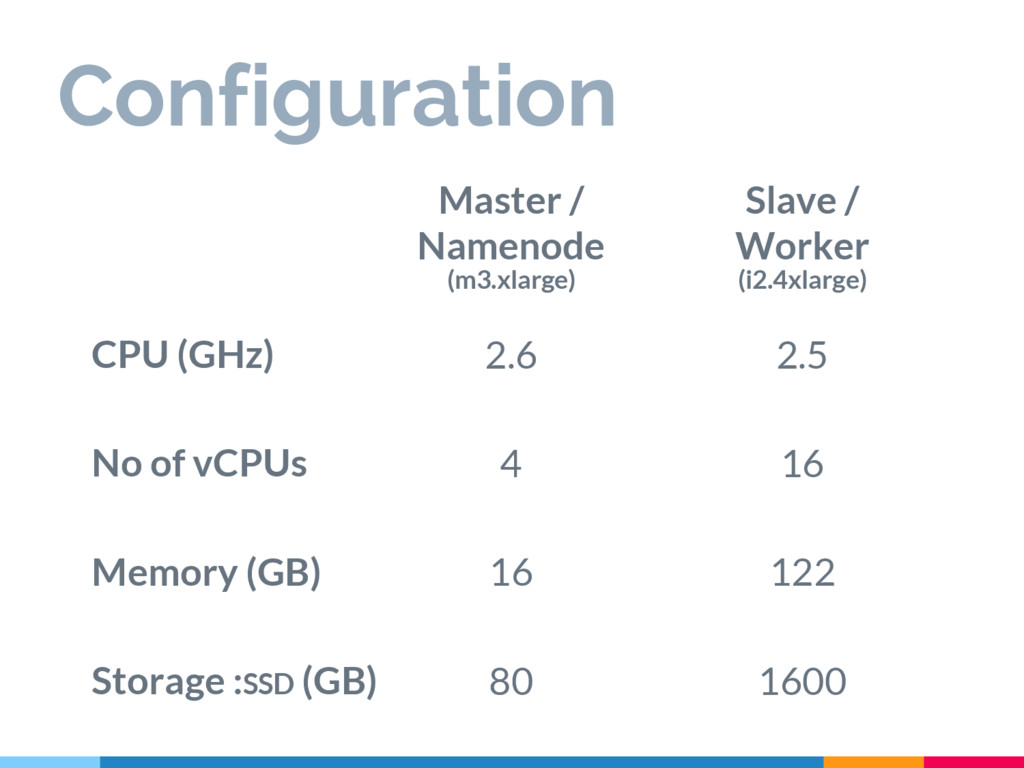
  5. Configuration Master / Namenode 2.6 4 16 80 Slave /

    Worker 2.5 16 122 1600 CPU (GHz) No of vCPUs Memory (GB) Storage :SSD (GB) (m3.xlarge) (i2.4xlarge)
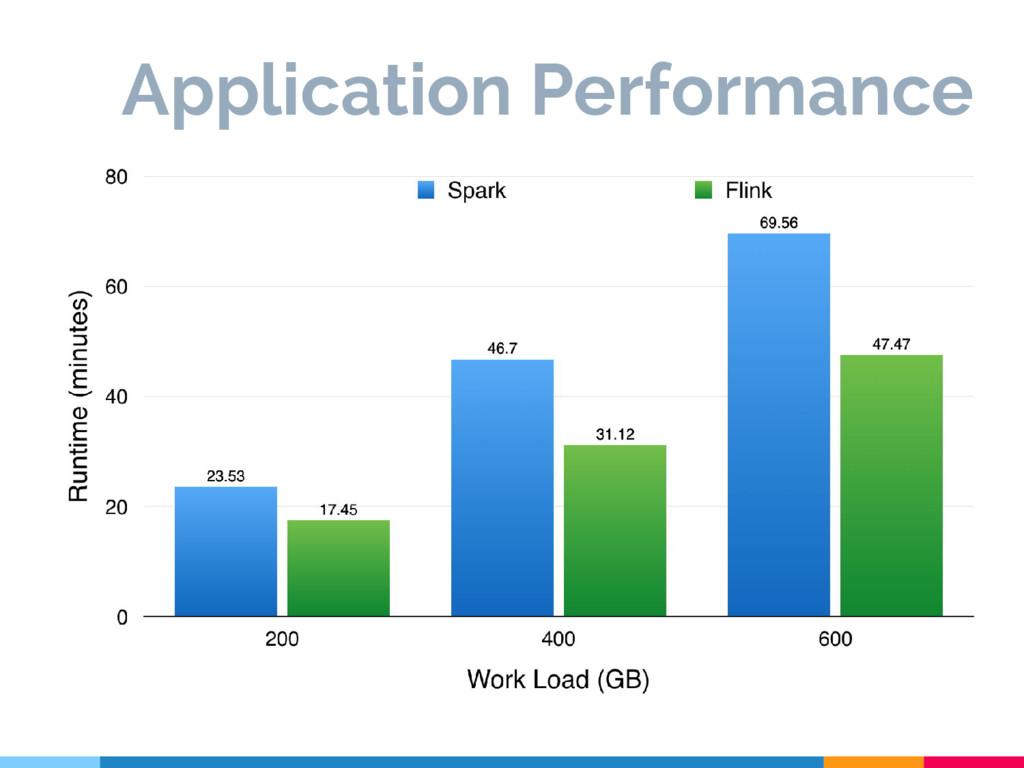
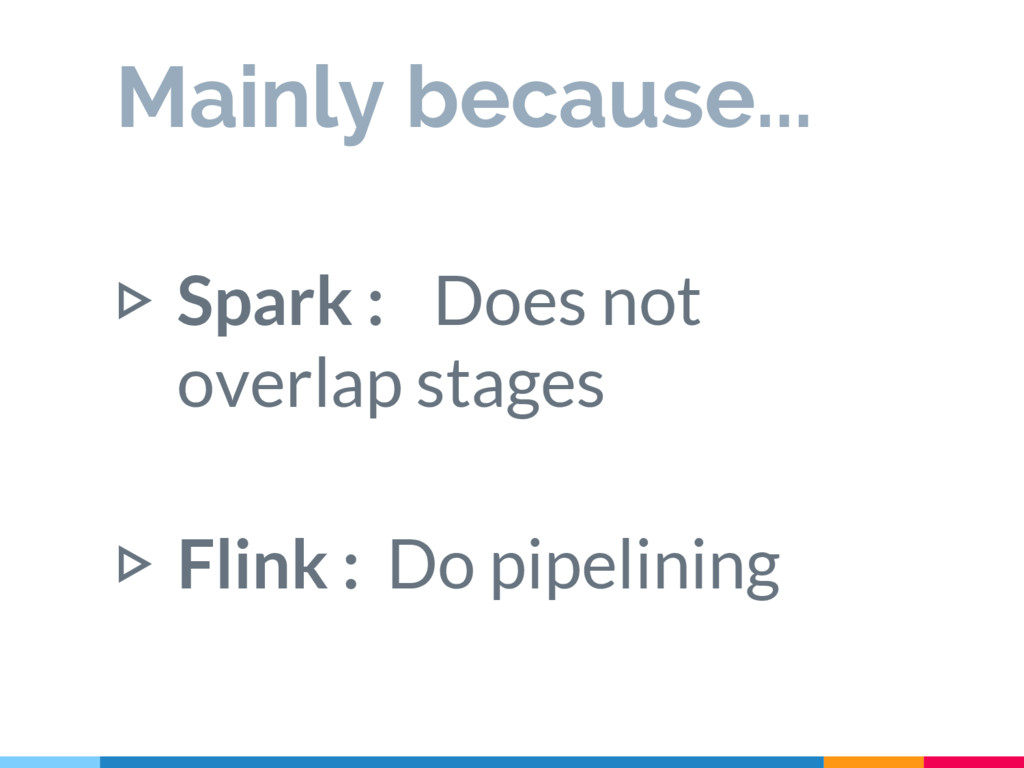
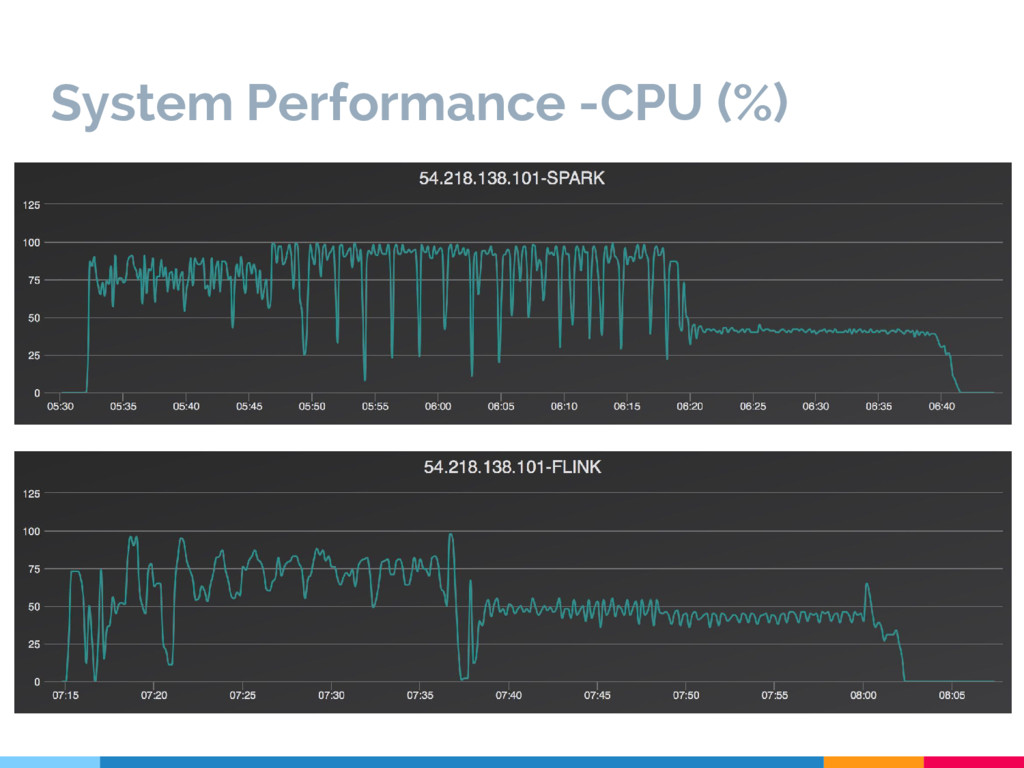
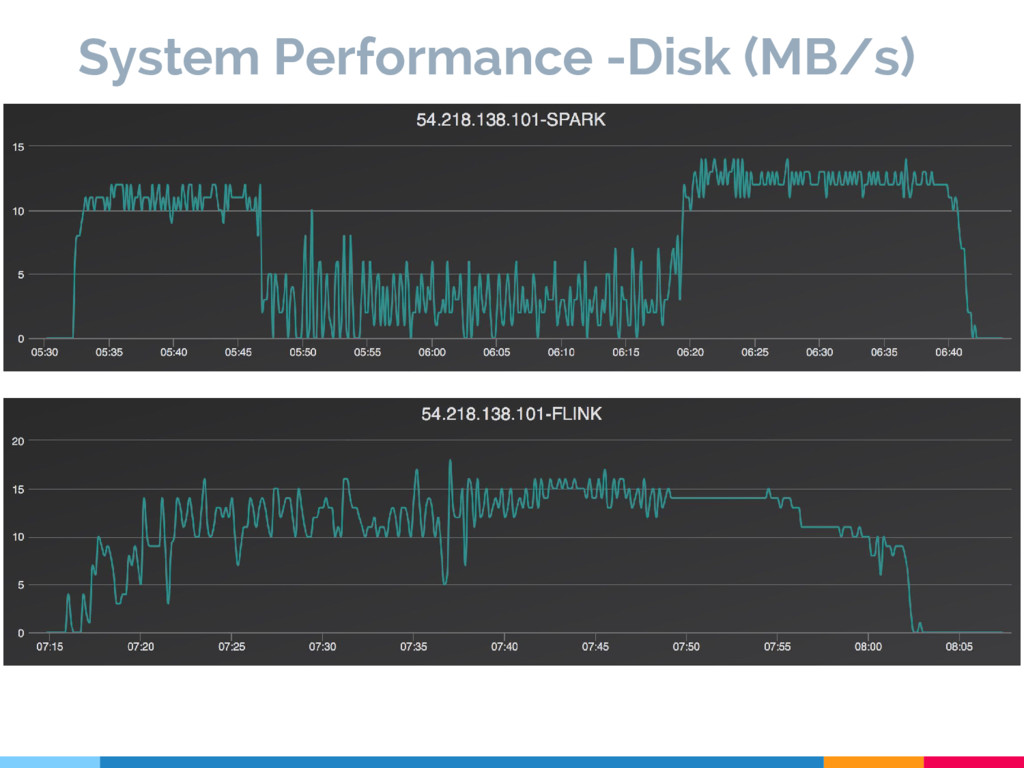
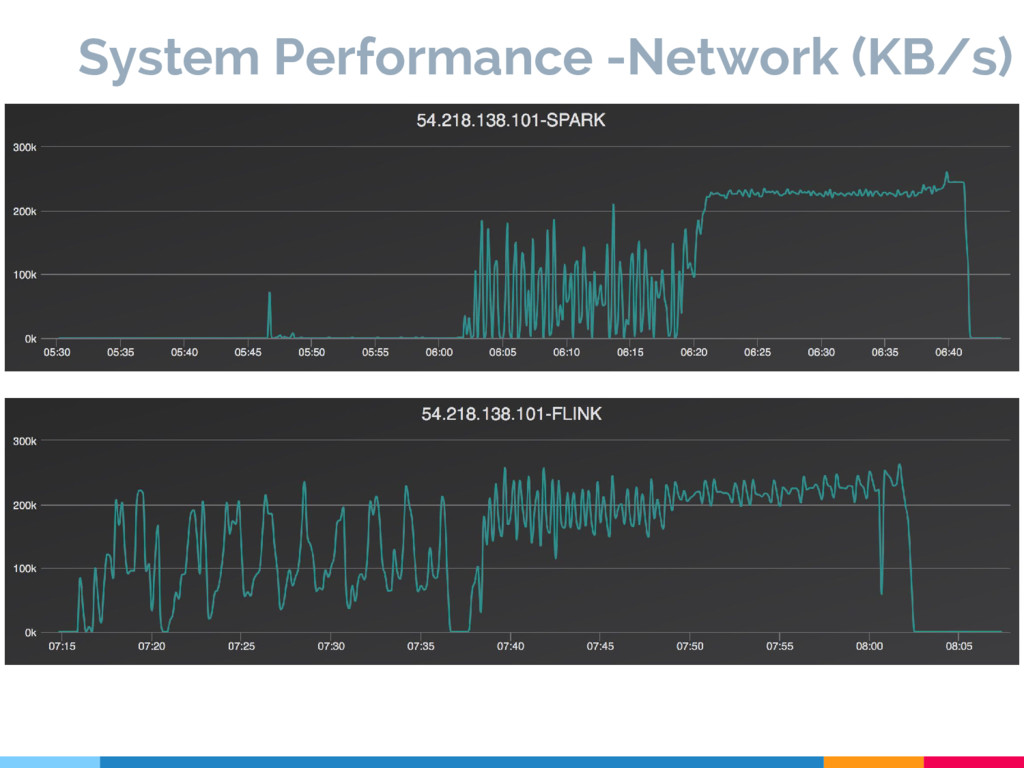
  6. ▷ Spark : Does not overlap stages ▷ Flink :

    Do pipelining Mainly because...
  7. Collectl- Monitor • Tool used to collect and draw results.

    • https://github. com/shelan/collectl- monitoring
  8. EC2 claims 800 GB disks, But Disk File system (DF)

    does shows only 30GB. If you are using I2 or R3 instances you should create a file system and partition disks manually.
  9. Large Spark or Flink Batch applications can fail with not

    enough disk space Configure Flink temp directory and Spark local directory to a partition with at least enough space to store the total input.
  10. Reproducing experiments on EC2 may cost you a lot Spot

    instances which allow to reduce the cost by 10x is also supported by Karamel
  11. IncompatibleClassChangeError when running StreamBench built for MR2 on hadoop2.x No

    explicitly defined dependencies for previous versions, but one of the dependencies (mahout) had internal references to hadoop1.x jar
  12. Summary ▷ Introducing reproducible experiments on cloud ▷ Performance Comparison

    of Spark and Flink ▷ Reproducible experiments are available online (https://github.com/karamel-lab)