Overview 2. Background Information 1. Continual learning 2. Prompt-based tuning 3. Dialogue state tracking 3. Continual Prompt Tuning for Dialogue State Tracking - Model Structure(Method) 4. Experiment Result 2
Overview 2. Background Information 1. Continual learning 2. Prompt-based tuning 3. Dialogue state tracking 3. Continual Prompt Tuning for Dialogue State Tracking - Model Structure(Method) 4. Experiment Result 3
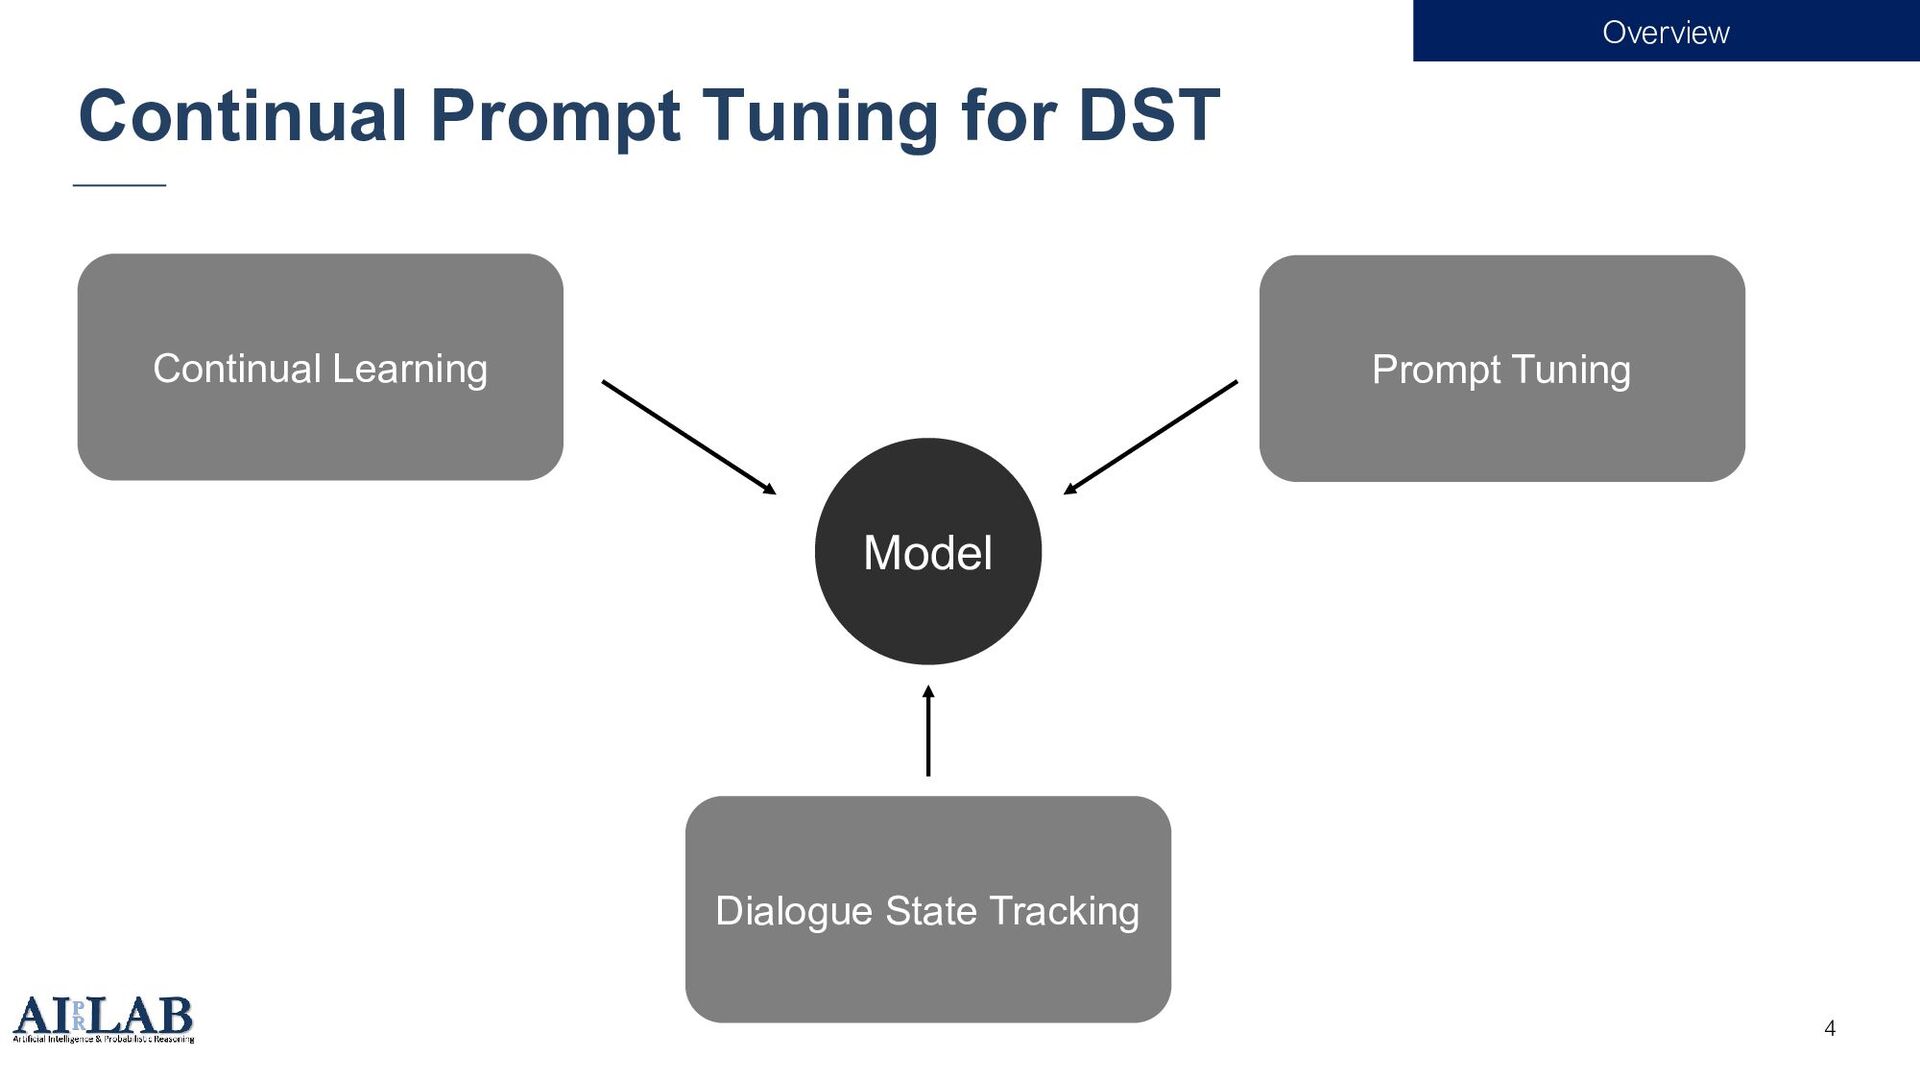
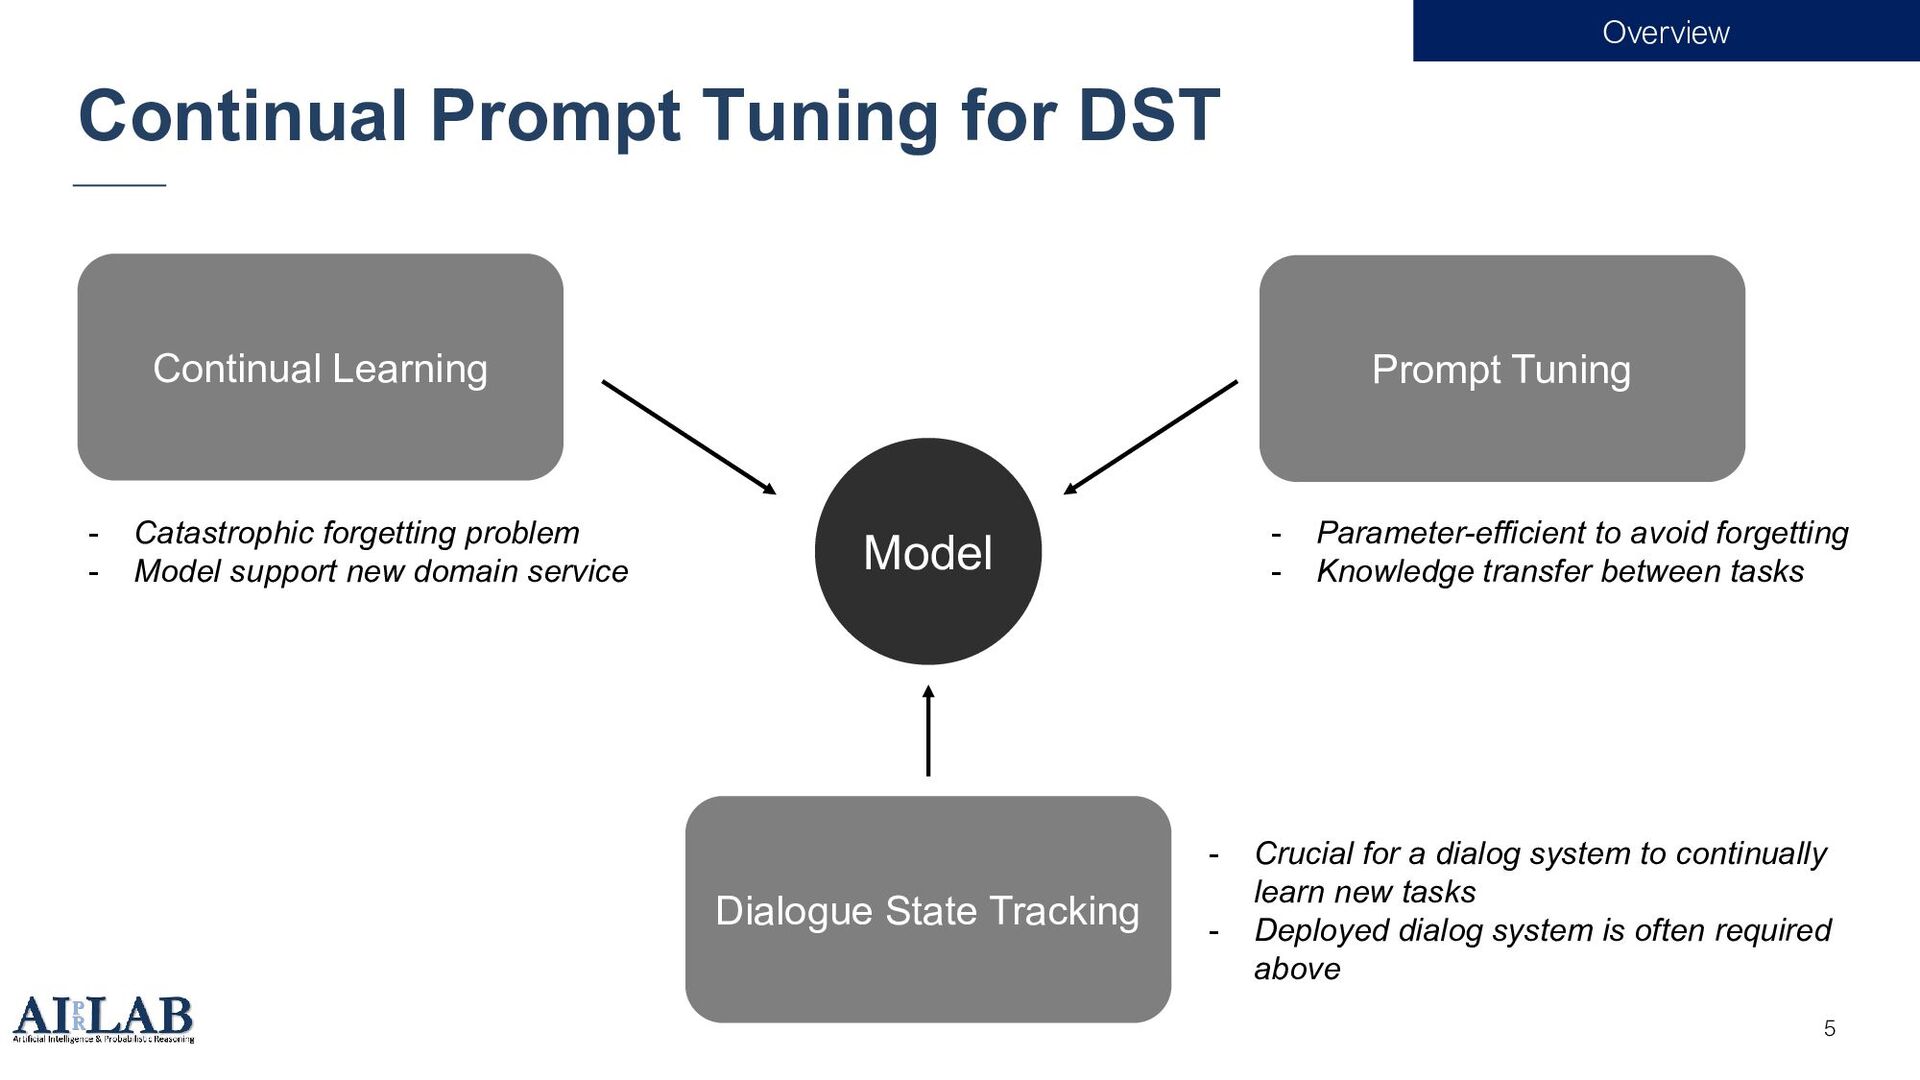
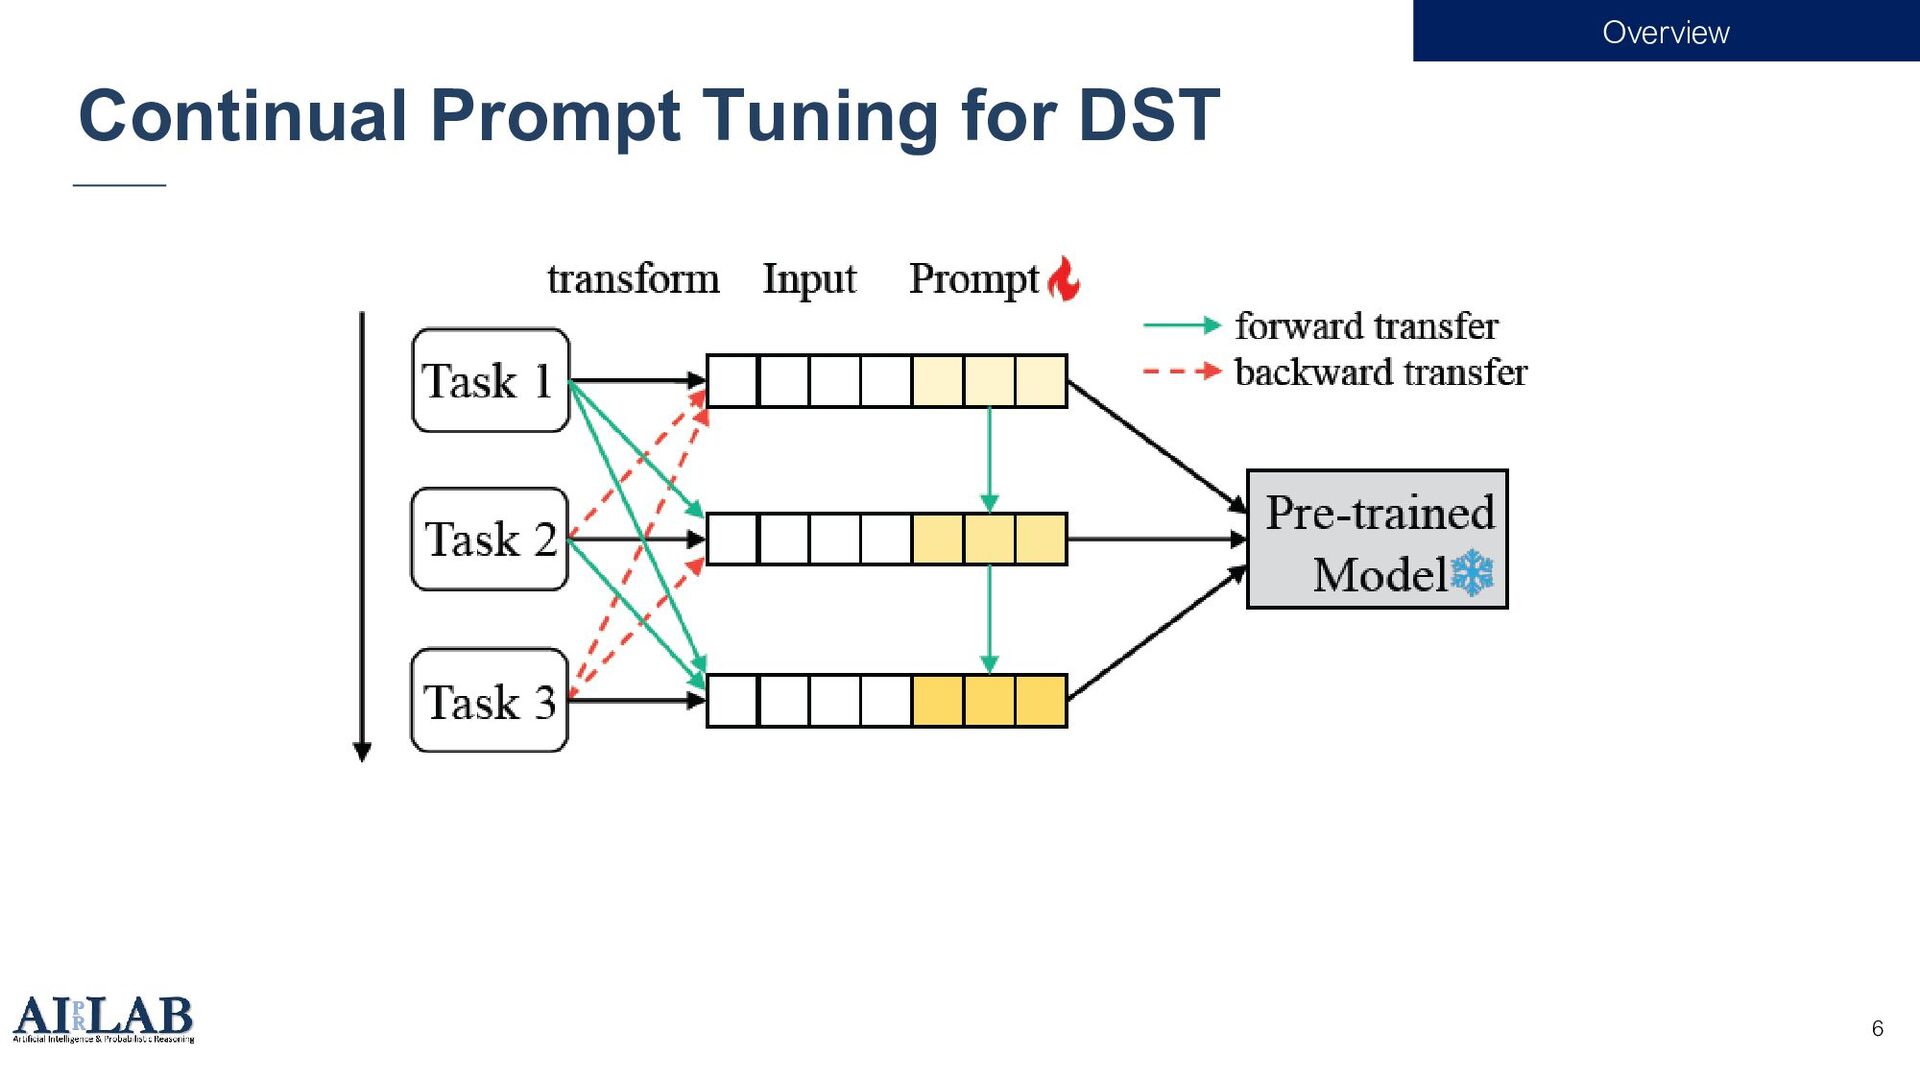
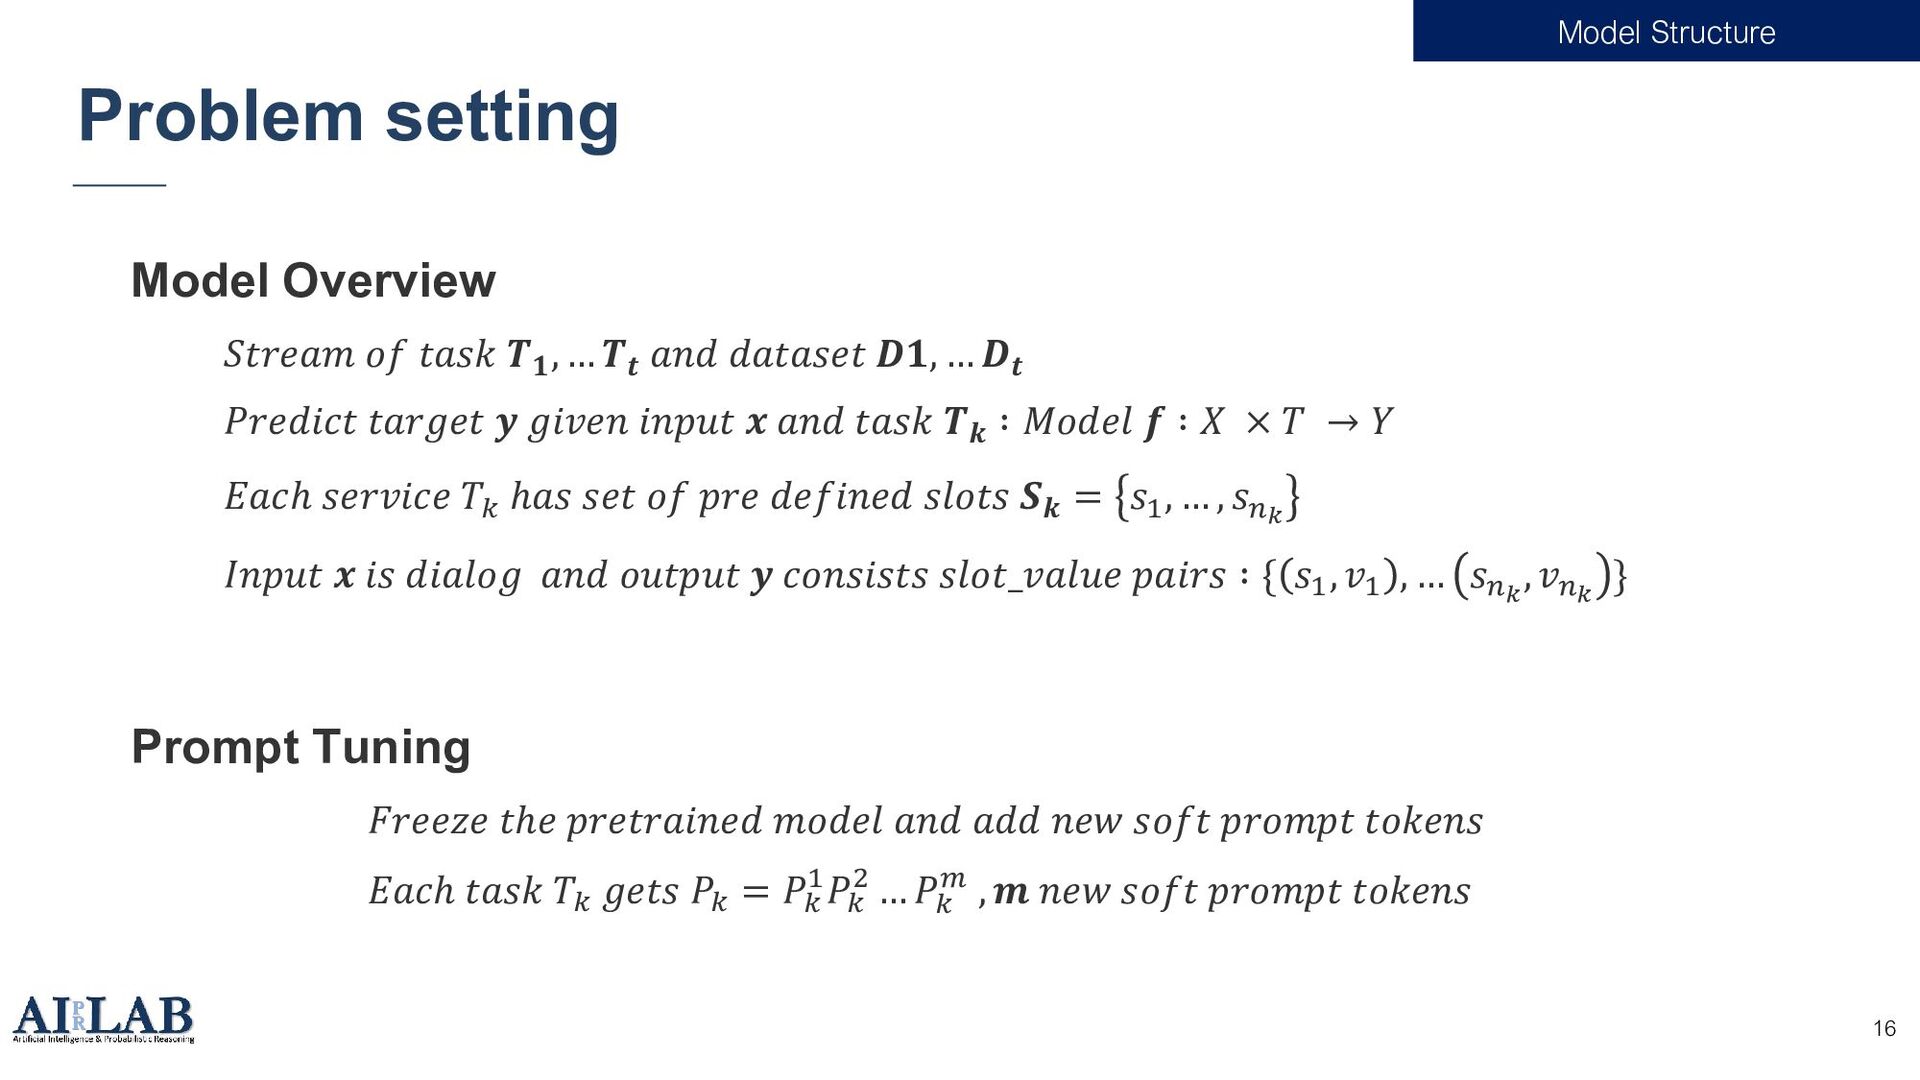
Tuning Dialogue State Tracking Model - Catastrophic forgetting problem - Model support new domain service - Parameter-efficient to avoid forgetting - Knowledge transfer between tasks - Crucial for a dialog system to continually learn new tasks - Deployed dialog system is often required above
Overview 2. Background Information 1. Continual learning 2. Prompt-based tuning 3. Dialogue state tracking 3. Continual Prompt Tuning for Dialogue State Tracking - Model Structure(Method) 4. Experiment Result 8
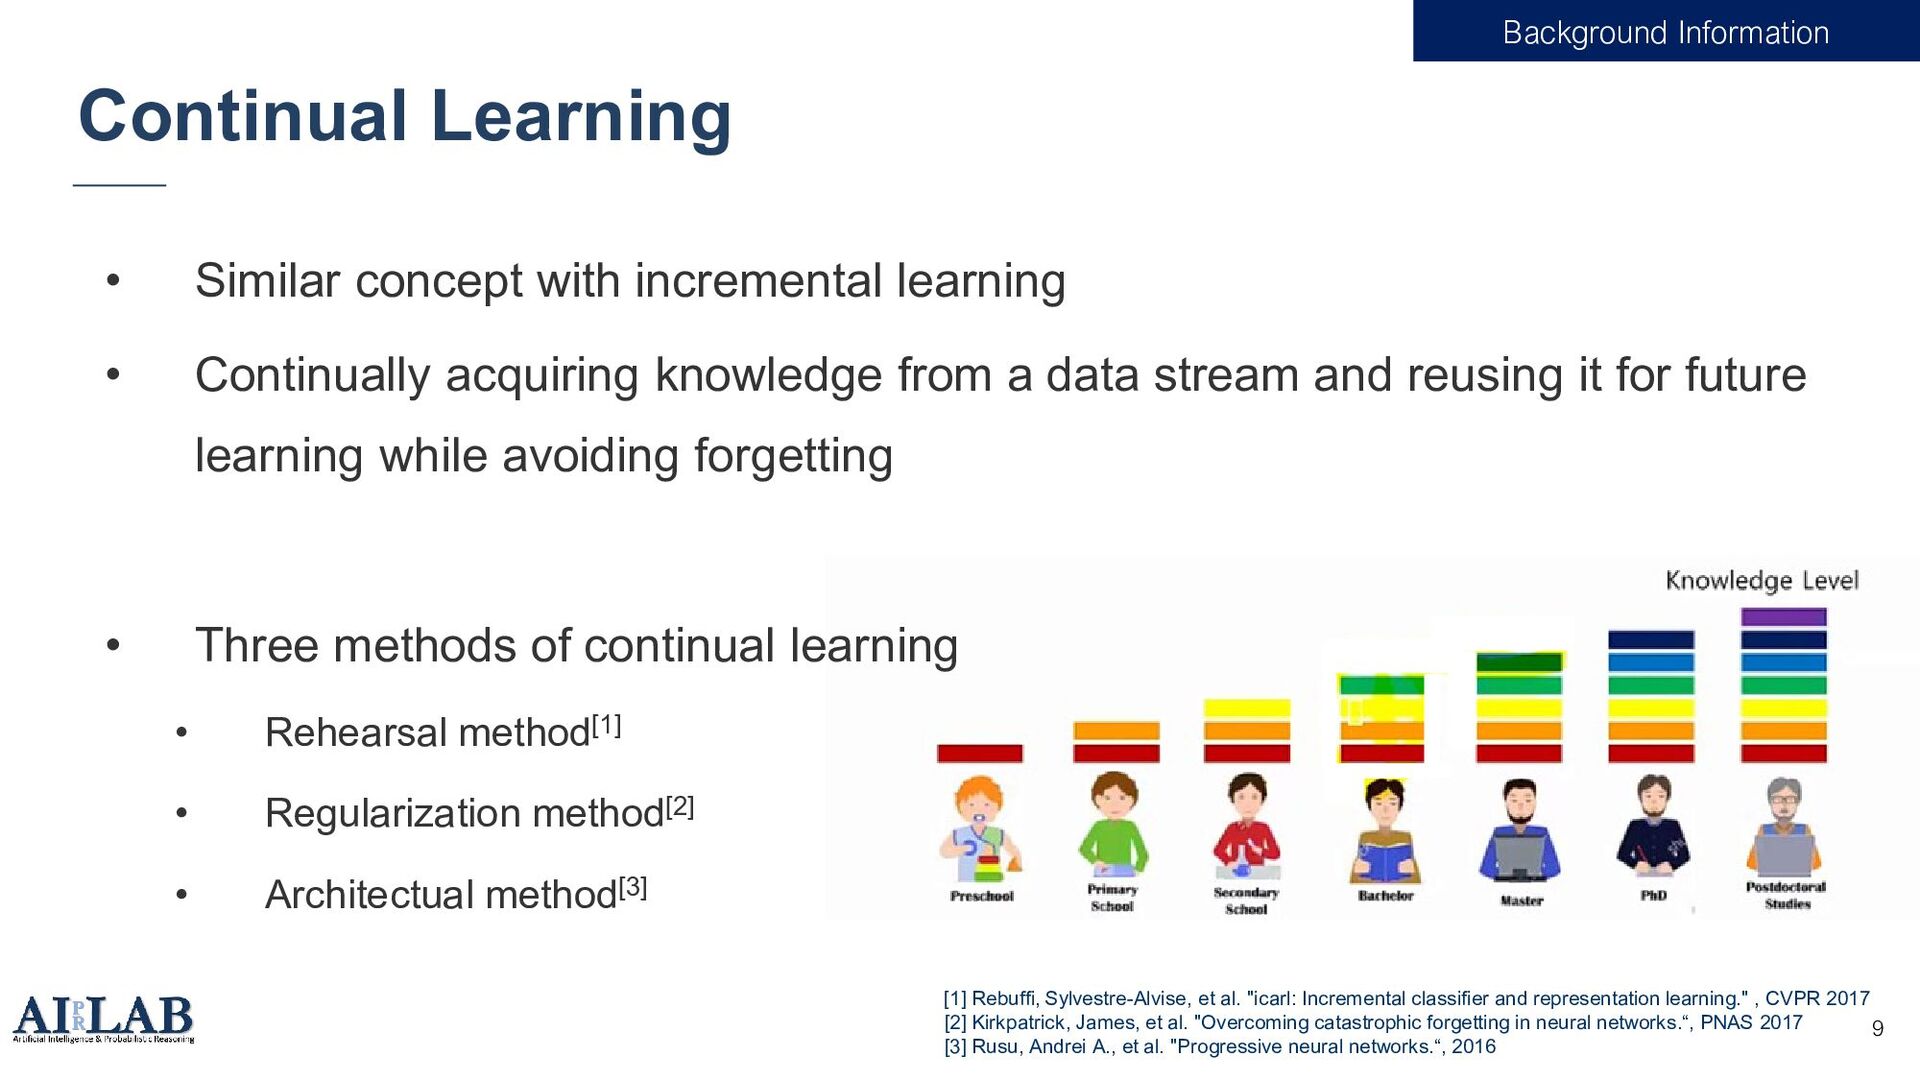
Continually acquiring knowledge from a data stream and reusing it for future learning while avoiding forgetting • Three methods of continual learning • Rehearsal method[1] • Regularization method[2] • Architectual method[3] [1] Rebuffi, Sylvestre-Alvise, et al. "icarl: Incremental classifier and representation learning." , CVPR 2017 [2] Kirkpatrick, James, et al. "Overcoming catastrophic forgetting in neural networks.“, PNAS 2017 [3] Rusu, Andrei A., et al. "Progressive neural networks.“, 2016 Background Information
methods have been applied[1] • AdapterCL[2] • Most related with this paper • Freezes the pre-trained model and learn adapter • Paper method is more parameter-efficient [1 Lee, Sungjin. "Toward continual learning for conversational agents.“, 2017 [2] Madotto, Andrea, et al. "Continual learning in task-oriented dialogue systems.“, 2021 Background Information
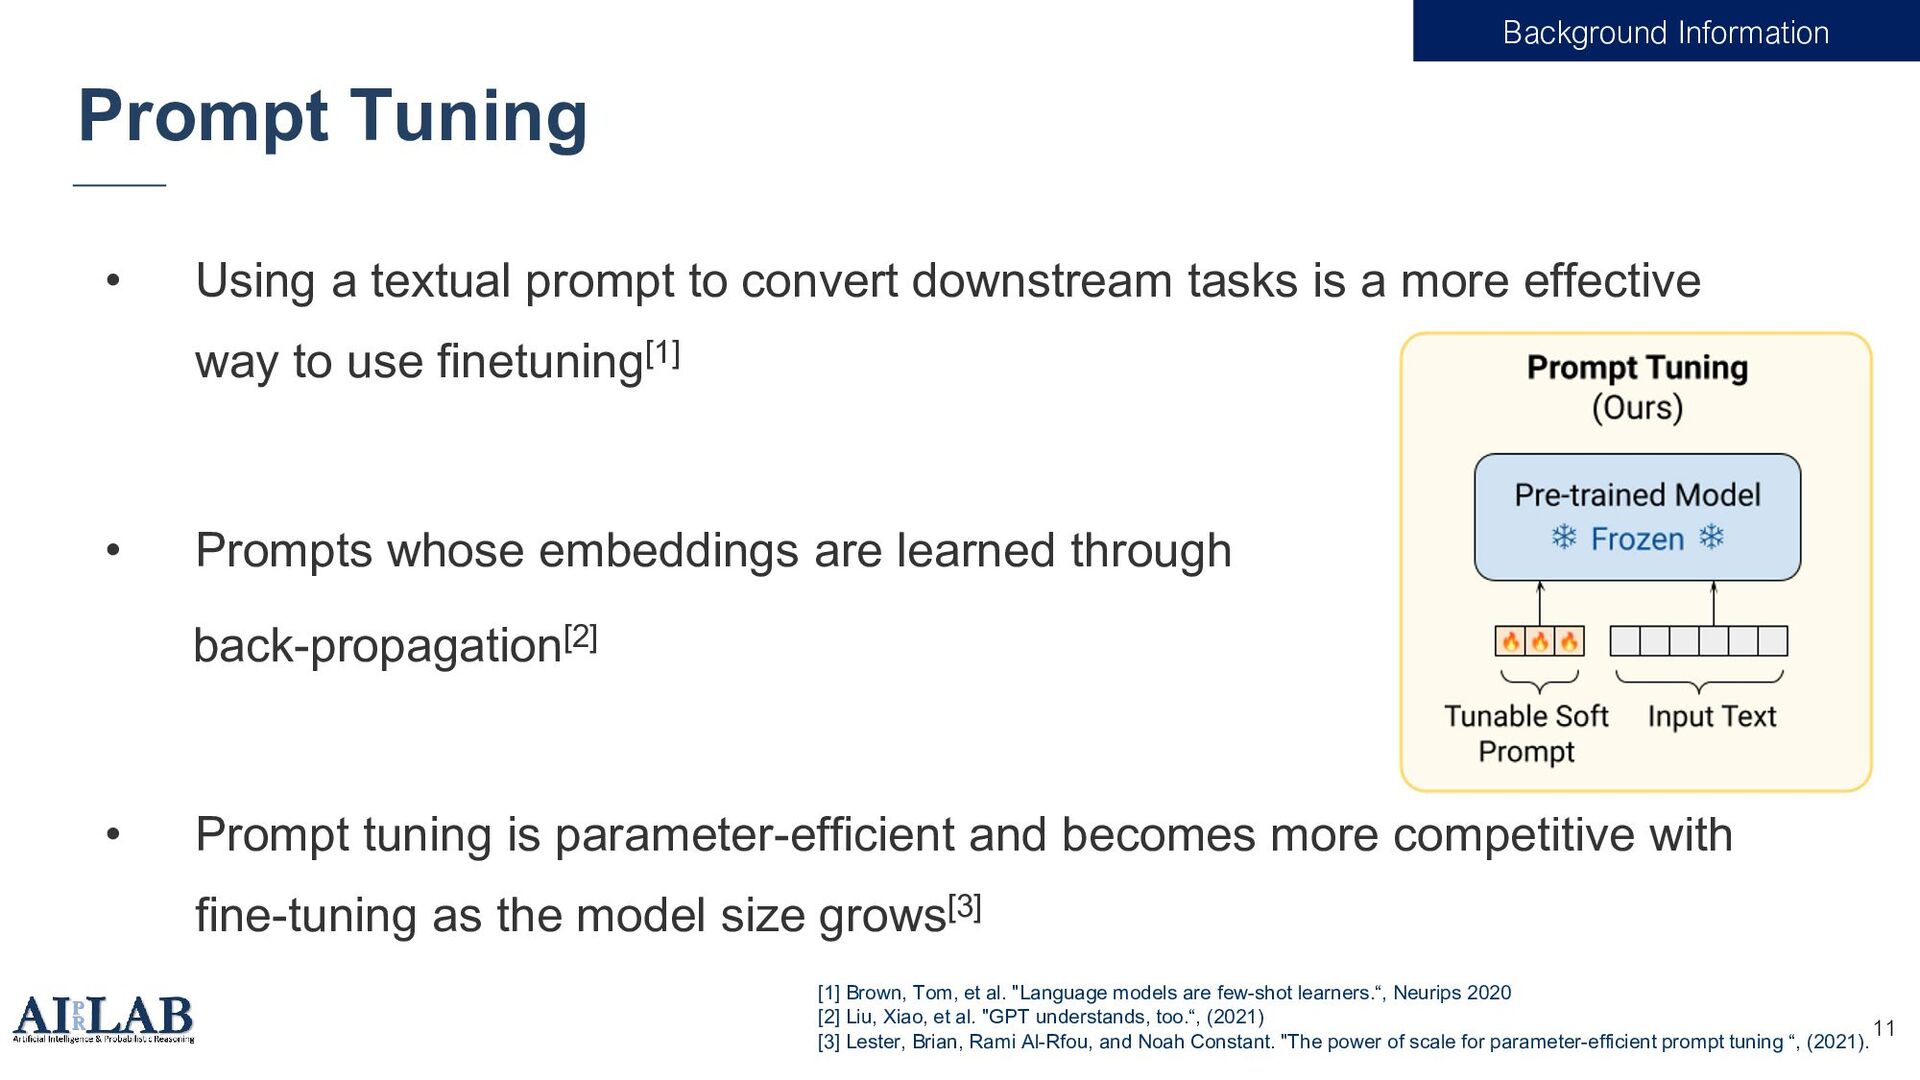
downstream tasks is a more effective way to use finetuning[1] • Prompts whose embeddings are learned through back-propagation[2] • Prompt tuning is parameter-efficient and becomes more competitive with fine-tuning as the model size grows[3] [1] Brown, Tom, et al. "Language models are few-shot learners.“, Neurips 2020 [2] Liu, Xiao, et al. "GPT understands, too.“, (2021) [3] Lester, Brian, Rami Al-Rfou, and Noah Constant. "The power of scale for parameter-efficient prompt tuning “, (2021). Background Information
• Embedding adapter transforms all tokens embeddings but do not affect transformer layers’ computation • Gu[2] and Vu[3] further explore the transferability of soft prompts across tasks • One-step adaptation -> Prompt transfer in the continual learning setting [1] Zhu, Yaoming, et al. "Counter-interference adapter for multilingual machine translation.“, 2021 [2] Gu, Yuxian, et al. "Ppt: Pre-trained prompt tuning for few-shot learning.", 2021 [3] Vu, Tu, et al. "Spot: Better frozen model adaptation through soft prompt transfer.“, 2021 Background Information
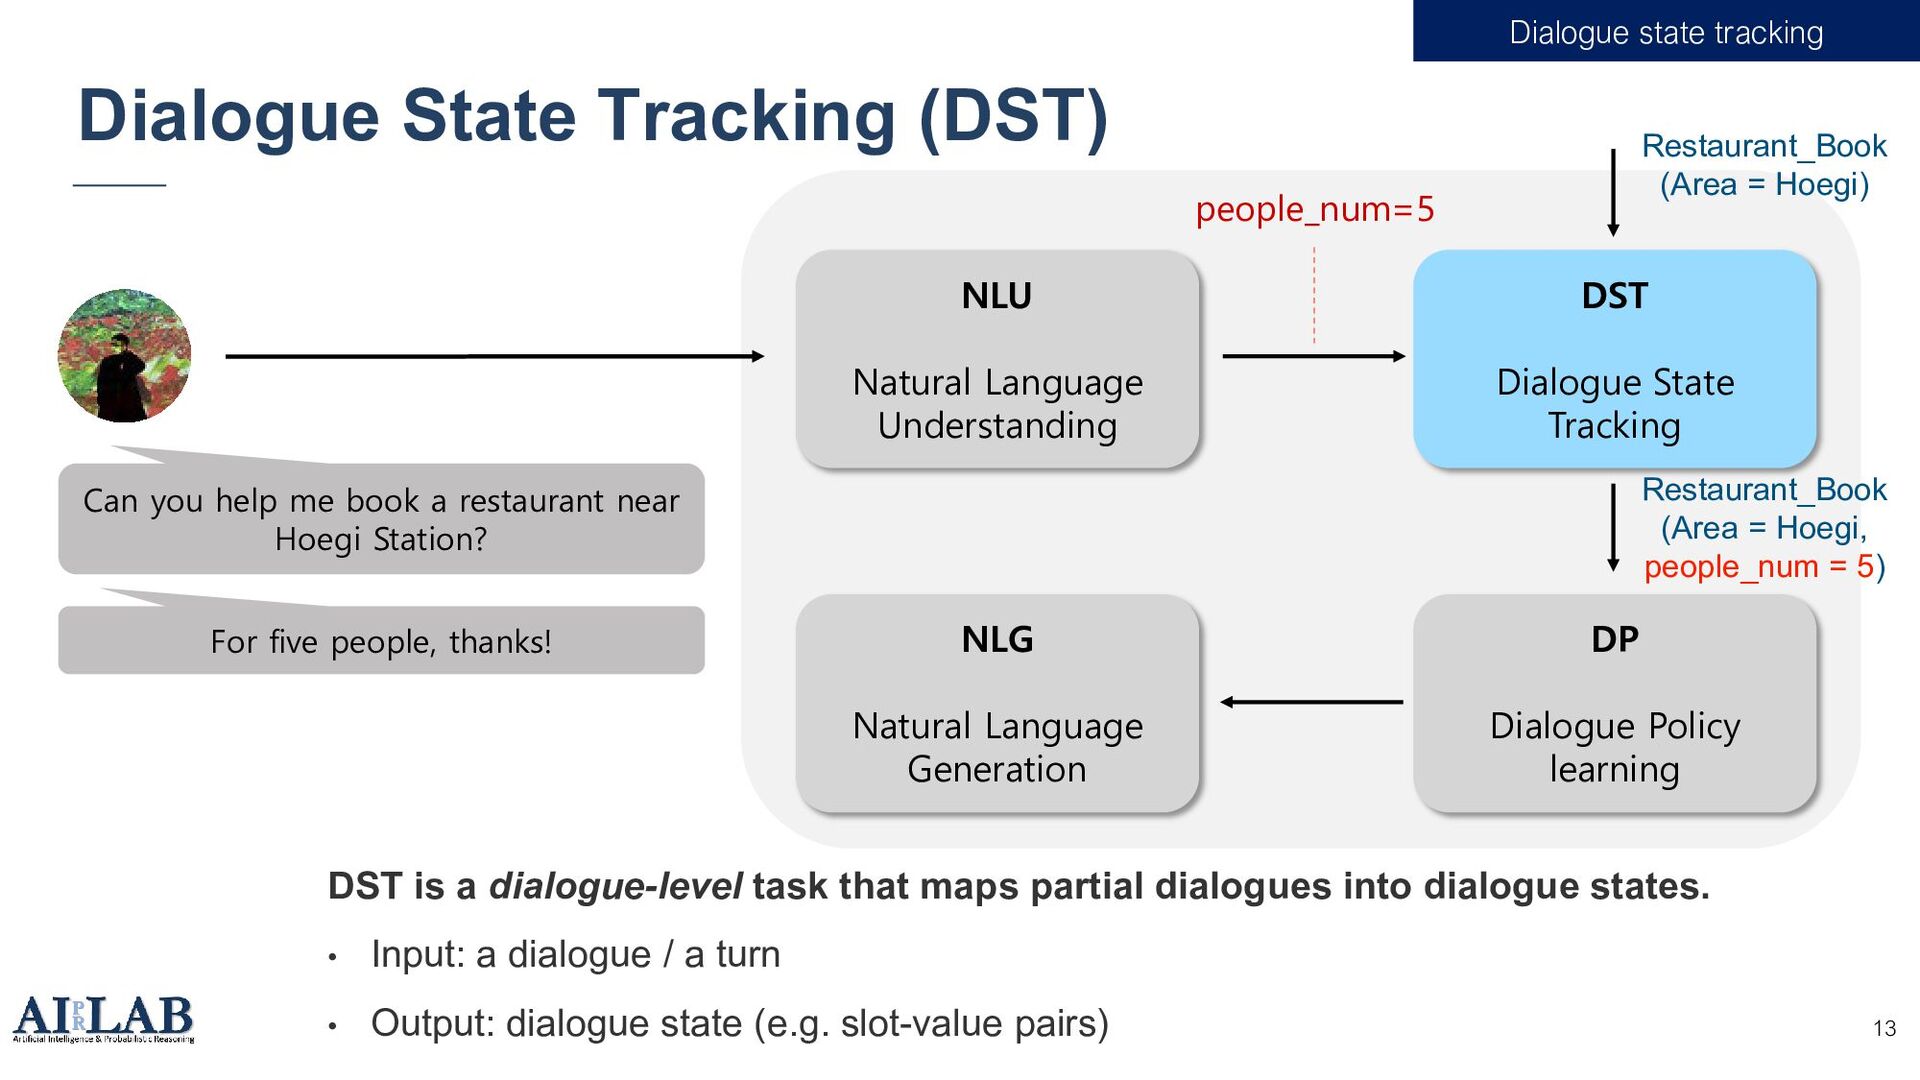
Dialogue State Tracking NLG Natural Language Generation DP Dialogue Policy learning people_num=5 Restaurant_Book (Area = Hoegi) Restaurant_Book (Area = Hoegi, people_num = 5) DST is a dialogue-level task that maps partial dialogues into dialogue states. • Input: a dialogue / a turn • Output: dialogue state (e.g. slot-value pairs) Can you help me book a restaurant near Hoegi Station? For five people, thanks! Dialogue state tracking
(slot, value) pairs in one pass[1] • Or generate value for each given slot separately[2] • Efficiency vs Incorporating more information • Integrates multiple slot descriptions into a single query and generates all values in one pass [1] Madotto, Andrea, et al. "Continual learning in task-oriented dialogue systems.“, 2021 [2] Wu, Chien-Sheng, et al. "Transferable multi-domain state generator for task-oriented dialogue systems.“, 2019 Background Information
Overview 2. Background Information 1. Continual learning 2. Prompt-based tuning 3. Dialogue state tracking 3. Continual Prompt Tuning for Dialogue State Tracking - Model Structure(Method) 4. Experiment Result 15
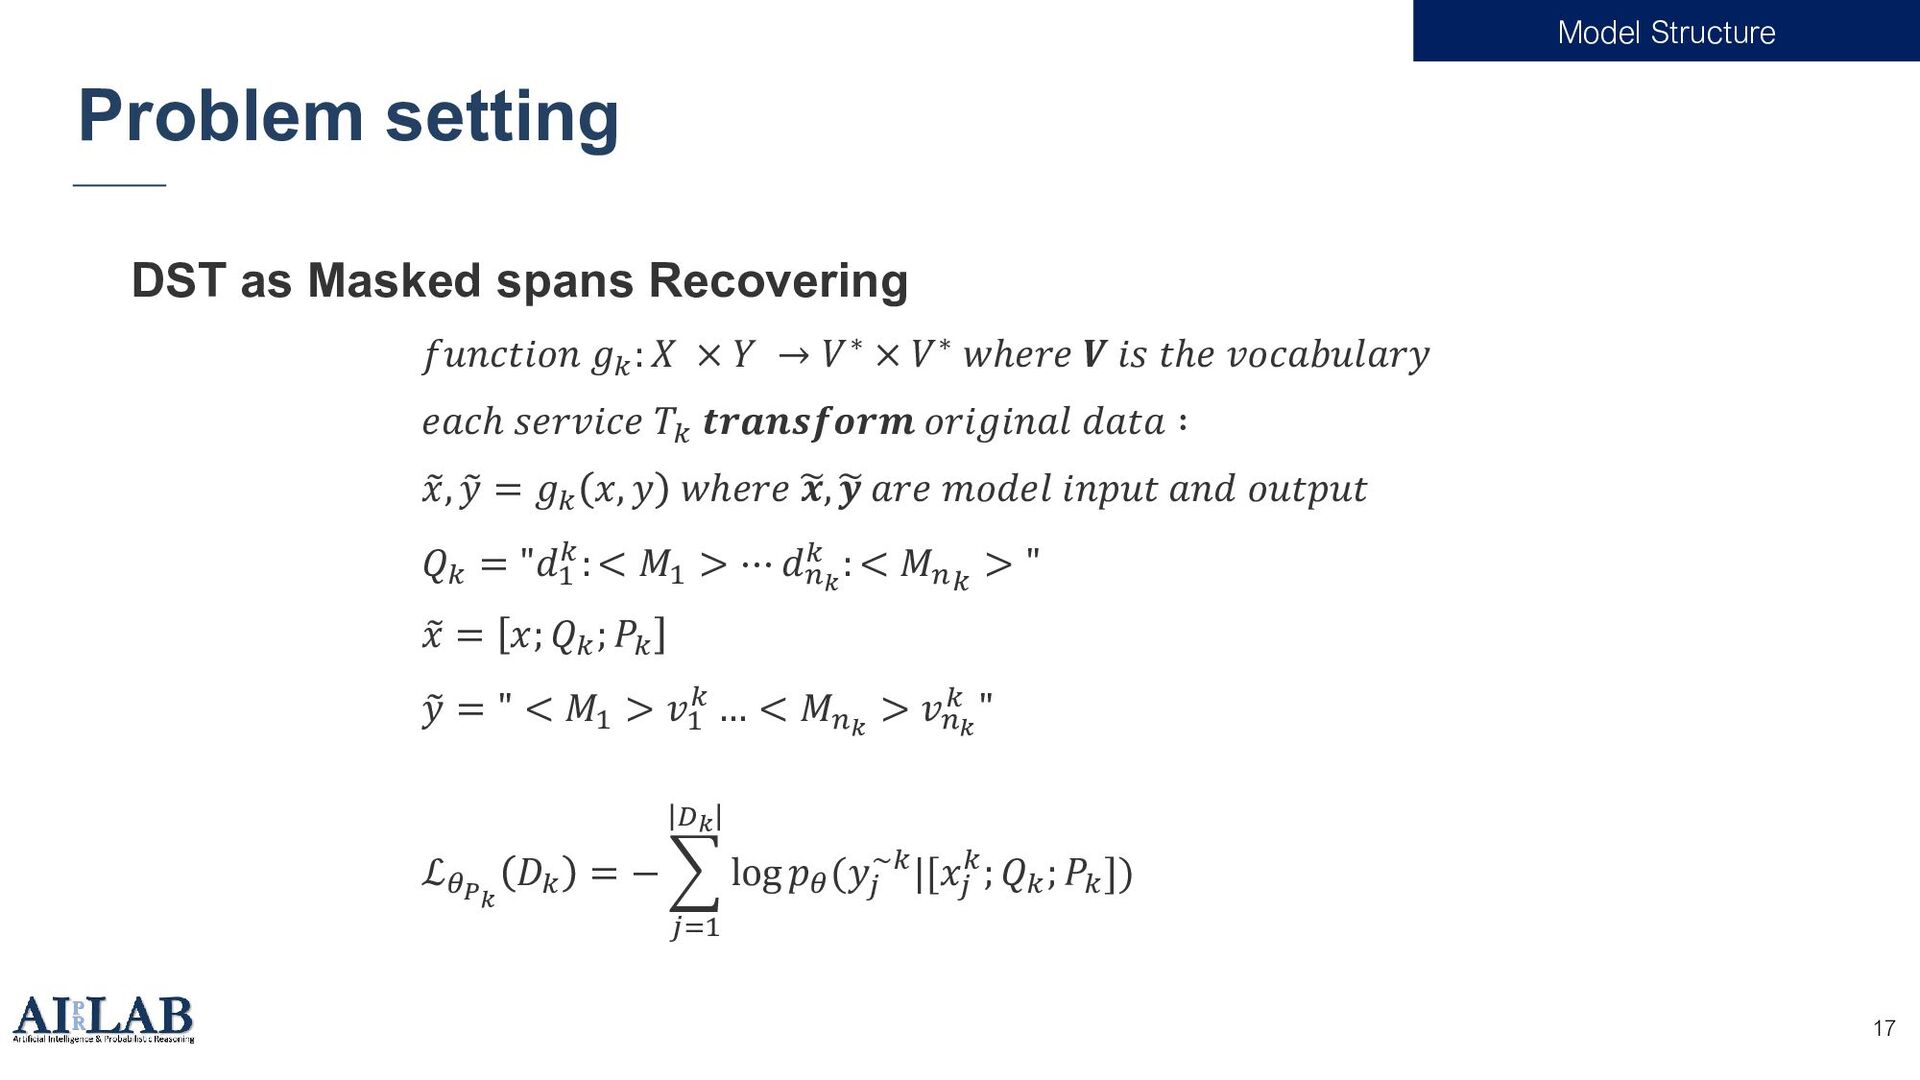
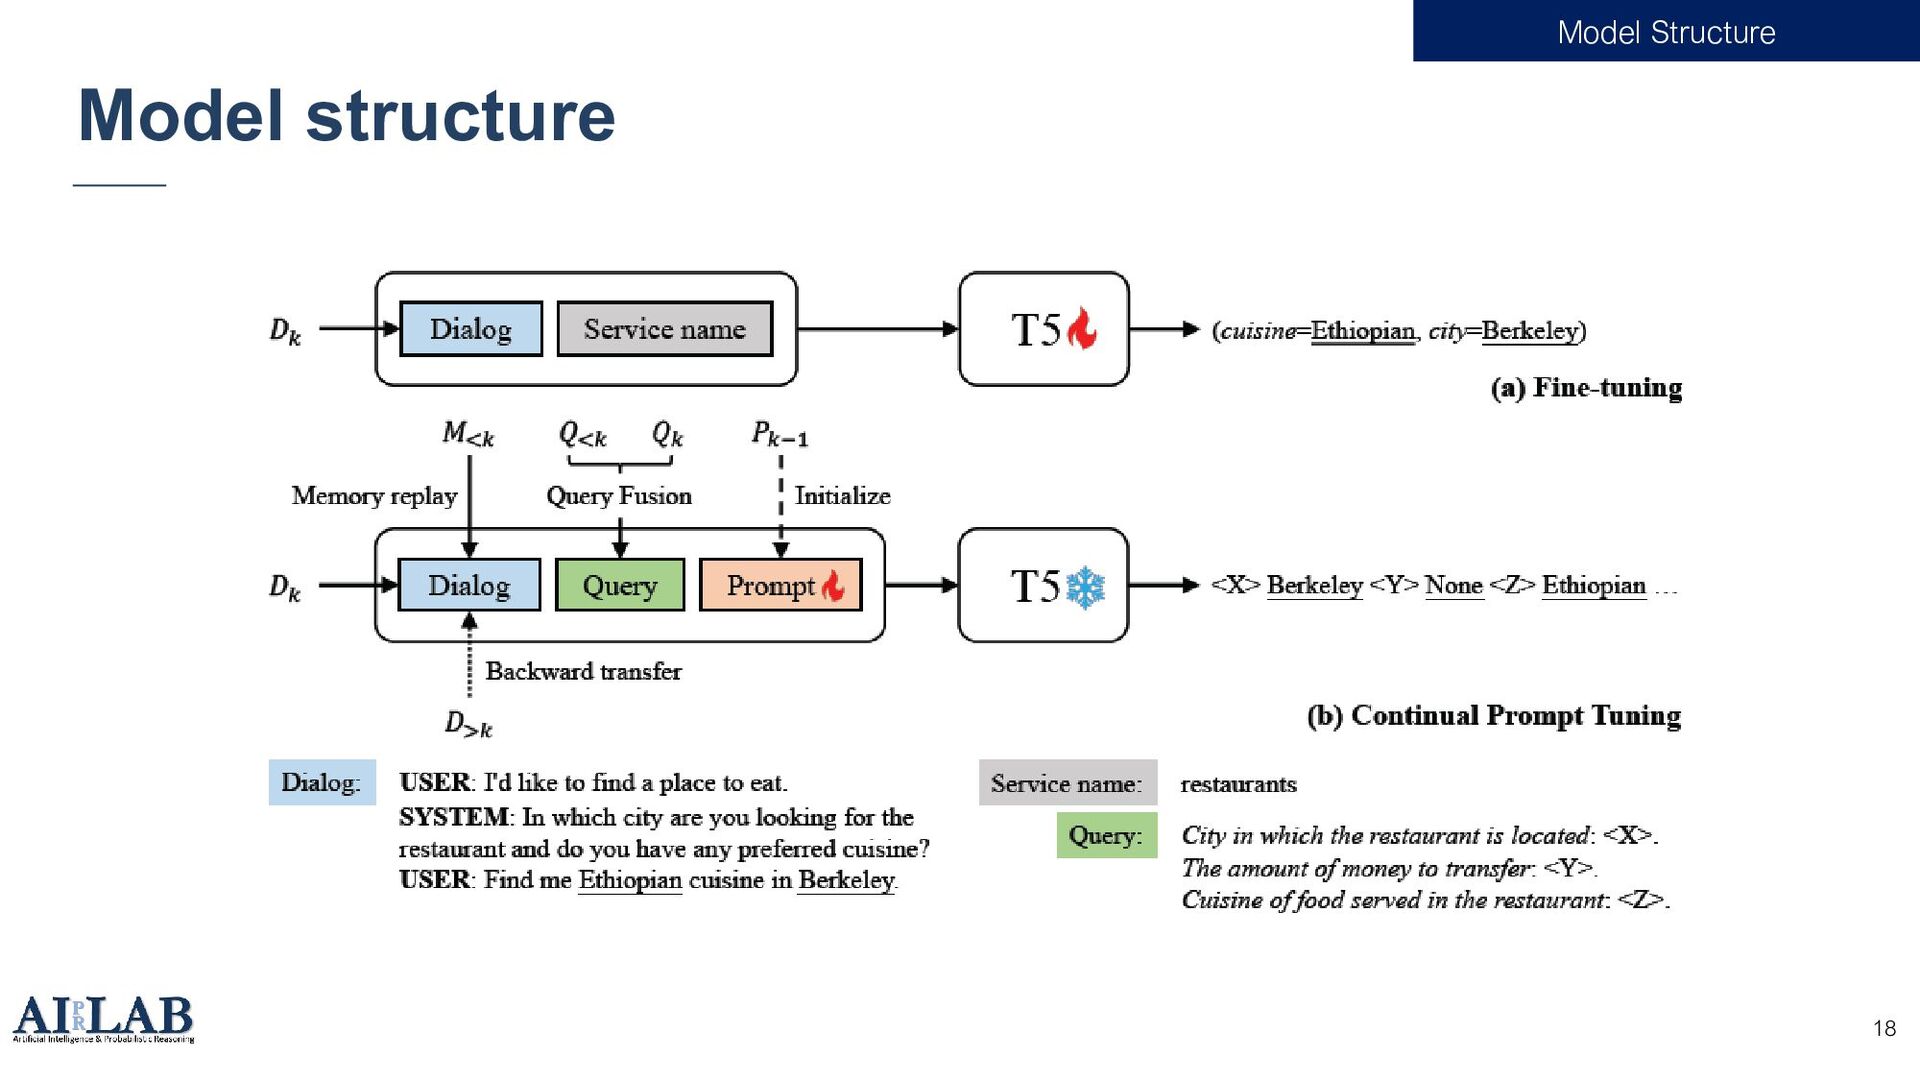
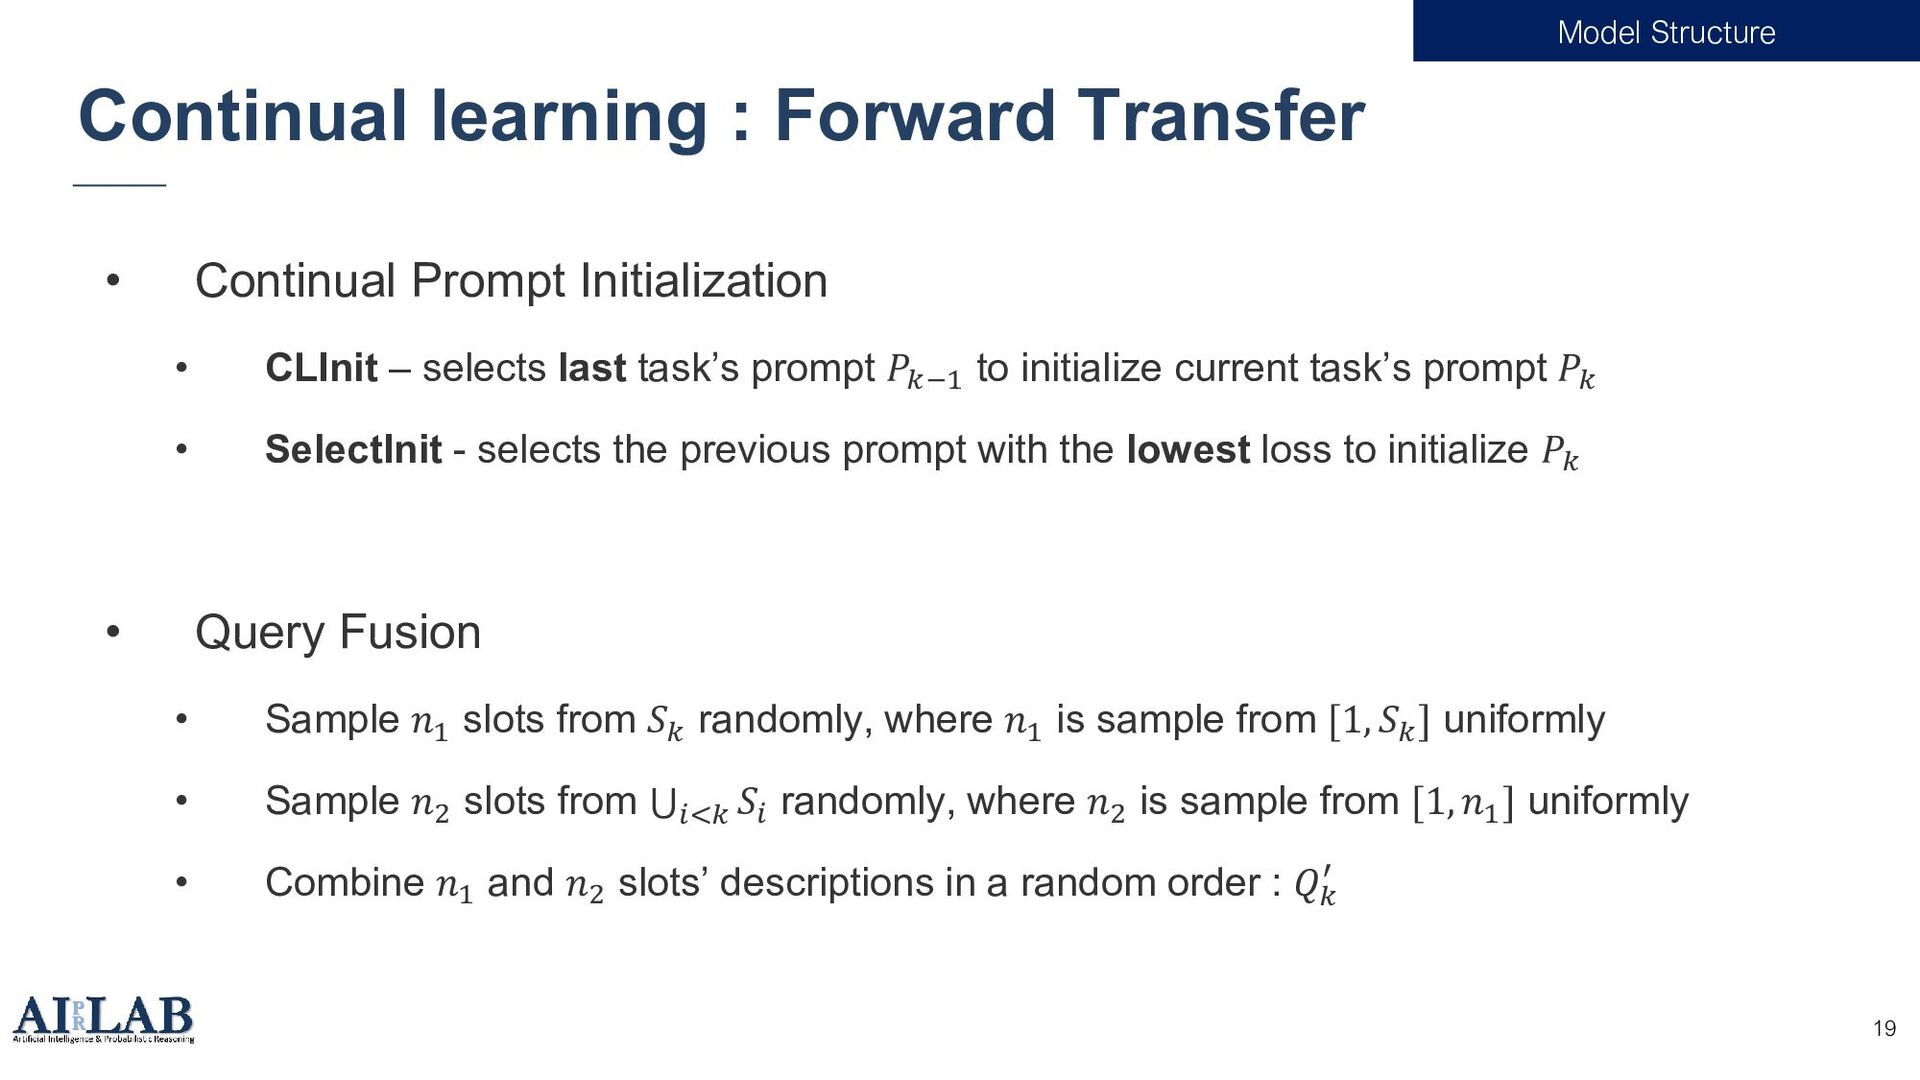
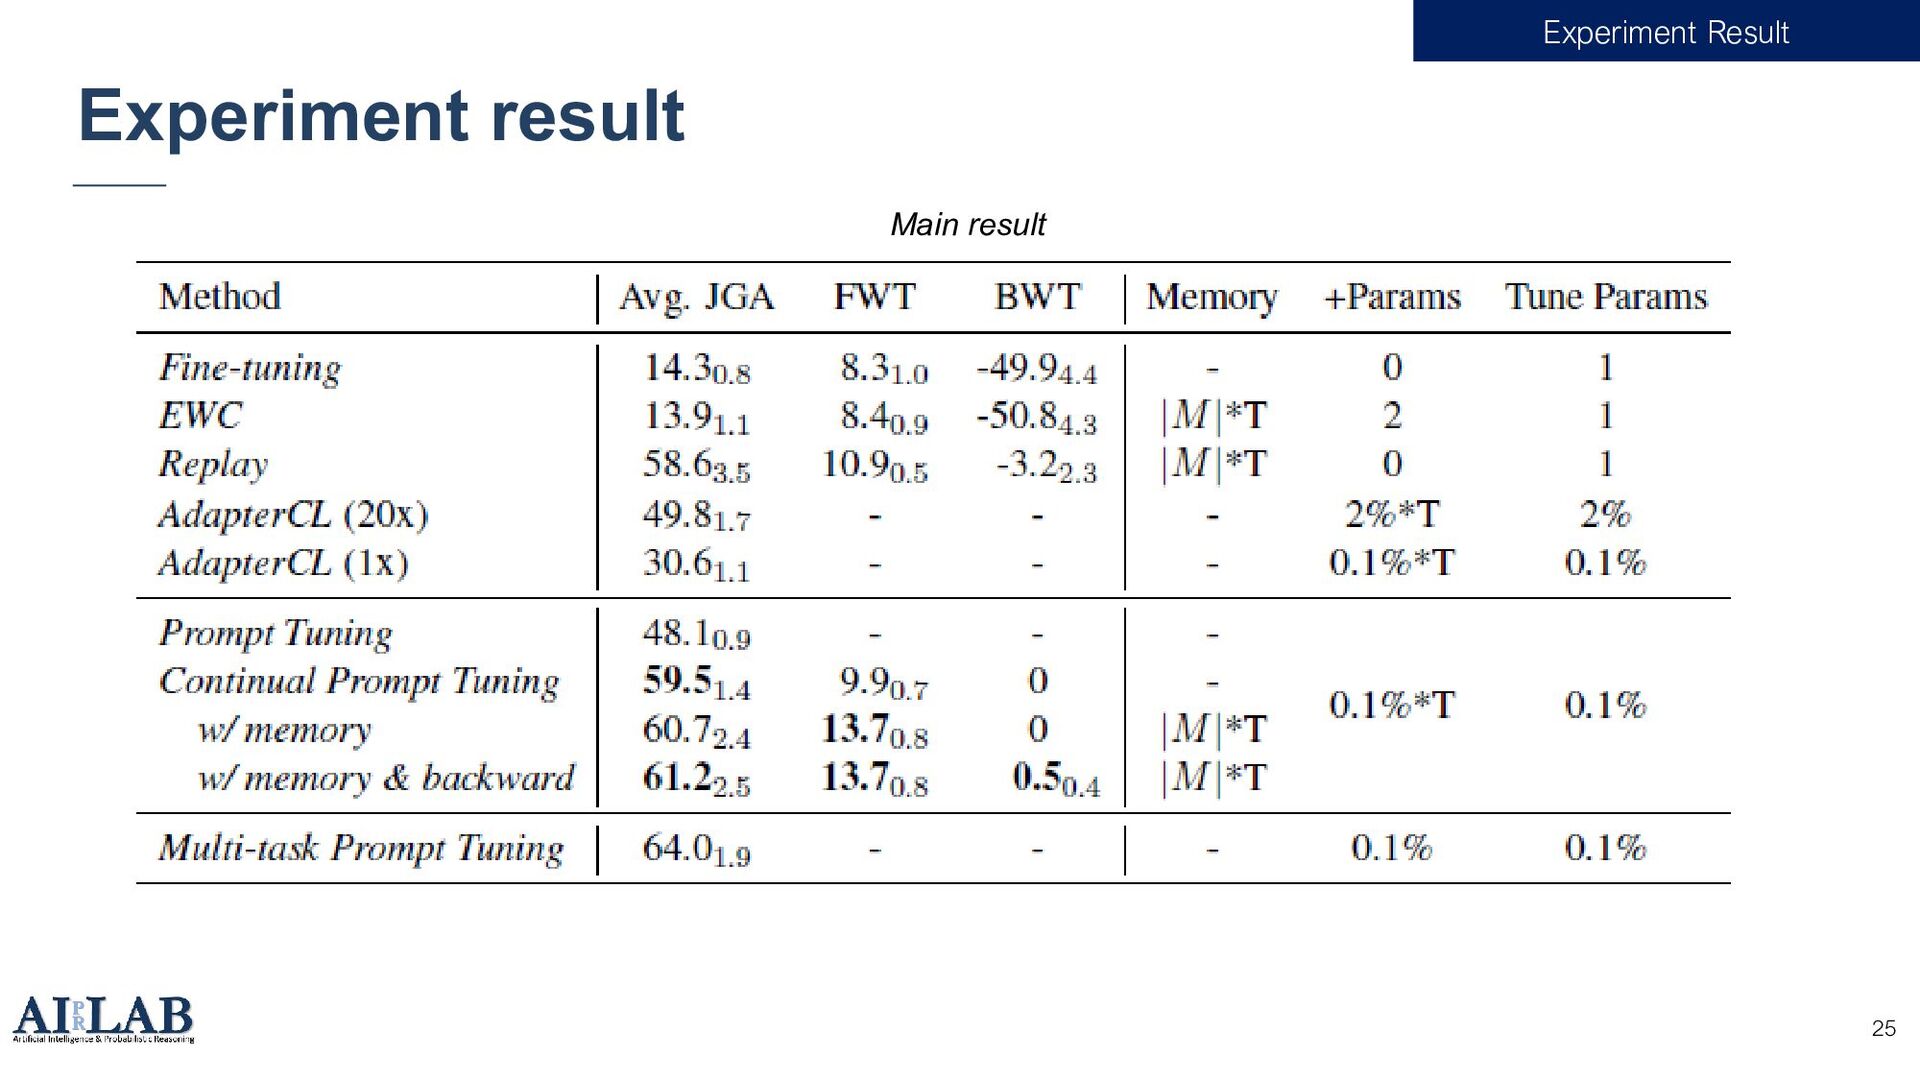
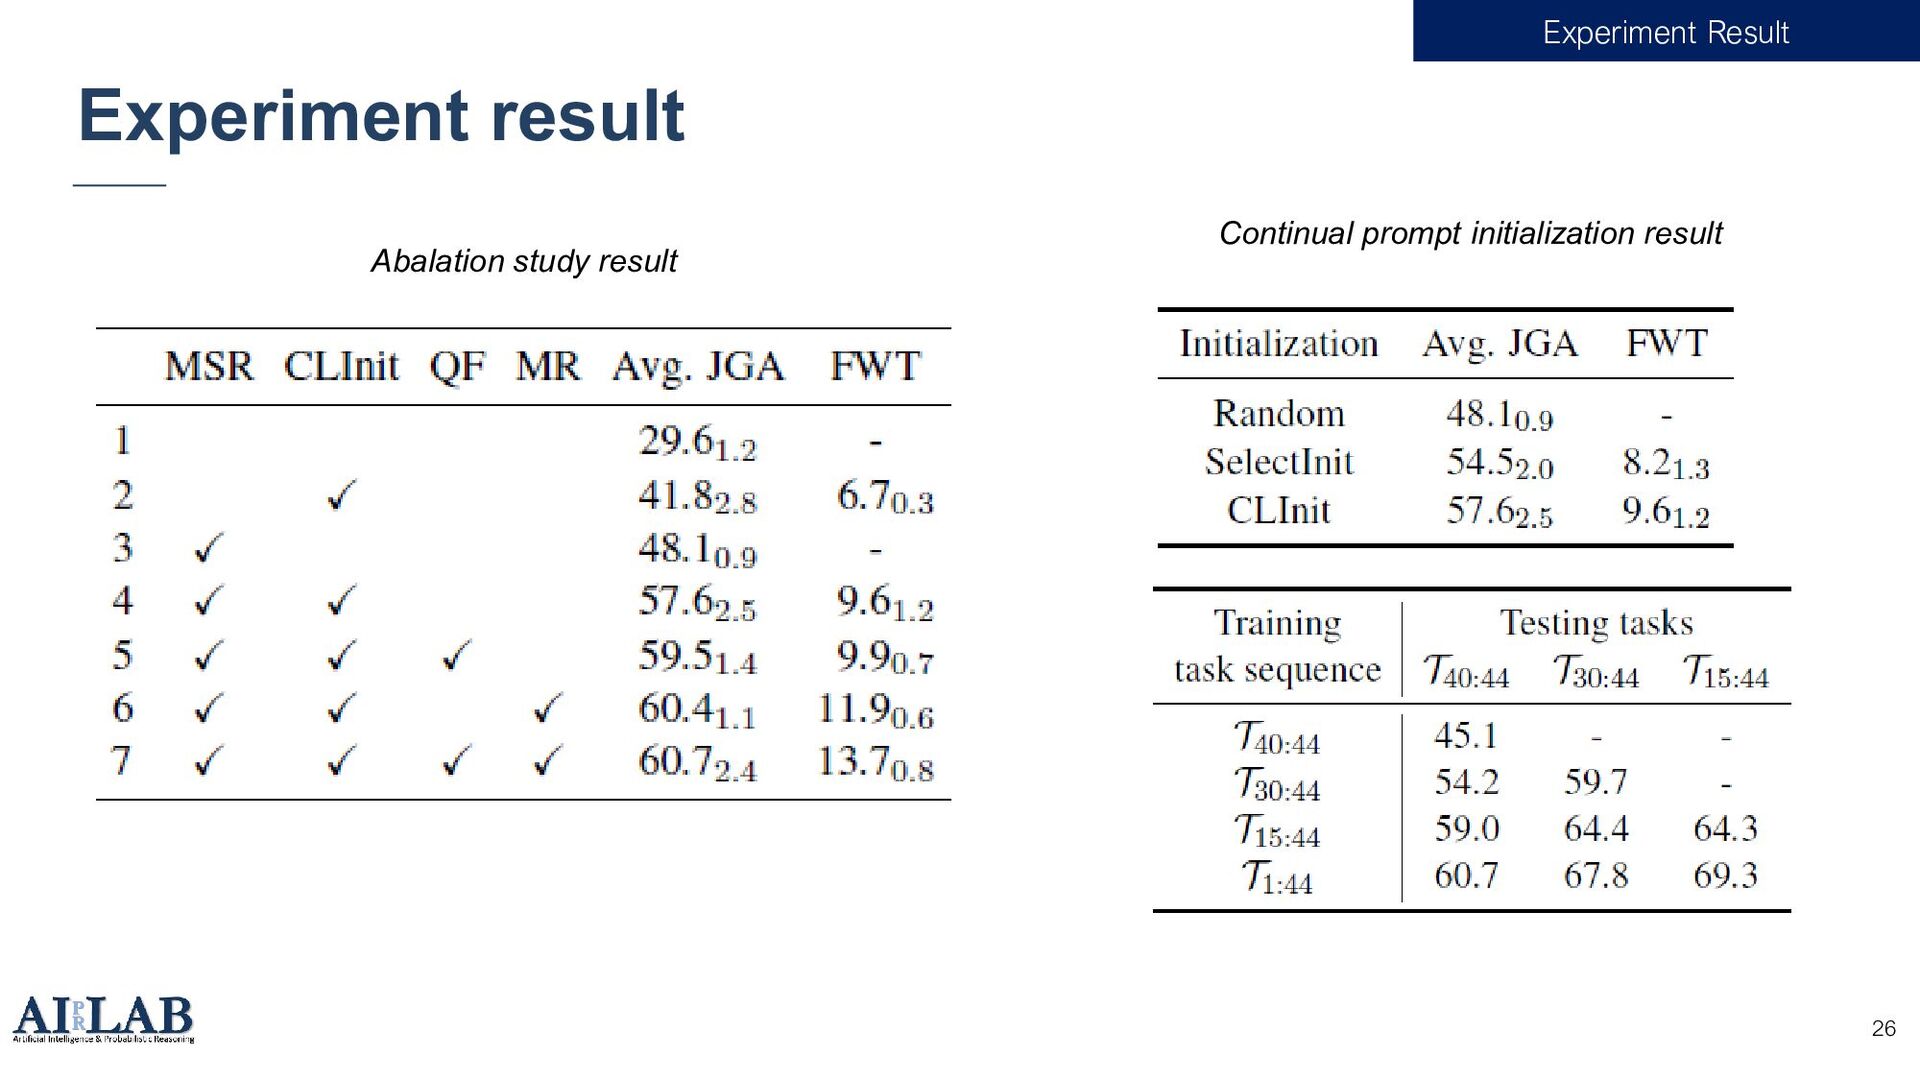
• CLInit – selects last task’s prompt 𝑃𝑃𝑘𝑘−1 to initialize current task’s prompt 𝑃𝑃𝑘𝑘 • SelectInit - selects the previous prompt with the lowest loss to initialize 𝑃𝑃𝑘𝑘 • Query Fusion • Sample 𝑛𝑛1 slots from 𝑆𝑆𝑘𝑘 randomly, where 𝑛𝑛1 is sample from [1, 𝑆𝑆𝑘𝑘 ] uniformly • Sample 𝑛𝑛2 slots from ⋃𝑖𝑖<𝑘𝑘 𝑆𝑆𝑖𝑖 randomly, where 𝑛𝑛2 is sample from [1, 𝑛𝑛1 ] uniformly • Combine 𝑛𝑛1 and 𝑛𝑛2 slots’ descriptions in a random order : 𝑄𝑄𝑘𝑘 ′ Model Structure
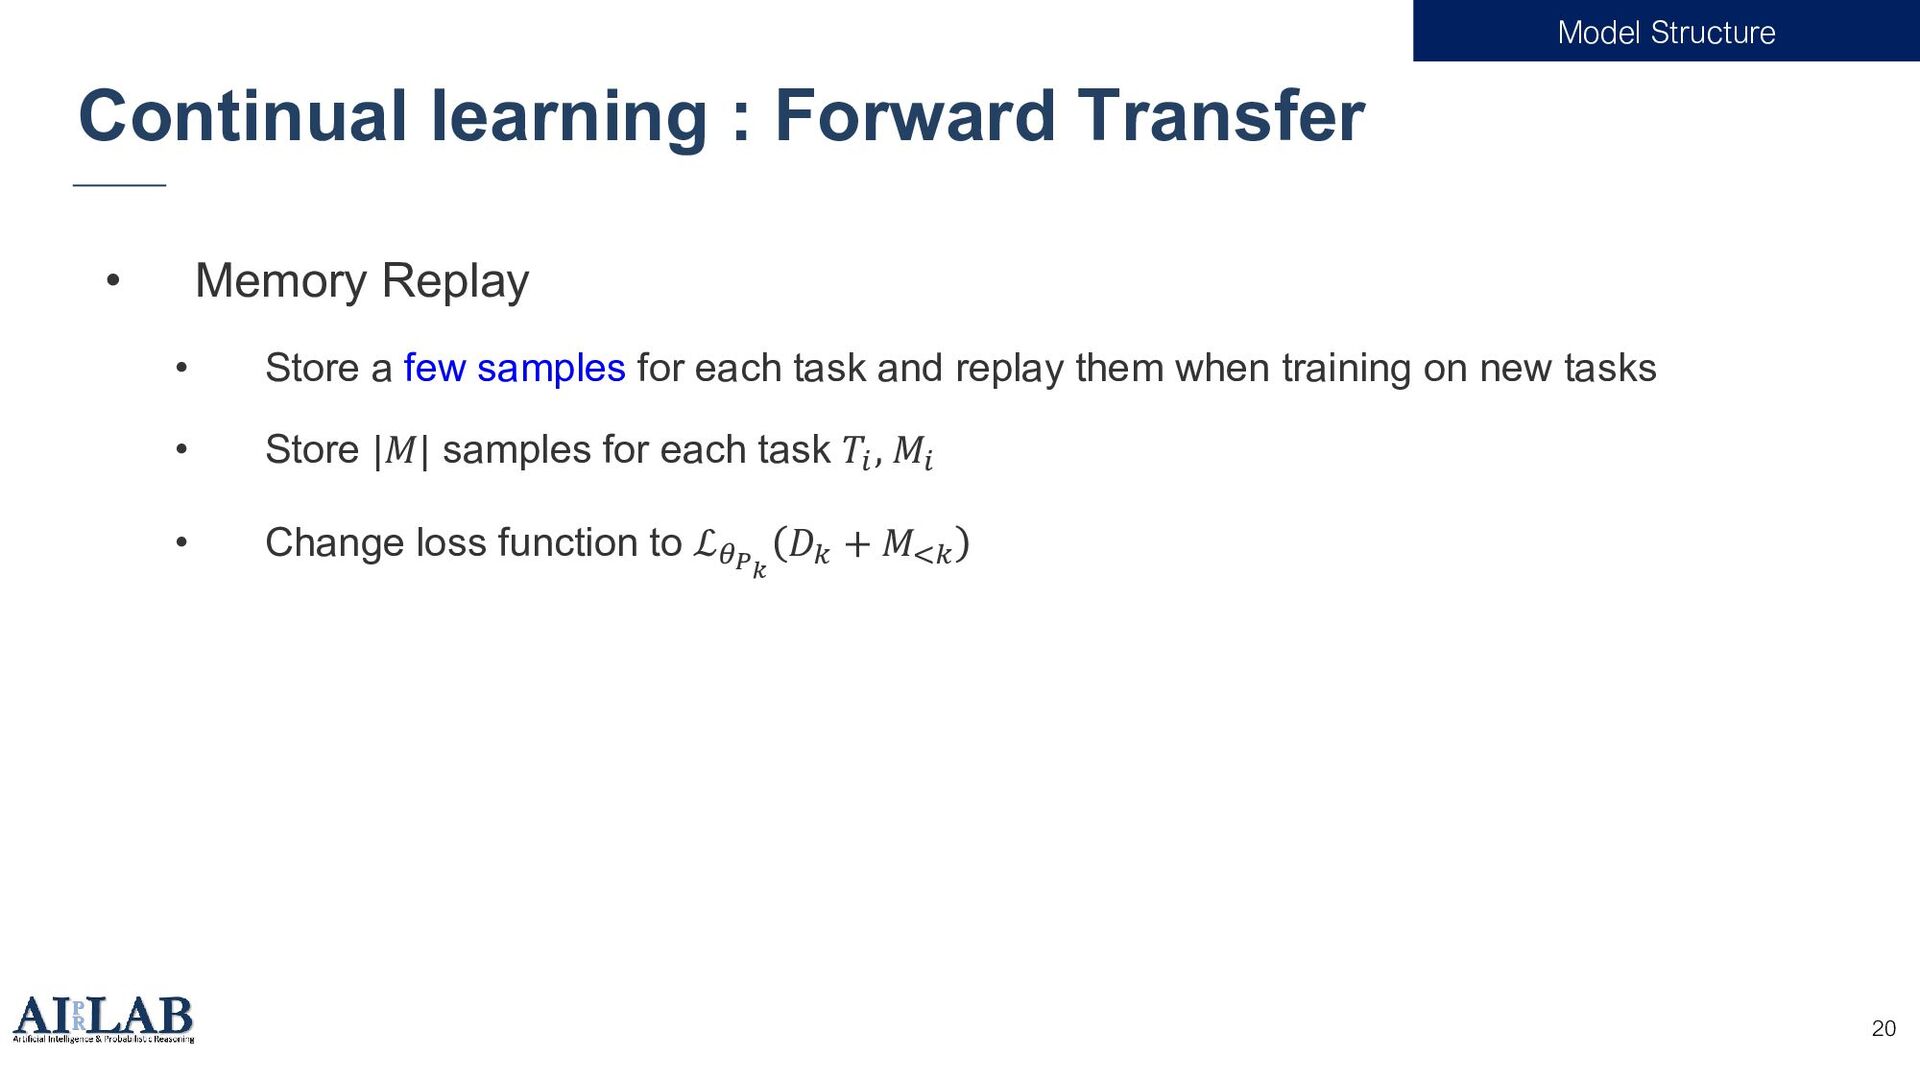
Store a few samples for each task and replay them when training on new tasks • Store |𝑀𝑀| samples for each task 𝑇𝑇𝑖𝑖 , 𝑀𝑀𝑖𝑖 • Change loss function to ℒ𝜃𝜃𝑃𝑃𝑘𝑘 𝐷𝐷𝑘𝑘 + 𝑀𝑀<𝑘𝑘 Model Structure
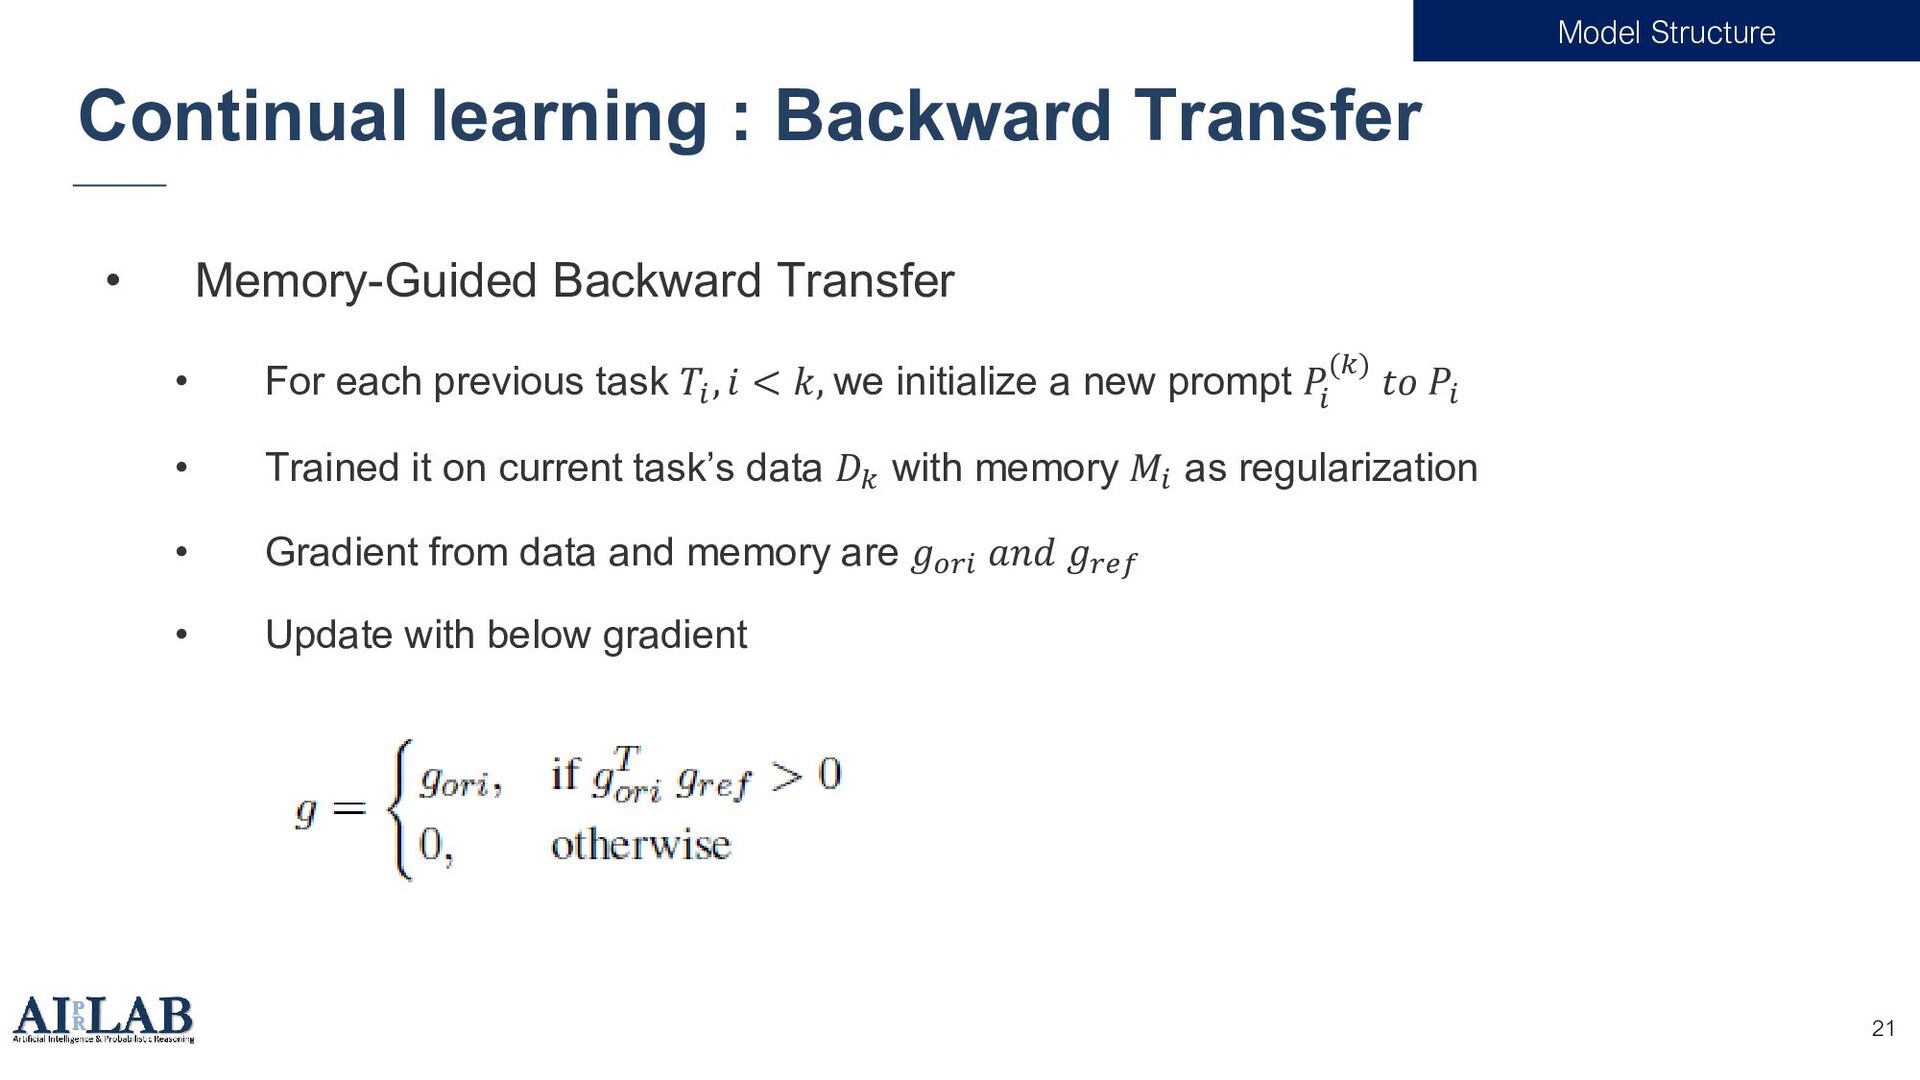
• For each previous task 𝑇𝑇𝑖𝑖 , 𝑖𝑖 < 𝑘𝑘, we initialize a new prompt 𝑃𝑃 𝑖𝑖 (𝑘𝑘) 𝑡𝑡𝑡𝑡 𝑃𝑃𝑖𝑖 • Trained it on current task’s data 𝐷𝐷𝑘𝑘 with memory 𝑀𝑀𝑖𝑖 as regularization • Gradient from data and memory are 𝑔𝑔𝑜𝑜𝑜𝑜𝑜𝑜 𝑎𝑎𝑎𝑎𝑎𝑎 𝑔𝑔𝑟𝑟𝑟𝑟𝑟𝑟 • Update with below gradient Model Structure
Overview 2. Background Information 1. Continual learning 2. Prompt-based tuning 3. Dialogue state tracking 3. Continual Prompt Tuning for Dialogue State Tracking - Model Structure(Method) 4. Experiment Result 23


 shhwang
 shibuiwilliam
 tomonom
 anikisencyo
 sira
 ftakahashi
 hellosct1
 hotchpotch
 resolutionfoundation
 rikkabotan7
 mickey_0226
 ishiirikie
 recsyslab
 sabderemane
 ianozsvald
 honzajavorek
 inesmontani
 michielstock
 aleyda
 szymonslowik
 ks91
 gurzu
 mayatellez
 codingconduct
 rasagy