Share
Embed

Transcript
37 slides
-
PT2TT : Prompt Tuning via Pre-training Task Template Transfer 황
승 현 한국과학기술원 김재철AI대학원 석사과정 석사학위논문심사 발표 2023-12-05 -
Contents 2 1. Background Information 2. Pilot Experiments 3. Method
4. Experiments 5. Conclusion -
Contents 3 1. Background Information 2. Pilot Experiments 3. Method
4. Experiments 5. Conclusion -
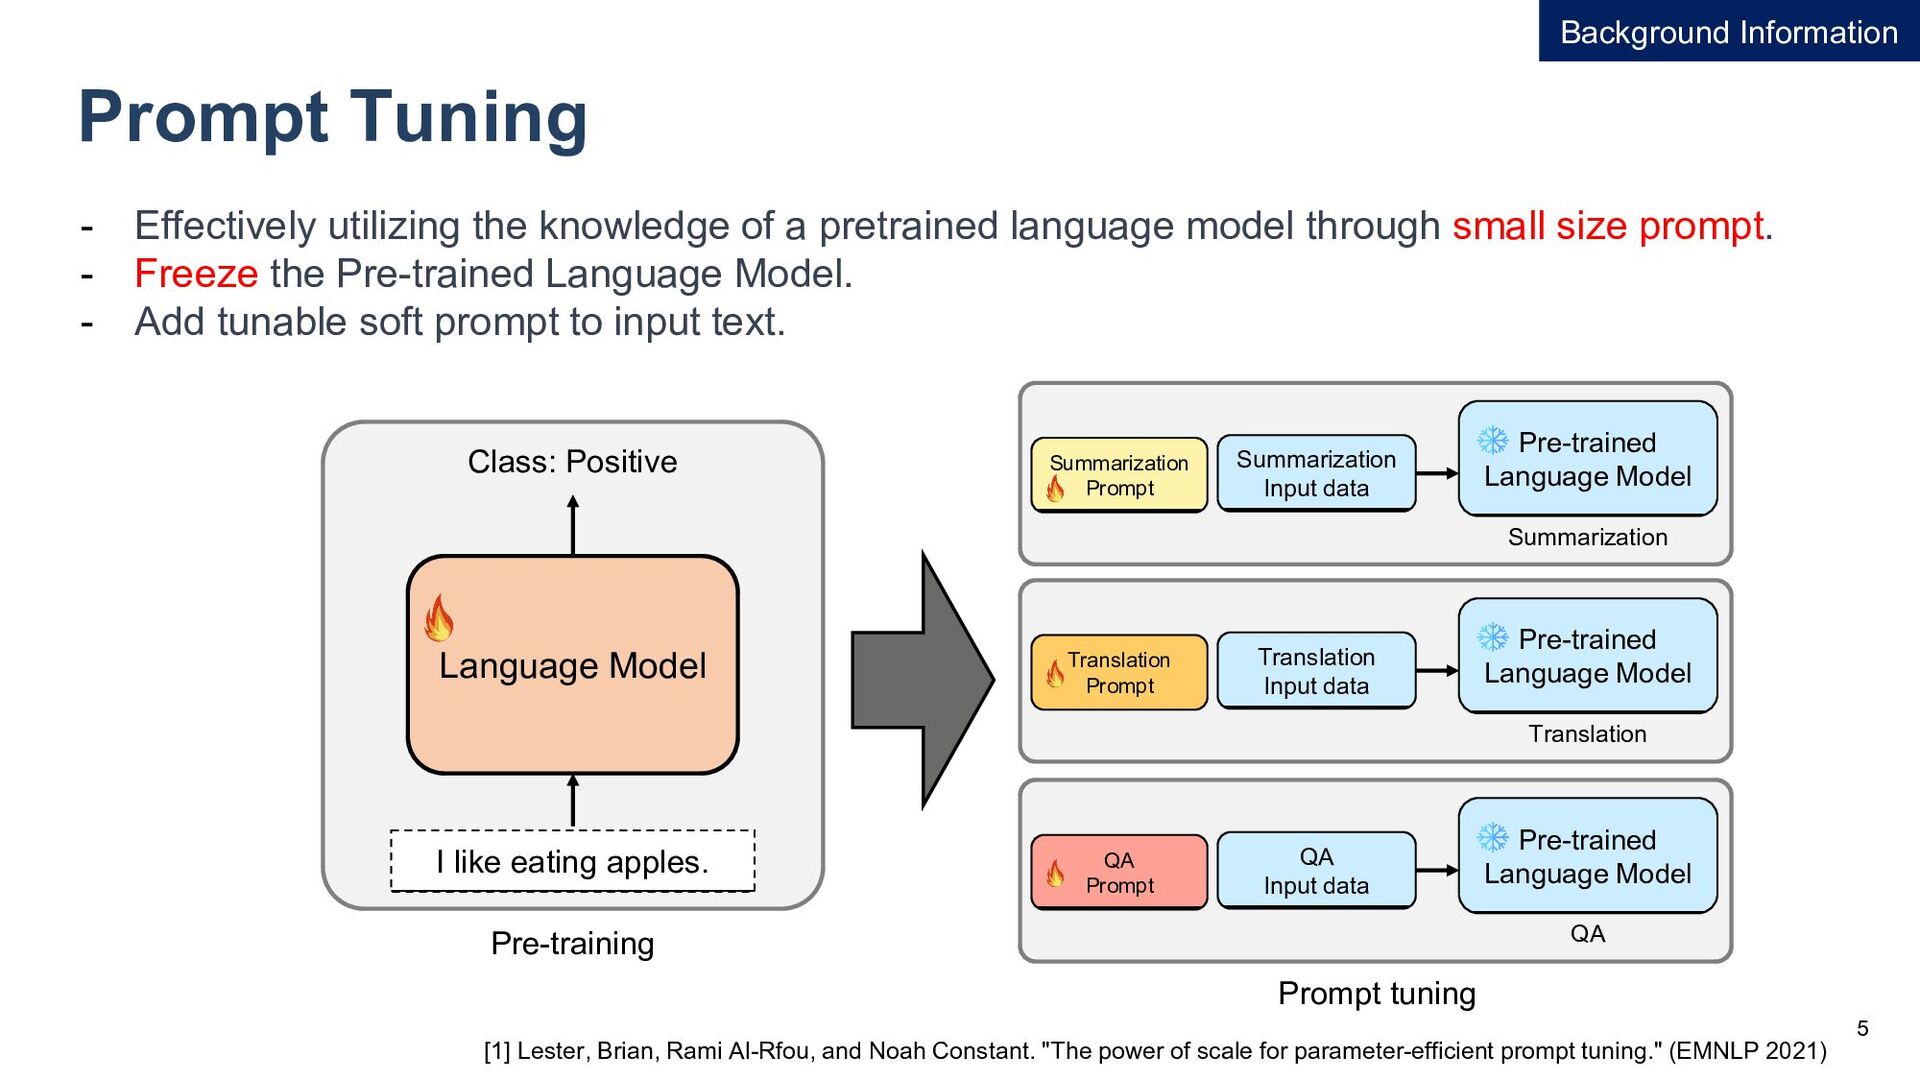
Prompt Tuning 5 - Effectively utilizing the knowledge of a
pretrained language model through small size prompt. - Freeze the Pre-trained Language Model. - Add tunable soft prompt to input text. Pre-training Language Model I like eating apples. Class: Positive Pre-trained Language Model Summarization Prompt Summarization Prompt tuning Summarization Input data Pre-trained Language Model Translation Prompt Translation Translation Input data Pre-trained Language Model QA Prompt QA QA Input data [1] Lester, Brian, Rami Al-Rfou, and Noah Constant. "The power of scale for parameter-efficient prompt tuning." (EMNLP 2021) Background Information -
Demystifying Prompts via Perplexity Estimation[1] 6 [1] Gonen, Hila, et
al. "Demystifying prompts in language models via perplexity estimation." (arXiv:2212.04037, Meta AI Research) - Performance varies based on prompt choice and familiarity. - Lower perplexity prompts yield better results. - Use GPT-3 and backtranslation to generate low-perplexity, high-performance prompts. Background Information -
Different Input Processing Methods 7 [1] Raffel, Colin, et al.
"Exploring the limits of transfer learning with a unified text-to-text transformer." (JMLR). [2] Asai, Akari, et al. "ATTEMPT: Parameter-efficient multi-task tuning via attentional mixtures of soft prompts." (EMNLP 2022). [3] Ding, Ning, et al. "OpenPrompt: An open-source framework for prompt-learning." (arXiv:2111.01998). - Use input processing using various methods according to research protocols. - Pre-training task of T5[1] and ATTEMPT[2] use task-specific tokens. - OpenPrompt[3] adds contextually relevant tokens, including masked sentences. Background Information -
Input Tuning[1] 8 [1] An, Shengnan, et al. "Input-tuning: Adapting
unfamiliar inputs to frozen pretrained models." (arXiv:2203.03131). Figure: An example of Input Tuning - Investigates the limitations of prompt-tuning for natural language generation (NLG) tasks, specifically when dealing with unfamiliar inputs. - “Input-tuning," a method that fine-tunes both the continuous prompts and the input representations to better adapt to such inputs. Background Information -
Contents 9 1. Background Information 2. Pilot Experiments 3. Method
4. Experiments 5. Conclusion -
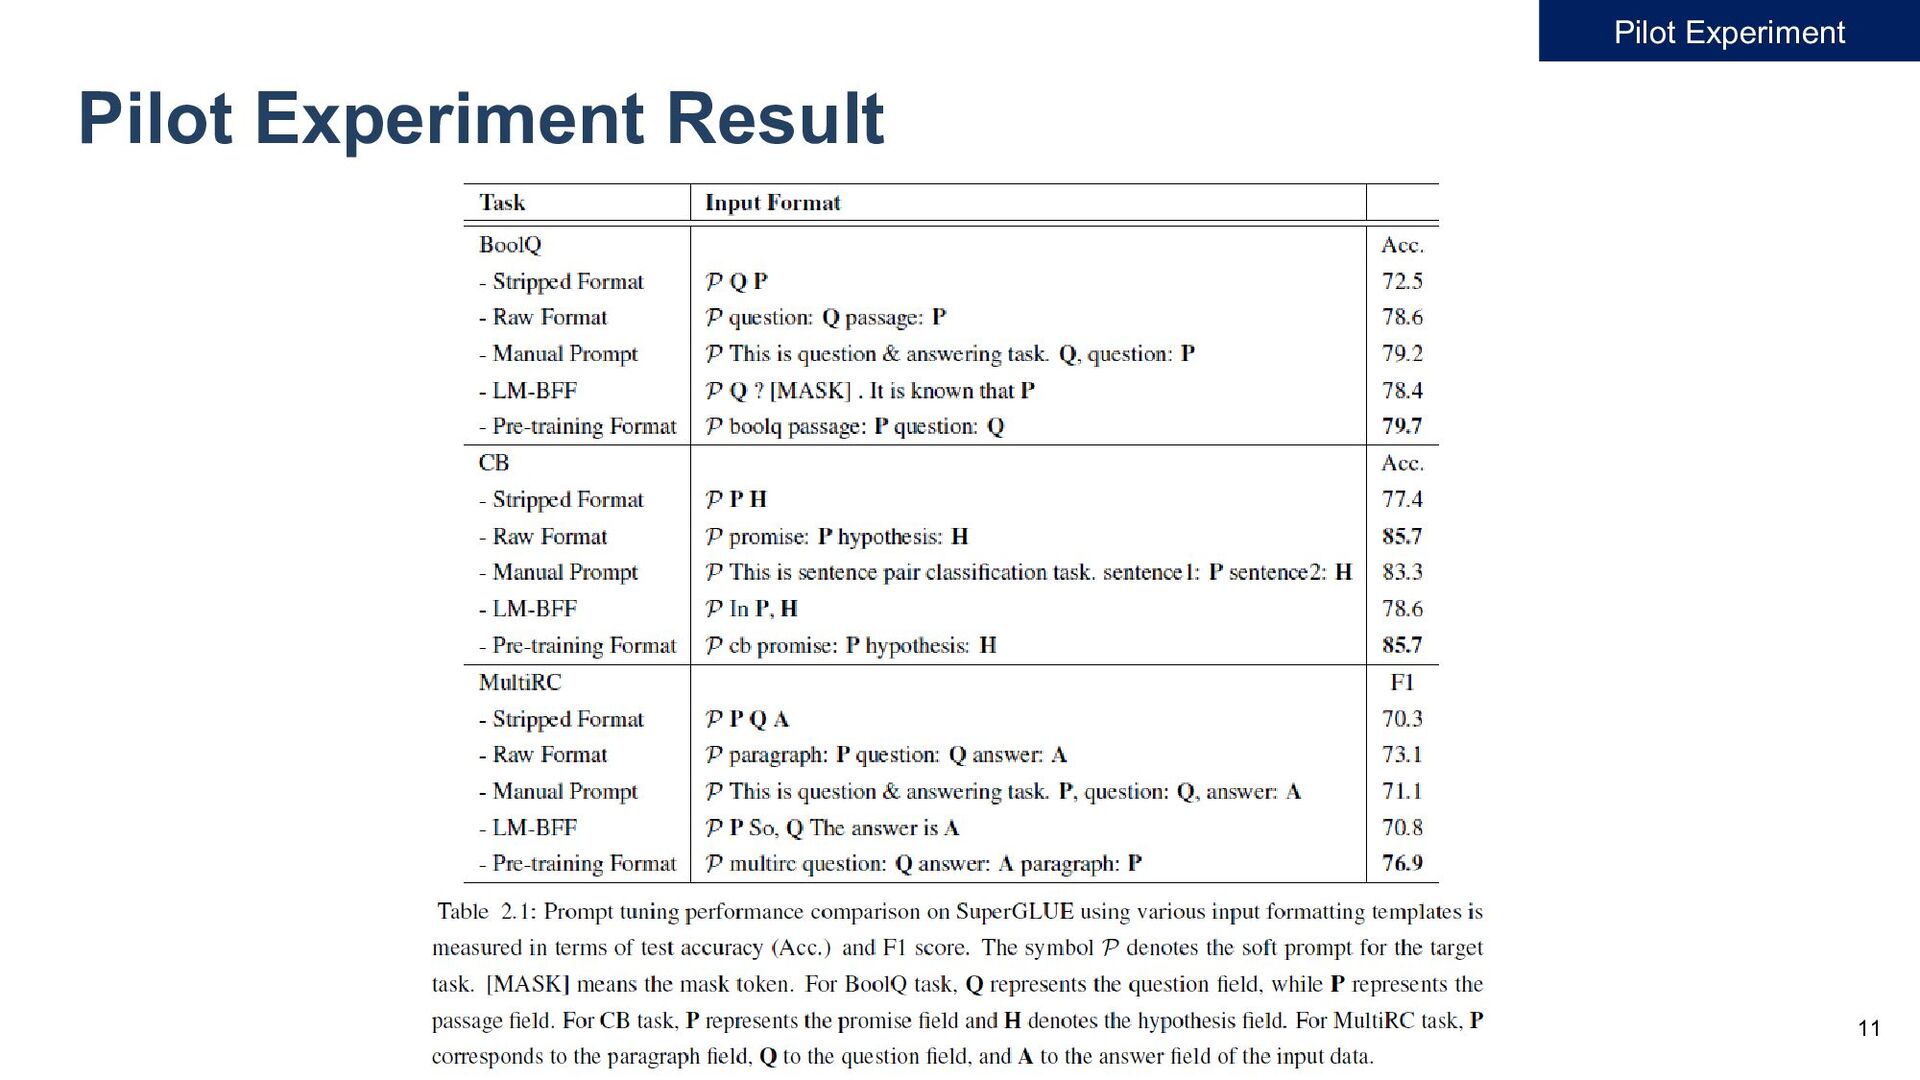
10 Objective What is the ideal input format in prompt
tuning? [1] Raffel, Colin, et al. "Exploring the limits of transfer learning with a unified text-to-text transformer." (The Journal of ML Research). [2] Gao, Tianyu, Adam Fisch, and Danqi Chen. "Making pre-trained language models better few-shot learners." (ACL 2021). 1. The pre-training format used by the T5[1] at pre-training process. 2. The raw format which simply concatenates field names and values. 3. The LM-BFF[2] format generated from the language model. 4. The hand-crafted format (manual prompt) which contains task descriptions. 5. The stripped format which simply concatenates input values only. Pilot Experiment -
Contents 12 1. Background Information 2. Pilot Experiments 3. Method
4. Experiments 5. Conclusion -
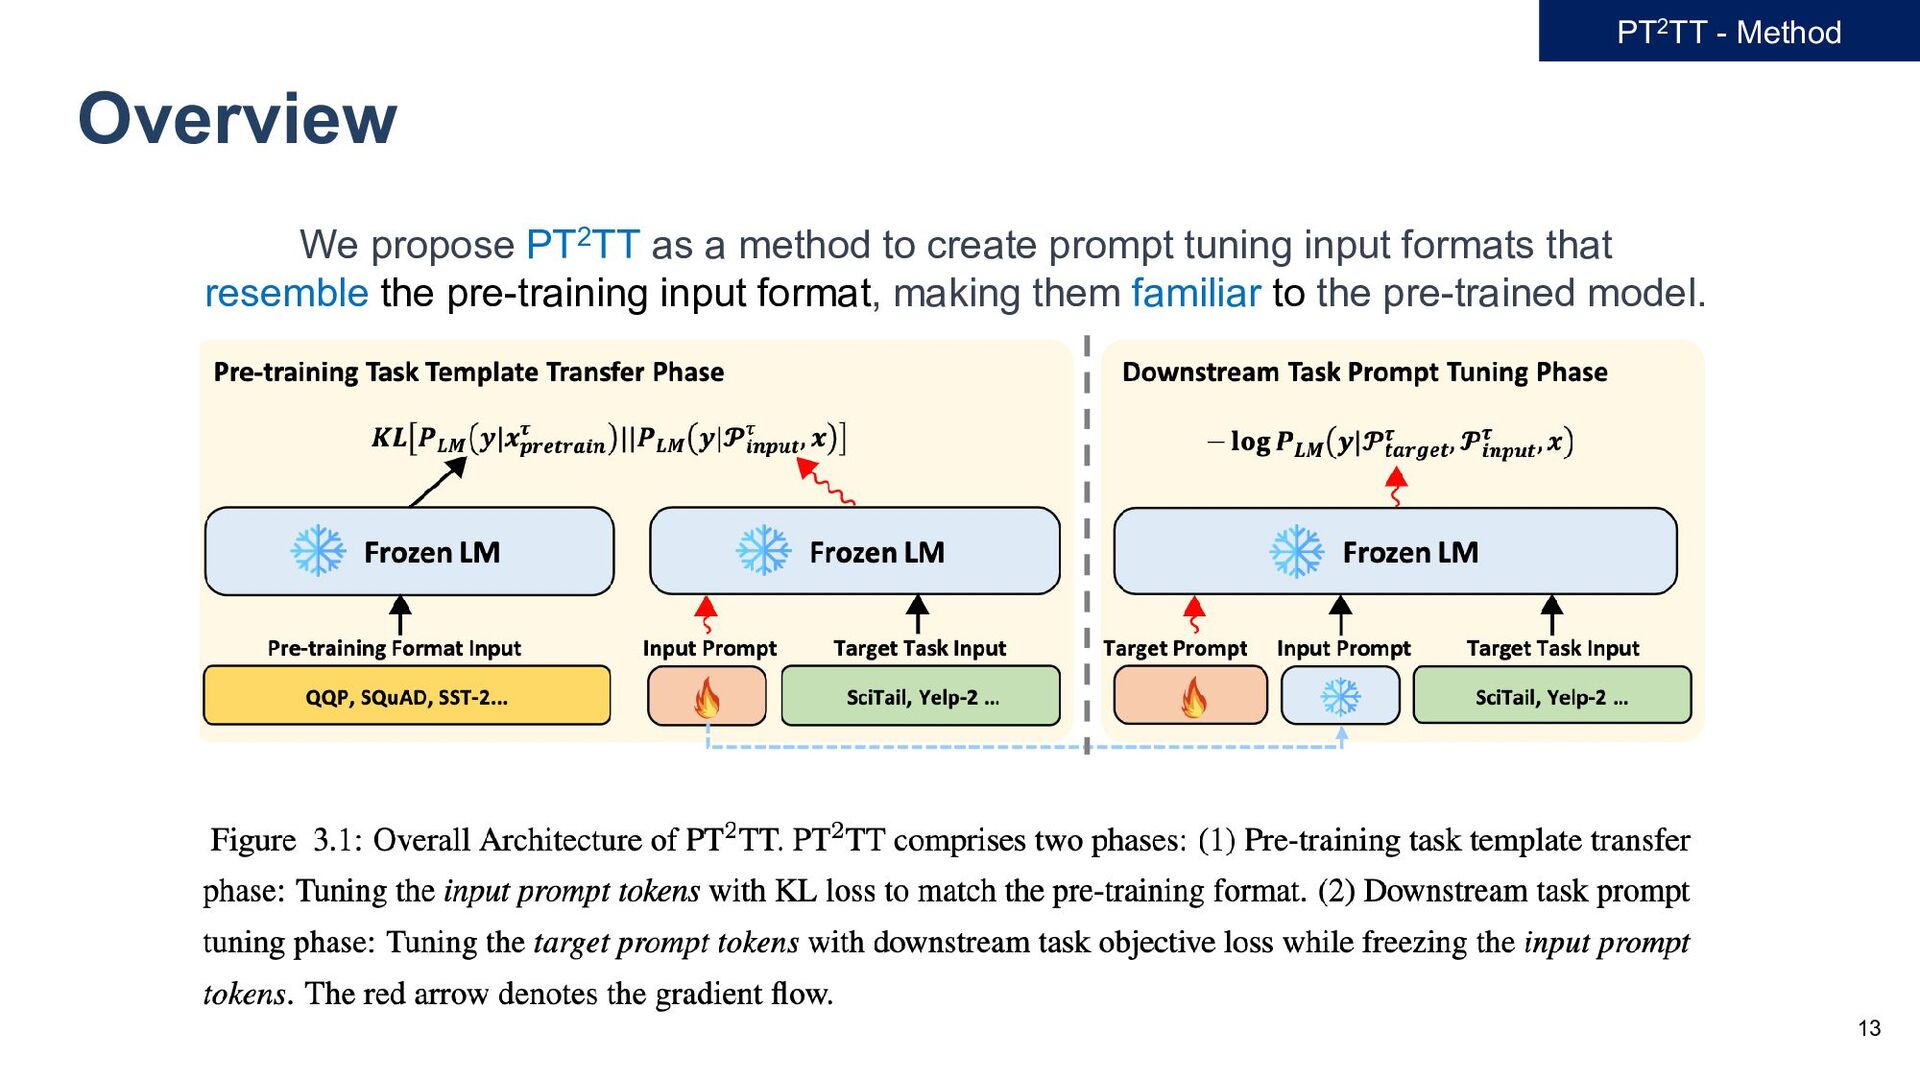
13 Overview We propose PT2TT as a method to create
prompt tuning input formats that resemble the pre-training input format, making them familiar to the pre-trained model. PT2TT - Method -
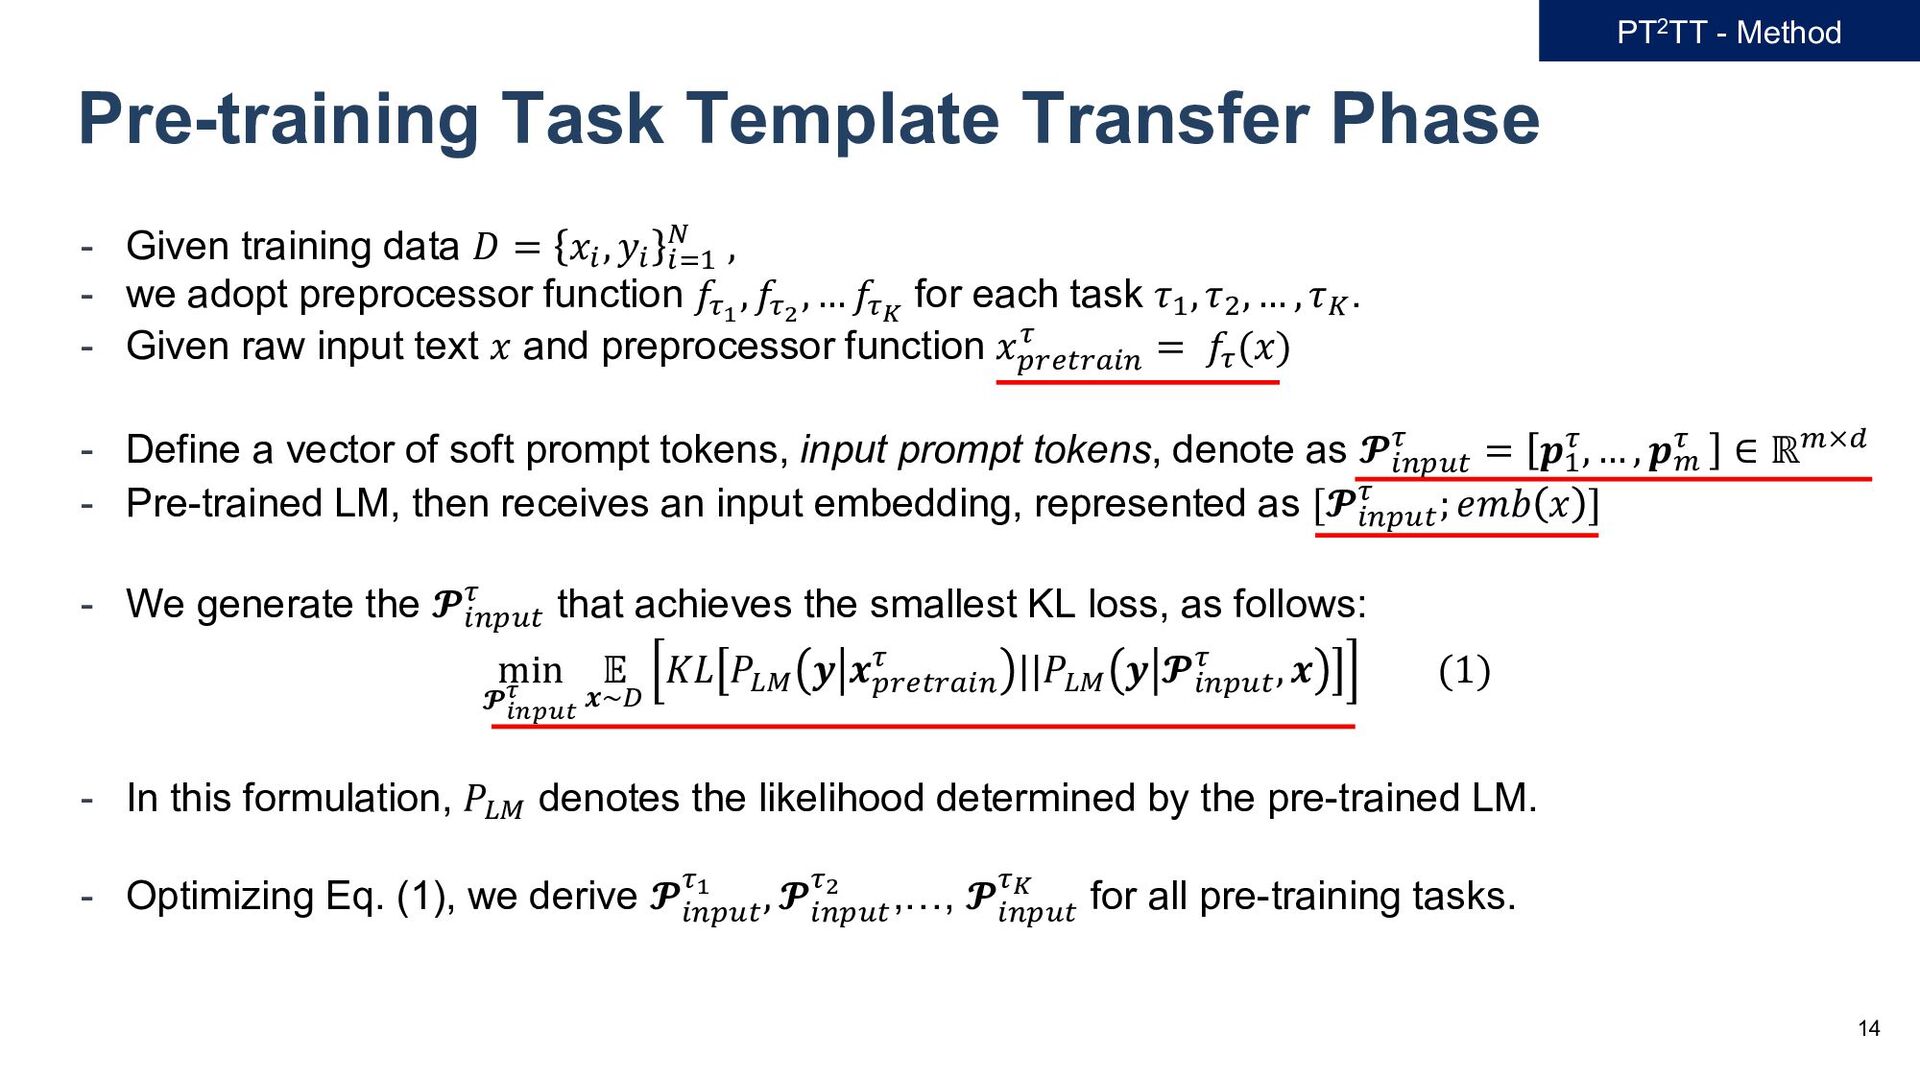
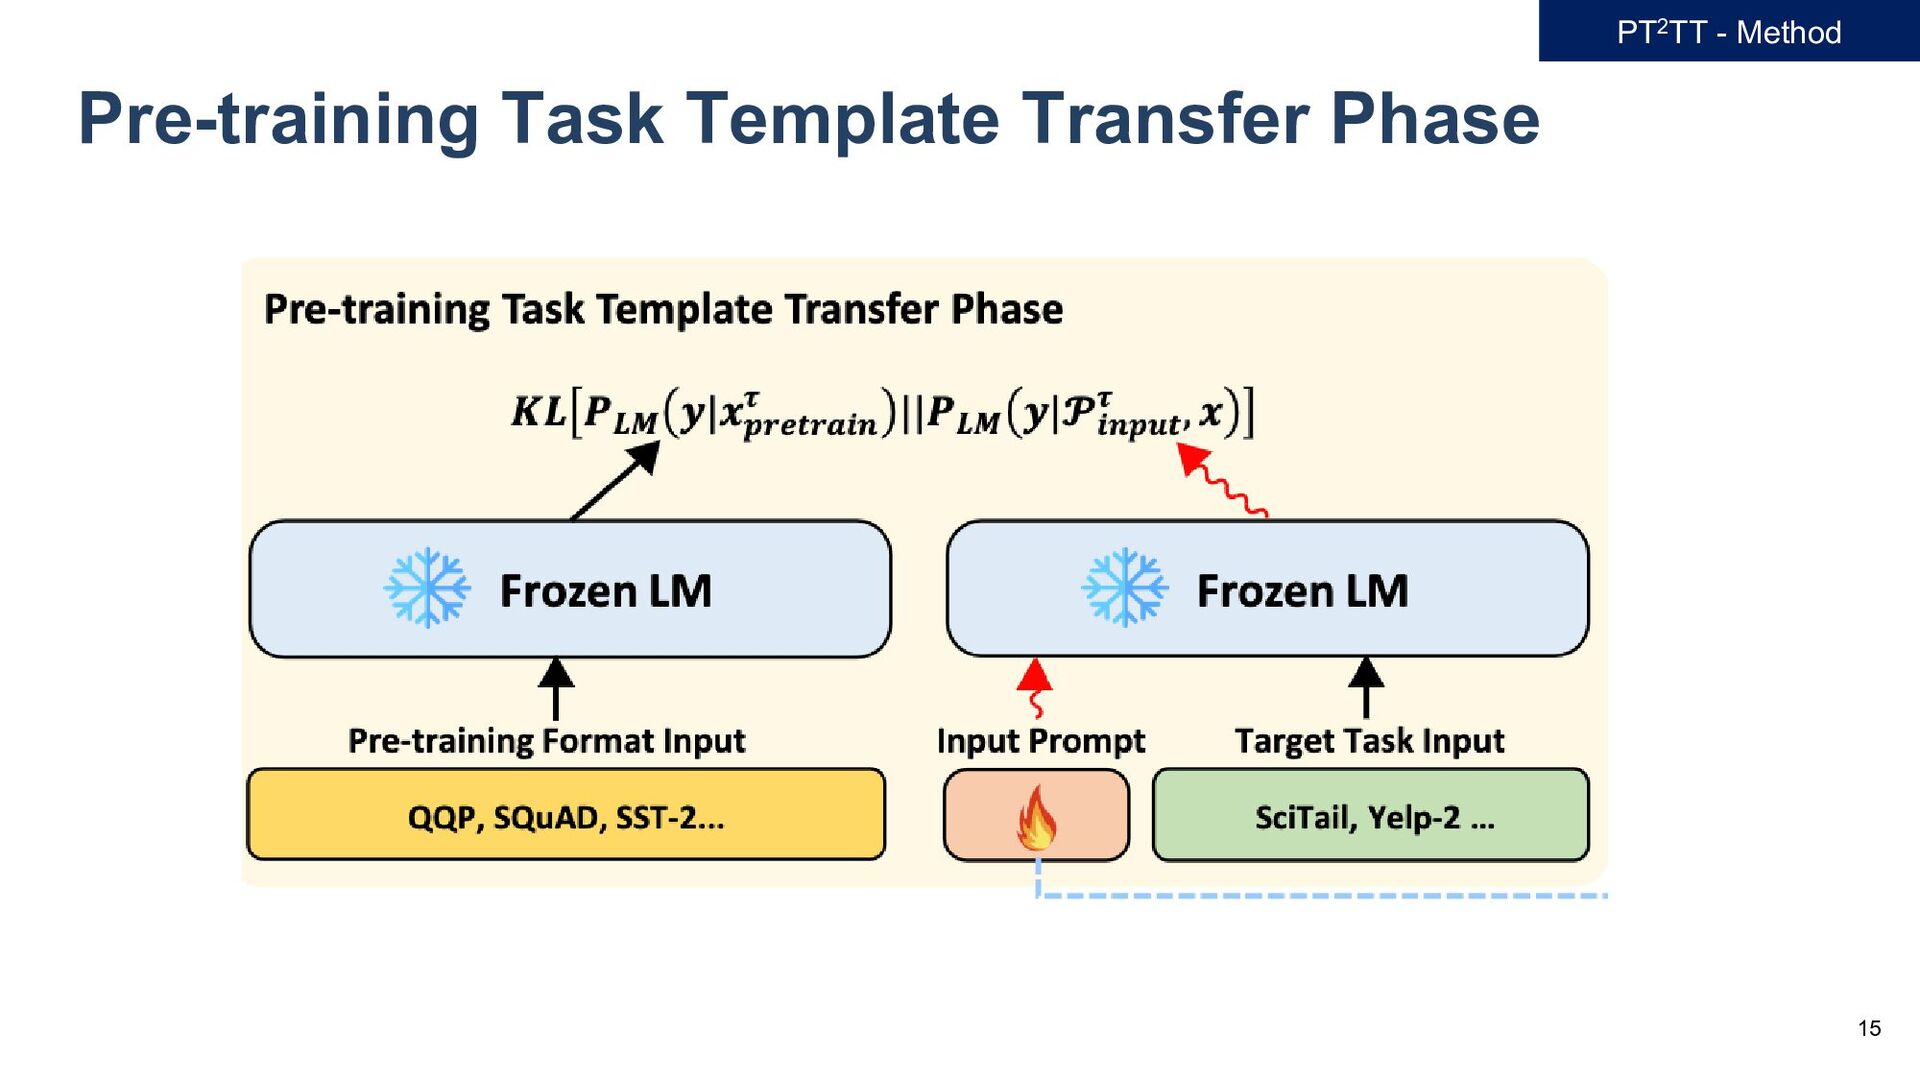
14 Pre-training Task Template Transfer Phase - Given training data
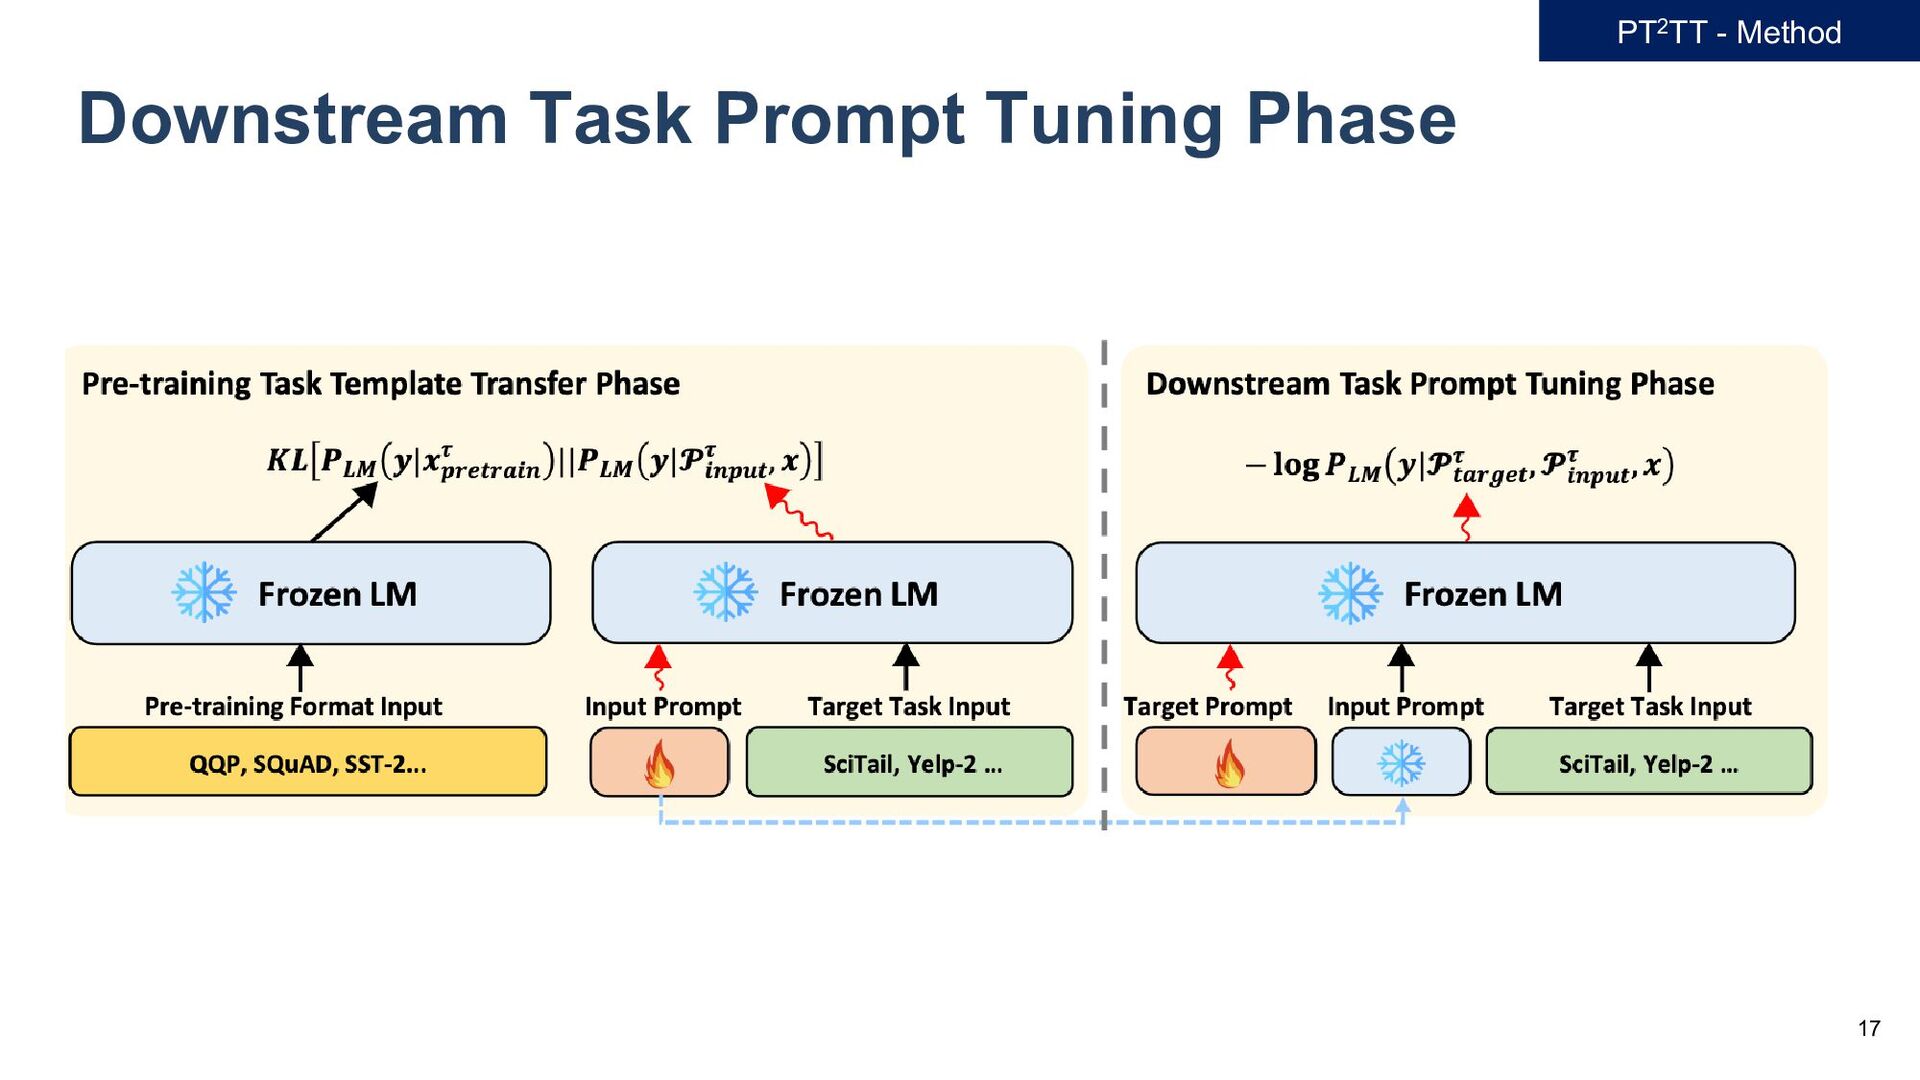
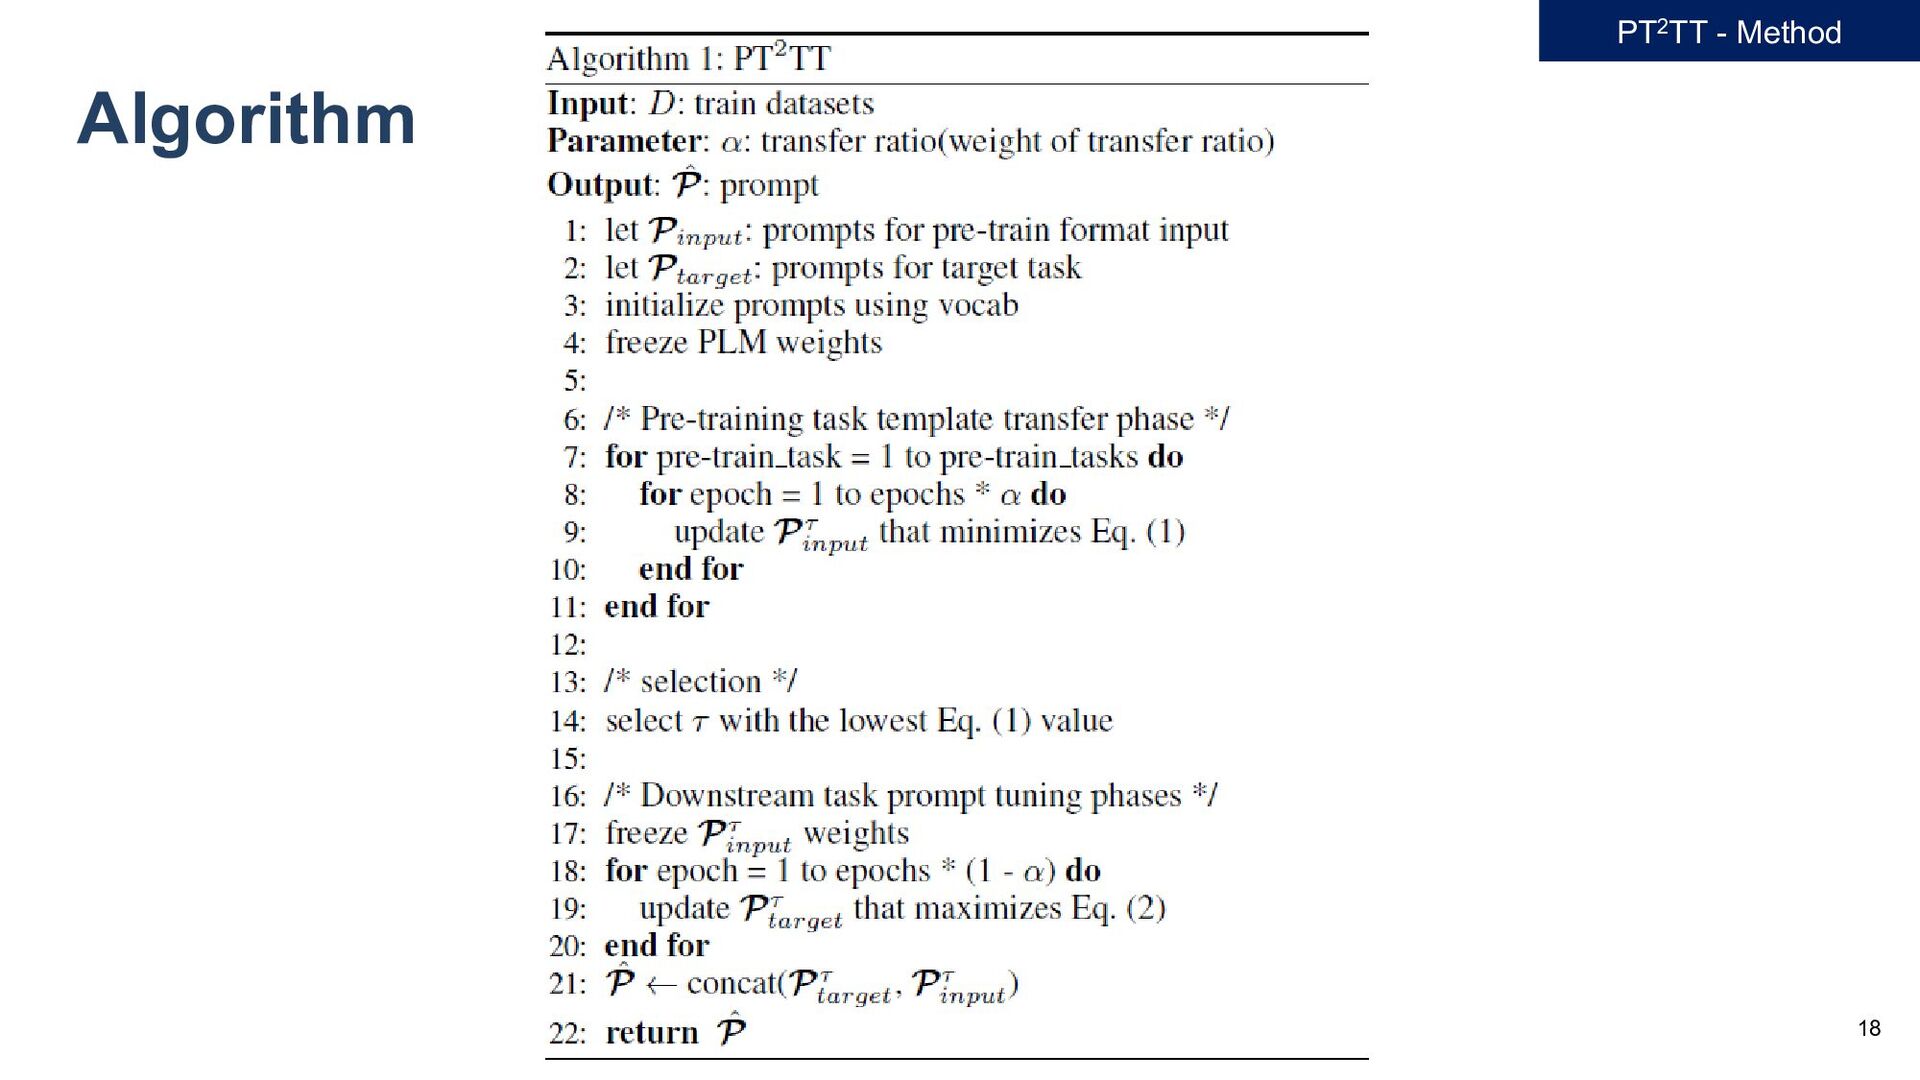
𝐷𝐷 = 𝑥𝑥𝑖𝑖 , 𝑦𝑦𝑖𝑖 𝑖𝑖=1 𝑁𝑁 , - we adopt preprocessor function 𝑓𝑓𝜏𝜏1 , 𝑓𝑓𝜏𝜏2 , … 𝑓𝑓𝜏𝜏𝐾𝐾 for each task 𝜏𝜏1 , 𝜏𝜏2 , … , 𝜏𝜏𝐾𝐾 . - Given raw input text 𝑥𝑥 and preprocessor function 𝑥𝑥𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝 𝜏𝜏 = 𝑓𝑓𝜏𝜏 (𝑥𝑥) - Define a vector of soft prompt tokens, input prompt tokens, denote as 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 = 𝒑𝒑1 𝜏𝜏, … , 𝒑𝒑𝑚𝑚 𝜏𝜏 ∈ ℝ𝑚𝑚×𝑑𝑑 - Pre-trained LM, then receives an input embedding, represented as [𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 ; 𝑒𝑒𝑒𝑒𝑒𝑒 𝑥𝑥 ] - We generate the 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 that achieves the smallest KL loss, as follows: min 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 𝔼𝔼 𝒙𝒙~𝐷𝐷 𝐾𝐾𝐾𝐾 𝑃𝑃𝐿𝐿𝐿𝐿 𝒚𝒚 𝒙𝒙𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝𝑝 𝜏𝜏 ||𝑃𝑃𝐿𝐿𝐿𝐿 𝒚𝒚 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 , 𝒙𝒙 (1) - In this formulation, 𝑃𝑃𝐿𝐿𝐿𝐿 denotes the likelihood determined by the pre-trained LM. - Optimizing Eq. (1), we derive 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏1 , 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏2 ,…, 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏𝐾𝐾 for all pre-training tasks. PT2TT - Method -
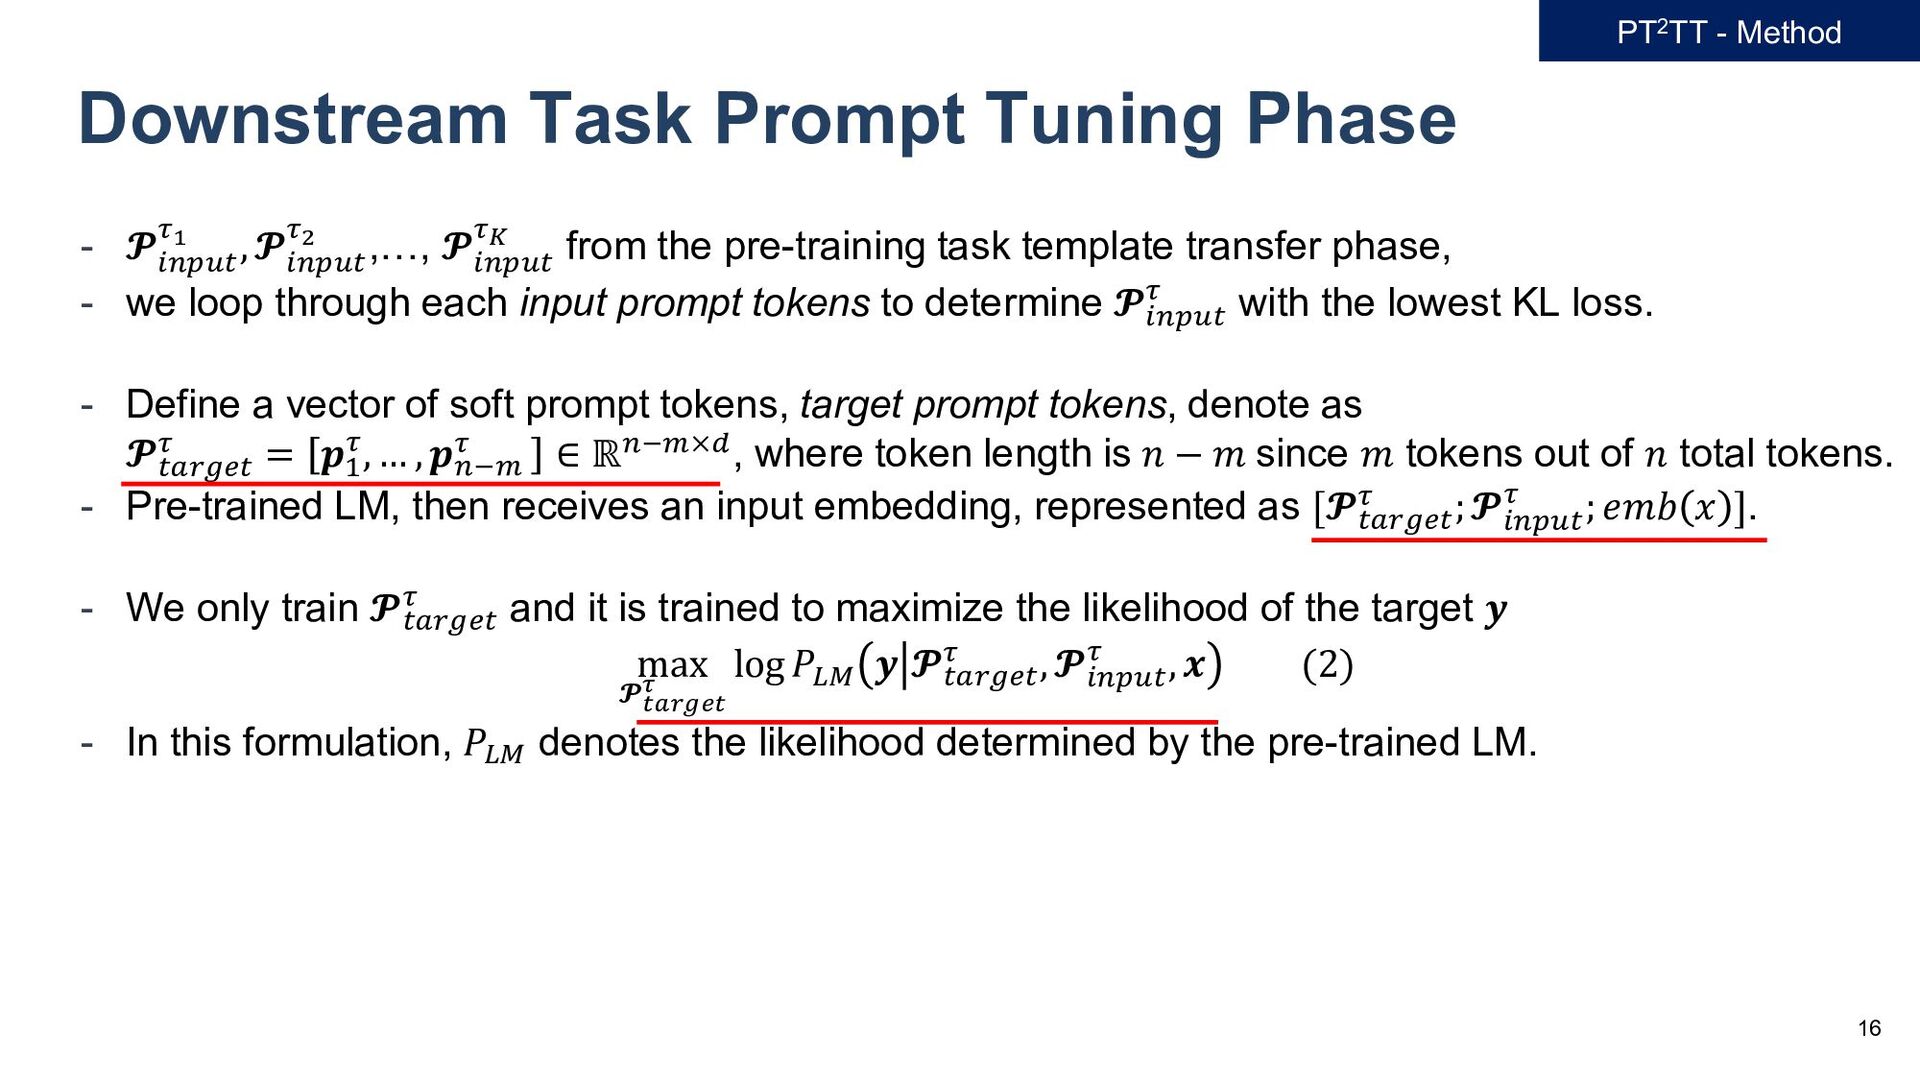
16 Downstream Task Prompt Tuning Phase - 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏1 ,
𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏2 ,…, 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏𝐾𝐾 from the pre-training task template transfer phase, - we loop through each input prompt tokens to determine 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 with the lowest KL loss. - Define a vector of soft prompt tokens, target prompt tokens, denote as 𝓟𝓟𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡 𝜏𝜏 = 𝒑𝒑1 𝜏𝜏, … , 𝒑𝒑𝑛𝑛−𝑚𝑚 𝜏𝜏 ∈ ℝ𝑛𝑛−𝑚𝑚×𝑑𝑑, where token length is 𝑛𝑛 − 𝑚𝑚 since 𝑚𝑚 tokens out of 𝑛𝑛 total tokens. - Pre-trained LM, then receives an input embedding, represented as [𝓟𝓟𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡 𝜏𝜏 ; 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 ; 𝑒𝑒𝑒𝑒𝑒𝑒 𝑥𝑥 ]. - We only train 𝓟𝓟𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡 𝜏𝜏 and it is trained to maximize the likelihood of the target 𝒚𝒚 max 𝓟𝓟𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡 𝜏𝜏 log 𝑃𝑃𝐿𝐿𝐿𝐿 𝒚𝒚 𝓟𝓟𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡𝑡 𝜏𝜏 , 𝓟𝓟𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖𝑖 𝜏𝜏 , 𝒙𝒙 (2) - In this formulation, 𝑃𝑃𝐿𝐿𝐿𝐿 denotes the likelihood determined by the pre-trained LM. PT2TT - Method -
Contents 19 1. Background Information 2. Pilot Experiments 3. Method
4. Experiments 5. Conclusion -
[1] Wang et al. "GLUE: A multi-task benchmark and analysis
platform for natural language understanding." (arXiv:1804.07461). [2] Wang et al. "Superglue: A stickier benchmark for general-purpose language understanding systems.“ (Neurips 2019). [3] Fisch et al. "MRQA 2019 shared task: Evaluating generalization in reading comprehension." (arXiv:1910.09753). [4] Sakaguchi et al. "Winogrande: An adversarial winograd schema challenge at scale." (Communications of the ACM 2021). [5] Zhang et al. "Character-level convolutional networks for text classification." (Neurips 2015). [6] Khot et al. "Scitail: A textual entailment dataset from science question answering." (AAAI 2018). [7] Zhang et al. "PAWS: Paraphrase adversaries from word scrambling." (arXiv:1904.01130). 20 Source tasks - SST-2[1], QQP[1], MNLI[1], QNLI[1], ReCoRD[2], SQuAD[3] Target tasks - 5 SuperGLUE[2] tasks (BoolQ, CB, MultiRC, WiC, WSC) - 4 Other tasks (WinoGrande[4], Yelp-2[5], SciTail[6], PAWS-Wiki[7]) - 4 MRQA[3] tasks (Natural Questions, HotpotQA, SearchQA, NewsQA) Settings PT2TT - Experiments -
21 Model details - Default setting : T5-base[1], total 100
vectors for soft prompt tokens, batch size 8 Baselines - Fine tuning, Prompt tuning[2] - Adapter[3], SPoT[4], BitFit[5] - ATTEMPT[6], MPT[7] Settings [1] Raffel, Colin, et al. "Exploring the limits of transfer learning with a unified text-to-text transformer." (JMLR). [2] Lester et al. "The power of scale for parameter-efficient prompt tuning." (EMNLP 2021) [3] Houlsby et al. "Parameter-efficient transfer learning for NLP." (ICML 2019). [4] Vu et al. "SPoT: Better frozen model adaptation through soft prompt transfer." (ACL 2022). [5] Zaken et al. "Bitfit: Simple parameter-efficient fine-tuning for transformer-based masked language-models." (ACL 2022) [6] Asai et al. "Attentional mixtures of soft prompt tuning for parameter-efficient multi-task knowledge sharing." (EMNLP 2022). [7] Wang et al. "Multitask prompt tuning enables parameter-efficient transfer learning." (ICLR 2023) PT2TT - Experiments -
22 Main Result PT2TT - Experiments [1] Wang, Zhen, et
al. "Multitask prompt tuning enables parameter-efficient transfer learning." (ICLR 2023). -
23 Main Result PT2TT - Experiments [1] Wang, Zhen, et
al. "Multitask prompt tuning enables parameter-efficient transfer learning." (ICLR 2023). -
25 Conclusion Conclusion - PT2TT, an approach to reformatting input
data to align with the training data format used for open-source large language models (LLMs) such as T5 - By incorporating soft prompts, we enhanced the performance of LLMs for various downstream tasks, leveraging the latent, residual context. - Our approach is only applicable if the pre-training task template is based on an open-source Large Language Model (LLM) where such formats are disclosed - There is a need to investigate algorithms to determine selection method and other hyperparameters for each prompt tokens related. -
31 Appendix - Background Prefix-Tuning[1] [1] XL Li, P Liang.
"Prefix-Tuning: Optimizing Continuous Prompts for Generation. " (ACL 2021) - Freeze the Pretrained Language Model. - Add Learnable Soft Prompts in front of each Transformer Layer. - Only 0.1% Soft Prompts achieve Full model's performance in Table to Text Generation Task. Figure: An example of Prefix-Tuning -
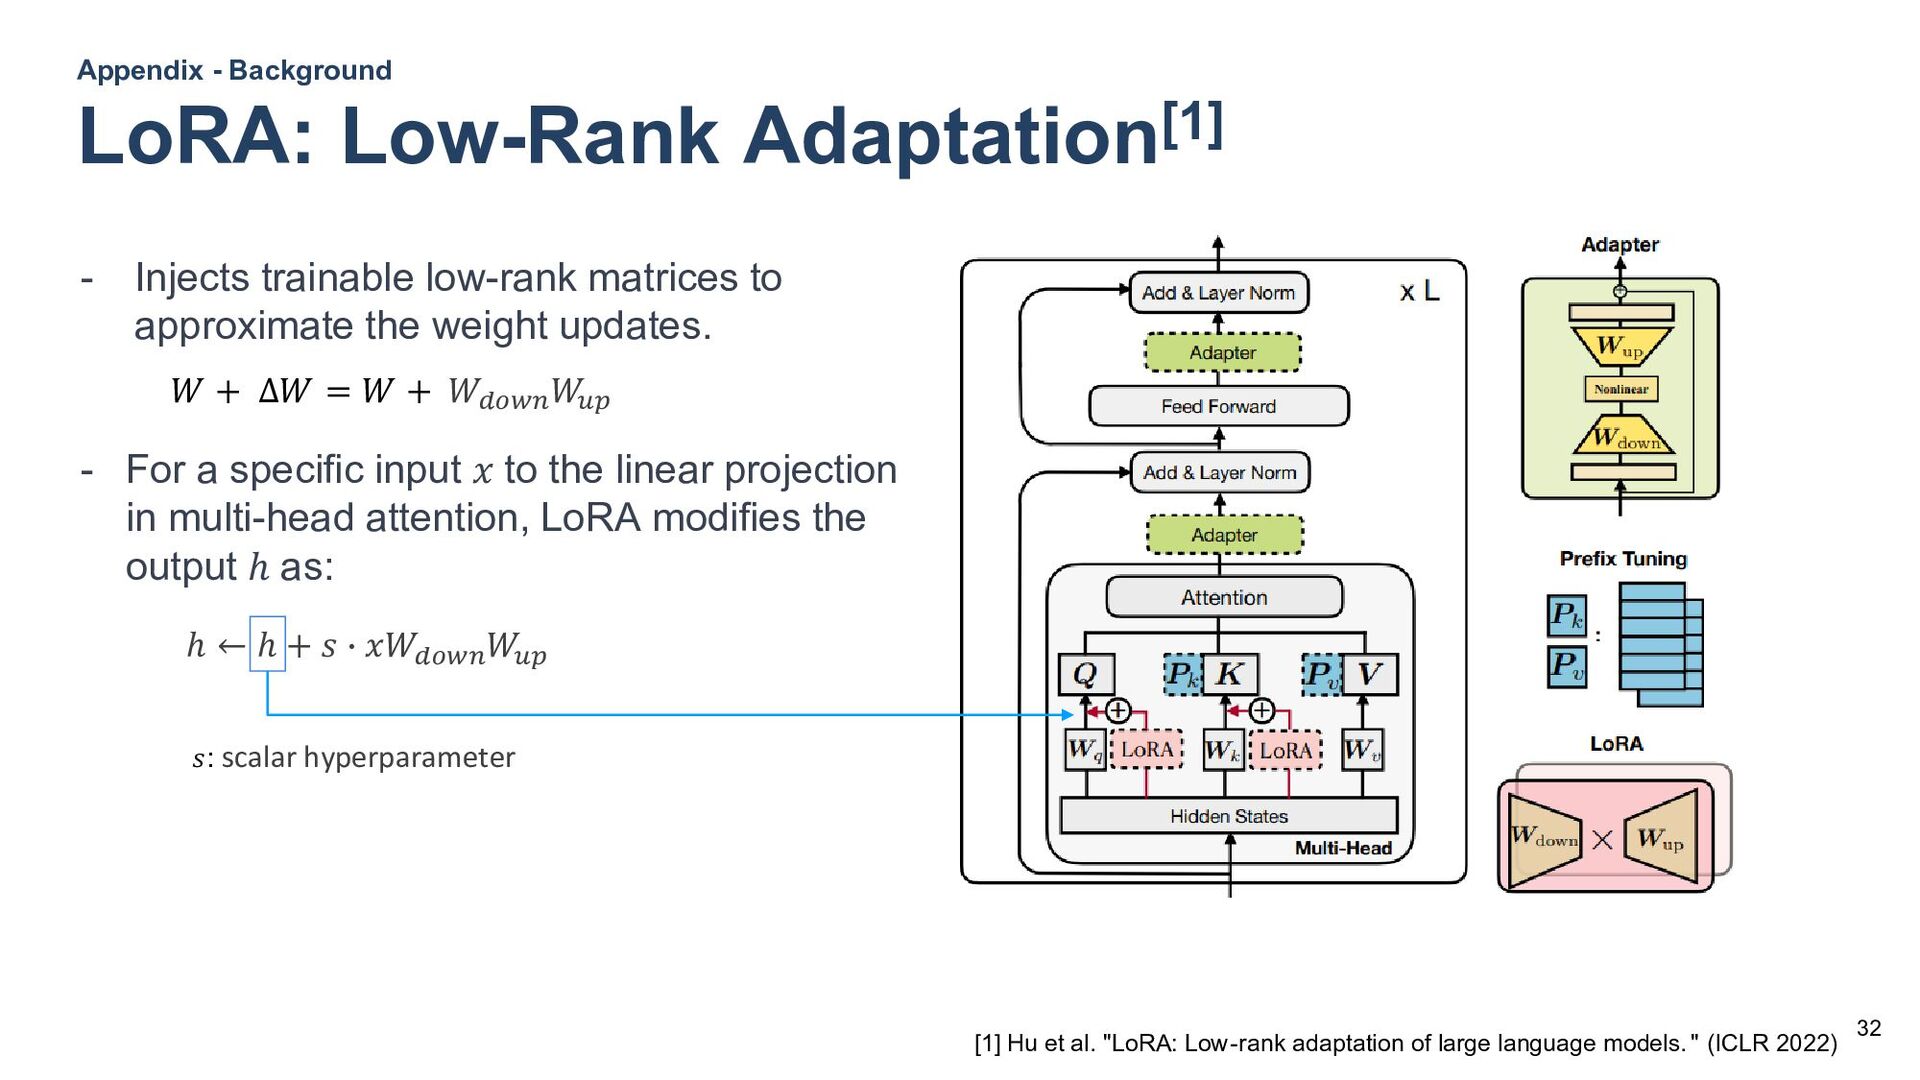
- Injects trainable low-rank matrices to approximate the weight updates.
- For a specific input 𝑥𝑥 to the linear projection in multi-head attention, LoRA modifies the output ℎ as: 32 Appendix - Background LoRA: Low-Rank Adaptation[1] [1] Hu et al. "LoRA: Low-rank adaptation of large language models. " (ICLR 2022) ℎ ← ℎ + 𝑠𝑠 � 𝑥𝑥𝑊𝑊𝑑𝑑𝑑𝑑𝑑𝑑𝑑𝑑 𝑊𝑊 𝑢𝑢𝑢𝑢 𝑠𝑠: scalar hyperparameter 𝑊𝑊 + ∆𝑊𝑊 = 𝑊𝑊 + 𝑊𝑊𝑑𝑑𝑑𝑑𝑑𝑑𝑑𝑑 𝑊𝑊 𝑢𝑢𝑢𝑢 -
33 Appendix - Background P-Tuning[1] [1] X Liu, Y Zheng,
et al. "P-Tuning: GPT understands, too." (arXiv 2021) - Freeze the Pretrained Language Model. - Add Prompt Encoder to transform a pseudo prompt into a soft prompt. - Show that GPT series (GPT-2) can solve NLU tasks first. Figure: An example of P-Tuning (BiLSTM + two MLP) -
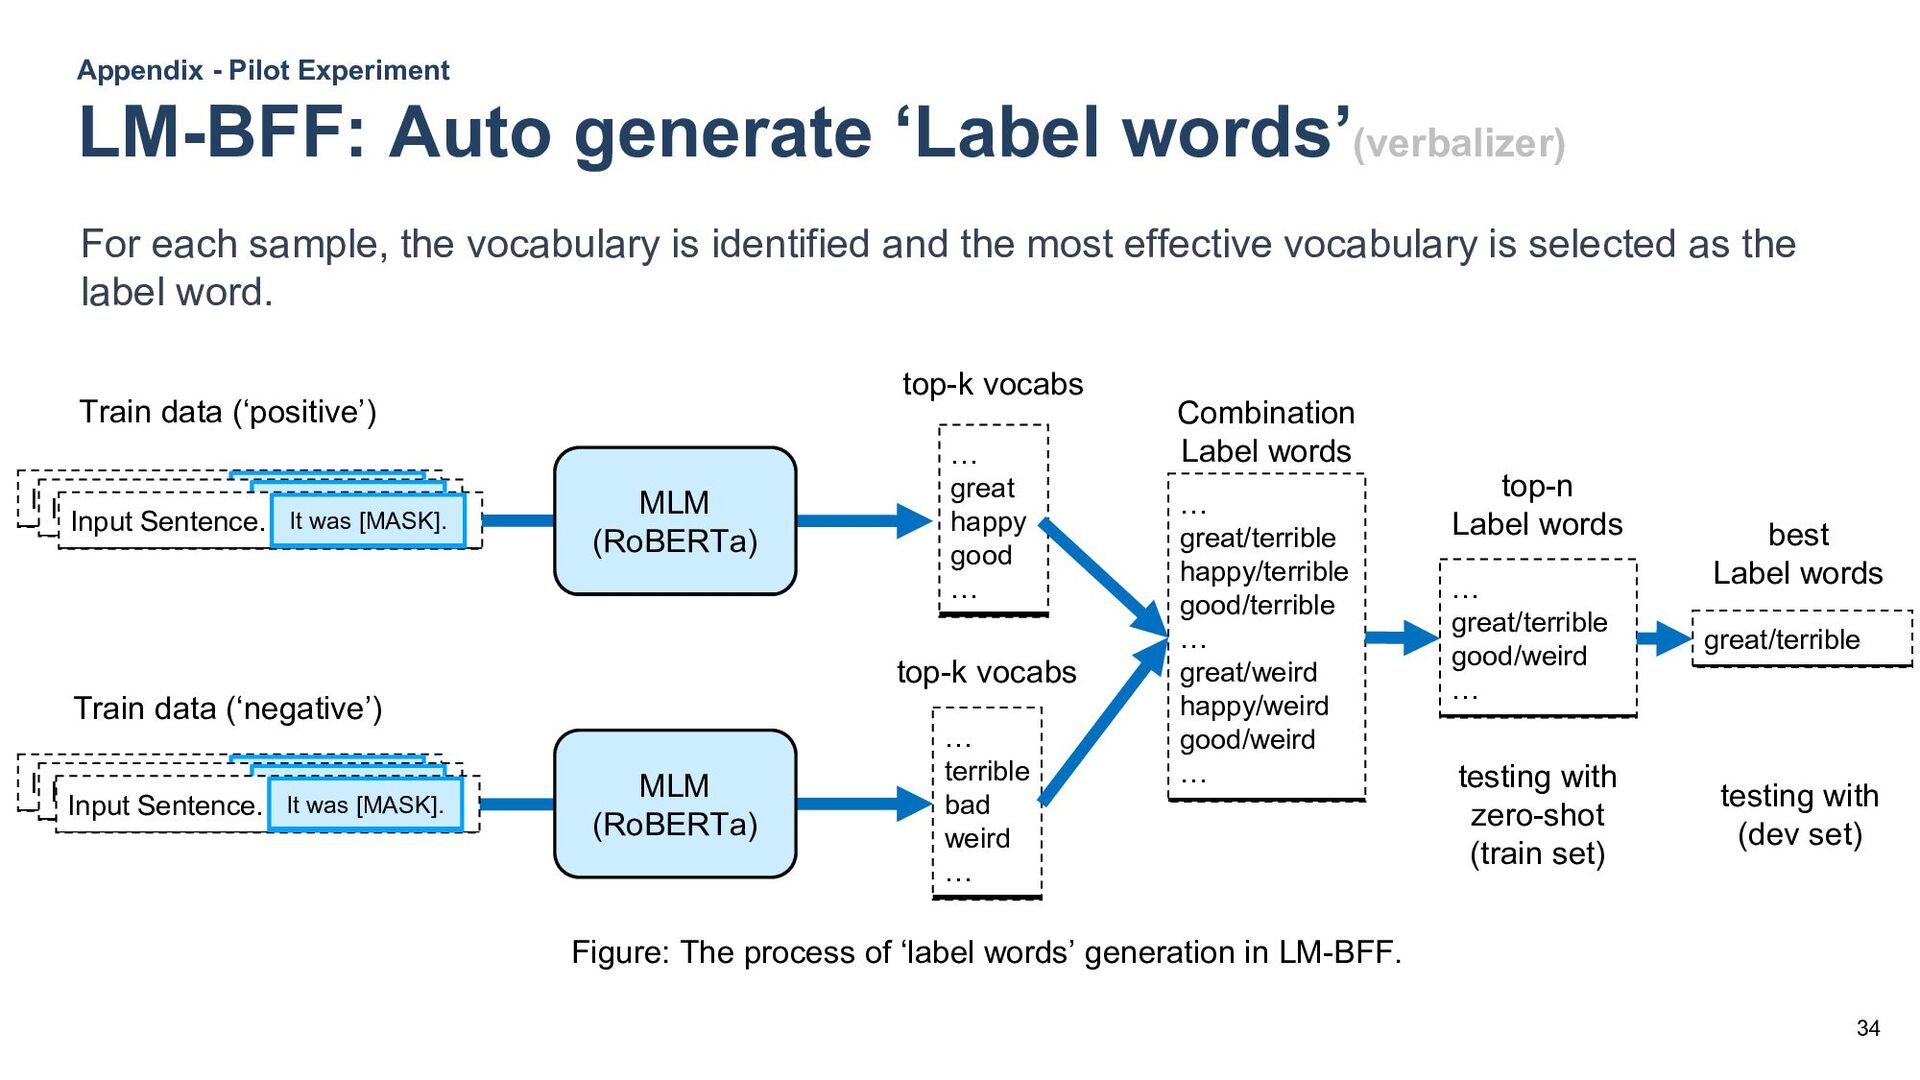
34 Appendix - Pilot Experiment LM-BFF: Auto generate ‘Label words’(verbalizer)
For each sample, the vocabulary is identified and the most effective vocabulary is selected as the label word. MLM (RoBERTa) … great/terrible happy/terrible good/terrible … great/weird happy/weird good/weird … … great/terrible good/weird … Input Sentence. It was [MASK]. Input Sentence. It was [MASK]. Input Sentence. It was [MASK]. Input Sentence. It was [MASK]. Input Sentence. It was [MASK]. Input Sentence. It was [MASK]. great/terrible Train data (‘positive’) Train data (‘negative’) … terrible bad weird … top-k vocabs … great happy good … top-k vocabs Combination Label words top-n Label words best Label words testing with zero-shot (train set) testing with (dev set) MLM (RoBERTa) Figure: The process of ‘label words’ generation in LM-BFF. -
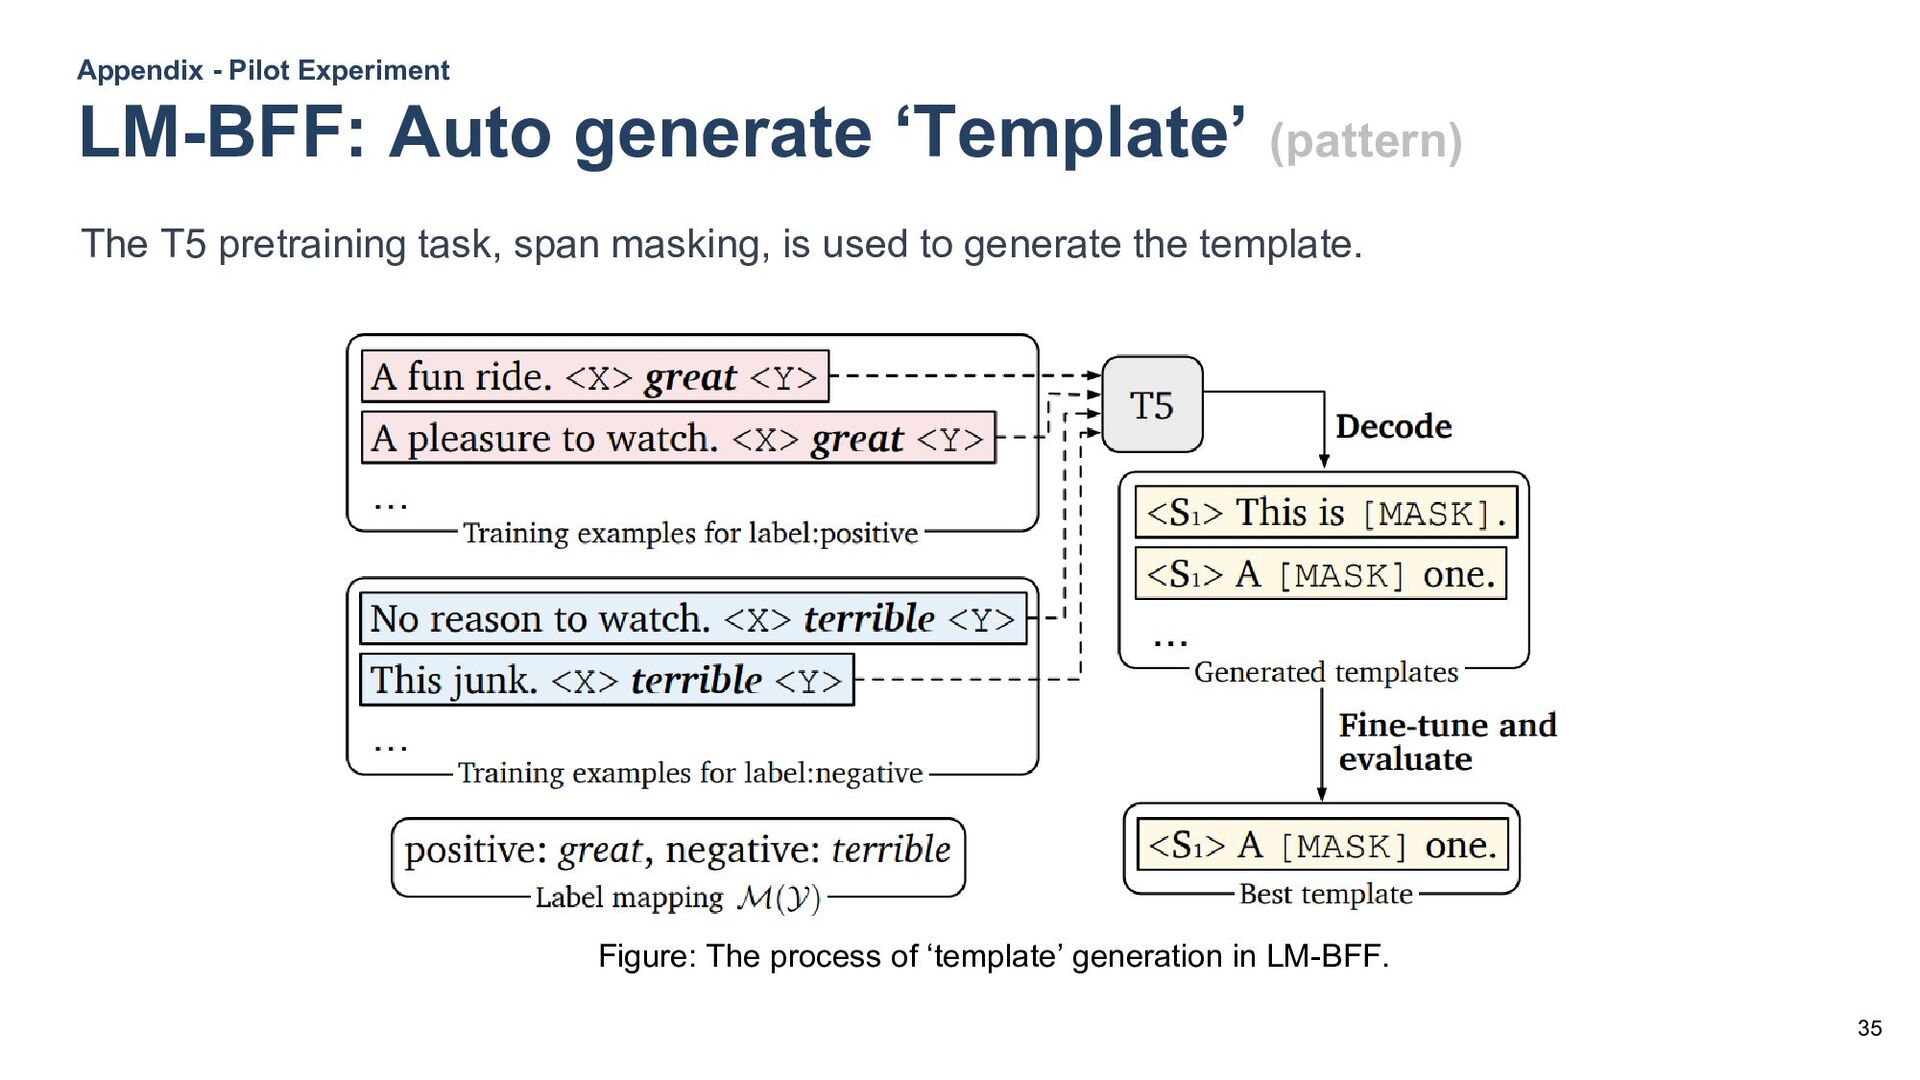
35 Appendix - Pilot Experiment LM-BFF: Auto generate ‘Template’ (pattern)
The T5 pretraining task, span masking, is used to generate the template. Figure: The process of ‘template’ generation in LM-BFF. -
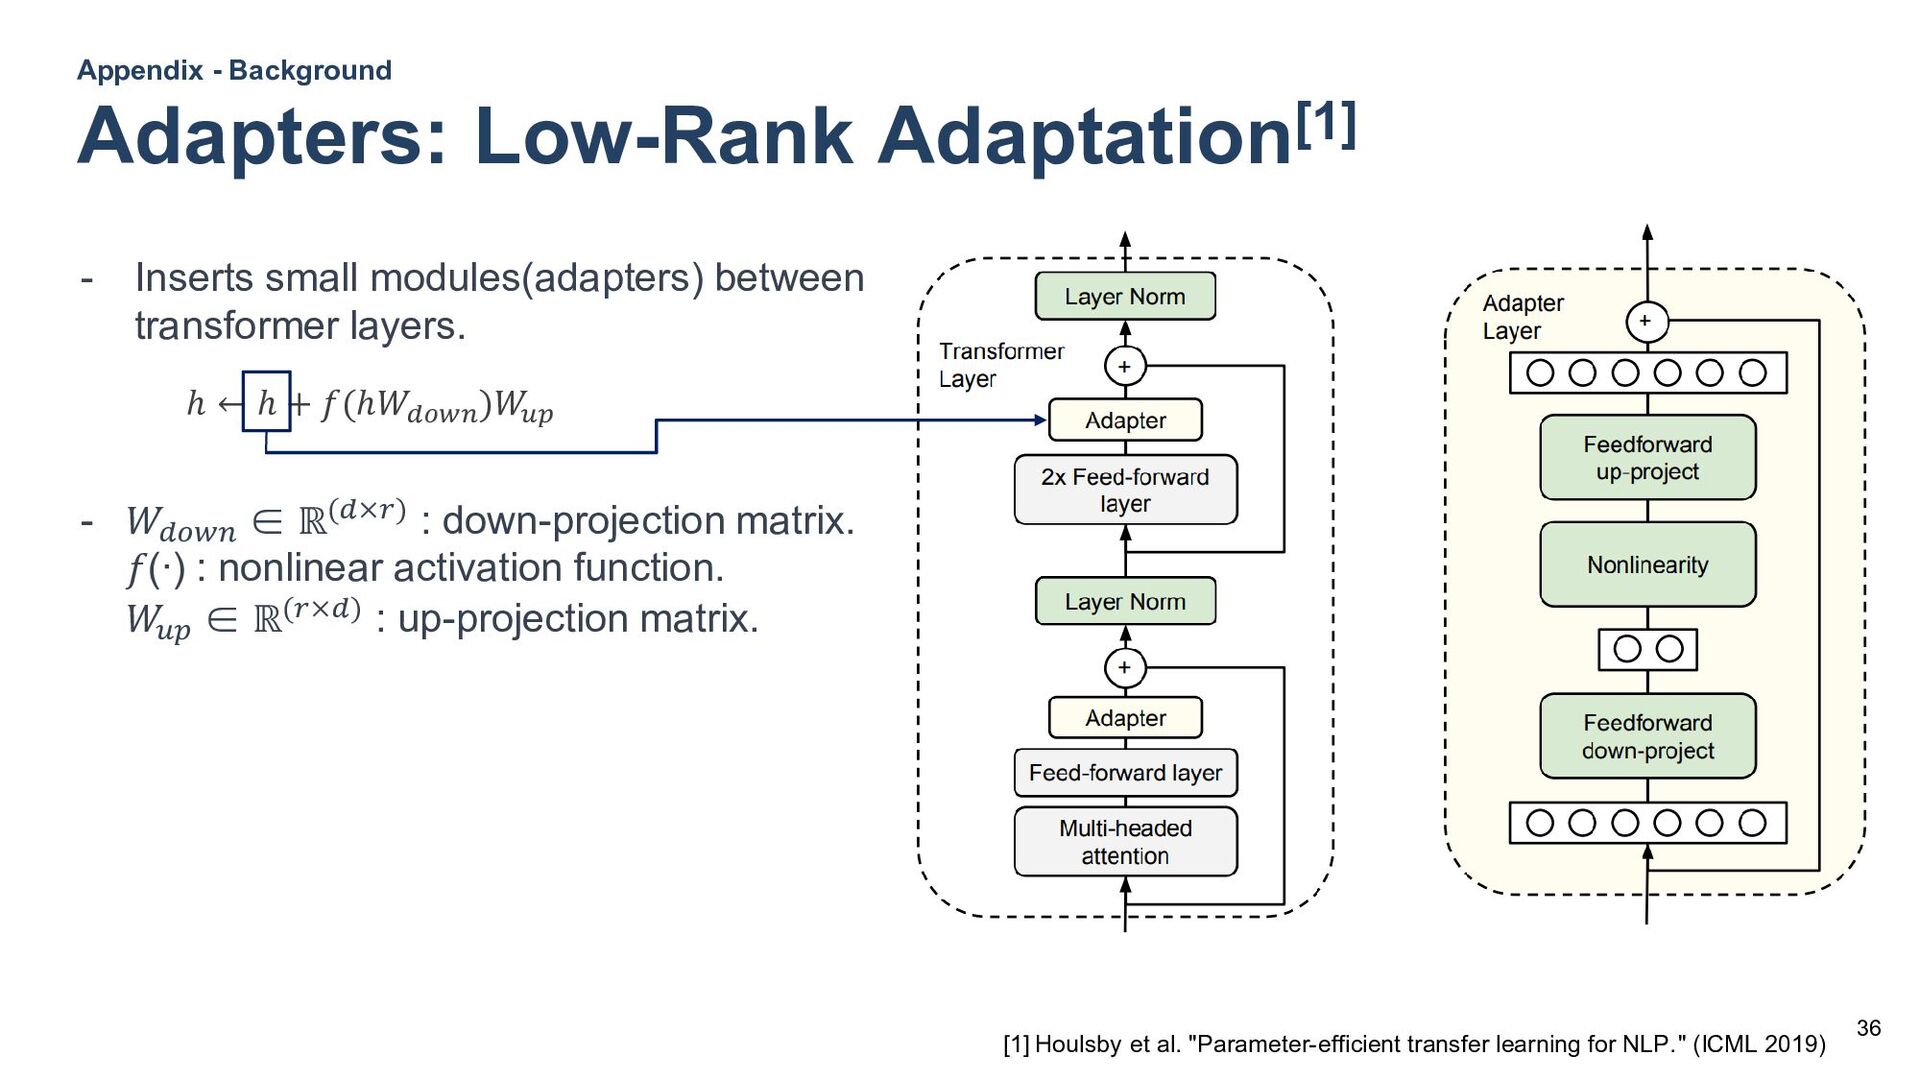
- Inserts small modules(adapters) between transformer layers. - 𝑊𝑊𝑑𝑑𝑑𝑑𝑑𝑑𝑑𝑑 ∈
ℝ(𝑑𝑑×𝑟𝑟) : down-projection matrix. 𝑓𝑓(∙) : nonlinear activation function. 𝑊𝑊 𝑢𝑢𝑢𝑢 ∈ ℝ(𝑟𝑟×𝑑𝑑) : up-projection matrix. 36 Appendix - Background Adapters: Low-Rank Adaptation[1] [1] Houlsby et al. "Parameter-efficient transfer learning for NLP." (ICML 2019) ℎ ← ℎ + 𝑓𝑓(ℎ𝑊𝑊𝑑𝑑𝑑𝑑𝑑𝑑𝑑𝑑 )𝑊𝑊 𝑢𝑢𝑢𝑢 -
37 Appendix - Baseline SPoT: Soft Prompt Transfer [1] -
Initialize target prompt with most relevant source prompt. - Relevance is measured by cosine similarity between prematurely trained source prompt and target prompt. [1] Vu et al. "SPoT: Better Frozen Model Adaptation through Soft Prompt Transfer. " (ACL 2022) -
38 Appendix - Baseline ATTEMPT: Attentional Mixture of Prompt Tuning[1]
- Initialize target prompt with addition of (1) attentional mixture of frozen source prompts, and (2) trainable prompt designated for the target task Figure: Overall architecture of ATTEMPT. It combines multiple soft prompts trained on large-scale dataset (source prompts) to generate instance-wise target prompts. [1] Asai et al. "ATTEMPT: Parameter-Efficient Multi-task Tuning via Attentional Mixtures of Soft Prompts. " (EMNLP 2022) -
39 Appendix - Baseline MPT: Multitask Prompt Tuning[1] - Decompose
source prompt into (1) a full-rank matrix which is shared across other source prompts (2) source-task-specific low-rank matrix to minimize interference between tasks - Further enhance performance via distillation. Figure: An illustration on prompt decomposition for two tasks in MPT. [1] Wang et al. "Multitask Prompt Tuning Enables Parameter-Efficient Transfer Learning." (ICLR 2023) -
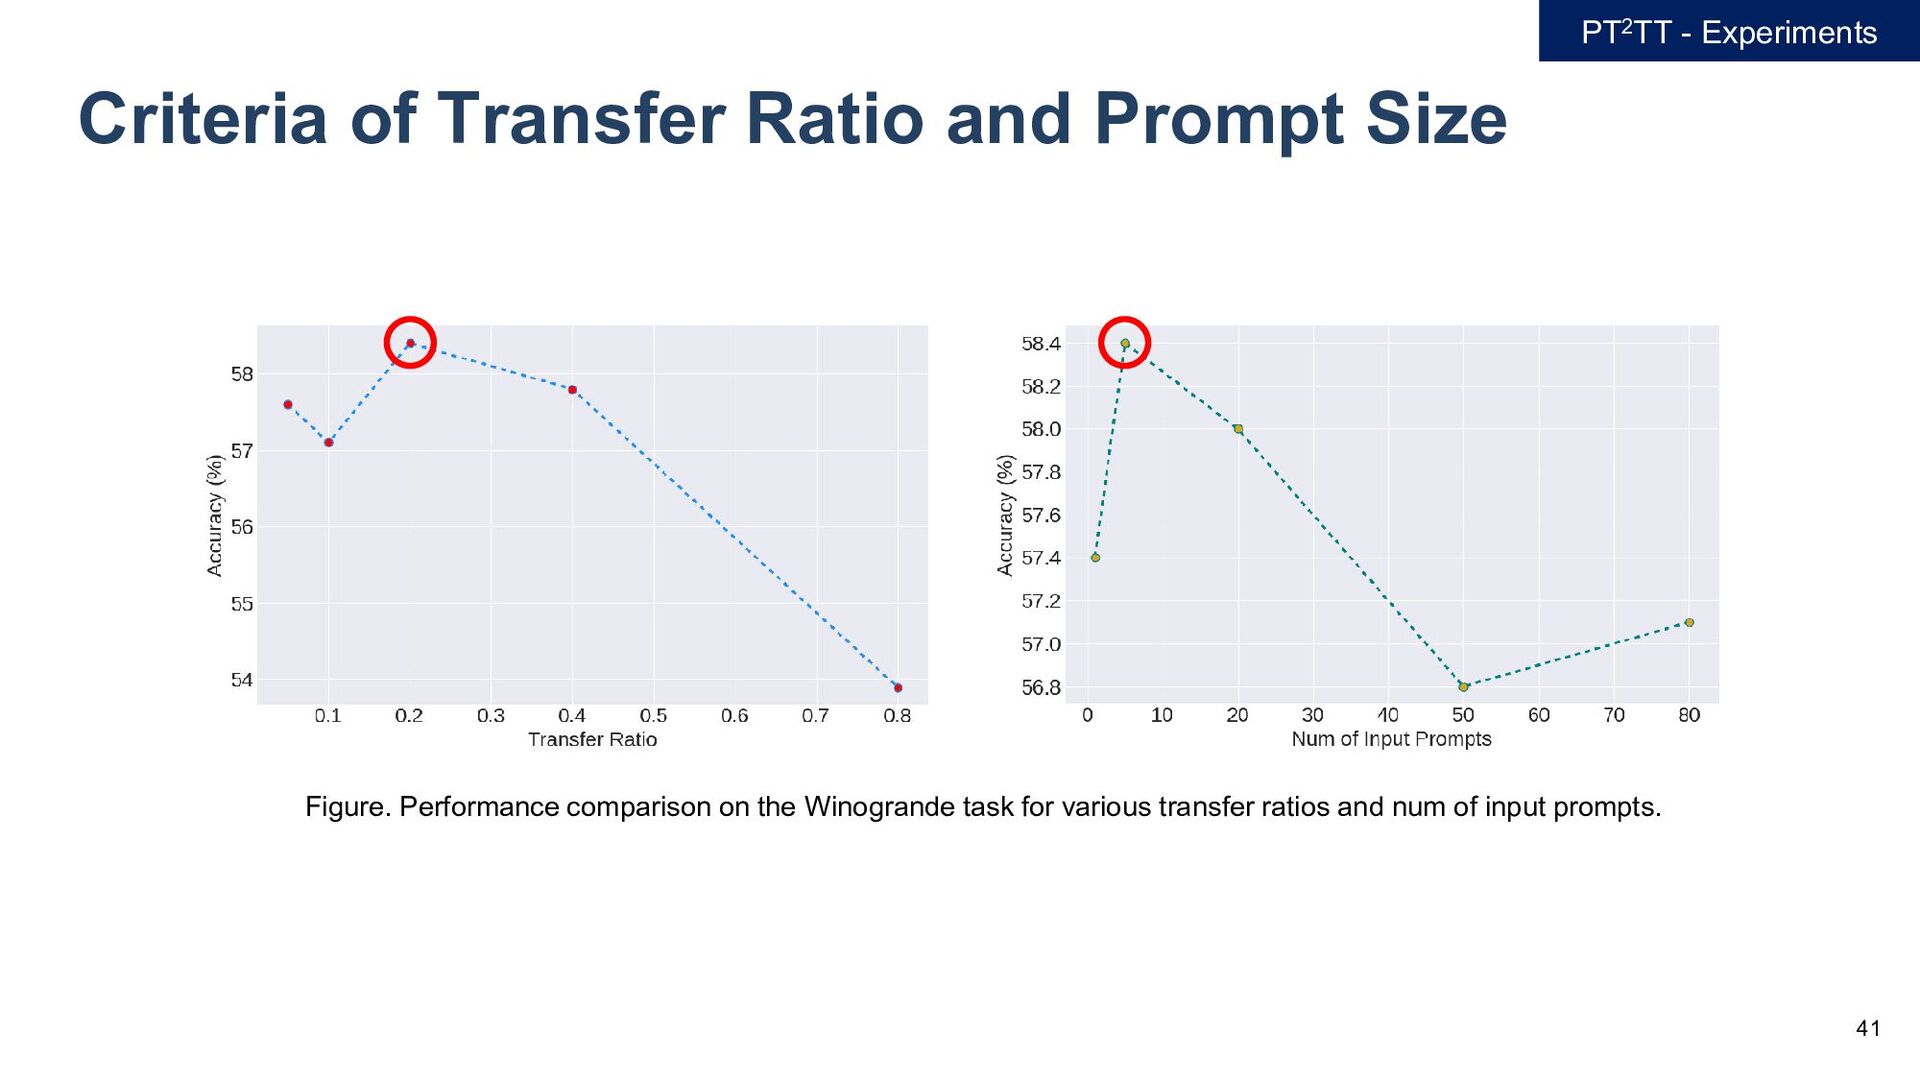
41 Criteria of Transfer Ratio and Prompt Size Figure. Performance
comparison on the Winogrande task for various transfer ratios and num of input prompts. PT2TT - Experiments
 shhwang
 xspa2012
 kzmssk
 institutdelelevage
 tattaka
 tomonom
 stktu
 kogoro
 shibuiwilliam
 emna__ayadi
 reverentgeek
 szymonslowik
 ammeep
 bkeepers
 tonyrice
 skipperchong
 mfonobong
 techseoconnect
 thekraken
 sergeychernyshev
 akademiya2063