Share
Embed
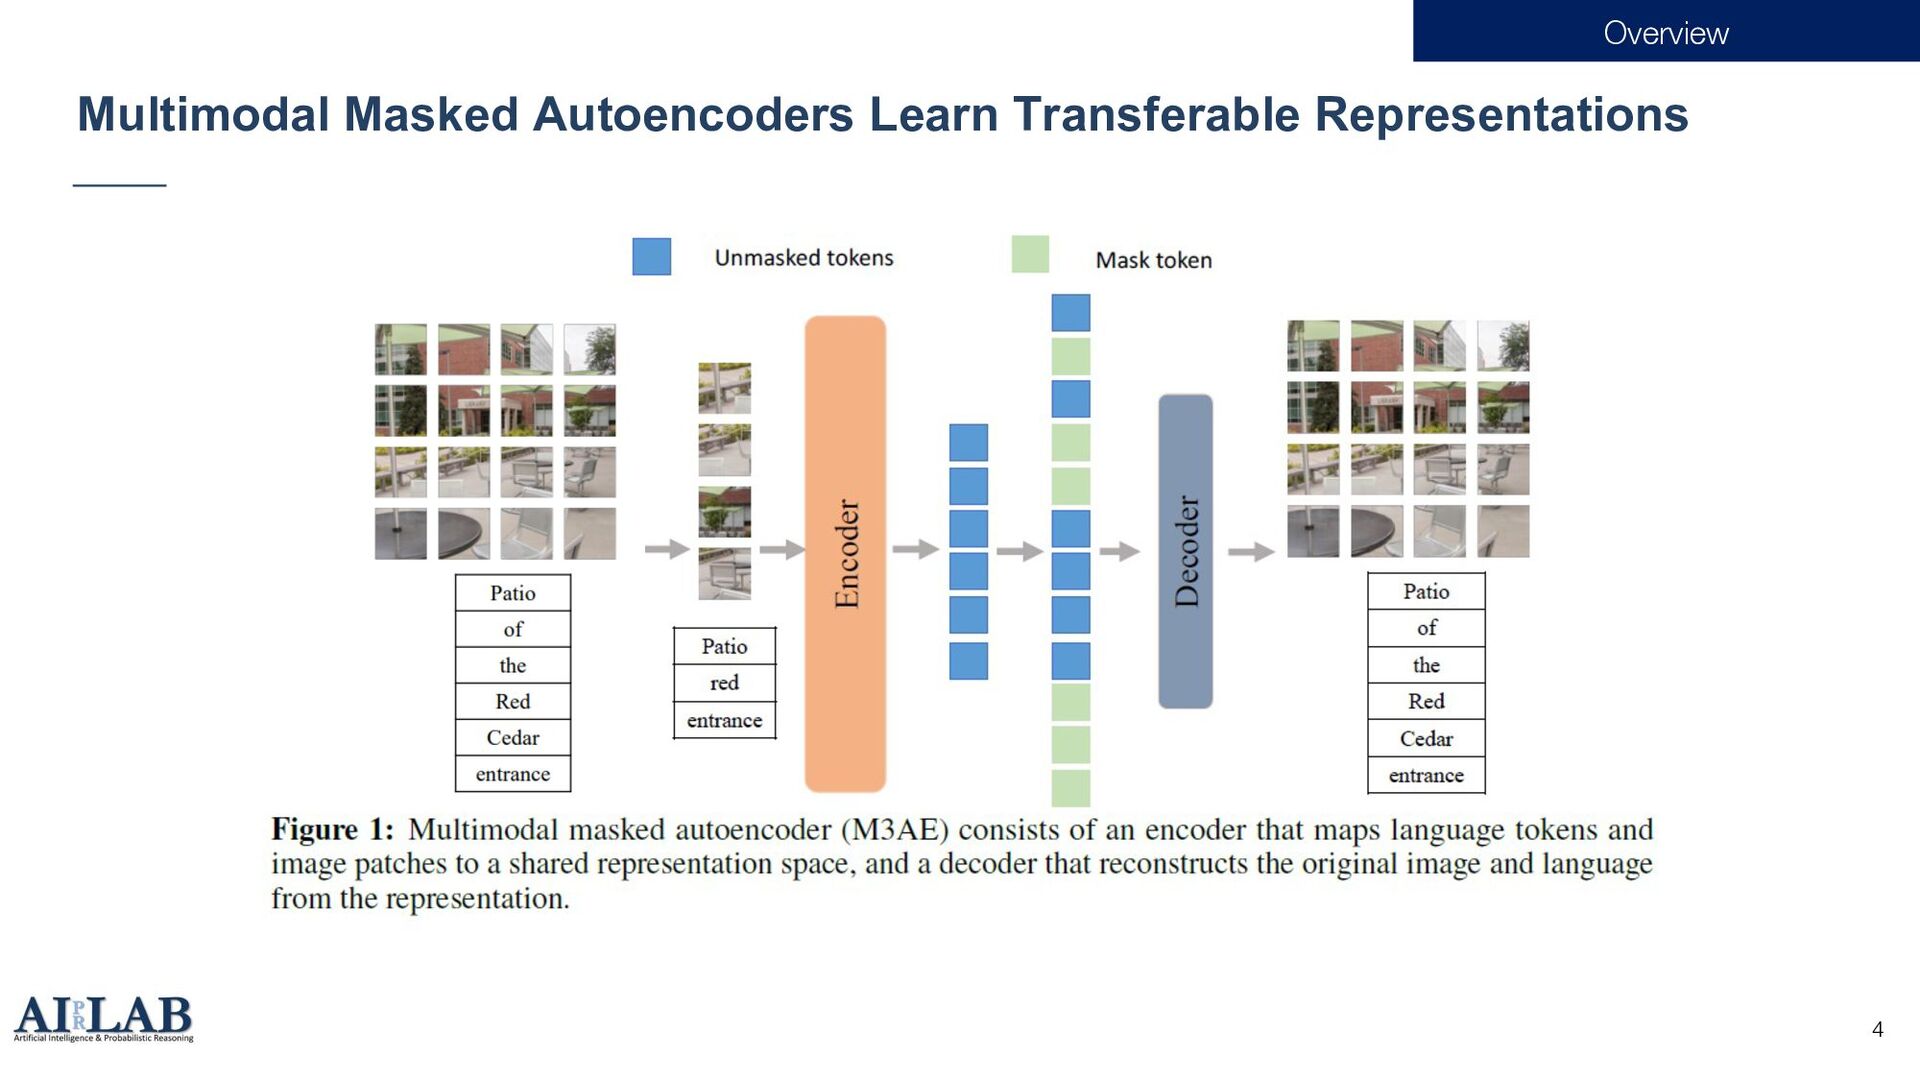
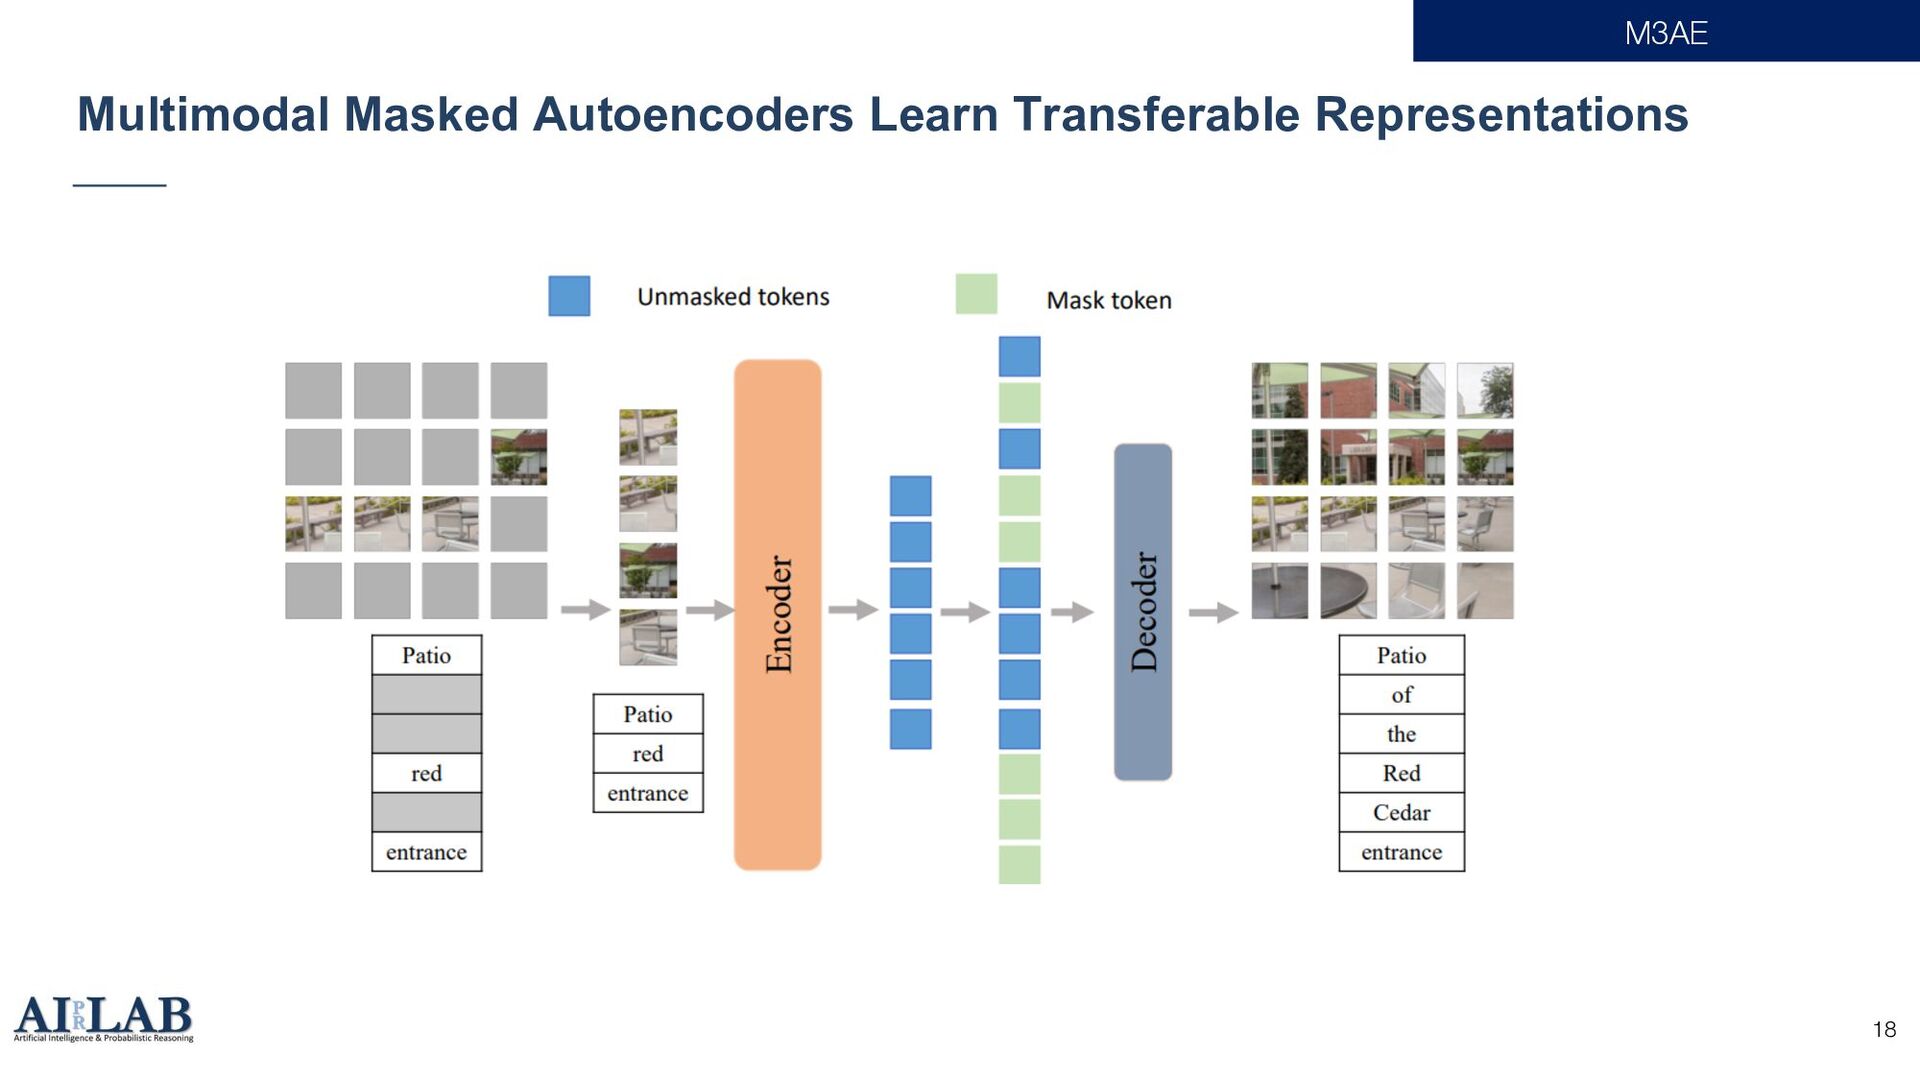
Multimodal Masked Autoencoders Learn Transferable Representations
Seunghyun Hwang
September 11, 2023
Transcript
31 slides
-
Multimodal Masked Autoencoders Learn Transferable Representations Presented by Seunghyun Hwang
2023. 9. 21. 1 Xinyang Geng, Hao Liu, Lisa Lee, Dale Schuurmans, Sergey Levine, Pieter Abbeel UC Berkely, Google Brain Preprint, 2022 Reading club 4 Research outcome 1 -
Contents 1. Multimodal Masked Autoencoders Learn Transferable Representations – Overview
2. Background Information 1. Multimodal learning 2. Self-supervised representation learning via contrastive – CLIP[1] 3. Self-supervised representation learning via reconstruction – MAE[2] 3. M3AE - Model Structure(Method) 4. Result 2 -
Contents 1. Multimodal Masked Autoencoders Learn Transferable Representations – Overview
2. Background Information 1. Multimodal learning 2. Self-supervised representation learning via contrastive – CLIP[1] 3. Self-supervised representation learning via reconstruction – MAE[2] 3. M3AE - Model Structure(Method) 4. Result 3 -
Contents 1. Multimodal Masked Autoencoders Learn Transferable Representations – Overview
2. Background Information 1. Multimodal learning 2. Self-supervised representation learning via contrastive – CLIP[1] 3. Self-supervised representation learning via reconstruction – MAE[2] 3. M3AE - Model Structure(Method) 4. Result 5 -
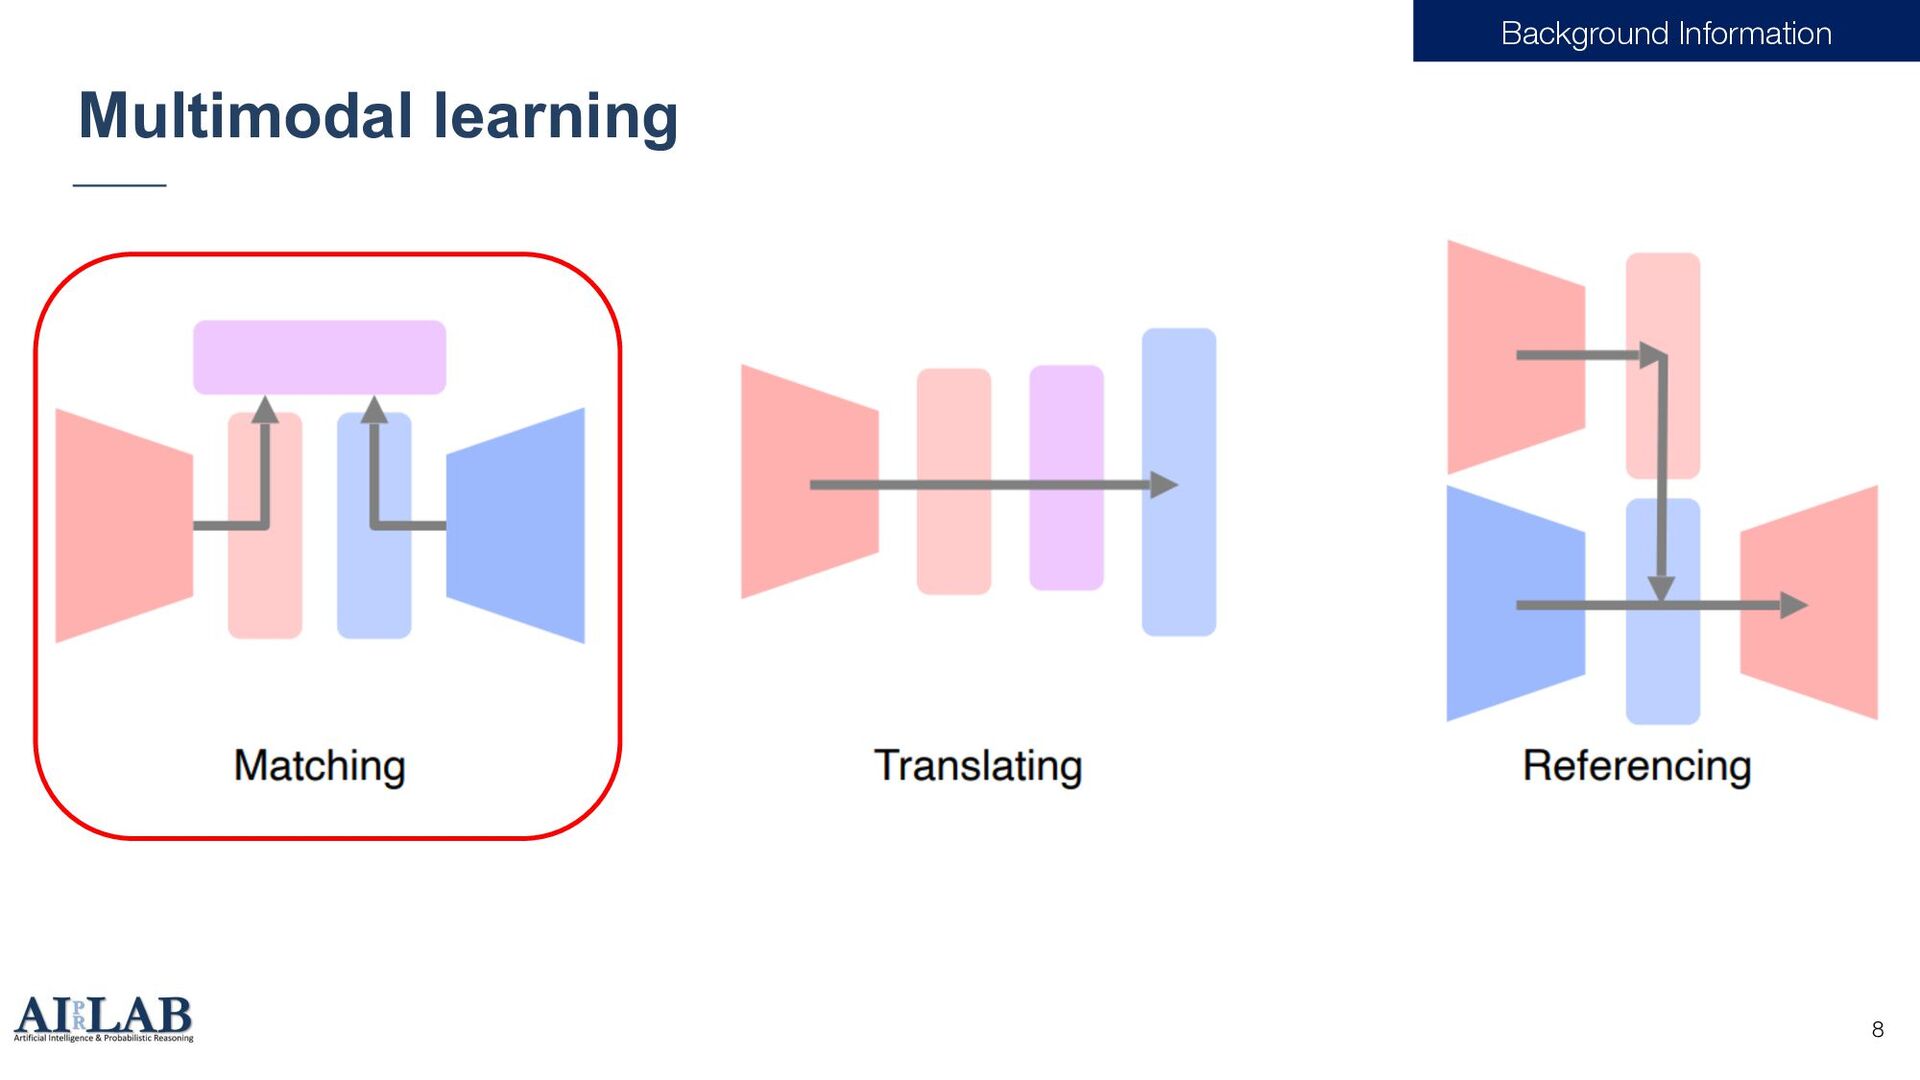
Multimodal learning 6 [1] Wei, Jason, et al. "Chain of
thought prompting elicits reasoning in large language models." 2022. [2] Brown, Tom, et al. "Language models are few-shot learners.“, Neurips 2020 Background Information Unimodal Multi-modal -
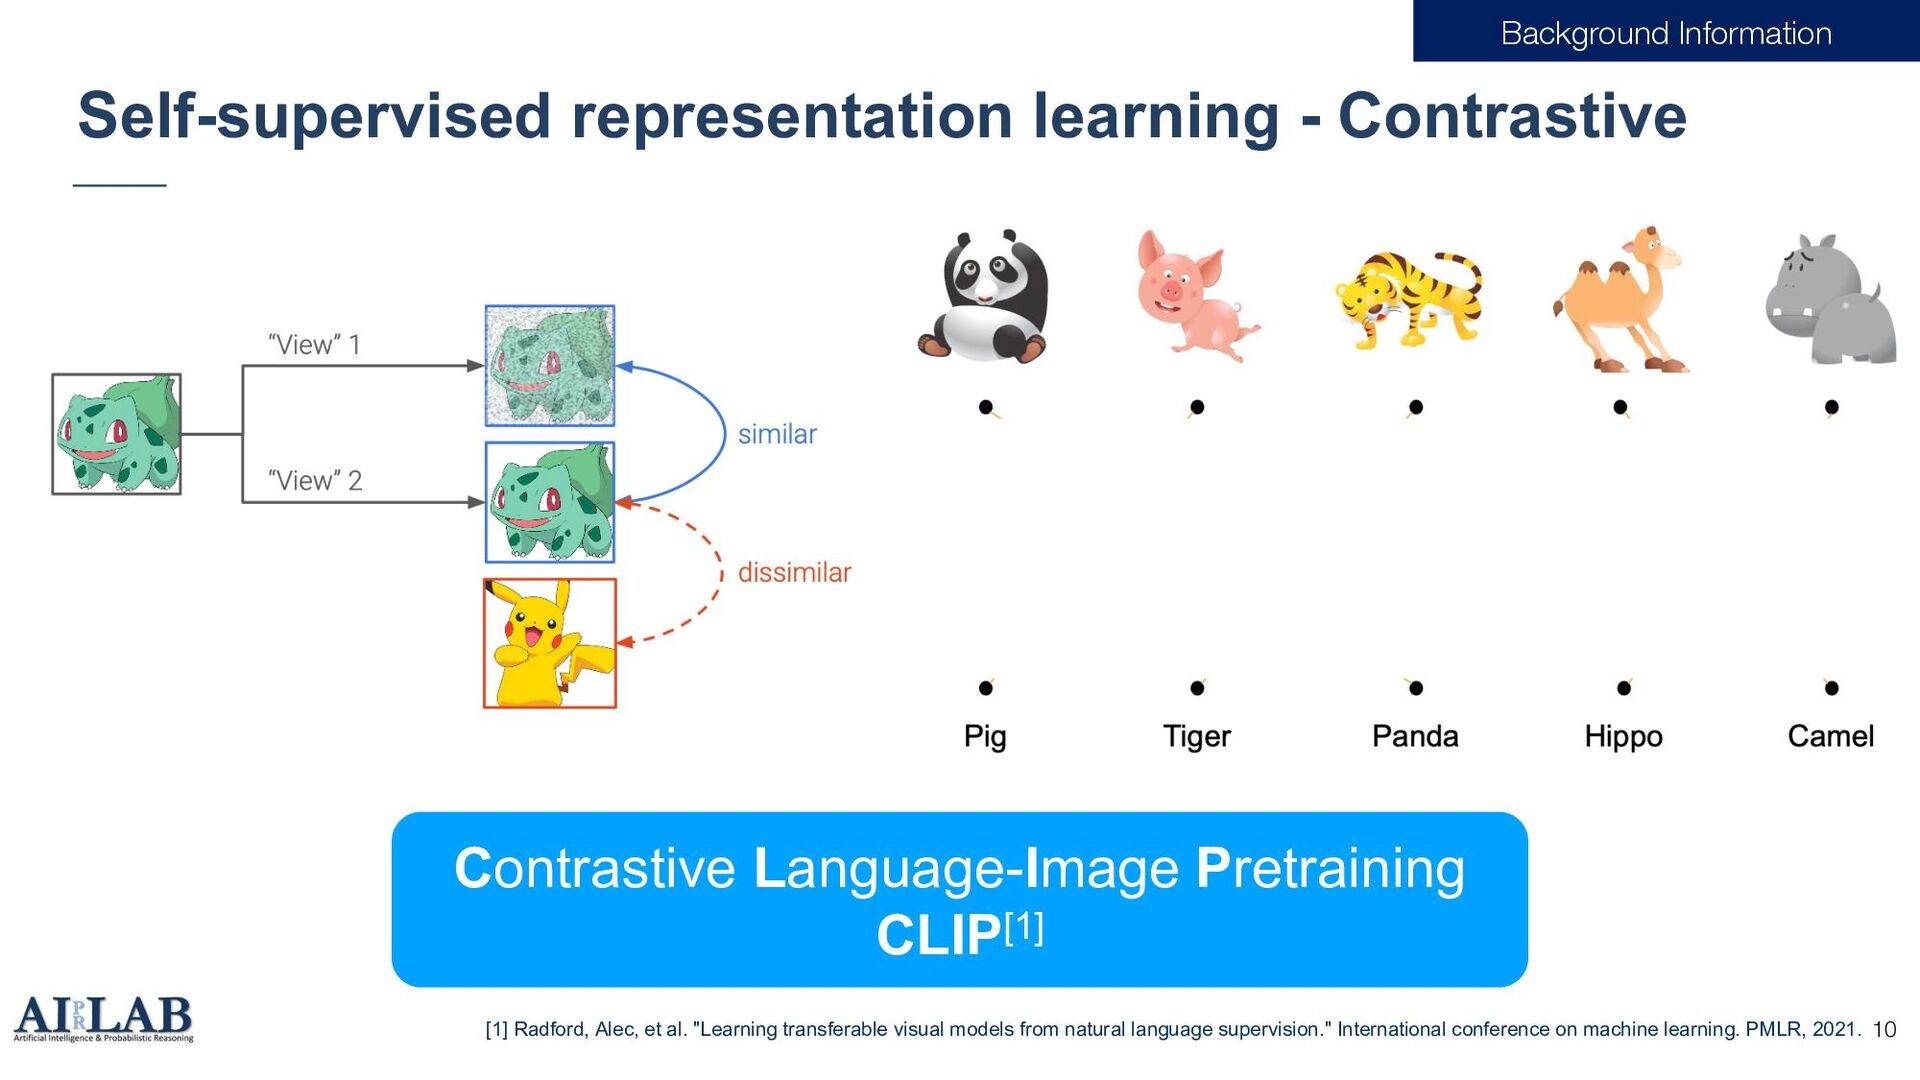
Self-supervised representation learning - Contrastive 10 Background Information Contrastive Language-Image
Pretraining CLIP[1] [1] Radford, Alec, et al. "Learning transferable visual models from natural language supervision." International conference on machine learning. PMLR, 2021. -
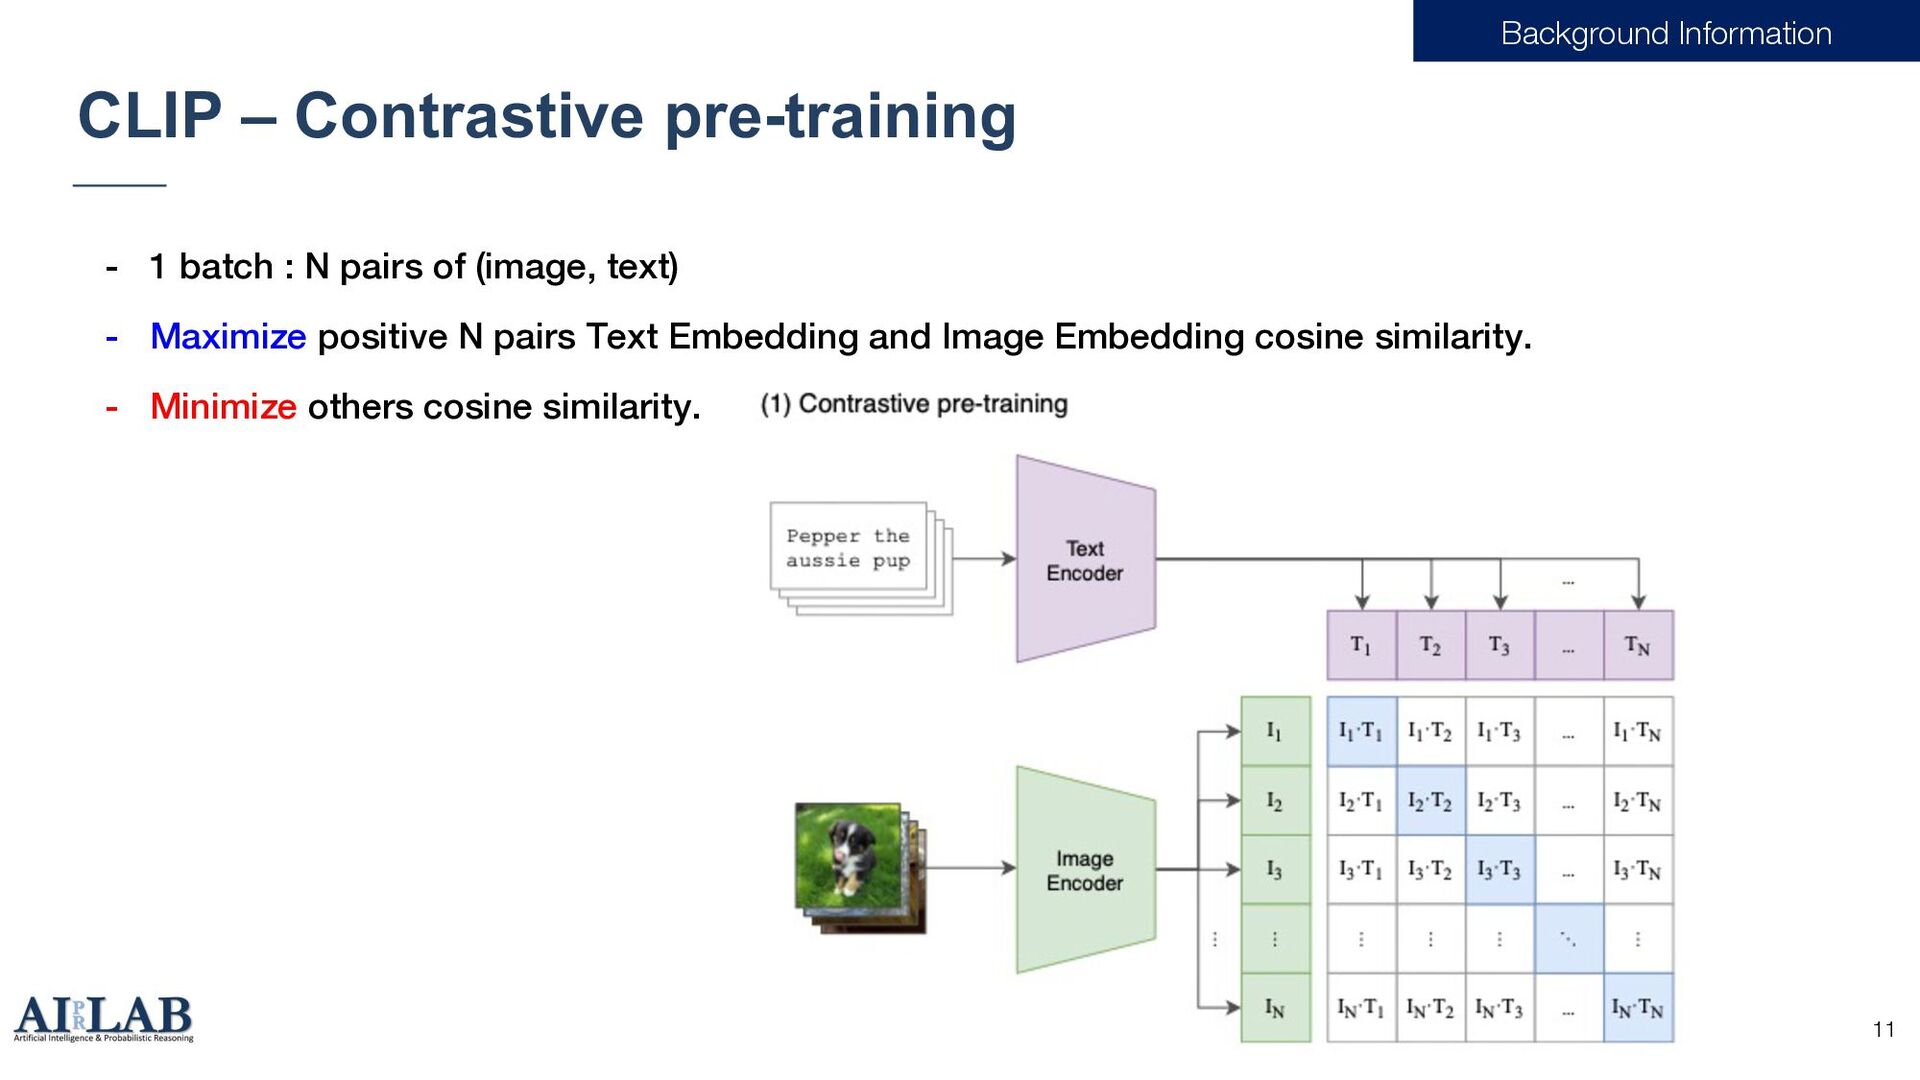
CLIP – Contrastive pre-training 11 Background Information - 1 batch
: N pairs of (image, text) - Maximize positive N pairs Text Embedding and Image Embedding cosine similarity. - Minimize others cosine similarity. -
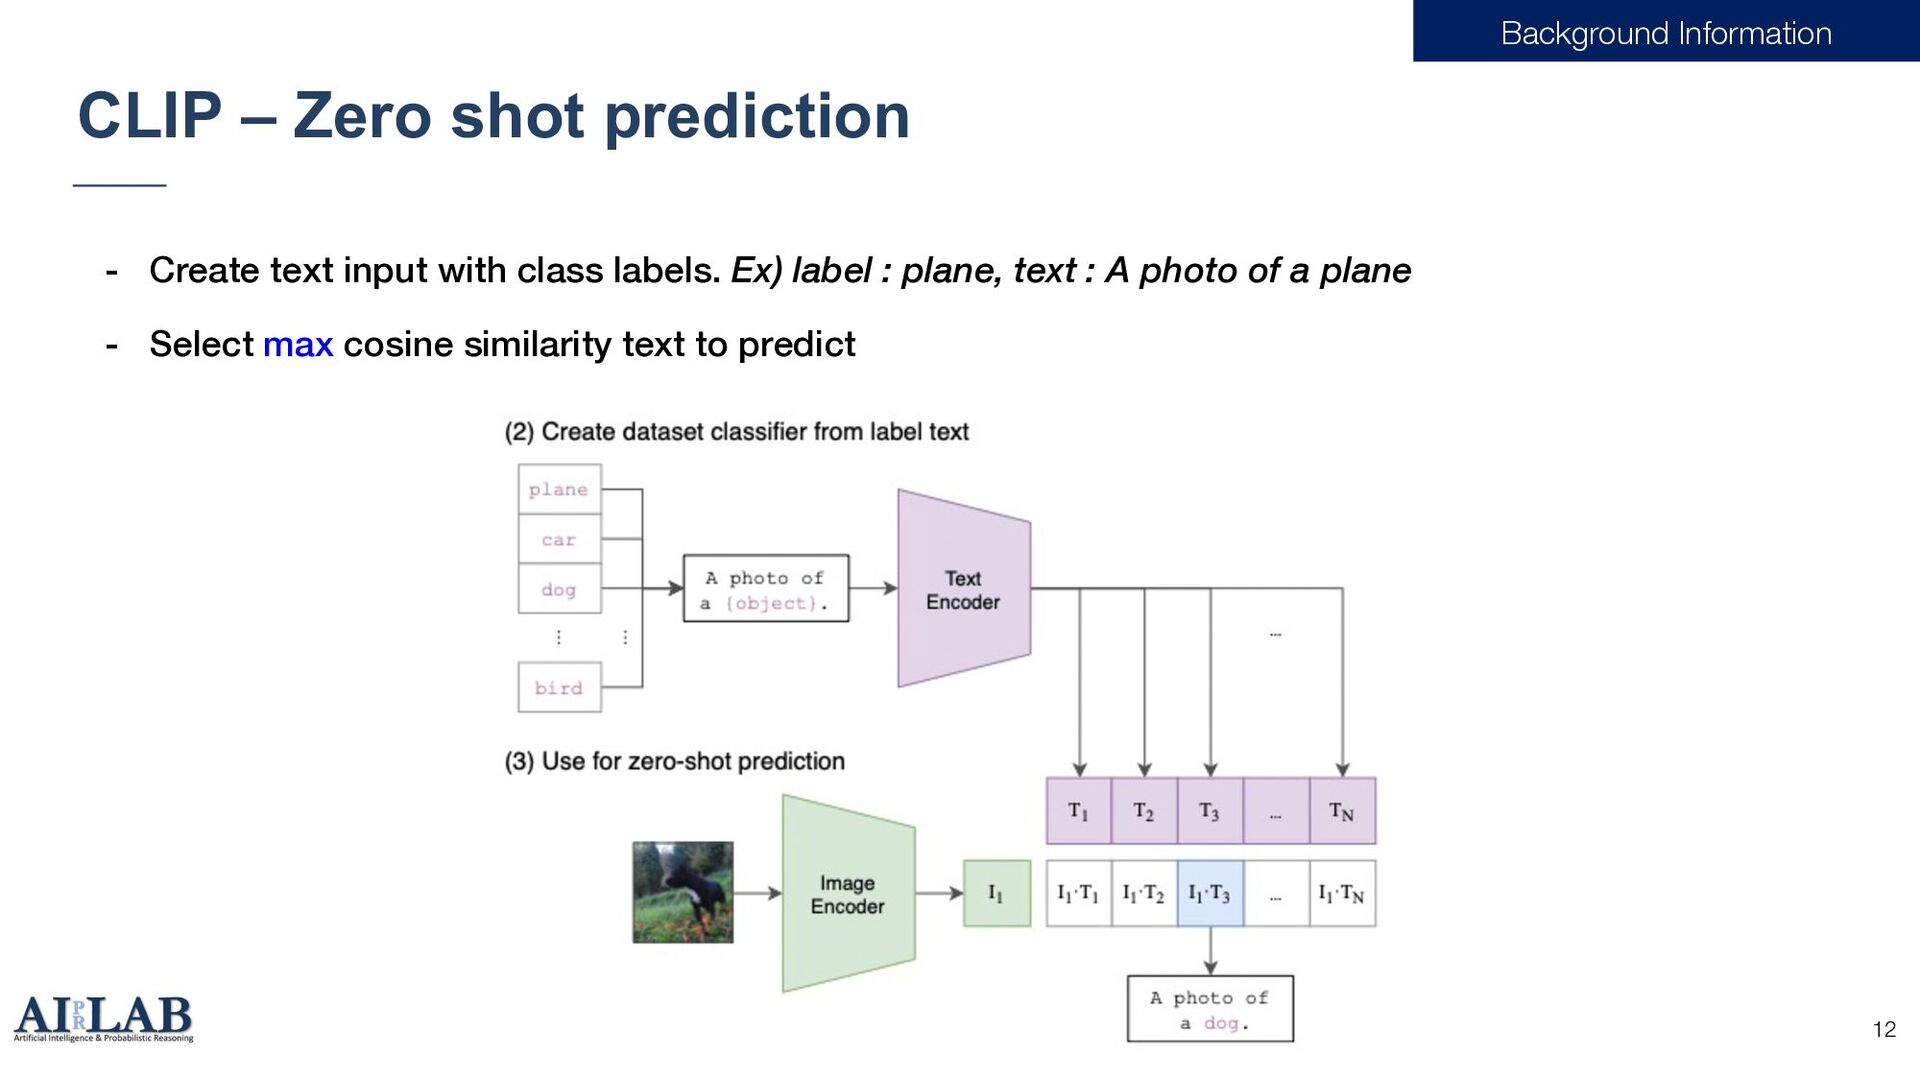
CLIP – Zero shot prediction 12 Background Information - Create
text input with class labels. Ex) label : plane, text : A photo of a plane - Select max cosine similarity text to predict -
Masked language model – BERT[1] 15 Background Information [1] Devlin,
Jacob, et al. "Bert: Pre-training of deep bidirectional transformers for language understanding." arXiv preprint arXiv:1810.04805 (2018). -
Masked Autoencoders Are Scalable Vision Learners[1] 16 Background Information MAE
= Auto encoder + Masked token [1] He, Kaiming, et al. "Masked autoencoders are scalable vision learners." CVPR. 2022. -
Contents 1. Multimodal Masked Autoencoders Learn Transferable Representations – Overview
2. Background Information 1. Multimodal learning 2. Self-supervised representation learning via contrastive – CLIP[1] 3. Self-supervised representation learning via reconstruction – MAE[2] 3. M3AE - Model Structure(Method) 4. Result 17 -
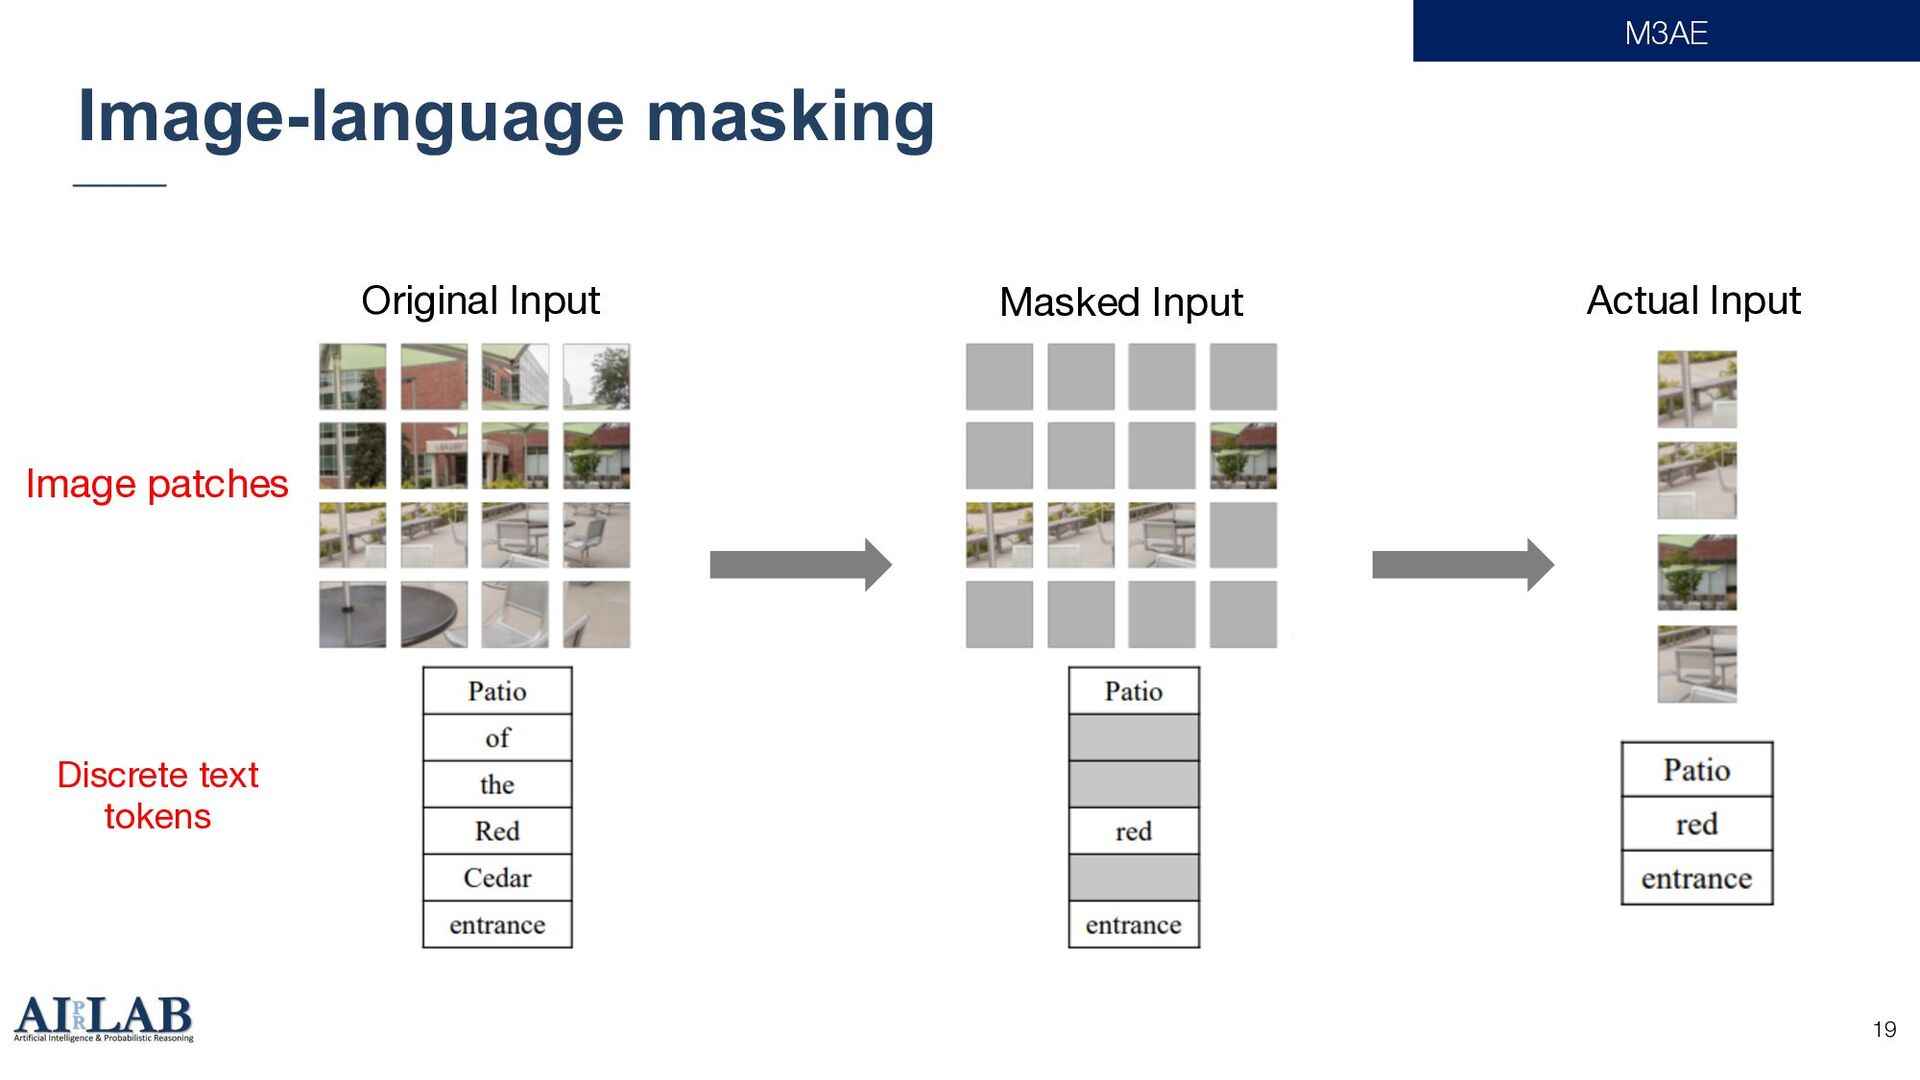
Image-language masking 19 M3AE Original Input Masked Input Actual Input
Image patches Discrete text tokens -
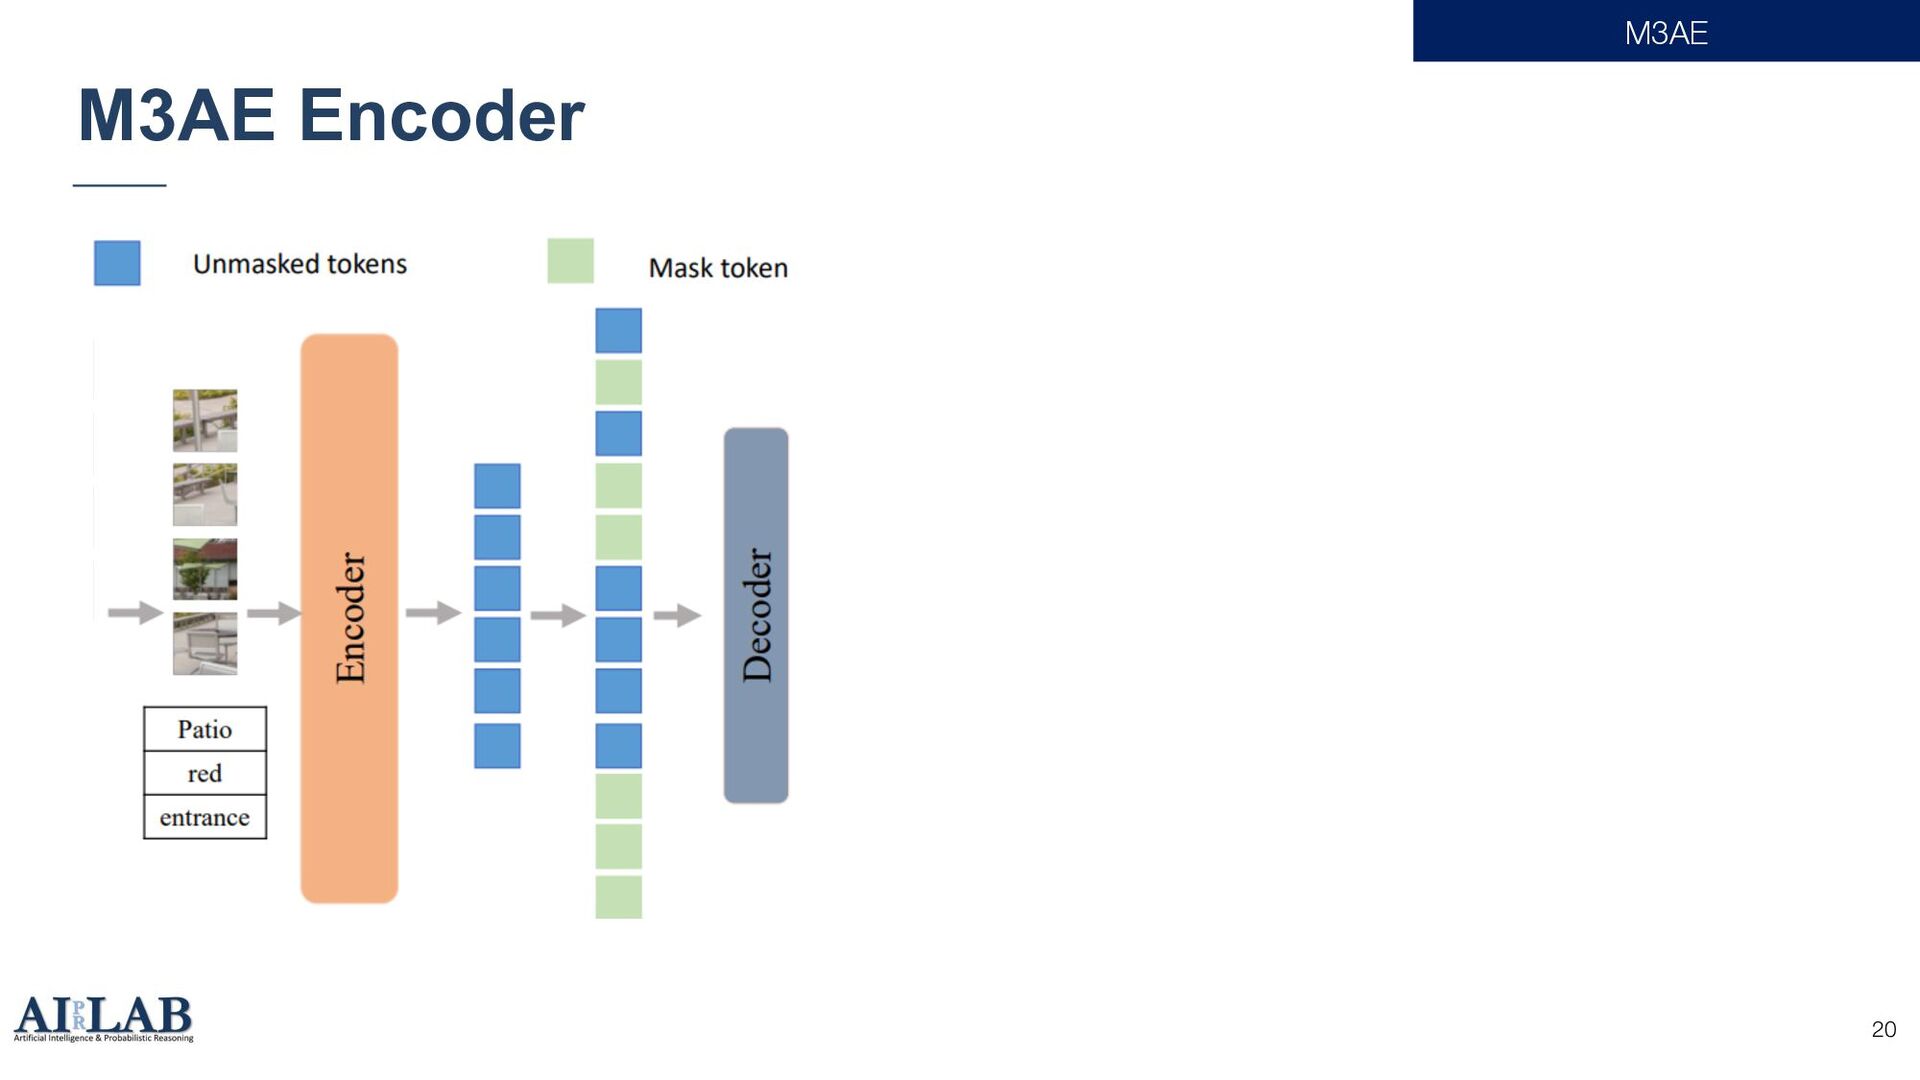
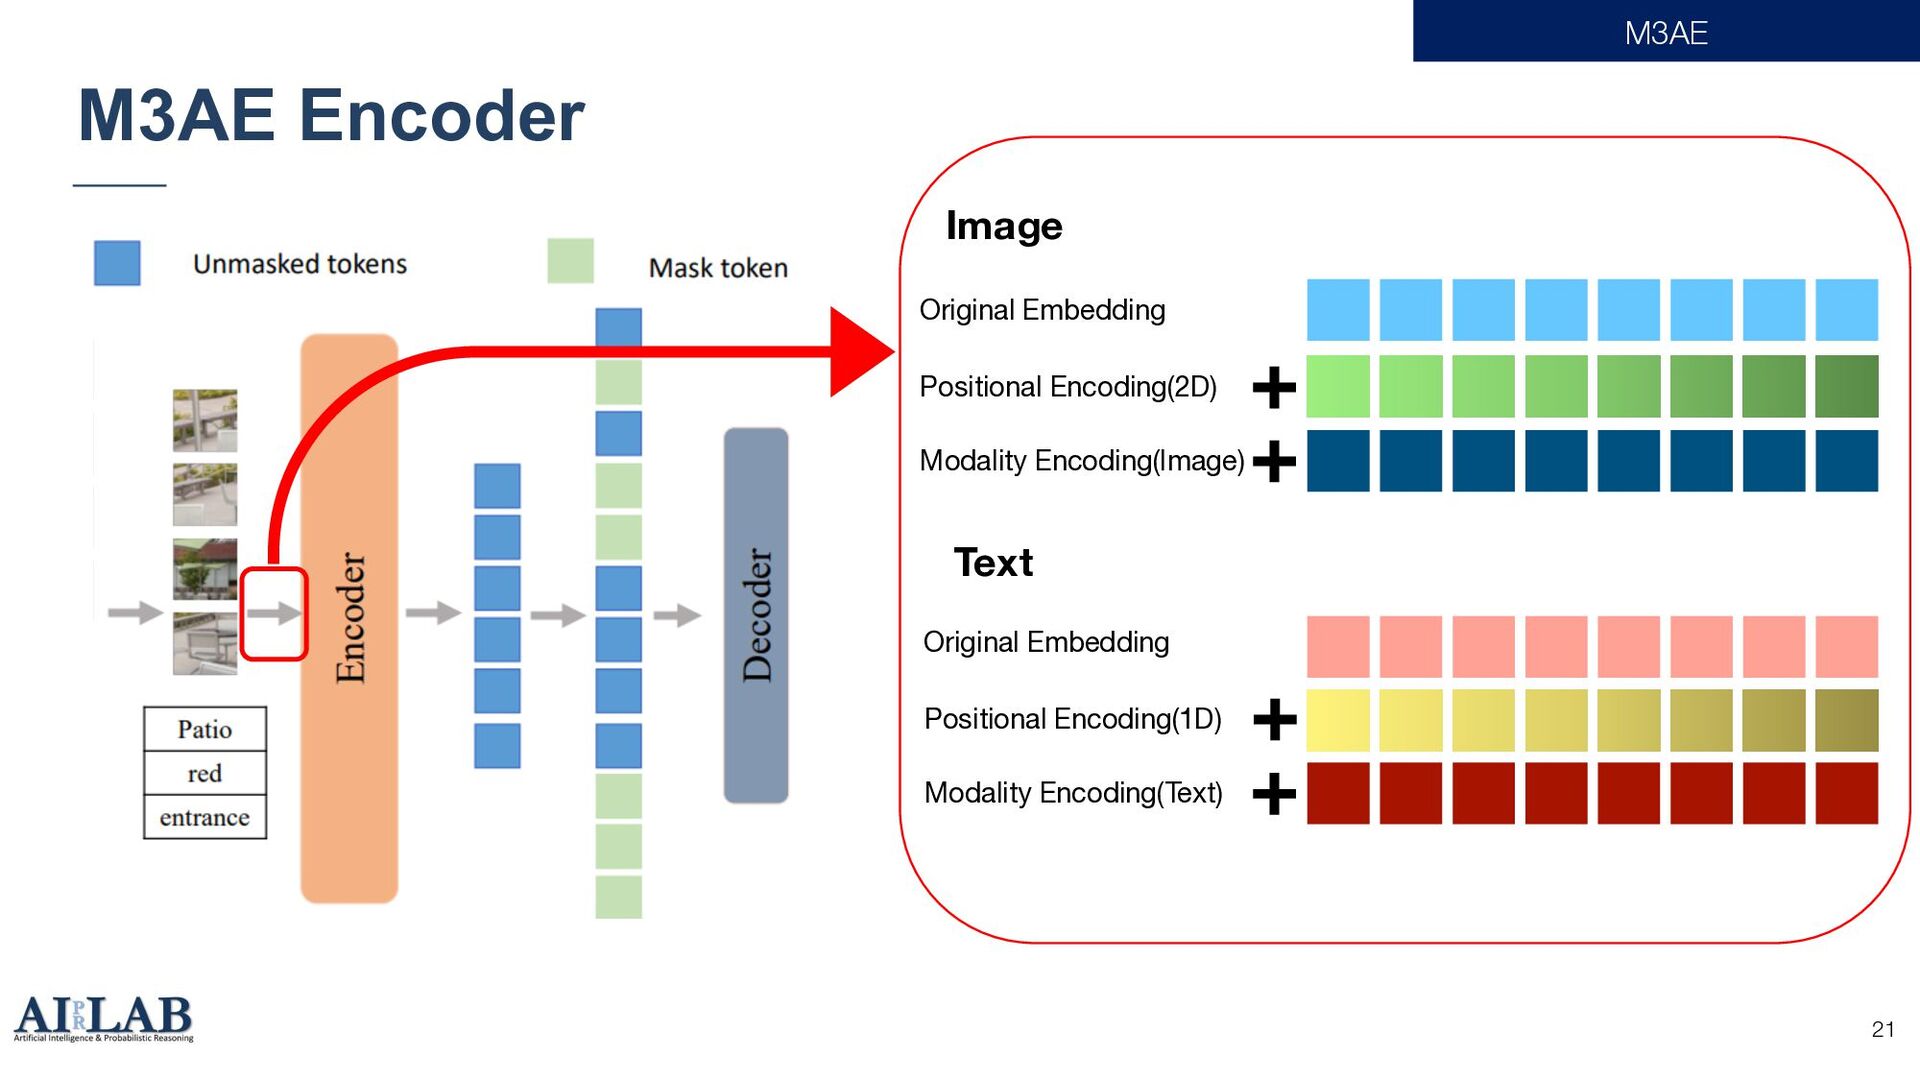
M3AE Encoder 21 M3AE Image Text Original Embedding Positional Encoding(1D)
Modality Encoding(Text) Original Embedding Positional Encoding(2D) Modality Encoding(Image) -
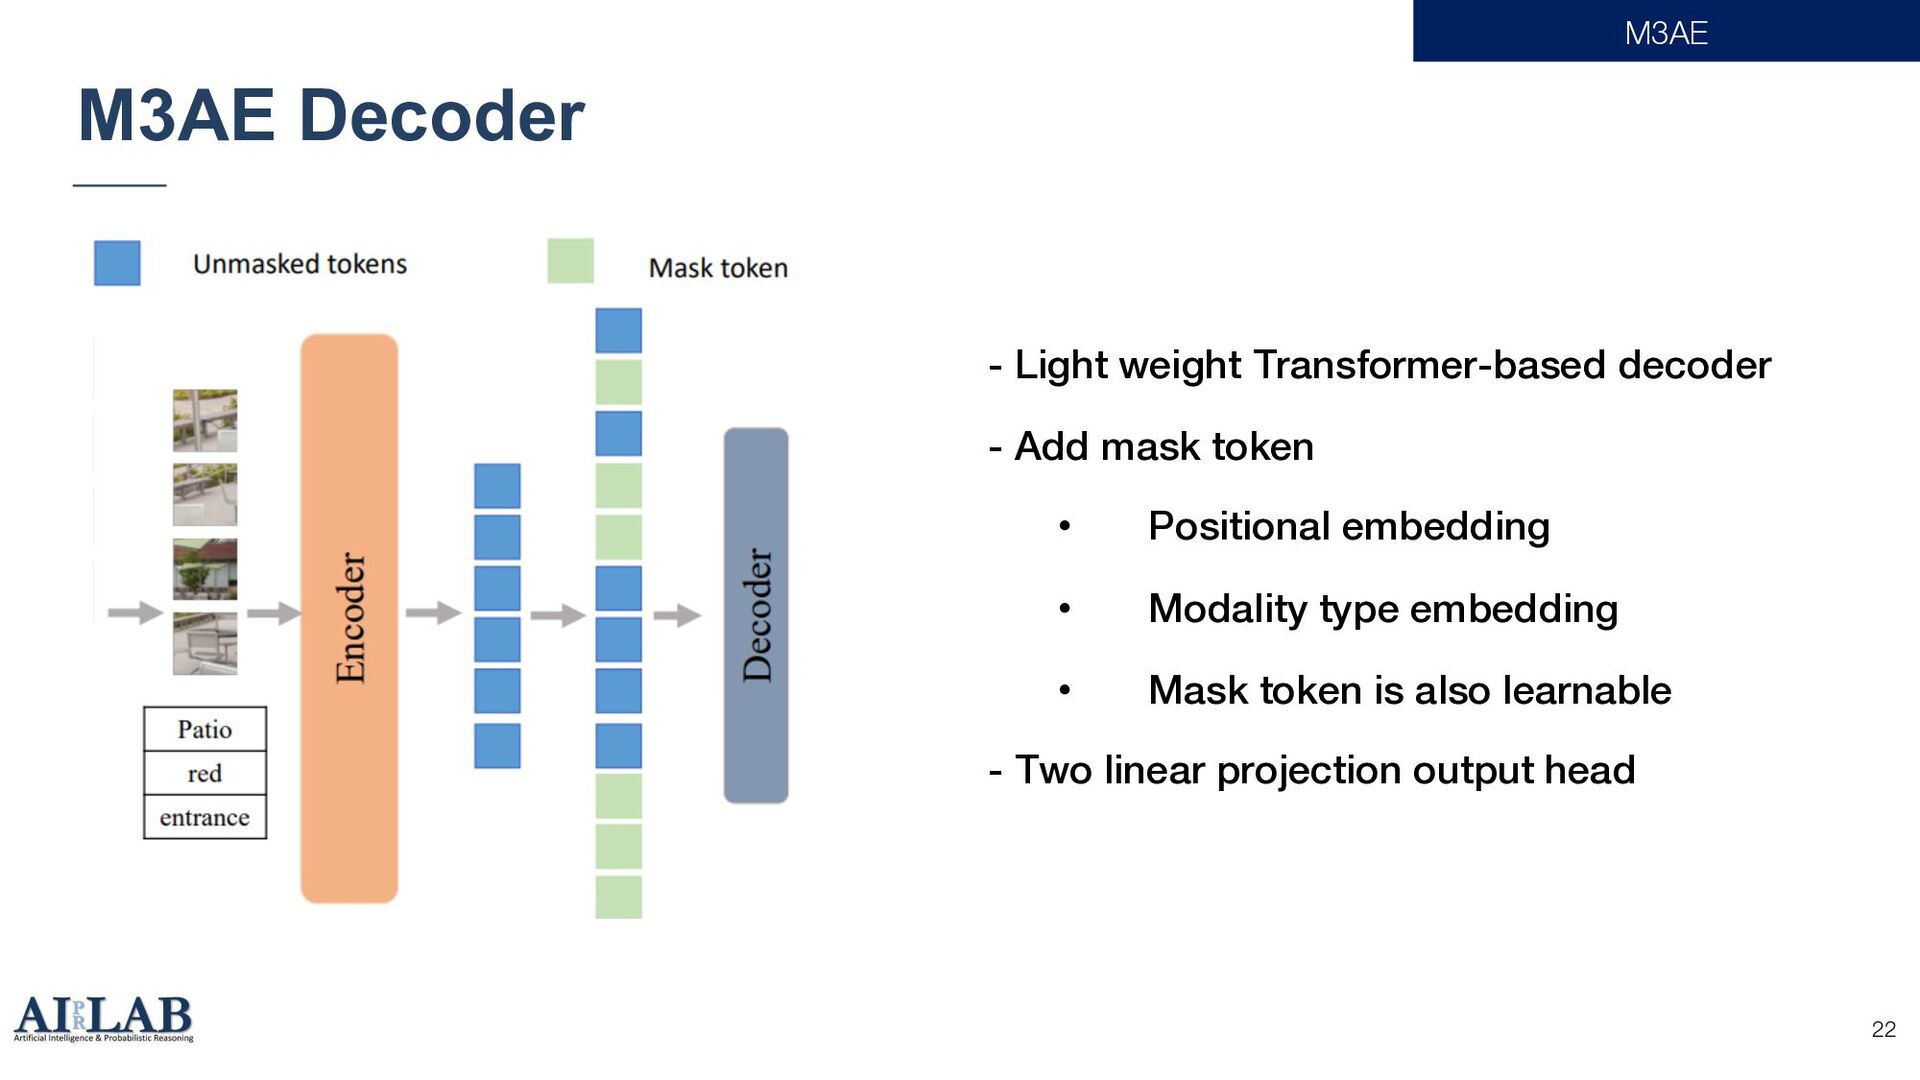
M3AE Decoder 22 M3AE - Light weight Transformer-based decoder -
Add mask token • Positional embedding • Modality type embedding • Mask token is also learnable - Two linear projection output head -
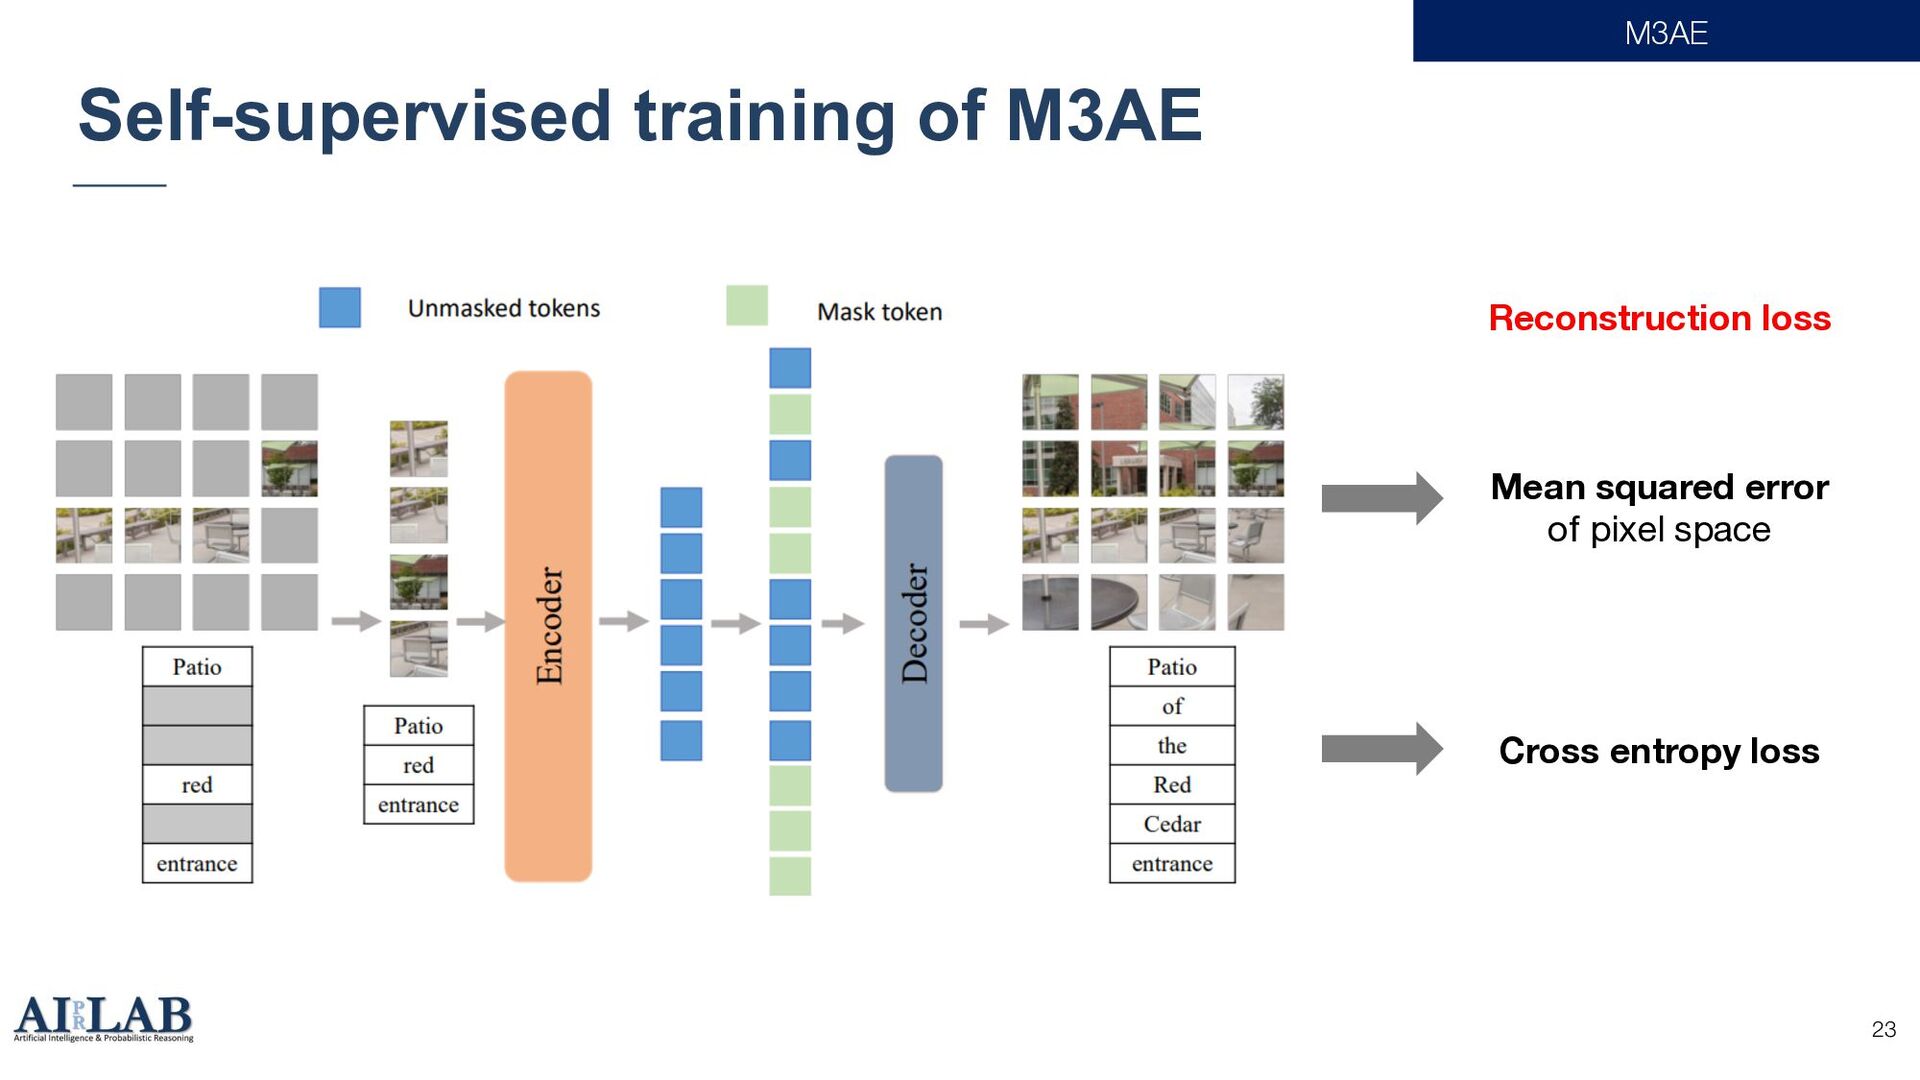
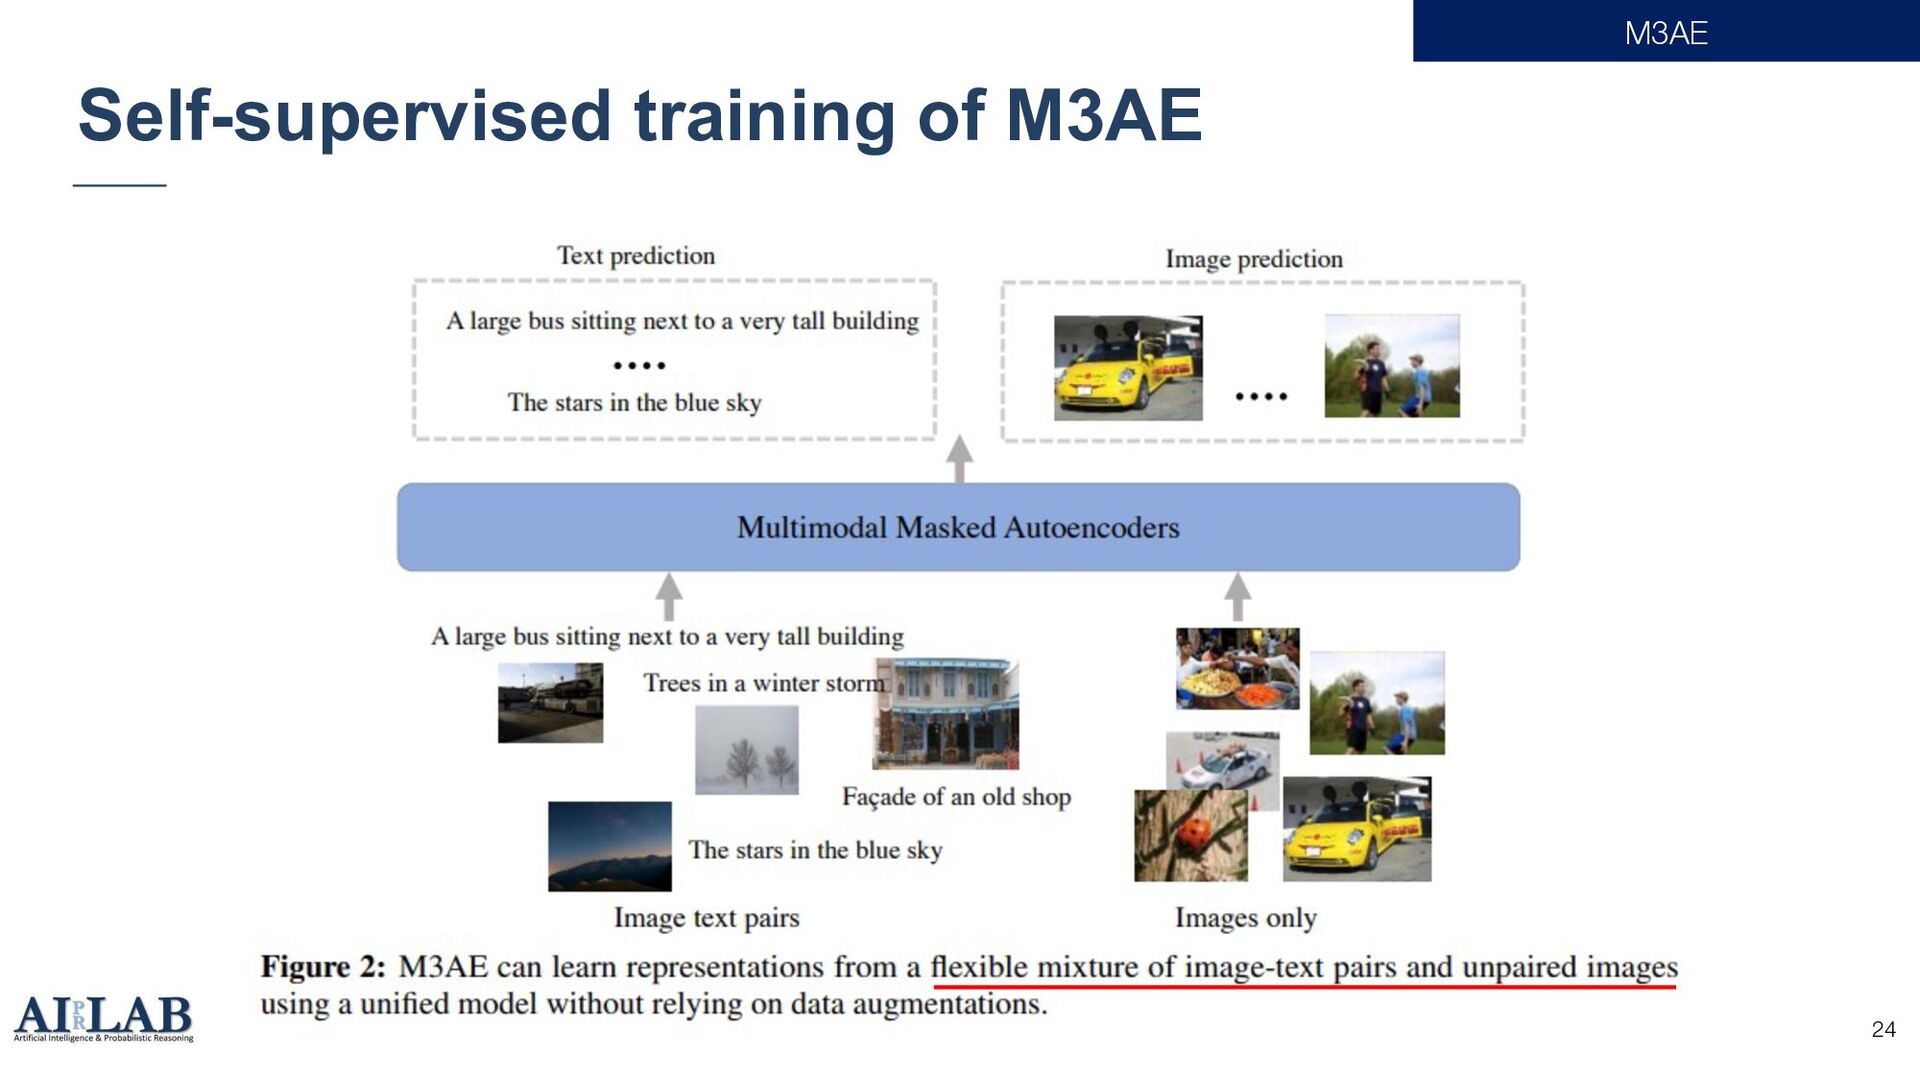
Self-supervised training of M3AE 23 M3AE Reconstruction loss Mean squared
error of pixel space Cross entropy loss -
Contents 1. Multimodal Masked Autoencoders Learn Transferable Representations – Overview
2. Background Information 1. Multimodal learning 2. Self-supervised representation learning via contrastive – CLIP[1] 3. Self-supervised representation learning via reconstruction – MAE[2] 3. M3AE - Model Structure(Method) 4. Result 25 -
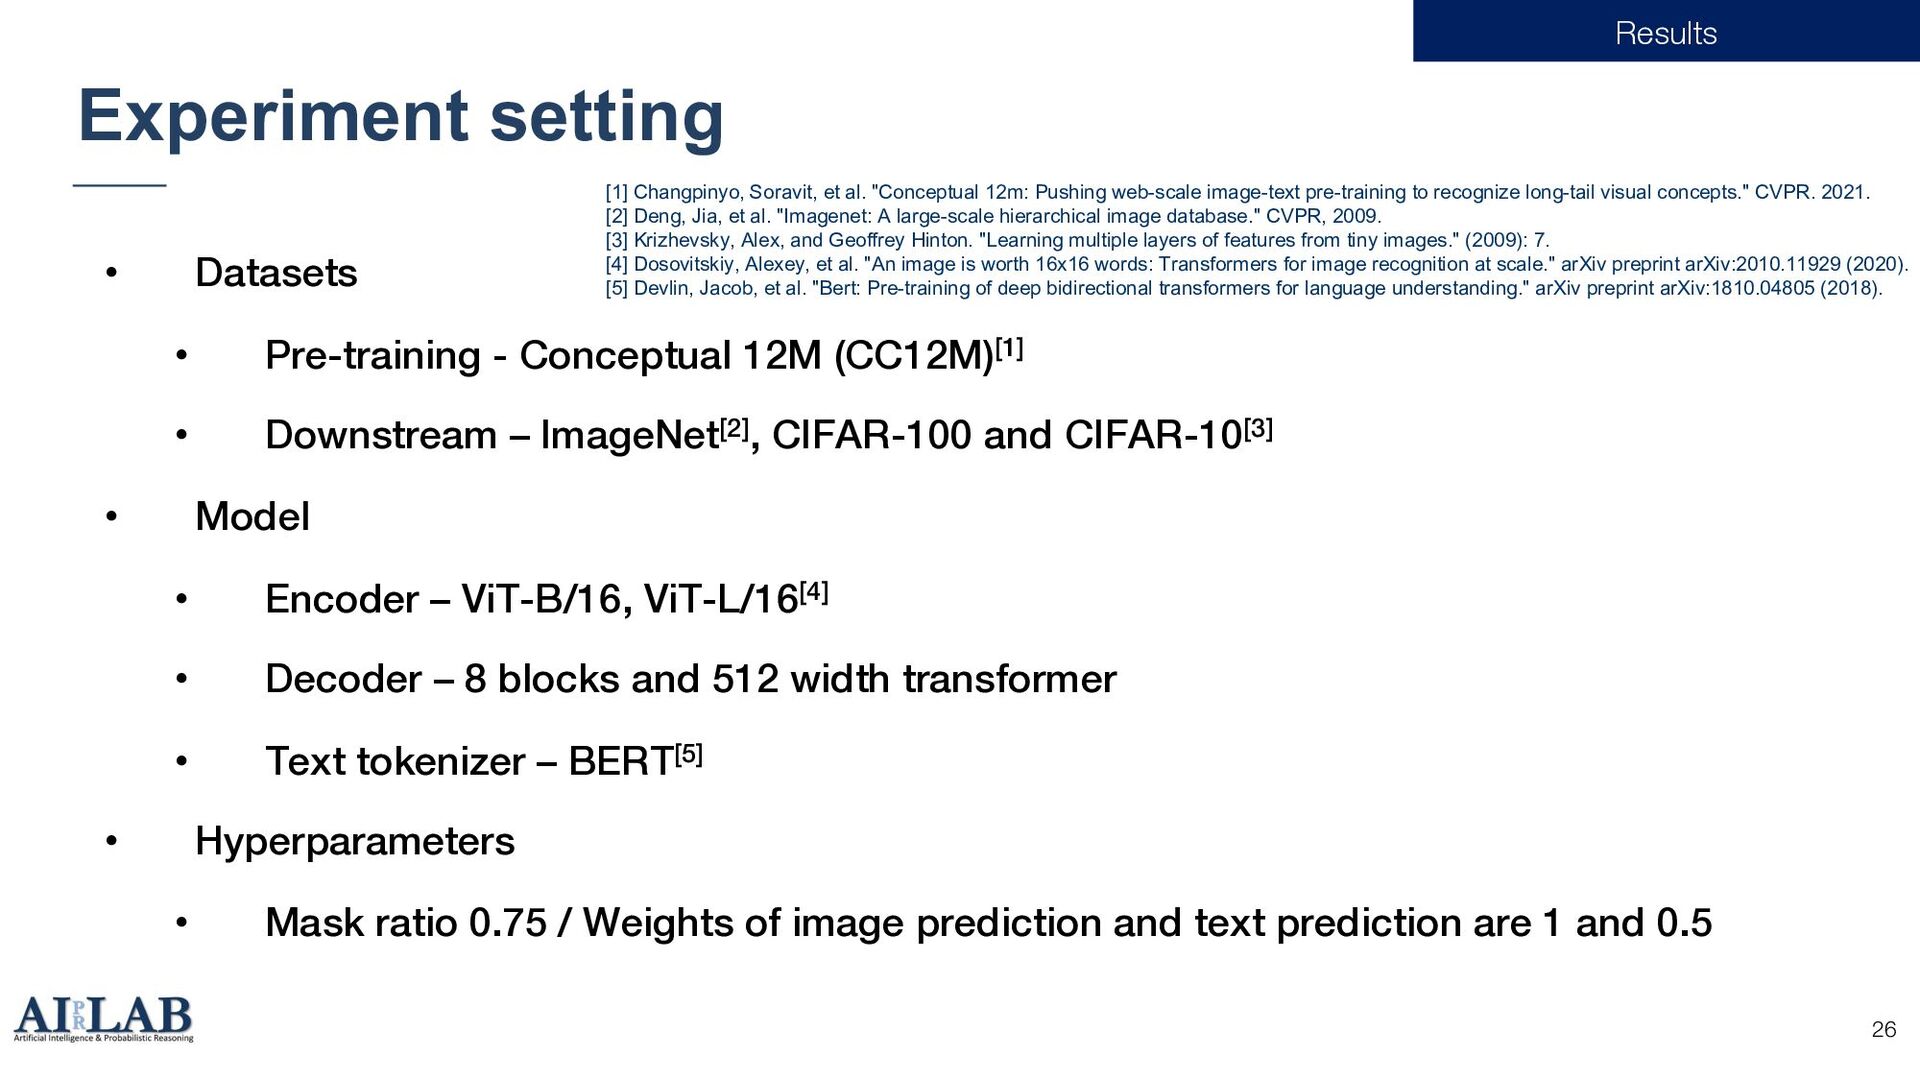
Experiment setting 26 Results • Datasets • Pre-training - Conceptual
12M (CC12M)[1] • Downstream – ImageNet[2], CIFAR-100 and CIFAR-10[3] • Model • Encoder – ViT-B/16, ViT-L/16[4] • Decoder – 8 blocks and 512 width transformer • Text tokenizer – BERT[5] • Hyperparameters • Mask ratio 0.75 / Weights of image prediction and text prediction are 1 and 0.5 [1] Changpinyo, Soravit, et al. "Conceptual 12m: Pushing web-scale image-text pre-training to recognize long-tail visual concepts." CVPR. 2021. [2] Deng, Jia, et al. "Imagenet: A large-scale hierarchical image database." CVPR, 2009. [3] Krizhevsky, Alex, and Geoffrey Hinton. "Learning multiple layers of features from tiny images." (2009): 7. [4] Dosovitskiy, Alexey, et al. "An image is worth 16x16 words: Transformers for image recognition at scale." arXiv preprint arXiv:2010.11929 (2020). [5] Devlin, Jacob, et al. "Bert: Pre-training of deep bidirectional transformers for language understanding." arXiv preprint arXiv:1810.04805 (2018).