Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Adequate Full Text Search
Search
Florian Gilcher
November 25, 2014
Programming
180
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Adequate Full Text Search
given at Elasticsearch UG in November 2014
Florian Gilcher
November 25, 2014
More Decks by Florian Gilcher
See All by Florian Gilcher
A new contract with users
skade
1
560
Using Rust to interface with my dive computer
skade
0
330
async/.await with async-std
skade
1
840
Training Rust
skade
1
160
Internet of Streams - IoT in Rust
skade
0
140
How DevRel is failing communities
skade
0
150
The power of the where clause
skade
0
750
Three Years of Rust
skade
1
260
Rust as a CLI language
skade
1
260
Other Decks in Programming
See All in Programming
Kotlinize Is Not Just Converting to Kotlin
chigichan24
1
220
小さなアプリを作って公開するまで
onozaty
0
150
flutter_test のその先へ — Flutter アプリの LLM 機能に「評価」という品質保証を
kosukesaigusa
0
200
Enforcing Your Architecture with Unit Tests in the AI Era (Swift Connection X)
steliosf
PRO
1
150
クラウドゲーミングのパフォーマンス最適化に挑む / Cloud Gaming Performance Tuning
vivion
0
330
オーケストレーション記述言語 Katari
yukikurage
0
240
PyConTW 2026 - AI Coding 不只是工具升級, 區域醫院醫療資訊系統協作開發與資訊團隊轉型實踐
cclai999
0
240
動画プレイヤーはなぜカクつくのか 〜Flutterのレンダリングとネイティブの境界を解剖する〜
naruogram
0
330
Web3Dライブラリを作ってVue Custom Rendererの仕組みを理解しよう / lets learn vue custom renderer by making 3d library
drumath2237
1
130
SODA - FACT BOOK(JP)
sodainc
1
40k
Railsのためのパスキー実践入門 〜マルチテナントSaaSでの意思決定〜
utakaha
4
3.7k
Lambda durable functionsでHuman in the Loopを楽に…楽に……
har1101
2
300
Featured
See All Featured
Chasing Engaging Ingredients in Design
codingconduct
0
390
AI Search: Implications for SEO and How to Move Forward - #ShenzhenSEOConference
aleyda
1
1.4k
Agile Leadership in an Agile Organization
kimpetersen
PRO
0
310
How to Grow Your eCommerce with AI & Automation
katarinadahlin
PRO
2
350
Into the Great Unknown - MozCon
thekraken
41
2.8k
Mind Mapping
helmedeiros
1
430
Google's AI Overviews - The New Search
badams
0
1.7k
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Building Flexible Design Systems
yeseniaperezcruz
330
41k
Reality Check: Gamification 10 Years Later
codingconduct
0
2.4k
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
Highjacked: Video Game Concept Design
rkendrick25
PRO
1
560
Transcript
None
$ cat .profile GIT_AUTHOR_NAME=Florian Gilcher
[email protected]
TM_COMPANY=Asquera GmbH TWITTER_HANDLE=argorak GITHUB_HANDLE=skade
• Backend developer • Focused on infrastructure and databases
• Elasticsearch Usergroup • mrgn.in meetup • Rust Usergroup (co-org)
• organizer alumni eurucamp • organizer alumni JRubyConf.EU • Ruby Berlin board member
Adequate Full Text Search
The evaluation problem
Given almost no time and an unknown problem space, how
do I evaluate "fitness for purpose"?
You can't
Given almost no time and only a glimpse of the
problem space, how do I evaluate "fitness for purpose"?
How much of a glimpse do I need?
In this talk, I’ll present: • a solution unfit for
purpose • a solution fit for purpose, but only in cer- tain boundaries • a comparison to a fully fledged solution
To the daily practitioners: I’ll gloss over a lot of
points.
• Elasticsearch • PostgreSQL • MongoDB
Issue 1 Search systems are not binary. Faults in the
system degrade the quality of the system, rarely break it.
Issue 2 Full text searchers are far more focused on
inputs then on output.
Building Block 1 An inverted index
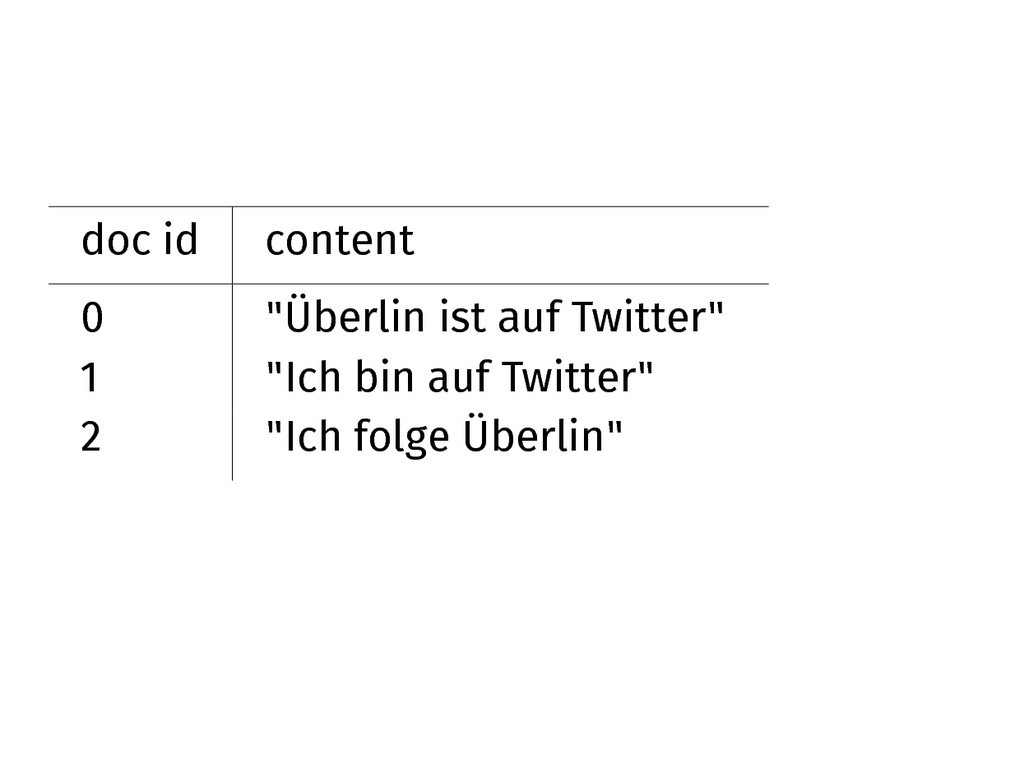
doc id content 0 "Überlin ist auf Twitter" 1 "Ich
bin auf Twitter" 2 "Ich folge Überlin"
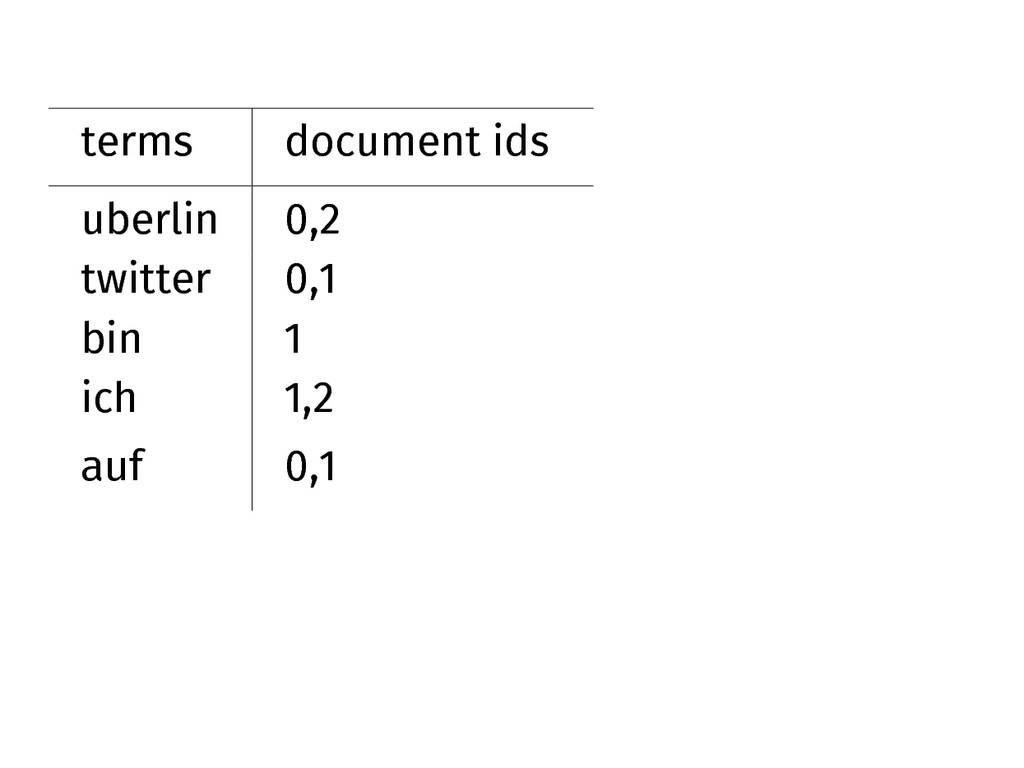
terms document ids uberlin 0,2 twitter 0,1 bin 1 ich
1,2 auf 0,1
Initial search rules are easy: if one or more of
the terms to the left is searched for, find the document that matches. Count the matches.
Building Block 2 Textual input
Full text searchers generally work on real world text. Get
hold of as many samples as possible. If necessary, write some on your own.
Don’t use an random generator. Or spend your next weeks
writing a sophisticated one.
Your system should bring capabilities handling real world text.
Analysis
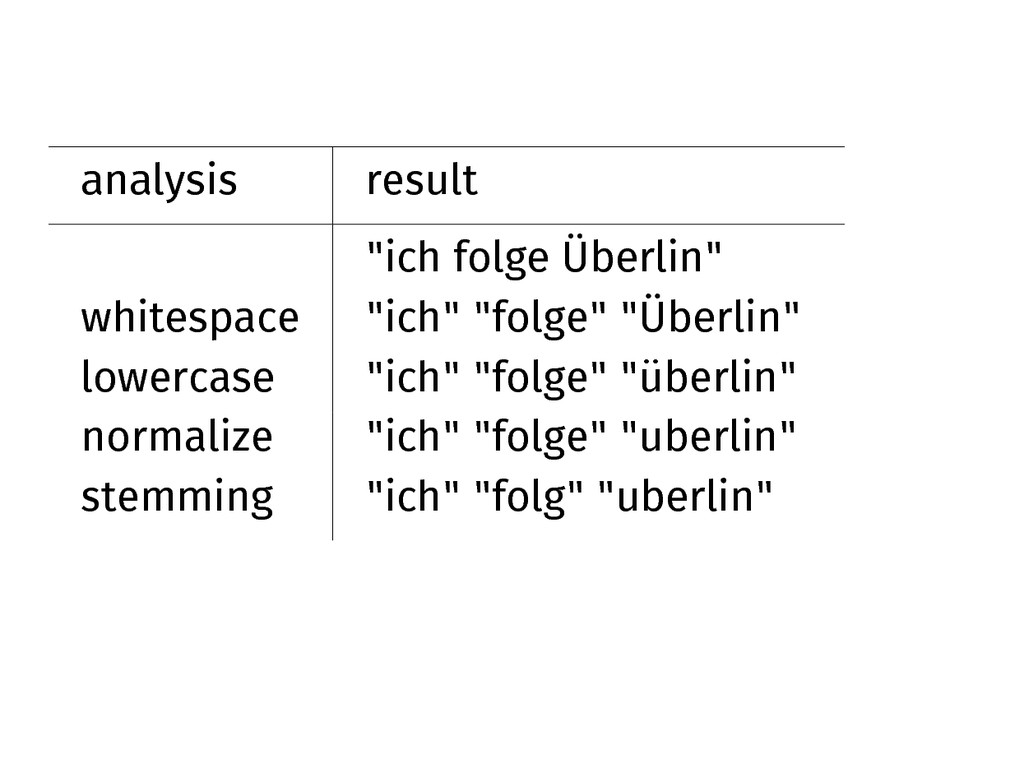
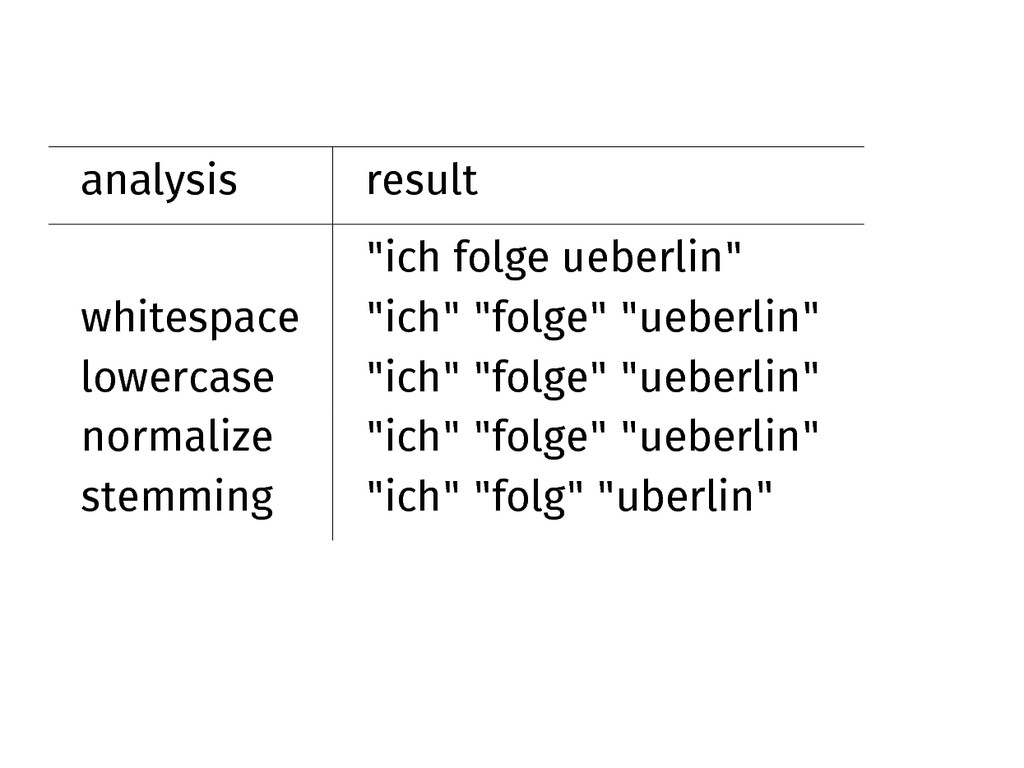
Analysis determines which terms end up at the left side
of the table in the first place.
analysis result "ich folge Überlin" whitespace "ich" "folge" "Überlin" lowercase
"ich" "folge" "überlin" normalize "ich" "folge" "uberlin" stemming "ich" "folg" "uberlin"
analysis result "ich folge ueberlin" whitespace "ich" "folge" "ueberlin" lowercase
"ich" "folge" "ueberlin" normalize "ich" "folge" "ueberlin" stemming "ich" "folg" "uberlin"
This step happens both on indexing and queries.
Manipulating analysis is the basis for manipulating matches.
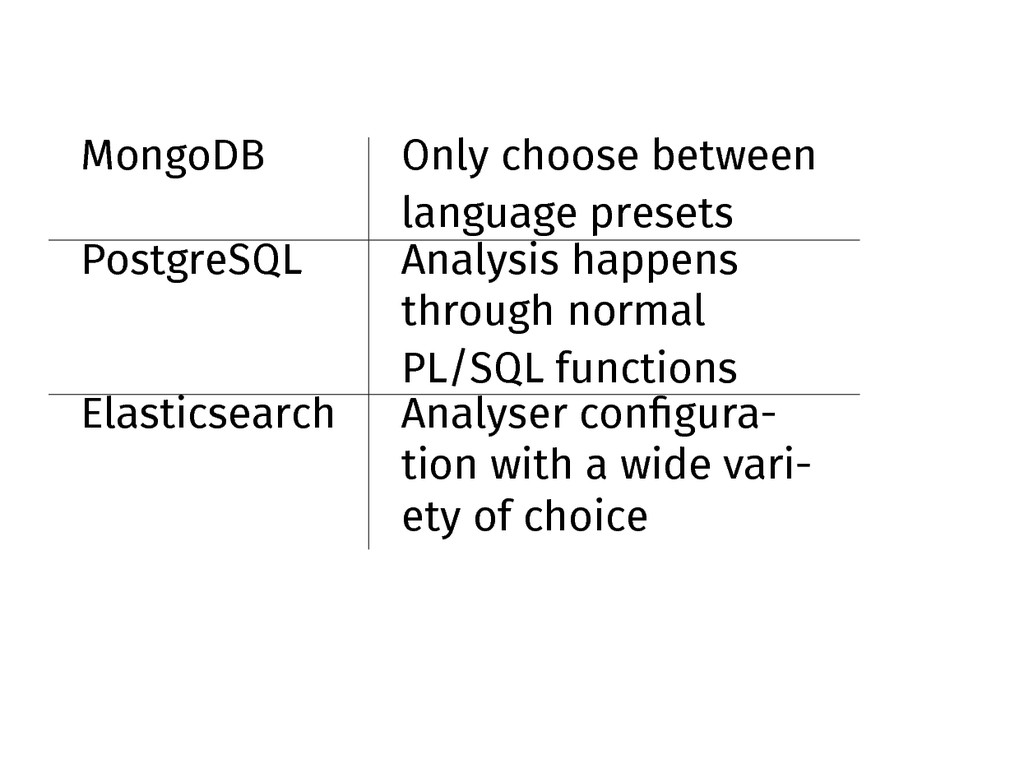
Can I manipulate analysis?
MongoDB Only choose between language presets PostgreSQL Analysis happens through
normal PL/SQL functions Elasticsearch Analyser configura- tion with a wide vari- ety of choice
Ü
Does your system comfortably speak Unicode?
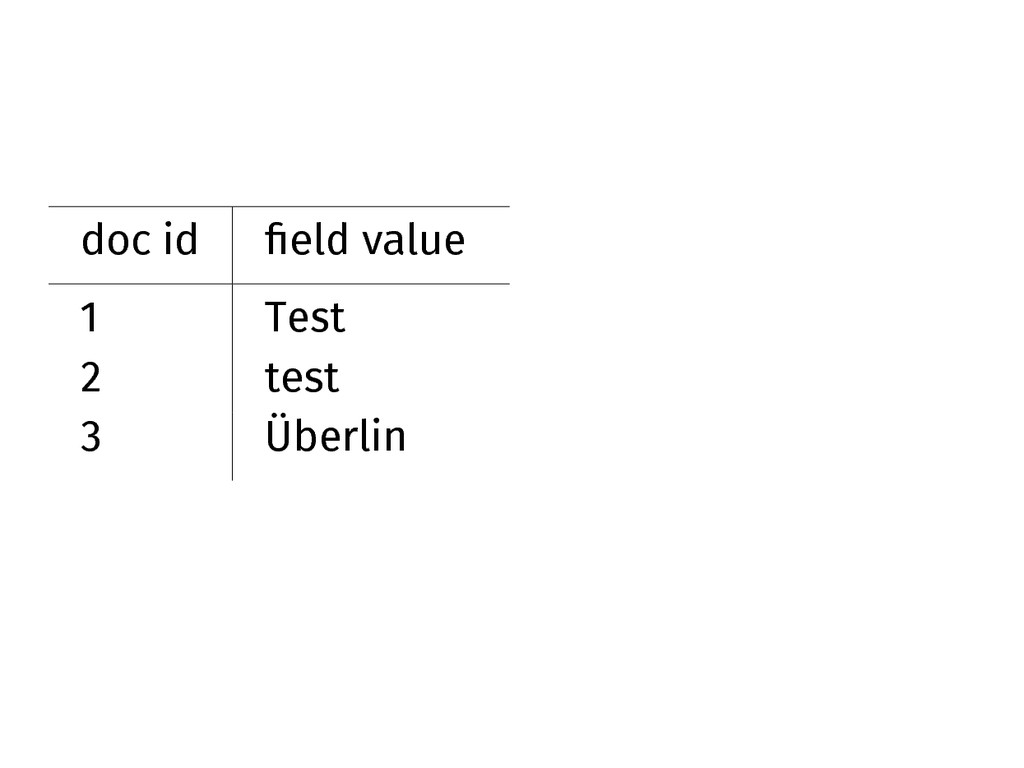
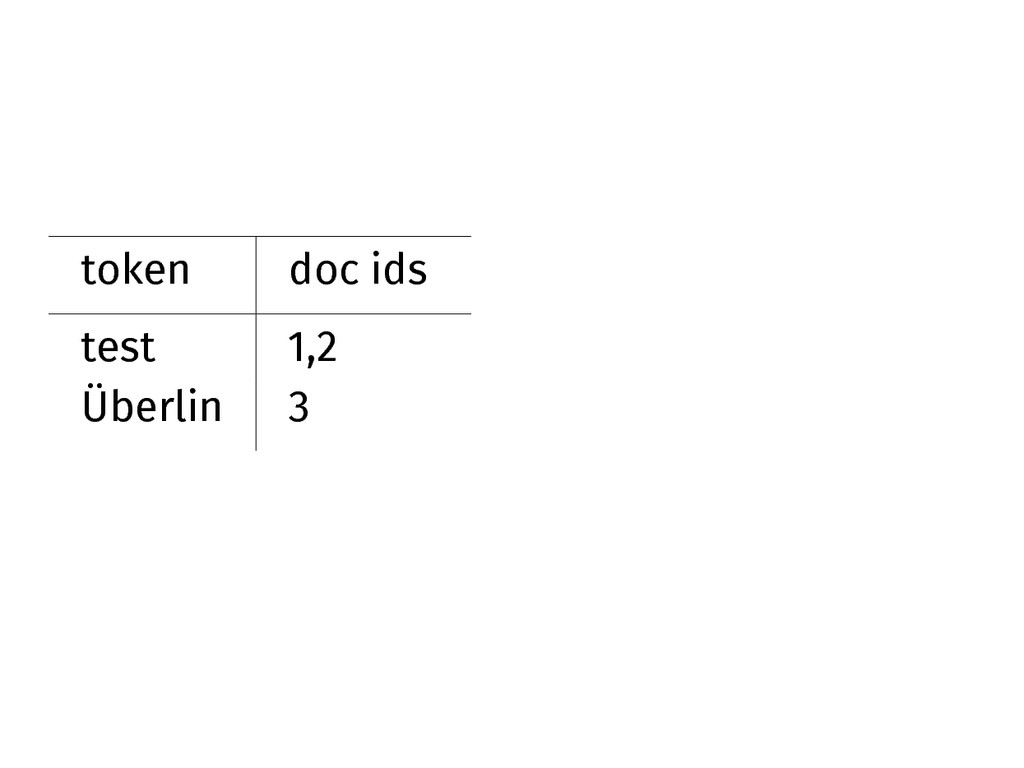
doc id field value 1 Test 2 test 3 Überlin
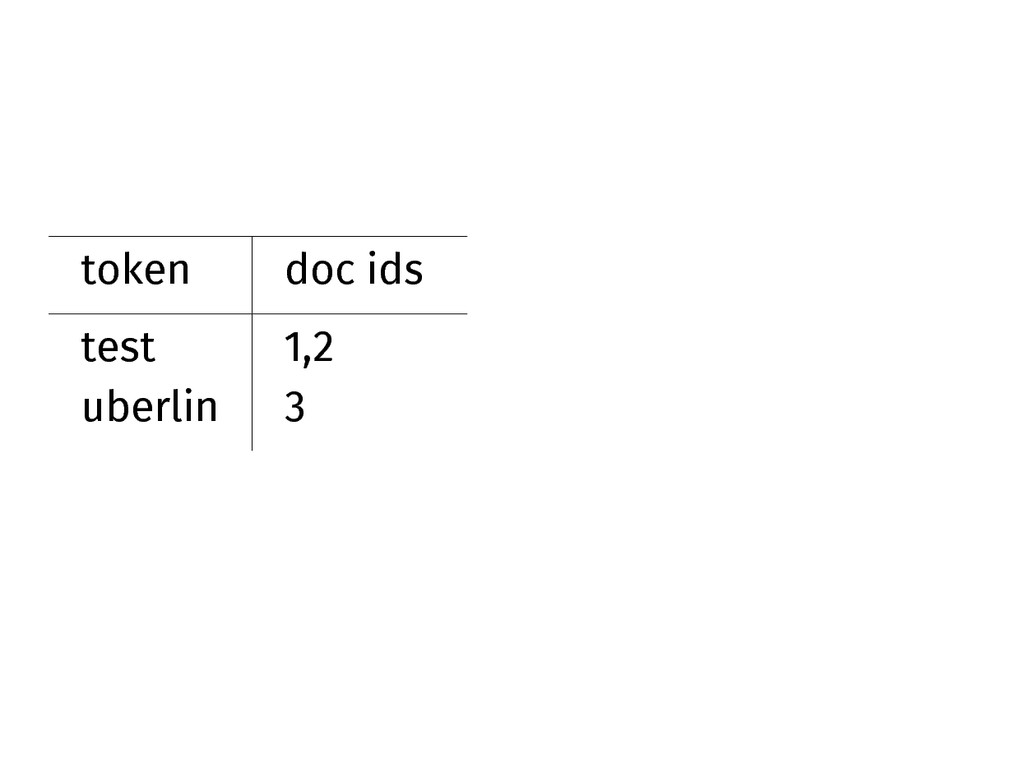
token doc ids test 1,2 uberlin 3
MongoDB
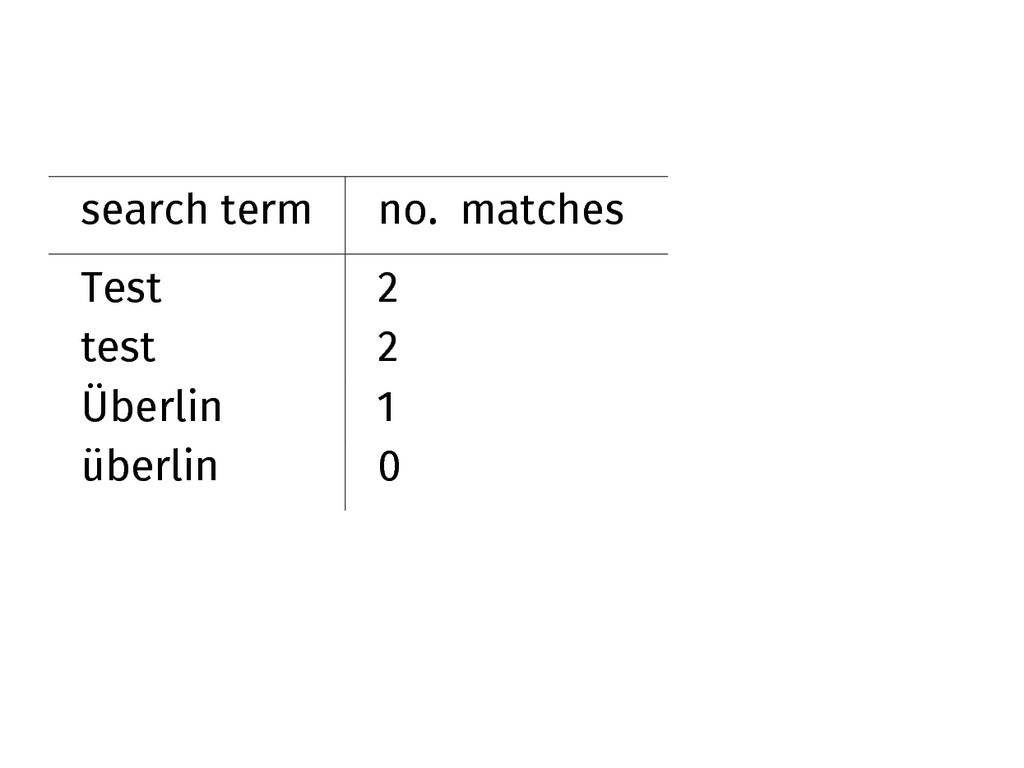
search term no. matches Test 2 test 2 Überlin 1
überlin 0
token doc ids test 1,2 Überlin 3
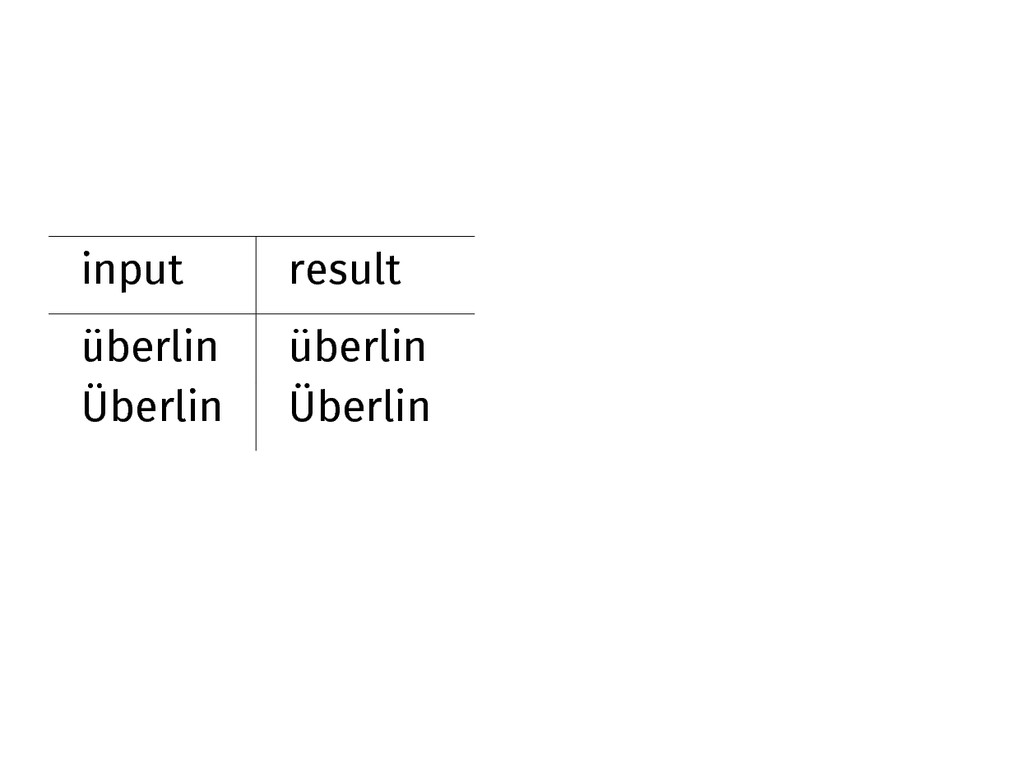
input result überlin überlin Überlin Überlin
MongoDB fails at the simplest case, lowercasing german umlauts, in
german settings.
The exact analysis behaviour is not user-controllable, for simplicities sake.
The suggestion is to preprocess yourself.
None
Further down the Unicode
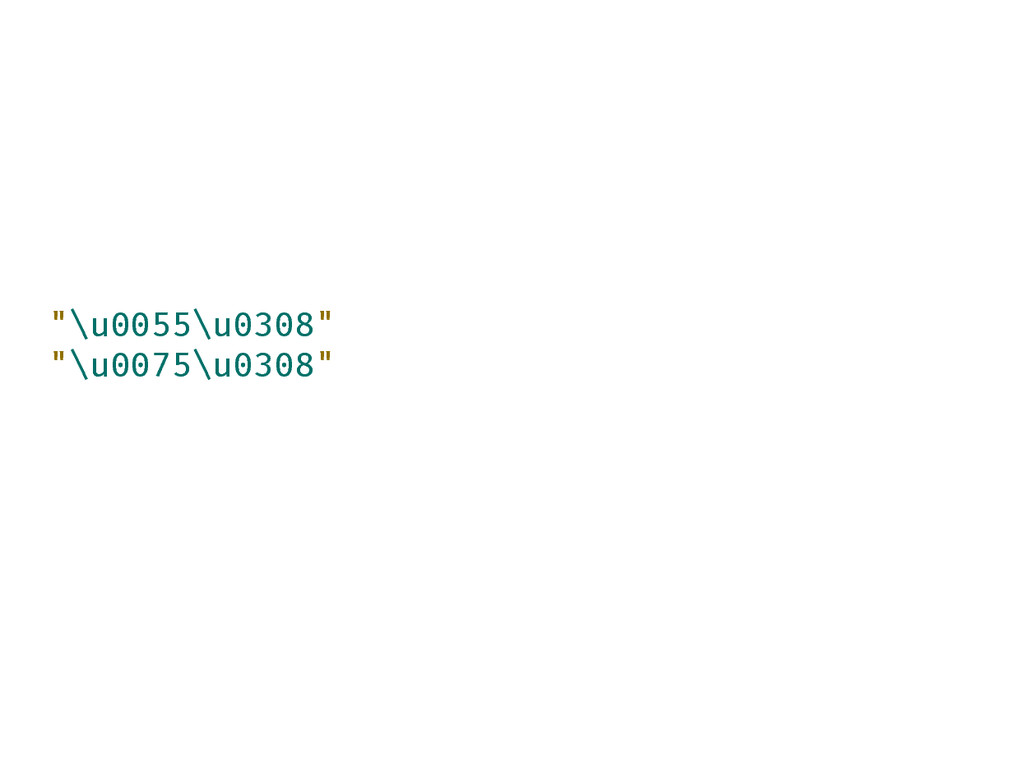
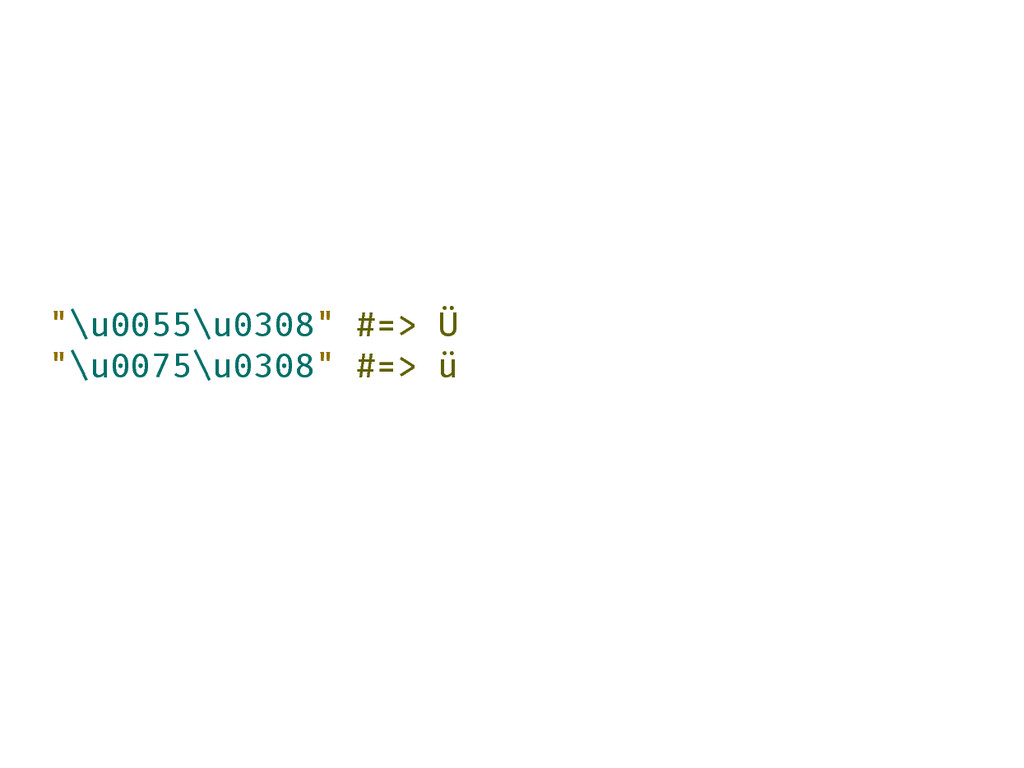
How well does you system handle "creative" codes?
"\u0055\u0308" "\u0075\u0308"
"\u0055\u0308" #=> Ü "\u0075\u0308" #=> ü
PostgreSQL
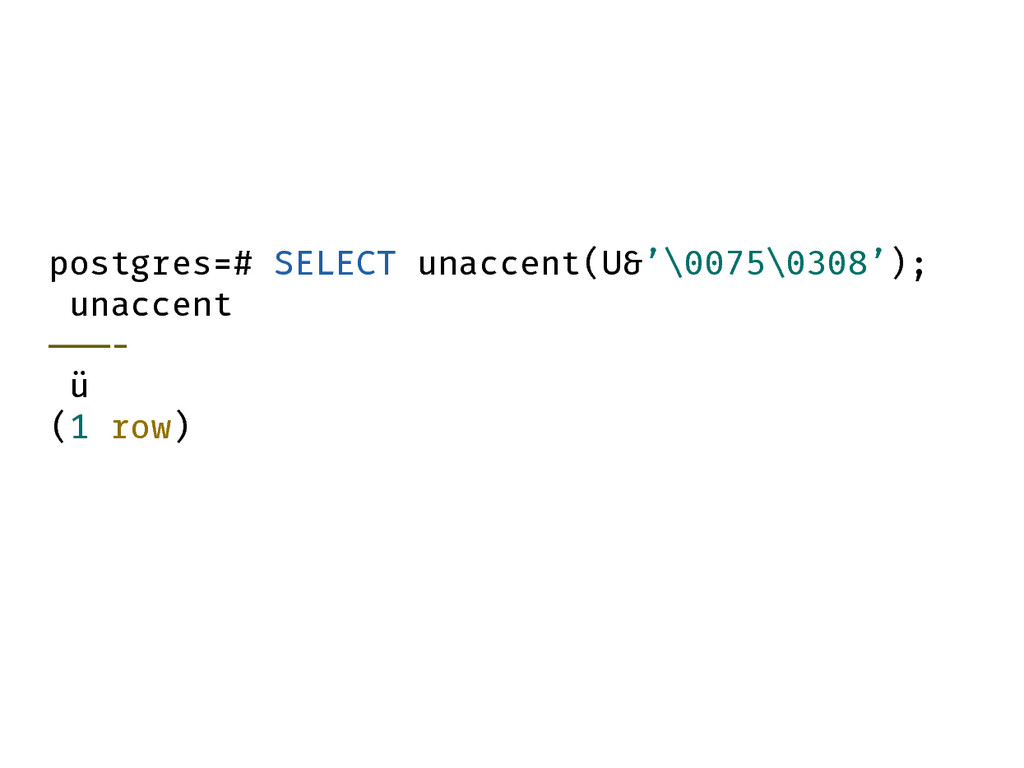
postgres=# SELECT unaccent(U&’\0075\0308’); unaccent ———- ü (1 row)
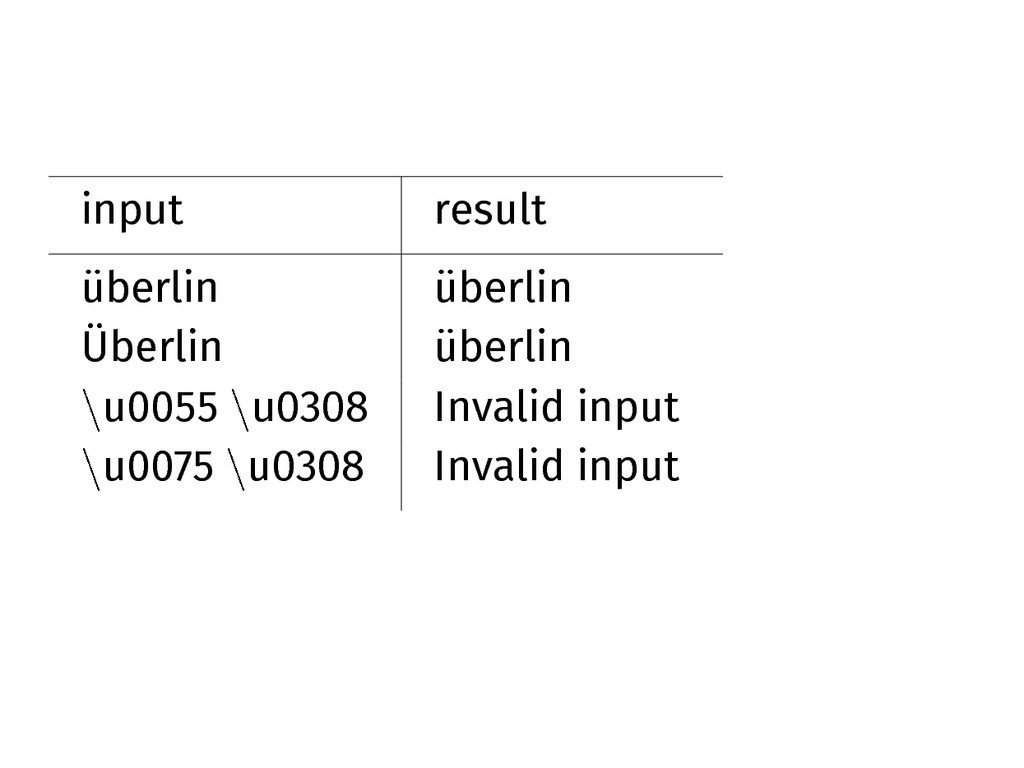
PostgreSQL handles UCS-2 level 1, not UTF.
No combining chars.
“ we should really reject combining chars, but can’t do
that w/o breaking BC.”
sigh, Software
If you use PostgreSQL and text manipulation, you probably have
a bug in the hiding there.
UCS-2 for all textual data is a doable constraint, though.
input result überlin überlin Überlin überlin \u0055 \u0308 Invalid input
\u0075 \u0308 Invalid input
Elasticsearch
Elasticsearch can handle all those cases and then some, using
the analysis-icu plugin.
Install it and use it.
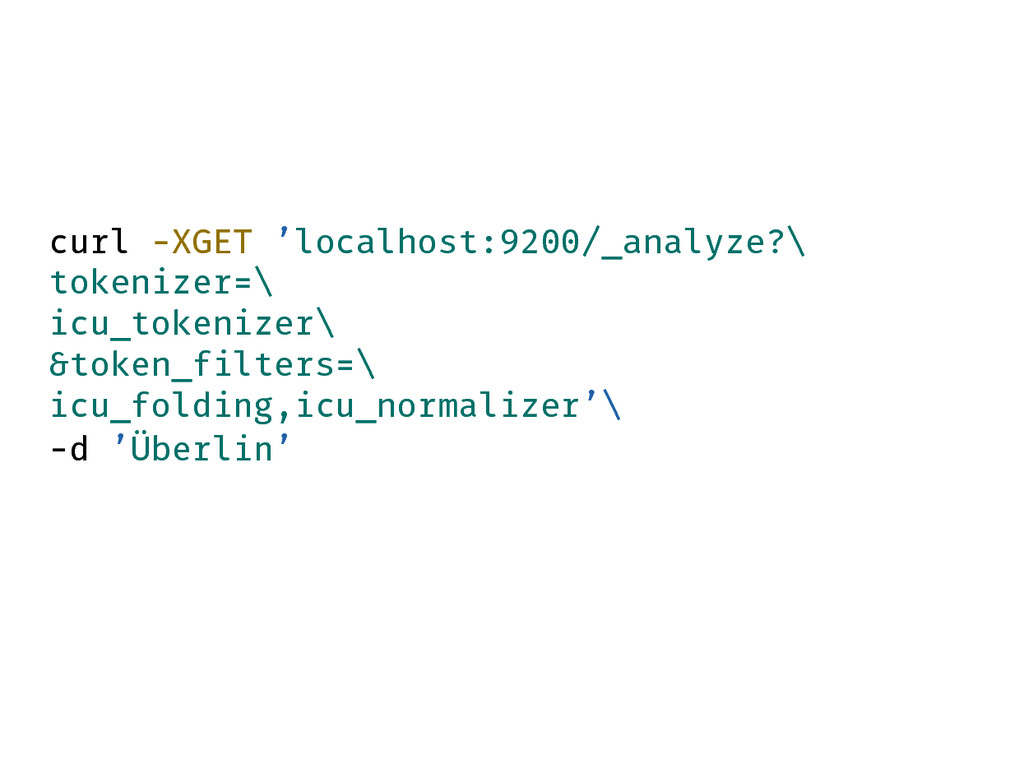
curl -XGET ’localhost:9200/_analyze?\ tokenizer=\ icu_tokenizer\ &token_filters=\ icu_folding,icu_normalizer’\ -d ’Überlin’
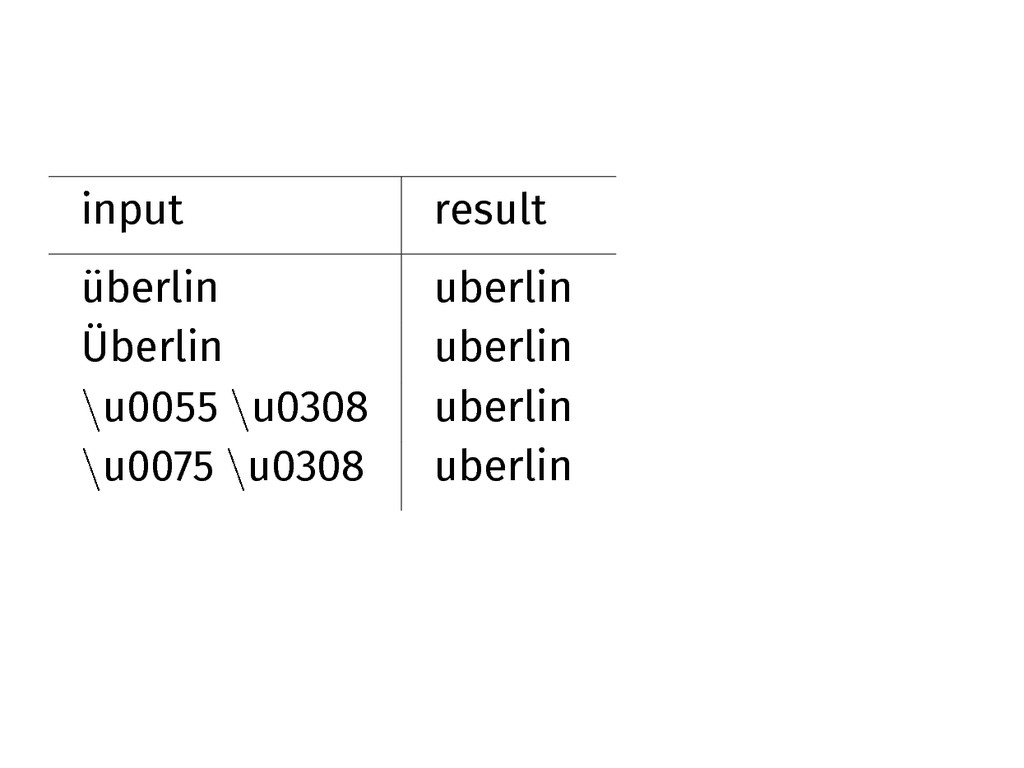
input result überlin uberlin Überlin uberlin \u0055 \u0308 uberlin \u0075
\u0308 uberlin
The way the system supports you in safely inserting textual
input is of paramount importance!
Find the worst shenanegans of you language, try it out.
l’elision, c’est magnifique
Building Block 3 Scoring
Search is all about relevance and combinations thereof.
Was the match in the title or the body of
a document?
How many options do I have?
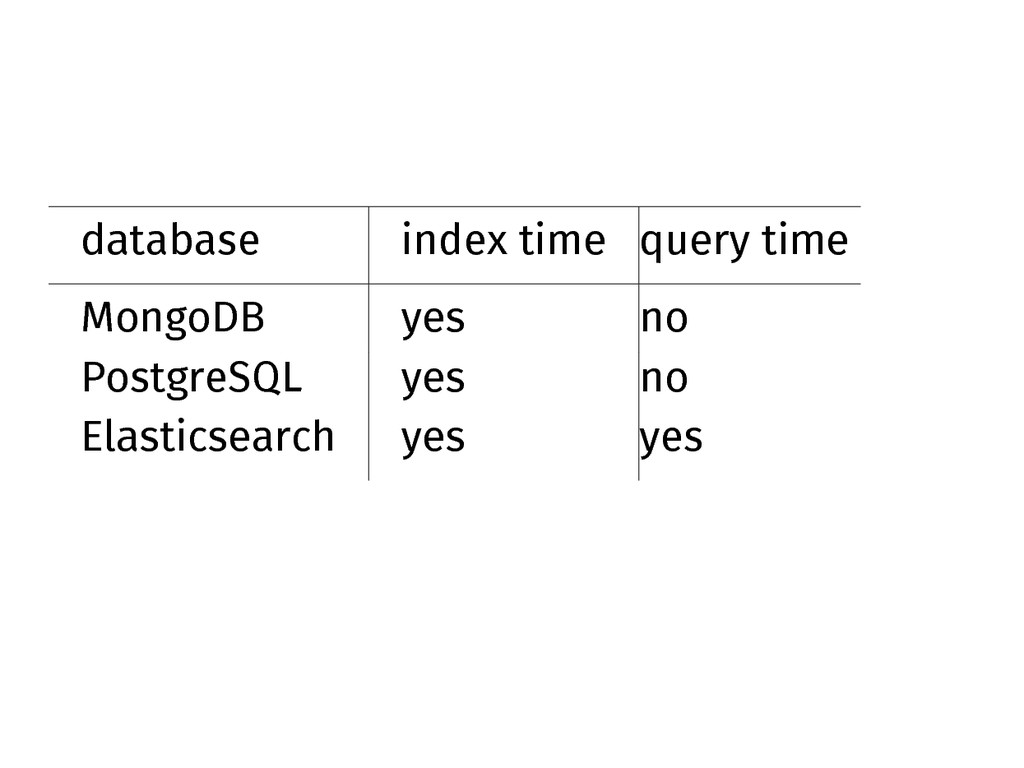
All three systems can weight matches on fields differently.
When can I decide those weights?
database index time query time MongoDB yes no PostgreSQL yes
no Elasticsearch yes yes
Weights during index time need a rebuild of the index
every time you change them.
If in doubt, choose query time weights.
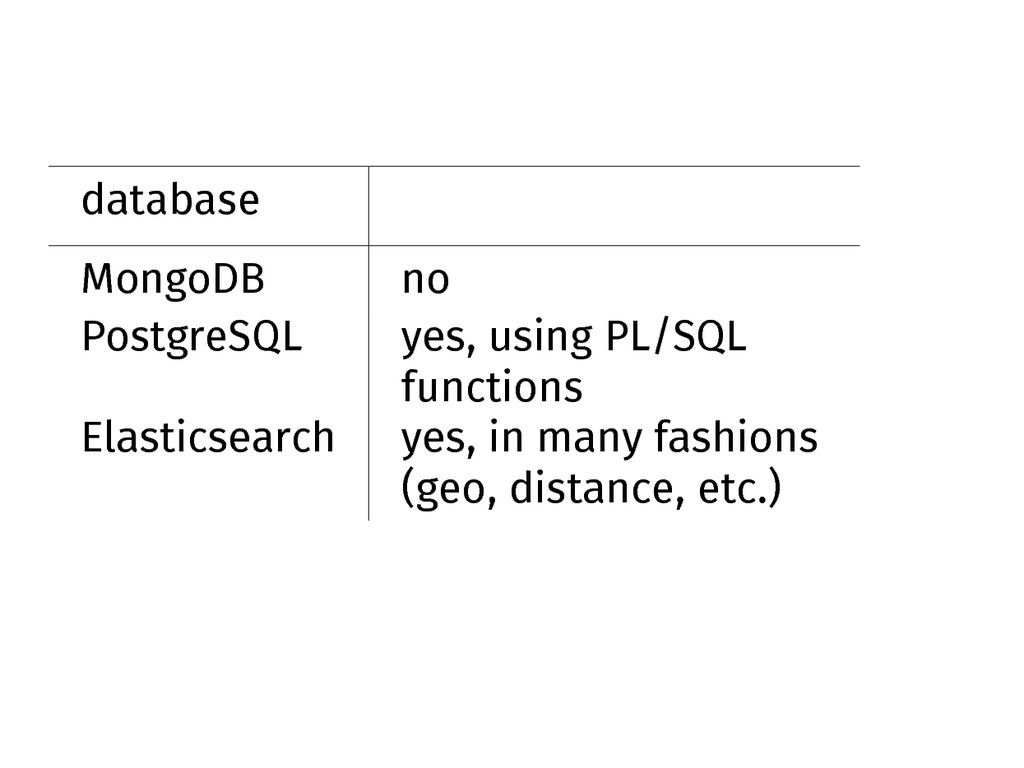
Can I influence the scoring/ranking further?
database MongoDB no PostgreSQL yes, using PL/SQL functions Elasticsearch yes,
in many fashions (geo, distance, etc.)
Building Block 4 Documentation
I glossed over a lot of details.
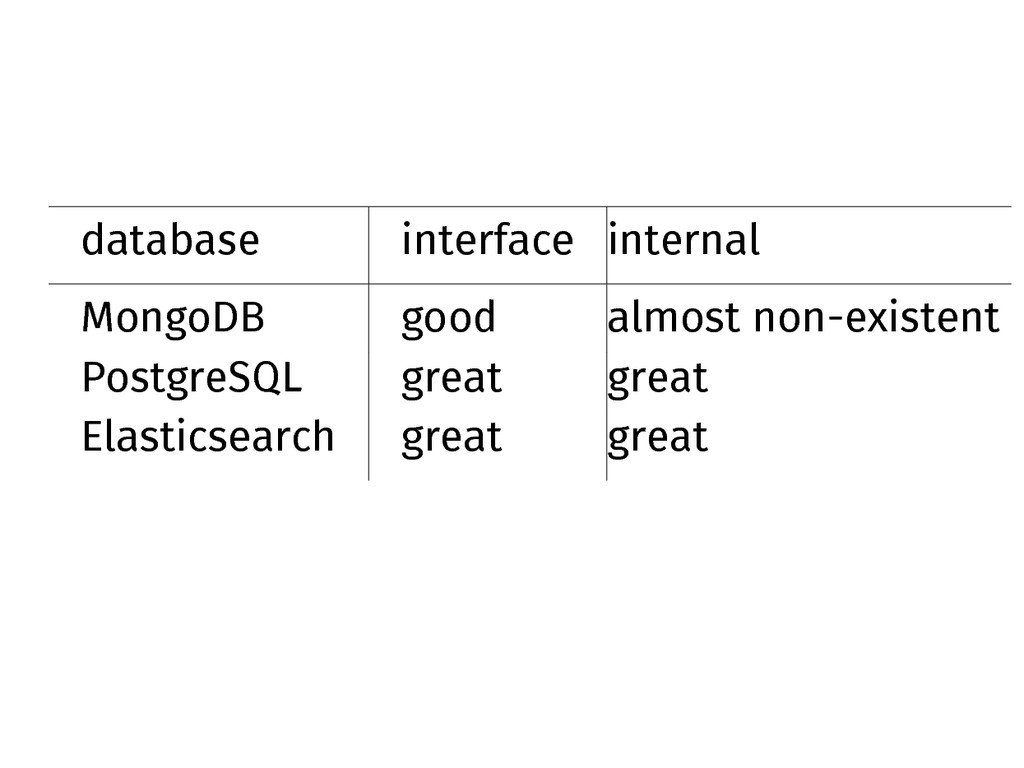
How well is the process documented, internally and interface-wise?
database interface internal MongoDB good almost non-existent PostgreSQL great great
Elasticsearch great great
Can I grow beyond?
And this is where the fun starts and we stop.
What’s adequate?
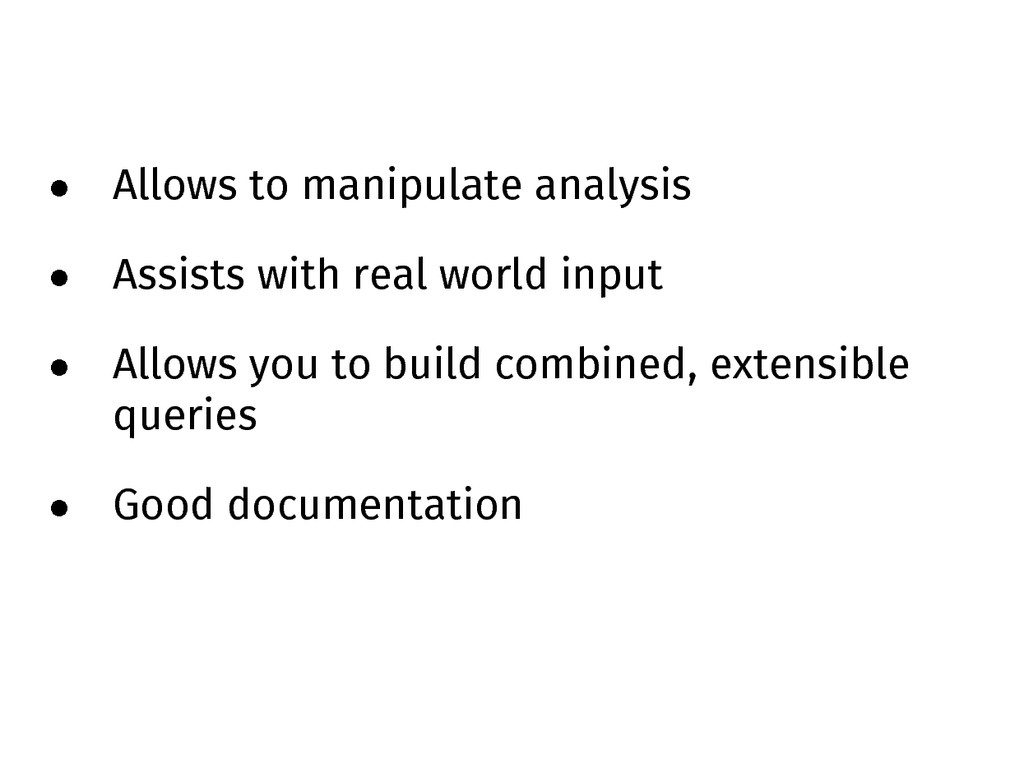
• Allows to manipulate analysis • Assists with real world
input • Allows you to build combined, extensible queries • Good documentation
MongoDB is not fit for purpose with holes that can
only be fixed by careful preparation of that data.
That preparation needs lots of detail knowledge you probably don’t
want to aquire.
PostgreSQL is adequate and in the PostgreSQL tradition of stable,
well-documented features. It doesn’t win prices, but is workable and reliable.
A good solution if search is just a bystander. A
thousand times better than LIKE.
Elasticsearch is based on Lucene and comes with all the
goodies and also has great documentations and guides.
If search is at the core of your product, use
a proper search engine.
References on the meetup group tomorrow.
Thank you!
None
COURSES
Elasticsearch for managers: http://esmanagers2014.asquera.de/
None
December 2nd
Getting started workshop: http://purchases.elastic- search.com/class/elasticsearch/elk-work- shop/berlin-germany/2014-12-15
None
December 15th


 skade
 chigichan24
 onozaty
 kosukesaigusa
 steliosf
 vivion
 yukikurage
 cclai999
 naruogram
 drumath2237
 sodainc
 utakaha
 har1101
 codingconduct
 aleyda
 kimpetersen
 katarinadahlin
 thekraken
 helmedeiros
 badams
 aarron
 yeseniaperezcruz
 cassininazir
 rkendrick25