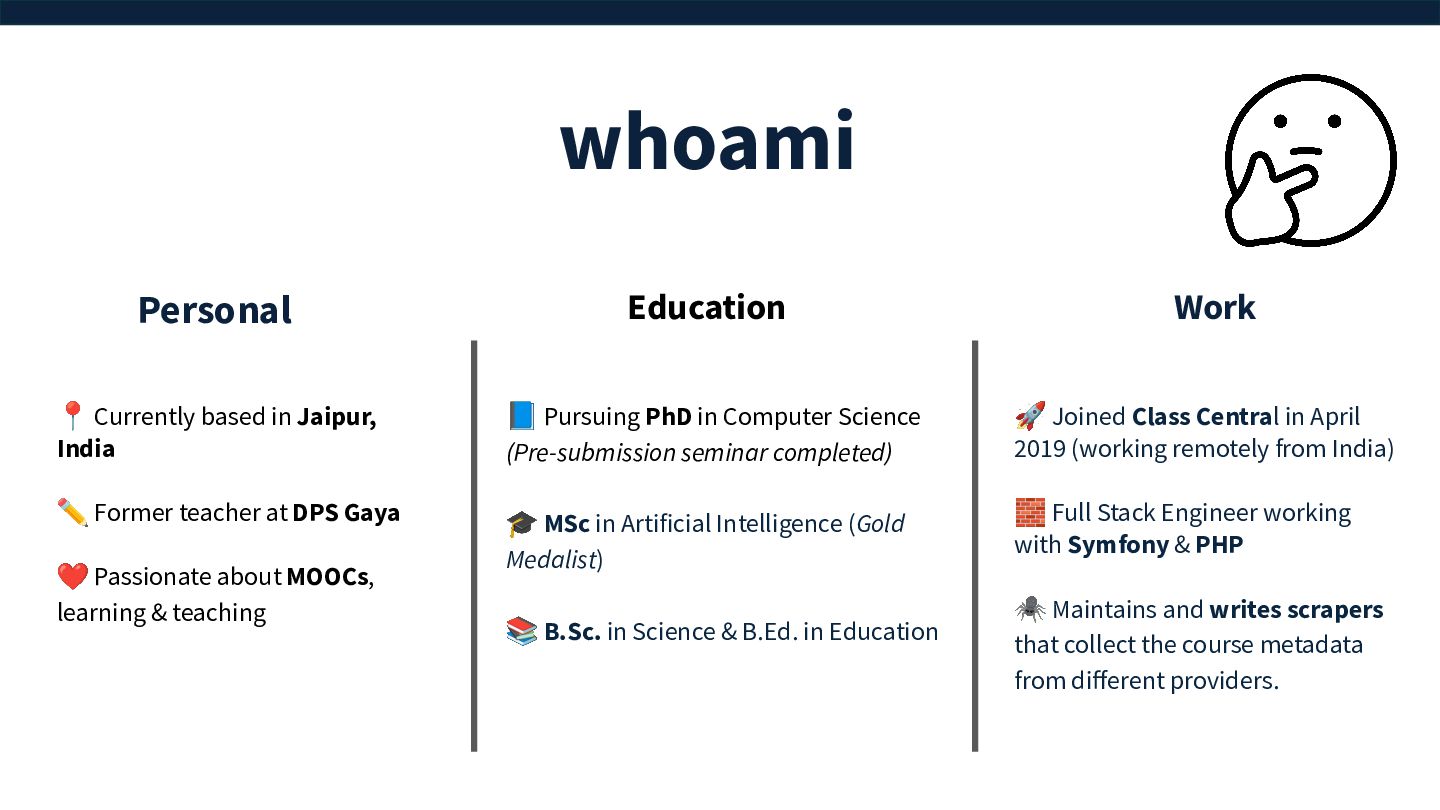
at DPS Gaya ❤ Passionate about MOOCs, learning & teaching Personal Education Work 📘 Pursuing PhD in Computer Science (Pre-submission seminar completed) 🎓 MSc in Artificial Intelligence (Gold Medalist) 📚 B.Sc. in Science & B.Ed. in Education 🚀 Joined Class Central in April 2019 (working remotely from India) 🧱 Full Stack Engineer working with Symfony & PHP 🕷 Maintains and writes scrapers that collect the course metadata from different providers.
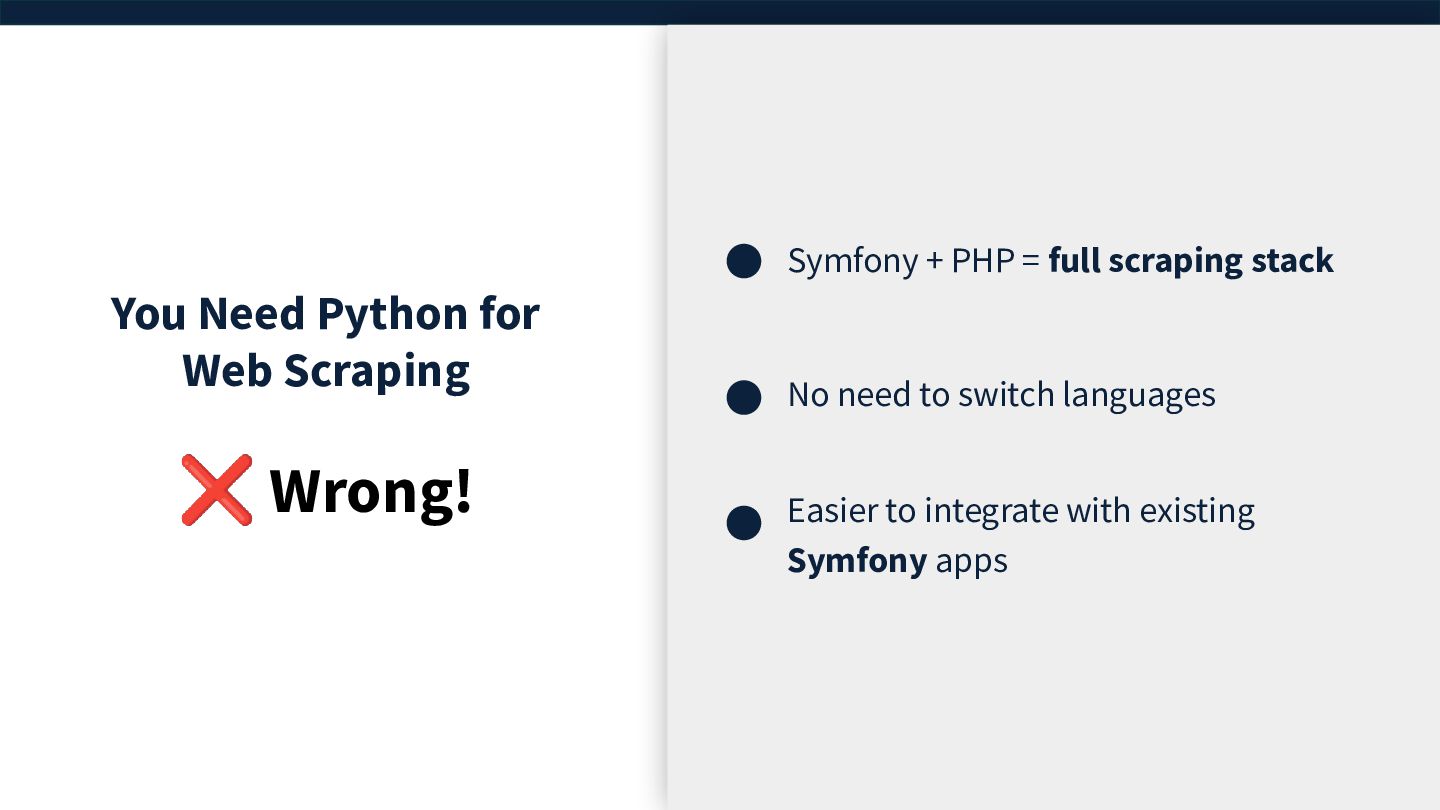
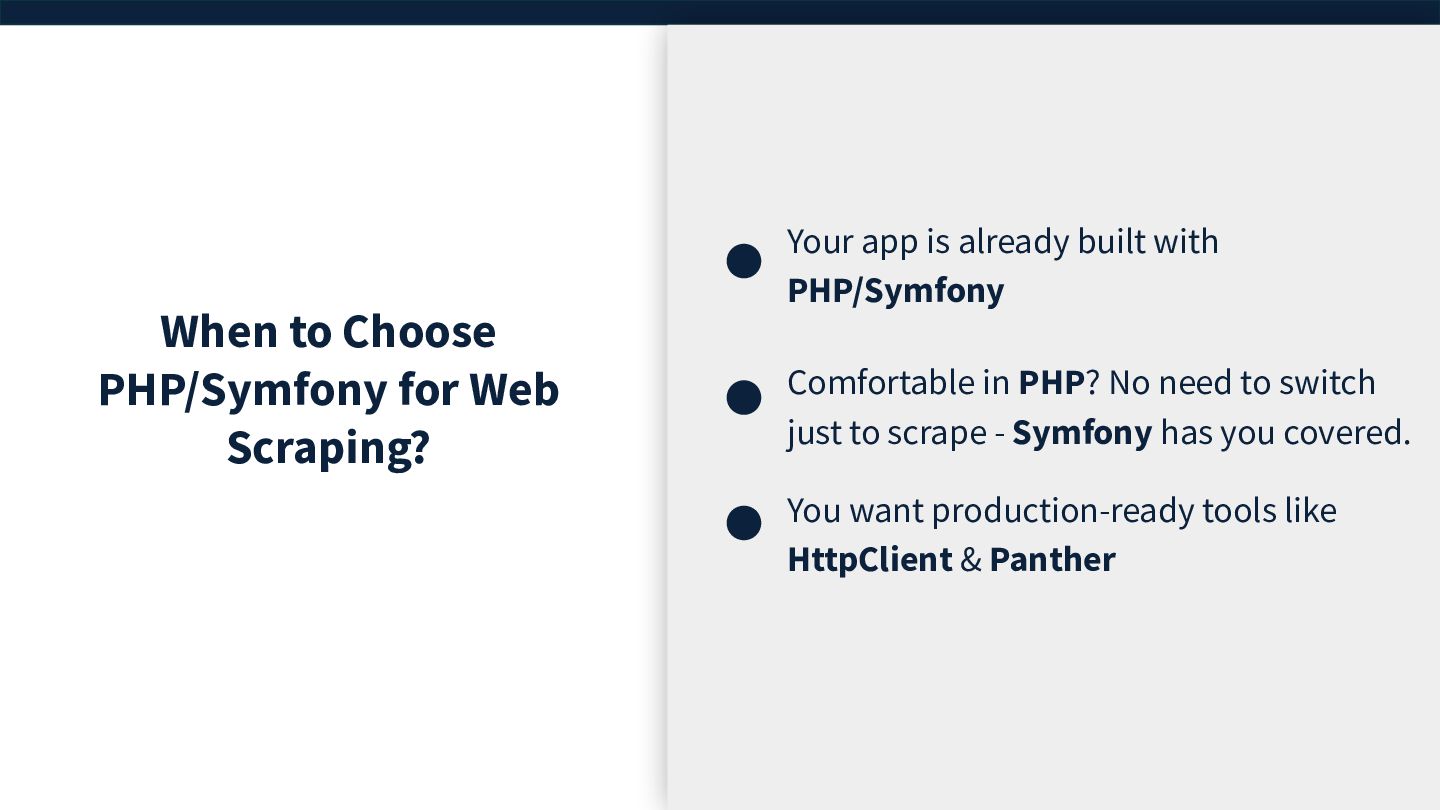
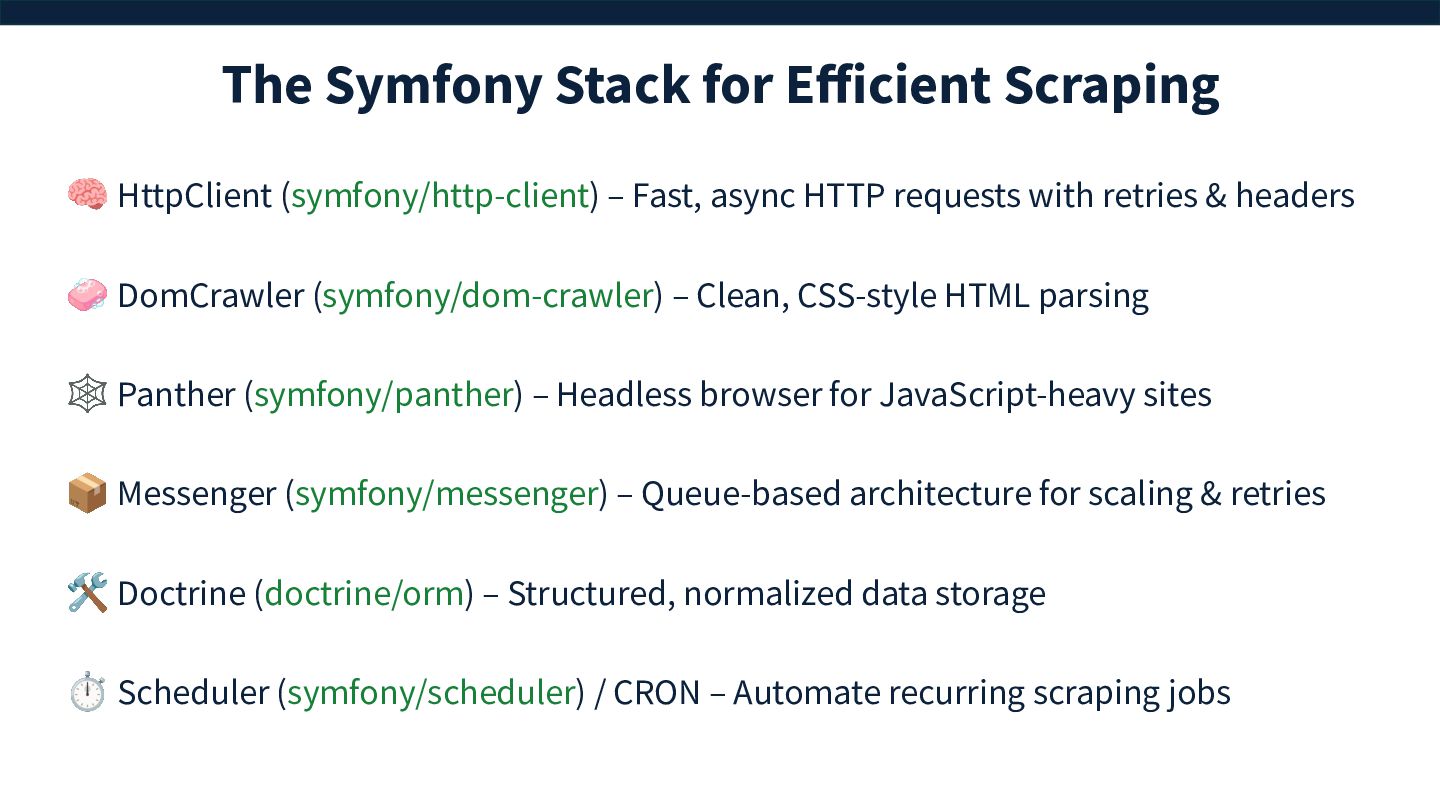
already built with PHP/Symfony Comfortable in PHP? No need to switch just to scrape - Symfony has you covered. You want production-ready tools like HttpClient & Panther
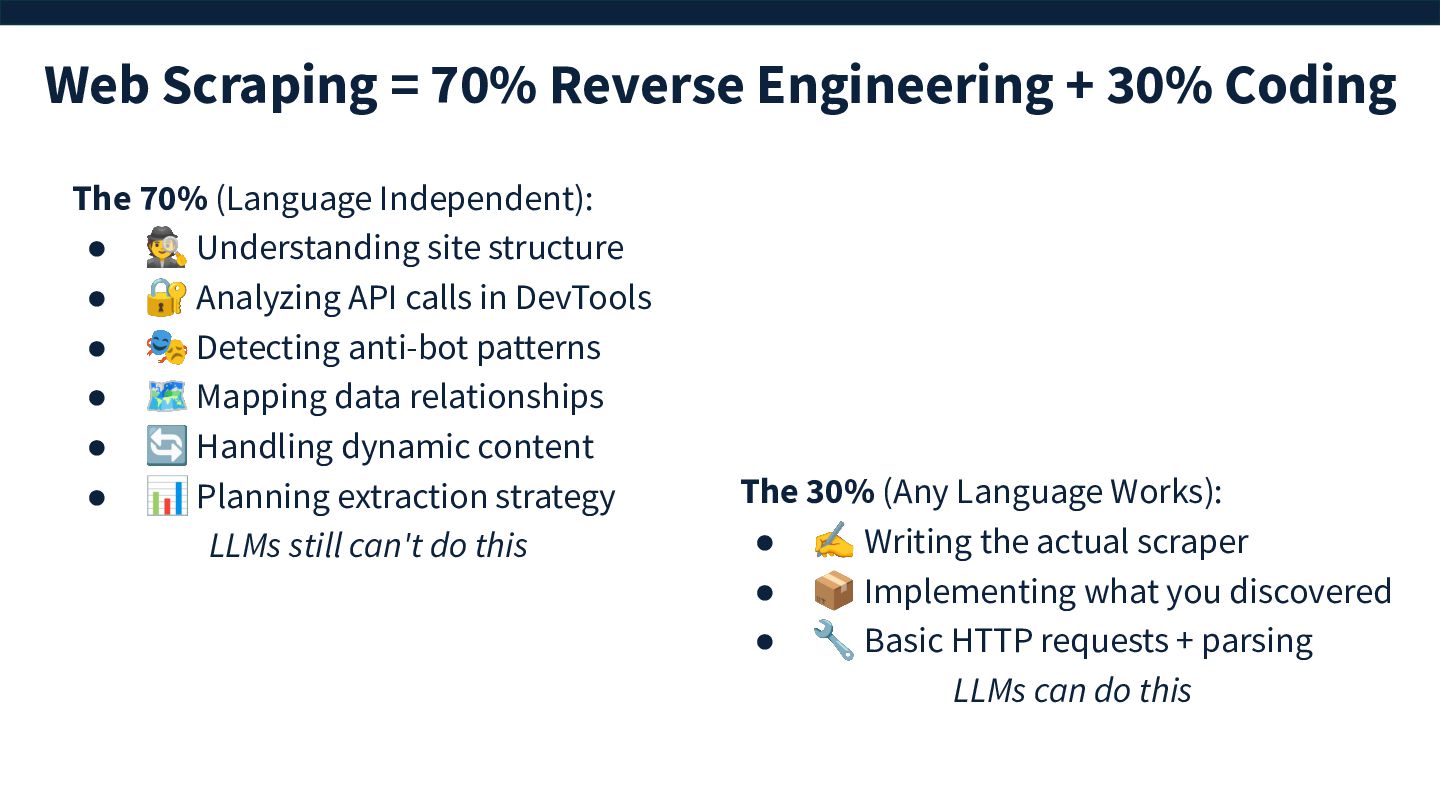
🔐 Analyzing API calls in DevTools • 🎭 Detecting anti-bot patterns • 🗺 Mapping data relationships • 🔄 Handling dynamic content • 📊 Planning extraction strategy LLMs still can't do this Web Scraping = 70% Reverse Engineering + 30% Coding The 30% (Any Language Works): • ✍ Writing the actual scraper • 📦 Implementing what you discovered • 🔧 Basic HTTP requests + parsing LLMs can do this
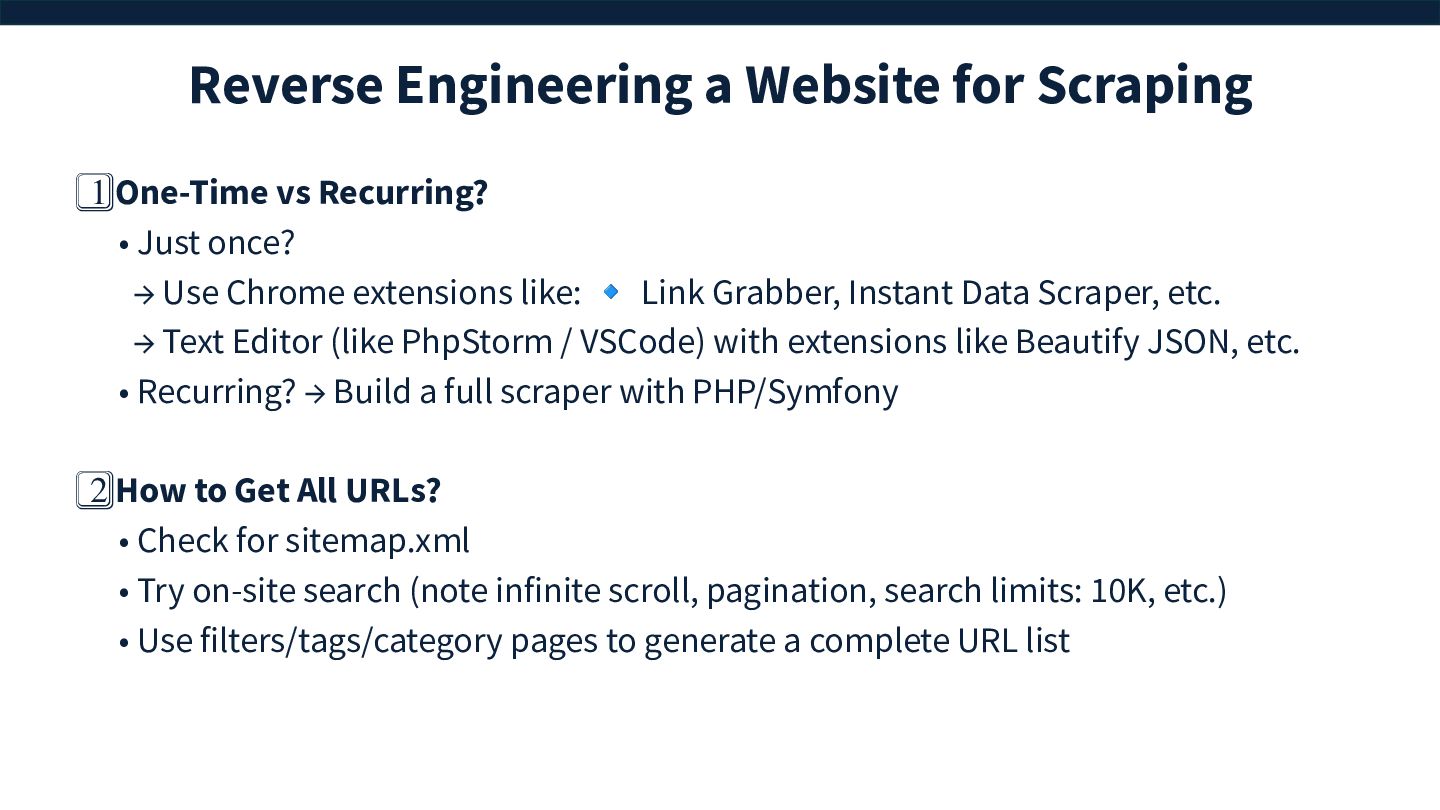
extensions like: 🔹 Link Grabber, Instant Data Scraper, etc. → Text Editor (like PhpStorm / VSCode) with extensions like Beautify JSON, etc. • Recurring? → Build a full scraper with PHP/Symfony 2⃣ How to Get All URLs? • Check for sitemap.xml • Try on-site search (note infinite scroll, pagination, search limits: 10K, etc.) • Use filters/tags/category pages to generate a complete URL list Reverse Engineering a Website for Scraping
or anti-bot services? • Look for honeypot links, trap fields in forms • Do they block unknown user-agents or IPs? 4⃣ Check Rate Limits & Behaviors • How many pages before throttling or blocking? • Test with different delays, headers, and user-agents • Use browser dev tools to simulate real user interaction Reverse Engineering a Website for Scraping (Contd.)
Strategy Accordingly • Headless browser needed (Panther)? • How to rotate IPs and user-agents? • Is it worth caching/storing intermediate HTML? • What retry and backoff strategy will you use? • How often will scraping run — once or recurring? • How will you detect and avoid bot traps or honeypots?
requests with headers • 🌀 cURL – Advanced requests, cookies, proxies, redirects, and POST handling • 🔄 curl_multi_* – Perform asynchronous/multi-threaded scraping • 🎭 Custom headers, user-agents, timeouts, and cookies supported The Core PHP Stack for Web Scraping
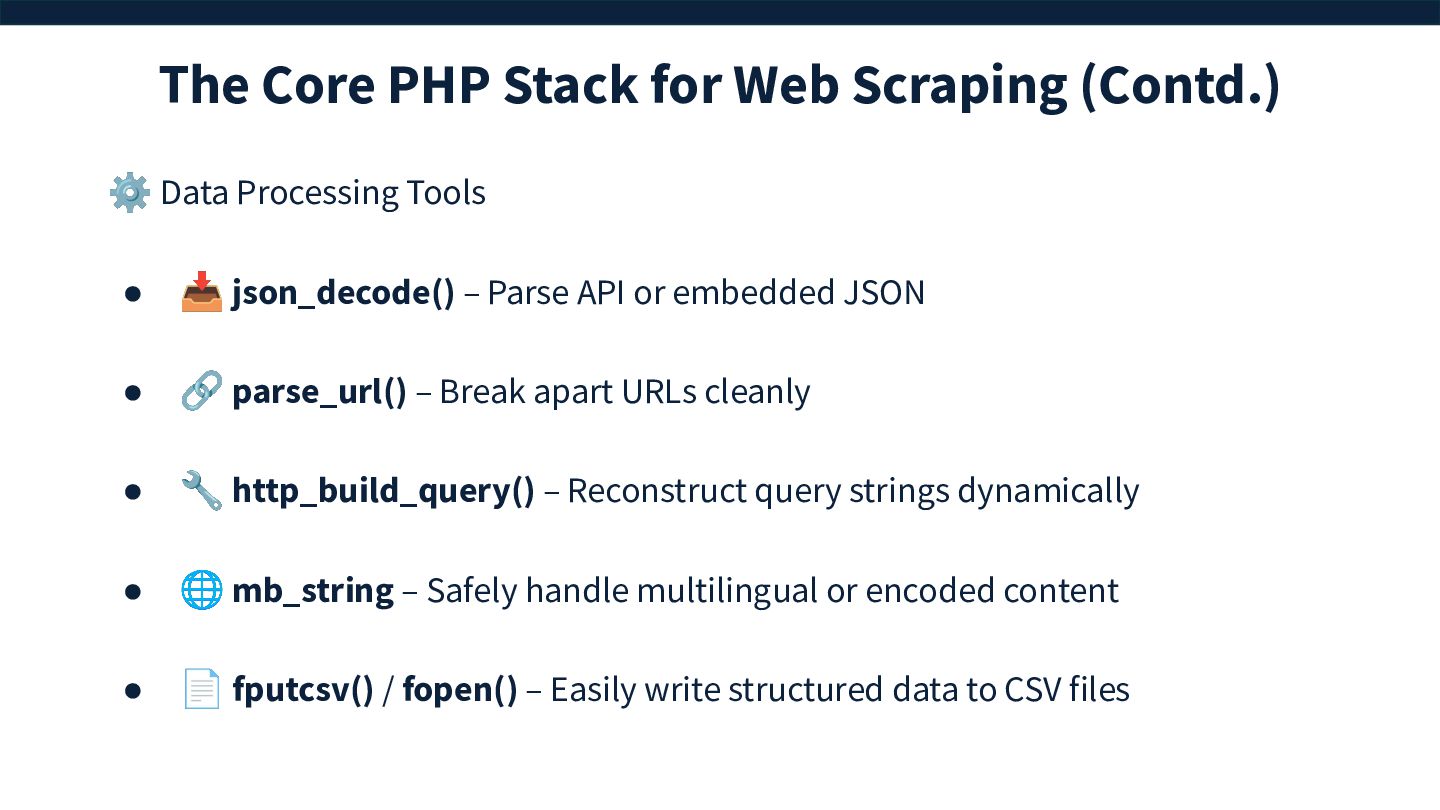
parsing • 🔎 DOMXPath – CSS-like, precise element querying • 📦 SimpleXML – Clean parsing for XML/RSS feeds • 🧵 preg_match() / preg_match_all() – When regex is the best tool for the job The Core PHP Stack for Web Scraping (Contd.)
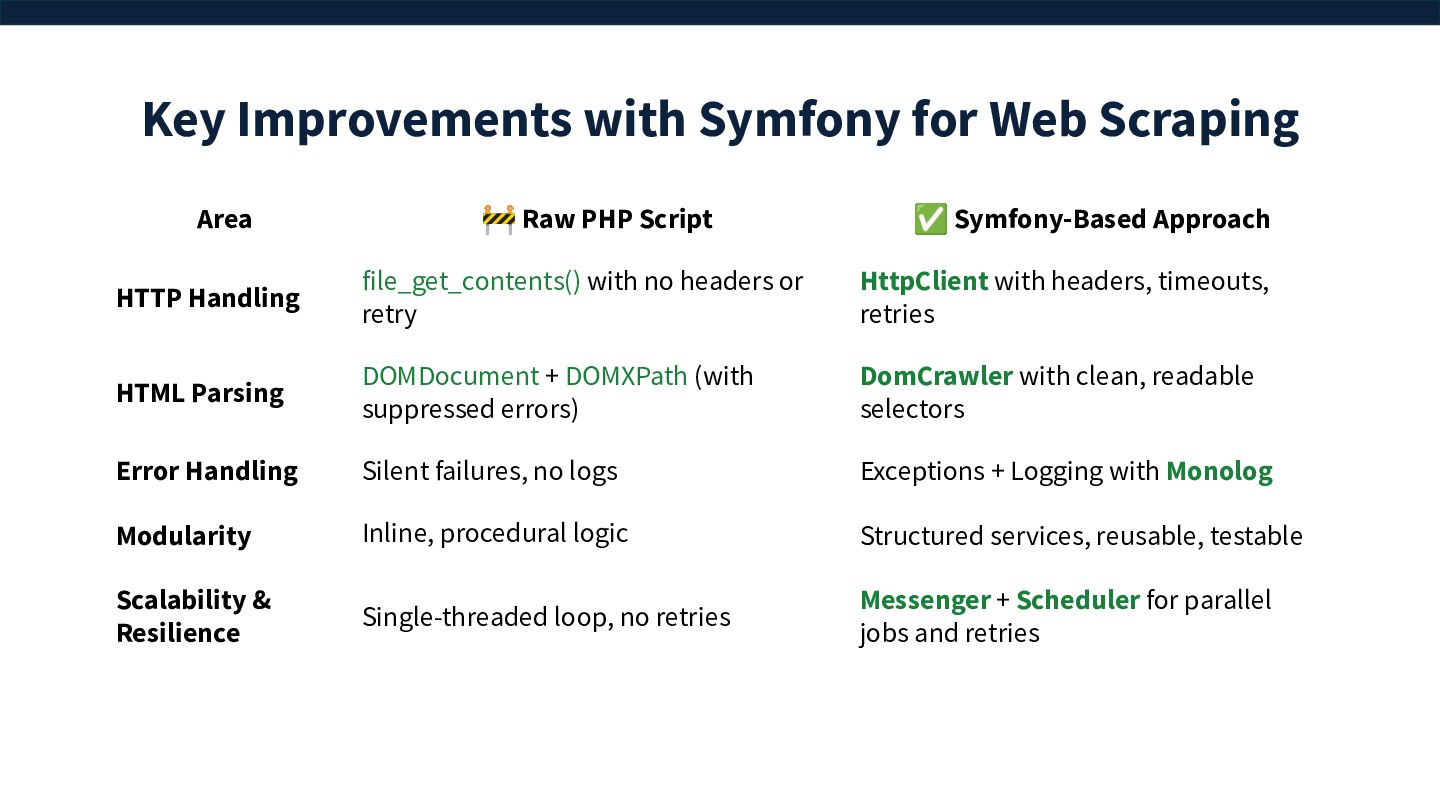
file_get_contents() with no headers or retry HttpClient with headers, timeouts, retries HTML Parsing DOMDocument + DOMXPath (with suppressed errors) DomCrawler with clean, readable selectors Error Handling Silent failures, no logs Exceptions + Logging with Monolog Modularity Inline, procedural logic Structured services, reusable, testable Scalability & Resilience Single-threaded loop, no retries Messenger + Scheduler for parallel jobs and retries Key Improvements with Symfony for Web Scraping
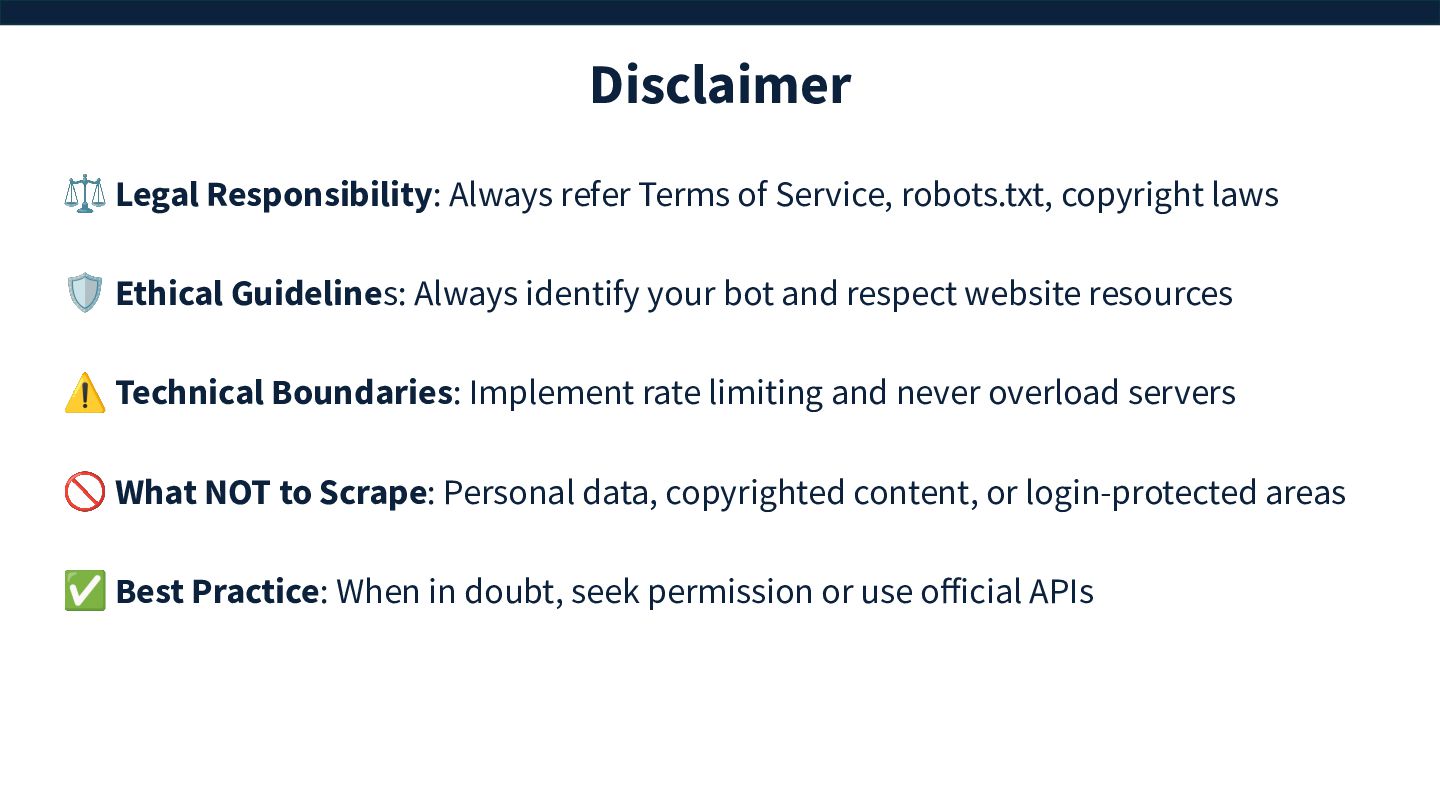
laws 🛡 Ethical Guidelines: Always identify your bot and respect website resources ⚠ Technical Boundaries: Implement rate limiting and never overload servers 🚫 What NOT to Scrape: Personal data, copyrighted content, or login-protected areas ✅ Best Practice: When in doubt, seek permission or use official APIs Disclaimer


 signer
 naochim2026
 eller86
 pawan_pharm
 suisan
 bvr7352
 hiola
 yoshimura_datam
 uranoken
 juanmartin2026
 auctria
 auna
 helmedeiros
 thirion
 reverentgeek
 deanohume
 soudai
 jonoalderson
 palkan
 skoyamalab
 trallard
 keithpitt
 axbom