Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Backlink Indexing Service Checklist for Tier-2 ...

Backlink Indexing Service Checklist for Tier-2 T3 PBN

"The homepage is indexed. Why is the money link still a ghost? This PDF is the field checklist behind a backlink indexing service workflow for Tier-2, Tier-3, and PBN posts: pre-flight headers, bottom-up URL order, drip-feed windows, and Day-7 error codes. It is written for link builders who already bought placements and need Google to store the href-bearing URL, not the vanity homepage. Use it with drip-feed indexing, a bulk index checker pass, and Pay-per-Result refunds on URLs that do not store. Process only — Google still decides indexation.

Backlink Indexing Service: https://en.speedyindex.com/

Author: Linda Bjorkvin, Project Manager, SpeedyIndex.
Tokens are deducted only for indexed URLs (100 tokens each).
Google report on Day 7, Yandex on Day 15.
No GSC verification required for third-party donors.

Avatar for Linda Bjorkvin

Linda Bjorkvin PRO

September 19, 2026

More Decks by Linda Bjorkvin

Other Decks in Marketing & SEO

Transcript

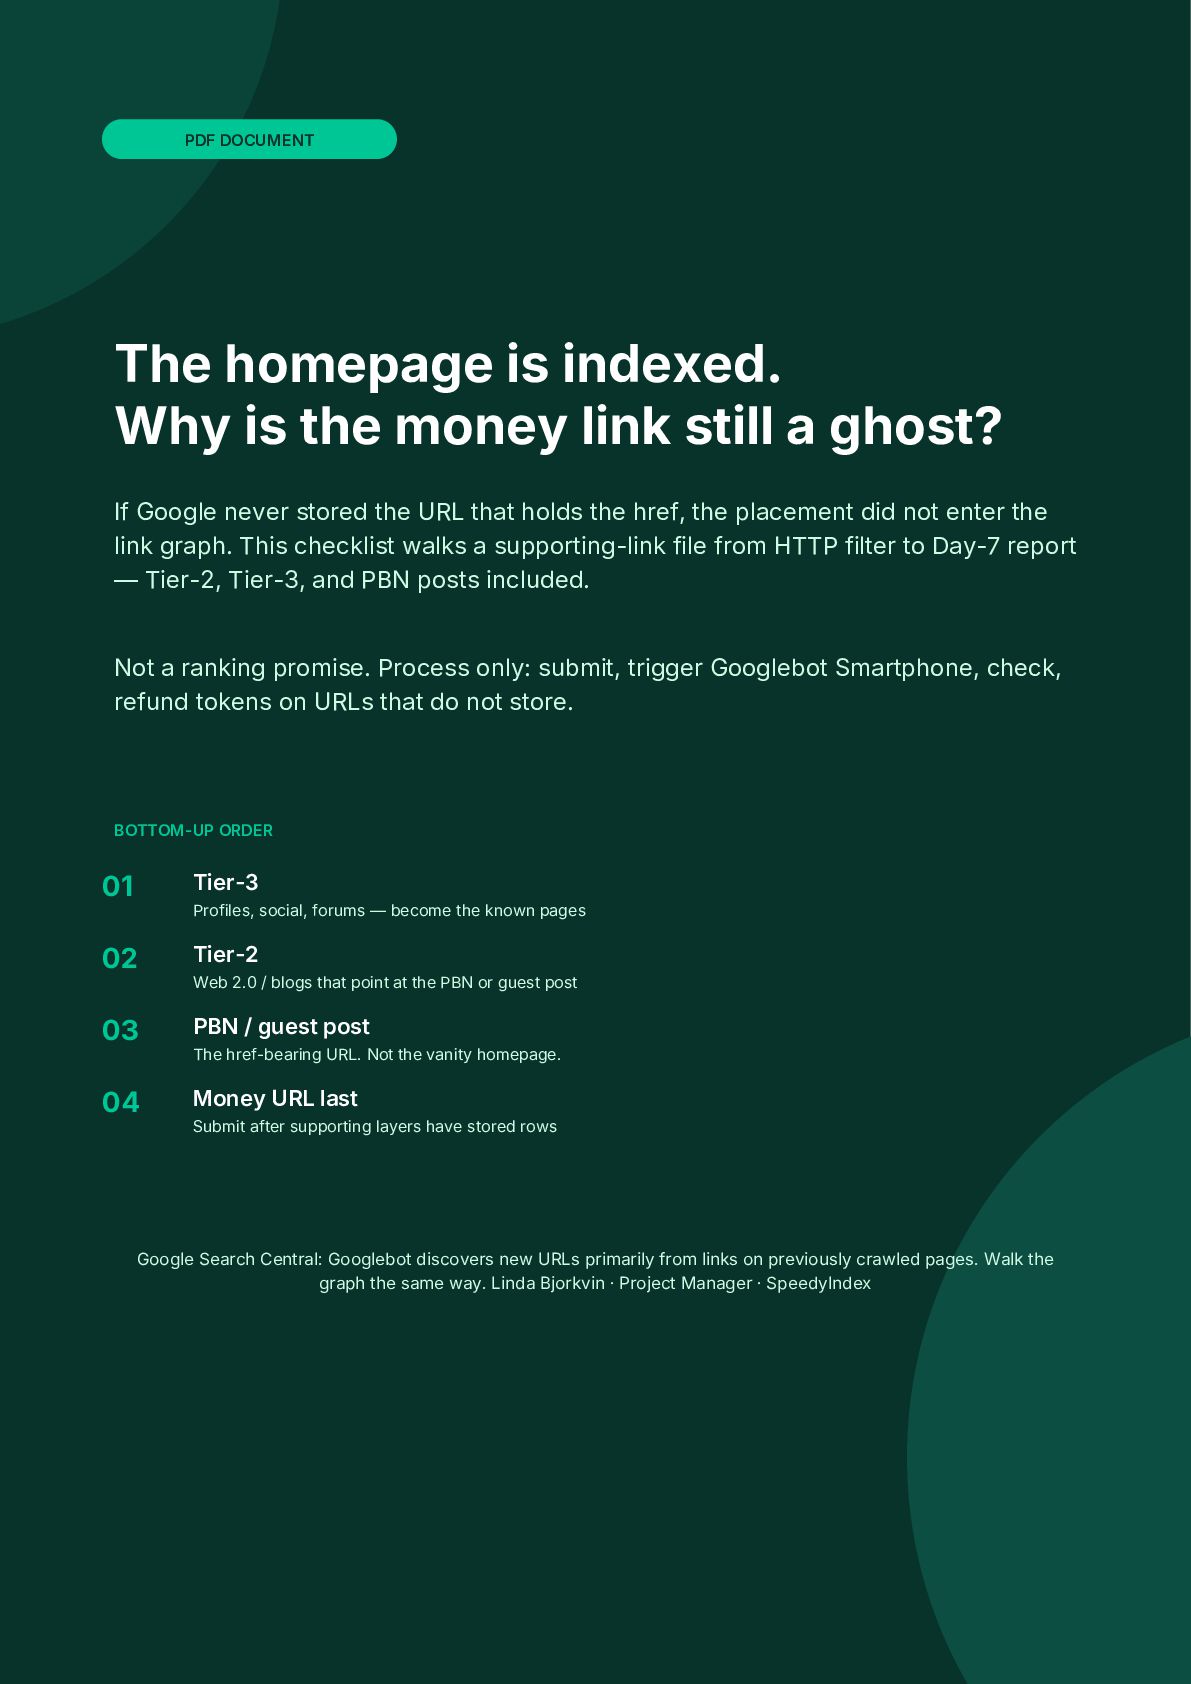
  1. PDF DOCUMENT The homepage is indexed. Why is the money

    link still a ghost? If Google never stored the URL that holds the href, the placement did not enter the link graph. This checklist walks a supporting-link file from HTTP filter to Day-7 report — Tier-2, Tier-3, and PBN posts included. Not a ranking promise. Process only: submit, trigger Googlebot Smartphone, check, refund tokens on URLs that do not store. BOTTOM-UP ORDER 01 Tier-3 02 Tier-2 03 PBN / guest post 04 Money URL last Profiles, social, forums — become the known pages Web 2.0 / blogs that point at the PBN or guest post The href-bearing URL. Not the vanity homepage. Submit after supporting layers have stored rows Google Search Central: Googlebot discovers new URLs primarily from links on previously crawled pages. Walk the graph the same way. Linda Bjorkvin · Project Manager · SpeedyIndex
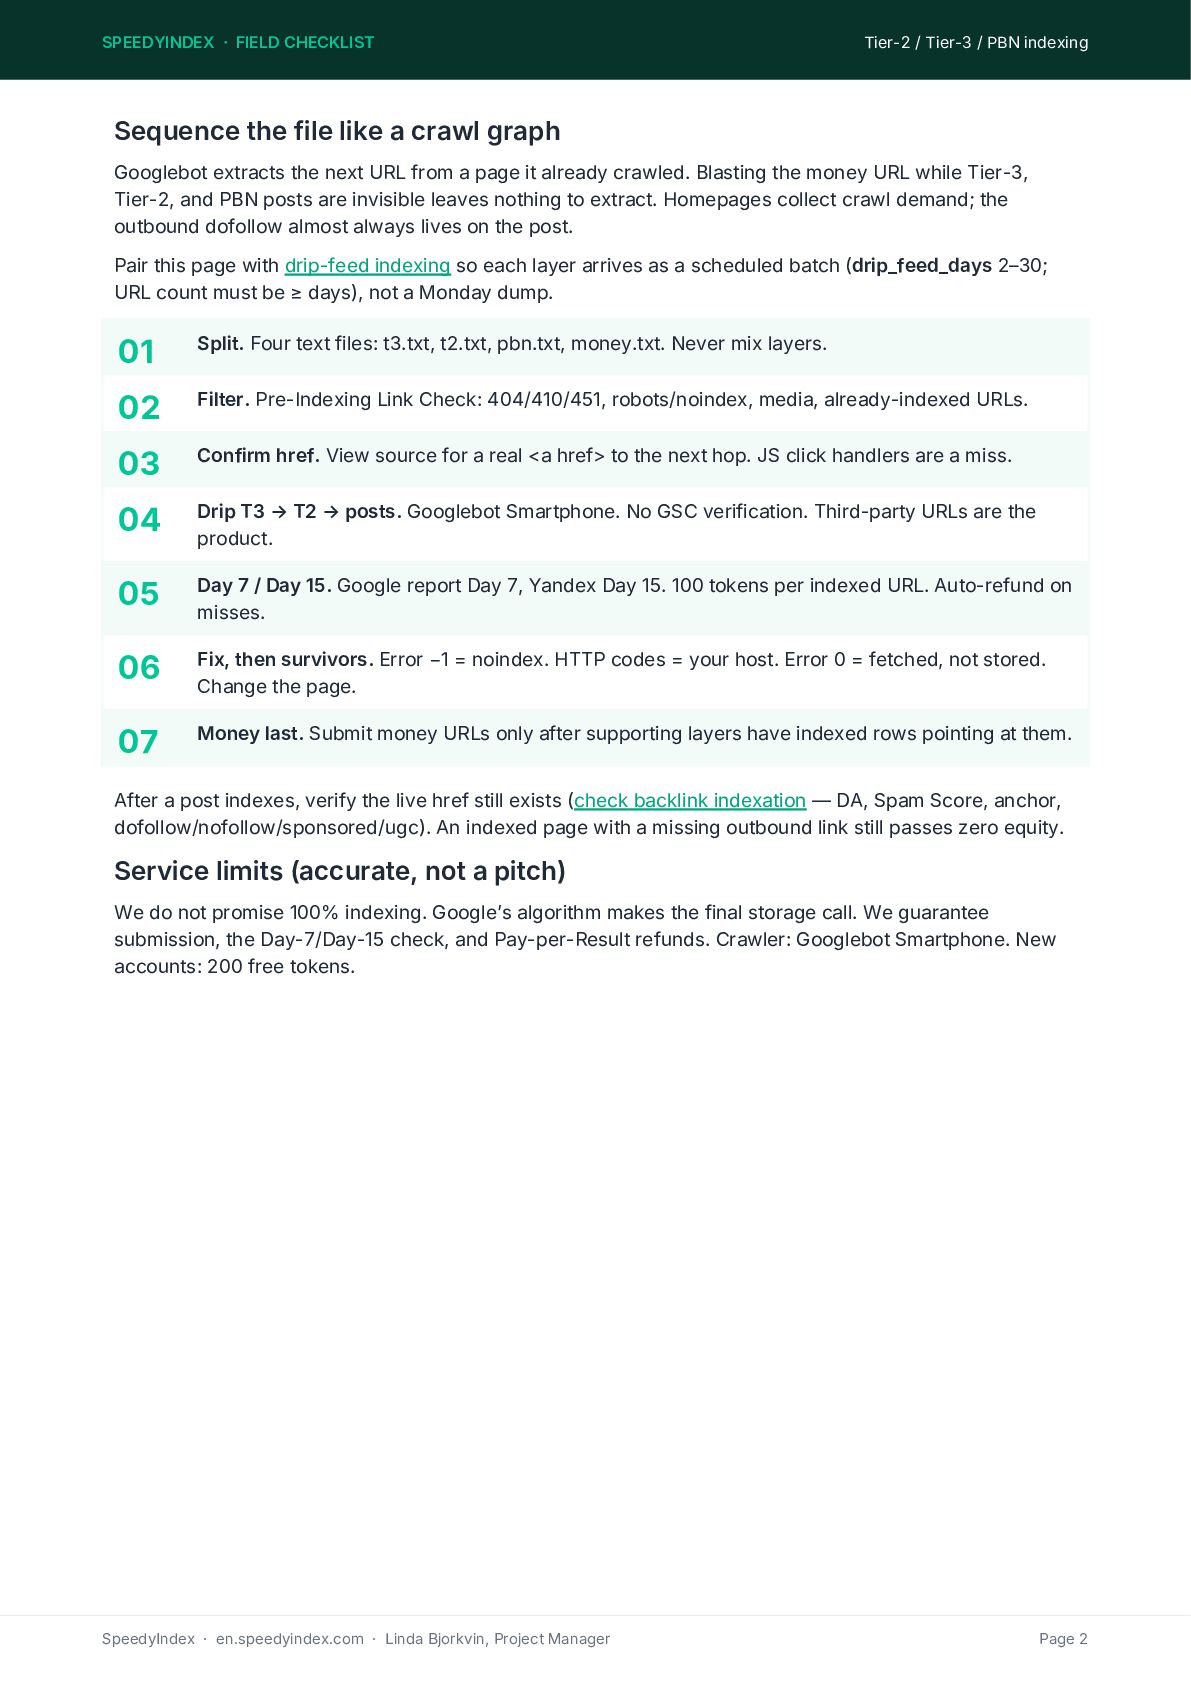
  2. SPEEDYINDEX · FIELD CHECKLIST Tier-2 / Tier-3 / PBN indexing

    Sequence the file like a crawl graph Googlebot extracts the next URL from a page it already crawled. Blasting the money URL while Tier-3, Tier-2, and PBN posts are invisible leaves nothing to extract. Homepages collect crawl demand; the outbound dofollow almost always lives on the post. Pair this page with drip-feed indexing so each layer arrives as a scheduled batch (drip_feed_days 2–30; URL count must be ≥ days), not a Monday dump. 01 Split. Four text files: t3.txt, t2.txt, pbn.txt, money.txt. Never mix layers. 02 Filter. Pre-Indexing Link Check: 404/410/451, robots/noindex, media, already-indexed URLs. 03 Confirm href. View source for a real <a href> to the next hop. JS click handlers are a miss. 04 Drip T3 → T2 → posts. Googlebot Smartphone. No GSC verification. Third-party URLs are the product. 05 Day 7 / Day 15. Google report Day 7, Yandex Day 15. 100 tokens per indexed URL. Auto-refund on misses. 06 Fix, then survivors. Error −1 = noindex. HTTP codes = your host. Error 0 = fetched, not stored. Change the page. 07 Money last. Submit money URLs only after supporting layers have indexed rows pointing at them. After a post indexes, verify the live href still exists (check backlink indexation — DA, Spam Score, anchor, dofollow/nofollow/sponsored/ugc). An indexed page with a missing outbound link still passes zero equity. Service limits (accurate, not a pitch) We do not promise 100% indexing. Google’s algorithm makes the final storage call. We guarantee submission, the Day-7/Day-15 check, and Pay-per-Result refunds. Crawler: Googlebot Smartphone. New accounts: 200 free tokens. SpeedyIndex · en.speedyindex.com · Linda Bjorkvin, Project Manager Page 2
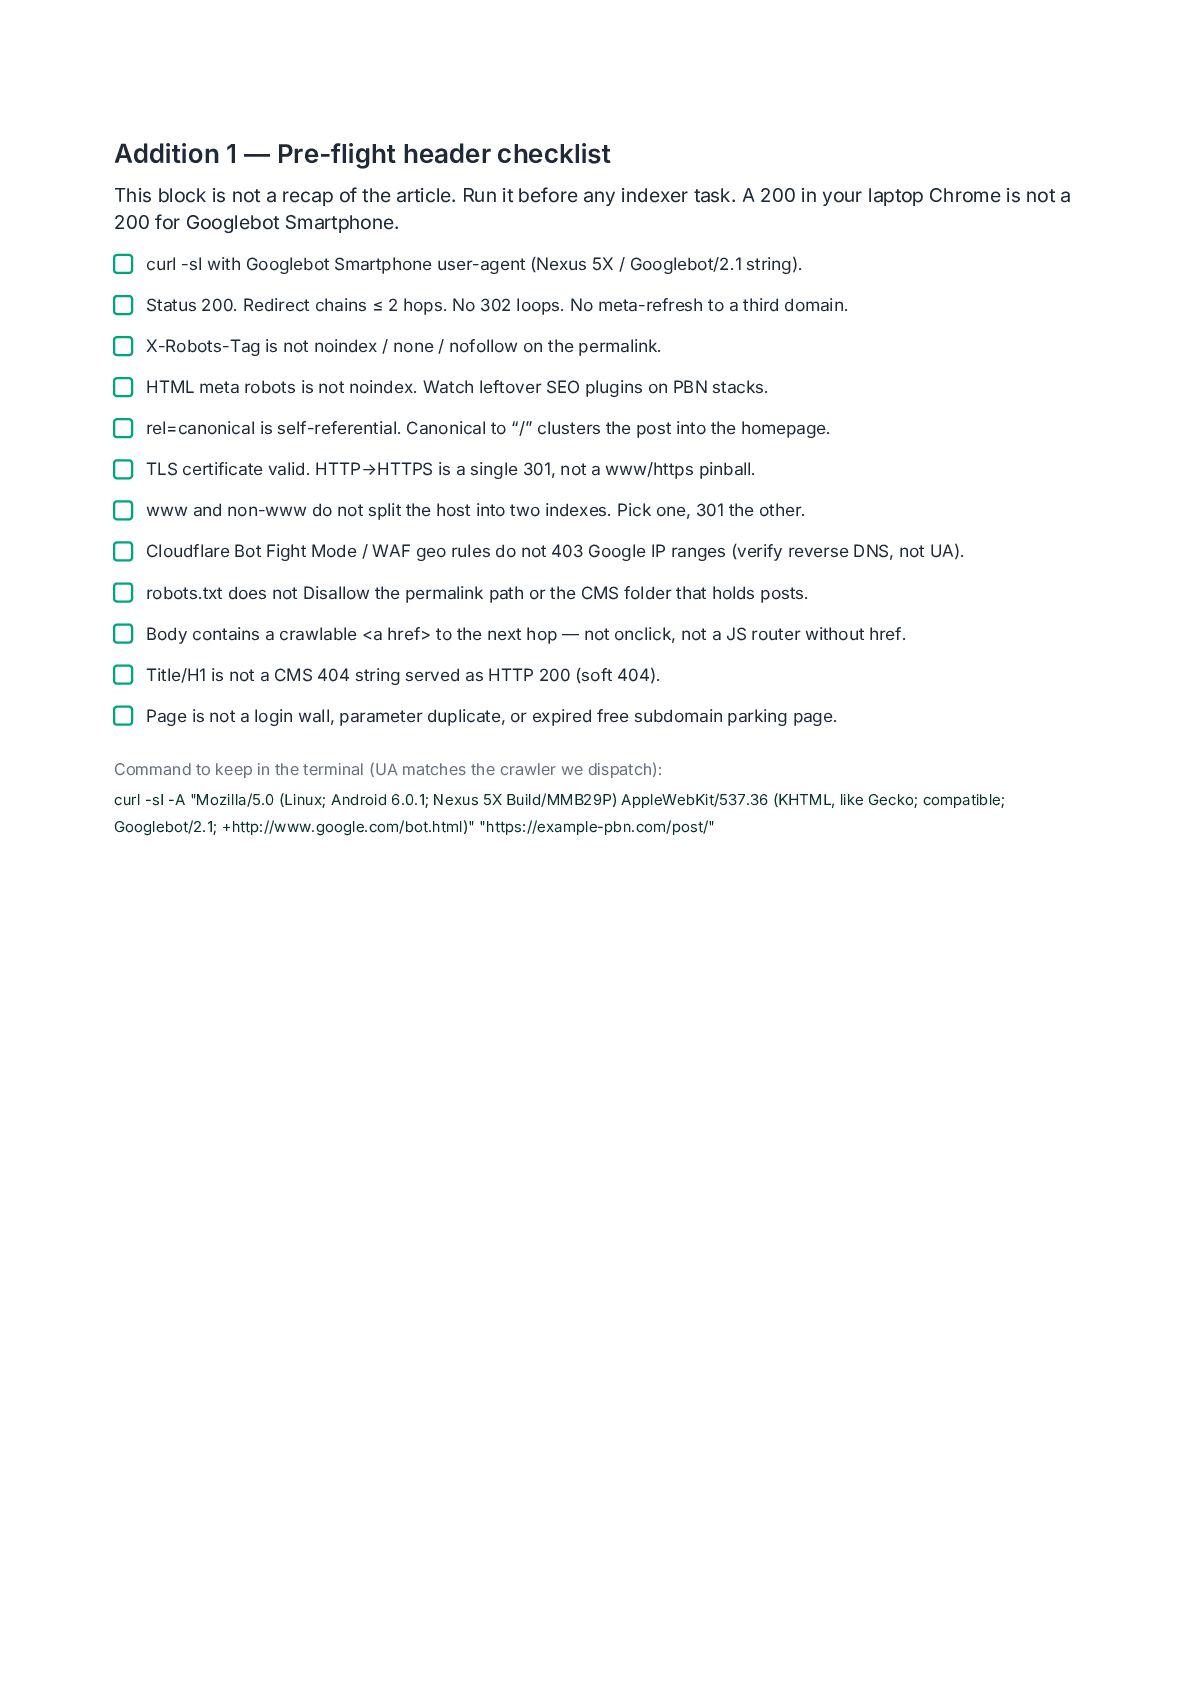
  3. Addition 1 — Pre-flight header checklist This block is not

    a recap of the article. Run it before any indexer task. A 200 in your laptop Chrome is not a 200 for Googlebot Smartphone. curl -sI with Googlebot Smartphone user-agent (Nexus 5X / Googlebot/2.1 string). Status 200. Redirect chains ≤ 2 hops. No 302 loops. No meta-refresh to a third domain. X-Robots-Tag is not noindex / none / nofollow on the permalink. HTML meta robots is not noindex. Watch leftover SEO plugins on PBN stacks. rel=canonical is self-referential. Canonical to “/” clusters the post into the homepage. TLS certificate valid. HTTP→HTTPS is a single 301, not a www/https pinball. www and non-www do not split the host into two indexes. Pick one, 301 the other. Cloudflare Bot Fight Mode / WAF geo rules do not 403 Google IP ranges (verify reverse DNS, not UA). robots.txt does not Disallow the permalink path or the CMS folder that holds posts. Body contains a crawlable <a href> to the next hop — not onclick, not a JS router without href. Title/H1 is not a CMS 404 string served as HTTP 200 (soft 404). Page is not a login wall, parameter duplicate, or expired free subdomain parking page. Command to keep in the terminal (UA matches the crawler we dispatch): curl -sI -A "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko; compatible; Googlebot/2.1; +http://www.google.com/bot.html)" "https://example-pbn.com/post/"
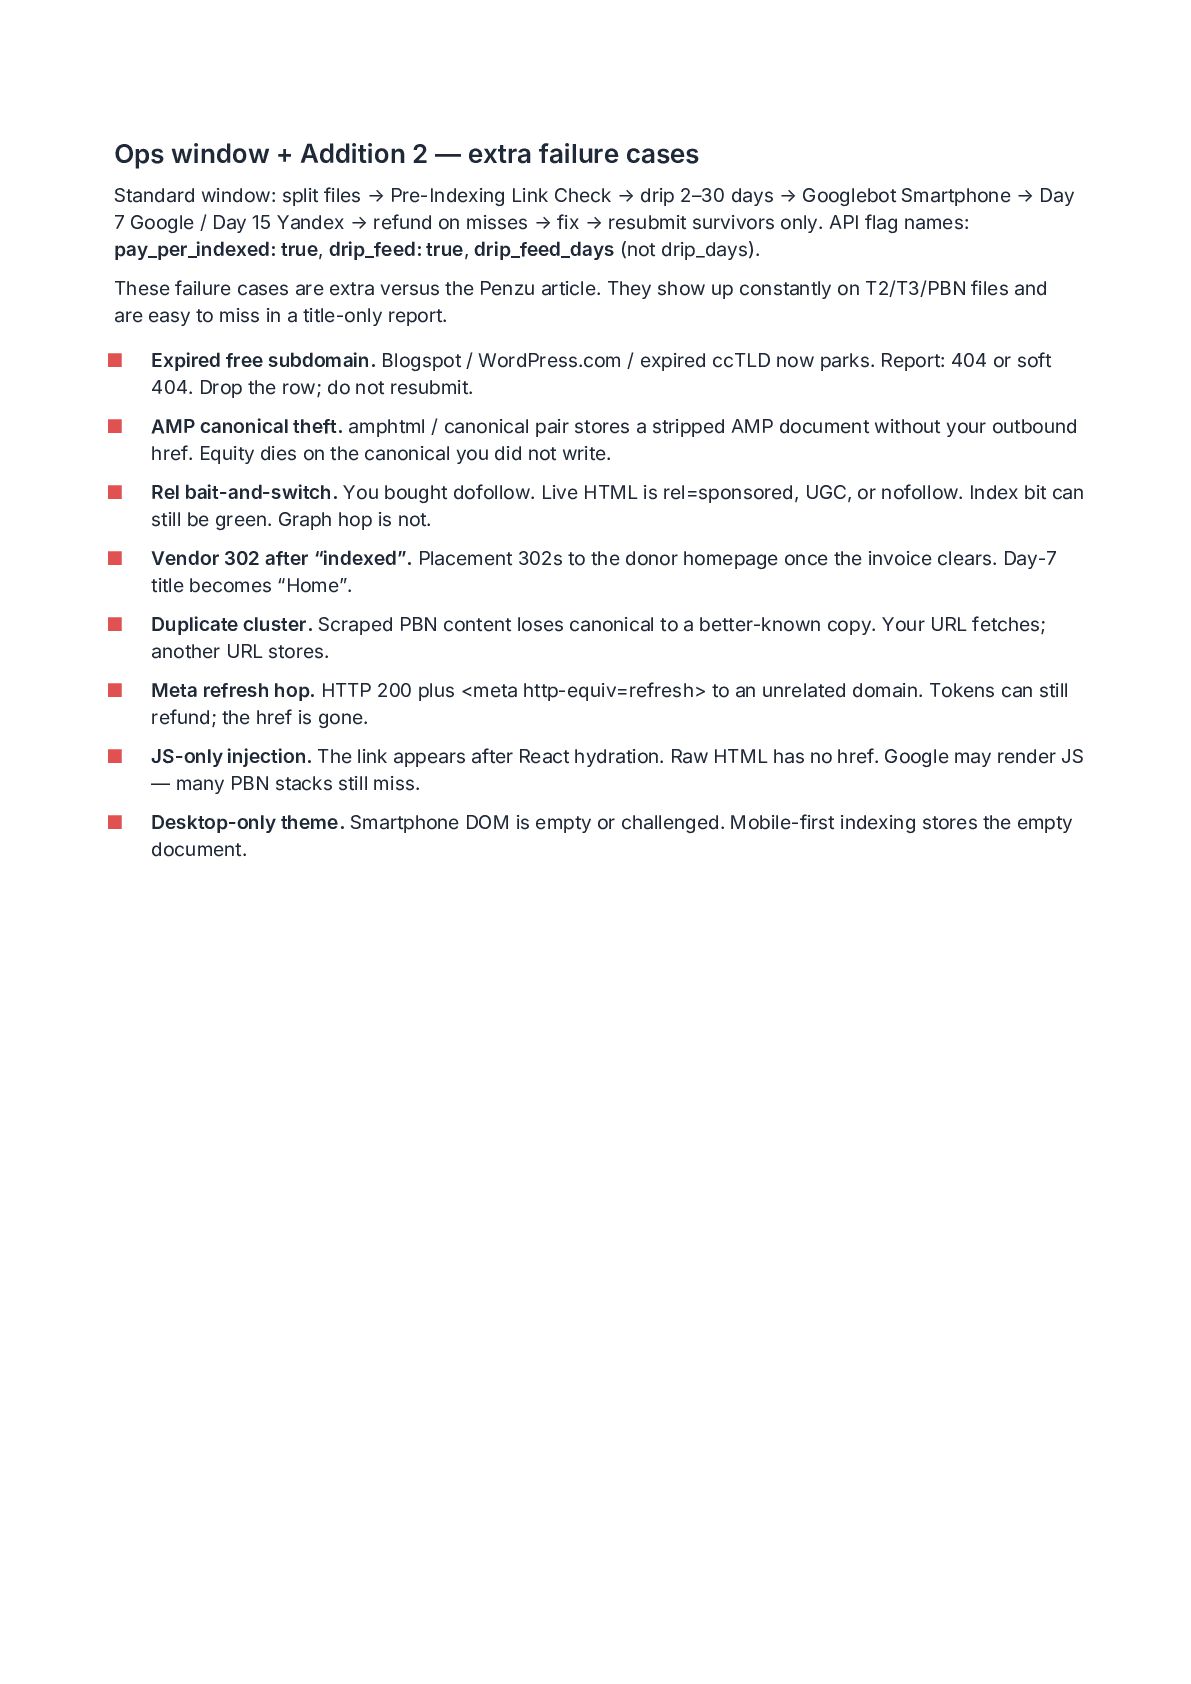
  4. Ops window + Addition 2 — extra failure cases Standard

    window: split files → Pre-Indexing Link Check → drip 2–30 days → Googlebot Smartphone → Day 7 Google / Day 15 Yandex → refund on misses → fix → resubmit survivors only. API flag names: pay_per_indexed: true, drip_feed: true, drip_feed_days (not drip_days). These failure cases are extra versus the Penzu article. They show up constantly on T2/T3/PBN files and are easy to miss in a title-only report. ▪ Expired free subdomain. Blogspot / WordPress.com / expired ccTLD now parks. Report: 404 or soft 404. Drop the row; do not resubmit. ▪ AMP canonical theft. amphtml / canonical pair stores a stripped AMP document without your outbound href. Equity dies on the canonical you did not write. ▪ Rel bait-and-switch. You bought dofollow. Live HTML is rel=sponsored, UGC, or nofollow. Index bit can still be green. Graph hop is not. ▪ Vendor 302 after “indexed”. Placement 302s to the donor homepage once the invoice clears. Day-7 title becomes “Home”. ▪ Duplicate cluster. Scraped PBN content loses canonical to a better-known copy. Your URL fetches; another URL stores. ▪ Meta refresh hop. HTTP 200 plus <meta http-equiv=refresh> to an unrelated domain. Tokens can still refund; the href is gone. ▪ JS-only injection. The link appears after React hydration. Raw HTML has no href. Google may render JS — many PBN stacks still miss. ▪ Desktop-only theme. Smartphone DOM is empty or challenged. Mobile-first indexing stores the empty document.
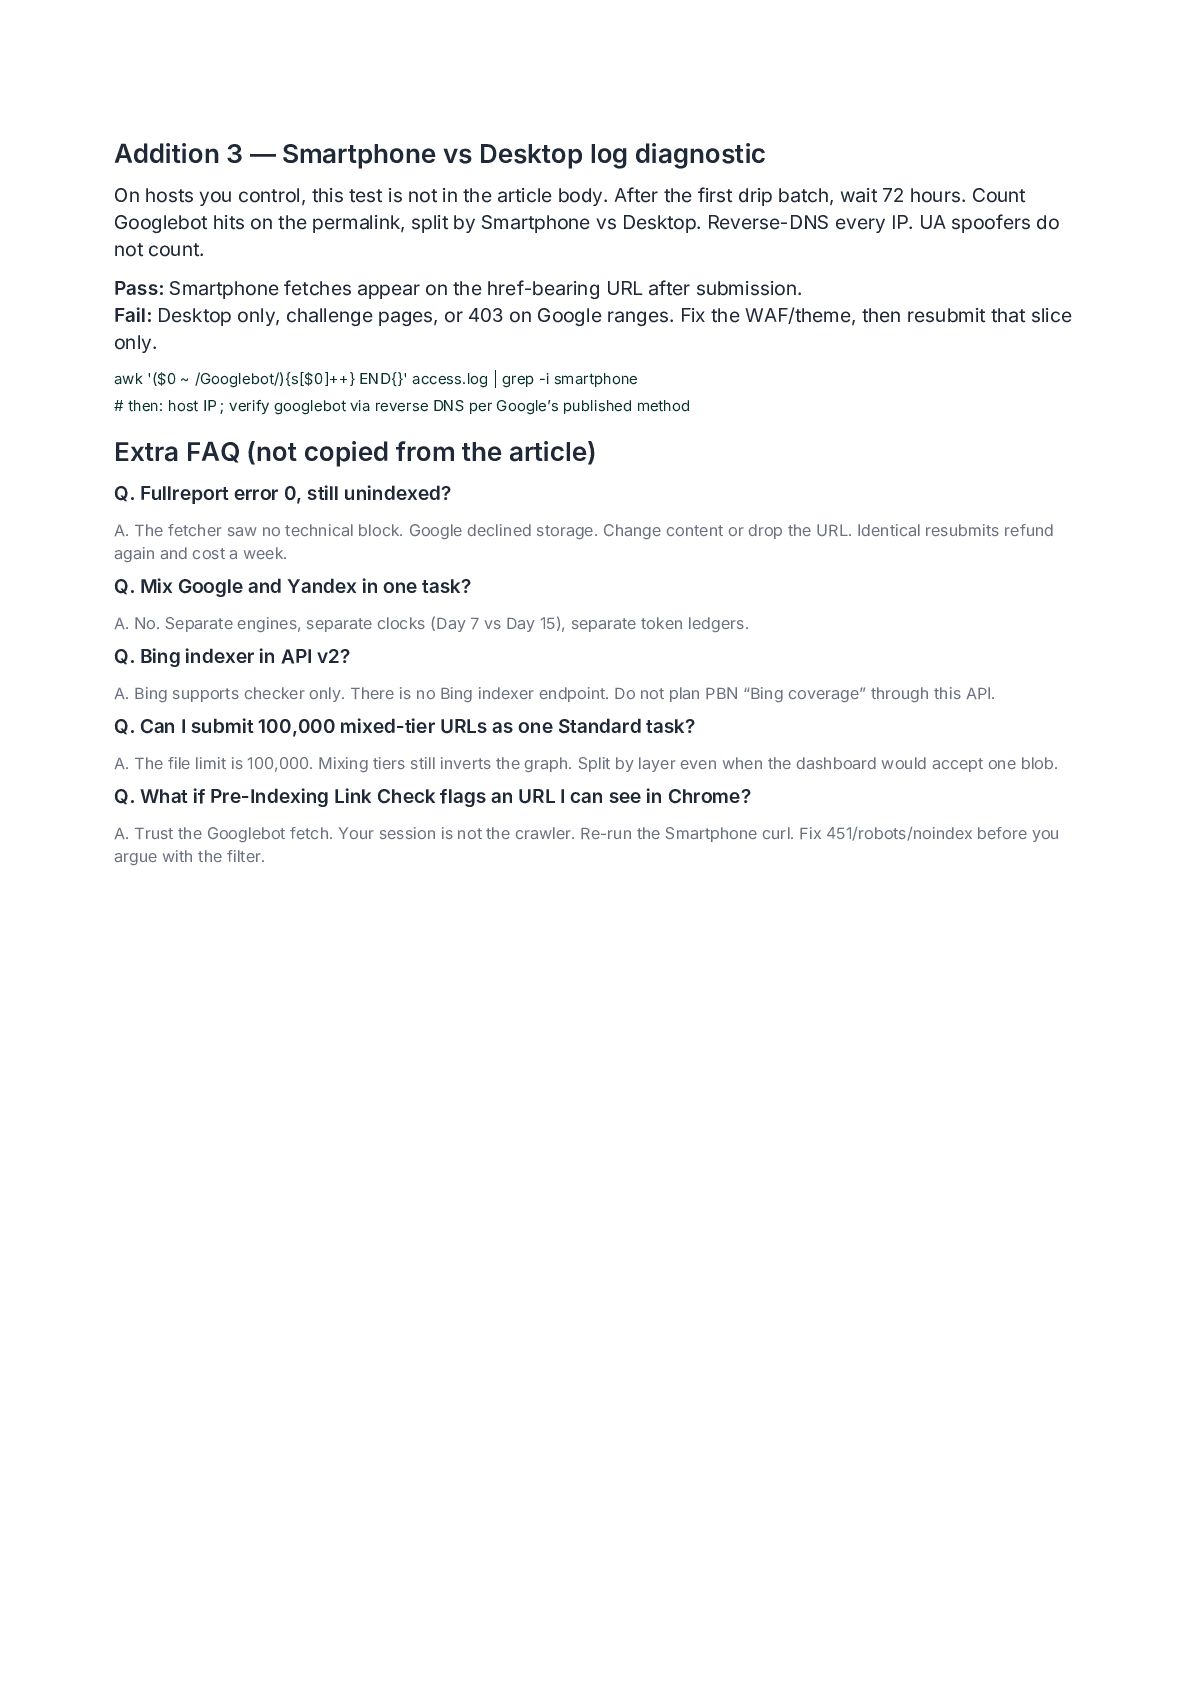
  5. Addition 3 — Smartphone vs Desktop log diagnostic On hosts

    you control, this test is not in the article body. After the first drip batch, wait 72 hours. Count Googlebot hits on the permalink, split by Smartphone vs Desktop. Reverse-DNS every IP. UA spoofers do not count. Pass: Smartphone fetches appear on the href-bearing URL after submission. Fail: Desktop only, challenge pages, or 403 on Google ranges. Fix the WAF/theme, then resubmit that slice only. awk '($0 ~ /Googlebot/){s[$0]++} END{}' access.log | grep -i smartphone # then: host IP ; verify googlebot via reverse DNS per Google’s published method Extra FAQ (not copied from the article) Q. Fullreport error 0, still unindexed? A. The fetcher saw no technical block. Google declined storage. Change content or drop the URL. Identical resubmits refund again and cost a week. Q. Mix Google and Yandex in one task? A. No. Separate engines, separate clocks (Day 7 vs Day 15), separate token ledgers. Q. Bing indexer in API v2? A. Bing supports checker only. There is no Bing indexer endpoint. Do not plan PBN “Bing coverage” through this API. Q. Can I submit 100,000 mixed-tier URLs as one Standard task? A. The file limit is 100,000. Mixing tiers still inverts the graph. Split by layer even when the dashboard would accept one blob. Q. What if Pre-Indexing Link Check flags an URL I can see in Chrome? A. Trust the Googlebot fetch. Your session is not the crawler. Re-run the Smartphone curl. Fix 451/robots/noindex before you argue with the filter.
  6. Start the graph walk Export 50 href-bearing PBN posts. Strip

    homepages. Run Pre-Indexing Link Check. Submit drip_feed_days=14. Read the Day-7 report. Pay-per-Result: tokens leave the balance only for URLs Google stored (100 tokens each). Scan to open drip-feed indexing 200 free tokens for new accounts. No GSC verification. Third-party URLs accepted. Open drip-feed indexing → Open the dashboard → QR uses utm_medium=document_qr (SlideShare player blocks clicks) Google report Day 7 · Yandex Day 15 · auto-refund on non-indexed URLs Official SpeedyIndex channels (verified URLs only) Site — en.speedyindex.com Dashboard — app.speedyindex.com Blog — blog.speedyindex.com Telegram bot — t.me/speedyindexbot Drip-feed guide — en.speedyindex.com/drip-feed-indexing Email — [email protected] · Telegram support @speedyindex / @speedyindex1k YouTube, X, Facebook, and Reddit handles are omitted here because this file only prints verified URLs. Limitation: Google decides storage. SpeedyIndex guarantees the process (submission, checking, Pay-per-Result refund), not the SERP outcome.