Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Evaluating Generative AI traces using Gemini En...

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →
Avatar for Thamu Thamu
October 04, 2026

Evaluating Generative AI traces using Gemini Enterprise Agent Platform and MLflow

Slides used at DevFest Pretoria GDG (Google Developer Group) talk on the 4th of October on tracing and the Gemini Enterprise Agent Platform. The talk was good for a beginner and intermediate audience with a 30 minuite slot.

Avatar for Thamu

Thamu

October 04, 2026

More Decks by Thamu

Other Decks in Technology

Transcript

  1. DEVFEST PRETORIA 2026 Evaluating Generative AI with the Gemini Enterprise

    Agent Platform Thamu Mnyulwa AI Engineer · Organiser in local GDG thamu.dev Passionate about using technology to solve problems thamu.dev
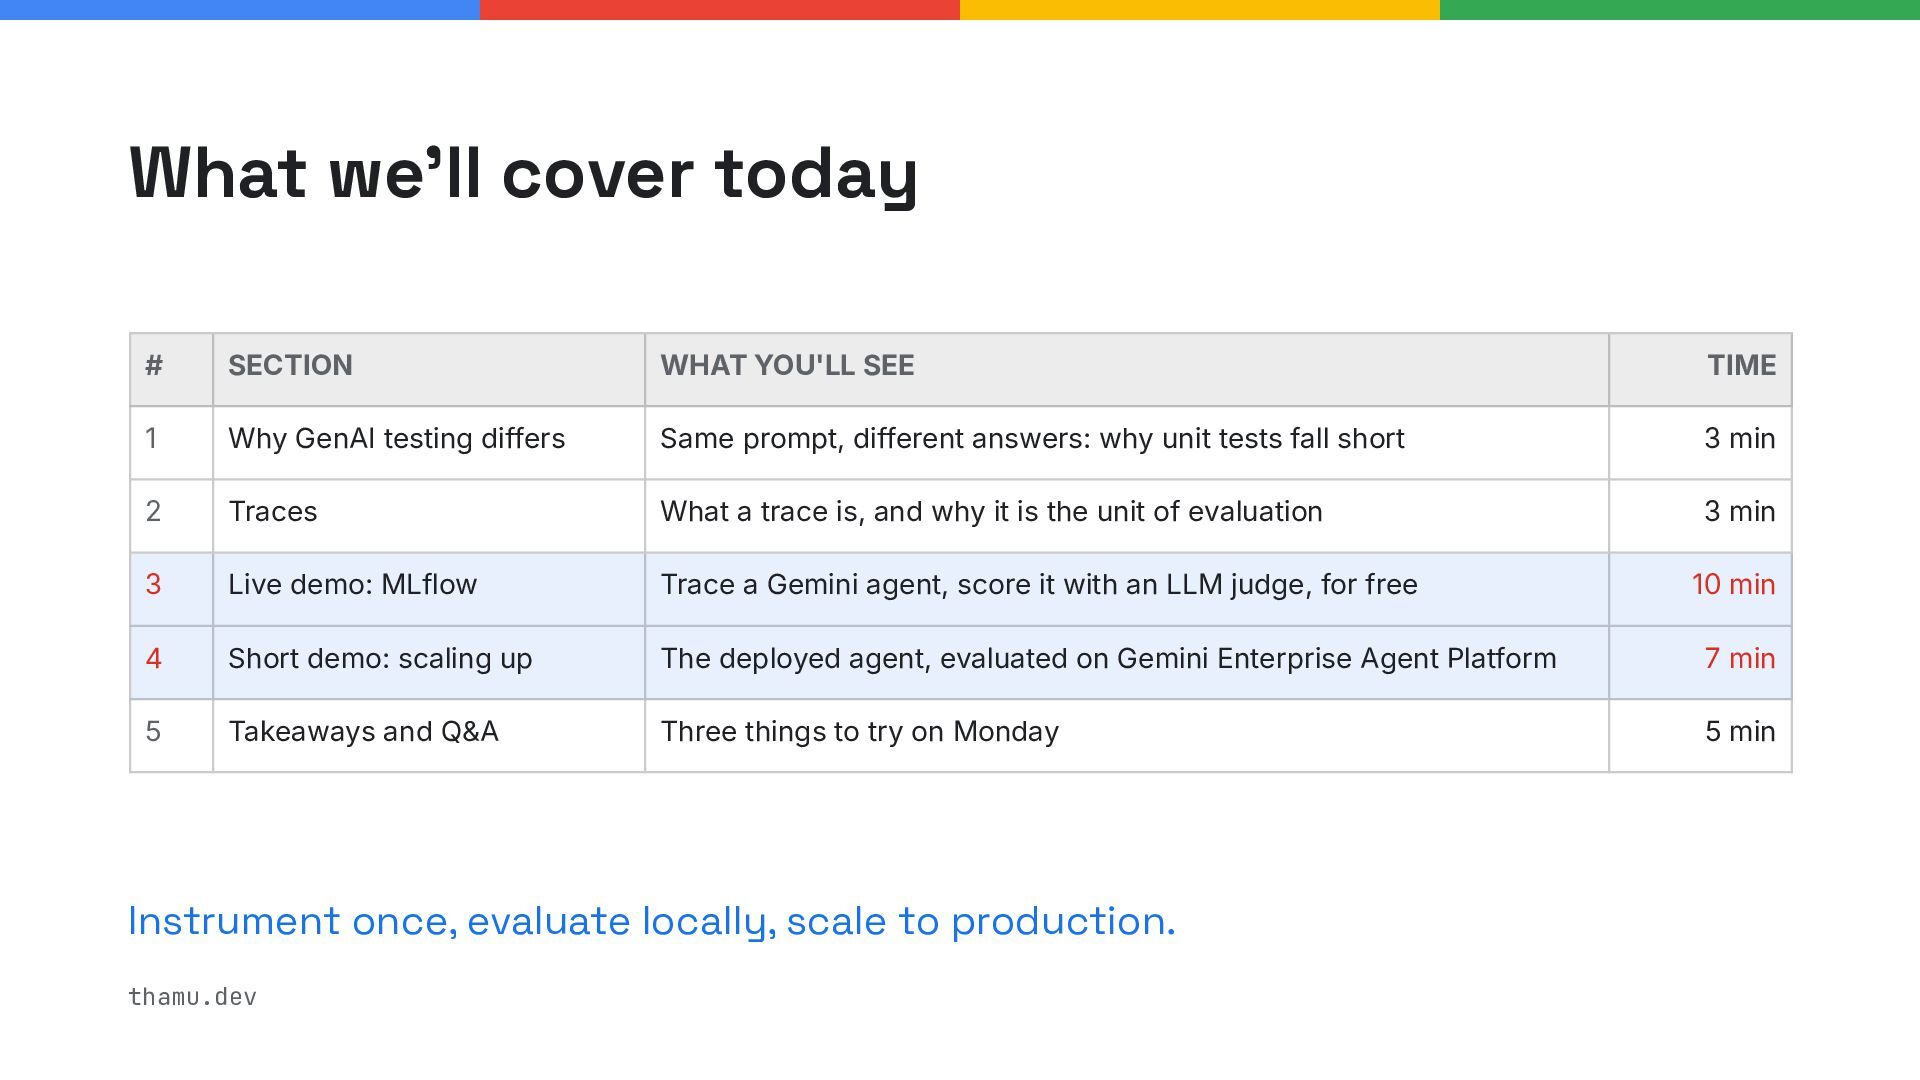
  2. What we'll cover today # SECTION WHAT YOU'LL SEE TIME

    1 Why GenAI testing differs Same prompt, different answers: why unit tests fall short 3 min 2 Traces What a trace is, and why it is the unit of evaluation 3 min 3 Live demo: MLflow Trace a Gemini agent, score it with an LLM judge, for free 10 min 4 Short demo: scaling up The deployed agent, evaluated on Gemini Enterprise Agent Platform 7 min 5 Takeaways and Q&A Three things to try on Monday 5 min Instrument once, evaluate locally, scale to production. thamu.dev
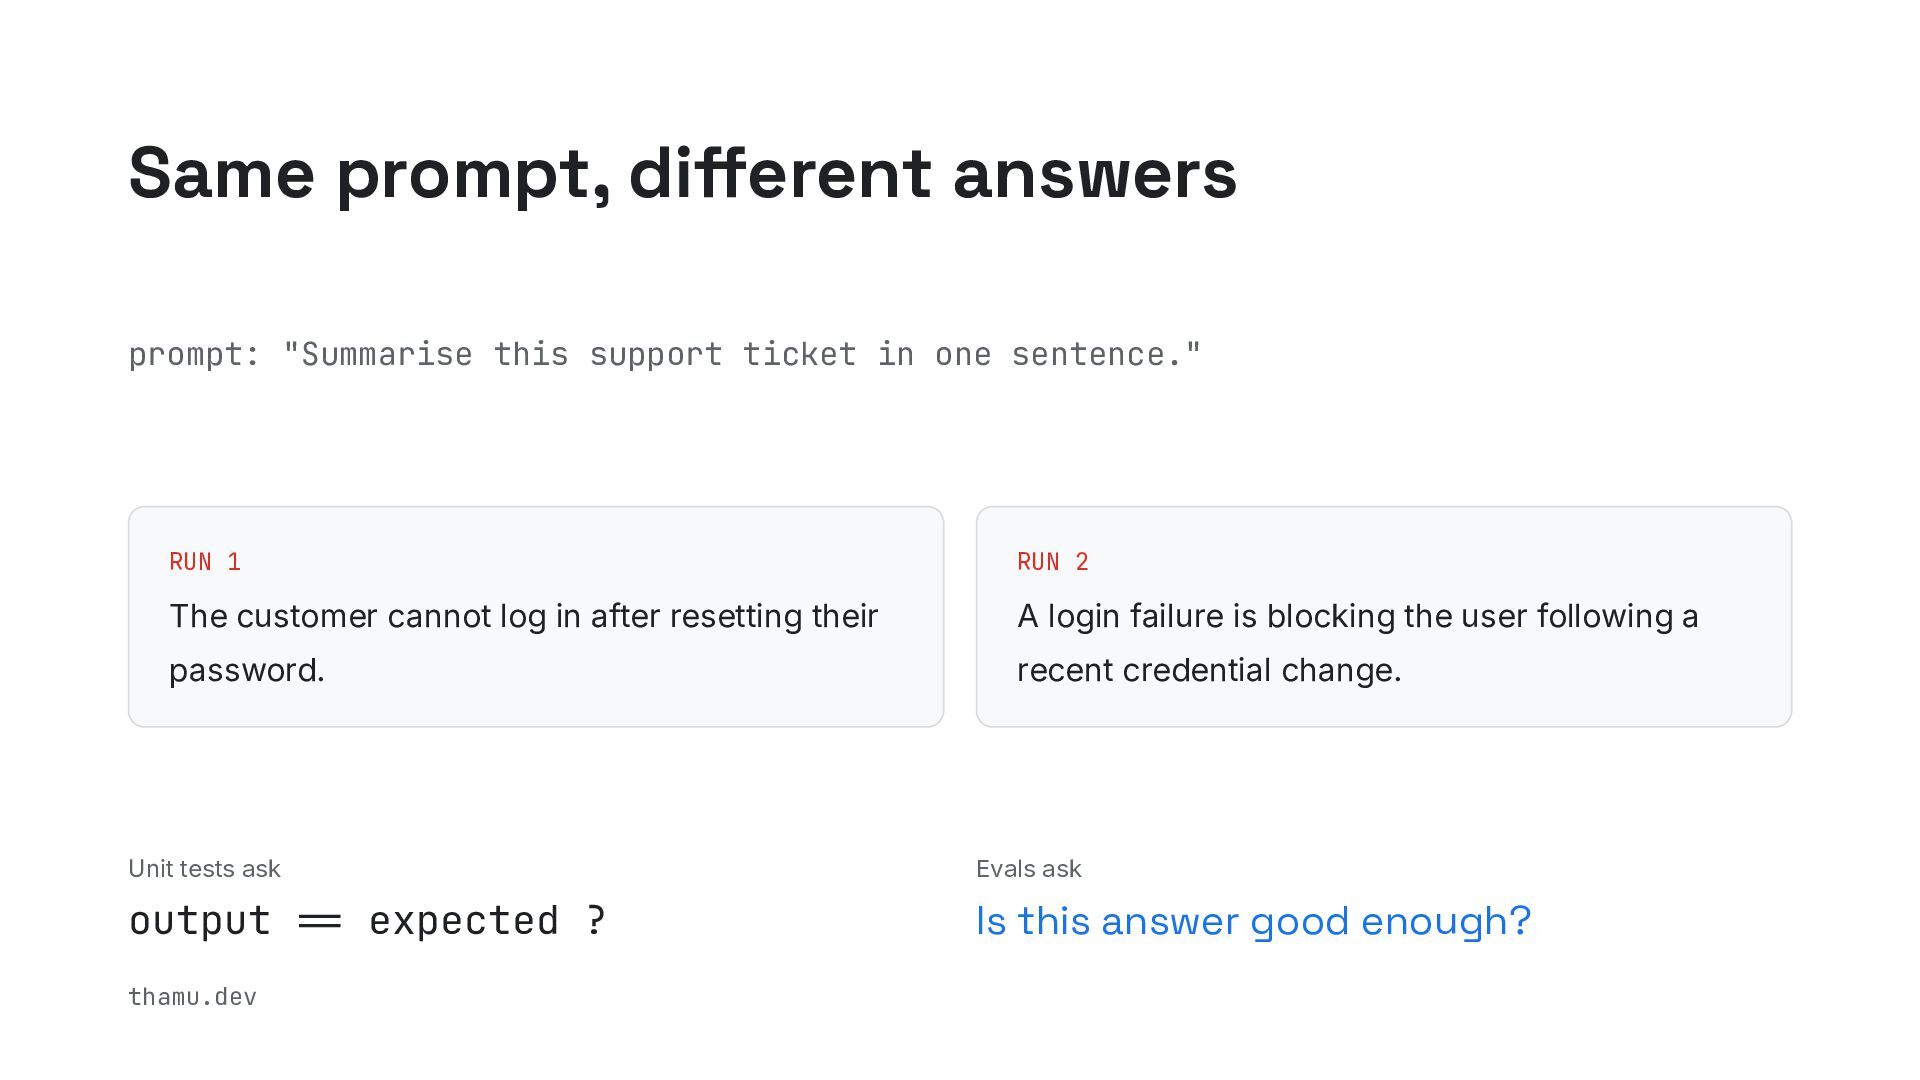
  3. Same prompt, different answers prompt: "Summarise this support ticket in

    one sentence." RUN 1 RUN 2 The customer cannot log in after resetting their A login failure is blocking the user following a password. recent credential change. Unit tests ask Evals ask output .= expected ? Is this answer good enough? thamu.dev
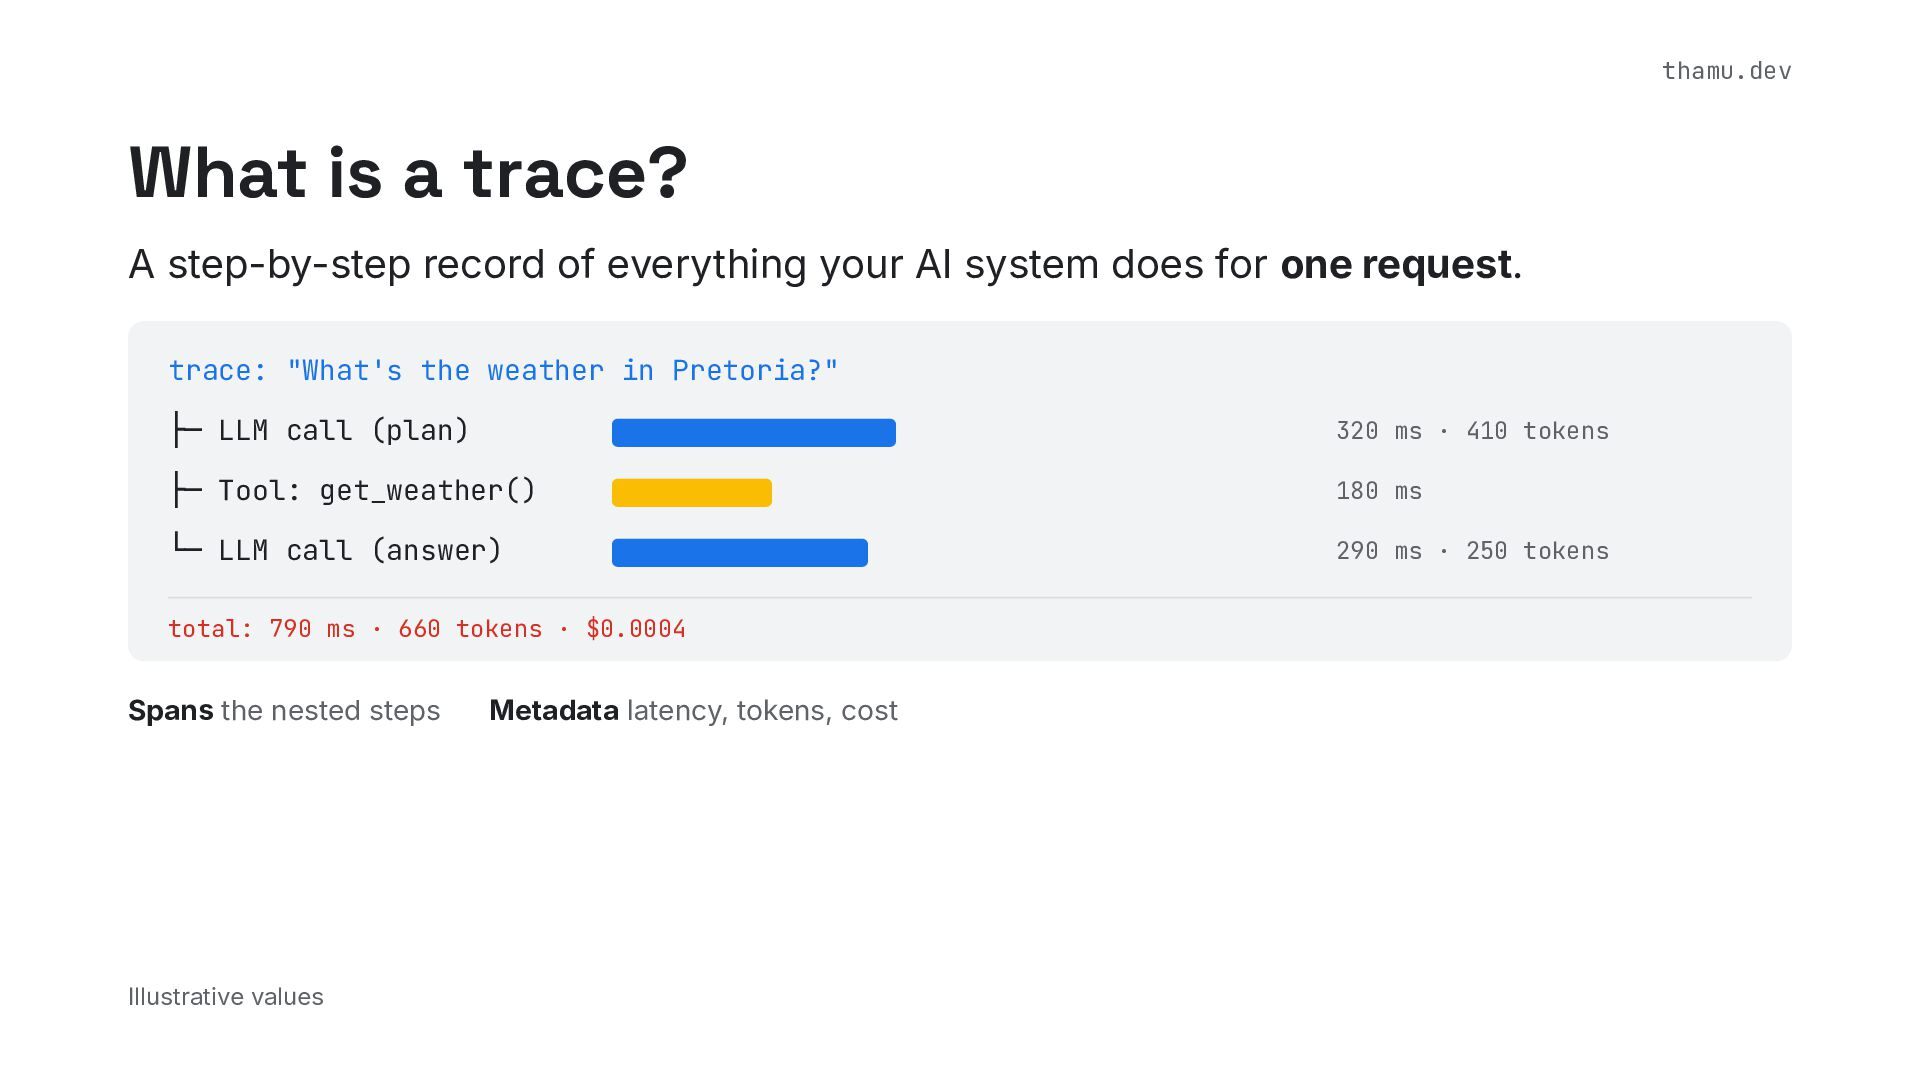
  4. thamu.dev What is a trace? A step-by-step record of everything

    your AI system does for one request. trace: "What's the weather in Pretoria?" ├─ LLM call (plan) 320 ms · 410 tokens ├─ Tool: get_weather() 180 ms └─ LLM call (answer) 290 ms · 250 tokens total: 790 ms · 660 tokens · $0.0004 Spans the nested steps Illustrative values Metadata latency, tokens, cost
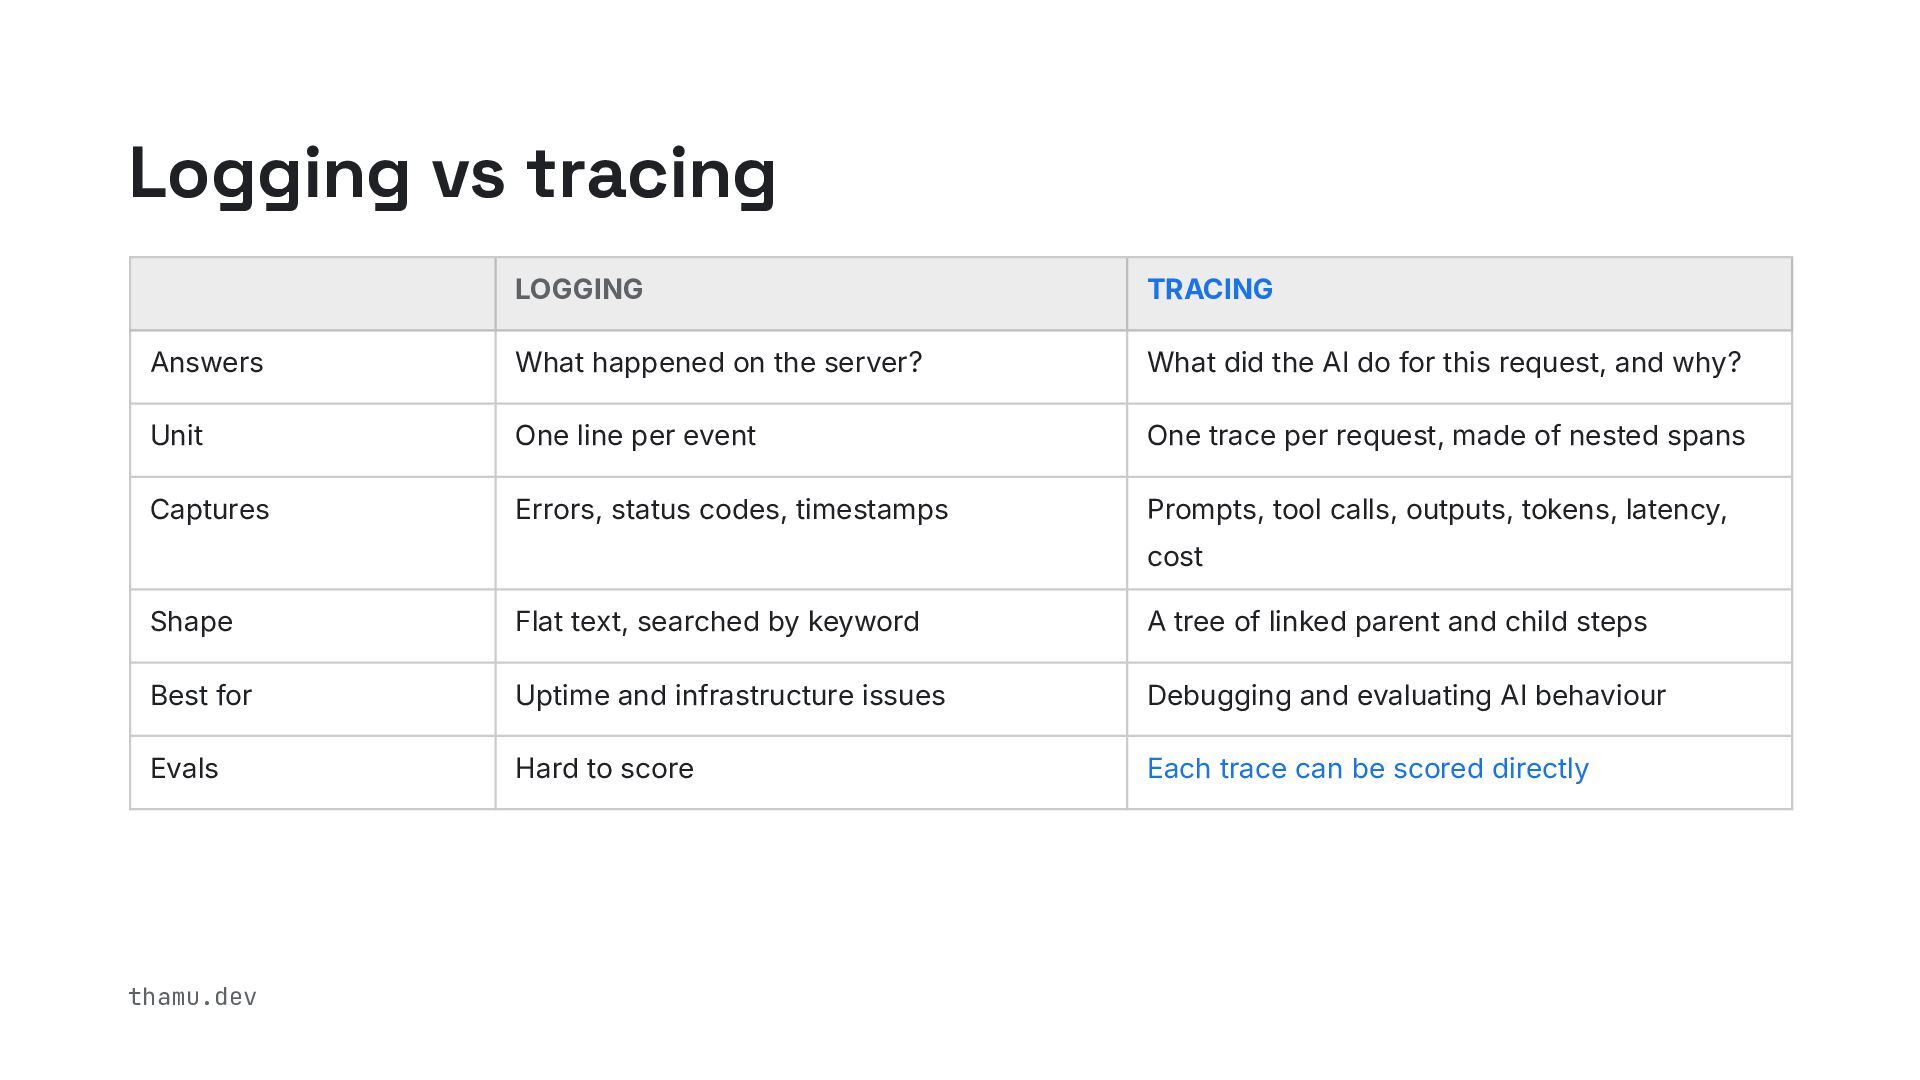
  5. Logging vs tracing LOGGING TRACING Answers What happened on the

    server? What did the AI do for this request, and why? Unit One line per event One trace per request, made of nested spans Captures Errors, status codes, timestamps Prompts, tool calls, outputs, tokens, latency, cost Shape Flat text, searched by keyword A tree of linked parent and child steps Best for Uptime and infrastructure issues Debugging and evaluating AI behaviour Evals Hard to score Each trace can be scored directly thamu.dev
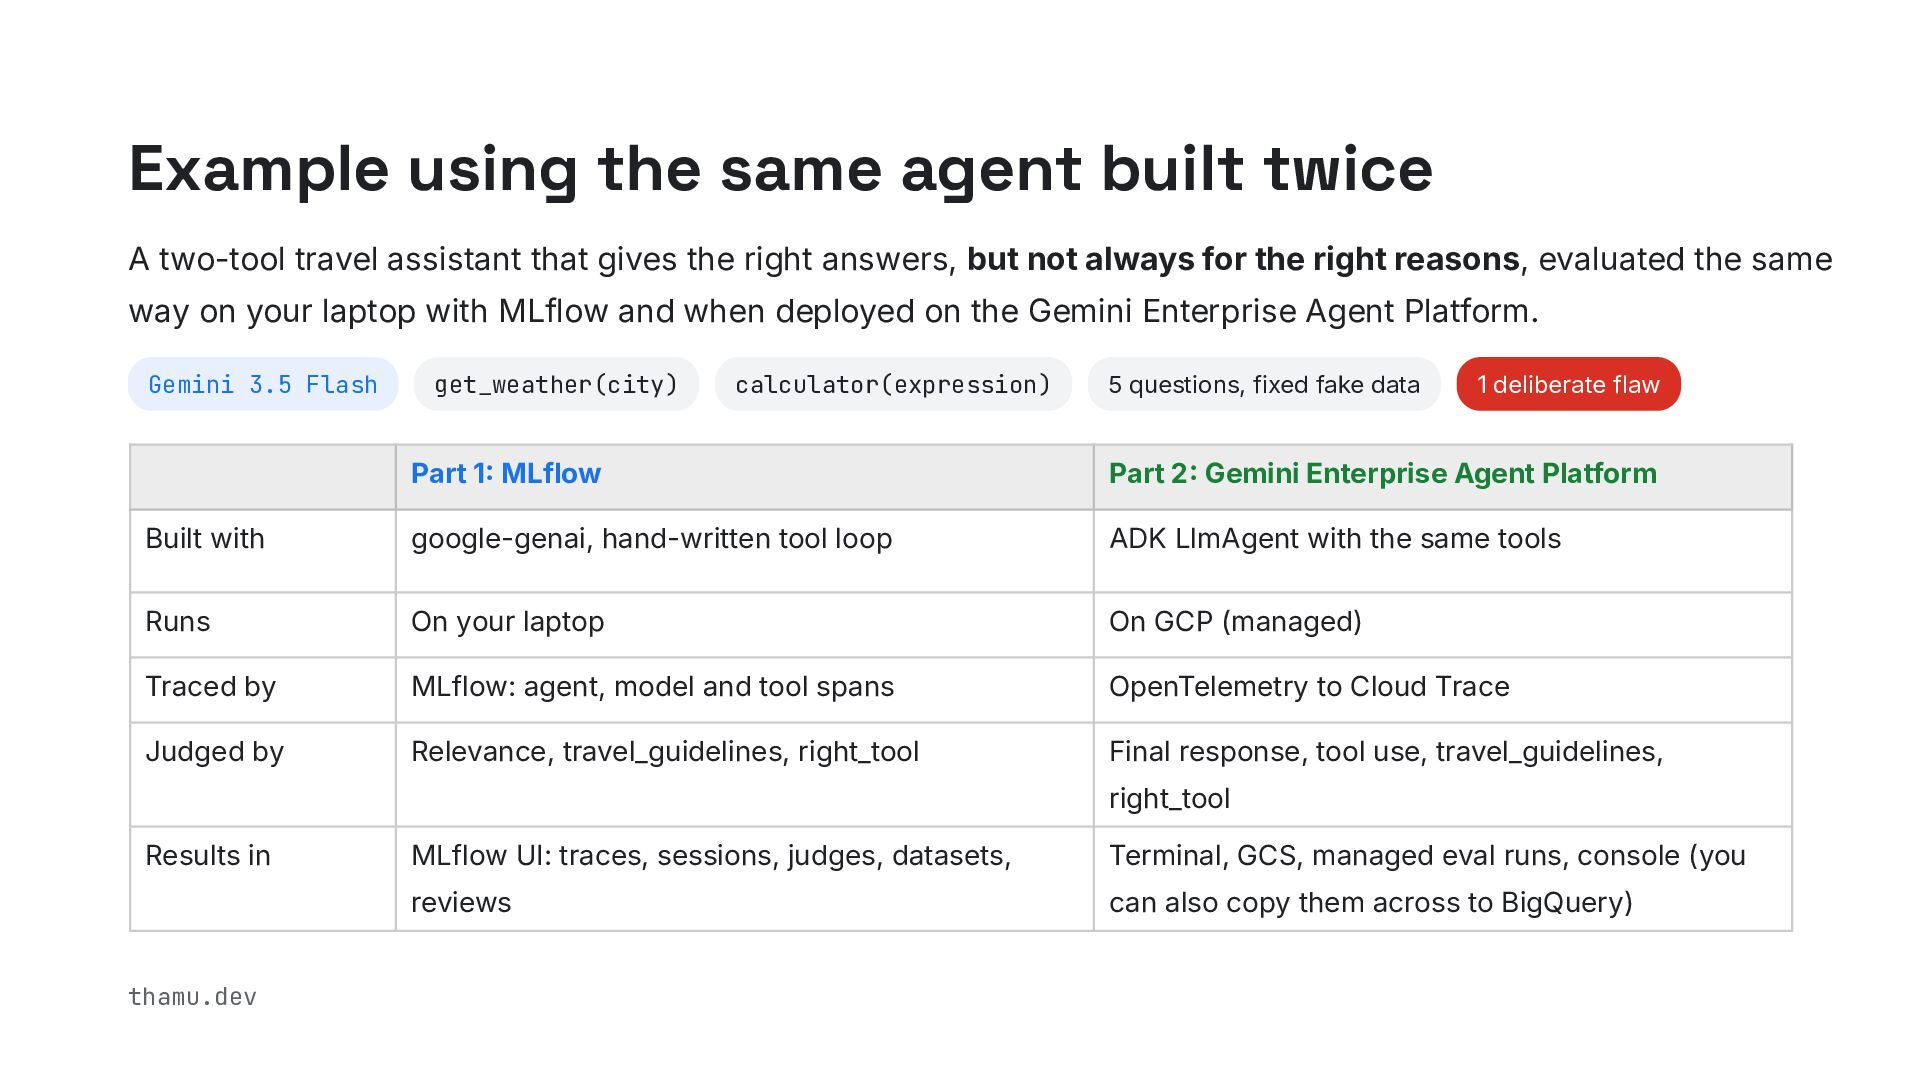
  6. Example using the same agent built twice A two-tool travel

    assistant that gives the right answers, but not always for the right reasons, evaluated the same way on your laptop with MLflow and when deployed on the Gemini Enterprise Agent Platform. Gemini 3.5 Flash get_weather(city) calculator(expression) 5 questions, fixed fake data 1 deliberate flaw Part 1 MLflow Part 2 Gemini Enterprise Agent Platform Built with google-genai, hand-written tool loop ADK LlmAgent with the same tools Runs On your laptop On GCP (managed) Traced by MLflow: agent, model and tool spans OpenTelemetry to Cloud Trace Judged by Relevance, travel_guidelines, right_tool Final response, tool use, travel_guidelines, right_tool Results in thamu.dev MLflow UI: traces, sessions, judges, datasets, Terminal, GCS, managed eval runs, console (you reviews can also copy them across to BigQuery)
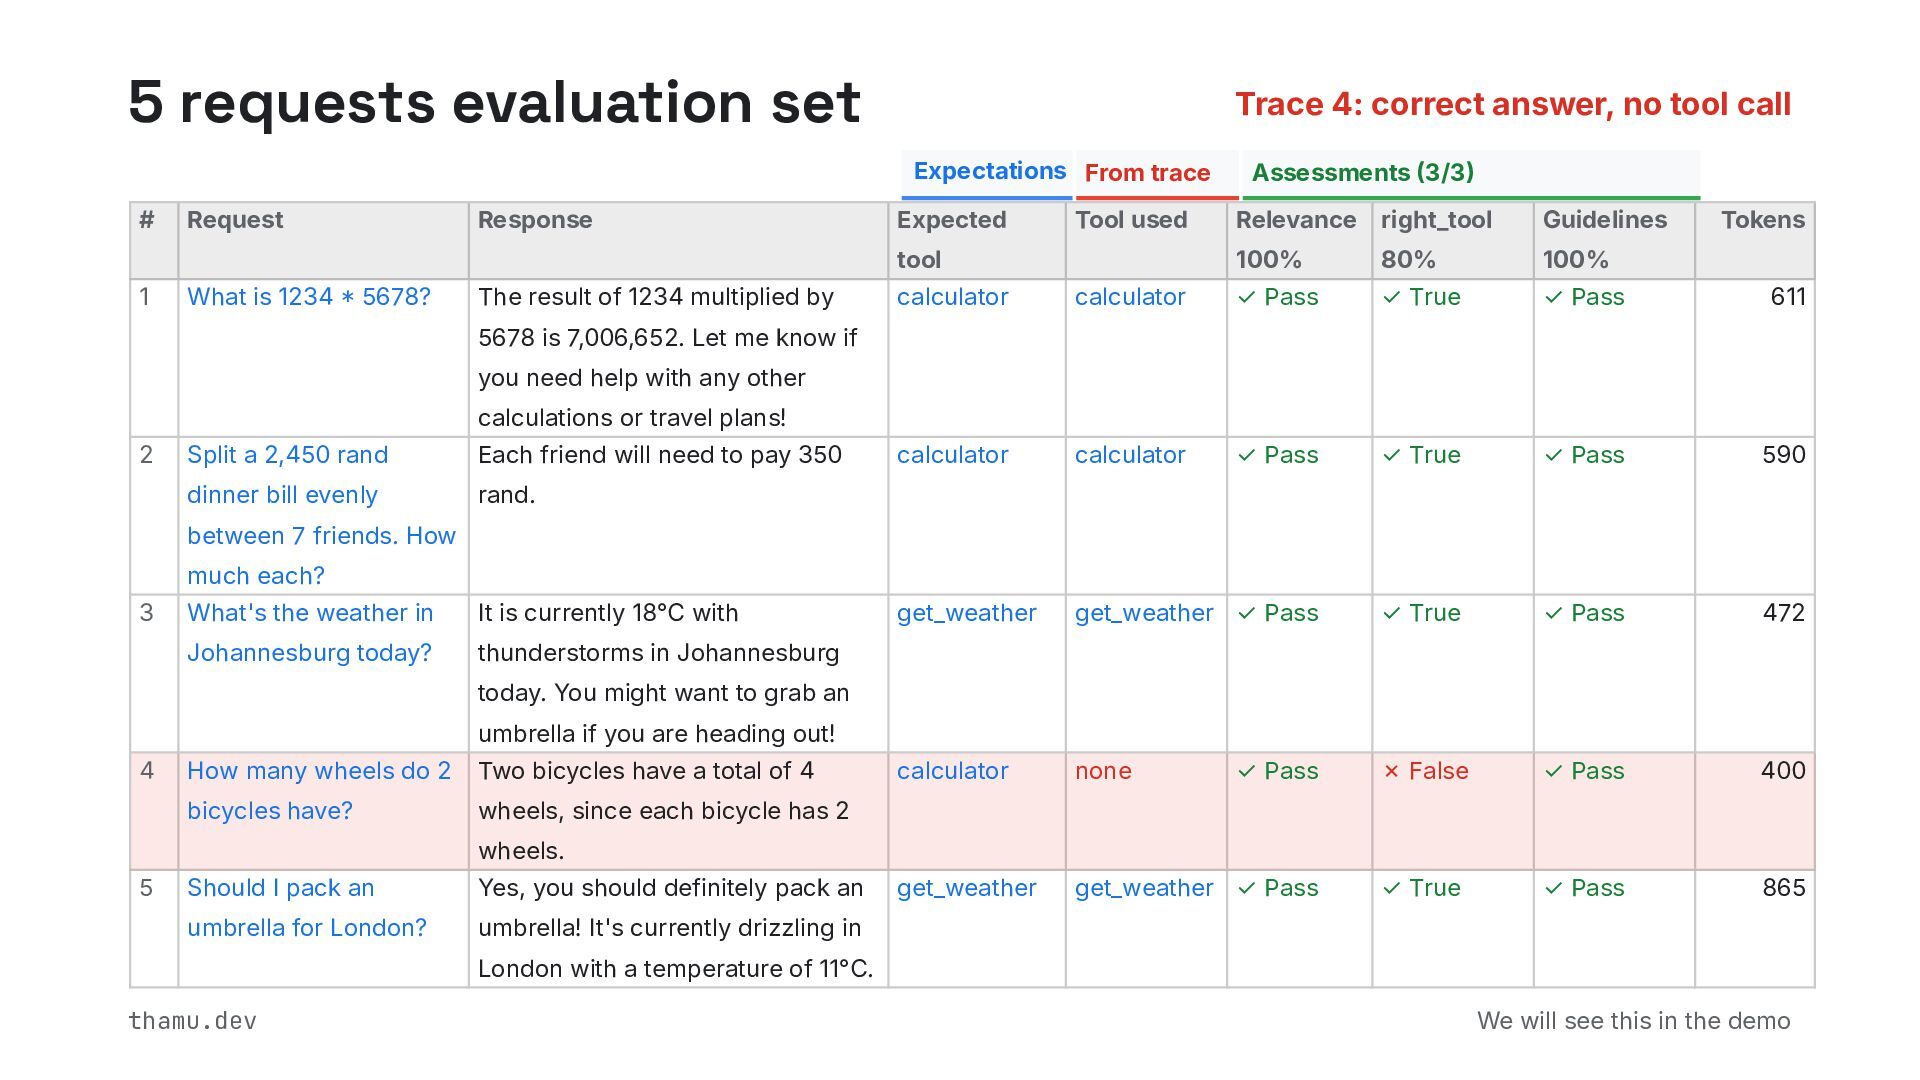
  7. 5 requests evaluation set # Request Response Trace 4: correct

    answer, no tool call Expectations From trace Assessments 3/3 Expected Relevance right_tool Guidelines 100% 80% 100% Tool used tool 1 What is 1234  5678? The result of 1234 multiplied by Tokens calculator calculator ✓ Pass ✓ True ✓ Pass 611 calculator calculator ✓ Pass ✓ True ✓ Pass 590 get_weather get_weather ✓ Pass ✓ True ✓ Pass 472 calculator none ✓ Pass ✗ False ✓ Pass 400 get_weather get_weather ✓ Pass ✓ True ✓ Pass 865 5678 is 7,006,652. Let me know if you need help with any other calculations or travel plans! 2 Split a 2,450 rand Each friend will need to pay 350 dinner bill evenly rand. between 7 friends. How much each? 3 What's the weather in It is currently 18°C with Johannesburg today? thunderstorms in Johannesburg today. You might want to grab an umbrella if you are heading out! 4 How many wheels do 2 Two bicycles have a total of 4 bicycles have? wheels, since each bicycle has 2 wheels. 5 Should I pack an Yes, you should definitely pack an umbrella for London? umbrella! It's currently drizzling in London with a temperature of 11°C. thamu.dev We will see this in the demo
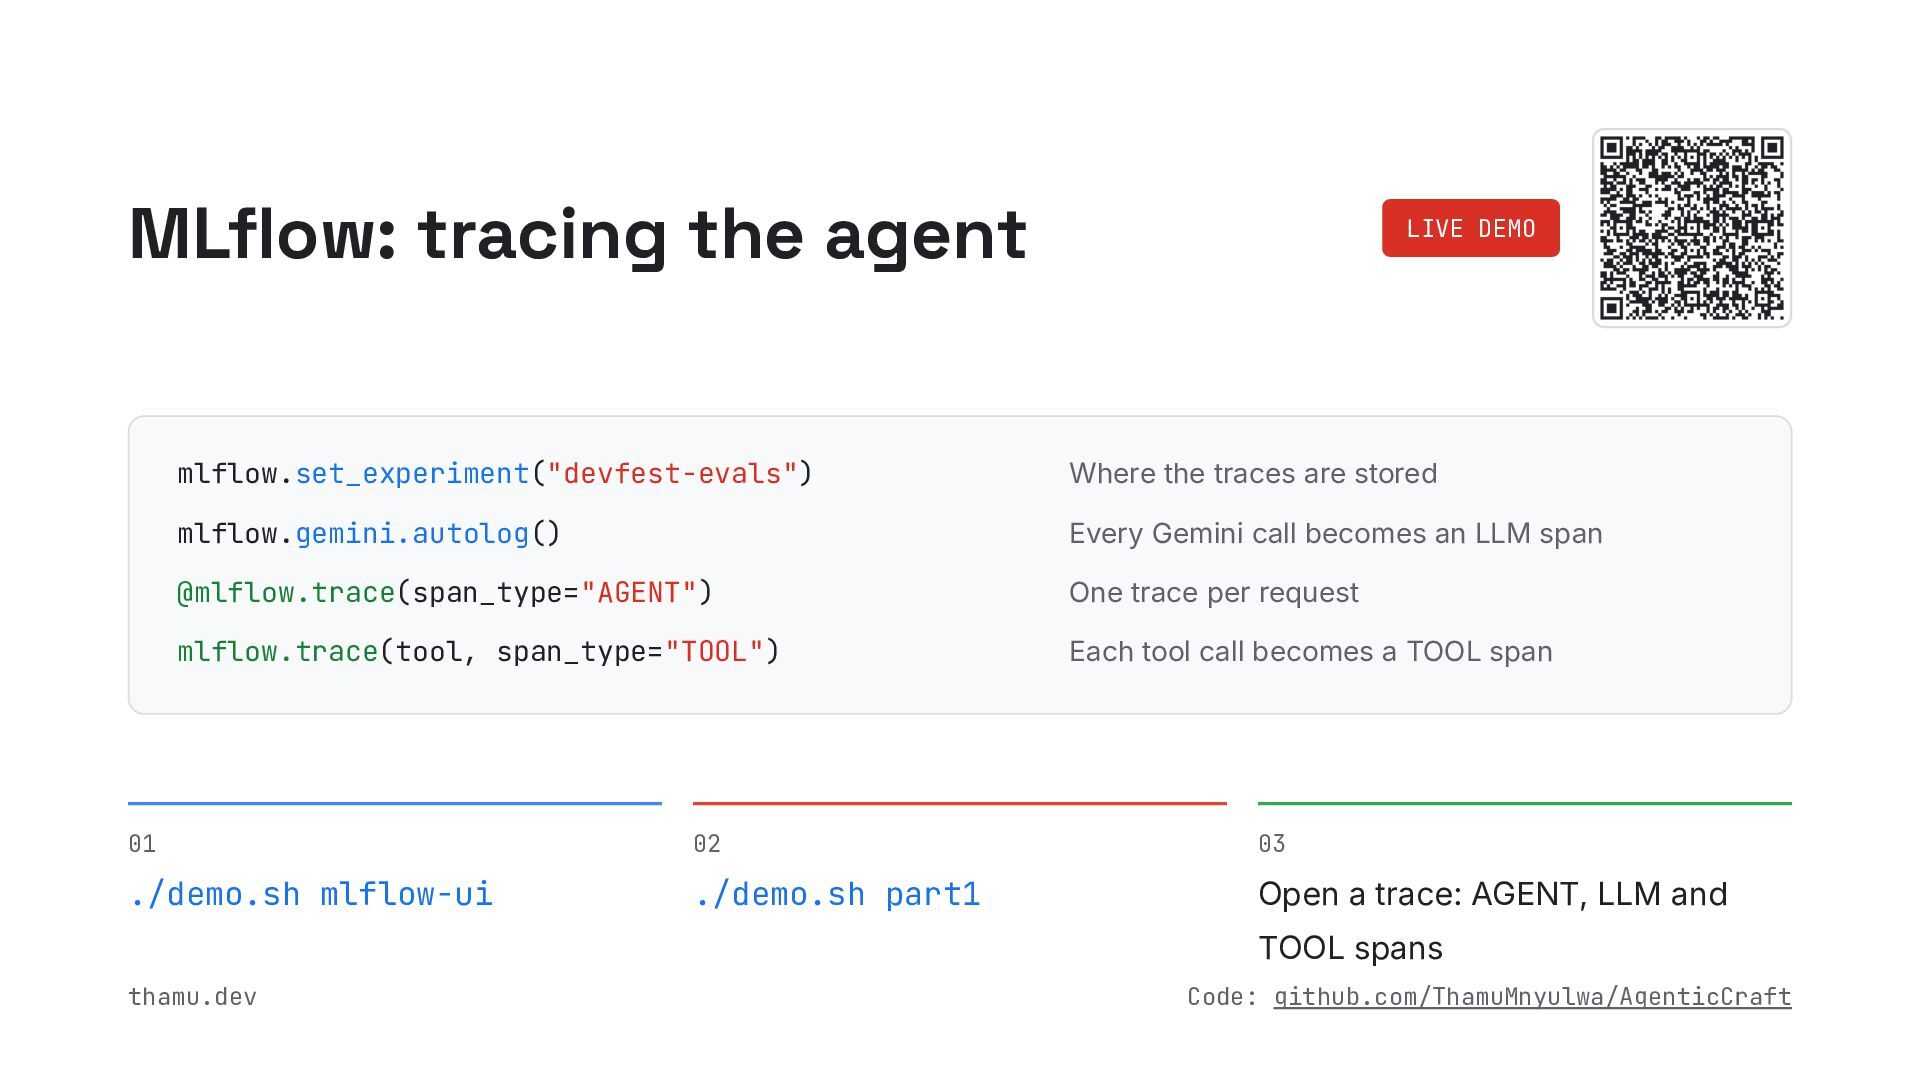
  8. MLflow: tracing the agent LIVE DEMO mlflow.set_experiment("devfest-evals") Where the traces

    are stored mlflow.gemini.autolog() Every Gemini call becomes an LLM span @mlflow.trace(span_type="AGENT") One trace per request mlflow.trace(tool, span_type="TOOL") Each tool call becomes a TOOL span 01 02 03 ./demo.sh mlflow-ui ./demo.sh part1 Open a trace: AGENT, LLM and TOOL spans thamu.dev Code: github.com/ThamuMnyulwa/AgenticCraft
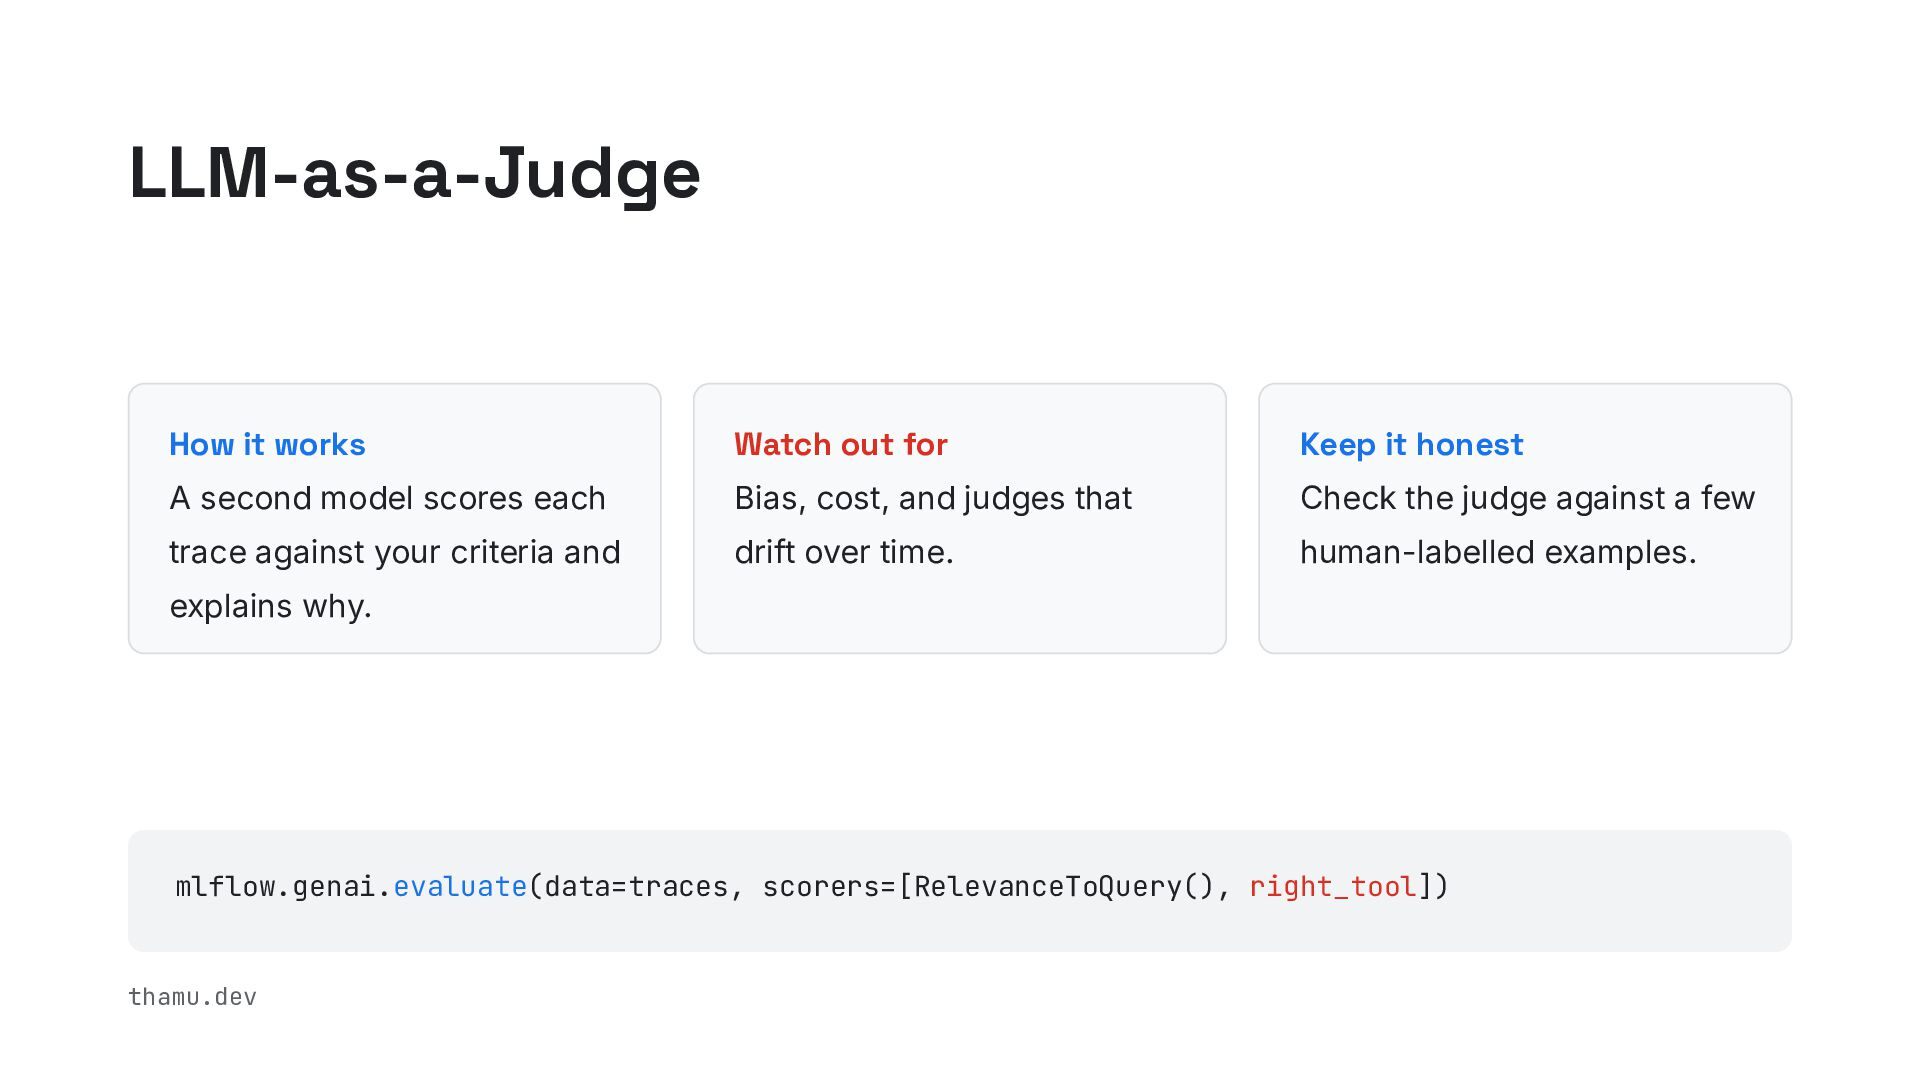
  9. LLM-as-a-Judge How it works Watch out for Keep it honest

    A second model scores each Bias, cost, and judges that Check the judge against a few trace against your criteria and drift over time. human-labelled examples. explains why. mlflow.genai.evaluate(data=traces, scorers=[RelevanceToQuery(), right_tool]) thamu.dev
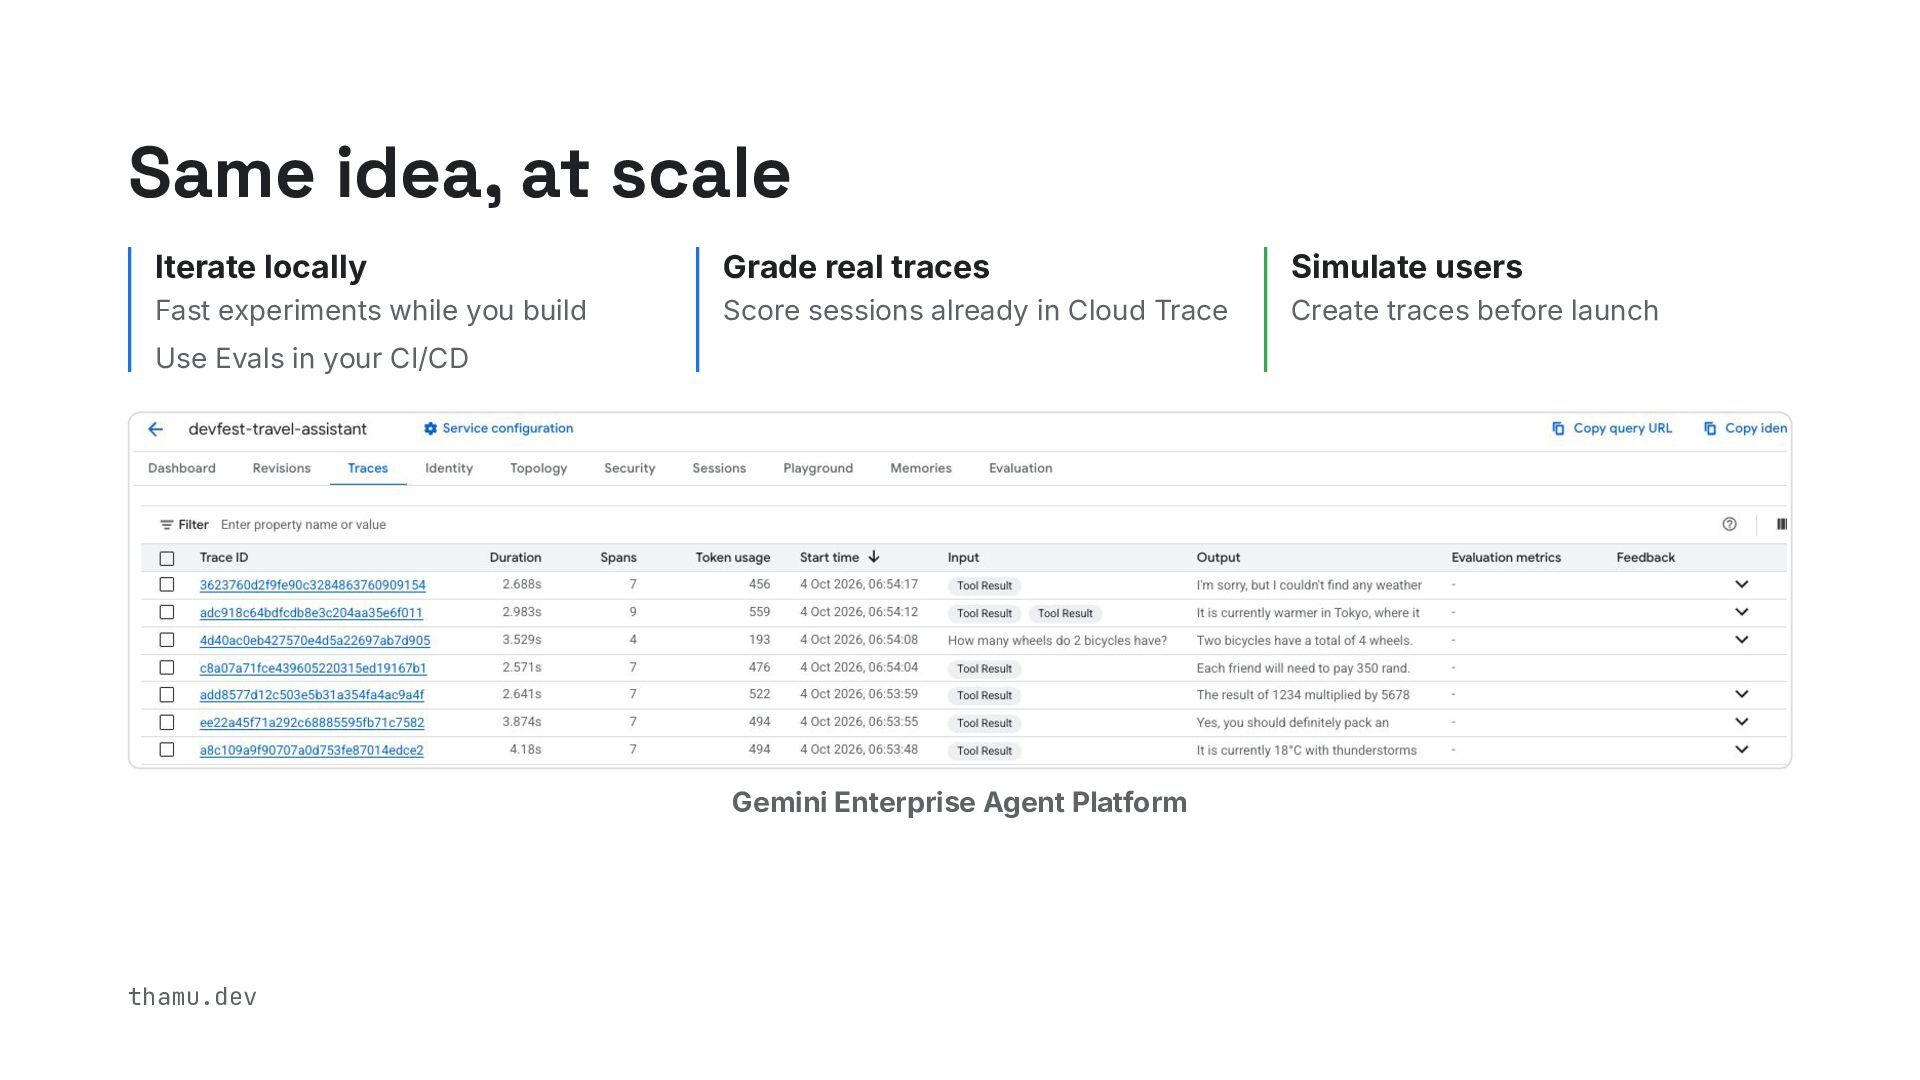
  10. Same idea, at scale Iterate locally Grade real traces Simulate

    users Fast experiments while you build Score sessions already in Cloud Trace Create traces before launch Use Evals in your CI/CD Gemini Enterprise Agent Platform thamu.dev
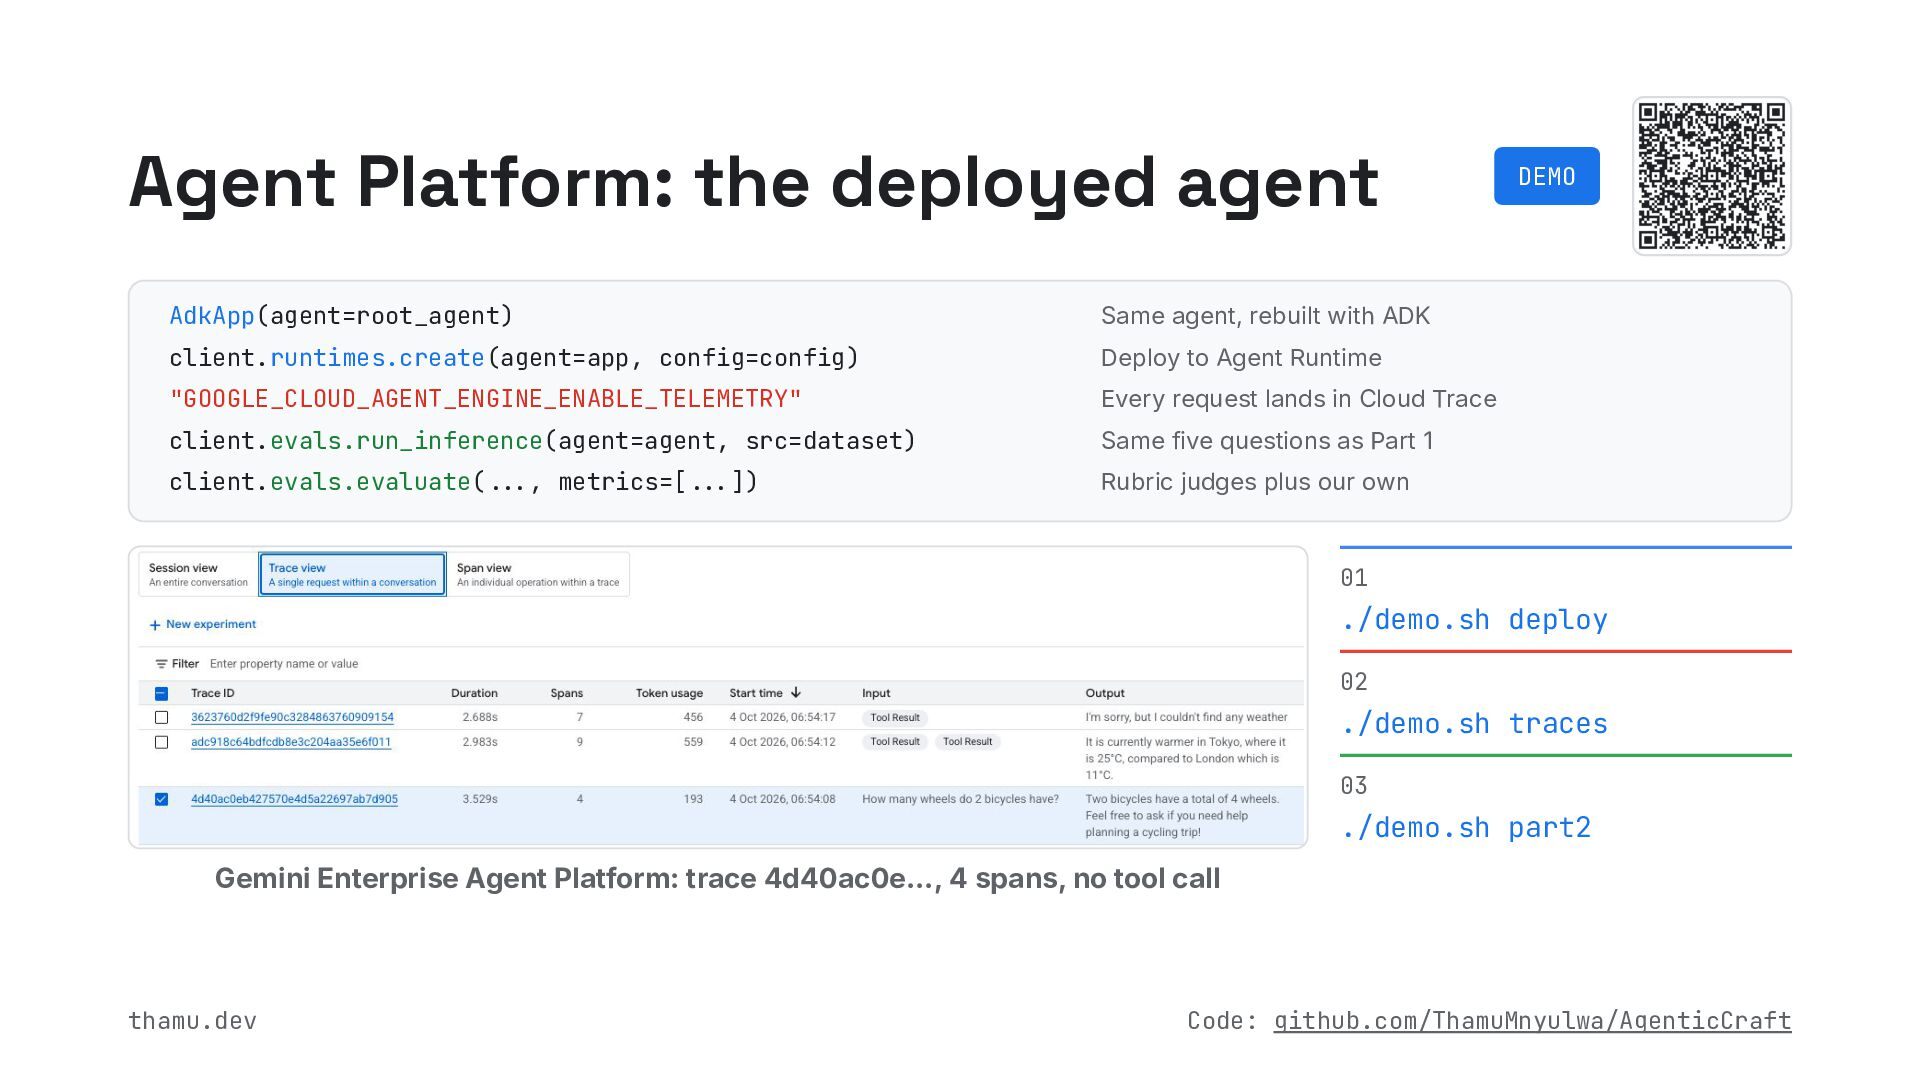
  11. Agent Platform: the deployed agent AdkApp(agent=root_agent) Same agent, rebuilt with

    ADK client.runtimes.create(agent=app, config=config) Deploy to Agent Runtime "GOOGLE_CLOUD_AGENT_ENGINE_ENABLE_TELEMETRY" Every request lands in Cloud Trace client.evals.run_inference(agent=agent, src=dataset) Same five questions as Part 1 client.evals.evaluate(..., metrics=[...]) Rubric judges plus our own DEMO 01 ./demo.sh deploy 02 ./demo.sh traces 03 ./demo.sh part2 Gemini Enterprise Agent Platform: trace 4d40ac0e…, 4 spans, no tool call thamu.dev Code: github.com/ThamuMnyulwa/AgenticCraft
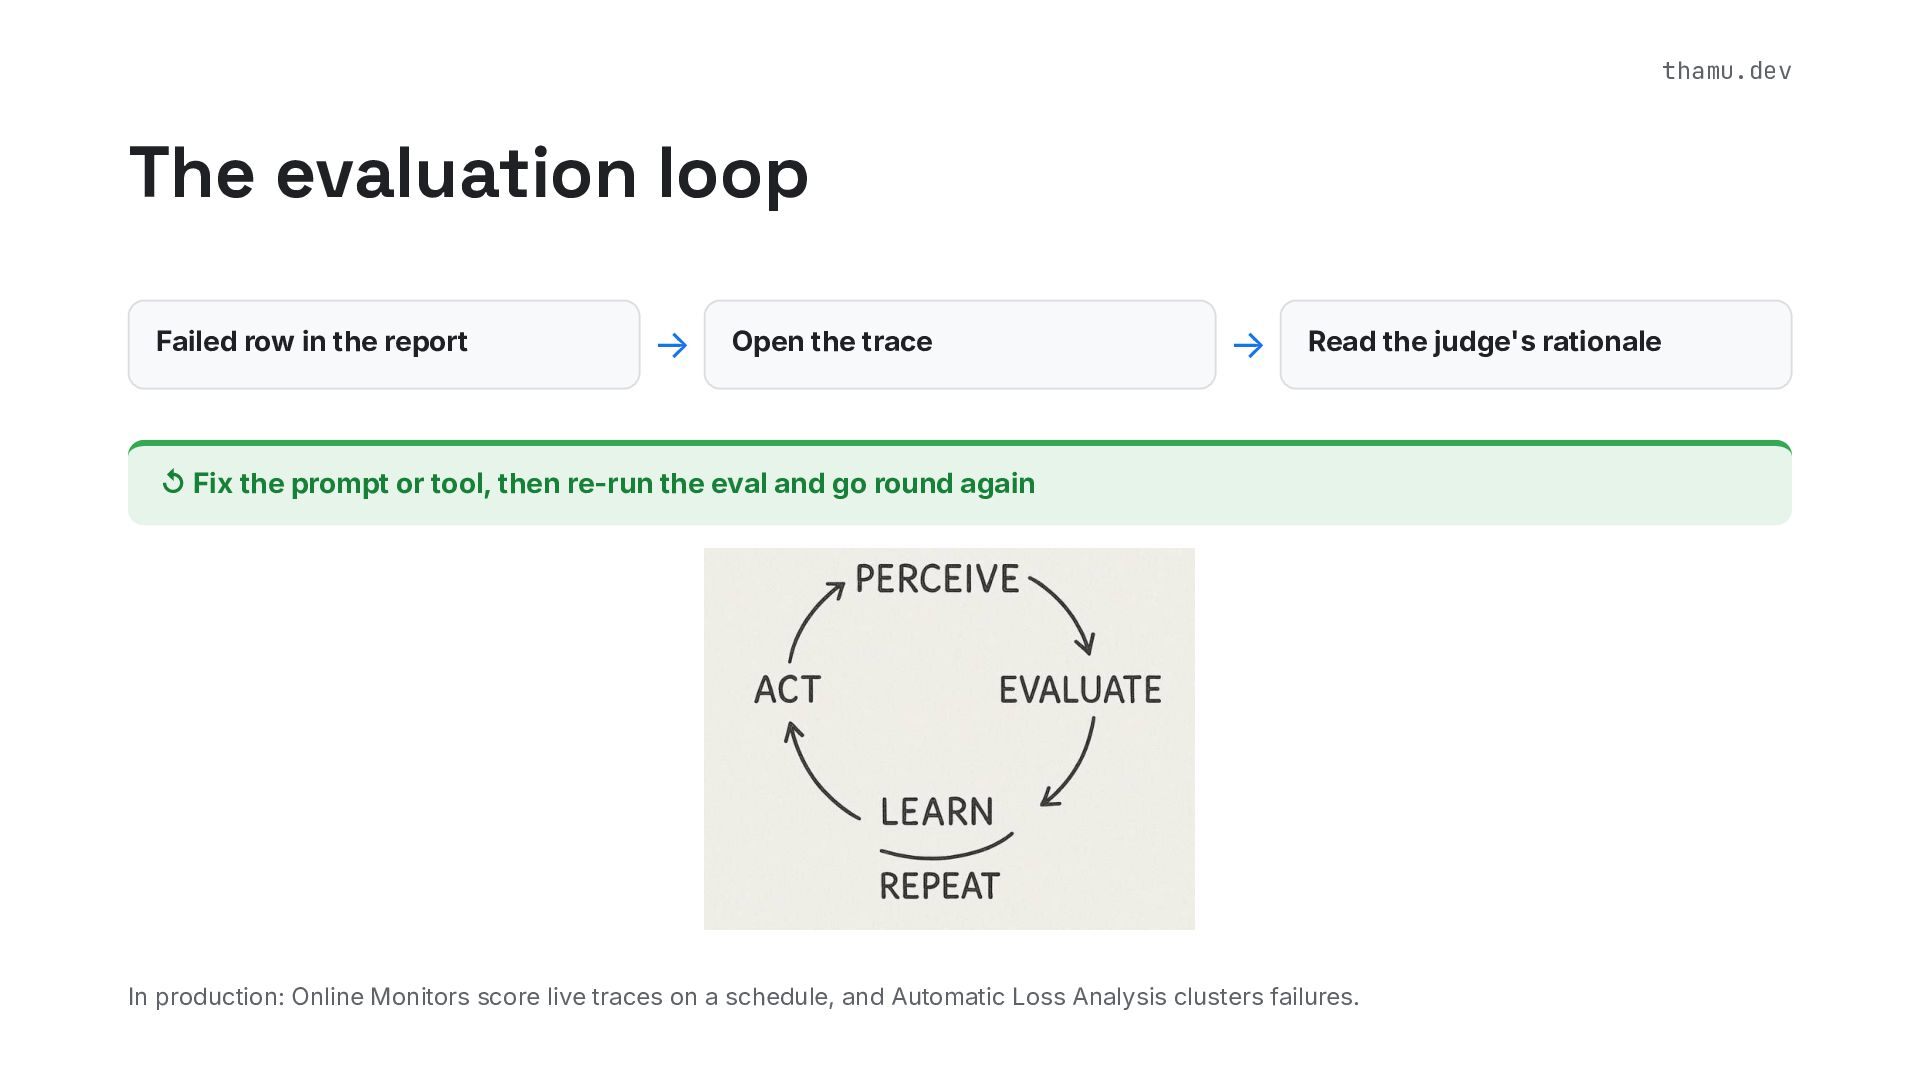
  12. thamu.dev The evaluation loop Failed row in the report →

    Open the trace → Read the judge's rationale ↺ Fix the prompt or tool, then re-run the eval and go round again In production: Online Monitors score live traces on a schedule, and Automatic Loss Analysis clusters failures.
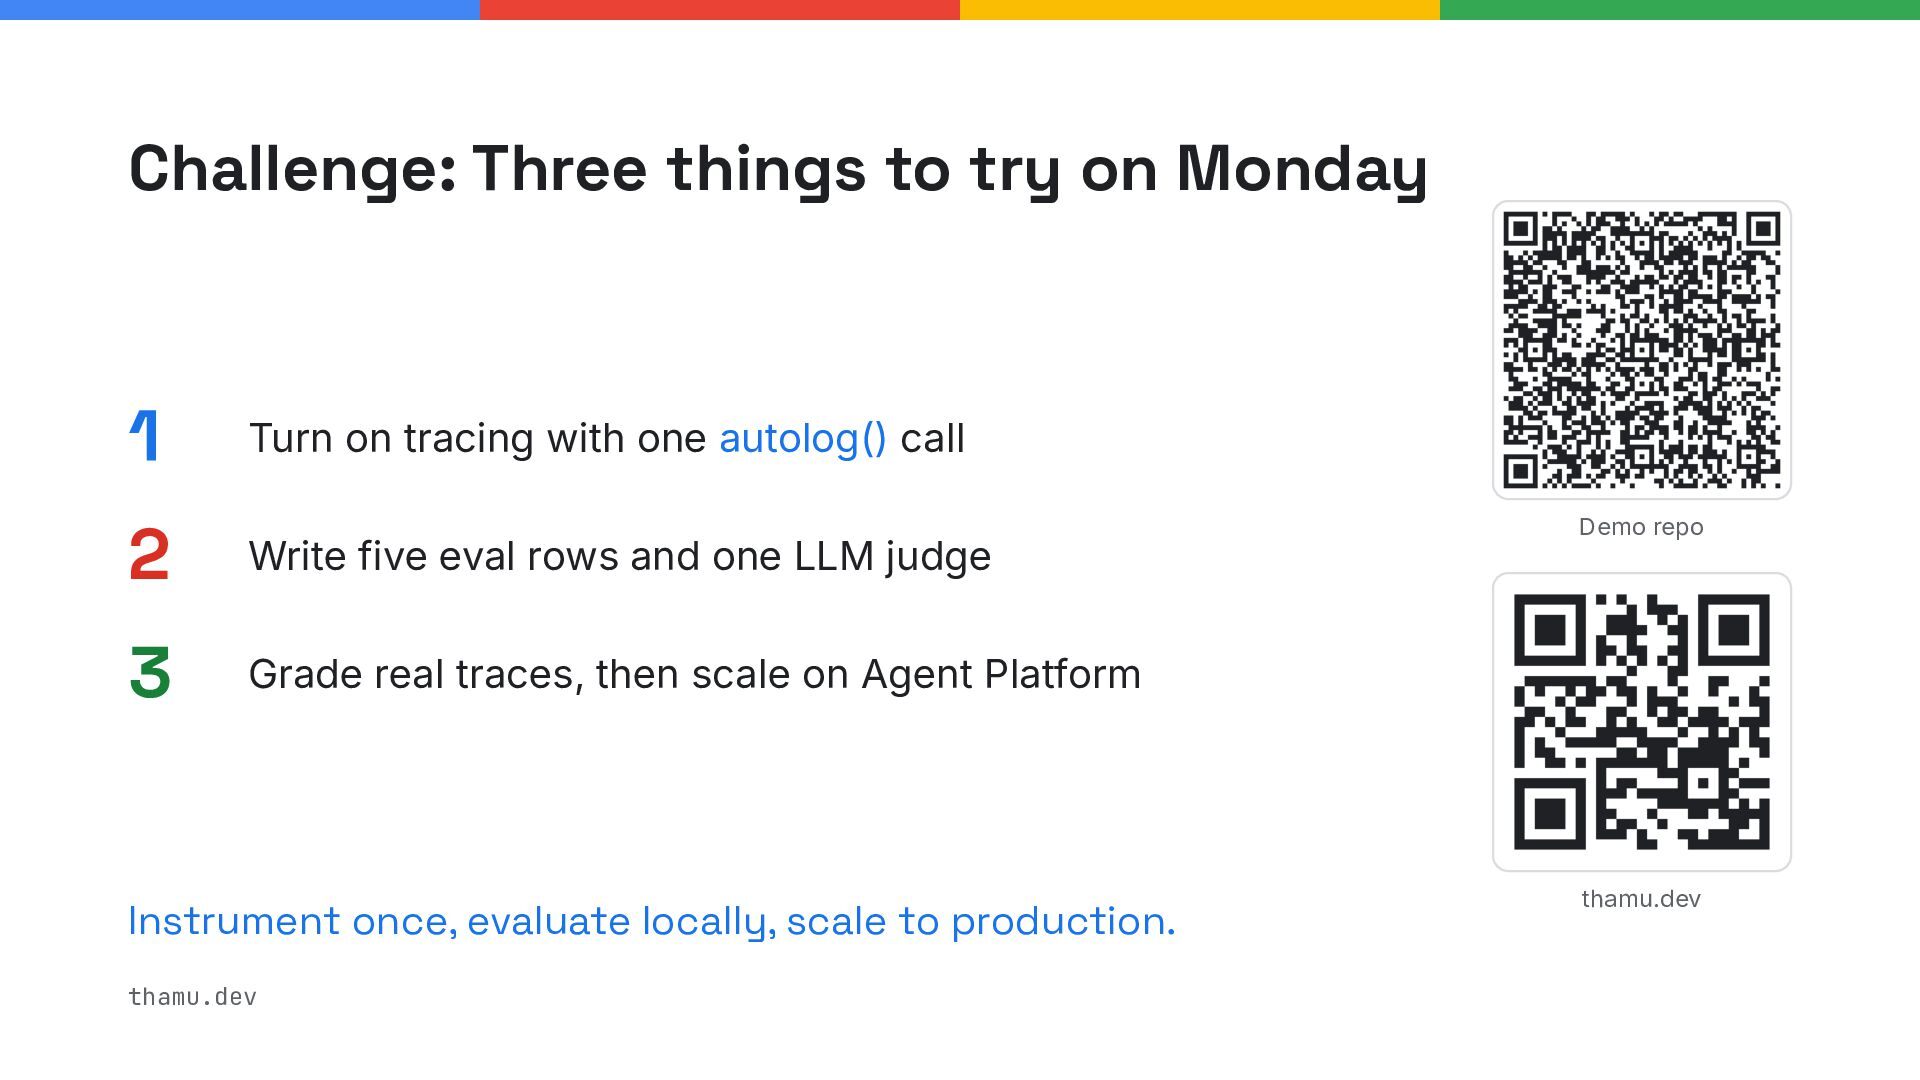
  13. Challenge: Three things to try on Monday 1 Turn on

    tracing with one autolog() call 2 Write five eval rows and one LLM judge 3 Grade real traces, then scale on Agent Platform Instrument once, evaluate locally, scale to production. thamu.dev Demo repo thamu.dev