Compare Jev and Flash Lite for grading AI agents. See head-to-head results, learn prompt rewrites for zero mistakes, and discover when each model is the right choice.
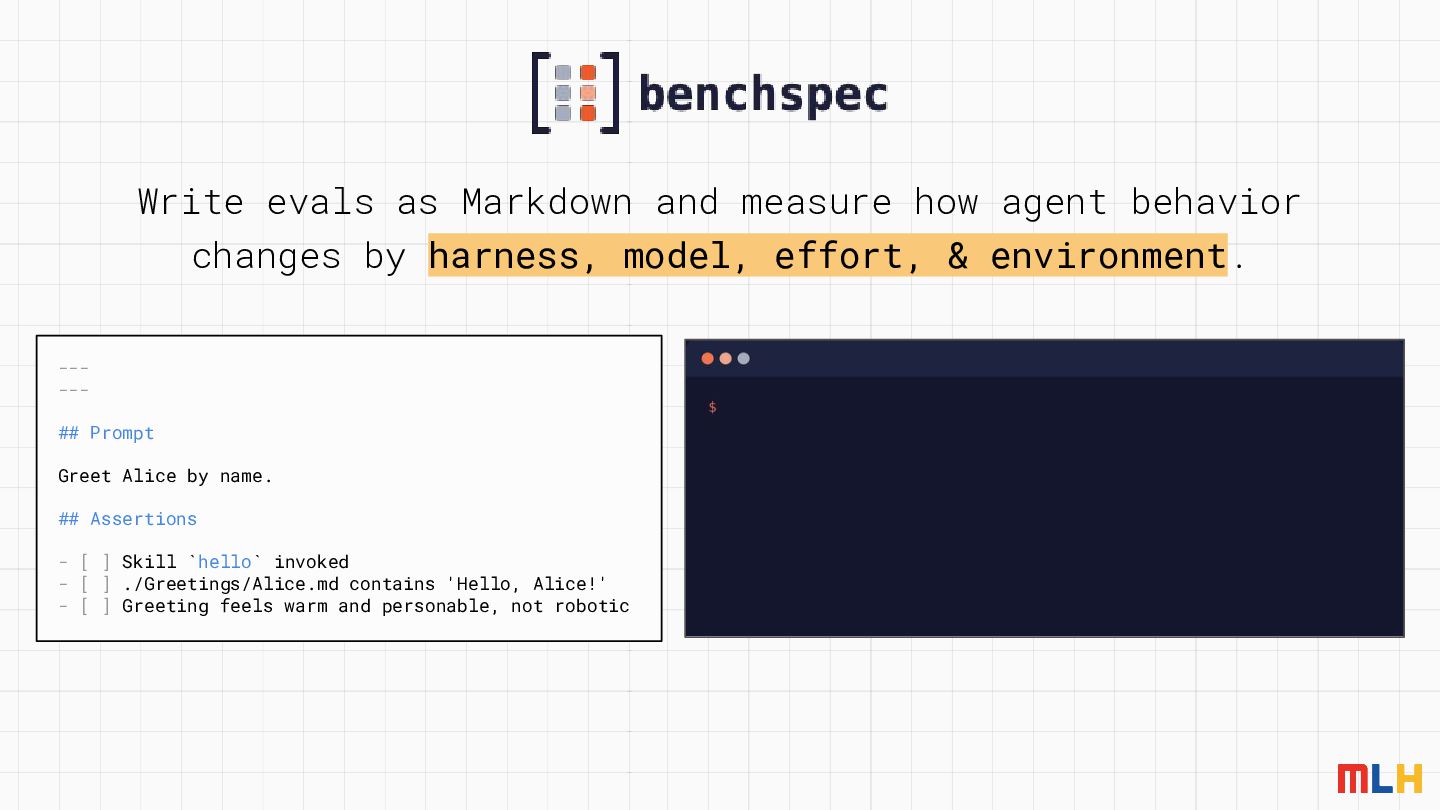
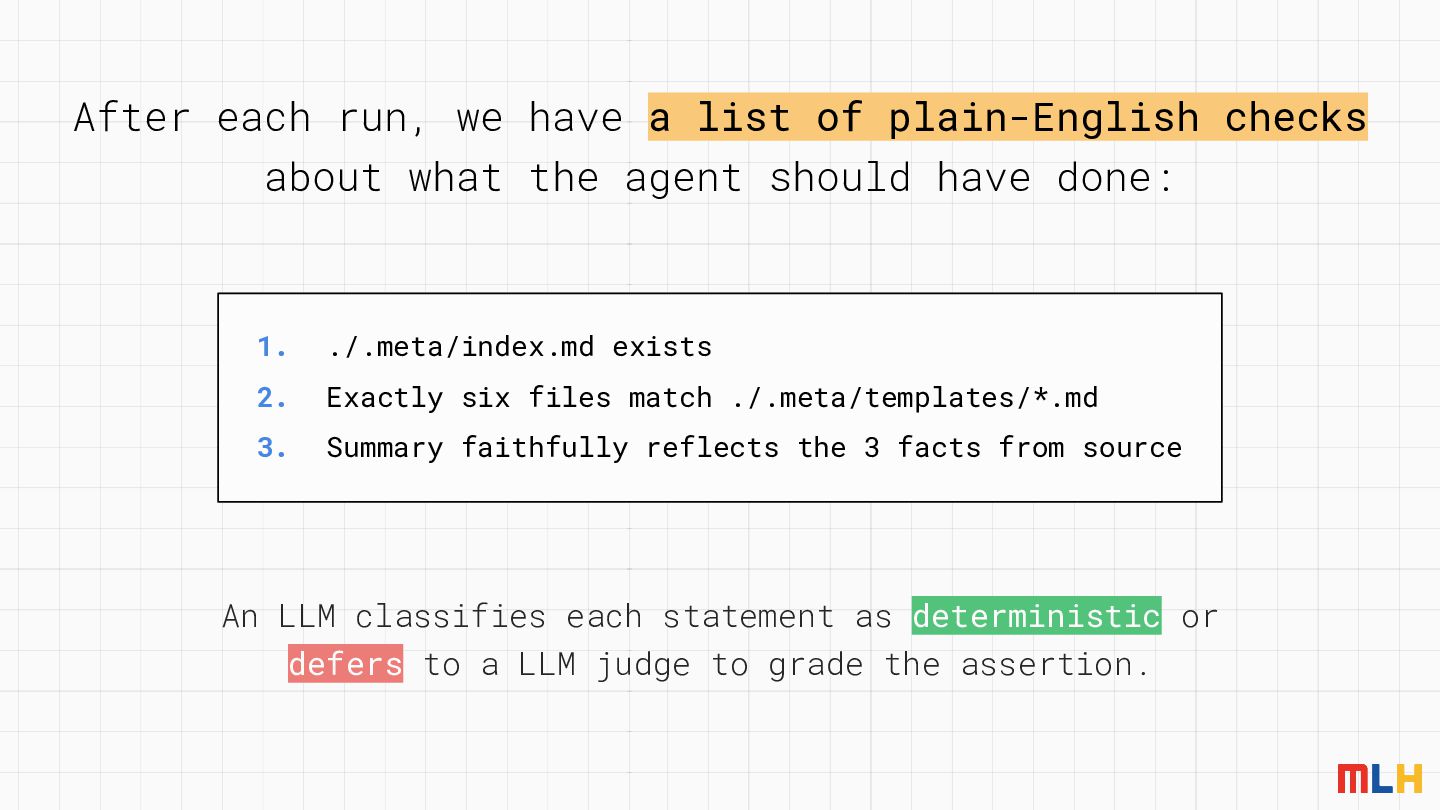
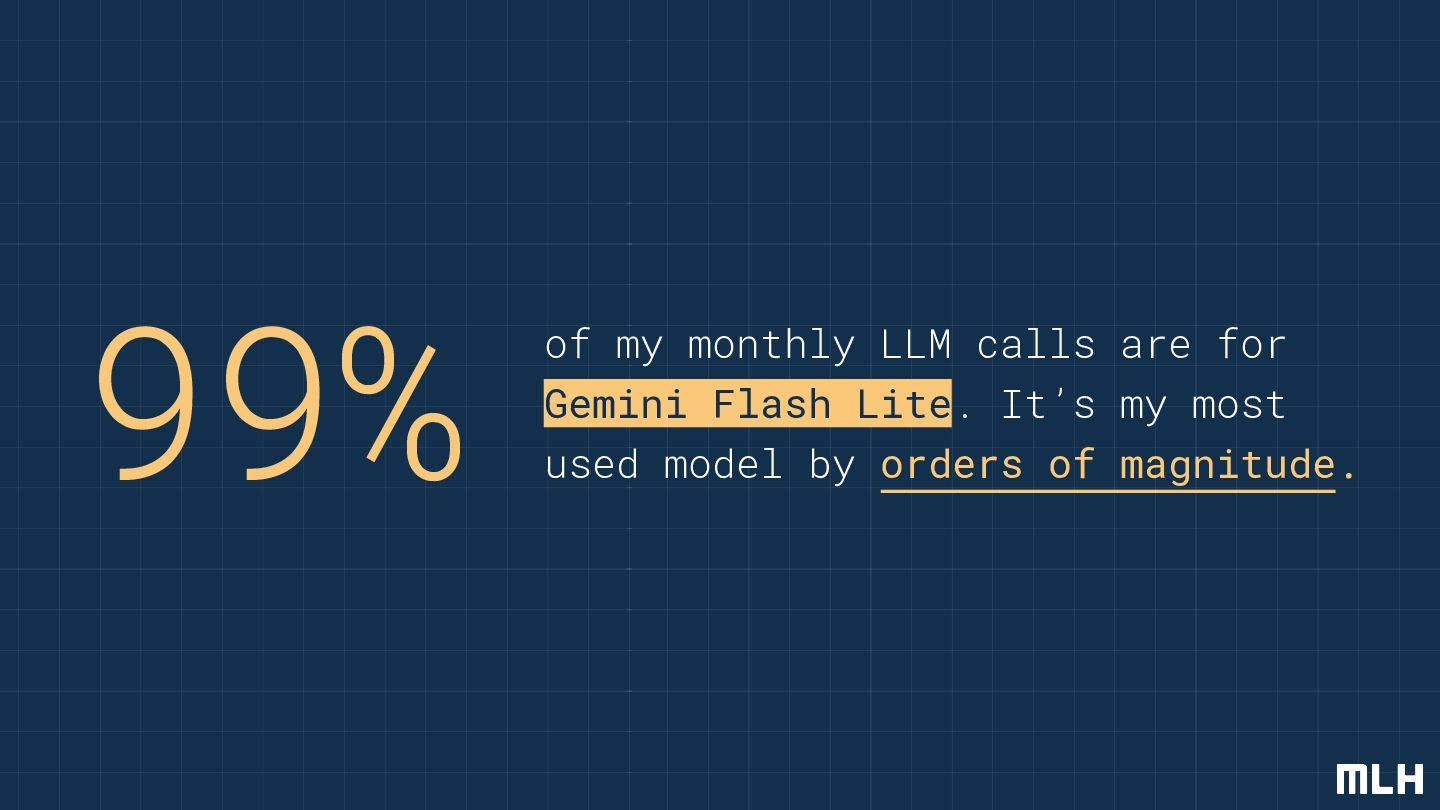
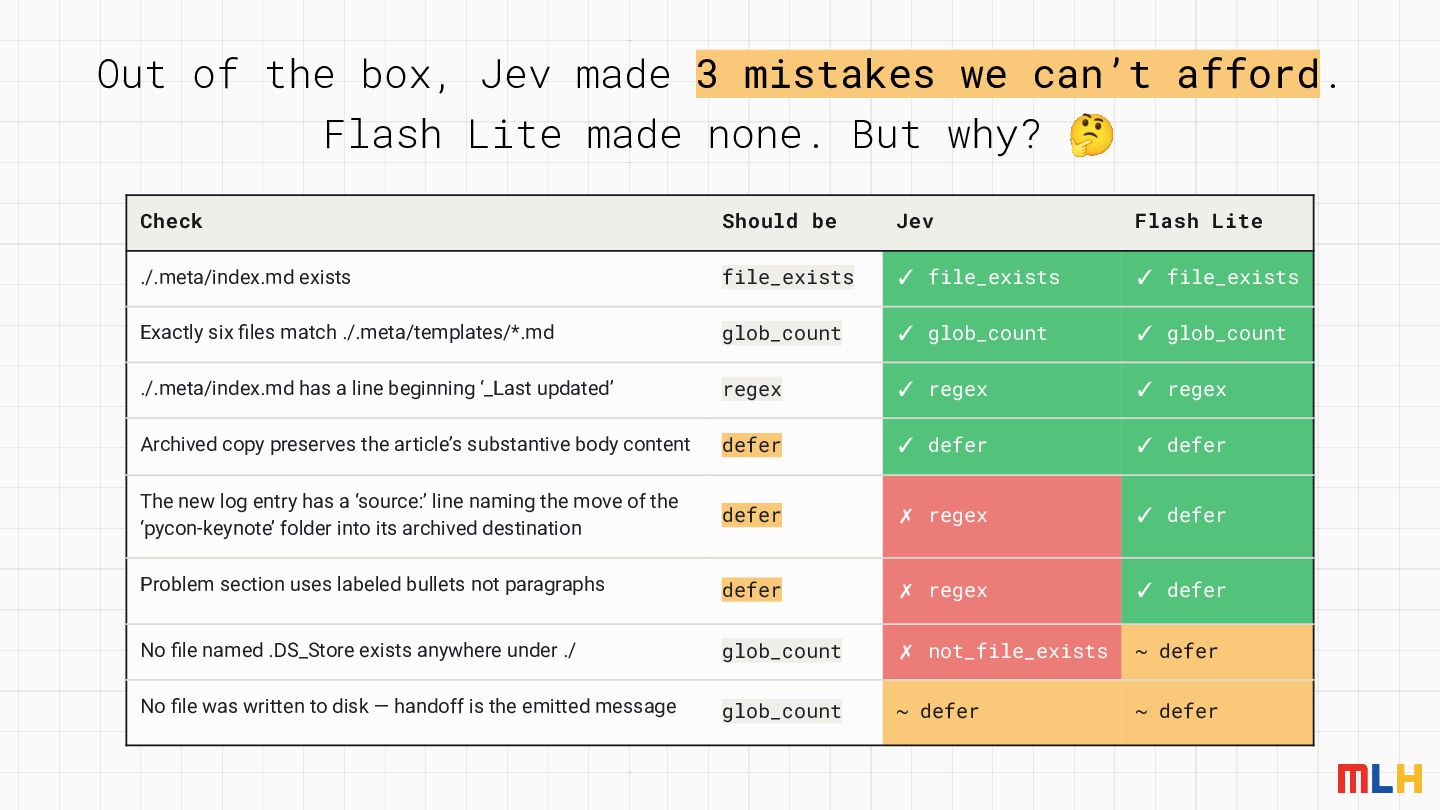
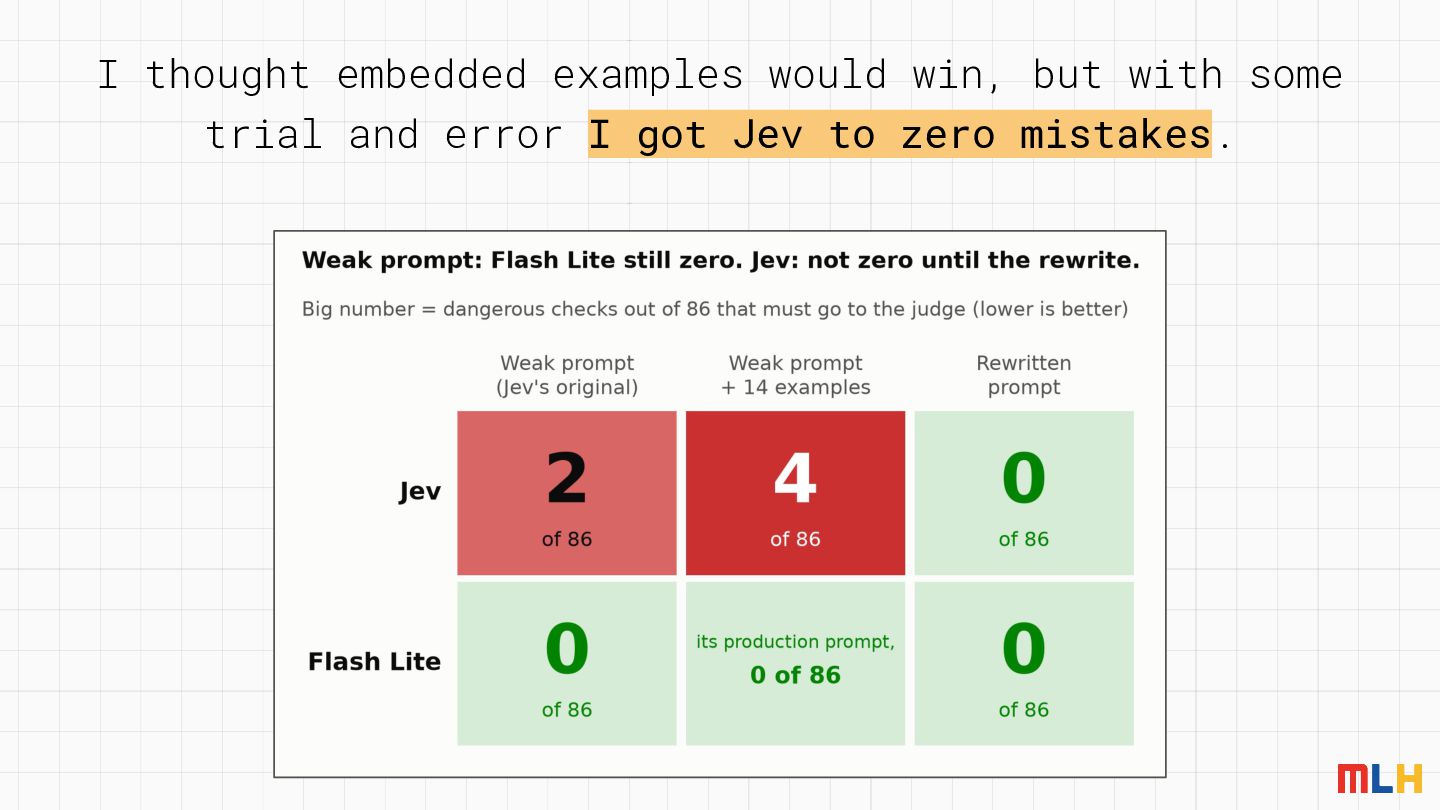
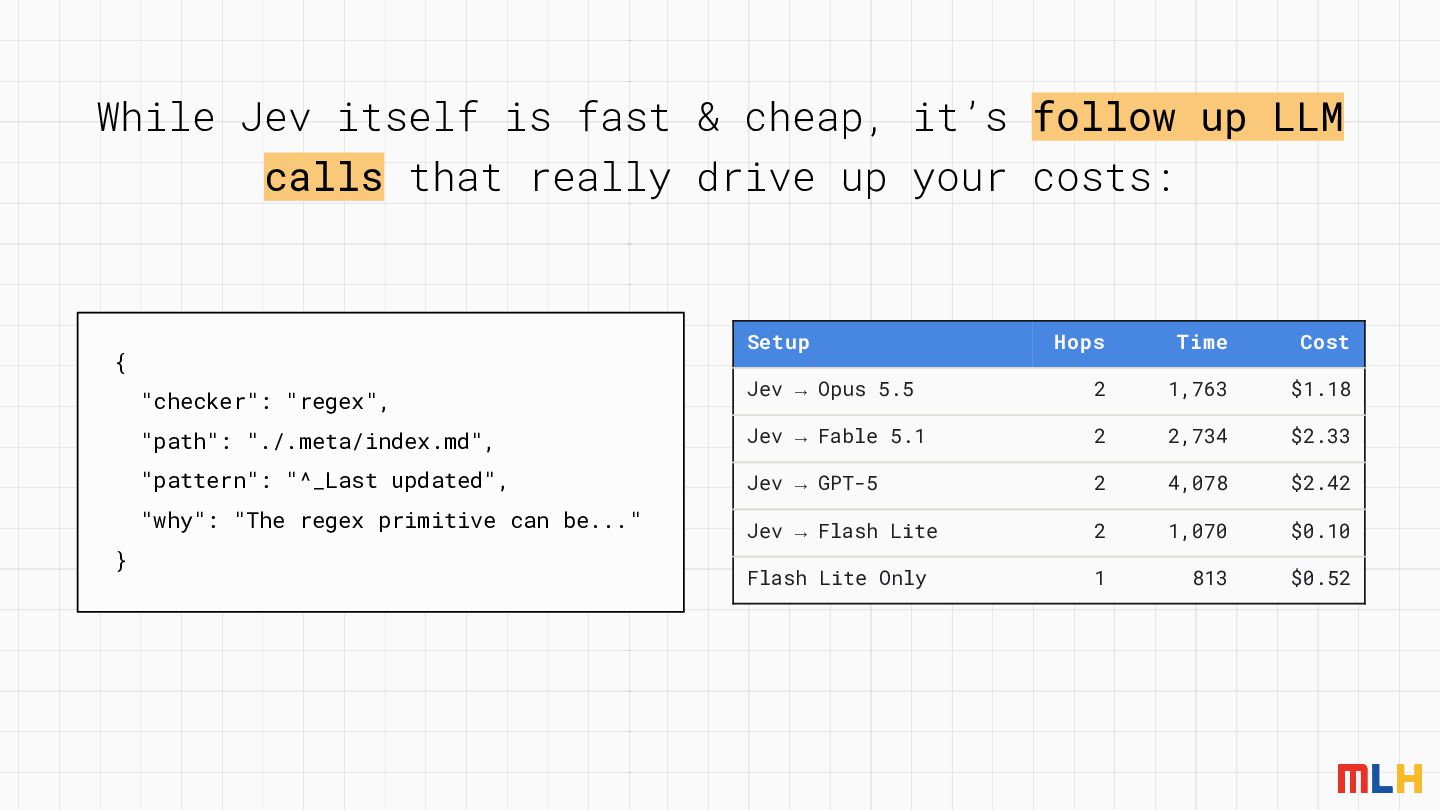
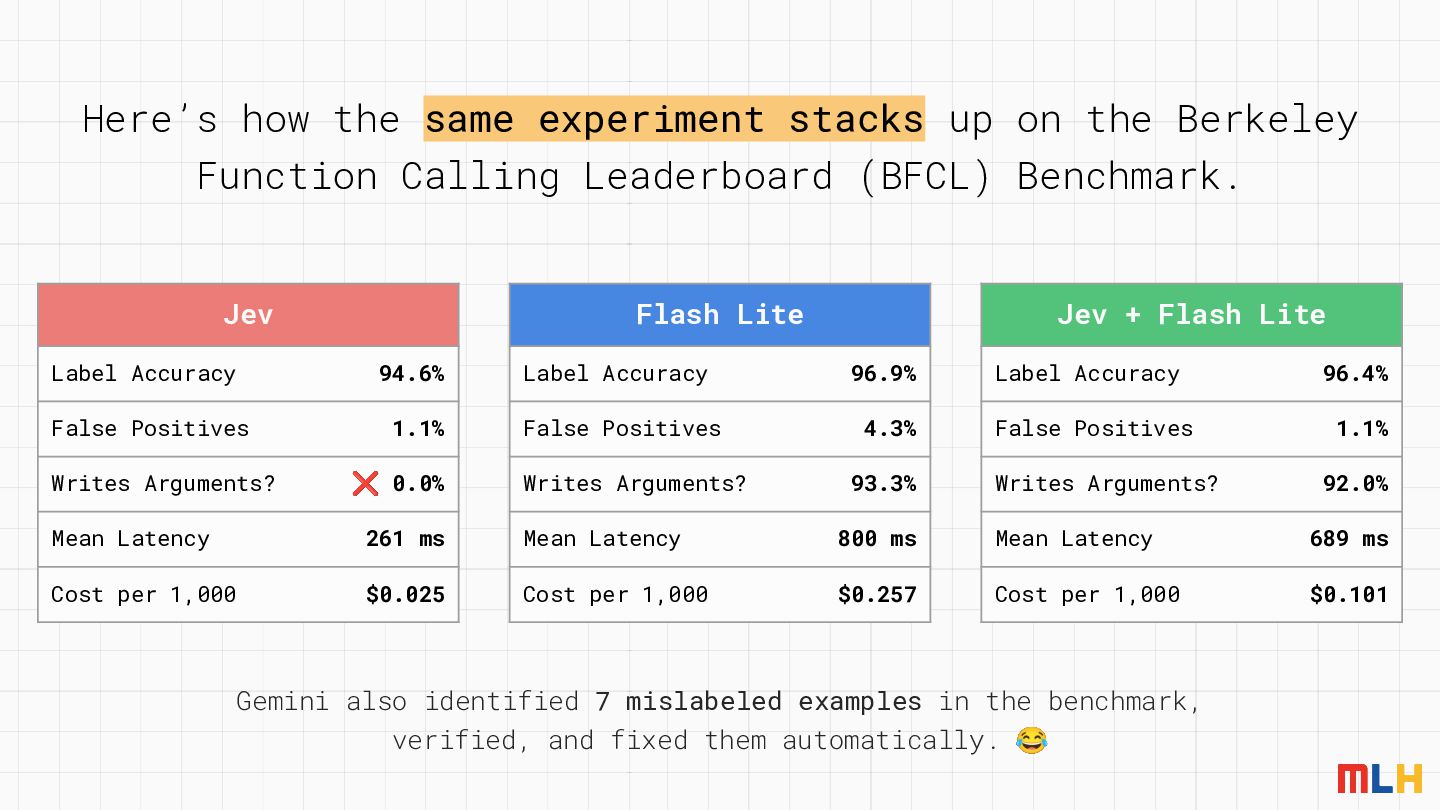
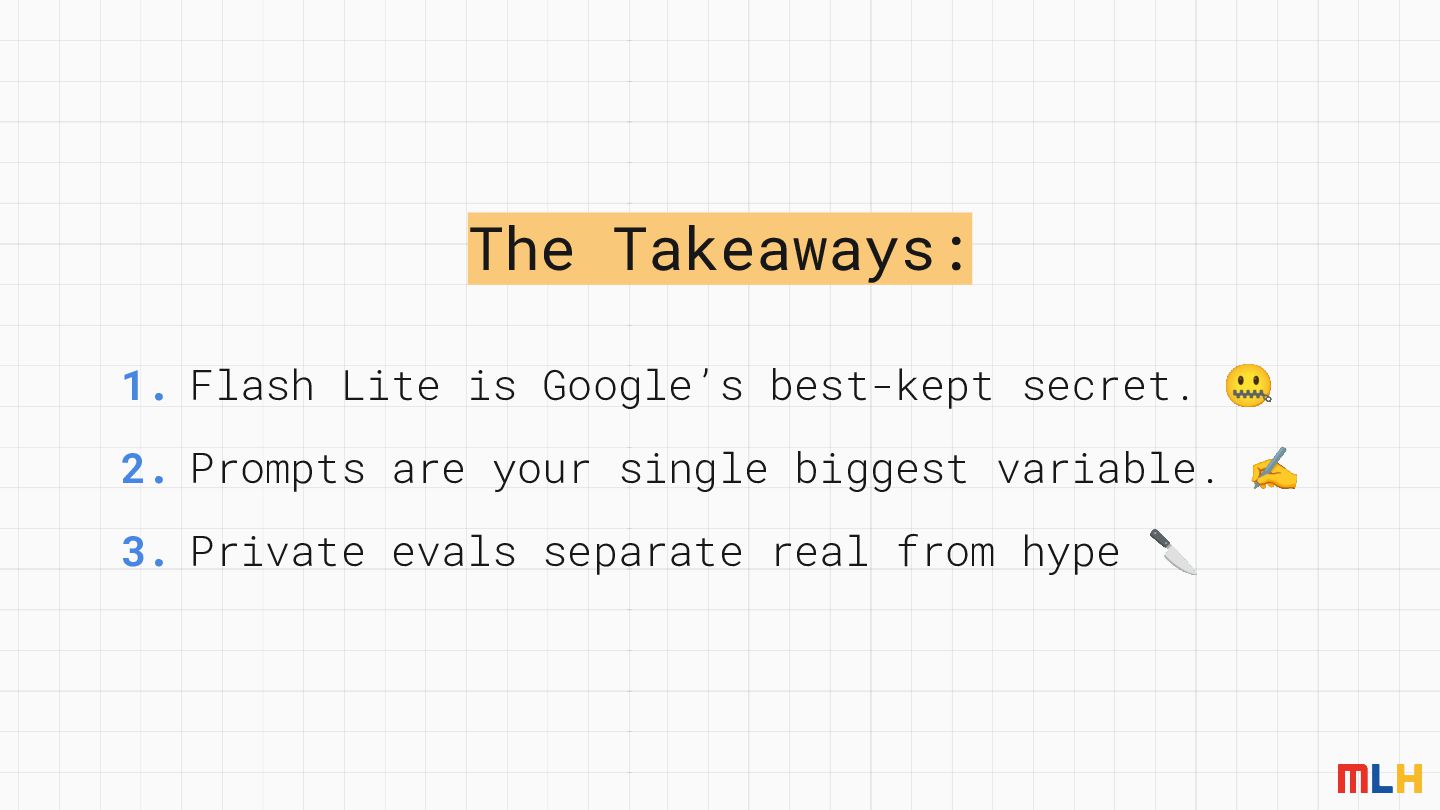
I build benchspec, a tool that grades AI agents. Its trickiest job is reading each plain-English test (“exactly 6 files match templates/*.md”) and deciding whether a quick script can check it or it needs a paid AI grader. I tried swapping the model that makes that call, Gemini Flash Lite, for Jev. On paper Jev won: 15x cheaper, a third faster, and just as accurate. The catch is that Jev isn’t generative. It can say “count the files,” but it can’t write the pattern or the number the script needs, so every answer needs a second model call before it’s useful. Flash Lite does both in one call. Live, I’ll show the head-to-head results, replay Jev’s misses in the Jev Playground, and walk through the prompt rewrite that got Jev to zero dangerous mistakes.


 theycallmeswift
 shisyu_gaku
 aoto
 oracle4engineer
 sansantech
 tsukuboshi
 mkdev10
 furuton
 nayuts
 mochizuki875
 ichiki1023
 ufried
 jacobtomlinson
 aleyda
 reverentgeek
 aemeredith
 katarinadahlin
 baasie
 ryanjones
 dougneiner
 tammyeverts
 rabernat
 maggiecrowley