Making Connections: Artificial Intelligence mee...

Making Connections: Artificial Intelligence meets Abstract Ingenuity using NYT Connections by Uyi Uwadiae
What happens when you pit eight leading AI models against The New York Times Connections puzzle?
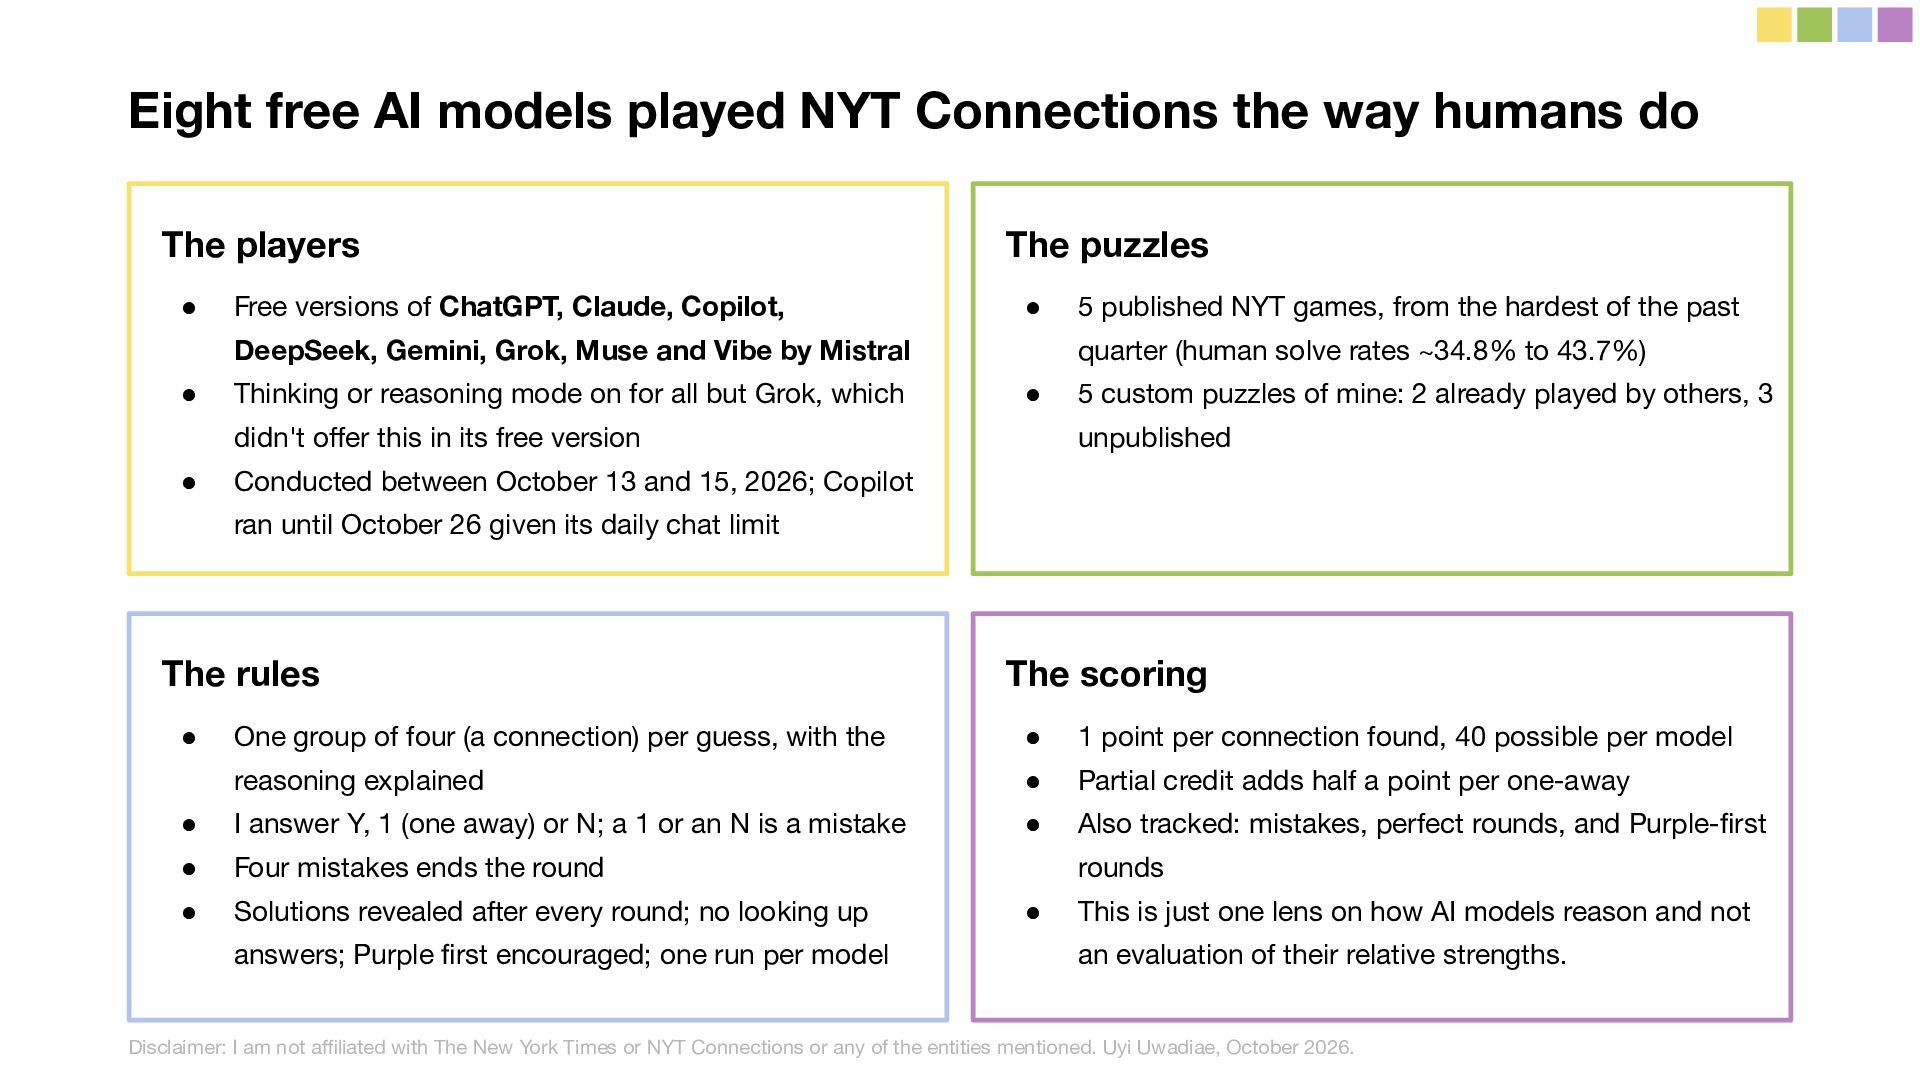
In this data-driven experiment, I tested free versions of Gemini, Claude, DeepSeek, Vibe by Mistral, Copilot, ChatGPT, Muse, and Grok across 10 rigorous rounds of Connections—combining 5 historically difficult published NYT games with 5 original custom puzzles designed to test zero-shot lateral thinking.
Key Highlights & Findings:
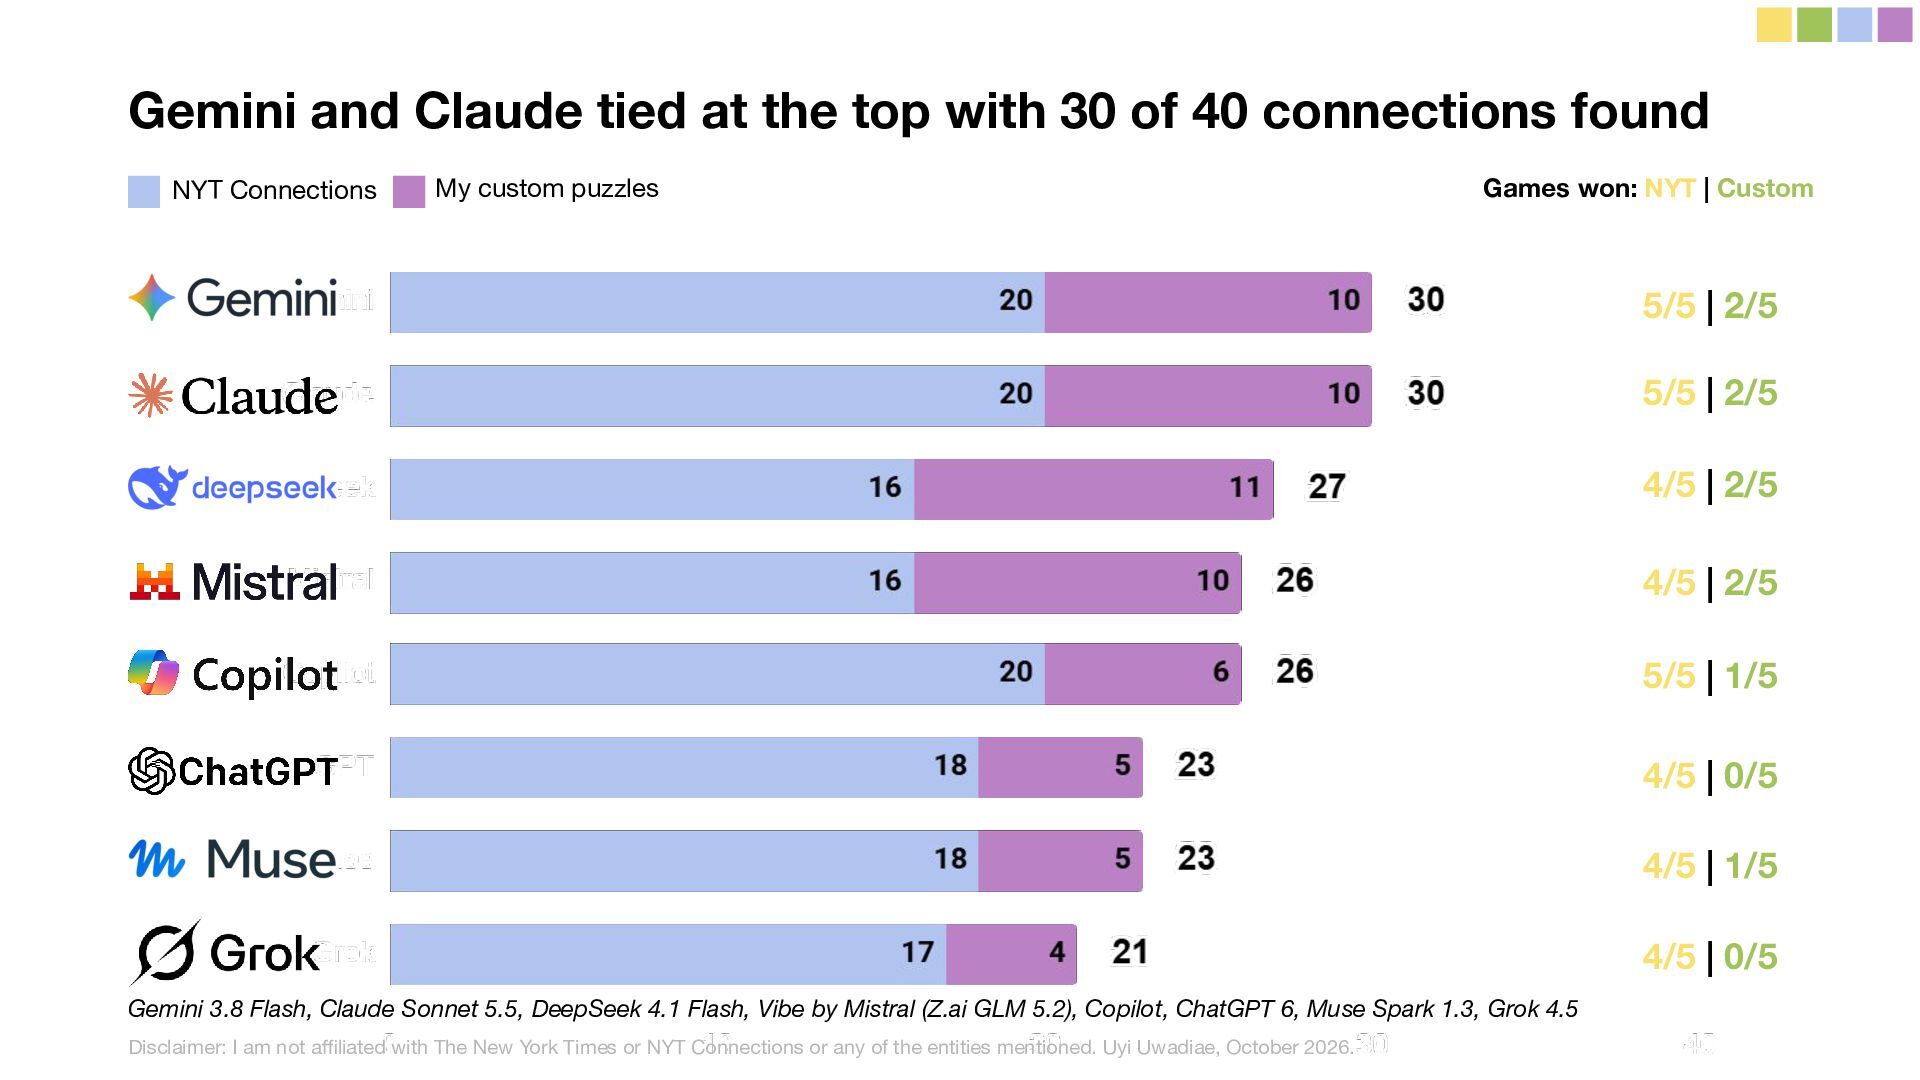
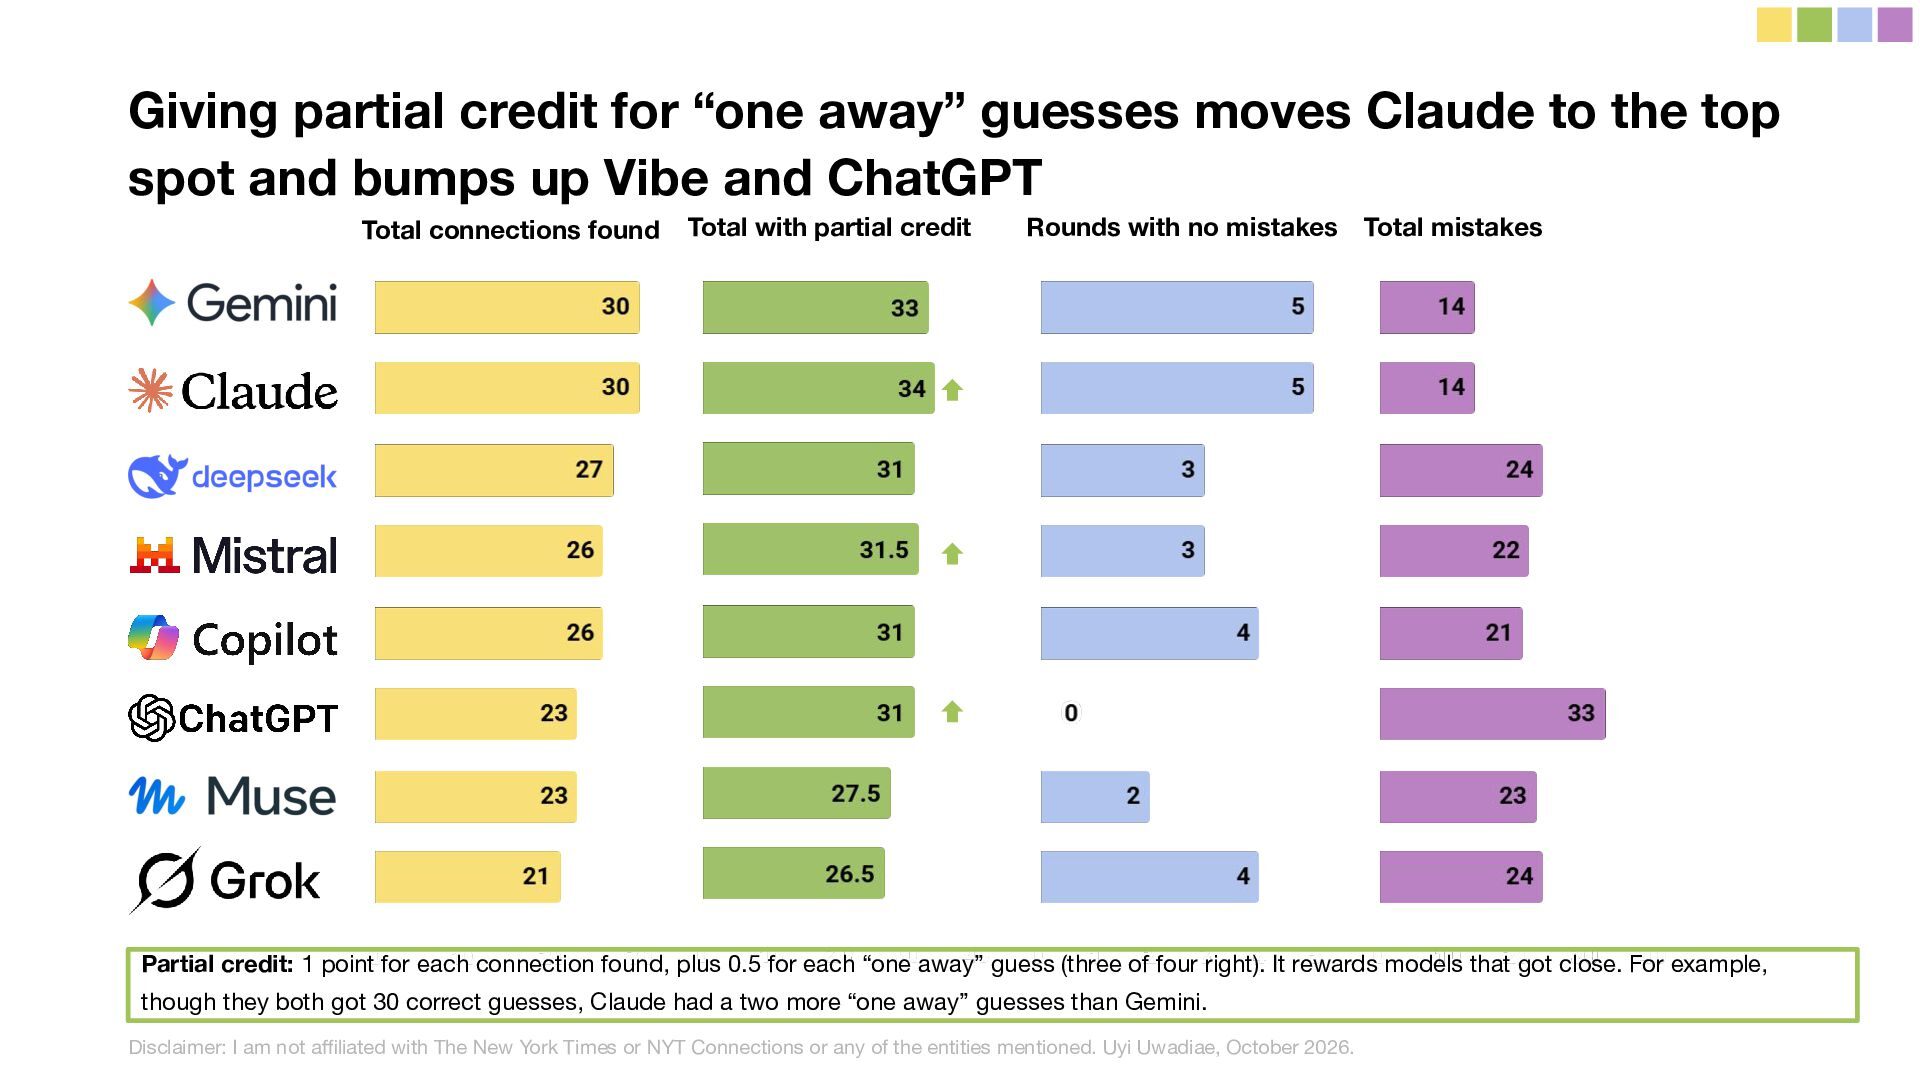
The Top Tier: Gemini and Claude tied for the most connections found (30/40), with Claude taking the top spot when factoring in partial credit for "one-away" guesses.
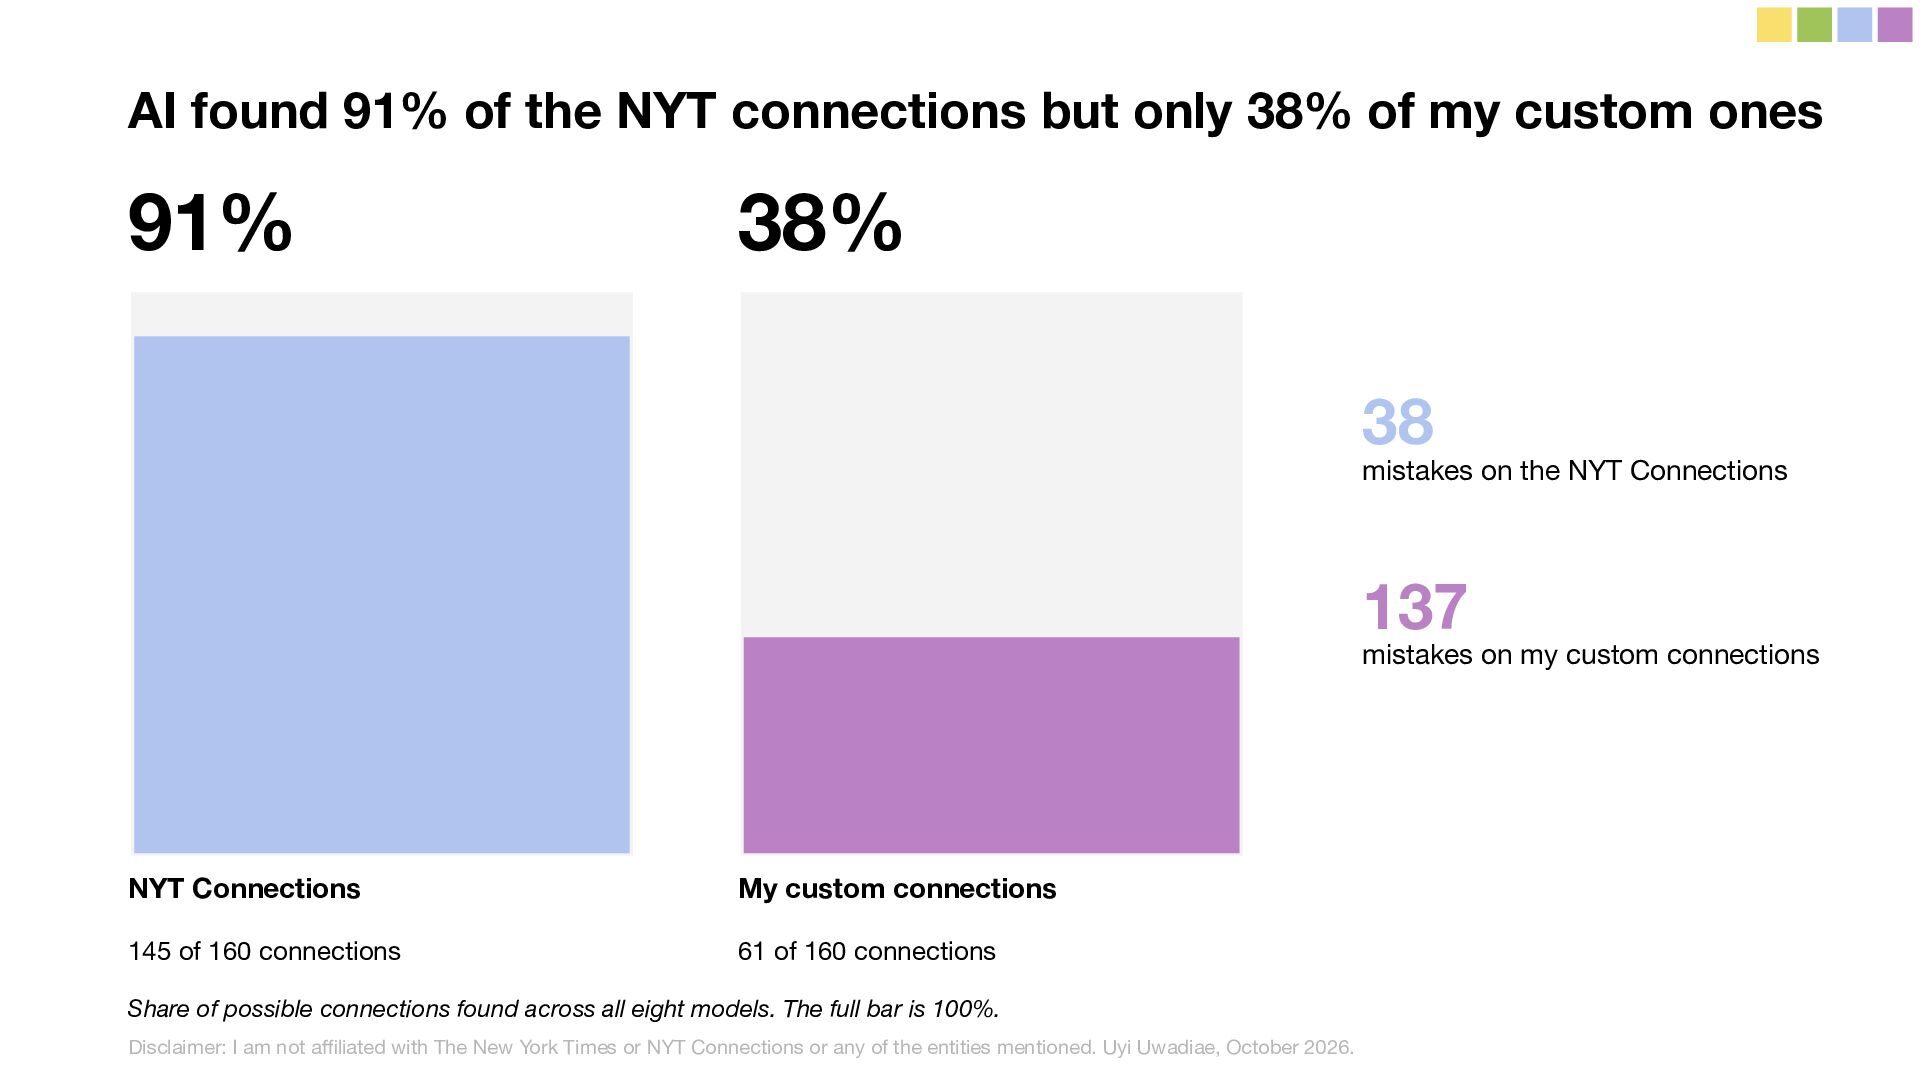
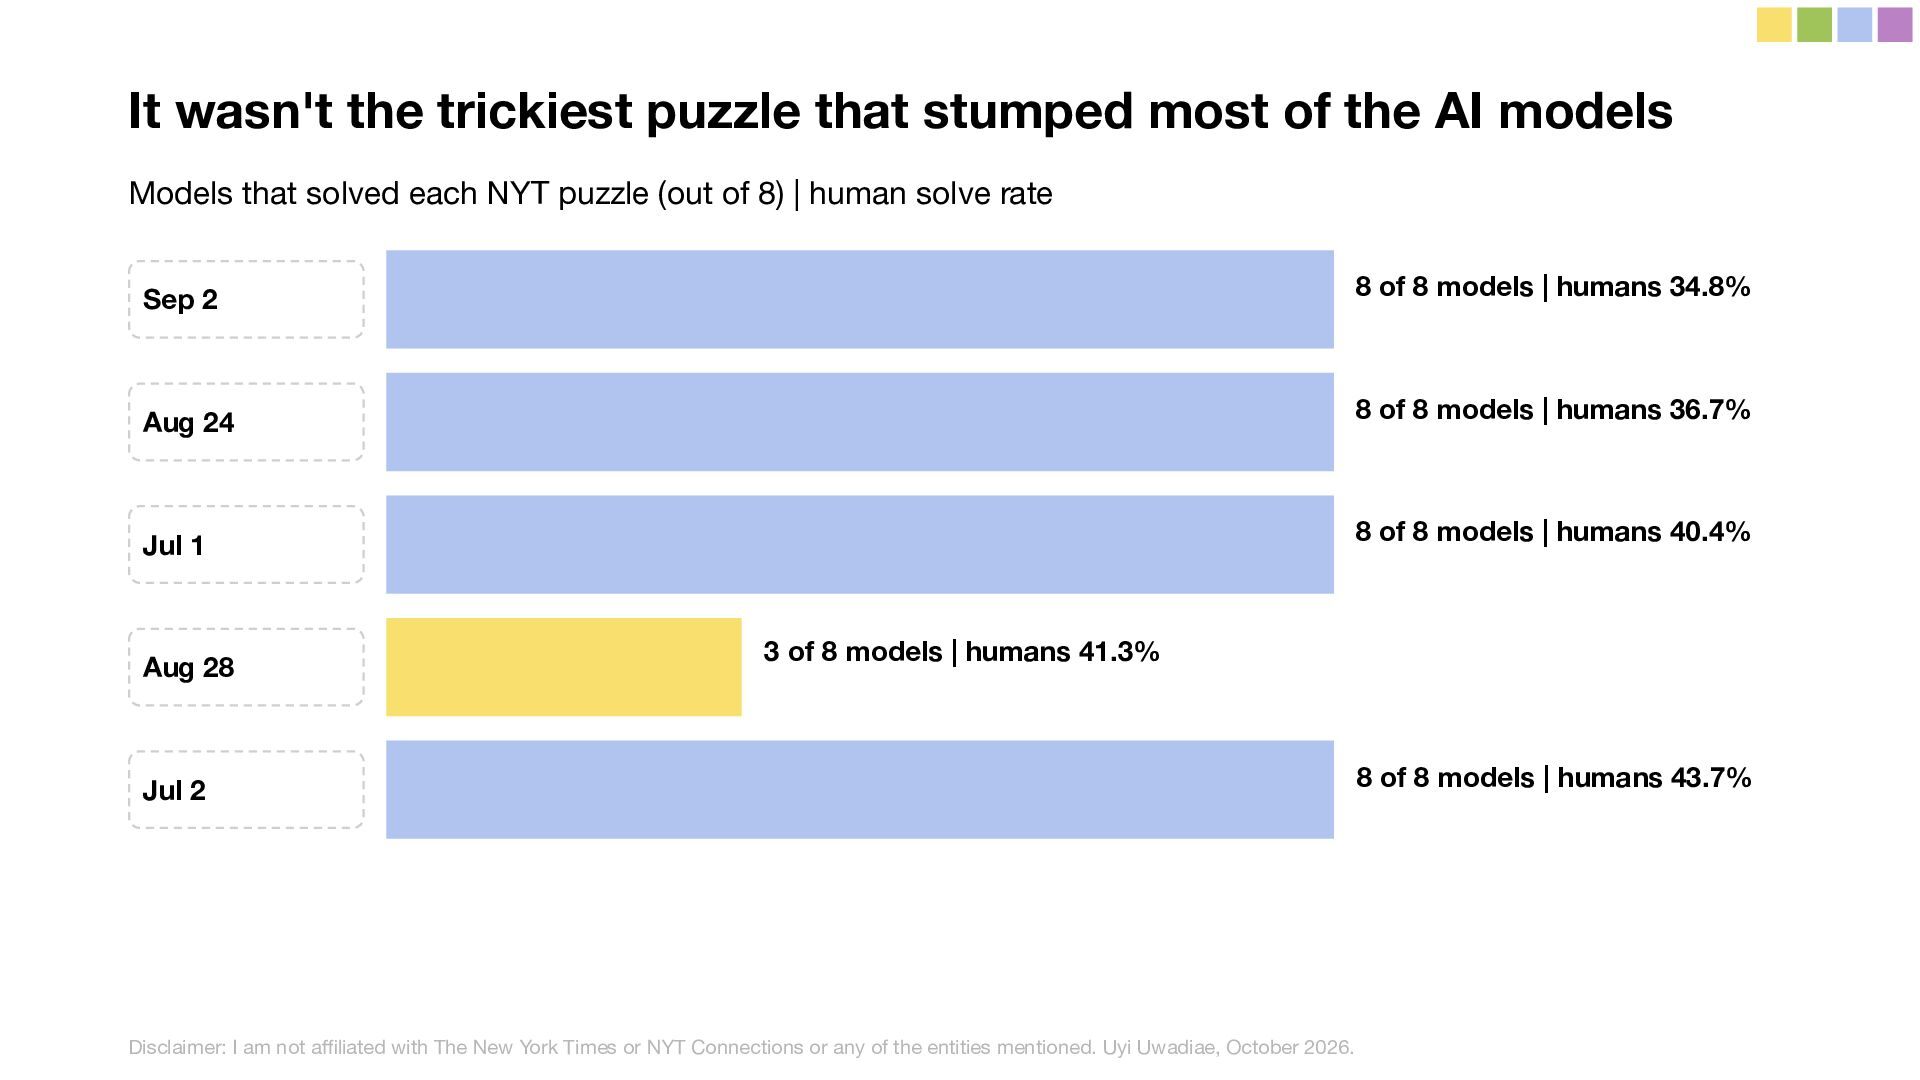
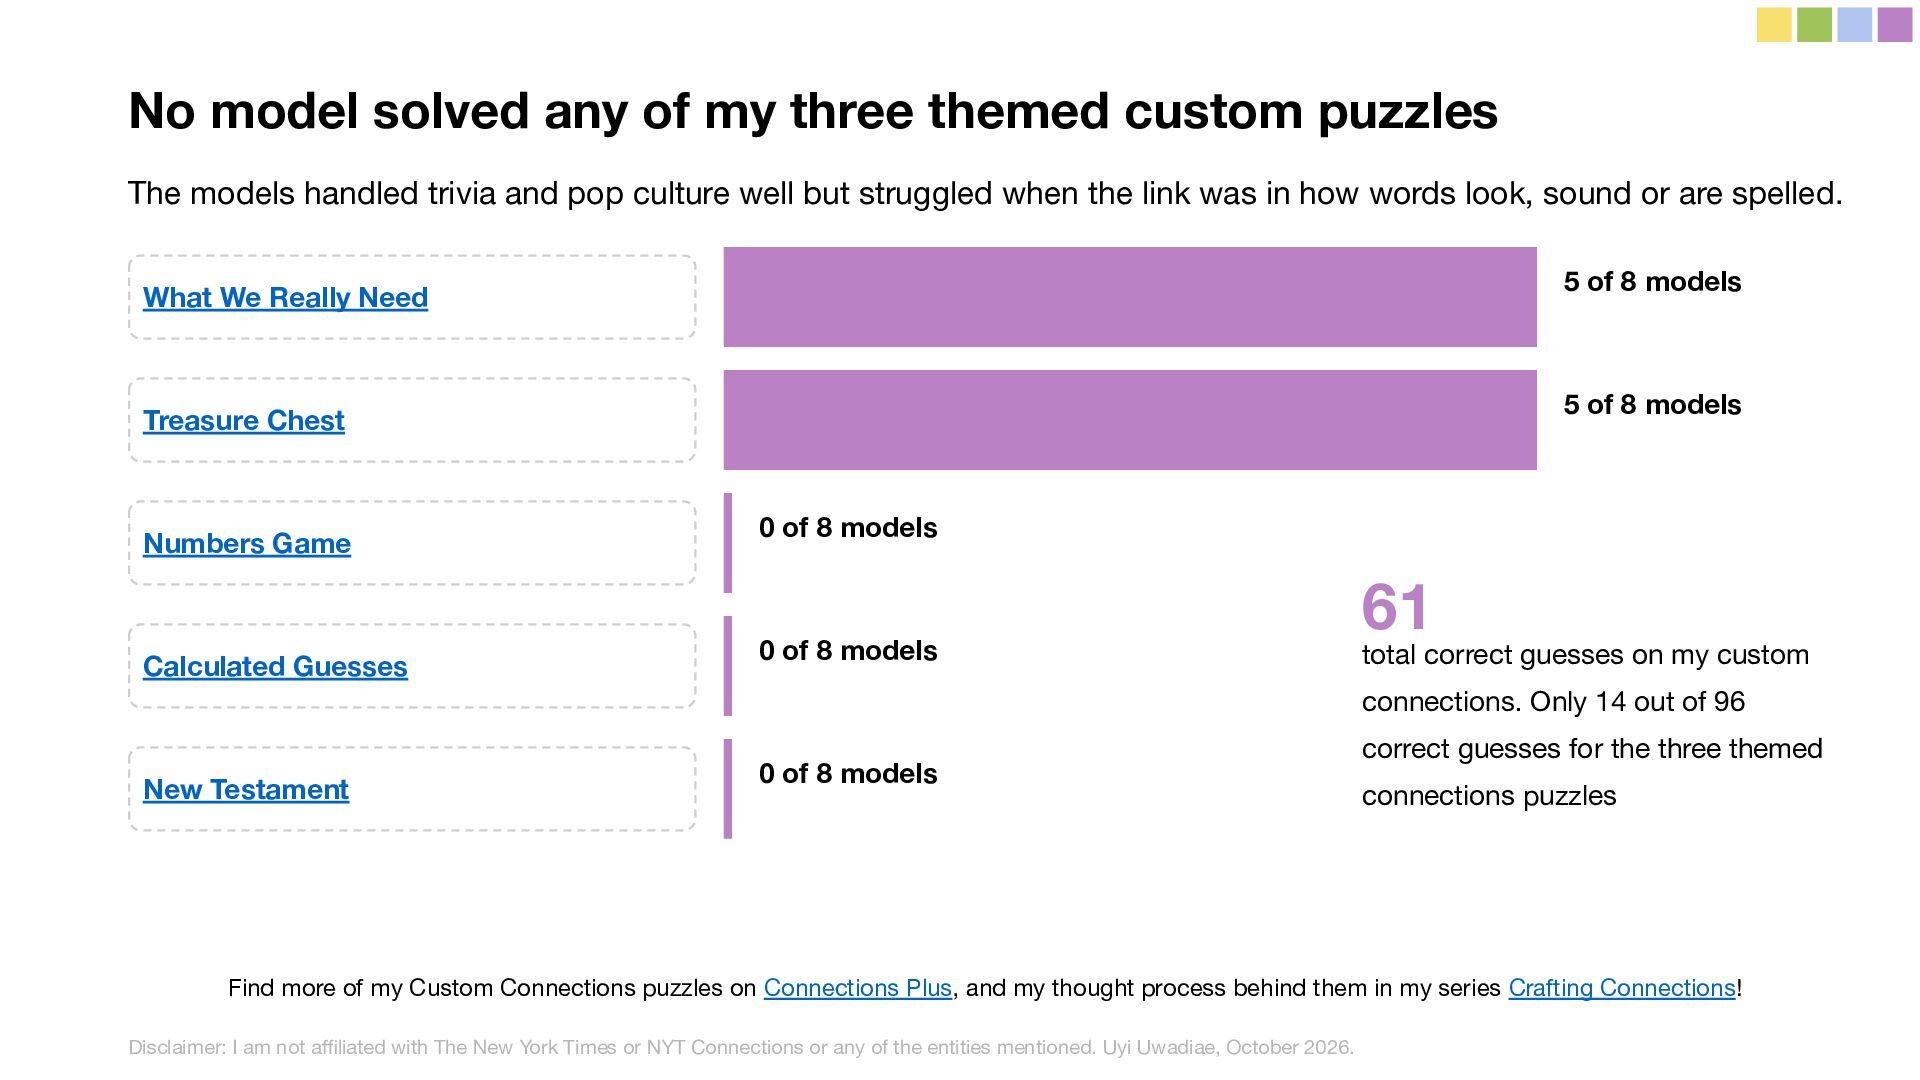
The Custom Puzzle Wall: While models successfully cleared 91% of official NYT boards, they hit a 100% impenetrable cognitive wall on non-semantic, visual, and structural custom puzzles (0/8 on themed boards) due to tokenization blind spots.
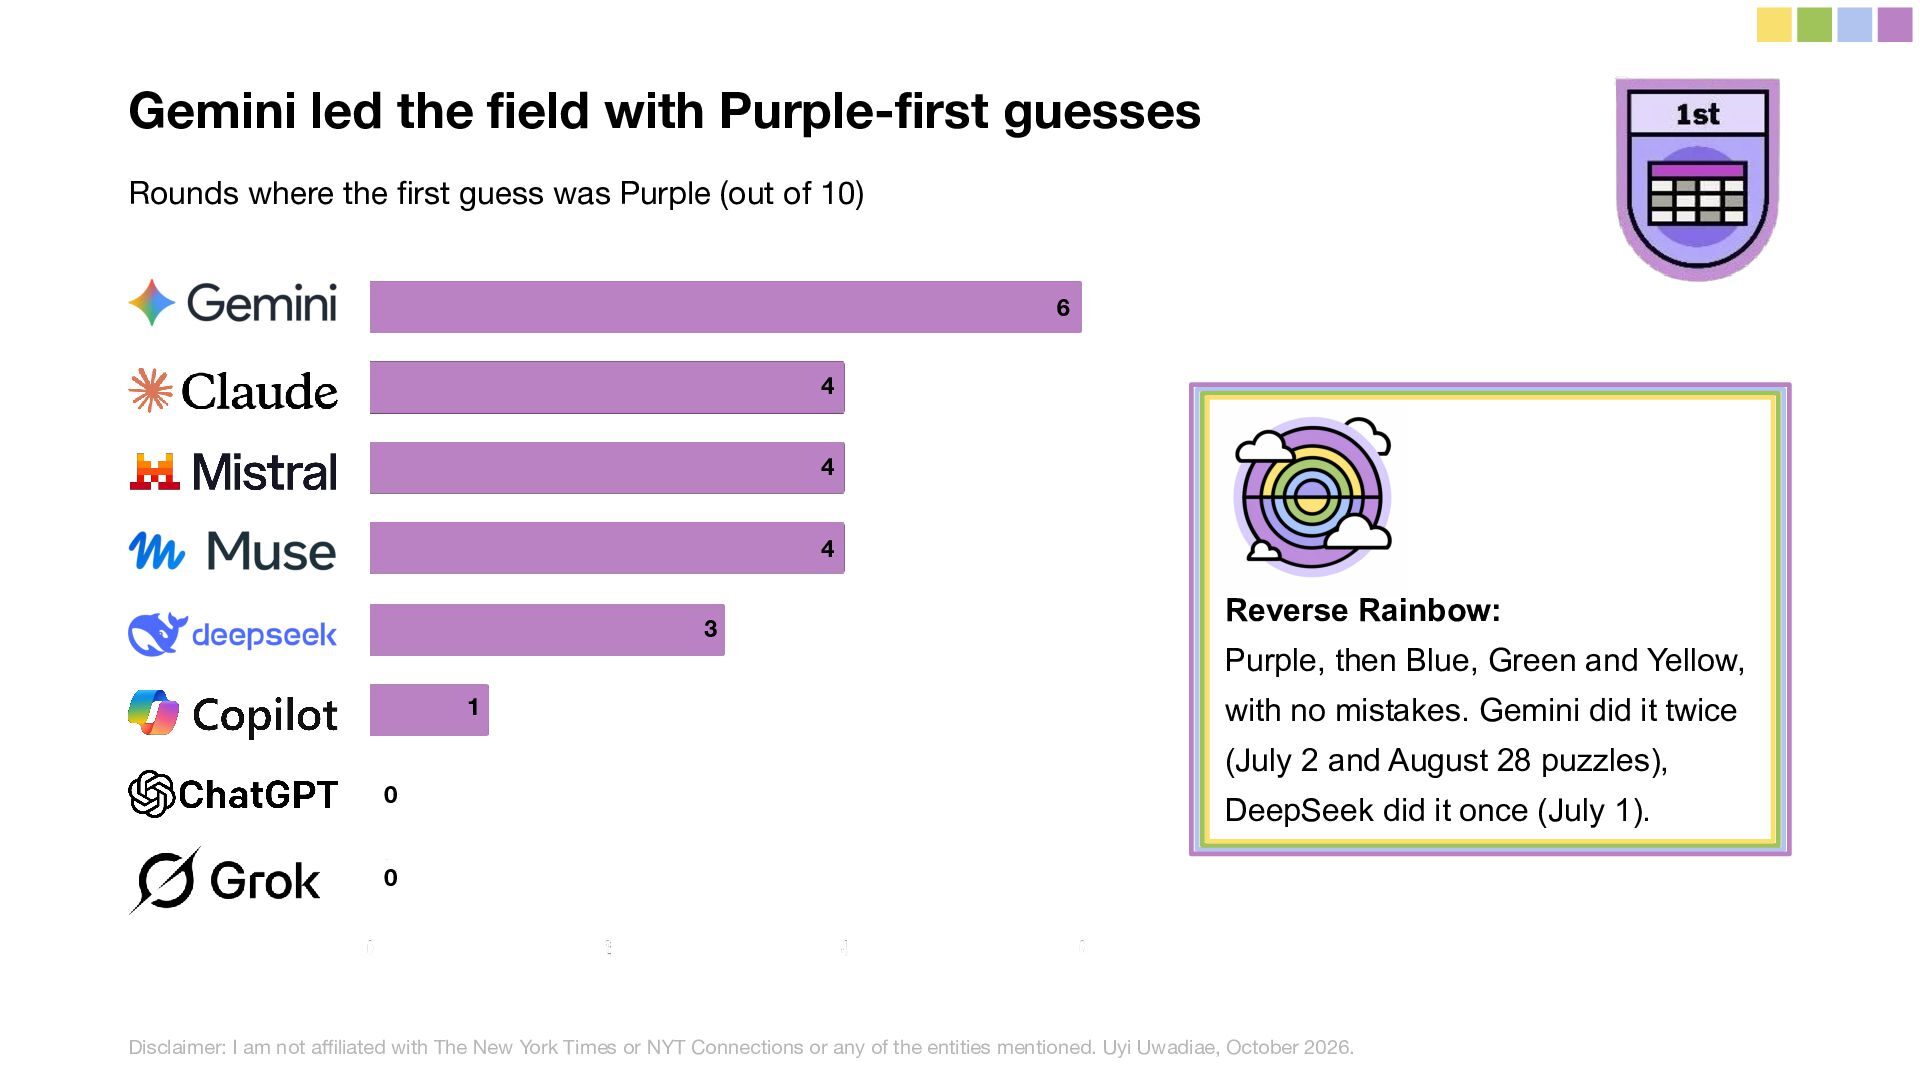
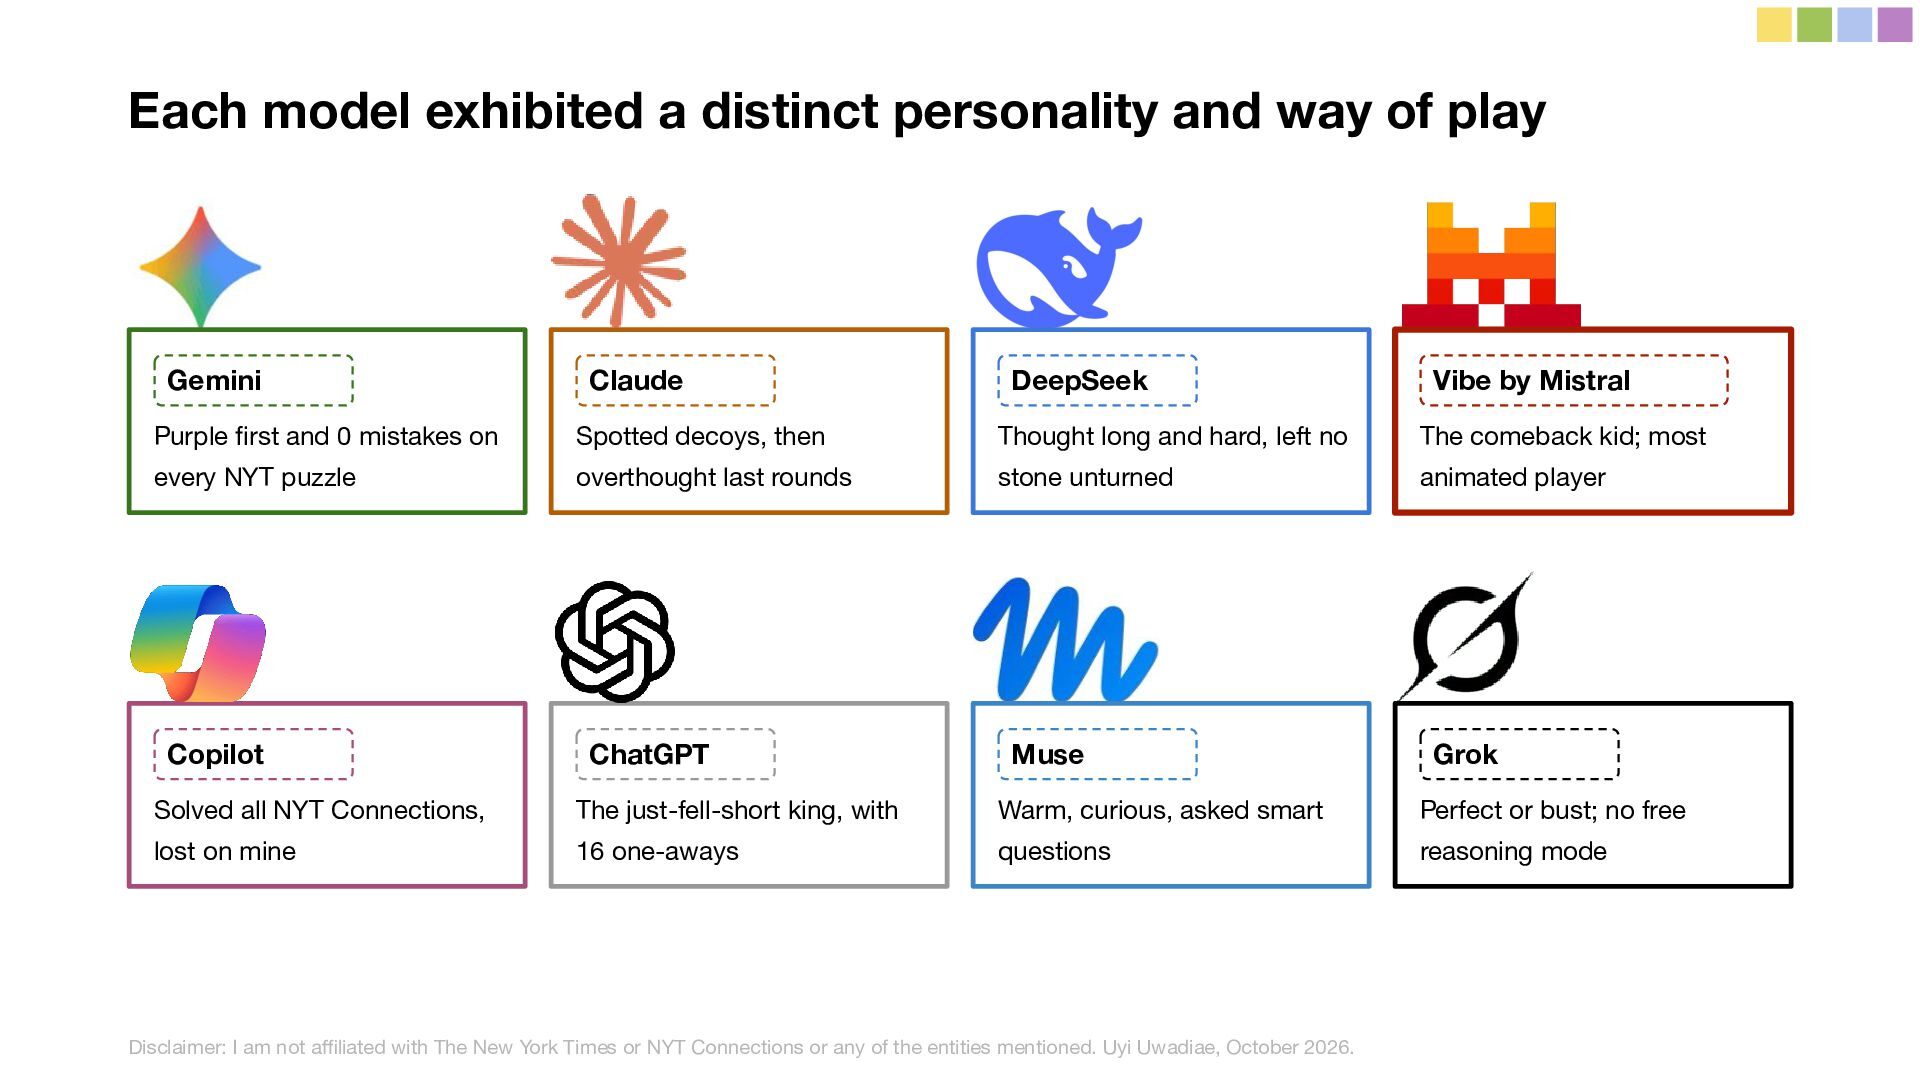
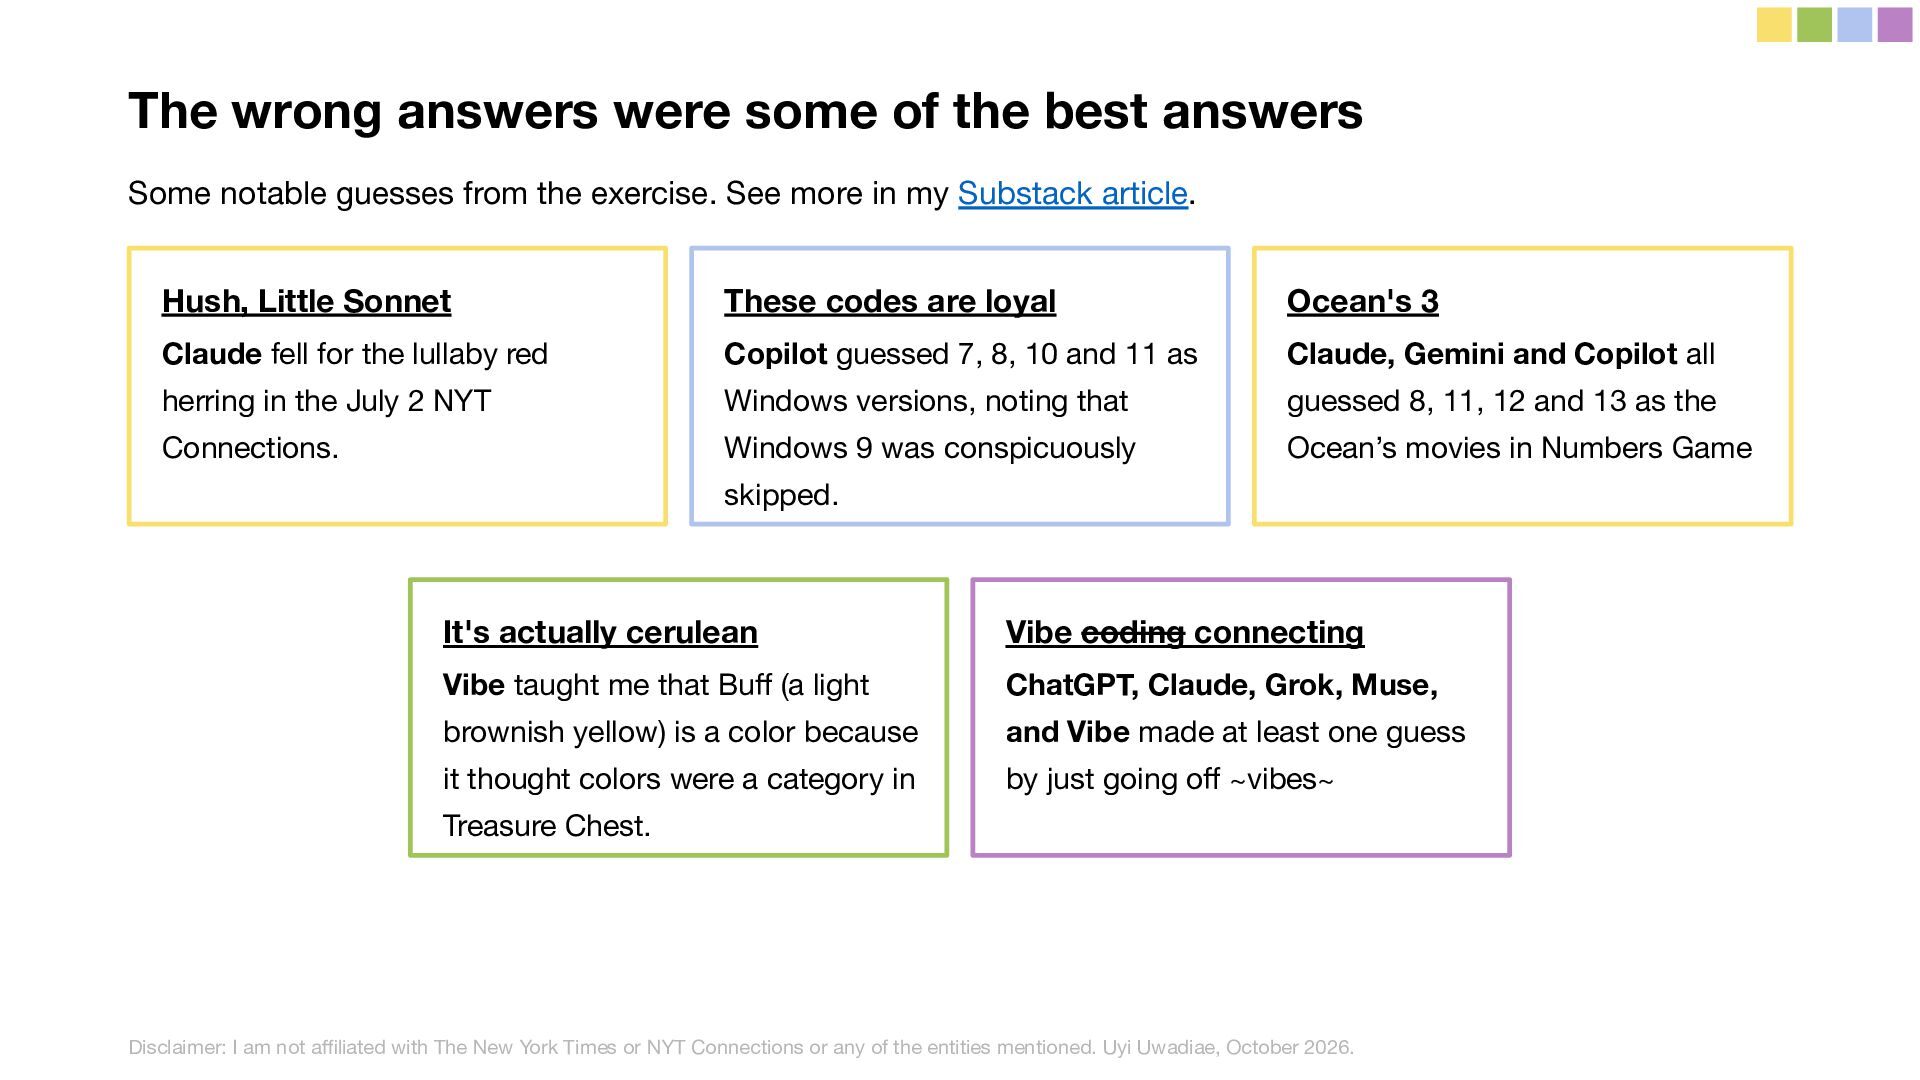
Model Personalities & Quirks: From Gemini’s aggressive "Purple-first" hunting to ChatGPT's 16 near-miss "one-aways" and Copilot's hilarious Windows version hallucinations, each model exhibited a distinct behavioral play style.
Ultimately, this benchmark illustrates why generative AI excels at semantic pattern retrieval, but why true lateral creativity, visual intuition, and abstract wordplay remain uniquely human.
Check out my companion essays and the Crafting Connections series on Substack and Medium!

 uyiuwadiae
 orimanabu
 lycorptech_jp
 tkito
 ginjihayashi
 takano0131
 kamadamakoto
 nejumi
 visional_engineering_and_design
 falken
 shotashiratori
 bulbulpaul
 ryudai
 davidcarrasco
 hannesfritz
 codingconduct
 katarinadahlin
 addyosmani
 ryanjones
 katiecoart
 thirion
 akademiya2063
 bcantrill
 pwiseman
 stephenakadiri