Share
Embed
Faster, Practical GLL Parsing
Presented at Compiler Construction (CC) 2015 in London.
Event link: http://www.etaps.org/index.php/2015/cc
Iguana Parsing Framework: https://github.com/iguana-parser

Ali Afroozeh
April 17, 2015
Transcript
97 slides
-
Faster, Practical GLL Parsing Ali Afroozeh and Anastasia Izmaylova The
foundation of the Iguana parsing framework -
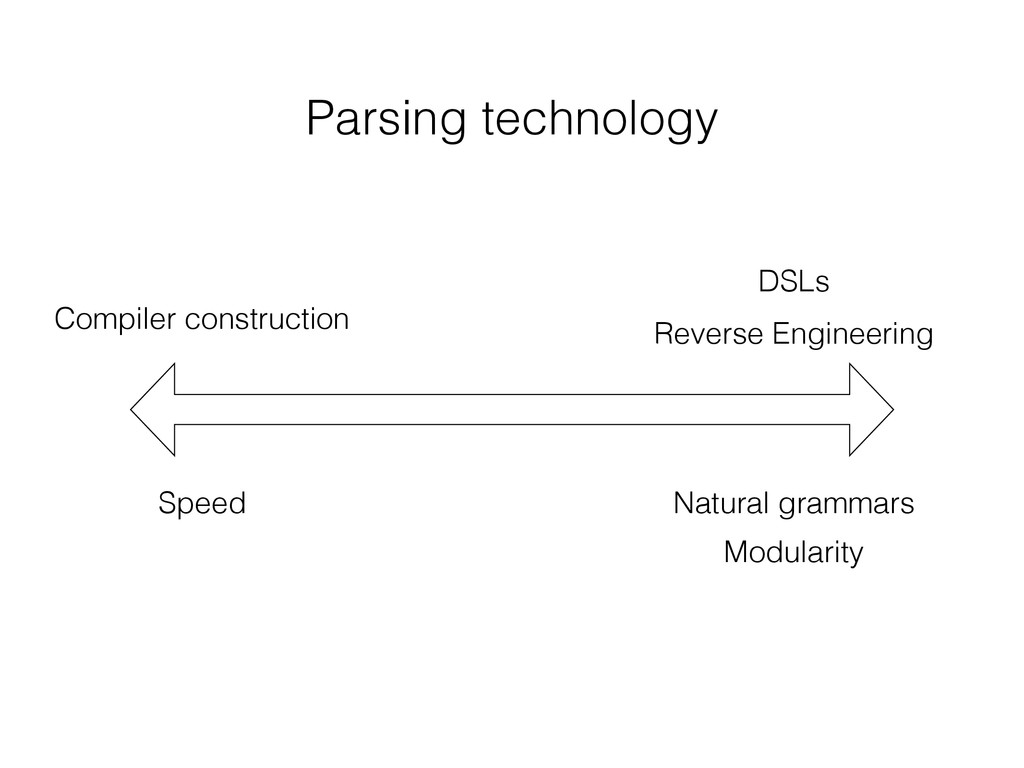
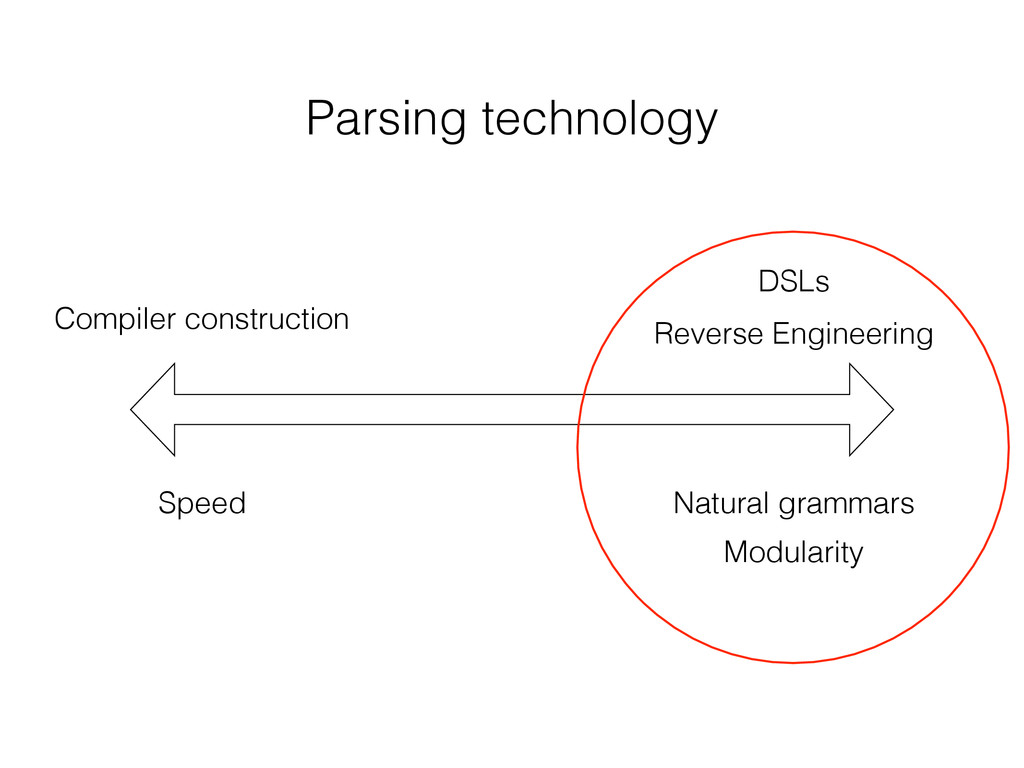
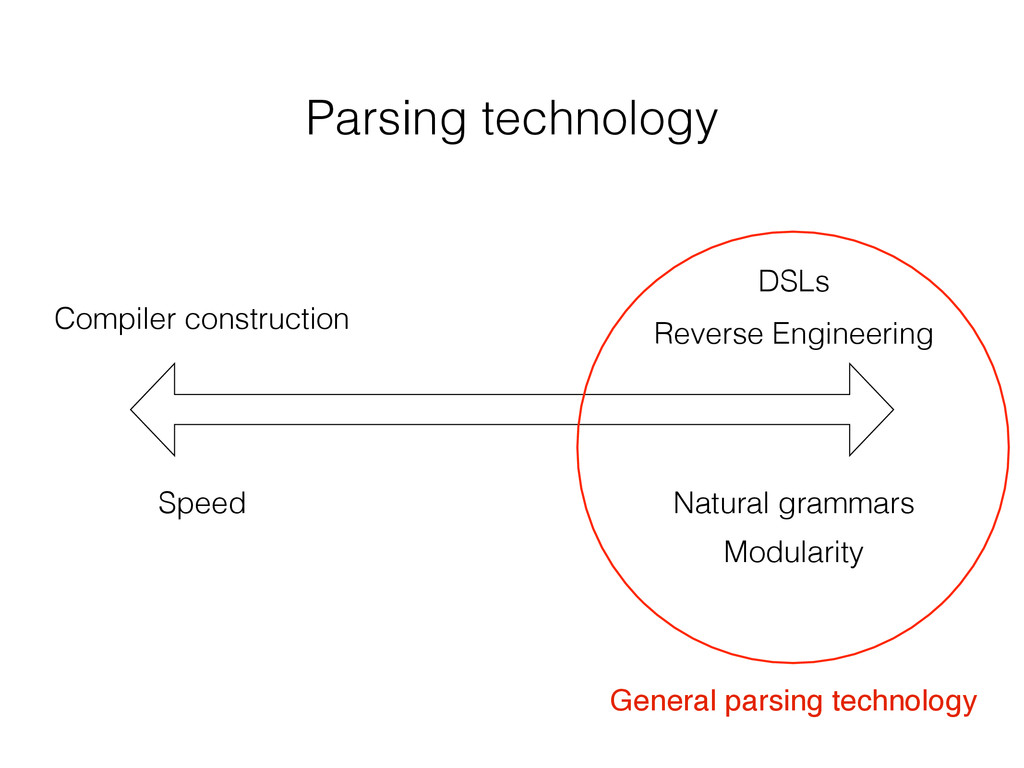
Parsing technology Compiler construction DSLs Reverse Engineering Speed Natural grammars
Modularity General parsing technology -
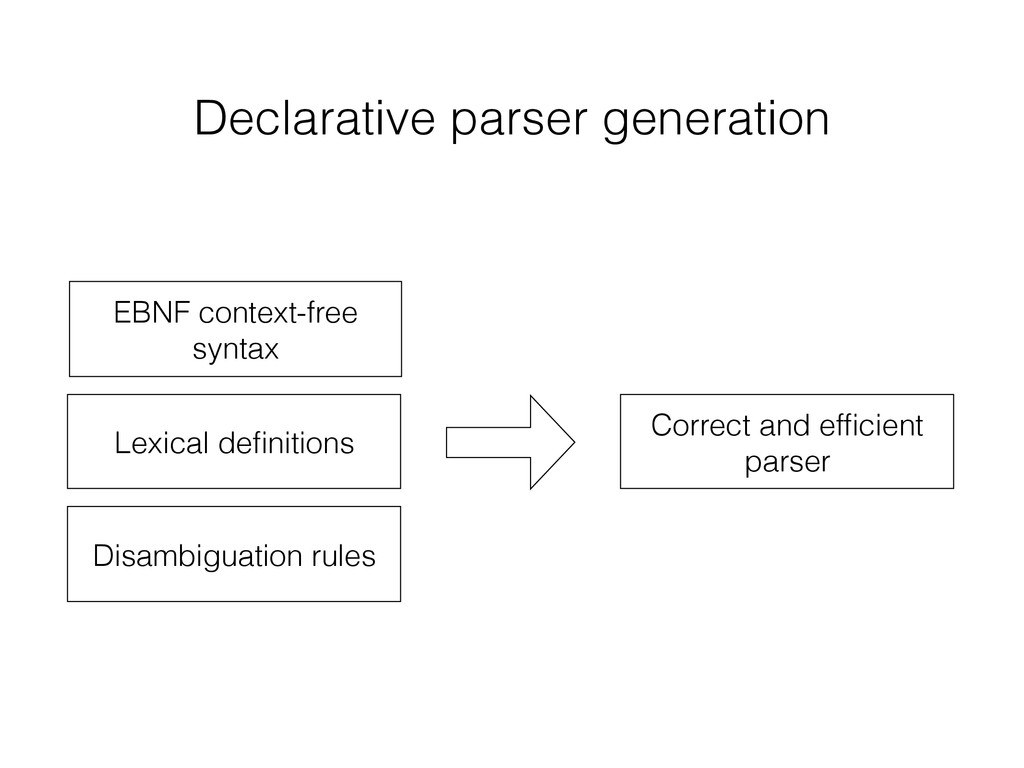
Declarative parser generation EBNF context-free syntax Disambiguation rules Lexical definitions
Correct and efficient parser -
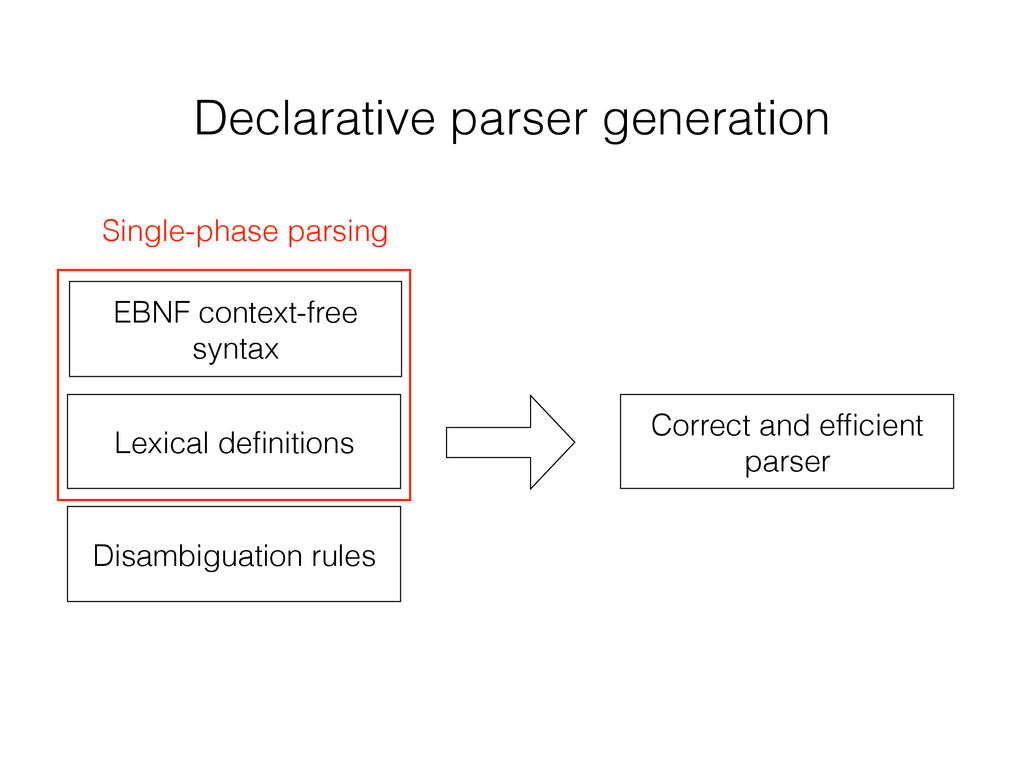
Declarative parser generation EBNF context-free syntax Disambiguation rules Lexical definitions
Correct and efficient parser Single-phase parsing -
• Performance improvement of GLL parsing • Efficient implementation of
GLL parsing Contributions -
• Performance improvement of GLL parsing • Efficient implementation of
GLL parsing • Implementation of lexical disambiguation filters Contributions -
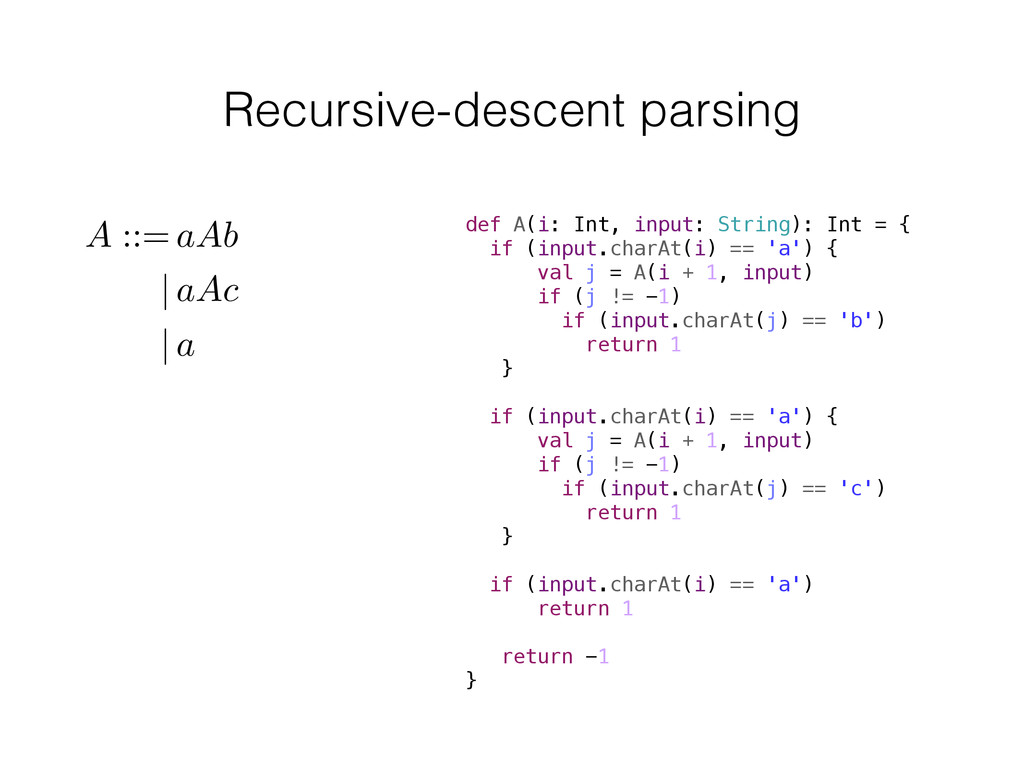
def A(i: Int, input: String): Int = { if (input.charAt(i)
== 'a') { val j = A(i + 1, input) if (j != -1) if (input.charAt(j) == 'b') return 1 } if (input.charAt(i) == 'a') { val j = A(i + 1, input) if (j != -1) if (input.charAt(j) == 'c') return 1 } if (input.charAt(i) == 'a') return 1 return -1 } A ::= aAb | aAc | a Recursive-descent parsing -
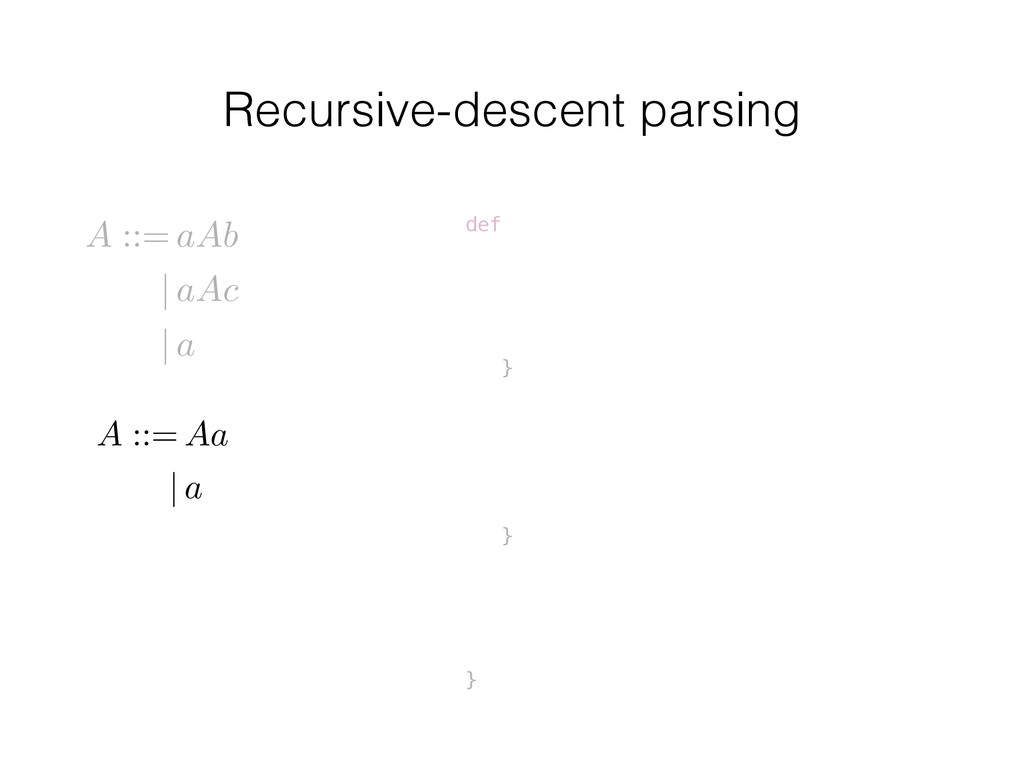
def } } } A ::= aAb | aAc |
a A ::= Aa | a Recursive-descent parsing -
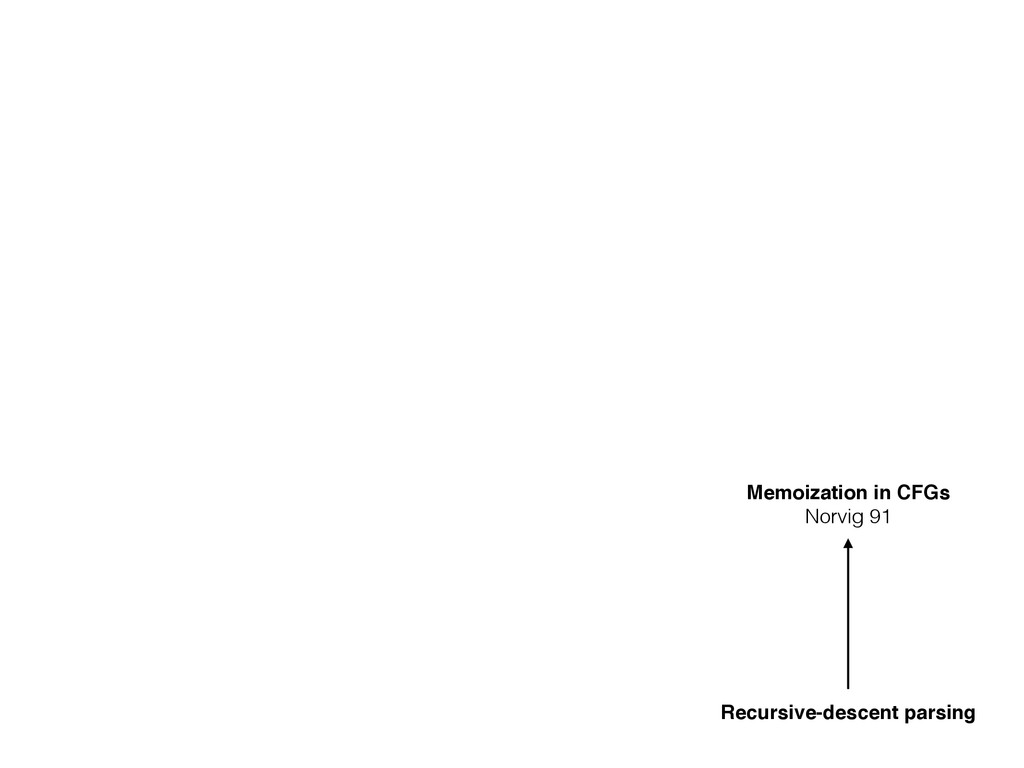
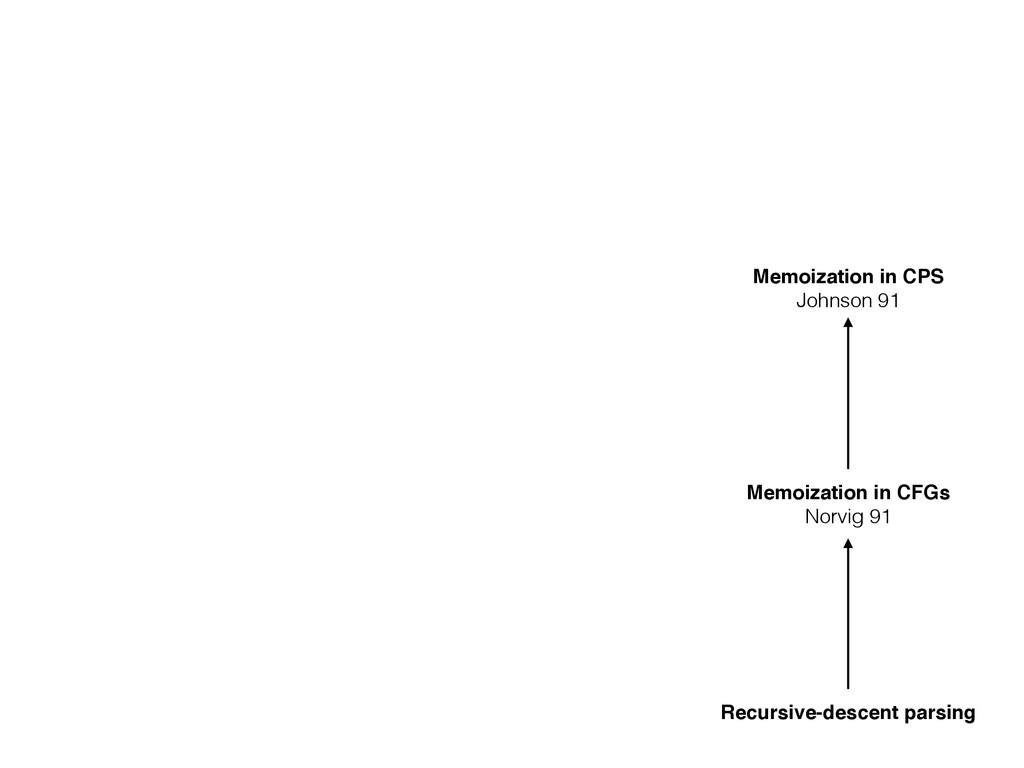
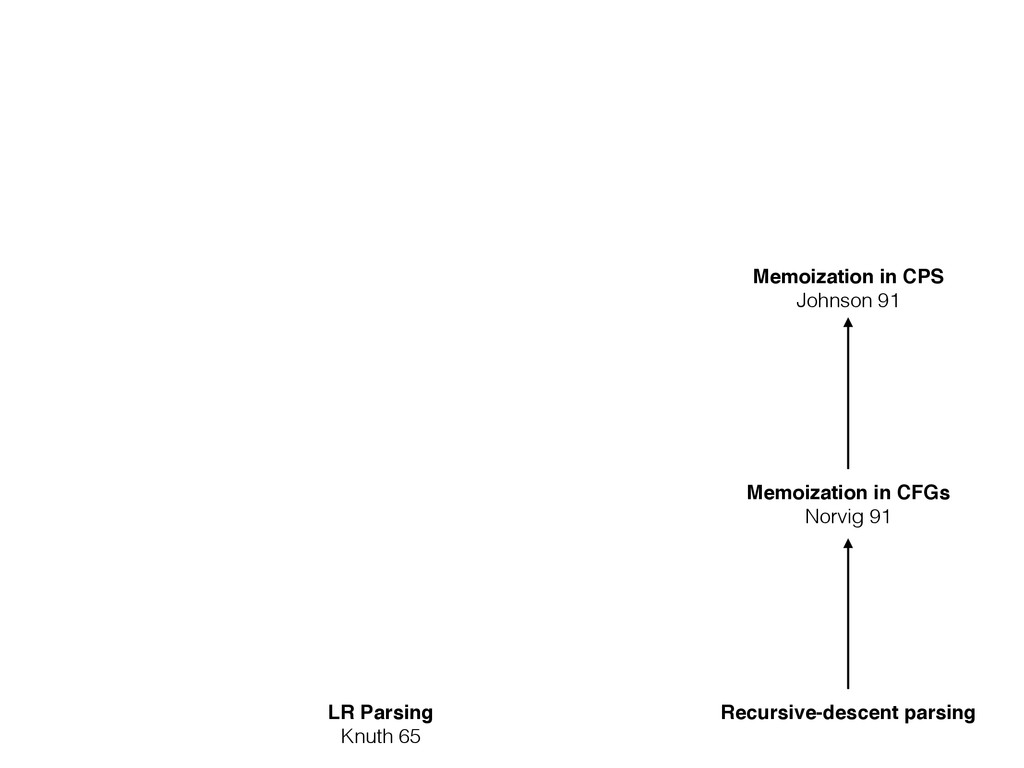
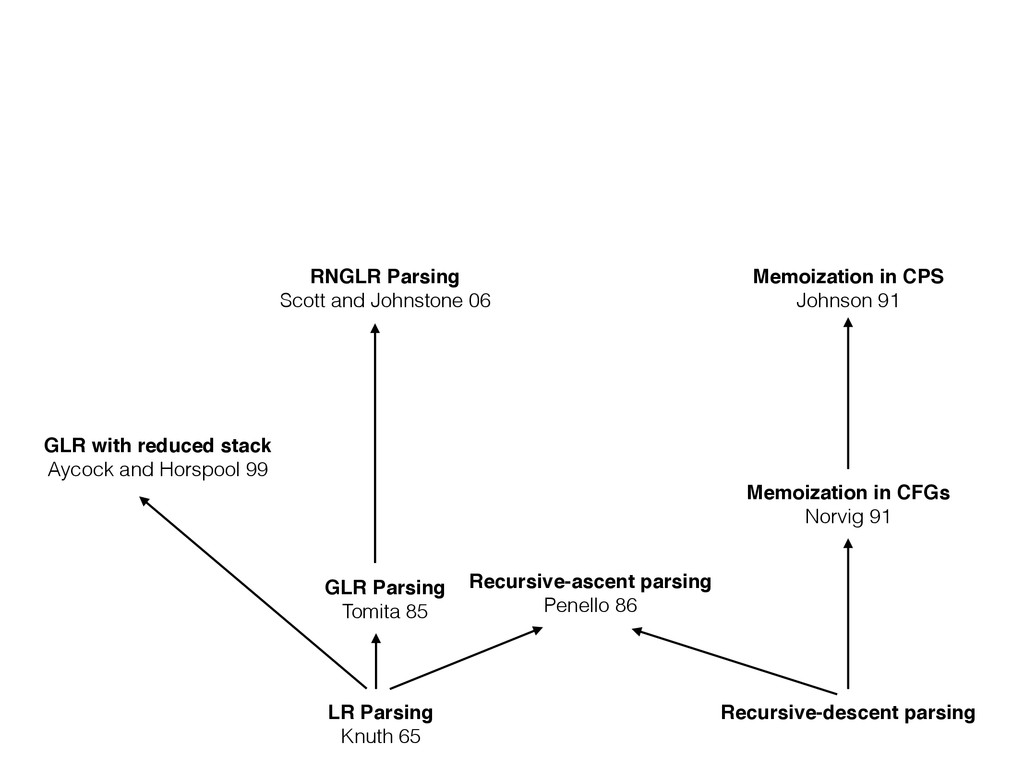
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 LR Parsing Knuth 65 -
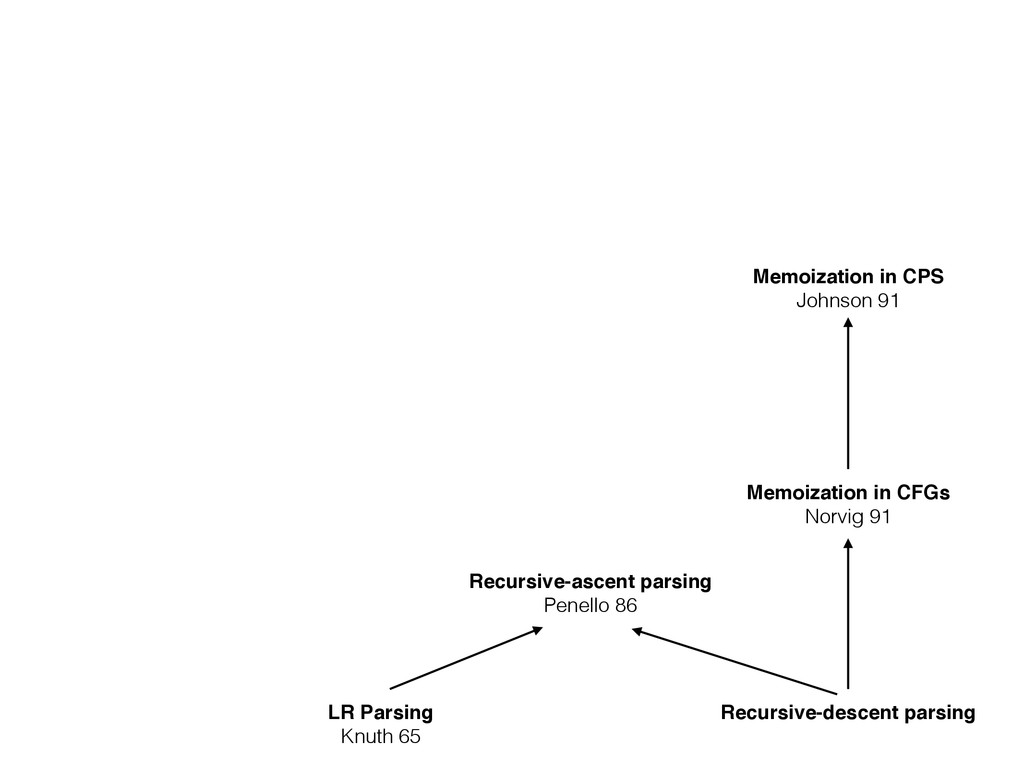
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 -
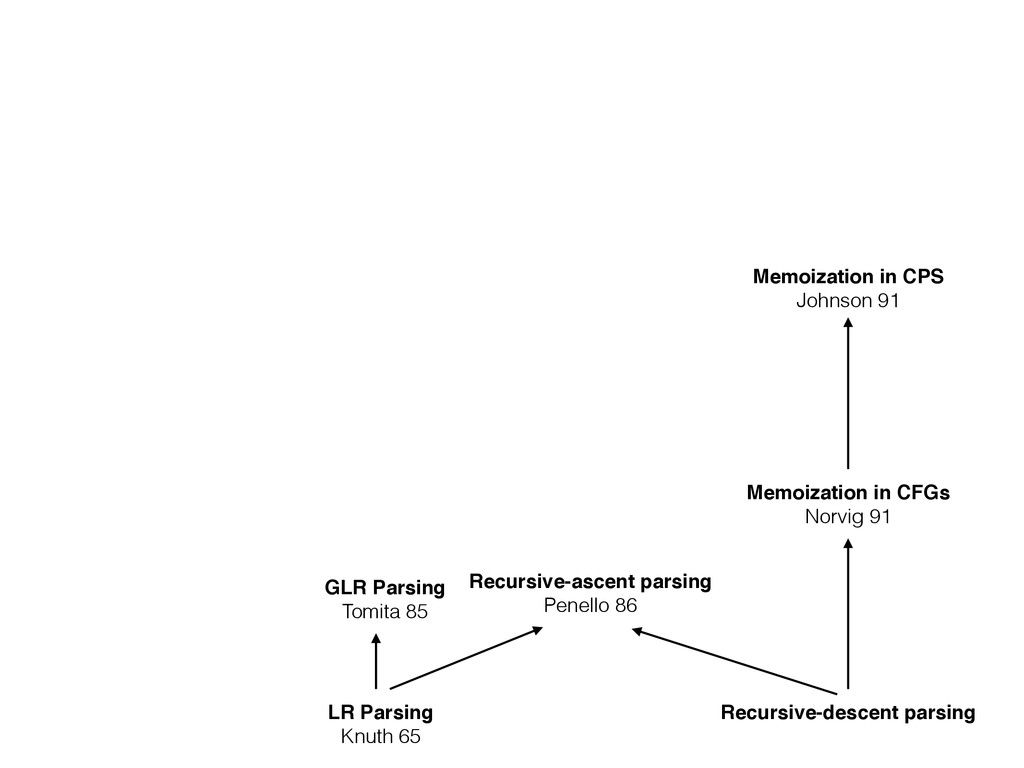
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 -
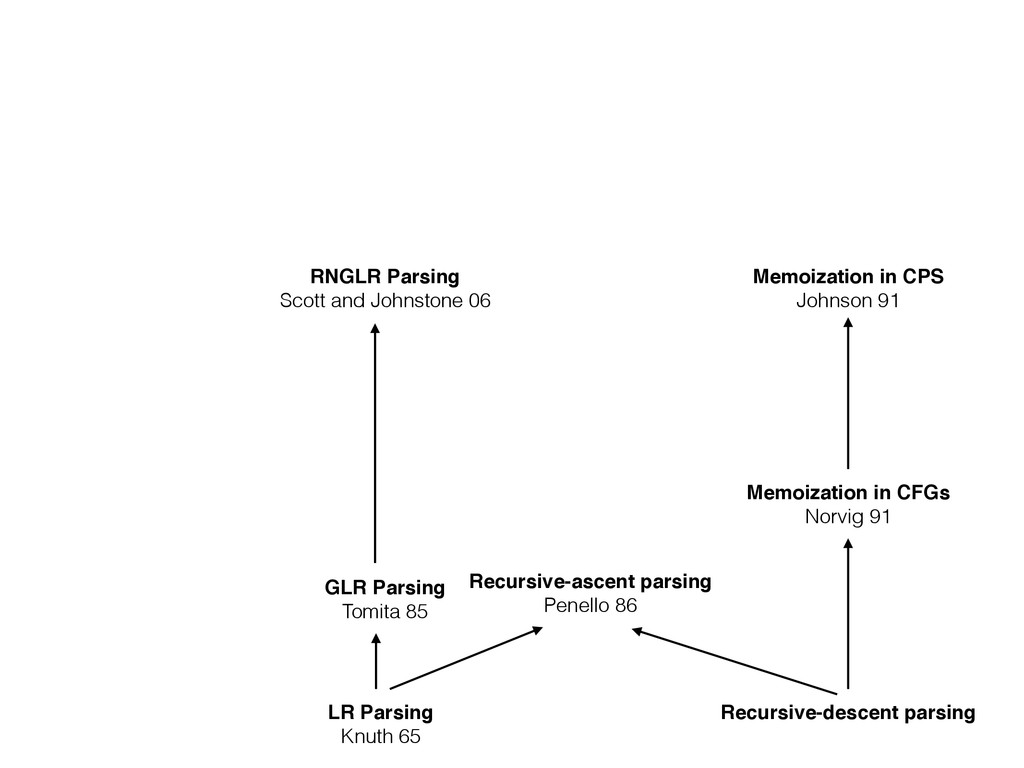
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 RNGLR Parsing Scott and Johnstone 06 -
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 RNGLR Parsing Scott and Johnstone 06 GLR with reduced stack Aycock and Horspool 99 -
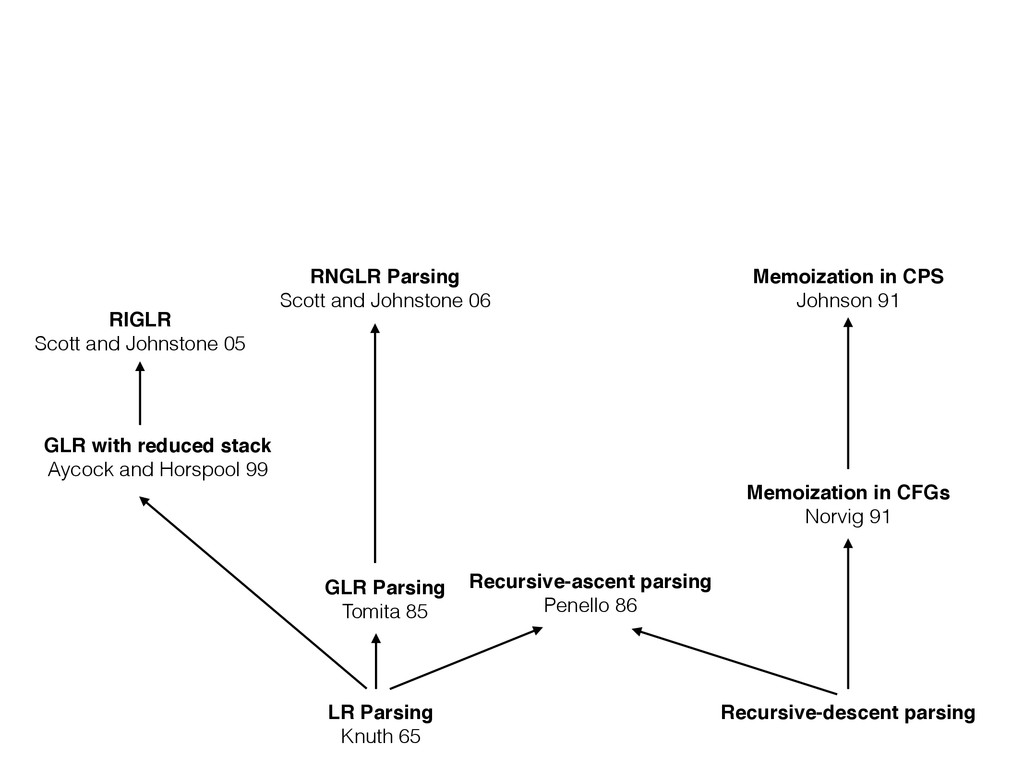
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 RNGLR Parsing Scott and Johnstone 06 GLR with reduced stack Aycock and Horspool 99 RIGLR Scott and Johnstone 05 -
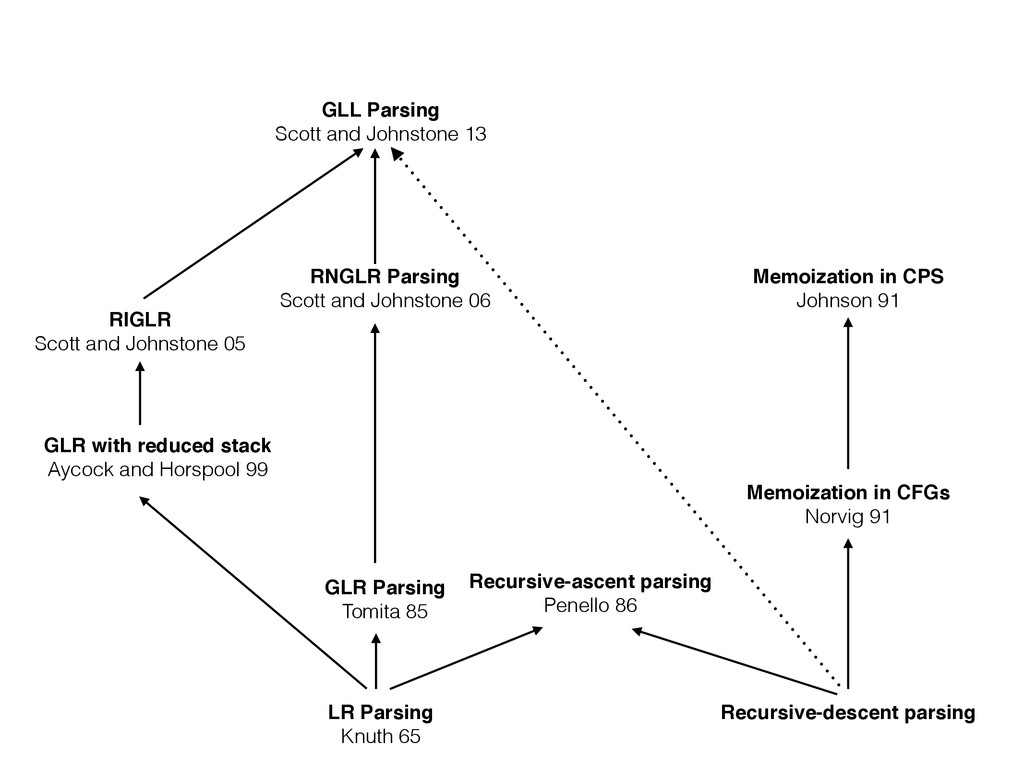
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 RNGLR Parsing Scott and Johnstone 06 GLR with reduced stack Aycock and Horspool 99 RIGLR Scott and Johnstone 05 GLL Parsing Scott and Johnstone 13 -
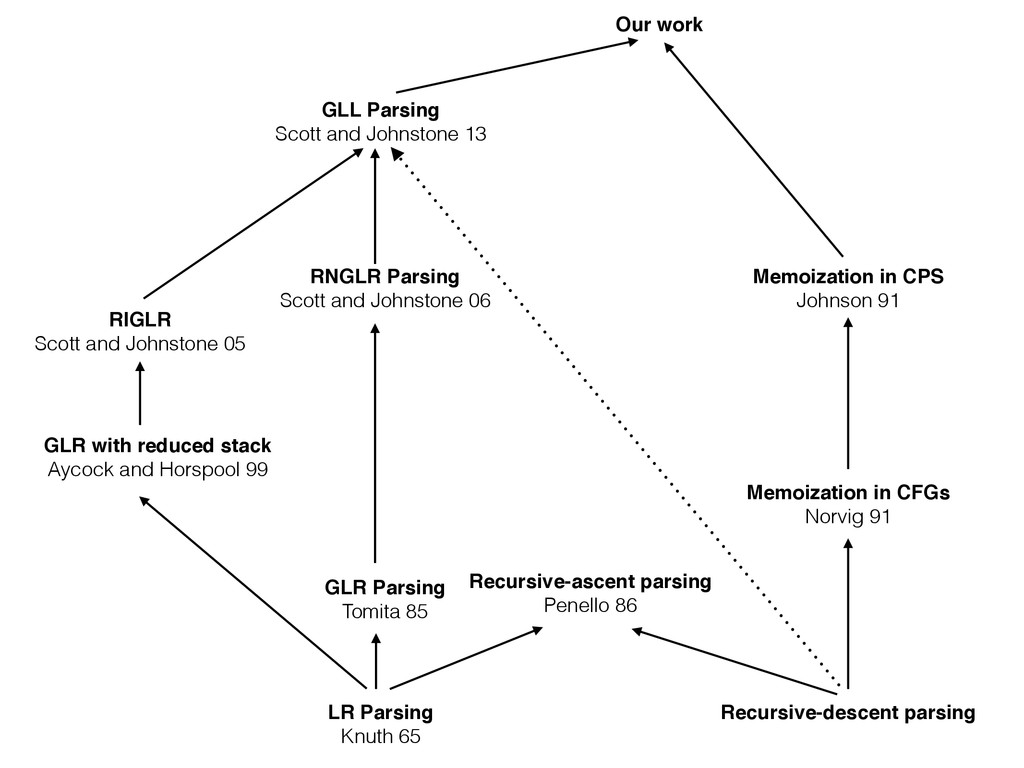
Recursive-descent parsing Memoization in CFGs Norvig 91 Memoization in CPS
Johnson 91 Recursive-ascent parsing Penello 86 LR Parsing Knuth 65 GLR Parsing Tomita 85 RNGLR Parsing Scott and Johnstone 06 GLR with reduced stack Aycock and Horspool 99 RIGLR Scott and Johnstone 05 GLL Parsing Scott and Johnstone 13 Our work -
descriptor, and jumps to execute the code associated with the
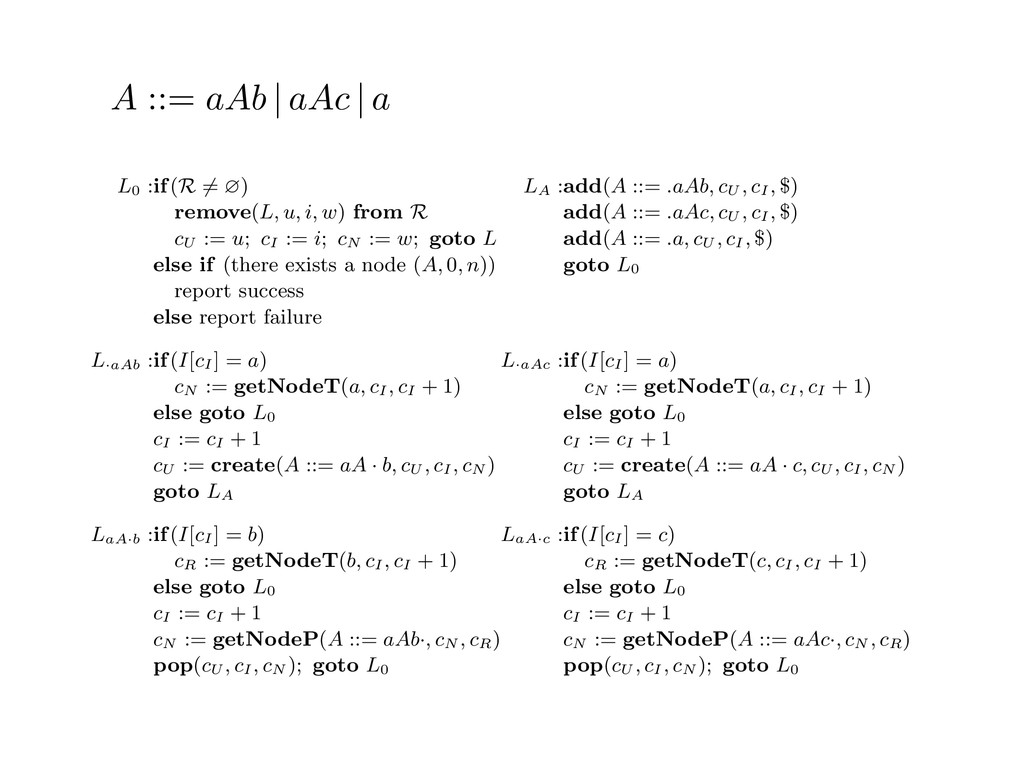
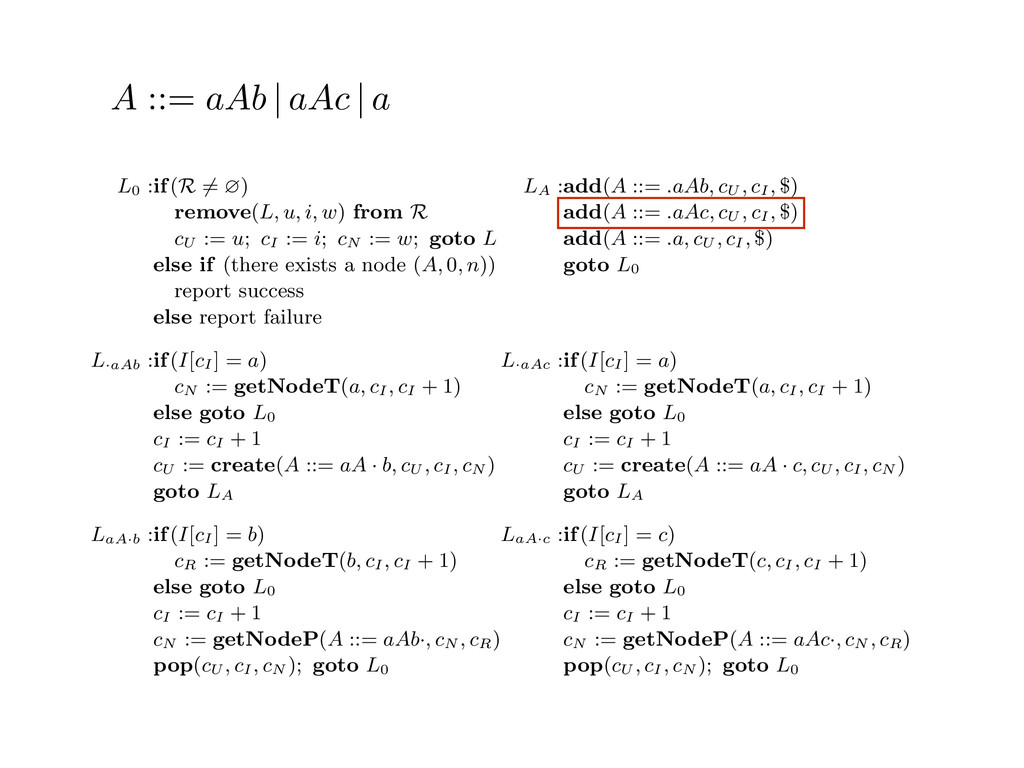
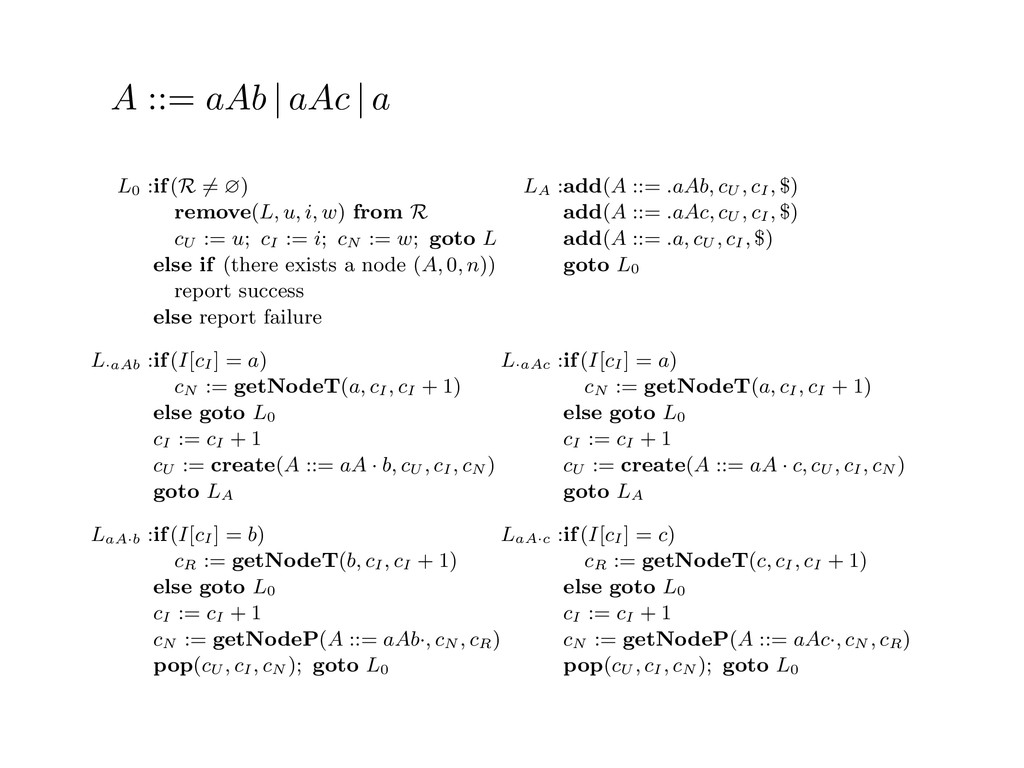
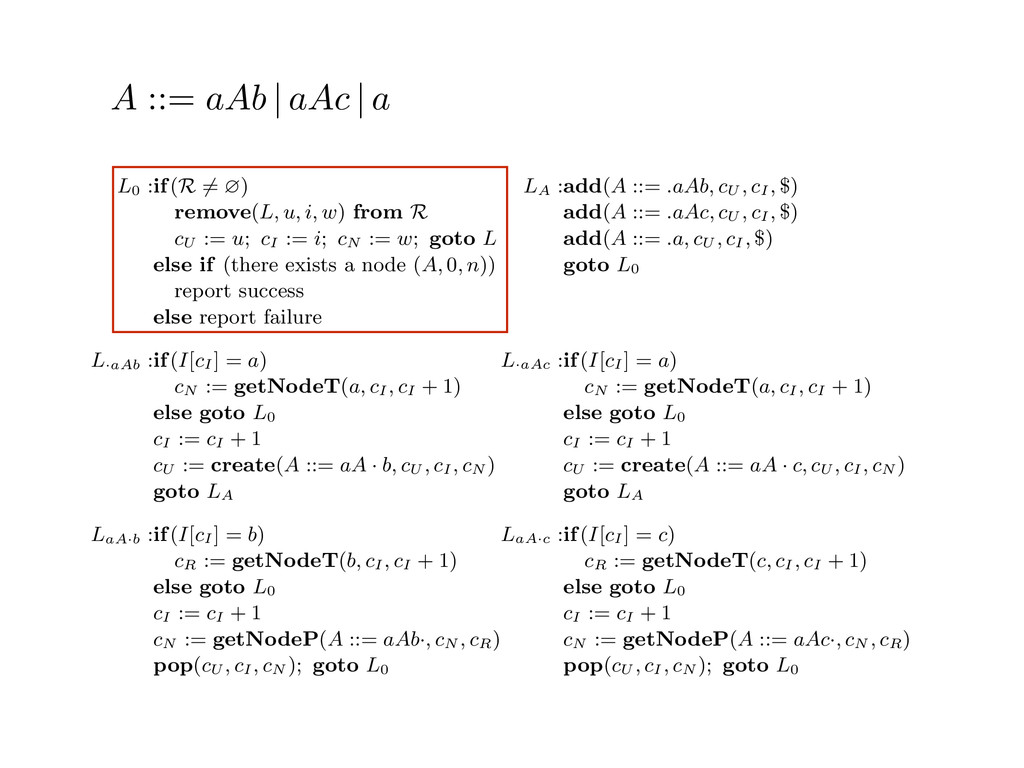
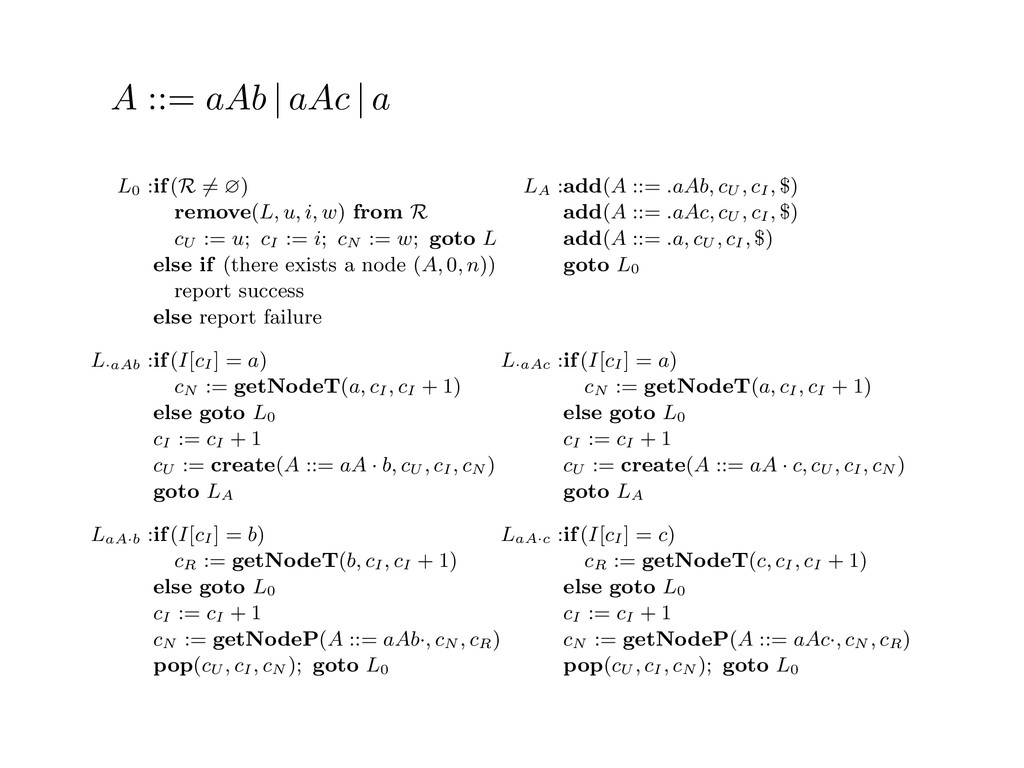
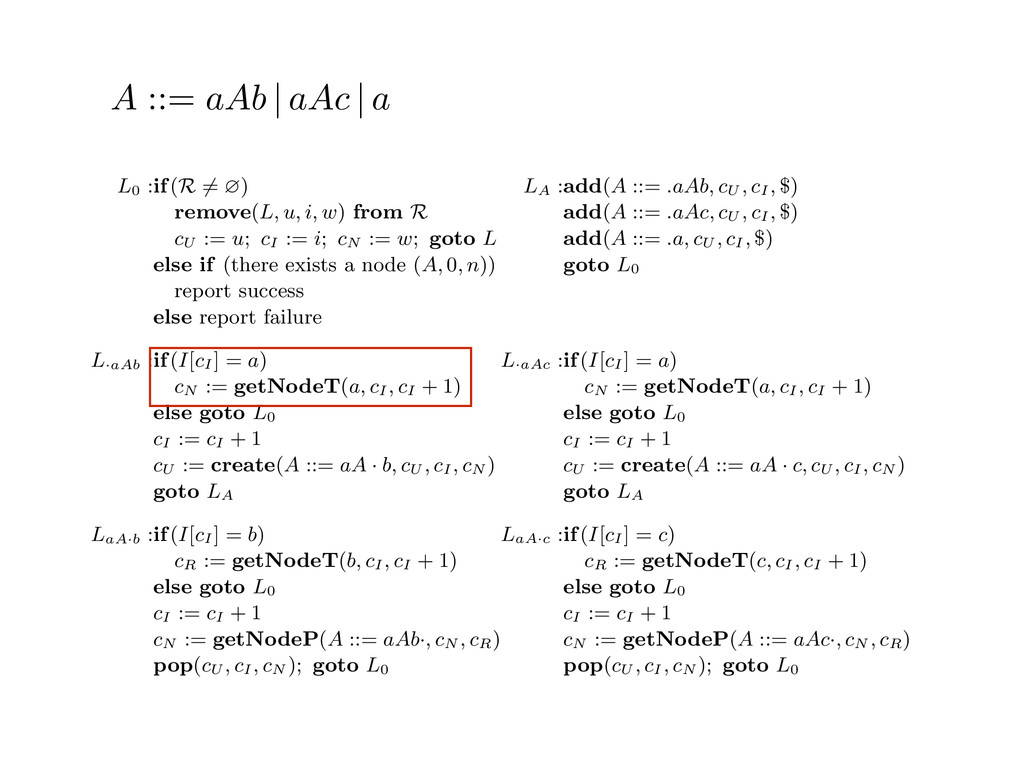
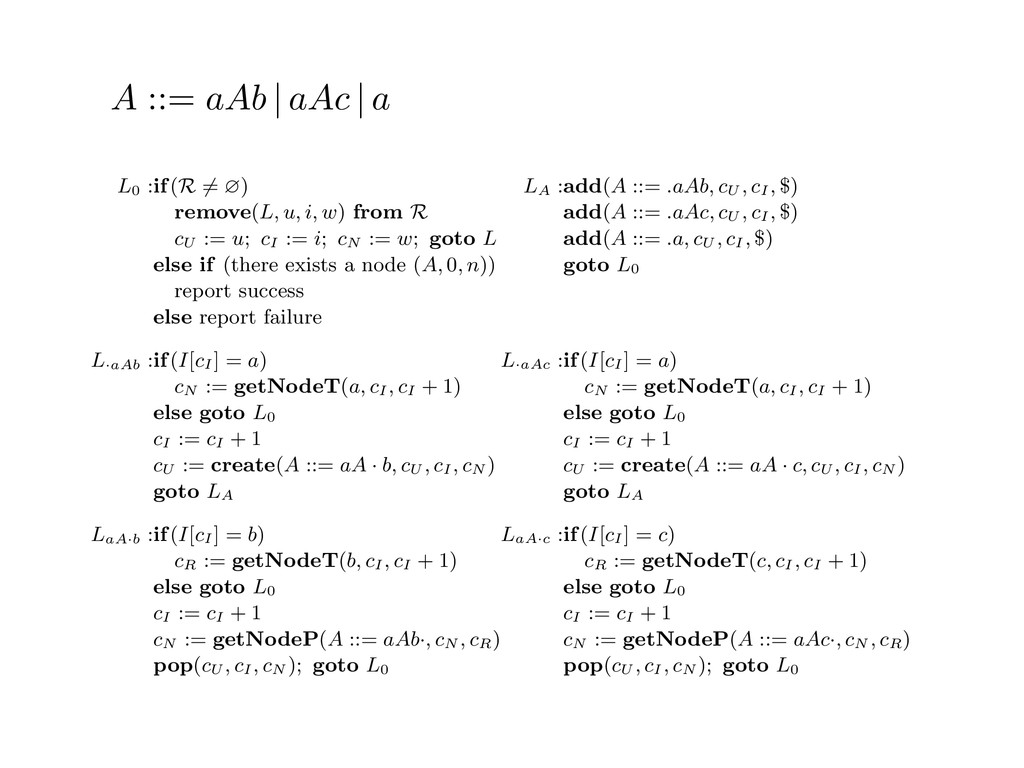
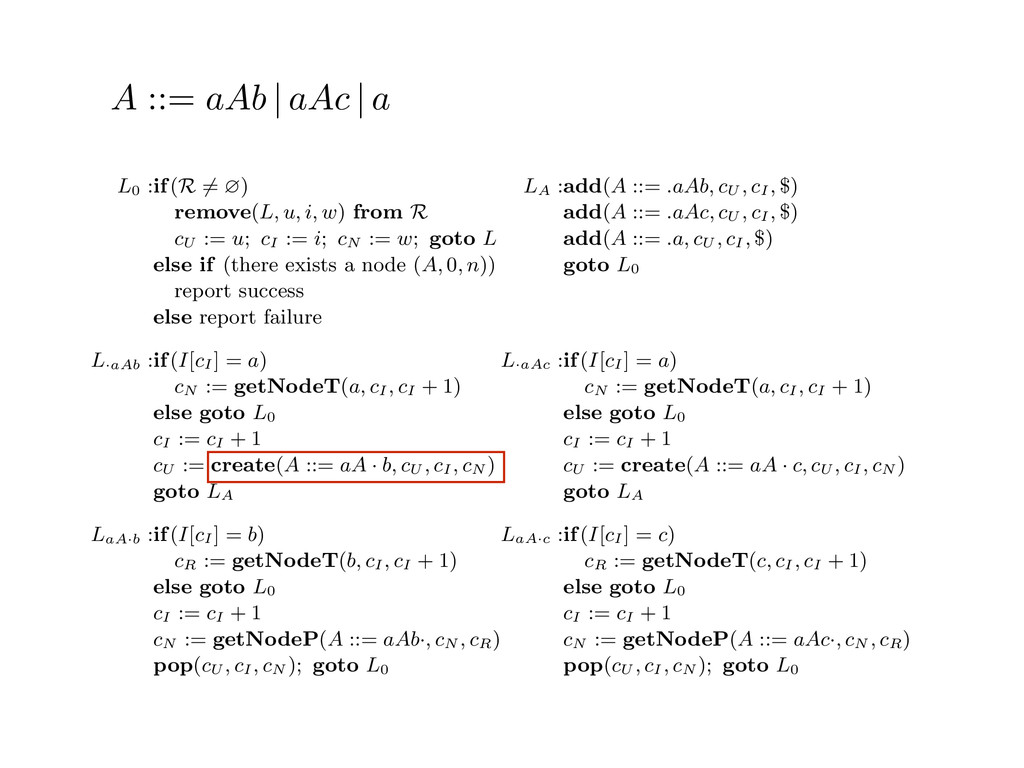
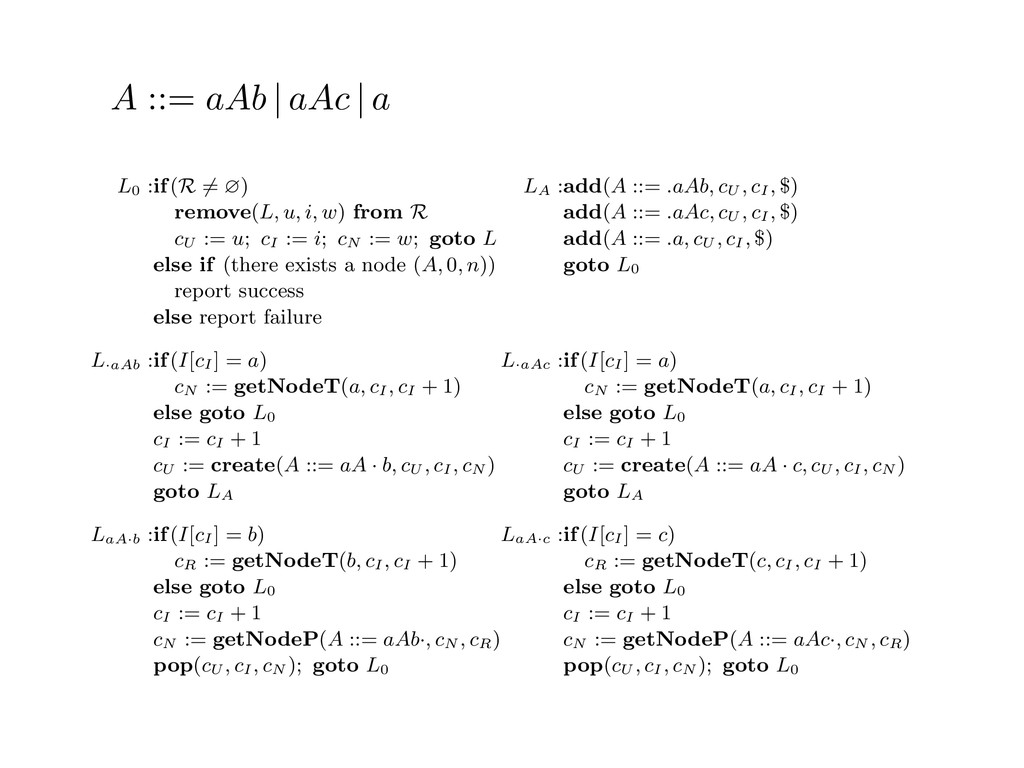
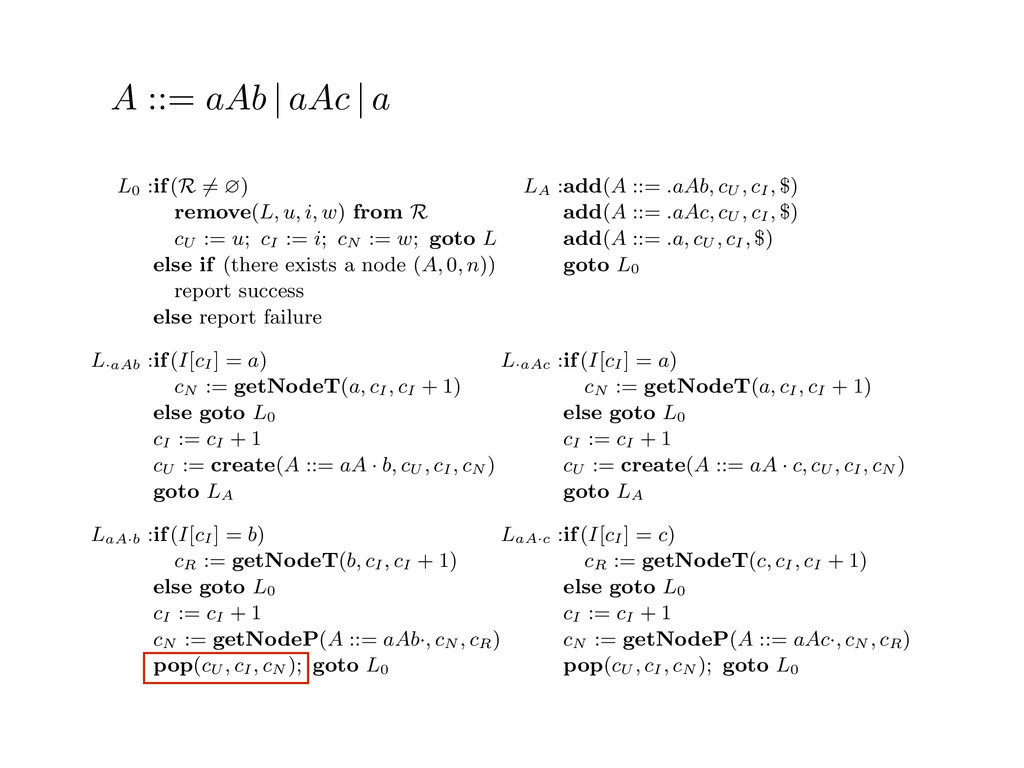
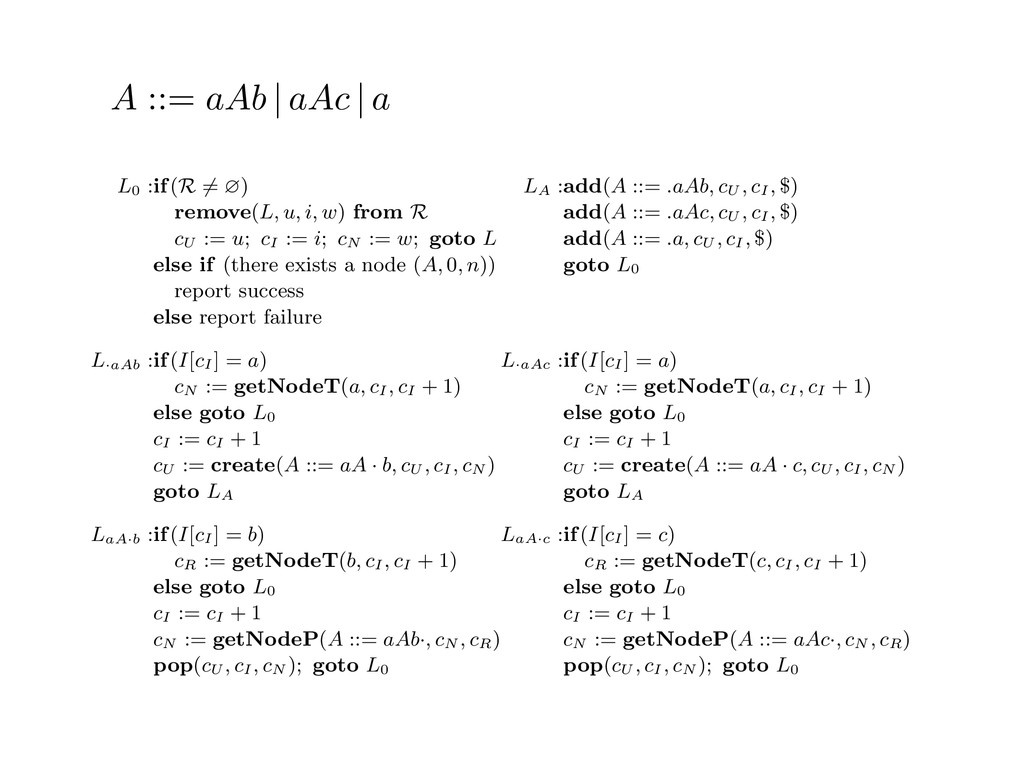
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
descriptor, and jumps to execute the code associated with the
grammar slot of the descriptor. An example of a GLL parser is given below for the grammar 0 : A ::= aAb | aAc | a. R := ?; P := ?; U := ? cU := (L0, 0); cI := 0; cN := $ L0 : if (R 6= ?) LA : add (A ::= .aAb, cU , cI , $) remove (L, u, i, w) from R add (A ::= .aAc, cU , cI , $) cU := u; cI := i; cN := w; goto L add (A ::= .a, cU , cI , $) else if (there exists a node (A, 0, n)) goto L0 report success else report failure L·aAb : if (I[cI ] = a) L·aAc : if (I[cI ] = a) cN := getNodeT (a, cI , cI + 1) cN := getNodeT (a, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cU := create (A ::= aA · b, cU , cI , cN ) cU := create (A ::= aA · c, cU , cI , cN ) goto LA goto LA LaA·b : if (I[cI ] = b) LaA·c : if (I[cI ] = c) cR := getNodeT (b, cI , cI + 1) cR := getNodeT (c, cI , cI + 1) else goto L0 else goto L0 cI := cI + 1 cI := cI + 1 cN := getNodeP (A ::= aAb·, cN , cR ) cN := getNodeP (A ::= aAc·, cN , cR ) pop (cU , cI , cN ); goto L0 pop (cU , cI , cN ); goto L0 We describe the execution of a GLL parser by explaining the steps of the parser at di↵erent grammar slots. Here, and in the rest of the paper, we do not include A ::= aAb | aAc | a -
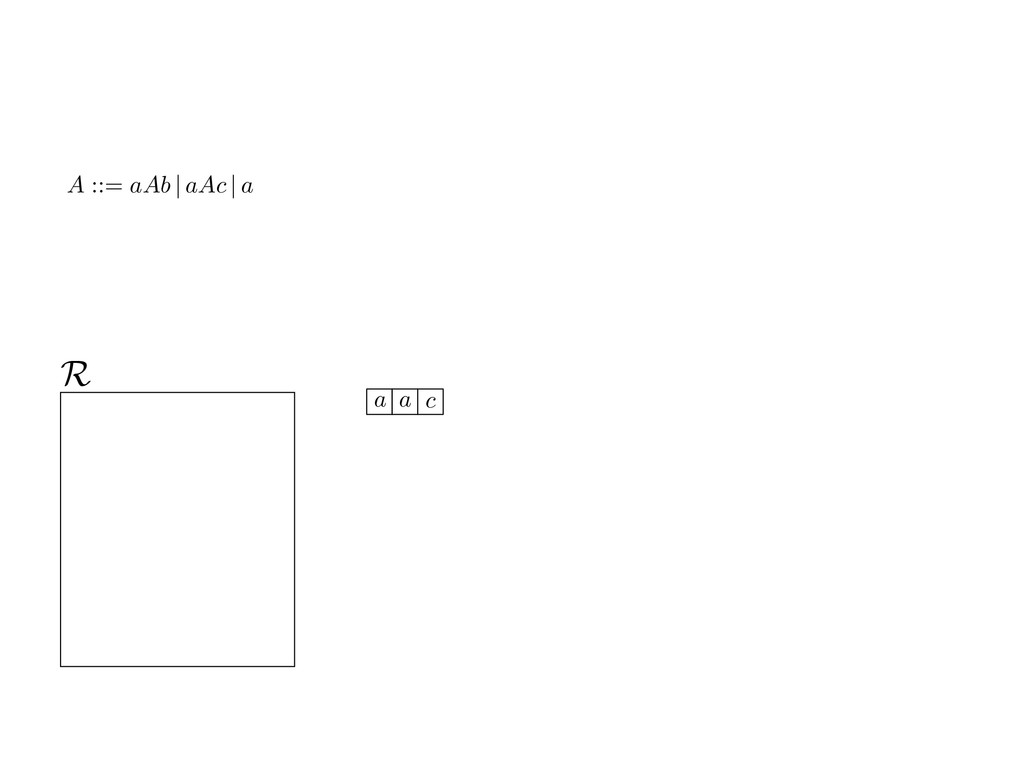
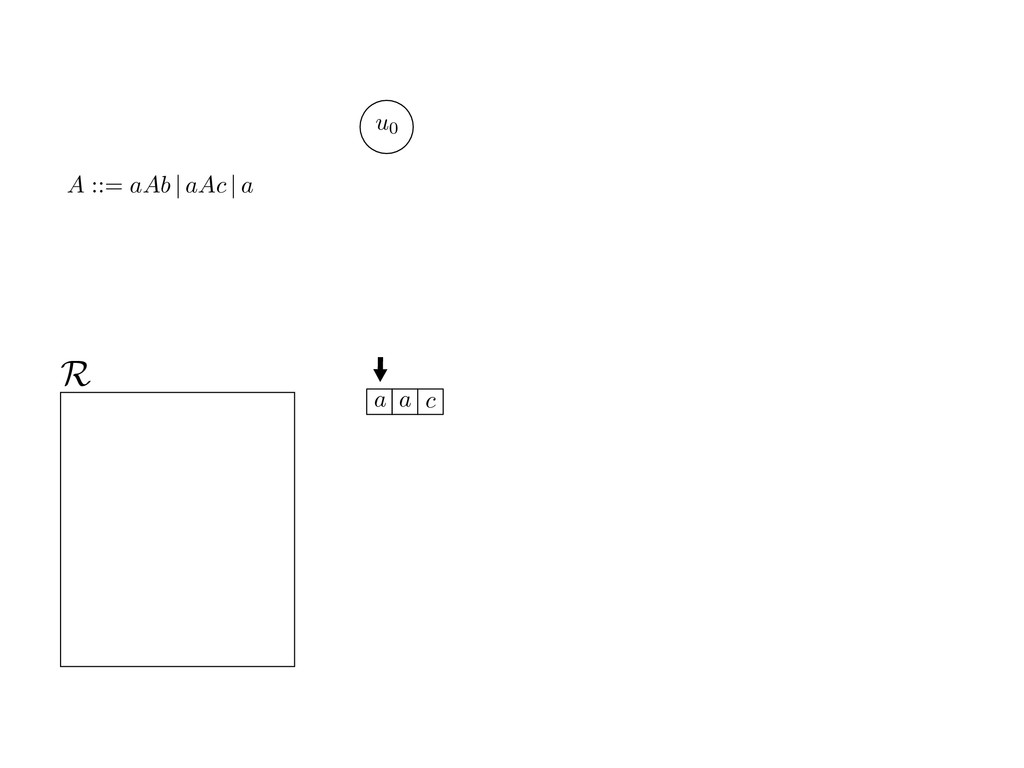
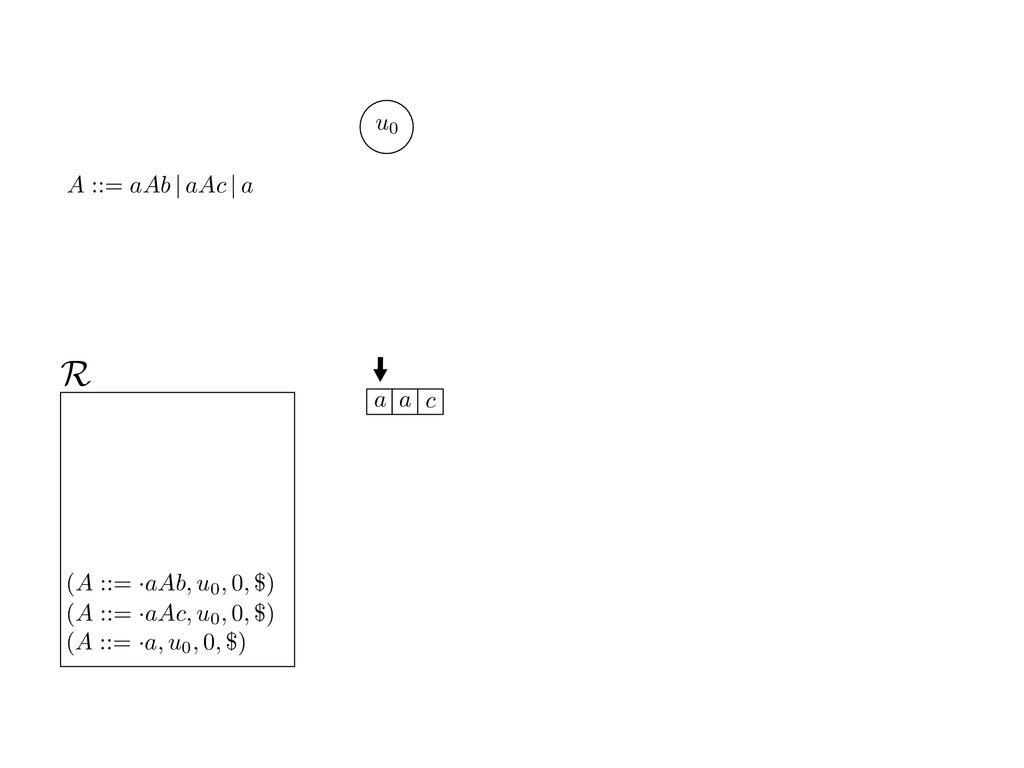
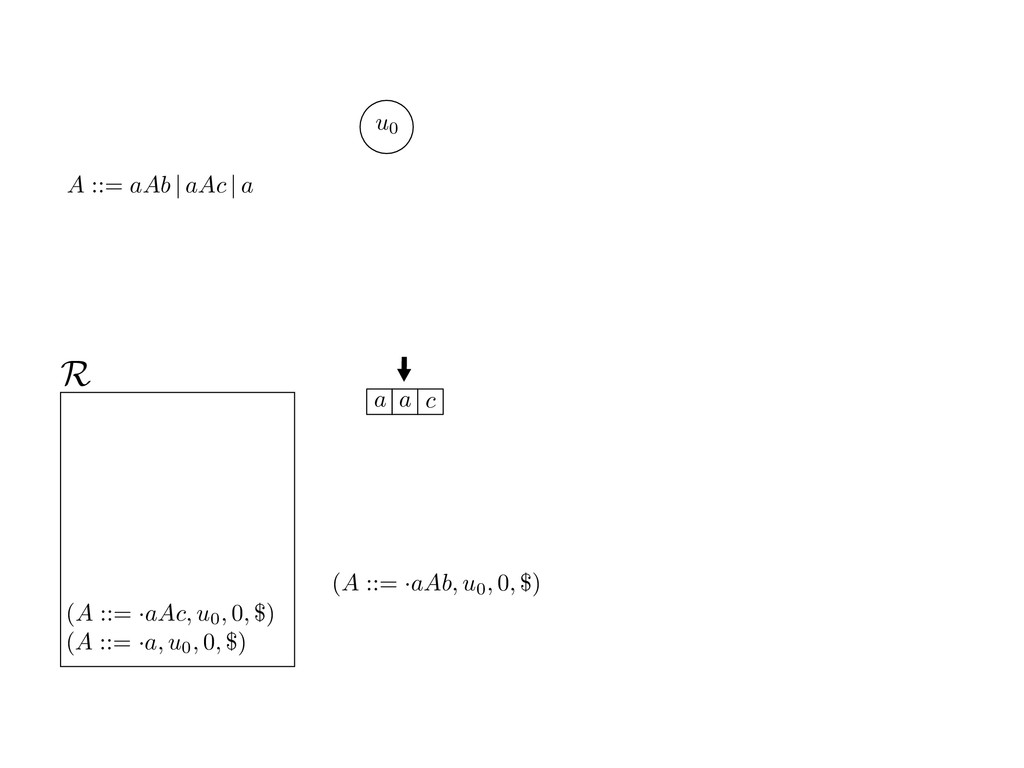
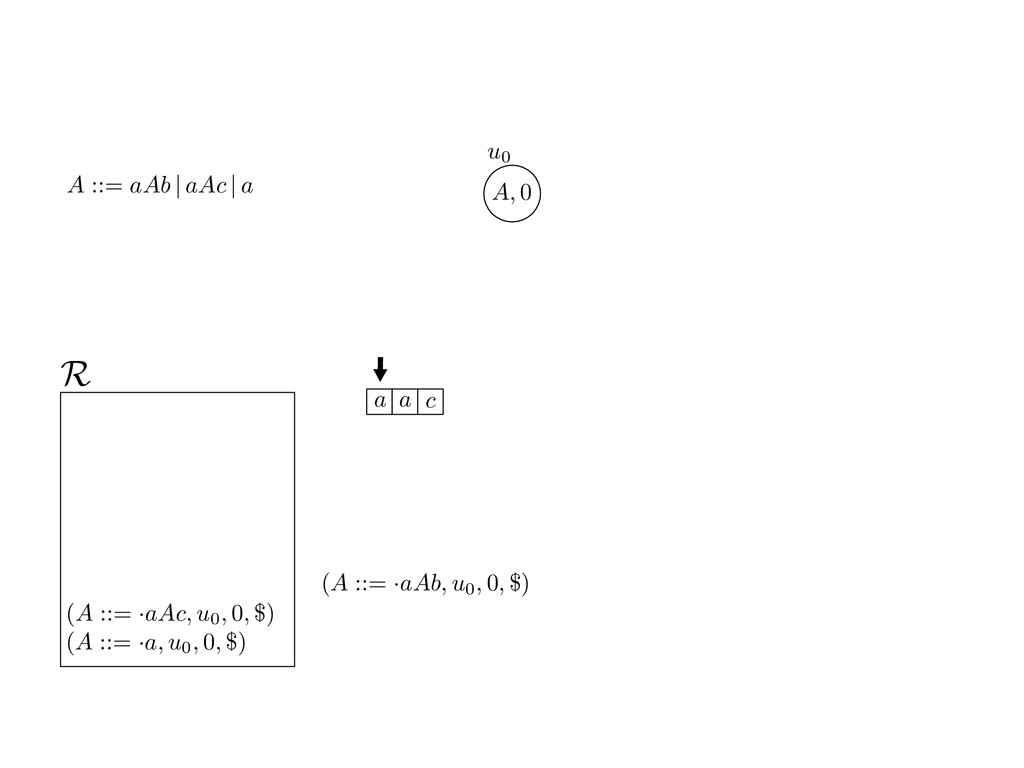
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) u0 A ::= aAb | aAc | a a a c R -
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) u0 A ::= aAb | aAc | a a a c R -
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) u0 A ::= aAb | aAc | a a a c R -
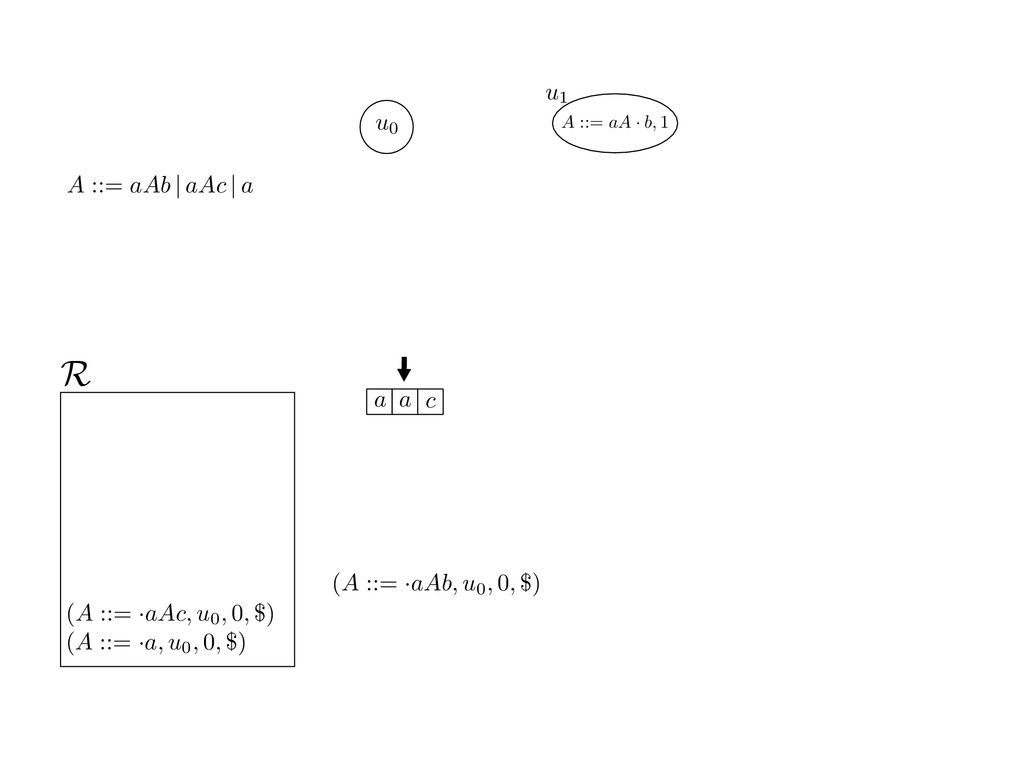
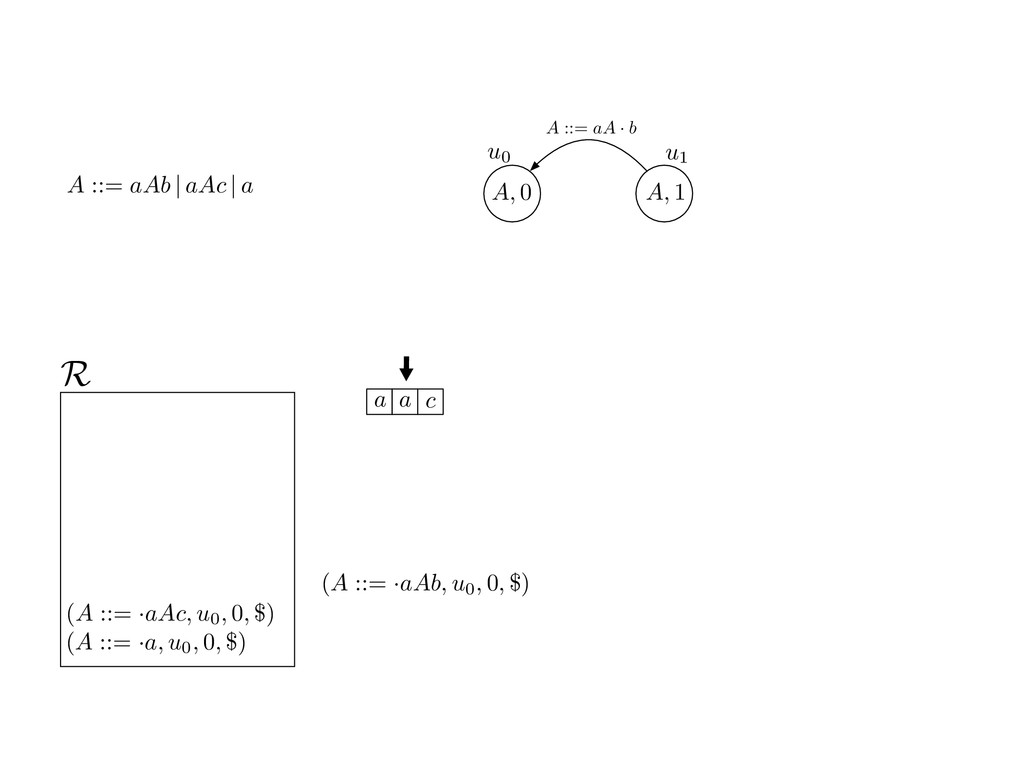
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
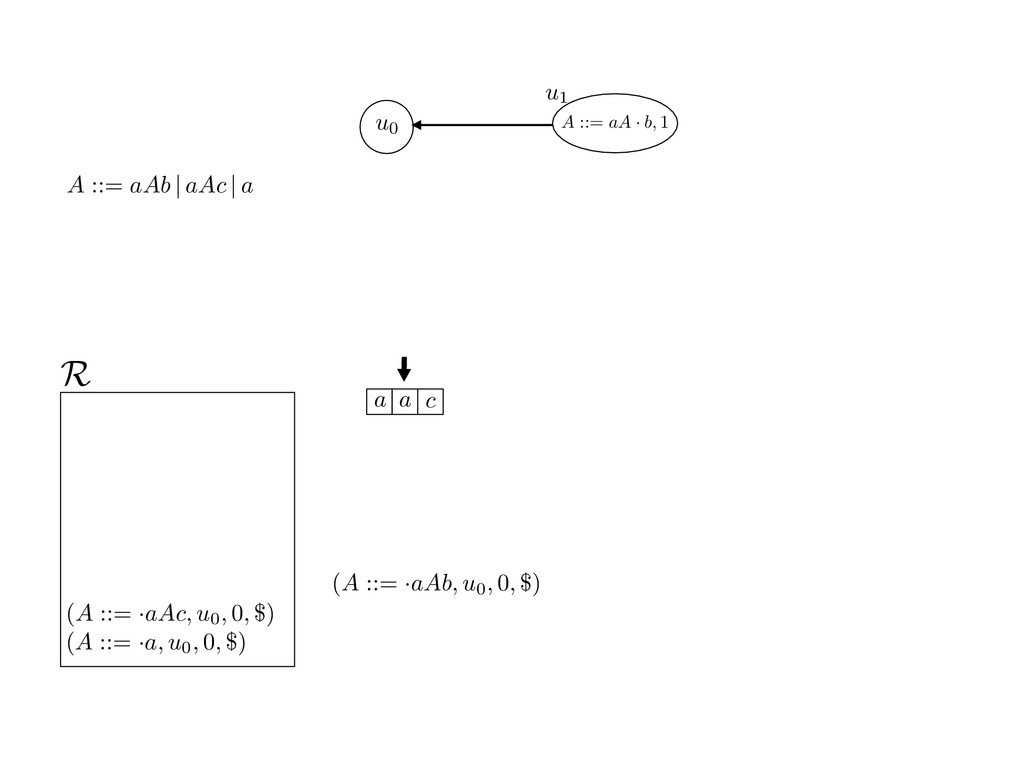
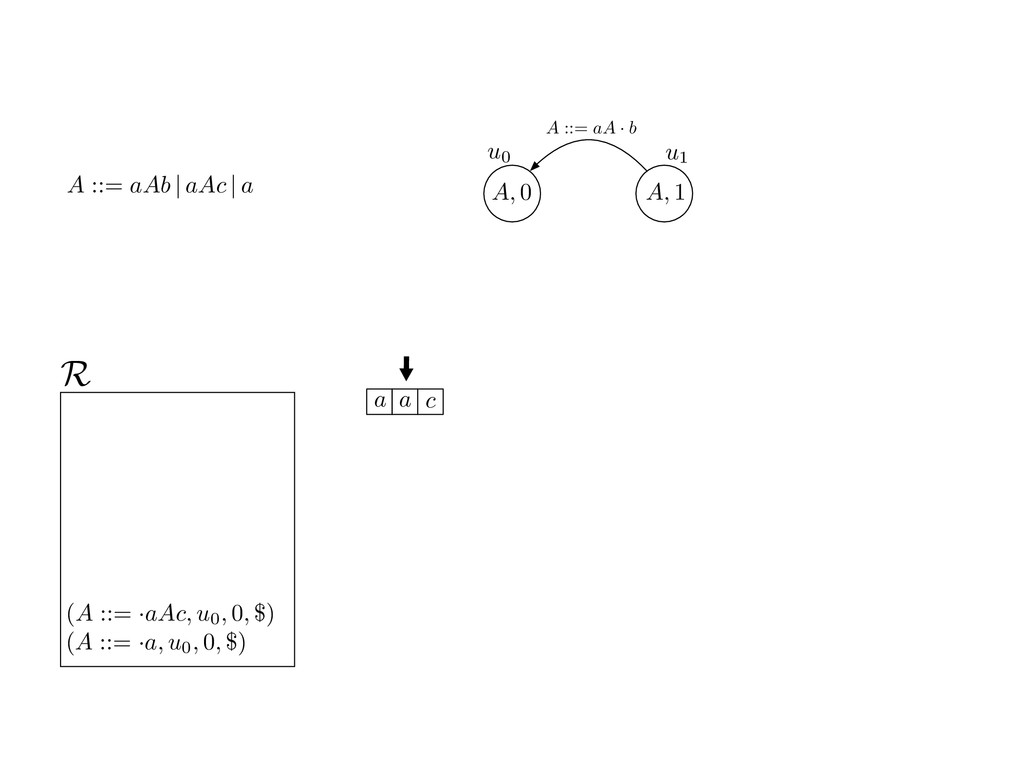
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
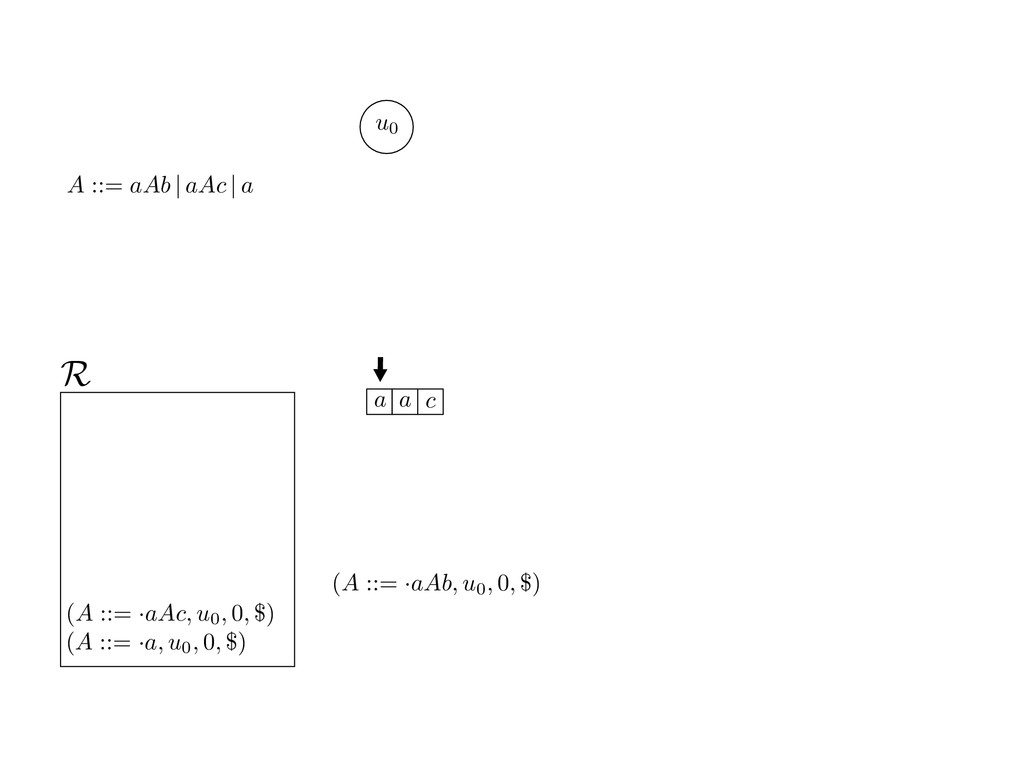
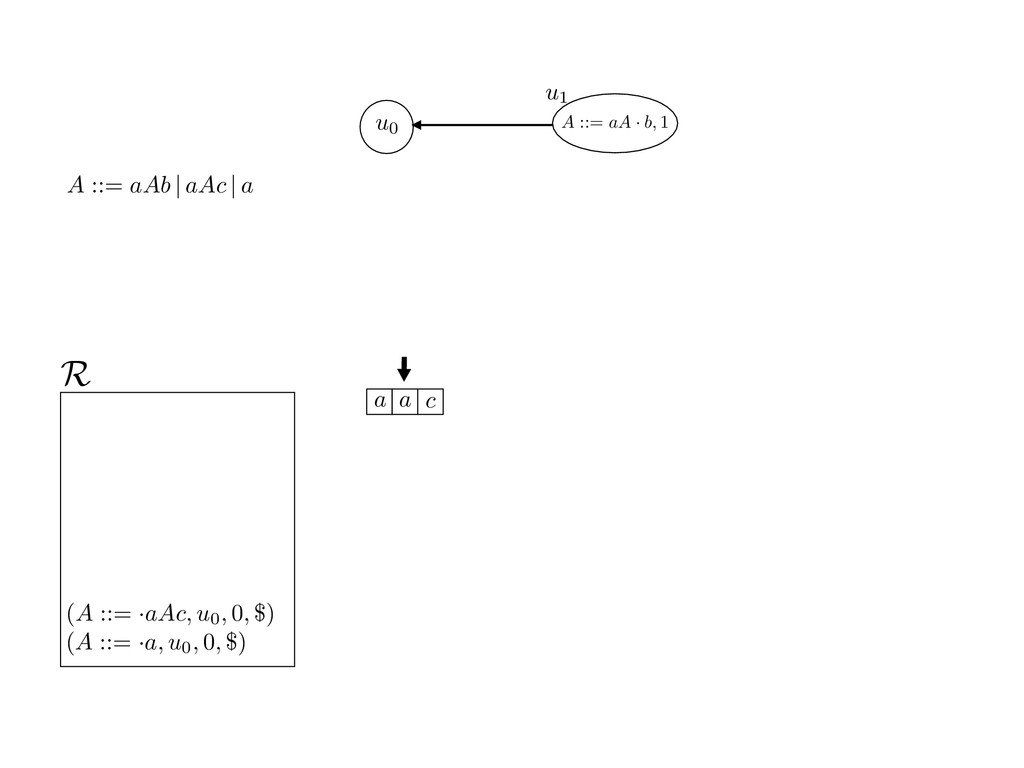
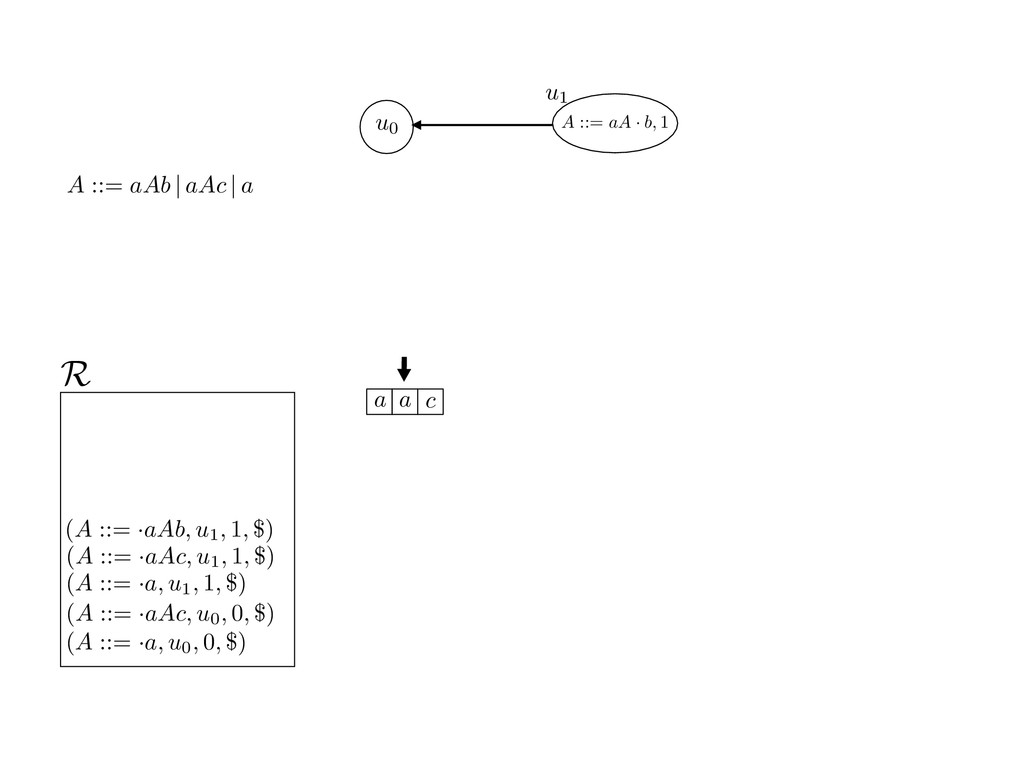
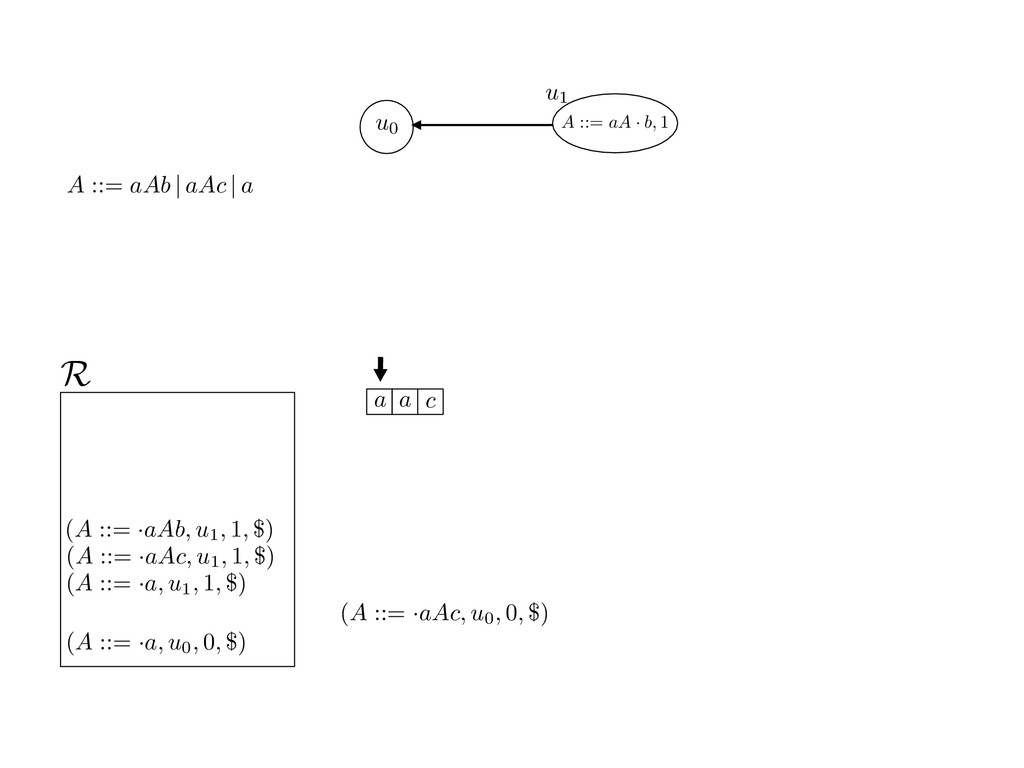
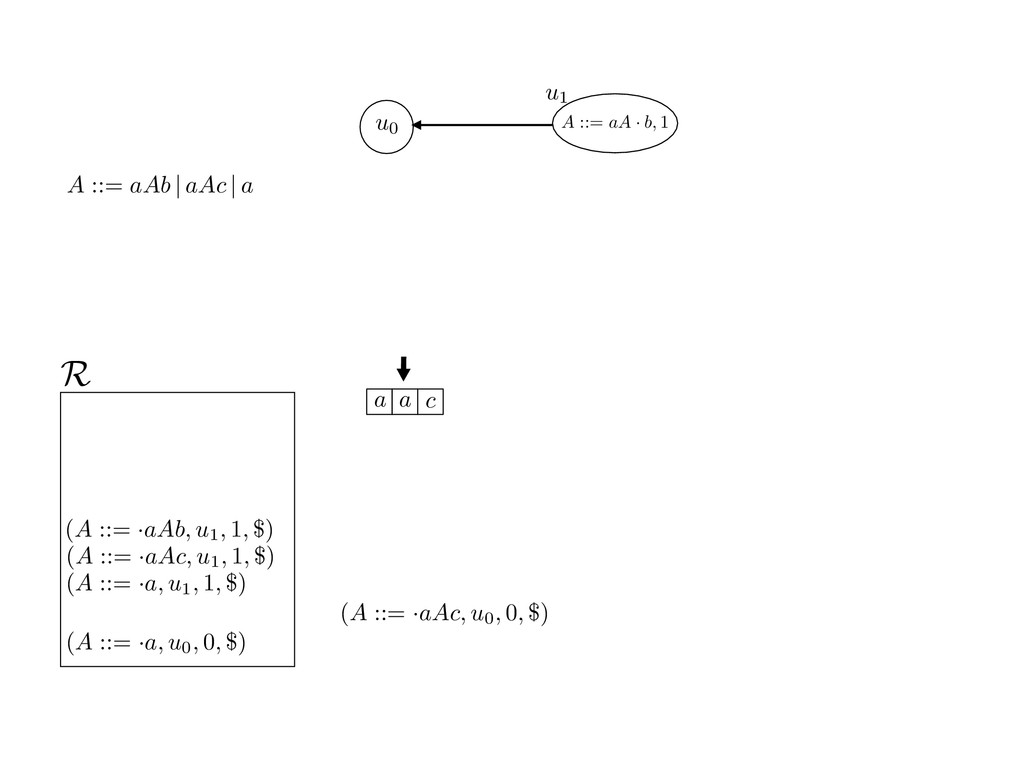
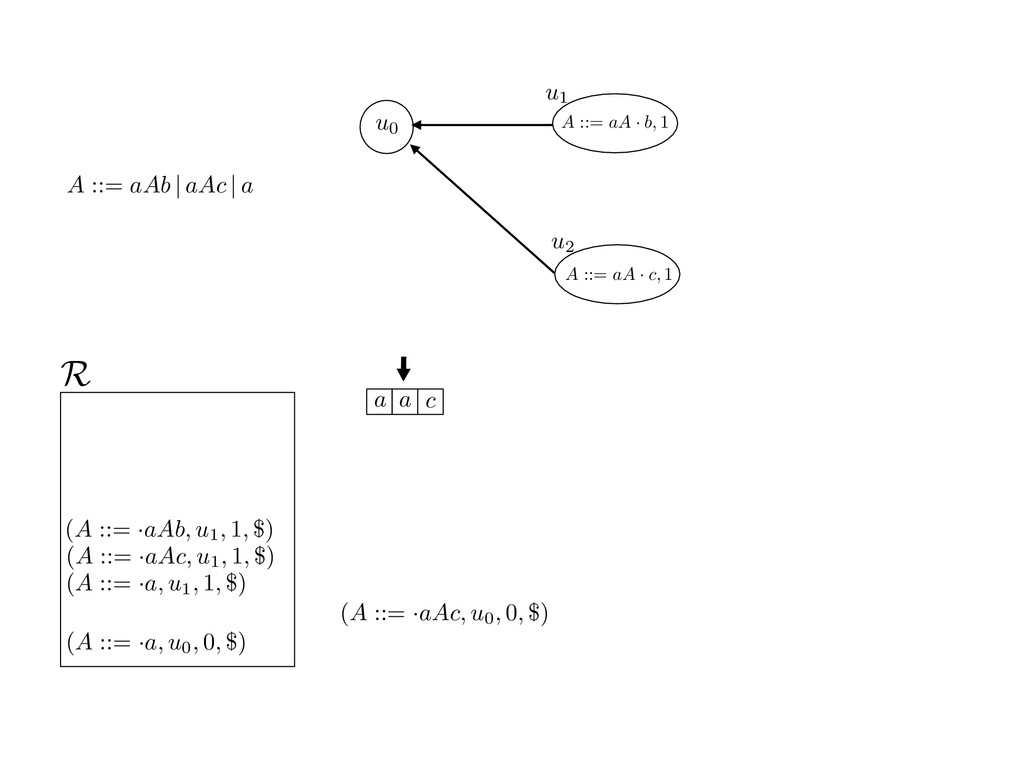
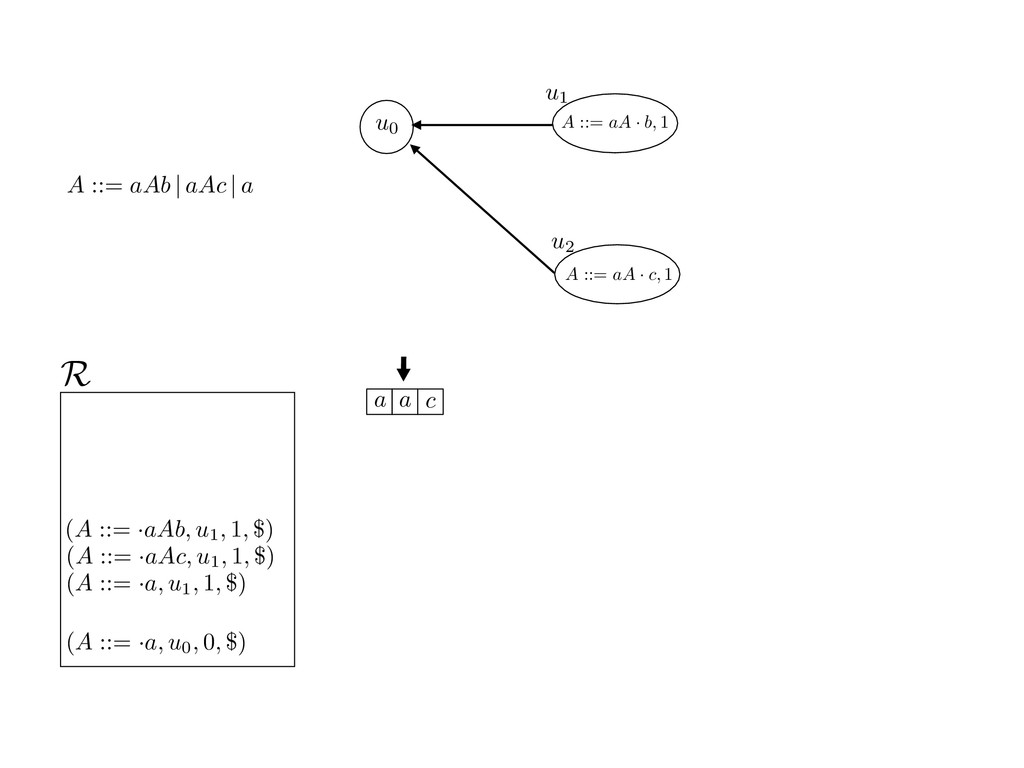
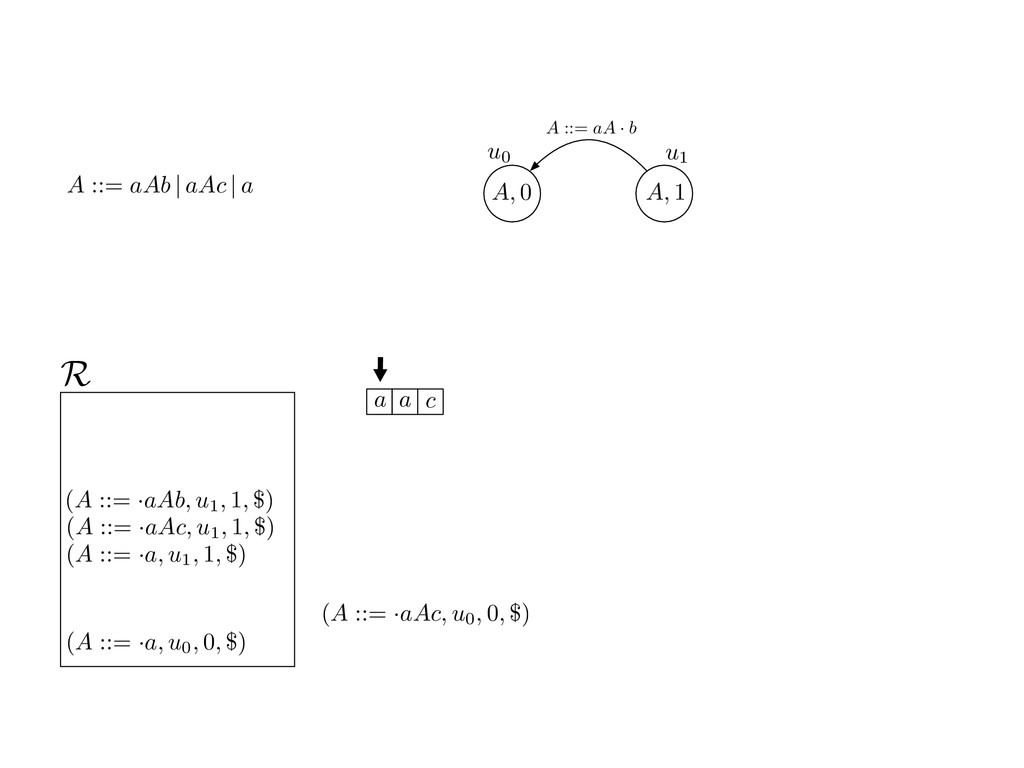
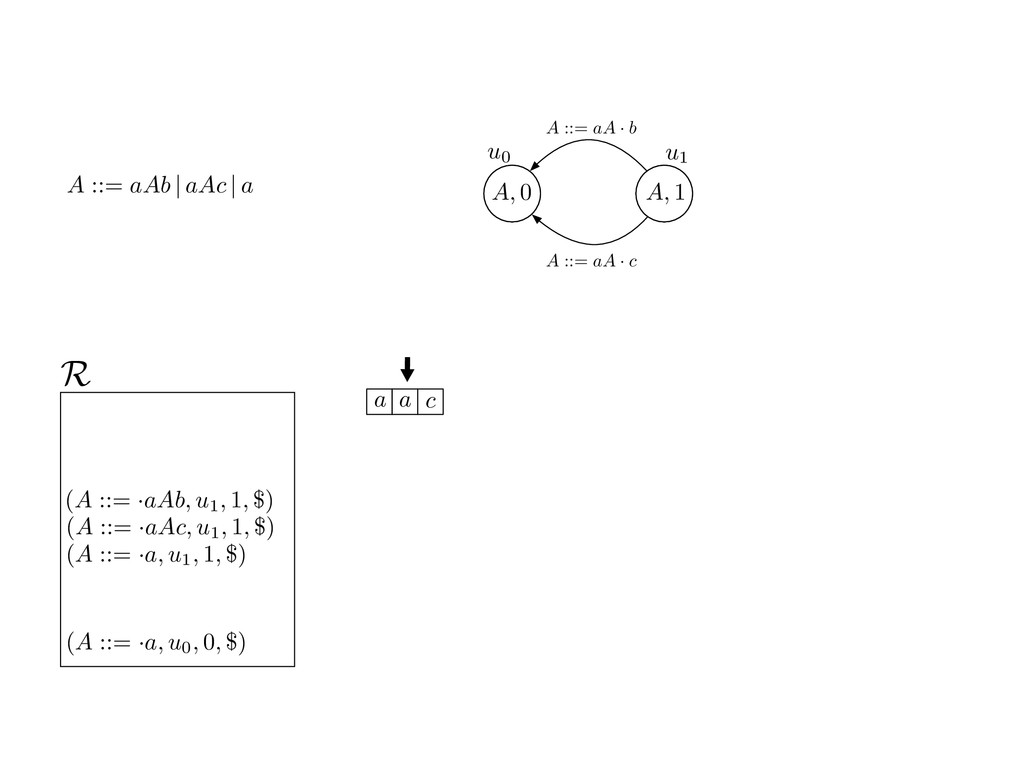
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
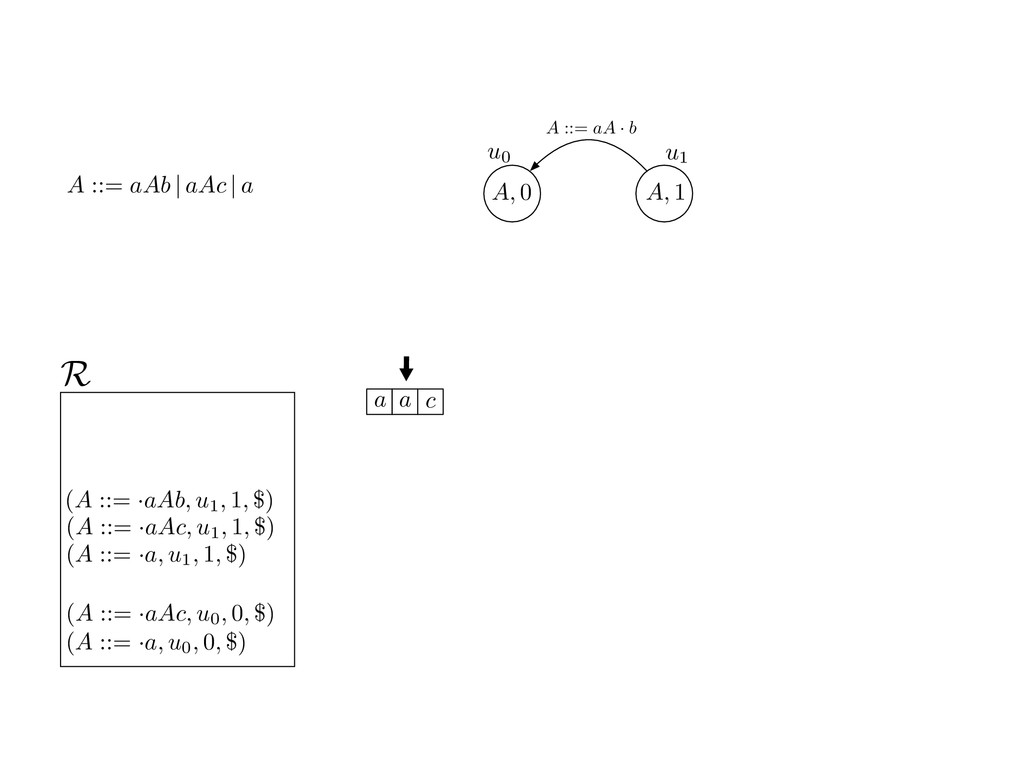
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 -
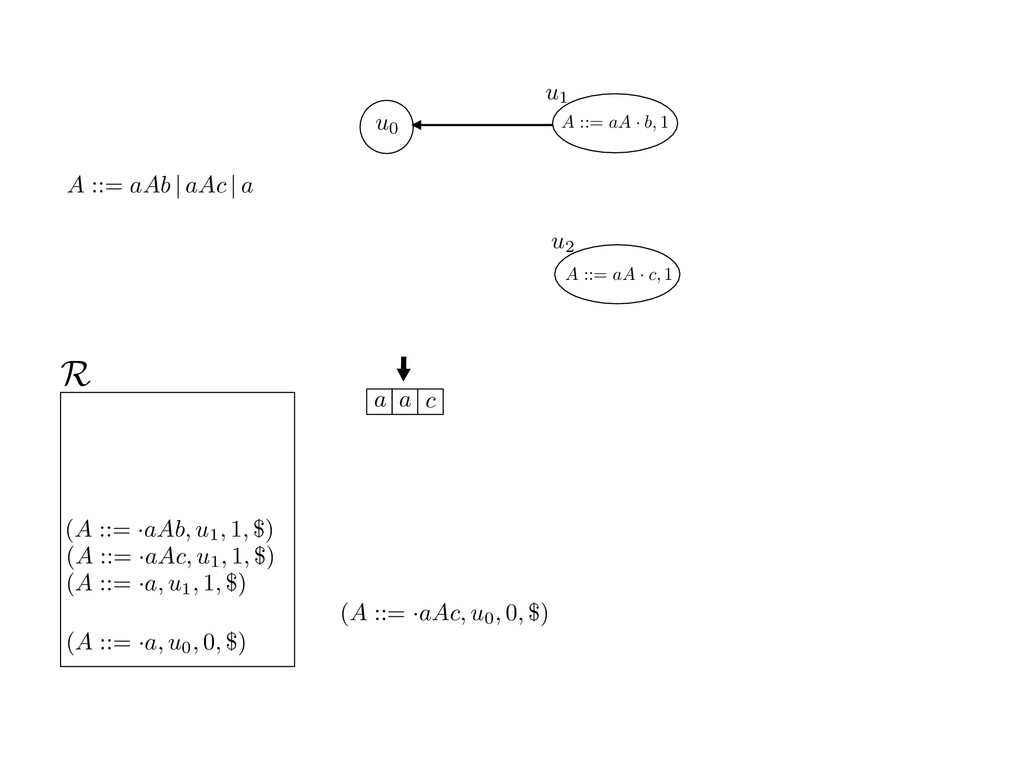
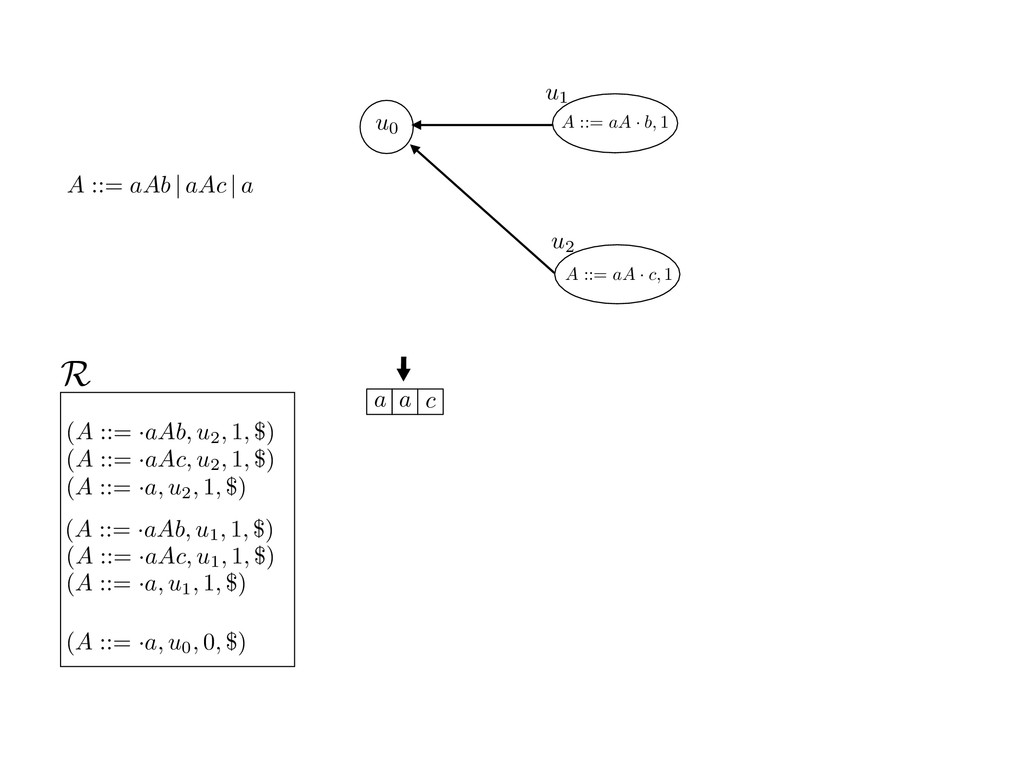
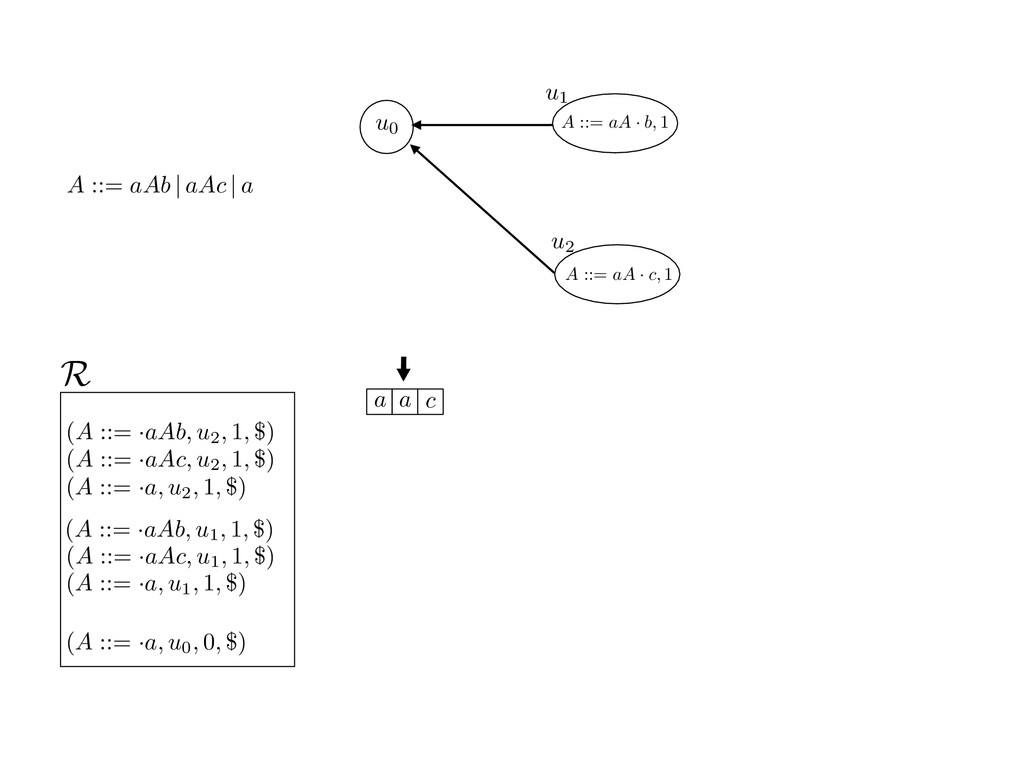
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 -
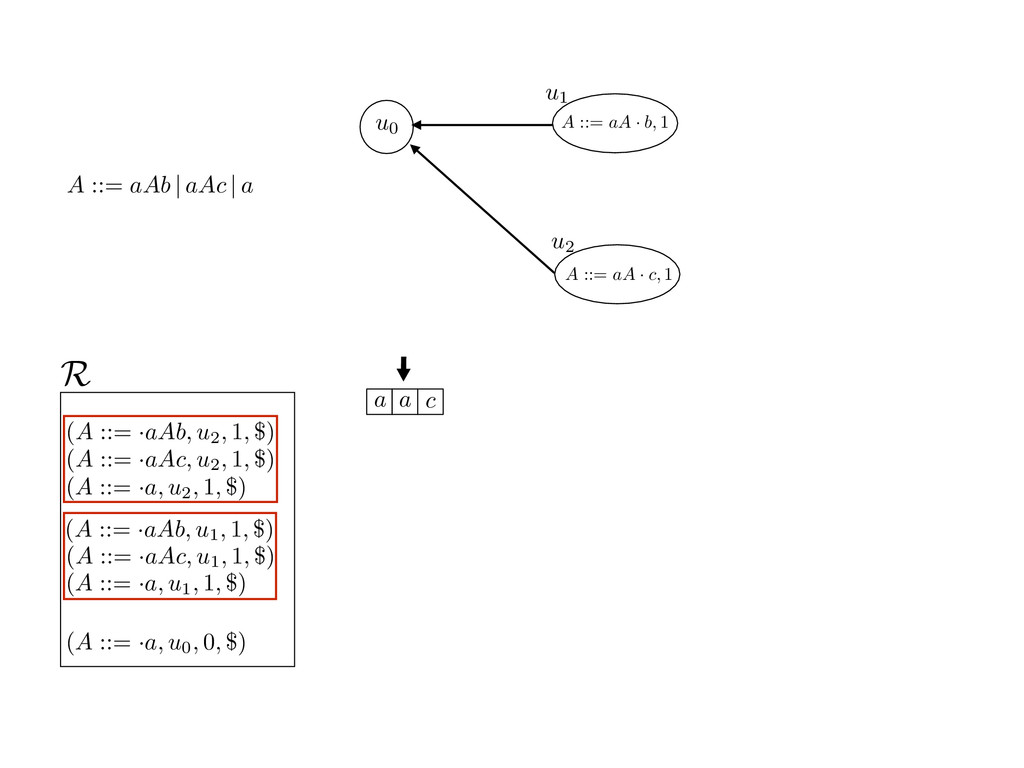
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 (A ::= ·aAb, u2, 1, $) (A ::= ·aAc, u2, 1, $) (A ::= ·a, u2, 1, $) -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 (A ::= ·aAb, u2, 1, $) (A ::= ·aAc, u2, 1, $) (A ::= ·a, u2, 1, $) -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 (A ::= ·aAb, u2, 1, $) (A ::= ·aAc, u2, 1, $) (A ::= ·a, u2, 1, $) -
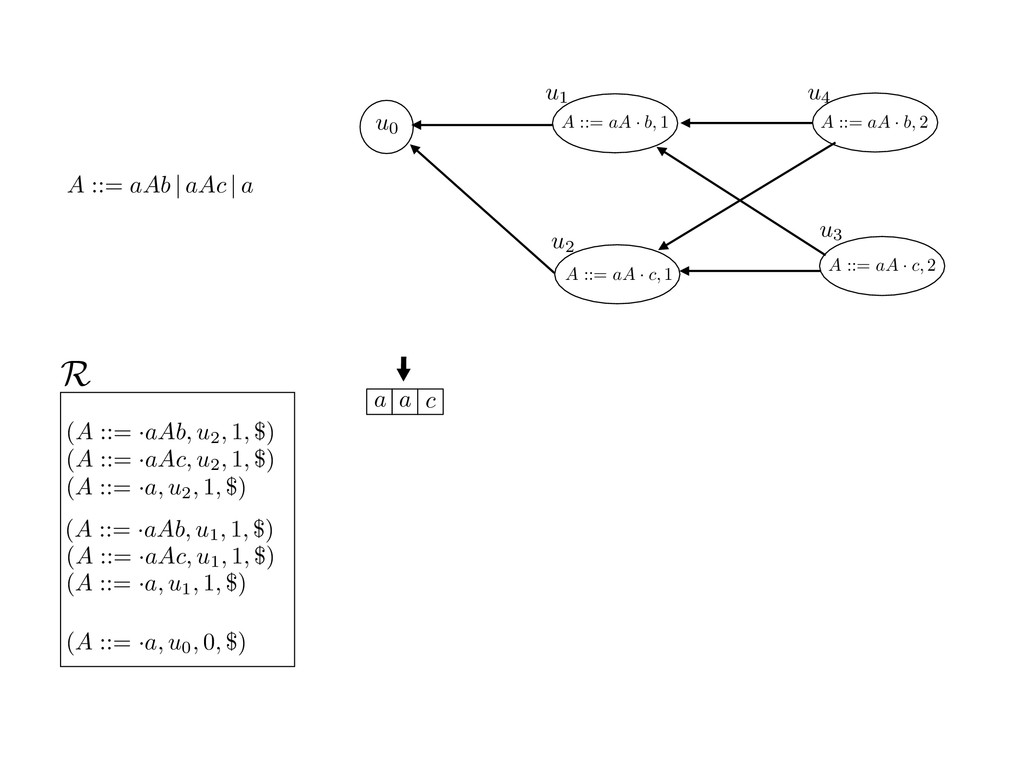
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 (A ::= ·aAb, u2, 1, $) (A ::= ·aAc, u2, 1, $) (A ::= ·a, u2, 1, $) A ::= aA · b, 2 A ::= aA · c, 2 u3 u4 -
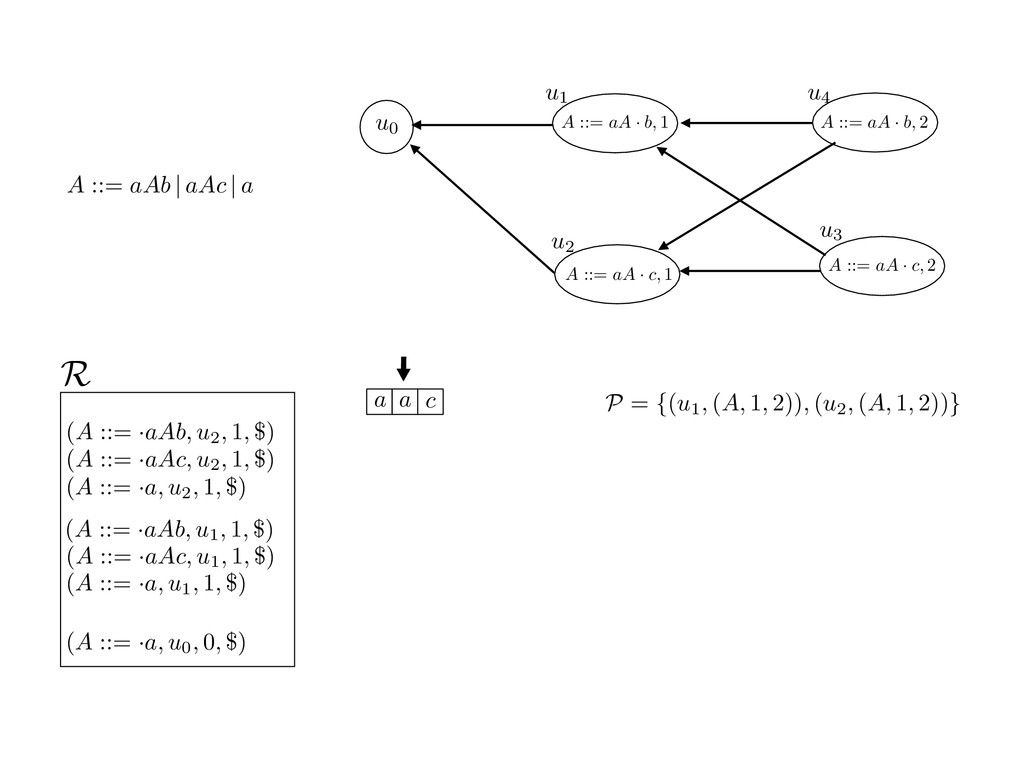
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) u0 A ::= aAb | aAc | a a a c R A ::= aA · b, 1 u1 u2 A ::= aA · c, 1 (A ::= ·aAb, u2, 1, $) (A ::= ·aAc, u2, 1, $) (A ::= ·a, u2, 1, $) A ::= aA · b, 2 A ::= aA · c, 2 u3 u4 P = {(u1, (A, 1, 2)), (u2, (A, 1, 2))} -
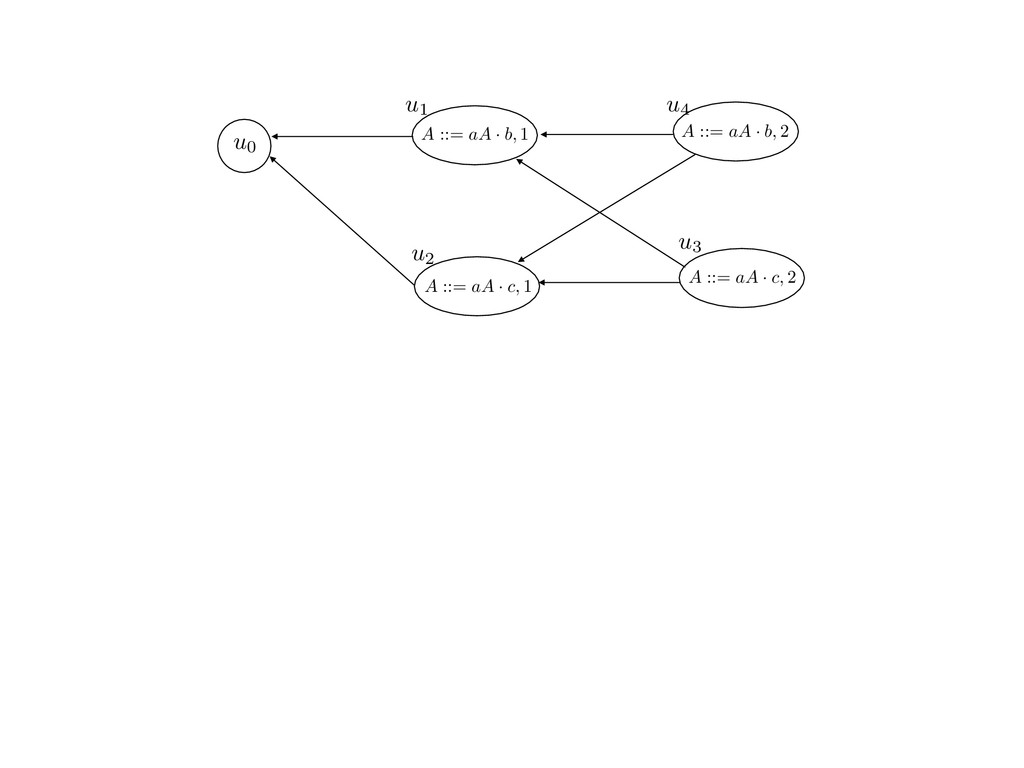
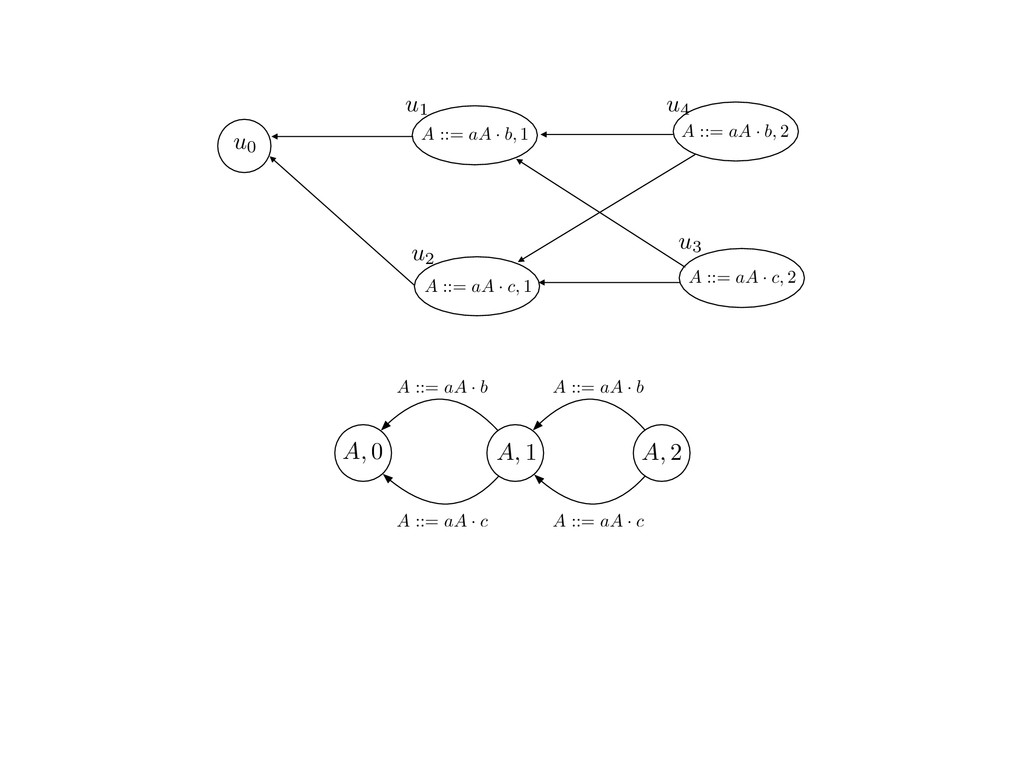
A ::= aA · b, 1 u1 u2 A ::=
aA · c, 1 A ::= aA · b, 2 A ::= aA · c, 2 u3 u4 u0 -
A ::= aA · b, 1 u1 u2 A ::=
aA · c, 1 A ::= aA · b, 2 A ::= aA · c, 2 u3 u4 u0 A, 2 A, 1 A, 0 A ::= aA · b A ::= aA · b A ::= aA · c A ::= aA · c -
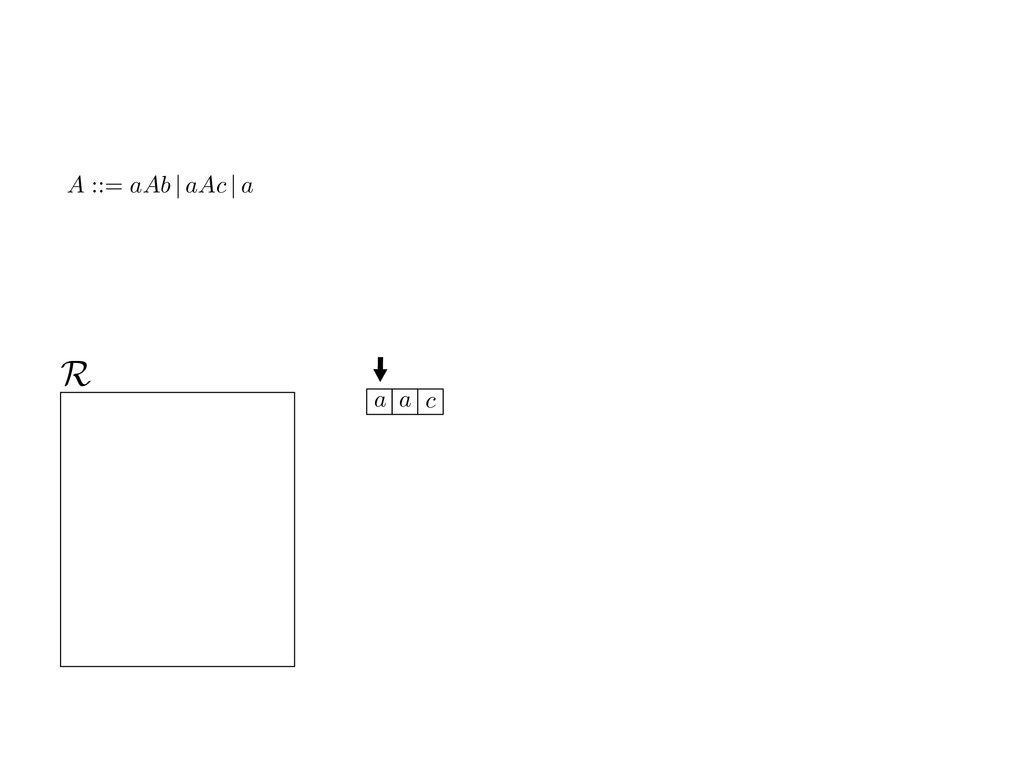
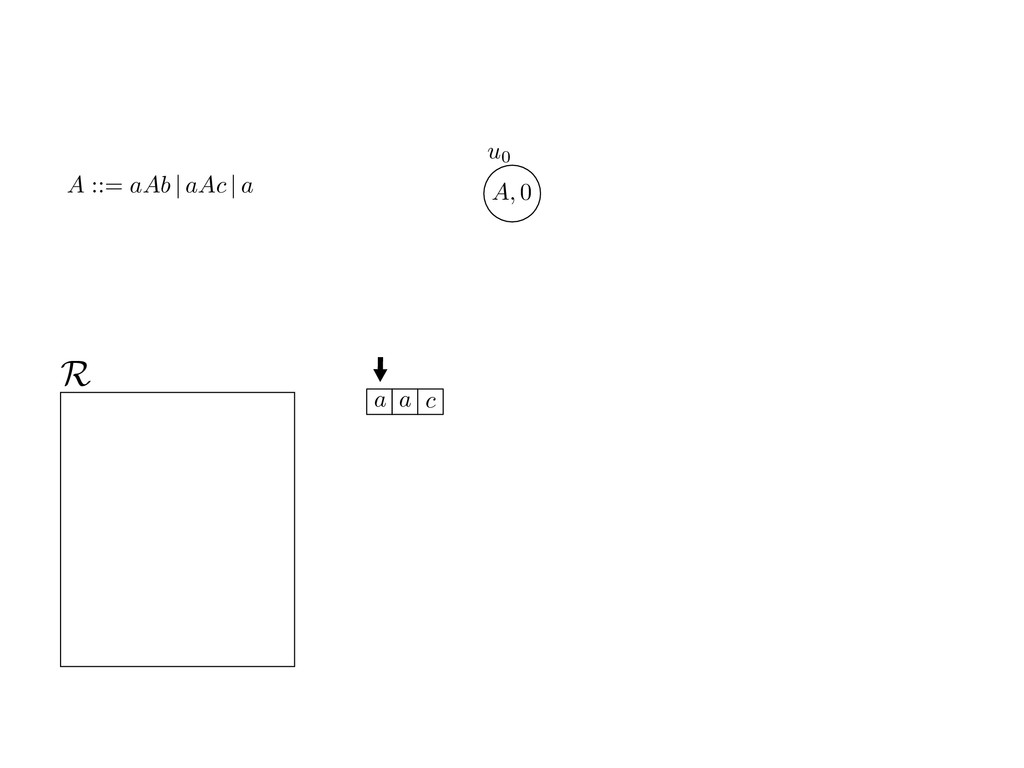
A ::= aAb | aAc | a a a c
R A, 0 u0 -
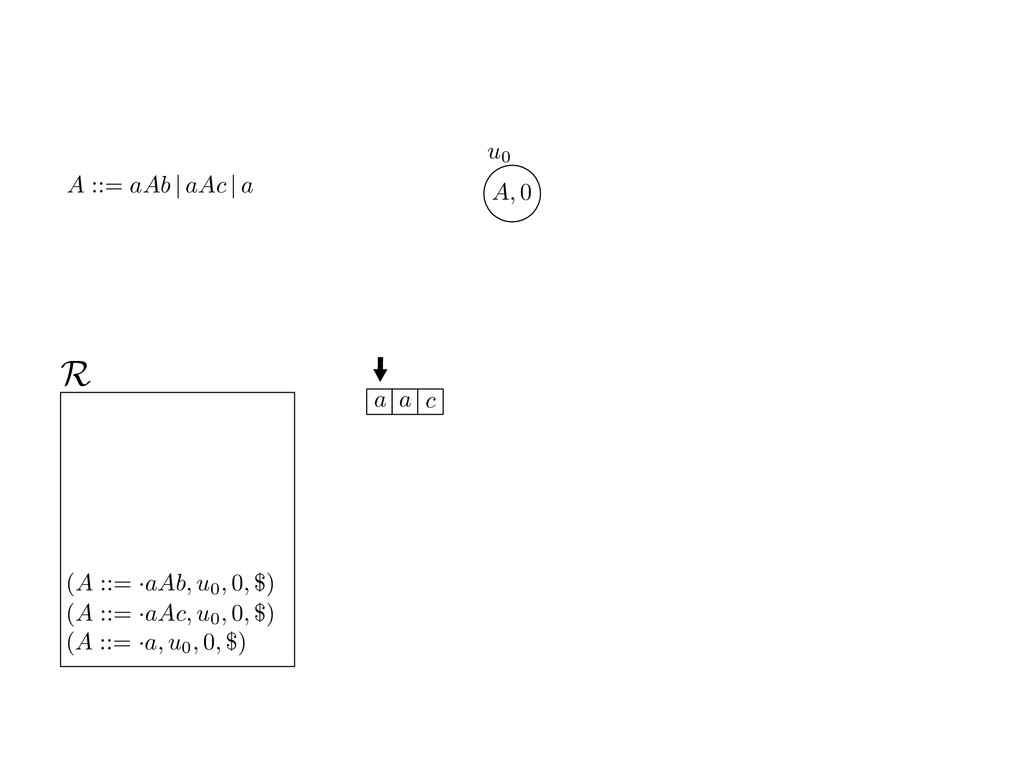
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) A ::= aAb | aAc | a a a c R A, 0 u0 -
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) A ::= aAb | aAc | a a a c R A, 0 u0 -
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) A ::= aAb | aAc | a a a c R A, 0 u0 -
(A ::= ·aAb, u0, 0, $) (A ::= ·aAc, u0,
0, $) (A ::= ·a, u0, 0, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 -
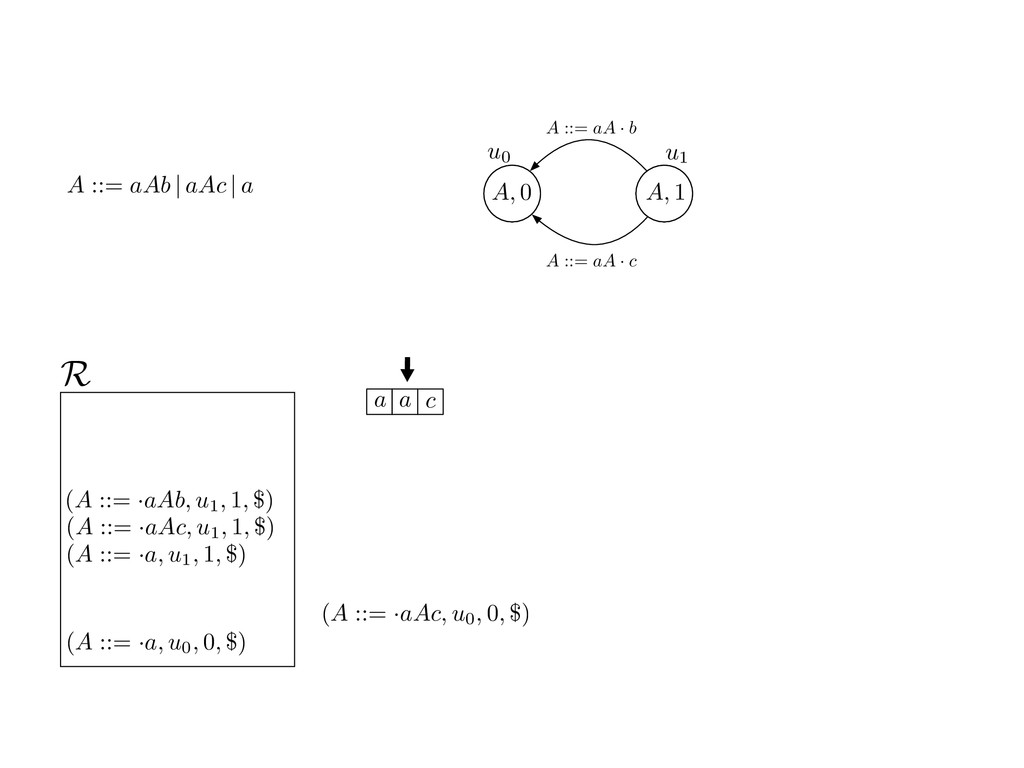
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 -
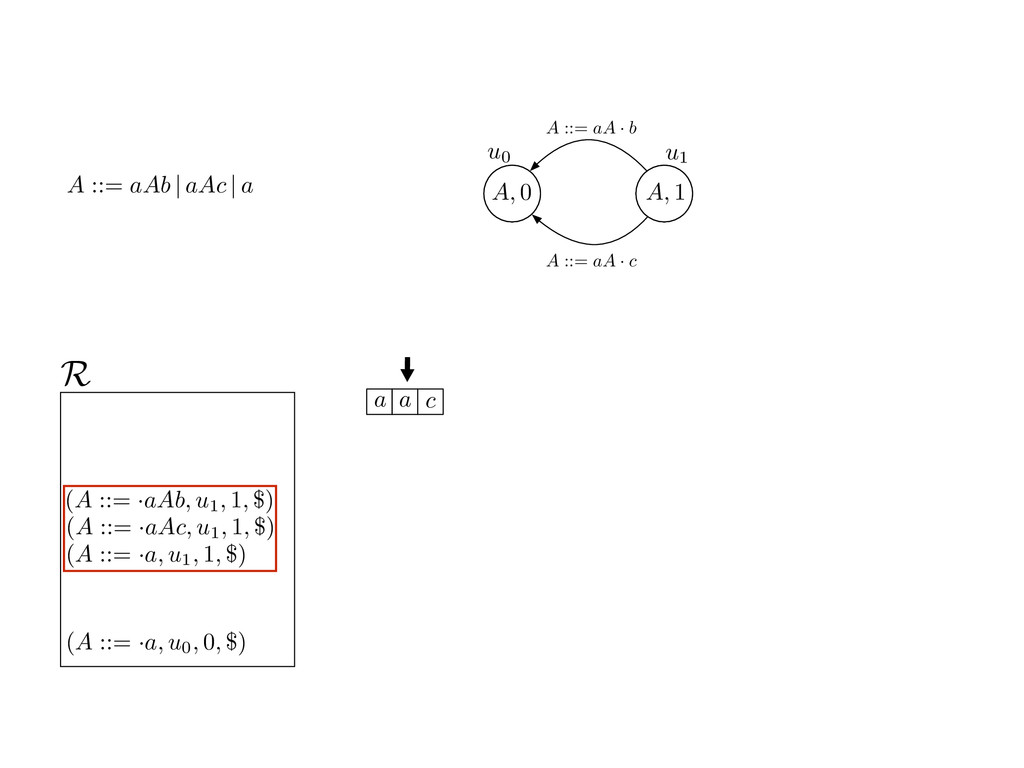
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 -
(A ::= ·aAc, u0, 0, $) (A ::= ·a, u0,
0, $) (A ::= ·a, u1, 1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 A, 1 A, 0 A ::= aA · c -
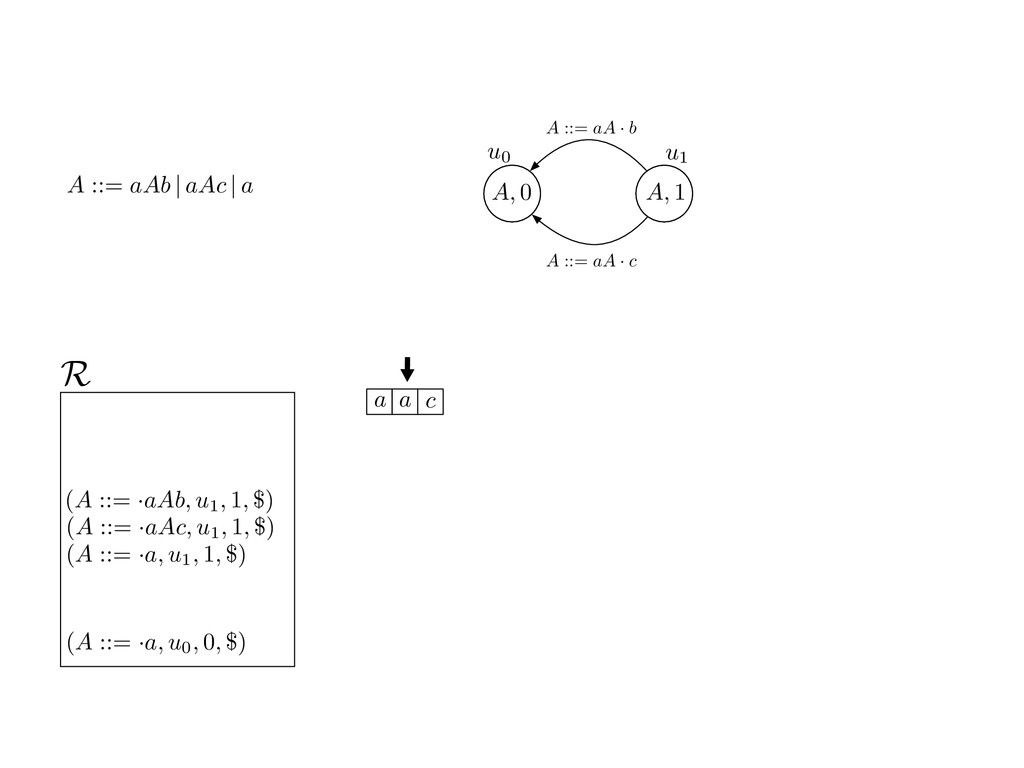
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 A, 1 A, 0 A ::= aA · c -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 A, 1 A, 0 A ::= aA · c -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 1 A, 0 A ::= aA · b u1 u0 A, 1 A, 0 A ::= aA · c -
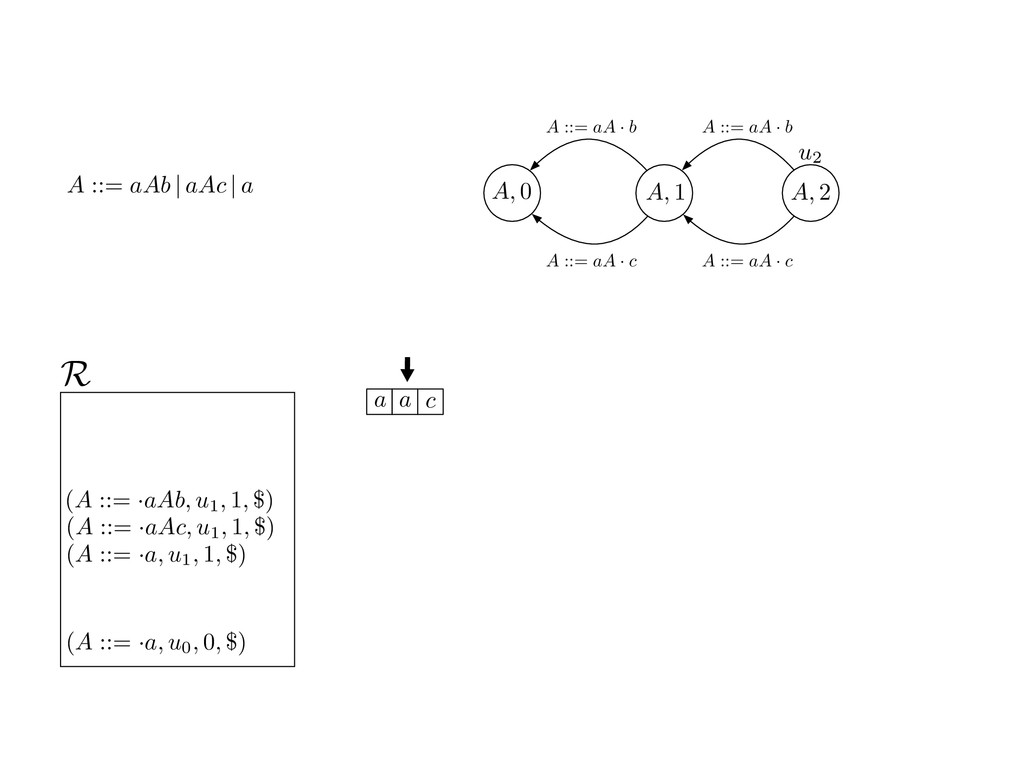
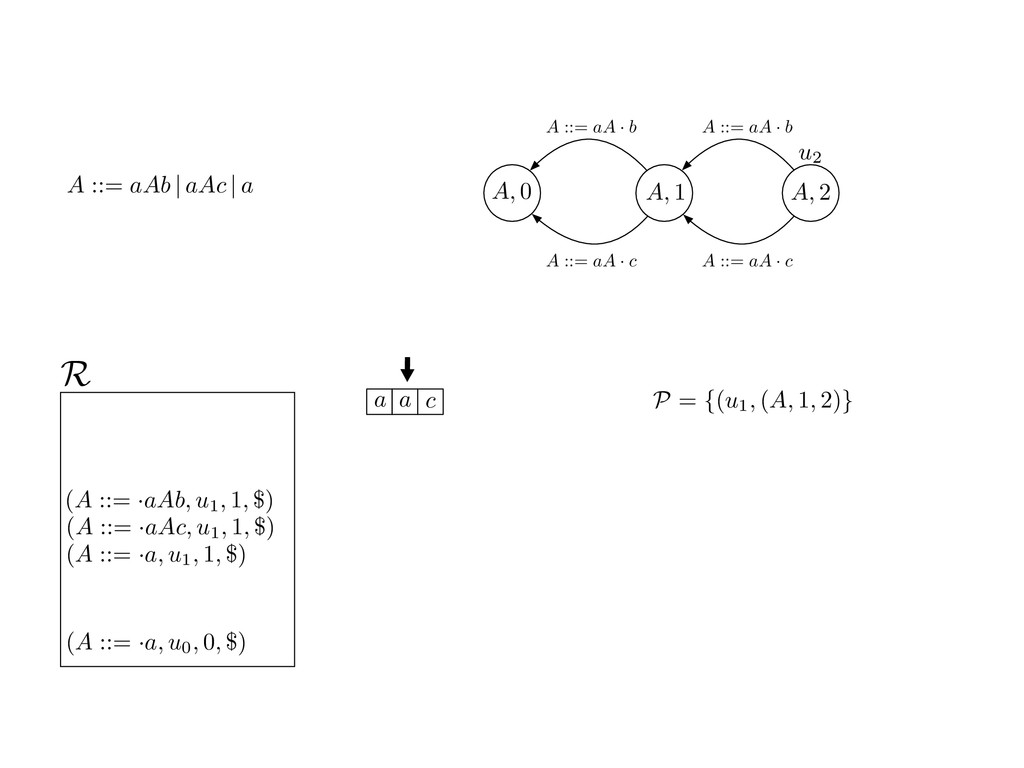
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 2 A, 1 A, 0 A ::= aA · b A ::= aA · b A ::= aA · c A ::= aA · c u2 -
(A ::= ·a, u0, 0, $) (A ::= ·a, u1,
1, $) (A ::= ·aAb, u1, 1, $) (A ::= ·aAc, u1, 1, $) A ::= aAb | aAc | a a a c R A, 2 A, 1 A, 0 A ::= aA · b A ::= aA · b A ::= aA · c A ::= aA · c u2 P = {(u1, (A, 1, 2)} -
Acknowledgement Alex ten Brink proposed the same modification to the
GSS in GLL recognizers. -
Hash tables local to GSS nodes • GSS node as
a common element • Faster hash code calculation • Fewer hash collisions -
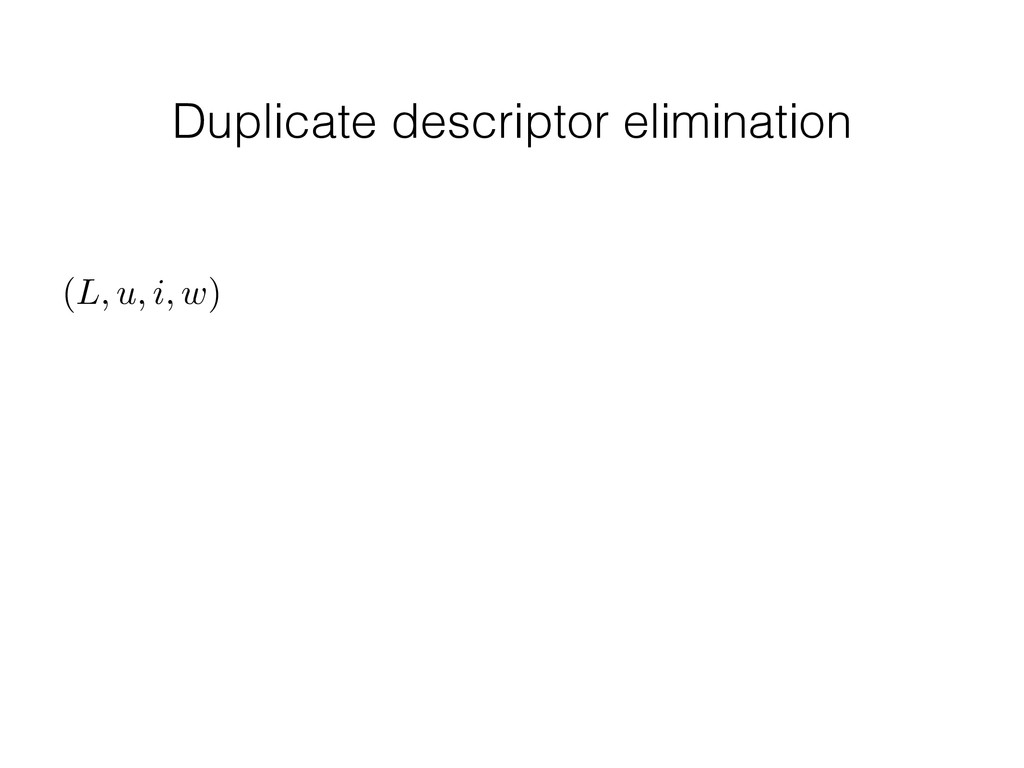
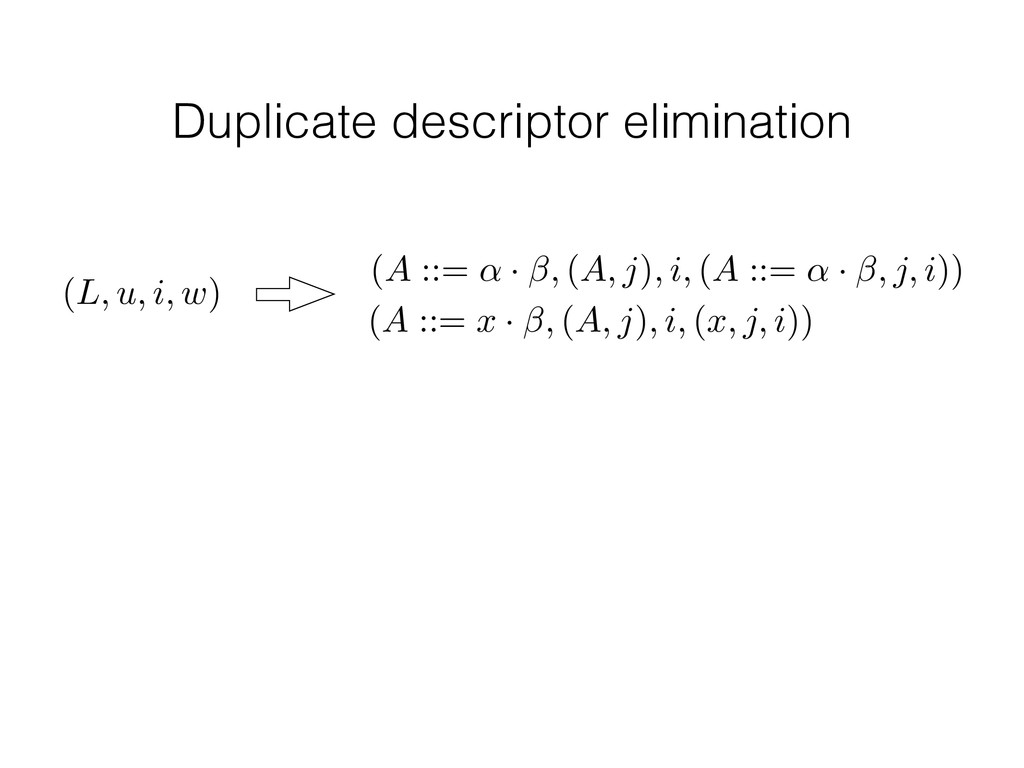
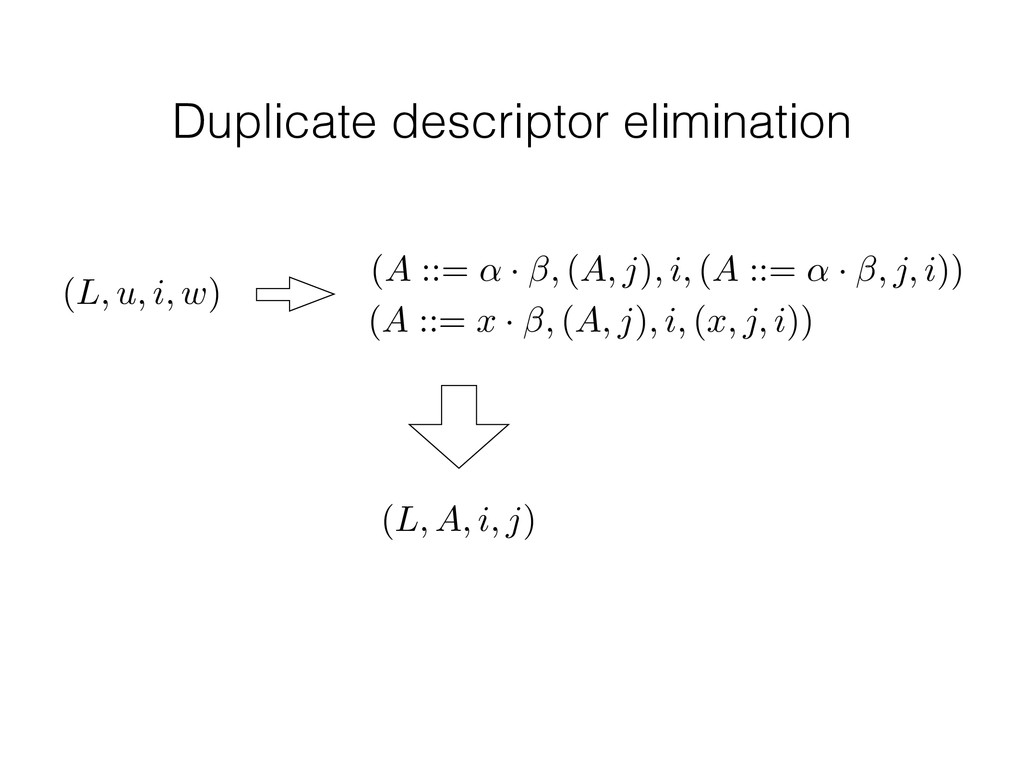
Duplicate descriptor elimination (L, u, i, w) (A ::= ↵
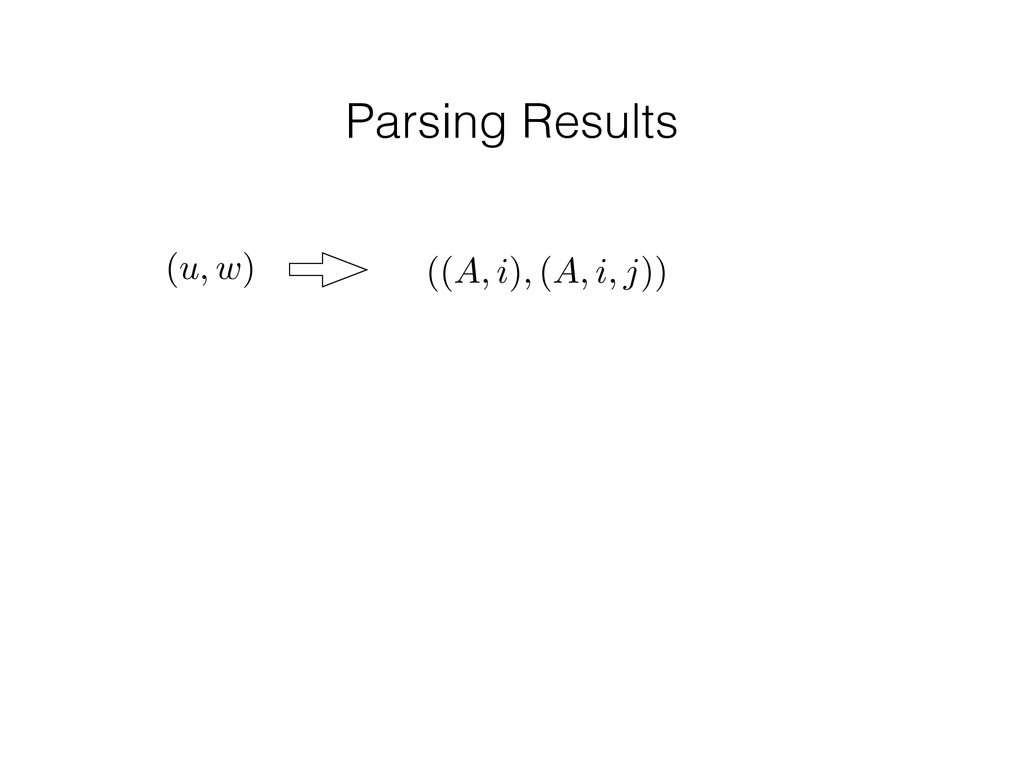
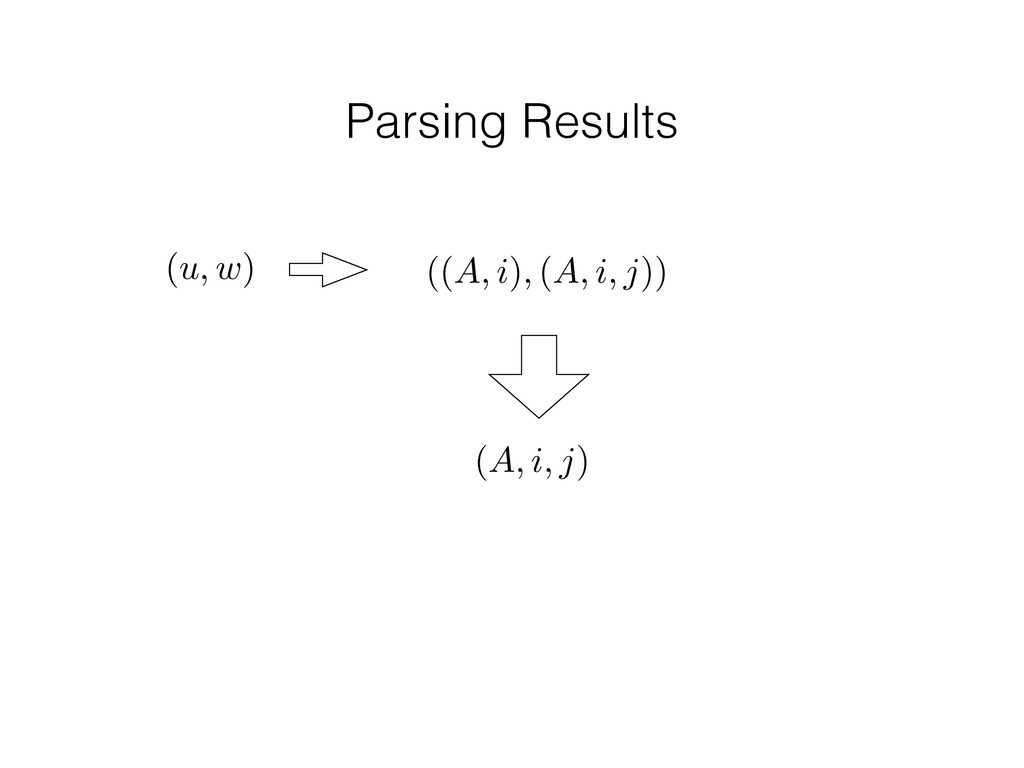
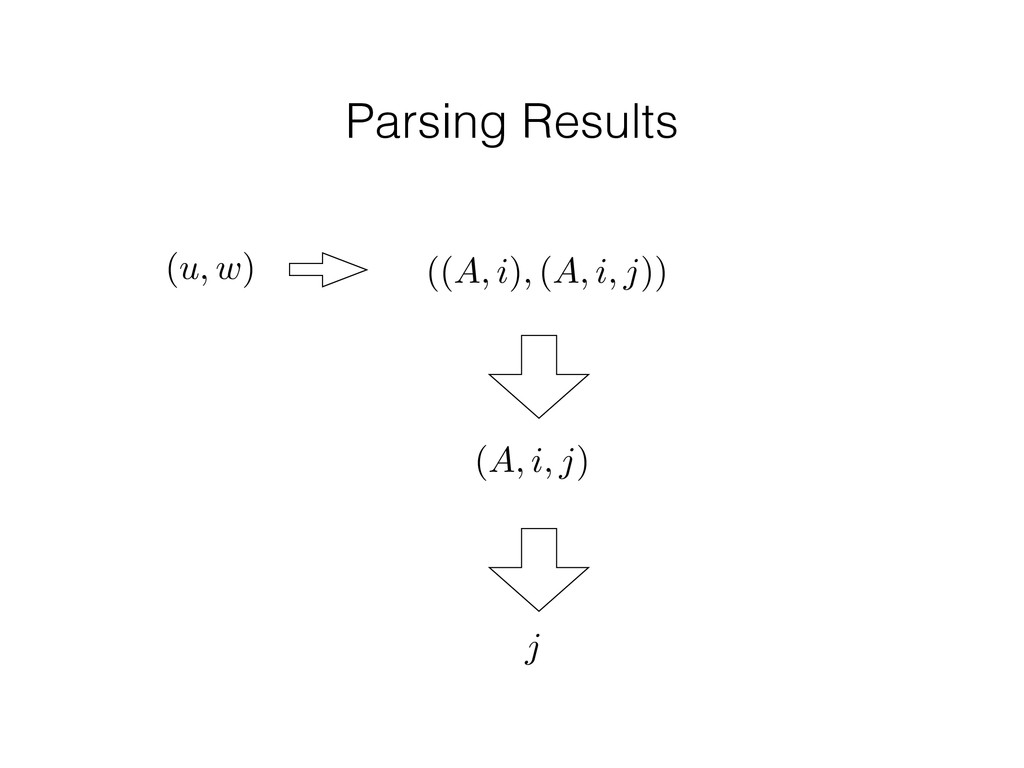
· , (A, j), i, (A ::= ↵ · , j, i)) ( A ::= x · , ( A, j ) , i, ( x, j, i )) -
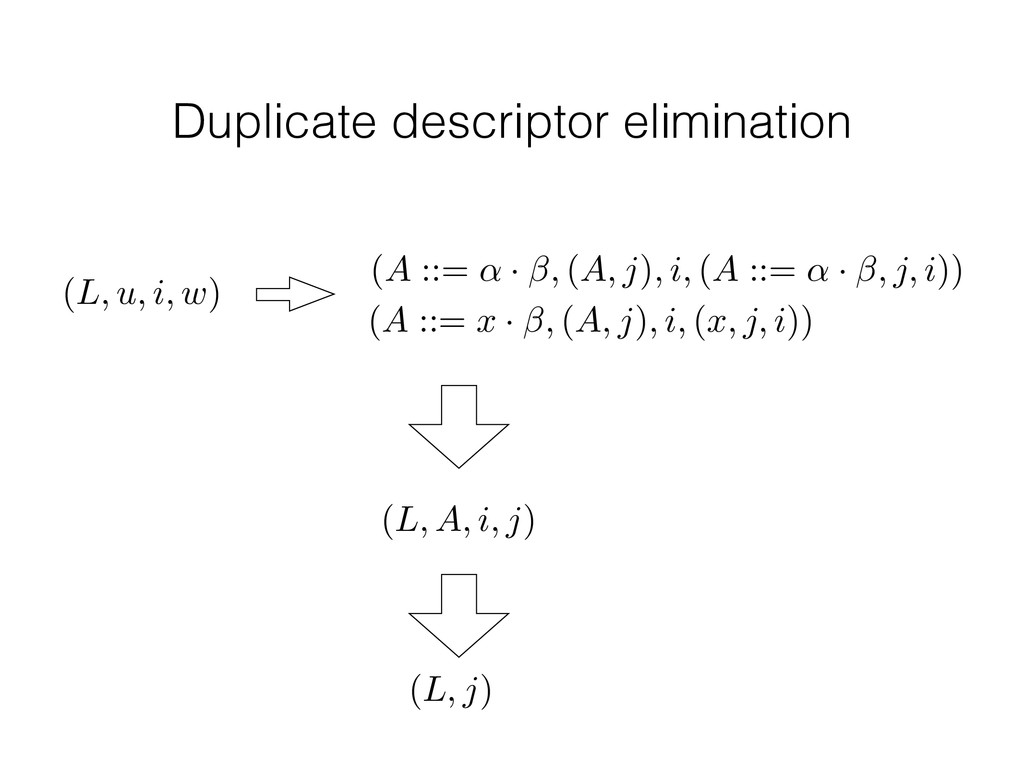
Duplicate descriptor elimination (L, u, i, w) (L, A, i,
j) (A ::= ↵ · , (A, j), i, (A ::= ↵ · , j, i)) ( A ::= x · , ( A, j ) , i, ( x, j, i )) -
Duplicate descriptor elimination (L, u, i, w) (L, j) (L,
A, i, j) (A ::= ↵ · , (A, j), i, (A ::= ↵ · , j, i)) ( A ::= x · , ( A, j ) , i, ( x, j, i )) -
adapted from [14]. This grammar defines a Term as either
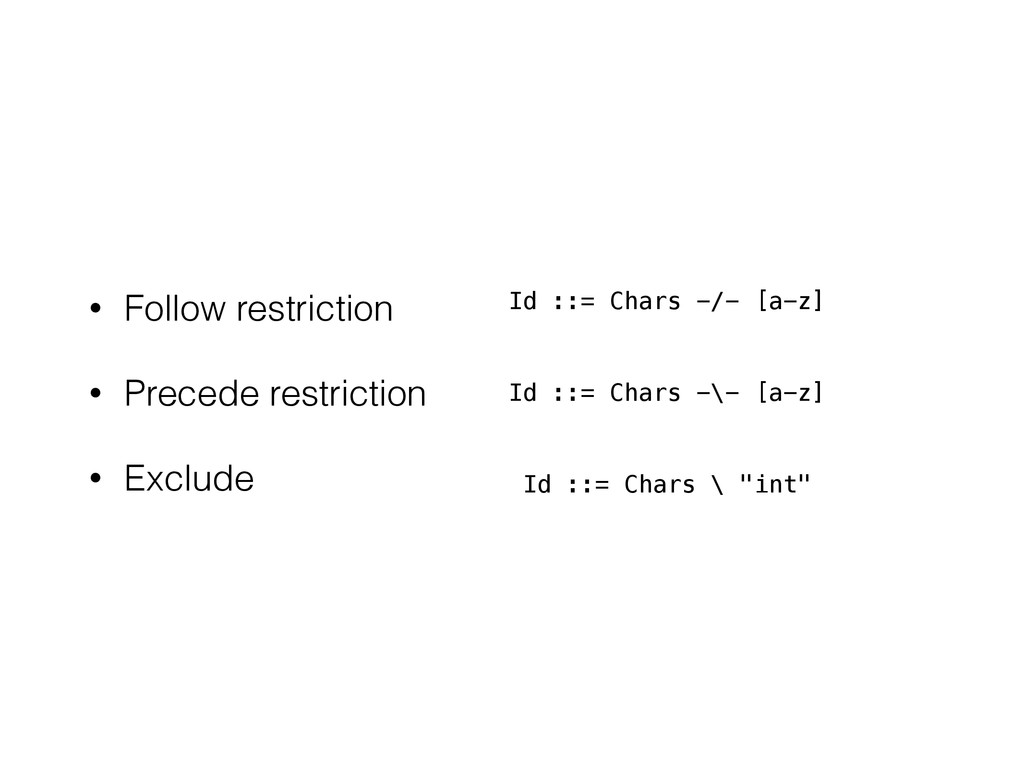
a sequence of two erms, an identifier, a number, or the keyword "int". Id is defined as one or more repetition of a single character, and WS defines a possibly empty blank. Term ::= Term WS Term | Id | Num | "int" Id ::= Chars Chars ::= Chars Char | Char Char ::= ' a ' | .. | ' z ' Num ::= ' 1 ' | .. | ' 9 ' WS ::= ' ' | ✏ his grammar is ambiguous. For example, the input string "hi" can be parsed s either Term(Id("hi")), or Term(Term(Id("h")),Term(Id("i"))). Follow- ng the longest match rule, the first derivation is the intended one, as in the sec- nd one "h" is recognized as an identifier, while it is followed by "i". We can use follow restriction ( / ) to disallow an identifier to be followed by another char- cter: Id ::= Chars -/- Char. Another ambiguity occurs in the input string intx" which can be parsed as either Term(Id("intx")) or Term(Term("int"), erm(Id("x"))). We can solve this problem by adding a precede restriction ( \ ) s follows: Id ::= Char -\- Chars, specifying that Id cannot be preceded by character. Finally, we should exclude the recognition of "int" as Id. For this, e use an exclusion rule: Id ::= Chars \"int". Below we formally define each of these restrictions and show how they can be van den Brand et al. 2002 -
adapted from [14]. This grammar defines a Term as either
a sequence of two erms, an identifier, a number, or the keyword "int". Id is defined as one or more repetition of a single character, and WS defines a possibly empty blank. Term ::= Term WS Term | Id | Num | "int" Id ::= Chars Chars ::= Chars Char | Char Char ::= ' a ' | .. | ' z ' Num ::= ' 1 ' | .. | ' 9 ' WS ::= ' ' | ✏ his grammar is ambiguous. For example, the input string "hi" can be parsed s either Term(Id("hi")), or Term(Term(Id("h")),Term(Id("i"))). Follow- ng the longest match rule, the first derivation is the intended one, as in the sec- nd one "h" is recognized as an identifier, while it is followed by "i". We can use follow restriction ( / ) to disallow an identifier to be followed by another char- cter: Id ::= Chars -/- Char. Another ambiguity occurs in the input string intx" which can be parsed as either Term(Id("intx")) or Term(Term("int"), erm(Id("x"))). We can solve this problem by adding a precede restriction ( \ ) s follows: Id ::= Char -\- Chars, specifying that Id cannot be preceded by character. Finally, we should exclude the recognition of "int" as Id. For this, e use an exclusion rule: Id ::= Chars \"int". Below we formally define each of these restrictions and show how they can be “hi": Term(Term(Id("h")), Term(Id("i"))) Term(Id("hi")) van den Brand et al. 2002 -
adapted from [14]. This grammar defines a Term as either
a sequence of two erms, an identifier, a number, or the keyword "int". Id is defined as one or more repetition of a single character, and WS defines a possibly empty blank. Term ::= Term WS Term | Id | Num | "int" Id ::= Chars Chars ::= Chars Char | Char Char ::= ' a ' | .. | ' z ' Num ::= ' 1 ' | .. | ' 9 ' WS ::= ' ' | ✏ his grammar is ambiguous. For example, the input string "hi" can be parsed s either Term(Id("hi")), or Term(Term(Id("h")),Term(Id("i"))). Follow- ng the longest match rule, the first derivation is the intended one, as in the sec- nd one "h" is recognized as an identifier, while it is followed by "i". We can use follow restriction ( / ) to disallow an identifier to be followed by another char- cter: Id ::= Chars -/- Char. Another ambiguity occurs in the input string intx" which can be parsed as either Term(Id("intx")) or Term(Term("int"), erm(Id("x"))). We can solve this problem by adding a precede restriction ( \ ) s follows: Id ::= Char -\- Chars, specifying that Id cannot be preceded by character. Finally, we should exclude the recognition of "int" as Id. For this, e use an exclusion rule: Id ::= Chars \"int". Below we formally define each of these restrictions and show how they can be “hi": Term(Term(Id("h")), Term(Id("i"))) Term(Id("hi")) “intx": Term(Id("intx")) Term(Term("int"), Term(Id("x"))) van den Brand et al. 2002 -
adapted from [14]. This grammar defines a Term as either
a sequence of two erms, an identifier, a number, or the keyword "int". Id is defined as one or more repetition of a single character, and WS defines a possibly empty blank. Term ::= Term WS Term | Id | Num | "int" Id ::= Chars Chars ::= Chars Char | Char Char ::= ' a ' | .. | ' z ' Num ::= ' 1 ' | .. | ' 9 ' WS ::= ' ' | ✏ his grammar is ambiguous. For example, the input string "hi" can be parsed s either Term(Id("hi")), or Term(Term(Id("h")),Term(Id("i"))). Follow- ng the longest match rule, the first derivation is the intended one, as in the sec- nd one "h" is recognized as an identifier, while it is followed by "i". We can use follow restriction ( / ) to disallow an identifier to be followed by another char- cter: Id ::= Chars -/- Char. Another ambiguity occurs in the input string intx" which can be parsed as either Term(Id("intx")) or Term(Term("int"), erm(Id("x"))). We can solve this problem by adding a precede restriction ( \ ) s follows: Id ::= Char -\- Chars, specifying that Id cannot be preceded by character. Finally, we should exclude the recognition of "int" as Id. For this, e use an exclusion rule: Id ::= Chars \"int". Below we formally define each of these restrictions and show how they can be “hi": Term(Term(Id("h")), Term(Id("i"))) Term(Id("hi")) “intx": Term(Id("intx")) Term(Term("int"), Term(Id("x"))) "int" Term(Id(“int”)) Term(“int”) van den Brand et al. 2002 -
• Follow restriction • Precede restriction • Exclude Id ::=
Chars -/- [a-z] Id ::= Chars -\- [a-z] Id ::= Chars \ "int" -
A ::= a A -/- [x] b A, 1 A,
0 A ::= aA · b u1 u0 A, 1 A, 0 A ::= aA · c | a A c | a -
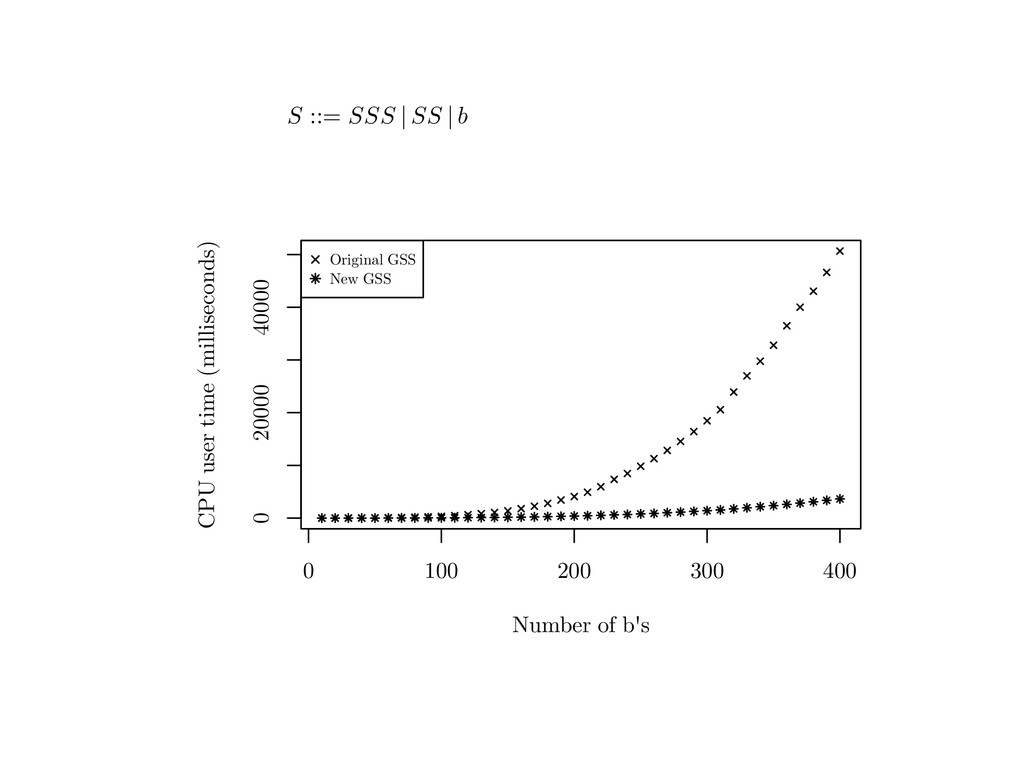
0 100 200 300 400 0 20000 40000 Number of
b's CPU user time (milliseconds) Original GSS New GSS S ::= SSS | SS | b -
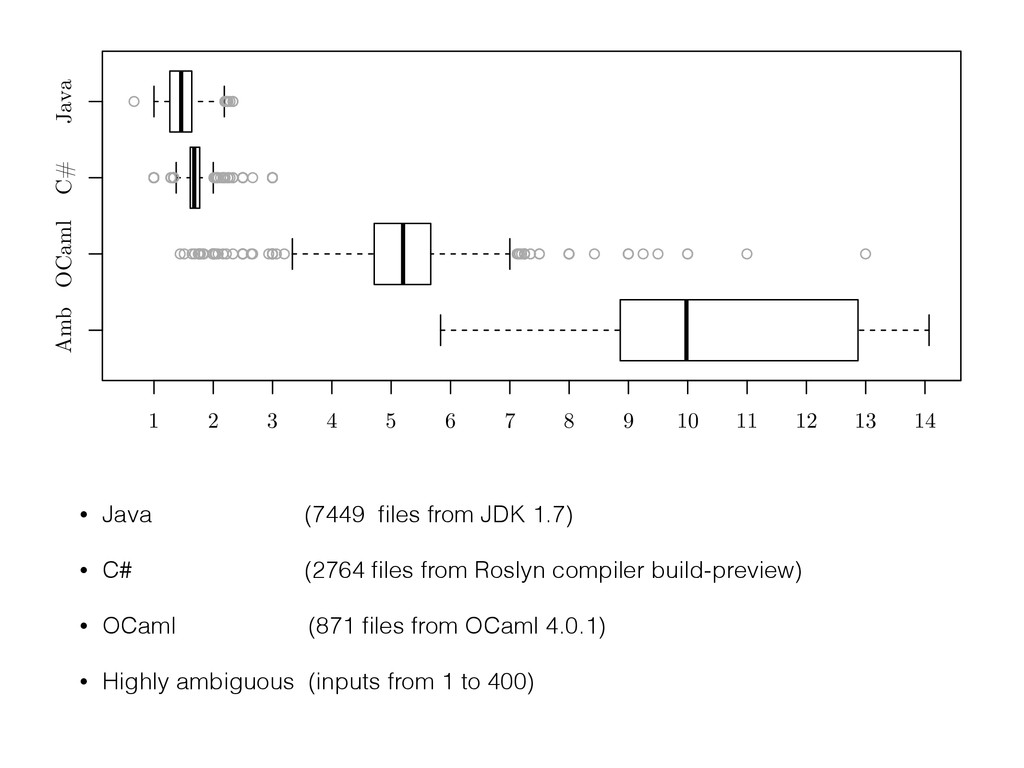
• • • • • • • • • •
• • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • •• • • • • • • • • • • • • • • • • • • • • • • • •• • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • • ••• • • • • • • • • • • • Amb OCaml C# Java 1 2 3 4 5 6 7 8 9 10 11 12 13 14 • Java (7449 files from JDK 1.7) • C# (2764 files from Roslyn compiler build-preview) • OCaml (871 files from OCaml 4.0.1) • Highly ambiguous (inputs from 1 to 400) -
“Invasive Green Iguana in Grand CaymanSascha” by Grabow www.saschagrabow.com -
CC BY-SA 3.0 https://github.com/cwi-swat/iguana
 afroozeh
 sishi2026
 institutdelelevage
 ishiirikie
 yukiar
 kanojikajino
 dk999
 hirachan
 rikkabotan7
 resolutionfoundation
 imai448
 takasehideki
 marktimemedia
 katiecoart
 techseoconnect
 akosma
 jlugia
 thirion
 mlcsv
 carmenintech
 reverentgeek
 sabderemane
 stephenakadiri